Search Results: "cas"

20 November 2015

Sylvain Beucler: Rebuilding Android proprietary SDK binaries

Going back to Android recently, I saw that all tools binaries from the Android project are now click-wrapped by a quite ugly proprietary license, among others an anti-fork clause (details below). Apparently those T&C are years old, but the click-wrapping is newer. This applies to the SDK, the NDK, Android Studio, and all the essentials you download through the Android SDK Manager. Since I keep my hands clean of smelly EULAs, I'm working on rebuilding the Android tools I need.
We're talking about hours-long, quad-core + 8GB-RAM + 100GB-disk-eating builds here, so I'd like to publish them as part of a project who cares. As a proof-of-concept, the Replicant project ships a 4.2 SDK and I contributed build instructions for ADT and NDK (which I now use daily). (Replicant is currently stuck to a 2013 code base though.) I also have in-progress instructions on my hard-drive to rebuild various newer versions of the SDK/API levels, and for the NDK whose releases are quite hard to reproduce (no git tags, requires fixes committed after the release, updates are partial rebuilds, etc.) - not to mention that Google doesn't publish the source code until after the official release (closed development) :/ And in some cases like Android Support Repository [not Library] I didn't even find the proper source code, only an old prebuilt. Would you be interested in contributing, and would you recommend a structure that would promote Free, rebuilt Android *DK? The legalese Anti-fork clause:
3.4 You agree that you will not take any actions that may cause or result in the fragmentation of Android, including but not limited to distributing, participating in the creation of, or promoting in any way a software development kit derived from the SDK.
So basically the source is Apache 2 + GPL, but the binaries are non-free. By the way this is not a GPL violation because right after:
3.5 Use, reproduction and distribution of components of the SDK licensed under an open source software license are governed solely by the terms of that open source software license and not this License Agreement.
Still, AFAIU by clicking "Accept" to get the binary you still accept the non-free "Terms and Conditions". (Incidentally, if Google wanted SDK forks to spread and increase fragmentation, introducing an obnoxious EULA is probably the first thing I'd have recommended. What was its legal team thinking?) Indemnification clause:
12.1 To the maximum extent permitted by law, you agree to defend, indemnify and hold harmless Google, its affiliates and their respective directors, officers, employees and agents from and against any and all claims, actions, suits or proceedings, as well as any and all losses, liabilities, damages, costs and expenses (including reasonable attorneys fees) arising out of or accruing from (a) your use of the SDK, (b) any application you develop on the SDK that infringes any copyright, trademark, trade secret, trade dress, patent or other intellectual property right of any person or defames any person or violates their rights of publicity or privacy, and (c) any non-compliance by you with this License Agreement.
Usage restriction:
3.1 Subject to the terms of this License Agreement, Google grants you a limited, worldwide, royalty-free, non-assignable and non-exclusive license to use the SDK solely to develop applications to run on the Android platform. 3.3 You may not use the SDK for any purpose not expressly permitted by this License Agreement. Except to the extent required by applicable third party licenses, you may not: (a) copy (except for backup purposes), modify, adapt, redistribute, decompile, reverse engineer, disassemble, or create derivative works of the SDK or any part of the SDK; or (b) load any part of the SDK onto a mobile handset or any other hardware device except a personal computer, combine any part of the SDK with other software, or distribute any software or device incorporating a part of the SDK.
If you know the URLs, you can still direct-download some of the binaries which don't embed the license, but all this feels fishy. GNU licensing didn't answer me (yet). Maybe debian-legal has an opinion? In any case, the difficulty to reproduce the *DK builds is worrying enough to warrant an independent rebuild. Did you notice this?

Timo Jyrinki: Converting an existing installation to LUKS using luksipc

This is a burst of notes that I wrote in an e-mail in June when asked about it, and I'm not going to have any better steps since I don't remember even that amount as back then. I figured it's better to have it out than not.

So... if you want to use LUKS In-Place Conversion Tool, the notes below on converting a shipped-with-Ubuntu Dell XPS 13 Developer Edition (2015 Intel Broadwell model) may help you. There were a couple of small learnings to be had...

The page http://www.johannes-bauer.com/linux/luksipc/ itself is good and without errors, although funnily uses reiserfs as an example. It was only a bit unclear why I did save the initial_keyfile.bin since it was then removed in the next step (I guess it's for the case you want to have a recovery file hidden somewhere in case you forget the passphrase).

For using the tool I booted from a 14.04.2 LTS USB live image and operated there, including downloading and compiling luksipc in the live session. The exact reason of resizing before luksipc was a bit unclear to me at first so I simply indeed resized the main rootfs partition and left unallocated space in the partition table.


Then finally I ran ./luksipc -d /dev/sda4 etc.


I realized I want /boot to be on an unencrypted partition to be able to load the kernel + initrd from grub before entering into LUKS unlocking. I couldn't resize the luks partition anymore since it was encrypted... So I resized what I think was the empty small DIAGS partition (maybe used for some system diagnostic or something, I don't know), or possibly the next one that is the actual recovery partition one can reinstall the pre-installed Ubuntu from. And naturally I had some problems because it seems vfatresize tool didn't do what I wanted it to do and gparted simply crashed when I tried to use it first to do the same. Anyway, when done with getting some extra free space somewhere, I used the remaining 350MB for /boot where I copied the rootfs's /boot contents to.

After adding the passphrase in luks I had everything encrypted etc and decryptable, but obviously I could only access it from a live session by manual cryptsetup luksOpen + mount /dev/mapper/myroot commands. I needed to configure GRUB, and I needed to do it with the grub-efi-amd64 which was a bit unfamiliar to me. There's also grub-efi-amd64-signed I have installed now but I'm not sure if it was required for the configuration. Secure boot is not enabled by default in BIOS so maybe it isn't needed.


I did GRUB installation I think inside rootfs chroot where I also mounted /dev/sda6 as /boot (inside the rootfs chroot), ie mounted dev, sys with -o bind to under the chroot (from outside chroot) and mount -t proc proc proc too. I did a lot of trial and effort so I surely also tried from outside the chroot, in the live session, using some parameters to point to the mounted rootfs's directories...


I needed to definitely install cryptsetup etc inside the encrypted rootfs with apt, and I remember debugging for some time if they went to the initrd correctly after I executed mkinitramfs/update-initramfs inside the chroot.


At the end I had grub asking for the password correctly at bootup. Obviously I had edited the rootfs's /etc/fstab to include the new /boot partition, I changed / to be "UUID=/dev/mapper/myroot / ext4 errors=remount-ro 0 ", kept /boot/efi as coming from the /dev/sda1 and so on. I had also added "myroot /dev/sda4 none luks" to /etc/crypttab. I seem to also have GRUB_CMDLINE_LINUX="cryptdevice=/dev/sda4:myroot root=/dev/mapper/myroot" in /etc/default/grub.

The only thing I did save from the live session was the original partition table if I want to revert.


So the original was:

Found valid GPT with protective MBR; using GPT.
Disk /dev/sda: 500118192 sectors, 238.5 GiB
Logical sector size: 512 bytes
...
First usable sector is 34, last usable sector is 500118158
Partitions will be aligned on 2048-sector boundaries
Total free space is 6765 sectors (3.3 MiB)

Number Start (sector) End (sector) Size Code Name
1 2048 1026047 500.0 MiB EF00 EFI system partition
2 1026048 1107967 40.0 MiB FFFF Basic data partition
3 1107968 7399423 3.0 GiB 0700 Basic data partition
4 7399424 467013631 219.2 GiB 8300
5 467017728 500117503 15.8 GiB 8200

And I now have:


Number Start (sector) End (sector) Size Code Name

1 2048 1026047 500.0 MiB EF00 EFI system partition
2 1026048 1107967 40.0 MiB FFFF Basic data partition
3 1832960 7399423 2.7 GiB 0700 Basic data partition
4 7399424 467013631 219.2 GiB 8300
5 467017728 500117503 15.8 GiB 8200
6 1107968 1832959 354.0 MiB 8300

So it seems I did not edit DIAGS (and it was also originally just 40MB) but did something with the recovery partition while preserving its contents. It's a FAT partition so maybe I was able to somehow resize it after all.


The 16GB partition is the default swap partition. I did not encrypt it at least yet, I tend to not run into swap anyway ever in my normal use with the 8GB RAM.


If you go this route, good luck! :D

Pau Garcia i Quiles: Desktops DevRoom @ FOSDEM 2016: Have you submitted your talk yet?

FOSDEM 2016 is going to be great (again!) and you still have the chance to be one of the stars. Have you submitted your talk to the Desktops DevRoom yet? No? Remember: we will only accept proposals until December 6th. After that, the Organization Team will get busy and vote and choose the talks. Here is the full Call for Participation, in case you need to check the details on how to submit: FOSDEM Desktops DevRoom 2016 Call for Participation Topics include anything related to the Desktop: desktop environments, software development for desktop/cross-platform, applications, UI, etc

17 November 2015

Sven Hoexter: Failing with F5: assign a http profile and an irule at the same time

Beside of an upgrade to TMOS 11.4.1HF9 I wanted to use a maintenance today to assign some specific irule to a VS. Within the irule I use some HTTP functions so when I tried to add the irule to the already existing VS the tmsh correctly told me that I also need a http profile on this VS. Thanks tmsh you're right, oversight by myself. So what I did was:
tmsh modify ltm virtual mySpecialVS rules   mySpecialiRule   profiles add   company-http-profile  
tmsh accepted but all my tests ended at the VS. I could connect but got no reply at all. That was strange because I tested this irule extensively. So I reverted back to the known good state with just plain tcp forwarding. My next try was to assign only the http profile without the irule.
tmsh modify ltm virtual mySpecialVS profiles add   company-http-profile  
Tested that and it worked. So what on earth was wrong with my irule? I added some debug statements and readded the irule like this:
tmsh modify ltm virtual mySpecialVS rules   mySpecialiRule  
And now it worked as intended. So I went on and removed my debug statements, tested again and it still works. Let's see if I can reproduce that case some time later this week to fill a proper bugreport with F5. Update: Turns out it was all my fault. Due to a misunderstanding about RULE_INIT and the static namespace, I managed to overwrite important variables globally. Lesson learned: Be very careful if you use "static::" or better avoid it. Also think twice if you start to set things on the RULE_INIT event. Since it's only called on saving an irule or restarts of the device, your errors might show only later when you do not expect that.

16 November 2015

Daniel Pocock: Quick start using Blender for video editing

Updated 2015-11-16 for WebM Although it is mostly known for animation, Blender includes a non-linear video editing system that is available in all the current stable versions of Debian, Ubuntu and Fedora. Here are some screenshots showing how to start editing a video of a talk from a conference. In this case, there are two input files:
  • A video file from a DSLR camera, including an audio stream from a microphone on the camera
  • A separate audio file with sound captured by a lapel microphone attached to the speaker's smartphone. This is a much better quality sound and we would like this to replace the sound included in the video file.
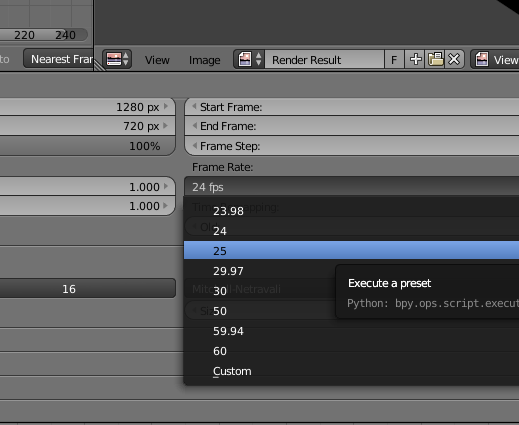
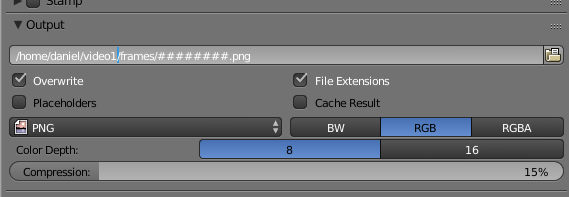
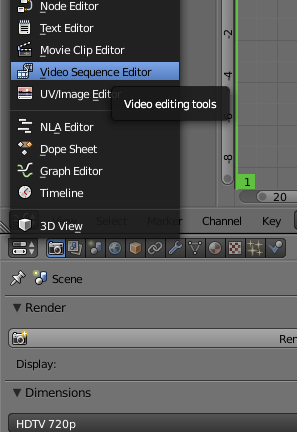
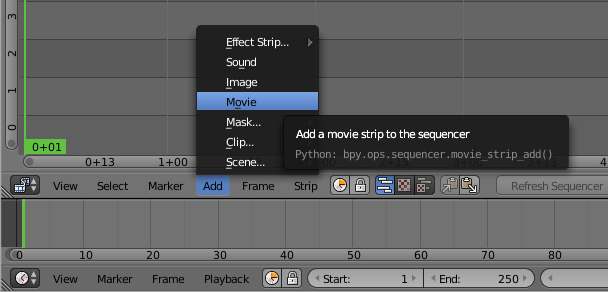
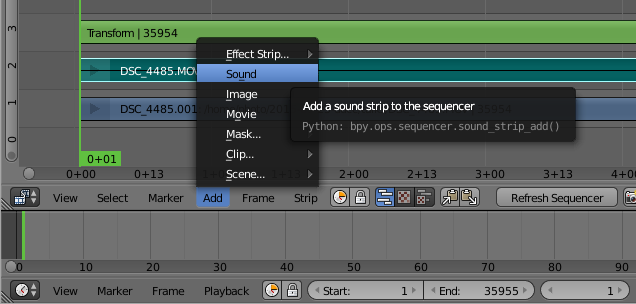
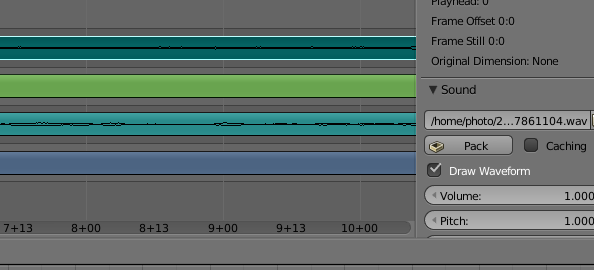
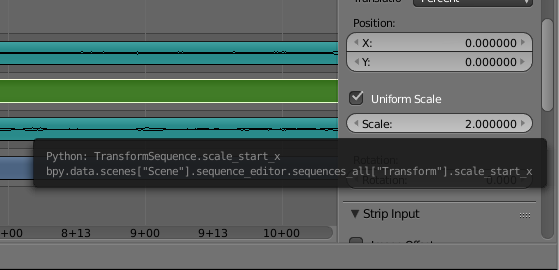
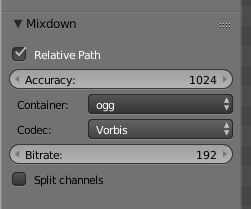
Open Blender and choose the video editing mode Launch Blender and choose the video sequence editor from the pull down menu at the top of the window: Now you should see all the video sequence editor controls: Setup the properties for your project Click the context menu under the strip editor panel and change the panel to a Properties panel: The video file we are playing with is 720p, so it seems reasonable to use 720p for the output too. Change that here: The input file is 25fps so we need to use exactly the same frame rate for the output, otherwise you will either observe the video going at the wrong speed or there will be a conversion that is CPU intensive and degrades the quality. Also check that the resolution_percentage setting under the picture dimensions is 100%: Now specify output to PNG files. Later we will combine them into a WebM file with a script. Specify the directory where the files will be placed and use the # placeholder to specify the number of digits to use to embed the frame number in the filename: Now your basic rendering properties are set. When you want to generate the output file, come back to this panel and use the Animation button at the top. Editing the video Use the context menu to change the properties panel back to the strip view panel: Add the video file: and then right click the video strip (the lower strip) to highlight it and then add a transform strip: Audio waveform Right click the audio strip to highlight it and then go to the properties on the right hand side and click to show the waveform: Rendering length By default, Blender assumes you want to render 250 frames of output. Looking in the properties to the right of the audio or video strip you can see the actual number of frames. Put that value in the box at the bottom of the window where it says 250: Enable AV-sync Also at the bottom of the window is a control to enable AV-sync. If your audio and video are not in sync when you preview, you need to set this AV-sync option and also make sure you set the frame rate correctly in the properties: Add the other sound strip Now add the other sound file that was recorded using the lapel microphone: Enable the waveform display for that sound strip too, this will allow you to align the sound strips precisely: You will need to listen to the strips to make an estimate of the time difference. Use this estimate to set the "start frame" in the properties for your audio strip, it will be a negative value if the audio strip starts before the video. You can then zoom the strip panel to show about 3 to 5 seconds of sound and try to align the peaks. An easy way to do this is to look for applause at the end of the audio strips, the applause generates a large peak that is easily visible. Once you have synced the audio, you can play the track and you should not be able to hear any echo. You can then silence the audio track from the camera by right clicking it, look in the properties to the right and change volume to 0. Make any transforms you require For example, to zoom in on the speaker, right click the transform strip (3rd from the bottom) and then in the panel on the right, click to enable "Uniform Scale" and then set the scale factor as required: Render the video output to PNG Click the context menu under the Curves panel and choose Properties again. Click the Animation button to generate a sequence of PNG files for each frame. Render the audio output On the Properties panel, click the Audio button near the top. Choose a filename for the generated audio file. Look on the bottom left-hand side of the window for the audio file settings, change it to the ogg container and Vorbis codec: Ensure the filename has a .ogg extension Now look at the top right-hand corner of the window for the Mixdown button. Click it and wait for Blender to generate the audio file. Combine the PNG files and audio file into a WebM video file You will need to have a few command line tools installed for manipulating the files from scripts. Install them using the package manager, for example, on a Debian or Ubuntu system: # apt-get install mjpegtools vpx-tools mkvtoolnix
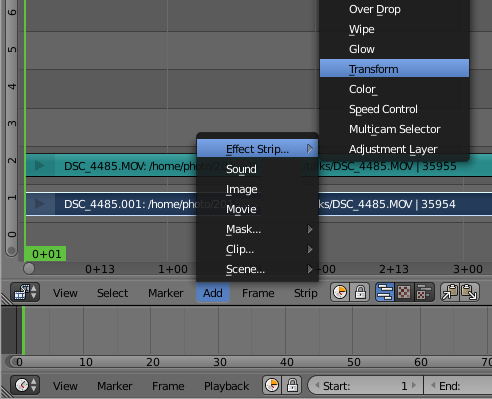
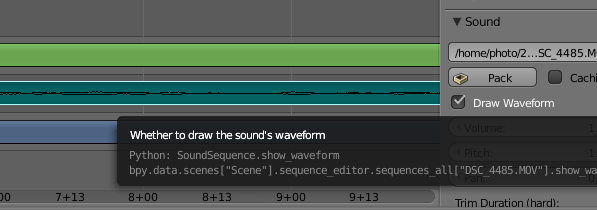
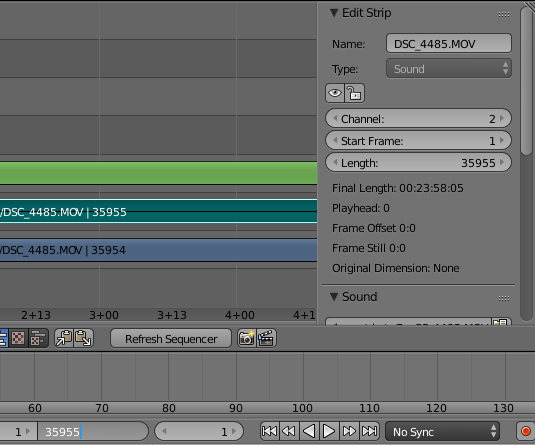
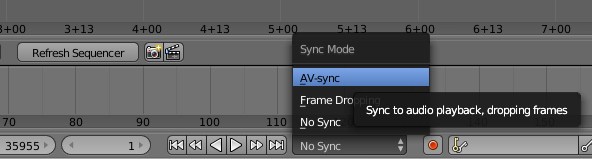
Now create a script like the following:
#!/bin/bash -e
# Set this to match the project properties
FRAME_RATE=25
# Set this to the rate you desire:
TARGET_BITRATE=1000
WORK_DIR=$ HOME /video1
PNG_DIR=$ WORK_DIR /frames
YUV_FILE=$ WORK_DIR /video.yuv
WEBM_FILE=$ WORK_DIR /video.webm
AUDIO_FILE=$ WORK_DIR /audio-mixed.ogg
NUM_FRAMES= find $ PNG_DIR  -type f   wc -l 
png2yuv -I p -f $FRAME_RATE -b 1 -n $NUM_FRAMES \
    -j $ PNG_DIR /%08d.png > $ YUV_FILE 
vpxenc --good --cpu-used=0 --auto-alt-ref=1 \
   --lag-in-frames=16 --end-usage=vbr --passes=2 \
   --threads=2 --target-bitrate=$ TARGET_BITRATE  \
   -o $ WEBM_FILE -noaudio $ YUV_FILE 
rm $ YUV_FILE 
mkvmerge -o $ WEBM_FILE  -w $ WEBM_FILE -noaudio $ AUDIO_FILE 
rm $ WEBM_FILE -noaudio
Next steps There are plenty of more comprehensive tutorials, including some videos on Youtube, explaining how to do more advanced things like fading in and out or zooming and panning dynamically at different points in the video. If the lighting is not good (faces too dark, for example), you can right click the video strip, go to the properties panel on the right hand side and click Modifiers, Add Strip Modifier and then select "Color Balance". Use the Lift, Gamma and Gain sliders to adjust the shadows, midtones and highlights respectively.

Julien Danjou: Profiling Python using cProfile: a concrete case

Writing programs is fun, but making them fast can be a pain. Python programs are no exception to that, but the basic profiling toolchain is actually not that complicated to use. Here, I would like to show you how you can quickly profile and analyze your Python code to find what part of the code you should optimize. What's profiling? Profiling a Python program is doing a dynamic analysis that measures the execution time of the program and everything that compose it. That means measuring the time spent in each of its functions. This will give you data about where your program is spending time, and what area might be worth optimizing. It's a very interesting exercise. Many people focus on local optimizations, such as determining e.g. which of the Python functions range or xrange is going to be faster. It turns out that knowing which one is faster may never be an issue in your program, and that the time gained by one of the functions above might not be worth the time you spend researching that, or arguing about it with your colleague. Trying to blindly optimize a program without measuring where it is actually spending its time is a useless exercise. Following your guts alone is not always sufficient. There are many types of profiling, as there are many things you can measure. In this exercise, we'll focus on CPU utilization profiling, meaning the time spent by each function executing instructions. Obviously, we could do many more kind of profiling and optimizations, such as memory profiling which would measure the memory used by each piece of code something I talk about in The Hacker's Guide to Python. cProfile Since Python 2.5, Python provides a C module called cProfile which has a reasonable overhead and offers a good enough feature set. The basic usage goes down to:
>>> import cProfile
>>> cProfile.run('2 + 2')
2 function calls in 0.000 seconds

Ordered by: standard name

ncalls tottime percall cumtime percall filename:lineno(function)
1 0.000 0.000 0.000 0.000 <string>:1(<module>)
1 0.000 0.000 0.000 0.000 method 'disable' of '_lsprof.Profiler' objects

Though you can also run a script with it, which turns out to be handy:
$ python -m cProfile -s cumtime lwn2pocket.py
72270 function calls (70640 primitive calls) in 4.481 seconds

Ordered by: cumulative time

ncalls tottime percall cumtime percall filename:lineno(function)
1 0.004 0.004 4.481 4.481 lwn2pocket.py:2(<module>)
1 0.001 0.001 4.296 4.296 lwn2pocket.py:51(main)
3 0.000 0.000 4.286 1.429 api.py:17(request)
3 0.000 0.000 4.268 1.423 sessions.py:386(request)
4/3 0.000 0.000 3.816 1.272 sessions.py:539(send)
4 0.000 0.000 2.965 0.741 adapters.py:323(send)
4 0.000 0.000 2.962 0.740 connectionpool.py:421(urlopen)
4 0.000 0.000 2.961 0.740 connectionpool.py:317(_make_request)
2 0.000 0.000 2.675 1.338 api.py:98(post)
30 0.000 0.000 1.621 0.054 ssl.py:727(recv)
30 0.000 0.000 1.621 0.054 ssl.py:610(read)
30 1.621 0.054 1.621 0.054 method 'read' of '_ssl._SSLSocket' objects
1 0.000 0.000 1.611 1.611 api.py:58(get)
4 0.000 0.000 1.572 0.393 httplib.py:1095(getresponse)
4 0.000 0.000 1.572 0.393 httplib.py:446(begin)
60 0.000 0.000 1.571 0.026 socket.py:410(readline)
4 0.000 0.000 1.571 0.393 httplib.py:407(_read_status)
1 0.000 0.000 1.462 1.462 pocket.py:44(wrapped)
1 0.000 0.000 1.462 1.462 pocket.py:152(make_request)
1 0.000 0.000 1.462 1.462 pocket.py:139(_make_request)
1 0.000 0.000 1.459 1.459 pocket.py:134(_post_request)
[ ]

This prints out all the function called, with the time spend in each and the number of times they have been called. Advanced visualization with KCacheGrind While being useful, the output format is very basic and does not make easy to grab knowledge for complete programs. For more advanced visualization, I leverage KCacheGrind. If you did any C programming and profiling these last years, you may have used it as it is primarily designed as front-end for Valgrind generated call-graphs. In order to use, you need to generate a cProfile result file, then convert it to KCacheGrind format. To do that, I use pyprof2calltree.
$ python -m cProfile -o myscript.cprof myscript.py
$ pyprof2calltree -k -i myscript.cprof

And the KCacheGrind window magically appears!
Concrete case: Carbonara optimization I was curious about the performances of Carbonara, the small timeserie library I wrote for Gnocchi. I decided to do some basic profiling to see if there was any obvious optimization to do. In order to profile a program, you need to run it. But running the whole program in profiling mode can generate a lot of data that you don't care about, and adds noise to what you're trying to understand. Since Gnocchi has thousands of unit tests and a few for Carbonara itself, I decided to profile the code used by these unit tests, as it's a good reflection of basic features of the library. Note that this is a good strategy for a curious and naive first-pass profiling. There's no way that you can make sure that the hotspots you will see in the unit tests are the actual hotspots you will encounter in production. Therefore, a profiling in conditions and with a scenario that mimics what's seen in production is often a necessity if you need to push your program optimization further and want to achieve perceivable and valuable gain. I activated cProfile using the method described above, creating a cProfile.Profile object around my tests (I actually started to implement that in testtools). I then run KCacheGrind as described above. Using KCacheGrind, I generated the following figures.
The test I profiled here is called test_fetch and is pretty easy to understand: it puts data in a timeserie object, and then fetch the aggregated result. The above list shows that 88 % of the ticks are spent in set_values (44 ticks over 50). This function is used to insert values into the timeserie, not to fetch the values. That means that it's really slow to insert data, and pretty fast to actually retrieve them. Reading the rest of the list indicates that several functions share the rest of the ticks, update, _first_block_timestamp, _truncate, _resample, etc. Some of the functions in the list are not part of Carbonara, so there's no point in looking to optimize them. The only thing that can be optimized is, sometimes, the number of times they're called.
The call graph gives me a bit more insight about what's going on here. Using my knowledge about how Carbonara works, I don't think that the whole stack on the left for _first_block_timestamp makes much sense. This function is supposed to find the first timestamp for an aggregate, e.g. with a timestamp of 13:34:45 and a period of 5 minutes, the function should return 13:30:00. The way it works currently is by calling the resample function from Pandas on a timeserie with only one element, but that seems to be very slow. Indeed, currently this function represents 25 % of the time spent by set_values (11 ticks on 44). Fortunately, I recently added a small function called _round_timestamp that does exactly what _first_block_timestamp needs that without calling any Pandas function, so no resample. So I ended up rewriting that function this way:
def _first_block_timestamp(self):
- ts = self.ts[-1:].resample(self.block_size)
- return (ts.index[-1] - (self.block_size * self.back_window))
+ rounded = self._round_timestamp(self.ts.index[-1], self.block_size)
+ return rounded - (self.block_size * self.back_window)

And then I re-run the exact same test to compare the output of cProfile.
The list of function seems quite different this time. The number of time spend used by set_values dropped from 88 % to 71 %.
The call stack for set_values shows that pretty well: we can't even see the _first_block_timestamp function as it is so fast that it totally disappeared from the display. It's now being considered insignificant by the profiler. So we just speed up the whole insertion process of values into Carbonara by a nice 25 % in a few minutes. Not that bad for a first naive pass, right?

Norbert Preining: Movies: Monuments Men and Interstellar

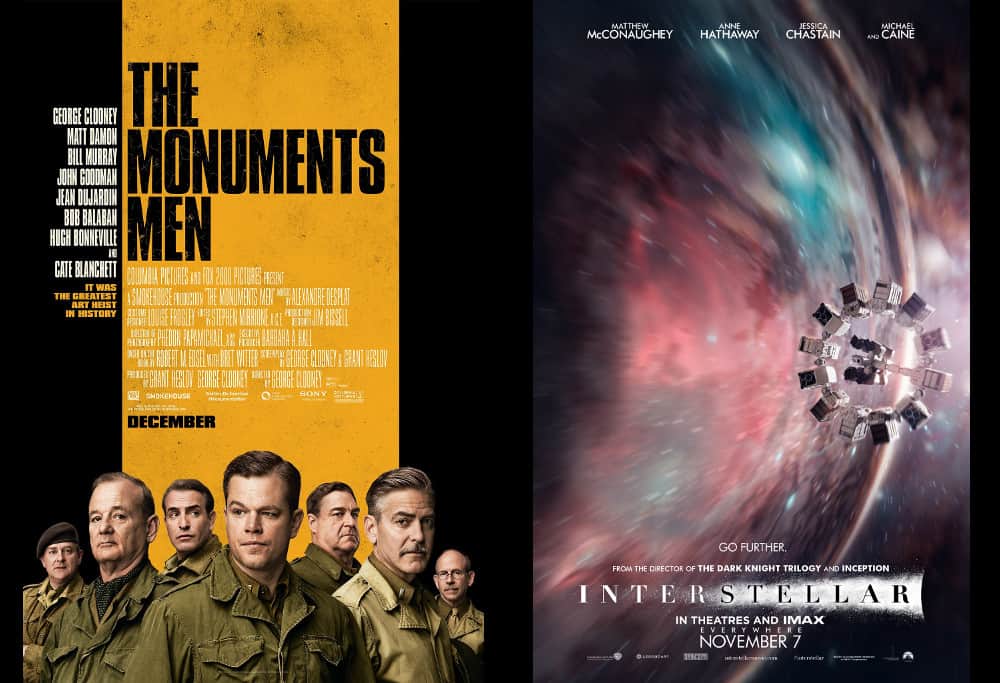
Over the rainy weekend we watched two movies: Monuments Men (in Japanese it is called Michelangelo Project!) and Interstellar. Both blockbuster movies from the usual American companies, they are light-years away when it comes to quality. The Monuments Men are boring, without a story, without depth, historically inaccurate, a complete failure. Interstellar, although a long movie, keeps you frozen in the seat while being as scientific as possible and starts your brain working heavily. monuments-men-interstellar My personal verdict: 3 rotten eggs (because Rotten Tomatoes are not stinky enough) for the Monuments Men, and 4 stars for Interstellar. Story First for the plot of the two movies: The Monuments Men is loosely based on a true story about rescuing pieces of art at the end of the second world war, before the Nazis destroy them or the Russian take them away. A group of art experts is sent into Europe and manages to find several hiding places of art taken by the Nazis. Interstellar is set in near future where the conditions on the earth are deteriorating to a degree that human life seems to be soon impossible. Some years before the movie plays a group of astronauts were sent through a wormhole into a different galaxy to search for new inhabitable planets. Now it is time to check out these planets, and try to establish colonies there. Cooper, a retired NASA officer and pilot, now working as farmer, and his daughter are guided by some mysterious way to a secret NASA facility. Cooper is drafted for being a pilot on the reconnaissance mission, and leaves earth and our galaxy through the same wormhole. (Not telling more!) Monuments Men Looking at the cast of Monuments Men (George Clooney, Matt Damon, Bill Murray, John Goodman, Jean Dujardin, Bob Balaban, Hugh Bonneville, and Cate Blanchett) one would expect a great movie but from the very first to the very last scene, it is a slowly meandering shallow flow of sticked together scenes without much coherence. Tension is generated only through unrelated events (stepping onto a landmine, patting a horse), but never developed properly. Dialogs are shallow and boring with one exception: When Frank Stokes (George Clooney) meets the one German and inquires general about the art, predicting his future being hanged. Historically, the movie is as inaccurate as it can be despite Clooney stating that 80 percent of the story is still completely true and accurate, and almost all of the scenes happened . That contrasts starkly with the verdict of Nigel Pollard (Swansea University): There s a kernel of history there, but The Monuments Men plays fast and loose with it in ways that are probably necessary to make the story work as a film, but the viewer ends up with a fairly confused notion of what the organisation was, and what it achieved. The movie leaves a bitter aftertaste, hailing of American heroism paired with the usual stereotypes (French amour, German retarded, Russian ignorance, etc). Together with the half baked dialogues it feels like a permanent coitus interruptus. Interstellar Interstellar cannot serve with a similar cast, but still a few known people (Matthew McConaughey, Anne Hathaway, and Michael Caine!). But I believe this is actually a sign of quality. Well balancing scientific accuracy and the requirements for blockbusters, the movie successfully spans the bridge between complicated science, in particular general gravity, and entertainment. While not going so far to call the move edutainment (like both the old and new Cosmos), it is surprising how much of hard science is packed into this movie. This is mostly thanks to the theoretical physicist Kip Thorne acting as scientific consultant for the movie, but also due to the director Christopher Nolan being serious about it and studying relativity at Caltech. Of course, scientific accuracy has limits nobody knows what happens if one crosses the event horizon of a black hole, and even the existence of wormholes is purely theoretical by now. Still, throughout the movie it follows the two requirements laid out by Kip Thorne: First, that nothing would violate established physical laws. Second, that all the wild speculations would spring from science and not from the fertile mind of a screenwriter. I think the biggest compliment was that, despite the length, despite a long day out (see next blog), despite the rather unfamiliar topic, my wife, who is normally not interested in space movies and that kind, didn t fall asleep throughout the movie, and I had to stop several times to explain details of the theory of gravity and astronomy. So in some sense it was perfect edutainment!
15 November 2015

Manuel A. Fernandez Montecelo: Work on aptitude

Midsummer for me is also known as Noite do Lume Novo (literally New Fire Night ), one of the big calendar events of the year, marking the end of the school year and the beginning of summer. On this day, there are celebrations not very unlike the bonfires in the Guy Fawkes Night in England or Britain [1]. It is a bit different in that it is not a single event for the masses, more of a friends and neighbours thing, and that it lasts for a big chunk of the night (sometimes until morning). Perhaps for some people, or outside bigger towns or cities, Guy Fawkes Night is also celebrated in that way and that's why during the first days of November there are fireworks rocketing and cracking in the neighbourhoods all around. Like many other celebrations around the world involving bonfires, many of them also happening around the summer solstice, it is supposed to be a time of renewal of cycles, purification and keeping the evil spirits away; with rituals to that effect like jumping over the fire when the flames are not high and it is safe enough. So it was fitting that, in the middle of June (almost Midsummer in the northern hemisphere), I learnt that I was about to leave my now-previous job, which is a pretty big signal and precursor for renewal (and it might have something to do with purifying and keeping the evil away as well ;-) ). Whatever... But what does all of this have to do with aptitude or Debian, anyway? For one, it was a question of timing. While looking for a new job (and I am still at it), I had more spare time than usual. DebConf 15 @ Heidelberg was within sight, and for the first time circumstances allowed me to attend this event. It also coincided with the time when I re-gained access to commit to aptitude on the 19th of June. Which means Renewal. End of June was also the time of the announcement of the colossal GCC-5/C++11 ABI transition in Debian, that was scheduled to start on the 1st of August, just before the DebConf. Between 2 and 3 thousand source packages in Debian were affected by this transition, which a few months later is not yet finished (although the most important parts were completed by mid-end September). aptitude itself is written in C++, and depends on several libraries written in C++, like Boost, Xapian and SigC++. All of them had to be compiled with the new C++11 ABI of GCC-5, in unison and in a particular order, for aptitude to continue to work (and for minimal breakage). aptitude and some dependencies did not even compile straight away, so this transition meant that aptitude needed attention just to keep working. Having recently being awarded again with the Aptitude Hat, attending DebConf for the first time and sailing towards the Transition Maelstrom, it was a clear sign that Something Had to Be Done (to avoid the sideways looks and consequent shame at DebConf, if nothing else). Happily (or a bit unhappily for me, but let's pretend...), with the unexpected free time in my hands, I changed the plans that I had before re-gaining the Aptitude Hat (some of them involving Debian, but in other ways maybe I will post about that soon). In July I worked to fix the problems before the transition started, so aptitude would be (mostly) ready, or in the worst case broken only for a few days, while the chain of dependencies was rebuilt. But apart from the changes needed for the new GCC-5, it was decided at the last minute that Boost 1.55 would not be rebuilt with the new ABI, and that the only version with the new ABI would be 1.58 (which caused further breakage in aptitude, was added to experimental only a few days before, and was moved to unstable after the transition had started). Later, in the first days of the transition, aptitude was affected for a few days by breakage in the dependencies, due to not being compiled in sequence according to the transition levels (so with a mix of old and new ABI). With the critical intervention of Axel Beckert (abe / XTaran), things were not so bad as they could have been. He was busy testing and uploading in the critical days when I was enjoying a small holiday on my way to DebConf, with minimal internet access and communicating almost exclusively with him; and he promptly tended the complaints arriving in the Bug Tracking System and asked for rebuilds of the dependencies with the new ABI. He also brought the packaging up to shape, which had decayed a bit in the last few years. Gruesome Challenges But not all was solved yet, more storms were brewing and started to appear in the horizon, in the form of clouds of fire coming from nearby realms. The APT Deities, which had long ago spilled out their secret, inner challenge (just the initial paragraphs), were relentless. Moreover, they were present at Heidelberg in full force, in or close to their home grounds, and they were Marching Decidedly towards Victory: apt BTS Graph, 2015-11-15 In the talk @ DebConf This APT has Super Cow Powers (video available), by David Kalnischkies, they told us about the niceties of apt 1.1 (still in experimental but hopefully coming to unstable soon), and they boasted about getting the lead in our arms race (should I say bugs race?) by a few open bug reports. This act of provocation further escalated the tensions. The fierce competition which had been going on for some time gained new heights. So much so that APT Deities and our team had to sit together in the outdoor areas of the venue and have many a weissbier together, while discussing and fixing bugs. But beneath the calm on the surface, and while pretending to keep good diplomatic relations, I knew that Something Had to Be Done, again. So I could only do one thing jump over the bonfire and Keep the Evil away, be that Keep Evil bugs Away or Keep Evil APT Deities Away from winning the challenge, or both. After returning from DebConf I continued to dedicate time to the project, more than a full time job in some weeks, and this is what happened in the last few months, summarised in another graph, showing the evolution of the BTS for aptitude: aptitude BTS Graph, 2015-11-15 The numbers for apt right now (15th November 2015) are: The numbers for aptitude right now are: The Aftermath As we can see, for the time being I could keep the Evil at bay, both in terms of bugs themselves and re-gaining the lead in the bugs race the Evil APT Deities were thwarted again in their efforts. ... More seriously, as most of you suspected, the graph above is not the whole truth, so I don't want to boast too much. A big part of the reduction in the number of bugs is because of merging duplicates, closing obsolete bugs, applying translations coming from multiple contributors, or simple fixes like typos and useful suggestions needing minor changes. Many of remaining problems are comparatively more difficult or time consuming that the ones addressed so far (except perhaps avoiding the immediate breakage of the transition, that took weeks to solve), and there are many important problems still there, chief among those is aptitude offering very poor solutions to resolve conflicts. Still, even the simplest of the changes takes effort, and triaging hundreds of bugs is not fun at all and mostly a thankless effort althought there is the occasionally kind soul that thanks you for handling a decade-old bug. If being subjected to the rigours of the BTS and reading and solving hundreds of bug reports is not Purification, I don't know what it is. Apart from the triaging, there were 118 bugs closed (or pending) due to changes made in the upstream part or the packaging in the last few months, and there are many changes that are not reflected in bugs closed (like most of the changes needed due to the C++11 ABI transition, bugs and problems fixed that had no report, and general rejuvenation or improvement of some parts of the code). How long this will last, I cannot know. I hope to find a job at some point, which obviously will reduce the time available to work on this. But in the meantime, for all aptitude users: Enjoy the fixes and new features! Notes [1] ^ Some visitors of the recent mini-DebConf @ Cambridge perhaps thought that the fireworks and throngs gathered were in honour of our mighty Universal Operating System, but sadly they were not. They might be, some day. In any case, the reports say that the visitors enjoyed the fireworks.

Lunar: Reproducible builds: week 29 in Stretch cycle

What happened in the reproducible builds effort this week: Toolchain fixes Emmanuel Bourg uploaded eigenbase-resgen/1.3.0.13768-2 which uses of the scm-safe comment style by default to make them deterministic. Mattia Rizzolo started a new thread on debian-devel to ask a wider audience for issues about the -Wdate-time compile time flag. When enabled, GCC and clang print warnings when __DATE__, __TIME__, or __TIMESTAMP__ are used. Having the flag set by default would prompt maintainers to remove these source of unreproducibility from the sources. Packages fixed The following packages have become reproducible due to changes in their build dependencies: bmake, cyrus-imapd-2.4, drobo-utils, eigenbase-farrago, fhist, fstrcmp, git-dpm, intercal, libexplain, libtemplates-parser, mcl, openimageio, pcal, powstatd, ruby-aggregate, ruby-archive-tar-minitar, ruby-bert, ruby-dbd-odbc, ruby-dbd-pg, ruby-extendmatrix, ruby-rack-mobile-detect, ruby-remcached, ruby-stomp, ruby-test-declarative, ruby-wirble, vtprint. The following packages became reproducible after getting fixed: Some uploads fixed some reproducibility issues, but not all of them: Patches submitted which have not made their way to the archive yet: reproducible.debian.net The fifth and sixth armhf build nodes have been set up, resulting in five more builder jobs for armhf. More than 10,000 packages have now been identified as reproducible with the reproducible toolchain on armhf. (Vagrant Cascadian, h01ger) Helmut Grohne and Mattia Rizzolo now have root access on all 12 build nodes used by reproducible.debian.net and jenkins.debian.net. (h01ger) reproducible-builds.org is now linked from all package pages and the reproducible.debian.net dashboard. (h01ger) profitbricks-build5-amd64 and profitbricks-build6-amd64, responsible for running amd64 tests now run 398.26 days in the future. This means that one of the two builds that are being compared will be run on a different minute, hour, day, month, and year. This is not yet the case for armhf. FreeBSD tests are also done with 398.26 days difference. (h01ger) The design of the Arch Linux test page has been greatly improved. (Levente Polyak) diffoscope development Three releases of diffoscope happened this week numbered 39 to 41. It includes support for EPUB files (Reiner Herrmann) and Free Pascal unit files, usually having .ppu as extension (Paul Gevers). The rest of the changes were mostly targetting at making it easier to run diffoscope on other systems. The tlsh, rpm, and debian modules are now all optional. The test suite will properly skip tests that need optional tools or modules when they are not available. As a result, diffosope is now available on PyPI and thanks to the work of Levente Polyak in Arch Linux. Getting these versions in Debian was a bit cumbersome. Version 39 was uploaded with an expired key (according to the keyring on ftp.debian.org which will hopefully be updated soon) which is currently handled by keeping the files in the queue without REJECTing them. This prevented any other Debian Developpers to upload the same version. Version 40 was uploaded as a source-only upload but failed to build from source which had the undesirable side effect of removing the previous version from unstable. The package faild to build from source because it was built passing -I to debbuild. This excluded the ELF object files and static archives used by the test suite from the archive, preventing the test suite to work correctly. Hopefully, in a nearby future it will be possible to implement a sanity check to prevent such mistakes in the future. It has also been identified that ppudump outputs time in the system timezone without considering the TZ environment variable. Zachary Vance and Paul Gevers raised the issue on the appropriate channels. strip-nondeterminism development Chris Lamb released strip-nondeterminism version 0.014-1 which disables stripping Mono binaries as it is too aggressive and the source of the problem is being worked on by Mono upstream. Package reviews 133 reviews have been removed, 115 added and 103 updated this week. Chris West and Chris Lamb reported 57 new FTBFS bugs. Misc. The video of h01ger and Chris Lamb's talk at MiniDebConf Cambridge is now available. h01ger gave a talk at CCC Hamburg on November 13th, which was well received and sparked some interest among Gentoo folks. Slides and video should be available shortly. Frederick Kautz has started to revive Dhiru Kholia's work on testing Fedora packages. Your editor wish to once again thank #debian-reproducible regulars for reviewing these reports weeks after weeks.

14 November 2015

Daniel Pocock: Migrating data from Windows phones

Many of the people who have bought Windows phones seek relief sooner or later. Sometimes this comes about due to peer pressure or the feeling of isolation, in other cases it is the frustration of the user interface or the realization that they can't run cool apps like Lumicall. Frequently, the user has been given the phone as a complimentary upgrade when extending a contract without perceiving the time, effort and potential cost involved in getting their data out of the phone, especially if they never owned a smartphone before. When a Windows phone user does decide to cut their losses, they are usually looking to a friend or colleague with technical expertise to help them out. Personally, I'm not sure that anybody I would regard as an IT expert has ever had a Windows phone though, meaning that many experts are probably also going to be scratching their heads when somebody asks them for help. Therefore, I've put together this brief guide to help deal with these phones more expediently when they are encountered. The Windows phones have really bad support for things like CalDAV and WebDAV so don't get your hopes up about using such methods to backup the data to any arbitrary server. Searching online you can find some hacks that involve creating a Google or iCloud account in the phone and then modifying the advanced settings to send the data to an arbitrary server. These techniques vary a lot between specific versions of the Windows Phone OS and so the techniques I've described below are probably easier. Identify the Windows Live / Hotmail account The user may not remember or realize that a Microsoft account was created when they first obtained the phone. It may have been created for them by the phone, a friend or the salesperson in the phone shop. Look in the settings (Accounts) to find the account ID / email address. If the user hasn't been using this account, they may not recognize it and probably won't know the password for it. It is essential to try and obtain (or reset) the password before going any further, so start with the password recovery process. Microsoft may insist on sending a password reset email to some other email address that the user has previously provided or linked to their phone. Extracting data from the phone In many cases, the easiest way to extract the data is to download it from Microsoft live.com rather than extracting it from the phone. Even if the user doesn't realize it, the data is probably all replicated in live.com and so there is no further loss of privacy by logging in there to extract it. Set up an IMAP mail client An IMAP client will be used to download the user's emails (from the live.com account they may never have used) and SMS. Install Mozilla Thunderbird (IceDove on Debian), GNOME Evolution or a similar program on the user's PC. Configure the IMAP mail client to connect to the live.com account. Some clients, like Thunderbird, will automatically set up all the server details when you enter the live.com account ID. For manual account setup, the details here may help. Email backup If the user was not using the live.com account ID for email correspondence, there may not be a lot of mail in it. There may be some billing receipts or other things that are worth keeping though. Create a new folder (or set of folders) in the user's preferred email account and drag and drop the messages from the live.com Inbox to the new folder(s). SMS backup SMS backup can also be done through live.com. It is slightly more complicated than email backup, but similar.
  • In the live.com Outlook email index page, look for the settings button and click Manage Categories.
  • Enable the Contacts and Photos categories with a tick in each of them.
  • Go back to the main Inbox page and look for the categories section on the bottom left-hand side of the screen, under the folder list. Click the Contacts category.
  • The page may now appear blank. That is normal.
  • On the top right-hand corner of the page, click the Arrange menu and choose Conversation.
  • All the SMS messages should now appear on the screen.
  • Under the mail folders list on the left-hand side of the page, click to create a new folder with a name like SMS.
  • Select all the SMS messages and look for the option to move them to a folder. Send them to the SMS folder you created.
  • Now use the IMAP mail client to locate the SMS folder and copy everything from there to a new folder in the user's preferred mail server or local disk.
Contacts backup On the top left-hand corner of the live.com email page, there is a chooser to select other live.com applications. Select People. You should now see a list of all the user's contacts. Look for the option to export them to Outlook and other programs. This will export them as a CSV file. You can now import the CSV file into another application. GNOME Evolution has an import wizard with an option for Outlook file format. To load the contacts into a WebDAV address book, such as DAViCal, configure the address book in Evolution and then select it as the destination when running the CSV import wizard. WARNING: beware of using the Mozilla Thunderbird address book with contact data from mobile devices and other sources. It can't handle more than two email addresses per contact and this can lead to silent data loss if contacts are not fully saved. Calendar backup Now go to the live.com application chooser again and select the calendar application. Microsoft provides instructions to extract the calendar, summarised here:
  • Look for the Share button at the top somewhere and click it.
  • On the left-hand side of the page, click Get a link
  • On the right-hand side, choose Show event details to ensure you get a full calendar and then click Create underneath it.
  • Look for the link with a webcals prefix. If you are downloading with a tool like wget, change the scheme prefix to https. Fetch the file from this link and save it with an ics extension.
  • Inspect the ics calendar file to make sure it looks like real iCalendar data.
You can now import the ics file into another application. GNOME Evolution has an import wizard with an option for iCalendar file format. To load the calendar entries into a CalDAV server, such as DAViCal, configure the calendar server in Evolution and then select it as the destination when running the import wizard. Backup the user's photos, videos and other data files Hopefully you will be able to do this step without going through live.com. Try enabling the MTP or PTP mode in the phone and attach it to the computer using the USB cable. Hopefully the computer will recognize it in at least one of those modes. Use the computer's file manager or another tool to simply backup the entire directory structure. Reset the phone to factory defaults Once the user has their hands on a real phone, it is likely they will never want to look at that Windows phone again. It is time to erase the Windows phone, there is no going back. Go to the Settings and About and tap the factory reset option. It is important to do this before obliterating the live.com account, otherwise there are scenarios where you could be locked out of the phone and unable to erase it. Erasing may take some time. The phone will reboot and then display an animation of some gears spinning around for a few minutes and then reboot again. Wait for it to completely erase. Permanently close the Microsoft live.com account Keeping track of multiple accounts and other services is tedious and frustrating for most people, especially with services that try to force the user to receive email in different places. You can help eliminate user fatigue by helping them permanently close the live.com account so they never have to worry about it again. Follow the instructions on the Microsoft site. At some point it will suggest certain actions you should take before closing the account, most can be ignored. One thing you should do is remove the link between the live.com account ID and the phone. It is a good idea to do this as otherwise you may have problems erasing the device, if you haven't already done so. Before completely closing the account, also verify that the factory reset of the phone completed successfully. Dispose of the Windows phone safely If you can identify any faults with the phone, the user may be able to return it under the terms of the warranty. Some phone companies may allow the user to exchange it for something more desirable when it fails under warranty. It may be tempting to sell the phone to a complete stranger on eBay or install a custom ROM on it. In practice, neither option may be worth the time and effort involved. You may be tempted to put it beyond use so nobody else will suffer with it, but please try to do so in a way that is respectful of the environment. Putting the data into a new phone Prepare the new phone with a suitable ROM such as Replicant or Cyanogenmod. Install the F-Droid app on the new phone. From F-droid, install the DAVdroid app. DAVdroid will allow you to quickly sync the new phone against any arbitrary CalDAV and WebDAV server to populate it with the user's calendar and contact / address book data. Now is a good time to install other interesting apps like Lumicall, Conversations and K-9 Mail.

13 November 2015

Daniel Pocock: How much video RAM for a 4k monitor?

I previously wrote about my experience moving to a 4K monitor. I've been relatively happy with it except for one thing: I found that 1GB video RAM simply isn't sufficient for a stable system. This wasn't immediately obvious as it appeared to work in the beginning, but over time I've observed that it was not sufficient. I'm not using it for gaming or 3D rendering. My typical desktop involves several virtual workspaces with terminal windows, web browsers, a mail client, IRC and Eclipse. Sometimes I use vlc for playing media files. Using the nvidia-settings tool, I observed that the Used Dedicated memory statistic would frequently reach the maximum, 1024MB. On a few occasions, X crashed with errors indicating it was out of memory. After observing these problems, I put another card with 4GB video RAM into the system and I've observed it using between 1024 MB and 1300 MB at any one time. This leaves me feeling that people with only basic expectations for their desktop should aim for at least 2GB video RAM for 4k. That said, I've continued to enjoy many benefits of computing with a 4K monitor. In addition to those mentioned in my previous blog, here are some things that were easier for me with 4K:
  • Using gitk to look through many commits on the master branch of reSIProcate and cherry-pick some things to the resiprocate-1.9 branch. gitk only used half the screen and I was able to use the right hand side of the screen to look at the code in an editor in more detail.
  • Simultaneously monitoring logs from two Android devices running Lumicall and a repro SIP proxy server in three terminal windows arranged side by side, up to 125 lines of text in each.
  • Using WebRTC sites in the Mozilla browser while having a browser console window, source code and SIP proxy logs all open at the same time, none of them overlapping.
You can do much of this with a pair of monitors, but there is something quite nice about doing it all on a single 4K screen.

11 November 2015

Kees Cook: evolution of seccomp

I m excited to see other people thinking about userspace-to-kernel attack surface reduction ideas. Theo de Raadt recently published slides describing Pledge. This uses the same ideas that seccomp implements, but with less granularity. While seccomp works at the individual syscall level and in addition to killing processes, it allows for signaling, tracing, and errno spoofing. As de Raadt mentions, Pledge could be implemented with seccomp very easily: libseccomp would just categorize syscalls. I don t really understand the presentation s mention of Optional Security , though. Pledge, like seccomp, is an opt-in feature. Nothing in the kernel refuses to run unpledged programs. I assume his point was that when it gets ubiquitously built into programs (like stack protector), it s effectively not optional (which is alluded to later as comprehensive applicability ~= mandatory mitigation ). Regardless, this sensible (though optional) design gets me back to his slide on seccomp, which seems to have a number of misunderstandings: OpenBSD has some interesting advantages in the syscall filtering department, especially around sockets. Right now, it s hard for Linux syscall filtering to understand why a given socket is being used. Something like SOCK_DNS seems like it could be quite handy. Another nice feature of Pledge is the path whitelist feature. As it s still under development, I hope they expand this to include more things than just paths. Argument inspection is a weak point for seccomp, but under Linux, most of the arguments are ultimately exposed to the LSM layer. Last year I experimented with creating a seccomp LSM for path matching where programs could declare whitelists, similar to standard LSMs. So, yes, Linux could match this API on seccomp . It d just take some extensions to libseccomp to implement pledge(), as I described at the top. With OpenBSD doing a bunch of analysis work on common programs, it d be excellent to see this usable on Linux too. So far on Linux, only a few programs (e.g. Chrome, vsftpd) have bothered to do this using seccomp, and it could be argued that this is ultimately due to how fine grained it is.

2015, Kees Cook. This work is licensed under a Creative Commons Attribution-ShareAlike 3.0 License.
Creative Commons License

10 November 2015

Jaldhar Vyas: Happy Diwali and Sal Mubarak 2072

Wishing you all a happy Diwali and Gujarati New Year (V.S. 2072 called Plavanga.)Instead of being something sane like a flat disk supported by four elephants standing on a tortoise, the Earth is an oblate spheroid in heliocentric orbit. The Moon too offends by maintaining an unreasonably non-epicyclic orbit. Combined this means that the Americas (plus Iceland if there any Hindus there) observe Diwali today whereas in India and the rest of the world it is tomorrow. Technically in these longitudes the Ashvayuja amavasya tithi pervades both Tuesday and Wednesday but as Lakshmi Puja takes place at the pradosha kala it means it should be celebrated today though no doubt most of the non-astronomically minded people will just follow India any way. The New Year is on Thursday all over the world.Regardless of when you celebrate, may your year be full of happiness, good fortune and prosperity.


Norbert Preining: Music check: Google versus Apple Is that all? You can do better, Google!

Ok, I have been an iPhone user since I moved to Japan and got my first smart-phone ever. First a 3s, then a 4s, then a 5s that I dropped into the toilet, so I switched the SIM back into the 4s to have a working phone. Furthermore, I am a heavy music listener and used iTunes Radio for 3 months. Since I am planning to change phones to an Android phone (being fed up with Apple s super-closed environment), I tried out Google Music Plus for about 3 months, too. Here is my verict Google Music is a big pain, far from iTunes in comfort and user friendliness. music-check-google-vs-apple My move to Android is not very much in danger. General description of the service In principle, iTunes Radio and Google Music Subscription do the same things: There are slight differences, that often create confusion, especially with Apple s services: If you are only signed in, you can listen to music stations and can skip some music (limited), but you cannot listen to arbitrary songs from the whole Apple Music library. Then there is another service from Apple, called iTunes Match, that only allows you to upload your music library to the cloud, but other than that again only listening to normal radio stations. Google Music is much simpler, there are only two options: By default it is free to have your music (up to 25000 songs) in the cloud, but if you want to listen to radio stations or any other music in the Google music store, you need a subscription. Prizes and features overview:
Apple Google
No subscription iTunes Match iTunes Radio No subscription With subscription
Prize 0 25$/year 10$/month 0 10$/month
(early access 8$)
Cloud space 0 100000 25000
Extra service Radio stations Radio stations Radio/all music Nothing Radio/all music
Music on the go the application Let us first consider the applications provided to listen to music on your smart phone: Apple Music can of course only be used on Apple devices, and uses the built-in Music application. Start up time is about a few seconds after a cold boot (all on my 4s), and music streaming starts with hardly any delay. Responsiveness is good, and the user interface is clear and easy. Google s application is available on iOS and Android. I have tested the latest version on iOS, but it is a pain in the butt: Managing your library Here iTunes is the way to go, bit of a pain when using Linux, but there are other reasons I have a Windows installation in parallel, so I don t mind to boot now and then into Windows. iTunes gives you very powerful tools to change all kind of data. Google gives you a few options: Use your iTunes library in this case all your playlists and ratings (but see later) are also uploaded. I am not sure what happens if I retag a song in iTunes, or change anything else in there. I guess the song will not be re-uploaded, but who knows for sure. Furthermore, you can edit your library via the web interface, but this is rather poor. Searching your library Over times your library grows and there are hundreds if not thousands of artists. So you want to search them. The natural way would be to scroll to the first letter of the artist you are searching, and then look it up. Well, that works perfectly in both Apple s and Google s application unless you are having artists written in some strange script like Japanese or Korean. iTunes allows you to set a field called something like Artist name for sorting , which allows me to put for example or into the artist field, and into the sort field Tomokawa Kazuki and Kim Doo Soo . This way I find the artists in the correct place. Google on the other hand uses simple Unicode order sorting how could you do that? This is simply plain wrong, and everyone should know that by now. Japanese people will never be able to find anything in their list. And in contrast to Goole Contacts Google Music does not support phonetic name fields (similar to the order sort artist) for artists. What I had to do now is to rename all the artists to include first the phonetic name, followed by the proper name, like in Tomokawa Kazuki ( ) . Something I strongly detest! Radio stations I might have a slightly peculiar music taste, but the radio stations mixed by Google are simply a pain. The reason is easy to explain: I live in Japan, and so what Google does is mixing about 80% of J-Pop into the radio, all those happy yodeling girlies I really dislike (see my Anti J-Pop campaign for alternatives yes, they do exist also in Japan!). iTunes radio is here more relaxed it seems. I appreciate Google s trial to cater to local (dis)taste, but besides voting down each and every song I hear I don t see any other option. And honestly, I cannot go through all this voting down without dying from pain inflicted by J-Pop. Other than this, the two radio stations are probably more or less the same but as I said, due to the local colorit it is hard to compare. Rating Ohhh, what a dire point. So there you have you well curated iTunes library with 5-star ratings. I used the ratings in a way that those songs I like get 1 star, those I even like more get 2 stars, and my absolute favorites got 5 stars. I didn t do any negative ratings. iTunes/iOS Music app allows you to easily adjust rating, and they are synced between devices. All as you would expect. Now for Google they did have a 5-star rating system at some time, but:
Thank you for your feedback. We ve decided to remove the 5-star Rating lab. This decision wasn t made lightly, but Thumbs Up/Down is integral for the future vision for Play Music and will be a central design point for our future releases. Please note that we ll continue to store your ratings that you ve set via the star lab or via iTunes, and we ll translate them to thumbs up/down (1-2 stars = thumbs down, 4-5 stars = thumbs up).
Here we go with the move to a new design they threw away the 5-star system, without any reason but integral for future vision rubbish sales speak. Besides being a very very poor rating system to have only an up and down (good-bad-don t care), the translation from my rating system to the thumbs up-down is just plain wrong. <rant>
Why on earth is the current movement to reduce functionality and rob users of control? Gnome 3 is the prime example of how we stupiditize users by taken any freedom from them in the name of simple design. Google now does the same. I am so sick of getting patronized this way, so Gnome3 was completely banished from my computer and replaced by Cinnamon, which uses the same (good) underlying technique, but takes users seriously!
</rant> Overall verdict As much as I would like to see Google Music a valid alternative to iTunes, by now it makes the impression of a quickly hacked together rotten piece of code that tries to get a share of the market without providing equivalent service. Google is using its market presence and convenience to convert people, not features and quality. I can only hope that this changes in the future. That still leaves me with the question move to Android or remain with iOS

9 November 2015

Lunar: Reproducible builds: week 28 in Stretch cycle

What happened in the reproducible builds effort this week: Toolchain fixes Chris Lamb filled a bug on python-setuptools with a patch to make the generated requires.txt files reproducible. The patch has been forwarded upstream. Chris also understood why the she-bang in some Python scripts kept being undeterministic: setuptools as called by dh-python could skip re-installing the scripts if the build had been too fast (under one second). #804339 offers a patch fixing the issue by passing --force to setup.py install. #804141 reported on gettext asks for support of SOURCE_DATE_EPOCH in gettextize. Santiago Vila pointed out that it doesn't felt appropriate as gettextize is supposed to be an interactive tool. The problem reported seems to be in avahi build system instead. Packages fixed The following packages became reproducible due to changes in their build dependencies: celestia, dsdo, fonts-taml-tscu, fte, hkgerman, ifrench-gut, ispell-czech, maven-assembly-plugin, maven-project-info-reports-plugin, python-avro, ruby-compass, signond, thepeg, wagon2, xjdic. The following packages became reproducible after getting fixed: Some uploads fixed some reproducibility issues but not all of them: Patches submitted which have not made their way to the archive yet: Chris Lamb closed a wrongly reopened bug against haskell-devscripts that was actually a problem in haddock. reproducible.debian.net FreeBSD tests are now run for three branches: master, stable/10, release/10.2.0. (h01ger) diffoscope development Support has been added for Free Pascal unit files (.ppc). (Paul Gevers) The homepage is now available using HTTPS, thanks to Let's Encrypt!. Work has been done to be able to publish diffoscope on the Python Package Index (also known as PyPI): the tlsh module is now optional, compatibility with python-magic has been added, and the fallback code to handle RPM has been fixed. Documentation update Reiner Herrmann, Paul Gevers, Niko Tyni, opi, and Dhole offered various fixes and wording improvements to the reproducible-builds.org. A mailing-list is now available to receive change notifications. NixOS, Guix, and Baserock are featured as projects working on reproducible builds. Package reviews 70 reviews have been removed, 74 added and 17 updated this week. Chris Lamb opened 22 new fail to build from source bugs. New issues this week: randomness_in_ocaml_provides, randomness_in_qdoc_page_id, randomness_in_python_setuptools_requires_txt, gettext_creates_ChangeLog_files_and_entries_with_current_date. Misc. h01ger and Chris Lamb presented Beyond reproducible builds at the MiniDebConf in Cambridge on November 8th. They gave an overview of where we stand and the changes in user tools, infrastructure, and development practices that we might want to see happening. Feedback on these thoughts are welcome. Slides are already available, and the video should be online soon. At the same event, a meeting happened with some members of the release team to discuss the best strategy regarding releases and reproducibility. Minutes have been posted on the Debian reproducible-builds mailing-list.

Vasudev Kamath: Forwarding host port to service in container

Problem I've lxc container running distcc daemon and I would like to forward the distcc traffic coming to my host system to container.
Solution Following simple script which uses iptable did the job.
 #!/bin/sh
 set -e
usage()  
    cat <<EOF
    $(basename $0) [options] <in-interface> <out-interface> <port> <destination>
    --clear           Clear the previous rules before inserting new
                      ones
    --protocol        Protocol for the rules to use.
    in-interface      Interface on which incoming traffic is expected
    out-interface     Interface to which incoming traffic is to be
                      forwarded.
    port              Port to be forwarded. Can be integer or string
                      from /etc/services.
    destination       IP and port of the destination system to which
                      traffic needs to be forwarded. This should be in
                      form <destination_ip:port>
(C) 2015 Vasudev Kamath - This program comes with ABSOLUTELY NO
WARRANTY. This is free software, and you are welcome to redistribute
it under the GNU GPL Version 3 (or later) License
EOF
 
setup_portforwarding ()  
    local protocol="$1"
    iptables -t nat -A PREROUTING -i $IN_INTERFACE -p "$protocol" --dport $PORT \
           -j DNAT --to $DESTINATION
    iptables -A FORWARD -p "$protocol" -d $ DESTINATION%%\:*  --dport $PORT -j ACCEPT
    # Returning packet should have gateway IP
    iptables -t nat -A POSTROUTING -s $ DESTINATION%%\:*  -o \
           $IN_INTERFACE -j SNAT --to $ IN_IP%%\/* 
 
if [ $(id -u) -ne 0 ]; then
    echo "You need to be root to run this script"
    exit 1
fi
while true; do
    case "$1" in
      --clear)
          CLEAR_RULES=1
          shift
          ;;
      --protocol --protocol=*?)
      if [ "$1" = "--protocol" -a -n "$2" ];then
          PROTOCOL="$2"
          shift 2
      elif [ "$ 1#--protocol= " != "$1" ]; then
          PROTOCOL="$ 1$--protocol= "
          shift 1
      else
          echo "You need to specify protocl (tcp udp)"
          exit 2
      fi
      ;;
      *)
          break
          ;;
    esac
done
if [ $# -ne 4 ]; then
    usage $0
    exit 2
fi
IN_INTERFACE="$1"
OUT_INTERFACE="$2"
PORT="$3"
DESTINATION="$4"
# Get the incoming interface IP. This is used for SNAT.
IN_IP=$(ip addr show $IN_INTERFACE \
             perl -nE '/inet\s(.*)\sbrd/ and print $1')
if [ -n "$CLEAR_RULES" ]; then
    iptables -t nat -X
    iptables -t nat -F
    iptables -F
fi
if [ -n "$PROTOCOL" ]; then
    setup_portforwarding $PROTOCOL
else
    setup_portforwarding tcp
    setup_portforwarding udp
fi
Coming to systemd-nspawn I see there is --port option which takes argument in form proto:hostport:destport where proto can be either tcp or udp, hostport and destport are number from 1-65535. This option assumes private networking enabled in the container. I've not tried this option yet but that simplifies quite a lot of thing, its like -p switch used by docker.

Daniel Pocock: debian.org RTC: announcing XMPP, SIP presence and more

Announced 7 November 2015 on the debian-devel-announce mailing list. The Debian Project now has an XMPP service available to all Debian Developers. Your Debian.org email identity can be used as your XMPP address. The SIP service has also been upgraded and now supports presence. SIP and XMPP presence, rosters and messaging are not currently integrated. The Lumicall app has been improved to enable rapid setup for Debian.org SIP users. This announcement concludes the maintenance window on the RTC services. All services are now running on jessie (using packages from jessie-backports). XMPP and SIP enable a whole new world of real-time multimedia communications possibilities: video/webcam, VoIP, chat messaging, desktop sharing and distributed, federated communication are the most common use cases. Details about how to get started and get support are explained in the User Guide in the Debian wiki. As it is a wiki, you are completely welcome to help it evolve. Several of the people involved in the RTC team were also at the Cambridge mini-DebConf (7-8 November). The password for all these real time communication services can be set via the LDAP control panel. Please note that this password needs to be different to any of your other existing debian.org passwords. Please use a strong password and please keep it secure. Some of the infrastructure, like the TURN server, is shared by clients of both SIP and XMPP. Please configure your XMPP and SIP clients to use the TURN server for audio or video streaming to work most reliably through NAT. A key feature of both our XMPP and SIP services is that they support federated inter-connectivity with other domains. Please try it. The FedRTC service for Fedora developers is one example of another SIP service that supports federation. For details of how it works and how we establish trust between domains, please see the RTC Quick Start Guide. Please reach out to other communities you are involved with and help them consider enabling SIP and XMPP federation of their own communities/domains: as Metcalfe's law suggests, each extra person or community who embraces open standards like SIP and XMPP has far more than just an incremental impact on the value of these standards and makes them more pervasive. If you are keen to support and collaborate on the wider use of Free RTC technology, please consider joining the Free RTC mailing list sponsored by FSF Europe. There will also be a dedicated debian-rtc list for discussion of these technologies within Debian and derivatives. This service has been made possible by the efforts of the DSA team in the original SIP+WebRTC project and the more recent jessie upgrades and XMPP project. Real-time communications systems have specific expectations for network latency, connectivity, authentication schemes and various other things. Therefore, it is a great endorsement of the caliber of the team and the quality of the systems they have in place that they have been able to host this largely within their existing framework for Debian services. Feedback from the DSA team has also been helpful in improving the upstream software and packaging to make them convenient for system administrators everywhere. Special thanks to Peter Palfrader and Luca Filipozzi from the DSA team, Matthew Wild from the Prosody XMPP server project, Scott Godin from the reSIProcate project, Juliana Louback for her contributions to JSCommunicator during GSoC 2014, Iain Learmonth for helping get the RTC team up and running, Enrico Tassi, Sergei Golovan and Victor Seva for the Prosody and prosody-modules packaging and also the Debian backports team, especially Alexander Wirt, helping us ensure that rapidly evolving packages like those used in RTC are available on a stable Debian system.

Vasudev Kamath: Taming systemd-nspawn for running containers

I've been trying to run containers using systemd-nspawn for quite some time. I was always bumping to one or other dead end. This is not systemd-nspawn's fault, rather my impatience stopping me from reading manual pages properly lack of good tutorial like article available online. Compared to this LXC has a quite a lot of good tutorials and howto's available online. This article is my effort to create a notes putting all required information in one place.
Creating a Debian Base Install First step is to have a minimal Debian system some where on your hard disk. This can be easily done using debootsrap. I wrote a custom script to avoid reading manual every time I want to run debootstrap. Parts of this script (mostly packages and the root password generation) is stolen from lxc-debian template provided by lxc package.
#!/bin/sh
set -e
set -x
usage ()  
    echo "$ 0##/*  [options] <suite> <target> [<mirror>]"
    echo "Bootstrap rootfs for Debian"
    echo
    cat <<EOF
    --arch         set the architecture to install
    --root-passwd  set the root password for bootstrapped rootfs
    EOF
 
# copied from the lxc-debian template
packages=ifupdown,\
locales,\
libui-dialog-perl,\
dialog,\
isc-dhcp-client,\
netbase,\
net-tools,\
iproute,\
openssh-server,\
dbus
if [ $(id -u) -ne 0 ]; then
    echo "You must be root to execute this command"
    exit 2
fi
if [ $# -lt 2 ]; then
   usage $0
fi
while true; do
    case "$1" in
        --root-passwd --root-passwd=?*)
            if [ "$1" = "--root-passwd" -a -n "$2" ]; then
                ROOT_PASSWD="$2"
                shift 2
            elif [ "$1" != "$ 1#--root-passwd= " ]; then
                ROOT_PASSWD="$ 1#--root-passwd= "
                shift 1
            else
                # copied from lxc-debian template
                ROOT_PASSWD="$(dd if=/dev/urandom bs=6 count=1 2>/dev/null base64)"
                ECHO_PASSWD="yes"
            fi
            ;;
        --arch --arch=?*)
            if [ "$1" = "--arch" -a -n "$2" ]; then
                ARCHITECTURE="$2"
                shift 2
            elif [ "$1" != "$ 1#--arch= " ]; then
                ARCHITECTURE="$ 1#--arch= "
                shift 1
            else
                ARCHITECTURE="$(dpkg-architecture -q DEB_HOST_ARCH)"
            fi
            ;;
        *)
            break
            ;;
    esac
done
release="$1"
target="$2"
if [ -z "$1" ]   [ -z "$2" ]; then
    echo "You must specify suite and target"
    exit 1
fi
if [ -n "$3" ]; then
    MIRROR="$3"
fi
MIRROR=$ MIRROR:-http://httpredir.debian.org/debian 
echo "Downloading Debian $release ..."
debootstrap --verbose --variant=minbase --arch=$ARCHITECTURE \
             --include=$packages \
             "$release" "$target" "$MIRROR"
if [ -n "$ROOT_PASSWD" ]; then
    echo "root:$ROOT_PASSWD"   chroot "$target" chpasswd
    echo "Root password is '$ROOT_PASSWRD', please change!"
fi
It just gets my needs done, if you don't like it feel free to modify or use debootstrap directly. !NB Please install dbus package in the minimal base install, otherwise you will not be able to control the container using machinectl
Manually Running Container and then persisting it Next we need to run the container manually. This is done by using following command.
systemd-nspawn -bD   /path/to/container --network-veth \
     --network-bridge=natbr0 --machine=Machinename
--machine option is not mandatory, if not specified systemd-nspawn will take the directory name as machine name, and if you have characters like - in the directory name it translates to hexcode x2d and controlling container with name becomes difficult. --network-veth specifies the systemd-nspawn to enable virtual ethernet based networking and --network-bridge tells the bridge interface on host system to be used by systemd-nspawn. These options together constitutes private networking for container. If not specified container can use host systems interface there by removing network isolation of container. Once you run this command container comes up. You can now run machinectl to control the container. Container can be persisted using following command
machinectl enable container-name
This will create a symbolic link of /lib/systemd/system/systemd-nspawn@service to /etc/systemd/system/machine.target.wants/. This allows you to start or stop container using machinectl or systemctl command. Only catch here is your base install should be in /var/lib/machines/. What I do in my case is create a symbolic link from my base container to /var/lib/machines/container-name. !NB Note that symbolic link name under /var/lib/machines should be same as the container name you gave using --machine switch or the directory name if you didn't specify --machine
Persisting Container Networking We did persist the container in above step, but this doesn't persist the networking options we provided in command line. systemd-nspawn@.service provides following command to invoke container.
ExecStart=/usr/bin/systemd-nspawn --quiet --keep-unit --boot --link-journal=try-guest --network-veth --settings=override --machine=%I
To persist the bridge networking configuration we did in command line, we need the help of systemd-networkd. So first we need to enable the systemd-networkd.service on both container and the host system.
systemctl enable systemd-networkd.service
Now inside the container, interfaces will be named as hostN. Depending on how many interfaces we have N increments. In our example case we had single interface, hence it will named as host0. By default network interfaces will be down inside container, hence systemd-networkd is needed to put it up. We put the following in /etc/systemd/network/host0.network file inside the container.
[Match]
Name=host0
[Network]
Description=Container wired interface host0
DHCP=yes
And in the host system we just configure the bridge interface using systemd-nspawn. I put following in natbr0.netdev in /etc/systemd/network/
[NetDev]
Description=Bridge natbr0
Name=natbr0
Kind=bridge
In my case I already had configured the bridge using /etc/network/interfaces file for lxc. I think its not really needed to use systemd-networkd in this case. Since systemd-networkd doesn't do anything if network / virtual device is already present I safely put above configuration and enabled systemd-networkd. Just for the notes here is my natbr0 configuration in interfaces file.
auto natbr0
iface natbr0 inet static
   address 172.16.10.1
   netmask 255.255.255.0
   pre-up brctl addbr natbr0
   post-down brctl delbr natbr0
   post-down sysctl net.ipv4.ip_forward=0
   post-down sysctl net.ipv6.conf.all.forwarding=0
   post-up sysctl net.ipv4.ip_forward=1
   post-up sysctl net.ipv6.conf.all.forwarding=1
   post-up iptables -A POSTROUTING -t mangle -p udp --dport bootpc -s 172.16.0.0/16 -j CHECKSUM --checksum-fill
   pre-down iptables -D POSTROUTING -t mangle -p udp --dport bootpc -s 172.16.0.0/16 -j CHECKSUM --checksum-fill
Once this is done just reload the systemd-networkd and make sure you have dnsmasq or any other DHCP server running in your system. Now the last part is to tell systemd-nspawn to use the bridge networking interface we have defined. This is done using container-name.nspawn file. Put this file under /etc/systemd/nspawn folder.
[Exec]
Boot=on
[Files]
Bind=/home/vasudev/Documents/Python/upstream/apt-offline/
[Network]
VirtualEthernet=yes
Bridge=natbr0
Here you can specify networking, and files mounting section of the container. For full list please refer the systemd.nspawn manual page. Now all this is done you can happily do
machinectl start container-name
#or
systemctl start systemd-nspawn@container-name
Resource Control Now all things said and done, one last part remains. Yes what is the point if we can't control how much resource does the container use. Atleast it is more important for me, because I use old and bit low powered laptop. Systemd provides way to control the resource using Control interface. To see all the the interfaces exposed by systemd please refer systemd.resource-control manual page. The way to control the resource is using systemctl. Once container starts running we can run following command.
systemctl set-property container-name CPUShares=200 CPUQuota=30% MemoryLimit=500M
The manual page does say that these things can be put under [Slice] section of unit files. Now I don't have clear idea if this can be put under .nspawn files or not. For the sake of persisting the container I manually wrote the service file for container by copying systemd-nspawn@.service and adding [Slice] section. But if I don't know how to find out if this had any effect or not. If some one knows about this please share your suggestions to me and I will update this section with your provided information.
Conclussion All in all I like systemd-nspawn a lot. I use it to run container for development of apt-offline. I previously used lxc where all can be controlled using a single config file. But I feel systemd-nspawn is more tightly integrated with system than lxc. There is definitely more in systemd-nspawn than I've currently figured out. Only thing is its not as popular as other alternatives and definitely lacks good howto documentation.For now only way out is dig the manual pages, scratch your head, pull your hair out and figure out new possibilities in systemd-nspawn. ;-)

8 November 2015

Daniel Pocock: Problems observed during Cambridge mini-DebConf RTC demo

A few problems were observed during the demo of RTC services at the Cambridge mini-DebConf yesterday. As it turns out, many of them are already documented and solutions are available for some of them. Multiple concurrent SIP registrations I had made some test calls on Friday using rtc.debian.org and I still had the site open in another tab in another browser window. When people tried to call me during the demo, both tabs were actually ringing but only one was visible. When a SIP client registers, the SIP registration server sends it a list of all other concurrent registrations in the response message. We simply need to extend JSCommunicator to inspect the response message and give some visual feedback about other concurrent registrations. Issue #69. SIP also provides a mechanism to clear concurrent registrations and that could be made available with a button or configuration option too (Issue #9). Callee hears ringing before connectivity checks completed The second issue during the WebRTC demo was that the callee (myself) was alerted about the call before the ICE checks had been performed. The optimal procedure to provide a slick user experience is to run the connectivity checks before alerting the callee. If the connectivity checks fail, the callee should never be alerted with a ringing sound and would never know somebody had tried to call. The caller would be told that the call was unable to be attempted and encouraged to consider trying again on another wifi network. RFC 5245 recommends that connectivity checks should be done first but it is not mandatory. One reason this is problematic with WebRTC is the need to display the pop-up asking the user for permission to share their microphone and webcam: the popup must appear before connectivity checks can commence. This has been discussed in the JsSIP issue tracker. Non-WebRTC softphones, such as Lumicall, do the connectivity checks before alerting the callee. Dealing with UDP blocking It appears the corporate wifi network in the venue was blocking the UDP packets so the connectivity checks could never complete, not even using a TURN server to relay the packets. People trying to use the service on home wifi networks, in small offices and mobile tethering should not have this problem as these services generally permit UDP by default. Some corporate networks, student accommodation and wifi networks in some larger hotels have blocked UDP and in these cases, additional effort must be made to get through the firewall. The TURN server we are running for rtc.debian.org also supports a TLS transport but it simply isn't configured yet. At the time we originally launched the WebRTC service in 2013, the browsers didn't support TURN over TLS at all but now they do. This is probably the biggest problem encountered during the demo but it does not require any code change to resolve this, just configuration, so a solution is well within reach. During the demo, we worked around the issue by turning off the wifi on my laptop and using tethering with a 4G mobile network. All the calls made successfully during the demo used the tethering solution. Add a connectivity check timeout The ICE connectivity checks appeared to keep running for a long time. Usually, if UDP is not blocked, the ICE checks would complete in less than two seconds. Therefore, the JavaScript needs to set a timeout between two and five seconds when it starts the checks and give the user a helpful warning about their network problems if the timeout is exceeded. Issue #73 in JSCommunicator. While these lengthy connectivity checks appear disappointing, it is worth remembering that this is an improvement over the first generation of softphones: none of them made these checks at all, they would simply tell the user the call had been answered but audio and video would only be working in one direction or not at all. Microphone issues One of the users calling into the demo, Juliana, was visible on the screen but we couldn't hear her. This was a local audio hardware issue with her laptop or headset. It would be useful if the JavaScript could provide visual feedback when it detects a voice (issue #74) and even better, integrating with the sound settings so that the user can see if the microphone is muted or the gain is very low (issue #75). Thanks to participants in the demo I'd like to thank all the participants in the demo, including Juliana Louback who called us from New York, Laura Arjona who called us from Madrid, Daniel Silverstone who called from about three meters away in the front row and Iain Learmonth who helped co-ordinate the test calls over IRC. Thanks are also due to Steve McIntyre, the local Debian community, ARM and the other sponsors for making another mini-DebConf in the UK this year.

7 November 2015

Mart n Ferrari: Tales from the SRE trenches: Coda

This is the fifth -and last- part in a series of articles about SRE, based on the talk I gave in the Romanian Association for Better Software. Previous articles can be found here: part 1, part 2, part 3, and part 4.

Other lessons learned Apart from these guidelines for SRE I have described in previous posts, there were a few other practices I learned at google that I believe could benefit most operations teams out there (and developers too!).

Automate everything It's worth repeating, it is not sustainable to do things manually. When your manual work grows linearly with your usage, either your service is not growing enough, or you will need to hire more people than there are available in the market.

Involve Ops in systems design Nobody knows better than Ops the challenges of a real production environment, getting early feedback from your operations team can save you a lot of trouble down the road. They might give you insights about scalability, capacity planning, redundancy, and the very real limitations of hardware.

Give Ops time and space to innovate If there is so much emphasis on limiting the amount of operational load put on SRE, that freed time is not only used for creating monitoring dashboards or writing documentation. As I said in the beginning, SRE is an engineering team. And when engineers are not running around putting fires off all day long, they get creative. Many interesting innovations come from SREs even when there is no requirement for them.

Write design documents Design documents are not only useful for writing software. Fleshing out the details of any system on paper is a very useful way to find problems early in the process, communicate with your team exactly what are you building, and convince them why it is a great idea.

Review your code, version your changes This is something that is ubiquitous at Google, and not exclusive to SRE: everything is committed into source control: big systems, small scripts, configuration files. It might not seem worth it at the beginning, but having complete history of all your production environment is invaluable. And with source control, another rule comes into play: no change is committed without first being reviewed by a peer. It can be frustrating having to find a reviewer and wait for the approval for every small change, and some times reviews will be suboptimal, but once you get used to it, the benefits greatly out-weights any annoyances.

Before touching, measure Monitoring is not only for sending alerts, it is an essential tool of SRE. It allows you to gauge your availability, evaluate trends, forecast growth, perform forensic analysis. Also very importantly, it should give you the data needed to take decisions based on reality and not on guesses. Before optimising, find really where the bottleneck is; do not decide which database instance to use until you saw the utilisation of the past few months, etc. And speaking of that... We really need to have a chat about your current monitoring system. But that's for another day.
I hope I did not bore you too much with these walls of text! Some people told me directly they were enjoying these posts, so soon I will be writing more about related topics. In particular I would like to write about modern monitoring and Prometheus. I would love to hear your comments, questions, and criticisms. Comment

Next.

Previous.