Search Results: "reg"

15 October 2015

Wouter Verhelst: On Planet Debian and the Code of Conduct

I am not going to talk about Norbert Preining's continuous ranting against Debian's Code of Conduct. Suffice to say that it annoys me, and that I think he is wrong. I am, however going to mention that contrary to his statements (penultimate paragraph), yes, the Code of Conduct is supposed to apply to Planet Debian as well. Its introductory paragraph states:
The Debian Project, the producers of the Debian system, have adopted a code of conduct for participants to its mailinglists, IRC channels and other modes of communication within the project.
Note the "other modes of communication within the project" bit. Planet Debian is planet.debian.org. If your blog is aggregated there, you are communicating within the project. At least that's my interpretation of it.

14 October 2015

Rhonda D'Vine: Post DebConf15

There are some things that I didn't mention in my sort-of quickly written entry about DebConf15. So first things first. When I received the mail about the room allocation I was at first confused. I was put into a room with other ladies, which I didn't expect. Granted, two of the other three names were people that knew me since a while, but it still felt like a mistake might have happened. But after a while I realized what has happened: It wasn't a mistake, it was intentional, I was finally recognized as woman for the room allocation too, which made me extremely happy. I was just just concerned about the third person who would be in our room who doesn't know me yet and whether it would make them feel uncomfortable. In the end, that was no trouble at all. I felt so empowered and more accepted than ever in this community. And when finally being on-site there another thing happened with me. I started to use the women's restroom. Up to now I usually had the feeling of "it's fine for me to use the male one, and I don't want other women to feel uncomfortable", but somehow, with a skirt on, it in the end made me feeling uncomfortable. Additionally, there were only three times in total when I used the male toilet (and one was on the boat for the daytrip), and every single time of it I felt extremely uncomfortable with it, like others might think I'm just faking it. It at least in my mind doesn't help with accepting me as female when I go to the male restroom. And it's not a Good choice! as a woman did put it during the conference dinner when there was a longer queue infront of the male restroom. It's not so much of a choice over here. But I give her the doubt of not knowing how important these little steps became to me over time. Totally unrelated to the restroom question but interestingly featuring it a fair bit I was made aware of the Assigned Male cartoon. I instantly fell in love with it, and in case you want to enlighten yourself a bit more about how some things you might say or do get received by trans people, be very much invited to read it. Sophie is currently on European tour with her book, unfortunately Vienna/Austria doesn't seem to be part of europe in that respect so I hope someone will be able to visit one of her stations to pick up a book for me ... And then there was also a small inofficial Nail Polish BoF going on at DebConf. I left it on my fingers for the next two weeks, totally in love with it. Unfortunately the nail polish I got for myself after DebConf had a rather big brush so I wasn't able to work on it, I failed miserably. ... which brings me to the empowerment that DebConf meant for me this year, and the time since. Given that I left the nail polish on I even took the comfort in being myself to go to work in my skirt on a more regular basis. Also, a very nice friend did visit me and we went lipstick shopping. I loved the color she chose, even though in the meantime it isn't visible enough for me and I guess I'll get another one rather sooner than later. Also, about what I mentioned in my last blog post was that my name change within the Debian project was granted. A quick update on that is that also now my GPG key got replaced. I guess it's finally time for me to write a gpg transition statement, even though I don't follow those myself. I still prefer meeting up with people face-to-face for signing their new keys. But given that it's called a transition statement makes it more appealing to me on that grounds. :) And I got invited to a local podcast show. Actually I know the person who does the podcast since several years already, he's also part of the local free software community who attends various events, and he does a podcast since several years now called Biertaucher (named after cooling the beer in a fountain). It is held in German language, so if you don't understand German you might want to skip these links.
In the first episode that I joined in I talked about DebConf. Afterwards we were sitting together and talking about that they would like to have more social topics too, not just technical things. So we took that chance and talked in Biertaucher #221 about Polyamory, which was a quite interesting experience. The host intentionally asked questions coming from a quite ignorant point of view, but it went nice. We were three poly people sharing our views and insight how it works for us.
Then there was Biertaucher #223 where it was just me and one of the hosts. We didn't had much to talk about from the past week, so we agreed to talk about Transgender in the end. Granted, it's mostly my personal story, but I guess I got some important topics addressed in a useful way. And, after getting my name changed in Debian, I thought about what it might take to get my name changed officially, too (as if it could get more official than using it throughout my work environment, both payed and voluntary, but ...). I covered that in the podcast, but mostly it is either quite expensive or requires me to change my gender in the register of births, which require a lot of other hassles that include psychiatry. Or, settle for a so-called "gender neutral" name as first name, which both doesn't sound very convincing somehow ... Only time can tell I guess. Guess that's enough for now, if I forgot something I might come back to it. :) One last note: I consider the Debian project a very welcoming one, and that can only work for a fair amount of people if the tone is right. So yes, I wholeheartly agree with the Code of Conduct. And I'm very disappointed to see that there are still people in the project that are advocating for a freedom of expression, so to say. Respectful communication with each other is a must in a bigger community to make it work, not something that might be a nice to have, and calling someone names and ridiculing them for stating that is absolutely not acceptable. I encourage those people to watch How to Throughly Offend and Insult People in Open Source presentation (or at least read the slides) that Gina Likins gave earlier this year. It might give them an idea why it's important to communicate respectful with each other, and that includes banning degrading terms like "SJW" from your vocabulary because it actually speaks a lot more about your own attitude than about the one of the person you use it for.

/personal permanent link Comments: 8 Flattr this

Lunar: Reproducible builds: week 24 in Stretch cycle

What happened in the reproducible builds effort this week: Toolchain fixes Scott Kitterman fixed an issue with non-deterministic Depends generated by dh-python identified by Santiago Vila and Chris Lamb. Lunar updated the patch against dpkg which makes the order of files in control.tar.gz deterministic using the new --sort=name option available in GNU Tar 1.28. josch released sbuild version 0.66.0-1 with several fixes and improvements. The most notable one for reproducible builds is the new --build-path option and $build_path configuration variable added by akira which allows to explicitly chose a given build path. Reiner Herrmann wrote a new patch for dh-systemd to sort the list of unit files in the generated maintainer scripts. Packages fixed The following packages became reproducible due to changes in their build dependencies: aoeui, apron, camlmix, cudf, findlib, glpk-java, hawtjni, haxe, java-atk-wrapper, llvm-py, misery, mtasc, ocamldsort, optcomp, spamoracle. The following packages became reproducible after getting fixed: Some uploads fixed some reproducibility issues but not all of them: Untested Patches submitted which have not made their way to the archive yet: reproducible.debian.net ProfitBricks once again increased their support for reproducible builds in Debian and in other free software projects by adding 58 new cores and 138 GiB of RAM to the already existing setup. Two new amd64 build nodes and 16 new amd64 build jobs have been added which doubles the build capacity per day and allows us to spot many kind of problems earlier. The size of the tmpfs where builds are performed has also been increased from 70 to 200 GiB on all amd64 build nodes. Huge thanks! When examining a package, a link now points to a table listing all previous recorded tests for the same package. (Mattia) The menu on the package pages has also been improved. (h01ger) Packages in the depwait state are now rescheduled automatically after five days. (h01ger) Links to documentation and other projects being tested have been made more visible on the landing page. (h01ger) To reduce noise on the team IRC channel five different types of notifications have been turned into mail notifications. The remaining ones have been shortened and the status changes have been limited to unstable and experimental. (h01ger) Maintainer notifications about status changes in a package will only be sent out once per day, and not on each status change. (h01ger) diffoscope development Some more experiments of concurrent processing have been made. None were good and reliable enough to be shared, though. Package reviews 48 reviews have been removed, 189 added and 23 updated this week. 9 FTBFS bugs were reported by Chris Lamb. Misc. h01ger met with Levente Polyak to discuss testing Arch Linux on Debian continuous test system with an easily extensible framework. The idea is to also allow testing of other distributions, and provide a nice package based view like the one for Debian.

Mario Lang: ccidentals in Haskell

I've had quite some fun recently (re)learning Haskell. My learning project is to implement braille music notation parsing in Haskell. Given that i've already implemented most of this stuff in C++, it gives me a great opportunity to rethink my algorithms. Not everything I've had to implement until now was actually pretty. I spent yesterday evening implementing accidentals handling, which turned out to be quite a mess. However, I wanted to share my definition of the circle of fifths, because I find it rather concise.
The problem Given a key signature (often expressed as the number of sharp or flat accidentals), tell which pitch classes are actually raised/lowered. While reading through music notation software, I have seen several implementations of this basic concept. However, I have never seen one which was so concise.
module Accidental where
import           Data.Map (Map)
import qualified Data.Map as Map (fromList)
import qualified Haskore.Basic.Pitch as Pitch
fifths n   n >  0    = let [a,b,c,d,e,f,g] = fifths (n-1)
                       in  [d,e,f,g+1,a,b,c]
           n <  0    = let [a,b,c,d,e,f,g] = fifths (n+1)
                       in  [e,f,g,a,b,c,d-1]
           otherwise = replicate 7 0
Given this, we can easily define a Map of pitches to currently active accidentals/alterations. List comprehension to the rescue!
accidentals :: Int -> Map Pitch.T Pitch.Relative
accidentals k = Map.fromList [ ((o, c), a)
                               o <- [0..maxOctave]
                             , (c, a) <- zip diatonicSteps $ fifths k
                             , a /= 0
                             ] where
  maxOctave = 9
  diatonicSteps = [Pitch.C, Pitch.D, Pitch.E, Pitch.F, Pitch.G,
                   Pitch.A, Pitch.B]
The full source code for the haskore-braille (WIP) package can be found on GitHub. If you have any comments regarding the implementation, please drop me a mail.

13 October 2015

Julien Danjou: Benchmarking Gnocchi for fun & profit

We got pretty good feedback on Gnocchi so far, even if we only had little. Recently, in order to have a better feeling of where we were at, we wanted to know how fast (or slow) Gnocchi was. The early benchmarks that some of the Mirantis engineers ran last year showed pretty good signs. But a year later, it was time to get real numbers and have a good understanding of Gnocchi capacity. Benchmark tools The first thing I realized when starting that process, is that we were lacking of tools to run benchmarks. Therefore I started to write some benchmark tools in python-gnocchiclient, which provides a command line tool to interrogate Gnocchi. I added a few basic commands to measure metric performance, such as:
$ gnocchi benchmark metric create -w 48 -n 10000 -a low
+----------------------+------------------+
Field Value
+----------------------+------------------+
client workers 48
create executed 10000
create failures 0
create failures rate 0.00 %
create runtime 8.80 seconds
create speed 1136.96 create/s
delete executed 10000
delete failures 0
delete failures rate 0.00 %
delete runtime 39.56 seconds
delete speed 252.75 delete/s
+----------------------+------------------+

The command line tool supports the --verbose switch to have detailed progress report on the benchmark progression. So far it supports metric operations only, but that's the most interesting part of Gnocchi. Spinning up some hardware I got a couple of bare metal servers to test Gnocchi on. I dedicated the first one to Gnocchi, and used the second one as the benchmark client, plugged on the same network. Each server is made of 2 Intel Xeon E5-2609 v3 (12 cores in total) and 32 GB of RAM. That provides a lot of CPU to handle requests in parallel. Then I simply performed a basic RHEL 7 installation and ran devstack to spin up an installation of Gnocchi based on the master branch, disabling all of the others OpenStack components. I then tweaked the Apache httpd configuration to use the worker MPM and increased the maximum number of clients that can sent request simultaneously. I configured Gnocchi to use the PostsgreSQL indexer, as it's the recommended one, and the file storage driver, based on Carbonara (Gnocchi own storage engine). That means files were stored locally rather than in Ceph or Swift. Using the file driver is less scalable (you have to run on only one node or uses a technology like NFS to share the files), but it was good enough for this benchmark and to have some numbers and profiling the beast. The OpenStack Keystone authentication middleware was not enabled in this setup, as it would add some delay validating the authentication token. Metric CRUD operations Metric creation is pretty fast. I managed to attain 1500 metric/s created pretty easily. Deletion is now asynchronous, which means it's faster than in Gnocchi 1.2, but it's still slower than creation: 300 metric/s can be deleted. That does not sound like a huge issue since metric deletion is actually barely used in production. Retrieving metric information is also pretty fast and goes up to 800 metric/s. It'd be easy to achieve very higher throughput for this one, as it'd be easy to cache, but we didn't feel the need to implement it so far. Another important thing is that all of these numbers are constant and barely depends on the number of the metric already managed by Gnocchi.
Operation Details Rate
Create metric Created 100k metrics in 77 seconds 1300 metric/s
Delete metric Deleted 100k metrics in 190 seconds 524 metric/s
Show metric Show a metric 100k times in 149 seconds 670 metric/s
Sending and getting measures Pushing measures into metrics is one of the hottest topic. Starting with Gnocchi 1.1, the measures pushed are treated asynchronously, which makes it much faster to push new measures. Getting new numbers on that feature was pretty interesting. The number of metric per second you can push depends on the batch size, meaning the number of actual measurements you send per call. The naive approach is to push 1 measure per call, and in that case, Gnocchi is able to handle around 600 measures/s. With a batch containing 100 measures, the number of calls per second goes down to 450, but since you push 100 measures each time, that means 45k measures per second pushed into Gnocchi! I've pushed the test further, inspired by the recent blog post of InfluxDB claiming to achieve 300k points per second with their new engine. I ran the same benchmark on the hardware I had, which is roughly two times smaller than the one they used. I achieved to push Gnocchi to a little more than 120k measurement per second. If I had same hardware as they used, I could interpolate the results to achieve almost 250k measures/s pushed. Obviously, you can't strictly compare Gnocchi and InfluxDB since they are not doing exactly the same thing, but it still looks way better than what I expected. Using smaller batch sizes of 1k or 2k improve the throughput further to around 125k measures/s.
Operation Details Rate
Push metric 5k Push 5M measures with batch of 5k measures in 40 seconds 122k measures/s
Push metric 4k Push 5M measures with batch of 4k measures in 40 seconds 125k measures/s
Push metric 3k Push 5M measures with batch of 3k measures in 40 seconds 123k measures/s
Push metric 2k Push 5M measures with batch of 2k measures in 41 seconds 121k measures/s
Push metric 1k Push 5M measures with batch of 1k measures in 44 seconds 113k measures/s
Push metric 500 Push 5M measures with batch of 500 measures in 51 seconds 98k measures/s
Push metric 100 Push 5M measures with batch of 100 measures in 112 seconds 45k measures/s
Push metric 10 Push 5M measures with batch of 10 measures in 852 seconds 6k measures/s
Push metric 1 Push 500k measures with batch of 1 measure in 800 seconds 624 measures/s
Get measures Push 43k measures of 1 metric 260k measures/s
What about getting measures? Well, it's actually pretty fast too. Retrieving a metric with 1 month of data with 1 minute interval (that's 43k points) takes less than 2 second. Though it's actually slower than what I expected. The reason seems to be that the JSON is 2 MB big and encoding it takes a lot of time for Python. I'll investigate that. Another point I discovered, is that by default Gnocchi returns all the datapoints for each granularities available for the asked period, which might double the size of the returned data for nothing if you don't need it. It'll be easy to add an option to the API to only retrieve what you need though! Once benchmarked, that meant I was able to retrieve 6 metric/s per second, which translates to around 260k measures/s. Metricd speed New measures that are pushed into Gnocchi are processed asynchronously by the gnocchi-metricd daemon. When doing the benchmarks above, I ran into a very interesting issue: sending 10k measures on a metric would make gnocchi-metricd uses up to 2 GB RAM and 120 % CPU for more than 10 minutes. After further investigation, I found that the naive approach we used to resample datapoints in Carbonara using Pandas was causing that. I reported a bug on Pandas and the upstream author was kind enough to provide a nice workaround, that I sent as a pull request to Pandas documentation. I wrote a fix for Gnocchi based on that, and started using it. Computing the standard aggregation methods set (std, count, 95pct, min, max, sum, median, mean) for 10k batches of 1 measure (worst case scenario) for one metric with 10k measures now takes only 20 seconds and uses 100 MB of RAM 45 faster. That means that in normal operations, where only a few new measures are processed, the operation of updating a metric only takes a few milliseconds. Awesome! Comparison with Ceilometer For comparison sake, I've quickly run some read operations benchmark in Ceilometer. I've fed it with one month of samples for 100 instances polled every minute. That represents roughly 4.3M samples injected, and that took a while almost 1 hour whereas it would have taken less than a minute in Gnocchi. Then I tried to retrieve some statistics in the same way that we provide them in Gnocchi, which mean aggregating them over a period of 60 seconds over a month.
Operation Details Rate
Read metric SQL Read measures for 1 metric 2min 58s
Read metric MongoDB Read measures for 1 metric 28s
Read metric Gnocchi Read measures for 1 metric 2s
Obviously, Ceilometer is very slow. It has to look into 4M of samples to compute and return the result, which takes a lot of time. Whereas Gnocchi just has to fetch a file and pass it over. That also means that the more samples you have (so the more time you collect data and the more resources you have), slower Ceilometer will become. This is not a problem with Gnocchi, as I emphasized when I started designing it. Most Gnocchi operations are O(log R) where R is the number of metrics or resources, whereas most Ceilometer operations are O(log S) where S is the number of samples (measures). Since is R millions of time smaller than S, Gnocchi gets to be much faster. And what's even more interesting, is that Gnocchi is entirely scalable horizontally. Adding more Gnocchi servers (for the API and its background processing worker metricd) will multiply Gnocchi performances by the number of servers added. Improvements There are several things to improve in Gnocchi, such as splitting Carbonara archives to make them more efficient, especially from drivers such as Ceph and Swift. It's already on my plate, and I'm looking forwarding to working on that! And if you have any questions, feel free to shoot them in the comment section.

12 October 2015

Joachim Breitner: Incredible Proof Machine put to the test

I m currently on the way home, returning from a four-day workshop for high school students; ages 13 to 20, grade 9 to 13. My goal was to teach them something about proofs and logic, in a ambitiously formal and abstract way. For this workshop, I created a computer program called The Incredible Proof Machine that allows the kids to explore creating a proof, by placing blocks on a canvas and drawing connections between them (see my previous blog post for an introduction). Subtracting time spent on on breaks, organizational stuff, the time the student needed to prepare a final presentation, I think we were working for a total of 14 hours, during which we covered propositional logic. I generally let the students explore and try to solve the tasks of one session mostly on their own, followed by a common discussion of what they have just done, what it means why it makes sense etc. The sessions were: assumptions and conclusions in general, with conjunction; implication; disjunction; falsum and tertium non datur. We also briefly discussed paper proofs with the student: how they look, and how they relate to the Proof Machine proofs. We had some lecture notes that we handed out pice-wise after each session. The sections were mildly1 password-protected to avoid that the quicker students would work ahead, thus keeping the group together. One or two of the 13 students were doing very well and eventually, I gave them the passwords to the predicate logic section and let them work them on them on their own. The quickest managed to solve almost all of these as well, but (as far I as I can tell) without a deeper understanding of the quantifiers, and more a mechanical intuition. As expected, the students were able to solve most of the exercises, even when a proper understanding of the logical semantics was not yet fully developed. This was by design: I believe that this way it was more motivating and encouraging, as they could make it work , compared to a more traditional approach of first throwing a lot of theory at them and then expecting them to apply it. This was confirmed by their feedback after the workshop. I was happy with my implementation. The students immediately could work with it with very few hick-ups, and only one minor bug occurred2, which I could fix on the spot. Having everything run on in the browser was a big plus, given that we had no stable internet connection for everyone: Once the Incredible Proof Machine was loaded, the student could continue to work offline. Personally, I find that the UI is occasionally too sluggish, especially on the weaker laptops, but it seems that the students did not seem to mind. Some students tried to connect outputs with outputs or inputs with inputs and the visualization did make it clearly visible that such a link is not actually connected to the block. The predicate logic part is a bit less convincing, with e.g. scoping of local constants not easily understood. I would say that this part would work better if some explanation is given before the students start working on the more involved rules. Our room was equipped with a smartboard, and I was delighted when I found out, mostly by accident, that I could actually use my finger to drag the blocks of the proof and to draw connections. This not only gave me a Minority Report -like feeling, but also meant that it was much easier for the students to follow my explanations when they could just watch my hand, instead of trying to locate the mouse pointer on a regular projector. I m generally doubtful whether such fancy technological toys are useful in the class room, but in this case at least I liked it. The ability to scribble anywhere on the screen was occasionally a plus as well. All in all I believe the Proof Machine was a useful tool, and I am sure that without it, it would have been tricky to have students voluntarily spend 14 hours on such a relatively dry and abstract topic. Given the amount of work that went into the development, I hope that this will not be the last occasion where it is put to good use. So if you have to teach formal logic and natural deduction-style proofs, you are welcome to use the Incredible Proof Machine to get your students excited. It is purely static, i.e. needs no special server-side infrastructure, and you can define your own logic (i.e. proof rules), sessions and tasks. Also, there are a few interesting way in which the Proof Machine could be extended. In particular, I d like it to be able to generate a normal , natural-language proof from a given proof even if it will sound a bit mechanical and then use hover-highlight effects to relate the formulas and sentences in the text proof to the connections and blocks in the graphical proof. Contributions are welcome!

  1. JavaScript based with no crypto or even obfuscation in the code.
  2. Due to differences between the task specification as given in the code, and the task specification when normalizing the syntax of the terms, the proofs that the students created were lost when they re-loaded the page.

Ben Armstrong: Learning Nova Scotia Plants with Anki Flashcards

plants_of_nova_scotiaOne of the greatest pleasures of walking and hiking is to appreciate all of the many living things encountered along the way. A big part of that appreciation for me is to be able to identify individual species and learn the relationships among them. To that end, I would like to introduce a flashcard deck I created, based on the glossary of the excellent, and also free, Nova Scotia Plants, by Marian C. Munro, Ruth E. Newell, and Nicholas M. Hill, so that I could more effectively use the book as an amateur student of our local flora. Creating the Nova Scotia Plants glossary for Anki I authored the deck on Debian, using the free software utility pdftotext (from poppler-utils), the small shell script below to produce a rough draft, and a text editor to clean up any errors, inconsistencies, and artefacts caused by the conversion process, such as descriptions which wrapped to a second line.
#!/bin/sh
pdftotext -f 40 -l 55 \
  'Print Nova Scotia Plants complete manuscript.pdf' \
  glossary_raw.txt
egrep -v '^[ixvl]+$' glossary_raw.txt   \
  grep -P '^\f?[ a-z]+'   \
  sed -re 's/^\f?([^ ]+)( [- ]+ ? [- ]+ )( ?(.+))/\1\t\4/' \
  > glossary_import.txt
Nova Scotia Plants The Anki flashcard deck is intended as a companion for studying Nova Scotia Plants, linked above, and available either as a single PDF file, or multiple, smaller PDFs per section or family. This ebook has been a constant companion to me on my tablet during my walks and to study in quiet moments of the day. It has enriched my enjoyment of nature in Nova Scotia immeasurably. I am indebted to the authors for the years of work they put into it, and for making it available to the public for free. I hope you get as much out of it as I have. Anki for devices One of the criteria I used in selecting Anki as my flashcard software is that it is available for Debian, but also should work on my devices. I use the free software, AnkiDroid, on my Android phone and tablet, available both in F-Droid and the Google Play store. I understand there is also AnkiMobile for iOS, but that is not free. Feedback Please take the time to give me feedback. I spent an afternoon and a morning putting these materials together to share, and am eager to hear if my work has benefited you. Let me know if you have any suggestions for improvements, and don t forget to leave a review at ankiweb.net. facebooktwittergoogle_plusredditpinterestlinkedinmail

Dirk Eddelbuettel: Seinfeld streak at GitHub: Round Two

So one year ago, I posted a reference to the Seinfeld Streak as used in an even earlier post of regular updates to to the Rcpp Gallery:
This is sometimes called Jerry Seinfeld's secret to productivity: Just keep at it. Don't break the streak.
Now it is one year later and it seems I just doubled up with a second year of GitHub streaking
github activity october 2014 to october 2015
Maybe someone should send help.

This post by Dirk Eddelbuettel originated on his Thinking inside the box blog. Please report excessive re-aggregation in third-party for-profit settings.

11 October 2015

Ben Armstrong: Colours of Autumn 2015, Bluff Trail

My friend Ross Mayhew and I enjoyed a perfect Autumn afternoon yesterday, full of colours on the Bluff Trail. Not all of these photos do justice to the splendour and intricate detail I had hoped to capture, but I hope you enjoy them all the same. Click the photo to start the slideshow.
Late afternoon at the top of Pot Lake loopLate afternoon at the top of Pot Lake loop
On my way to hike, the Canada holly hints of things to come Canada holly berries bright red and close to the branch (vs. dusky red false holly berries on long stems) Unsure which fern this is. Ross says Christmas, but the leaf margins aren t serrated, but smooth. Sheltered by this mossy stump, a pretty mushroom Moss found climbing up a rotted stump, peculiar in that it has flat, fern-like fronds Ross and I spent a while examining this peculiar flat-fronded moss The reds of the huckleberries and maples were striking A tiny fern by a trickle of water across the path A familiar view overlooking Cranberry Lake, now in its fall splendour Brilliant Canada holly berries along the bog at our hike s end
facebooktwittergoogle_plusredditpinterestlinkedinmail

9 October 2015

Miriam Ruiz: Thick Skin (within Free/Open Source communities)

The definition of thick-skinned in different dictionaries ranges from not easily offended to largely unaffected by the needs and feelings of other people; insensitive , going through able to ignore personal criticism , ability to withstand criticism and show no signs of any criticism you may receive getting to you , an insensitive nature or impervious to criticism . It essentially describes an emotionally detached attitude regarding one s social environment, the capacity or ignoring or minimizing the effects of others criticism and the priorization of the protection of one s current state over the capacity of empathizing and taking into account what others may say that don t conform to one s current way of thinking. It is essentially setting up barriers against whatever others may do that might provoke any kind of crisis or change in you. There are a few underlying assumptions in the use of this term as a something good to have, when it comes to interactions with your own community: In the first place, it assumes that your own community is essentially hostile to you, and you will have to be constantly in guard against them. It assumes that it is better to set up barriers against the influence of others within your own comunity, because in fact your own peers are out there essentially to hurt you. Or, at least, they do not care a damn about you. In second place, it assumes that changes are wrong, that personal evolution is wrong, and that the more insensitive you are to your peer s opinions, the best, because they really have nothing to contribute to help you grow as a person. I m smart; you re dumb. I m big; you re little. I m right; you re wrong; And there s nothing you can do about it. (from the film Matilda). Matilda s dad is in fact the first reference that comes to my mind when we re talking about really thick skin. Scene of the film Matilda: I'm smart, You're dumb. I'm big, You're little. I'm right, You're wrong When the main recommendation when the level of aggressiveness within a community is that someone has to make their skin thicker, they are assuming that a bullying environment will help the results. This is nothing new. It s the same theoretical base that you can see in hazing and in other activities involving harassment, abuse or humiliation in college, when initiating a person into some groups. It s supposed to build character, to make someone closer to the alpha male stereotype and, in essence, make us better men (yes, I am using the word men on purpose, because insensitiveness is not usually seen as a positive trait in females). The assumption is that a community with a hard environment and individuals prepared for the war is more effective than a more civilized one. Luckily, that s not the point of view of most members of the Debian Community, and many other Free/Open Source projects. The Code of Conduct is very explicit when it says that a community in which people feel threatened is not a healthy community , and that is good. The Debian Project welcomes and encourages participation by everyone (Diversity Statement), including those with a thin skin, and I m happy about that. There are still a lot of things to improve, of course, but I have the feeling that -despite the occasional complains that having to be respectful to others take the fun away- we re moving in the right direction. The best tip I can give you on thickening your skin = don t. That is, don t thicken your skin. Having a thin skin means you re letting the world in, you re letting what s out there affect what s in you. It means you re connected. You re open. You re considerate and you ll consider it whatever it might be. Having a thin skin may be dangerous, sure, because you might take in so much that you pop, like that blueberry girl from Willy Wonka. But life is dangerous. A thick skin protects you from everything, but it also protects you from everything from the gentle touches of life, from the subtle emotions of others, the deep connections, the meaningful interactions. (Top Ten Tips on how to Thicken your Skin).

8 October 2015

Norbert Preining: Looking at the facts: Sarah Sharp s crusade

Much has been written around the internet about this geeky kernel maintainer Sarah Sharp who left kernel development. I have now spent two hours reading through lkml posts, and want to summarize a few mails from the long thread, since most of the usual news sites just rewrap the original blog of hers without adding any background. darth-cookie The whole thread evolved out call for stable kernel review by Greg Kroah-Hartman where he complained about too many patches that are not actually in rc1 before going into stable:
<rant>
  I'm sitting on top of over 170 more patches that have been marked for
  the stable releases right now that are not included in this set of
  releases.  The fact that there are this many patches for stable stuff
  that are waiting to be merged through the main -rc1 merge window cycle
  is worrying to me.
  [...]
from where it developed into a typical Linus rant on people flagging crap for stable, followed by some jokes:
On Fri, Jul 12, 2013 at 8:47 AM, Steven Rostedt <rostedt@goodmis.org> wrote:
> I tend to hold things off after -rc4 because you scare me more than Greg
> does ;-)
 
Have you guys *seen* Greg? The guy is a freakish giant. He *should*
scare you. He might squish you without ever even noticing.
 
              Linus
and Ingo Molnar giving advice to Greg KH:
So Greg, if you want it all to change, create some _real_ threat: be frank 
with contributors and sometimes swear a bit. That will cut your mailqueue 
in half, promise!
with Greg KH taking a funny position in answering:
Ok, I'll channel my "inner Linus" and take a cue from my kids and start
swearing more.
Up to now a pretty decent and normal thread with some jokes and poking, nobody minded, and reading through it I had a good time. The thread continues with a discussion on requirements what to submit to stable, and some side threads on particular commits. And then, out of the blue, Social Justice Warrior (SJW) Sarah Sharp pops in with a very important contribution:
Seriously, guys?  Is this what we need in order to get improve -stable?
Linus Torvalds is advocating for physical intimidation and violence.
Ingo Molnar and Linus are advocating for verbal abuse.
 
Not *fucking* cool.  Violence, whether it be physical intimidation,
verbal threats or verbal abuse is not acceptable.  Keep it professional
on the mailing lists.
 
Let's discuss this at Kernel Summit where we can at least yell at each
other in person.  Yeah, just try yelling at me about this.  I'll roar
right back, louder, for all the people who lose their voice when they
get yelled at by top maintainers.  I won't be the nice girl anymore.
Onto which Linus answers in a great way:
That's the spirit.
 
Greg has taught you well. You have controlled your fear. Now, release
your anger. Only your hatred can destroy me.
 
Come to the dark side, Sarah. We have cookies.
On goes Sarah, gearing up in her SJW mode and starting to rant:
However, I am serious about this.  Linus, you're one of the worst
offenders when it comes to verbally abusing people and publicly tearing
their emotions apart.
 
http://marc.info/?l=linux-kernel&m=135628421403144&w=2
http://marc.info/?l=linux-acpi&m=136157944603147&w=2
 
I'm not going to put up with that shit any more.
Linus himself made clear what he thinks of her:
Trust me, there's a really easy way for me to curse at people: if you
are a maintainer, and you make excuses for your bugs rather than
trying to fix them, I will curse at *YOU*.
 
Because then the problem really is you.
[...]
It is easy to verify what Linus said, by reading the above two links and the answers of the maintainers, both agreed that it was their failure and were sorry. (Mauro s answer, Rafael s answer) It is just the geeky SJW that was not even attacked (who would dare to attack a woman nowadays?). The overall reaction to her by the maintainers can be exemplified by Thomas Gleixner s post:
Just for the record. I got grilled by Linus several times over the
last years and I can't remember a single instance where it was
unjustified.
What follows is a nearly endless discussion with Sarah meandering around, changing permanently her opinion what is acceptable. Linus tried to explain to her in simple words, without success, she continues to rant around. Here arguments are so weak I had nothing but good laugh:
> Sarah, that's a pretty potent argument by Linus, that "acting 
> professionally" risks replacing a raw but honest culture with a
> polished but dishonest culture - which is harmful to developing
> good technology.
> 
> That's a valid concern. What's your reply to that argument?
 
I don't feel the need to comment, because I feel it's a straw man
argument.  I feel that way because I disagree with the definition of
professionalism that people have been pushing.
 
To me, being "professional" means treating each other with respect.  I
can show emotion, express displeasure, be direct, and still show respect
for my fellow developers.
 
For example, I find the following statement to be both direct and
respectful, because it's criticizing code, not the person:
 
"This code is SHIT!  It adds new warnings and it's marked for stable
when it's clearly *crap code* that's not a bug fix.  I'm going to revert
this merge, and I expect a fix from you IMMEDIATELY."
 
The following statement is not respectful, because it targets the
person:
 
"Seriously, Maintainer.  Why are you pushing this kind of *crap* code to
me again?  Why the hell did you mark it for stable when it's clearly
not a bug fix?  Did you even try to f*cking compile this?"
Fortunately, she was immediately corrected and Ingo Molnar wrote an excellent refutation (starting another funny thread) of all her emails, statements, accusations (all of the email is a good read):
_That_ is why it might look to you as if the person was
attacked, because indeed the actions of the top level maintainer were
wrong and are criticised.
 
... and now you want to 'shut down' the discussion. With all due respect,
you started it, you have put out various heavy accusations here and elsewhere,
so you might as well take responsibility for it and let the discussion be
brought to a conclusion, wherever that may take us, compared to your initial view?
(He retracted that last statement, though I don t see a reason for it) Last but not least, let us return to her blog post, where she states herself that:
FYI, comments will be moderated by someone other than me. As this is my blog, not a
government entity, I have the right to replace any comment I feel like with 
 fart fart fart fart .
and she made lots of use of it, I counted at least 10 instances. She seems to remove or fart fart fart any comment that is not in line with her opinion. Further evidence is provided by this post on lkml. Everyone is free to have his own opinion (sorry, his/her), and I am free to form my own opinion on Sarah Sharp by just simply reading the facts. I am more than happy that one more SJW has left Linux development, as the proliferation of cleaning of speech from any personality has taken too far a grip. Coming to my home-base in Debian, unfortunately there is no one in the position and the state of mind of Linus, so we are suffering the same stupidities imposed by social justice worriers and some brainless feminists (no, don t get me wrong, these are two independent attributes. I do NOT state that feminism is brainless) that Linus and the maintainer crew was able to fend of this time. I finish with my favorite post from that thread, by Steven Rosted (from whom I also stole the above image!):
On Tue, 2013-07-16 at 18:37 -0700, Linus Torvalds wrote:
> Emotions aren't bad. Quite the reverse. 
 
Spock and Dr. Sheldon Cooper strongly disagree.
Post Scriptum (after a bike ride) The last point by Linus is what I criticize most on Debian nowdays, it has become a sterilized over-governed entity, where most fun is gone. Making fun is practically forbidden, since there is the slight chance that some minority somewhere on this planet might feel hurt, and by this we are breaking the CoC. Emotions are restricted to the Happy happy how nice we are and how good we are level of US and also Japanese self-reenforcement society. Post Post Scriptum I just read Sarah Sharp s post on What makes a good community? , and without giving a full account or review, I am just pi**ed by the usage of the word microaggressions I can only recommend everyone to read this article and this article to get a feeling how bs the idea of microaggressions has taken over academia and obviously not only academia. Post3 Scriptum I am happy to see Lars Wirzenius, Gunnar Wolf, and Mart n Ferrari opposing my view. I agree with them that my comments concerning Debian are not mainstream in Debian something that is not very surprising, though, and I think it is great that they have fun in Debian, like many other contributors. Post4 Scriptum Although nobody will read this, here is a great response from a female developer:
[...] To Linus: You're a hero to many of us. Don't change. Please. You DO
NOT need to take time away from doing code to grow a pair of breasts
and judge people's emotional states: [...]
Nothing to add here!

7 October 2015

Emanuele Rocca: systemd is your friend

Today I want to talk a bit about some cool features of systemd, the default Debian init system since the release of Jessie. Ubuntu has also adopted systemd in 15.04, meaning that you are going to find it literally everywhere.
Logging The component responsible for logging in systemd is called journal. It collects and stores logs in a structured, indexed journal (hence the name). The journal can replace traditional syslog daemons such as rsyslog and syslog-ng, or work together with them. By default Debian keeps on using rsyslog, but if you don't need to ship logs to a centralized server (or do other fancy things) it is possible to stop using rsyslog right now and rely on systemd-journal instead. The obvious question is: why would anybody use a binary format for logs instead of a bunch of tried and true plain-text files? As it turns out, there are quite a lot of good reasons to do so. The killer features of systemd-journald for me are:
  • Index tons of logs while being able to search with good performance: O(log(n)) instead of O(n) which is what you get with text files
  • No need to worry about log rotation anymore, in any shape or form
The last point in particular is really critical in my opinion. Traditional log rotation implementations rely on cron jobs to check how much disk space is used by logs, compressing/removing old files. Log rotation is usually: 1) annoying to configure; 2) hard to get right; 3) prone to DoS attacks. With journald, there is pretty much nothing to configure. Log rotation is built into the daemon disk space allocation logic itself. This also allows to avoid vulnerability windows due to time-based rotation, which is what you get with logrotate and friends. Enough high-level discussions though, here is how to use the journal! Check if you already have the directory /var/log/journal, otherwise create it (as root). Then restart systemd-journald as follows: sudo systemctl restart systemd-journald You can get all messages produced since the last boot with journalctl -b. All messages produced today can get extracted using journalctl --since=today. Want to get all logs related to ssh? Try with journalctl _SYSTEMD_UNIT=ssh.service. There are many more filtering options available, you can read all about them with man journalctl. journald's configuration file is /etc/systemd/journald.conf. Two of the most interesting options are SystemMaxUse and SystemKeepFree, which can be used to change the amount of disk space dedicated to logging. They default to 10% and 15% of the /var filesystem respectively. Here is a little cheatsheet:
journalctl -b                # Show all messages since last boot
journalctl -f                # Tail your logs
journalctl --since=yesterday # Show all messages produced since yesterday
journalctl -pcrit            # Filter messages by priority
journalctl /bin/su           # Filter messages by program
journalctl --disk-usage      # The amount of space in use for journaling
Further reading:
Containers A relatively little known component of systemd is systemd-nspawn. It is a small, straightforward container manager. If you don't already have a chroot somewhere, here is how to create a basic Debian Jessie chroot under /srv/chroots/jessie:
$ debootstrap jessie /srv/chroots/jessie http://http.debian.net/debian/
With systemd-nspawn you can easily run a shell inside the chroot:
$ sudo systemd-nspawn -D /srv/chroots/jessie
Spawning container jessie on /srv/chroots/jessie.
Press ^] three times within 1s to kill container.
/etc/localtime is not a symlink, not updating container timezone.
root@jessie:~#
Done. Everything works out of the box: no need for you to mount /dev, /run and friends, systemd-nspawn took care of that. Networking also works. If you want to actually boot the system, just add the -b switch to the previous command:
$ sudo systemd-nspawn -b -D /srv/chroots/jessie
Spawning container jessie on /srv/chroots/jessie.
Press ^] three times within 1s to kill container.
/etc/localtime is not a symlink, not updating container timezone.
systemd 215 running in system mode. (+PAM +AUDIT +SELINUX +IMA +SYSVINIT +LIBCRYPTSETUP +GCRYPT +ACL +XZ -SECCOMP -APPARMOR)
Detected virtualization 'systemd-nspawn'.
Detected architecture 'x86-64'.
Welcome to Debian GNU/Linux jessie/sid!
Set hostname to <orion>.
[  OK  ] Reached target Remote File Systems (Pre).
[  OK  ] Reached target Encrypted Volumes.
[  OK  ] Reached target Paths.
[  OK  ] Reached target Swap.
[  OK  ] Created slice Root Slice.
[  OK  ] Created slice User and Session Slice.
[  OK  ] Listening on /dev/initctl Compatibility Named Pipe.
[  OK  ] Listening on Delayed Shutdown Socket.
[  OK  ] Listening on Journal Socket (/dev/log).
[  OK  ] Listening on Journal Socket.
[  OK  ] Created slice System Slice.
[  OK  ] Created slice system-getty.slice.
[  OK  ] Listening on Syslog Socket.
         Mounting POSIX Message Queue File System...
         Mounting Huge Pages File System...
         Mounting FUSE Control File System...
         Starting Copy rules generated while the root was ro...
         Starting Journal Service...
[  OK  ] Started Journal Service.
[  OK  ] Reached target Slices.
         Starting Remount Root and Kernel File Systems...
[  OK  ] Mounted Huge Pages File System.
[  OK  ] Mounted POSIX Message Queue File System.
[  OK  ] Mounted FUSE Control File System.
[  OK  ] Started Copy rules generated while the root was ro.
[  OK  ] Started Remount Root and Kernel File Systems.
         Starting Load/Save Random Seed...
[  OK  ] Reached target Local File Systems (Pre).
[  OK  ] Reached target Local File Systems.
         Starting Create Volatile Files and Directories...
[  OK  ] Reached target Remote File Systems.
         Starting Trigger Flushing of Journal to Persistent Storage...
[  OK  ] Started Load/Save Random Seed.
         Starting LSB: Raise network interfaces....
[  OK  ] Started Create Volatile Files and Directories.
         Starting Update UTMP about System Boot/Shutdown...
[  OK  ] Started Trigger Flushing of Journal to Persistent Storage.
[  OK  ] Started Update UTMP about System Boot/Shutdown.
[  OK  ] Started LSB: Raise network interfaces..
[  OK  ] Reached target Network.
[  OK  ] Reached target Network is Online.
[  OK  ] Reached target System Initialization.
[  OK  ] Listening on D-Bus System Message Bus Socket.
[  OK  ] Reached target Sockets.
[  OK  ] Reached target Timers.
[  OK  ] Reached target Basic System.
         Starting /etc/rc.local Compatibility...
         Starting Login Service...
         Starting LSB: Regular background program processing daemon...
         Starting D-Bus System Message Bus...
[  OK  ] Started D-Bus System Message Bus.
         Starting System Logging Service...
[  OK  ] Started System Logging Service.
         Starting Permit User Sessions...
[  OK  ] Started /etc/rc.local Compatibility.
[  OK  ] Started LSB: Regular background program processing daemon.
         Starting Cleanup of Temporary Directories...
[  OK  ] Started Permit User Sessions.
         Starting Console Getty...
[  OK  ] Started Console Getty.
[  OK  ] Reached target Login Prompts.
[  OK  ] Started Login Service.
[  OK  ] Reached target Multi-User System.
[  OK  ] Reached target Graphical Interface.
         Starting Update UTMP about System Runlevel Changes...
[  OK  ] Started Cleanup of Temporary Directories.
[  OK  ] Started Update UTMP about System Runlevel Changes.
Debian GNU/Linux jessie/sid orion console
orion login:
That's it! Just one command to start a shell in your chroot or boot the container, again zero configuration needed. Finally, systemd provides a command called machinectl that allows you to introspect and control your container:
$ sudo machinectl status jessie
jessie
           Since: Wed 2015-10-07 11:22:56 CEST; 55min ago
          Leader: 32468 (systemd)
         Service: nspawn; class container
            Root: /srv/chroots/jessie
         Address: fe80::8e70:5aff:fe81:2290
                  192.168.122.1
                  192.168.1.13
              OS: Debian GNU/Linux jessie/sid
            Unit: machine-jessie.scope
                   32468 /lib/systemd/systemd
                   system.slice
                     dbus.service
                       32534 /usr/bin/dbus-daemon --system --address=systemd: --nofork --nopidfile -...
                     cron.service
                       32539 /usr/sbin/cron
                     systemd-journald.service
                       32487 /lib/systemd/systemd-journald
                     systemd-logind.service
                       32532 /lib/systemd/systemd-logind
                     console-getty.service
                       32544 /sbin/agetty --noclear --keep-baud console 115200 38400 9600 vt102
                     rsyslog.service
                       32540 /usr/sbin/rsyslogd -n
With machinectl you can also reboot, poweroff, terminate your containers and more. There are so many things to learn about systemd and containers! Here are some references. This stuff is pretty exciting. Now that all major distributions use systemd by default, we can expect to have access to tools like journalctl and systemd-nspawn everywhere!

Dirk Eddelbuettel: RcppRedis 0.1.6

An incremental RcppRedis release arrived on CRAN yesterday. Russell Pierce contributed four new function for pushing and popping to/from lists, and added authentication support. I added a simple ping command as well.
Changes in version 0.1.6 (2015-10-05)
  • Added support (including new unit tests) for lpop, rpop, lpush, rpush as well as auth via augmented constructor (all thanks to PRs #11 and #13 by Russell Pierce)
  • Added ping command and unit test
Courtesy of CRANberries, there is also a diffstat report for the most recent release. More information is on the RcppRedis page.

This post by Dirk Eddelbuettel originated on his Thinking inside the box blog. Please report excessive re-aggregation in third-party for-profit settings.

6 October 2015

Ben Armstrong: Cranberry Lake and nearby bog Fall, 2015

On one of my regular walks with a friend, we decided today to walk part of the BLT Trail to Cranberry Lake and the bog just past it, an easy 5 km round trip.
On the trail to the lake, golds dominateOn the trail to the lake, golds dominate
A calm day, the lake like glassA calm day, the lake like glass
In the bog, copper and golden huesIn the bog, copper and golden hues
On the margins of the bog, brilliant orange and redOn the margins of the bog, brilliant orange and red
The reds, dark greens and dead trees in counterpointThe reds, dark greens and dead trees in counterpoint
At our turning point, my cranberry patch provided a puckery snackAt our turning point, my cranberry patch provided a puckery snack
facebooktwittergoogle_plusredditpinterestlinkedinmail

4 October 2015

Dirk Eddelbuettel: RcppArmadillo 0.6.100.0.0

armadillo image The somewhat regular monthly upstream Armadillo update brings us a first release of the 6.* series. This follows an earlier test release announced on the list, and released to the Rcpp drat. And as version 6.100.0 was released on Friday by Conrad, we rolled it into RcppArmadillo release 0.6.100.0.0 yesterday. Following yet another full test against all reverse dependencies, got uploaded to CRAN which has now accepted it. A matching upload to Debian will follow shortly. Armadillo is a powerful and expressive C++ template library for linear algebra aiming towards a good balance between speed and ease of use with a syntax deliberately close to a Matlab. This release a few changes:
Changes in RcppArmadillo version 0.6.100.0.0 (2015-10-03)
  • Upgraded to Armadillo 6.100.0 ("Midnight Blue")
    • faster norm() and normalise() when using ATLAS or OpenBLAS
    • added Schur decomposition: schur()
    • stricter handling of matrix objects by hist() and histc()
    • advanced constructors for using auxiliary memory by Mat, Col, Row and Cube now have the default of strict = false
    • Cube class now delays allocation of .slice() related structures until needed
    • expanded join_slices() to handle joining cubes with matrices
Courtesy of CRANberries, there is also a diffstat report for the most recent CRAN release. As always, more detailed information is on the RcppArmadillo page. Questions, comments etc should go to the rcpp-devel mailing list off the R-Forge page.

This post by Dirk Eddelbuettel originated on his Thinking inside the box blog. Please report excessive re-aggregation in third-party for-profit settings.

2 October 2015

Daniel Pocock: Want to be selected for Google Summer of Code 2016?

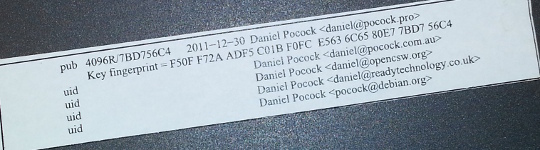
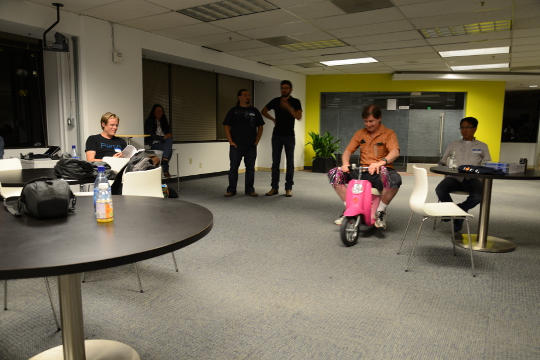
I've mentored a number of students in 2013, 2014 and 2015 for Debian and Ganglia and most of the companies I've worked with have run internships and graduate programs from time to time. GSoC 2015 has just finished and with all the excitement, many students are already asking what they can do to prepare and be selected for Outreachy or GSoC in 2016. My own observation is that the more time the organization has to get to know the student, the more confident they can be selecting that student. Furthermore, the more time that the student has spent getting to know the free software community, the more easily they can complete GSoC. Here I present a list of things that students can do to maximize their chance of selection and career opportunities at the same time. These tips are useful for people applying for GSoC itself and related programs such as GNOME's Outreachy or graduate placements in companies. Disclaimers There is no guarantee that Google will run the program again in 2016 or any future year until the Google announcement. There is no guarantee that any organization or mentor (including myself) will be involved until the official list of organizations is published by Google. Do not follow the advice of web sites that invite you to send pizza or anything else of value to prospective mentors. Following the steps in this page doesn't guarantee selection. That said, people who do follow these steps are much more likely to be considered and interviewed than somebody who hasn't done any of the things in this list. Understand what free software really is You may hear terms like free software and open source software used interchangeably. They don't mean exactly the same thing and many people use the term free software for the wrong things. Not all projects declaring themselves to be "free" or "open source" meet the definition of free software. Those that don't, usually as a result of deficiencies in their licenses, are fundamentally incompatible with the majority of software that does use genuinely free licenses. Google Summer of Code is about both writing and publishing your code and it is also about community. It is fundamental that you know the basics of licensing and how to choose a free license that empowers the community to collaborate on your code well after GSoC has finished. Please review the definition of free software early on and come back and review it from time to time. The The GNU Project / Free Software Foundation have excellent resources to help you understand what a free software license is and how it works to maximize community collaboration. Don't look for shortcuts There is no shortcut to GSoC selection and there is no shortcut to GSoC completion. The student stipend (USD $5,500 in 2014) is not paid to students unless they complete a minimum amount of valid code. This means that even if a student did find some shortcut to selection, it is unlikely they would be paid without completing meaningful work. If you are the right candidate for GSoC, you will not need a shortcut anyway. Are you the sort of person who can't leave a coding problem until you really feel it is fixed, even if you keep going all night? Have you ever woken up in the night with a dream about writing code still in your head? Do you become irritated by tedious or repetitive tasks and often think of ways to write code to eliminate such tasks? Does your family get cross with you because you take your laptop to Christmas dinner or some other significant occasion and start coding? If some of these statements summarize the way you think or feel you are probably a natural fit for GSoC. An opportunity money can't buy The GSoC stipend will not make you rich. It is intended to make sure you have enough money to survive through the summer and focus on your project. Professional developers make this much money in a week in leading business centers like New York, London and Singapore. When you get to that stage in 3-5 years, you will not even be thinking about exactly how much you made during internships. GSoC gives you an edge over other internships because it involves publicly promoting your work. Many companies still try to hide the potential of their best recruits for fear they will be poached or that they will be able to demand higher salaries. Everything you complete in GSoC is intended to be published and you get full credit for it. Imagine a young musician getting the opportunity to perform on the main stage at a rock festival. This is how the free software community works. It is a meritocracy and there is nobody to hold you back. Having a portfolio of free software that you have created or collaborated on and a wide network of professional contacts that you develop before, during and after GSoC will continue to pay you back for years to come. While other graduates are being screened through group interviews and testing days run by employers, people with a track record in a free software project often find they go straight to the final interview round. Register your domain name and make a permanent email address Free software is all about community and collaboration. Register your own domain name as this will become a focal point for your work and for people to get to know you as you become part of the community. This is sound advice for anybody working in IT, not just programmers. It gives the impression that you are confident and have a long term interest in a technology career. Choosing the provider: as a minimum, you want a provider that offers DNS management, static web site hosting, email forwarding and XMPP services all linked to your domain. You do not need to choose the provider that is linked to your internet connection at home and that is often not the best choice anyway. The XMPP foundation maintains a list of providers known to support XMPP. Create an email address within your domain name. The most basic domain hosting providers will let you forward the email address to a webmail or university email account of your choice. Configure your webmail to send replies using your personalized email address in the From header. Update your ~/.gitconfig file to use your personalized email address in your Git commits. Create a web site and blog Start writing a blog. Host it using your domain name. Some people blog every day, other people just blog once every two or three months. Create links from your web site to your other profiles, such as a Github profile page. This helps reinforce the pages/profiles that are genuinely related to you and avoid confusion with the pages of other developers. Many mentors are keen to see their students writing a weekly report on a blog during GSoC so starting a blog now gives you a head start. Mentors look at blogs during the selection process to try and gain insight into which topics a student is most suitable for. Create a profile on Github Github is one of the most widely used software development web sites. Github makes it quick and easy for you to publish your work and collaborate on the work of other people. Create an account today and get in the habbit of forking other projects, improving them, committing your changes and pushing the work back into your Github account. Github will quickly build a profile of your commits and this allows mentors to see and understand your interests and your strengths. In your Github profile, add a link to your web site/blog and make sure the email address you are using for Git commits (in the ~/.gitconfig file) is based on your personal domain. Start using PGP Pretty Good Privacy (PGP) is the industry standard in protecting your identity online. All serious free software projects use PGP to sign tags in Git, to sign official emails and to sign official release files. The most common way to start using PGP is with the GnuPG (GNU Privacy Guard) utility. It is installed by the package manager on most Linux systems. When you create your own PGP key, use the email address involving your domain name. This is the most permanent and stable solution. Print your key fingerprint using the gpg-key2ps command, it is in the signing-party package on most Linux systems. Keep copies of the fingerprint slips with you. This is what my own PGP fingerprint slip looks like. You can also print the key fingerprint on a business card for a more professional look. Using PGP, it is recommend that you sign any important messages you send but you do not have to encrypt the messages you send, especially if some of the people you send messages to (like family and friends) do not yet have the PGP software to decrypt them. If using the Thunderbird (Icedove) email client from Mozilla, you can easily send signed messages and validate the messages you receive using the Enigmail plugin. Get your PGP key signed Once you have a PGP key, you will need to find other developers to sign it. For people I mentor personally in GSoC, I'm keen to see that you try and find another Debian Developer in your area to sign your key as early as possible. Free software events Try and find all the free software events in your area in the months between now and the end of the next Google Summer of Code season. Aim to attend at least two of them before GSoC. Look closely at the schedules and find out about the individual speakers, the companies and the free software projects that are participating. For events that span more than one day, find out about the dinners, pub nights and other social parts of the event. Try and identify people who will attend the event who have been GSoC mentors or who intend to be. Contact them before the event, if you are keen to work on something in their domain they may be able to make time to discuss it with you in person. Take your PGP fingerprint slips. Even if you don't participate in a formal key-signing party at the event, you will still find some developers to sign your PGP key individually. You must take a photo ID document (such as your passport) for the other developer to check the name on your fingerprint but you do not give them a copy of the ID document. Events come in all shapes and sizes. FOSDEM is an example of one of the bigger events in Europe, linux.conf.au is a similarly large event in Australia. There are many, many more local events such as the Debian UK mini-DebConf in Cambridge, November 2015. Many events are either free or free for students but please check carefully if there is a requirement to register before attending. On your blog, discuss which events you are attending and which sessions interest you. Write a blog during or after the event too, including photos. Quantcast generously hosted the Ganglia community meeting in San Francisco, October 2013. We had a wild time in their offices with mini-scooters, burgers, beers and the Ganglia book. That's me on the pink mini-scooter and Bernard Li, one of the other Ganglia GSoC 2014 admins is on the right. Install Linux GSoC is fundamentally about free software. Linux is to free software what a tree is to the forest. Using Linux every day on your personal computer dramatically increases your ability to interact with the free software community and increases the number of potential GSoC projects that you can participate in. This is not to say that people using Mac OS or Windows are unwelcome. I have worked with some great developers who were not Linux users. Linux gives you an edge though and the best time to gain that edge is now, while you are a student and well before you apply for GSoC. If you must run Windows for some applications used in your course, it will run just fine in a virtual machine using Virtual Box, a free software solution for desktop virtualization. Use Linux as the primary operating system. Here are links to download ISO DVD (and CD) images for some of the main Linux distributions: If you are nervous about getting started with Linux, install it on a spare PC or in a virtual machine before you install it on your main PC or laptop. Linux is much less demanding on the hardware than Windows so you can easily run it on a machine that is 5-10 years old. Having just 4GB of RAM and 20GB of hard disk is usually more than enough for a basic graphical desktop environment although having better hardware makes it faster. Your experiences installing and running Linux, especially if it requires some special effort to make it work with some of your hardware, make interesting topics for your blog. Decide which technologies you know best Personally, I have mentored students working with C, C++, Java, Python and JavaScript/HTML5. In a GSoC program, you will typically do most of your work in just one of these languages. From the outset, decide which language you will focus on and do everything you can to improve your competence with that language. For example, if you have already used Java in most of your course, plan on using Java in GSoC and make sure you read Effective Java (2nd Edition) by Joshua Bloch. Decide which themes appeal to you Find a topic that has long-term appeal for you. Maybe the topic relates to your course or maybe you already know what type of company you would like to work in. Here is a list of some topics and some of the relevant software projects:
  • System administration, servers and networking: consider projects involving monitoring, automation, packaging. Ganglia is a great community to get involved with and you will encounter the Ganglia software in many large companies and academic/research networks. Contributing to a Linux distribution like Debian or Fedora packaging is another great way to get into system administration.
  • Desktop and user interface: consider projects involving window managers and desktop tools or adding to the user interface of just about any other software.
  • Big data and data science: this can apply to just about any other theme. For example, data science techniques are frequently used now to improve system administration.
  • Business and accounting: consider accounting, CRM and ERP software.
  • Finance and trading: consider projects like R, market data software like OpenMAMA and connectivity software (Apache Camel)
  • Real-time communication (RTC), VoIP, webcam and chat: look at the JSCommunicator or the Jitsi project
  • Web (JavaScript, HTML5): look at the JSCommunicator
Before the GSoC application process begins, you should aim to learn as much as possible about the theme you prefer and also gain practical experience using the software relating to that theme. For example, if you are attracted to the business and accounting theme, install the PostBooks suite and get to know it. Maybe you know somebody who runs a small business: help them to upgrade to PostBooks and use it to prepare some reports. Make something Make some small project, less than two week's work, to demonstrate your skills. It is important to make something that somebody will use for a practical purpose, this will help you gain experience communicating with other users through Github. For an example, see the servlet Juliana Louback created for fixing phone numbers in December 2013. It has since been used as part of the Lumicall web site and Juliana was selected for a GSoC 2014 project with Debian. There is no better way to demonstrate to a prospective mentor that you are ready for GSoC than by completing and publishing some small project like this yourself. If you don't have any immediate project ideas, many developers will also be able to give you tips on small projects like this that you can attempt, just come and ask us on one of the mailing lists. Ideally, the project will be something that you would use anyway even if you do not end up participating in GSoC. Such projects are the most motivating and rewarding and usually end up becoming an example of your best work. To continue the example of somebody with a preference for business and accounting software, a small project you might create is a plugin or extension for PostBooks. Getting to know prospective mentors Many web sites provide useful information about the developers who contribute to free software projects. Some of these developers may be willing to be a GSoC mentor. For example, look through some of the following: Getting on the mentor's shortlist Once you have identified projects that are interesting to you and developers who work on those projects, it is important to get yourself on the developer's shortlist. Basically, the shortlist is a list of all students who the developer believes can complete the project. If I feel that a student is unlikely to complete a project or if I don't have enough information to judge a student's probability of success, that student will not be on my shortlist. If I don't have any student on my shortlist, then a project will not go ahead at all. If there are multiple students on the shortlist, then I will be looking more closely at each of them to try and work out who is the best match. One way to get a developer's attention is to look at bug reports they have created. Github makes it easy to see complaints or bug reports they have made about their own projects or other projects they depend on. Another way to do this is to search through their code for strings like FIXME and TODO. Projects with standalone bug trackers like the Debian bug tracker also provide an easy way to search for bug reports that a specific person has created or commented on. Once you find some relevant bug reports, email the developer. Ask if anybody else is working on those issues. Try and start with an issue that is particularly easy and where the solution is interesting for you. This will help you learn to compile and test the program before you try to fix any more complicated bugs. It may even be something you can work on as part of your academic program. Find successful projects from the previous year Contact organizations and ask them which GSoC projects were most successful. In many organizations, you can find the past students' project plans and their final reports published on the web. Read through the plans submitted by the students who were chosen. Then read through the final reports by the same students and see how they compare to the original plans. Start building your project proposal now Don't wait for the application period to begin. Start writing a project proposal now. When writing a proposal, it is important to include several things:
  • Think big: what is the goal at the end of the project? Does your work help the greater good in some way, such as increasing the market share of Linux on the desktop?
  • Details: what are specific challenges? What tools will you use?
  • Time management: what will you do each week? Are there weeks where you will not work on GSoC due to vacation or other events? These things are permitted but they must be in your plan if you know them in advance. If an accident or death in the family cut a week out of your GSoC project, which work would you skip and would your project still be useful without that? Having two weeks of flexible time in your plan makes it more resilient against interruptions.
  • Communication: are you on mailing lists, IRC and XMPP chat? Will you make a weekly report on your blog?
  • Users: who will benefit from your work?
  • Testing: who will test and validate your work throughout the project? Ideally, this should involve more than just the mentor.
If your project plan is good enough, could you put it on Kickstarter or another crowdfunding site? This is a good test of whether or not a project is going to be supported by a GSoC mentor. Learn about packaging and distributing software Packaging is a vital part of the free software lifecycle. It is very easy to upload a project to Github but it takes more effort to have it become an official package in systems like Debian, Fedora and Ubuntu. Packaging and the communities around Linux distributions help you reach out to users of your software and get valuable feedback and new contributors. This boosts the impact of your work. To start with, you may want to help the maintainer of an existing package. Debian packaging teams are existing communities that work in a team and welcome new contributors. The Debian Mentors initiative is another great starting place. In the Fedora world, the place to start may be in one of the Special Interest Groups (SIGs). Think from the mentor's perspective After the application deadline, mentors have just 2 or 3 weeks to choose the students. This is actually not a lot of time to be certain if a particular student is capable of completing a project. If the student has a published history of free software activity, the mentor feels a lot more confident about choosing the student. Some mentors have more than one good student while other mentors receive no applications from capable students. In this situation, it is very common for mentors to send each other details of students who may be suitable. Once again, if a student has a good Github profile and a blog, it is much easier for mentors to try and match that student with another project. GSoC logo generic Conclusion Getting into the world of software engineering is much like joining any other profession or even joining a new hobby or sporting activity. If you run, you probably have various types of shoe and a running watch and you may even spend a couple of nights at the track each week. If you enjoy playing a musical instrument, you probably have a collection of sheet music, accessories for your instrument and you may even aspire to build a recording studio in your garage (or you probably know somebody else who already did that). The things listed on this page will not just help you walk the walk and talk the talk of a software developer, they will put you on a track to being one of the leaders. If you look over the profiles of other software developers on the Internet, you will find they are doing most of the things on this page already. Even if you are not selected for GSoC at all or decide not to apply, working through the steps on this page will help you clarify your own ideas about your career and help you make new friends in the software engineering community.
30 September 2015

Ben Armstrong: Halifax Mainland Common: Early Fall, 2015

A friend and I regularly meet to chat over coffee and then usually finish up by walking the maintained trail in the Halifax Mainland Common Park, but today we decided to take a brief excursion onto the unmaintained trails criss-crossing the park. The last gasp of a faint summer and early signs of fall are evident everywhere. Some mushrooms are dried and cracked in a mosaic pattern: image image Ferns and other brush are browning amongst the various greens of late summer: image A few late blueberries still cling to isolated bushes here and there: image The riot of fall colours in this small clearing, dotted with cotton-grass, burst into view as we round a corner, set behind by a backdrop of nearby buildings: image image The ferns here are vivid, like a slow burning fire that will take the rest of fall to burn out: image We appreciate one last splash of colour before we head back under the cover of woods to rejoin the maintained trail: image So many times we ve travelled our usual route on automatic . I m happy today we left the more travelled trail to share in these glimpses of the changing of seasons in a wilderness preserved for our enjoyment immediately at hand to a densely populated part of the city. facebooktwittergoogle_plusredditpinterestlinkedinmail

Chris Lamb: Free software activities in September 2015

Inspired by Rapha l Hertzog, here is a monthly update covering a large part of what I have been doing in the free software world:
Debian The Reproducible Builds project was also covered in depth on LWN as well as in Lunar's weekly reports (#18, #19, #20, #21, #22).
Uploads
  • redis A new upstream release, as well as overhauling the systemd configuration, maintaining feature parity with sysvinit and adding various security hardening features.
  • python-redis Attempting to get its Debian Continuous Integration tests to pass successfully.
  • libfiu Ensuring we do not FTBFS under exotic locales.
  • gunicorn Dropping a dependency on python-tox now that tests are disabled.


RC bugs


I also filed FTBFS bugs against actdiag, actdiag, bangarang, bmon, bppphyview, cervisia, choqok, cinnamon-control-center, clasp, composer, cpl-plugin-naco, dirspec, django-countries, dmapi, dolphin-plugins, dulwich, elki, eqonomize, eztrace, fontmatrix, freedink, galera-3, golang-git2go, golang-github-golang-leveldb, gopher, gst-plugins-bad0.10, jbofihe, k3b, kalgebra, kbibtex, kde-baseapps, kde-dev-utils, kdesdk-kioslaves, kdesvn, kdevelop-php-docs, kdewebdev, kftpgrabber, kile, kmess, kmix, kmldonkey, knights, konsole4, kpartsplugin, kplayer, kraft, krecipes, krusader, ktp-auth-handler, ktp-common-internals, ktp-text-ui, libdevice-cdio-perl, libdr-tarantool-perl, libevent-rpc-perl, libmime-util-java, libmoosex-app-cmd-perl, libmoosex-app-cmd-perl, librdkafka, libxml-easyobj-perl, maven-dependency-plugin, mmtk, murano-dashboard, node-expat, node-iconv, node-raw-body, node-srs, node-websocket, ocaml-estring, ocaml-estring, oce, odb, oslo-config, oslo.messaging, ovirt-guest-agent, packagesearch, php-svn, php5-midgard2, phpunit-story, pike8.0, plasma-widget-adjustableclock, plowshare4, procps, pygpgme, pylibmc, pyroma, python-admesh, python-bleach, python-dmidecode, python-libdiscid, python-mne, python-mne, python-nmap, python-nmap, python-oslo.middleware, python-riemann-client, python-traceback2, qdjango, qsapecng, ruby-em-synchrony, ruby-ffi-rzmq, ruby-nokogiri, ruby-opengraph-parser, ruby-thread-safe, shortuuid, skrooge, smb4k, snp-sites, soprano, stopmotion, subtitlecomposer, svgpart, thin-provisioning-tools, umbrello, validator.js, vdr-plugin-prefermenu, vdr-plugin-vnsiserver, vdr-plugin-weather, webkitkde, xbmc-pvr-addons, xfsdump & zanshin.

27 September 2015

Niels Thykier: There is nothing like (missing) iptables (rules) to make you use tor

I have been fiddling with setting up both iptables and tor on my local machine. Most of it was fairly easy to do, once I dedicated the time to actually do it. Configuring both at the same time also made things easier for me, but YMMV. Regardless, it did take quite a while researching, tweaking and testing most of that time was spent on the iptables front for me. I ended up doing this incrementally. The major 5 steps I went through were:
  1. Created a basic incoming (INPUT) firewall enforcing
  2. Installed tor + torsocks and aliased a few commands to run with torsocks
  3. Created a basic outgoing (OUTPUT) firewall permissive
  4. Make the outgoing firewall enforcing
  5. Migrate the majority of programs and services to use tor.
Some of these overlapped time-wise and I certainly revisited the configuration a couple of times. A couple of things, that I learned:
  • You probably want to have a look at netstat --listen -put --numeric when you write your INPUT firewall.
  • The tor developers have tried a lot to make things easy. It is scary how often torsocks program [args] just works(tm).
    • That said, it does not always work.
  • Tor and iptables (OUTPUT) can have a synergy effect on each other.
    • Notably, when it is easier to just torsocks a program than adding the necessary iptables rules.
  • Writing iptables rules become a lot easier once:
    • You learn how to iptables s LOG rule
    • You use sensible-editor + iptables-restore or something like puppet s firewall module

Filed under: Debian

Ben Armstrong: Annual Bluff Hike, 2015

Here is a photo journal of our hike on the Bluff Wilderness Trail with my friend, Ryan Neily, as is our tradition at this time of year. Rather than hike all four loops, as we achieved last year, we chose to cover only the Pot Lake and Indian Hill loops. Like our meandering pace, our conversations were enjoyable and far ranging, with Nature doing her part, stimulating our minds and bodies and refreshing our spirits.
A break at the summit of Pot Lake loop. Click to start slideshow.A break at the summit of Pot Lake loop. Click to start slideshow.
Northern bayberry A few showers quickly dissipated into light mist on the first leg of the hike Ryan, enjoying one of the many beautiful views Cormorant or shag. Hard to say from this poor, zoomed cellphone shot. Darkened pool amongst the rugged trees Late summer colours A riot of life shoots up in every crevice Large boulders and trees, forming a non-concrete alley along the trail margin Huckleberries still plentiful on the Indian Hill loop Sustenance to keep us going Not at all picked over, like the Pot Lake loop We break here for lunch Just about ready to embark on the last half We are surprised by the productivity of these short, scrubby huckleberries Barely rising from the reindeer moss, each huckleberry twig provides sweet, juicy handfuls A small pond on the trip back A break on the home stretch Common juniper, which nevertheless is not so common out here Immature green common juniper berries (actually cones)
facebooktwittergoogle_plusredditpinterestlinkedinmail

Next.

Previous.