Search Results: "nate"

1 September 2014

Dirk Eddelbuettel: littler 0.2.0

We are happy to announce a new release of littler. A few minor things have changes since the last release: max-heap image Full details are provided at the ChangeLog The code is available via the GitHub repo, from tarballs off my littler page and the local directory here. A fresh package will got to Debian's incoming queue shortly as well. Comments and suggestions are welcome via the mailing list or issue tracker at the GitHub repo.

This post by Dirk Eddelbuettel originated on his Thinking inside the box blog. Please report excessive re-aggregation in third-party for-profit settings.

Peter Palfrader: Fun and Profit with lirc

= Fun and Profit with lirc == Getting the basics A couple weeks ago I got myself a small USB Infrared Transceiver from the people at iguanaworks. It comes in different models and I got the dual socket one that allows me to hook up external IR emitters. The goal was to remote control my stereo from my desktop machine, so using wired IR blasters gives me the flexibility I need with the wiring. They provide Debian packages built for some version of Ubunutu from their website. I wanted to build them from source, so apt-get source from their repository it is. The build process of the package is pretty broken -- it assumes there already is an iguanair user for instance. If somebody could package this up properly for Debian that'd be real nice. And who knows, maybe upstream would appreciate that as well. At first glance the software looks free enough. Once iguanair has been built and installed, lirc needs a recompile -- it will pick up the iguanair library automatically. Their Getting Started docs are actually pretty good. == Learning the IR codes Anyway, once the software was set up, I needed the IR-codes to send to my Denon. There are a couple of databases for varios remote controls and receivers on the internet, but I didn't find a single entry for my old Denon AVR-1600RD. Fortunately lirc alls you to learn codes off a remote control you already have, and since the iguana device also comes with a receiver, I could use irrecord to get the needed magic bytes for commands like power on/off, mute, volume up/down. This actually worked quite well, the only problem was realizing that the IR blasters are really picky about being properly aligned and close to the receiver (my Denon). Once I got that right, all the recorded codes worked. lircd.conf for Denon AVR-1600RD == Putting it all together I can now use this to mute my stereo using irsend send_once denon KEY_MUTE for instance. What I also wanted to get out of this was that the stereo should be shut off automatically when my machine goes to sleep, or when I haven't used it in a while. Since my Denon only has a power toggle command and does not appear to have a discrete power-off command -- at least I don't know it -- I needed something on my system to keep state, and it means I no longer should use my real remote control or else things will get out of sync. I have written a small wrapper script that does this for me -- stereo. It's in /usr/local/bin . === Initialisation On boot, the script creates its state file when called with the init command. There is a small init script that takes care of this, as well as turning off the stereo when the machine reboots or powers off. === Power off on suspend In addition to powering off the stereo when the machine goes down, I also want it to do that when it goes to sleep. Enter /etc/pm/sleep.d/20 stereo . === Power off on idle Furthermore, I run the script out of cron every 5 minutes - to see if anything is using the alsa device. If there isn't for half an hour the stereo gets turned off. Crontab entry: */5 * * * * /usr/local/bin/stereo off-if-idle === Manually controlling it And last not least I have integrated it into my xbindkeys config. I am abusing a couple special keys that I never ever use. Here's the snippet from my ~/.xbindkeysrc : "stereo mute" XF86HomePage "stereo vol-" XF86Search "stereo vol+" XF86Mail "stereo toggle" c:193 "stereo touch" c:192 Cheers,

31 August 2014

Thorsten Alteholz: My Debian activities in August 2014

FTP assistant By pure chance I was able to accept 237 packages, the same number as last month. 33 times I contacted the maintainer to ask a question about a package and 55 times I had to reject a package. The reject number increased a bit as I also worked on packages that already got a note but had not been fully processed. In contrast I only filed three serious bugs this month. Currently there are about 200 packages still waiting in the NEW queue As the freeze for Jessie comes closer every day, I wonder whether all of them can be processed in time. So I don t mind if every maintainer checks the package again and maybe uploads an improved version that can be processed faster. Squeeze LTS This was my second month that I did some work for the Squeeze LTS initiative, started by Raphael Hertzog at Freexian All in all I got assigned a workload of 16.5h for August. I spent these hours to upload new versions of As last month I prepared these uploads on the basis of the corresponding DSAs for Wheezy. For these packages backporting the Wheezy patches to Squeeze was rather easy. I also had a look at python-django and eglibc. Although the python-django patches apply now, the package fails some tests and these issues need some further investigation. In case of eglibc, my small pbuilder didn t have enough resources and trying to build the package resulted in a full disk after more than three hours of work. For PHP5 Ond ej Sur (the real maintainer) suggested to use point releases of upstream instead of applying only patches. I am curious about how much effort is needed for this approach. Stay tuned, next month you will be told more details! Anyway, this is still a lot of fun and I hope I can finish python-django, eglibc and php5 in September. Other packages This month my meep packages plus mpb have been part of a small hdf5 transition. All five packages needed a small patch and a new upload. As the patch was already provided by Gilles Filippini, this was done rather quickly. Support If you would like to support my Debian work you could either be part of the Freexian initiative (see above) or consider to send some bitcoins to 1JHnNpbgzxkoNexeXsTUGS6qUp5P88vHej. Contact me at donation@alteholz.eu if you prefer another way to donate. Every kind of support is most appreciated.

30 August 2014

Francois Marier: Outsourcing your webapp maintenance to Debian

Modern web applications are much more complicated than the simple Perl CGI scripts or PHP pages of the past. They usually start with a framework and include lots of external components both on the front-end and on the back-end. Here's an example from the Node.js back-end of a real application:
$ npm list   wc -l
256
What if one of these 256 external components has a security vulnerability? How would you know and what would you do if of your direct dependencies had a hard-coded dependency on the vulnerable version? It's a real problem and of course one way to avoid this is to write everything yourself. But that's neither realistic nor desirable. However, it's not a new problem. It was solved years ago by Linux distributions for C and C++ applications. For some reason though, this learning has not propagated to the web where the standard approach seems to be to "statically link everything". What if we could build on the work done by Debian maintainers and the security team?

Case study - the Libravatar project As a way of discussing a different approach to the problem of dependency management in web applications, let me describe the decisions made by the Libravatar project.

Description Libravatar is a federated and free software alternative to the Gravatar profile photo hosting site. From a developer point of view, it's a fairly simple stack: The service is split between the master node, where you create an account and upload your avatar, and a few mirrors, which serve the photos to third-party sites. Like with Gravatar, sites wanting to display images don't have to worry about a complicated protocol. In a nutshell, all that a site needs to do is hash the user's email and add that hash to a base URL. Where the federation kicks in is that every email domain is able to specify a different base URL via an SRV record in DNS. For example, francois@debian.org hashes to 7cc352a2907216992f0f16d2af50b070 and so the full URL is:
http://cdn.libravatar.org/avatar/7cc352a2907216992f0f16d2af50b070
whereas francois@fmarier.org hashes to 0110e86fdb31486c22dd381326d99de9 and the full URL is:
http://fmarier.org/avatar/0110e86fdb31486c22dd381326d99de9
due to the presence of an SRV record on fmarier.org.

Ground rules The main rules that the project follows is to:
  1. only use Python libraries that are in Debian
  2. use the versions present in the latest stable release (including backports)

Deployment using packages In addition to these rules around dependencies, we decided to treat the application as if it were going to be uploaded to Debian:
  • It includes an "upstream" Makefile which minifies CSS and JavaScript, gzips them, and compiles PO files (i.e. a "build" step).
  • The Makefile includes a test target which runs the unit tests and some lint checks (pylint, pyflakes and pep8).
  • Debian packages are produced to encode the dependencies in the standard way as well as to run various setup commands in maintainer scripts and install cron jobs.
  • The project runs its own package repository using reprepro to easily distribute these custom packages.
  • In order to update the repository and the packages installed on servers that we control, we use fabric, which is basically a fancy way to run commands over ssh.
  • Mirrors can simply add our repository to their apt sources.list and upgrade Libravatar packages at the same time as their system packages.

Results Overall, this approach has been quite successful and Libravatar has been a very low-maintenance service to run. The ground rules have however limited our choice of libraries. For example, to talk to our queuing system, we had to use the raw Python bindings to the C Gearman library instead of being able to use a nice pythonic library which wasn't in Debian squeeze at the time. There is of course always the possibility of packaging a missing library for Debian and maintaining a backport of it until the next Debian release. This wouldn't be a lot of work considering the fact that responsible bundling of a library would normally force you to follow its releases closely and keep any dependencies up to date, so you may as well share the result of that effort. But in the end, it turns out that there is a lot of Python stuff already in Debian and we haven't had to package anything new yet. Another thing that was somewhat scary, due to the number of packages that were going to get bumped to a new major version, was the upgrade from squeeze to wheezy. It turned out however that it was surprisingly easy to upgrade to wheezy's version of Django, Apache and Postgres. It may be a problem next time, but all that means is that you have to set a day aside every 2 years to bring everything up to date.

Problems The main problem we ran into is that we optimized for sysadmins and unfortunately made it harder for new developers to setup their environment. That's not very good from the point of view of welcoming new contributors as there is quite a bit of friction in preparing and testing your first patch. That's why we're looking at encoding our setup instructions into a Vagrant script so that new contributors can get started quickly. Another problem we faced is that because we use the Debian version of jQuery and minify our own JavaScript files in the build step of the Makefile, we were affected by the removal from that package of the minified version of jQuery. In our setup, there is no way to minify JavaScript files that are provided by other packages and so the only way to fix this would be to fork the package in our repository or (preferably) to work with the Debian maintainer and get it fixed globally in Debian. One thing worth noting is that while the Django project is very good at issuing backwards-compatible fixes for security issues, sometimes there is no way around disabling broken features. In practice, this means that we cannot run unattended-upgrades on our main server in case something breaks. Instead, we make use of apticron to automatically receive email reminders for any outstanding package updates. On that topic, it can occasionally take a while for security updates to be released in Debian, but this usually falls into one of two cases:
  1. You either notice because you're already tracking releases pretty well and therefore could help Debian with backporting of fixes and/or testing;
  2. or you don't notice because it has slipped through the cracks or there simply are too many potential things to keep track of, in which case the fact that it eventually gets fixed without your intervention is a huge improvement.
Finally, relying too much on Debian packaging does prevent Fedora users (a project that also makes use of Libravatar) from easily contributing mirrors. Though if we had a concrete offer, we would certainly look into creating the appropriate RPMs.

Is it realistic? It turns out that I'm not the only one who thought about this approach, which has been named "debops". The same day that my talk was announced on the DebConf website, someone emailed me saying that he had instituted the exact same rules at his company, which operates a large Django-based web application in the US and Russia. It was pretty impressive to read about a real business coming to the same conclusions and using the same approach (i.e. system libraries, deployment packages) as Libravatar. Regardless of this though, I think there is a class of applications that are particularly well-suited for the approach we've just described. If a web application is not your full-time job and you want to minimize the amount of work required to keep it running, then it's a good investment to restrict your options and leverage the work of the Debian community to simplify your maintenance burden. The second criterion I would look at is framework maturity. Given the 2-3 year release cycle of stable distributions, this approach is more likely to work with a mature framework like Django. After all, you probably wouldn't compile Apache from source, but until recently building Node.js from source was the preferred option as it was changing so quickly. While it goes against conventional wisdom, relying on system libraries is a sustainable approach you should at least consider in your next project. After all, there is a real cost in bundling and keeping up with external dependencies. This blog post is based on a talk I gave at DebConf 14: slides, video.

Gergely Nagy: Happy

For the past decade or so, I wasn't exactly happy. I struggled with low self esteem, likely bordered on depression at times. I disappointed friends, family and most of all, myself. There were times I not only disliked the person I was, but hated it. This wasn't healthy, nor forward-looking, I knew that all along, and that made the situation even worse. I tried to maintain a more enthusiastic mask, pretended that nothing's wrong. Being fully aware that there actually is nothing terribly wrong, while still feeling worthless, just added insult to injury.In the past few years, things started to improve. I had a job, things to care about, things to feel passionate about, people around me who knew nothing about the shadows on my heart, yet still smiled, still supported me. But years of self loathing does not disappear overnight.Then one day, some six months ago, my world turned upside down. Years of disappointment, hate and loathing - poof, gone. Today, I'm happy. This is something I have not been able to tell myself in all honesty in this century yet (except maybe for very brief periods of time, when I was happy for someone else).[Engaged]A little over six months ago, I met someone, someone I could open up to. I still remember the first hour, where we talked about our own shortcomings and bad habits. At the end of the day, when She ordered me a crazy-pancake (a pancake with half a dozen random fillings), I felt happy. She is everything I could ever wish for, and more. She isn't just the woman I love, with whom I'll say the words in a couple of months. She's much more than a partner, a friend a soul-mate combined in one person. She is my inspiration, my role model and my Guardian Angel too.I no longer feel worthless, nor inadequate. I am disappointed with myself no more. I do not hate, I do not loathe, and past mistakes, past feelings seem so far away! I can share everything with Her, She does not judge, nor condemn: she supports and helps. With Her, I am happy. With Her, I am who I wanted myself to be. With Her, I am complete.Thank You.

Dirk Eddelbuettel: BH release 1.54.0-4

Another small new release of our BH package providing Boost headers for use by R is now on CRAN. This one brings a one-file change: the file any.hpp comprising the Boost.Any library --- as requested by a fellow package maintainer needing it for a pending upload to CRAN. No other changes were made.
Changes in version 1.54.0-4 (2014-08-29)
  • Added Boost Any requested by Greg Jeffries for his nabo package
Courtesy of CRANberries, there is also a diffstat report for the most recent release. Comments and suggestions are welcome via the mailing list or issue tracker at the GitHub repo.

This post by Dirk Eddelbuettel originated on his Thinking inside the box blog. Please report excessive re-aggregation in third-party for-profit settings.

28 August 2014

Tim Retout: Pump.io update 1

[The story so far: I'm packaging pump.io for Debian.] 4 packages uploaded to NEW: 2 packages eliminated as not needed: 1 package in progress: Got my eye on: Thoughts Currently I'm averaging around one package upload a day, I think? Which would mean ~1 month to go? But there may be challenges around getting packages through the NEW queue in time to build-depend on them. Someone has asked my temporary Twitter account whether I have a pump.io account. Technically, yes, I do - but I don't post anything on it, because I want to run my own server in the long term. As part of running my own server, I always find that easier if I'm installing software from Debian packages. Hence this work. Sledgehammer, meet nut.

23 August 2014

Antti-Juhani Kaijanaho: A milestone toward a doctorate

Yesterday I received my official diploma for the degree of Licentiate of Philosophy. The degree lies between a Master s degree and a doctorate, and is not required; it consists of the coursework required for a doctorate, and a Licentiate Thesis, in which the student demonstrates good conversance with the field of research and the capability of independently and critically applying scientific research methods (official translation of the Government decree on university degrees 794/2004, Section 23 Paragraph 2). The title and abstract of my Licentiate Thesis follow:
Kaijanaho, Antti-Juhani
The extent of empirical evidence that could inform evidence-based design of programming languages. A systematic mapping study.
Jyv skyl : University of Jyv skyl , 2014, 243 p.
(Jyv skyl Licentiate Theses in Computing,
ISSN 1795-9713; 18)
ISBN 978-951-39-5790-2 (nid.)
ISBN 978-951-39-5791-9 (PDF)
Finnish summary Background: Programming language design is not usually informed by empirical studies. In other fields similar problems have inspired an evidence-based paradigm of practice. Central to it are secondary studies summarizing and consolidating the research literature. Aims: This systematic mapping study looks for empirical research that could inform evidence-based design of programming languages. Method: Manual and keyword-based searches were performed, as was a single round of snowballing. There were 2056 potentially relevant publications, of which 180 were selected for inclusion, because they reported empirical evidence on the efficacy of potential design decisions and were published on or before 2012. A thematic synthesis was created. Results: Included studies span four decades, but activity has been sparse until the last five years or so. The form of conditional statements and loops, as well as the choice between static and dynamic typing have all been studied empirically for efficacy in at least five studies each. Error proneness, programming comprehension, and human effort are the most common forms of efficacy studied. Experimenting with programmer participants is the most popular method. Conclusions: There clearly are language design decisions for which empirical evidence regarding efficacy exists; they may be of some use to language designers, and several of them may be ripe for systematic reviewing. There is concern that the lack of interest generated by studies in this topic area until the recent surge of activity may indicate serious issues in their research approach. Keywords: programming languages, programming language design, evidence-based paradigm, efficacy, research methods, systematic mapping study, thematic synthesis
A Licentiate Thesis is assessed by two examiners, usually drawn from outside of the home university; they write (either jointly or separately) a substantiated statement about the thesis, in which they suggest a grade. The final grade is almost always the one suggested by the examiners. I was very fortunate to have such prominent scientists as Dr. Stefan Hanenberg and Prof. Stein Krogdahl as the examiners of my thesis. They recommended, and I received, the grade very good (4 on a scale of 1 5). The thesis has been accepted for publication published in our faculty s licentiate thesis series and will in due course appear has appeared in our university s electronic database (along with a very small number of printed copies). In the mean time, if anyone wants an electronic preprint, send me email at antti-juhani.kaijanaho@jyu.fi.
Figure 1 of the thesis: an overview of the mapping processFigure 1 of the thesis: an overview of the mapping process
As you can imagine, the last couple of months in the spring were very stressful for me, as I pressed on to submit this thesis. After submission, it took me nearly two months to recover (which certain people who emailed me on Planet Haskell business during that period certainly noticed). It represents the fruit of almost four years of work (way more than normally is taken to complete a Licentiate Thesis, but never mind that), as I designed this study in Fall 2010.
Figure 8 of the thesis: Core studies per publication yearFigure 8 of the thesis: Core studies per publication year
Recently, I have been writing in my blog a series of posts in which I have been trying to clear my head about certain foundational issues that irritated me during the writing of the thesis. The thesis contains some of that, but that part of it is not very strong, as my examiners put it, for various reasons. The posts have been a deliberately non-academic attempt to shape the thoughts into words, to see what they look like fixed into a tangible form. (If you go read them, be warned: many of them are deliberately provocative, and many of them are intended as tentative in fact if not in phrasing; the series also is very incomplete at this time.) I closed my previous post, the latest post in that series, as follows:
In fact, the whole of 20th Century philosophy of science is a big pile of failed attempts to explain science; not one explanation is fully satisfactory. [...] Most scientists enjoy not pondering it, for it s a bit like being a cartoon character: so long as you don t look down, you can walk on air.
I wrote my Master s Thesis (PDF) in 2002. It was about the formal method called B ; but I took a lot of time and pages to examine the history and content of formal logic. My supervisor was, understandably, exasperated, but I did receive the highest possible grade for it (which I never have fully accepted I deserved). The main reason for that digression: I looked down, and I just had to go poke the bridge I was standing on to make sure I was not, in fact, walking on air. In the many years since, I ve taken a lot of time to study foundations, first of mathematics, and more recently of science. It is one reason it took me about eight years to come up with a doable doctoral project (and I am still amazed that my department kept employing me; but I suppose they like my teaching, as do I). The other reason was, it took me that long to realize how to study the design of programming languages without going where everyone has gone before. Debian people, if any are still reading, may find it interesting that I found significant use for the dctrl-tools toolset I have been writing for Debian for about fifteen years: I stored my data collection as a big pile of dctrl-format files. I ended up making some changes to the existing tools (I should upload the new version soon, I suppose), and I wrote another toolset (unfortunately one that is not general purpose, like the dctrl-tools are) in the process. For the Haskell people, I mainly have an apology for not attending to Planet Haskell duties in the summer; but I am back in business now. I also note, somewhat to my regret, that I found very few studies dealing with Haskell. I just checked; I mention Haskell several times in the background chapter, but it is not mentioned in the results chapter (because there were not studies worthy of special notice). I am already working on extending this work into a doctoral thesis. I expect, and hope, to complete that one faster.

Daniel Pocock: Want to be selected for Google Summer of Code 2015?

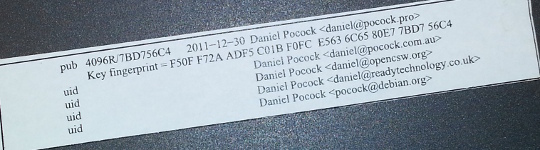
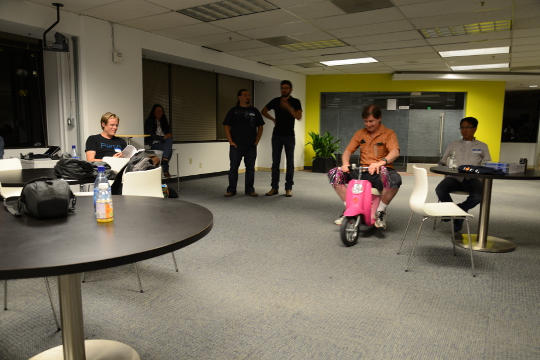
I've mentored a number of students in 2013 and 2014 for Debian and Ganglia and most of the companies I've worked with have run internships and graduate programs from time to time. GSoC 2014 has just finished and with all the excitement, many students are already asking what they can do to prepare and be selected in 2015. My own observation is that the more time the organization has to get to know the student, the more confident they can be selecting that student. Furthermore, the more time that the student has spent getting to know the free software community, the more easily they can complete GSoC. Here I present a list of things that students can do to maximize their chance of selection and career opportunities at the same time. These tips are useful for people applying for GSoC itself and related programs such as GNOME's Outreach Program for Women or graduate placements in companies. Disclaimers There is no guarantee that Google will run the program again in 2015 or any future year. There is no guarantee that any organization or mentor (including myself) will be involved until the official list of organizations is published by Google. Do not follow the advice of web sites that invite you to send pizza or anything else of value to prospective mentors. Following the steps in this page doesn't guarantee selection. That said, people who do follow these steps are much more likely to be considered and interviewed than somebody who hasn't done any of the things in this list. Understand what free software really is You may hear terms like free software and open source software used interchangeably. They don't mean exactly the same thing and many people use the term free software for the wrong things. Not all open source projects meet the definition of free software. Those that don't, usually as a result of deficiencies in their licenses, are fundamentally incompatible with the majority of software that does use genuinely free licenses. Google Summer of Code is about both writing and publishing your code and it is also about community. It is fundamental that you know the basics of licensing and how to choose a free license that empowers the community to collaborate on your code well after GSoC has finished. Please review the definition of free software early on and come back and review it from time to time. The The GNU Project / Free Software Foundation have excellent resources to help you understand what a free software license is and how it works to maximize community collaboration. Don't look for shortcuts There is no shortcut to GSoC selection and there is no shortcut to GSoC completion. The student stipend (USD $5,500 in 2014) is not paid to students unless they complete a minimum amount of valid code. This means that even if a student did find some shortcut to selection, it is unlikely they would be paid without completing meaningful work. If you are the right candidate for GSoC, you will not need a shortcut anyway. Are you the sort of person who can't leave a coding problem until you really feel it is fixed, even if you keep going all night? Have you ever woken up in the night with a dream about writing code still in your head? Do you become irritated by tedious or repetitive tasks and often think of ways to write code to eliminate such tasks? Does your family get cross with you because you take your laptop to Christmas dinner or some other significant occasion and start coding? If some of these statements summarize the way you think or feel you are probably a natural fit for GSoC. An opportunity money can't buy The GSoC stipend will not make you rich. It is intended to make sure you have enough money to survive through the summer and focus on your project. Professional developers make this much money in a week in leading business centers like New York, London and Singapore. When you get to that stage in 3-5 years, you will not even be thinking about exactly how much you made during internships. GSoC gives you an edge over other internships because it involves publicly promoting your work. Many companies still try to hide the potential of their best recruits for fear they will be poached or that they will be able to demand higher salaries. Everything you complete in GSoC is intended to be published and you get full credit for it. Imagine a young musician getting the opportunity to perform on the main stage at a rock festival. This is how the free software community works. It is a meritocracy and there is nobody to hold you back. Having a portfolio of free software that you have created or collaborated on and a wide network of professional contacts that you develop before, during and after GSoC will continue to pay you back for years to come. While other graduates are being screened through group interviews and testing days run by employers, people with a track record in a free software project often find they go straight to the final interview round. Register your domain name and make a permanent email address Free software is all about community and collaboration. Register your own domain name as this will become a focal point for your work and for people to get to know you as you become part of the community. This is sound advice for anybody working in IT, not just programmers. It gives the impression that you are confident and have a long term interest in a technology career. Choosing the provider: as a minimum, you want a provider that offers DNS management, static web site hosting, email forwarding and XMPP services all linked to your domain. You do not need to choose the provider that is linked to your internet connection at home and that is often not the best choice anyway. The XMPP foundation maintains a list of providers known to support XMPP. Create an email address within your domain name. The most basic domain hosting providers will let you forward the email address to a webmail or university email account of your choice. Configure your webmail to send replies using your personalized email address in the From header. Update your ~/.gitconfig file to use your personalized email address in your Git commits. Create a web site and blog Start writing a blog. Host it using your domain name. Some people blog every day, other people just blog once every two or three months. Create links from your web site to your other profiles, such as a Github profile page. This helps reinforce the pages/profiles that are genuinely related to you and avoid confusion with the pages of other developers. Many mentors are keen to see their students writing a weekly report on a blog during GSoC so starting a blog now gives you a head start. Mentors look at blogs during the selection process to try and gain insight into which topics a student is most suitable for. Create a profile on Github Github is one of the most widely used software development web sites. Github makes it quick and easy for you to publish your work and collaborate on the work of other people. Create an account today and get in the habbit of forking other projects, improving them, committing your changes and pushing the work back into your Github account. Github will quickly build a profile of your commits and this allows mentors to see and understand your interests and your strengths. In your Github profile, add a link to your web site/blog and make sure the email address you are using for Git commits (in the ~/.gitconfig file) is based on your personal domain. Start using PGP Pretty Good Privacy (PGP) is the industry standard in protecting your identity online. All serious free software projects use PGP to sign tags in Git, to sign official emails and to sign official release files. The most common way to start using PGP is with the GnuPG (GNU Privacy Guard) utility. It is installed by the package manager on most Linux systems. When you create your own PGP key, use the email address involving your domain name. This is the most permanent and stable solution. Print your key fingerprint using the gpg-key2ps command, it is in the signing-party package on most Linux systems. Keep copies of the fingerprint slips with you. This is what my own PGP fingerprint slip looks like. You can also print the key fingerprint on a business card for a more professional look. Using PGP, it is recommend that you sign any important messages you send but you do not have to encrypt the messages you send, especially if some of the people you send messages to (like family and friends) do not yet have the PGP software to decrypt them. If using the Thunderbird (Icedove) email client from Mozilla, you can easily send signed messages and validate the messages you receive using the Enigmail plugin. Get your PGP key signed Once you have a PGP key, you will need to find other developers to sign it. For people I mentor personally in GSoC, I'm keen to see that you try and find another Debian Developer in your area to sign your key as early as possible. Free software events Try and find all the free software events in your area in the months between now and the end of the next Google Summer of Code season. Aim to attend at least two of them before GSoC. Look closely at the schedules and find out about the individual speakers, the companies and the free software projects that are participating. For events that span more than one day, find out about the dinners, pub nights and other social parts of the event. Try and identify people who will attend the event who have been GSoC mentors or who intend to be. Contact them before the event, if you are keen to work on something in their domain they may be able to make time to discuss it with you in person. Take your PGP fingerprint slips. Even if you don't participate in a formal key-signing party at the event, you will still find some developers to sign your PGP key individually. You must take a photo ID document (such as your passport) for the other developer to check the name on your fingerprint but you do not give them a copy of the ID document. Events come in all shapes and sizes. FOSDEM is an example of one of the bigger events in Europe, linux.conf.au is a similarly large event in Australia. There are many, many more local events such as the Debian France mini-DebConf in Lyon, 2015. Many events are either free or free for students but please check carefully if there is a requirement to register before attending. On your blog, discuss which events you are attending and which sessions interest you. Write a blog during or after the event too, including photos. Quantcast generously hosted the Ganglia community meeting in San Francisco, October 2013. We had a wild time in their offices with mini-scooters, burgers, beers and the Ganglia book. That's me on the pink mini-scooter and Bernard Li, one of the other Ganglia GSoC 2014 admins is on the right. Install Linux GSoC is fundamentally about free software. Linux is to free software what a tree is to the forest. Using Linux every day on your personal computer dramatically increases your ability to interact with the free software community and increases the number of potential GSoC projects that you can participate in. This is not to say that people using Mac OS or Windows are unwelcome. I have worked with some great developers who were not Linux users. Linux gives you an edge though and the best time to gain that edge is now, while you are a student and well before you apply for GSoC. If you must run Windows for some applications used in your course, it will run just fine in a virtual machine using Virtual Box, a free software solution for desktop virtualization. Use Linux as the primary operating system. Here are links to download ISO DVD (and CD) images for some of the main Linux distributions: If you are nervous about getting started with Linux, install it on a spare PC or in a virtual machine before you install it on your main PC or laptop. Linux is much less demanding on the hardware than Windows so you can easily run it on a machine that is 5-10 years old. Having just 4GB of RAM and 20GB of hard disk is usually more than enough for a basic graphical desktop environment although having better hardware makes it faster. Your experiences installing and running Linux, especially if it requires some special effort to make it work with some of your hardware, make interesting topics for your blog. Decide which technologies you know best Personally, I have mentored students working with C, C++, Java, Python and JavaScript/HTML5. In a GSoC program, you will typically do most of your work in just one of these languages. From the outset, decide which language you will focus on and do everything you can to improve your competence with that language. For example, if you have already used Java in most of your course, plan on using Java in GSoC and make sure you read Effective Java (2nd Edition) by Joshua Bloch. Decide which themes appeal to you Find a topic that has long-term appeal for you. Maybe the topic relates to your course or maybe you already know what type of company you would like to work in. Here is a list of some topics and some of the relevant software projects:
  • System administration, servers and networking: consider projects involving monitoring, automation, packaging. Ganglia is a great community to get involved with and you will encounter the Ganglia software in many large companies and academic/research networks. Contributing to a Linux distribution like Debian or Fedora packaging is another great way to get into system administration.
  • Desktop and user interface: consider projects involving window managers and desktop tools or adding to the user interface of just about any other software.
  • Big data and data science: this can apply to just about any other theme. For example, data science techniques are frequently used now to improve system administration.
  • Business and accounting: consider accounting, CRM and ERP software.
  • Finance and trading: consider projects like R, market data software like OpenMAMA and connectivity software (Apache Camel)
  • Real-time communication (RTC), VoIP, webcam and chat: look at the JSCommunicator or the Jitsi project
  • Web (JavaScript, HTML5): look at the JSCommunicator
Before the GSoC application process begins, you should aim to learn as much as possible about the theme you prefer and also gain practical experience using the software relating to that theme. For example, if you are attracted to the business and accounting theme, install the PostBooks suite and get to know it. Maybe you know somebody who runs a small business: help them to upgrade to PostBooks and use it to prepare some reports. Make something Make some small project, less than two week's work, to demonstrate your skills. It is important to make something that somebody will use for a practical purpose, this will help you gain experience communicating with other users through Github. For an example, see the servlet Juliana Louback created for fixing phone numbers in December 2013. It has since been used as part of the Lumicall web site and Juliana was selected for a GSoC 2014 project with Debian. There is no better way to demonstrate to a prospective mentor that you are ready for GSoC than by completing and publishing some small project like this yourself. If you don't have any immediate project ideas, many developers will also be able to give you tips on small projects like this that you can attempt, just come and ask us on one of the mailing lists. Ideally, the project will be something that you would use anyway even if you do not end up participating in GSoC. Such projects are the most motivating and rewarding and usually end up becoming an example of your best work. To continue the example of somebody with a preference for business and accounting software, a small project you might create is a plugin or extension for PostBooks. Getting to know prospective mentors Many web sites provide useful information about the developers who contribute to free software projects. Some of these developers may be willing to be a GSoC mentor. For example, look through some of the following: Getting on the mentor's shortlist Once you have identified projects that are interesting to you and developers who work on those projects, it is important to get yourself on the developer's shortlist. Basically, the shortlist is a list of all students who the developer believes can complete the project. If I feel that a student is unlikely to complete a project or if I don't have enough information to judge a student's probability of success, that student will not be on my shortlist. If I don't have any student on my shortlist, then a project will not go ahead at all. If there are multiple students on the shortlist, then I will be looking more closely at each of them to try and work out who is the best match. One way to get a developer's attention is to look at bug reports they have created. Github makes it easy to see complaints or bug reports they have made about their own projects or other projects they depend on. Another way to do this is to search through their code for strings like FIXME and TODO. Projects with standalone bug trackers like the Debian bug tracker also provide an easy way to search for bug reports that a specific person has created or commented on. Once you find some relevant bug reports, email the developer. Ask if anybody else is working on those issues. Try and start with an issue that is particularly easy and where the solution is interesting for you. This will help you learn to compile and test the program before you try to fix any more complicated bugs. It may even be something you can work on as part of your academic program. Find successful projects from the previous year Contact organizations and ask them which GSoC projects were most successful. In many organizations, you can find the past students' project plans and their final reports published on the web. Read through the plans submitted by the students who were chosen. Then read through the final reports by the same students and see how they compare to the original plans. Start building your project proposal now Don't wait for the application period to begin. Start writing a project proposal now. When writing a proposal, it is important to include several things:
  • Think big: what is the goal at the end of the project? Does your work help the greater good in some way, such as increasing the market share of Linux on the desktop?
  • Details: what are specific challenges? What tools will you use?
  • Time management: what will you do each week? Are there weeks where you will not work on GSoC due to vacation or other events? These things are permitted but they must be in your plan if you know them in advance. If an accident or death in the family cut a week out of your GSoC project, which work would you skip and would your project still be useful without that? Having two weeks of flexible time in your plan makes it more resilient against interruptions.
  • Communication: are you on mailing lists, IRC and XMPP chat? Will you make a weekly report on your blog?
  • Users: who will benefit from your work?
  • Testing: who will test and validate your work throughout the project? Ideally, this should involve more than just the mentor.
If your project plan is good enough, could you put it on Kickstarter or another crowdfunding site? This is a good test of whether or not a project is going to be supported by a GSoC mentor. Learn about packaging and distributing software Packaging is a vital part of the free software lifecycle. It is very easy to upload a project to Github but it takes more effort to have it become an official package in systems like Debian, Fedora and Ubuntu. Packaging and the communities around Linux distributions help you reach out to users of your software and get valuable feedback and new contributors. This boosts the impact of your work. To start with, you may want to help the maintainer of an existing package. Debian packaging teams are existing communities that work in a team and welcome new contributors. The Debian Mentors initiative is another great starting place. In the Fedora world, the place to start may be in one of the Special Interest Groups (SIGs). Think from the mentor's perspective After the application deadline, mentors have just 2 or 3 weeks to choose the students. This is actually not a lot of time to be certain if a particular student is capable of completing a project. If the student has a published history of free software activity, the mentor feels a lot more confident about choosing the student. Some mentors have more than one good student while other mentors receive no applications from capable students. In this situation, it is very common for mentors to send each other details of students who may be suitable. Once again, if a student has a good Github profile and a blog, it is much easier for mentors to try and match that student with another project. GSoC logo generic Conclusion Getting into the world of software engineering is much like joining any other profession or even joining a new hobby or sporting activity. If you run, you probably have various types of shoe and a running watch and you may even spend a couple of nights at the track each week. If you enjoy playing a musical instrument, you probably have a collection of sheet music, accessories for your instrument and you may even aspire to build a recording studio in your garage (or you probably know somebody else who already did that). The things listed on this page will not just help you walk the walk and talk the talk of a software developer, they will put you on a track to being one of the leaders. If you look over the profiles of other software developers on the Internet, you will find they are doing most of the things on this page already. Even if you are not selected for GSoC at all or decide not to apply, working through the steps on this page will help you clarify your own ideas about your career and help you make new friends in the software engineering community.
Tim Retout: Packaging pump.io for Debian

I intend to intend to package pump.io for Debian. It's going to take a long time, but I don't know whether that's weeks or years yet. The world needs decentralized social networking. I discovered the tools that let me create this wiki summary of the progress in pump.io packaging. There are at least 35 dependencies that need uploading, so this would go a lot faster if it weren't a solo effort - if anyone else has some time, please let me know! But meanwhile I'm hoping to build some momentum. I think it's important to keep the quality of the packaging as high as possible, even while working through so many. It would cost a lot of time later if I had to go back and fix bugs in everything. I really want to be running the test suites in these builds, but it's not always easy. One of the milestones along the way might be packaging nodeunit. Nodeunit is a Nodejs unit testing framework (duh), used by node-bcrypt (and, unrelatedly, statsd, which would be pretty cool to have in Debian too). Last night I filed eight pull requests to try and fix up copyright/licensing issues in dependencies of nodeunit. Missing copyright statements are one of the few things I can't fix by myself as a packager. All I can do is wait, and package other dependencies in the meantime. Fortunately there are plenty of those. And I have not seen so many issues in direct dependencies of pump.io itself - or at least they've been fixed in git.

Steve Kemp: Updating Debian Administration, the code

So I previously talked about the setup behind Debian Administration, and my complaints about the slownes. The previous post talked about the logical setup, and the hardware. This post talks about the more interesting thing. The code. The code behind the site was originally written by Denny De La Haye. I found it and reworked it a lot, most obviously adding structure and test cases. Once I did that the early version of the site was born. Later my version became the official version, as when Denny setup Police State UK he used my codebase rather than his. So the code huh? Well as you might expect it is written in Perl. There used to be this layout:
]
yawns/cgi-bin/index.cgi
yawns/cgi-bin/Pages.pl
yawns/lib/...
yawns/htdocs/
Almost every request would hit the index.cgi script, which would parse the request and return the appropriate output via the standard CGI interface. How did it know what you wanted? Well sometimes there would be a paramater set which would be looked up in a dispatch-table:
/cgi-bin/index.cgi?article=40         - Show article 40
/cgi-bin/index.cgi?view_user=Steve    - Show the user Steve
/cgi-bin/index.cgi?recent_comments=10 - Show the most recent comments.
Over time the code became hard to update because there was no consistency, and over time the site became slow because this is not a quick setup. Spiders, bots, and just average users would cause a lot of perl processes to run. So? What did I do? I moved the thing to using FastCGI, which avoids the cost of forking Perl and loading (100k+) the code. Unfortunately this required a bit of work because all the parameter handling was messy and caused issues if I just renamed index.cgi -> index.fcgi. The most obvious solution was to use one parameter, globally, to specify the requested mode of operation. Hang on? One parameter to control the page requested? A persistant environment? What does that remind me of? Yes. CGI::Application. I started small, and pulled some of the code out of index.cgi + Pages.pl, and over into a dedicated CGI::Application class: So now every part of the site that is called by Ajax has one persistent handler, and every part of the site which returns RSS feeds has another. I had some fun setting up the sessions to match those created by the old stuff, but I quickly made it work, as this example shows: The final job was the biggest, moving all the other (non-feed, non-ajax) modes over to a similar CGI::Application structure. There were 53 modes that had to be ported, and I did them methodically, first porting all the Poll-related requests, then all the article-releated ones, & etc. I think I did about 15 a day for three days. Then the rest in a sudden rush. In conclusion the code is now fast because we don't use CGI, and instead use FastCGI. This allowed minor changes to be carried out, such as compiling the HTML::Template templates which determine the look and feel, etc. Those things don't make sense in the CGI environment, but with persistence they are essentially free. The site got a little more of a speed boost when I updated DNS, and a lot more when I blacklisted a bunch of IP-space. As I was wrapping this up I realized that the code had accidentally become closed - because the old repository no longer exists. That is not deliberate, or intentional, and will be rectified soon. The site would never have been started if I'd not seen Dennys original project, and although I don't think others would use the code it should be possible. I remember at the time I was searching for things like "Perl CMS" and finding Slashcode, and Scoop, which I knew were too heavyweight for my little toy blog. In conclusion Debian Administration website is 10 years old now. It might not have changed the world, it might have become less relevant, but I'm glad I tried, and I'm glad there were years when it really was the best place to be. These days there are HowtoForges, blogs, spam posts titled "How to install SSH on Trusty", "How to install SSH on Wheezy", "How to install SSH on Precise", and all that. No shortage of content, just finding the good from the bad is the challenge. Me? The single best resource I read these days is probably LWN.net. Starting to ramble now. Go look at my quick hack for remote command execution https://github.com/skx/nanoexec ?

22 August 2014

Ian Donnelly: Wrapping Up

Hi Everybody! I have been keeping very busy on this blog the past few days with some very exciting updates! Everything is now in place for my Google Summer of Code project! Elektra now has the ability to merge KeySets, ucf has been patched to allow custom merge commands, we included a new elektra-merge script to use in conjunction with the new ucf command, and we wrote a great tutorial on how to use Elektra to merge configuration files in any package using ucf. There are few things I have missed updating you all on or are still wrapping up. First of all, I would like to address the Debian packages. While Elektra includes everything needed for my Google Summer of Code Project, it must be built from source right now. Unfortunately, with the rapid development Elektra has seen the past few months, we did not pay enough attention to the Debian packages and they became dusty and riddles with bugs. Fortunately, we have a solution and his name is Pino Toscano. Pino has, very graciously, agreed to help us fix our Debian packages back into shape. If you wish to see the current progress of the packages, you can check his repo. Pino has already made fantastic progress creating the Debian packages. I will post here when packages are all fixed up and the latest versions of Elektra are into the Debian repo. Some great news that we just received is that Elektra 0.8.7 has just been accepted into Debian unstable! This is huge progress for our team and means that users can now download our packages directly from Debian s unstable repo and test out these new features. Obviously, the normal caveats apply for any packages in unstable but this is still an amazing piece of news and I would like to thank Pino again for all the support he has provided. Another worthy piece of news that I unfortunately haven t had time to cover is that thanks to Felix Berlakovich Elektra has a new plug-in called ini. In case you couldn t guess, this new plug-in is used to mount ini files and the good news is that it is a vast improvement on our older simpleini plug-in. While it is still a work in progress, this new plug-in is much more powerful than simpleini. The new plug-in supports section and comments and works with many more ini files than the old plug-in. You may have noticed that I used this new plug-in to mount smb.conf in my technical demo of Samba using Elektra from configuration merging. Since smb.conf follows the same syntax as an ini file this new plug-in works great for mounting this file into the Elektra Key Database. I hope my blogs so far have been very informative and helpful. Sincerely,
Ian S. Donnelly

21 August 2014

Dirk Eddelbuettel: RcppEigen 0.3.2.2.0

A new upstream release of the Eigen C++ template library for linear algebra was released a few days ago. And Yixuan Qiu did some really nice work rolling this into a new RcppEigen released and then sent me a nice pull requent. The new version is now on CRAN, and I will prepare a Debian in a moment too. Upstream changes for Eigen are summarized in their changelog. On the RcppEigen side, Yixuan also rolled in some more changes on as() and wrap() converters as noted below in the NEWS entry.
Changes in RcppEigen version 0.3.2.2.0 (2014-08-19)
  • Updated to version 3.2.2 of Eigen
  • Rcpp::as() now supports the conversion from R vector to row array , i.e., Eigen::Array<T, 1, Eigen::Dynamic>
  • Rcpp::as() now supports the conversion from dgRMatrix (row oriented sparse matrices, defined in Matrix package) to Eigen::MappedSparseMatrix<T, Eigen::RowMajor>
  • Conversion from R matrix to Eigen::MatrixXd and Eigen::ArrayXXd using Rcpp::as() no longer gives compilation errors
Courtesy of CRANberries, there are diffstat reports for the most recent release. Questions, comments etc about RcppEigen should go to the rcpp-devel mailing list off the R-Forge page.

This post by Dirk Eddelbuettel originated on his Thinking inside the box blog. Please report excessive re-aggregation in third-party for-profit settings.

20 August 2014

Aurelien Jarno: MIPS Creator CI20

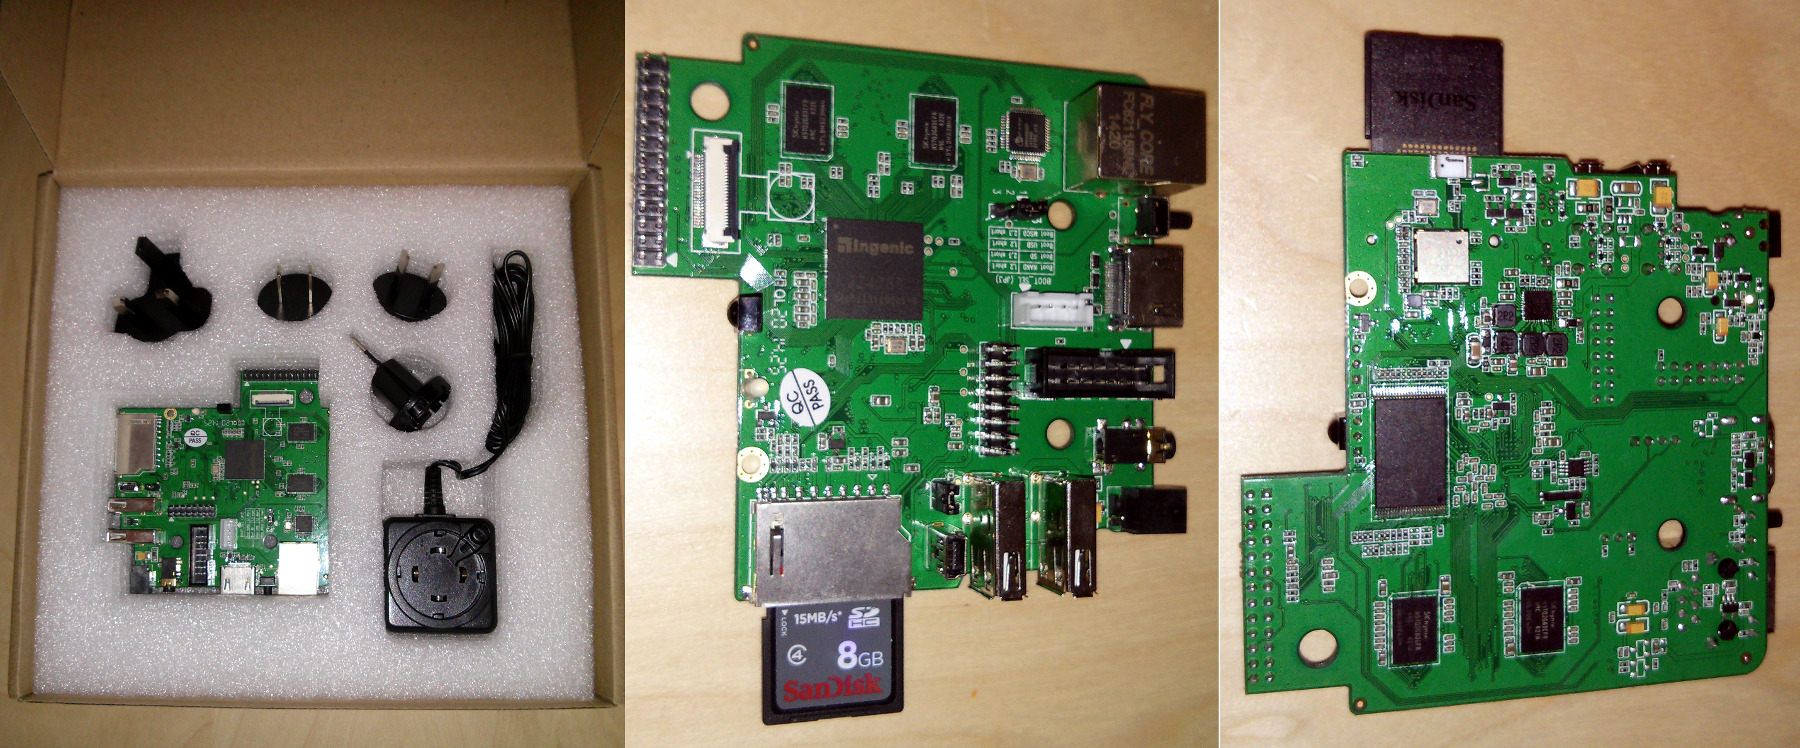
I have received two MIPS Creator CI20 boards, thanks to Imagination Technologies. It s a small MIPS32 development board: mips-ci20 As you can see it comes in a nice packaging with a world-compatible power adapter. It uses a Ingenic JZ4780 SoC with a dual core MIPS32 CPU running at 1.2GHz with a PowerVR SGX540 GPU. The board is fitted with 1GB of RAM, 8GB of NOR flash, HDMI output, USB 2.0 ports, Ethernet + Wi-Fi + BlueTooth, SD card slot, IR receiver, expansion headers and more. The schematics are available. The Linux kernel and the U-Boot bootloader sources are also available. Powering this board with a USB keyboard, a USB mouse and a HDMI display, it boots off the internal flash on a Debian Wheezy up to the XFCE environment. Besides the kernel, the Wi-Fi + Bluetooth firmware, and very few configuration changes, it runs a vanilla Debian. Unfortunately I haven t found time to play more with it yet, but it looks already quite promising. The board has not been formally announced yet, so I do not know when it will become available, nor the price, but if you are interested I ll bring it to DebConf14. Don t hesitate to ask me if you want to look at it or play with it.

Holger Levsen: 20140819-lts-july-2014

Debian LTS - impressions and thoughts from my first month involvement About LTS - we want feedback and more companies supporting it financially Squeeze LTS, and even more Debian LTS, is a pretty young project, started in May 2014, so it's still a bit unclear where exactly we'll be going :) One purpose of this post is to spread some information about the initiative and invite you to tell us what you think about it or what your needs are. LTS stands for "Long Term Support" and the goal of the project is to extend the security support for Squeeze (aka the current oldstable distribution) by two years. If it weren't for Squeeze LTS, the security support for it would have been stopped in May 2014 (=one year after the release of the current stable distribution), which for many is a too short timespan after it's release in February 2011. It's an experiment, we hope that there will be a similar Wheezy LTS initiative in future, but the future is unwritten and things will change based on our experiences and your needs. If you have feedback on the direction LTS should take (or anything else LTS related), please comment on the lts mailing list. For immediate feedback there is also the #debian-lts IRC channel. Another quite pragmatic way to express your needs is to read more about how to financially contribute to LTS and then doing exactly that - and unsurprisingly we are prioritizing the updates based on the needs expressed from our paying customers. My LTS work in July 2014 So, "somehow" I started working for money on Debian LTS in July, which means there were 10h I got paid, and probably another 10h where I did LTS related work unpaid. I used those to release four updates for squeeze-lts (linux-2.6, file, munin and reportbug) fixing 22 CVEs in total. The unpaid work was mostly spent on unsuccessfully working on security updates and on adding support for LTS to the security team tracker, which I improved but couldn't fully address and which I haven't properly shared / committed yet... but at least I have a local instance of the tracker now, which - for LTS - is more useful than the .debian.org one. Hopefully during DebConf14 we'll manage to fix the tracker for good. Without success I've looked at libtasn1-3 (where the first fixes applied easily but then the code had changed too much from what was in squeeze compared to the available patches that I gave up) and libxstream-java (which is at version 1.3, while patches exist for upstream branches 1.4 and 2.x, but those need newer java to build and maybe if I'll spend two more hours I'll can get it build and then I'll have to find a useful test case, which looked quite difficult on a brief look.. so maybe I give up on libxstream-java too.... OTOH, if you use it and can do some testing, please do tell me. Working on all these updates turned out to be more team work than expected and a lot of work involving code (which I did expect), and often code which I'd normally not look at... similarily with tools: one has to deal with tools one doesnt like, eg I had to install cdbs... :-) And as I usually like challenges, this has actually been a lot of fun! Though it's also pretty cool to use common best practices, easy and understandable workflows. I love README.Source (or better yet, when it's not needed). And while git is of course really really great, it's still very desirable if your package builds twice (=many times) in a row, without resetting it via git. Some more observations The first 16 updates (until July 19th) didn't have a DLA ID, until I suggested to introduce them and insisted until we agreed. So now we agreed to put the DLA ID in the subject of the announcement mails and there is also some tool support for generating the templates/mails, but enforcing proper subjects is not done, as silent bounces are useless (and non silent ones can be abused too easily). I'm not really happy about this, but who is happy with the way email works today? And I agree, it's not the end of the world if an LTS announcement is done without a proper ID, but it looks unprofessional and could be avoided, but we have more important work to do. But one day we should automate this better. Another detail I'm not entirely happy is the policy/current decision that "almost everything is fine to upload if deemed sensible by the uploader" (which is everyone in the Debian upload keyring(s)). In discussions before actually having the archive some people suggested the desire to upload new upstream versions too (eg newer kernels, iceweasel or other software to keep running a squeeze desktop in the modern world were discussed). I sincerely hope for most intrusive new upstream versions squeeze-(sloppy-)backports is used instead, and squeeze-lts rather not. Luckily so far all uploads were (IMHO) sensible and so, right now, I will just say that I hope it will stay this way. And it's true, one also has to install these upgrades in the first place. But people do that blindly all the time... So by design/desire currently there is no gatekeeping mechanism whatsover (no NEW, no proposed updates), except that only some selected "few" can upload. What is uploaded (and signed correctly), gets pushed to archive, buildds and the mirrors, and hopefully maybe someone will send an announcement. So far this has worked remarkedly well - and it's also the way the Debian Security team works, as I'm told. Looking at this from a process quality / automatisation perspective, all this manual and errorprone labour seems very strange to me. ;-) And then there is another thing: as already mentioned, the people working paid hours for this, are prioritizing their work based on customer requests. So we did two updates (python-scipy and file), which are not fixed in wheezy yet. I think this is unfortunate and while I could probably prepare the wheezy DSA for file, I don't really want to join the Security Team... or maybe I want/should join the Security Team and be a seldomly active member (eg fixing file in wheezy now....) A note related to this: out of those 37 uploads done until today, 16 were done by those two people being paid, while the other 21 uploads were done by 10 volunteers (or at least not paid by Debian LTS). It will be interesting to see how this statistics evolves over time. Last, but not least, there is also this can of worms (aka: the discussion) about paying people to work on Debian... I do agree it's work we didnt find volunteers for and I also see how the (financial side of the) setup is done outside of Debian (and well too, btw!), but... then we also use Debian ressources like buildds, the archive itself and official mailing lists. Also I'm currently biased in this discussion, as I directly (and happily) profit from it. I'm mentioning this here, because I believe it's important we discuss this and come to both good and practical conclusions. FWIW, we have also discussed this on the list, feel free to search the archives for it. To bring this post to an end: for those attending DebConf14 (directly or thanks to some ninjas), there will be an event about LTS in Portland, though I'm not sure yet what I will have to talk about what hasn't been already covered here :-) But this probably means that will be a good opportunity for you to do lots of talking instead! I'm curious what you will have to say! Thanks for reading this far. I think I can promise that my next LTS report will be shorter :-D

Dirk Eddelbuettel: RcppArmadillo 0.4.400.0

After two pre-releases in the last few days, Conrad finalised a new Armadillo version 4.400 today. I had kept up with the pre-releases, tested twice against all eighty (!!) CRAN dependents of RcppArmadillo and have hence uploaded RcppArmadillo 0.4.400.0 to CRAN and into Debian. This release brings a number of new upstream features which are detailed below. As included is s bugfix for sparse matrix creation at the RcppArmadillo end which was found by the ASAN tests at CRAN --- which are similar to the sanitizers tests I recently blogged. I was able to develop and test the fix in the very docker r-devel-san images I had written about which was nice. Special thanks also to Ryan Curtin for help with the fix.
Changes in RcppArmadillo version 0.4.400.0 (2014-08-19)
  • Upgraded to Armadillo release Version 4.400 (Winter Shark Alley)
    • added gmm_diag class for statistical modelling using Gaussian Mixture Models; includes multi-threaded implementation of k-means and Expectation-Maximisation for parameter estimation
    • added clamp() for clamping values to be between lower and upper limits
    • expanded batch insertion constructors for sparse matrices to add values at repeated locations
    • faster handling of subvectors by dot()
    • faster handling of aliasing by submatrix views
  • Corrected a bug (found by the g++ Address Sanitizer) in sparse matrix initialization where space for a sentinel was allocated, but the sentinel was not set; with extra thanks to Ryan Curtin for help
  • Added a few unit tests for sparse matrices
Courtesy of CRANberries, there is also a diffstat report for the most recent release. As always, more detailed information is on the RcppArmadillo page. Questions, comments etc should go to the rcpp-devel mailing list off the R-Forge page.

This post by Dirk Eddelbuettel originated on his Thinking inside the box blog. Please report excessive re-aggregation in third-party for-profit settings.

18 August 2014

Julien Danjou: OpenStack Ceilometer and the Gnocchi experiment

A little more than 2 years ago, the Ceilometer project was launched inside the OpenStack ecosystem. Its main objective was to measure OpenStack cloud platforms in order to provide data and mechanisms for functionalities such as billing, alarming or capacity planning. In this article, I would like to relate what I've been doing with other Ceilometer developers in the last 5 months. I've lowered my involvement in Ceilometer itself directly to concentrate on solving one of its biggest issue at the source, and I think it's largely time to take a break and talk about it. Ceilometer early design For the last years, Ceilometer didn't change in its core architecture. Without diving too much in all its parts, one of the early design decision was to build the metering around a data structure we called samples. A sample is generated each time Ceilometer measures something. It is composed of a few fields, such as the the resource id that is metered, the user and project id owning that resources, the meter name, the measured value, a timestamp and a few free-form metadata. Each time Ceilometer measures something, one of its components (an agent, a pollster ) constructs and emits a sample headed for the storage component that we call the collector. This collector is responsible for storing the samples into a database. The Ceilometer collector uses a pluggable storage system, meaning that you can pick any database system you prefer. Our original implementation has been based on MongoDB from the beginning, but we then added a SQL driver, and people contributed things such as HBase or DB2 support. The REST API exposed by Ceilometer allows to execute various reading requests on this data store. It can returns you the list of resources that have been measured for a particular project, or compute some statistics on metrics. Allowing such a large panel of possibilities and having such a flexible data structure allows to do a lot of different things with Ceilometer, as you can almost query the data in any mean you want. The scalability issue We soon started to encounter scalability issues in many of the read requests made via the REST API. A lot of the requests requires the data storage to do full scans of all the stored samples. Indeed, the fact that the API allows you to filter on any fields and also on the free-form metadata (meaning non indexed key/values tuples) has a terrible cost in terms of performance (as pointed before, the metadata are attached to each sample generated by Ceilometer and is stored as is). That basically means that the sample data structure is stored in most drivers in just one table or collection, in order to be able to scan them at once, and there's no good "perfect" sharding solution, making data storage scalability painful. It turns out that the Ceilometer REST API is unable to handle most of the requests in a timely manner as most operations are O(n) where n is the number of samples recorded (see big O notation if you're unfamiliar with it). That number of samples can grow very rapidly in an environment of thousands of metered nodes and with a data retention of several weeks. There is a few optimizations to make things smoother in general cases fortunately, but as soon as you run specific queries, the API gets barely usable. During this last year, as the Ceilometer PTL, I discovered these issues first hand since a lot of people were feeding me back with this kind of testimony. We engaged several blueprints to improve the situation, but it was soon clear to me that this was not going to be enough anyway.
Thinking outside the box Unfortunately, the PTL job doesn't leave him enough time to work on the actual code nor to play with anything new. I was coping with most of the project bureaucracy and I wasn't able to work on any good solution to tackle the issue at its root. Still, I had a few ideas that I wanted to try and as soon as I stepped down from the PTL role, I stopped working on Ceilometer itself to try something new and to think a bit outside the box. When one takes a look at what have been brought recently in Ceilometer, they can see the idea that Ceilometer actually needs to handle 2 types of data: events and metrics. Events are data generated when something happens: an instance start, a volume is attached, or an HTTP request is sent to an REST API server. These are events that Ceilometer needs to collect and store. Most OpenStack components are able to send such events using the notification system built into oslo.messaging. Metrics is what Ceilometer needs to store but that is not necessarily tied to an event. Think about an instance CPU usage, a router network bandwidth usage, the number of images that Glance is storing for you, etc These are not events, since nothing is happening. These are facts, states we need to meter. Computing statistics for billing or capacity planning requires both of these data sources, but they should be distinct. Based on that assumption, and the fact that Ceilometer was getting support for storing events, I started to focus on getting the metric part right. I had been a system administrator for a decade before jumping into OpenStack development, so I know a thing or two on how monitoring is done in this area, and what kind of technology operators rely on. I also know that there's still no silver bullet this made it a good challenge. The first thing that came to my mind was to use some kind of time-series database, and export its access via a REST API as we do in all OpenStack services. This should cover the metric storage pretty well. Cooking Gnocchi
A cloud of gnocchis!
At the end of April 2014, this led met to start a new project code-named Gnocchi. For the record, the name was picked after confusing so many times the OpenStack Marconi project, reading OpenStack Macaroni instead. At least one OpenStack project should have a "pasta" name, right? The point of having a new project and not send patches on Ceilometer, was that first I had no clue if it was going to make something that would be any better, and second, being able to iterate more rapidly without being strongly coupled with the release process. The first prototype started around the following idea: what you want is to meter things. That means storing a list of tuples of (timestamp, value) for it. I've named these things "entities", as no assumption are made on what they are. An entity can represent the temperature in a room or the CPU usage of an instance. The service shouldn't care and should be agnostic in this regard. One feature that we discussed for several OpenStack summits in the Ceilometer sessions, was the idea of doing aggregation. Meaning, aggregating samples over a period of time to only store a smaller amount of them. These are things that time-series format such as the RRDtool have been doing for a long time on the fly, and I decided it was a good trail to follow. I assumed that this was going to be a requirement when storing metrics into Gnocchi. The user would need to provide what kind of archiving it would need: 1 second precision over a day, 1 hour precision over a year, or even both. The first driver written to achieve that and store those metrics inside Gnocchi was based on whisper. Whisper is the file format used to store metrics for the Graphite project. For the actual storage, the driver uses Swift, which has the advantages to be part of OpenStack and scalable. Storing metrics for each entities in a different whisper file and putting them in Swift turned out to have a fantastic algorithm complexity: it was O(1). Indeed, the complexity needed to store and retrieve metrics doesn't depends on the number of metrics you have nor on the number of things you are metering. Which is already a huge win compared to the current Ceilometer collector design. However, it turned out that whisper has a few limitations that I was unable to circumvent in any manner. I needed to patch it to remove a lot of its assumption about manipulating file, or that everything is relative to now (time.time()). I've started to hack on that in my own fork, but then everything broke. The whisper project code base is, well, not the state of the art, and have 0 unit test. I was starring at a huge effort to transform whisper into the time-series format I wanted, without being sure I wasn't going to break everything (remember, no test coverage). I decided to take a break and look into alternatives, and stumbled upon Pandas, a data manipulation and statistics library for Python. Turns out that Pandas support time-series natively, and that it could do a lot of the smart computation needed in Gnocchi. I built a new file format leveraging Pandas for computing the time-series and named it carbonara (a wink to both the Carbon project and pasta, how clever!). The code is quite small (a third of whisper's, 200 SLOC vs 600 SLOC), does not have many of the whisper limitations and it has test coverage. These Carbonara files are then, in the same fashion, stored into Swift containers. Anyway, Gnocchi storage driver system is designed in the same spirit that the rest of OpenStack and Ceilometer storage driver system. It's a plug-in system with an API, so anyone can write their own driver. Eoghan Glynn has already started to write a InfluxDB driver, working closely with the upstream developer of that database. Dina Belova started to write an OpenTSDB driver. This helps to make sure the API is designed directly in the right way. Handling resources Measuring individual entities is great and needed, but you also need to link them with resources. When measuring the temperature and the number of a people in a room, it is useful to link these 2 separate entities to a resource, in that case the room, and give a name to these relations, so one is able to identify what attribute of the resource is actually measured. It is also important to provide the possibility to store attributes on these resources, such as their owners, the time they started and ended their existence, etc.
Relationship of entities and resources
Once this list of resource is collected, the next step is to list and filter them, based on any criteria. One might want to retrieve the list of resources created last week or the list of instances hosted on a particular node right now. Resources also need to be specialized. Some resources have attributes that must be stored in order for filtering to be useful. Think about an instance name or a router network. All of these requirements led to to the design of what's called the indexer. The indexer is responsible for indexing entities, resources, and link them together. The initial implementation is based on SQLAlchemy and should be pretty efficient. It's easy enough to index the most requested attributes (columns), and they are also correctly typed. We plan to establish a model for all known OpenStack resources (instances, volumes, networks, ) to store and index them into the Gnocchi indexer in order to request them in an efficient way from one place. The generic resource class can be used to handle generic resources that are not tied to OpenStack. It'd be up to the users to store extra attributes. Dropping the free form metadata we used to have in Ceilometer makes sure that querying the indexer is going to be efficient and scalable.
The indexer classes and their relations
REST API All of this is exported via a REST API that was partially designed and documented in the Gnocchi specification in the Ceilometer repository; though the spec is not up-to-date yet. We plan to auto-generate the documentation from the code as we are currently doing in Ceilometer. The REST API is pretty easy to use, and you can use it to manipulate entities and resources, and request the information back.
Macroscopic view of the Gnocchi architecture
Roadmap & Ceilometer integration All of this plan has been exposed and discussed with the Ceilometer team during the last OpenStack summit in Atlanta in May 2014, for the Juno release. I led a session about this entire concept, and convinced the team that using Gnocchi for our metric storage would be a good approach to solve the Ceilometer collector scalability issue. It was decided to conduct this project experiment in parallel of the current Ceilometer collector for the time being, and see where that would lead the project to. Early benchmarks Some engineers from Mirantis did a few benchmarks around Ceilometer and also against an early version of Gnocchi, and Dina Belova presented them to us during the mid-cycle sprint we organized in Paris in early July. The following graph sums up pretty well the current Ceilometer performance issue. The more you feed it with metrics, the more slow it becomes.
For Gnocchi, while the numbers themselves are not fantastic, what is interesting is that all the graphs below show that the performances are stable without correlation with the number of resources, entities or measures. This proves that, indeed, most of the code is built around a complexity of O(1), and not O(n) anymore.
Next steps
Cl ment drawing the logo
While the Juno cycle is being wrapped-up for most projects, including Ceilometer, Gnocchi development is still ongoing. Fortunately, the composite architecture of Ceilometer allows a lot of its features to be replaced by some other code dynamically. That, for example, enables Gnocchi to provides a Ceilometer dispatcher plugin for its collector, without having to ship the actual code in Ceilometer itself. That should help the development of Gnocchi to not be slowed down by the release process for now. The Ceilometer team aims to provide Gnocchi as a sort of technology preview with the Juno release, allowing it to be deployed along and plugged with Ceilometer. We'll discuss how to integrate it in the project in a more permanent and strong manner probably during the OpenStack Summit for Kilo that will take place next November in Paris.

17 August 2014

Francesca Ciceri: Adventures in Mozillaland #4

Yet another update from my internship at Mozilla, as part of the OPW. An online triage workshop One of the most interesting thing I've done during the last weeks has been to held an online Bug Triage Workshop on the #testday channel at irc.mozilla.org.
That was a first time for me: I had been a moderator for a series of training sessions on IRC organized by Debian Women, but never a "speaker".
The experience turned out to be a good one: creating the material for the workshop had me basically summarize (not too much, I'm way too verbose!) all what I've learned in this past months about triaging in Mozilla, and speaking of it on IRC was a sort of challenge to my usual shyness. And I was so very lucky that a participant was able to reproduce the bug I picked as example, thus confirming it! How cool is that? ;) The workshop was about the very basics of triaging for Firefox, and we mostly focused on a simplified lifecycle of bugs, a guided tour of bugzilla (including the quicksearch and the advanced one, the list view, the individual bug view) and an explanation of the workflow of the triager. I still have my notes, and I plan to upload them to the wiki, sooner or later. I'm pretty satisfied of the outcome: the only regret is that the promoting wasn't enough, so we have few participants.
Will try to promote it better next time! :) about:crashes Another thing that had me quite busy in the last weeks was to learn more about crashes and stability in general.
If you are unfortunate enough to experience a crash with Firefox, you're probably familiar with the Mozilla Crash Reporter dialog box asking you to submit the crash report. But how does it works? From the client-side, Mozilla uses Breakpad as set of libraries for crash reporting. The Mozilla specific implementation adds to that a crash-reporting UI, a server to collect and process crash reported data (and particularly to convert raw dumps into readable stack traces) and a web interface, Socorro to view and parse crash reports. Curious about your crashes? The about:crashes page will show you a list of the submitted and unsubmitted crash reports. (And by the way, try to type about:about in the location bar, to find all the super-secret about pages!) For the submitted ones clicking on the CrashID will take you to the crash report on crash-stats, the website where the reports are stored and analyzed. The individual crash report page on crash-stats is awesome: it shows you the reported bug numbers if any bug summaries match the crash signature, as well as many other information. If crash-stats does not show a bug number, you really should file one! The CrashKill team works on these reports tracking the general stability of the various channels, triaging the top crashes, ensuring that the crash bugs have enough information and are reproducible and actionable by the devs.
The crash-stats site is a mine of information: take a look at the Top Crashes for Firefox 34.0a1.
If you click on a individual crash, you will see lots of details about it: just on the first tab ("Signature Summary") you can find a breakdown of the crashes by OS, by graphic vendors or chips or even by uptime range.
A very useful one is the number of crashes per install, so that you know how widespread is the crashing for that particular signature. You can also check the comments the users have submitted with the crash report, on the "Comments" tab. One and Done tasks review Last week I helped the awesome group of One and Done developers, doing some reviewing of the tasks pages. One and Done is a brilliant idea to help people contribute to the QA Mozilla teams.
It's a website proposing the user a series of tasks of different difficulty and on different topics to contribute to Mozilla. Each task is self-contained and can last few minutes or be a bit more challenging. The team has worked hard on developing it and they have definitely done an awesome job! :) I'm not a coding person, so I just know that they're using Django for it, but if you are interested in all the dirty details take a look at the project repository. My job has been only to check all the existent tasks and verify that the description and instruction are correct, that the task is properly tagged and so on. My impression is that this an awesome tool, well written and well thought with a lot of potential for helping people in their first steps into Mozilla. Something that other projects should definitely imitate (cough Debian cough). What's next? Next week I'll be back on working on bugs. I kind of love bugs, I have to admit it. And not squashing them: not being a coder make me less of a violent person toward digital insects. Herding them is enough for me. I'm feeling extremely non-violent toward bugs. I'll try to help Liz with the Test Plan for Firefox 34, on the triaging/verifying bugs part.
I'll also try to triage/reproduce some accessibility bugs (thanks Mario for the suggestion!).

Next.

Previous.