Search Results: "spa"

15 June 2016

Steve Kemp: So I should document the purple server a little more

I should probably document the purple server I hacked together in Perl and mentioned in my last post. In short it allows you to centralise notifications. Send "alerts" to it, and when they are triggered they will be routed from that central location. There is only a primitive notifier included, which sends data to the console, but there are sample stubs for sending by email/pushover, and escalation. In brief you create alerts by sending a JSON object via HTTP-POST. These objects contain a bunch of fields, but the two most important are: When an update is received any existing alert has its values updated, which makes heartbeat alerts trivial. Send a message with: "id": "heartbeat", "raise": "+5m", .. The existing alert will be updated each time such a new event is submitted, which means that the time at which that alert will raise will be pushed back by five minutes. If you send this every 60 seconds then you'll get informed of an outage five minutes after your server explodes (because the "+5m" will have been turned into an absolute time, and that time will eventually become in the past - triggering a notification). Alerts are keyed on the source IP which sent the submission and the id field, meaning you can send the same update from multiple hosts without causing any problems. Notifications can be viewed in a reasonably pretty Web UI, so you can clear raised-alerts, see the pending ones, and suppress further notifications on something that has been raised. (By default notifications are issued every sixty seconds, until the alert is cleared. There is support for only raising an alert once, which is useful for services you might deliver events via, such as pushover which will repeat themselves.) Anyway this is a fun project, which is a significantly simplified and less scalable version of a project which is open-sourced already and used at Bytemark.

Russ Allbery: Review: Matter

Review: Matter, by Iain M. Banks
Publisher: Orbit
Copyright: February 2008
ISBN: 0-316-00536-3
Format: Hardcover
Pages: 593
Sursamen is an Arithmetic, Mottled, Disputed, Multiply Inhabited, Multi-million Year Safe, and Godded Shellworld. It's a constructed world with multiple inhabitable levels, each lit by thermonuclear "suns" on tracks, each level supported above the last by giant pillars. Before the recorded history of the current Involved Species, a culture called the Veil created the shellworlds with still-obscure technology for some unknown purpose, and then disappeared. Now, they're inhabited by various transplants and watched over by a hierarchy of mentor and client species. In the case of Sursamen, both the Aultridia and the Oct claim jurisdiction (hence "Disputed"), and are forced into an uneasy truce by the Nariscene, a more sophisticated species that oversees them both. On Sursamen, on level eight to be precise, are the Sarl, a culture with an early industrial level of technology in the middle of a war of conquest to unite their level (and, they hope, the next level down). Their mentors are the Oct, who claim descendance from the mysterious Veil. The Deldeyn, the next level down, are mentored by the Aultridia, a species that evolved from a parasite on Xinthian Tensile Aranothaurs. Since a Xinthian, treated by the Sarl as a god, lives in the heart of Sursamen (hence "Godded"), tensions between the Sarl and the Aultridians run understandably high. The ruler of the Sarl had three sons and a daughter. The oldest was killed by the people he is conquering as Matter starts. The middle son is a womanizer and a fop who, as the book opens, watches a betrayal that he's entirely unprepared to deal with. The youngest is a thoughtful, bookish youth pressed into a position that he also is not well-prepared for. His daughter left the Sarl, and Sursamen itself, fifteen years previously. Now, she's a Special Circumstances agent for the Culture. Matter is the eighth Culture novel, although (like most of the series) there's little need to read the books in any particular order. The introduction to the Culture here is a bit scanty, so you'll have more background and understanding if you've read the previous novels, but it doesn't matter a great deal for the story. Sharp differences in technology levels have turned up in previous Culture novels (although the most notable example is a minor spoiler), but this is the first Culture novel I recall where those technological differences were given a structure. Usually, Culture novels have Special Circumstances meddling in, from their perspective, "inferior" cultures. But Sursamen is not in Culture space or directly the Culture's business. The Involved Species that governs Sursamen space is the Morthanveld: an aquatic species roughly on a technology level with the Culture themselves. The Nariscene are their client species; the Oct and Aultridia are, in turn, client species (well, mostly) of the Nariscene, while meddling with the Sarl and Deldeyn. That part of this book reminded me of Brin's Uplift universe. Banks's Involved Species aren't the obnoxious tyrants of Brin's universe, and mentoring doesn't involve the slavery of the Uplift universe. But some of the politics are a bit similar. And, as with Uplift, all the characters are aware, at least vaguely, of the larger shape of galactic politics. Even the Sarl, who themselves have no more than early industrial technology. When Ferbin flees the betrayal to try to get help, he ascends out of the shellworld to try to get assistance from an Involved species, or perhaps his sister (which turns out to be the same thing). Banks spends some time here, mostly through Ferbin and his servant (who is one of the better characters in this book), trying to imagine what it would be like to live in a society that just invented railroads while being aware of interstellar powers that can do practically anything. The plot, like the world on which it's set, proceeds on multiple levels. There is court intrigue within the Sarl, war on their level and the level below, and Ferbin's search for support and then justice. But the Sarl live in an artifact with some very mysterious places, including the best set piece in the book: an enormous waterfall that's gradually uncovering a lost city on the level below the Sarl, and an archaeological dig that proceeds under the Deldeyn and Sarl alike. Djan Seriy decides to return home when she learns of events in Sarl, originally for reasons of family loyalty and obligation, but she's a bit more in touch with the broader affairs of the galaxy, including the fact that the Oct are acting very strangely. There's something much greater at stake on Sursamen than tedious infighting between non-Involved cultures. As always with Banks, the set pieces and world building are amazing, the scenery is jaw-dropping, and I have some trouble warming to the characters. Dramatic flights across tower-studded landscapes seeking access to forbidden world-spanning towers largely, but don't entirely, make up for not caring about most of the characters for most of the book. This did change, though: although I never particularly warmed to Ferbin, I started to like his younger brother, and I really liked his sister and his servant by the end of the book. Unfortunately, the end of Matter is, if not awful, at least exceedingly abrupt. As is typical of Banks, we get a lot of sense of wonder but not much actual explanation, and the denouement is essentially nonexistent. (There is a coy epilogue hiding after the appendices, but it mostly annoyed me and provides only material for extrapolation about the characters.) Another SF author would have written a book about the Xinthian, the Veil, the purpose of the shellworlds, and the deep history of the galaxy. I should have known going in that Banks isn't that sort of SF author, but it was still frustrating. Still, Banks is an excellent writer and this is a meaty, complex, enjoyable story with some amazing moments of wonder and awe. If you like Culture novels in general, you will like this. If you like set-piece-heavy SF on a grand scale, such as Alastair Reynolds or Kim Stanley Robinson, you probably like this. Recommended. Rating: 8 out of 10

13 June 2016

Olivier Gr goire: Third week at GSoC

I begin this week by finish my QT tutorial. With that new knowledge, I was able to implemet my method launchSmartInfo(int) on LRC. After that, I needed to implement the gnome client too. I followed the tutorial on QT so I thought I can just learn GTK+ by reading the code. Finally, I just lost a lot of time by doing that and I didn't learn a lot. In response to that problem I finally use an GTK+ tutorial. I began to try to show n transparente window with some text in front of the call view. To do that, I want to use clutter library ------------ Conclusion: as you can see, I lost a lot of time in this GUI learning. Now it's done, I can move forward! :)

Olivier Gr goire: Third week at GSoC

I begin this week by finish my QT tutorial. With that new knowledge, I was able to implemet my method launchSmartInfo(int) on LRC. After that, I needed to implement the gnome client too. I followed the tutorial on QT so I thought I can just learn GTK+ by reading the code. Finally, I just lost a lot of time by doing that and I didn't learn a lot. In response to that problem I finally use an GTK+ tutorial. I began to try to show an transparente window with some text in front of the call view. To do that, I want to use clutter library ------------ Conclusion: as you can see, I lost a lot of time in this GUI learning. Now it's done, I can move forward! :)

Kevin Avignon: GSOC 2016 : The end

Hi guys, Well because of health problems, I won t be able to meet the expectation for the midterm evaluation coming next week and I will have to step down from the program. It pains me to do so since the project was taking me out of my comfort zone and forcing to adapt to a Continue reading GSOC 2016 : The end

Raphaël Hertzog: Freexian s report about Debian Long Term Support, May 2016

A Debian LTS logoLike each month, here comes a report about the work of paid contributors to Debian LTS. Individual reports In May, 166 work hours have been dispatched among 9 paid contributors. Their reports are available: Evolution of the situation The number of sponsored hours stayed the same over May but will likely increase a little bit the next month as we have two new Bronze sponsors being processed. The security tracker currently lists 36 packages with a known CVE and the dla-needed.txt file lists 36 packages awaiting an update. Despite the higher than usual number of work hours dispatched in May, we still have more open CVE than we used to have at the end of the squeeze LTS period. So more support is always needed Thanks to our sponsors New sponsors are in bold.

No comment Liked this article? Click here. My blog is Flattr-enabled.

12 June 2016

Mario Lang: A Raspberry Pi Zero in a Handy Tech Active Star 40 Braille Display

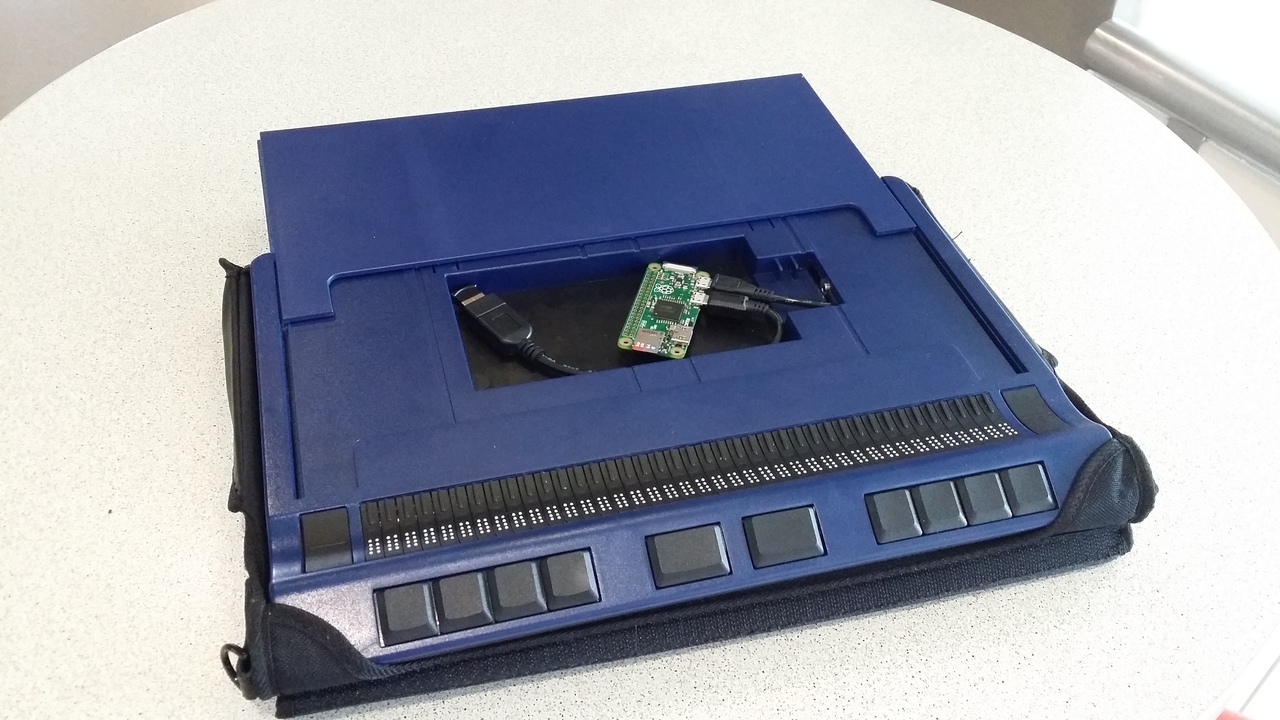
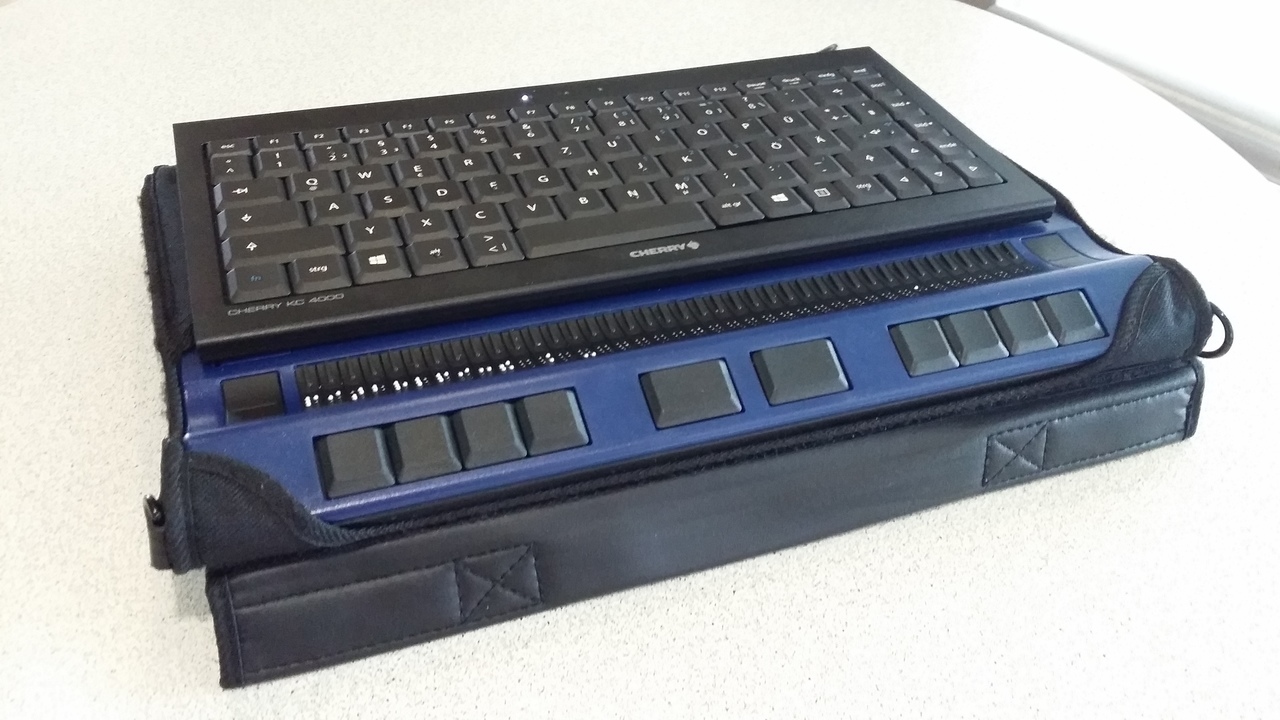
TL;DR: I put a $5 Raspberry Pi Zero, a Bluetooth USB dongle, and the required adapter cable into my new Handy Tech Active Star 40 braille display. An internal USB port provides the power. This has transformed my braille display into an ARM-based, monitorless, Linux laptop that has a keyboard and a braille display. It can be charged/powered via USB so it can also be run from a power bank or a solar charger, thus potentially being able to run for days, rather than just hours, without needing a standard wall-jack. [picture: a Raspberry Pi Zero embedded within an Active Star 40] [picture: a braille display with a keyboard on top and a Raspberry Pi Zero inside]
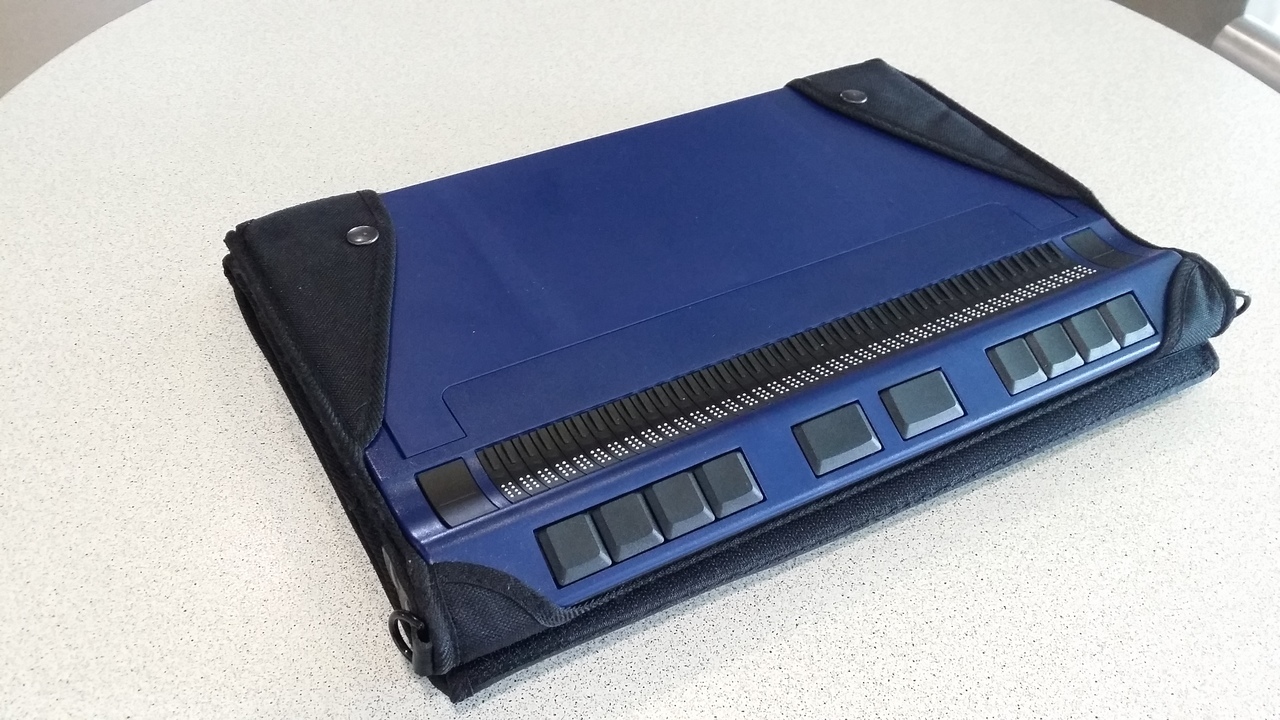
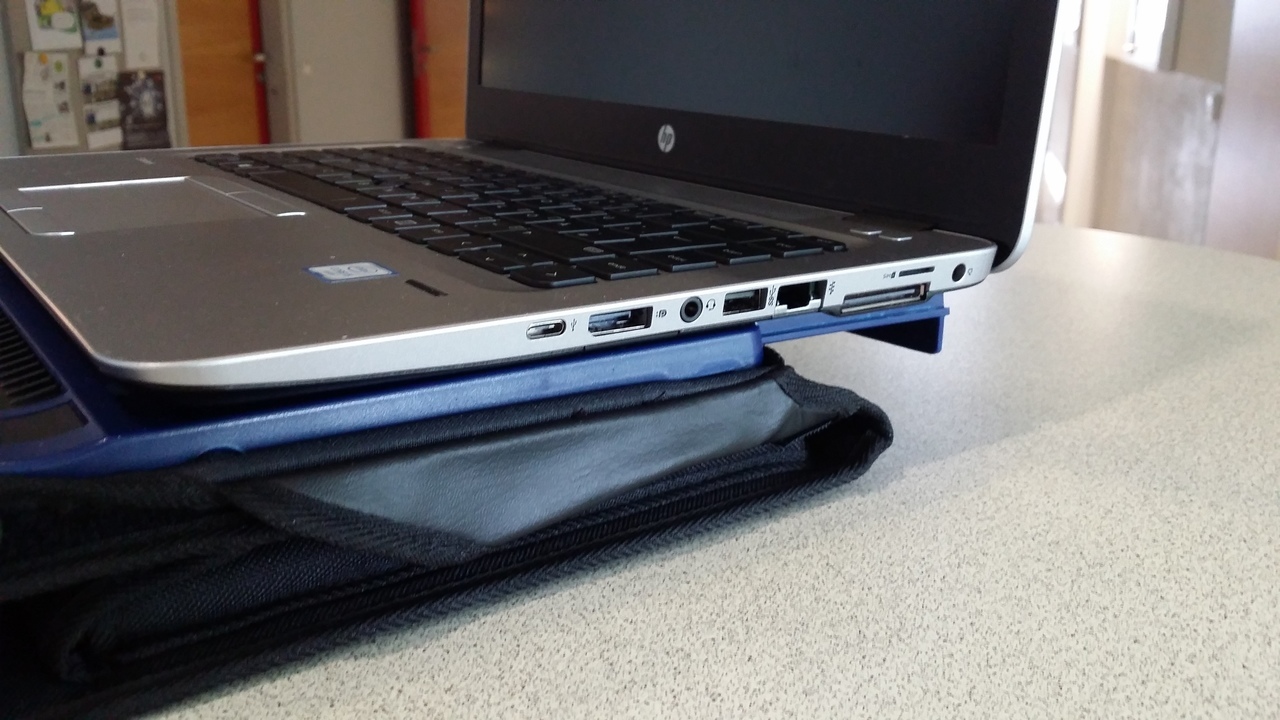
Some Background on Braille Display Form Factors Braille displays come in various sizes. There are models tailored for desktop use (with 60 cells or more), models tailored for portable use with a laptop (usually with 40 cells), and, nowadays, there are even models tailored for on-the-go use with a smartphone or similar (with something like 14 or 18 cells). Back in the old days, braille displays were rather massive. A 40-cell braille display was typically about the size of a 13" laptop. In modern times, manufacturers have managed to reduce the size of the internals such that a 40-cell display can be placed in front of a laptop or keyboard instead of placing the laptop on top of the braille display. While this is a nice achievement, I personally haven't found it to be very convenient because you now have to place two physically separate devices on your lap. It's OK if you have a real desk, but, at least in my opinion, if you try to use your laptop as its name suggests, it's actually inconvenient to use a small form factor, 40-cell display. For this reason, I've been waiting for a long-promised new model in the Handy Tech Star series. In 2002, they released the Handy Tech Braille Star 40, which is a 40-cell braille display with enough space to put a laptop directly on top of it. To accommodate larger laptop models, they even built in a little platform at the back that can be pulled out to effectively enlarge the top surface. Handy Tech has now released a new model, the Active Star 40, that has essentially the same layout but modernized internals. [picture: a plain Active Star 40] You can still pull out the little platform to increase the space that can be used to put something on top. [picture: an Active Star 40 with extended platform and a laptop on top] But, most conveniently, they've designed in an empty compartment, roughly the size of a modern smartphone, beneath the platform. The original idea was to actually put a smartphone inside, but this has turned out (at least to me) to not be very feasible. Fortunately, they thought about the need for electricity and added a Micro USB cable terminating within the newly created, empty compartment. My first idea was to put a conventional Raspberry Pi inside. When I received the braille display, however, we immediately noticed that a standard-sized rpi is roughly 3mm too high to fit into the empty compartment. Fortunately, though, a co-worker noticed that the Raspberry Pi Zero was available for order. The Raspberry Pi Zero is a lot thinner, and fits perfectly inside (actually, I think there's enough space for two, or even three, of them). So we ordered one, along with some accessories like a 64GB SDHC card, a Bluetooth dongle, and a Micro USB adapter cable. The hardware arrived a few days later, and was immediately bootstrapped with the assistance of very helpful friends. It works like a charm!
Technical Details The backside of the Handy Tech Active Star 40 features two USB host ports that can be used to connect devices such as a keyboard. A small form-factor, USB keyboard with a magnetic clip-on is included. When a USB keyboard is connected, and when the display is used via Bluetooth, the braille display firmware additionally offers the Bluetooth HID profile, and key press/release events received via the USB port are passed through to it. I use the Bluetooth dongle for all my communication needs. Most importantly, BRLTTY is used as a console screen reader. It talks to the braille display via Bluetooth (more precisely, via an RFCOMM channel). The keyboard connects through to Linux via the Bluetooth HID profile. Now, all that is left is network connectivity. To keep the energy consumption as low as possible, I decided to go for Bluetooth PAN. It appears that the tethering mode of my mobile phone works (albeit with a quirk), so I can actually access the internet as long as I have cell phone reception. Additionally, I configured a Bluetooth PAN access point on my desktop machines at home and at work, so I can easily (and somewhat more reliably) get IP connectivity for the rpi when I'm near one of these machines. I plan to configure a classic Raspberry Pi as a mobile Bluetooth access point. It would essentially function as a Bluetooth to ethernet adapter, and should allow me to have network connectivity in places where I don't want to use my phone.
BlueZ 5 and PAN It was a bit challenging to figure out how to actually configure Bluetooth PAN with BlueZ 5. I found the bt-pan python script (see below) to be the only way so far to configure PAN without a GUI. It handles both ends of a PAN network, configuring a server and a client. Once instructed to do so (via D-Bus) in client mode, BlueZ will create a new network device - bnep0 - once a connection to a server has been established. Typically, DHCP is used to assign IP addresses for these interfaces. In server mode, BlueZ needs to know the name of a bridge device to which it can add a slave device for each incoming client connection. Configuring an address for the bridge device, as well as running a DHCP server + IP Masquerading on the bridge, is usually all you need to do.
A Bluetooth PAN Access Point with Systemd I'm using systemd-networkd to configure the bridge device. /etc/systemd/network/pan.netdev:
[NetDev]
Name=pan
Kind=bridge
ForwardDelaySec=0
/etc/systemd/network/pan.network:
[Match]
Name=pan
[Network]
Address=0.0.0.0/24
DHCPServer=yes
IPMasquerade=yes
Now, BlueZ needs to be told to configure a NAP profile. To my surprise, there seems to be no way to do this with stock BlueZ 5.36 utilities. Please correct me if I'm wrong. Luckily, I found a very nice blog post, as well as an accommodating Python script that performs the required D-Bus calls. For convenience, I use a Systemd service to invoke the script and to ensure that its dependencies are met. /etc/systemd/system/pan.service:
[Unit]
Description=Bluetooth Personal Area Network
After=bluetooth.service systemd-networkd.service
Requires=systemd-networkd.service
PartOf=bluetooth.service
[Service]
Type=notify
ExecStart=/usr/local/sbin/pan
[Install]
WantedBy=bluetooth.target
/usr/local/sbin/pan:
#!/bin/sh
# Ugly hack to work around #787480
iptables -F
iptables -t nat -F
iptables -t mangle -F
iptables -t nat -A POSTROUTING -o eth0 -j MASQUERADE
exec /usr/local/sbin/bt-pan --systemd --debug server pan
This last file wouldn't be necessary if IPMasquerade= were supported in Debian right now (see #787480). After the obligatory systemctl daemon-reload and systemctl restart systemd-networkd, you can start your Bluetooth Personal Area Network with systemctl start pan.
Bluetooth PAN Client with Systemd Configuring the client is also quite easy to do with Systemd. /etc/systemd/network/pan-client.network:
[Match]
Name=bnep*
[Network]
DHCP=yes
/etc/systemd/system/pan@.service:
[Unit]
Description=Bluetooth Personal Area Network client
[Service]
Type=notify
ExecStart=/usr/local/sbin/bt-pan --debug --systemd client %I --wait
Now, after the usual configuration reloading, you should be able to connect to a specific Bluetooth access point with:
systemctl start pan@00:11:22:33:44:55
Pairing via the Command Line Of course, the server and client-side service configuration require a pre-existing pairing between the server and each of its clients. On the server, start bluetoothctl and issue the following commands:
power on
agent on
default-agent
scan on
scan off
pair XX:XX:XX:XX:XX:XX
trust XX:XX:XX:XX:XX:XX
Once you've set scan mode to on, wait a few seconds until you see the device you're looking for scroll by. Note its device address, and use it for the pair and (optional) trust commands. On the client, the sequence is essentially the same except that you don't need to issue the trust command. The server needs to trust a client in order to accept NAP profile connections from it without waiting for manual confirmation by the user. I'm actually not sure if this is the optimal sequence of commands. It might be enough to just pair the client with the server and issue the trust command on the server, but I haven't tried this yet.
Enabling Use of the Bluetooth HID Profile Essentially the same as above also needs to be done in order to use the Bluetooth HID profile of the Active Star 40 on Linux. However, instead of agent on, you need to issue the command agent KeyboardOnly. This explicitly tells bluetoothctl that you're specifically looking for a HID profile.
Configuring Bluetooth via the Command Line Feels Vague While I'm very happy that I actually managed to set all of this up, I must admit that the command-line interface to BlueZ feels a bit incomplete and confusing. I initially thought that agents were only for PIN code entry. Now that I've discovered that "agent KeyboardOnly" is used to enable the HID profile, I'm not sure anymore. I'm surprised that I needed to grab a script from a random git repository in order to be able to set up PAN. I remember, with earlier version of BlueZ, that there was a tool called pand that you could use to do all of this from the command-line. I don't seem to see anything like that for BlueZ 5 anymore. Maybe I'm missing something obvious?
Performance The data rate is roughly 120kB/s, which I consider acceptable for such a low power solution. The 1GHz ARM CPU actually feels sufficiently fast for a console/text-mode person like me. I'll rarely be using much more than ssh and emacs on it anyway.
Console fonts and screen dimensions The default dimensions of the framebuffer on the Raspberry Pi Zero are a bit unexpectedly strange. fbset reports that the screen dimension is 656x416 pixels (of course, no monitor connected). With a typical console font of 8x16, I got 82 columns and 26 lines. With a 40 cell braille display, the 82 columns are very inconvenient. Additionally, as a braille user, I would like to be able to view Unicode braille characters in addition to the normal charset on the console. Fortunately, Linux supports 512 glyphs, while most console fonts do only provide 256. console-setup can load and combine two 256-glyph fonts at once. So I added the following to /etc/default/console-setup to make the text console a lot more friendly to braille users:
SCREEN_WIDTH=80
SCREEN_HEIGHT=25
FONT="Lat15-Terminus16.psf.gz brl-16x8.psf"

Note

You need console-braille installed for brl-16x8.psf to be available.

Further Projects There's a 3.5mm audio jack inside the braille display as well. Unfortunately, there are no converters from Mini-HDMI to 3.5mm audio that I know of. It would be very nice to be able to use the sound card that is already built into the Raspberry Pi Zero, but, unfortunately, this doesn't seem possible at the moment. Alternatively, I'm looking at using a Micro USB OTG hub and an additional USB audio adapter to get sound from the Raspberry Pi Zero to the braille display's speakers. Unfortunately, the two USB audio adapters I've tried so far have run hot for some unknown reason. So I have to find some other chipset to see if the problem goes away. A little nuisance, currently, is that you need to manually power off the Raspberry, wait a few seconds, and then power down the braille display. Turning the braille display off cuts power delivery via the internal USB port. If this is accidentally done too soon then the Raspberry Pi Zero is shut down ungracefully (which is probably not the best way to do it). We're looking into connecting a small, buffering battery to the GPIO pins of the rpi, and into notifying the rpi when external power has dropped. A graceful, software-initiated shutdown can then be performed. You can think of it as being like a mini UPS for Micro USB.
The image If you are a happy owner of a Handy Tech Active Star 40 and would like to do something similar, I am happy to share my current (Raspbian Stretch based) image. In fact, if there is enough interest by other blind users, we might even consider putting a kit together that makes it as easy as possible for you to get started. Let me know if this could be of interest to you.
Thanks Thanks to Dave Mielke for reviewing the text of this posting. Thanks to Simon Kainz for making the photos for this article. And I owe a big thank you to my co-workers at Graz University of Technology who have helped me a lot to bootstrap really quickly into the rpi world.
P.S. My first tweet about this topic is just five days ago, and apart from the soundcard not working yet, I feel like the project is already almost complete! By the way, I am editing the final version of this blog posting from my newly created monitorless ARM-based Linux laptop via an ssh connection to my home machine.

11 June 2016

Shirish Agarwal: The road to debconf 2016, tourism and arts.

A longish blog post, please bear, a second part of the blog post would be published in few days from now. My fixed visa finally arrived, yeah:) But this story doesn t start here, it starts about a year back. While I have been contributing to Debian in my free time over the years, and sometimes paid time as well, I had never thought of going overseas as the experiences I knew from friends and relatives, it isn t easy to get all the permissions and paperwork done to say the least (bureaucracy @ work). But last year, when Debconf 15 was being launched, there are/were 2-3 friends of mine who are studying, doing their Ph.D. in some computer/web stuff, living in Germany currently that they goaded me to apply. The first few times I gave some standard excuses, but when they kept on for a while, just to shut them up I applied to the debconf team applying for food, accommodation and travel sponsorship. I didn t have high hopes as there obviously are many more talented peers around me who understand FOSS and Debian at a much more fundamental, philosophical as well as technical level than me. Much to my surprise though, about a month (and around two or three weeks just before the event was about to take place) I got the bursary/sponsorships for food, accommodation as well as travel. I was unsure that the remaining time was enough to get a visa hence declined that time around. That whole episode gave me the confidence that perhaps my application would be accepted if I applied again. Using my previous years understanding, decided to give it a shot again as this would also enable me to get a feel of visa bureaucracy as well as gain a bit of novice understanding about what factors go in choosing a flight and believe me the latter part proved to be pretty confusing. While the visa business seems easy, the form at least is easy and what they ask, it can be troublesome as far as visa-processing process is concerned. It took a better part of the month to get the visa which I needed. The in-between time is and can be a bit stressful as you have committed funds for travel i.e. the airline tickets and are in a limbo as you didn t know that if the visa is cancelled for some reason, your tickets would be refunded or not. A little history is needed and hopefully is helpful for anybody who s applying for a short-stay Visa in South Africa. Exactly, A month and day back I had applied for visa. The visa I had applied for is 17 days as the flights within my budget was for those days only. The visa I got was for 10 days only which was ending in the middle of the conference. I tried many avenues to get information and was told that I needed to write a correction letter telling/sharing the information about the correct time period and dates in BOLD with a heavier weight/point which is what I did and gave to VFS office without any further payment on my part. It took a bit more time than the first time around but the consulate co-operated. While I can understand the oversight as they probably get more visas requests along with special and urgent requests so such occurrences can happen. I am and was happy that there was a recourse rather than starting from scratch which probably would have made me more anxious due to the first experience . Apparently I was lucky that I had done with Qatar Airways as later came to know that there are other airways which don t refund money even after visa rejection . This information I got to know pretty late in the game otherwise I wouldn t have been much stressed. As had committed knew had to go the whole hog and whatever barriers are there, have overcome at least as far as the visa part/process is concerned. Now after few days, will probably start to worry about the actual travel, part nervousness, part excitement, nervousness as it will be an alien land, am obese so traveling economy on 787-8 and 777-300 ER will be tricky. The 787-8 will probably be a rough ride as it s a 9 hr. journey and the seat are a mere 18 , the cattle class as shared by one of our esteemed politicians. This blame has to do with Boeing 787 rather than anybody else. Hopefully, if there is a next time, would make better choices. Anyways,have selected an aisle seat so that will be able to walk every hr. or so to get the circulation in legs going as leg room in economy is not much from my domestic air travel experiences. If I do survive the travel, then will see South Africa and try to get some free time and explore South Africa and try to figure out how are they able to get one and half time tourists while we get around half figure for a whole year even though we are bigger (area-wise) to South Africa. I did find something positive for us as well, it s not all doldrums all around. Now, I had been thinking about if I know any South African music and movies. I had explored djembe while growing up in teens but other than that, not much. The only music I have heard is Harry Belafonte . So I hope to bring some Indian movies and music with me so that people if they have not explored Bollywood as well as Indian classical music could explore some of it, of course it will be pale imitation of what Sawai Gandharva Music Festival for instance gives. I also hope to hear and get some music and movies to learn more about South Africa.
Filed under: Miscellenous Tagged: #bollywood, #Debconf Germany 2015, #Debconf South Africa 2016, #Debconf15, #Debconf16, #djembe, #South-African consulate, music, tourism, visa

10 June 2016

Jaminy Prabaharan: Weekly Report for GSoC16-week 1 and week2

After introducing ourselves to the community, we start contributing to the open and free source software. Since this is the first week, I have went through theories which would help me in coding. Before coding it is always safer to refer to theories so that we don t need to spare time in debugging. The following were my week 1-4 plans:

These two weeks I have completed my first two tasks in the list.I have committed and pushed my works in GitHub.https://github.com/Jaminy/GSoC

Successfully logged into the email account using IMAP and examined each folders.Examined inbox to extract To , From and CC of the last message received.Trying to extract all message details to put in CSV file.


9 June 2016

Patrick Schoenfeld: Ansible: Indenting in Templates

When using ansible to configure systems and services, templates can reach a significant complexity. Proper indenting can help to improve the readability of the templates, which is very important for further maintenance. Unfortunately the default settings for the jinja2 template engine in ansible do enable trim_blocks only, while a combination with lstrip_blocks would be better. But here comes the good news: It s possible to enable that setting on a per-template base. The secret is to add a special comment to the very first line of a template:
#jinja2: lstrip_blocks: True
This setting does the following: If enabled, leading spaces and tabs are stripped from the start of a line to a block . So a resulting template could look like this:
global
 % for setting in global_settings % 
     % if setting ... % 
    option   setting  
     % endif % 
 % endfor % 
Unfortunately (or fortunately, if you want to see it this way  this does not strip leading spaces and tabs where the indentation is followed by pure text, e.g. the whitespaces in line 4 are preserved. So as a matter of fact, if you care for the indentation in the resulting target file, you need to indent those lines according to the indentation wanted in the target file instead, like it is done in the example. In less simple cases, with more deep nesting, this may seem odd, but hey: it s the best compromise between a good, readable template and a consistently indented output file.

8 June 2016

Daniel Pocock: Working to pass GSoC

GSoC students have officially been coding since 23 May (about 2.5 weeks) and are almost half-way to the mid-summer evaluation (20 - 27 June). Students who haven't completed some meaningful work before that deadline don't receive payment and in such a large program, there is no possibility to give students extensions or let them try and catch up later. Every project and every student are different, some are still getting to know their environment while others have already done enough to pass the mid-summer evaluation. I'd like to share a few tips to help students ensure they don't inadvertently fail the mid-summer evaluation Kill electronic distractions As a developer of real-time communications projects, many people will find it ironic or hypocritical that this is at the top of my list. Switch off the mobile phone or put it in silent mode so it doesn't even vibrate. Research has suggested that physically turning it off and putting it out of sight has significant benefits. Disabling the voicemail service can be an effective way of making sure no time is lost listening to a bunch of messages later. Some people may grumble at first but if they respect you, they'll get into the habit of emailing you and waiting for you to respond when you are not working. Get out a piece of paper and make a list of all the desktop notifications on your computer, whether they are from incoming emails, social media, automatic updates, security alerts or whatever else. Then figure out how to disable them all one-by-one. Use email to schedule fixed times for meetings with mentors. Some teams/projects also have fixed daily or weekly times for IRC chat. For a development project like GSoC, it is not necessary or productive to be constantly on call for 3 straight months. Commit every day Habits are a powerful thing. Successful students have a habit of making at least one commit every day. The "C" in GSoC is for Code and commits are a good way to prove that coding is taking place. GSoC is not a job, it is like a freelance project. There is no safety-net for students who get sick or have an accident and mentors are not bosses, each student is expected to be their own boss. Although Google has started recommending students work full time, 40 hours per week, it is unlikely any mentors have any way to validate these hours. Mentors can look for a commit log, however, and simply won't be able to pass a student if there isn't code. There may be one day per week where a student writes a blog or investigates a particularly difficult bug and puts a detailed report in the bug tracker but by the time we reach the second or third week of GSoC, most students are making at least one commit in 3 days out of every 5. Consider working away from home/family/friends Can you work without anybody interrupting you for at least five or six hours every day? Do you feel pressure to help with housework, cooking, siblings or other relatives? Even if there is no pressure to do these things, do you find yourself wandering away from the computer to deal with them anyway? Do family, friends or housemates engage in social activities, games or other things in close proximity to where you work? All these things can make a difference between passing and failing. Maybe these things were tolerable during high school or university. GSoC, however, is a stepping stone into professional life and that means making a conscious decision to shut those things out and focus. Some students have the ability to manage these distractions well, but it is not for everybody. Think about how leading sports stars or musicians find a time and space to be "in the zone" when training or rehearsing, this is where great developers need to be too. Some students find the right space in a public library or campus computer lab. Some students have been working in hacker spaces or at empty desks in local IT companies. These environments can also provide great networking opportunities. Managing another summer job concurrently with GSoC It is no secret that some GSoC students have another job as well. Sometimes the mentor is aware of it, sometimes it has not been disclosed. The fact is, some students have passed GSoC while doing a summer job or internship concurrently but some have also failed badly in both GSoC and their summer job. Choosing one or the other is the best way to succeed, get the best results and maximize the quality of learning and community interaction. For students in this situation, now it is not too late to make the decision to withdraw from GSoC or the other job. If doing a summer job concurrently with GSoC is unavoidable, the chance of success can be greatly increased by doing the GSoC work in the mornings, before starting the other job. Some students have found that they actually finish more quickly and produce better work when GSoC is constrained to a period of 4 or 5 hours each morning and their other job is only in the afternoon. On the other hand, if a student doesn't have the motivation or energy to get up and work on GSoC before the other job then this is a strong sign that it is better to withdraw from GSoC now.

Gunnar Wolf: University degrees and sysadmin skills

I'll tune in to the post-based conversation being held on Planet Debian: Russell Coker wonders about what's needed to get university graduates with enough skills for a sysadmin job, to which Lucas Nussbaum responds with his viewpoints. They present a very contrasting view of what's needed for students And for a good reason, I'd say: Lucas is an academician; I don't know for sure about Russell, but he seems to be a down-to-the-earth, dirty-handed, proficient sysadmin working on the field. They both contact newcomers to their fields, and will notice different shortcomings. I tend to side with Lucas' view. That does not come as a surprise, as I've been working for over 15 years in an university, and in the last few years I started walking from a mostly-operative sysadmin in an academic setting towards becoming an academician that spends most of his time sysadmining. Subtle but important distinction. I teach at the BSc level at UNAM, and am a Masters student at IPN (respectively, Mexico's largest and second-largest universities). And yes, the lack of sysadmin abilities in both is surprising. But so is a good understanding of programming. And I'm sure that, were I to dig into several different fields, I'd feel the same: Student formation is very basic at each of those fields. But I see that as natural. Of course, if I were to judge people as geneticists as they graduate from Biology, or were I to judge them as topologists as they graduate from Mathematics, or any other discipline in which I'm not an expert, I'd surely not know where to start Given I have about 20 years of professional life on my shoulders, I'm quite skewed as to what is basic for a computing professional. And of course, there are severe holes in my formation, in areas I never used. I know next to nothing of electronics, my mathematical basis is quite flaky, and I'm a poor excuse when talking about artificial intelligence. Where am I going with this? An university degree (BSc in English, would amount to "licenciatura" in Spanish) is not for specialization. It is to have a sufficiently broad panorama of the field, and all of the needed tools to start digging deeper and specializing either by yourself, working on a given field and learning its details as you go, or going through a postgraduate program (Specialization, Masters, Doctorate). Even most of my colleagues at the Masters in Engineering in Security and Information Technology lack of a good formation in fields I consider essential. However, what does information security mean? Many among them are working on legal implications of several laws that touch our field. Many other are working on authenticity issues in images, audios and other such media. Many other are trying to come up with mathematical ways to cheapen the enormous burden of crypto operations (say, "shaving" CPU cycles off a very large exponentiation). Others are designing autonomous learning mechanisms to characterize malware. Were I as a computing professional to start talking about their research, I'd surely reveal I know nothing about it and get laughed at. That's because I haven't specialized in those fields. University education should give a broad universal basis to enter a professional field. It should not focus on teaching tools or specific procedures (although some should surely be presented as examples or case studies). Although I'd surely be happy if my university's graduates were to know everything about administering a Debian system, that would be wrong for a university to aim at; I'd criticize it the same way I currently criticize programs that mix together university formation and industry certification as if they were related.

Tanguy Ortolo: Process command line arguments in shell

When writing a wrapper script, one often has to process the command line arguments to transform them according to his needs, to change some arguments, to remove or insert some, or perhaps to reorder them.Naive approach The naive approach to do that is :
# Process arguments, building a new argument list
new_args=""
for arg in "$@"
do
    case "$arg"
    in
        --foobar)
            # Convert --foobar to the new syntax --foo=bar
            new_args="$args --foo=bar"
        ;;
        *)
            # Take other options as they are
            new_args="$args $arg"
        ;;
    esac
done
# Call the actual program
exec program $new_args
This naive approach is simple, but fragile, as it will break on arguments that contain a space. For instance, calling wrapper --foobar "some file" (where some file is a single argument) will result in the call program --foo=bar some file (where some and file are two distinct arguments). Correct approach To handle spaces in arguments, we need either: except standard shell does support arrays, or rather, it does support one specific array: the positional parameter list "$@" . This leads to one solution to process arguments in a reliable way, which consists in rebuilding the positional parameter list with the built-in command set --:
# Process arguments, building a new argument list in "$@"
# "$@" will need to be cleared, not right now but on first iteration only
first_iter=1
for arg in "$@"
do
    if [ "$first_iter" -eq 1 ]
    then
        # Clear the argument list
        set --
        first_iter=0
    fi
    case "$arg"
    in
        --foobar) set -- "$@" --foo=bar ;;
        *) set -- "$@" "$arg" ;;
    esac
done
# Call the actual program
exec program "$@"
Notes
  1. I you prefer, for arg in "$@" can be simplified to just for arg.
  2. As a reminder, and contrary to what it looks like, quoted "$@" does not expand to a single field, but to one field per positional parameter.

6 June 2016

Reproducible builds folks: Reprotest has a preliminary CLI and configuration file handling

Author: ceridwen This is the first draft of reprotest's interface, and I welcome comments on how to improve it. At the moment, reprotest's CLI takes two mandatory arguments, the build command to run and the build artifact file to test after running the build. If the build command or build artifact have spaces, they have to be passed as strings, e.g. "debuild -b -uc -us". For optional arguments, it has --variations, which accepts a list of possible build variations to test, one or more of 'captures_environment', 'domain_host', 'filesystem', 'home', 'kernel', 'locales', 'path', 'shell', 'time', 'timezone', 'umask', and 'user_group' (see variations for more information); --dont_vary, which makes reprotest not test any variations in the given list (the default is to run all variations); --source_root, which accepts a directory to run the build command in and defaults to the current working directory; and --verbose, which will eventually enable more detailed logging. To get help for the CLI, run reprotest -h or reprotest --help. The config file has one section, basics, and the same options as the CLI, except there's no dont_vary option, and there are build_command and artifact options. If build_command and/or artifact are set in the config file, reprotest can be run without passing those as command-line arguments. Command-line arguments always override config file options. Reprotest currently searches the working directory for the config file, but it will also eventually search the user's home directory. A sample config file is below.
[basics]
build_command = setup.py sdist
artifact = dist/reprotest-0.1.tar.gz
source_root = reprotest/
variations =
  captures_environment
  domain_host
  filesystem
  home
  host
  kernel
  locales
  path
  shell
  time
  timezone
  umask
  user_group
At the moment, the only build variations that reprotest actually tests are the environment variable variations: captures_environment, home, locales, and timezone. Over the next week, I plan to add the rest of the basic variations and accompanying tests. I also need to write tests for the CLI and the configuration file. After that, I intend to work on getting (s)chroot communication working, which will involve integrating autopkgtest code. Some of the variations require specific other packages to be installed: for instance, the locales variation currently requires the fr_CH.UTF-8 locale. Locales are a particular problem because I don't know of a way in Debian to specify that a given locale must be installed. For other packages, it's unclear to me whether I should specify them as depends or recommends: they aren't dependencies in a strict sense, but marking them as dependencies will make it easier to install a fully-functional reprotest. When reprotest runs with variations enabled that it can't test because it doesn't have the correct packages installed, I intend to have it print a warning but continue to run. tests.reproducible-builds.org also has different settings, such as different locales, for different architectures. I'm not clear on why this is. I'd prefer to avoid having to generate a giant list of variations based on architecture, but if necessary, I can do that. The prebuilder script contains variations specific to Linux, to Debian, and to pbuilder/cowbuilder. I'm not including Debian-specific variations until I get much more of the basic functionality implemented, and I'm not sure I'm going to include pbuilder-specific variations ever, because it's probably better for extensibility to other OSes, e.g. BSD, to add support for plugins or more complicated configurations. I implemented the variations by creating a function for each variation. Each function takes as input two build commands, two source trees, and two sets of environment variables and returns the same. At the moment, I'm using dictionaries for the environment variables, mutating them in-place and passing the references forward. I'm probably going to replace those at some point with an immutable mapping. While at the moment, reprotest only builds on the existing system, when I start extending it to other build environments, this will require double-dispatch, because the code that needs to be executed will depend on both the variation to be tested and the environment being built on. At the moment, I'm probably going to implement this with a dictionary with tuple keys of (build_environment, variation) or nested dictionaries. If it's necessary for code to depend on OS or architecture, too, this could end up becoming a triple or quadruple dispatch.

John Goerzen: How git-annex replaces Dropbox + encfs with untrusted providers

git-annex has been around for a long time, but I just recently stumbled across some of the work Joey has been doing to it. This post isn t about it s traditional roots in git or all the features it has for partial copies of large data sets, but rather for its live syncing capabilities like Dropbox. It takes a bit to wrap your head around, because git-annex is just a little different from everything else. It s sort of like a different-colored smell. The git-annex wiki has a lot of great information both low-level reference and a high-level 10-minute screencast showing how easy it is to set up. I found I had to sort of piece together the architecture between those levels, so I m writing this all down hoping it will benefit others that are curious. Ir you just want to use it, you don t need to know all this. But I like to understand how my tools work. Overview git-annex lets you set up a live syncing solution that requires no central provider at all, or can be used with a completely untrusted central provider. Depending on your usage pattern, this central provider could require only a few MBs of space even for repositories containing gigabytes or terabytes of data that is kept in sync. Let s take a look at the high-level architecture of the tool. Then I ll illustrate how it works with some scenarios. Three Layers Fundamentally, git-annex takes layers that are all combined in Dropbox and separates them out. There is the storage layer, which stores the literal data bytes that you are interested in. git-annex indexes the data in storage by a hash. There is metadata, which is for things like a filename-to-hash mapping and revision history. And then there is an optional layer, which is live signaling used to drive the real-time syncing. git-annex has several modes of operation, and the one that enables live syncing is called the git-annex assistant. It runs as a daemon, and is available for Linux/POSIX platforms, Windows, Mac, and Android. I ll be covering it here. The storage layer The storage layer simply is blobs of data. These blobs are indexed by a hash, and can be optionally encrypted at rest at remote backends. git-annex has a large number of storage backends; some examples include rsync, a remote machine with git-annex on it that has ssh installed, WebDAV, S3, Amazon Glacier, removable USB drive, etc. There s a huge list. One of the git-annex features is that each client knows the state of each storage repository, as well as the capability set of each storage repository. So let s say you have a workstation at home and a laptop you take with you to work or the coffee shop. You d like changes on one to be instantly recognized on another. With something like Dropbox or OwnCloud, every file in the set you want synchronized has to reside on a server in the cloud. With git-annex, it can be configured such that the server in the cloud only contains a copy of a file until every client has synced it up, at which point it gets removed. Think about it that is often what you want anyhow, so why maintain an unnecessary copy after it s synced everywhere? (This behavior is, of course, configurable.) git-annex can also avoid storing in the cloud entirely if the machines are able to reach each other directly at least some of the time. The metadata layer Metadata about your files includes a mapping from the file names to the storage location (based on hashes), change history, and information about the status of each machine that participates in the syncing. On your clients, git-annex stores this using git. This detail is very useful to some, and irrelevant to others. Some of the git-annex storage backends can support only storage (S3, for instance). Some can support both storage and metadata (rsync, ssh, local drives, etc.) You can even configure a backend to support only metadata (more on why that may be useful in a bit). When you are working with a git-backed repository for git-annex, it can hold data, metadata, or both. So, to have a working sync system, you must have a way to transport both the data and the metadata. The transport for the metadata is generally rsync or git, but it can also be XMPP in which Git changesets are basically wrapped up in XMPP presence messages. Joey says, however, that there are some known issues with XMPP servers sometimes dropping or reordering some XMPP messages, so he doesn t encourage that method currently. The live signaling layer So once you have your data and metadata, you can already do syncs via git annex sync --contents. But the real killer feature here will be automatic detection of changes, both on the local and the remote. To do that, you need some way of live signaling. git-annex supports two methods. The first requires ssh access to a remote machine where git-annex is installed. In this mode of operation, when the git-annex assistant fires up, it opens up a persistent ssh connection to the remote and runs the git-annex-shell over there, which notifies it of changes to the git metadata repository. When a change is detected, a sync is initiated. This is considered ideal. A substitute can be XMPP, and git-annex actually converts git commits into a form that can be sent over XMPP. As I mentioned above, there are some known reliability issues with this and it is not the recommended option. Encryption When it comes to encryption, you generally are concerned about all three layers. In an ideal scenario, the encryption and decryption happens entirely on the client side, so no service provider ever has any details about your data. The live signaling layer is encrypted pretty trivially; the ssh sessions are, of course, encrypted and TLS support in XMPP is pervasive these days. However, this is not end-to-end encryption; those messages are decrypted by the service provider, so a service provider could theoretically spy on metadata, which may include change times and filenames, though not the contents of files themselves. The data layer also can be encrypted very trivially. In the case of the dumb backends like S3, git-annex can use symmetric encryption or a gpg keypair and all that ever shows up on the server are arbitrarily-named buckets. You can also use a gcrypt-based git repository. This can cover both data and metadata and, if the target also has git-annex installed, the live signalling layer. Using a gcrypt-based git repository for the metadata and live signalling is the only way to accomplish live syncing with 100% client-side encryption. All of these methods are implemented in terms of gpg, and can support symmetric of public-key encryption. It should be noted here that the current release versions of git-annex need a one-character patch in order to fix live syncing with a remote using gcrypt. For those of you running jessie, I recommend the version in jessie-backports, which is presently 5.20151208. For your convenience, I have compiled an amd64 binary that can drop in over /usr/bin/git-annex if you have this version. You can download it and a gpg signature for it. Note that you only need this binary on the clients; the server can use the version from jessie-backports without issue. Putting the pieces together: some scenarios Now that I ve explained the layers, let s look at how they fit together. Scenario 1: Central server In this scenario, you might have a workstation and a laptop that sync up with each other by way of a central server that also has a full copy of the data. This is the scenario that most closely resembles Dropbox, box, or OwnCloud. Here you would basically follow the steps in the git-assistant screencast: install git-annex on a server somewhere, and point your clients to it. If you want full end-to-end encryption, I would recommend letting git-annex generate a gpg keypair for you, which you would then need to copy to both your laptop and workstation (but not the server). Every change you make locally will be synced to the server, and then from the server to your other PC. All three systems would be configured in the client transfer group. Scenario 1a: Central server without a full copy of the data In this scenario, everything is configured the same except the central server is configured with the transfer transfer group. This means that the actual data synced to it is deleted after it has been propagated to all clients. Since git-annex can verify which repository has received a copy of which data, it can easily enough delete the actual file content from the central server after it has been copied to all the clients. Many people use something like Dropbox or OwnCloud as a multi-PC syncing solution anyhow, so once the files have been synced everywhere, it makes sense to remove them from the central server. This is often a good ideal for people. There are some obvious downsides that are sometimes relevant. For instance, to add a third sync client, it must be able to initially copy down from one of the existing clients. Or, if you intend to access the data from a device such as a cell phone where you don t intend for it to have a copy of all data all the time, you won t have as convenient way to download your data. Scenario 1b: Split data/metadata central servers Imagine that you have a shell or rsync account on some remote system where you can run git-annex, but don t have much storage space. Maybe you have a cheap VPS or shell account somewhere, but it s just not big enough to hold your data. The answer to this would be to use this shell or rsync account for the metadata, but put the data elsewhere. You could, for instance, store the data in Amazon S3 or Amazon Glacier. These backends aren t capable of storing the git-annex metadata, so all you need is a shell or rsync account somewhere to sync up the metadata. (Or, as below, you might even combine a fully distributed approach with this.) Then you can have your encrypted data pushed up to S3 or some such service, which presumably will grow to whatever size you need. Scenario 2: Fully distributed Like git itself, git-annex does not actually need a central server at all. If your different clients can reach each other directly at least some of the time, that is good enough. Of course, a given client will not be able to do fully automatic live sync unless it can reach at least one other client, so changes may not propagate as quickly. You can simply set this up by making ssh connections available between your clients. git-annex assistant can automatically generate appropriate ~/.ssh/authorized_keys entries for you. Scenario 2a: Fully distributed with multiple disconnected branches You can even have a graph of connections available. For instance, you might have a couple machines at home and a couple machines at work with no ability to have a direct connection between them (due to, say, firewalls). The two machines at home could sync with each other in real-time, as could the two machines at work. git-annex also supports things like USB drives as a transport mechanism, so you could throw a USB drive in your pocket each morning, pop it in to one client at work, and poof both clients are synced up over there. Repeat when you get home in the evening, and you re synced there. The USB drive s repository can, of course, be of the transport type so data is automatically deleted from it once it s been synced everywhere. Scenario 3: Hybrid git-annex can support LAN sync even if you have a central server. If your laptop, say, travels around but is sometimes on the same LAN as your PC, git-annex can easily sync directly between the two when they are reachable, saving a round-trip to the server. You can assign a cost to each remote, and git-annex will always try to sync first to the lowest-cost path that is available. Drawbacks of git-annex There are some scenarios where git-annex with the assistant won t be as useful as one of the more traditional instant-sync systems. The first and most obvious one is if you want to access the files without the git-annex client. For instance, many of the other tools let you generate a URL that you can email to people, and then they can download files without any special client software. This is not directly possible with git-annex. You could, of course, make something like a public_html directory be managed with git-annex, but it wouldn t provide things like obfuscated URLs, password-protected sharing, time-limited sharing, etc. that you get with other systems. While you can share your repositories with others that have git-annex, you can t share individual subdirectories; for a given repository, it is all or nothing. The Android client for git-annex is a pretty interesting thing: it is mostly a small POSIX environment, providing a terminal, git, gpg, and the same web interface that you get on a standalone machine. This means that the git-annex Android client is fully functional compared to a desktop one. It also has a quick setup process for syncing off your photos/videos. On the other hand, the integration with the Android ecosystem is poor compared to most other tools. Other git-annex features git-annex has a lot to offer besides the git-annex assistant. Besides the things I ve already mentioned, any given git-annex repository including your client repository can have a partial copy of the full content. Say, for instance, that you set up a git-annex repository for your music collection, which is quite large. You want some music on your netbook, but don t have room for it all. You can tell git-annex to get or drop files from the netbook s repository without deleting them remotely. git-annex has quite a few ways to automate and configure this, including making sure that at least a certain number of copies of a file exist in your git-annex ecosystem. Conclusion I initially started looking at git-annex due to the security issues with encfs, and the difficulty with setting up ecryptfs in this way. (I had been layering encfs atop OwnCloud). git-annex certainly ticks the box for me security-wise, and obviously anything encrypted with encfs wasn t going to be shared with others anyhow. I ll be using git-annex more in the future, I m sure.

Scarlett Clark: Debian: Reproducible builds Week 2

This was a holiday week for me, so my time was rather crammed into a short space.
I still managed to make progress though. kapptemplate:
https://bugs.kde.org/show_bug.cgi?id=363448
I was given the green light to push this upstream. So this will eventually trickle down and all will benefit, not just debian.
I will leave bug open though as it will need to be applied to all the releases I expect.
https://bugs.debian.org/cgi-bin/bugreport.cgi?bug=825122 choqok:
https://bugs.debian.org/cgi-bin/bugreport.cgi?bug=825322
For this I was able to come up with a patch for kconfig_compiler to encode generated files to utf-8.
Review request is here:
https://git.reviewboard.kde.org/r/128102/ kxmlgui:
WIP this has been a steep learning curve, according to the notes it was an easy embedded kernel version, that was not the case! After grueling hours of
trying to sort out randomness in debug output I finally narrowed it down to cases where QStringLiteral was used and there were non letter characters eg. ( <") These were causing debug symbols to generate with ( lambda() ) which caused unreproducible symbol/debug files. It is now a case of fixing all of these in the code to use QString::fromUtf8 seems to fix this. I am working on a mega patch for upstream and it should be ready early in the week. Other items were minor and not notable enough to blog about  Have a great day.

4 June 2016

Jaminy Prabaharan: Weekly Report for GSoC16-Community bonding period

April 23rd to May 23rd The period of introducing ourselves to the Debian community. I have updated my debian wiki page to introduce more about myself to the Debian community. https://wiki.debian.org/SummerOfCode2016/StudentApplications/Jaminy There was a webRTC session of MiniDebconf through Jitsi on 3oth April to know more about the Debian resources. During this period I have updated my PC with the Debian latest version, Jessie and got practised with the new platform.I have also learnt some basic theories on my project such as VoIP and IMAP. I was assigned by my mentor Daniel Pocock to work on telepathy reSIProcate.

System used
  • Debian GNU/Linux 8.3 (jessie)
  • Ubuntu 14.04.4 LTS (trusty)

Telepathy-Qt

First you have to configure the telepathy-qt library properly to be able to install reSIProcate. It s important to notice that you shouldn t install telepathy-qt from apt-get because in this way it wont have the telepathy-qt4-service shared library.

$ mkdir ~/telepathy-qt-stuff
$ cd ~/telepathy-qt-stuff
$ git clone https://github.com/dpocock/telepathy-qt-debian
$ cd telepathy-qt-debian
$ git checkout jessie-build-all-shared
$ cd ..

Then you should download the tar http://http.debian.net/debian/pool/main/t/telepathy-qt/telepathy-qt_0.9.6.1.orig.tar.gz in the telepathy-qt-stuff folder and continue:

$ tar xzf telepathy-qt_0.9.6.1.orig.tar.gz
$ cd telepathy-qt_0.9.6.1
$ [ -d debian ] && echo "warning: debian/ already exists!"
$ cp -r ../telepathy-qt-debian/debian .
$ dpkg-buildpackage -rfakeroot -i.* -j13 -us -uc
$ cd ..
$ ls *.deb

Now you should see a list of libtelepathy-qt* and telepathy-qt* .deb packages. You just have to install a few more packages:

$ dpkg -i libtelepathy-qt4-2_0.9.6.1-2_amd64.deb libtelepathy-qt4-dev_0.9.6.1-2_amd64.deb libtelepathy-qt4-farstream2_0.9.6.1-2_amd64.deb

After that you have the necessary packages to install reSIProcate.

$ dpkg -l   grep telepathy-qt

Should return you something like this:

ii

libtelepathy-qt4-2:amd64

0.9.6.1-2

amd64

Telepathy framework Qt 4 library

ii

libtelepathy-qt4-dev

0.9.6.1-2

amd64

Qt 4 Telepathy library (headers and static library)

ii

libtelepathy-qt4-farstream2:amd64

0.9.6.1-2

amd64

Telepathy/Farsight integration Qt 4 library

reSIProcate

After installing telepathy-qt properly you would be able to configure reSIProcate.

Make sure you have added backports to your /etc/apt/sources.list file

$ git clone https://github.com/resiprocate/resiprocate
$ cd resiprocate
$ apt-get install libpq-dev dh-autoreconf
$ apt-get build-dep resiprocate
$ apt-get install -t jessie-backports libradcli-dev
$ ./build/debian.sh
$ make

And then you are done!

3 June 2016

Gunnar Wolf: Stop it with those short PGP key IDs!

Debian is quite probably the project that most uses a OpenPGP implementation (that is, GnuPG, or gpg) for many of its internal operations, and that places most trust in it. PGP is also very widely used, of course, in many other projects and between individuals. It is regarded as a secure way to do all sorts of crypto (mainly, encrypting/decrypting private stuff, signing public stuff, certifying other people's identities). PGP's lineage traces back to Phil Zimmerman's program, first published in 1991 By far, not a newcomer PGP is secure, as it was 25 years ago. However, some uses of it might not be so. We went through several migrations related to algorithmic weaknesses (i.e. v3 keys using MD5; SHA1 is strongly discouraged, although not yet completely broken, and it should be avoided as well) or to computational complexity (as the migration away from keys smaller than 2048 bits, strongly prefering 4096 bits). But some vulnerabilities are human usage (that is, configuration-) related. Today, Enrico Zini gave us a heads-up in the #debian-keyring IRC channel, and started a thread in the debian-private mailing list; I understand the mail to a private list was partly meant to get our collective attention, and to allow for potentially security-relevant information to be shared. I won't go into details about what is, is not, should be or should not be private, but I'll post here only what's public information already. What are short and long key IDs? I'll start by quoting Enrico's mail:
there are currently at least 3 ways to refer to a gpg key: short key ID (last 8 hex digits of fingerprint), long key ID (last 16 hex digits) and full fingerprint. The short key ID used to be popular, and since 5 years it is known that it is computationally easy to generate a gnupg key with an arbitrary short key id. A mitigation to this is using "keyid-format long" in gpg.conf, and a better thing to do, especially in scripts, is to use the full fingerprint to refer to a key, or just ship the public key for verification and skip the key servers. Note that in case of keyid collision, gpg will download and import all the matching keys, and will use all the matching keys for verifying signatures.
So... What is this about? We humans are quite bad at recognizing and remembering randomly-generated strings with no inherent patterns in them. Every GPG key can be uniquely identified by its fingerprint, a 128-bit string, usually encoded as ten blocks of four hexadecimal characters (this allows for 160 bits; I guess there's space for a checksum in it). That is, my (full) key's signature is:
AB41 C1C6 8AFD 668C A045  EBF8 673A 03E4 C1DB 921F
However, it's quite hard to recognize such a long string, let alone memorize it! So, we often do what humans do: Given that strong cryptography implies a homogenous probability distribution, people compromised on using just a portion of the key the last portion. The short key ID. Mine is then the last two blocks (shown in boldface): C1DB921F. We can also use what's known as the long key ID, that's twice as long: 64 bits. However, while I can speak my short key ID on a single breath (and maybe even expect you to remember and note it down), try doing so with the long one (shown in italics above): 673A03E4C1DB921F. Nah. Too much for our little, analog brains. This short and almost-rememberable number has then 32 bits of entropy I have less than one in 4,000,000,000 chance of generating a new key with this same short key ID. Besides, key generation is a CPU-intensive operation, so it's quite unlikely we will have a collision, right? Well, wrong. Previous successful attacks on short key IDs Already five years ago, Asheesh Laroia migrated his 1024D key to a 4096R. And, as he describes in his always-entertaining fashion, he made his computer sweat until he was able to create a new key for which the short key ID collided with the old one. It might not seem like a big deal, as he did this non-maliciously, but this easily should have spelt game over for the usage of short key IDs. After all, being able to generate a collision is usually the end for cryptographic systems. Asheesh specifically mentioned in his posting how this could be abused. But we didn't listen. Short key IDs are just too convenient! Besides, they allow us to have fun, can be a means of expression! I know of at least two keys that would qualify as vanity: Obey Arthur Liu's 0x29C0FFEE (created in 2009) and Keith Packard's 0x00000011 (created in 2012). Then we got the Evil 32 project. They developed Scallion, started (AFAICT) in 2012. Scallion automates the search for a 32-bit collision using GPUs; they claim that it takes only four seconds to find a collision. So, they went through the strong set of the public PGP Web of Trust, and created a (32-bit-)colliding key for each of the existing keys. And what happened now? What happened today? We still don't really know, but it seems we found a first potentially malicious collision that is, the first "nonacademic" case. Enrico found two keys sharing the 9F6C6333 short ID, apparently belonging to the same person (as would be the case of Asheesh, mentioned above). After contacting Gustavo, though, he does not know about the second That is, it can be clearly regarded as an impersonation attempt. Besides, what gave away this attempt are the signatures it has: Both keys are signed by what appears to be the same three keys: B29B232A, F2C850CA and 789038F2. Those three keys are not (yet?) uploaded to the keyservers, though... But we can expect them to appear at any point in the future. We don't know who is behind this, or what his purpose is. We just know this looks very evil. Now, don't panic: Gustavo's key is safe. Same for his certifiers, Marga, Agust n and Maxy. It's just a 32-bit collision. So, in principle, the only parties that could be cheated to trust the attacker are humans, right? Nope. Enrico tested on the PGP pathfinder & key statistics service, a keyserver that finds trust paths between any two arbitrary keys in the strong set. Surprise: The pathfinder works on the short key IDs, even when supplied full fingerprints. So, it turns out I have three faked trust paths into our impostor. What next? There are several things this should urge us to do. And there are surely many other important recommendations. But this is a good set of points to start with. [update] I was pointed at Daniel Kahn Gillmor's 2013 blog post, OpenPGP Key IDs are not useful. Daniel argues, in short, that cutting a fingerprint in order to get a (32- or 64-bit) short key ID is the worst of all worlds, and we should rather target either always showing full fingerprints, or not showing it at all (and leaving all the crypto-checking bits to be done by the software, as comparing 160-bit strings is not natural for us humans). [update] This post was picked up by LWN.net. A very interesting discussion continues in their comments.

Simon D saulniers: Google Summer Of Code

I am part of the group of students working with the Debian organization. You can see my profile on the Debian wiki here.

Improving distributed and secure communication using free software This the title of my project for this summer. It sounds good, but what am I going to really do? Well, since I m a student at Universit du Qu bec Montr al, I have had the opportunity to meet with the company Savoir-Faire Linux in Montreal last year and that s when I found out about their exciting project: Ring.
Ring is one of the few projects which bring communication confidentiality and freedom in the hands of the users.

OpenDHT Ring is divided in multiple components as explained here: https://ring.cx/en/about/technical. The component I work on is called OpenDHT. This is the distributed hash table which enables Ring users to communicate in a decentralized network. I have already been working on this project for a year now, so you won t see me posting reports where I say I have to find my way around in this project. In fact, I have contributed to rewriting a major part of the code for better maintainability. In the begining of last summer, I was able to be part of a research association between Savoir-Faire Linux and Universit du Qu bec Montr al. We have been working on adding two major features to OpenDHT.

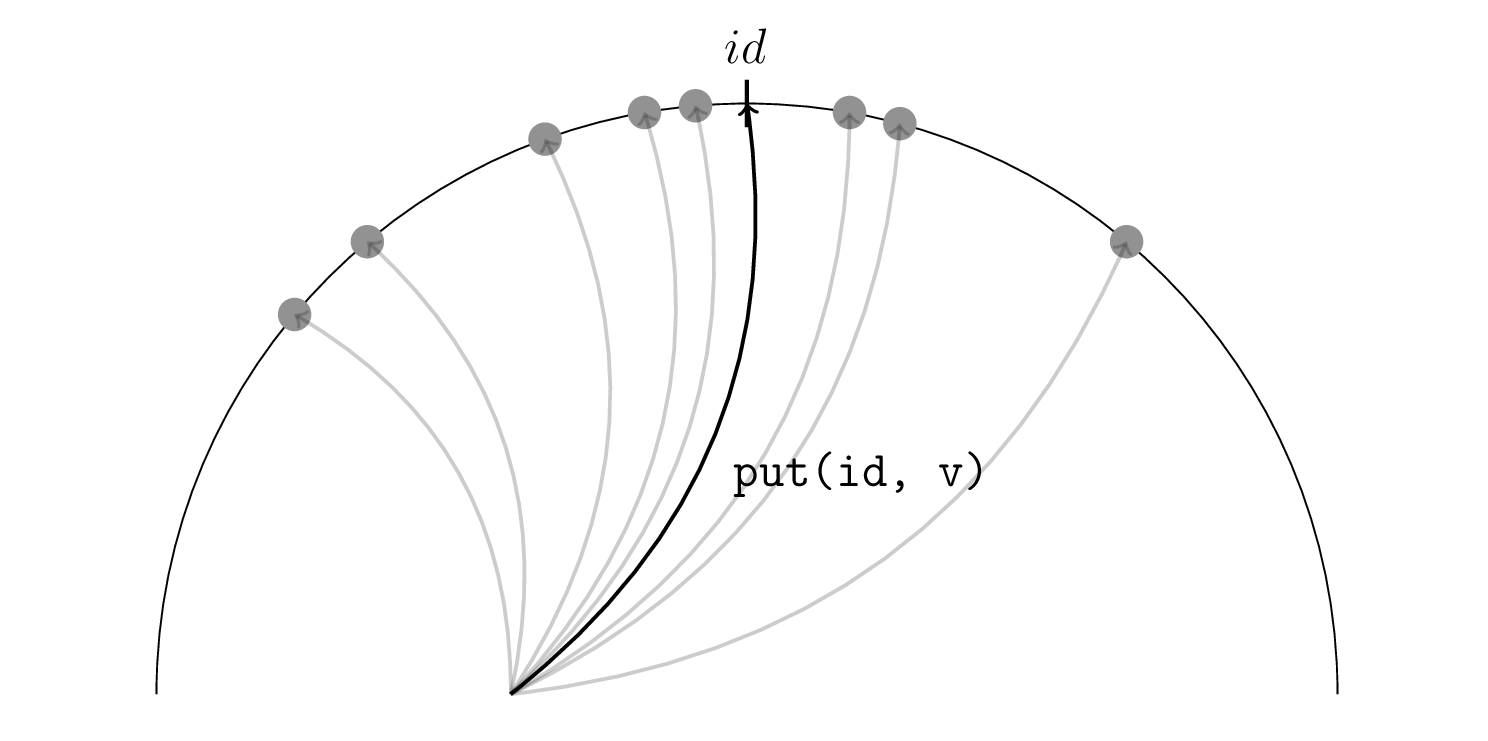
Short introduction to Distributed Hash Tables OpenDHT is based on the Kademlia design. If you know about DHTs, you are aware that they define the notion of distance using the XOR metric. This makes the tuple (H_n, xor) a metric space, where H_n is the space of identifier keys of length n. This way, you can find an identifier be the closest to a target hash than the rest of the nodes in the network.
In order to find some data that is associated with some hash h, you have to find the nodes in the network for which the distance between their hash identifier and the target hash h is minimized. The group of nodes which are the closest to the target hash (OpenDHT allows up to 8 nodes) will hold data for that hash.

Data persistence Let s say you ask a group of 8 nodes to hold some data for a hash and you want the data to hold the whole time until its expiration time as come. If the group of 8 nodes change because that for some reason those nodes leave or others just arrive and have an id that is closer to the target hash than the initial group of 8 nodes. The data would then not be found on the new group of 8 nodes. A first and simple solution was to count on the initial creator of the value to periodically announce the value to the group of 8 nodes. However, what if this node leaves? This is one of the main problem that I ve been working on solving since 2015. A first version of this was produced on September 2015. However, we experienced traffic issues and were forced to redesign the OpenDHT network requests engine. We are presently working on adding a Query feature that would enable filtering of data on remote nodes, hence substantially lowering the overall traffic produced by a response to a get request.

Indexation During the last year, I have also been working on the design of a solution for the use case of indexation. In a more technical way, this is the capability to find data by providing a map where its key is a string field and the mapped value is the value associated to that field, much like in a form. This could help find data for which you don t know the hash, but you have specific information about its content. In other words, this would be a search engine for OpenDHT. I have already created a working, but still in progress, version of this. You can find it on http://opendht.net, on the index branch. Now, Nicolas Reynaud (kaldoran) is contributing to this during the GSOC.

Roadmap As I explained on my page on the Debian Wiki, I am going to work on:
  1. Developing new functionalities in OpenDHT aiming at reducing overall generated traffic.
  2. Maintenance and optimization of the OpenDHT code in general.
  3. Optimizing data persistence solution over the distributed hash table.
  4. Merge (1) in the Ring daemon component in order to benefit from lower traffic in Ring.
  5. Make OpenDHT use TCP protocol instead of UDP. This is going to reduce code complexity and enhance robsutness of the DHT.
For further details, read my reports!

2 June 2016

Kevin Avignon: Making a platformer in F# with MonoGame

Hey guys, Being myself a fan of functional programming and cross-platform development, I thought you might like a nice read on how to create your very first platformer game with F# & MonoGame. Making a platformer in F# with MonoGame For those not having any prior knowledge of F#, don t worry, I m going to do Continue reading Making a platformer in F# with MonoGame

Next.

Previous.