Search Results: "reg"

23 November 2015

Lunar: Reproducible builds: week 30 in Stretch cycle

What happened in the reproducible builds effort this week: Toolchain fixes Mattia Rizzolo uploaded a version of perl to the reproducible repository including the patch written by Niko Tyni to add support for SOURCE_DATE_EPOCH in Pod::Man. Dhole sent an updated version of his patch adding support for SOURCE_DATE_EPOCH in GCC to the upstream mailing list. Several comments have been made in response which have been quickly addressed by Dhole. Dhole also forwarded his patch adding support for SOURCE_DATE_EPOCH in libxslt upstream. Packages fixed The following packages have become reproducible due to changes in their build dependencies: antlr3/3.5.2-3, clusterssh, cme, libdatetime-set-perl, libgraphviz-perl, liblingua-translit-perl, libparse-cpan-packages-perl, libsgmls-perl, license-reconcile, maven-bundle-plugin/2.4.0-2, siggen, stunnel4, systemd, x11proto-kb. The following packages became reproducible after getting fixed: Some uploads fixed some reproducibility issues, but not all of them: reproducible.debian.net Vagrant Cascadian has set up a new armhf node using a Raspberry Pi 2. It should soon be added to the Jenkins infrastructure. diffoscope development diffoscope version 42 was release on November 20th. It adds a missing dependency on python3-pkg-resources and to prevent similar regression another autopkgtest to ensure that the command line is functional when Recommends are not installed. Two more encoding related problems have been fixed (#804061, #805418). A missing Build-Depends has also been added on binutils-multiarch to make the test suite pass on architectures other than amd64. Package reviews 180 reviews have been removed, 268 added and 59 updated this week. 70 new fail to build from source bugs have been reported by Chris West, Chris Lamb and Niko Tyni. New issue this week: randomness_in_ocaml_preprocessed_files. Misc. Jim MacArthur started to work on a system to rebuild and compare packages built on reproducible.debian.net using .buildinfo and snapshot.debian.org. On December 1-3rd 2015, a meeting of about 40 participants from 18 different free software projects will be held in Athens, Greece with the intent of improving the collaboration between projects, helping new efforts to be started, and brainstorming on end-user aspects of reproducible builds.

Thomas Goirand: OpenStack Liberty and Debian

Long over due post It s been a long time I haven t written here. And lots of things happened in the OpenStack planet. As a full time employee with the mission to package OpenStack in Debian, it feels like it is kind of my duty to tell everyone about what s going on. Liberty is out, uploaded to Debian Since my last post, OpenStack Liberty, the 12th release of OpenStack, was released. In late August, Debian was the first platform which included Liberty, as I proudly outran both RDO and Canonical. So I was the first to make the announcement that Liberty passed most of the Tempest tests with the beta 3 release of Liberty (the Beta 3 is always kind of the first pre-release, as this is when feature freeze happens). Though I never made the announcement that Liberty final was uploaded to Debian, it was done just a single day after the official release. Before the release, all of Liberty was living in Debian Experimental. Following the upload of the final packages in Experimental, I uploaded all of it to Sid. This represented 102 packages, so it took me about 3 days to do it all. Tokyo summit I had the pleasure to be in Tokyo for the Mitaka summit. I was very pleased with the cross-project sessions during the first day. Lots of these sessions were very interesting for me. In fact, I wish I could have attended them all, but of course, I can t split myself in 3 to follow all of the 3 tracks. Then there was the 2 sessions about Debian packaging on upstream OpenStack infra. The goal is to setup the OpenStack upstream infrastructure to allow packaging using Gerrit, and gating each git commit using the usual tools: building the package and checking there s no FTBFS, running checks like lintian, piuparts and such. I knew already the overview of what was needed to make it happen. What I didn t know was the implementation details, which I hoped we could figure out during the 1:30 slot. Unfortunately, this didn t happen as I expected, and we discussed more general things than I wished. I was told that just reading the docs from the infra team was enough, but in reality, it was not. What currently needs to happen is building a Debian based image, using disk-image-builder, which would include the usual tools to build packages: git-buildpackage, sbuild, and so on. I m still stuck at this stage, which would be trivial if I knew a bit more about how upstream infra works, since I already know how to setup all of that on a local machine. I ve been told by Monty Tailor that he would help. Though he s always a very busy man, and to date, he still didn t find enough time to give me a hand. Nobody replied to my request for help in the openstack-dev list either. Hopefully, with a bit of insistence, someone will help. Keystone migration to Testing (aka: Debian Stretch) blocked by python-repoze.who Absolutely all of OpenStack Liberty, as of today, has migrated to Stretch. All? No. Keystone is blocked by a chain of dependency. Keystone depends on python-pysaml2, itself blocked by python-repoze.who. The later, I upgraded it to version 2.2. Though python-repoze.what depends on version <= 1.9, which is blocking the migration. Since python-repoze.who-plugins, python-repoze.what and python-repoze.what-plugins aren t used by any package anymore, I asked for them to be removed from Debian (see #805407). Until this request is processed by the FTP masters, Keystone, which is the most important piece of OpenStack (it does the authentication) will be blocked for migration to Stretch. New OpenStack server packages available On my presentation at Debconf 15, I quickly introduced new services which were released upstream. I have since packaged them all: Congress, unfortunately, was not accepted to Sid yet, because of some licensing issues, especially with the doc of python-pulp. I will correct this (remove the non-free files) and reattempt an upload. I hope to make them all available in jessie-backports (see below). For the previous release of OpenStack (ie: Kilo), I skipped the uploads of services which I thought were not really critical (like Ironic, Designate and more). But from the feedback of users, they would really like to have them all available. So this time, I will upload them all to the official jessie-backports repository. Keystone v3 support For those who don t know about it, Keystone API v3 means that, on top of the users and tenant, there s a new entity called a domain . All of the Liberty is now coming with Keystone v3 support. This includes the automated Keystone catalog registration done using debconf for all *-api packages. As much as I could tell by running tempest on my CI, everything still works pretty well. In fact, Liberty is, to my experience, the first release of OpenStack to support Keystone API v3. Uploading Liberty to jessie-backports I have rebuilt all of Liberty for jessie-backports on my laptop using sbuild. This is more than 150 packages (166 packages currently). It took me about 3 days to rebuild them all, including unit tests run at build time. As soon as #805407 is closed by the FTP masters, all what s remaining will be available in Stretch (mostly Keystone), and the upload will be possible. As there will be a lot of NEW packages (from the point of view of backports), I do expect that the approval will take some time. Also, I have to warn the original maintainers of the packages that I don t maintain (for example, those maintained within the DPMT), that because of the big number of packages, I will not be able to process the usual communication to tell that I m uploading to backports. However, here s the list of package. If you see one that you maintain, and that you wish to upload the backport by yourself, please let me know. Here s the list of packages, hopefully, exhaustive, that I will upload to jessie-backports, and that I don t maintain myself: alabaster contextlib2 kazoo python-cachetools python-cffi python-cliff python-crank python-ddt python-docker python-eventlet python-git python-gitdb python-hypothesis python-ldap3 python-mock python-mysqldb python-pathlib python-repoze.who python-setuptools python-smmap python-unicodecsv python-urllib3 requests routes ryu sphinx sqlalchemy turbogears2 unittest2 zzzeeksphinx. More than ever, I wish I could just upload these to a PPA^W Bikeshed, to minimize the disruption for both the backports FTP masters, other maintainers, and our OpenStack users. Hopefully, Bikesheds will be available soon. I am sorry to give that much approval work to the backports FTP masters, however, using the latest stable system with the latest release, is what most OpenStack users really want to do. All other major distributions have specific repositories too (ie: RDO for CentOS / Red Hat, and cloud archive for Ubuntu), and stable-backports is currently the only place where I can upload support for the Stable release. Debian listed as supported distribution on openstack.org Good news! If you go at http://www.openstack.org/marketplace/distros/ you will see a list of supported distributions. I am proud to be able to tell that, after 6 months of lobbying from my side, Debian is also listed there. The process of having Debian there included talking with folks from the OpenStack foundation, and having Bdale to sign an agreement so that the Debian logo could be reproduced on openstack.org. Thanks to Bdale Garbee, Neil McGovern, Jonathan Brice, and Danny Carreno, without who this wouldn t have happen.

20 November 2015

Jonathan Dowland: smartmontools

It's been at least a year since I last did any work on Debian, but this week I finally uploaded a new version of squishyball, an audio sample comparison tool, incorporating a patch from Thibaut Girka which fixes the X/X/Y test method. Shamefully Thibaut's patch is nearly a year old too. Better late than never... I've also uploaded a new version of smartmontools which updates the package to the new upstream version. I'm not the regular maintainer for this package, but it is in the set of packages covered by the collab-maint team. To be polite I uploaded it to DELAYED-7, so it will take a week to hit unstable. I've temporarily put a copy of the package here in the meantime.

John Goerzen: I do not fear

I am so saddened by the news this week. The attacks in Paris, Beirut, and Mali. The reaction of fear, anger, and hate. Governors racing to claim they will keep out refugees, even though they lack the power to do so. Congress voting to keep out refugees. Emotions are a powerful thing. They can cause people to rise up and accomplish stunning things that move humanity forward. And they can move us back. Fear, and the manipulation of it, is one of those. What have I to fear? Even if the United States accepted half a million Syrian refugees tomorrow, I would be far more likely to die in a car accident than at the hands of a Syrian terrorist. I am a careful and cautious person, but I understand that life is not lived unless risk is balanced. I know there is a risk of being in a car crash every time I drive somewhere but if that kept me at home, I would never see my kids violin concert, the beautiful painted canyon of Texas, or the Flint Hills of Kansas. So I drive smart and carefully, but I still drive without fear. I accept this level of risk as necessary to have a life worth living in this area (where there are no public transit options and the nearest town is miles away). I have had pain in my life. I ve seen grandparents pass away, I ve seen others with health scares. These things are hard to think about, but they happen to us all at some point. What have I to fear? I do not fear giving food to the hungry, shelter to the homeless, comfort to those that have spent the last years being shot at. I do not fear helping someone that is different than me. If I fail to do these things for someone because of where they come from or what their holy book is, then I have become less human. I have become consumed by fear. I have let the terrorists have control over my life. And I refuse to do that. If governors really wanted to save lives, they would support meaningful mass transit alternatives that would prevent tens of thousands of road deaths a year. They would support guaranteed health care for all. They would support good education, science-based climate change action, clean water and air, mental health services for all, and above all, compassion for everyone. By supporting Muslim registries, we look like Hitler to them. By discriminating against refugees based on where they re from or their religion, we support the terrorists, making it easy for them to win hearts and minds. By ignoring the fact that entering the country as a refugee takes years, as opposed to entering as a tourist taking only minutes, we willfully ignore the truth about where dangers lie. So what do I have to fear? Only, as the saying goes, fear. Fear is making this country turn its backs on the needy. Fear is making not just the US but much of Europe turn its backs on civil liberties and due process. Fear gives the terrorists control, and that helps them win. I refuse. I simply refuse to play along. No terrorist, no politician, no bigot gets to steal MY humanity. Ultimately, however, I know that the long game is not one of fear. The arc of the universe bends towards justice, and ultimately, love wins. It takes agonizingly long sometimes, but in the end, love wins. So I do not fear.

Daniel Pocock: Databases of Muslims and homosexuals?

One US presidential candidate has said a lot recently, but the comments about making a database of Muslims may qualify as the most extreme. Of course, if he really wanted to, somebody with this mindset could find all the Muslims anyway. A quick and easy solution would involve tracing all the mobile phone signals around mosques on a Friday. Mr would-be President could compel Facebook and other social networks to disclose lists of users who identify as Muslim. Databases are a dangerous side-effect of gay marriage In 2014 there was significant discussion about Brendan Eich's donation to the campaign against gay marriage. One fact that never ranked very highly in the debate at the time is that not all gay people actually support gay marriage. Even where these marriages are permitted, not everybody who can marry now is choosing to do so. The reasons for this are varied, but one key point that has often been missed is that there are two routes to marriage equality: one involves permitting gay couples to visit the register office and fill in a form just as other couples do. The other route to equality is to remove all the legal artifacts around marriage altogether. When the government does issue a marriage certificate, it is not long before other organizations start asking for confirmation of the marriage. Everybody from banks to letting agents and Facebook wants to know about it. Many companies outsource that data into cloud CRM systems such as Salesforce. Before you know it, there are numerous databases that somebody could mine to make a list of confirmed homosexuals. Of course, if everybody in the world was going to live happily ever after none of this would be a problem. But the reality is different. While discrimination: either against Muslims or homosexuals - is prohibited and can even lead to criminal sanctions in some countries, this attitude is not shared globally. Once gay people have their marriage status documented in the frequent flyer or hotel loyalty program, or in the public part of their Facebook profile, there are various countries where they are going to be at much higher risk of prosecution/persecution. The equality to marry in the US or UK may mean they have less equality when choosing travel destinations. Those places are not as obscure as you might think: even in Australia, regarded as a civilized and laid-back western democracy, the state of Tasmania fought tooth-and-nail to retain the criminalization of virtually all homosexual conduct until 1997 when the combined actions of the federal government and high court compelled the state to reform. Despite the changes, people with some of the most offensive attitudes are able to achieve and retain a position of significant authority. The same Australian senator who infamously linked gay marriage with bestiality has successfully used his position to set up a Senate inquiry as a platform for conspiracy theories linking Halal certification with terrorism. There are many ways a database can fall into the wrong hands Ironically, one of the most valuable lessons about the risk of registering Muslims and homosexuals was an injustice against the very same tea-party supporters a certain presidential candidate is trying to woo. In 2013, it was revealed IRS employees had started applying a different process to discriminate against groups with Tea party in their name. It is not hard to imagine other types of rogue or misinformed behavior by people in positions of authority when they are presented with information that they don't actually need about somebody's religion or sexuality. Beyond this type of rogue behavior by individual officials and departments, there is also the more sinister proposition that somebody truly unpleasant is elected into power and can immediately use things like a Muslim database, surveillance data or the marriage database for a program of systematic discrimination. France had a close shave with this scenario in the 2002 presidential election when
Jean-Marie Le Pen, who has at least six convictions for racism or inciting racial hatred made it to the final round in a two-candidate run-off with Jacques Chirac. The best data security The best way to be safe- wherever you go, both now and in the future - is not to have data about yourself on any database. When filling out forms, think need-to-know. If some company doesn't really need your personal mobile number, your date of birth, your religion or your marriage status, don't give it to them.

Sylvain Beucler: Mini-sendmail... in bash

I recently faced an environment where there is no MTA. WTF? The reason is that people who work there get security audits on a regular basis, and the security people are usually mo...deratly skilled guys who blindly run a set of scripts, e.g. by ordering to disable Apache modules that "where seen enabled in /etc/apache2/mods-available/"... To avoid spending days arguing with them and nitpicking with non-technical managers, the system is trimmed to the minimum - and there is no MTA. No MTA, so no cron output, so difficulty to understand why last night's cron job failed miserably. Since it was not my role to reshape the whole business unit, I decided to hack a super-light, but functional way to get my cron output:
cat <<'EOF' > /usr/sbin/sendmail
#!/bin/bash
(
    echo "From me  $(LANG=C date)"
    cat
    echo
) >> /var/mail/all
EOF
chmod 755 /usr/sbin/sendmail
It works! :) There is a companion logrotate script, to avoid filling the file system:
cat <<'EOF' > /etc/logrotate.d/mail-all
/var/mail/all  
  daily
  rotate 10
  compress
  delaycompress
  notifempty
  create 622 root mail
 
EOF
Bootstrap with:
touch /var/mail/all
logrotate -f /var/mail/all
You now can check your sys-mails with:
mutt -f /var/mail/all
;)

17 November 2015

Dirk Eddelbuettel: RcppAnnoy 0.0.7

A new version of RcppAnnoy, our Rcpp-based R integration of the nifty Annoy library by Erik, is now on CRAN. Annoy is a small, fast, and lightweight C++ template header library for approximate nearest neighbours. This release mostly just catches up with the Annoy release 1.6.2 of last Friday. No new features were added on our side. Courtesy of CRANberries, there is also a diffstat report for this release.

This post by Dirk Eddelbuettel originated on his Thinking inside the box blog. Please report excessive re-aggregation in third-party for-profit settings.

16 November 2015

Julien Danjou: Profiling Python using cProfile: a concrete case

Writing programs is fun, but making them fast can be a pain. Python programs are no exception to that, but the basic profiling toolchain is actually not that complicated to use. Here, I would like to show you how you can quickly profile and analyze your Python code to find what part of the code you should optimize. What's profiling? Profiling a Python program is doing a dynamic analysis that measures the execution time of the program and everything that compose it. That means measuring the time spent in each of its functions. This will give you data about where your program is spending time, and what area might be worth optimizing. It's a very interesting exercise. Many people focus on local optimizations, such as determining e.g. which of the Python functions range or xrange is going to be faster. It turns out that knowing which one is faster may never be an issue in your program, and that the time gained by one of the functions above might not be worth the time you spend researching that, or arguing about it with your colleague. Trying to blindly optimize a program without measuring where it is actually spending its time is a useless exercise. Following your guts alone is not always sufficient. There are many types of profiling, as there are many things you can measure. In this exercise, we'll focus on CPU utilization profiling, meaning the time spent by each function executing instructions. Obviously, we could do many more kind of profiling and optimizations, such as memory profiling which would measure the memory used by each piece of code something I talk about in The Hacker's Guide to Python. cProfile Since Python 2.5, Python provides a C module called cProfile which has a reasonable overhead and offers a good enough feature set. The basic usage goes down to:
>>> import cProfile
>>> cProfile.run('2 + 2')
2 function calls in 0.000 seconds

Ordered by: standard name

ncalls tottime percall cumtime percall filename:lineno(function)
1 0.000 0.000 0.000 0.000 <string>:1(<module>)
1 0.000 0.000 0.000 0.000 method 'disable' of '_lsprof.Profiler' objects

Though you can also run a script with it, which turns out to be handy:
$ python -m cProfile -s cumtime lwn2pocket.py
72270 function calls (70640 primitive calls) in 4.481 seconds

Ordered by: cumulative time

ncalls tottime percall cumtime percall filename:lineno(function)
1 0.004 0.004 4.481 4.481 lwn2pocket.py:2(<module>)
1 0.001 0.001 4.296 4.296 lwn2pocket.py:51(main)
3 0.000 0.000 4.286 1.429 api.py:17(request)
3 0.000 0.000 4.268 1.423 sessions.py:386(request)
4/3 0.000 0.000 3.816 1.272 sessions.py:539(send)
4 0.000 0.000 2.965 0.741 adapters.py:323(send)
4 0.000 0.000 2.962 0.740 connectionpool.py:421(urlopen)
4 0.000 0.000 2.961 0.740 connectionpool.py:317(_make_request)
2 0.000 0.000 2.675 1.338 api.py:98(post)
30 0.000 0.000 1.621 0.054 ssl.py:727(recv)
30 0.000 0.000 1.621 0.054 ssl.py:610(read)
30 1.621 0.054 1.621 0.054 method 'read' of '_ssl._SSLSocket' objects
1 0.000 0.000 1.611 1.611 api.py:58(get)
4 0.000 0.000 1.572 0.393 httplib.py:1095(getresponse)
4 0.000 0.000 1.572 0.393 httplib.py:446(begin)
60 0.000 0.000 1.571 0.026 socket.py:410(readline)
4 0.000 0.000 1.571 0.393 httplib.py:407(_read_status)
1 0.000 0.000 1.462 1.462 pocket.py:44(wrapped)
1 0.000 0.000 1.462 1.462 pocket.py:152(make_request)
1 0.000 0.000 1.462 1.462 pocket.py:139(_make_request)
1 0.000 0.000 1.459 1.459 pocket.py:134(_post_request)
[ ]

This prints out all the function called, with the time spend in each and the number of times they have been called. Advanced visualization with KCacheGrind While being useful, the output format is very basic and does not make easy to grab knowledge for complete programs. For more advanced visualization, I leverage KCacheGrind. If you did any C programming and profiling these last years, you may have used it as it is primarily designed as front-end for Valgrind generated call-graphs. In order to use, you need to generate a cProfile result file, then convert it to KCacheGrind format. To do that, I use pyprof2calltree.
$ python -m cProfile -o myscript.cprof myscript.py
$ pyprof2calltree -k -i myscript.cprof

And the KCacheGrind window magically appears!
Concrete case: Carbonara optimization I was curious about the performances of Carbonara, the small timeserie library I wrote for Gnocchi. I decided to do some basic profiling to see if there was any obvious optimization to do. In order to profile a program, you need to run it. But running the whole program in profiling mode can generate a lot of data that you don't care about, and adds noise to what you're trying to understand. Since Gnocchi has thousands of unit tests and a few for Carbonara itself, I decided to profile the code used by these unit tests, as it's a good reflection of basic features of the library. Note that this is a good strategy for a curious and naive first-pass profiling. There's no way that you can make sure that the hotspots you will see in the unit tests are the actual hotspots you will encounter in production. Therefore, a profiling in conditions and with a scenario that mimics what's seen in production is often a necessity if you need to push your program optimization further and want to achieve perceivable and valuable gain. I activated cProfile using the method described above, creating a cProfile.Profile object around my tests (I actually started to implement that in testtools). I then run KCacheGrind as described above. Using KCacheGrind, I generated the following figures.
The test I profiled here is called test_fetch and is pretty easy to understand: it puts data in a timeserie object, and then fetch the aggregated result. The above list shows that 88 % of the ticks are spent in set_values (44 ticks over 50). This function is used to insert values into the timeserie, not to fetch the values. That means that it's really slow to insert data, and pretty fast to actually retrieve them. Reading the rest of the list indicates that several functions share the rest of the ticks, update, _first_block_timestamp, _truncate, _resample, etc. Some of the functions in the list are not part of Carbonara, so there's no point in looking to optimize them. The only thing that can be optimized is, sometimes, the number of times they're called.
The call graph gives me a bit more insight about what's going on here. Using my knowledge about how Carbonara works, I don't think that the whole stack on the left for _first_block_timestamp makes much sense. This function is supposed to find the first timestamp for an aggregate, e.g. with a timestamp of 13:34:45 and a period of 5 minutes, the function should return 13:30:00. The way it works currently is by calling the resample function from Pandas on a timeserie with only one element, but that seems to be very slow. Indeed, currently this function represents 25 % of the time spent by set_values (11 ticks on 44). Fortunately, I recently added a small function called _round_timestamp that does exactly what _first_block_timestamp needs that without calling any Pandas function, so no resample. So I ended up rewriting that function this way:
def _first_block_timestamp(self):
- ts = self.ts[-1:].resample(self.block_size)
- return (ts.index[-1] - (self.block_size * self.back_window))
+ rounded = self._round_timestamp(self.ts.index[-1], self.block_size)
+ return rounded - (self.block_size * self.back_window)

And then I re-run the exact same test to compare the output of cProfile.
The list of function seems quite different this time. The number of time spend used by set_values dropped from 88 % to 71 %.
The call stack for set_values shows that pretty well: we can't even see the _first_block_timestamp function as it is so fast that it totally disappeared from the display. It's now being considered insignificant by the profiler. So we just speed up the whole insertion process of values into Carbonara by a nice 25 % in a few minutes. Not that bad for a first naive pass, right?

Dirk Eddelbuettel: Rcpp 0.12.2: More refinements

The second update in the 0.12.* series of Rcpp is now on the CRAN network for GNU R. As usual, I will also push a Debian package. This follows the 0.12.0 release from late July which started to add some serious new features, and builds upon the 0.12.1 release in September. It also marks the sixth release this year where we managed to keep a steady bi-montly release frequency. Rcpp has become the most popular way of enhancing GNU R with C or C++ code. As of today, 512 packages on CRAN depend on Rcpp for making analytical code go faster and further. That is up by more than fifty package from the last release in September (and we recently blogged about crossing 500 dependents). This release once again features pull requests from two new contributors with Nathan Russell and Tianqi Chen joining in. As shown below, other recent contributors (such as such as Dan) are keeping at it too. Keep'em coming! Luke Tierney also email about a code smell he spotted and which we took care of. A big Thank You! to everybody helping with code, bug reports or documentation. See below for a detailed list of changes extracted from the NEWS file.
Changes in Rcpp version 0.12.2 (2015-11-14)
  • Changes in Rcpp API:
    • Correct return type in product of matrix dimensions (PR #374 by Florian)
    • Before creating a single String object from a SEXP, ensure that it is from a vector of length one (PR #376 by Dirk, fixing #375).
    • No longer use STRING_ELT as a left-hand side, thanks to a heads-up by Luke Tierney (PR #378 by Dirk, fixing #377).
    • Rcpp Module objects are now checked more carefully (PR #381 by Tianqi, fixing #380)
    • An overflow in Matrix column indexing was corrected (PR #390 by Qiang, fixing a bug reported by Allessandro on the list)
    • Nullable types can now be assigned R_NilValue in function signatures. (PR #395 by Dan, fixing issue #394)
    • operator<<() now always shows decimal points (PR #396 by Dan)
    • Matrix classes now have a transpose() function (PR #397 by Dirk fixing #383)
    • operator<<() for complex types was added (PRs #398 by Qiang and #399 by Dirk, fixing #187)
  • Changes in Rcpp Attributes:
    • Enable export of C++ interface for functions that return void.
  • Changes in Rcpp Sugar:
    • Added new Sugar function cummin(), cummax(), cumprod() (PR #389 by Nathan Russell fixing #388)
    • Enabled sugar math operations for subsets; e.g. x[y] + x[z]. (PR #393 by Kevin and Qiang, implementing #392)
  • Changes in Rcpp Documentation:
    • The NEWS file now links to GitHub issue tickets and pull requests.
    • The Rcpp.bib file with bibliographic references was updated.
Thanks to CRANberries, you can also look at a diff to the previous release As always, even fuller details are on the Rcpp Changelog page and the Rcpp page which also leads to the downloads page, the browseable doxygen docs and zip files of doxygen output for the standard formats. A local directory has source and documentation too. Questions, comments etc should go to the rcpp-devel mailing list off the R-Forge page.

This post by Dirk Eddelbuettel originated on his Thinking inside the box blog. Please report excessive re-aggregation in third-party for-profit settings.

15 November 2015

Manuel A. Fernandez Montecelo: Work on aptitude

Midsummer for me is also known as Noite do Lume Novo (literally New Fire Night ), one of the big calendar events of the year, marking the end of the school year and the beginning of summer. On this day, there are celebrations not very unlike the bonfires in the Guy Fawkes Night in England or Britain [1]. It is a bit different in that it is not a single event for the masses, more of a friends and neighbours thing, and that it lasts for a big chunk of the night (sometimes until morning). Perhaps for some people, or outside bigger towns or cities, Guy Fawkes Night is also celebrated in that way and that's why during the first days of November there are fireworks rocketing and cracking in the neighbourhoods all around. Like many other celebrations around the world involving bonfires, many of them also happening around the summer solstice, it is supposed to be a time of renewal of cycles, purification and keeping the evil spirits away; with rituals to that effect like jumping over the fire when the flames are not high and it is safe enough. So it was fitting that, in the middle of June (almost Midsummer in the northern hemisphere), I learnt that I was about to leave my now-previous job, which is a pretty big signal and precursor for renewal (and it might have something to do with purifying and keeping the evil away as well ;-) ). Whatever... But what does all of this have to do with aptitude or Debian, anyway? For one, it was a question of timing. While looking for a new job (and I am still at it), I had more spare time than usual. DebConf 15 @ Heidelberg was within sight, and for the first time circumstances allowed me to attend this event. It also coincided with the time when I re-gained access to commit to aptitude on the 19th of June. Which means Renewal. End of June was also the time of the announcement of the colossal GCC-5/C++11 ABI transition in Debian, that was scheduled to start on the 1st of August, just before the DebConf. Between 2 and 3 thousand source packages in Debian were affected by this transition, which a few months later is not yet finished (although the most important parts were completed by mid-end September). aptitude itself is written in C++, and depends on several libraries written in C++, like Boost, Xapian and SigC++. All of them had to be compiled with the new C++11 ABI of GCC-5, in unison and in a particular order, for aptitude to continue to work (and for minimal breakage). aptitude and some dependencies did not even compile straight away, so this transition meant that aptitude needed attention just to keep working. Having recently being awarded again with the Aptitude Hat, attending DebConf for the first time and sailing towards the Transition Maelstrom, it was a clear sign that Something Had to Be Done (to avoid the sideways looks and consequent shame at DebConf, if nothing else). Happily (or a bit unhappily for me, but let's pretend...), with the unexpected free time in my hands, I changed the plans that I had before re-gaining the Aptitude Hat (some of them involving Debian, but in other ways maybe I will post about that soon). In July I worked to fix the problems before the transition started, so aptitude would be (mostly) ready, or in the worst case broken only for a few days, while the chain of dependencies was rebuilt. But apart from the changes needed for the new GCC-5, it was decided at the last minute that Boost 1.55 would not be rebuilt with the new ABI, and that the only version with the new ABI would be 1.58 (which caused further breakage in aptitude, was added to experimental only a few days before, and was moved to unstable after the transition had started). Later, in the first days of the transition, aptitude was affected for a few days by breakage in the dependencies, due to not being compiled in sequence according to the transition levels (so with a mix of old and new ABI). With the critical intervention of Axel Beckert (abe / XTaran), things were not so bad as they could have been. He was busy testing and uploading in the critical days when I was enjoying a small holiday on my way to DebConf, with minimal internet access and communicating almost exclusively with him; and he promptly tended the complaints arriving in the Bug Tracking System and asked for rebuilds of the dependencies with the new ABI. He also brought the packaging up to shape, which had decayed a bit in the last few years. Gruesome Challenges But not all was solved yet, more storms were brewing and started to appear in the horizon, in the form of clouds of fire coming from nearby realms. The APT Deities, which had long ago spilled out their secret, inner challenge (just the initial paragraphs), were relentless. Moreover, they were present at Heidelberg in full force, in or close to their home grounds, and they were Marching Decidedly towards Victory: apt BTS Graph, 2015-11-15 In the talk @ DebConf This APT has Super Cow Powers (video available), by David Kalnischkies, they told us about the niceties of apt 1.1 (still in experimental but hopefully coming to unstable soon), and they boasted about getting the lead in our arms race (should I say bugs race?) by a few open bug reports. This act of provocation further escalated the tensions. The fierce competition which had been going on for some time gained new heights. So much so that APT Deities and our team had to sit together in the outdoor areas of the venue and have many a weissbier together, while discussing and fixing bugs. But beneath the calm on the surface, and while pretending to keep good diplomatic relations, I knew that Something Had to Be Done, again. So I could only do one thing jump over the bonfire and Keep the Evil away, be that Keep Evil bugs Away or Keep Evil APT Deities Away from winning the challenge, or both. After returning from DebConf I continued to dedicate time to the project, more than a full time job in some weeks, and this is what happened in the last few months, summarised in another graph, showing the evolution of the BTS for aptitude: aptitude BTS Graph, 2015-11-15 The numbers for apt right now (15th November 2015) are: The numbers for aptitude right now are: The Aftermath As we can see, for the time being I could keep the Evil at bay, both in terms of bugs themselves and re-gaining the lead in the bugs race the Evil APT Deities were thwarted again in their efforts. ... More seriously, as most of you suspected, the graph above is not the whole truth, so I don't want to boast too much. A big part of the reduction in the number of bugs is because of merging duplicates, closing obsolete bugs, applying translations coming from multiple contributors, or simple fixes like typos and useful suggestions needing minor changes. Many of remaining problems are comparatively more difficult or time consuming that the ones addressed so far (except perhaps avoiding the immediate breakage of the transition, that took weeks to solve), and there are many important problems still there, chief among those is aptitude offering very poor solutions to resolve conflicts. Still, even the simplest of the changes takes effort, and triaging hundreds of bugs is not fun at all and mostly a thankless effort althought there is the occasionally kind soul that thanks you for handling a decade-old bug. If being subjected to the rigours of the BTS and reading and solving hundreds of bug reports is not Purification, I don't know what it is. Apart from the triaging, there were 118 bugs closed (or pending) due to changes made in the upstream part or the packaging in the last few months, and there are many changes that are not reflected in bugs closed (like most of the changes needed due to the C++11 ABI transition, bugs and problems fixed that had no report, and general rejuvenation or improvement of some parts of the code). How long this will last, I cannot know. I hope to find a job at some point, which obviously will reduce the time available to work on this. But in the meantime, for all aptitude users: Enjoy the fixes and new features! Notes [1] ^ Some visitors of the recent mini-DebConf @ Cambridge perhaps thought that the fireworks and throngs gathered were in honour of our mighty Universal Operating System, but sadly they were not. They might be, some day. In any case, the reports say that the visitors enjoyed the fireworks.

Lunar: Reproducible builds: week 29 in Stretch cycle

What happened in the reproducible builds effort this week: Toolchain fixes Emmanuel Bourg uploaded eigenbase-resgen/1.3.0.13768-2 which uses of the scm-safe comment style by default to make them deterministic. Mattia Rizzolo started a new thread on debian-devel to ask a wider audience for issues about the -Wdate-time compile time flag. When enabled, GCC and clang print warnings when __DATE__, __TIME__, or __TIMESTAMP__ are used. Having the flag set by default would prompt maintainers to remove these source of unreproducibility from the sources. Packages fixed The following packages have become reproducible due to changes in their build dependencies: bmake, cyrus-imapd-2.4, drobo-utils, eigenbase-farrago, fhist, fstrcmp, git-dpm, intercal, libexplain, libtemplates-parser, mcl, openimageio, pcal, powstatd, ruby-aggregate, ruby-archive-tar-minitar, ruby-bert, ruby-dbd-odbc, ruby-dbd-pg, ruby-extendmatrix, ruby-rack-mobile-detect, ruby-remcached, ruby-stomp, ruby-test-declarative, ruby-wirble, vtprint. The following packages became reproducible after getting fixed: Some uploads fixed some reproducibility issues, but not all of them: Patches submitted which have not made their way to the archive yet: reproducible.debian.net The fifth and sixth armhf build nodes have been set up, resulting in five more builder jobs for armhf. More than 10,000 packages have now been identified as reproducible with the reproducible toolchain on armhf. (Vagrant Cascadian, h01ger) Helmut Grohne and Mattia Rizzolo now have root access on all 12 build nodes used by reproducible.debian.net and jenkins.debian.net. (h01ger) reproducible-builds.org is now linked from all package pages and the reproducible.debian.net dashboard. (h01ger) profitbricks-build5-amd64 and profitbricks-build6-amd64, responsible for running amd64 tests now run 398.26 days in the future. This means that one of the two builds that are being compared will be run on a different minute, hour, day, month, and year. This is not yet the case for armhf. FreeBSD tests are also done with 398.26 days difference. (h01ger) The design of the Arch Linux test page has been greatly improved. (Levente Polyak) diffoscope development Three releases of diffoscope happened this week numbered 39 to 41. It includes support for EPUB files (Reiner Herrmann) and Free Pascal unit files, usually having .ppu as extension (Paul Gevers). The rest of the changes were mostly targetting at making it easier to run diffoscope on other systems. The tlsh, rpm, and debian modules are now all optional. The test suite will properly skip tests that need optional tools or modules when they are not available. As a result, diffosope is now available on PyPI and thanks to the work of Levente Polyak in Arch Linux. Getting these versions in Debian was a bit cumbersome. Version 39 was uploaded with an expired key (according to the keyring on ftp.debian.org which will hopefully be updated soon) which is currently handled by keeping the files in the queue without REJECTing them. This prevented any other Debian Developpers to upload the same version. Version 40 was uploaded as a source-only upload but failed to build from source which had the undesirable side effect of removing the previous version from unstable. The package faild to build from source because it was built passing -I to debbuild. This excluded the ELF object files and static archives used by the test suite from the archive, preventing the test suite to work correctly. Hopefully, in a nearby future it will be possible to implement a sanity check to prevent such mistakes in the future. It has also been identified that ppudump outputs time in the system timezone without considering the TZ environment variable. Zachary Vance and Paul Gevers raised the issue on the appropriate channels. strip-nondeterminism development Chris Lamb released strip-nondeterminism version 0.014-1 which disables stripping Mono binaries as it is too aggressive and the source of the problem is being worked on by Mono upstream. Package reviews 133 reviews have been removed, 115 added and 103 updated this week. Chris West and Chris Lamb reported 57 new FTBFS bugs. Misc. The video of h01ger and Chris Lamb's talk at MiniDebConf Cambridge is now available. h01ger gave a talk at CCC Hamburg on November 13th, which was well received and sparked some interest among Gentoo folks. Slides and video should be available shortly. Frederick Kautz has started to revive Dhiru Kholia's work on testing Fedora packages. Your editor wish to once again thank #debian-reproducible regulars for reviewing these reports weeks after weeks.

14 November 2015

Daniel Pocock: Migrating data from Windows phones

Many of the people who have bought Windows phones seek relief sooner or later. Sometimes this comes about due to peer pressure or the feeling of isolation, in other cases it is the frustration of the user interface or the realization that they can't run cool apps like Lumicall. Frequently, the user has been given the phone as a complimentary upgrade when extending a contract without perceiving the time, effort and potential cost involved in getting their data out of the phone, especially if they never owned a smartphone before. When a Windows phone user does decide to cut their losses, they are usually looking to a friend or colleague with technical expertise to help them out. Personally, I'm not sure that anybody I would regard as an IT expert has ever had a Windows phone though, meaning that many experts are probably also going to be scratching their heads when somebody asks them for help. Therefore, I've put together this brief guide to help deal with these phones more expediently when they are encountered. The Windows phones have really bad support for things like CalDAV and WebDAV so don't get your hopes up about using such methods to backup the data to any arbitrary server. Searching online you can find some hacks that involve creating a Google or iCloud account in the phone and then modifying the advanced settings to send the data to an arbitrary server. These techniques vary a lot between specific versions of the Windows Phone OS and so the techniques I've described below are probably easier. Identify the Windows Live / Hotmail account The user may not remember or realize that a Microsoft account was created when they first obtained the phone. It may have been created for them by the phone, a friend or the salesperson in the phone shop. Look in the settings (Accounts) to find the account ID / email address. If the user hasn't been using this account, they may not recognize it and probably won't know the password for it. It is essential to try and obtain (or reset) the password before going any further, so start with the password recovery process. Microsoft may insist on sending a password reset email to some other email address that the user has previously provided or linked to their phone. Extracting data from the phone In many cases, the easiest way to extract the data is to download it from Microsoft live.com rather than extracting it from the phone. Even if the user doesn't realize it, the data is probably all replicated in live.com and so there is no further loss of privacy by logging in there to extract it. Set up an IMAP mail client An IMAP client will be used to download the user's emails (from the live.com account they may never have used) and SMS. Install Mozilla Thunderbird (IceDove on Debian), GNOME Evolution or a similar program on the user's PC. Configure the IMAP mail client to connect to the live.com account. Some clients, like Thunderbird, will automatically set up all the server details when you enter the live.com account ID. For manual account setup, the details here may help. Email backup If the user was not using the live.com account ID for email correspondence, there may not be a lot of mail in it. There may be some billing receipts or other things that are worth keeping though. Create a new folder (or set of folders) in the user's preferred email account and drag and drop the messages from the live.com Inbox to the new folder(s). SMS backup SMS backup can also be done through live.com. It is slightly more complicated than email backup, but similar.
  • In the live.com Outlook email index page, look for the settings button and click Manage Categories.
  • Enable the Contacts and Photos categories with a tick in each of them.
  • Go back to the main Inbox page and look for the categories section on the bottom left-hand side of the screen, under the folder list. Click the Contacts category.
  • The page may now appear blank. That is normal.
  • On the top right-hand corner of the page, click the Arrange menu and choose Conversation.
  • All the SMS messages should now appear on the screen.
  • Under the mail folders list on the left-hand side of the page, click to create a new folder with a name like SMS.
  • Select all the SMS messages and look for the option to move them to a folder. Send them to the SMS folder you created.
  • Now use the IMAP mail client to locate the SMS folder and copy everything from there to a new folder in the user's preferred mail server or local disk.
Contacts backup On the top left-hand corner of the live.com email page, there is a chooser to select other live.com applications. Select People. You should now see a list of all the user's contacts. Look for the option to export them to Outlook and other programs. This will export them as a CSV file. You can now import the CSV file into another application. GNOME Evolution has an import wizard with an option for Outlook file format. To load the contacts into a WebDAV address book, such as DAViCal, configure the address book in Evolution and then select it as the destination when running the CSV import wizard. WARNING: beware of using the Mozilla Thunderbird address book with contact data from mobile devices and other sources. It can't handle more than two email addresses per contact and this can lead to silent data loss if contacts are not fully saved. Calendar backup Now go to the live.com application chooser again and select the calendar application. Microsoft provides instructions to extract the calendar, summarised here:
  • Look for the Share button at the top somewhere and click it.
  • On the left-hand side of the page, click Get a link
  • On the right-hand side, choose Show event details to ensure you get a full calendar and then click Create underneath it.
  • Look for the link with a webcals prefix. If you are downloading with a tool like wget, change the scheme prefix to https. Fetch the file from this link and save it with an ics extension.
  • Inspect the ics calendar file to make sure it looks like real iCalendar data.
You can now import the ics file into another application. GNOME Evolution has an import wizard with an option for iCalendar file format. To load the calendar entries into a CalDAV server, such as DAViCal, configure the calendar server in Evolution and then select it as the destination when running the import wizard. Backup the user's photos, videos and other data files Hopefully you will be able to do this step without going through live.com. Try enabling the MTP or PTP mode in the phone and attach it to the computer using the USB cable. Hopefully the computer will recognize it in at least one of those modes. Use the computer's file manager or another tool to simply backup the entire directory structure. Reset the phone to factory defaults Once the user has their hands on a real phone, it is likely they will never want to look at that Windows phone again. It is time to erase the Windows phone, there is no going back. Go to the Settings and About and tap the factory reset option. It is important to do this before obliterating the live.com account, otherwise there are scenarios where you could be locked out of the phone and unable to erase it. Erasing may take some time. The phone will reboot and then display an animation of some gears spinning around for a few minutes and then reboot again. Wait for it to completely erase. Permanently close the Microsoft live.com account Keeping track of multiple accounts and other services is tedious and frustrating for most people, especially with services that try to force the user to receive email in different places. You can help eliminate user fatigue by helping them permanently close the live.com account so they never have to worry about it again. Follow the instructions on the Microsoft site. At some point it will suggest certain actions you should take before closing the account, most can be ignored. One thing you should do is remove the link between the live.com account ID and the phone. It is a good idea to do this as otherwise you may have problems erasing the device, if you haven't already done so. Before completely closing the account, also verify that the factory reset of the phone completed successfully. Dispose of the Windows phone safely If you can identify any faults with the phone, the user may be able to return it under the terms of the warranty. Some phone companies may allow the user to exchange it for something more desirable when it fails under warranty. It may be tempting to sell the phone to a complete stranger on eBay or install a custom ROM on it. In practice, neither option may be worth the time and effort involved. You may be tempted to put it beyond use so nobody else will suffer with it, but please try to do so in a way that is respectful of the environment. Putting the data into a new phone Prepare the new phone with a suitable ROM such as Replicant or Cyanogenmod. Install the F-Droid app on the new phone. From F-droid, install the DAVdroid app. DAVdroid will allow you to quickly sync the new phone against any arbitrary CalDAV and WebDAV server to populate it with the user's calendar and contact / address book data. Now is a good time to install other interesting apps like Lumicall, Conversations and K-9 Mail.

Juliana Louback: PaperTrail - Powered by IBM Watson

On the final semester of my MSc program at Columbia SEAS, I was lucky enough to be able to attend a seminar course taught by Alfio Gliozzo entitled Q&A with IBM Watson. A significant part of the course is dedicated to learning how to leverage the services and resources available on the Watson Developer Cloud. This post describes the course project my team developed, the PaperTrail application.

Project Proposal Create an application to assist in the development of future academic papers. Based on a paper s initial proposal, Paper Trail predicts publications to be used as references or acknowledgement of prior art and provides a trend analysis of major topics and methods. The objective is to speed the discovery of relevant papers early in the research process, and allow for early assessment of the depth of prior research concerning the initial proposal.

Meet the Team Wesley Bruning, Software Engineer, MSc. in Computer Science Xavier Gonzalez, Industrial Engineer, MSc. in Data Science Juliana Louback, Software Engineer, MSc. in Computer Science Aaron Zakem, Patent Attorney, MSc. in Computer Science

Prior Art A significant amount of attention has been given to this topic over the past few decades. The table below shows the work the team deemed most relevant due to recency, accuracy and similarity of functionality. priorArt The variation in accuracy displayed is a result of experimentation with different dataset sizes and algorithm variations. More information and details can be found in the prior art report. The main differential of PaperTrail is providing a form of access to the citation prediciton and trend analysis algorithm. With the exception of the project by McNee et al., these algorithmns aren t currently available for general use. The application on researchindex.net is open to use but its objective is to rank publications and authors for given topics.

Algorithm Citation Prediction: PaperTrail builds on the work done by Wolski s team in Fall 2014. This algorithmn builds a reference graph used to define research communities, with an associated vector of topic scores generated by an LDA model. The papers in each research community are then ranked by importance within the community with a custom ranking algorithm. When a target document is given to algorithm as input, the LDA model is used to generate a vector of topics that are present in the document. The communities with the most similar topic vectors are selected and the publications within these communities with highest rank and greatest similarity to the input document are recommended as references. A more detailed description can be found here. Trend Analysis: Initially, the idea was to use the AlchemyData News API to obtain statistics pertaining to the amount of publications on a given topic over time. However, with the exception of buzz-words (i.e. big data ), many more specialized topics appeared very infrequently in news articles, if at all. This isn t entirely surprising given the target audience of PaperTrail. As a work around, we use the Alchemy Language API to extract keywords from the abstracts in the dataset, in addition to relevance scores. The PaperTrail database could then be queried for entry counts for a given year and keyword to provide an indication of publication trends in academia. Note that the Alchemy Language API extracts multiple-word keywords as well as single words.

Data To maintain consistency with Wolski s project, we are using the DBLP data as made available on aminer.org. The DBLP-Citation-network V5 dataset contains 1,572,277 entries; we are limited to the use of entries that contain both abstracts and citations, bringing the dataset size down to 265,865 entries.

Architecture A high-level visualization of the project architecture is displayed below. Before launching PaperTrail, it s necessary to train Wolski s algorithm offline. Currently any documentation with regard to the performance of said algorithm is unavailable; the PaperTrail project will include an evaluation phase and report the findings made. The PaperTrail app and database will be hosted on the Bluemix Platform. ptArchitecture

Status Report Phases completed:
  • Project design
  • Prior art research
  • Data cleansing
  • Development and deployment of an alpha version of the PaperTrail app
Phases under development:
  • Algorithm training and evaluation
  • Keyword extraction
  • MapReduce of publication frequency by year and topic
  • Data visualization component

Craig Small: Mixing pysnmp and stdin

Depending on the application, sometimes you want to have some socket operations going (such as loading a website) and have stdin being read. There are plenty of examples for this in python which usually boil down to making stdin behave like a socket and mixing it into the list of sockets select() cares about. A while ago I asked an email list could I have pysnmp use a different socket map so I could add my own sockets in (UDP, TCP and a zmq to name a few) and the Ilya the author of pysnmp explained how pysnmp can use a foreign socket map. This sample code below is merely an mixture of Ilya s example code and the way stdin gets mixed into the fold. I have also updated to the high-level pysnmp API which explains the slight differences in the calls.
  1. from time import time
  2. import sys
  3. import asyncore
  4. from pysnmp.hlapi import asyncore as snmpAC
  5. from pysnmp.carrier.asynsock.dispatch import AsynsockDispatcher
  6.  
  7.  
  8. class CmdlineClient(asyncore.file_dispatcher):
  9.     def handle_read(self):
  10.     buf = self.recv(1024)
  11.     print "you said  ".format(buf)
  12.  
  13.  
  14. def myCallback(snmpEngine, sendRequestHandle, errorIndication,
  15.                errorStatus, errorIndex, varBinds, cbCtx):
  16.     print "myCallback!!"
  17.     if errorIndication:
  18.         print(errorIndication)
  19.         return
  20.     if errorStatus:
  21.         print('%s at %s' % (errorStatus.prettyPrint(),
  22.               errorIndex and varBinds[int(errorIndex)-1] or '?')
  23.              )
  24.         return
  25.  
  26.     for oid, val in varBinds:
  27.     if val is None:
  28.         print(oid.prettyPrint())
  29.     else:
  30.         print('%s = %s' % (oid.prettyPrint(), val.prettyPrint()))
  31.  
  32. sharedSocketMap =   
  33. transportDispatcher = AsynsockDispatcher()
  34. transportDispatcher.setSocketMap(sharedSocketMap)
  35. snmpEngine = snmpAC.SnmpEngine()
  36. snmpEngine.registerTransportDispatcher(transportDispatcher)
  37. sharedSocketMap[sys.stdin] = CmdlineClient(sys.stdin)
  38.  
  39. snmpAC.getCmd(
  40.     snmpEngine,
  41.     snmpAC.CommunityData('public'),
  42.     snmpAC.UdpTransportTarget(('127.0.0.1', 161)),
  43.     snmpAC.ContextData(),
  44.     snmpAC.ObjectType(
  45.         snmpAC.ObjectIdentity('SNMPv2-MIB', 'sysDescr', 0)),
  46.     cbFun=myCallback)
  47.  
  48. while True:
  49.     asyncore.poll(timeout=0.5, map=sharedSocketMap)
  50.     if transportDispatcher.jobsArePending() or transportDispatcher.transportsAreWorking():
  51.         transportDispatcher.handleTimerTick(time())
Some interesting lines from the above code: With all this I can handle keyboard presses and network traffic, such as a simple SNMP poll.

13 November 2015

Francois Marier: How Tracking Protection works in Firefox

Firefox 42, which was released last week, introduced a new feature in its Private Browsing mode: tracking protection. If you are interested in how this list is put together and then used in Firefox, this post is for you.

Safe Browsing lists There are many possible ways to download URL lists to the browser and check against that list before loading anything. One of those is already implemented as part of our malware and phishing protection. It uses the Safe Browsing v2.2 protocol. In a nutshell, the way that this works is that each URL on the block list is hashed (using SHA-256) and then that list of hashes is downloaded by Firefox and stored into a data structure on disk:
  • ~/.cache/mozilla/firefox/XXXX/safebrowsing/mozstd-track* on Linux
  • ~/Library/Caches/Firefox/Profiles/XXXX/safebrowsing/mozstd-track* on Mac
  • C:\Users\XXXX\AppData\Local\mozilla\firefox\profiles\XXXX\safebrowsing\mozstd-track* on Windows
This sbdbdump script can be used to extract the hashes contained in these files and will output something like this:
$ ~/sbdbdump/dump.py -v .
- Reading sbstore: mozstd-track-digest256
[mozstd-track-digest256] magic 1231AF3B Version 3 NumAddChunk: 1 NumSubChunk: 0 NumAddPrefix: 0 NumSubPrefix: 0 NumAddComplete: 1696 NumSubComplete: 0
[mozstd-track-digest256] AddChunks: 1445465225
[mozstd-track-digest256] SubChunks:
...
[mozstd-track-digest256] addComplete[chunk:1445465225] e48768b0ce59561e5bc141a52061dd45524e75b66cad7d59dd92e4307625bdc5
...
[mozstd-track-digest256] MD5: 81a8becb0903de19351427b24921a772
The name of the blocklist being dumped here (mozstd-track-digest256) is set in the urlclassifier.trackingTable preference which you can find in about:config. The most important part of the output shown above is the addComplete line which contains a hash that we will see again in a later section.

List lookups Once it's time to load a resource, Firefox hashes the URL, as well as a few variations of it, and then looks for it in the local lists. If there's no match, then the load proceeds. If there's a match, then we do an additional check against a pairwise allowlist. The pairwise allowlist (hardcoded in the urlclassifier.trackingWhitelistTable pref) is designed to encode what we call "entity relationships". The list groups related domains together for the purpose of checking whether a load is first or third party (e.g. twitter.com and twimg.com both belong to the same entity). Entries on this list (named mozstd-trackwhite-digest256) look like this:
twitter.com/?resource=twimg.com
which translates to "if you're on the twitter.com site, then don't block resources from twimg.com. If there's a match on the second list, we don't block the load. It's only when we get a match on the first list and not the second one that we go ahead and cancel the network load. If you visit our test page, you will see tracking protection in action with a shield icon in the URL bar. Opening the developer tool console will expose the URL of the resource that was blocked:
The resource at "https://trackertest.org/tracker.js" was blocked because tracking protection is enabled.

Creating the lists The blocklist is created by Disconnect according to their definition of tracking. The Disconnect list is on their Github page, but the copy we use in Firefox is the copy we have in our own repository. Similarly the Disconnect entity list is from here but our copy is in our repository. Should you wish to be notified of any changes to the lists, you can simply subscribe to this Atom feed. To convert this JSON-formatted list into the binary format needed by the Safe Browsing code, we run a custom list generation script whenever the list changes on GitHub. If you run that script locally using the same configuration as our server stack, you can see the conversion from the original list to the binary hashes. Here's a sample entry from the mozstd-track-digest256.log file:
[m] twimg.com >> twimg.com/
[canonicalized] twimg.com/
[hash] e48768b0ce59561e5bc141a52061dd45524e75b66cad7d59dd92e4307625bdc5
and one from mozstd-trackwhite-digest256.log:
[entity] Twitter >> (canonicalized) twitter.com/?resource=twimg.com, hash a8e9e3456f46dbe49551c7da3860f64393d8f9d96f42b5ae86927722467577df
This in combination with the sbdbdump script mentioned earlier, will allow you to audit the contents of the local lists.

Serving the lists The way that the binary lists are served to Firefox is through a custom server component written by Mozilla: shavar. Every hour, Firefox requests updates from shavar.services.mozilla.com. If new data is available, then the whole list is downloaded again. Otherwise, all it receives in return is an empty 204 response. Should you want to play with it and run your own server, follow the installation instructions and then go into about:config to change these preferences to point to your own instance:
browser.trackingprotection.gethashURL
browser.trackingprotection.updateURL
Note that on Firefox 43 and later, these prefs have been renamed to:
browser.safebrowsing.provider.mozilla.gethashURL
browser.safebrowsing.provider.mozilla.updateURL

Learn more If you want to learn more about how tracking protection works in Firefox, you can find all of the technical details on the Mozilla wiki or you can ask questions on our mailing list. Thanks to Tanvi Vyas for reviewing a draft of this post.

11 November 2015

Kees Cook: evolution of seccomp

I m excited to see other people thinking about userspace-to-kernel attack surface reduction ideas. Theo de Raadt recently published slides describing Pledge. This uses the same ideas that seccomp implements, but with less granularity. While seccomp works at the individual syscall level and in addition to killing processes, it allows for signaling, tracing, and errno spoofing. As de Raadt mentions, Pledge could be implemented with seccomp very easily: libseccomp would just categorize syscalls. I don t really understand the presentation s mention of Optional Security , though. Pledge, like seccomp, is an opt-in feature. Nothing in the kernel refuses to run unpledged programs. I assume his point was that when it gets ubiquitously built into programs (like stack protector), it s effectively not optional (which is alluded to later as comprehensive applicability ~= mandatory mitigation ). Regardless, this sensible (though optional) design gets me back to his slide on seccomp, which seems to have a number of misunderstandings: OpenBSD has some interesting advantages in the syscall filtering department, especially around sockets. Right now, it s hard for Linux syscall filtering to understand why a given socket is being used. Something like SOCK_DNS seems like it could be quite handy. Another nice feature of Pledge is the path whitelist feature. As it s still under development, I hope they expand this to include more things than just paths. Argument inspection is a weak point for seccomp, but under Linux, most of the arguments are ultimately exposed to the LSM layer. Last year I experimented with creating a seccomp LSM for path matching where programs could declare whitelists, similar to standard LSMs. So, yes, Linux could match this API on seccomp . It d just take some extensions to libseccomp to implement pledge(), as I described at the top. With OpenBSD doing a bunch of analysis work on common programs, it d be excellent to see this usable on Linux too. So far on Linux, only a few programs (e.g. Chrome, vsftpd) have bothered to do this using seccomp, and it could be argued that this is ultimately due to how fine grained it is.

2015, Kees Cook. This work is licensed under a Creative Commons Attribution-ShareAlike 3.0 License.
Creative Commons License

Jonathan Dowland: Useful Mac programs

A little over a year ago I wrote about how I'd been using a Mac as my main work machine. I hadn't written anything on the subject since. Here are four useful Mac programs that I can recommend to people. Sizeup, from Irradiated Software. A bit Like Windows' aero snap, but on steroids. I love this. I regularly move windows between two desktops (external and internal display), resize and centre them or put them in one quarter of the screen with just a few presses. The "snapback" feature is also great. X Lossless Decoder (XLD). A handy transcoder that can use QuickTime encoders and so can write out Apple/Quicktime/iTunes-encoded AAC/MP4 files en-mass, translating file meta-data.
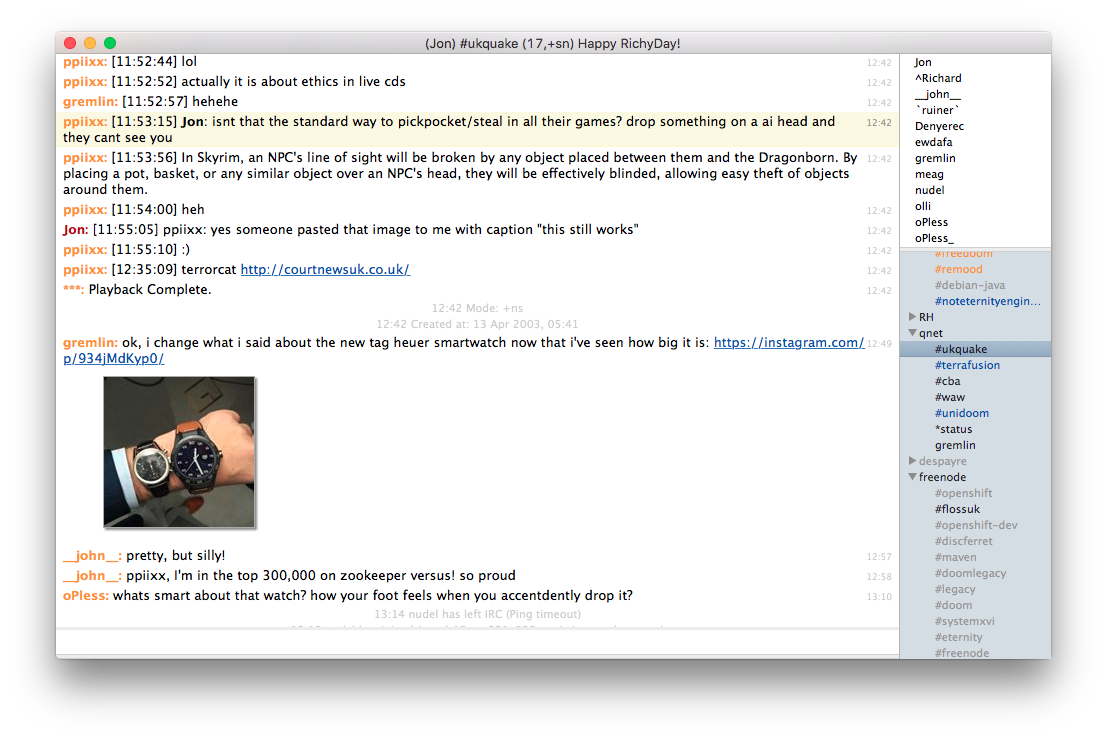
LimeChat LimeChat
LimeChat, an IRC client. I theme it to look like Colloquy. The net result is pretty clean. I like using a proportional-font for text things, so getting IRC out of a terminal is a win for me. LimeChat automatically fetches and thumbnails URIs to images that people paste in channels, which is either incredibly convenient or a curse, depending on the channel. You can toggle that behaviour but only across the whole client, not on a channel or network basis. Finally, 1Password is an incredibly slick password manager. I use it in a very basic fashion: no mobile client, no syncing to anything outside of my workstation. You could also use LastPass which is similar and has a Linux client. I haven't tried it, but there's a third party tool to read 1Password password stores on Linux written by Ryan Coleman of SDL fame called 1pass.

10 November 2015

Jaldhar Vyas: Happy Diwali and Sal Mubarak 2072

Wishing you all a happy Diwali and Gujarati New Year (V.S. 2072 called Plavanga.)Instead of being something sane like a flat disk supported by four elephants standing on a tortoise, the Earth is an oblate spheroid in heliocentric orbit. The Moon too offends by maintaining an unreasonably non-epicyclic orbit. Combined this means that the Americas (plus Iceland if there any Hindus there) observe Diwali today whereas in India and the rest of the world it is tomorrow. Technically in these longitudes the Ashvayuja amavasya tithi pervades both Tuesday and Wednesday but as Lakshmi Puja takes place at the pradosha kala it means it should be celebrated today though no doubt most of the non-astronomically minded people will just follow India any way. The New Year is on Thursday all over the world.Regardless of when you celebrate, may your year be full of happiness, good fortune and prosperity.

Daniel Pocock: Aggregating tasks from multiple issue trackers

After my experiments with the iCalendar format at the beginning of 2015, including Bugzilla feeds from Fedora and reSIProcate, aggregating tasks from the Debian Maintainer Dashboard, Github issue lists and even unresolved Nagios alerts, I decided this was fertile ground for a GSoC student. In my initial experiments, I tried using the Mozilla Lightning plugin (Iceowl-extension on Debian/Ubuntu) and GNOME Evolution's task manager. Setting up the different feeds in these clients is not hard, but they have some rough edges. For example, Mozilla Lightning doesn't tell you if a feed is not responding, this can be troublesome if the Nagios server goes down, no alerts are visible, so you assume all is fine. To take things further, Iain Learmonth and I proposed a GSoC project for a student to experiment with the concept. Harsh Daftary from Mumbai, India was selected to work on it. Over the summer, he developed a web application to pull together issue, task and calendar feeds from different sources and render them as a single web page. Harsh presented his work at DebConf15 in Heidelberg, Germany, the video is available here. The source code is in a Github repository. The code is currently running as a service at horizon.debian.net although it is not specific to Debian and is probably helpful for any developer who works with more than one issue tracker.

9 November 2015

Ben Armstrong: The passing of Debian Live

Debian Live has passed on. And it has done so in not happy circumstances. (You can search the list archives for more if you are confused.) I have reposted here my response to this one thread because it s all I really want to say, after all of the years of working with the team. I d like to add as a postscript, that while the focus of this article was to remain positive in the face of Daniel s announcement of the closure of his project, that event has left a lot of users confused about the status of live support in Debian going forward. Read my posts here and here addressing that confusion.
On 09/11/15 12:47 PM, Daniel Baumann wrote:
> So long, and thanks for all the fish[7].
>
> Daniel
>
> [7] http://live.debian.net/project/downstream/ Enough bitter words have been said. I don t want to add any more. So: I m proud. Indeed, that long list of downstreams does speak to the impact you ve had in inspiring and equipping people to make their own live images. I m proud to have been a small part of this project. I m thankful. I m thankful that I was able to, through this project, contribute to something for a while that had a positive impact on many people, and made Debian more awesome. I remember the good times. I remember fondly the good times we had in the project s heyday. I certainly found your enthusiasm and vision for the project, Daniel, personally inspiring. It motivated me to contribute. Debconf10 was a highlight among those experiences, but also I had many good times and made many friendships online, too. I m sad. I m sad, because although I made some attempts to liaise between Debian Live and the CD and Installer teams, I don t feel I did an effective job there, and that contributed to the situation we now find ourselves in. If I did you or the project injury in trying to fulfill that role, please forgive me. I m hopeful. I m hopeful that whichever way we all go from here, that the bitterness will not be forever. That we ll heal. That we ll have learned. That we ll move on to accomplish new things, bigger and better things. Thank you, Daniel. Thank you, Debian Live team. Ben
facebooktwittergoogle_plusredditpinterestlinkedinmail

Next.

Previous.