Search Results: "ron"

6 November 2016

Russell Coker: Is a Thinkpad Still Like a Rolls-Royce

For a long time the Thinkpad has been widely regarded as the Rolls-Royce of laptops . Since 2003 one could argue that Rolls-Royce is no longer the Rolls-Royce of cars [1]. The way that IBM sold the Think business unit to Lenovo and the way that Lenovo is producing both Thinkpads and cheaper Ideapads is somewhat similar to the way the Rolls-Royce trademark and car company were separately sold to companies that are known for making cheaper cars. Sam Varghese has written about his experience with Thinkpads and how he thinks it s no longer the Rolls-Royce of laptops [2]. Sam makes some reasonable points to support this claim (one of which only applies to touchpad users not people like me who prefer the Trackpoint), but I think that the real issue is whether it s desirable to have a laptop that could be compared to a Rolls-Royce nowadays. Support The Rolls-Royce car company is known for great reliability and support as well as features that other cars lack (mostly luxury features). The Thinkpad marque (both before and after it was sold to Lenovo) was also known for great support. You could take a Thinkpad to any service center anywhere in the world and if the serial number indicated that it was within the warranty period it would be repaired without any need for paperwork. The Thinkpad service centers never had any issue with repairing a Thinkpad that lacked a hard drive just as long as the problem could be demonstrated. It was also possible to purchase an extended support contract at any time which covered all repairs including motherboard replacement. I know that not everyone had as good an experience as I had with Thinkpad support, but I ve been using them since 1998 without problems which is more than I can say for most hardware. Do we really need great reliability from laptops nowadays? When I first got a laptop hardly anyone I knew owned one. Nowadays laptops are common. Having a copy of important documents on a USB stick is often a good substitute for a reliable laptop, when you are in an environment where most people own laptops it s usually not difficult to find someone who will let you use theirs for a while. I think that there is a place for a laptop with RAID-1 and ECC RAM, it s a little known fact that Thinkpads have a long history of supporting the replacement of a CD/DVD drive with a second hard drive (I don t know if this is still supported) but AFAIK they have never supported ECC RAM. My first Thinkpad cost $3,800. In modern money that would be something like $7,000 or more. For that price you really want something that s well supported to protect the valuable asset. Sam complains about his new Thinkpad costing more than $1000 and needing to be replaced after 2.5 years. Mobile phones start at about $600 for the more desirable models (IE anything that runs Pokemon Go) and the new Google Pixel phones range from $1079 to $1,419. Phones aren t really expected to be used for more than 2.5 years. Phones are usually impractical to service in any way so for most of the people who read my blog (who tend to buy the more expensive hardware) they are pretty much a disposable item costing $600+. I previously wrote about a failed Nexus 5 and the financial calculations for self-insuring an expensive phone [3]. I think there s no way that a company can provide extended support/warranty while making a profit and offering a deal that s good value to customers who can afford to self-insure. The same applies for the $499 Lenovo Ideapad 310 and other cheaper Lenovo products. Thinkpads (the higher end of the Lenovo laptop range) are slightly more expensive than the most expensive phones but they also offer more potential for the user to service them. Features My first Thinkpad was quite underpowered when compared to desktop PCs, it had 32M of RAM and could only be expanded to 96M at a time when desktop PCs could be expanded to 128M easily and 256M with some expense. It had a 800*600 display when my desktop display was 1280*1024 (37% of the pixels). Nowadays laptops usually start at about 8G of RAM (with a small minority that have 4G) and laptop displays start at about 1366*768 resolution (51% of the pixels in a FullHD display). That compares well to desktop systems and also is capable of running most things well. My current Thinkpad is a T420 with 8G of RAM and a 1600*900 display (69% of FullHD), it would be nice to have higher resolution but this works well and it was going cheap when I needed a new laptop. Modern Thinkpads don t have some of the significant features that older ones had. The legendary Butterfly Keyboard is long gone, killed by the wide displays that economies of scale and 16:9 movies have forced upon us. It s been a long time since Thinkpads had some of the highest resolution displays and since anyone really cared about it (you only need pixels to be small enough that you can t see them). For me one of the noteworthy features of the Thinkpads has been the great keyboard. Mechanical keys that feel like a desktop keyboard. It seems that most Thinkpads are getting the rubbery keyboard design made popular by Apple. I guess this is due to engineering factors in designing thin laptops and the fact that most users don t care. Matthew Garrett has blogged about the issue of Thinkpad storage configured as RAID mode without any option to disable it [4]. This is an annoyance (which incidentally has been worked around) and there are probably other annoyances like it. Designing hardware and an OS are both complex tasks. The interaction between Windows and the hardware is difficult to get right from both sides and the people who design the hardware often don t think much about Linux support. It has always been this way, the early Thinkpads had no Linux support for special IBM features (like fan control) and support for ISA-PnP was patchy. It is disappointing that Lenovo doesn t put a little extra effort into making sure that Linux works well on their hardware and this might be a reason for considering another brand. Service Life I bought my curent Thinkpad T420 in October 2013 [5] It s more than 3 years old and has no problems even though I bought it refurbished with a reduced warranty. This is probably the longest I ve had a Thinkpad working well, which seems to be a data point against the case that modern Thinkpads aren t as good. I bought a T61 in February 2010 [6], it started working again (after mysteriously not working for a month in late 2013) and apart from the battery lasting 5 minutes and a CPU cooling problem it still works well. If that Thinkpad had cost $3,800 then I would have got it repaired, but as it cost $796 (plus the cost of a RAM upgrade) and a better one was available for $300 it wasn t worth repairing. In the period 1998 to 2010 I bought a 385XD, a 600E, a T21, a T43, and a T61 [6]. During that time I upgraded laptops 4 times in 12 years (I don t have good records of when I bought each one). So my average Thinkpad has lasted 3 years. The first 2 were replaced to get better performance, the 3rd was replaced when an employer assigned me a Thinkpad (and sold it to be when I left), and 4 and 5 were replaced due to hardware problems that could not be fixed economically given the low cost of replacement. Conclusion Thinkpads possibly don t have the benefits over other brands that they used to have. But in terms of providing value for the users it seems that they are much better than they used to be. Until I wrote this post I didn t realise that I ve broken a personal record for owning a laptop. It just keeps working and I hadn t even bothered looking into the issue. For some devices I track how long I ve owned them while thinking can I justify replacing it yet , but the T420 just does everything I want. The battery still lasts 2+ hours which is a new record too, with every other Thinkpad I ve owned the battery life has dropped to well under an hour within a year of purchase. If I replaced this Thinkpad T420 now it will have cost me less than $100 per year (or $140 per year including the new SSD I installed this year), that s about 3 times better than any previous laptop! I wouldn t feel bad about replacing it as I ve definitely got great value for money from it. But I won t replace it as it s doing everything I want. I ve just realised that by every measure (price, reliability, and ability to run all software I want to run) I ve got the best Thinkpad I ve ever had. Maybe it s not like a Rolls-Royce, but I d much rather drive a 2016 Tesla than a 1980 Rolls-Royce anyway.

5 November 2016

Russ Allbery: Review: The Just City

Review: The Just City, by Jo Walton
Series: Thessaly #1
Publisher: Tor
Copyright: 2014
Printing: January 2015
ISBN: 0-7653-3266-3
Format: Hardcover
Pages: 368
The premise for The Just City is easy to state: The time-traveling goddess Athene (Athena) decides to organize and aid an attempt to create the society described in Plato's Republic. She chooses Thera (modern Santorini) before the eruption, as a safe place where this experiment wouldn't alter history. The elders of the city are seeded by people throughout history who at some point prayed to Athene, wanting to live in the Republic. The children of the age of ten that Plato suggested starting with are purchased as slaves from various points in history and transported by Athene to the island. Apollo, shaken and confused by Daphne wanting to turn into a tree rather than sleep with him, finds out about this experiment as Athene tries to explain the concept of consent to him. He decides that becoming human for a while might help him learn about volition and equal significance, and that this is the perfect location. He's one of the three viewpoint characters. The others are two women: one (Maia) from Victorian times who prayed to Athene in a moment of longing for the tentative sexual equality of the Republic and was recruited as one of the elders, and another (Simmea) who is bought as a slave and becomes one of the children. I should admit up-front that I've never read Plato's Republic, or indeed much of Plato at all, just small bits for classes. The elders (and of course the gods) all have, and are attempting to stick quite closely to Plato's outline of the ideal city. The children haven't, though, so the book is quite readable for people like me who only remember a few vague aspects of Plato's vision from school. The reader learns the principles alongside Simmea. One of Walton's strengths is taking a science fiction concept, putting real people into it, and letting the quotidian mingle with the fantastic. Simmea is my favorite character here: her journey to the city is deeply traumatic, but the opportunity she gets there is incredible and unforeseen, and she comes to love the city while still understanding, and arguing about, its possible flaws. Maia is nearly as successful; Walton does a good job with committee debates and discussions, avoids coming down too heavily on the drama, and shows a believable picture of people with very different backgrounds and beliefs coming together to flesh out the outlines of something they all agree with, or at least want to try. I found Apollo less engaging as a character, partly because I never quite understood his motives or his weird failure to understand the principles of consent. Walton doesn't portray him as either hopelessly arrogant or hopelessly narcissistic, which would have been easy outs, but in avoiding those two obvious explanations for his failures of empathy, I felt like she left him with an odd and unexplained hole in his personality. He's a weirdly passive half-character for much of the book, although he does develop a bit more towards the end (which was probably the point). Half the fun of this book is working out what the Republic would be like in practice, and what breakdowns and compromises would happen as soon as you put real people in it. Athene obviously has to do a bit of cheating to make a utopia invented as an intellectual exercise work out in practice, plus a bit more for comfort (electricity and indoor plumbing, for instance). The most substantial cheat is robots to replace slaves and do quite a bit that slaves couldn't. Birth control (something Plato obviously never would have thought of) is another notable cheat; it's postulated to be an ancient method since lost, but even if that existed, there's no way it would be this reliable. But otherwise, the society mostly works, and Walton shows enough of the arguing and mechanics to make that believable, while still avoiding infodumps and boring descriptions. It's neatly done, although I'm still a bit dubious that the elders from later eras would have put up with the primitive conditions with this little complaint. The novel needs a plot, of course, and that's the other half of the fun. I can't talk about this in any detail without spoiling the book, since the plot only kicks in about halfway through once the setup and character introductions are complete. That makes it hard to explain why I found this a bit less successful, although parts of it are brilliant. What worked for me is the growth of Simmea and her friends as students and philosophers, the arguments and discussions (and their growing enthusiasm for argument and discussion), and the way Greek mythology is woven subtly and undramatically into the story. It really does feel like sitting in on ancient Greek philosophical arguments and experiments, and by that measure Walton has succeeded admirably in her goal. What didn't work for me was the driving conflict of the story, once it's introduced. I can't describe it without spoilers, but it's an old trope in science fiction and one with little scientific basis. It may seem weird to argue that point in a book with time-traveling Greek gods, a literal Lethe, and a Greek idea of souls, but those are mythological background material. The SF trope is something about which I have personal expertise and which simply doesn't work that way, and I had a harder time getting past that than alternate metaphysical properties. It threw me out of the book a bit. I see why Walton chose the conflict she did, but I felt like she could have gotten to the same place in the plot, admittedly with more difficulty, by using some of the more dubious aspects of Plato's long-term plan plus some other obstacles that were already built into the world. This more direct approach added a bit of SF-style analysis of the unknown that seemed weirdly at odds with the rest of the story (even if the delight of one of the characters is endearing). That complaint aside, I really enjoyed reading this book. Apollo didn't entirely work for me, but all of the other characters are excellent, and Walton keeps the story moving at a comfortable clip. Given the amount of description required, particularly for an audience that may not have read the Republic, a lesser writer could have easily slipped into the infodump trap. Walton never does. Fair warning, though: The Just City does end on a cliffhanger, and is in no way a standalone novel. You will probably want to have the sequel on hand. Followed by The Philosopher Kings. Rating: 7 out of 10

Russ Allbery: Fall haul post

It's been a while since I've done one of these. danah boyd It's Complicated (non-fiction)
Jeffrey A. Carver Eternity's End (sff)
Becky Chambers A Closed and Common Orbit (sff)
Stephen Deas The Adamantine Palace (sff)
Robert Heinlein The Green Hills of Earth / The Menace from Earth (sff)
Robert Heinlein Revolt in 2100 / Methuselah's Children (sff)
Marjorie M. Liu The Iron Hunt (sff)
Larry Niven The Ringworld Engineers (sff)
Don Norman The Design of Everyday Things (non-fiction)
Kurt Vonnegut Slaughterhouse-Five (sff)
Jo Walton Necessity (sff)
Eileen Wilks Tempting Danger (sff) I picked up some extra used books since I was placing a book order to pick up Necessity anyway, and fleshed out my early Heinlein novels mostly out of curiousity. I've already reviewed The Design of Everyday Things, which I got from the work book club.

Clint Adams: TWO EVERETT MEN, FIVE I. W. W. DEAD; FIFTY WOUNDED

Two Everett citizens were killed and a score wounded, several seriously, this afternoon when the steamer Verona drew up to the City dock and attempted to land its crowd of almost 200 I. W. W. Sheriff McRae tried to parley with them. A shot was fired from the boat at the sheriff and a general battle followed. The Verona backed away from the wharf and returned to Seattle. On arrival there the I.W.W. crowd was arrested, five were found to be dead and about 30 wounded.

3 November 2016

Iain R. Learmonth: PATHspider Plugins

This post is cross-posted on the MAMI Project blog here. In today s Internet we see an increasing deployment of middleboxes. While middleboxes provide in-network functionality that is necessary to keep networks manageable and economically viable, any packet mangling whether essential for the needed functionality or accidental as an unwanted side effect makes it more and more difficult to deploy new protocols or extensions of existing protocols. For the evolution of the protocol stack, it is important to know which network impairments exist and potentially need to be worked around. While classical network measurement tools are often focused on absolute performance values, PATHspider performs A/B testing between two different protocols or different protocol extensions to perform controlled experiments of protocol-dependent connectivity problems as well as differential treatment. PATHspider 1.0.1 has been released today and is now available from GitHub, PyPI and Debian unstable. This is a small stable update containing a documentation fix for the example plugin. PATHspider now contains 3 built-in plugins for measuring path transparency to explicit congestion notification, DiffServ code points and TCP Fast Open. It s easy to write your own plugins, and if they re good enough, they may be included in the PATHspider distribution at the next feature release. We have a GitHub repository you can fork that has a premade directory structure for new plugins. You ll need to implement logic for performing the two connections, for the A and the B tests. Once you ve verified your connection logic is working with Wireshark, you can move on to writing Observer functions to analyse the connections made in real time as PATHspider runs. The final step is to merge the results of the connection logic (e.g. did the operating system report a timeout?) with the results of your observer functions (e.g. was ECN successfully negotiated?) and write out the final result. We have dedicated a section of the manual to the development of plugins and we really see plugins as first-class citizens in the PATHspider ecosystem. While future releases of PATHspider may contain new plugins, we re also making it easier to write plugins by providing reusable library functions such as the tcp_connect() function of the SynchronisedSpider that allows for easy A/B testing of TCP connections with any globally configured state set. We also provide reusable observer functions for simple tasks such as determining if a 3-way handshake completed or if there was an ICMP unreachable message received.
If you d like to check out PATHspider, you can find the website at https://pathspider.net/. Current development of PATHspider is supported by the European Union s Horizon 2020 project MAMI. This project has received funding from the European Union s Horizon 2020 research and innovation programme under grant agreement No 688421. The opinions expressed and arguments employed reflect only the authors view. The European Commission is not responsible for any use that may be made of that information.

Simon Josefsson: Why I don t Use 2048 or 4096 RSA Key Sizes

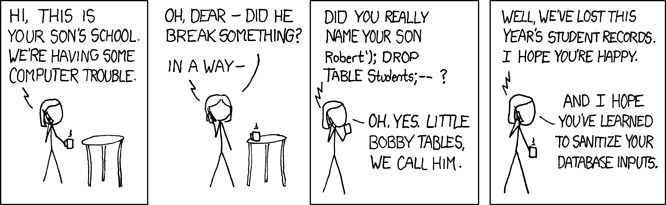
I have used non-standard RSA key size for maybe 15 years. For example, my old OpenPGP key created in 2002. With non-standard key sizes, I mean a RSA key size that is not 2048 or 4096. I do this when I generate OpenPGP/SSH keys (using GnuPG with a smartcard like this) and PKIX certificates (using GnuTLS or OpenSSL, e.g. for XMPP or for HTTPS). People sometimes ask me why. I haven t seen anyone talk about this, or provide a writeup, that is consistent with my views. So I wanted to write about my motivation, so that it is easy for me to refer to, and hopefully to inspire others to think similarily. Or to provoke discussion and disagreement that s fine, and hopefully I will learn something. Before proceeding, here is some context: When building new things, it is usually better to use the Elliptic Curve technology algorithm Ed25519 instead of RSA. There is also ECDSA which has had a comparatively slow uptake, for a number of reasons that is widely available and is a reasonable choice when Ed25519 is not available. There are also post-quantum algorithms, but they are newer and adopting them today requires a careful cost-benefit analysis. First some background. RSA is an asymmetric public-key scheme, and relies on generating private keys which are the product of distinct prime numbers (typically two). The size of the resulting product, called the modulus n, is usually expressed in bit length and forms the key size. Historically RSA key sizes used to be a couple of hundred bits, then 512 bits settled as a commonly used size. With better understanding of RSA security levels, the common key size evolved into 768, 1024, and later 2048. Today s recommendations (see keylength.com) suggest that 2048 is on the weak side for long-term keys (5+ years), so there has been a trend to jump to 4096. The performance of RSA private-key operations starts to suffer at 4096, and the bandwidth requirements is causing issues in some protocols. Today 2048 and 4096 are the most common choices. My preference for non-2048/4096 RSA key sizes is based on the simple and na ve observation that if I would build a RSA key cracker, there is some likelihood that I would need to optimize the implementation for a particular key size in order to get good performance. Since 2048 and 4096 are dominant today, and 1024 were dominent some years ago, it may be feasible to build optimized versions for these three key sizes. My observation is a conservative decision based on speculation, and speculation on several levels. First I assume that there is an attack on RSA that we don t know about. Then I assume that this attack is not as efficient for some key sizes than others, either on a theoretical level, at implementation level (optimized libraries for certain characteristics), or at an economic/human level (decision to focus on common key sizes). Then I assume that by avoiding the efficient key sizes I can increase the difficulty to a sufficient level. Before analyzing whether those assumptions even remotely may make sense, it is useful to understand what is lost by selecting uncommon key sizes. This is to understand the cost of the trade-off. A significant burden would be if implementations didn t allow selecting unusual key sizes. In my experience, enough common applications support uncommon key sizes, for example GnuPG, OpenSSL, OpenSSH, FireFox, and Chrome. Some applications limit the permitted choices; this appears to be rare, but I have encountered it once. Some environments also restrict permitted choices, for example I have experienced that LetsEncrypt has introduced a requirement for RSA key sizes to be a multiples of 8. I noticed this since I chose a RSA key size of 3925 for my blog and received a certificate from LetsEncrypt in December 2015 however during renewal in 2016 it lead to an error message about the RSA key size. Some commercial CAs that I have used before restrict the RSA key size to one of 1024, 2048 or 4096 only. Some smart-cards also restrict the key sizes, sadly the YubiKey has this limitation. So it is not always possible, but possible often enough for me to be worthwhile. Another cost is that RSA signature operations are slowed down. This is because the exponentiation function is faster than multiplication, and if the bit pattern of the RSA key is a 1 followed by several 0 s, it is quicker to compute. I have not done benchmarks, but I have not experienced that this is a practical problem for me. I don t notice RSA operations in the flurry of all of other operations (network, IO) that is usually involved in my daily life. Deploying this on a large scale may have effects, of course, so benchmarks would be interesting. Back to the speculation that leads me to this choice. The first assumption is that there is an attack on RSA that we don t know about. In my mind, until there are proofs that the currently known attacks (GNFS-based attacks) are the best that can be found, or at least some heuristic argument that we can t do better than the current attacks, the probability for an unknown RSA attack is therefor, as strange as it may sound, 100%. The second assumption is that the unknown attack(s) are not as efficient for some key sizes than others. That statement can also be expressed like this: the cost to mount the attack is higher for some key sizes compared to others. At the implementation level, it seems reasonable to assume that implementing a RSA cracker for arbitrary key sizes could be more difficult and costlier than focusing on particular key sizes. Focusing on some key sizes allows optimization and less complex code. At the mathematical level, the assumption that the attack would be costlier for certain types of RSA key sizes appears dubious. It depends on the kind of algorithm the unknown attack is. For something similar to GNFS attacks, I believe the same algorithm applies equally for a RSA key size of 2048, 2730 and 4096 and that the running time depends mostly on the key size. Other algorithms that could crack RSA, such as some approximation algorithms, does not seem likely to be thwarted by using non-standard RSA key sizes either. I am not a mathematician though. At the economical or human level, it seems reasonable to say that if you can crack 95% of all keys out there (sizes 1024, 2048, 4096) then that is good enough and cracking the last 5% is just diminishing returns of the investment. Here I am making up the 95% number. Currently, I would guess that more than 95% of all RSA key sizes on the Internet are 1024, 2048 or 4096 though. So this aspect holds as long as people behave as they have done. The final assumption is that by using non-standard key sizes I raise the bar sufficiently high to make an attack impossible. To be honest, this scenario appears unlikely. However it might increase the cost somewhat, by a factor or two or five. Which might make someone target a lower hanging fruit instead. Putting my argument together, I have 1) identified some downsides of using non-standard RSA Key sizes and discussed their costs and implications, and 2) mentioned some speculative upsides of using non-standard key sizes. I am not aware of any argument that the odds of my speculation is 0% likely to be true. It appears there is some remote chance, higher than 0%, that my speculation is true. Therefor, my personal conservative approach is to hedge against this unlikely, but still possible, attack scenario by paying the moderate cost to use non-standard RSA key sizes. Of course, the QA engineer in me also likes to break things by not doing what everyone else does, so I end this with an ObXKCD.
Guido G nther: Debian Fun in October 2016

Debian LTS October marked the eighteenth month I contributed to Debian LTS under the Freexian umbrella. I spent 10 hours (out of allocated 9) Other Debian stuff Some other Free Software activities

Jan Wagner: Container Orchestration Thoughts

Container Orchestration ThoughtsSince some time everybody (read developer) want to run his new microservice stacks in containers. I can understand that building and testing an application is important for developers.
One of the benefits of containers is, that developer (in theory) can put their new version of applications into production on their own. This is the point where operations is affected and operations needs to evaluate, if that might evolve into better workflow. For yolo^WdevOps people there are some challenges that needs to be solved, or at least mitigated, when things needs to be done in large(r) scale.

Orchestration Engine Running Docker, which is actual the most preferred container solution, on a single host with docker command line client is something you can do, but there you leave the gap between dev and ops.

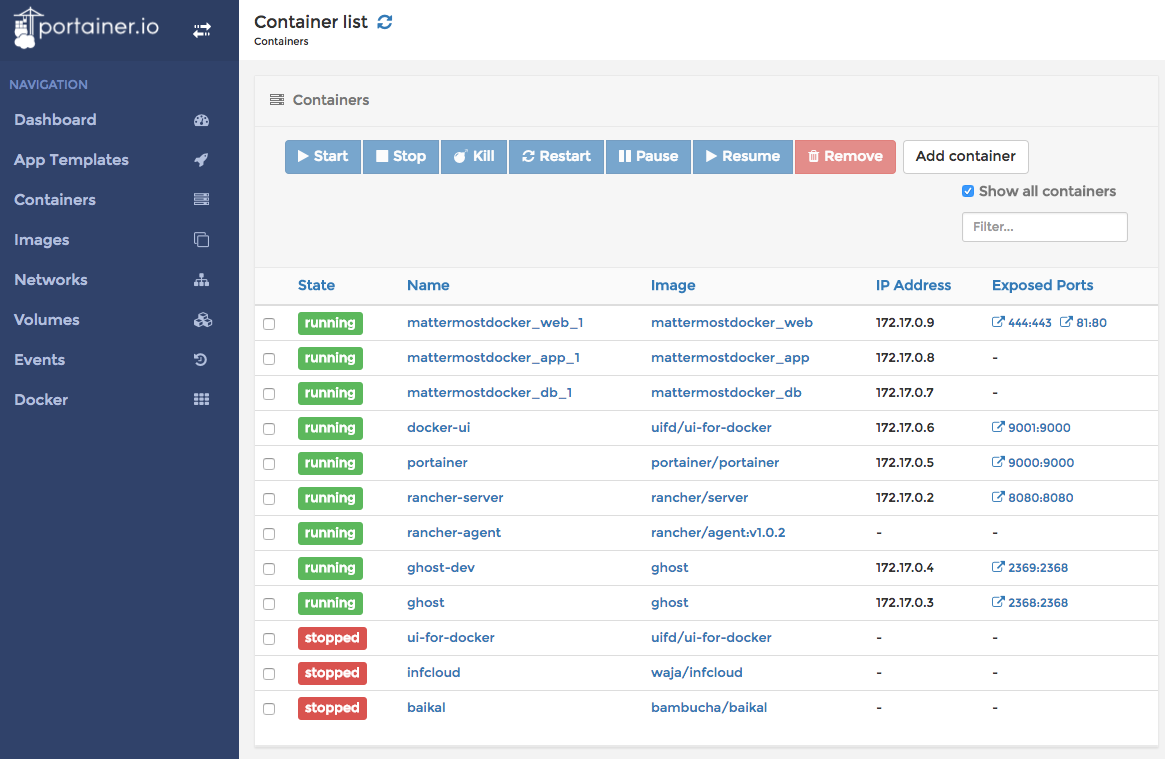
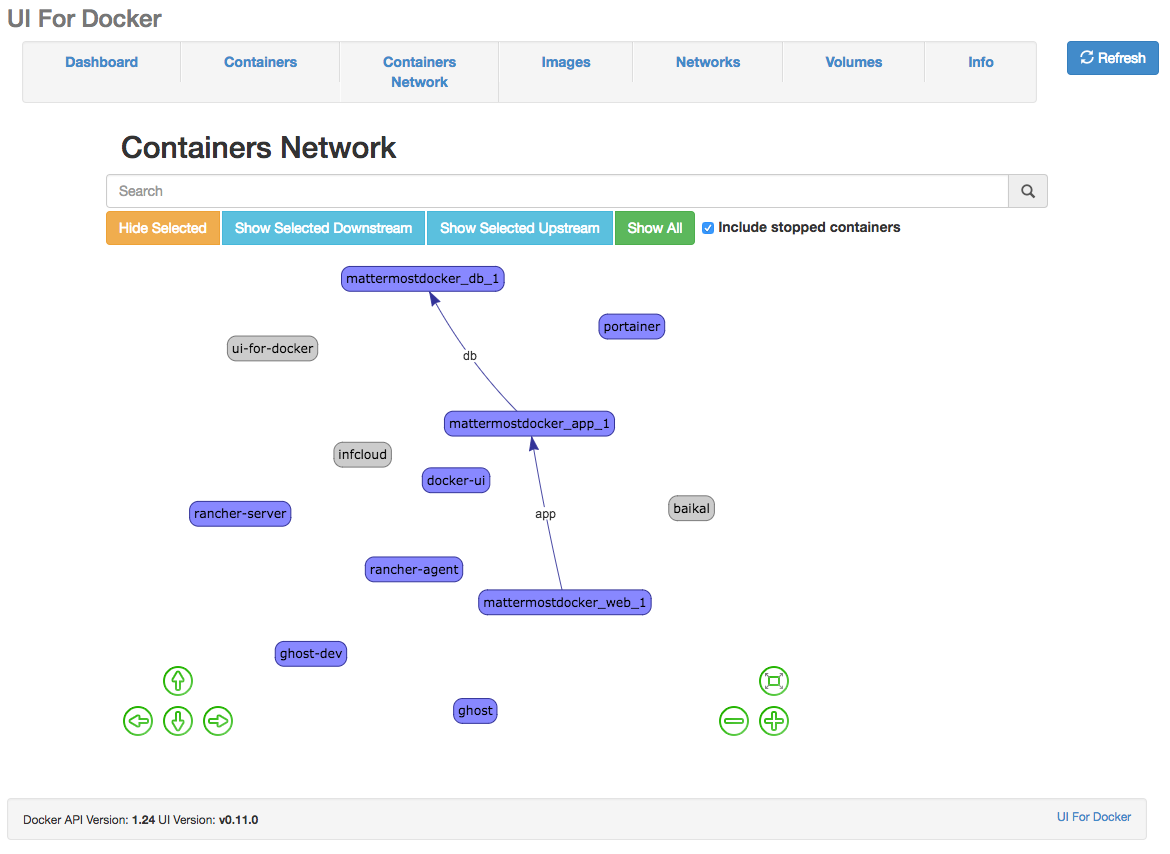
UI For Docker Since some time there is UI For Docker available for visualizing and managing containers on a single docker node. It's pretty awesome and the best feature so far is the Container Network view, which also shows the linked container. Container Orchestration Thoughts

Portainer Portainer is pretty new and it can be deployed as easy as UI For Docker. But the (first) great advantage: it can handle Docker Swarm. Beside that it has many other great features. Container Orchestration Thoughts

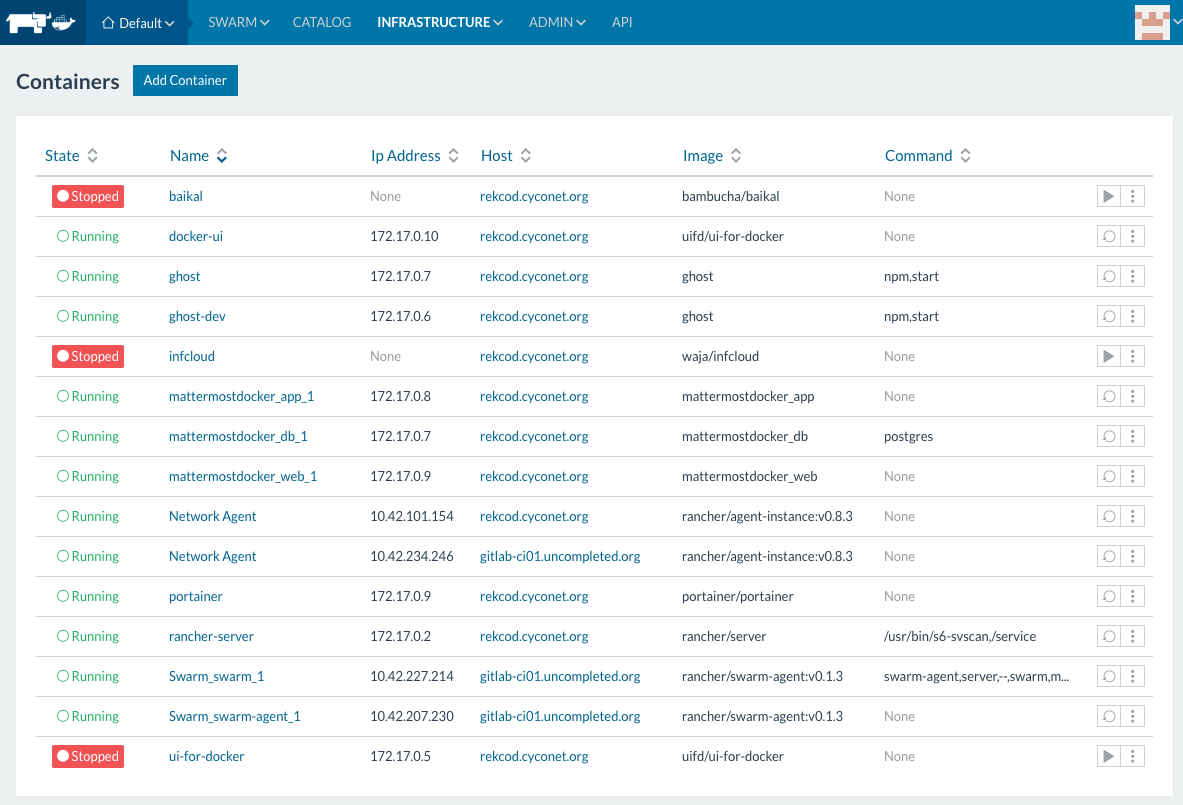
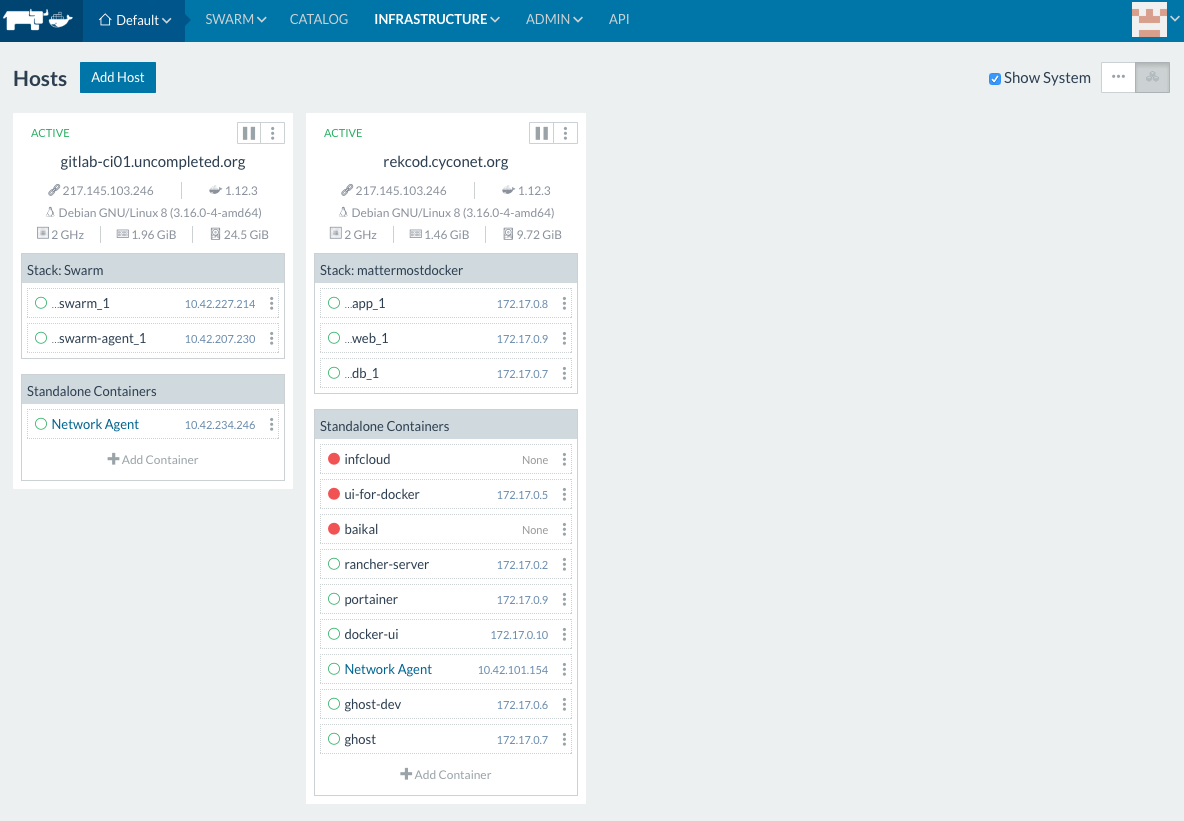
Rancher Rancher describes themselves as 'container management platform' that 'supports and manages all of your Kubernetes, Mesos, and Swarm clusters'. This is great because this are all of the relevant docker cluster orchestrations at the market actually. Container Orchestration Thoughts For the use cases, we are facing, Kubernetes and Mesos seems both like bloated beasts. Usman Ismail has written a really good comparison of Orchestration Engine options which goes into details. Container Orchestration Thoughts

Docker Swarm As there is actually no clear defacto standard/winner of the (container) orchestration wars, I would prevent to be in a vendor lock-in situation (yet). Docker swarm seems to be evolving and is getting more nice features other competitors doesn't provide.
Due the native integration into the docker framework and great community I believe Docker Swarm will be the Docker Orchestration of the choice on the long run. This should be supported by Rancher 1.2 which is not released yet.
From this point of view it looks very reasonable that Docker Swarm in combination with Rancher (1.2) might be a good strategy to maintain your container farms in the future. If you think to put Docker Swarm into production in the actual state, I recommend to read Docker swarm mode: What to know before going live on production by Panjamapong Sermsawatsri.

Persistent Storage While it is a best practice to use data volume container these days, providing persistent storage across multiple hosts for shared volumes seems to be tricky. In theory you can mount a shared-storage volume as a data volume and there are several volume plugins which supports shared storage. For example you can use the convoy plugin which gives you:
  • thin provisioned volumes
  • snapshots of volumes
  • backup of snapshots
  • restore volumes
As backend you can use:
  • Device Mapper
  • Virtual File System(VFS)/Network File System(NFS)
  • Amazon Elastic Block Store(EBS)
The good thing is, that convoy is integrated into Rancher. For more information I suggest to read Setting Up Shared Volumes with Convoy-NFS, which also mentions some limitations. If you want test Persistent Storage Service, Rancher provides some documentation. Actually I did not evaluate shared-storage volumes yet, but I don't see a solution I would love to use in production (at least on-premise) without strong downsides. But maybe things will go further and there might be a great solution for this caveats in the future.

Keeping base images up-to-date Since some time there are many projects that tries to detect security problems in your container images in several ways.
Beside general security considerations you need to deal somehow with issues in your base images that you build your applications on. Of course, even if you know you have a security issue in your application image, you need to fix it, which depends on the way how you based your application upon.

Ways to base your application image
  • You can build your application image entire from scratch, which leaves all the work to your development team and I wouldn't recommend it that way.
  • You also can create one (or more) intermediate image(s) that will be used by your development team.
  • The development team might ground their work on images in public available or private (for example the one bundled to your gitlab CI/CD solution) registries.

Whats the struggle with the base image? If you are using images being not (well) maintained by other people, you have to wait for them to fix your base image. Using external images might also lead into trust problems (can you trust those people in general?).
In an ideal world, your developers have always fresh base images with fixed security issues. This can probably be done by rebuilding every intermediate image periodically or when the base image changes.

Paradigm change Anyway, if you have a new application image available (with no known security issues), you need to deploy it to production. This is summarized by Jason McKay in his article Docker Security: How to Monitor and Patch Containers in the Cloud:
To implement a patch, update the base image and then rebuild the application image. This will require systems and development teams to work closely together.
So patching security issues in the container world changes workflow significant. In the old world operation teams mostly rolled security fixes for the base systems independent from development teams.
Now hitting containers the production area this might change things significant.

Bringing updated images to production Imagine your development team doesn't work steady on a project, cause the product owner consider it feature complete. The base image is provided (in some way) consistently without security issues. The application image is build on top of that automatically on every update of the base image.
How do you push in such a scenario the security fixes to production? From my point of view you have two choices:
  • Let the development team require to test the resulting application image and put it into production
  • Push the new application image without review by the development team into production
The first scenario might lead into a significant delay until the fixes hit production created by the probably infrequent work of the development team. The latter one brings your security fixes early to production by the notable higher risk to break your application. This risk can be reduced by implementing massive tests into CI/CD pipelines by the development team. Rolling updates provided by Docker Swarm might also reduce the risk of ending with a broken application. When you are implementing an update process of your (application) images to production, you should consider Watchtower that provides Automatic Updates for Docker Containers.

Conclusion Not being a product owner or the operations part of an application that is facing a widely adopted usage that would compensate the actual tradeoffs we are still facing I tend not to move large scale production projects into a container environment.
This means not that this might be a bad idea for others, but I'd like to sort out some of the caveats before. I'm still interested to put smaller projects into production, being not scared to reimplement or move them on a new stack.
For smaller projects with a small number of hosts Portainer looks not bad as well as Rancher with the Cattle orchestration engine if you just want to manage a couple of nodes. Things are going to be interesting if Rancher 1.2 supports Docker swarm cluster out of the box. Let's see what the future will bring us to the container world and how to make a great stack out of it.

Update I suggest to read Docker in Production: A History of Failure and the answer Docker in Production: A retort to understand the actual challenges when running Docker in larger scale production environments.

2 November 2016

Reproducible builds folks: Reproducible Builds: week 79 in Stretch cycle

What happened in the Reproducible Builds effort between Sunday October 23 and Saturday October 29 2016: Upcoming events The second Reproducible Builds World Summit will be held from December 13th-15th in Berlin! See the link for more details. Other events: Introduction to Reproducible Builds - Vagrant Cascadian will be presenting at the SeaGL.org Conference In Seattle, USA on November 12th, 2016. Reproducible Debian Hackathon - A small hackathon organized in Boston, USA on December 3rd and 4th. If you are interested in attending, contact Valerie Young - spectranaut in the #debian-reproducible IRC channel on irc.oftc.net. IRC meeting The next IRC meeting will be held on 2016-11-01 at 18:00 UTC. The meeting after that will be held on 2016-11-15 at 18:00 UTC. Reproducible work in other projects Ximin Luo has had his fix to bug 77985 accepted into GCC. This is needed to be able to write test cases for patches to make GCC produce debugging symbols that are reproducible regardless of the build path. There was continued discussion on the mailing list regarding our build path proposals. It has now been decided to use an environment variable SOURCE_PREFIX_MAP instead of the older proposal SOURCE_ROOT_DIR. This would be similar to GCC's existing -fdebug-prefix-map option, which allows for better disambiguation between paths from different packages. mandoc's makewhatis is now reproducible. It is used by all the BSDs, including FreeBSD, as well as Alpine Linux and Void Linux. Packages reviewed and fixed, and bugs filed Chris Lamb: Reiner Herrmann: Reviews of unreproducible packages 145 package reviews have been added, 608 have been updated and 94 have been removed in this week, adding to our knowledge about identified issues. 3 issue types have been updated: Weekly QA work During of reproducibility testing, some FTBFS bugs have been detected and reported by: tests.reproducible-builds.org Debian: General: diffoscope development Misc. This week's edition was written by Ximin Luo, Chris Lamb and Holger Levsen and reviewed by a bunch of Reproducible Builds folks on IRC.

Markus Koschany: My Free Software Activities in October 2016

Welcome to gambaru.de. Here is my monthly report that covers what I have been doing for Debian. If you re interested in Android, Java, Games and LTS topics, this might be interesting for you. Debian Android Debian Games Debian Java Debian LTS This was my eight month as a paid contributor and I have been paid to work 13 hours on Debian LTS, a project started by Rapha l Hertzog. In that time I did the following: Non-maintainer uploads QA

Raphaël Hertzog: My Free Software Activities in October 2016

My monthly report covers a large part of what I have been doing in the free software world. I write it for my donors (thanks to them!) but also for the wider Debian community because it can give ideas to newcomers and it s one of the best ways to find volunteers to work with me on projects that matter to me. Debian LTS Last month I started to work on tiff3 but had not enough time to complete an update, it turns out the issues were hairy enough that nobody else picked up the package. So this month I started again with tiff3 and tiff and I ended up spending my 13h on those two packages. I filed bugs for issues that were not yet reported to the BTS (#842361 for CVE-2016-5652, #842046 for CVE-2016-5319/CVE-2016-3633/CVE-2015-8668). I marked many CVE as not affecting tiff3 as this source package does not ship the tools (the tiff source package does). Since upstream decided to drop many tools instead of fixing the corresponding security issues, I opted to remove the tools as well. Before doing this, I looked up reverse dependencies of libtiff-tools to ensure that none of the tools removed are used by other packages (the maintainer seems to agree too). I backported upstream patches for CVE-2016-6223 and CVE-2016-5652. But the bulk of the time, I spent on CVE-2014-8128, CVE-2015-7554 and CVE-2016-5318. I believe they are all variants of the same problem and upstream seems to agree since he opened a sort of meta-bug to track them. I took inspiration from a patch suggested in ticket #2499 and generalized it a bit by trying to add the tag data for all tags manipulated by the various tools. It was a tiresome process as there are many tags used in multiple places. But in the end, it works as expected. I can no longer reproduce any of the segfaults with the problematic files. I asked for review/test on the mailing list but did not get much feedback. I m going to upload the updated packages soon. Distro Tracker I noticed a sudden raise in the number of email addresses being automatically unsubscribed from the Debian Package Tracker and I got a few request of bounces. It turns out the BTS has been relaying lots of spam with executables files and those are bounced by Google (and not silently discarded). This is all very unfortunate the spam flood is unlikely to stop soon and I can t expect Google to change either, so I had little choice except trying to make the bounce handler smarter. That s what I did: I have a list of regular expression that will discard a bounce. In other words, once matched the bounce won t count towards the limit that triggers the automatic unsubscription. Misc Debian work Bugs filed. In #839403, I suggest the possibility to set the default pin priority for a source in the sources.list file directly. In #840436 I ask the selenium-firefoxdriver maintainer to do what is required to get this non-free package auto-built. Packaging. I sponsored puppet-lint 2.0.2-0.1 and I reviewed the rozofs package (wihch I just sponsored into experimental for a start). Publicity. I m maintaining the Debian account on Twitter and Facebook. I have been using twitterfeed.com up to now but it s closing down. I followed their recommendations and switched to dlvr.it to automatically post entries out of the micronews.debian.org feed. In #841165, I reported that the chroots created by sbuild-createchroot are lacking the usual IPv6 entries created by netbase. In #841503, I report a very common cryptsetup upgrade failure that I saw multiple times (both in Debian and in Kali). Thanks See you next month for a new summary of my activities.

No comment Liked this article? Click here. My blog is Flattr-enabled.

1 November 2016

Simon Richter: Using the Arduino IDE with a tiling window manager

The Arduino IDE does not work properly with tiling window managers, because they do some interesting reparenting. To solve this, add
_JAVA_AWT_WM_NONREPARENTING=1
export _JAVA_AWT_WM_NONREPARENTING
to the start script or your environment. Credit: "Joost"

Jaldhar Vyas: Sal Mubarak 2073!

Wishing every one a happy Gujarati New Year, Vikram Samvat 2073 named Kilaka and hoping the upcoming year will be yuuge for you. These next couple of paragraphs are totally not an excuse for why it will take a few more days for me to reach seven blog posts. Reading reports about Diwali in the American press, I see a bit of confusion whether Diwali is one day or five. Well, technically it is just one (Sunday 30th this year.) but there are a number of other observances around it which could be classed as subsidiaries if you want to look at it that way. The season commenced last Wednesday with Rama Ekadashi. (where the Gujarati name is different I'll use that and put the Sanskrit name in parentheses.) That's a fast day and therefore not much fun. Thursday was Vagh Barash (vyaghra dvadashi) which as the name suggests is something to do with tigers but we don't in my experience particularly do anything special that day. Friday, things began in earnest with Dhan Terash (dhana trayodashi) when Lakshmi the Goddess of prosperity is worshipped. It is also a good day to buy gold. Saturday was Kali Chaudash (Kali Chaturdashi or Naraka Chaturdashi) On this day many Gujarati families including mine worship their Kuladevi (patron Goddess of the family) even if She is not an aspect of Kali. (Others observe this on the Ashtami of Navaratri.) The day is also associated with the God Hanuman. Some people say it is His Jayanti (birthday) though we observe it in Chaitra (March-April.) It is also the best day for learning mantras and I initiated a couple of people including my son into a mantra I know. Sunday was Diwali (Deepavali) proper. As a Brahmana I spent much of the day signing blessings in the account books of shopkeepers. Well, nowadays only a few old people have actual account books so usually the print out a spreadsheet and I sign that. But home is where the main action is. Lights are lit, fireworks are set off, and prayers are offered to Lakshmi. But most important of all, this is the day good boys and girls get presents. Unfortunately I have nothing interesting to report; just the usual utilitarian items of clothing. Fireworks by the way are technically illegal in New Jersey not that that ever stopped anyone from getting them. The past few years, Jersey City has attempted to compromise by allowing a big public fireworks display. Although it was nice and sunny all day, by nighttime we had torrential rain and the firework display got washed out. So I'm glad I rebelled against the system with my small cache of sparklers. Today (or yesterday by the time this gets posted.) was the Gujarati New Years Day. There is also the commemoration of the time the God Krishna lifted up Mt Govardhan with one finger which every mandir emulates by making an annakuta or mountain of food. Tuesday is Bhai Beeja (Yama Dvitiya in Sanskrit or Bhai Duj in Hindi) when sisters cook a meal for their brothers. My son is also going to make something (read: microwave something) for his sister. So those are the five days of Diwali. Though many will not consider it to be truly over until this Saturday, the lucky day of Labh Pancham (Labha panchami.) And if I still haven't managed to write seven blog posts by then, there is always Deva Diwali...

31 October 2016

Chris Lamb: Free software activities in October 2016

Here is my monthly update covering what I have been doing in the free software world (previously):

Debian & Reproducible builds

Whilst anyone can inspect the source code of free software for malicious flaws, most GNU/Linux distributions provide binary (or "compiled") packages to end users. The motivation behind the Reproducible Builds effort is to allow verification that no flaws have been introduced either maliciously and accidentally during this compilation process by promising identical binary packages are always generated from a given source.

  • Presented a talk entitled "Reproducible Builds" talk at Software Freedom Kosova, in Prishtina, Republic of Kosovo.

  • I filed my 2,500th bug in the Debian BTS: #840972: golang-google-appengine: accesses the internet during build.

  • In order to build packages reproducibly, one not only needs identical sources but also some external and sharable definition of the environment used for a particular build, stipulating such things such as the version numbers of the required build-dependencies. It is not currently clear how to handle these .buildinfo files after the archive software has processed them and how to make them available to the world so I started development on a proof-of-concept server to see what issues arise in practice. It is available at buildinfo.debian.net.

  • Chaired an IRC meeting and ran a poll to determine a regular time .

  • Submitted two design proposals to our wiki page.

  • Improvements to our tests.reproducible-builds.org testing framework:

    • Move regular "Scheduled in..." messages to the #debian-reproducible-changes IRC channel.
    • Use our log_info method instead of manual echo calls.
    • Correct an "all sources packages" "all source packages" typo.
    • Submit .buildinfo files to buildinfo.debian.net.
    • Create GPG key on nodes for buildinfo.debian.net at deploy time, not "lazily".

My work in the Reproducible Builds project was also covered in our weekly reports. (#75, #76, #77 & #78).

I also submitted 14 patches to fix specific reproducibility issues in bio-eagle, cf-python, fastx-toolkit, fpga-icestorm, http-icons, lambda-align, mypy, playitslowly, seabios, stumpwm, sympa, tj3, wims-help & xotcl.
Debian LTS

This month I have been paid to work 13 hours on Debian Long Term Support (LTS). In that time I did the following:
  • Seven days of "frontdesk" duties, triaging CVEs, etc.
  • Issued DLA 647-1 for freeimage correcting an out-of-bounds write vulnerability in the XMP image handling functionality.
  • Issued DLA 649-1 for python-django fixing a possible CSRF protection bypass on sites that use Google Analytics.
  • Issued DLA 654-1 for libxfixes preventing an integer overflow when a malicious client sent INT_MAX as a "length".
  • Issued DLA 662-1 for quagga correcting a programming error where two constants were confused that could cause stack overrun in IPv6 routing code.
  • Issued DLA 688-1 for cairo to prevent a DoS attack where a malicious SVG could generate invalid pointers.

Uploads
  • gunicorn:
    • 19.6.0-7 Set supplementary groups when changing uid, add an example systemd .service file to gunicorn-examples, and expand README.Debian to make it clearer what to do now that /etc/gunicorn.d has been removed.
    • 19.6.0-8 Correct previous supplementary groups patch to be compatible with Python 3.
  • redis:
    • 3:3.2.4-2 Ensure that sentinel's configuration actually writes to a pidfile location so that systemd can detect that the daemon has started.
    • 3:3.2.5-1 New upstream release.
  • libfiu:
    • 0.94-8 Fix FTBFS under Bash due to lack of && in debian/rules.
    • 0.94-9 Ensure the build is reproducible by sorting injected modules.
  • aptfs (2:0.8-2) Minor cosmetic changes.

NMUs
  • libxml-dumper-perl (0.81-1.2) Move away from a unsupported debhelper compat level 4.
  • netatalk (2.2.5-1.1) Drop build-dependency on hardening-includes.

QA uploads
  • anon-proxy (00.05.38+20081230-4) Move to a supported debhelper compatibility level 9.
  • ara (1.0.32) Make the build reproducible.
  • binutils-m68hc1x (1:2.18-8) Make the build reproducible & move to a supported debhelper compatibility level.
  • fracplanet (0.4.0-5) Make the build reproducible.
  • libnss-ldap (265-5) Make the build reproducible.
  • python-uniconvertor (1.1.5-3) Fix an "option release requires an argument" FTBFS. (#839375)
  • ripole (0.2.0+20081101.0215-3) Actually include the ripole binary in package. (#839919) & enable hardening flags.
  • twitter-bootstrap (2.0.2+dfsg-10) Fix incorrect copyright formatting when building under Bash. (#824592)
  • zpaq (1.10-3) Make the build reproducible.


Debian FTP Team

As a Debian FTP assistant I ACCEPTed 147 packages: ace-link, amazon-s2n, avy, basez, bootstrap-vz, bucklespring, camitk, carettah, cf-python, debian-reference, dfcgen-gtk, efivar, entropybroker, fakesleep, gall, game-data-packager, gitano, glare, gnome-panel, gnome-shell-extension-dashtodock, gnome-shell-extension-refreshwifi, gnome-shell-extension-remove-dropdown-arrows, golang-github-gogits-go-gogs-client, golang-github-gucumber-gucumber, golang-github-hlandau-buildinfo, golang-github-hlandau-dexlogconfig, golang-github-hlandau-goutils, golang-github-influxdata-toml, golang-github-jacobsa-crypto, golang-github-kjk-lzma, golang-github-miekg-dns, golang-github-minio-sha256-simd, golang-github-nfnt-resize, golang-github-nicksnyder-go-i18n, golang-github-pointlander-compress, golang-github-pointlander-jetset, golang-github-pointlander-peg, golang-github-rfjakob-eme, golang-github-thecreeper-go-notify, golang-github-twstrike-gotk3adapter, golang-github-unknwon-goconfig, golang-gopkg-dancannon-gorethink.v1, golang-petname, haskell-argon2, haskell-binary-parsers, haskell-bindings-dsl, haskell-deriving-compat, haskell-hackage-security, haskell-hcwiid, haskell-hsopenssl-x509-system, haskell-megaparsec, haskell-mono-traversable-instances, haskell-prim-uniq, haskell-raaz, haskell-readable, haskell-readline, haskell-relational-record, haskell-safe-exceptions, haskell-servant-client, haskell-token-bucket, haskell-zxcvbn-c, irclog2html, ironic-ui, lace, ledger, libdancer2-plugin-passphrase-perl, libdatetime-calendar-julian-perl, libdbix-class-optimisticlocking-perl, libdbix-class-schema-config-perl, libgeo-constants-perl, libgeo-ellipsoids-perl, libgeo-functions-perl, libgeo-inverse-perl, libio-async-loop-mojo-perl, libmojolicious-plugin-assetpack-perl, libmojolicious-plugin-renderfile-perl, libparams-validationcompiler-perl, libspecio-perl, libtest-time-perl, libtest2-plugin-nowarnings-perl, linux, lua-scrypt, mono, mutt-vc-query, neutron, node-ansi-font, node-buffer-equal, node-defaults, node-formatio, node-fs-exists-sync, node-fs.realpath, node-is-buffer, node-jison-lex, node-jju, node-jsonstream, node-kind-of, node-lex-parser, node-lolex, node-loud-rejection, node-random-bytes, node-randombytes, node-regex-not, node-repeat-string, node-samsam, node-set-value, node-source-map-support, node-spdx-correct, node-static-extend, node-test, node-to-object-path, node-type-check, node-typescript, node-unset-value, nutsqlite, opencv, openssl1.0, panoramisk, perl6, pg-rage-terminator, pg8000, plv8, puppet-module-oslo, pymoc, pyramid-jinja2, python-bitbucket-api, python-ceilometermiddleware, python-configshell-fb, python-ewmh, python-gimmik, python-jsbeautifier, python-opcua, python-pyldap, python-s3transfer, python-testing.common.database, python-testing.mysqld, python-testing.postgresql, python-wheezy.template, qspeakers, r-cran-nleqslv, recommonmark, rolo, shim, swift-im, tendermint-go-clist, tongue, uftrace & zaqar-ui.

Antoine Beaupr : My free software activities, October 2016

Debian Long Term Support (LTS) This is my 7th month working on Debian LTS, started by Raphael Hertzog at Freexian, after a long pause during the summer. I have worked on the following packages and CVEs: I have also helped review work on the following packages:
  • imagemagick: reviewed BenH's work to figure out what was done. unfortunately, I forgot to officially take on the package and Roberto started working on it in the meantime. I nevertheless took time to review Roberto's work and outline possible issues with the original patchset suggested
  • tiff: reviewed Raphael's work on the hairy TIFFTAG_* issues, all the gory details in this email
The work on ImageMagick and GraphicsMagick was particularly intriguing. Looking at the source of those programs makes me wonder why were are still using them at all: it's a tangled mess of C code that is bound to bring up more and more vulnerabilities, time after time. It seems there's always an "Magick" vulnerability waiting to be fixed out there... I somehow hoped that the fork would bring more stability and reliability, but it seems they are suffering from similar issues because, fundamentally, they haven't rewritten ImageMagick... It looks this is something that affects all image programs. The review I have done on the tiff suite give me the same shivering sensation as reviewing the "Magick" code. It feels like all image libraries are poorly implemented and then bound to be exploited somehow... Nevertheless, if I had to use a library of the sort in my software, I would stay away from the "Magick" forks and try something like imlib2 first... Finally, I also did some minor work on the user and developer LTS documentation and some triage work on samba, xen and libass. I also looked at the dreaded CVE-2016-7117 vulnerability in the Linux kernel to verify its impact on wheezy users. I also looked at implementing a --lts flag for dch (see bug #762715). It was difficult to get back to work after such a long pause, but I am happy I was able to contribute a significant number of hours. It's a bit difficult to find work sometimes in LTS-land, even if there's actually always a lot of work to be done. For example, I used to be one of the people doing frontdesk work, but those duties are now assigned until the end of the year, so it's unlikely I will be doing any of that for the forseable future. Similarly, a lot of packages were assigned when I started looking at the available packages. There was an interesting discussion on the internal mailing list regarding unlocking package ownership, because some people had packages locked for weeks, sometimes months, without significant activity. Hopefully that situation will improve after that discussion. Another interesting discussion I participated in is the question of whether the LTS team should be waiting for unstable to be fixed before publishing fixes in oldstable. It seems the consensus right now is that it shouldn't be mandatory to fix issues in unstable before we fix security isssues in oldstable and stable. After all, security support for testing and unstable is limited. But I was happy to learn that working on brand new patches is part of our mandate as part of the LTS work. I did work on such a patch for tar which ended up being adopted by the original reporter, although upstream ended up implementing our recommendation in a better way. It's coincidentally the first time since I start working on LTS that I didn't get the number of requested hours, which means that there are more people working on LTS. That is a good thing, but I am worried it may also mean people are more spread out and less capable of focusing for longer periods of time on more difficult problems. It also means that the team is growing faster than the funding, which is unfortunate: now is a good time as any to remind you to see if you can make your company fund the LTS project if you are still running Debian wheezy.

Other free software work It seems like forever that I did such a report, and while I was on vacation, a lot has happened since the last report.

Monkeysign I have done extensive work on Monkeysign, trying to bring it kicking and screaming in the new world of GnuPG 2.1. This was the objective of the 2.1 release, which collected about two years of work and patches, including arbitrary MUA support (e.g. Thunderbird), config files support, and a release on PyPI. I have had to release about 4 more releases to try and fix the build chain, ship the test suite with the program and have a primitive preferences panel. The 2.2 release also finally features Tor suport! I am also happy to have moved more documentation to Read the docs, part of which I mentionned in in a previous article. The git repositories and issues were also moved to a Gitlab instance which will hopefully improve the collaboration workflow, although we still have issues in streamlining the merge request workflow. All in all, I am happy to be working on Monkeysign, but it has been a frustrating experience. In the last years, I have been maintaining the project largely on my own: although there are about 20 contributors in Monkeysign, I have committed over 90% of the commits in the code. New contributors recently showed up, and I hope this will release some pressure on me being the sole maintainer, but I am not sure how viable the project is.

Funding free software work More and more, I wonder how to sustain my contributions to free software. As a previous article has shown, I work a lot on the computer, even when I am not on a full-time job. Monkeysign has been a significant time drain in the last months, and I have done this work on a completely volunteer basis. I wouldn't mind so much except that there is a lot of work I do on a volunteer basis. This means that I sometimes must prioritize paid consulting work, at the expense of those volunteer projects. While most of my paid work usually revolves around free sofware, the benefits of paid work are not always immediately obvious, as the primary objective is to deliver to the customer, and the community as a whole is somewhat of a side-effect. I have watched with interest joeyh's adventures into crowdfunding which seems to be working pretty well for him. Unfortunately, I cannot claim the incredible (and well-deserved) reputation Joey has, and even if I could, I can't live with 500$ a month. I would love to hear if people would be interested in funding my work in such a way. I am hesitant in launching a crowdfunding campaign because it is difficult to identify what exactly I am working on from one month to the next. Looking back at earlier reports shows that I am all over the place: one month I'll work on a Perl Wiki (Ikiwiki), the next one I'll be hacking at a multimedia home cinema (Kodi). I can hardly think of how to fund those things short of "just give me money to work on anything I feel like", which I can hardly ask for of anyone. Even worse, it feels like the audience here is either friends or colleagues. It would make little sense for me to seek funding from those people: colleagues have the same funding problems I do, and I don't want to empoverish my friends... So far I have taken the approach of trying to get funding for work I am doing, bit by bit. For example, I have recently been told that LWN actually pays for contributed articles and have started running articles by them before publishing them here. This is looking good: they will publish an article I wrote about the Omnia router I have recently received. I give them exclusive rights on the article for two weeks, but I otherwise retain full ownership over the article and will publish them after the exclusive period here. Hopefully, I will be able to find more such projects that pays for the work I do on a day to day basis.

Open Street Map editing I have ramped up my OpenStreetMap contributions, having (temporarily) moved to a different location. There are lots of things to map here: trails, gaz stations and lots of other things are missing from the map. Sometimes the effort looks a bit ridiculous, reminding me of my early days of editing OSM. I have registered to OSM Live, a project to fund OSM editors that, I must admit, doesn't help much with funding my work: with the hundreds of edits I did in October, I received the equivalent of 1.80$CAD in Bitcoins. This may be the lowest hourly salary I have ever received, probably going at a rate of 10 per hour! Still, it's interesting to be able to point people to the project if someone wants to contribute to OSM mappers. But mappers should have no illusions about getting a decent salary from this effort, I am sorry to say.

Bounties I feel this is similar to the "bounty" model used by the Borg project: I claimed around $80USD in that project for what probably amounts to tens of hours of work, yet another salary that would qualify as "poor". Another example is a feature I would like to implement in Borg: support for protocols other than SSH. There is currently no bounty on this, but a similar feature, S3 support has one of the largest bounties Borg has ever seen: $225USD. And the claimant for the bounty hasn't actually implemented the feature, instead backing up to S3, the patch (to a third-party tool) actually enables support for Amazon Cloud Drive, a completely different API. Even at $225, I wouldn't be able to complete any of those features and get a decent salary. As well explained by the Snowdrift reviews, bounties just don't work at all... The ludicrous 10% fee charged by Bountysource made sure I would never do business with them ever again anyways.

Other work There are probably more things I did recently, but I am having difficulty keeping track of the last 5 months of on and off work, so you will forgive that I am not as exhaustive as I usually am.

James Bromberger: The Debian Cloud Sprint 2016

I m at an airport, about to board the first of three flights across the world, from timezone +8 to timezone -8. I ll be in transit 27 hours to get to Seattle, Washington state. I m leaving my wife and two young children behind. My work has given me a days worth of leave under the Corporate Social Responsibility program, and I m taking three days annual leave, to do this. 27 hours each way in transit, for 3 days on the ground. Why? Backstory I started playing in technology as a kid in the 1980s; my first PC was a clone (as they were called) 286 running MS-DOS. It was clunky, and the most I could do to extend it was to write batch scripts. As a child I had no funds for commercial compilers, no network connections (this was pre Internet in Australia), no access to documentation, and no idea where to start programming properly. It was a closed world. I hit university in the summer of 1994 to study Computer Science and French. I d heard of Linux, and soon found myself installing the Linux distributions of the day. The Freedom of the licensing, the encouragement to use, modify, share, was in stark contrast to the world of consumer PCs of the late 1980 s. It was there at the UCC at UWA I discovered Debian. Some of the kind network/system admins at the University maintained a Debian mirror on the campus LAN, updated regularly and always online. It was fast, and more importantly, free for me to access. Back in the 1990s, bandwidth in Australia was incredibly expensive. The vast distances of the country mean that bandwidth was scarce. Telcos were in races to put fiber between Perth and the Eastern States, and without that in place, IP connectivity was constrained, and thus costly. Over many long days and nights I huddled down, learning window managers, protocols, programming and scripting languages. I became a system/network administrator, web developer, dev ops engineer, etc. My official degree workload, algorithmic complexity, protocol stacks, were interesting, but fiddling with Linux based implementations was practical. Volunteer After years of consuming the output of Debian and running many services with it I decided to put my hand up and volunteer as a Debian Developer: it was time to give back. I had benefited from Debian, and I saw others benefit from it as well. As the 2000 s started, I had my PGP key in the Debian key ring. I had adopted a package and was maintaining it load balancing Apache web servers. The web was yet to expand to the traffic levels you see today; most web sites were served from one physical web server. Site Reliability Engineering was a term not yet dreamed of. What became more apparent was the applicability of Linux, Open Source, and in my line-of-sight Debian to a wider community beyond myself and my university peers. Debain was being used to revive recycled computers that were being donated to charities; in some cases, unable to transfer commercial software licenses with the hardware that was no longer required by organisations that had upgraded. It appeared that Debian was being used as a baseline above which society in general had access to fundamental capability of computing and network services. The removal of subscriptions, registrations, and the encouragement of distribution meant this occurred at rates that could never be tracked, and more importantly, the consensus was that it should not be automatically tracked. The privacy of the user is paramount more important than some statistics for the Developer to ponder. When the Bosnia-Herzegovina war ended in 1995, I recall an email from academics there, having found some connectivity, writing to ask if they would be able to use Debian as part of their re-deployment of services for the Tertiary institutions in the region. This was an unnecessary request as Debian GNU/Linux is freely available, but it was a reminder that, for the country to have tried to procure commercial solutions at that time would have been difficult. Instead, those that could do the task just got on with it. There s been many similar project where the grass-roots organisations non profits, NGOs, and even just loose collectives of individuals have turned to Linux, Open Source, and sometimes Debian to solve their problems. Many fine projects have been established to make technology accessible to all, regardless of race, gender, nationality, class, or any other label society has used to divide humans. Big hat tip to Humanitarian Open Street Map, Serval Project. I ve always loved Debian s position on being the Universal operating system. Its vast range of packages and wide range of computing architectures supported means that quite often a litmus test of is project X a good project? was met with is it packaged for Debian? . That wide range of architectures has meant that administrators of systems had fewer surprises and a faster adoption cycle when changing platforms, such as the switch from x86 32 bit to x86 64 bit. Enter the Cloud I first laid eyes on the AWS Cloud in 2008. It was nothing like the rich environment you see today. The first thing I looked for was my favourite operating system, so that what I already knew and was familiar with was available in this environment to minimise the learning curve. However there were no official images, which was disconcerting. In 2012 I joined AWS as an employee. Living in Australia they hired me into the field sales team as a Solution Architect a sort of pre-sales tech with a customer focused depth in security. It was a wonderful opportunity, and I learnt a great deal. It also made sense (to me, at least) to do something about getting Debian s images blessed. It turned out, that I had to almost define what that was: images endorsed by a Debian Developer, handed to the AWS Marketplace team. And so since 2013 I have done so, keeping track of Debian s releases across the AWS regions, collaborating with other Debian folk on other cloud platforms to attempt a unified approach to generating and maintaining these images. This included (for a stint) generating them into the AWS GovCloud Region, and still into the AWS China (Beijing) Region the other side of the so-called Great Firewall of China. So why the trip? We ve had focus groups at the Debconf (Debian conference) around the world, but its often difficult to get the right group of people in the same rooms at the same time. So the proposal was to hold a focused Debian Cloud Sprint. Google was good enough to host this, for all the volunteers across all the cloud providers. Furthermore, donated funds were found to secure the travel for a set of people to attend who otherwise could not. I was lucky enough to be given a flight. So here I am, in the terminal in Australia: my kids are tucked up in bed, dreaming of the candy they just collected for Halloween. It will be a draining week I am sure, but if it helps set and improve the state of Debian then its worth it.

28 October 2016

Matthew Garrett: Of course smart homes are targets for hackers

The Wirecutter, an in-depth comparative review site for various electrical and electronic devices, just published an opinion piece on whether users should be worried about security issues in IoT devices. The summary: avoid devices that don't require passwords (or don't force you to change a default and devices that want you to disable security, follow general network security best practices but otherwise don't worry - criminals aren't likely to target you.

This is terrible, irresponsible advice. It's true that most users aren't likely to be individually targeted by random criminals, but that's a poor threat model. As I've mentioned before, you need to worry about people with an interest in you. Making purchasing decisions based on the assumption that you'll never end up dating someone with enough knowledge to compromise a cheap IoT device (or even meeting an especially creepy one in a bar) is not safe, and giving advice that doesn't take that into account is a huge disservice to many potentially vulnerable users.

Of course, there's also the larger question raised by the last week's problems. Insecure IoT devices still pose a threat to the wider internet, even if the owner's data isn't at risk. I may not be optimistic about the ease of fixing this problem, but that doesn't mean we should just give up. It is important that we improve the security of devices, and many vendors are just bad at that.

So, here's a few things that should be a minimum when considering an IoT device:
  • Does the vendor publish a security contact? (If not, they don't care about security)
  • Does the vendor provide frequent software updates, even for devices that are several years old? (If not, they don't care about security)
  • Has the vendor ever denied a security issue that turned out to be real? (If so, they care more about PR than security)
  • Is the vendor able to provide the source code to any open source components they use? (If not, they don't know which software is in their own product and so don't care about security, and also they're probably infringing my copyright)
  • Do they mark updates as fixing security bugs? (If not, they care more about hiding security issues than fixing them)
  • Has the vendor ever threatened to prosecute a security researcher? (If so, again, they care more about PR than security)
  • Does the vendor provide a public minimum support period for the device? (If not, they don't care about security or their users)

    I've worked with big name vendors who did a brilliant job here. I've also worked with big name vendors who responded with hostility when I pointed out that they were selling a device with arbitrary remote code execution. Going with brand names is probably a good proxy for many of these requirements, but it's insufficient.

    So here's my recommendations to The Wirecutter - talk to a wide range of security experts about the issues that users should be concerned about, and figure out how to test these things yourself. Don't just ask vendors whether they care about security, ask them what their processes and procedures look like. Look at their history. And don't assume that just because nobody's interested in you, everybody else's level of risk is equal.


  • comment count unavailable comments

    Alessio Treglia: The logical contradictions of the Universe

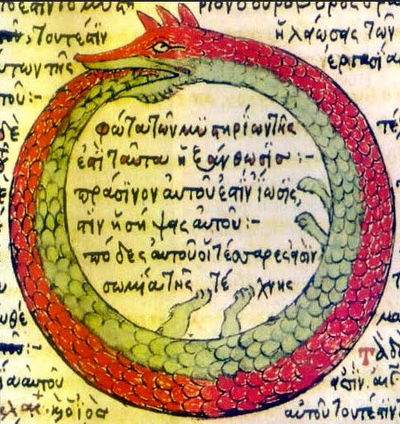
    Ouroboros

    Ouroboros

    Is Erwin Schr dinger s wave function which did in the atomic and subatomic world an operation altogether similar to the one performed by Newton in the macroscopic world an objective reality or just a subjective knowledge? Physicists, philosophers and epistemologist have debated at length on this matter. In 1960, theoretical physicist Eugene Wigner has proposed that the observer s consciousness is the dividing line that triggers the collapse of the wave function[1], and this theory was later taken up and developed in recent years. The rules of quantum mechanics are correct but there is only one system which may be treated with quantum mechanics, namely the entire material world. There exist external observers which cannot be treated within quantum mechanics, namely human (and perhaps animal) minds, which perform measurements on the brain causing wave function collapse [2]. The English mathematical physicist and philosopher of science Roger Penrose developed the hypothesis called Orch-OR (Orchestrated objective reduction) according to which consciousness originates from processes within neurons, rather than from the connections between neurons (the conventional view). The mechanism is believed to be a quantum physical process called objective reduction which is orchestrated by the molecular structures of the microtubules of brain cells (which constitute the cytoskeleton of the cells themselves). Together with the physician Stuart Hameroff, Penrose has suggested a direct relationship between the quantum vibrations of microtubules and the formation of consciousness.

    <Read More [by Fabio Marzocca]>

    Jaldhar Vyas: Get Ready For Bikini Season With These n Weird Tricks

    It all started last June when my son had his Janoi (Yagnopavita) ceremony -- the ritual by which a Brahmana boy becomes "twice-born" and eligible to study the Vedas. As well as a profound religious experience, it is also an important social occasion with a reception for as many friends and family as can attend. (I think our final guest total was ~250.) This meant new outfits for everyone which might be exciting for some people but not me. I still don't know why I couldn't just keep wearing the khes and pitambar from the puja but no, apparently that's a faux pas. So I relented and agreed to wear my "darbari" suit from my wedding. And it didn't fit. I knew I had gained some weight in the intermediate 17 years but the thing was sitcom levels of too small. I ended up having to purchase a new one, a snazzy (and shiny!) maroon number with gold stripes (or were they black stripes?) Problem having been solved, much was eaten, more weight was gained and then I forgot about the whole thing. Tip 1: Actually Do Something. I have over the years tried to improve my physical condition but it has never gotten very far. For instance I have a treadmill/coatrack and a couple of years ago I began using it in earnest. I got to the point where I actually ran a 10K race without dying. But I did not train systematically and I ended up in some pain which caused me to stop working out for a while and then I never got around to restarting. Diets have also failed because I don't have a clear idea of what and how much I am eating. All I know is that women go into the kitchen and when they come out they have food. By what eldritch process this occurs is a mystery, I just eat whats given to me thankful that the magic happens. Once I was moved to try and help but quickly fell afoul of the lack of well-defined algorithms in Gujarati home cooking.
    "How much saffron should I add?"
    "this much."
    "How much is this much in SI units?"
    "You're annoying me. Get out."
    Fast forward to March of this year. For my birthday, my wife got me a Fitbit fitness tracker. This is what I had needed all this time. It measure heart rate, distance travelled, time slept and several other pieces of info you can use to really plan a fitness regimen rationally. For example, I was chagrined to learn that sometimes when I'm at the computer, I am so immobile that the fitbit thought I was asleep. So I started planning to taken more frequent breaks. (A recent firmware upgrade has added the ability to nudge to walk atleast 250 paces each daytime hour which is handy for this.) Also by checking my heart rate I discovered that I went on the treadmill I ran too fast thereby stressing my body for little gain and ending up going too slow to get much aerobic effect. Now I can pace myself appropriately for maximum cardiac efficiency without ending up injuring myself and giving up. I also get a little more activity each day by simple changes such as taking the stairs instead of the lift and instead of getting off at the 14th street PATH I go all the way to 34th street and walk down. Tip 2: You must have data in order to see what you did right or wrong and to plan what you need to do moving forward. One caveat about these fitness trackers. They are not anywhere as accurate as a proper checkup from a doctor who specializes in such things. If you want to do any kind of pro or amateur athletics you probably should not rely on them but for the average shlub who just wants to avoid appearing on the news being winched off his sofa by the fire brigade they are good enough. Another practice I began was keeping a food diary. It can be a real eye-opener to see how much you are actually eating. It is probably much more than you thought. I am fortunate that my diet is pretty good to begin with. Vegetarian, (not vegan, Hindus eat dairy products,) mostly home-cooked with fresh ingredients, not fried or processed, and I don't drink alcohol. However there were a few optimizations I could make. I drink a lot of soda; atleast two cans a day. I really ought to stop altogether but in lieu of that I have atleast switched from Coke to Coke Zero thereby saving a lot of empty calories. I now eat 4 rotlis with my dinner instead of six. We as a family eat more green vegetables instead of potatos, skim milk instead of whole fat, canola oil instead of corn oil, and less rice and don't slather ghee on everything quite so much. One entirely new practice I've adopted that may seem faddish but works for me is intermittent fasting. The idea is to steadily train your body to need less food by eating all your days allowed amount pf calories during a 6-8 hour window and not eating at all during the remaining time. It's hard to get used to for many people but I fast atleast 2-3 times a month for religious reasons anyway so I adapted pretty quickly. The fitbit tells me how many calories I am expending and how many I can eat to maintain a healthy level of weight loss but other than that I don't bother with "food groups" or specific diets such as paleo, or low-carb etc. As long as what you eat is reasonably balanced and you are burning more calories than you are adding, it should be enough for weight loss. Indeed from the end of March to now, I've lost 3 stones (20Kg) even with the occasional "cheat" day. Tip 3: All published diets are bullshit without scientifically proven efficacy. Don't bother with them. Experiment instead and see what works for you and your metabolism. As long as you are getting all the proper nutrients (you shouldn't need a supplement unless you have an actual medical condition.) and you have a net calorie deficit, it's all good. If you eat food you enjoy, you are more likely to stick to your diet. The proper amount of sleep is one area of a healthy lifestyle I am still doing poorly in and the reasons are not all raven-related. I have always had problems with insomnia and was once actually diagnosed with sleep apnea. Losing weight has helped a lot but the fitbit is still reporting that I toss and turn a lot during the night. And that's when I'm in bed in the first place. I stay up much too late which can also lead to subsidiary bad behaviours such as midnight snacking. It's something I need to work on. Tip 4: Stop blogging at all hours of the night, It's not doing you any good. So that's what I'm doing. Moving forward, I need to deal with the sleep thing and I would also like to start some program of strength-training, I'm doing ok in terms of aerobic exercise but from what I've read, you also have to build up muscles to keep weight loss permanent. The difficulty is that it would involve joining a gym and then actually going to that gym so I've put it off for now. The immediate threat is Diwali (and Thanksgiving and Christmas...) My wife bought 4 lbs of sweets today and I can feel their presence in the fridge calling to me.

    26 October 2016

    Steinar H. Gunderson: Why does software development take so long?

    Nageru 1.4.0 is out (and on its way through the Debian upload process right now), so now you can do live video mixing with multichannel audio to your heart's content. I've already blogged about most of the interesting new features, so instead, I'm trying to answer a question: What took so long? To be clear, I'm not saying 1.4.0 took more time than I really anticipated (on the contrary, I pretty much understood the scope from the beginning, and there was a reason why I didn't go for building this stuff into 1.0.0); but if you just look at the changelog from the outside, it's not immediately obvious why multichannel audio support should take the better part of three months of develoment. What I'm going to say is of course going to be obvious to most software developers, but not everyone is one, and perhaps my experiences will be illuminating. Let's first look at some obvious things that isn't the case: First of all, development is not primarily limited by typing speed. There are about 9,000 lines of new code in 1.4.0 (depending a bit on how you count), and if it was just about typing them in, I would be done in a day or two. On a good keyboard, I can type plain text at more than 800 characters per minute but you hardly ever write code for even a single minute at that speed. Just as when writing a novel, most time is spent thinking, not typing. I also didn't spend a lot of time backtracking; most code I wrote actually ended up in the finished product as opposed to being thrown away. (I'm not as lucky in all of my projects.) It's pretty common to do so if you're in an exploratory phase, but in this case, I had a pretty good idea of what I wanted to do right from the start, and that plan seemed to work. This wasn't a difficult project per se; it just needed to be done (which, in a sense, just increases the mystery). However, even if this isn't at the forefront of science in any way (most code in the world is pretty pedestrian, after all), there's still a lot of decisions to make, on several levels of abstraction. And a lot of those decisions depend on information gathering beforehand. Let's take a look at an example from late in the development cycle, namely support for using MIDI controllers instead of the mouse to control the various widgets. I've kept a pretty meticulous TODO list; it's just a text file on my laptop, but it serves the purpose of a ghetto bugtracker. For 1.4.0, it contains 83 work items (a single-digit number is not ticked off, mostly because I decided not to do those things), which corresponds roughly 1:2 to the number of commits. So let's have a look at what the ~20 MIDI controller items went into. First of all, to allow MIDI controllers to influence the UI, we need a way of getting to it. Since Nageru is single-platform on Linux, ALSA is the obvious choice (if not, I'd probably have to look for a library to put in-between), but seemingly, ALSA has two interfaces (raw MIDI and sequencer). Which one do you want? It sounds like raw MIDI is what we want, but actually, it's the sequencer interface (it does more of the MIDI parsing for you, and generally is friendlier). The first question is where to start picking events from. I went the simplest path and just said I wanted all events anything else would necessitate a UI, a command-line flag, figuring out if we wanted to distinguish between different devices with the same name (and not all devices potentially even have names), and so on. But how do you enumerate devices? (Relatively simple, thankfully.) What do you do if the user inserts a new one while Nageru is running? (Turns out there's a special device you can subscribe to that will tell you about new devices.) What if you get an error on subscription? (Just print a warning and ignore it; it's legitimate not to have access to all devices on the system. By the way, for PCM devices, all of these answers are different.) So now we have a sequencer device, how do we get events from it? Can we do it in the main loop? Turns out it probably doesn't integrate too well with Qt, but it's easy enough to put it in a thread. The class dealing with the MIDI handling now needs locking; what mutex granularity do we want? (Experience will tell you that you nearly always just want one mutex. Two mutexes give you all sorts of headaches with ordering them, and nearly never gives any gain.) ALSA expects us to poll() a given set of descriptors for data, but on shutdown, how do you break out of that poll to tell the thread to go away? (The simplest way on Linux is using an eventfd.) There's a quirk where if you get two or more MIDI messages right after each other and only read one, poll() won't trigger to alert you there are more left. Did you know that? (I didn't. I also can't find it documented. Perhaps it's a bug?) It took me some looking into sample code to find it. Oh, and ALSA uses POSIX error codes to signal errors (like nothing more is available ), but it doesn't use errno. OK, so you have events (like controller 3 was set to value 47 ); what do you do about them? The meaning of the controller numbers is different from device to device, and there's no open format for describing them. So I had to make a format describing the mapping; I used protobuf (I have lots of experience with it) to make a simple text-based format, but it's obviously a nightmare to set up 50+ controllers by hand in a text file, so I had to make an UI for this. My initial thought was making a grid of spinners (similar to how the input mapping dialog already worked), but then I realized that there isn't an easy way to make headlines in Qt's grid. (You can substitute a label widget for a single cell, but not for an entire row. Who knew?) So after some searching, I found out that it would be better to have a tree view (Qt Creator does this), and then you can treat that more-or-less as a table for the rows that should be editable. Of course, guessing controller numbers is impossible even in an editor, so I wanted it to respond to MIDI events. This means the editor needs to take over the role as MIDI receiver from the main UI. How you do that in a thread-safe way? (Reuse the existing mutex; you don't generally want to use atomics for complicated things.) Thinking about it, shouldn't the MIDI mapper just support multiple receivers at a time? (Doubtful; you don't want your random controller fiddling during setup to actually influence the audio on a running stream. And would you use the old or the new mapping?) And do you really need to set up every single controller for each bus, given that the mapping is pretty much guaranteed to be similar for them? Making a guess bus button doesn't seem too difficult, where if you have one correctly set up controller on the bus, it can guess from a neighboring bus (assuming a static offset). But what if there's conflicting information? OK; then you should disable the button. So now the enable/disable status of that button depends on which cell in your grid has the focus; how do you get at those events? (Install an event filter, or subclass the spinner.) And so on, and so on, and so on. You could argue that most of these questions go away with experience; if you're an expert in a given API, you can answer most of these questions in a minute or two even if you haven't heard the exact question before. But you can't expect even experienced developers to be an expert in all possible libraries; if you know everything there is to know about Qt, ALSA, x264, ffmpeg, OpenGL, VA-API, libusb, microhttpd and Lua (in addition to C++11, of course), I'm sure you'd be a great fit for Nageru, but I'd wager that pretty few developers fit that bill. I've written C++ for almost 20 years now (almost ten of them professionally), and that experience certainly helps boosting productivity, but I can't say I expect a 10x reduction in my own development time at any point. You could also argue, of course, that spending so much time on the editor is wasted, since most users will only ever see it once. But here's the point; it's not actually a lot of time. The only reason why it seems like so much is that I bothered to write two paragraphs about it; it's not a particular pain point, it just adds to the total. Also, the first impression matters a lot if the user can't get the editor to work, they also can't get the MIDI controller to work, and is likely to just go do something else. A common misconception is that just switching languages or using libraries will help you a lot. (Witness the never-ending stream of software that advertises written in Foo or uses Bar as if it were a feature.) For the former, note that nothing I've said so far is specific to my choice of language (C++), and I've certainly avoided a bunch of battles by making that specific choice over, say, Python. For the latter, note that most of these problems are actually related to library use libraries are great, and they solve a bunch of problems I'm really glad I didn't have to worry about (how should each button look?), but they still give their own interaction problems. And even when you're a master of your chosen programming environment, things still take time, because you have all those decisions to make on top of your libraries. Of course, there are cases where libraries really solve your entire problem and your code gets reduced to 100 trivial lines, but that's really only when you're solving a problem that's been solved a million times before. Congrats on making that blog in Rails; I'm sure you're advancing the world. (To make things worse, usually this breaks down when you want to stray ever so slightly from what was intended by the library or framework author. What seems like a perfect match can suddenly become a development trap where you spend more of your time trying to become an expert in working around the given library than actually doing any development.) The entire thing reminds me of the famous essay No Silver Bullet by Fred Brooks, but perhaps even more so, this quote from John Carmack's .plan has struck with me (incidentally about mobile game development in 2006, but the basic story still rings true):
    To some degree this is already the case on high end BREW phones today. I have a pretty clear idea what a maxed out software renderer would look like for that class of phones, and it wouldn't be the PlayStation-esq 3D graphics that seems to be the standard direction. When I was doing the graphics engine upgrades for BREW, I started along those lines, but after putting in a couple days at it I realized that I just couldn't afford to spend the time to finish the work. "A clear vision" doesn't mean I can necessarily implement it in a very small integral number of days.
    In a sense, programming is all about what your program should do in the first place. The how question is just the what , moved down the chain of abstractions until it ends up where a computer can understand it, and at that point, the three words multichannel audio support have become those 9,000 lines that describe in perfect detail what's going on.

    Next.

    Previous.