Search Results: "xam"

21 December 2013

Russell Coker: Links December 2013

Andres Lozano gave an interesting TED talk about the use of electrodes inside the brain (deep brain stimulation) to treat Alzheimers disease, Parkinson s disease, and depression [1]. Daniel Pocock wrote an interesting post commenting on some bad political decisions being made in Australia titled Evacuating Australia [2]. You can read that as a suggestion to leave Australia or to try and make Australia better. Marco Tempest gave an interesting TED talk about Nikola Tesla [3]. The presentation method is one that I ve never seen before so I recommend watching the talk even if you already know all about Tesla. Charmian Gooch gave an interesting TED talk about global corruption [4]. I think we need people to send the information on shell company ownership to organisations like Wikileaks. The punishment for leaking such information would be a lot less than Chelsea Manning is getting and the chance of getting caught is also low. Rich Mogul wrote an interesting and insightful article for Macworld about the Apple approach to security problems [5]. To avoid the problem of users disabling security features they work to make the secure way of doing things EASIER for the user. That won t work with all security problems but it s something we need to think about when working on computer security. Ray Raphael gave an interesting TED talk about the parts of the US revolution that don t appear in history books [6]. He warns the listener to beware of the narrative forms, but another way to interpret his talk is that you should present your version of history in the narrative form that is best accepted. That lesson is well known and it s easy to see history being deliberately distorted in most media outlets. Will Wright gave an interesting TED talk about how he designed the game Spore and his ideas about games in general [7]. Spore is a really good game. Chris Lintott gave an interesting TED talk about crowd-sourced astronomy titled How to Discover a Planet from Your Sofa [8]. He referenced the Zooniverse.org site which lists many crowd-sourced science projects [9]. Jake Socha gave an interesting TED talk about flying snakes, you have to see this to believe it [10]. Nikita Bier gave an interesting TED talk about his webapp to analyse economic policies [11]. Apparently 60% of people were going to vote in their best economic interest before seeing his site and 66% would do so afterwards that could change an election result. Anya Kamenetz wrote an interesting article for Salon about The Iliad Project which aims to use Indigogo to help identify new anti-biotics [12]. The current ways of discovering anti-biotics aren t working, lets hope this one does. Peter Finocchiaro wrote an interesting Salon article about how right-wing politicians in the US were opposed to Nelson Mandela [13] racism meets anti-communism. Katie McDonough wrote an interesting Salon article about Rick Santorum and Bill O Reilly comparing Obamacare to apartheid while supposedly honoring Nelson Mandela [14], Katie also notes that Nelson enshrined universal healthcare in the South African constitution something all countries should do. Mary Elizabeth Williams wrote a Salon article about Susan Boyle s announcement about being diagnosed with Asperger Syndrome [15]. Not a surprise though, some people can be diagnosed with Autism by merely watching them on TV. Amelia Hill wrote an article for The Guardian/The Observer about the educational results of Home Schooling [16]. Apparently Home-Schooled kids learn significantly more and home-educated children of working-class parents achieved considerably higher marks in tests than the children of professional, middle-class parents and that gender differences in exam results disappear among home-taught children . Wow, Home Schooling beats gender and class problems! I m sure it s even better for GLBT kids too. Robert Reich wrote an interesting Salon article about the way rich people in the US give tax-deductable (taxpayer supported) donations to charities that benefit themselves [17]. Dan Savage wrote a very funny review of Sarah Palin s latest Christmas book, one classic quote is why should I have to read the whole thing? Lord knows Sarah Palin didn t write the whole thing [18]. He makes a good point that we should use the term happy holidays instead of happy Christmas just to show that we aren t assholes.

Daniel Kahn Gillmor: Kevin M. Igoe should step down from CFRG Co-chair

I've said recently that pervasive surveillance is wrong. I don't think anyone from the NSA should have a leadership position in the development or deployment of Internet communications, because their interests are at odds with the interest of the rest of the Internet. But someone at the NSA is in exactly such a position. They ought to step down. Here's the background: The Internet Research Task Force (IRTF) is a body tasked with research into underlying concepts, themes, and technologies related to the Internet as a whole. They act as a research organization that cooperates and complements the engineering and standards-setting activities of the Internet Engineering Task Force (IETF). The IRTF is divided into issue-specific research groups, each of which has a Chair or Co-Chairs who have "wide discretion in the conduct of Research Group business", and are tasked with organizing the research and discussion, ensuring that the group makes progress on the relevant issues, and communicating the general sense of the results back to the rest of the IRTF and the IETF. One of the IRTF's research groups specializes in cryptography: the Crypto Forum Research Group (CFRG). There are two current chairs of the CFRG: David McGrew <mcgrew@cisco.com> and Kevin M. Igoe <kmigoe@nsa.gov>. As you can see from his e-mail address, Kevin M. Igoe is affiliated with the National Security Agency (NSA). The NSA itself actively tries to weaken cryptography on the Internet so that they can improve their surveillance, and one of the ways they try to do so is to "influence policies, standards, and specifications". On the CFRG list yesterday, Trevor Perrin requested the removal of Kevin M. Igoe from his position as Co-chair of the CFRG. Trevor's specific arguments rest heavily on the technical merits of a proposed cryptographic mechanism called Dragonfly key exchange, but I think the focus on Dragonfly itself is the least of the concerns for the IRTF. I've seconded Trevor's proposal, and asked Kevin directly to step down and to provide us with information about any attempts by the NSA to interfere with or subvert recommendations coming from these standards bodies. Below is my letter in full:
From: Daniel Kahn Gillmor <dkg@fifthhorseman.net>
To: cfrg@ietf.org, Kevin M. Igoe <kmigoe@nsa.gov>
Date: Sat, 21 Dec 2013 16:29:13 -0500
Subject: Re: [Cfrg] Requesting removal of CFRG co-chair
On 12/20/2013 11:01 AM, Trevor Perrin wrote:
> I'd like to request the removal of Kevin Igoe from CFRG co-chair.
Regardless of the conclusions that anyone comes to about Dragonfly
itself, I agree with Trevor that Kevin M. Igoe, as an employee of the
NSA, should not remain in the role of CFRG co-chair.
While the NSA clearly has a wealth of cryptographic knowledge and
experience that would be useful for the CFRG, the NSA is apparently
engaged in a series of attempts to weaken cryptographic standards and
tools in ways that would facilitate pervasive surveillance of
communication on the Internet.
The IETF's public position in favor of privacy and security rightly
identifies pervasive surveillance on the Internet as a serious problem:
https://www.ietf.org/media/2013-11-07-internet-privacy-and-security.html
The documents Trevor points to (and others from similar stories)
indicate that the NSA is an organization at odds with the goals of the IETF.
While I want the IETF to continue welcoming technical insight and
discussion from everyone, I do not think it is appropriate for anyone
from the NSA to be in a position of coordination or leadership.
----
Kevin, the responsible action for anyone in your position is to
acknowledge the conflict of interest, and step down promptly from the
position of Co-Chair of the CFRG.
If you happen to also subscribe to the broad consensus described in the
IETF's recent announcement -- that is, if you care about privacy and
security on the Internet -- then you should also reveal any NSA activity
you know about that attempts to subvert or weaken the cryptographic
underpinnings of IETF protocols.
Regards,
	--dkg
I'm aware that an abdication by Kevin (or his removal by the IETF chair) would probably not end the NSA's attempts to subvert standards bodies or weaken encryption. They could continue to do so by subterfuge, for example, or by private influence on other public members. We may not be able to stop them from doing this in secret, and the knowledge that they may do so seems likely to cast a pall of suspicion over any IETF and IRTF proceedings in the future. This social damage is serious and troubling, and it marks yet another cost to the NSA's reckless institutional disregard for civil liberties and free communication. But even if we cannot rule out private NSA influence over standards bodies and discussion, we can certainly explicitly reject any public influence over these critical communications standards by members of an institution so at odds with the core principles of a free society. Kevin M. Igoe, please step down from the CFRG Co-chair position. And to anyone (including Kevin) who knows about specific attempts by the NSA to undermine the communications standards we all rely on: please blow the whistle on this kind of activity. Alert a friend, a colleague, or a journalist. Pervasive surveillance is an attack on all of us, and those who resist it are heroes.

Kees Cook: DOM scraping

For a long time now I ve used mechanize (via either Perl or Python) for doing website interaction automation. Stuff like playing web games, checking the weather, or reviewing my balance at the bank. However, as the use of javascript continues to increase, it s getting harder and harder to screen-scrape without actually processing DOM events. To do that, really only browsers are doing the right thing, so getting attached to an actual browser DOM is generally the only way to do any kind of web interaction automation. It seems the thing furthest along this path is Selenium. Initially, I spent some time trying to make it work with Firefox, but gave up. Instead, this seems to work nicely with Chrome via the Chrome WebDriver. And even better, all of this works out of the box on Ubuntu 13.10 via python-selenium and chromium-chromedriver. Running /usr/lib/chromium-browser/chromedriver2_server from chromium-chromedriver starts a network listener on port 9515. This is the WebDriver API that Selenium can talk to. When requests are made, chromedriver2_server spawns Chrome, and all the interactions happen against that browser. Since I prefer Python, I avoided the Java interfaces and focused on the Python bindings:
#!/usr/bin/env python
import sys
from selenium import webdriver
from selenium.common.exceptions import NoSuchElementException
from selenium.webdriver.common.keys import Keys
caps = webdriver.DesiredCapabilities.CHROME
browser = webdriver.Remote("http://localhost:9515", caps)
browser.get("https://bank.example.com/")
assert "My Bank" in browser.title
try:
    elem = browser.find_element_by_name("userid")
    elem.send_keys("username")
    elem = browser.find_element_by_name("password")
    elem.send_keys("wheee my password" + Keys.RETURN)
except NoSuchElementException:
    print "Could not find login elements"
    sys.exit(1)
assert "Account Balances" in browser.title
xpath = "//div[text()='Balance']/../../td[2]/div[contains(text(),'$')]"
balance = browser.find_element_by_xpath(xpath).text
print balance
browser.close()
This would work pretty great, but if you need to save any state between sessions, you ll want to be able to change where Chrome stores data (since by default in this configuration, it uses an empty temporary directory via --user-data-dir=). Happily, various things about the browser environment can be controlled, including the command line arguments. This is configurable by expanding the desired capabilities variable:
caps = webdriver.DesiredCapabilities.CHROME
caps["chromeOptions"] =  
        "args": ["--user-data-dir=/home/user/somewhere/to/store/your/session"],
     
A great thing about this is that you get to actually watch the browser do its work. However, in cases where this interaction is going to be fully automated, you likely won t have a Xorg session running, so you ll need to wrap the WebDriver in one (since it launches Chrome). I used Xvfb for this:
#!/bin/bash
# Start WebDriver under fake X and wait for it to be listening
xvfb-run /usr/lib/chromium-browser/chromedriver2_server &
pid=$!
while ! nc -q0 -w0 localhost 9515; do
    sleep 1
done
the-chrome-script
rc=$?
# Shut down WebDriver
kill $pid
exit $rc
Alternatively, all of this could be done in the python script too, but I figured it s easier to keep the support infrastructure separate from the actual test script itself. I actually leave the xvfb-run call external too, so it s easier to debug the browser in my own X session. One bug I encountered was that the WebDriver s cache of the browser s DOM can sometimes get out of sync with the actual browser s DOM. I didn t find a solution to this, but managed to work around it. I m hoping later versions fix this. :)

2013, Kees Cook. This work is licensed under a Creative Commons Attribution-ShareAlike 3.0 License.
Creative Commons License

18 December 2013

Joey Hess: what charlie's missing about bitcoin

(Posted as a comment to Charles Stross's blog post about bitcoin) Bitcoin is a piece of software which tries to implement a particular SFnal future. One in which the world currency is de-centralized, deflationary, all early bitcoin adopters own their own planetoids, and all visitors are automatically charged for the air they breath. Thing is, the real world is more complicated than that. Assuming Bitcoin did manage to become an important currency, countries would naturally try to regulate it. In 30 years, by the time bitcoin mining has slowed right down, the legal system will be fully caught up to the internet. Bitcoin tries to make its code the law (as Lessig used to say), but the law can certainly affect its code. The law could, for example, require that bitcoin be changed to stop increasing the difficulty of mining new blocks. Then bitcoin is suddenly an inflationary currency. This would be a hard fork in the block chain, but one enforced by financial regulators. Miners would be tracked down and forced to comply. Some would perhaps go underground and run the deflationary bitcoin network on TOR hidden services. Lots of possible ways it could play out. That's only one scenario, covering one of the many problems with Bitcoin that make Charlie hate it. So it seems to me that Bitcoin should be a gold mine for Science Fiction authors, if nothing else..

Daniel Pocock: Embedding Python in multi-threaded C++ applications

Embedding Python into other applications to provide a scripting mechanism is a popular practice. Ganglia can run user-supplied Python scripts for metric collection and the Blender project does it too, allowing users to develop custom tools and use script code to direct their animations. There are various reasons people choose Python:
  • Modern, object orientated style of programming
  • Interpreted language (no need to compile things, just edit and run the code)
  • Python has a vast array of modules providing many features such as database and network access, data processing, etc
The bottom line is that the application developer who chooses to embed Python in their existing application can benefit from the product of all this existing code multiplied by the imagination of their users. Enter repro repro is the SIP proxy of the reSIProcate project. reSIProcate is an advanced SIP implementation developed in C++. repro is a multi-threaded process. repro's most serious competitor is the Kamailio SIP proxy. Kamailio has its own bespoke scripting language that it has inherited from the SIP Express Router (SER) family of projects. repro has always been far more rigid in its capabilities than Kamailio. On the other hand, while Kamailio has given users great flexibility, it has also come at a cost: users can easily build configurations that are not valid or may not do what they really intend if they don't understand the intricacies of the SIP protocol. Here is an example of the Kamailio configuration script (from Daniel's excellent blog about building a Skype-like service in less than an hour) Kamailio also has a wide array of plugins for things like database and LDAP access. repro only had embedded bdb and MySQL support. Embedding Python into repro appears to be a quick way to fill many of these gaps and allow users to combine the power of the reSIProcate stack with their own custom routing logic. On the other hand, it is not simply copying the Kamailio scripting solution: rather, it provides a distinctive alternative. Starting the integration Embedding Python is such a popular practice that there is even dedicated documentation on the subject. As well as looking there, I also looked over the example provided by the embedded Python module for Ganglia. Looking over the Ganglia mod_python code I noticed a lot of boilerplate code for reference counting and other tedious activities. Given that reSIProcate is C++ code, I thought I would look for a C++ solution to this and I came across PyCXX. PyCXX is licensed under BSD-like terms similar to reSIProcate itself so it is a good fit. There is also the alternative Boost.Python API, however, reSIProcate has been built without Boost dependencies so I decided to stick with PyCXX. I looked over the PyCXX examples and the documentation and was able to complete a first cut of the embedded Python scripting feature very quickly. Using PyCXX One unusual thing I noticed about PyCXX is that the Debian package, python-cxx-dev does not provide any shared library. Instead, some uncompiled source files are provided and each project using PyCXX must compile them and link them statically itself. Here is how I do that in the Makefile.am for pyroute in repro:
AM_CXXFLAGS = -I $(top_srcdir)
reproplugin_LTLIBRARIES = libpyroute.la
libpyroute_la_SOURCES = PyRoutePlugin.cxx
libpyroute_la_SOURCES += PyRouteWorker.cxx
libpyroute_la_SOURCES += $(PYCXX_SRCDIR)/cxxextensions.c
libpyroute_la_SOURCES += $(PYCXX_SRCDIR)/cxx_extensions.cxx
libpyroute_la_SOURCES += $(PYCXX_SRCDIR)/cxxsupport.cxx
libpyroute_la_SOURCES += $(PYCXX_SRCDIR)/../IndirectPythonInterface.cxx
libpyroute_la_CPPFLAGS = $(DEPS_PYTHON_CFLAGS)
libpyroute_la_LDFLAGS = -module -avoid-version
libpyroute_la_LDFLAGS += $(DEPS_PYTHON_LIBS)
EXTRA_DIST = example.py
noinst_HEADERS = PyRouteWorker.hxx
noinst_HEADERS += PyThreadSupport.hxx
The value PYCXX_SRCDIR must be provided on the configure command line. On Debian, it is /usr/share/python2.7/CXX/Python2 Going multi-threaded My initial implementation simply invoked the Python method from the main routing thread of the repro SIP proxy. This meant that it would only be suitable for executing functions that complete quickly, ruling out the use of any Python scripts that talk to network servers or other slow activities. When the proxy becomes heavily loaded, it is important that it can complete many tasks asynchronously, such as forwarding chat messages between users in real-time. Therefore, it was essential to extend the solution to run the Python scripts in a pool of worker threads. At this point, I had an initial feeling that there may be danger in just calling the Python methods from some other random threads started by my own code. I went to see the manual and I came across this specific documentation about the subject. It looks quite easy, just wrap the call to the user-supplied Python code in something like this:
PyGILState_STATE gstate;
gstate = PyGILState_Ensure();
/* Perform Python actions here. */
result = CallSomeFunction();
/* evaluate result or handle exception */
/* Release the thread. No Python API allowed beyond this point. */
PyGILState_Release(gstate);
Unfortunately, I found that this would not work and that one of two problems occur when using this code:
  • The thread blocks on the call to PyGILState_Ensure()
  • The program crashes with a segmentation fault when the call to a Python method was invoked
Exactly which of these outcomes I experienced seemed to depend on whether I tried to explicitly call PyEval_ReleaseThread() from the main thread after doing the Py_Initialize() and other setup tasks. I tried various permutations of using PyGILState_Ensure()PyGILState_Release() and/or PyEval_SaveThread()/PyEval_ReleaseThread() but I always had one of the same problems. The next thing that occurred to me is that maybe PyCXX provides some framework for thread integration: I had a look through the code and couldn't find any reference to the threading functionality from the C API. I went looking for more articles and mailing list discussions and found implementation notes such as this one in Linux Journal and this wiki from the Blender developers. Most of them just appeared to be repeating what was in the manual, with a few subtle differences, but none of this provided an immediate solution. Eventually, I discovered this other blog about concurrency with embedded Python and it suggests something not highlighted in any of the other resources: calling PyThreadState_New(m_interpreterState) in each thread after it starts and before it does anything else. Combining this with the use of PyEval_SaveThread()/PyEval_ReleaseThread() fixed the problem: the use of PyThreadState_New() was not otherwise mentioned in the relevant section of the Python guide. I decided to take this solution a step further and create a convenient C++ class to encapsulate the logic, you can see this in PyThreadSupport.hxx:
class PyExternalUser
 
   public:
      PyExternalUser(PyInterpreterState* interpreterState)
       : mInterpreterState(interpreterState),
         mThreadState(PyThreadState_New(mInterpreterState))  ;
   class Use
    
      public:
         Use(PyExternalUser& user)
          : mUser(user)
           PyEval_RestoreThread(mUser.getThreadState());  ;
         ~Use()   mUser.setThreadState(PyEval_SaveThread());  ;
      private:
         PyExternalUser& mUser;
    ;
   friend class Use;
   protected:
      PyThreadState* getThreadState()   return mThreadState;  ;
      void setThreadState(PyThreadState* threadState)   mThreadState = threadState;  ;
   private:
      PyInterpreterState* mInterpreterState;
      PyThreadState* mThreadState;
 ;
and the way to use it is demonstrated in the PyRouteWorker class. Observe how PyExternalUser::Use is instantiated in the PyRouteWorker::process() method: when it goes out of scope (either due to a normal return, an error or an exception) the necessary call to PyEval_SaveThread() is made in the PyExternalUser::Use::~Use() destructor. Using other Python modules and DSO problems All of the above worked for basic Python such as this trivial example script:
def on_load():
    '''Do initialisation when module loads'''
    print 'example: on_load invoked'
def provide_route(method, request_uri, headers):
    '''Process a request URI and return the target URI(s)'''
    print 'example: method = ' + method
    print 'example: request_uri = ' + request_uri
    print 'example: From = ' + headers["From"]
    print 'example: To = ' + headers["To"]
    routes = list()
    routes.append('sip:bob@example.org')
    routes.append('sip:alice@example.org')
    return routes
However, it needs a more credible and useful test: using the python-ldap module to try and query an LDAP server appears like a good choice. Upon trying to use import ldap in the Python script, repro would refuse to load the Python script, choking on an error like this:
Traceback (most recent call last):
  File "/usr/lib/python2.7/dist-packages/ldap/__init__.py", line 22, in 
    import _ldap
ImportError: /usr/lib/python2.7/dist-packages/_ldap.so: undefined symbol: PyExc_SystemError
I looked at the file _ldap.so and discovered that it is linked with the LDAP libraries but not explicitly linked to any version of the Python runtime libraries. It expects the application hosting it to provide the Python symbols globally. In my own implementation, my embedded Python encapsulation code is provide as a DSO plugin, similar to the way plugins are loaded in Ganglia or Apache. The DSO links to Python: the DSO is loaded by a dlopen() call from the main process. The main repro binary has no direct link to Python libraries. Adding RTLD_GLOBAL to the top-level dlopen() call for loading the plugin is one way to ensure the Python symbols are made available to the Python modules loaded indirectly by the Python interpreter. This solution may be suitable for applications that don't mix and match many different components. Doing something useful with it Now it was all working nicely, I took a boilerplate LDAP Python example and used it for making a trivial script that converts sip:user@example.org to something like sip:9001@pbx.example.org, assuming that 9001 is the telephoneNumber associated with the user@ email address in LDAP. It is surprisingly simple and easily adaptable to local requirements depending upon the local LDAP structures:
import ldap
from urlparse import urlparse
def on_load():
    '''Do initialisation when module loads'''
    #print 'ldap router: on_load invoked'
def provide_route(method, request_uri, headers):
    '''Process a request URI and return the target URI(s)'''
    #print 'ldap router: request_uri = ' + request_uri
    _request_uri = urlparse(request_uri)
    routes = list()
    
    # Basic LDAP server parameters:
    server_uri = 'ldaps://ldap.example.org'
    base_dn = "dc=example,dc=org"
    # this domain will be appended to the phone numbers when creating
    # the target URI:
    phone_domain = 'pbx.example.org'
    # urlparse is not great for "sip:" URIs,
    # the user@host portion is in the 'path' element:
    filter = "(&(objectClass=inetOrgPerson)(mail=%s))" % _request_uri.path
    #print "Using filter: %s" % filter
    try:
        con = ldap.initialize(server_uri)
        scope = ldap.SCOPE_SUBTREE
        retrieve_attributes = None
        result_id = con.search(base_dn, scope, filter, retrieve_attributes)
        result_set = []
        while 1:
            timeout = 1
            result_type, result_data = con.result(result_id, 0, None)
            if (result_data == []):
                break
            else:
                if result_type == ldap.RES_SEARCH_ENTRY:
                    result_set.append(result_data)
        if len(result_set) == 0:
            #print "No Results."
            return routes
        for i in range(len(result_set)):
            for entry in result_set[i]:
                if entry[1].has_key('telephoneNumber'):
                    phone = entry[1]['telephoneNumber'][0]
                    routes.append('sip:' + phone + '@' + phone_domain)
    except ldap.LDAPError, error_message:
        print "Couldn't Connect. %s " % error_message
    return routes
Embedded Python opens up a world of possibilities After Ganglia 3.1.0 introduced an embedded Python scripting facility, dozens of new modules started appearing in github. Python scripting lowers the barrier for new contributors to a project and makes it much easier to fine tune free software projects to meet local requirements: hopefully we will see similar trends with the repro SIP proxy and other projects that choose Python. The code is committed here in the reSIProcate repository. These features will appear in the next beta release of reSIProcate and Debian packages will be available in unstable in a few days.

Daniel Kahn Gillmor: automatically have uscan check signatures

If you maintain software in debian, one of your regular maintenance tasks is checking for new upstream versions, reviewing them, and preparing them for debian if appropriate. One of those steps is often to verify the cryptographic signature on the upstream source archive. At the moment, most maintainers do the cryptographic check manually, or maybe even don't bother to do it at all. For the common case of detached OpenPGP signatures, though, uscan can now do it for you automatically (as of devscripts version 2.13.3). You just need to tell uscan what keys you expect upstream to be signing with, and how to find the detached signature. So, for example, Damien Miller recently announced his new key that he will be using to sign OpenSSH releases (his new key has OpenPGP fingerprint 59C2 118E D206 D927 E667 EBE3 D3E5 F56B 6D92 0D30 -- you can verify it has been cross-signed by his older key, and his older key has been revoked with the indication that it was superceded by this one). Having done a reasonable verification of Damien's key, if i was the openssh package maintainer, i'd do the following:
cd ~/src/openssh/
gpg --export '59C2 118E D206 D927 E667  EBE3 D3E5 F56B 6D92 0D30' >> debian/upstream-signing-key.pgp
And then upon noticing that the signature files are named with a simple .asc suffix on the upstream distribution site, we can use the following pgpsigurlmangle option in debian/watch:
version=3
opts=pgpsigurlmangle=s/$/.asc/ ftp://ftp.openbsd.org/pub/OpenBSD/OpenSSH/portable/openssh-(.*)\.tar\.gz 
I've filed this specific example as debian bug #732441. If you notice a package with upstream signatures that aren't currently being checked by uscan (or if you are upstream, you sign your packages, and you want your debian maintainer to verify them), you can file similar bugs. Or, if you maintain a package for debian, you can just fix up your package so that this check is there on the next upload. If you maintain a package whose upstream doesn't sign their releases, ask them why not -- wouldn't upstream prefer that their downstream users can verify that each release wasn't tampered with? Of course, none of these checks take the the place of the real work of a debian package maintainer: reviewing the code and the changelogs, thinking about what changes have happened, and how they fit into the broader distribution. But it helps to automate one of the basic safeguards we should all be using. Let's eliminate the possibility that the file was tampered with at the upstream distribution mirror or while in transit over the network. That way, the maintainer's time and energy can be spent where they're more needed.Tags: crypto, devscripts, openpgp, package maintenance, signatures, uscan

17 December 2013

Joey Hess: completely linux distribution-independent packaging

Sometimes it makes sense to ship a program to linux users in ready-to-run form that will work no matter what distribution they are using. This is hard. Often a commerical linux game will bundle up a few of the more problimatic libraries, and ship a dynamic executable that still depends on other system libaries. These days they're building and shipping entire Debian derivatives instead, to avoid needing to deal with that. There have been a few efforts to provide so-called one click install package systems that AFAIK, have not been widely used. I don't know if they generally solved the problem. More modern appoaches seem to be things like docker, which move the application bundle into a containerized environment. I have not looked at these, but so far it does not seem to have spread widely enough to be a practical choice if you're wanting to provide something that will work for a majority of linux users. So, I'm surprised that I seem to have managed to solve this problem using nothing more than some ugly shell scripts. My standalone tarballs of git-annex now seem fairly good at running on a very wide variety of systems. For example, I unpacked the tarball into the Debian-Installer initramfs and git-annex could run there. I can delete all of /usr and it keeps working! All it needs is a basic sh, which even busybox provides. Looks likely that the new armel standalone tarball of git-annex will soon be working on embedded systems as odd as the Synology NAS, and it's already been verified to work on Raspbian. (I'm curious if it would work on Android, but that might be a stretch.) Currently these tarballs are built for a specific architecture, but there's no particular reason a single one couldn't combine binaries built for each supported architecture. technical details The main trick is to ship a copy of ld-linux.so, as well as all the glibc libraries and associated files, and of course every other library and file the application needs. Shipping ld-linux.so lets a shell script wrapper be made around each binary, that runs ld-linux.so and passes it the library directories to search. This way the binary can be run, bypassing the system's own dynamic linker (which might not like it) and using the included glibc. For example a shell script that runs the git binary from the bundle:
exec "$GIT_ANNEX_LINKER" --library-path "$GIT_ANNEX_LD_LIBRARY_PATH" "$GIT_ANNEX_SHIMMED/git/git" "$@"
I have to set quite a lot of environment variables, to avoid using any files from the system and instead use ones from my tarball. One important one is GCONV_PATH. Note that LD_LIBRARY_PATH does not have to be set, and this is nice because it allows running a few programs from the host system, such as its web browser. worse is better Of course I'll take a proper distribution package anytime over this. Still, it seems to work quite well, in all the horrible cases that require it.

16 December 2013

Erich Schubert: Java Hotspot Compiler - a heavily underappreciated technology

When I had my first contacts with Java, probably around Java 1.1 or Java 1.2, it felt all clumsy and slow. And this is still the reputation that Java has to many developers: bloated source code and slow performance.
The last years I've worked a lot with Java; it would not have been my personal first choice, but as this is usually the language the students know best, it was the best choice for this project, the data mining framework ELKI.
I've learned a lot on Java since, also on debugging and optimizing Java code. ELKI contains a number of tasks that require a good number chrunching performance; something where Java particularly had the reputation of being slow.
I must say, this is not entirely fair. Sure, the pure matrix multiplication performance of Java is not up to Fortran (BLAS libraries are usually implemented in Fortran, and many tools such as R or NumPy will use them for the heavy lifting). But there are other tasks than matrix multiplication, too!
There is a number of things where Java could be improved a lot. Some of this will be coming with Java 8, others is still missing. I'd particularly like to see native BLAS support and multi-valued on-stack returns (to allow intrinsic sincos, for example).

In this post, I want to emphasize that usually the Hotspot compiler does an excellent job.
A few years ago, I have always been laughing at those that claimed "Java code can even be faster than C code"; because the Java JVM is written in C. Having had a deeper look at what the hotspot compiler does, I'm now saying: I'm not surprised that quite often, reasonably good Java code outperforms reasonably good C code.
In fact, I'd love to see a "hotspot" optimizer for C.
So what is it what makes Hotspot so fast? In my opinion, the key ingredient to hotspot performance is aggressive inlining. And this is exactly why "reasonably well written" Java code can be faster than C code written at a similar level.
Let me explain this at an example. Assuming we want to compute a pariwise distance matrix; but we want the code to be able to support arbitrary distance functions. The code will roughly look like this (not heavily optimized):
for (int i = 0; i < size; i++)  
  for (int j = i + 1; j < size; j++)  
    matrix[i][j] = computeDistance(data[i], data[j]);
   
 
In C, if you want to be able to choose computeDistance at runtime, you would likely make it a function pointer, or in C++ use e.g. boost::function or a virtual method. In Java, you would use an interface method instead, i.e. distanceFunction.distance().
In C, your compiler will most likely emit a jmp *%eax instruction to jump to the method to compute the distance; with virtual methods in C++, it would load the target method from the vtable and then jmp there. Technically, it will likely be a "register-indirect absolute jump". Java will, however, try to inline this code at runtime, i.e. it will often insert the actual distance function used at the location of this call.
Why does this make a difference? CPUs have become quite good at speculative execution, prefetching and caching. Yet, it can still pay off to save those jmps as far as I can tell; and if it is just to allow the CPU to apply these techniques to predict another branch better. But there is also a second effect: the hotspot compiler will be optimizing the inlined version of the code, whereas the C compiler has to optimize the two functions independently (as it cannot know they will be only used in this combination).
Hotspot can be quite aggressive there. It will even inline and optimize when it is not 100% sure that these assumptions are correct. It will just add simple tests (e.g. adding some type checks) and jump back to the interpreter/compiler when these assumptions fail and then reoptimize again.
You can see the inlining effect in Java when you use the -Xcomp flag, telling the Java VM to compile everything at load time. It cannot do as much speculative inlining there, as it does not know which method will be called and which class will be seen. Instead, it will have to compile the code using virtual method invocations, just like C++ would use for executing this. Except that in Java, every single method will be virtual (in C++, you have to be explicit). You will likely see a substantial performance drop when using this flag, it is not recommended to use. Instead, let hotspot perform its inlining magic. It will inline a lot by default - in particular tiny methods such as getters and setters.
I'd love to see something similar in C or C++. There are some optimizations that can only be done at runtime, not at compile time. Maybe not even at linking time; but only with runtime type information, and that may also change over time (e.g. the user first computes a distance matrix for Euclidean distance, then for Manhattan distance).

Don't get me wrong. I'm not saying Java is perfect. There are a lot of common mistakes, such as using java.util.Collections for primitive types, which comes at a massive memory cost and garbage collection overhead. The first thing to debug when optimizing Java applications is to check for memory usage overhead. But all in all, good Java code can indeed perform well, and may even outperform C code, due to the inlining optimization I just discussed; in particular on large projects where you cannot fine-tune inlining in C anymore.

Sometimes, Hotspot may also fail. Which is largely why I've been investigating these issues recently. In ELKI 0.6.0 I'm facing a severe performance regression with linear scans (which is actually the simpler codepath, not using indexes but using a simple loop as seen above). I had this with 0.5.0 before, but back then I was able to revert back to an earlier version that still performed good (even though the code was much more redundant). This time, I would have had to revert a larger refactoring that I wanted to keep, unfortunately.
Because the regression was quite severe - from 600 seconds to 1500-2500 seconds (still clearly better than -Xcomp) - I first assumed I was facing an actual programming bug. Careful inspection down to the assembler code produced by the hotspot VM did not reveal any such error. Then I tried Java 8, and the regression was gone.
So apparently, it is not a programming error, but Java 7 failed at optimizing it remotely as good as it did with the previous ELKI version!
If you are an Java guru, interested at tracking down this regression, feel free to contact me. It's in an open source project, ELKI. I'd be happy to have good performance even for linear-scans, and Java 7. But I don't want to waste any more hours on this, but instead plan to move on to Java 8 for other reasons (lambda expressions, which will greatly reduce the amount of glue coded needed), too. Plus, Java 8 is faster in my benchmarks.

15 December 2013

Daniel Pocock: A bias against Bitcoin?

A statement from the European Banking Authority is warning people about the risks of using Bitcoin for payment and investment/speculation. The press notes that the EBA paper stops short of telling people not to use the digital currency. Many of the points made in the warning appear to be well founded on the facts: however, exactly the same points could be made about everything from gift vouchers to bullion. It is not clear why Bitcoin should be singled out for special attention like this. Yes, gold and silver bullion are not issued by any central authority. Bullion values rise and fall many times in each day. When bullion values dipped earlier in 2013, some short term speculators sold at a loss: but for every scared seller, there was also somebody else willing to buy. Has anybody seen any stories of disgruntled investors throwing their gold out with the rubbish when the market moved? A more interesting example is that of the gift vouchers offered by many chains of retail stores. With many stores going through restructuring and liquidation in recent years, customers holding the vouchers have been left high and dry. Unlike temporary dips in bullion or Bitcoin values, the vouchers have often become truly worthless. The story has been repeated again and again around the world, including HMV in the UK and Mothercare in Australia. Community sense When retailers enter bankruptcy, it is usually at the instigation of a single person such as a prominent shareholder or the lender. Bitcoin and bullion, on the other hand, are arguably much harder for any single person or small group to pull the plug on so dramatically. Their value depends on their widespread acceptance around the globe rather than any single point of failure. Bitcoin's future I'm yet to see any evidence that Bitcoin is a long term store of value. Even the most knowledgeable proponents of Bitcoin agree that it is not technically perfect, due to the lack of true anonymity. When a truly anonymous solution is found, it will be interesting to see if the industry migrates away from Bitcoin. On the other hand, the threat of a truly anonymous community cryptocurrency is a scary thing for governments in the surveillance age. It could be argued that governments may become active players in the Bitcoin market in order to keep more anonymous solutions from gaining market share. For example, if a government was to accept remittence of taxes by Bitcoin or if smaller countries were to use Bitcoin to facilitate foreign exchange (bypassing the use of US dollars) this would make the currency far more credible for other mainstream purposes.

13 December 2013

Sylvain Le Gall: Release of OASIS 0.4.0

I am happy to announce that OASIS v0.4.0 has just been released. Logo OASIS small OASIS is a tool to help OCaml developers to integrate configure, build and install systems in their projects. It should help to create standard entry points in the source code build system, allowing external tools to analyse projects easily. This tool is freely inspired by Cabal which is the same kind of tool for Haskell. You can find the new release here and the changelog here. More information about OASIS in general on the OASIS website. I have recently resumed my work on OASIS and this will be hopefully the new version that will lead to quicker iteration in the development of OASIS. The development process was slowdown by the fact, that I feared introducing new fields in _oasis or regression. This was a pain and I decided to change my development model. Features The most important step is the introduction of AlphaFeatures and BetaFeatures fields. They allow to introduce pieces of code that will only be activated if certain features are listed in those fields. It should help to be always ready to release. The features also cover other aspect like flag_tests and flag_docs which has been introduced in OASIS v0.3.0. In fact the features API is now used to introduce all enhancement while keeping backward compatibility with regard to OASISFormat. Rather than defining a ~since_version:0.3 for fields we use a feature that handle the maturity level of the feature. When I feel a specific feature is ready to ship, I just change the InDev Alpha to InDev Beta and then SinceVersion 0.4. On the long term, when we won't support anymore a version of OASIS that existed before the SinceVersion, the feature will always be true and I will fully integrate it in the code. The only constraint around features is: if you use AlphaFeatures or BetaFeatures field, you must use the latest OASISFormat... Features section in the manual. Example of features available: Automate Another topic is automation of testing releases. For OASIS v0.3.0, I ran tests on all platforms manually, late in the development of v0.3.0 and it was painful to fix. So I have decided to setup a Jenkins instance that automate testing on Linux. On the long term, I plan to also setup a Mac OS X builder and start looking at Windows as well. This should help me catch errors early and be able to fix them quickly. However, for v0.4.0 I have decided to just release what I have and which has mainly be tested on Linux. The point here is to quickly release and iterate, rather than wait for perfection. Hopefully end user testing will allow to quickly discover new bugs. Time boxed release In the coming months, I will try to do time boxed releases. I will try to release version of OASIS every 15th of the month. The point here is to try to iterate faster and avoid long delay between release. See you in 1 month for the next release.
Daniel Pocock: xWiki: 10 years and a WebRTC success story

Six months ago, I wrote to the leaders of several open source web frameworks and asked them about their vision for WebRTC and if they would come to the WebRTC Conference in Paris this week (now finished). The most promising response was from Ludovic Dubost, founder of the xWiki project. Ludovic successfully demonstrated their shiny new WebRTC capabilities today in front of an audience including many far more experienced telephony operators who are still only getting to terms with this technology. What is xWiki? Don't let the wiki name limit your perception of this project. xWiki is a lot more than just another wiki hosting framework. As a bare minimum, you can certainly use it in the same way as other wikis, doing lightweight markup that is easier than HTML. On the other hand, xWiki really shines when it comes to extensibility. The xWiki team are Java developers and so xWiki appeals most to other Java developers who may want to leverage some library code from their web portal from time to time, without even having to compile anything. Here are some examples and here is one of the most trivial ones:
 velocity 
Your username is $xcontext.getUser(), welcome to the site.
 /velocity 
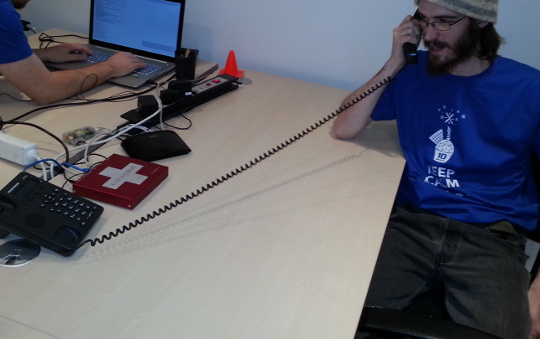
WebRTC capabilities The xWiki team chose XMPP as a chat protocol (using the Candy XMPP JavaScript chat) as the foundation for real-time communication. They have then extended this by creating a custom signalling mechanism and making it convenient for users of a chat session to upgrade the session to voice/video with a mouseclick. The whole experience works within the browser without any plugins. 10 years of xWiki It was also xWiki's 10th birthday today and this provided the perfect opportunity for a party: cjdns and enigmabox While at the xWiki office, it was interesting to see a lot of innovative work taking place, including this VoIP setup where a Grandstream phone is attached to an Enigmabox operated by Caleb from the cjdns project.
11 December 2013

Daniel Pocock: Get WebRTC going faster

On Saturday, Lumicall began offering free calls from browser to mobile using the free and open WebRTC technology. It should be no surprise that the service has been popular. Is it really free and open? The only way to prove this technology is free is to help people implement this for themself. On Monday, I uploaded reSIProcate v1.9.0 beta7 packages to Debian. The reSIProcate SIP proxy, repro, is one of the core components of the solution behind the free Lumicall service. Simply install the repro and resiprocate-turn-server packages using apt-get and make the following changes to the configuration (use your own IP addresses of course). I've taken this diff from my own runtime environment, only hiding my passwords, so that you can see exactly how I got it working:
--- repro.config.orig	2013-12-11 17:36:27.179228324 +0100
+++ repro-ws.sip5060.net.config	2013-12-11 17:48:24.159938649 +0100
@@ -143,6 +143,41 @@
 # Transport6TlsClientVerification = None
 # Transport6RecordRouteUri = sip:h1.sipdomain.com;transport=WS
 
+Transport1Interface = 195.8.117.57:80
+Transport1Type = WS
+Transport1RecordRouteUri = auto
+
+Transport2Interface = 2001:67c:1388:1000::57:80
+Transport2Type = WS
+Transport2RecordRouteUri = auto
+
+Transport3Interface = 195.8.117.57:5060
+Transport3Type = TCP
+Transport3RecordRouteUri = auto
+
+Transport4Interface = 2001:67c:1388:1000::57:5060
+Transport4Type = TCP
+Transport4RecordRouteUri = auto
+
+Transport5Interface = 195.8.117.57:443
+Transport5Type = WSS
+#Transport5RecordRouteUri = auto
+Transport5TlsDomain = ws.sip5060.net
+Transport5TlsClientVerification = None
+Transport5RecordRouteUri = sip:ws.sip5060.net;transport=WSS
+Transport5TlsCertificate = /etc/ssl/ssl.crt/ws.sip5060.net-bundle.crt
+Transport5TlsPrivateKey = /etc/ssl/private/ws.sip5060.net-key.pem
+
+Transport6Interface = 2001:67c:1388:1000::57:443
+Transport6Type = WSS
+#Transport6RecordRouteUri = auto
+Transport6TlsDomain = ws.sip5060.net
+Transport6TlsClientVerification = None
+Transport6RecordRouteUri = sip:ws.sip5060.net;transport=WSS
+Transport6TlsCertificate = /etc/ssl/ssl.crt/ws.sip5060.net-bundle.crt
+Transport6TlsPrivateKey = /etc/ssl/private/ws.sip5060.net-key.pem
+
+
 # Comma separated list of DNS servers, overrides default OS detected list (leave blank 
 # for default)
 DNSServers =
@@ -455,7 +490,7 @@
 ForceRecordRouting = false
 
 # Assume path option
-AssumePath = false
+AssumePath = true
 
 # Disable registrar
 DisableRegistrar = false
@@ -481,7 +516,7 @@
 # WARNING: Before enabling this, ensure you have a RecordRouteUri setup, or are using
 # the alternate transport specification mechanism and defining a RecordRouteUri per
 # transport: TransportXRecordRouteUri
-DisableOutbound = true
+DisableOutbound = false
 
 # Set the draft version of outbound to support (default: RFC5626)
 # Other accepted values are the versions of the IETF drafts, before RFC5626 was issued
@@ -505,7 +540,7 @@
 # WARNING: Before enabling this, ensure you have a RecordRouteUri setup, or are using
 # the alternate transport specification mechanism and defining a RecordRouteUri per
 # transport: TransportXRecordRouteUri
-EnableFlowTokens = false
+EnableFlowTokens = true
 
 # Enable use of flow-tokens in non-outbound cases for clients detected to be behind a NAT.  
 # This a more selective flow token hack mode for clients not supporting RFC5626.  The 

This is a diff against the /etc/repro/repro.config file distributed in the Debian package version 1.9.0~beta7-1. In the example above, I've included WSS transport defintions for WebSockets over TLS. Use the standard procedure for creating webserver SSL certificates to create certificates for repro and make sure you insert the correct filenames in the TLS parameters above. I've also duplicated every transport for IPv6. If you don't want TLS/WSS or IPv6, just comment those entries out (and renumber the remaining transports). Web-based SIP proxy setup Once you have repro running, go to the web admin interface (port 5080, username: admin, password: admin) and finish the setup using the web UI. The following steps are essential:
  • Add your domain (and restart the repro daemon after adding your domain)
  • Add some users
  • Add any routes to external services (optional - in my next blog I'll demonstrate how to route WebRTC calls to Asterisk using the Debian packages and less than 20 lines of configuration)
Set up reTurn, the TURN server Just put your IP addresses in /etc/reTurnServer.config and add the following line to /etc/reTurnServer-users.txt:
test:notasecret:reTurn:authorized
IMPORTANT: the realm in the users file (reTurn in the example and default config) must be identical to the AuthenticationRealm in the /etc/reTurnServer.config file. On your own web site Simply install your own apache server and clone the webrtc.lumicall.org demo site. Modify the file js/custom.js and include the settings for your own server.
# cd /var/www
# mkdir webcall
# cd webcall
# wget -r -nH http://webrtc.lumicall.org
# vi js/custom.js
In the custom.js, make sure you use a ws:// URL if you didn't set up SSL certificates and use a wss:// URL if you did. The IP or domain of your repro server must be in the ws:// or wss:// URL. Now navigate to the URL ending with /webcall on your server. For RHEL, Fedora and other RPM users Can somebody please assist with the review of the cajun-jsonapi dependency package so I can upload this new version of reSIProcate to Fedora? I'm also planning to make v1.9.0 available in EPEL6 when it is released in January. Questions? Please come and ask questions or discuss your experiences on the Free RTC mailing list sponsored by FSF Europe.

10 December 2013

Kees Cook: live patching the kernel

A nice set of recent posts have done a great job detailing the remaining ways that a root user can get at kernel memory. Part of this is driven by the ideas behind UEFI Secure Boot, but they come from the same goal: making sure that the root user cannot directly subvert the running kernel. My perspective on this is toward making sure that an attacker who has gained access and then gained root privileges can t continue to elevate their access and install invisible kernel rootkits. An outline for possible attack vectors is spelled out by Matthew Gerrett s continuing useful kernel lockdown patch series. The set of attacks was examined by Tyler Borland in Bypassing modules_disabled security . His post describes each vector in detail, and he ultimately chooses MSR writing as the way to write kernel memory (and shows an example of how to re-enable module loading). One thing not mentioned is that many distros have MSR access as a module, and it s rarely loaded. If modules_disabled is already set, an attacker won t be able to load the MSR module to begin with. However, the other general-purpose vector, kexec, is still available. To prove out this method, Matthew wrote a proof-of-concept for changing kernel memory via kexec. Chrome OS is several steps ahead here, since it has hibernation disabled, MSR writing disabled, kexec disabled, modules verified, root filesystem read-only and verified, kernel verified, and firmware verified. But since not all my machines are Chrome OS, I wanted to look at some additional protections against kexec on general-purpose distro kernels that have CONFIG_KEXEC enabled, especially those without UEFI Secure Boot and Matthew s lockdown patch series. My goal was to disable kexec without needing to rebuild my entire kernel. For future kernels, I have proposed adding /proc/sys/kernel/kexec_disabled, a partner to the existing modules_disabled, that will one-way toggle kexec off. For existing kernels, things got more ugly. What options do I have for patching a running kernel? First I looked back at what I d done in the past with fixing vulnerabilities with systemtap. This ends up being a rather heavy-duty way to go about things, since you need all the distro kernel debug symbols, etc. It does work, but has a significant problem: since it uses kprobes, a root user can just turn off the probes, reverting the changes. So that s not going to work. Next I looked at ksplice. The original upstream has gone away, but there is still some work being done by Jiri Slaby. However, even with his updates which fixed various build problems, there were still more, even when building a 3.2 kernel (Ubuntu 12.04 LTS). So that s out too, which is too bad, since ksplice does exactly what I want: modifies the running kernel s functions via a module. So, finally, I decided to just do it by hand, and wrote a friendly kernel rootkit. Instead of dealing with flipping page table permissions on the normally-unwritable kernel code memory, I borrowed from PaX s KERNEXEC feature, and just turn off write protect checking on the CPU briefly to make the changes. The return values for functions on x86_64 are stored in RAX, so I just need to stuff the kexec_load syscall with mov -1, %rax; ret (-1 is EPERM):
#define pr_fmt(fmt) KBUILD_MODNAME ": " fmt
#include <linux/init.h>
#include <linux/module.h>
#include <linux/slab.h>
static unsigned long long_target;
static char *target;
module_param_named(syscall, long_target, ulong, 0644);
MODULE_PARM_DESC(syscall, "Address of syscall");
/* mov $-1, %rax; ret */
unsigned const char bytes[] =   0x48, 0xc7, 0xc0, 0xff, 0xff, 0xff, 0xff,
                                0xc3  ;
unsigned char *orig;
/* Borrowed from PaX KERNEXEC */
static inline void disable_wp(void)
 
        unsigned long cr0;
        preempt_disable();
        barrier();
        cr0 = read_cr0();
        cr0 &= ~X86_CR0_WP;
        write_cr0(cr0);
 
static inline void enable_wp(void)
 
        unsigned long cr0;
        cr0 = read_cr0();
        cr0  = X86_CR0_WP;
        write_cr0(cr0);
        barrier();
        preempt_enable_no_resched();
 
static int __init syscall_eperm_init(void)
 
        int i;
        target = (char *)long_target;
        if (target == NULL)
                return -EINVAL;
        /* save original */
        orig = kmalloc(sizeof(bytes), GFP_KERNEL);
        if (!orig)
                return -ENOMEM;
        for (i = 0; i < sizeof(bytes); i++)  
                orig[i] = target[i];
         
        pr_info("writing %lu bytes at %p\n", sizeof(bytes), target);
        disable_wp();
        for (i = 0; i < sizeof(bytes); i++)  
                target[i] = bytes[i];
         
        enable_wp();
        return 0;
 
module_init(syscall_eperm_init);
static void __exit syscall_eperm_exit(void)
 
        int i;
        pr_info("restoring %lu bytes at %p\n", sizeof(bytes), target);
        disable_wp();
        for (i = 0; i < sizeof(bytes); i++)  
                target[i] = orig[i];
         
        enable_wp();
        kfree(orig);
 
module_exit(syscall_eperm_exit);
MODULE_LICENSE("GPL");
MODULE_AUTHOR("Kees Cook <kees@outflux.net>");
MODULE_DESCRIPTION("makes target syscall always return EPERM");
If I didn t want to leave an obvious indication that the kernel had been manipulated, the module could be changed to: And with this in place, it s just a matter of loading it with the address of sys_kexec_load (found via /proc/kallsyms) before I disable module loading via modprobe. Here s my upstart script:
# modules-disable - disable modules after rc scripts are done
#
description "disable loading modules"
start on stopped module-init-tools and stopped rc
task
script
        cd /root/modules/syscall_eperm
        make clean
        make
        insmod ./syscall_eperm.ko \
                syscall=0x$(egrep ' T sys_kexec_load$' /proc/kallsyms   cut -d" " -f1)
        modprobe disable
end script
And now I m safe from kexec before I have a kernel that contains /proc/sys/kernel/kexec_disabled.

2013, Kees Cook. This work is licensed under a Creative Commons Attribution-ShareAlike 3.0 License.
Creative Commons License

Russ Allbery: krb5-sync 3.0

krb5-sync is the software we run at Stanford to synchronize principal information from a central Heimdal realm to Active Directory, allowing users to use either a Linux-based Kerberos environment or Active Directory with the same account and password. The original intent of this release was to add a new feature to allow a subsidiary instance of an account in the MIT or Heimdal realm to be synchronized with the instance-less account in Active Directory. This allows, for example, an rra/windows instance to be used to set and maintain the password for an rra principal in Active Directory. In the process of implementing that, though, I ended up doing a significant overall of the code, since the plugin architecture was quite awkward and dated. The code now uses the MIT Kerberos data structures in a more natural and native way, since MIT Kerberos has now added direct support for plugins of this sort. Kerberos contexts and Kerberos error codes are used uniformly throughout the plugin, which provides consistent and more robust error handling and reporting. I also significantly enhanced the test suite, although it still needs more work to test the core functionality that has complex external dependencies. This release also drops support for all versions of MIT Kerberos prior to 1.9, which required an external patch; to run krb5-sync 3.0, you should upgrade to a recent version of MIT Kerberos. This allowed me to drop support for the legacy API. There are a couple of major backward-incompatible changes in this release (and both unfortunately are not handled automatically by the Debian package upgrade, since it's hard to find and safely modify KDC configuration). First, the ad_ldap_base configuration option is now mandatory when synchronizing account status and its meaning has changed. Previously, dc elements for the realm were appended to a provided partial base. Now, the complete DN of the root of the Active Directory tree should be provided. This is more flexible and more useful with a wider variety of Active Directory setups. Second, I took advantage of the backward-incompatibilities to change the module name to sync.so from krb5_sync.so, since the latter sounded weirdly redundant and verbose when installed in the Kerberos plugin directory. This will require a configuration change to the plugin configuration for the KDC or kadmin server. Also in this release are a couple of new options: ad_queue_only, which forces all changes to be queued for later processing instead of processed in real time, and syslog, which can be used to turn off the internal syslog logging of non-errors from the module. (This is mostly useful for test suites.) Now, password changes are queued on any Active Directory failure, not just a few oddly-distinguished ones. The previous behavior was rather specific to Stanford's needs, and queuing all password changes shouldn't pose any problems. Finally, the krb5-sync-backend utility program for manipulating the queued changes has been completely rewritten and is much cleaner. It now uses the Net::Remctl::Backend Perl module for command and option handling, so that module (provided with remctl 3.4 or later) must be installed. It also requires IPC::Run, which is available from CPAN. It uniformly supports a -d option to specify the queue location, and skips event files during processing that no longer exist. You can get the latest release from krb5-sync distribution page.

8 December 2013

Russell Coker: A Basic Income for Australia

There has been a lot of discussion recently about the concept of a Basic Income (Wikipedia), largely due to the efforts to change the Swiss constitution to provide a Basic Income [1]. The concept of a Basic Income is that residents get a fixed payment without having to be sick, disabled, looking for work, or eligible for other forms of social security. A Basic Income wouldn t replace all other forms of social security, one of the most obvious examples is that sick people will often need money for medical care in additional to living expenses. Also I believe that it shouldn t be means tested in any way. I think that one of the problems with current payment schemes is that there are complex eligibility criteria which require effort for the applicant and for government agencies to prevent accidental or fraudulent over-payment. The tax rates could be raised slightly to make it revenue neutral. Newstart In Australia the main form of social security for unemployed people at the moment is called Newstart [2]. Currently Newstart payments range from a maximum of $501 per fortnight for a single person ($13,026 per annum), to a maximum of $699.90 per fortnight for someone who is a carer. The Newstart payments start to decrease if the recipient earns more than $62 per fortnight. The minimum wage in Australia is $16.37 per hour for permanent work or $20.30 for casual work [3]. So if someone works for more than 3 hours at a casual rate (and I can t imagine 4 hours a fortnight being anything other than casual) then their Newstart payments will decrease. The payment decreases are fairly significant, for every dollar that is earned about 50 cents will be deducted from the payments. That s a great incentive to either avoid opportunities to do part-time work or to do cash-only work that s outside the tax system. The most obvious way of implementing a Basic Income would be to replace Newstart. Then anyone who is in that situation would be free to just not get a job which would be OK IMHO as people who don t want to work probably wouldn t do a good job if the government forced them to get a job. People who are unemployed who want to work could work as much as they want and scale up according to what their employer asks and how much money they need. Currently the full-time minimum wage is $622.20 per week (I m not sure exactly how they get that from $16.37). That s almost 2.5* the Newstart allowance for a single person (but less than twice the Newstart allowance for a carer). While Newstart (and the other forms of social security) don t provide a great income, it seems that the difference between Newstart and the minimum wage isn t that great particularly when you consider that working involves some expenses for travel etc. There doesn t seem to be a great financial incentive for someone to leave Newstart and get a minimum wage job. People Who Want Social Security Some people think it s great to get government payments while others find it embarrassing to need such payments and won t necessarily apply if they are eligible. I think that the current system of forcing people to apply for social security is a way of discouraging people who find themselves unexpectedly in a difficult situation but doesn t discourage people who are happy not to work. This seems to effectively reduce the incidence of payments to the people who most tax-payers would regard as the most worthy recipients. Economics Charles Stross wrote about some ideas related to this [4]. He suggests that as the workforce participation has been steadily reducing due to technology we should move to a social model that isn t based around working to live but working to buy luxuries that aren t covered by the Basic Income. One of the many economic changes related to a Basic Income is that the minimum wage could be smaller than it might otherwise be. For example if the minimum wage was decreased by the same amount that the Basic Income provided then the minimum income would remain the same while employers would pay less, this would affect the viability of certain types of contract work web sites if they were subject to minimum wage laws (currently they just ignore the minimum wage laws by paying based on job completion instead of hours worked). I don t think that the minimum wage should decrease that much though, currently employers are able to run viable businesses with the minimum wage laws and I don t think that a Basic Income should be used as a way of helping corporations avoid paying their employees. If we had a Basic Income then there s many ways that it could be used to stabilise the economy. If people could pay their rent even if they lost their job then a down-turn in one area of the economy wouldn t immediately affect other areas. Also if rent payments were deducted automatically from an account used to receive the Basic Income then landlords would be more likely to rent to poor people as they could be guaranteed to receive rent payments (it would be easy to have a contractual agreement for rent to take priority and have bank computers enforce that). The Implementation Problem I don t think that my idea would have any significant negative effects. It wouldn t decrease government revenues if tax was adjusted accordingly. It wouldn t make people stop working as people who don t want to work already avoid it. It would help people who are out of work to get work by reducing the barriers to entry in terms of paperwork and of unreasonable cuts to Newstart making it bad value to take part time work. I think that the big problem with implementing it is people who want to prevent poor people from having opportunities. They want to reduce social security and minimum wages even though such changes will in the long run only give less tax revenue and greater expense in law enforcement. It seems rather ironic that such hostility often comes from people at the low end of the middle class whos jobs are most likely to be at risk from new technology. As on-going technological development reduces the number of workers that are required to keep things running we need to have some form of payment to the people who aren t doing enough work to survive. A decent Basic Income is a much better option than giving Newstart payments and forcing a significant portion of the population into a degrading search for jobs that don t exist. As that s the inevitable future I think we should make political changes to deal with it sooner rather than later. However a Basic Income might be implemented now it s surely going to be a lot better than what might happen if we wait until the majority of the population are unemployed before doing something about it.

7 December 2013

Daniel Pocock: Free calling from browser to mobile with free software

Lumicall is now offering free calls from browser to mobile. The whole service is powered by free software using open standards.
  • The person receiving the call must have the open source Lumicall app on their phone (Android and Cyanogenmod phones supported)
  • The person making the call just goes to http://webrtc.lumicall.org and dials the number in international format. For example, for the UK mobile 07123 45678, you need to dial +44712345678
Credits Various open source projects have made this possible, in particular: The service is enabled by WebRTC which is part of the latest HTML and JavaScript standards. You need to have the latest version of Mozilla Firefox, Google Chrome or another modern web browser supporting WebRTC - so there is no need to install any plugin. Feedback and discussion Please come and join us on the mailing list for any of the third-party projects that are involved. Please also join the Free real-time communications list sponsored by the FSF Europe for any general discussion about the future of free communications with free software. WebRTC Conference this week I'll be presenting some of my own work with WebRTC at the WebRTC Conference and Exhibition 2013 in Paris this week. Various other free software developers are also in the program, including Ludovic Dubost from xWiki and Emil Ivov from Jitsi

6 December 2013

Steve Kemp: So PaaS

I just realised a lot of my projects are deployed in the same way: This includes both Apache-based projects, and node.js projects. I'm sure I could generalize this, and do clever things with git-hooks. Right now for example I have run-scripts which look like this:

#!/bin/sh
#
# /etc/service/blogspam.js/run - Runs the blogspam.net API.
#
# update the repository.
git pull --update --quiet
# install dependencies, if appropriate.
npm install
# launche
exec node server.js
It seems the only thing that differs is the name of the directory and the remote git clone URL. With a bit of scripting magic I'm sure you could push applications to a virgin Debian installation and have it do the right thing. I think the only obvious thing I'm missing is a list of Debian dependencies. Perhaps adding soemthing like the packages.json file I could add an extra step:
apt-get update -qq
apt-get install --yes --force-yes $(cat packages.apt)
Making deployments easy is a good thing, and consistency helps..

Petter Reinholdtsen: Debian Edu interview: Klaus Knopper

It has been a while since I managed to publish the last interview, but the Debian Edu / Skolelinux community is still going strong, and yesterday we even had a new school administrator show up on #debian-edu to share his success story with installing Debian Edu at their school. This time I have been able to get some helpful comments from the creator of Knoppix, Klaus Knopper, who was involved in a Skolelinux project in Germany a few years ago. Who are you, and how do you spend your days? I am Klaus Knopper. I have a master degree in electrical engineering, and is currently professor in information management at the university of applied sciences Kaiserslautern / Germany and freelance Open Source software developer and consultant. All of this is pretty much of the work I spend my days with. Apart from teaching, I'm also conducting some more or less experimental projects like the Knoppix GNU/Linux live system (Debian-based like Skolelinux), ADRIANE (a blind-friendly talking desktop system) and LINBO (Linux-based network boot console, a fast remote install and repair system supporting various operating systems). How did you get in contact with the Skolelinux / Debian Edu project? The credit for this have to go to Kurt Gramlich, who is the German coordinator for Skolelinux. We were looking for an all-in-one open source community-supported distribution for schools, and Kurt introduced us to Skolelinux for this purpose. What do you see as the advantages of Skolelinux / Debian Edu? What do you see as the disadvantages of Skolelinux / Debian Edu? For these reasons and experience from our project, I would now rather consider using plain Debian for schools next time, until Skolelinux is more closely integrated into Debian and becomes upgradeable without reinstallation. Which free software do you use daily? GNU/Linux with LXDE desktop, bash for interactive dialog and programming, texlive for documentation and correspondence, occasionally LibreOffice for document format conversion. Various programming languages for teaching. Which strategy do you believe is the right one to use to get schools to use free software? Strong arguments are

5 December 2013

Daniel Kahn Gillmor: The legal utility of deniability in secure chat

This Monday, I attended a workshop on Multi-party Off the Record Messaging and Deniability hosted by the Calyx Institute. The discussion was a combination of legal and technical people, looking at how the characteristics of this particular technology affect (or do not affect) the law. This is a report-back, since I know other people wanted to attend. I'm not a lawyer, but I develop software to improve communications security, I care about these questions, and I want other people to be aware of the discussion. I hope I did not misrepresent anything below. I'd be happy if anyone wants to offer corrections. BackgroundOff the Record Messaging (OTR) is a way to secure instant messaging (e.g. jabber/XMPP, gChat, AIM). The two most common characteristics people want from a secure instant messaging program are:
Authentication
Each participant should be able to know specifically who the other parties are on the chat.
Confidentiality
The content of the messages should only be intelligible to the parties involved with the chat; it should appear opaque or encrypted to anyone else listening in. Note that confidentiality effectively depends on authentication -- if you don't know who you're talking to, you can't make sensible assertions about confidentiality.
As with many other modern networked encryption schemes, OTR relies on each user maintaining a long-lived "secret key", and publishing a corresponding "public key" for their peers to examine. These keys are critical for providing authentication (and by extension, for confidentiality). But OTR offers several interesting characteristics beyond the common two. Its most commonly cited characteristics are "forward secrecy" and "deniability".
Forward secrecy
Assuming the parties communicating are operating in good faith, forward secrecy offers protection against a special kind of adversary: one who logs the encrypted chat, and subsequently steals either party's long-term secret key. Without forward secrecy, such an adversary would be able to discover the content of the messages, violating the confidentiality characteristic. With forward secrecy, this adversary is be stymied and the messages remain confidential.
Deniability
Deniability only comes into play when one of the parties is no longer operating in good faith (e.g. their computer is compromised, or they are collaborating with an adversary). In this context, if Alice is chatting with Bob, she does not want Bob to be able to cryptographically prove to anyone else that she made any of the specific statements in the conversation. This is the focus of Monday's discussion. To be clear, this kind of deniability means Alice can correctly say "you have no cryptographic proof I said X", but it does not let her assert "here is cryptographic proof that I did not say X" (I can't think of any protocol that offers the latter assertion). The opposite of deniability is a cryptographic proof of origin, which usually runs something like "only someone with access to Alice's secret key could have said X."
The traditional two-party OTR protocol has offered both forward secrecy and deniability for years. But deniability in particular is a challenging characteristic to provide for group chat which is the domain of Multi-Party OTR (mpOTR). You can read some past discussion about the challenges of deniability in mpOTR (and why it's harder when there are more than two people chatting) from the otr-users mailing list. If you're not doing anything wrong... The discussion was well-anchored by a comment from another participant who cheekily asked "If you're not doing anything wrong, why do you need to hide your chat at all, let alone be able to deny it?" The general sense of the room was that we'd all heard this question many times, from many people. There are lots of problems with the ideas behind the question from many perspectives. But just from a legal perspective, there are at least two problems with the way this question is posed: In these situations, people confront real risk from the law. If we care about these people, we need to figure out if we can build systems to help them reduce that legal risk (of course we also need to fix broken laws, and the legal environment in general, but those approaches were out of scope for this discussion). The Legal Utility of Deniability Monday's meeting was called specifically because it wasn't clear how much real-world usefulness there is in the "deniability" characteristic, and whether this feature is worth the development effort and implementation tradeoffs required. In particular, the group was interested in deniability's utility in legal contexts; many (most?) people in the room were lawyers, and it's also not clear that deniability has much utility outside of a formal legal setting. If your adversary isn't constrained by some rule of law, they probably won't care at all whether there is a cryptographic proof or not that you wrote a particular message (In retrospect, one possible exception is exposure in the media, but we did not discuss that scenario). Places of possible usefulness So where might deniability come in handy during civil litigation or a criminal trial? Presumably the circumstance is that a piece of a chat log is offered as incriminating evidence, and the defendant is trying to deny something that they appear to have said in the log. This denial could take place in two rather different contexts: during rules over admissibility of evidence, or (once admitted) in front of a jury. In legal wrangling over admissibility, apparently a lot of horse-trading can go on -- each side concedes some things in exchange for the other side conceding other things. It appears that cryptographic proof of origin (that is, a lack of deniability) on the chat logs themselves might reduce the amount of leverage a defense lawyer can get from conceding or arguing strongly over that piece of evidence. For example, if the chain of custody of a chat transcript is fuzzy (i.e. the transcript could have been mishandled or modified somehow before reaching trial), then a cryptographic proof of origin would make it much harder for the defense to contest the chat transcript on the grounds of tampering. Deniability would give the defense more bargaining power. In arguing about already-admitted evidence before a jury, deniability in this sense seems like a job for expert witnesses, who would need to convince the jury of their interpretation of the data. There was a lot of skepticism in the room over this, both around the possibility of most jurors really understanding what OTR's claim of deniability actually means, and on jurors' ability to distinguish this argument from a bogus argument presented by an opposing expert witness who is willing to lie about the nature of the protocol (or who misunderstands it and passes on their misunderstanding to the jury). The complexity of the tech systems involved in a data-heavy prosecution or civil litigation are themselves opportunities for lawyers to argue (and experts to weigh in) on the general reliability of these systems. Sifting through the quantities of data available and ensuring that the appropriate evidence is actually findable, relevant, and suitably preserved for the jury's inspection is a hard and complicated job, with room for error. OTR's deniability might be one more element in a multi-pronged attack on these data systems. These are the most compelling arguments for the legal utility of deniability that I took away from the discussion. I confess that they don't seem particularly strong to me, though some level of "avoiding a weaker position when horse-trading" resonates with me. What about the arguments against its utility? Limitations The most basic argument against OTR's deniability is that courts don't care about cryptographic proof for digital evidence. People are convicted or lose civil cases based on unsigned electronic communications (e.g. normal e-mail, plain chat logs) all the time. OTR's deniability doesn't provide any legal cover stronger than trying to claim you didn't write a given e-mail that appears to have originated from your account. As someone who understands the forgeability of e-mail, i find this overall situation troubling, but it seems to be where we are. Worse, OTR's deniability doesn't cover whether you had a conversation, just what you said in that conversation. That is, Bob can still cryptographically prove to an adversary (or before a judge or jury) that he had a communication with someone controlling Alice's secret key (which is probably Alice); he just can't prove that Alice herself said any particular part of the conversation he produces. Additionally, there are runtime tradeoffs depending on how the protocol manages to achieve these features. For example, forward secrecy itself requires an additional round trip or two when compared to authenticated, encrypted communications without forward secrecy (a "round trip" is a message from Alice to Bob followed by a message back from Bob to Alice). Getting proper deniability into the mpOTR spec might incur extra latency (imagine having to wait 60 seconds after everyone joins before starting a group chat, or a pause in the chat of 15 seconds when a new member joins) or extra computational power (meaning that they might not work well on slower/older devices) or an order of magnitude more bandwidth (meaning that chat might not work at all on a weak connection). There could also simply be complexity that makes it harder to correctly implement a protocol with deniability than an alternate protocol without deniability. Incorrectly-implemented software can put its users at risk. I don't know enough about the current state of mpOTR to know what the specific tradeoffs are for the deniability feature, but it's clear there will be some. Who decides whether the tradeoffs are worth the feature? Other kinds of deniability Further weakening the case for the legal utility of OTR's deniability, there seem to be other ways to get deniability in a legal context over a chat transcript. There are deniability arguments that can be made from outside the protocol. For example, you can always claim someone else took control of your computer while you were asleep or using the bathroom or eating dinner, or you can claim that your computer had a virus that exported your secret key and it must have been used by someone else. If you're desperate enough to sacrifice your digital identity, you could arrange to have your secret key published, at which point anyone can make signed statements with it. Having forward secrecy makes it possible to expose your secret key without exposing the content of your past communications to any listener who happened to log them. Conclusion My takeaway from the discussion is that the legal utility of OTR's deniability is non-zero, but quite low; and that development energy focused on deniability is probably only justified if there are very few costs associated with it. Several folks pointed out that most communications-security tools are too complicated or inconvenient to use for normal people. If we have limited development energy to spend on securing instant messaging, usability and ubiquity would be a better focus than this form of deniability. Secure chat systems that take too long to make, that are too complex, or that are too cumbersome are not going to be adopted. But this doesn't mean people won't chat at all -- they'll just use cleartext chat, or maybe they'll use supposedly "secure" protocols with even worse properties: for example, without proper end-to-end authentication (permitting spoofing or impersonation by the server operator or potentially by anyone else); with encryption that is reversible by the chatroom operator or flawed enough to be reversed by any listener with a powerful computer; without forward secrecy; or so on. As a demonstration of this, we heard some lawyers in the room admit to using Skype to talk with their clients even though they know it's not a safe communications channel because their clients' adversaries might have access to the skype messaging system itself. My conclusion from the meeting is that there are a few particular situations where deniability could be useful legally, but that overall, it is not where we as a community should be spending our development energy. Perhaps in some future world where all communications are already authenticated, encrypted, and forward-secret by default, we can look into improving our protocols to provide this characteristic, but for now, we really need to work on usability, popularization, and wide deployment. Thanks Many thanks to Nick Merrill for organizing the discussion, to Shayana Kadidal and Stanley Cohen for providing a wealth of legal insight and legal experience, to Tom Ritter for an excellent presentation of the technical details, and to everyone in the group who participated in the interesting and lively discussion. Tags: chat, deniability, otr, security

4 December 2013

Aigars Mahinovs: Translation management workflows

Whatever you do with translations, consider translation management issues. For example, you are developing a multilingual web site. All kinds of labels and buttons and form fields are nicely translatable with trans template tag and ugettext. You have po files that follow your code from dev to stage to production environment.
Now you add a CMS into the mix. And suddenly - you translations are in more than one place, in more than one format and follow different routes to production.
Now imagine that you need to add Chinese language to your entire site. The translator is an off-site contractor. What files would you send to him to translate? How would you generate them? How will you integrate them?
If someone adds or changes a page on production in English: how will your developers see that change? how will you know that an updated translation for Chinese is needed? how will you manage the update of the translation?
If you make a CMS and don't have at least the export_po_file and import_po_file management commands, then you are not really multilingual. It is either that or figuring out your own answer for the above questions.
I have finally found a Django-based CMS that has those - http://pythonhosted.org/django-page-cms/ . Have not really tried it yet, but I am hopeful.

Next.

Previous.