Search Results: "ana"

13 June 2016

Satyam Zode: GSoC 2016 Week 2 and 3: Reproducible Builds in Debian

This is report on my previous week activities with Debian Reproducible-Builds. In last 10 days, I had build different Debain packages at my own using prebuilder to experience the reproducibility issues. I am thankful to deki and Lunar for suggesting me to do that task. Based on this experience, I managed to find more use cases for hide=profiles specification. I also researched differences of different unreproducible Debian packages on http://tests.reproducible-builds.org . There are many packages available for examination. In brief I did following tasks: Upcoming week will be an important as well as fun week because I will be implementing the use cases. Right now, I am currently looking at different softwares which ignores stuff and taking notes of it. So that, it will help me during implementing solution of use cases. I am also looking forward to feedback from community on use cases and CLI interfaces. Have a great week :)

Raphaël Hertzog: Freexian s report about Debian Long Term Support, May 2016

A Debian LTS logoLike each month, here comes a report about the work of paid contributors to Debian LTS. Individual reports In May, 166 work hours have been dispatched among 9 paid contributors. Their reports are available: Evolution of the situation The number of sponsored hours stayed the same over May but will likely increase a little bit the next month as we have two new Bronze sponsors being processed. The security tracker currently lists 36 packages with a known CVE and the dla-needed.txt file lists 36 packages awaiting an update. Despite the higher than usual number of work hours dispatched in May, we still have more open CVE than we used to have at the end of the squeeze LTS period. So more support is always needed Thanks to our sponsors New sponsors are in bold.

No comment Liked this article? Click here. My blog is Flattr-enabled.

Keerthana Krishnan: Installing reSIProcate with apt-get source package

I had earlier tried to install telepathy according to the instructions I found here. But that gave me a an unexplainable error. So after a few unsuccessful attempts, I decided to install it from the apt-get source. First, install telepathy-qt. This is the part that gave me all the errors and this is where I had made changes from the source I had been using.
  1. Check and make sure you have the proper dependencies installed for the package.
    $ sudo apt-get build-dep telepathy-qt
  2. If you are installing the package in the home folder, you can skip this step, but usually, it s better to have a dedicated file/file structure. If you do have one, cd into that folder
    $ mkdir ~/telepathy-qt-stuff
    $ cd ~/telepathy-qt-stuff
  3. Next, get telepathy-qt from the source :
    $ apt-get source telepathy-qt
    $ apt-get source -b telepathy-qt
  4. Check and make sure that there are a list of libtelepathy-qt* and telepathy-qt* .deb packages. You just have to install a few more packages:
    $ ls *.deb
  5. Next, you have to install a few more packages:
    $ dpkg -i libtelepathy-qt4-2_0.9.6.1-?_amd64.deb libtelepathy-qt4-dev_0.9.6.1-?_amd64.deb libtelepathy-qt4-farstream2_0.9.6.1-?_amd64.deb

    Obviously, we have to replace the ? with the version number of the .deb package.
  6. After that you have the necessary packages to install reSIProcate:
    $ dpkg -l grep telepathy-qt
    This should return something like :
    ii libtelepathy-qt4-2:amd64 0.9.6.1-2 amd64 Telepathy framework Qt 4 library
    ii libtelepathy-qt4-dev 0.9.6.1-2 amd64 Qt 4 Telepathy library (headers and static library)
    ii libtelepathy-qt4-farstream2:amd64 0.9.6.1-2 amd64 Telepathy/Farsight integration Qt 4 library
The next part is to install and configure reSIProcate.
  1. Include the proper backport line in the /etc/apt/sources.list file. Be sure to run sudo apt-get update after any changes to the source file
  2. Clone the code from the git repo :
    $ git clone https://github.com/resiprocate/resiprocate
    $ cd resiprocate
  3. Check the build dependencies and install what s required:
    $ apt-get install libpq-dev dh-autoreconf
    $ apt-get build-dep resiprocate
    $ apt-get install -t jessie-backports libradcli-dev
  4. Build the packages:
    $ ./build/debian.sh
    $ sudo make
  5. Finally, ensure all your packages are built right by running sudo make check
And then you re done!

Keerthana Krishnan: A beginner s guide to Debian Source Packages

Source packages have a very different process of installation and handling while compared to the traditional executable packages which are handled by the sudo apt-get install command. Source packages provide source for a software. These are used to build other packages. Source code can be studied or errors can be fixed in this by downloading these to your system. To access these you have to add deb-src lines sources.list in /etc/apt/sources.list If you had followed my earlier article on setting up Jessie, this means you have to remove the # in front of the deb-src lines. First, find the required source package online in the debian packages list here. Be sure to select the Source Package Names option while searching. When you find a package it will have a list of binary packages that are built from this source package. Make sure you have all the dependencies to build the package by running:
     $ apt-get build-dep packagename
Then, download the source package, using the following command:
     $ apt-get source packagename
This will download three files: a .orig.tar.gz, a .dsc and a .diff.gz. In the case of packages made specifically for Debian, the last of these is not downloaded and the first usually won t have orig in the name. The .dsc file is used by dpkg-source for unpacking the source package into the directory packagename-version. Within each downloaded source package there is a debian/ directory that contains the files needed for creating the .deb package. To auto-build the package when it s been downloaded, just add -b to the command line, like this:
     $ apt-get -b source packagename
If you decide not to create the .deb at the time of the download, you can create it later by running:
     $ dpkg-buildpackage -rfakeroot -uc -b
from within the directory that was created for the package after downloading. To install the package built by the commands above one must use the package manager directly, like this:
     # dpkg -i file.deb
There s a difference between apt-get s source method and its other methods. The source method can be used by normal users, without needing special root powers. The files are downloaded to the directory from which the apt-get source package command was called. Tip : If you are a developer testing software, you may need to run the make command after this. Be sure to run make check as well later to make sure there are no errors and everything is alright. Most of the commands I ve used here was by following the APT How To documentation which is marked as obsolete for some reason but turned out to be pretty useful. Hope it works for you too!

12 June 2016

Iustin Pop: Elsa Bike Trophy 2016 my first bike race!

Elsa Bike Trophy 2016 my first bike race! So today, after two months of intermittent training using Zwift and some actual outside rides, I did my first bike race. Not of 2016, not of 2000+, but like ever. Which is strange, as I learned biking very young, and I did like to bike. But as it turned out, even though I didn't like running as a child, I did participate in a number of running events over the years, but no biking ones. The event Elsa Bike Trophy is a mountain bike event cross-country, not downhill or anything crazy; it takes part in Estavayer-le-Lac, and has two courses - one 60Km with 1'791m altitude gain, and a smaller one of 30Km with 845m altitude gain. I went, of course, for the latter. 845m is more than I ever did in a single ride, so it was good enough for a first try. The web page says that this smaller course est nerveux, technique et ne laisse que peu de r pit . I choose to think that's a bit of an exaggeration, and that it will be relatively easy (as I'm not too skilled technically). The atmosphere there was like for the running races, with the exception of bike stuff being sold, and people on very noisy rollers. I'm glad for my trainer which sounds many decibels quieter The long race started at 12:00, and the shorter one at 12:20. While waiting for the start I had to concerns in mind: whether I'm able to do the whole course (endurance), and whether it will be too cold (the weather kept moving towards rain). I had a small concern about the state of the course, as it was not very nice weather recently, but a small one. And then, after one hour plus of waiting, go! Racing, with a bit of "swimming" At first thing went as expected. Starting on paved roads, moving towards the small town exit, a couple of 14% climbs, then more flat roads, then a nice and hard 18% short climb (I'll never again complain about < 10%!), then entering the woods. It became quickly apparent that the ground in the forest was in much worse state than I feared. Much worse as in a few orders of magnitude. In about 5 minutes after entering the tree cover, my reasonably clean, reasonably light bike became a muddy, heavy monster. And the pace that until then went quite OK became walking pace, as the first rider that didn't manage to keep going up because the wheel turned out of the track blocked the one behind him, which had to stop, and repeat until we were one line (or two, depending on how wide the trail was) of riders walking their bikes up. While on dry ground walking your bike up is no problem, or hiking through mud with good hiking shoes is also no problem, walking up with biking shoes is a pain. Your foot slides and you waste half of your energy "swimming" in the mud. Once the climb is over, you get on the bike, and of course the pedals and cleats are full of heavy mud, so it takes a while until you can actually clip in. Here the trail version of SPD was really useful, as I could pedal reasonably well without being clipped-in, just had to be careful and push too hard. Then maybe you exit the trail and get on paved road, but the wheels are so full of mud that you still are very slow (and accelerate very slowly), until the shed enough of the mud to become somewhat more "normal". After a bit of this "up through mud, flat and shedding mud", I came upon the first real downhill section. I would have been somewhat confident in dry ground, but I got scared and got off my bike. Better safe than sorry was the thing for now. And after this is was a repetition of the above: climb, sometimes (rarely) on the bike, most times pushing the bike, fast flat sections through muddy terrain where any mistake of controlling the bike can send the front wheel flying due to the mud being highly viscous, slow flat sections through very liquid mud where it definitely felt like swimming, or any dry sections. My biggest fear, uphill/endurance, was unfounded. The most gains I made were on the dry uphills, where I had enough stamina to overtake. On flat ground I mostly kept order (i.e. neither being overtaken nor overtaking), but on downhill sections, I lost lots of time, and was overtaken a lot. Still, it was a good run. And then, after about 20 kilometres out of the 30, I got tired enough of getting off the bike, on the bike, and also tired mentally and not being careful enough, that I stopped getting off the bike on downhills. And the feeling was awesome! It was actually much much easier to flow through the mud and rocks and roots on downhill, even when it was difficult (for me) like 40cm drops (estimated), than doing it on foot, where you slide without control and the bike can come crashing down on you. It was a liberating feel, like finally having overcome the mud. I was soo glad to have done a one-day training course with Swiss Alpine Adventure, as it really helped. Thanks Dave! Of course, people were still overtaking me, but I also overtook some people (who were on foot; he he, I wasn't the only one it seems). And being easier, I had some more energy so I was able to push a bit harder on the flats and dry uphill sections. And then the remaining distance started shrinking, and the last downhill was over, I entered through familiar roads the small town, a passer-by cries "one kilometre left", I push hard (I mean, hard as I could after all the effort), and I reach the finish. Oh, and my other concern, the rain? Yes it did rain somewhat, and I was glad for it (I keep overheating); there was a single moment I felt cold, when exiting a nice cosy forest into a field where the wind was very strong headwind, of course. Lessons learned I did learn a lot in this first event. Results So, how did I do after all? As soon as I reached the finish and recovered my items, among which the phone, I checked the datasport page: I was rank 59/68 in my category. Damn, I hoped (and thought) I would do better. Similar % in the overall ranking for this distance. That aside, it was mighty fun. So much fun I'd do it again tomorrow! I forgot the awesome atmosphere of such events, even in the back of the rankings. And then, after I reach drive home and open on my workstation the datasport page, I get very confused: the overall number of participants was different. And the I realised: not everybody finished the race when I first checked (d'oh)! Final ranking: 59 out of 84 in my category, and 247/364 in the overall 30km rankings. That makes it 70% and 67% respectively, which matches somewhat with my usual running results a few years back (but a bit worse). It is in any case better than what I thought originally, yay! Also, Strava activity for some more statistics (note that my Garmin says it was not 800+ meters of altitude ): I'd embed a Veloviewer nice 3D-map but I can't seem to get the embed option, hmm TODO: train more endurance, train more technique, train in more various conditions!

Mario Lang: A Raspberry Pi Zero in a Handy Tech Active Star 40 Braille Display

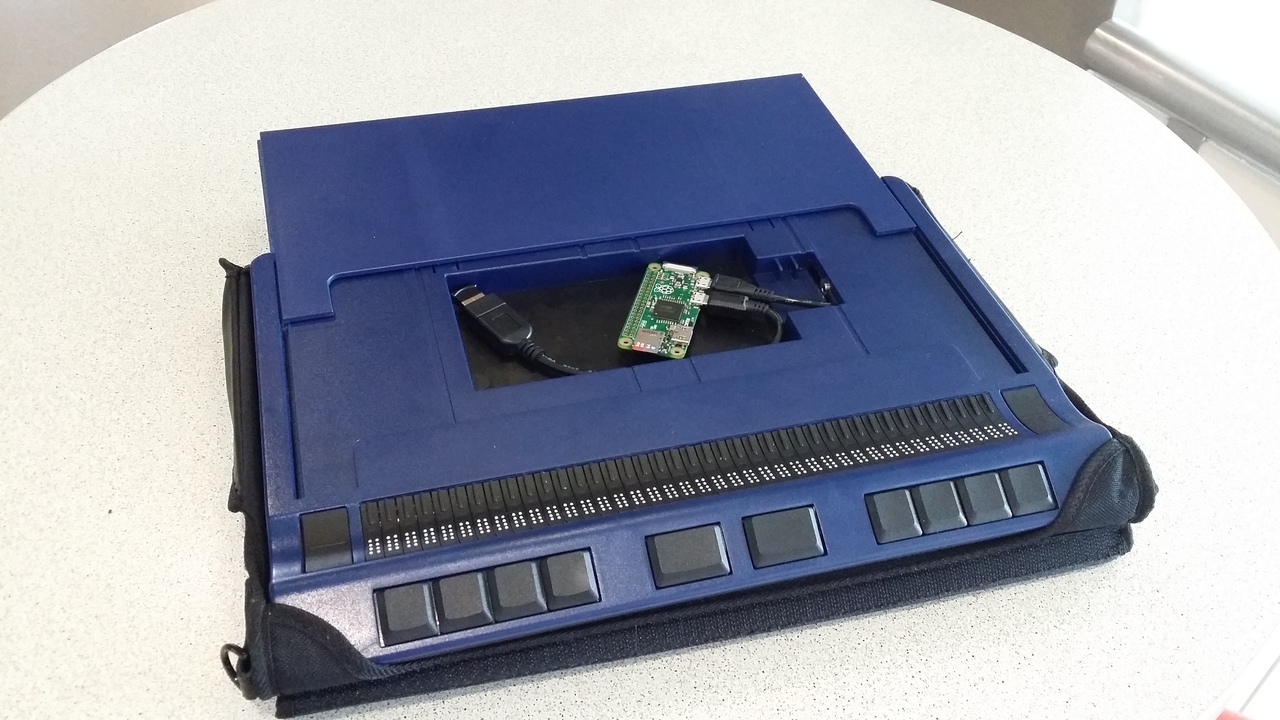
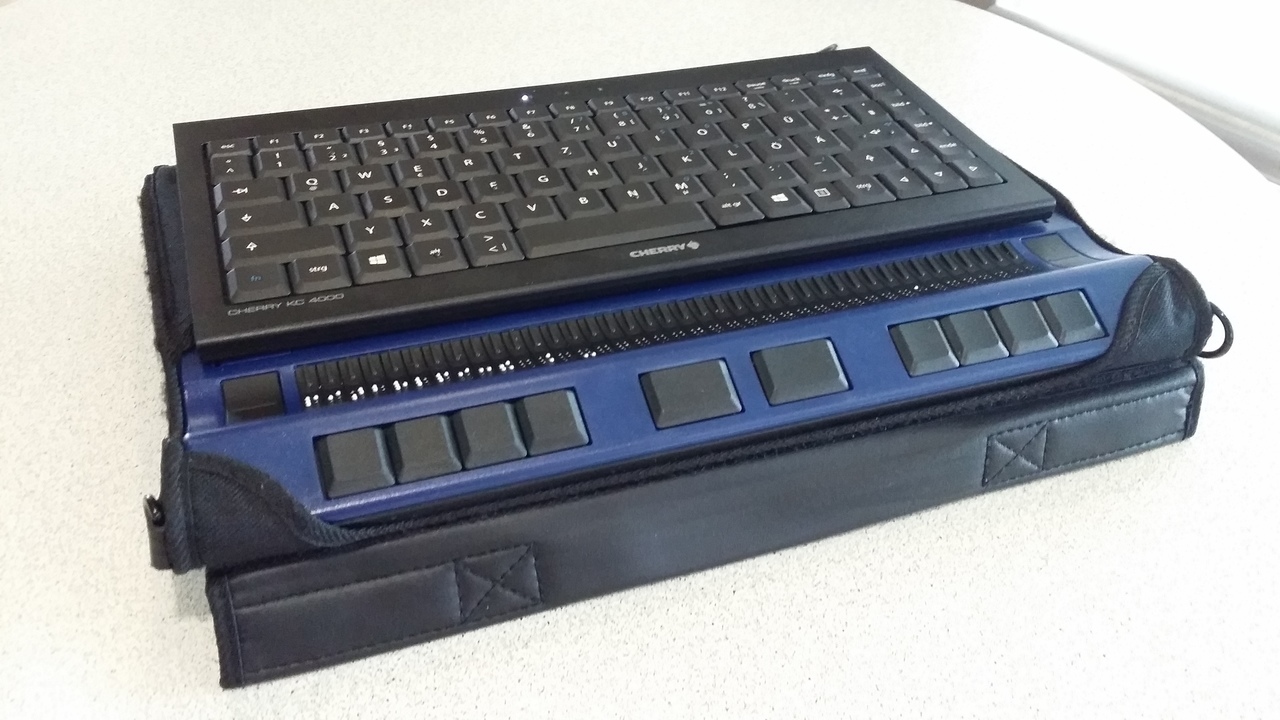
TL;DR: I put a $5 Raspberry Pi Zero, a Bluetooth USB dongle, and the required adapter cable into my new Handy Tech Active Star 40 braille display. An internal USB port provides the power. This has transformed my braille display into an ARM-based, monitorless, Linux laptop that has a keyboard and a braille display. It can be charged/powered via USB so it can also be run from a power bank or a solar charger, thus potentially being able to run for days, rather than just hours, without needing a standard wall-jack. [picture: a Raspberry Pi Zero embedded within an Active Star 40] [picture: a braille display with a keyboard on top and a Raspberry Pi Zero inside]
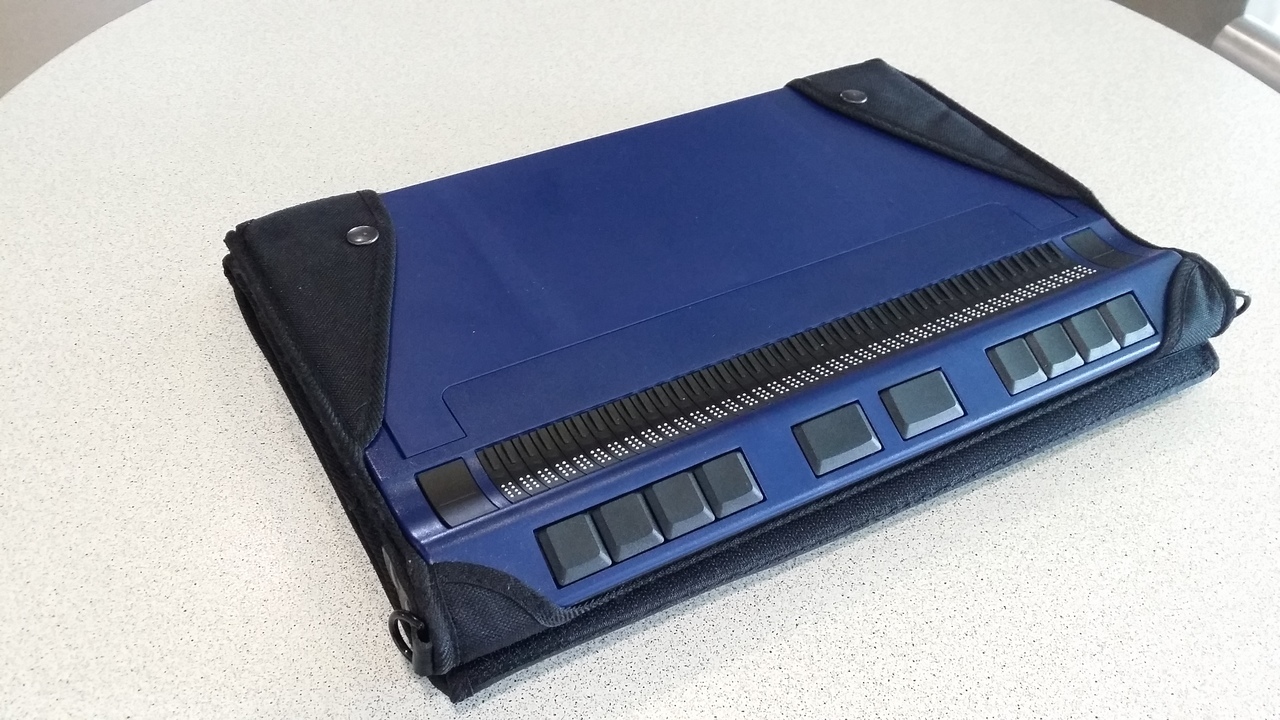
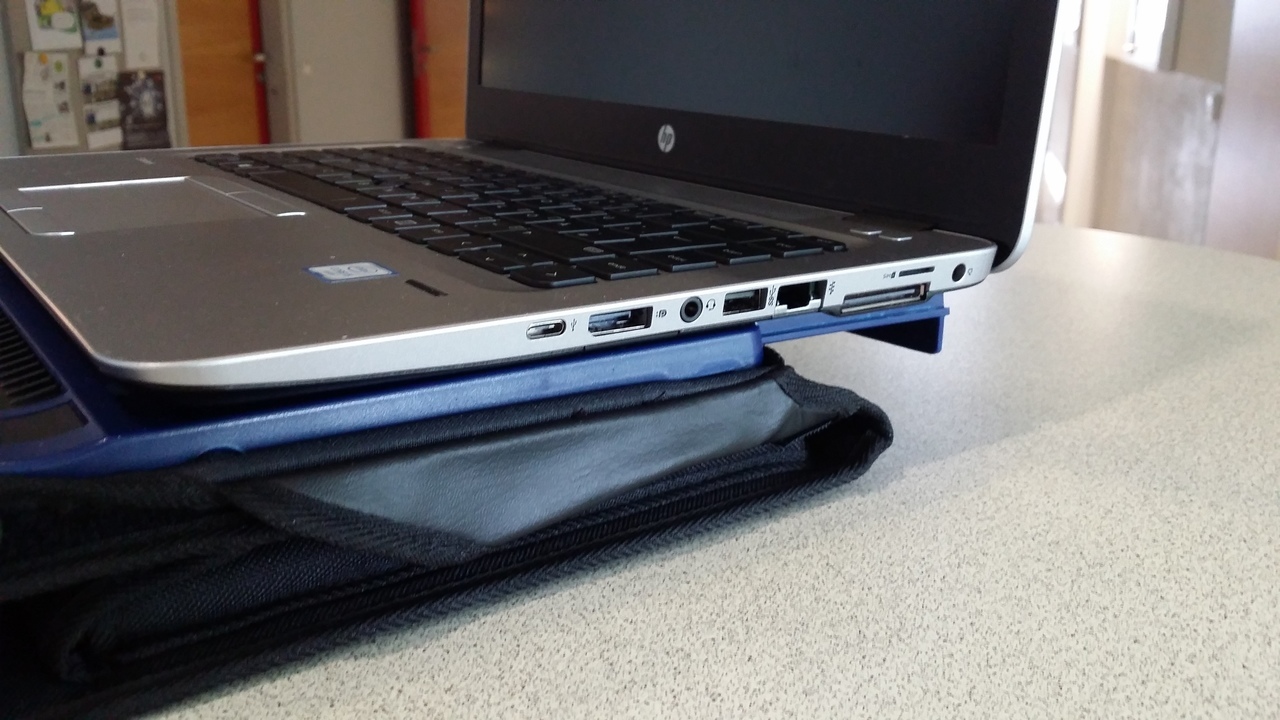
Some Background on Braille Display Form Factors Braille displays come in various sizes. There are models tailored for desktop use (with 60 cells or more), models tailored for portable use with a laptop (usually with 40 cells), and, nowadays, there are even models tailored for on-the-go use with a smartphone or similar (with something like 14 or 18 cells). Back in the old days, braille displays were rather massive. A 40-cell braille display was typically about the size of a 13" laptop. In modern times, manufacturers have managed to reduce the size of the internals such that a 40-cell display can be placed in front of a laptop or keyboard instead of placing the laptop on top of the braille display. While this is a nice achievement, I personally haven't found it to be very convenient because you now have to place two physically separate devices on your lap. It's OK if you have a real desk, but, at least in my opinion, if you try to use your laptop as its name suggests, it's actually inconvenient to use a small form factor, 40-cell display. For this reason, I've been waiting for a long-promised new model in the Handy Tech Star series. In 2002, they released the Handy Tech Braille Star 40, which is a 40-cell braille display with enough space to put a laptop directly on top of it. To accommodate larger laptop models, they even built in a little platform at the back that can be pulled out to effectively enlarge the top surface. Handy Tech has now released a new model, the Active Star 40, that has essentially the same layout but modernized internals. [picture: a plain Active Star 40] You can still pull out the little platform to increase the space that can be used to put something on top. [picture: an Active Star 40 with extended platform and a laptop on top] But, most conveniently, they've designed in an empty compartment, roughly the size of a modern smartphone, beneath the platform. The original idea was to actually put a smartphone inside, but this has turned out (at least to me) to not be very feasible. Fortunately, they thought about the need for electricity and added a Micro USB cable terminating within the newly created, empty compartment. My first idea was to put a conventional Raspberry Pi inside. When I received the braille display, however, we immediately noticed that a standard-sized rpi is roughly 3mm too high to fit into the empty compartment. Fortunately, though, a co-worker noticed that the Raspberry Pi Zero was available for order. The Raspberry Pi Zero is a lot thinner, and fits perfectly inside (actually, I think there's enough space for two, or even three, of them). So we ordered one, along with some accessories like a 64GB SDHC card, a Bluetooth dongle, and a Micro USB adapter cable. The hardware arrived a few days later, and was immediately bootstrapped with the assistance of very helpful friends. It works like a charm!
Technical Details The backside of the Handy Tech Active Star 40 features two USB host ports that can be used to connect devices such as a keyboard. A small form-factor, USB keyboard with a magnetic clip-on is included. When a USB keyboard is connected, and when the display is used via Bluetooth, the braille display firmware additionally offers the Bluetooth HID profile, and key press/release events received via the USB port are passed through to it. I use the Bluetooth dongle for all my communication needs. Most importantly, BRLTTY is used as a console screen reader. It talks to the braille display via Bluetooth (more precisely, via an RFCOMM channel). The keyboard connects through to Linux via the Bluetooth HID profile. Now, all that is left is network connectivity. To keep the energy consumption as low as possible, I decided to go for Bluetooth PAN. It appears that the tethering mode of my mobile phone works (albeit with a quirk), so I can actually access the internet as long as I have cell phone reception. Additionally, I configured a Bluetooth PAN access point on my desktop machines at home and at work, so I can easily (and somewhat more reliably) get IP connectivity for the rpi when I'm near one of these machines. I plan to configure a classic Raspberry Pi as a mobile Bluetooth access point. It would essentially function as a Bluetooth to ethernet adapter, and should allow me to have network connectivity in places where I don't want to use my phone.
BlueZ 5 and PAN It was a bit challenging to figure out how to actually configure Bluetooth PAN with BlueZ 5. I found the bt-pan python script (see below) to be the only way so far to configure PAN without a GUI. It handles both ends of a PAN network, configuring a server and a client. Once instructed to do so (via D-Bus) in client mode, BlueZ will create a new network device - bnep0 - once a connection to a server has been established. Typically, DHCP is used to assign IP addresses for these interfaces. In server mode, BlueZ needs to know the name of a bridge device to which it can add a slave device for each incoming client connection. Configuring an address for the bridge device, as well as running a DHCP server + IP Masquerading on the bridge, is usually all you need to do.
A Bluetooth PAN Access Point with Systemd I'm using systemd-networkd to configure the bridge device. /etc/systemd/network/pan.netdev:
[NetDev]
Name=pan
Kind=bridge
ForwardDelaySec=0
/etc/systemd/network/pan.network:
[Match]
Name=pan
[Network]
Address=0.0.0.0/24
DHCPServer=yes
IPMasquerade=yes
Now, BlueZ needs to be told to configure a NAP profile. To my surprise, there seems to be no way to do this with stock BlueZ 5.36 utilities. Please correct me if I'm wrong. Luckily, I found a very nice blog post, as well as an accommodating Python script that performs the required D-Bus calls. For convenience, I use a Systemd service to invoke the script and to ensure that its dependencies are met. /etc/systemd/system/pan.service:
[Unit]
Description=Bluetooth Personal Area Network
After=bluetooth.service systemd-networkd.service
Requires=systemd-networkd.service
PartOf=bluetooth.service
[Service]
Type=notify
ExecStart=/usr/local/sbin/pan
[Install]
WantedBy=bluetooth.target
/usr/local/sbin/pan:
#!/bin/sh
# Ugly hack to work around #787480
iptables -F
iptables -t nat -F
iptables -t mangle -F
iptables -t nat -A POSTROUTING -o eth0 -j MASQUERADE
exec /usr/local/sbin/bt-pan --systemd --debug server pan
This last file wouldn't be necessary if IPMasquerade= were supported in Debian right now (see #787480). After the obligatory systemctl daemon-reload and systemctl restart systemd-networkd, you can start your Bluetooth Personal Area Network with systemctl start pan.
Bluetooth PAN Client with Systemd Configuring the client is also quite easy to do with Systemd. /etc/systemd/network/pan-client.network:
[Match]
Name=bnep*
[Network]
DHCP=yes
/etc/systemd/system/pan@.service:
[Unit]
Description=Bluetooth Personal Area Network client
[Service]
Type=notify
ExecStart=/usr/local/sbin/bt-pan --debug --systemd client %I --wait
Now, after the usual configuration reloading, you should be able to connect to a specific Bluetooth access point with:
systemctl start pan@00:11:22:33:44:55
Pairing via the Command Line Of course, the server and client-side service configuration require a pre-existing pairing between the server and each of its clients. On the server, start bluetoothctl and issue the following commands:
power on
agent on
default-agent
scan on
scan off
pair XX:XX:XX:XX:XX:XX
trust XX:XX:XX:XX:XX:XX
Once you've set scan mode to on, wait a few seconds until you see the device you're looking for scroll by. Note its device address, and use it for the pair and (optional) trust commands. On the client, the sequence is essentially the same except that you don't need to issue the trust command. The server needs to trust a client in order to accept NAP profile connections from it without waiting for manual confirmation by the user. I'm actually not sure if this is the optimal sequence of commands. It might be enough to just pair the client with the server and issue the trust command on the server, but I haven't tried this yet.
Enabling Use of the Bluetooth HID Profile Essentially the same as above also needs to be done in order to use the Bluetooth HID profile of the Active Star 40 on Linux. However, instead of agent on, you need to issue the command agent KeyboardOnly. This explicitly tells bluetoothctl that you're specifically looking for a HID profile.
Configuring Bluetooth via the Command Line Feels Vague While I'm very happy that I actually managed to set all of this up, I must admit that the command-line interface to BlueZ feels a bit incomplete and confusing. I initially thought that agents were only for PIN code entry. Now that I've discovered that "agent KeyboardOnly" is used to enable the HID profile, I'm not sure anymore. I'm surprised that I needed to grab a script from a random git repository in order to be able to set up PAN. I remember, with earlier version of BlueZ, that there was a tool called pand that you could use to do all of this from the command-line. I don't seem to see anything like that for BlueZ 5 anymore. Maybe I'm missing something obvious?
Performance The data rate is roughly 120kB/s, which I consider acceptable for such a low power solution. The 1GHz ARM CPU actually feels sufficiently fast for a console/text-mode person like me. I'll rarely be using much more than ssh and emacs on it anyway.
Console fonts and screen dimensions The default dimensions of the framebuffer on the Raspberry Pi Zero are a bit unexpectedly strange. fbset reports that the screen dimension is 656x416 pixels (of course, no monitor connected). With a typical console font of 8x16, I got 82 columns and 26 lines. With a 40 cell braille display, the 82 columns are very inconvenient. Additionally, as a braille user, I would like to be able to view Unicode braille characters in addition to the normal charset on the console. Fortunately, Linux supports 512 glyphs, while most console fonts do only provide 256. console-setup can load and combine two 256-glyph fonts at once. So I added the following to /etc/default/console-setup to make the text console a lot more friendly to braille users:
SCREEN_WIDTH=80
SCREEN_HEIGHT=25
FONT="Lat15-Terminus16.psf.gz brl-16x8.psf"

Note

You need console-braille installed for brl-16x8.psf to be available.

Further Projects There's a 3.5mm audio jack inside the braille display as well. Unfortunately, there are no converters from Mini-HDMI to 3.5mm audio that I know of. It would be very nice to be able to use the sound card that is already built into the Raspberry Pi Zero, but, unfortunately, this doesn't seem possible at the moment. Alternatively, I'm looking at using a Micro USB OTG hub and an additional USB audio adapter to get sound from the Raspberry Pi Zero to the braille display's speakers. Unfortunately, the two USB audio adapters I've tried so far have run hot for some unknown reason. So I have to find some other chipset to see if the problem goes away. A little nuisance, currently, is that you need to manually power off the Raspberry, wait a few seconds, and then power down the braille display. Turning the braille display off cuts power delivery via the internal USB port. If this is accidentally done too soon then the Raspberry Pi Zero is shut down ungracefully (which is probably not the best way to do it). We're looking into connecting a small, buffering battery to the GPIO pins of the rpi, and into notifying the rpi when external power has dropped. A graceful, software-initiated shutdown can then be performed. You can think of it as being like a mini UPS for Micro USB.
The image If you are a happy owner of a Handy Tech Active Star 40 and would like to do something similar, I am happy to share my current (Raspbian Stretch based) image. In fact, if there is enough interest by other blind users, we might even consider putting a kit together that makes it as easy as possible for you to get started. Let me know if this could be of interest to you.
Thanks Thanks to Dave Mielke for reviewing the text of this posting. Thanks to Simon Kainz for making the photos for this article. And I owe a big thank you to my co-workers at Graz University of Technology who have helped me a lot to bootstrap really quickly into the rpi world.
P.S. My first tweet about this topic is just five days ago, and apart from the soundcard not working yet, I feel like the project is already almost complete! By the way, I am editing the final version of this blog posting from my newly created monitorless ARM-based Linux laptop via an ssh connection to my home machine.

10 June 2016

Valerie Young: Week 1 on Reproducible Builds

In this post I m reviewing what I ve done the last 6 days of Outreachy-funded reproducible builds work, outline what I plan to do the next two weeks, and speculate on long term goals. For those of you involved in the Debian reproducible builds project, please provide feedback about future plans and work! Week One review One week of Outreachy completed! What have I done? The change that broke everything was the addition of a directory: tests.reproducible-builds.org/debian The directory was added to contain all Debian-specific pages, in line with the other project s reproducible builds status pages: arch linux, fedora, coreboot, etcs. Previously, all Debian pages we simply served directly out of the DocumentRoot. To fix all the broken things, I m pretty sure I had to find, inspect, and add /debian or change global variables within every file pointer in the entire tests website. Sometime tedious, but chasing down bugs and complaints was mostly fun  I also learned (everything I now know) about Apache websites, redirects, the website/navigation/directory structure of tests.reproducible-builds.org, and the roles of many of the reproducible scripts in jenkins.debian.net/bin. Week Two plan What will or should I do next? In the short term, over the next two weeks, I hope to make useful improvements to the tests website and backend while continuing to get up to speed (as well as learn Python). Have other thoughts about minor improvements to tests.reproducible-builds.org? Please let me know! The above list is not internally prioritized, feel free to ask for things to be bubbled up. Longer-term goals My long term summer goal is to make the Debian test code more easily extensible to show the reproducible results from other projects. This will lower the barrier for new projects to keep track of the reproducibility of their code, for great good. This starts with the reproducible.db database, which presently only tracks reproducible testing results for the Debian project. The reproducible builds project s needs have outgrown the original SQLight database, so this redesigning includes a migration to Postgre. Goals of the redesign include ease of querying/comparing packages across distributions, as well as generalization to include results from projects other than Debian. I ll start on this work in two weeks, when I get to DebCamp!  Redesigning the database will also lead to updating the python script which use that data to produce the Debian tests website. Other project scripts (like Fedora, RedHat and Coreboot) can then be updated to track results in the database as well, instead simply directly producing their own test websites. update: as an intermediate step before redesigned the reproducible.db database to handle multiple projects h01ger recommended I help the FreeBSD project recorded tests to a FreeBSD specific database.

8 June 2016

Daniel Pocock: Working to pass GSoC

GSoC students have officially been coding since 23 May (about 2.5 weeks) and are almost half-way to the mid-summer evaluation (20 - 27 June). Students who haven't completed some meaningful work before that deadline don't receive payment and in such a large program, there is no possibility to give students extensions or let them try and catch up later. Every project and every student are different, some are still getting to know their environment while others have already done enough to pass the mid-summer evaluation. I'd like to share a few tips to help students ensure they don't inadvertently fail the mid-summer evaluation Kill electronic distractions As a developer of real-time communications projects, many people will find it ironic or hypocritical that this is at the top of my list. Switch off the mobile phone or put it in silent mode so it doesn't even vibrate. Research has suggested that physically turning it off and putting it out of sight has significant benefits. Disabling the voicemail service can be an effective way of making sure no time is lost listening to a bunch of messages later. Some people may grumble at first but if they respect you, they'll get into the habit of emailing you and waiting for you to respond when you are not working. Get out a piece of paper and make a list of all the desktop notifications on your computer, whether they are from incoming emails, social media, automatic updates, security alerts or whatever else. Then figure out how to disable them all one-by-one. Use email to schedule fixed times for meetings with mentors. Some teams/projects also have fixed daily or weekly times for IRC chat. For a development project like GSoC, it is not necessary or productive to be constantly on call for 3 straight months. Commit every day Habits are a powerful thing. Successful students have a habit of making at least one commit every day. The "C" in GSoC is for Code and commits are a good way to prove that coding is taking place. GSoC is not a job, it is like a freelance project. There is no safety-net for students who get sick or have an accident and mentors are not bosses, each student is expected to be their own boss. Although Google has started recommending students work full time, 40 hours per week, it is unlikely any mentors have any way to validate these hours. Mentors can look for a commit log, however, and simply won't be able to pass a student if there isn't code. There may be one day per week where a student writes a blog or investigates a particularly difficult bug and puts a detailed report in the bug tracker but by the time we reach the second or third week of GSoC, most students are making at least one commit in 3 days out of every 5. Consider working away from home/family/friends Can you work without anybody interrupting you for at least five or six hours every day? Do you feel pressure to help with housework, cooking, siblings or other relatives? Even if there is no pressure to do these things, do you find yourself wandering away from the computer to deal with them anyway? Do family, friends or housemates engage in social activities, games or other things in close proximity to where you work? All these things can make a difference between passing and failing. Maybe these things were tolerable during high school or university. GSoC, however, is a stepping stone into professional life and that means making a conscious decision to shut those things out and focus. Some students have the ability to manage these distractions well, but it is not for everybody. Think about how leading sports stars or musicians find a time and space to be "in the zone" when training or rehearsing, this is where great developers need to be too. Some students find the right space in a public library or campus computer lab. Some students have been working in hacker spaces or at empty desks in local IT companies. These environments can also provide great networking opportunities. Managing another summer job concurrently with GSoC It is no secret that some GSoC students have another job as well. Sometimes the mentor is aware of it, sometimes it has not been disclosed. The fact is, some students have passed GSoC while doing a summer job or internship concurrently but some have also failed badly in both GSoC and their summer job. Choosing one or the other is the best way to succeed, get the best results and maximize the quality of learning and community interaction. For students in this situation, now it is not too late to make the decision to withdraw from GSoC or the other job. If doing a summer job concurrently with GSoC is unavoidable, the chance of success can be greatly increased by doing the GSoC work in the mornings, before starting the other job. Some students have found that they actually finish more quickly and produce better work when GSoC is constrained to a period of 4 or 5 hours each morning and their other job is only in the afternoon. On the other hand, if a student doesn't have the motivation or energy to get up and work on GSoC before the other job then this is a strong sign that it is better to withdraw from GSoC now.

Reproducible builds folks: Reproducible builds: week 58 in Stretch cycle

What happened in the Reproducible Builds effort between May 29th and June 4th 2016: Media coverage Ed Maste will present Reproducible Builds in FreeBSD at BDSCan 2016 in Ottawa, Canada on June 11th. GSoC and Outreachy updates Toolchain fixes Other upstream fixes Packages fixed The following 53 packages have become reproducible due to changes in their build-dependencies: angband blktrace code-saturne coinor-symphony device-tree-compiler mpich rtslib ruby-bcrypt ruby-bson-ext ruby-byebug ruby-cairo ruby-charlock-holmes ruby-curb ruby-dataobjects-sqlite3 ruby-escape-utils ruby-ferret ruby-ffi ruby-fusefs ruby-github-markdown ruby-god ruby-gsl ruby-hdfeos5 ruby-hiredis ruby-hitimes ruby-hpricot ruby-kgio ruby-lapack ruby-ldap ruby-libvirt ruby-libxml ruby-msgpack ruby-ncurses ruby-nfc ruby-nio4r ruby-nokogiri ruby-odbc ruby-oj ruby-ox ruby-raindrops ruby-rdiscount ruby-redcarpet ruby-redcloth ruby-rinku ruby-rjb ruby-rmagick ruby-rugged ruby-sdl ruby-serialport ruby-sqlite3 ruby-unicode ruby-yajl ruby-zoom thin The following packages have become reproducible after being fixed: Some uploads have addressed some reproducibility issues, but not all of them: Uploads with an unknown result because they fail to build: Patches submitted that have not made their way to the archive yet: Package reviews 45 reviews have been added, 25 have been updated and 25 have been removed in this week. 12 FTBFS bugs have been reported by Chris Lamb and Niko Tyni. diffoscope development strip-nondeterminism development Mattia uploaded strip-nondeterminism 0.018-1 which improved support for *.epub files. tests.reproducible-builds.org Misc. Last week we also learned about progress of reproducible builds in FreeBSD. Ed Maste announced a change to record the build timestamp during ports building, which is required for later reproduction. This week's edition was written by Reiner Herrman, Holger Levsen and Chris Lamb and reviewed by a bunch of Reproducible builds folks on IRC.

Lucas Nussbaum: Re: Sysadmin Skills and University Degrees

Russell Coker wrote about Sysadmin Skills and University Degrees. I couldn t agree more that a major deficiency in Computer Science degrees is the lack of sysadmin training. It seems like most sysadmins learned most of what they know from experience. It s very hard to recruit young engineers (freshly out of university) for sysadmin jobs, and the job interviews are often a bit depressing. Sysadmins jobs are also not very popular with this public, probably because university curriculums fail to emphasize what s exciting about those jobs. However, I think I disagree rather deeply with Russell s detailed analysis. First, Version Control. Well, I think that it s pretty well covered in university curriculums nowadays. From my point of view, teaching CS in Universit de Lorraine (France), mostly in Licence Professionnelle Administration de Syst mes, R seaux et Applications base de Logiciels Libres (warning: french), a BSc degree focusing on Linux systems administration, it s not usual to see student projects with a mandatory use of Git. And it doesn t seem to be a major problem for students (which always surprises me). However, I wouldn t rate Version Control as the most important thing that is required for a sysadmin. Similarly Dependencies and Backups are things that should be covered, but probably not as first class citizens. I think that there are several pillars in the typical sysadmin knowledge. First and foremost, sysadmins need a good understanding of the inner workings of an operating system. I sometimes feel that many Operating Systems Design courses are a bit too much focused on the Design side of things. Yes, it s useful to understand the low-level mechanisms, and be able to (mentally) recreate an OS from scratch. But it s also interesting to know how real systems are actually built, and what are the trade-off involved. I very much enjoyed reading Branden Gregg s Systems Performance: Enterprise and the Cloud because each chapter starts with a great overview of how things are in the real world, with a very good level of detail. Also, addressing OS design from the point of view of performance could be a way to turn those courses into something more attractive for students: many people like to measure, benchmark, optimize things, and it s quite easy to demonstrate how different designs, or different configurations, make a big difference in terms of performance in the context of OS design. It s possible to be a sysadmin and ignore, say, the existence of the VFS, but there s a large class of problems that you will never be able to solve. It can be a good trade-off for a curriculum (e.g. at the BSc level) to decide to ignore most of the low-level stuff, but it s important to be aware of it. Students also need to learn how to design a proper infrastructure (that meets requirements in terms of scalability, availability, security, and maybe elasticity). Yes, backups are important. But monitoring is, too. As well as high availability. In order to scale, it s important to be able to automatize stuff. Russell writes that Sysadmins need some programming skills, but that s mostly scripting and basic debugging. Well, when you design an infrastructure, or when you use configuration management tools such as Puppet, in some sense, you are programming, and in terms of needs to abstract things, it s actually similar to doing object-oriented programming, with similar choices (should I use that off-the-shelf puppet module, or re-develop my own? How should everything fit together?). Also, when debugging, it s often useful to be able to dig into code, understand what the developer was trying to do, and if the expected behavior actually matches what you are seeing. It often results in spending a lot of time to create a one-line fix, and it requires very advanced programming skills. Again, it s possible to be a sysadmin with only limited software development knowledge, but there s a large class of things that you are unlikely to address properly. I think that what makes sysadmins jobs both very interesting and very challenging is that they require a very wide range of knowledge. There s often the ability to learn about new stuff (much more than in software development jobs). Of course, the difficult question is where to draw the line. What is the sysadmin knowledge that every CS graduate should have, even in curriculums not targeting sysadmin jobs? What is the sysadmin knowledge for a sysadmin BSc degree? for a sysadmin MSc degree?

Russell Coker: Sysadmin Skills and University Degrees

I think that a major deficiency in Computer Science degrees is the lack of sysadmin training. Version Control The first thing that needs to be added is the basics of version control. CVS (which is now regarded as obsolete) was initially released when I was in the first year of university. But SCCS and RCS had been in use for some time. I think that the people who designed my course were remiss in not adding any mention of version control (not even strategies for saving old versions of your work), one could say that they taught us about version control by letting us accidentally delete our assignments. :-# If a course is aimed at just teaching programmers (as most CS degrees are) then version control for group assignments should be a standard part of the course. Having some marks allocated for the quality of comments in the commit log would also be good. A modern CS degree should cover distributed version control, that means covering Git as it s the most popular distributed version control system nowadays. For people who want to work as sysadmins (as opposed to developers who run their own PCs) a course should have an optional subject for version control of an entire system. That includes tools like etckeeper for version control of system configuration and tools like Puppet for automated configuration and system maintenance. Dependencies It s quite reasonable for a CS degree to provide simplified problems for the students to solve so they can concentrate on one task. But in the real world the problems are more complex. One of the more difficult parts of managing real systems is dependencies. You have issues of header files etc at compile time and library versions at deployment. Often you need a program to run on systems with different versions of the OS which means making it compile for both and deal with differences in behaviour. There are lots of hacky things that people do to deal with dependencies in systems. People link compiled programs statically, install custom versions of interpreters in user home directories or /usr/local for daemons, and do many other things. These things can have bad consequences including data loss, system downtime, and security problems. It s not always wrong to do such things, but it s something that should only be done with knowledge of the potential consequences and a plan for mitigating them. A CS degree should teach the potential advantages and disadvantages of these options to allow graduates to make informed decisions. Backups I ve met many people who call themselves computer professionals and think that backups aren t needed. I ve seen production systems that were designed in a way that backups were impossible. The lack of backups is a serious problem for the entire industry. Some lectures about backups could be part of a version control subject in a general CS degree. For a degree that majors in Sysadmin at least one subject about backups is appropriate. For any backup (even backing up your home PC) you should have offsite backups to deal with fire damage, multiple backups of different ages (especially important now that encryption malware is a serious threat), and a plan for how fast you can restore things. The most common use of backups is to deal with the case of deleting the wrong file. Unfortunately this case seems to be the most rarely mentioned. Another common situation that should be covered is a configuration error that results in a system that won t boot correctly. It s a very common problem and one that can be solved quickly if you are prepared but which can take a long time if you aren t. For a Sysadmin course it is important to cover backups of systems in remote datacenters. Hardware A good CS degree should cover the process of selecting suitable hardware. Programmers often get to advise on the hardware used to run their code, especially at smaller companies. Reliability features such as RAID, ECC RAM, and clustering should be covered. Planning for upgrades is a very important part of this which is usually not taught. Not only do you need to plan for an upgrade without much downtime or cost but you also need to plan for what upgrades are possible. Next year will your system require hardware that is more powerful than you can buy next year? If so you need to plan for a cluster now. For a Sysadmin course some training about selecting cloud providers and remote datacenter hosting should be provided. There are many complex issues that determine whether it s most appropriate to use a cloud service, hosted virtual machines, hosted physical servers managed by the ISP, hosted physical servers purchased by the client, or on-site servers. Often a large system will involve 2 or more of those options, even some small companies use 3 or more of those options to try and provide the performance and reliability they need at a price they can afford. We Need Sysadmin Degrees Covering the basic coding skills takes a lot of time. I don t think we can reasonably expect a CS degree to cover all that and also give good coverage to sysadmin work. While some basic sysadmin skills are needed by every programmer I think we need to have separate majors for people who want a career in system administration. Sysadmins need some programming skills, but that s mostly scripting and basic debugging. Someone who s main job is as a sysadmin can probably expect to never make any significant change to a program that s more than 10,000 lines long. A large amount of the programming in a CS degree can be replaced by file a bug report for a sysadmin degree. This doesn t mean that sysadmins shouldn t be doing software development or that they aren t good at it. One noteworthy fact is that it appears that the most common job among developers of the Debian distribution of Linux is System Administration. Developing an OS involves some of the most intensive and demanding programming. But I think that more than a few people who do such work would have skipped a couple of programming subjects in favour of sysadmin subjects if they were given a choice. Suggestions Did I miss anything? What other sysadmin skills should be taught in a CS degree? Do any universities teach these things now? If so please name them in the comments, it is good to help people find universities that teach them what they want to learn and help them in their career.

6 June 2016

Carl Chenet: My Free Activities in May 2015

Follow me also on Diaspora*diaspora-banner or Twitter Trying to catch up with my blog posts about My Free Activities. This blog post will tell you about my free activities from January to May 2016. 1. Personal projects 2. Journal du hacker That s all folks! See you next month!

John Goerzen: How git-annex replaces Dropbox + encfs with untrusted providers

git-annex has been around for a long time, but I just recently stumbled across some of the work Joey has been doing to it. This post isn t about it s traditional roots in git or all the features it has for partial copies of large data sets, but rather for its live syncing capabilities like Dropbox. It takes a bit to wrap your head around, because git-annex is just a little different from everything else. It s sort of like a different-colored smell. The git-annex wiki has a lot of great information both low-level reference and a high-level 10-minute screencast showing how easy it is to set up. I found I had to sort of piece together the architecture between those levels, so I m writing this all down hoping it will benefit others that are curious. Ir you just want to use it, you don t need to know all this. But I like to understand how my tools work. Overview git-annex lets you set up a live syncing solution that requires no central provider at all, or can be used with a completely untrusted central provider. Depending on your usage pattern, this central provider could require only a few MBs of space even for repositories containing gigabytes or terabytes of data that is kept in sync. Let s take a look at the high-level architecture of the tool. Then I ll illustrate how it works with some scenarios. Three Layers Fundamentally, git-annex takes layers that are all combined in Dropbox and separates them out. There is the storage layer, which stores the literal data bytes that you are interested in. git-annex indexes the data in storage by a hash. There is metadata, which is for things like a filename-to-hash mapping and revision history. And then there is an optional layer, which is live signaling used to drive the real-time syncing. git-annex has several modes of operation, and the one that enables live syncing is called the git-annex assistant. It runs as a daemon, and is available for Linux/POSIX platforms, Windows, Mac, and Android. I ll be covering it here. The storage layer The storage layer simply is blobs of data. These blobs are indexed by a hash, and can be optionally encrypted at rest at remote backends. git-annex has a large number of storage backends; some examples include rsync, a remote machine with git-annex on it that has ssh installed, WebDAV, S3, Amazon Glacier, removable USB drive, etc. There s a huge list. One of the git-annex features is that each client knows the state of each storage repository, as well as the capability set of each storage repository. So let s say you have a workstation at home and a laptop you take with you to work or the coffee shop. You d like changes on one to be instantly recognized on another. With something like Dropbox or OwnCloud, every file in the set you want synchronized has to reside on a server in the cloud. With git-annex, it can be configured such that the server in the cloud only contains a copy of a file until every client has synced it up, at which point it gets removed. Think about it that is often what you want anyhow, so why maintain an unnecessary copy after it s synced everywhere? (This behavior is, of course, configurable.) git-annex can also avoid storing in the cloud entirely if the machines are able to reach each other directly at least some of the time. The metadata layer Metadata about your files includes a mapping from the file names to the storage location (based on hashes), change history, and information about the status of each machine that participates in the syncing. On your clients, git-annex stores this using git. This detail is very useful to some, and irrelevant to others. Some of the git-annex storage backends can support only storage (S3, for instance). Some can support both storage and metadata (rsync, ssh, local drives, etc.) You can even configure a backend to support only metadata (more on why that may be useful in a bit). When you are working with a git-backed repository for git-annex, it can hold data, metadata, or both. So, to have a working sync system, you must have a way to transport both the data and the metadata. The transport for the metadata is generally rsync or git, but it can also be XMPP in which Git changesets are basically wrapped up in XMPP presence messages. Joey says, however, that there are some known issues with XMPP servers sometimes dropping or reordering some XMPP messages, so he doesn t encourage that method currently. The live signaling layer So once you have your data and metadata, you can already do syncs via git annex sync --contents. But the real killer feature here will be automatic detection of changes, both on the local and the remote. To do that, you need some way of live signaling. git-annex supports two methods. The first requires ssh access to a remote machine where git-annex is installed. In this mode of operation, when the git-annex assistant fires up, it opens up a persistent ssh connection to the remote and runs the git-annex-shell over there, which notifies it of changes to the git metadata repository. When a change is detected, a sync is initiated. This is considered ideal. A substitute can be XMPP, and git-annex actually converts git commits into a form that can be sent over XMPP. As I mentioned above, there are some known reliability issues with this and it is not the recommended option. Encryption When it comes to encryption, you generally are concerned about all three layers. In an ideal scenario, the encryption and decryption happens entirely on the client side, so no service provider ever has any details about your data. The live signaling layer is encrypted pretty trivially; the ssh sessions are, of course, encrypted and TLS support in XMPP is pervasive these days. However, this is not end-to-end encryption; those messages are decrypted by the service provider, so a service provider could theoretically spy on metadata, which may include change times and filenames, though not the contents of files themselves. The data layer also can be encrypted very trivially. In the case of the dumb backends like S3, git-annex can use symmetric encryption or a gpg keypair and all that ever shows up on the server are arbitrarily-named buckets. You can also use a gcrypt-based git repository. This can cover both data and metadata and, if the target also has git-annex installed, the live signalling layer. Using a gcrypt-based git repository for the metadata and live signalling is the only way to accomplish live syncing with 100% client-side encryption. All of these methods are implemented in terms of gpg, and can support symmetric of public-key encryption. It should be noted here that the current release versions of git-annex need a one-character patch in order to fix live syncing with a remote using gcrypt. For those of you running jessie, I recommend the version in jessie-backports, which is presently 5.20151208. For your convenience, I have compiled an amd64 binary that can drop in over /usr/bin/git-annex if you have this version. You can download it and a gpg signature for it. Note that you only need this binary on the clients; the server can use the version from jessie-backports without issue. Putting the pieces together: some scenarios Now that I ve explained the layers, let s look at how they fit together. Scenario 1: Central server In this scenario, you might have a workstation and a laptop that sync up with each other by way of a central server that also has a full copy of the data. This is the scenario that most closely resembles Dropbox, box, or OwnCloud. Here you would basically follow the steps in the git-assistant screencast: install git-annex on a server somewhere, and point your clients to it. If you want full end-to-end encryption, I would recommend letting git-annex generate a gpg keypair for you, which you would then need to copy to both your laptop and workstation (but not the server). Every change you make locally will be synced to the server, and then from the server to your other PC. All three systems would be configured in the client transfer group. Scenario 1a: Central server without a full copy of the data In this scenario, everything is configured the same except the central server is configured with the transfer transfer group. This means that the actual data synced to it is deleted after it has been propagated to all clients. Since git-annex can verify which repository has received a copy of which data, it can easily enough delete the actual file content from the central server after it has been copied to all the clients. Many people use something like Dropbox or OwnCloud as a multi-PC syncing solution anyhow, so once the files have been synced everywhere, it makes sense to remove them from the central server. This is often a good ideal for people. There are some obvious downsides that are sometimes relevant. For instance, to add a third sync client, it must be able to initially copy down from one of the existing clients. Or, if you intend to access the data from a device such as a cell phone where you don t intend for it to have a copy of all data all the time, you won t have as convenient way to download your data. Scenario 1b: Split data/metadata central servers Imagine that you have a shell or rsync account on some remote system where you can run git-annex, but don t have much storage space. Maybe you have a cheap VPS or shell account somewhere, but it s just not big enough to hold your data. The answer to this would be to use this shell or rsync account for the metadata, but put the data elsewhere. You could, for instance, store the data in Amazon S3 or Amazon Glacier. These backends aren t capable of storing the git-annex metadata, so all you need is a shell or rsync account somewhere to sync up the metadata. (Or, as below, you might even combine a fully distributed approach with this.) Then you can have your encrypted data pushed up to S3 or some such service, which presumably will grow to whatever size you need. Scenario 2: Fully distributed Like git itself, git-annex does not actually need a central server at all. If your different clients can reach each other directly at least some of the time, that is good enough. Of course, a given client will not be able to do fully automatic live sync unless it can reach at least one other client, so changes may not propagate as quickly. You can simply set this up by making ssh connections available between your clients. git-annex assistant can automatically generate appropriate ~/.ssh/authorized_keys entries for you. Scenario 2a: Fully distributed with multiple disconnected branches You can even have a graph of connections available. For instance, you might have a couple machines at home and a couple machines at work with no ability to have a direct connection between them (due to, say, firewalls). The two machines at home could sync with each other in real-time, as could the two machines at work. git-annex also supports things like USB drives as a transport mechanism, so you could throw a USB drive in your pocket each morning, pop it in to one client at work, and poof both clients are synced up over there. Repeat when you get home in the evening, and you re synced there. The USB drive s repository can, of course, be of the transport type so data is automatically deleted from it once it s been synced everywhere. Scenario 3: Hybrid git-annex can support LAN sync even if you have a central server. If your laptop, say, travels around but is sometimes on the same LAN as your PC, git-annex can easily sync directly between the two when they are reachable, saving a round-trip to the server. You can assign a cost to each remote, and git-annex will always try to sync first to the lowest-cost path that is available. Drawbacks of git-annex There are some scenarios where git-annex with the assistant won t be as useful as one of the more traditional instant-sync systems. The first and most obvious one is if you want to access the files without the git-annex client. For instance, many of the other tools let you generate a URL that you can email to people, and then they can download files without any special client software. This is not directly possible with git-annex. You could, of course, make something like a public_html directory be managed with git-annex, but it wouldn t provide things like obfuscated URLs, password-protected sharing, time-limited sharing, etc. that you get with other systems. While you can share your repositories with others that have git-annex, you can t share individual subdirectories; for a given repository, it is all or nothing. The Android client for git-annex is a pretty interesting thing: it is mostly a small POSIX environment, providing a terminal, git, gpg, and the same web interface that you get on a standalone machine. This means that the git-annex Android client is fully functional compared to a desktop one. It also has a quick setup process for syncing off your photos/videos. On the other hand, the integration with the Android ecosystem is poor compared to most other tools. Other git-annex features git-annex has a lot to offer besides the git-annex assistant. Besides the things I ve already mentioned, any given git-annex repository including your client repository can have a partial copy of the full content. Say, for instance, that you set up a git-annex repository for your music collection, which is quite large. You want some music on your netbook, but don t have room for it all. You can tell git-annex to get or drop files from the netbook s repository without deleting them remotely. git-annex has quite a few ways to automate and configure this, including making sure that at least a certain number of copies of a file exist in your git-annex ecosystem. Conclusion I initially started looking at git-annex due to the security issues with encfs, and the difficulty with setting up ecryptfs in this way. (I had been layering encfs atop OwnCloud). git-annex certainly ticks the box for me security-wise, and obviously anything encrypted with encfs wasn t going to be shared with others anyhow. I ll be using git-annex more in the future, I m sure.


Scarlett Clark: Debian: Reproducible builds Week 2

This was a holiday week for me, so my time was rather crammed into a short space.
I still managed to make progress though. kapptemplate:
https://bugs.kde.org/show_bug.cgi?id=363448
I was given the green light to push this upstream. So this will eventually trickle down and all will benefit, not just debian.
I will leave bug open though as it will need to be applied to all the releases I expect.
https://bugs.debian.org/cgi-bin/bugreport.cgi?bug=825122 choqok:
https://bugs.debian.org/cgi-bin/bugreport.cgi?bug=825322
For this I was able to come up with a patch for kconfig_compiler to encode generated files to utf-8.
Review request is here:
https://git.reviewboard.kde.org/r/128102/ kxmlgui:
WIP this has been a steep learning curve, according to the notes it was an easy embedded kernel version, that was not the case! After grueling hours of
trying to sort out randomness in debug output I finally narrowed it down to cases where QStringLiteral was used and there were non letter characters eg. ( <") These were causing debug symbols to generate with ( lambda() ) which caused unreproducible symbol/debug files. It is now a case of fixing all of these in the code to use QString::fromUtf8 seems to fix this. I am working on a mega patch for upstream and it should be ready early in the week. Other items were minor and not notable enough to blog about  Have a great day.

5 June 2016

Ingo Juergensmann: Request for Adoption: Buildd.Net project

I've been running Buildd.Net for quite a long time. Buildd.Net is a project that focusses on the autobuilders, not the packages. It started back then when the m68k port had a small website running on kullervo, a m68k buildd. Kullervo was too loaded to deal with the increased load of that website, so together with Stephen Marenka we moved the page from kullervo to my server under the domain m68k.bluespice.org. Over time I got many requests if that page could do the same for other archs as well, so I started to hack the code to be able to deal with different archs: Buildd.Net was born. Since then many years passed by and Buildd.Net evolved into a rather complex project, being capable to deal with different archs and different releases, such as unstable, backports, non-free, etc. Sadly the wanna-build output changed over the years as well, but I didn't have the time anymore to keep up with the changes. Buildd.Net is based on:
  • some Bash scripts
  • some Python scripts
  • a PostgreSQL database
  • gnuplot for some graphs
  • some small Perl scripts
  • ... and maybe more...
As long as I was more deeply involved with the m68k autobuilders and others, I found Buildd.Net quite informative as I could get a quick overview how all of the buildds were performing. Based on the PostgreSQL database we could easily spot if a package was stuck on one of the buildds without directly watching the buildd logs. Storing the information from the buildds about the built packages in a SQL database can give you some benefit. Originally my plan was to use that kind of information for a better autobuilder setup. In the past it happened that large packages were built by buildds with, let's say, 64 MB of RAM and smaller packages were built on the buildds with 128 MB of RAM. Eventually this led to failed builds or excessive build times. Or m68k buildds like Apple Centris boxes or so suffered from slow disk I/O, while some Amiga buildds had reasonable disk speeds (consider 160 kB/s vs. 2 MB/s). As you can see there is/was a lot room for optimization of how packages can be distributed between buildds. This could have been done by analyzing the statistics and some scripting, but was never implemented because of missing skills and time on my side. The lack of time to keep up with the changes of the official wanna-build output (like new package states) is the main reason why I want to give Buildd.Net into good hands. If you are interested in this project, please contact me! I still believe that Buildd.Net can be beneficial to the Debian project. :-)
Kategorie:

Simon McVittie: Flatpak in Debian

Quite a lot has happened in xdg-app since last time I blogged about it. Most noticeably, it isn't called xdg-app any more, having been renamed to Flatpak. It is now available in Debian experimental under that name, and the xdg-app package that was briefly there has been removed. I'm currently in the process of updating Flatpak to the latest version 0.6.4. The privileged part has also spun off into a separate project, Bubblewrap, which recently had its first release (0.1.0). This is intended as a common component with which unprivileged users can start a container in a way that won't let them escalate privileges, like a more flexible version of linux-user-chroot. Bubblewrap has also been made available in Debian, maintained by Laszlo Boszormenyi (also maintainer of linux-user-chroot). Yesterday I sent a patch to update Laszlo's packaging for 0.1.0. I'm hoping to become a co-maintainer to upload that myself, since I suspect Flatpak and Bubblewrap might need to track each other quite closely. For the moment, Flatpak still uses its own internal copy of Bubblewrap, but I consider that to be a bug and I'd like to be able to fix it soon. At some point I also want to experiment with using Bubblewrap to sandbox some of the game engines that are packaged in Debian: networked games are a large attack surface, and typically consist of the sort of speed-optimized C or C++ code that is an ideal home for security vulnerabilities. I've already made some progress on jailing game engines with AppArmor, but making sensitive files completely invisible to the game engine seems even better than preventing them from being opened. Next weekend I'm going to be heading to Toronto for the GTK Hackfest, primarily to to talk to GNOME and Flatpak developers about their plans for sandboxing, portals and Flatpak. Hopefully we can make some good progress there: the more I know about the state of software security, the less happy I am with random applications all being equally privileged. Newer display technologies like Wayland and Mir represent an opportunity to plug one of the largest holes in typical application containerization, which is a major step in bringing sandboxes like Flatpak and Snap from proof-of-concept to a practical improvement in security. Other next steps for Flatpak in Debian:

Petter Reinholdtsen: A program should be able to open its own files on Linux

Many years ago, when koffice was fresh and with few users, I decided to test its presentation tool when making the slides for a talk I was giving for NUUG on Japhar, a free Java virtual machine. I wrote the first draft of the slides, saved the result and went to bed the day before I would give the talk. The next day I took a plane to the location where the meeting should take place, and on the plane I started up koffice again to polish the talk a bit, only to discover that kpresenter refused to load its own data file. I cursed a bit and started making the slides again from memory, to have something to present when I arrived. I tested that the saved files could be loaded, and the day seemed to be rescued. I continued to polish the slides until I suddenly discovered that the saved file could no longer be loaded into kpresenter. In the end I had to rewrite the slides three times, condensing the content until the talk became shorter and shorter. After the talk I was able to pinpoint the problem kpresenter wrote inline images in a way itself could not understand. Eventually that bug was fixed and kpresenter ended up being a great program to make slides. The point I'm trying to make is that we expect a program to be able to load its own data files, and it is embarrassing to its developers if it can't. Did you ever experience a program failing to load its own data files from the desktop file browser? It is not a uncommon problem. A while back I discovered that the screencast recorder gtk-recordmydesktop would save an Ogg Theora video file the KDE file browser would refuse to open. No video player claimed to understand such file. I tracked down the cause being file --mime-type returning the application/ogg MIME type, which no video player I had installed listed as a MIME type they would understand. I asked for file to change its behavour and use the MIME type video/ogg instead. I also asked several video players to add video/ogg to their desktop files, to give the file browser an idea what to do about Ogg Theora files. After a while, the desktop file browsers in Debian started to handle the output from gtk-recordmydesktop properly. But history repeats itself. A few days ago I tested the music system Rosegarden again, and I discovered that the KDE and xfce file browsers did not know what to do with the Rosegarden project files (*.rg). I've reported the rosegarden problem to BTS and a fix is commited to git and will be included in the next upload. To increase the chance of me remembering how to fix the problem next time some program fail to load its files from the file browser, here are some notes on how to fix it. The file browsers in Debian in general operates on MIME types. There are two sources for the MIME type of a given file. The output from file --mime-type mentioned above, and the content of the shared MIME type registry (under /usr/share/mime/). The file MIME type is mapped to programs supporting the MIME type, and this information is collected from the desktop files available in /usr/share/applications/. If there is one desktop file claiming support for the MIME type of the file, it is activated when asking to open a given file. If there are more, one can normally select which one to use by right-clicking on the file and selecting the wanted one using 'Open with' or similar. In general this work well. But it depend on each program picking a good MIME type (preferably a MIME type registered with IANA), file and/or the shared MIME registry recognizing the file and the desktop file to list the MIME type in its list of supported MIME types. The /usr/share/mime/packages/rosegarden.xml entry for the Shared MIME database look like this:
<?xml version="1.0" encoding="UTF-8"?>
<mime-info xmlns="http://www.freedesktop.org/standards/shared-mime-info">
  <mime-type type="audio/x-rosegarden">
    <sub-class-of type="application/x-gzip"/>
    <comment>Rosegarden project file</comment>
    <glob pattern="*.rg"/>
  </mime-type>
</mime-info>
This states that audio/x-rosegarden is a kind of application/x-gzip (it is a gzipped XML file). Note, it is much better to use an official MIME type registered with IANA than it is to make up ones own unofficial ones like the x-rosegarden type used by rosegarden. The desktop file of the rosegarden program failed to list audio/x-rosegarden in its list of supported MIME types, causing the file browsers to have no idea what to do with *.rg files:
% grep Mime /usr/share/applications/rosegarden.desktop
MimeType=audio/x-rosegarden-composition;audio/x-rosegarden-device;audio/x-rosegarden-project;audio/x-rosegarden-template;audio/midi;
X-KDE-NativeMimeType=audio/x-rosegarden-composition
%
The fix was to add "audio/x-rosegarden;" at the end of the MimeType= line. If you run into a file which fail to open the correct program when selected from the file browser, please check out the output from file --mime-type for the file, ensure the file ending and MIME type is registered somewhere under /usr/share/mime/ and check that some desktop file under /usr/share/applications/ is claiming support for this MIME type. If not, please report a bug to have it fixed. :)

3 June 2016

Gunnar Wolf: Stop it with those short PGP key IDs!

Debian is quite probably the project that most uses a OpenPGP implementation (that is, GnuPG, or gpg) for many of its internal operations, and that places most trust in it. PGP is also very widely used, of course, in many other projects and between individuals. It is regarded as a secure way to do all sorts of crypto (mainly, encrypting/decrypting private stuff, signing public stuff, certifying other people's identities). PGP's lineage traces back to Phil Zimmerman's program, first published in 1991 By far, not a newcomer PGP is secure, as it was 25 years ago. However, some uses of it might not be so. We went through several migrations related to algorithmic weaknesses (i.e. v3 keys using MD5; SHA1 is strongly discouraged, although not yet completely broken, and it should be avoided as well) or to computational complexity (as the migration away from keys smaller than 2048 bits, strongly prefering 4096 bits). But some vulnerabilities are human usage (that is, configuration-) related. Today, Enrico Zini gave us a heads-up in the #debian-keyring IRC channel, and started a thread in the debian-private mailing list; I understand the mail to a private list was partly meant to get our collective attention, and to allow for potentially security-relevant information to be shared. I won't go into details about what is, is not, should be or should not be private, but I'll post here only what's public information already. What are short and long key IDs? I'll start by quoting Enrico's mail:
there are currently at least 3 ways to refer to a gpg key: short key ID (last 8 hex digits of fingerprint), long key ID (last 16 hex digits) and full fingerprint. The short key ID used to be popular, and since 5 years it is known that it is computationally easy to generate a gnupg key with an arbitrary short key id. A mitigation to this is using "keyid-format long" in gpg.conf, and a better thing to do, especially in scripts, is to use the full fingerprint to refer to a key, or just ship the public key for verification and skip the key servers. Note that in case of keyid collision, gpg will download and import all the matching keys, and will use all the matching keys for verifying signatures.
So... What is this about? We humans are quite bad at recognizing and remembering randomly-generated strings with no inherent patterns in them. Every GPG key can be uniquely identified by its fingerprint, a 128-bit string, usually encoded as ten blocks of four hexadecimal characters (this allows for 160 bits; I guess there's space for a checksum in it). That is, my (full) key's signature is:
AB41 C1C6 8AFD 668C A045  EBF8 673A 03E4 C1DB 921F
However, it's quite hard to recognize such a long string, let alone memorize it! So, we often do what humans do: Given that strong cryptography implies a homogenous probability distribution, people compromised on using just a portion of the key the last portion. The short key ID. Mine is then the last two blocks (shown in boldface): C1DB921F. We can also use what's known as the long key ID, that's twice as long: 64 bits. However, while I can speak my short key ID on a single breath (and maybe even expect you to remember and note it down), try doing so with the long one (shown in italics above): 673A03E4C1DB921F. Nah. Too much for our little, analog brains. This short and almost-rememberable number has then 32 bits of entropy I have less than one in 4,000,000,000 chance of generating a new key with this same short key ID. Besides, key generation is a CPU-intensive operation, so it's quite unlikely we will have a collision, right? Well, wrong. Previous successful attacks on short key IDs Already five years ago, Asheesh Laroia migrated his 1024D key to a 4096R. And, as he describes in his always-entertaining fashion, he made his computer sweat until he was able to create a new key for which the short key ID collided with the old one. It might not seem like a big deal, as he did this non-maliciously, but this easily should have spelt game over for the usage of short key IDs. After all, being able to generate a collision is usually the end for cryptographic systems. Asheesh specifically mentioned in his posting how this could be abused. But we didn't listen. Short key IDs are just too convenient! Besides, they allow us to have fun, can be a means of expression! I know of at least two keys that would qualify as vanity: Obey Arthur Liu's 0x29C0FFEE (created in 2009) and Keith Packard's 0x00000011 (created in 2012). Then we got the Evil 32 project. They developed Scallion, started (AFAICT) in 2012. Scallion automates the search for a 32-bit collision using GPUs; they claim that it takes only four seconds to find a collision. So, they went through the strong set of the public PGP Web of Trust, and created a (32-bit-)colliding key for each of the existing keys. And what happened now? What happened today? We still don't really know, but it seems we found a first potentially malicious collision that is, the first "nonacademic" case. Enrico found two keys sharing the 9F6C6333 short ID, apparently belonging to the same person (as would be the case of Asheesh, mentioned above). After contacting Gustavo, though, he does not know about the second That is, it can be clearly regarded as an impersonation attempt. Besides, what gave away this attempt are the signatures it has: Both keys are signed by what appears to be the same three keys: B29B232A, F2C850CA and 789038F2. Those three keys are not (yet?) uploaded to the keyservers, though... But we can expect them to appear at any point in the future. We don't know who is behind this, or what his purpose is. We just know this looks very evil. Now, don't panic: Gustavo's key is safe. Same for his certifiers, Marga, Agust n and Maxy. It's just a 32-bit collision. So, in principle, the only parties that could be cheated to trust the attacker are humans, right? Nope. Enrico tested on the PGP pathfinder & key statistics service, a keyserver that finds trust paths between any two arbitrary keys in the strong set. Surprise: The pathfinder works on the short key IDs, even when supplied full fingerprints. So, it turns out I have three faked trust paths into our impostor. What next? There are several things this should urge us to do. And there are surely many other important recommendations. But this is a good set of points to start with. [update] I was pointed at Daniel Kahn Gillmor's 2013 blog post, OpenPGP Key IDs are not useful. Daniel argues, in short, that cutting a fingerprint in order to get a (32- or 64-bit) short key ID is the worst of all worlds, and we should rather target either always showing full fingerprints, or not showing it at all (and leaving all the crypto-checking bits to be done by the software, as comparing 160-bit strings is not natural for us humans). [update] This post was picked up by LWN.net. A very interesting discussion continues in their comments.

Reproducible builds folks: Reprotest repository exists and installs

Author: ceridwen I had family obligations for most of the past week, so I haven't had a chance to do more than get started on reprotest. The repository now contains a version of reprotest that can be installed with pip/setuptools (run python setup.py install in the repository directory or pip reprotest/ from its parent directory) or with debhelper (run debuild -b -uc -us in the repository, then install the resulting .deb). I've tested this works by installing into a virtualenv and onto my own system, but if anyone else wants to verify this, that would be great. At the moment, reprotest doesn't do anything, mind. I ended up importing significant amounts of code from autopkgtest into reprotest. While I may change my opinion as I read the code further, my first analysis is that much of the code responsible for processing command line arguments and config files (in lib/ and runner/) and building and communicating with the environments/virtual servers (in runner/, tools/, and virt-subproc/) can be adapted for reprotest. Once I have the chance to begin implementing functionality, I intend to discuss this in more detail.

Next.

Previous.