Search Results: "ag"

3 August 2007

David Moreno Garza: An end has a start

July 31st was my last day working for Sixbell-Nekotec Solutions (formerly known as Nekotec Tecnolog a). I lasted there three years. It seems like a life was spent there, heh: I entered after turning 20 and I’m leaving some days before I turn 23. Our future is still a bit fuzzy, but we are working on it. In the meantime, I’m getting back full-time to Mathematics next 13rd. But if our plans succeed and if everything goes right, we’ll be moving by the end of August or early September. Heh, yes, leaving school temporarily, again! Anyway, I’m unemployed right now. Listening to music most part of the day, taking Raquel to work, coding a bit here, there, doing some Debian labor, etc. Meh. An End Has A Start is one of the albums by the English band, The Editors, it makes a great title for my post now :-). I just listened to Taraf de Ha douks’ Maskarada, it’s not that great as the masterpiece as The Continuing Adventures. I’m getting addicted to the Cold War Kids.

2 August 2007

Russell Coker: Starting a Heartbeat Resource Without Heartbeat

The command crm_resource allows you to do basic editing of resources in the Heartbeat configuration database. But sometimes you need to do different things and the tool xmlstarlet is a good option. The below script can be used for testing Heartbeat OCF resource scripts. It uses the Heartbeat management program cibadmin to get the XML configuration data and then uses xmlstarlet to process it. The sel option for xmlstarlet selects some data from an XML file, the -t -m options instruct it to match data from a template. The template is the /resources/primitive part. The --value-of expression will print the values of some labels from the XML. The script will concatenate the name and value tags and export them as environment variables (see my post about Configuring a Heartbeat Service for an explanation of the use of the variables). The TYPE variable is the name of the script under the /usr/lib/ocf/resource.d/heartbeat directory. In recent versions of Heartbeat (2.1.x) the OCF_ROOT environment variable must be set before an OCF script is called. Setting it on older versions of Heartbeat doesn’t do any harm so I unconditionally set it in this script (which should work for all 2.x.x versions of Heartbeat). The first parameter for the script is the id of the service to be operated on and the second parameter is the operation to perform (start, stop, and status are the only interesting values). The script will echo the exit code to the screen (0 means success, 7 means that the service is not running or the operation failed, and any other number means a serious error that will trigger a STONITH if Heartbeat gets it). #!/bin/sh
$(cibadmin -Q -o resources xmlstarlet sel -t -m \
"/resources/primitive [@id='$1']/instance_attributes/attributes/nvpair" \
--value-of "concat('export OCF_RESKEY_',@name,'=',@value,'
','TYPE=',../../../@type,'
')")
OCF_ROOT=/usr/lib/ocf /usr/lib/ocf/resource.d/heartbeat/$TYPE $2
echo $? Below is another version of the same script that instead uses crm_resource to get the XML data. The output of crm_resource has a couple of lines of non-XML data at the start (removed by the grep) and also only gives the XML tree related to the primitive in question (so the /resources part is removed from the xmlstarlet command-line). #!/bin/sh
$(crm_resource -r $1 -x grep -v ^[a-z] xmlstarlet sel -t -m \
  "/primitive/instance_attributes/attributes/nvpair" --value-of \
  "concat('export OCF_RESKEY_',@name,'=',@value,'
','TYPE=',../../../@type,'
')")
OCF_ROOT=/usr/lib/ocf /usr/lib/ocf/resource.d/heartbeat/$TYPE $2
echo $? The problem with both of those scripts is that they rely on Heartbeat being operational. Performing any operations other than a status check while Heartbeat is running is a risky thing to do. If Heartbeat starts a service at the same time as you start it via such a script then the results will probably be undesired. One situation where it is safe to run this is when a service fails to start. After it has failed repeatedly Heartbeat may stop trying to restart it (depending on the configuration) in which case it will be safe to try and start it. Also you can put in temporary constraints to stop the resource from running by repeatedly running crm_resource -M -r ID until all nodes have been prohibited from running it (make sure you run crm_resource -U -r ID afterwards to remove the temporary constraints). The following script does the same thing but directly reads the XML file for the Heartbeat configuration. This is designed to be used when Heartbeat is not running. For example you could copy the XML file from a running cluster to a test machine and then test your OCF resource scripts. #!/bin/sh
$(cat /var/lib/heartbeat/crm/cib.xml xmlstarlet sel -t -m \
  "/cib/configuration/resources/primitive [@id='$1']/instance_attributes/attributes/nvpair" \
  --value-of \
  "concat('export OCF_RESKEY_',@name,'=',@value,'
','TYPE=',../../../@type,'
')")
OCF_ROOT=/usr/lib/ocf /usr/lib/ocf/resource.d/heartbeat/$TYPE $2
echo $?

Eddy Petrișor: softfloat rrdtool sequel

Hey, I am back from vacation. I was back on Saturday but I didn't had the time to blog or do Debian work, so hello :-D.

After coming back from my vacation I went back to the softfloat rrdtool thingie I was working on before and I finaly managed to compile a statically linked softfloat uclibc rrdtool. Needless to say that I found that a pain and I ended up:

If you are curious about the hideous details, just add a comment or email me and I'll send them or publish them.

So, in the end, I managed to produce a staticlly linked arm-softfloat-uclibc rrdtool which:
So that was fun. The total round trip for a round of graph generation was about 15 min which was more than cool and fast compared to the slow native variant, whohoo!

Now the downside, I am not through with it. If you look at the picture you'll notice that there is a "small-ish" problem: there are no scales, legends and no letters/glyphs of any kind, so the graphs are still quite useless, but better than nothing:


They should look something like this:


Notice any difference? :-/

Of course, I won't stop here!

I suspect the problems come from the cross compiled libfreetype and libart_lgpl, and I'll probably end up doing some native compiling after all, sigh!

Nico Golde: newsbeuter 0.5

I just uploaded the 0.5 release of the newsbeuter RSS feed reader to unstable.
Apart from improvements in HTML rendering and lock file handling the new release:
and finally you are also able to freely configure all key bindings.

The new filter language is pretty cool, you can now filter feeds for title, url, author etc. (see the documentation for all fields) using regular expressions like:
rssurl =~ "^http:\/\/nion\.modprobe.*", you can use the comparison operators and you are able to logical connect them.

The regexp support also enables you to killfile certain articles using the new ignore-article option, ignore-article "*" "title =~ \"SuSE\"" for example ;-P (press F to try it out)

With the notification support you are allowed to execute a specified program if a new article arrives, easy and useful for blog junkies.

Hopefully newsbeuter will become a good alternative for raggle and snownews users now as the snownews author is not really working on it anymore and raggle seems to have a stalled development as well.

Biella Coleman: Thanks and remember, get your plants!

Thanks for sending me the article and someone also sent me a link to an accessible copy here. And remember, plants work wonders to curb indoor air pollution, which can be as bad or worse than outdoor ones. Here is a list of some of the best polluting fightin’ plants . I used to have many many many plants but when you move nearly every year, you slowly have to get rid of them. last year in Canada we had one and we had to sadly part way with the plant that has been with us for 5 years. But now that I have moved somewhere that will be my home for a bit, I am going to go a little nuts with the plants again. I just love having them. Now I need to find a good greenhouse in NYC that does not charge an arm and a leg.

David Welton: Windows for Linux Users

After many months of few contributions, and lots of spam, I decided to shut down the Windows for Linux Users wiki, and transfer its contents to an article on my new personal web site: http://www.welton.it/articles/windows_for_linux_users.html I will still accept contributions, of course, but it's more efficient to simply apply them myself rather than sort through a lot of spam on a relatively static wiki. The content is based on my experiences with windows several years ago - I realized that I knew very little about using it productively, and so I attempted to share what I learned about turninig it into an environment I could be productive in. Since most people go from Windows to Linux, they're not likely to face those problems, but for those who do, some of the listed tips and tricks are useful. These days, I can happily report that I'm happily back to a windows-free life.

Russell Coker: Xen Saves

A couple of days ago the hardware that is used to host this blog was upgraded - doubling the amount of RAM in the machine. To do this the machine was halted, memtest86+ was run to ensure that the new RAM worked correctly, and then it was booted up again. During that process my ssh session was not stopped! I merely refrained from typing anything until the upgrade was complete. This is one feature I really like about Xen. It can save the memory image of a running domain to a file and then restart it later. TCP sessions remain open if timeouts have not elapsed. The command xm save can be used to save the state to a file and the command xm restore will restore it. In Debian the location of the save files is stored in the file /etc/default/xendomains with the variable name XENDOMAINS_SAVE and defaults to /var/lib/xen/save. A quick experiment with one test domain (running Debian/unstable in 128M of RAM and had just run apt-get dist-upgrade so the memory contents would not be all zeros) showed that gzip -9 would decrease the file to 35% of it’s size at a cost of just over 1 minute of CPU time on a Pentium-M 1.7GHz. But gzip -3 compresses it to 37% and only takes 9 seconds. 9 seconds of CPU time to save 80M of disk space seems a reasonable trade-off. In my particular case it saves CPU time as the encryption I use for my root filesystem takes more CPU time than gzip -3 so compressing the data saves time. But I don’t expect my case to be common. Now when Xen is used on a more modern machine with a faster CPU gzip -3 has the potential to save time as well as disk space. A machine with a CPU that is in aggregate 10x faster than my laptop (I think that means most 64bit multi-core CPUs) running with a single S-ATA disk (that will have a sustained contiguous read speed of 80MB/s and write speed that is less) will save time when saving multiple Xen DomU’s if it runs them in parallel and compresses them. Also gzip is not the fastest compression program. There may be other options that are better suited to the needs of Xen. I have filed a Debian bug 435406 requesting that compression be supported.

Meike Reichle: Some more positive things and Dear launchpad.net Part 2

More happy people: following up on my last post on nice free software experiences Chris Ball has responded by posting one of his. Are there any more? Also talking about free software nuisances I remembered my recent grudge with launchpad.net. At that time I was contacted by someone from Canonical shortly after that first post. He said he'd pass my comment on, but in the next days nothing happened so I turned to other things and only occasionally checked back on the site. A few days ago I've again checked back and guess what, the objectionable title has been replaced, both for people using launchpad and for those who don't. The page's title for peple who do not actually use launchpad now reads "X does not use launchpad" and "X in launchpad" for those who do. Much better! Well done launchpad.net!

Steve Kemp: You better stop the things you do

A year ago I setup a xen hosting platform, because I was selfish and wanted a lot more resources than I could otherwise buy within my budget. At that time I managed to setup a system which gave 7 users 256Mb of memory, 10Gb of disk space and 3 IP addresses all for 11.50 a month, or 138 a year. On the first anniversary I've managed to increase those resources such that our users can now have: All for the same price. One user decided to buy two accounts upon the machine, so that he could have a combined 512mb+20Gb account, and as the resources have increased this year this is no longer required - so we have a space free for one more user. Last year several people asked for accounts and I had to reject them - I don't want to be a hosting company I just want to have enough users to fill a machine so that I can be selfish and get a higher spec for myself! So if anybody who asked last year is still looking for cheap hosting there will be one space at the given spec and price available from this coming Friday / Saturday. (Unfortunately I must insist upon a years payment in advance.) Uptime last year was good I can recall two reboots with minimal notice, which is reasonable enough I think. You'll get as much support as I can offer, my mobile number, and a clean install of any Debian derived distribution. (The xen-shell package was developed for this service last year, and allows you to reboot your machine remotely, manage reverse DNS, and connect to the serial console if you break your networking. You'll be able to use that over SSH.) Please comment if you're interested - If there are more people interested I guess I'll work though the list in order of comments until somebody commits to paying.. Questions welcome,. TODO: Update website, get great testimonials about my "service" ;) Update: Space gone.

Joey Hess: xen hosting

Thanks to hosting my server on xen hosting, Kite will get a faster CPU, and twice as much disk this year as it got last year. And I'll be paying only half what I paid last year. I can't say enough good things about the little co-op Steve has set up. Ineed, my only complaint after a year of hosting Kite on xen is that I can't yet install my own kernel. But the much nicer hardware than I could afford, the absurdly low price (lower than any other xen hosting I've found), xen's shielding me from server reboots and downtime and general mucking around with nasty hardware and colos, the xen-shell management interface, and everything else, is great. There's one free slot opening up on the machine. Whoever gets it will be a very lucky person. Everyone who doesn't should consider putting together a system following the xen hosting model.

1 August 2007

Russell Coker: Advogato and Hateful/Divisive Posts

Firstly for the benefit of people who haven’t heard of it, the Advogato FAQ and the Wikipedia Page describe what Advogato does. Pete Zaitcev posted a strange article about me to Advogato. In it he accused me of “pumping hateful leftist propaganda into Advogato“, said propaganda being my regular blog posts. In an addendum he accused me of insanity, and said that my “attacks” were “divisive“. I considered writing an Advogato post in response but first read the Posting Guidelines which say: Both of those criteria rule out Pete’s post and any response that I might make would risk being in breach of such conditions - so I will use my blog as the Advogato admins recommend. Pete’s ad-hominem attack on me claiming that my posts are hateful is bizarre. Pete, for the benefit of all the interested onlookers could you please inform us which of my posts you consider hateful and why you have such an opinion? As a general rule you should always cite articles that you reference. When you make accusations without any evidence to back them up it makes you look bad and prevents any positive discussion of the acts in question. As for the accusation of being divisive, that only happens when people are forced to choose sides. For example when you encourage other people to rate me down on Advogato because of my political opinions that can divide the community (in a small way, neither you, nor me, nor Advogato is important enough to cause a serious problem in this regard). The idea that I was intentionally pumping anything into Advogato was also strange to me. When I entered the URL for my blog into the Advogato settings page I didn’t even realise that it was being syndicated until I reviewed my web logs some time later. It seems that Advogato only has a small number of readers, a recent post about strange ZCAV performance included a graph and judging by the referrer tags it seems that 412 people read the post from Advogato out of 10468 total (so Advogato gets less than 4% of my readers). Planet Debian seems to get more than 15x the number of readers of Advogato. Incidentally if you don’t currently include images in your blog the reader tracking ability is one reason for including an image in an occasional post. Another strange ad-hominem attack was the reference to “college indoctrination“. When I was in university I supported the Liberal party (the Australian equivalent of the Republican party in the US). The influence of Linux programmers (including some of Pete’s colleagues at Red Hat) had much more of an effect on my political opinions than that of my university experience. I am not criticising Pete for disagreeing with me in regard to politics (I don’t even know what he disagrees with). Here are my specific criticisms of Pete’s behaviour:
  1. Ad-hominem attacks

  2. Encouraging mis-use of Advogato trust metrics for political reasons (this one may not have been deliberate)

  3. Non-specific accusations which do not allow me to either defend myself against the accusations or change my actions if he turns out to have any reasonable points

  4. Hypocrisy - he breaks two of the posting guidelines for the purpose of criticising my blog posts which supposedly break some unwritten rule

  5. Not reading the Advogato FAQ - it has a specific section about political disagreements
But I’m not going to advocate voting him down on Advogato. He does write some interesting things on occasion. Check out his page on guns for example.

Romain Francoise: Converting Debian packages from dpatch to quilt

I've been using quilt a lot at work recently (in a non-Debian environment), and I've been enjoying it very much. So much that I've decided to convert my Debian packages to it, from dpatch. Once you're used to quilt, using dpatch is almost literally painful. :)

There doesn't seem to be a ready-made guide on how to convert packages from dpatch to quilt, so here's how to do it painlessly in five easy steps:
  1. Install the quilt package (duh) and make sure that the QUILT_PATCHES variable is set to debian/patches in your shell environment. Or you can set it in your ~/.quiltrc file instead (see this post for other interesting settings).
  2. Delete the build dependency on dpatch from your debian/control file, replacing it with a dependency on quilt (>= 0.40).
  3. In your debian/rules file, include /usr/share/quilt/quilt.make instead of /usr/share/dpatch/dpatch.make.
  4. Convert all your dpatch files by using the following command from your package's top level:
    for p in $(dpatch list-all); do \
    quilt import -P $p.diff debian/patches/$p.dpatch; \
    quilt push; \
    done
  5. Delete dpatch files:
    rm -f debian/patches/00list debian/patches/*.dpatch
And that's pretty much it! You'll probably want to clean up the headers of your debian/patches/*.diff files since they'll still contain some dpatch markers. You can now build your package as usual. To edit a patch, use quilt push <patch>, quilt edit <file1> <file2>, finish with quilt refresh to save the patch.

For more information on how to use quilt, read the tutorial, it's in /usr/share/doc/quilt. You won't regret switching!

Biella Coleman: Printers and air quality

Thinking of getting a new printer? Check this out first. Oh and if you have access to the original, can you please send to me??? My library does not have access to the journal and I may be getting a new printer soon so it is good to know which ones will not lodge particles into my lungs.

Lior Kaplan: 3rd (and last) reminder for the OO.org bug triage

Today, with the slogan “Please help the Debian oo.org team to help you”, I’ve sent the 3rd (and final) reminder to bug submitters which have bugs against open office in versions older than 2.0.0. In the last month, 22 bugs were reproduced with newer versions of open office, and 49 bugs were closed as fixed or not relevant any more. By mid August all the remaining will be closed as the submitter didn’t respond to 3 pings during a period of 6 weeks, and the bug is reported to an ancient version of open office. When version 2.2.x will propagate to testing, I’ll do another triage get updates for the rest of the bugs.

Neil Williams: epiphany-browser extensions

Baby mentions using epiphany-browser as the default Gnome browser.
I did this a few weeks ago (when I had problems with Galeon). The most important thing to do with epiphany is:
$ sudo apt-get install epiphany-extensions

That gives epiphany a whole new lease of life. Galeon bookmarks can be imported and there are wonderful things called Smart Bookmarks. Like Galeon, these can be put on the toolbar with input boxes so that an entry in the input is substituted into the URL of the bookmark. Firefox/iceweasel has these for searching but epiphany allows a much more useful customisation. I use them to create several very useful smart bookmarks:

That makes it easy to look up particular packages and buildd status - just enter the package name or bug number in an input box on the toolbar! Lovely. You can add as many as you can fit into your window.
Well worth installing - and customising. Thanks epiphany.

Isaac Clerencia: Dream of Californication

Wow, the pilot of Californication, a new TV series starring David Duchovny (from X-Files hall of fame), is awesome! Quoting Wikipedia, the show is about “a troubled novelist whose obsessions with sex and drugs interfere with his personal and professional lives”. It was created by Showtime and it will begin airing on August 13th but the preair was leaked some days ago. It’s really cool and full of memorable quotes, I hope the rest of the episodes are as nice as the pilot. Go watch it!

Ross Burton: Poky Linux 3.0 "Blinky" Released

After much blood, sweat and tears, Poky Linux 3.0 (also known as Blinky) is released. Poky is an OpenEmbedded derivative, focused on building GNOME Mobile-based images for embedded and handheld devices such as the Sharp Zaurus or the Nokia N800. Aside from the usual set of software updates and infrastructure improvements, Blinky contains the first public release of Sato, an example GTK+/Matchbox based PDA environment aimed at devices with high resolution, physically small screens. This includes a new Matchbox panel and desktop, the Pimlico suite of PIM applications, and a fast, clear GTK+ theme. Pretty much everyone at OpenedHand has been involved in Poky to some extent, so it's great to see a release. Personally I'm really pleased with how far Blinky has advanced over the last release, Clyde, and will shortly be working on a branch of Blinky to integrate the complete GNOME 2.20 release set. If anyone is interested in Poky then it is easy to try: there are for a several devices: the Nokia N800 and several Sharp Zaurus models; and Qemu images for both ARM and Intel. Give it a go and tell us what you think! NP: Love and Affection, Joan Armatrading

Ross Burton: Daily Mail vs British Medical Journal

From an article in the Daily Mail this week:
Previous studies have found that cannabis claims 30,000 lives a year by causing cancer, heart disease and bronchitis, and that it can double the risk of mental illnesses such as schizophrenia.
Now, I wonder where that data is from. Oh look, the British Medical Journal:
It may be argued that the extrapolation from small numbers of individual studies to potential large scale effects amounts to scaremongering. For example, one could calculate that if cigarettes cause an annual excess of 120 000 deaths among 13 million smokers, the corresponding figure for deaths among 3.2 million cannabis smokers would be 30 000, assuming equality of effect.
Genius. Thanks to Dr Ben Goldache for spotting this. NP: The Good, The Bad & The Queen, The Good, The Bad & The Queen

Lars Wirzenius: Obnam: Generating backup data sets

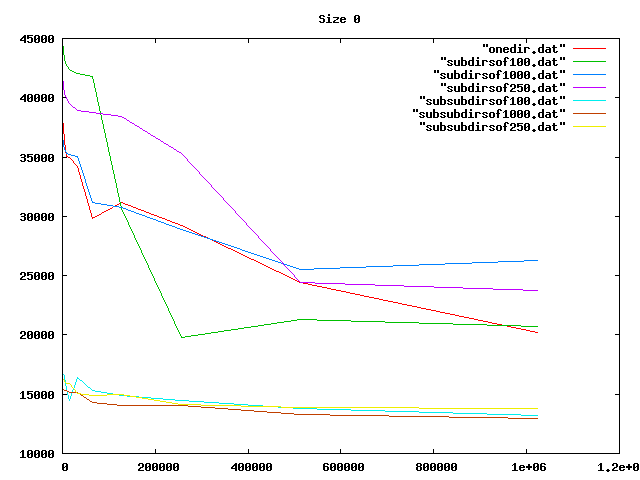
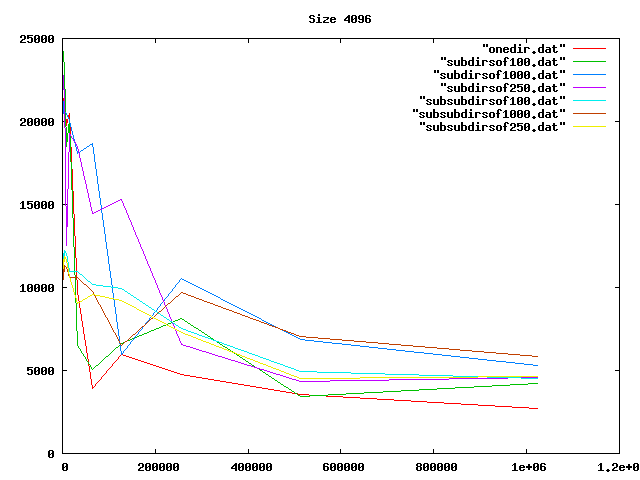
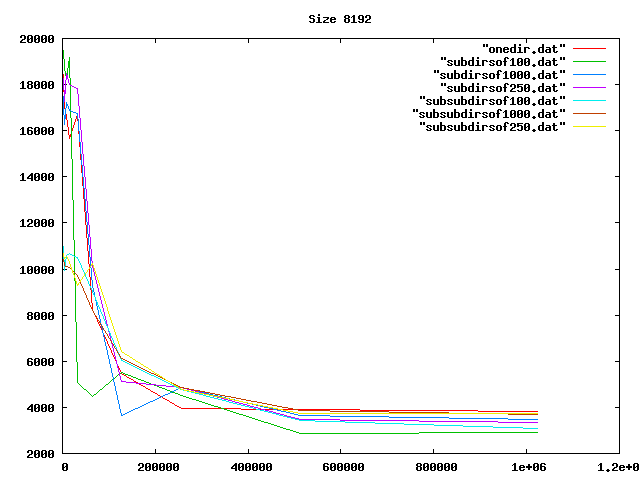
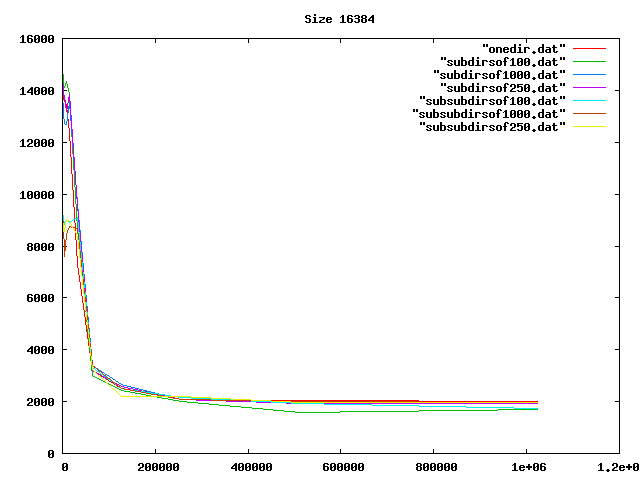
Sometimes in programming one gets to concentrate for a bit on a single, simple, pure program. A command line utility which is completely in batch mode, does not handle any kind of complicated data, does not need to deal with other programs, or the network, or anything nasty like that. Something where one can just look at the one or two interesting parts and not have to worry about anything else. This is the story of one such program. I need a program to generate test data sets for backup performance testing. The program needs to be reasonably efficient, since the simulated backups may be rather large. My first attempt was not fast enough. There were two reasons for this: the way I was generating random binary data, and the way I was generating filenames. The program generates random binary data to simulate large files, such as image, audio, or video files, and thus it needs to be uncompressible with the usual compression algorithms. My first attempt was to generate each output byte with the Python pseudo-random number generator (random.randint). This only results in about 0.1 megabyte/s (on my laptop), so I needed to improve it. After some iteration and advice, I landed on the following: I generate random bytes with the Python PRNG (random.getrandbits), and feed these to an MD5 checksum. After each byte, I get the current digest and append it to the output. This way, for each random byte, I get 16 bytes of output. It isn't completely random, but it satisfies the uncompressibility requirement. This resulted in about 2.5 MB/s. I then tweaked the code a bit, doing things like avoiding unnecessary arithmetic. I further decided to only feed the first few dozen bytes from the PRNG, and the rest as the same constant byte. The initial run of randomness is enough to make sure the output is unique for different files, so that compression doesn't find lots of duplicates of the big files. This resulted in a speed of about 6.6 MB/s on my laptop and about 13 MB/s on my server. This still didn't make the program fast enough, but the remaining problem was not that writing the contents of one file was too slow, but operations on directories were very, very slow. After benchmarking with zero-byte files, turns out that at the slowest, with file counts in the millions, it would create only a few tens of files per second. That's empty files, so only requiring an update of indoes and the creation of a new directory entry. Obviously, the problem was that I was putting too many files in directories, causing the filesystem to spend a lot time scanning them. I was creating up to 250 files per sub-directory, and then creating a new sub-directory. All of these sub-directories were going directly under the user's chosen output directory. To measure what the optimal size of a directory was, and whether to create two levels of sub-directories, I wrote a little benchmark program.
Graph, 0-byte files Graph, 4096-byte files Graph, 8196-byte files Graph, 16384-byte files Some graphs from the benchamrks: for 0, 4, 8, and 16 KiB files, for up to one million files of each size. onedir puts all files in the same directory, subdirsofN puts N files per directory, and subsubdirsofN has two levels of directories, the leaf directories getting N files each.
From the graphs I deduced that overall, having two levels of directories and up to 1000 files per sub-directory was the best option of those tested. On the other hand, the bigger the files, the less it mattered what the directory structure was. Perhaps the obvious reason for the slowness wasn't that, after all. Then I realized my code was slow because I was doing an os.listdir (listing all files in a directory) for every directory every time I creted a file. Fixing that idiocy made the code so fast that any overhead from the directory operations was no longer relevant. But at least I had some nice graphs. On the server I will be generating my test data the program is now happily generating just over 11 MB/s of test data. I wouldn't mind having it be a lot faster, but it's fast enough. It will take hours to generate hundreds of gigabytes, but I hopefully won't need to do that very often. Thus, further optimization isn't worth my time, right now. The program is genbackupdata, in case anyone else cares about it.

31 July 2007

Adeodato Sim : Coming out

I really believe we should not require repacking the original tarball to strip non-free but distributeable stuff, as long as that non-free stuff is not installed in the resulting binary packages, nor used in any parts of the building process.

Next.

Previous.