Search Results: "spa"

28 October 2016

Jaldhar Vyas: Get Ready For Bikini Season With These n Weird Tricks

It all started last June when my son had his Janoi (Yagnopavita) ceremony -- the ritual by which a Brahmana boy becomes "twice-born" and eligible to study the Vedas. As well as a profound religious experience, it is also an important social occasion with a reception for as many friends and family as can attend. (I think our final guest total was ~250.) This meant new outfits for everyone which might be exciting for some people but not me. I still don't know why I couldn't just keep wearing the khes and pitambar from the puja but no, apparently that's a faux pas. So I relented and agreed to wear my "darbari" suit from my wedding. And it didn't fit. I knew I had gained some weight in the intermediate 17 years but the thing was sitcom levels of too small. I ended up having to purchase a new one, a snazzy (and shiny!) maroon number with gold stripes (or were they black stripes?) Problem having been solved, much was eaten, more weight was gained and then I forgot about the whole thing. Tip 1: Actually Do Something. I have over the years tried to improve my physical condition but it has never gotten very far. For instance I have a treadmill/coatrack and a couple of years ago I began using it in earnest. I got to the point where I actually ran a 10K race without dying. But I did not train systematically and I ended up in some pain which caused me to stop working out for a while and then I never got around to restarting. Diets have also failed because I don't have a clear idea of what and how much I am eating. All I know is that women go into the kitchen and when they come out they have food. By what eldritch process this occurs is a mystery, I just eat whats given to me thankful that the magic happens. Once I was moved to try and help but quickly fell afoul of the lack of well-defined algorithms in Gujarati home cooking.
"How much saffron should I add?"
"this much."
"How much is this much in SI units?"
"You're annoying me. Get out."
Fast forward to March of this year. For my birthday, my wife got me a Fitbit fitness tracker. This is what I had needed all this time. It measure heart rate, distance travelled, time slept and several other pieces of info you can use to really plan a fitness regimen rationally. For example, I was chagrined to learn that sometimes when I'm at the computer, I am so immobile that the fitbit thought I was asleep. So I started planning to taken more frequent breaks. (A recent firmware upgrade has added the ability to nudge to walk atleast 250 paces each daytime hour which is handy for this.) Also by checking my heart rate I discovered that I went on the treadmill I ran too fast thereby stressing my body for little gain and ending up going too slow to get much aerobic effect. Now I can pace myself appropriately for maximum cardiac efficiency without ending up injuring myself and giving up. I also get a little more activity each day by simple changes such as taking the stairs instead of the lift and instead of getting off at the 14th street PATH I go all the way to 34th street and walk down. Tip 2: You must have data in order to see what you did right or wrong and to plan what you need to do moving forward. One caveat about these fitness trackers. They are not anywhere as accurate as a proper checkup from a doctor who specializes in such things. If you want to do any kind of pro or amateur athletics you probably should not rely on them but for the average shlub who just wants to avoid appearing on the news being winched off his sofa by the fire brigade they are good enough. Another practice I began was keeping a food diary. It can be a real eye-opener to see how much you are actually eating. It is probably much more than you thought. I am fortunate that my diet is pretty good to begin with. Vegetarian, (not vegan, Hindus eat dairy products,) mostly home-cooked with fresh ingredients, not fried or processed, and I don't drink alcohol. However there were a few optimizations I could make. I drink a lot of soda; atleast two cans a day. I really ought to stop altogether but in lieu of that I have atleast switched from Coke to Coke Zero thereby saving a lot of empty calories. I now eat 4 rotlis with my dinner instead of six. We as a family eat more green vegetables instead of potatos, skim milk instead of whole fat, canola oil instead of corn oil, and less rice and don't slather ghee on everything quite so much. One entirely new practice I've adopted that may seem faddish but works for me is intermittent fasting. The idea is to steadily train your body to need less food by eating all your days allowed amount pf calories during a 6-8 hour window and not eating at all during the remaining time. It's hard to get used to for many people but I fast atleast 2-3 times a month for religious reasons anyway so I adapted pretty quickly. The fitbit tells me how many calories I am expending and how many I can eat to maintain a healthy level of weight loss but other than that I don't bother with "food groups" or specific diets such as paleo, or low-carb etc. As long as what you eat is reasonably balanced and you are burning more calories than you are adding, it should be enough for weight loss. Indeed from the end of March to now, I've lost 3 stones (20Kg) even with the occasional "cheat" day. Tip 3: All published diets are bullshit without scientifically proven efficacy. Don't bother with them. Experiment instead and see what works for you and your metabolism. As long as you are getting all the proper nutrients (you shouldn't need a supplement unless you have an actual medical condition.) and you have a net calorie deficit, it's all good. If you eat food you enjoy, you are more likely to stick to your diet. The proper amount of sleep is one area of a healthy lifestyle I am still doing poorly in and the reasons are not all raven-related. I have always had problems with insomnia and was once actually diagnosed with sleep apnea. Losing weight has helped a lot but the fitbit is still reporting that I toss and turn a lot during the night. And that's when I'm in bed in the first place. I stay up much too late which can also lead to subsidiary bad behaviours such as midnight snacking. It's something I need to work on. Tip 4: Stop blogging at all hours of the night, It's not doing you any good. So that's what I'm doing. Moving forward, I need to deal with the sleep thing and I would also like to start some program of strength-training, I'm doing ok in terms of aerobic exercise but from what I've read, you also have to build up muscles to keep weight loss permanent. The difficulty is that it would involve joining a gym and then actually going to that gym so I've put it off for now. The immediate threat is Diwali (and Thanksgiving and Christmas...) My wife bought 4 lbs of sweets today and I can feel their presence in the fridge calling to me.

27 October 2016

Russ Allbery: DocKnot 1.00

I'm a bit of a perfectionist about package documentation, and I'm also a huge fan of consistency. As I've slowly accumulated more open source software packages (alas, fewer new ones these days since I have less day-job time to work on them), I've developed a standard format for package documentation files, particularly the README in the package and the web pages I publish. I've iterated on these, tweaking them and messing with them, trying to incorporate all my accumulated wisdom about what information people need. Unfortunately, this gets very tedious, since I have dozens of packages at this point and rarely want to go through the effort of changing every one of them every time I come up with a better way of phrasing something or change some aspect of my standard package build configuration. I also have the same information duplicated in multiple locations (the README and the web page for the package). And there's a lot of boilerplate that's common for all of my packages that I don't want to keep copying (or changing when I do things like change all eyrie.org URLs to HTTPS). About three years ago, I started seriously brainstorming ways of automating this process. I made a start on it during one self-directed day at my old job at Stanford, but only got it far enough to generate a few basic files. Since then, I keep thinking about it, keep wishing I had it, and keep not putting the work into finishing it. During this vacation, after a week and a half of relaxing and reading, I finally felt like doing a larger development project and finally started working on this for long enough to build up some momentum. Two days later, and this is finally ready for an initial release. DocKnot uses metadata (which I'm putting in docs/metadata) that's mostly JSON plus some documentation fragments and generates README, the web page for the package (in thread, the macro language I use for all my web pages), and (the other thing I've wanted to do and didn't want to tackle without this tool) README.md, a Markdown version of README that will look nice on GitHub. The templates that come with the package are all rather specific to me, particularly the thread template which would be unusable by anyone else. I have no idea if anyone else will want to use this package (and right now the metadata format is entirely undocumented). But since it's a shame to not release things as free software, and since I suspect I may need to upload it to Debian since, technically, this tool is required to "build" the README file distributed with my packages, here it is. I've also uploaded it to CPAN (it's my first experiment with the App::* namespace for things that aren't really meant to be used as a standalone Perl module). You can get the latest version from the DocKnot distribution page (which is indeed generated with DocKnot). Also now generated with DocKnot are the rra-c-util and C TAP Harness distribution pages. Let me know if you see anything weird; there are doubtless still a few bugs.

26 October 2016

Christoph Egger: Installing a python systemd service?

As web search engines and IRC seems to be of no help, maybe someone here has a helpful idea. I have some service written in python that comes with a .service file for systemd. I now want to build&install a working service file from the software's setup.py. I can override the build/build_py commands of setuptools, however that way I still lack knowledge wrt. the bindir/prefix where my service script will be installed. Solution Turns out, if you override the install command (not the install_data!), you will have self.root and self.install_scripts (and lots of other self.install_*). As a result, you can read the template and write the desired output file after calling super's run method. The fix was inspired by GateOne (which, however doesn't get the --root parameter right, you need to strip self.root from the beginning of the path to actually make that work as intended). As suggested on IRC, the snippet (and my software) no use pkg-config to get at the systemd path as well. This is a nice improvement orthogonal to the original problem. The implementation here follows bley.

def systemd_unit_path():
    try:
        command = ["pkg-config", "--variable=systemdsystemunitdir", "systemd"]
        path = subprocess.check_output(command, stderr=subprocess.STDOUT)
        return path.decode().replace('\n', '')
    except (subprocess.CalledProcessError, OSError):
        return "/lib/systemd/system"
class my_install(install):
    _servicefiles = [
        'foo/bar.service',
        ]
    def run(self):
        install.run(self)
        if not self.dry_run:
            bindir = self.install_scripts
            if bindir.startswith(self.root):
                bindir = bindir[len(self.root):]
            systemddir = "%s%s" % (self.root, systemd_unit_path())
            for servicefile in self._servicefiles:
                service = os.path.split(servicefile)[1]
                self.announce("Creating %s" % os.path.join(systemddir, service),
                              level=2)
                with open(servicefile) as servicefd:
                    servicedata = servicefd.read()
                with open(os.path.join(systemddir, service), "w") as servicefd:
                    servicefd.write(servicedata.replace("%BINDIR%", bindir))
Comments, suggestions and improvements, of course, welcome!

Daniel Pocock: FOSDEM 2017 Real-Time Communications Call for Participation

FOSDEM is one of the world's premier meetings of free software developers, with over five thousand people attending each year. FOSDEM 2017 takes place 4-5 February 2017 in Brussels, Belgium. This email contains information about:
  • Real-Time communications dev-room and lounge,
  • speaking opportunities,
  • volunteering in the dev-room and lounge,
  • related events around FOSDEM, including the XMPP summit,
  • social events (the legendary FOSDEM Beer Night and Saturday night dinners provide endless networking opportunities),
  • the Planet aggregation sites for RTC blogs
Call for participation - Real Time Communications (RTC) The Real-Time dev-room and Real-Time lounge is about all things involving real-time communication, including: XMPP, SIP, WebRTC, telephony, mobile VoIP, codecs, peer-to-peer, privacy and encryption. The dev-room is a successor to the previous XMPP and telephony dev-rooms. We are looking for speakers for the dev-room and volunteers and participants for the tables in the Real-Time lounge. The dev-room is only on Saturday, 4 February 2017. The lounge will be present for both days. To discuss the dev-room and lounge, please join the FSFE-sponsored Free RTC mailing list. To be kept aware of major developments in Free RTC, without being on the discussion list, please join the Free-RTC Announce list. Speaking opportunities Note: if you used FOSDEM Pentabarf before, please use the same account/username Real-Time Communications dev-room: deadline 23:59 UTC on 17 November. Please use the Pentabarf system to submit a talk proposal for the dev-room. On the "General" tab, please look for the "Track" option and choose "Real-Time devroom". Link to talk submission. Other dev-rooms and lightning talks: some speakers may find their topic is in the scope of more than one dev-room. It is encouraged to apply to more than one dev-room and also consider proposing a lightning talk, but please be kind enough to tell us if you do this by filling out the notes in the form. You can find the full list of dev-rooms on this page and apply for a lightning talk at https://fosdem.org/submit Main track: the deadline for main track presentations is 23:59 UTC 31 October. Leading developers in the Real-Time Communications field are encouraged to consider submitting a presentation to the main track. First-time speaking? FOSDEM dev-rooms are a welcoming environment for people who have never given a talk before. Please feel free to contact the dev-room administrators personally if you would like to ask any questions about it. Submission guidelines The Pentabarf system will ask for many of the essential details. Please remember to re-use your account from previous years if you have one. In the "Submission notes", please tell us about:
  • the purpose of your talk
  • any other talk applications (dev-rooms, lightning talks, main track)
  • availability constraints and special needs
You can use HTML and links in your bio, abstract and description. If you maintain a blog, please consider providing us with the URL of a feed with posts tagged for your RTC-related work. We will be looking for relevance to the conference and dev-room themes, presentations aimed at developers of free and open source software about RTC-related topics. Please feel free to suggest a duration between 20 minutes and 55 minutes but note that the final decision on talk durations will be made by the dev-room administrators. As the two previous dev-rooms have been combined into one, we may decide to give shorter slots than in previous years so that more speakers can participate. Please note FOSDEM aims to record and live-stream all talks. The CC-BY license is used. Volunteers needed To make the dev-room and lounge run successfully, we are looking for volunteers:
  • FOSDEM provides video recording equipment and live streaming, volunteers are needed to assist in this
  • organizing one or more restaurant bookings (dependending upon number of participants) for the evening of Saturday, 4 February
  • participation in the Real-Time lounge
  • helping attract sponsorship funds for the dev-room to pay for the Saturday night dinner and any other expenses
  • circulating this Call for Participation (text version) to other mailing lists
See the mailing list discussion for more details about volunteering. Related events - XMPP and RTC summits The XMPP Standards Foundation (XSF) has traditionally held a summit in the days before FOSDEM. There is discussion about a similar summit taking place on 2 and 3 February 2017. XMPP Summit web site - please join the mailing list for details. We are also considering a more general RTC or telephony summit, potentially in collaboration with the XMPP summit. Please join the Free-RTC mailing list and send an email if you would be interested in participating, sponsoring or hosting such an event. Social events and dinners The traditional FOSDEM beer night occurs on Friday, 3 February. On Saturday night, there are usually dinners associated with each of the dev-rooms. Most restaurants in Brussels are not so large so these dinners have space constraints and reservations are essential. Please subscribe to the Free-RTC mailing list for further details about the Saturday night dinner options and how you can register for a seat. Spread the word and discuss If you know of any mailing lists where this CfP would be relevant, please forward this email (text version). If this dev-room excites you, please blog or microblog about it, especially if you are submitting a talk. If you regularly blog about RTC topics, please send details about your blog to the planet site administrators:
Planet site Admin contact
All projects Free-RTC Planet (http://planet.freertc.org) contact planet@freertc.org
XMPP Planet Jabber (http://planet.jabber.org) contact ralphm@ik.nu
SIP Planet SIP (http://planet.sip5060.net) contact planet@sip5060.net
SIP (Espa ol) Planet SIP-es (http://planet.sip5060.net/es/) contact planet@sip5060.net
Please also link to the Planet sites from your own blog or web site as this helps everybody in the free real-time communications community. Contact For any private queries, contact us directly using the address fosdem-rtc-admin@freertc.org and for any other queries please ask on the Free-RTC mailing list. The dev-room administration team:

Joachim Breitner: Showcasing Applicative

My plan for this week s lecture of the CIS 194 Haskell course at the University of Pennsylvania is to dwell a bit on the concept of Functor, Applicative and Monad, and to highlight the value of the Applicative abstraction. I quite like the example that I came up with, so I want to share it here. In the interest of long-term archival and stand-alone presentation, I include all the material in this post.1

Imports In case you want to follow along, start with these imports:
import Data.Char
import Data.Maybe
import Data.List
import System.Environment
import System.IO
import System.Exit

The parser The starting point for this exercise is a fairly standard parser-combinator monad, which happens to be the result of the student s homework from last week:
newtype Parser a = P (String -> Maybe (a, String))
runParser :: Parser t -> String -> Maybe (t, String)
runParser (P p) = p
parse :: Parser a -> String -> Maybe a
parse p input = case runParser p input of
    Just (result, "") -> Just result
    _ -> Nothing -- handles both no result and leftover input
noParserP :: Parser a
noParserP = P (\_ -> Nothing)
pureParserP :: a -> Parser a
pureParserP x = P (\input -> Just (x,input))
instance Functor Parser where
    fmap f p = P $ \input -> do
	(x, rest) <- runParser p input
	return (f x, rest)
instance Applicative Parser where
    pure = pureParserP
    p1 <*> p2 = P $ \input -> do
        (f, rest1) <- runParser p1 input
        (x, rest2) <- runParser p2 rest1
        return (f x, rest2)
instance Monad Parser where
    return = pure
    p1 >>= k = P $ \input -> do
        (x, rest1) <- runParser p1 input
        runParser (k x) rest1
anyCharP :: Parser Char
anyCharP = P $ \input -> case input of
    (c:rest) -> Just (c, rest)
    []       -> Nothing
charP :: Char -> Parser ()
charP c = do
    c' <- anyCharP
    if c == c' then return ()
               else noParserP
anyCharButP :: Char -> Parser Char
anyCharButP c = do
    c' <- anyCharP
    if c /= c' then return c'
               else noParserP
letterOrDigitP :: Parser Char
letterOrDigitP = do
    c <- anyCharP
    if isAlphaNum c then return c else noParserP
orElseP :: Parser a -> Parser a -> Parser a
orElseP p1 p2 = P $ \input -> case runParser p1 input of
    Just r -> Just r
    Nothing -> runParser p2 input
manyP :: Parser a -> Parser [a]
manyP p = (pure (:) <*> p <*> manyP p)  orElseP  pure []
many1P :: Parser a -> Parser [a]
many1P p = pure (:) <*> p <*> manyP p
sepByP :: Parser a -> Parser () -> Parser [a]
sepByP p1 p2 = (pure (:) <*> p1 <*> (manyP (p2 *> p1)))  orElseP  pure []
A parser using this library for, for example, CSV files could take this form:
parseCSVP :: Parser [[String]]
parseCSVP = manyP parseLine
  where
    parseLine = parseCell  sepByP  charP ',' <* charP '\n'
    parseCell = do
        charP '"'
        content <- manyP (anyCharButP '"')
        charP '"'
        return content

We want EBNF Often when we write a parser for a file format, we might also want to have a formal specification of the format. A common form for such a specification is EBNF. This might look as follows, for a CSV file:
cell = '"',  not-quote , '"';
line = (cell,  ',', cell    ''), newline;
csv  =  line ;
It is straightforward to create a Haskell data type to represent an EBNF syntax description. Here is a simple EBNF library (data type and pretty-printer) for your convenience:
data RHS
  = Terminal String
    NonTerminal String
    Choice RHS RHS
    Sequence RHS RHS
    Optional RHS
    Repetition RHS
  deriving (Show, Eq)
ppRHS :: RHS -> String
ppRHS = go 0
  where
    go _ (Terminal s)     = surround "'" "'" $ concatMap quote s
    go _ (NonTerminal s)  = s
    go a (Choice x1 x2)   = p a 1 $ go 1 x1 ++ "   " ++ go 1 x2
    go a (Sequence x1 x2) = p a 2 $ go 2 x1 ++ ", "  ++ go 2 x2
    go _ (Optional x)     = surround "[" "]" $ go 0 x
    go _ (Repetition x)   = surround " " " " $ go 0 x
    surround c1 c2 x = c1 ++ x ++ c2
    p a n   a > n     = surround "(" ")"
            otherwise = id
    quote '\'' = "\\'"
    quote '\\' = "\\\\"
    quote c    = [c]
type Production = (String, RHS)
type BNF = [Production]
ppBNF :: BNF -> String
ppBNF = unlines . map (\(i,rhs) -> i ++ " = " ++ ppRHS rhs ++ ";")

Code to produce EBNF We had a good time writing combinators that create complex parsers from primitive pieces. Let us do the same for EBNF grammars. We could simply work on the RHS type directly, but we can do something more nifty: We create a data type that keeps track, via a phantom type parameter, of what Haskell type the given EBNF syntax is the specification:
newtype Grammar a = G RHS
ppGrammar :: Grammar a -> String
ppGrammar (G rhs) = ppRHS rhs
So a value of type Grammar t is a description of the textual representation of the Haskell type t. Here is one simple example:
anyCharG :: Grammar Char
anyCharG = G (NonTerminal "char")
Here is another one. This one does not describe any interesting Haskell type, but is useful when spelling out the special characters in the syntax described by the grammar:
charG :: Char -> Grammar ()
charG c = G (Terminal [c])
A combinator that creates new grammar from two existing grammars:
orElseG :: Grammar a -> Grammar a -> Grammar a
orElseG (G rhs1) (G rhs2) = G (Choice rhs1 rhs2)
We want the convenience of our well-known type classes in order to combine these values some more:
instance Functor Grammar where
    fmap _ (G rhs) = G rhs
instance Applicative Grammar where
    pure x = G (Terminal "")
    (G rhs1) <*> (G rhs2) = G (Sequence rhs1 rhs2)
Note how the Functor instance does not actually use the function. How should it? There are no values inside a Grammar! We cannot define a Monad instance for Grammar: We would start with (G rhs1) >>= k = , but there is simply no way of getting a value of type a that we can feed to k. So we will do without a Monad instance. This is interesting, and we will come back to that later. Like with the parser, we can now begin to build on the primitive example to build more complicated combinators:
manyG :: Grammar a -> Grammar [a]
manyG p = (pure (:) <*> p <*> manyG p)  orElseG  pure []
many1G :: Grammar a -> Grammar [a]
many1G p = pure (:) <*> p <*> manyG p
sepByG :: Grammar a -> Grammar () -> Grammar [a]
sepByG p1 p2 = ((:) <$> p1 <*> (manyG (p2 *> p1)))  orElseG  pure []
Let us run a small example:
dottedWordsG :: Grammar [String]
dottedWordsG = many1G (manyG anyCharG <* charG '.')
*Main> putStrLn $ ppGrammar dottedWordsG
'', ('', char, ('', char, ('', char, ('', char, ('', char, ('',  
Oh my, that is not good. Looks like the recursion in manyG does not work well, so we need to avoid that. But anyways we want to be explicit in the EBNF grammars about where something can be repeated, so let us just make many a primitive:
manyG :: Grammar a -> Grammar [a]
manyG (G rhs) = G (Repetition rhs)
With this definition, we already get a simple grammar for dottedWordsG:
*Main> putStrLn $ ppGrammar dottedWordsG
'',  char , '.',  char , '.' 
This already looks like a proper EBNF grammar. One thing that is not nice about it is that there is an empty string ('') in a sequence ( , ). We do not want that. Why is it there in the first place? Because our Applicative instance is not lawful! Remember that pure id <*> g == g should hold. One way to achieve that is to improve the Applicative instance to optimize this case away:
instance Applicative Grammar where
    pure x = G (Terminal "")
    G (Terminal "") <*> G rhs2 = G rhs2
    G rhs1 <*> G (Terminal "") = G rhs1
    (G rhs1) <*> (G rhs2) = G (Sequence rhs1 rhs2)
	 
Now we get what we want:
*Main> putStrLn $ ppGrammar dottedWordsG
 char , '.',  char , '.' 
Remember our parser for CSV files above? Let me repeat it here, this time using only Applicative combinators, i.e. avoiding (>>=), (>>), return and do-notation:
parseCSVP :: Parser [[String]]
parseCSVP = manyP parseLine
  where
    parseLine = parseCell  sepByP  charG ',' <* charP '\n'
    parseCell = charP '"' *> manyP (anyCharButP '"') <* charP '"'
And now we try to rewrite the code to produce Grammar instead of Parser. This is straightforward with the exception of anyCharButP. The parser code for that inherently monadic, and we just do not have a monad instance. So we work around the issue by making that a primitive grammar, i.e. introducing a non-terminal in the EBNF without a production rule pretty much like we did for anyCharG:
primitiveG :: String -> Grammar a
primitiveG s = G (NonTerminal s)
parseCSVG :: Grammar [[String]]
parseCSVG = manyG parseLine
  where
    parseLine = parseCell  sepByG  charG ',' <* charG '\n'
    parseCell = charG '"' *> manyG (primitiveG "not-quote") <* charG '"'
Of course the names parse are not quite right any more, but let us just leave that for now. Here is the result:
*Main> putStrLn $ ppGrammar parseCSVG
 ('"',  not-quote , '"',  ',', '"',  not-quote , '"'    ''), '
' 
The line break is weird. We do not really want newlines in the grammar. So let us make that primitive as well, and replace charG '\n' with newlineG:
newlineG :: Grammar ()
newlineG = primitiveG "newline"
Now we get
*Main> putStrLn $ ppGrammar parseCSVG
 ('"',  not-quote , '"',  ',', '"',  not-quote , '"'    ''), newline 
which is nice and correct, but still not quite the easily readable EBNF that we saw further up.

Code to produce EBNF, with productions We currently let our grammars produce only the right-hand side of one EBNF production, but really, we want to produce a RHS that may refer to other productions. So let us change the type accordingly:
newtype Grammar a = G (BNF, RHS)
runGrammer :: String -> Grammar a -> BNF
runGrammer main (G (prods, rhs)) = prods ++ [(main, rhs)]
ppGrammar :: String -> Grammar a -> String
ppGrammar main g = ppBNF $ runGrammer main g
Now we have to adjust all our primitive combinators (but not the derived ones!):
charG :: Char -> Grammar ()
charG c = G ([], Terminal [c])
anyCharG :: Grammar Char
anyCharG = G ([], NonTerminal "char")
manyG :: Grammar a -> Grammar [a]
manyG (G (prods, rhs)) = G (prods, Repetition rhs)
mergeProds :: [Production] -> [Production] -> [Production]
mergeProds prods1 prods2 = nub $ prods1 ++ prods2
orElseG :: Grammar a -> Grammar a -> Grammar a
orElseG (G (prods1, rhs1)) (G (prods2, rhs2))
    = G (mergeProds prods1 prods2, Choice rhs1 rhs2)
instance Functor Grammar where
    fmap _ (G bnf) = G bnf
instance Applicative Grammar where
    pure x = G ([], Terminal "")
    G (prods1, Terminal "") <*> G (prods2, rhs2)
        = G (mergeProds prods1 prods2, rhs2)
    G (prods1, rhs1) <*> G (prods2, Terminal "")
        = G (mergeProds prods1 prods2, rhs1)
    G (prods1, rhs1) <*> G (prods2, rhs2)
        = G (mergeProds prods1 prods2, Sequence rhs1 rhs2)
primitiveG :: String -> Grammar a
primitiveG s = G (NonTerminal s)
The use of nub when combining productions removes duplicates that might be used in different parts of the grammar. Not efficient, but good enough for now. Did we gain anything? Not yet:
*Main> putStr $ ppGrammar "csv" (parseCSVG)
csv =  ('"',  not-quote , '"',  ',', '"',  not-quote , '"'    ''), newline ;
But we can now introduce a function that lets us tell the system where to give names to a piece of grammar:
nonTerminal :: String -> Grammar a -> Grammar a
nonTerminal name (G (prods, rhs))
  = G (prods ++ [(name, rhs)], NonTerminal name)
Ample use of this in parseCSVG yields the desired result:
parseCSVG :: Grammar [[String]]
parseCSVG = manyG parseLine
  where
    parseLine = nonTerminal "line" $
        parseCell  sepByG  charG ',' <* newline
    parseCell = nonTerminal "cell" $
        charG '"' *> manyG (primitiveG "not-quote") <* charG '"
*Main> putStr $ ppGrammar "csv" (parseCSVG)
cell = '"',  not-quote , '"';
line = (cell,  ',', cell    ''), newline;
csv =  line ;
This is great!

Unifying parsing and grammar-generating Note how simliar parseCSVG and parseCSVP are! Would it not be great if we could implement that functionality only once, and get both a parser and a grammar description out of it? This way, the two would never be out of sync! And surely this must be possible. The tool to reach for is of course to define a type class that abstracts over the parts where Parser and Grammer differ. So we have to identify all functions that are primitive in one of the two worlds, and turn them into type class methods. This includes char and orElse. It includes many, too: Although manyP is not primitive, manyG is. It also includes nonTerminal, which does not exist in the world of parsers (yet), but we need it for the grammars. The primitiveG function is tricky. We use it in grammars when the code that we might use while parsing is not expressible as a grammar. So the solution is to let it take two arguments: A String, when used as a descriptive non-terminal in a grammar, and a Parser a, used in the parsing code. Finally, the type classes that we except, Applicative (and thus Functor), are added as constraints on our type class:
class Applicative f => Descr f where
    char :: Char -> f ()
    many :: f a -> f [a]
    orElse :: f a -> f a -> f a
    primitive :: String -> Parser a -> f a
    nonTerminal :: String -> f a -> f a
The instances are easily written:
instance Descr Parser where
    char = charP
    many = manyP
    orElse = orElseP
    primitive _ p = p
    nonTerminal _ p = p
instance Descr Grammar where
    char = charG
    many = manyG
    orElse = orElseG
    primitive s _ = primitiveG s
    nonTerminal s g = nonTerminal s g
And we can now take the derived definitions, of which so far we had two copies, and define them once and for all:
many1 :: Descr f => f a -> f [a]
many1 p = pure (:) <*> p <*> many p
anyChar :: Descr f => f Char
anyChar = primitive "char" anyCharP
dottedWords :: Descr f => f [String]
dottedWords = many1 (many anyChar <* char '.')
sepBy :: Descr f => f a -> f () -> f [a]
sepBy p1 p2 = ((:) <$> p1 <*> (many (p2 *> p1)))  orElse  pure []
newline :: Descr f => f ()
newline = primitive "newline" (charP '\n')
And thus we now have our CSV parser/grammar generator:
parseCSV :: Descr f => f [[String]]
parseCSV = many parseLine
  where
    parseLine = nonTerminal "line" $
        parseCell  sepBy  char ',' <* newline
    parseCell = nonTerminal "cell" $
        char '"' *> many (primitive "not-quote" (anyCharButP '"')) <* char '"'
We can now use this definition both to parse and to generate grammars:
*Main> putStr $ ppGrammar2 "csv" (parseCSV)
cell = '"',  not-quote , '"';
line = (cell,  ',', cell    ''), newline;
csv =  line ;
*Main> parse parseCSV "\"ab\",\"cd\"\n\"\",\"de\"\n\n"
Just [["ab","cd"],["","de"],[]]

The INI file parser and grammar As a final exercise, let us transform the INI file parser into a combined thing. Here is the parser (another artifact of last week s homework) again using applicative style2:
parseINIP :: Parser INIFile
parseINIP = many1P parseSection
  where
    parseSection =
        (,) <$  charP '['
            <*> parseIdent
            <*  charP ']'
            <*  charP '\n'
            <*> (catMaybes <$> manyP parseLine)
    parseIdent = many1P letterOrDigitP
    parseLine = parseDecl  orElseP  parseComment  orElseP  parseEmpty
    parseDecl = Just <$> (
        (,) <*> parseIdent
            <*  manyP (charP ' ')
            <*  charP '='
            <*  manyP (charP ' ')
            <*> many1P (anyCharButP '\n')
            <*  charP '\n')
    parseComment =
        Nothing <$ charP '#'
                <* many1P (anyCharButP '\n')
                <* charP '\n'
    parseEmpty = Nothing <$ charP '\n'
Transforming that to a generic description is quite straightforward. We use primitive again to wrap letterOrDigitP:
descrINI :: Descr f => f INIFile
descrINI = many1 parseSection
  where
    parseSection =
        (,) <*  char '['
            <*> parseIdent
            <*  char ']'
            <*  newline
            <*> (catMaybes <$> many parseLine)
    parseIdent = many1 (primitive "alphanum" letterOrDigitP)
    parseLine = parseDecl  orElse  parseComment  orElse  parseEmpty
    parseDecl = Just <$> (
        (,) <*> parseIdent
            <*  many (char ' ')
            <*  char '='
            <*  many (char ' ')
            <*> many1 (primitive "non-newline" (anyCharButP '\n'))
	    <*  newline)
    parseComment =
        Nothing <$ char '#'
                <* many1 (primitive "non-newline" (anyCharButP '\n'))
		<* newline
    parseEmpty = Nothing <$ newline
This yields this not very helpful grammar (abbreviated here):
*Main> putStr $ ppGrammar2 "ini" descrINI
ini = '[', alphanum,  alphanum , ']', newline,  alphanum,  alphanum ,  ' ' 
But with a few uses of nonTerminal, we get something really nice:
descrINI :: Descr f => f INIFile
descrINI = many1 parseSection
  where
    parseSection = nonTerminal "section" $
        (,) <$  char '['
            <*> parseIdent
            <*  char ']'
            <*  newline
            <*> (catMaybes <$> many parseLine)
    parseIdent = nonTerminal "identifier" $
        many1 (primitive "alphanum" letterOrDigitP)
    parseLine = nonTerminal "line" $
        parseDecl  orElse  parseComment  orElse  parseEmpty
    parseDecl = nonTerminal "declaration" $ Just <$> (
        (,) <$> parseIdent
            <*  spaces
            <*  char '='
            <*  spaces
            <*> remainder)
    parseComment = nonTerminal "comment" $
        Nothing <$ char '#' <* remainder
    remainder = nonTerminal "line-remainder" $
        many1 (primitive "non-newline" (anyCharButP '\n')) <* newline
    parseEmpty = Nothing <$ newline
    spaces = nonTerminal "spaces" $ many (char ' ')
*Main> putStr $ ppGrammar "ini" descrINI
identifier = alphanum,  alphanum ;
spaces =  ' ' ;
line-remainder = non-newline,  non-newline , newline;
declaration = identifier, spaces, '=', spaces, line-remainder;
comment = '#', line-remainder;
line = declaration   comment   newline;
section = '[', identifier, ']', newline,  line ;
ini = section,  section ;

Recursion (variant 1) What if we want to write a parser/grammar-generator that is able to generate the following grammar, which describes terms that are additions and multiplications of natural numbers:
const = digit,  digit ;
spaces =  ' '   newline ;
atom = const   '(', spaces, expr, spaces, ')', spaces;
mult = atom,  spaces, '*', spaces, atom , spaces;
plus = mult,  spaces, '+', spaces, mult , spaces;
expr = plus;
The production of expr is recursive (via plus, mult, atom). We have seen above that simply defining a Grammar a recursively does not go well. One solution is to add a new combinator for explicit recursion, which replaces nonTerminal in the method:
class Applicative f => Descr f where
     
    recNonTerminal :: String -> (f a -> f a) -> f a
instance Descr Parser where
     
    recNonTerminal _ p = let r = p r in r
instance Descr Grammar where
     
    recNonTerminal = recNonTerminalG
recNonTerminalG :: String -> (Grammar a -> Grammar a) -> Grammar a
recNonTerminalG name f =
    let G (prods, rhs) = f (G ([], NonTerminal name))
    in G (prods ++ [(name, rhs)], NonTerminal name)
nonTerminal :: Descr f => String -> f a -> f a
nonTerminal name p = recNonTerminal name (const p)
runGrammer :: String -> Grammar a -> BNF
runGrammer main (G (prods, NonTerminal nt))   main == nt = prods
runGrammer main (G (prods, rhs)) = prods ++ [(main, rhs)]
The change in runGrammer avoids adding a pointless expr = expr production to the output. This lets us define a parser/grammar-generator for the arithmetic expressions given above:
data Expr = Plus Expr Expr   Mult Expr Expr   Const Integer
    deriving Show
mkPlus :: Expr -> [Expr] -> Expr
mkPlus = foldl Plus
mkMult :: Expr -> [Expr] -> Expr
mkMult = foldl Mult
parseExpr :: Descr f => f Expr
parseExpr = recNonTerminal "expr" $ \ exp ->
    ePlus exp
ePlus :: Descr f => f Expr -> f Expr
ePlus exp = nonTerminal "plus" $
    mkPlus <$> eMult exp
           <*> many (spaces *> char '+' *> spaces *> eMult exp)
           <*  spaces
eMult :: Descr f => f Expr -> f Expr
eMult exp = nonTerminal "mult" $
    mkPlus <$> eAtom exp
           <*> many (spaces *> char '*' *> spaces *> eAtom exp)
           <*  spaces
eAtom :: Descr f => f Expr -> f Expr
eAtom exp = nonTerminal "atom" $
    aConst  orElse  eParens exp
aConst :: Descr f => f Expr
aConst = nonTerminal "const" $ Const . read <$> many1 digit
eParens :: Descr f => f a -> f a
eParens inner =
    id <$  char '('
       <*  spaces
       <*> inner
       <*  spaces
       <*  char ')'
       <*  spaces
And indeed, this works:
*Main> putStr $ ppGrammar "expr" parseExpr
const = digit,  digit ;
spaces =  ' '   newline ;
atom = const   '(', spaces, expr, spaces, ')', spaces;
mult = atom,  spaces, '*', spaces, atom , spaces;
plus = mult,  spaces, '+', spaces, mult , spaces;
expr = plus;

Recursion (variant 2) Interestingly, there is another solution to this problem, which avoids introducing recNonTerminal and explicitly passing around the recursive call (i.e. the exp in the example). To implement that we have to adjust our Grammar type as follows:
newtype Grammar a = G ([String] -> (BNF, RHS))
The idea is that the list of strings is those non-terminals that we are currently defining. So in nonTerminal, we check if the non-terminal to be introduced is currently in the process of being defined, and then simply ignore the body. This way, the recursion is stopped automatically:
nonTerminalG :: String -> (Grammar a) -> Grammar a
nonTerminalG name (G g) = G $ \seen ->
    if name  elem  seen
    then ([], NonTerminal name)
    else let (prods, rhs) = g (name : seen)
         in (prods ++ [(name, rhs)], NonTerminal name)
After adjusting the other primitives of Grammar (including the Functor and Applicative instances, wich now again have nonTerminal) to type-check again, we observe that this parser/grammar generator for expressions, with genuine recursion, works now:
parseExp :: Descr f => f Expr
parseExp = nonTerminal "expr" $
    ePlus
ePlus :: Descr f => f Expr
ePlus = nonTerminal "plus" $
    mkPlus <$> eMult
           <*> many (spaces *> char '+' *> spaces *> eMult)
           <*  spaces
eMult :: Descr f => f Expr
eMult = nonTerminal "mult" $
    mkPlus <$> eAtom
           <*> many (spaces *> char '*' *> spaces *> eAtom)
           <*  spaces
eAtom :: Descr f => f Expr
eAtom = nonTerminal "atom" $
    aConst  orElse  eParens parseExp
Note that the recursion is only going to work if there is at least one call to nonTerminal somewhere around the recursive calls. We still cannot implement many as naively as above.

Homework If you want to play more with this: The homework is to define a parser/grammar-generator for EBNF itself, as specified in this variant:
identifier = letter,  letter   digit   '-' ;
spaces =  ' '   newline ;
quoted-char = non-quote-or-backslash   '\\', '\\'   '\\', '\'';
terminal = '\'',  quoted-char , '\'', spaces;
non-terminal = identifier, spaces;
option = '[', spaces, rhs, spaces, ']', spaces;
repetition = ' ', spaces, rhs, spaces, ' ', spaces;
group = '(', spaces, rhs, spaces, ')', spaces;
atom = terminal   non-terminal   option   repetition   group;
sequence = atom,  spaces, ',', spaces, atom , spaces;
choice = sequence,  spaces, ' ', spaces, sequence , spaces;
rhs = choice;
production = identifier, spaces, '=', spaces, rhs, ';', spaces;
bnf = production,  production ;
This grammar is set up so that the precedence of , and is correctly implemented: a , b c will parse as (a, b) c. In this syntax for BNF, terminal characters are quoted, i.e. inside ' ', a ' is replaced by \' and a \ is replaced by \\ this is done by the function quote in ppRHS. If you do this, you should able to round-trip with the pretty-printer, i.e. parse back what it wrote:
*Main> let bnf1 = runGrammer "expr" parseExpr
*Main> let bnf2 = runGrammer "expr" parseBNF
*Main> let f = Data.Maybe.fromJust . parse parseBNF. ppBNF
*Main> f bnf1 == bnf1
True
*Main> f bnf2 == bnf2
True
The last line is quite meta: We are using parseBNF as a parser on the pretty-printed grammar produced from interpreting parseBNF as a grammar.

Conclusion We have again seen an example of the excellent support for abstraction in Haskell: Being able to define so very different things such as a parser and a grammar description with the same code is great. Type classes helped us here. Note that it was crucial that our combined parser/grammars are only able to use the methods of Applicative, and not Monad. Applicative is less powerful, so by giving less power to the user of our Descr interface, the other side, i.e. the implementation, can be more powerful. The reason why Applicative is ok, but Monad is not, is that in Applicative, the results do not affect the shape of the computation, whereas in Monad, the whole point of the bind operator (>>=) is that the result of the computation is used to decide the next computation. And while this is perfectly fine for a parser, it just makes no sense for a grammar generator, where there simply are no values around! We have also seen that a phantom type, namely the parameter of Grammar, can be useful, as it lets the type system make sure we do not write nonsense. For example, the type of orElseG ensures that both grammars that are combined here indeed describe something of the same type.

  1. It seems to be the week of applicative-appraising blog posts: Brent has posted a nice piece about enumerations using Applicative yesterday.
  2. I like how in this alignment of <*> and <* the > point out where the arguments are that are being passed to the function on the left.

25 October 2016

Laura Arjona Reina: Rankings, Condorcet and free software: Calculating the results for the Stretch Artwork Survey

We had 12 candidates for the Debian Stretch Artwork and a survey was set up for allowing people to vote which one they prefer.

The survey was run in my LimeSurvey instance, surveys.larjona.net. LimeSurvey its a nice free software with a lot of features. It provides a Ranking question type, and it was very easy for allowing people to vote in the Debian style (Debian uses the Condorcet method in its elections).

However, although LimeSurvey offers statistics and even graphics to show the results of many type of questions, its output for the Ranking type is not useful, so I had to export the data and use another tool to find the winner.
Export the data from LimeSurvey
I ve created a read-only user to visit the survey site. With this visitor you can explore the survey questionnaire, its results, and export the data.
Username: stretch
Password: artwork
First attempt, the quick and easy (and nonfree, I guess)
There is an online tool to calculate the Condorcet winner, http://www.ericgorr.net/condorcet/
The steps I followed to feed the tool with the data from LimeSurvey were these:
1.- Went to admin interface of lime survey, selected the stretch artwork survey, responses and statistics, export results to application
2.- Selected Completed responses only , Question codes , Answer codes , and exported to CSV. (results_stretch1.csv)
3.- Opened the CSV with LibreOffice Calc, and removed these columns:
id submitdate lastpage startlanguage
4.- Remove the first row containing the headers and saved the result (results_stretch2.csv)
5.- In commandline:
sort results_stretch2.csv   uniq -c > results_stretch3.csv
6.- Opened results_stretch3.csv with LibreOffice Calc and merge delimitors when importing.
7.- Removed the first column (blank) and added a column between the numbers and the first ranked option, and fulfilled that column with : value. Saved (results_stretch4.csv)
8.- Opened results_stretch4.csv with my preferred editor and search and replace ,:, for : and after that, search and replace , for > . Save the result (results_stretch5.csv)
9.- Went to http://condorcet.ericgorr.net/, selected Condorcet basic, tell me some things , and pasted the contents of results_stretch5.csv there.
The results are in results_stretch1.html
But where is the source code of this Condorcet tool?
I couldn t find the source code (nor license) of the solver by Eric Gorr.
The tool is mentioned in http://www.accuratedemocracy.com/z_tools.htm where other tools are listed and when the tool is libre software, is noted so. But not in this case.
There, I found another tool, VoteEngine, which is open source, so I tried with that.
Second attempt: VoteEngine, a Free Open Source Software tool made with Python
I used a modification of voteengine-0.99 (the original zip is available in http://vote.sourceforge.net/ and a diff with the changes I made (basically, Numeric -> numpy and Int -> int, inorder that works in Debian stable), here.
Steps 1 to 4 are the same as in the first attempt.
5.- Sorted alphabetically the different 12 options to vote, and
assigned a letter to each one (saved the assignments in a file called
6.- Opened results_stretch2.csv with my favorite editor, and search
and replace the name of the different options, for their corresponding
letter in stretch_key.txt file.
Searched and replaced , for (space). Then, saved the results into
7.- Copied the input.txt file from voteengine-0.99 into stretch.txt and edited the options
to our needs. Pasted the contents of results_stretch3_voteengine.cvs
at the end of stretch.txt
8.-In the commandline
./voteengine.py <stretch.txt  > winner.txt
(winner.txt contains the results for the Condorcet method).
9.- I edited again stretch.txt to change the method to shulze and
calculated the results, and again with the smith method. The winner in
the 3 methods is the same. I pasted the summary of these 3 methods
(shulze and smith provide a ranked list) in stretch_results.txt
If it can be done, it can be done with R
I found the algstat R package:
which includes a condorcet function but I couldn t make it work with the data.
I m not sure how the data needs to be shaped. I m sure that this can be done in R and the problem is me, in this case. Comments are welcome, and I ll try to ask to a friend whose R skills are better than mine!
And another SaaS
I found https://www.condorcet.vote/ and its source code. It would be interesting to deploy a local instance to drive future surveys, but for this time I didn t want to fight with PHP in order to use only the solver part, nor install another SaaS in my home server just to find that I need some other dependency or whatever.
I ll keep an eye on this, though, because it looks like a modern and active project.
Finally, devotee
Well and which software Debian uses for its elections?
There is a git repository with devotee, you can clone it:
I found that although the tool is quite modular, it s written specifically for the Debian case (votes received by mail, GPG signed, there is a quorum, and other particularities) and I was not sure if I could use it with my data. It is written in Perl and then I understood it worse than the Python from VoteEngine.
Maybe I ll return to it, though, when I have more time, to try to put our data in the shape of a typicall tally.txt file and then see if the module solving the condorcet winner can work for me.
That s all, folks! (for now )
Comments
You can coment on this blog post in this pump.io thread

Filed under: Tools Tagged: data mining, Debian, English, SaaS, statistics

Julian Andres Klode: Introducing DNS66, a host blocker for Android

ic_launcher I m proud (yes, really) to announce DNS66, my host/ad blocker for Android 5.0 and newer. It s been around since last Thursday on F-Droid, but it never really got a formal announcement. DNS66 creates a local VPN service on your Android device, and diverts all DNS traffic to it, possibly adding new DNS servers you can configure in its UI. It can use hosts files for blocking whole sets of hosts or you can just give it a domain name to block (or multiple hosts files/hosts). You can also whitelist individual hosts or entire files by adding them to the end of the list. When a host name is looked up, the query goes to the VPN which looks at the packet and responds with NXDOMAIN (non-existing domain) for hosts that are blocked. You can find DNS66 here: F-Droid is the recommended source to install from. DNS66 is licensed under the GNU GPL 3, or (mostly) any later version. Implementation Notes DNS66 s core logic is based on another project, dbrodie/AdBuster, which arguably has the cooler name. I translated that from Kotlin to Java, and cleaned up the implementation a bit: All work is done in a single thread by using poll() to detect when to read/write stuff. Each DNS request is sent via a new UDP socket, and poll() polls over all UDP sockets, a Device Socket (for the VPN s tun device) and a pipe (so we can interrupt the poll at any time by closing the pipe). We literally redirect your DNS servers. Meaning if your DNS server is 1.2.3.4, all traffic to 1.2.3.4 is routed to the VPN. The VPN only understands DNS traffic, though, so you might have trouble if your DNS server also happens to serve something else. I plan to change that at some point to emulate multiple DNS servers with fake IPs, but this was a first step to get it working with fallback: Android can now transparently fallback to other DNS servers without having to be aware that they are routed via the VPN. We also need to deal with timing out queries that we received no answer for: DNS66 stores the query into a LinkedHashMap and overrides the removeEldestEntry() method to remove the eldest entry if it is older than 10 seconds or there are more than 1024 pending queries. This means that it only times out up to one request per new request, but it eventually cleans up fine.
Filed under: Android, Uncategorized

Jaldhar Vyas: Aaargh gcc 5.x You Suck

Aaargh gcc 5.x You Suck I had to write a quick program today which is going to be run many thousands of times a day so it has to run fast. I decided to do it in c++ instead of the usual perl or javascript because it seemed appropriate and I've been playing around a lot with c++ lately trying to update my knowledge of its' modern features. So 200 LOC later I was almost done so I ran the program through valgrind a good habit I've been trying to instill. That's when I got a reminder of why I avoid c++.

==37698== HEAP SUMMARY:
==37698==     in use at exit: 72,704 bytes in 1 blocks
==37698==   total heap usage: 5 allocs, 4 frees, 84,655 bytes allocated
==37698== 
==37698== LEAK SUMMARY:
==37698==    definitely lost: 0 bytes in 0 blocks
==37698==    indirectly lost: 0 bytes in 0 blocks
==37698==      possibly lost: 0 bytes in 0 blocks
==37698==    still reachable: 72,704 bytes in 1 blocks
==37698==         suppressed: 0 bytes in 0 blocks
One of things I've learnt which I've been trying to apply more rigorously is to avoid manual memory management (news/deletes.) as much as possible in favor of modern c++ features such as std::unique_ptr etc. By my estimation there should only be three places in my code where memory is allocated and none of them should leak. Where do the others come from? And why is there a missing free (or delete.) Now the good news is that valgrind is saying that the memory is not technically leaking. It is still reachable at exit but that's ok because the OS will reclaim it. But this program will run a lot and I think it could still lead to problems over time such as memory fragmentation so I wanted to understand what was going on. Not to mention the bad aesthetics of it. My first assumption (one which has served me well over the years) was to assume that I had screwed up somewhere. Or perhaps it could some behind the scenes compiler magic. It turned out to be the latter -- sort of as I found out only after two hours of jiggling code in different ways and googling for clues. That's when I found this Stack Overflow question which suggests that it is either a valgrind or compiler bug. The answer specifically mentions gcc 5.1. I was using Ubuntu LTS which has gcc 5.4 so I have just gone ahead and assumed all 5.x versions of gcc have this problem. Sure enough, compiling the same program on Debian stable which has gcc 4.9 gave this...

==6045== 
==6045== HEAP SUMMARY:
==6045==     in use at exit: 0 bytes in 0 blocks
==6045==   total heap usage: 3 allocs, 3 frees, 10,967 bytes allocated
==6045== 
==6045== All heap blocks were freed -- no leaks are possible
==6045== 
...Much better. The executable was substantially smaller too. The time was not a total loss however. I learned that valgrind is pronounced val-grinned (it's from Norse mythology.) not val-grind as I had thought. So I have that going for me which is nice.

24 October 2016

Chris Lamb: Concorde

Today marks the 13th anniversary since the last passenger flight from New York arrived in the UK. Every seat was filled, a feat that had become increasingly rare for a plane that was a technological marvel but a commercial flop .


See also: A Rocket to Nowhere.

Reproducible builds folks: Reproducible Builds: week 78 in Stretch cycle

What happened in the Reproducible Builds effort between Sunday October 16 and Saturday October 22 2016: Media coverage Upcoming events buildinfo.debian.net In order to build packages reproducibly, you not only need identical sources but also some external definition of the environment used for a particular build. This definition includes the inputs and the outputs and, in the Debian case, are available in a $package_$architecture_$version.buildinfo file. We anticipate the next dpkg upload to sid will create .buildinfo files by default. Whilst it's clear that we also need to teach dak to deal with them (#763822) its not actually clear how to handle .buildinfo files after dak has processed them and how to make them available to the world. To this end, Chris Lamb has started development on a proof-of-concept .buildinfo server to see what issues arise. Source Reproducible work in other projects Packages reviewed and fixed, and bugs filed Reviews of unreproducible packages 99 package reviews have been added, 3 have been updated and 6 have been removed in this week, adding to our knowledge about identified issues. 6 issue types have been added: Weekly QA work During of reproducibility testing, some FTBFS bugs have been detected and reported by: diffoscope development tests.reproducible-builds.org Misc. Our poll to find a good time for an IRC meeting is still running until Tuesday, October 25st; please reply as soon as possible. We need a logo! Some ideas and requirements for a Reproducible Builds logo have been documented in the wiki. Contributions very welcome, even if simply by forwarding this information. This week's edition was written by Chris Lamb & Holger Levsen and reviewed by a bunch of Reproducible Builds folks on IRC.

23 October 2016

Carl Chenet: PyMoneroWallet: the Python library for the Monero wallet

Do you know the Monero crytocurrency? It s a cryptocurrency, like Bitcoin, focused on the security, the privacy and the untracabily. That s a great project launched in 2014, today called XMR on all cryptocurrency exchange platforms (like Kraken or Poloniex). So what s new? In order to work with a Monero wallet from some Python applications, I just wrote a Python library to use the Monero wallet: PyMoneroWallet monero-logo Using PyMoneroWallet is as easy as:
$ python3
>>> from monerowallet import MoneroWallet
>>> mw = MoneroWallet()
>>> mw.getbalance()
 'unlocked_balance': 2262265030000, 'balance': 2262265030000 
Lots of features are included, you should have a look at the documentation of the monerowallet module to know them all, but quickly here are some of them: And so on. Have a look at the complete documentation for extensive available functions. UPDATE: I m trying to launch a crowdfunding of the PyMoneroWallet project. Feel free to comment in this thread of the official Monero forum to let them know you think that PyMoneroWallet is a great idea  Feel free to contribute to this starting project to help spreading the Monero use by using the PyMoneroWallet project with your Python applications

22 October 2016

Ingo Juergensmann: Automatically update TLSA records on new Letsencrypt Certs

I've been using DNSSEC for some quite time now and it is working quite well. When LetsEncrypt went public beta I jumped on the train and migrated many services to LE-based TLS. However there was still one small problem with LE certs: When there is a new cert, all of the old TLSA resource records are not valid anymore and might give problems to strict DNSSEC checking clients. It took some while until my pain was big enough to finally fix it by some scripts. There are at least two scripts involved: 1) dnssec.sh
This script does all of my DNSSEC handling. You can just do a "dnssec.sh enable-dnssec domain.tld" and everything is configured so that you only need to copy the appropriate keys into the webinterface of your DNS registry.
host:~/bin# dnssec.sh
No parameter given.
Usage: dnsec.sh MODE DOMAIN
MODE can be one of the following:
enable-dnssec : perform all steps to enable DNSSEC for your domain
edit-zone     : safely edit your zone after enabling DNSSEC
create-dnskey : create new dnskey only
load-dnskey   : loads new dnskeys and signs the zone with them
show-ds       : shows DS records of zone
zoneadd-ds    : adds DS records to the zone file
show-dnskey   : extract DNSKEY record that needs to uploaded to your registrar
update-tlsa   : update TLSA records with new TLSA hash, needs old and new TLSA hashes as additional parameters
For updating zone-files just do a "dnssech.sh edit-zone domain.tld" to add new records and such and the script will take care e.g. of increasing the serial of the zone file. I find this very convenient, so I often use this script for non-DNSSEC-enabled domains as well. However you can spot the command line option "update-tlsa". This option needs the old and the new TLSA hashes beside the domain.tld parameter. However, this option is used from the second script: 2) check_tlsa.sh
This is a quite simple Bash script that parses the domains.txt from letsencrypt.sh script, looking up the old TLSA hash in the zone files (structured in TLD/domain.tld directories), compare the old with the new hash (by invoking tlsagen.sh) and if there is a difference in hashes, call dnssec.sh with the proper parameters:
#!/bin/bash
set -e
LEPATH="/etc/letsencrypt.sh"
for i in  cat /etc/letsencrypt.sh/domains.txt   awk ' print $1 '  ; do
  domain= echo $i   awk 'BEGIN  FS="."  ;  print $(NF-1)"."$NF ' 
  #echo -n "Domain: $domain"
  TLD= echo $i   awk 'BEGIN  FS="." ;  print $NF ' 
  #echo ", TLD: $TLD"
  OLDTLSA= grep -i "in.*tlsa" /etc/bind/$ TLD /$ domain    grep $ i    head -n 1   awk ' print $NF ' 
  if [ -n "$ OLDTLSA " ] ; then
  #echo "--> $ OLDTLSA "
  # Usage: tlsagen.sh cert.pem host[:port] usage selector mtype
  NEWTLSA= /path/to/tlsagen.sh $LEPATH/certs/$ i /fullchain.pem $ i  3 1 1   awk ' print $NF ' 
  #echo "==> $NEWTLSA"
  if [ "$ OLDTLSA " != "$ NEWTLSA " ] ; then
  /path/to/dnssec.sh update-tlsa $ domain  $ OLDTLSA  $ NEWTLSA  > /dev/null
  echo "TLSA RR update for $ i "
  fi
  fi
done
So, quite simple and obviously a quick hack. For sure someone else can write a cleaner and more sophisticated implementation to do the same stuff, but at least it works for meTM. Use it on your own risk and do whatever you want with these scripts (licensed under public domain). You can invoke check_tlsa.sh right after your crontab call for letsencrypt.sh. In a more sophisticated way it should be fairly easy to invoke these scripts from letsencrypt.sh post hooks as well.
Please find the files attached to this page (remove the .txt extension after saving, of course).
AttachmentSize
check_tlsa.sh.txt812 bytes
dnssec.sh.txt3.88 KB
Kategorie:

Matthieu Caneill: Debugging 101

While teaching this semester a class on concurrent programming, I realized during the labs that most of the students couldn't properly debug their code. They are at the end of a 2-year cursus, know many different programming languages and frameworks, but when it comes to tracking down a bug in their own code, they often lacked the basics. Instead of debugging for them I tried to give them general directions that they could apply for the next bugs. I will try here to summarize the very first basic things to know about debugging. Because, remember, writing software is 90% debugging, and 10% introducing new bugs (that is not from me, but I could not find the original quote). So here is my take at Debugging 101. Use the right tools Many good tools exist to assist you in writing correct software, and it would put you behind in terms of productivity not to use them. Editors which catch syntax errors while you write them, for example, will help you a lot. And there are many features out there in editors, compilers, debuggers, which will prevent you from introducing trivial bugs. Your editor should be your friend; explore its features and customization options, and find an efficient workflow with them, that you like and can improve over time. The best way to fix bugs is not to have them in the first place, obviously. Test early, test often I've seen students writing code for one hour before running make, that would fail so hard that hundreds of lines of errors and warnings were outputted. There are two main reasons doing this is a bad idea: I recommend to test your code (compilation and execution) every few lines of code you write. When something breaks, chances are it will come from the last line(s) you wrote. Compiler errors will be shorter, and will point you to the same place in the code. Once you get more confident using a particular language or framework, you can write more lines at once without testing. That's a slow process, but it's ok. If you set up the right keybinding for compiling and executing from within your editor, it shouldn't be painful to test early and often. Read the logs Spot the places where your program/compiler/debugger writes text, and read it carefully. It can be your terminal (quite often), a file in your current directory, a file in /var/log/, a web page on a local server, anything. Learn where different software write logs on your system, and integrate reading them in your workflow. Often, it will be your only information about the bug. Often, it will tell you where the bug lies. Sometimes, it will even give you hints on how to fix it. You may have to filter out a lot of garbage to find relevant information about your bug. Learn to spot some keywords like error or warning. In long stacktraces, spot the lines concerning your files; because more often, your code is to be blamed, rather than deeper library code. grep the logs with relevant keywords. If you have the option, colorize the output. Use tail -f to follow a file getting updated. There are so many ways to grasp logs, so find what works best with you and never forget to use it! Print foobar That one doesn't concern compilation errors (unless it's a Makefile error, in that case this file is your code anyway). When the program logs and output failed to give you where an error occured (oh hi Segmentation fault!), and before having to dive into a memory debugger or system trace tool, spot the portion of your program that causes the bug and add in there some print statements. You can either print("foo") and print("bar"), just to know that your program reaches or not a certain place in your code, or print(some_faulty_var) to get more insights on your program state. It will give you precious information.
stderr >> "foo" >> endl;
my_db.connect(); // is this broken?
stderr >> "bar" >> endl;
In the example above, you can be sure it is the connection to the database my_db that is broken if you get foo and not bar on your standard error. (That is an hypothetical example. If you know something can break, such as a database connection, then you should always enclose it in a try/catch structure). Isolate and reproduce the bug This point is linked to the previous one. You may or may not have isolated the line(s) causing the bug, but maybe the issue is not always raised. It can depend on many other things: the program or function parameters, the network status, the amount of memory available, the decisions of the OS scheduler, the user rights on the system or on some files, etc. More generally, any assumption you made on any external dependency can appear to be wrong (even if it's right 99% of the time). According to the context, try to isolate the set of conditions that trigger the bug. It can be as simple as "when there is no internet connection", or as complicated as "when the CPU load of some external machine is too high, it's a leap year, and the input contains illegal utf-8 characters" (ok, that one is fucked up; but it surely happens!). But you need to reliably be able to reproduce the bug, in order to be sure later that you indeed fixed it. Of course when the bug is triggered at every run, it can be frustrating that your program never works but it will in general be easier to fix. RTFM Always read the documentation before reaching out for help. Be it man, a book, a website or a wiki, you will find precious information there to assist you in using a language or a specific library. It can be quite intimidating at first, but it's often organized the same way. You're likely to find a search tool, an API reference, a tutorial, and many examples. Compare your code against them. Check in the FAQ, maybe your bug and its solution are already referenced there. You'll rapidly find yourself getting used to the way documentation is organized, and you'll be more and more efficient at finding instantly what you need. Always keep the doc window open! Google and Stack Overflow are your friends Let's be honest: many of the bugs you'll encounter have been encountered before. Learn to write efficient queries on search engines, and use the knowledge you can find on questions&answers forums like Stack Overflow. Read the answers and comments. Be wise though, and never blindly copy and paste code from there. It can be as bad as introducing malicious security issues into your code, and you won't learn anything. Oh, and don't copy and paste anyway. You have to be sure you understand every single line, so better write them by hand; it's also better for memorizing the issue. Take notes Once you have identified and solved a particular bug, I advise to write about it. No need for shiny interfaces: keep a list of your bugs along with their solutions in one or many text files, organized by language or framework, that you can easily grep. It can seem slightly cumbersome to do so, but it proved (at least to me) to be very valuable. I can often recall I have encountered some buggy situation in the past, but don't always remember the solution. Instead of losing all the debugging time again, I search in my bug/solution list first, and when it's a hit I'm more than happy I kept it. Further reading degugging Remember this was only Debugging 101, that is, the very first steps on how to debug code on your own, instead of getting frustrated and helplessly stare at your screen without knowing where to begin. When you'll write more software, you'll get used to more efficient workflows, and you'll discover tools that are here to assist you in writing bug-free code and spotting complex bugs efficiently. Listed below are some of the tools or general ideas used to debug more complex software. They belong more to a software engineering course than a Debugging 101 blog post. But it's good to know as soon as possible these exist, and if you read the manuals there's no reason you can't rock with them! Don't hesitate to comment on this, and provide your debugging 101 tips! I'll be happy to update the article with valuable feedback. Happy debugging!

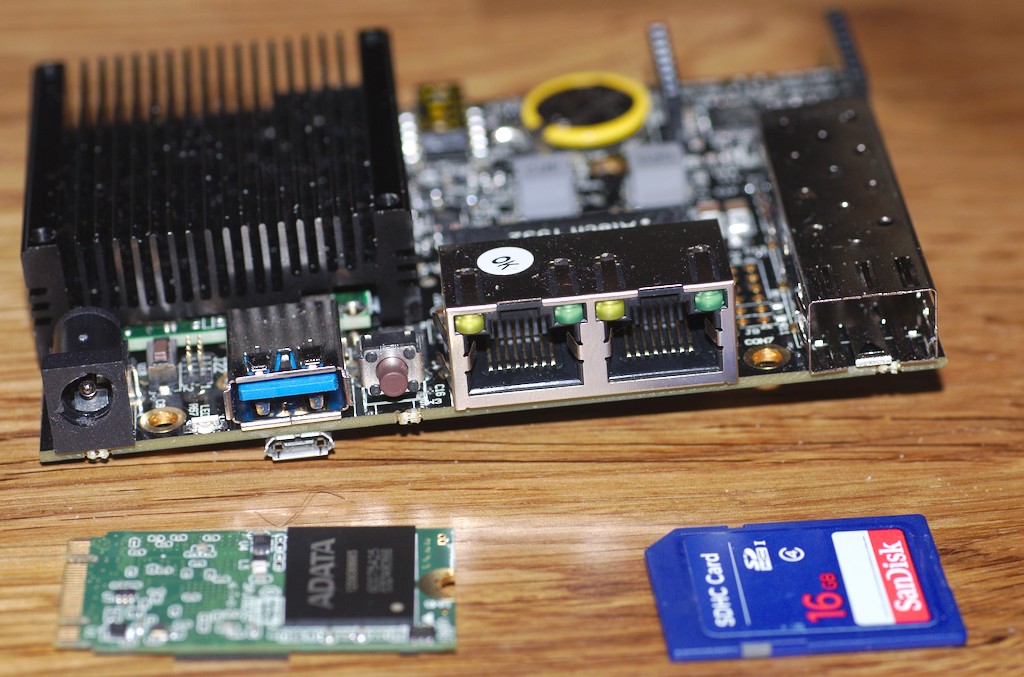
Christoph Egger: Running Debian on the ClearFog

Back in August, I was looking for a Homeserver replacement. During FrOSCon I was then reminded of the Turris Omnia project by NIC.cz. The basic SoC (Marvel Armada 38x) seemed to be nice hand have decent mainline support (and, with the turris, users interested in keeping it working). Only I don't want any WIFI and I wasn't sure the standard case would be all that usefully. Fortunately, there's also a simple board available with the same SoC called ClearFog and so I got one of these (the Base version). With shipping and the SSD (the only 2242 M.2 SSD with 250 GiB I could find, a ADATA SP600) it slightly exceeds the budget but well. ClearFog with SSD When installing the machine, the obvious goal was to use mainline FOSS components only if possible. Fortunately there's mainline kernel support for the device as well as mainline U-Boot. First attempts to boot from a micro SD card did not work out at all, both with mainline U-Boot and the vendor version though. Turns out the eMMC version of the board does not support any micro SD cards at all, a fact that is documented but others failed to notice as well. U-Boot As the board does not come with any loader on eMMC and booting directly from M.2 requires removing some resistors from the board, the easiest way is using UART for booting. The vendor wiki has some shell script wrapping an included C fragment to feed U-Boot to the device but all that is really needed is U-Boot's kwboot utility. For some reason the SPL didn't properly detect UART booting on my device (wrong magic number) but patching the if (in arch-mvebu's spl.c) and always assume UART boot is an easy way around. The plan then was to boot a Debian armhf rootfs with a defconfig kernel from USB stick. and install U-Boot and the rootfs to eMMC from within that system. Unfortunately U-Boot seems to be unable to talk to the USB3 port so no kernel loading from there. One could probably make UART loading work but switching between screen for serial console and xmodem seemed somewhat fragile and I never got it working. However ethernet can be made to work, though you need to set eth1addr to eth3addr (or just the right one of these) in U-Boot, saveenv and reboot. After that TFTP works (but is somewhat slow). eMMC There's one last step required to allow U-Boot and Linux to access the eMMC. eMMC is wired to the same PINs as the SD card would be. However the SD card has an additional indicator pin showing whether a card is present. You might be lucky inserting a dummy card into the slot or go the clean route and remove the pin specification from the device tree.
--- a/arch/arm/dts/armada-388-clearfog.dts
+++ b/arch/arm/dts/armada-388-clearfog.dts
@@ -306,7 +307,6 @@
                        sdhci@d8000  
                                bus-width = <4>;
-                               cd-gpios = <&gpio0 20 GPIO_ACTIVE_LOW>;
                                no-1-8-v;
                                pinctrl-0 = <&clearfog_sdhci_pins
                                             &clearfog_sdhci_cd_pins>;
Next Up is flashing the U-Boot to eMMC. This seems to work with the vendor U-Boot but proves to be tricky with mainline. The fun part boils down to the fact that the boot firmware reads the first block from eMMC, but the second from SD card. If you write the mainline U-Boot, which was written and tested for SD card, to eMMC the SPL will try to load the main U-Boot starting from it's second sector from flash -- obviously resulting in garbage. This one took me several tries to figure out and made me read most of the SPL code for the device. The fix however is trivial (apart from the question on how to support all different variants from one codebase, which I'll leave to the U-Boot developers):
--- a/include/configs/clearfog.h
+++ b/include/configs/clearfog.h
@@ -143,8 +143,7 @@
 #define CONFIG_SPL_LIBDISK_SUPPORT
 #define CONFIG_SYS_MMC_U_BOOT_OFFS             (160 << 10)
 #define CONFIG_SYS_U_BOOT_OFFS                 CONFIG_SYS_MMC_U_BOOT_OFFS
-#define CONFIG_SYS_MMCSD_RAW_MODE_U_BOOT_SECTOR        ((CONFIG_SYS_U_BOOT_OFFS / 512)\
-                                                + 1)
+#define CONFIG_SYS_MMCSD_RAW_MODE_U_BOOT_SECTOR        (CONFIG_SYS_U_BOOT_OFFS / 512)
 #define CONFIG_SYS_U_BOOT_MAX_SIZE_SECTORS     ((512 << 10) / 512) /* 512KiB */
 #ifdef CONFIG_SPL_BUILD
 #define CONFIG_FIXED_SDHCI_ALIGNED_BUFFER      0x00180000      /* in SDRAM */
Linux Now we have a System booting from eMMC with mainline U-Boot (which is a most welcome speedup compared to the UART and TFTP combination from the beginning). Getting to fine-tune linux on the device -- we want to install the armmp Debian kernel and have it work. As all the drivers are build as modules for that kernel this also means initrd support. Funnily U-Boots bootz allows booting a plain vmlinux kernel but I couldn't get it to boot a plain initrd. Passing a uImage initrd and a normal kernel however works pretty well. Back when I first tried there were some modules missing and ethernet didn't work with the PHY driver built as a module. In the meantime the PHY problem was fixed in the Debian kernel and almost all modules already added. Ben then only added the USB3 module on my suggestion and as a result, unstable's armhf armmp kernel should work perfectly well on the device (you still need to patch the device tree similar to the patch above). Still missing is an updated flash-kernel to automatically generate the initrd uImage which is work in progress but got stalled until I fixed the U-Boot on eMMC problem and everything should be fine -- maybe get debian u-boot builds for that board. Pro versus Base The main difference so far between the Pro and the Base version of the ClearFog is the switch chip which is included on the Pro. The Base instead "just" has two gigabit ethernet ports and a SFP. Both, linux' and U-Boot's device tree are intended for the Pro version which makes on of the ethernet ports unusable (it tries to find the switch behind the ethernet port which isn't there). To get both ports working (or the one you settled on earlier) there's a second patch to the device tree (my version might be sub-optimal but works), U-Boot -- the linux-kernel version is a trivial adaption:
--- a/arch/arm/dts/armada-388-clearfog.dts
+++ b/arch/arm/dts/armada-388-clearfog.dts
@@ -89,13 +89,10 @@
                internal-regs  
                        ethernet@30000  
                                mac-address = [00 50 43 02 02 02];
+                               managed = "in-band-status";
+                               phy = <&phy1>;
                                phy-mode = "sgmii";
                                status = "okay";
-
-                               fixed-link  
-                                       speed = <1000>;
-                                       full-duplex;
-                                ;
                         ;
                        ethernet@34000  
@@ -227,6 +224,10 @@
                                pinctrl-0 = <&mdio_pins>;
                                pinctrl-names = "default";
+                               phy1: ethernet-phy@1   /* Marvell 88E1512 */
+                                    reg = <1>;
+                                ;
+
                                phy_dedicated: ethernet-phy@0  
                                        /*
                                         * Annoyingly, the marvell phy driver
@@ -386,62 +386,6 @@
                tx-fault-gpio = <&expander0 13 GPIO_ACTIVE_HIGH>;
         ;
-       dsa@0  
-               compatible = "marvell,dsa";
-               dsa,ethernet = <&eth1>;
-               dsa,mii-bus = <&mdio>;
-               pinctrl-0 = <&clearfog_dsa0_clk_pins &clearfog_dsa0_pins>;
-               pinctrl-names = "default";
-               #address-cells = <2>;
-               #size-cells = <0>;
-
-               switch@0  
-                       #address-cells = <1>;
-                       #size-cells = <0>;
-                       reg = <4 0>;
-
-                       port@0  
-                               reg = <0>;
-                               label = "lan1";
-                        ;
-
-                       port@1  
-                               reg = <1>;
-                               label = "lan2";
-                        ;
-
-                       port@2  
-                               reg = <2>;
-                               label = "lan3";
-                        ;
-
-                       port@3  
-                               reg = <3>;
-                               label = "lan4";
-                        ;
-
-                       port@4  
-                               reg = <4>;
-                               label = "lan5";
-                        ;
-
-                       port@5  
-                               reg = <5>;
-                               label = "cpu";
-                        ;
-
-                       port@6  
-                               /* 88E1512 external phy */
-                               reg = <6>;
-                               label = "lan6";
-                               fixed-link  
-                                       speed = <1000>;
-                                       full-duplex;
-                                ;
-                        ;
-                ;
-        ;
-
        gpio-keys  
                compatible = "gpio-keys";
                pinctrl-0 = <&rear_button_pins>;
Conclusion Apart from the mess with eMMC this seems to be a pretty nice device. It's now happily running with a M.2 SSD providing enough storage for now and still has a mSATA/mPCIe plug left for future journeys. It seems to be drawing around 5.5 Watts with SSD and one Ethernet connected while mostly idle and can feed around 500 Mb/s from disk over an encrypted ethernet connection which is, I guess, not too bad. My plans now include helping to finish flash-kernel support, creating a nice case and probably get it deployed. I might bring it to FOSDEM first though. Working on it was really quite some fun (apart from the frustrating parts finding the one-block-offset ..) and people were really helpful. Big thanks here to Debian's arm folks, Ben Hutchings the kernel maintainer and U-Boot upstream (especially Tom Rini and Stefan Roese)

21 October 2016

Dirk Eddelbuettel: anytime 0.0.4: New features and fixes

A brand-new release of anytime is now on CRAN following the three earlier releases since mid-September. anytime aims to convert anything in integer, numeric, character, factor, ordered, ... format to POSIXct (or Date) objects -- and does so without requiring a format string. See the anytime page for a few examples. With release 0.0.4, we add two nice new features. First, NA, NaN and Inf are now simply skipped (similar to what the corresponding Base R functions do). Second, we now also accept large numeric values so that, _e.g., anytime(as.numeric(Sys.time()) also works, effectively adding another input type. We also have squashed an issue reported by the 'undefined behaviour' sanitizer, and the widened the test for when we try to deploy the gettz package get missing timezone information. A quick example of the new features:
anydate(c(NA, NaN, Inf, as.numeric(as.POSIXct("2016-09-01 10:11:12"))))
[1] NA           NA           NA           "2016-09-01"
The NEWS file summarises the release:

Changes in anytime version 0.0.4 (2016-10-20)
  • Before converting via lexical_cast, assign to atomic type via template logic to avoid an UBSAN issue (PR #15 closing issue #14)
  • More robust initialization and timezone information gathering.
  • More robust processing of non-finite input also coping with non-finite values such as NA, NaN and Inf which all return NA
  • Allow numeric POSIXt representation on input, also creating proper POSIXct (or, if requested, Date)

Courtesy of CRANberries, there is a comparison to the previous release. More information is on the anytime page. For questions or comments use the issue tracker off the GitHub repo.

This post by Dirk Eddelbuettel originated on his Thinking inside the box blog. Please report excessive re-aggregation in third-party for-profit settings.

20 October 2016

H ctor Or n Mart nez: Build a Debian package against Debian 8.0 using Download On Demand (DoD) service

In the previous post Open Build Service software architecture has been overviewed. In the current blog post, a tutorial on setting up a package build with OBS from Debian packages is presented. Steps: Generate a test environment by creating Stretch/SID VM Really, use whatever suits you best, but please create an untrusted test environment for this one. In the current tutorial it assumes $hostname is stretch , which should be stretch or sid suite. Be aware that copy & paste configuration files from current post might lead you into broken characters (i.e. ). Debian Stretch weekly netinst CD Enable experimental repository
# echo "deb http://httpredir.debian.org/debian experimental main" >> /etc/apt/sources.list.d/experimental.list
# apt-get update
Install and setup OBS server, api, worker and osc CLI packages
# apt-get install obs-server obs-api obs-worker osc
In the install process mysql database is needed, therefore if mysql server is not setup, a password needs to be provided.
When OBS API database obs-api is created, we need to pick a password for it, provide opensuse . The obs-api package will configure apache2 https webserver (creating a dummy certificate for stretch ) to serve OBS webui.
Add stretch and obs aliases to localhost entry in your /etc/hosts file.
Enable worker by setting ENABLED=1 in /etc/default/obsworker
Try to connect to the web UI https://stretch/
Login into OBS webui, default login credentials: Admin/opensuse).
From command line tool, try to list projects in OBS
 $ osc -A https://stretch ls
Accept dummy certificate and provide credentials (defaults: Admin/opensuse)
If the install proceeds as expected follow to the next step. Ensure all OBS services are running
# backend services
obsrun     813  0.0  0.9 104960 20448 ?        Ss   08:33   0:03 /usr/bin/perl -w /usr/lib/obs/server/bs_dodup
obsrun     815  0.0  1.5 157512 31940 ?        Ss   08:33   0:07 /usr/bin/perl -w /usr/lib/obs/server/bs_repserver
obsrun    1295  0.0  1.6 157644 32960 ?        S    08:34   0:07  \_ /usr/bin/perl -w /usr/lib/obs/server/bs_repserver
obsrun     816  0.0  1.8 167972 38600 ?        Ss   08:33   0:08 /usr/bin/perl -w /usr/lib/obs/server/bs_srcserver
obsrun    1296  0.0  1.8 168100 38864 ?        S    08:34   0:09  \_ /usr/bin/perl -w /usr/lib/obs/server/bs_srcserver
memcache   817  0.0  0.6 346964 12872 ?        Ssl  08:33   0:11 /usr/bin/memcached -m 64 -p 11211 -u memcache -l 127.0.0.1
obsrun     818  0.1  0.5  78548 11884 ?        Ss   08:33   0:41 /usr/bin/perl -w /usr/lib/obs/server/bs_dispatch
obsserv+   819  0.0  0.3  77516  7196 ?        Ss   08:33   0:05 /usr/bin/perl -w /usr/lib/obs/server/bs_service
mysql      851  0.0  0.0   4284  1324 ?        Ss   08:33   0:00 /bin/sh /usr/bin/mysqld_safe
mysql     1239  0.2  6.3 1010744 130104 ?      Sl   08:33   1:31  \_ /usr/sbin/mysqld --basedir=/usr --datadir=/var/lib/mysql --plugin-dir=/usr/lib/mysql/plugin --log-error=/var/log/mysql/error.log --pid-file=/var/run/mysqld/mysqld.pid --socket=/var/run/mysqld/mysqld.sock --port=3306
# web services
root      1452  0.0  0.1 110020  3968 ?        Ss   08:34   0:01 /usr/sbin/apache2 -k start
root      1454  0.0  0.1 435992  3496 ?        Ssl  08:34   0:00  \_ Passenger watchdog
root      1460  0.3  0.2 651044  5188 ?        Sl   08:34   1:46      \_ Passenger core
nobody    1465  0.0  0.1 444572  3312 ?        Sl   08:34   0:00      \_ Passenger ust-router
www-data  1476  0.0  0.1 855892  2608 ?        Sl   08:34   0:09  \_ /usr/sbin/apache2 -k start
www-data  1477  0.0  0.1 856068  2880 ?        Sl   08:34   0:09  \_ /usr/sbin/apache2 -k start
www-data  1761  0.0  4.9 426868 102040 ?       Sl   08:34   0:29 delayed_job.0
www-data  1767  0.0  4.8 425624 99888 ?        Sl   08:34   0:30 delayed_job.1
www-data  1775  0.0  4.9 426516 101708 ?       Sl   08:34   0:28 delayed_job.2
nobody    1788  0.0  5.7 496092 117480 ?       Sl   08:34   0:03 Passenger RubyApp: /usr/share/obs/api
nobody    1796  0.0  4.9 488888 102176 ?       Sl   08:34   0:00 Passenger RubyApp: /usr/share/obs/api
www-data  1814  0.0  4.5 282576 92376 ?        Sl   08:34   0:22 delayed_job.1000
www-data  1829  0.0  4.4 282684 92228 ?        Sl   08:34   0:22 delayed_job.1010
www-data  1841  0.0  4.5 282932 92536 ?        Sl   08:34   0:22 delayed_job.1020
www-data  1855  0.0  4.9 427988 101492 ?       Sl   08:34   0:29 delayed_job.1030
www-data  1865  0.2  5.0 492500 102964 ?       Sl   08:34   1:09 clockworkd.clock
www-data  1899  0.0  0.0  87100  1400 ?        S    08:34   0:00 /usr/bin/searchd --pidfile --config /usr/share/obs/api/config/production.sphinx.conf
www-data  1900  0.1  0.4 161620  8276 ?        Sl   08:34   0:51  \_ /usr/bin/searchd --pidfile --config /usr/share/obs/api/config/production.sphinx.conf
# OBS worker
root      1604  0.0  0.0  28116  1492 ?        Ss   08:34   0:00 SCREEN -m -d -c /srv/obs/run/worker/boot/screenrc
root      1605  0.0  0.9  75424 18764 pts/0    Ss+  08:34   0:06  \_ /usr/bin/perl -w ./bs_worker --hardstatus --root /srv/obs/worker/root_1 --statedir /srv/obs/run/worker/1 --id stretch:1 --reposerver http://obs:5252 --jobs 1
Create an OBS project for Download on Demand (DoD) Create a meta project file:
$ osc -A https://stretch:443 meta prj Debian:8 -e
<project name= Debian:8 >
<title>Debian 8 DoD</title>
<description>Debian 8 DoD</description>
<person userid= Admin role= maintainer />
<repository name= main >
<download arch= x86_64 url= http://deb.debian.org/debian/jessie/main repotype= deb />
<arch>x86_64</arch>
</repository>
</project>
Visit webUI to check project configuration Create a meta project configuration file:
$ osc -A https://stretch:443 meta prjconf Debian:8 -e
Add the following file, as found at build.opensuse.org
Repotype: debian
# create initial user
Preinstall: base-passwd
Preinstall: user-setup
# required for preinstall images
Preinstall: perl
# preinstall essentials + dependencies
Preinstall: base-files base-passwd bash bsdutils coreutils dash debconf
Preinstall: debianutils diffutils dpkg e2fslibs e2fsprogs findutils gawk
Preinstall: gcc-4.9-base grep gzip hostname initscripts insserv libacl1
Preinstall: libattr1 libblkid1 libbz2-1.0 libc-bin libc6 libcomerr2 libdb5.3
Preinstall: libgcc1 liblzma5 libmount1 libncurses5 libpam-modules
Preinstall: libpcre3 libsmartcols1
Preinstall: libpam-modules-bin libpam-runtime libpam0g libreadline6
Preinstall: libselinux1 libsemanage-common libsemanage1 libsepol1 libsigsegv2
Preinstall: libslang2 libss2 libtinfo5 libustr-1.0-1 libuuid1 login lsb-base
Preinstall: mount multiarch-support ncurses-base ncurses-bin passwd perl-base
Preinstall: readline-common sed sensible-utils sysv-rc sysvinit sysvinit-utils
Preinstall: tar tzdata util-linux zlib1g
Runscripts: base-passwd user-setup base-files gawk
VMinstall: libdevmapper1.02.1
Order: user-setup:base-files
# Essential packages (this should also pull the dependencies)
Support: base-files base-passwd bash bsdutils coreutils dash debianutils
Support: diffutils dpkg e2fsprogs findutils grep gzip hostname libc-bin 
Support: login mount ncurses-base ncurses-bin perl-base sed sysvinit 
Support: sysvinit-utils tar util-linux
# Build-essentials
Required: build-essential
Prefer: build-essential:make
# build script needs fakeroot
Support: fakeroot
# lintian support would be nice, but breaks too much atm
#Support: lintian
# helper tools in the chroot
Support: less kmod net-tools procps psmisc strace vim
# everything below same as for Debian:6.0 (apart from the version macros ofc)
# circular dependendencies in openjdk stack
Order: openjdk-6-jre-lib:openjdk-6-jre-headless
Order: openjdk-6-jre-headless:ca-certificates-java
Keep: binutils cpp cracklib file findutils gawk gcc gcc-ada gcc-c++
Keep: gzip libada libstdc++ libunwind
Keep: libunwind-devel libzio make mktemp pam-devel pam-modules
Keep: patch perl rcs timezone
Prefer: cvs libesd0 libfam0 libfam-dev expect
Prefer: gawk locales default-jdk
Prefer: xorg-x11-libs libpng fam mozilla mozilla-nss xorg-x11-Mesa
Prefer: unixODBC libsoup glitz java-1_4_2-sun gnome-panel
Prefer: desktop-data-SuSE gnome2-SuSE mono-nunit gecko-sharp2
Prefer: apache2-prefork openmotif-libs ghostscript-mini gtk-sharp
Prefer: glib-sharp libzypp-zmd-backend mDNSResponder
Prefer: -libgcc-mainline -libstdc++-mainline -gcc-mainline-c++
Prefer: -libgcj-mainline -viewperf -compat -compat-openssl097g
Prefer: -zmd -OpenOffice_org -pam-laus -libgcc-tree-ssa -busybox-links
Prefer: -crossover-office -libgnutls11-dev
# alternative pkg-config implementation
Prefer: -pkgconf
Prefer: -openrc
Prefer: -file-rc
Conflict: ghostscript-library:ghostscript-mini
Ignore: sysvinit:initscripts
Ignore: aaa_base:aaa_skel,suse-release,logrotate,ash,mingetty,distribution-release
Ignore: gettext-devel:libgcj,libstdc++-devel
Ignore: pwdutils:openslp
Ignore: pam-modules:resmgr
Ignore: rpm:suse-build-key,build-key
Ignore: bind-utils:bind-libs
Ignore: alsa:dialog,pciutils
Ignore: portmap:syslogd
Ignore: fontconfig:freetype2
Ignore: fontconfig-devel:freetype2-devel
Ignore: xorg-x11-libs:freetype2
Ignore: xorg-x11:x11-tools,resmgr,xkeyboard-config,xorg-x11-Mesa,libusb,freetype2,libjpeg,libpng
Ignore: apache2:logrotate
Ignore: arts:alsa,audiofile,resmgr,libogg,libvorbis
Ignore: kdelibs3:alsa,arts,pcre,OpenEXR,aspell,cups-libs,mDNSResponder,krb5,libjasper
Ignore: kdelibs3-devel:libvorbis-devel
Ignore: kdebase3:kdebase3-ksysguardd,OpenEXR,dbus-1,dbus-1-qt,hal,powersave,openslp,libusb
Ignore: kdebase3-SuSE:release-notes
Ignore: jack:alsa,libsndfile
Ignore: libxml2-devel:readline-devel
Ignore: gnome-vfs2:gnome-mime-data,desktop-file-utils,cdparanoia,dbus-1,dbus-1-glib,krb5,hal,libsmbclient,fam,file_alteration
Ignore: libgda:file_alteration
Ignore: gnutls:lzo,libopencdk
Ignore: gnutls-devel:lzo-devel,libopencdk-devel
Ignore: pango:cairo,glitz,libpixman,libpng
Ignore: pango-devel:cairo-devel
Ignore: cairo-devel:libpixman-devel
Ignore: libgnomeprint:libgnomecups
Ignore: libgnomeprintui:libgnomecups
Ignore: orbit2:libidl
Ignore: orbit2-devel:libidl,libidl-devel,indent
Ignore: qt3:libmng
Ignore: qt-sql:qt_database_plugin
Ignore: gtk2:libpng,libtiff
Ignore: libgnomecanvas-devel:glib-devel
Ignore: libgnomeui:gnome-icon-theme,shared-mime-info
Ignore: scrollkeeper:docbook_4,sgml-skel
Ignore: gnome-desktop:libgnomesu,startup-notification
Ignore: python-devel:python-tk
Ignore: gnome-pilot:gnome-panel
Ignore: gnome-panel:control-center2
Ignore: gnome-menus:kdebase3
Ignore: gnome-main-menu:rug
Ignore: libbonoboui:gnome-desktop
Ignore: postfix:pcre
Ignore: docbook_4:iso_ent,sgml-skel,xmlcharent
Ignore: control-center2:nautilus,evolution-data-server,gnome-menus,gstreamer-plugins,gstreamer,metacity,mozilla-nspr,mozilla,libxklavier,gnome-desktop,startup-notification
Ignore: docbook-xsl-stylesheets:xmlcharent
Ignore: liby2util-devel:libstdc++-devel,openssl-devel
Ignore: yast2:yast2-ncurses,yast2-theme-SuSELinux,perl-Config-Crontab,yast2-xml,SuSEfirewall2
Ignore: yast2-core:netcat,hwinfo,wireless-tools,sysfsutils
Ignore: yast2-core-devel:libxcrypt-devel,hwinfo-devel,blocxx-devel,sysfsutils,libstdc++-devel
Ignore: yast2-packagemanager-devel:rpm-devel,curl-devel,openssl-devel
Ignore: yast2-devtools:perl-XML-Writer,libxslt,pkgconfig
Ignore: yast2-installation:yast2-update,yast2-mouse,yast2-country,yast2-bootloader,yast2-packager,yast2-network,yast2-online-update,yast2-users,release-notes,autoyast2-installation
Ignore: yast2-bootloader:bootloader-theme
Ignore: yast2-packager:yast2-x11
Ignore: yast2-x11:sax2-libsax-perl
Ignore: openslp-devel:openssl-devel
Ignore: java-1_4_2-sun:xorg-x11-libs
Ignore: java-1_4_2-sun-devel:xorg-x11-libs
Ignore: kernel-um:xorg-x11-libs
Ignore: tetex:xorg-x11-libs,expat,fontconfig,freetype2,libjpeg,libpng,ghostscript-x11,xaw3d,gd,dialog,ed
Ignore: yast2-country:yast2-trans-stats
Ignore: susehelp:susehelp_lang,suse_help_viewer
Ignore: mailx:smtp_daemon
Ignore: cron:smtp_daemon
Ignore: hotplug:syslog
Ignore: pcmcia:syslog
Ignore: avalon-logkit:servlet
Ignore: jython:servlet
Ignore: ispell:ispell_dictionary,ispell_english_dictionary
Ignore: aspell:aspel_dictionary,aspell_dictionary
Ignore: smartlink-softmodem:kernel,kernel-nongpl
Ignore: OpenOffice_org-de:myspell-german-dictionary
Ignore: mediawiki:php-session,php-gettext,php-zlib,php-mysql,mod_php_any
Ignore: squirrelmail:mod_php_any,php-session,php-gettext,php-iconv,php-mbstring,php-openssl
Ignore: simias:mono(log4net)
Ignore: zmd:mono(log4net)
Ignore: horde:mod_php_any,php-gettext,php-mcrypt,php-imap,php-pear-log,php-pear,php-session,php
Ignore: xerces-j2:xml-commons-apis,xml-commons-resolver
Ignore: xdg-menu:desktop-data
Ignore: nessus-libraries:nessus-core
Ignore: evolution:yelp
Ignore: mono-tools:mono(gconf-sharp),mono(glade-sharp),mono(gnome-sharp),mono(gtkhtml-sharp),mono(atk-sharp),mono(gdk-sharp),mono(glib-sharp),mono(gtk-sharp),mono(pango-sharp)
Ignore: gecko-sharp2:mono(glib-sharp),mono(gtk-sharp)
Ignore: vcdimager:libcdio.so.6,libcdio.so.6(CDIO_6),libiso9660.so.4,libiso9660.so.4(ISO9660_4)
Ignore: libcdio:libcddb.so.2
Ignore: gnome-libs:libgnomeui
Ignore: nautilus:gnome-themes
Ignore: gnome-panel:gnome-themes
Ignore: gnome-panel:tomboy
Substitute: utempter
%ifnarch s390 s390x ppc ia64
Substitute: java2-devel-packages java-1_4_2-sun-devel
%else
 %ifnarch s390x
Substitute: java2-devel-packages java-1_4_2-ibm-devel
 %else
Substitute: java2-devel-packages java-1_4_2-ibm-devel xorg-x11-libs-32bit
 %endif
%endif
Substitute: yast2-devel-packages docbook-xsl-stylesheets doxygen libxslt perl-XML-Writer popt-devel sgml-skel update-desktop-files yast2 yast2-devtools yast2-packagemanager-devel yast2-perl-bindings yast2-testsuite
#
# SUSE compat mappings
#
Substitute: gcc-c++ gcc
Substitute: libsigc++2-devel libsigc++-2.0-dev
Substitute: glibc-devel-32bit
Substitute: pkgconfig pkg-config
%ifarch %ix86
Substitute: kernel-binary-packages kernel-default kernel-smp kernel-bigsmp kernel-debug kernel-um kernel-xen kernel-kdump
%endif
%ifarch ia64
Substitute: kernel-binary-packages kernel-default kernel-debug
%endif
%ifarch x86_64
Substitute: kernel-binary-packages kernel-default kernel-smp kernel-xen kernel-kdump
%endif
%ifarch ppc
Substitute: kernel-binary-packages kernel-default kernel-kdump kernel-ppc64 kernel-iseries64
%endif
%ifarch ppc64
Substitute: kernel-binary-packages kernel-ppc64 kernel-iseries64
%endif
%ifarch s390
Substitute: kernel-binary-packages kernel-s390
%endif
%ifarch s390x
Substitute: kernel-binary-packages kernel-default
%endif
%define debian_version 800
Macros:
%debian_version 800
Visit webUI to check project configuration Create an OBS project linked to DoD
$ osc -A https://stretch:443 meta prj test -e
<project name= test >
<title>test</title>
<description>test</description>
<person userid= Admin role= maintainer />
<repository name= Debian_8.0 >
<path project= Debian:8 repository= main />
<arch>x86_64</arch>
</repository>
</project>
Visit webUI to check project configuration Adding a package to the project
$ osc -A https://stretch:443 co test ; cd test
$ mkdir hello ; cd hello ; apt-get source -d hello ; cd - ; 
$ osc add hello 
$ osc ci -m "New import" hello
The package should go to dispatched state then get in blocked state while it downloads build dependencies from DoD link, eventually it should start building. Please check the journal logs to check if something went wrong or gets stuck. Visit webUI to check hello package build state OBS logging to the journal Check in the journal logs everything went fine:
$ sudo journalctl -u obsdispatcher.service -u obsdodup.service -u obsscheduler@x86_64.service -u obsworker.service -u obspublisher.service
Troubleshooting Currently we are facing few issues with web UI: And there are more issues that have not been reported, please do reportbug obs-api .

Daniel Pocock: Choosing smartcards, readers and hardware for the Outreachy project

One of the projects proposed for this round of Outreachy is the PGP / PKI Clean Room live image. Interns, and anybody who decides to start using the project (it is already functional for command line users) need to decide about purchasing various pieces of hardware, including a smart card, a smart card reader and a suitably secure computer to run the clean room image. It may also be desirable to purchase some additional accessories, such as a hardware random number generator. If you have any specific suggestions for hardware or can help arrange any donations of hardware for Outreachy interns, please come and join us in the pki-clean-room mailing list or consider adding ideas on the PGP / PKI clean room wiki. Choice of smart card For standard PGP use, the OpenPGP card provides a good choice. For X.509 use cases, such as VPN access, there are a range of choices. I recently obtained one of the SmartCard HSM cards, Card Contact were kind enough to provide me with a free sample. An interesting feature of this card is Elliptic Curve (ECC) support. More potential cards are listed on the OpenSC page here. Choice of card reader The technical factors to consider are most easily explained with a table:
On disk Smartcard reader without PIN-pad Smartcard reader with PIN-pad
Software Free/open Mostly free/open, Proprietary firmware in reader
Key extraction Possible Not generally possible
Passphrase compromise attack vectors Hardware or software keyloggers, phishing, user error (unsophisticated attackers) Exploiting firmware bugs over USB (only sophisticated attackers)
Other factors No hardware Small, USB key form-factor Largest form factor
Some are shortlisted on the GnuPG wiki and there has been recent discussion of that list on the GnuPG-users mailing list. Choice of computer to run the clean room environment There are a wide array of devices to choose from. Here are some principles that come to mind:
  • Prefer devices without any built-in wireless communications interfaces, or where those interfaces can be removed
  • Even better if there is no wired networking either
  • Particularly concerned users may also want to avoid devices with opaque micro-code/firmware
  • Small devices (laptops) that can be stored away easily in a locked cabinet or safe to prevent tampering
  • No hard disks required
  • Having built-in SD card readers or the ability to add them easily
SD cards and SD card readers The SD cards are used to store the master private key, used to sign the certificates/keys on the smart cards. Multiple copies are kept. It is a good idea to use SD cards from different vendors, preferably not manufactured in the same batch, to minimize the risk that they all fail at the same time. For convenience, it would be desirable to use a multi-card reader: although the software experience will be much the same if lots of individual card readers or USB flash drives are used. Other devices One additional idea that comes to mind is a hardware random number generator (TRNG), such as the FST-01. Can you help with ideas or donations? If you have any specific suggestions for hardware or can help arrange any donations of hardware for Outreachy interns, please come and join us in the pki-clean-room mailing list or consider adding ideas on the PGP / PKI clean room wiki.

19 October 2016

Pau Garcia i Quiles: FOSDEM Desktops DevRoom 2017 all for Participation

FOSDEM is one of the largest (5,000+ hackers!) gatherings of Free Software contributors in the world and happens each February in Brussels (Belgium, Europe). Once again, one of the tracks will be the Desktops DevRoom (formerly known as CrossDesktop DevRoom ), which will host Desktop-related talks. We are now inviting proposals for talks about Free/Libre/Open-source Software on the topics of Desktop development, Desktop applications and interoperability amongst Desktop Environments. This is a unique opportunity to show novel ideas and developments to a wide technical audience. Topics accepted include, but are not limited to: Talks can be very specific, such as the advantages/disadvantages of distributing a desktop application with snap vs flatpak, or as general as using HTML5 technologies to develop native applications. Topics that are of interest to the users and developers of all desktop environments are especially welcome. The FOSDEM 2016 schedule might give you some inspiration. Submissions Please include the following information when submitting a proposal: How to submit All submissions are made in the Pentabarf event planning tool: https://penta.fosdem.org/submission/FOSDEM17 To submit your talk, click on Create Event , then make sure to select the Desktops devroom as the Track . Otherwise your talk will not be even considered for any devroom at all. If you already have a Pentabarf account from a previous year, even if your talk was not accepted, please reuse it. Create an account if, and only if, you don t have one from a previous year. If you have any issues with Pentabarf, please contact desktops-devroom@lists.fosdem.org. Deadline The deadline for submissions is December 5th 2016. FOSDEM will be held on the weekend of 4 & 5 February 2017 and the Desktops DevRoom will take place on Sunday, February 5th 2017. We will contact every submitter with a yes or no before December 11th 2016. Recording permission The talks in the Desktops DevRoom will be audio and video recorded, and possibly streamed live too. In the Submission notes field, please indicate that you agree that your presentation will be licensed under the CC-By-SA-4.0 or CC-By-4.0 license and that you agree to have your presentation recorded. For example:
If my presentation is accepted for FOSDEM, I hereby agree to license all recordings, slides, and other associated materials under the Creative Commons Attribution Share-Alike 4.0 International License. Sincerely, <NAME>.
If you want us to stop the recording in the Q & A part (should you have one), please tell us. We can do that but only for the Q & A part. More information The official communication channel for the Desktops DevRoom is its mailing list desktops-devroom@lists.fosdem.org. Use this page to manage your subscription: https://lists.fosdem.org/listinfo/desktops-devroom Organization The Desktops DevRoom 2017 is managed by a team representing the most notable open desktops: If you want to join the team, please contact desktops-devroom@lists.fosdem.org

Rapha&#235;l Hertzog: Freexian s report about Debian Long Term Support, September 2016

A Debian LTS logoLike each month, here comes a report about the work of paid contributors to Debian LTS. Individual reports In September, about 152 work hours have been dispatched among 13 paid contributors. Their reports are available: Evolution of the situation The number of sponsored hours reached 172 hours per month thanks to maxcluster GmbH joining as silver sponsor and RHX Srl joining as bronze sponsor. We only need a couple of supplementary sponsors now to reach our objective of funding the equivalent of a full time position. The security tracker currently lists 39 packages with a known CVE and the dla-needed.txt file 34. It s a small bump compared to last month but almost all issues are affected to someone. Thanks to our sponsors New sponsors are in bold.

No comment Liked this article? Click here. My blog is Flattr-enabled.

18 October 2016

Enrico Zini: debtags and aptitude forget-new

I like to regularly go through the new packages section in aptitude to see what interesting new packages entered testing, but recently that joyful moment got less joyful for me because of a barrage of obscurely named packages. I have just realised that aptitude forget-new supports search patterns, and that brought back the joy. I put this in a script that I run before looking for new packages in aptitude:
aptitude forget-new '?tag(field::biology)
                     ?tag(devel::lang:ruby)
                     ?tag(devel::lang:perl)
                     ?tag(role::shared-lib)
                     ?tag(suite::openstack)
                     ?tag(implemented-in::php)
                     ~n^node-'
The actual content of the search pattern is purely a matter of taste. I'm happy to see how debtags becomes quite useful here, to keep my own user experience manageable as the size of Debian keeps growing. Update: pabs suggested to use apt post-invoke hooks. For example:
        $ cat /etc/apt/apt.conf.d/99forget-new
        APT::Update::Post-Invoke   "aptitude forget-new '~sdebug'";  ;

Next.

Previous.