Search Results: "tar"

5 October 2020

Russ Allbery: California general election

As normal, probably of direct interest only to California residents and apologies to everyone else since my hand-rolled blog software doesn't do cut tags. I'm only going to cover propositions, since the state-wide elections aren't very interesting and I both don't have strong opinions about the local elections and would guess that almost no one cares. See the voter guide for the full details on each proposition. Propositions 16 through 19 were put on the ballot by the legislature and thus were written as well as our regular laws. The remaining propositions are initiatives, which means I default to voting against them because they're usually poorly-written crap. Proposition 14: NO. I reluctantly supported the original proposition to fund stem cell research with state bonds because it was in the middle of the George W. Bush administration and his weird obsession with ending stem cell research. It seemed worth the cost to maintain the research, and I don't regret doing this. But since then we've reached a compromise on ongoing research, and this proposition looks a lot more like pork spending than investment. I am in favor of government support of basic research, but I think that's best done by a single grant institution that can pursue a coherent agenda. The federal government, when sane, does a decent job of this, and the California agency created by the previous proposition looks dodgy. The support for this proposition also comes primarily from research institutions that benefit from it. On top of that, there are way higher priorities right now for public investment than a very specific and limited type of medical research that isn't even the most important type of medical research to do right now. There is nothing magic about stem cells other than the fact that they make a certain type of Republican lose their minds. It's time to stop funding this specific research specially and roll it into general basic research funding. Proposition 15: YES. Yes to anything that repeals Proposition 13 in whole or in part. Repealing it for commercial and industrial real estate is a good first step. A rare exception in my general rule to vote against initiatives. Proposition 16: YES. Reverses a bad law to outlaw affirmative action in California. I am in favor of actual reparations, so I am of course in favor of this, which is far, far more mild. Proposition 17: YES. Restores voting rights to felons after completion of their sentence. I think it's inexcusable that any US citizen cannot vote, including people who are currently incarcerated, so of course I'm in favor of this more mild measure. (You may notice a theme.) When we say everyone should be able to vote, that should mean literally everyone. Proposition 18: YES. Allows 17-year-olds to vote in California (but not federal) elections in some specific circumstances. I'm generally in favor of lowering the voting age, and this seems inoffensive. (And the arguments against it are stupid.) Proposition 19: YES. This is a complicated legislative compromise around property tax that strengthens property tax limits for seniors moving within California while removing exemptions against increases for inherited real estate not used as a primary home. Some progressives are opposed to this because it doesn't go far enough and increases exemptions for seniors. I agree that those exemptions aren't needed and shouldn't be added, but closing the inheritance loophole is huge and worth this compromise. It's a tepid improvement for the somewhat better, but it's still worth approving (and was written by the legislature, so it's somewhat better written than the typical initiative). Proposition 20: NO. Another pile of "anyone who has ever committed a crime deserves to be treated as subhuman" bullshit. Typical harsher sentences and harsher parole nonsense. No to everything like this, always. Proposition 21: YES. This is my other exception of voting for an initiative, and that's because the California state legislature is completely incapable of dealing with any housing problem. This is a proposition that overhauls an ill-conceived state-wide restriction on how rent control can be handled. The problem with rent control is that a sane solution to housing problems in this state requires both rent control and massive new construction, and we only get the former and not the latter because the NIMBYism is endemic. (There's a pile of NIMBY crap on my local ballot this year.) I would much rather be approving those things together, because either of them alone makes things worse for a lot of people. So yes, the opponents of this proposition are right: it will make the housing crisis worse, because everyone refuses to deal with the supply side. That said, we need rent control as part of a humane solution, and the current state-wide rules are bad. For example, they disallow rent control on every property newer than a certain date that's forever fixed. This initiative replaces that with a much saner 15-year rolling window for maximizing profit, which is a better balance. I hate voting for this because the legislature should have done their job and passed comprehensive housing reform. But since they didn't, this is part of what they should have passed, and I'll vote for it. Particularly since it's opposed by all the huge commercial landlords. Proposition 22: NO. The "exclude Uber and Lyft from labor law" proposition, which is just as bullshit as it sounds. They're spending all of their venture capital spamming the crap out of everyone in the state to try to get this passed by lying about it. Just stunningly evil companies. If your business model requires exploiting labor, get a better business model. Proposition 23: NO. So, this is another mess. It appears to be part of some unionization fight between dialysis clinic employees and the for-profit dialysis clinics. I hate everything about this situation, starting from the fact that we have such a thing as for-profit dialysis clinics, which is a crime against humanity. But this proposition requires some very dodgy things, such as having a doctor on staff at every clinic for... reasons? This is very reminiscent of the bullshit laws about abortion clinics, which are designed to make it more expensive to operate a clinic for no justifiable reason. I'm happy to believe there is a bit more justification here, but this sort of regulation is tricky and should be done by the legislature in a normal law-making process. Medical regulation by initiative is just a horrible idea in every way. So while I am doubtless politically on the side of the proponents of the proposition, this is the wrong tool. Take it to the legislature. Proposition 24: NO. A deceptively-written supposed consumer privacy law written by tech companies that actually weakens consumer privacy in some critical ways that are profitable for them. No thanks, without even getting to the point that this sort of thing shouldn't be done by initiative. Proposition 25: YES. Yes, we should eliminate cash bail, which is essentially imprisoning people for being poor. No, this doesn't create a system of government profiling; judges already set bail and can revoke bail for flight risks. (This is not legislation by initiative; the state government already passed this law, but we have a dumb law that lets people oppose legislative action via initiative, so we have to vote to approve the law that our representatives already passed and that should have already gone into effect.)

4 October 2020

Sylvain Beucler: git filter-branch and --state-branch - how?

I'm mirroring and reworking a large Git repository with git filter-branch (conversion ETA: 20h), and I was wondering how to use --state-branch which is supposed to speed-up later updates, or split a large conversion in several updates. The documentation is pretty terse, the option can produce weird results (like an identity mapping that breaks all later updates, or calling the expensive tree-filter but discarding the results), wrappers are convoluted, but I got something to work so I'll share :) The main point is: run the initial script and the later updates in the same configuration, which means the target branch needs to be reset to the upstream branch each time, before it's rewritten again by filter-branch. In other words, don't re-run it on the rewritten branch, nor attempt some complex merge/cherry-pick.

git fetch
git branch --no-track -f myrewrite origin/master
git filter-branch \
  --xxx-filter ... \
  --xxx-filter ... \
  --state-branch refs/heads/filter-branch/myrewrite \
  -d /dev/shm/filter-branch/$$ -f \
  myrewrite
Updates restart from scratch but only take a few seconds to skim through all the already-rewritten commits, and maintain a stable history. Note that if the process is interrupted, the state-branch isn't modified, so it's not a stop/resume feature. If you want to split a lenghty conversion, you could simulate multiple upstream updates by checking out successive points in history (e.g. per year using $(git rev-list -1 --before='2020-01-01 00:00:00Z')). --state-branch isn't meant to rewrite in reverse chronological order either, because all commit ids would constantly change. Still, you can rewrite only the recent history for a quick discardable test. Be cautious when using/deleting rewritten branches, especially during early tests, because Git tends to save them to multiple places which may desync (e.g. .git/refs/heads/, .git/logs/refs/, .git/packed-refs). Also remember to delete the state-branch between different tests. Last, note the unique temporary directory -d to avoid ruining concurrent tests ^_^'

3 October 2020

Steve Kemp: Writing an assembler.

Recently I've been writing a couple of simple compilers, which take input in a particular format and generate assembly language output. This output can then be piped through gcc to generate a native executable. Public examples include this trivial math compiler and my brainfuck compiler. Of course there's always the nagging thought that relying upon gcc (or nasm) is a bit of a cheat. So I wondered how hard is it to write an assembler? Something that would take assembly-language program and generate a native (ELF) binary? And the answer is "It isn't hard, it is just tedious". I found some code to generate an ELF binary, and after that assembling simple instructions was pretty simple. I remember from my assembly-language days that the encoding of instructions can be pretty much handled by tables, but I've not yet gone into that. (Specifically there are instructions like "add rax, rcx", and the encoding specifies the source/destination registers - with different forms for various sized immediates.) Anyway I hacked up a simple assembler, it can compile a.out from this input:

.hello   DB "Hello, world\n"
.goodbye DB "Goodbye, world\n"
        mov rdx, 13        ;; write this many characters
        mov rcx, hello     ;; starting at the string
        mov rbx, 1         ;; output is STDOUT
        mov rax, 4         ;; sys_write
        int 0x80           ;; syscall
        mov rdx, 15        ;; write this many characters
        mov rcx, goodbye   ;; starting at the string
        mov rax, 4         ;; sys_write
        mov rbx, 1         ;; output is STDOUT
        int 0x80           ;; syscall
        xor rbx, rbx       ;; exit-code is 0
        xor rax, rax       ;; syscall will be 1 - so set to xero, then increase
        inc rax            ;;
        int 0x80           ;; syscall
The obvious omission is support for "JMP", "JMP_NZ", etc. That's painful because jumps are encoded with relative offsets. For the moment if you want to jump:
        push foo     ; "jmp foo" - indirectly.
        ret
:bar
        nop          ; Nothing happens
        mov rbx,33   ; first syscall argument: exit code
        mov rax,1    ; system call number (sys_exit)
        int 0x80     ; call kernel
:foo
        push bar     ; "jmp bar" - indirectly.
        ret
I'll update to add some more instructions, and see if I can use it to handle the output I generate from a couple of other tools. If so that's a win, if not then it was a fun learning experience:

Julian Andres Klode: Google Pixel 4a: Initial Impressions

Yesterday I got a fresh new Pixel 4a, to replace my dying OnePlus 6. The OnePlus had developed some faults over time: It repeatedly loses connection to the AP and the network, and it got a bunch of scratches and scuffs from falling on various surfaces without any protection over the past year.

Why get a Pixel? Camera: OnePlus focuses on stuffing as many sensors as it can into a phone, rather than a good main sensor, resulting in pictures that are mediocre blurry messes - the dreaded oil painting effect. Pixel have some of the best camera in the smartphone world. Sure, other hardware is far more capable, but the Pixels manage consistent results, so you need to take less pictures because they don t come out blurry half the time, and the post processing is so good that the pictures you get are just great. Other phones can shoot better pictures, sure - on a tripod. Security updates: Pixels provide 3 years of monthly updates, with security updates being published on the 5th of each month. OnePlus only provides updates every 2 months, and then the updates they do release are almost a month out of date, not counting that they are only 1st-of-month patches, meaning vendor blob updates included in the 5th-of-month updates are even a month older. Given that all my banking runs on the phone, I don t want it to be constantly behind. Feature updates: Of course, Pixels also get Beta Android releases and the newest Android release faster than any other phone, which is advantageous for Android development and being nerdy. Size and weight: OnePlus phones keep getting bigger and bigger. By today s standards, the OnePlus 6 at 6.18" and 177g is a small an lightweight device. Their latest phone, the Nord, has 6.44" and weighs 184g, the OnePlus 8 comes in at 180g with a 6.55" display. This is becoming unwieldy. Eschewing glass and aluminium for plastic, the Pixel 4a comes in at 144g.

First impressions

Accessories The Pixel 4a comes in a small box with a charger, USB-C to USB-C cable, a USB-OTG adapter, sim tray ejector. No pre-installed screen protector or bumper are provided, as we ve grown accustomed to from Chinese manufacturers like OnePlus or Xiaomi. The sim tray ejector has a circular end instead of the standard oval one - I assume so it looks like the o in Google? Google sells you fabric cases for 45 . That seems a bit excessive, although I like that a lot of it is recycled.

Haptics Coming from a 6.18" phablet, the Pixel 4a with its 5.81" feels tiny. In fact, it s so tiny my thumb and my index finger can touch while holding it. Cute! Bezels are a bit bigger, resulting in slightly less screen to body. The bottom chin is probably impracticably small, this was already a problem on the OnePlus 6, but this one is even smaller. Oh well, form over function. The buttons on the side are very loud and clicky. As is the vibration motor. I wonder if this Pixel thinks it s a Model M. It just feels great. The plastic back feels really good, it s that sort of high quality smooth plastic you used to see on those high-end Nokia devices. The finger print reader, is super fast. Setup just takes a few seconds per finger, and it works reliably. Other phones (OnePlus 6, Mi A1/A2) take like half a minute or a minute to set up.

Software The software - stock Android 11 - is fairly similar to OnePlus' OxygenOS. It s a clean experience, without a ton of added bloatware (even OnePlus now ships Facebook out of box, eww). It s cleaner than OxygenOS in some way - there are no duplicate photos apps, for example. On the other hand, it also has quite a bunch of Google stuff I could not care less about like YT Music. To be fair, those are minor noise once all 130 apps were transferred from the old phone. There are various things I miss coming from OnePlus such as off-screen gestures, network transfer rate indicator in quick settings, or a circular battery icon. But the Pixel has an always on display, which is kind of nice. Most of the cool Pixel features, like call screening or live transcriptions are unfortunately not available in Germany. The display is set to display the same amount of content as my 6.18" OnePlus 6 did, so everything is a bit tinier. This usually takes me a week or two to adjust too, and then when I look at the OnePlus again I ll be like Oh the font is huge , but right now, it feels a bit small on the Pixel. You can configure three colour profiles for the Pixel 4a: Natural, Boosted, and Adaptive. I have mine set to adaptive. I d love to see stock Android learn what OnePlus has here: the ability to adjust the colour temperature manually, as I prefer to keep my devices closer to 5500K than 6500K, as I feel it s a bit easier on the eyes. Or well, just give me the ability to load a ICM profile (though, I d need to calibrate the screen then - work!).

Migration experience Restoring the apps from my old phone only restore settings for a few handful out of 130, which is disappointing. I had to spent an hour or two logging in to all the other apps, and I had to fiddle far too long with openScale to get it to take its data over. It s a mystery to me why people do not allow their apps to be backed up, especially something innocent like a weight tracking app. One of my banking apps restored its logins, which I did not really like. KeePass2Android settings were restored as well, but at least the key file was not restored. I did not opt in to restoring my device settings, as I feel that restoring device settings when changing manufactures is bound to mess up some things. For example, I remember people migrating to OnePlus phones and getting their old DND schedule without any way to change it, because OnePlus had hidden the DND stuff. I assume that s the reason some accounts, like my work GSuite account were not migrated (it said it would migrate accounts during setup). I ve setup Bitwarden as my auto-fill service, so I could login into most of my apps and websites using the stored credentials. I found that often that did not work. Like Chrome does autofill fine once, but if I then want to autofill again, I have to kill and restart it, otherwise I don t get the auto-fill menu. Other apps did not allow any auto-fill at all, and only gave me the option to copy and paste. Yikes - auto-fill on Android still needs a lot of work.

Performance It hangs a bit sometimes, but this was likely due to me having set 2 million iterations on my Bitwarden KDF and using Bitwarden a lot, and then opening up all 130 apps to log into them which overwhelmed the phone a bit. Apart from that, it does not feel worse than the OnePlus 6 which was to be expected, given that the benchmarks only show a slight loss in performance. Photos do take a few seconds to process after taking them, which is annoying, but understandable given how much Google relies on computation to provide decent pictures.

Audio The Pixel has dual speakers, with the earpiece delivering a tiny sound and the bottom firing speaker doing most of the work. Still, it s better than just having the bottom firing speaker, as it does provide a more immersive experience. Bass makes this thing vibrate a lot. It does not feel like a resonance sort of thing, but you can feel the bass in your hands. I ve never had this before, and it will take some time getting used to.

Final thoughts This is a boring phone. There s no wow factor at all. It s neither huge, nor does it have high-res 48 or 64 MP cameras, nor does it have a ton of sensors. But everything it does, it does well. It does not pretend to be a flagship like its competition, it doesn t want to wow you, it just wants to be the perfect phone for you. The build is solid, the buttons make you think of a Model M, the camera is one of the best in any smartphone, and you of course get the latest updates before anyone else. It does not feel like a only 350 phone, but yet it is. 128GB storage is plenty, 1080p resolution is plenty, 12.2MP is you guessed it, plenty. The same applies to the other two Pixel phones - the 4a 5G and 5. Neither are particularly exciting phones, and I personally find it hard to justify spending 620 on the Pixel 5 when the Pixel 4a does job for me, but the 4a 5G might appeal to users looking for larger phones. As to 5G, I wouldn t get much use out of it, seeing as its not available anywhere I am. Because I m on Vodafone. If you have a Telekom contract or live outside of Germany, you might just have good 5G coverage already and it might make sense to get a 5G phone rather than sticking to the budget choice.

Outlook The big question for me is whether I ll be able to adjust to the smaller display. I now have a tablet, so I m less often using the phone (which my hands thank me for), which means that a smaller phone is probably a good call. Oh while we re talking about calls - I only have a data-only SIM in it, so I could not test calling. I m transferring to a new phone contract this month, and I ll give it a go then. This will be the first time I get VoLTE and WiFi calling, although it is Vodafone, so quality might just be worse than Telekom on 2G, who knows. A big shoutout to congstar for letting me cancel with a simple button click, and to @vodafoneservice on twitter for quickly setting up my benefits of additional 5GB per month and 10 discount for being an existing cable customer. I m also looking forward to playing around with the camera (especially night sight), and eSIM. And I m getting a case from China, which was handed over to the Airline on Sep 17 according to Aliexpress, so I guess it should arrive in the next weeks. Oh, and screen protector is not here yet, so I can t really judge the screen quality much, as I still have the factory protection film on it, and that s just a blurry mess - but good enough for setting it up. Please Google, pre-apply a screen protector on future phones and include a simple bumper case. I might report back in two weeks when I have spent some more time with the device.

Ritesh Raj Sarraf: First Telescope

Curiosity I guess this would be common to most of us. While I grew up, right from the childhood itself, the sky was always an intriguing view. The Stars, the Moon, the Eclipses; were all fascinating. As a child, in my region, religion and culture; the mythology also built up stories around it. Lunar Eclipses have a story of its own. During Solar Eclipses, parents still insist that we do not go out. And to be done with the food eating before/after the eclipse. Then there s the Hindu Astrology part, which claims its own theories and drags in mythology along. For example, you ll still find the Hindu Astrology making recommendations to follow certain practices with the planets, to get auspicious personal results. As far as I know, other religions too have similar beliefs about the planets. As a child, we are told the Moon to be addressed as an Uncle ( ). There s also a rhyme around it, that many of us must have heard. And if you look at our god, Lord Mahadev, he s got a crescent on his head
Lord Mahadev
Lord Mahadev

Reality Fast-forward to today, as I grew, so did some of my understanding. It is fascinating how mankind has achieved so much understanding of our surrounding. You could go through the documentaries on Mars Exploration, for example; to see how the rovers are providing invaluable data. As a mere individual, there s a limit to what one can achieve. But the questions flow in free.
  • Is there life beyond us
  • What s out there in the sky
  • Why is all this the way it is

Hobby The very first step, for me, for every such curiosity, has been to do the ground work, with the resources I have. To study on the subject. I have done this all my life. For example, I started into the Software domain as: A curiosity => A Hobby => A profession Same was the case with some of the other hobbies, equally difficult as Astronomy, that I developed a liking for. Just did the ground work, studied on those topics and then applied the knowledge to further improve it and build up some experience. And star gazing came in no different. As a complete noob, had to start with the A B C on the subject of Astronomy. Familiarize myself with the usual terms. As so on PS: Do keep in mind that not all hobbies have a successful end. For example, I always craved to be good with graphic designing, image processing and the likes, where I ve always failed. Never was able to keep myself motivated enough. Similar was my experience when trying to learn playing a musical instrument. Just didn t work out for me, then. There s also a phase in it, where you fail and then learn from the failures and proceed further, and then eventually succeed. But we all like to talk about the successes. :-)

Astronomy So far, my impression has been that this topic/domain will not suit most of the people. While the initial attraction may be strong, given the complexity and perseverance that Astronomy requires, most people would lose interest in it very soon. Then there s the realization factor. If one goes with an expectation to get quick results, they may get disappointed. It isn t like a point and shoot device that d give you results on the spot. There s also the expectation side of things. If you are a person more accustomed to taking pretty selfies, which always come right because the phone manufacturer does heavy processing on the images to ensure that you get to see the pretty fake self, for the most of the times; then star gazing with telescopes could be a frustrating experience altogether. What you get to see in the images on the internet will be very different than what you d be able to see with your eyes and your basic telescope. There s also the cost aspect. The more powerful (and expensive) your telescope, the better your view. And all things aside, it still may get you lose interest, after you ve done all the ground work and spent a good chunk of money on it. Simply because the object you are gazing at is more a still image, which can quickly get boring for many. On the other hand, if none of the things obstruct, then the domain of Astronomy can be quite fascinating. It is a continuous learning domain (reminds me of CI in our software field these days). It is just the beginning for us here, and we hope to have a lasting experience in it.

The Internet I have been indebted to the internet right from the beginning. The internet is what helped me be able to achieve all I wanted. It is one field with no boundaries. If there is a will, there is a way; and often times, the internet is the way.
  • I learnt computers over the internet.
  • Learnt more about gardening and plants over the internet
  • Learnt more about fish care-taking over the internet
And many many more things. Some of the communities over the internet are a great way to participation. They bridge the age gap, the regional gap and many more. For my Astronomy need, I was glad to see so many active communities, with great participants, on the internet.

Telescope While there are multiple options to start star gazing, I chose to start with a telescope. But as someone completely new to this domain, there was a long way to go. And to add to that, the real life: work + family I spent a good 12+ months reading up on the different types of telescopes, what they are, their differences, their costs, their practical availability etc. The good thing is that the market has offerings for everything. From a very basic binocular to a fully automatic Maksutov-Cassegrain scope. It all would depend on your budget.

Automatic vs Manual To make it easy for the users, the market has multiple options in the offering. One could opt-in for a cheap, basic and manually operated telescope; which would require the user to do a lot of ground study. On the other hand, users also have the option of automatic telescopes which do the hard work of locating and tracking the planetary objects. Either option aside, the end result of how much you ll be able to observe the sky, still depends on many many more factors: Enthusiasm over time, Light Pollution, Clear Skies, Timing etc. PS: The planetary objects move at a steady pace. Objects you lock into your view now will be gone out of the FOV in just a matter of minutes.

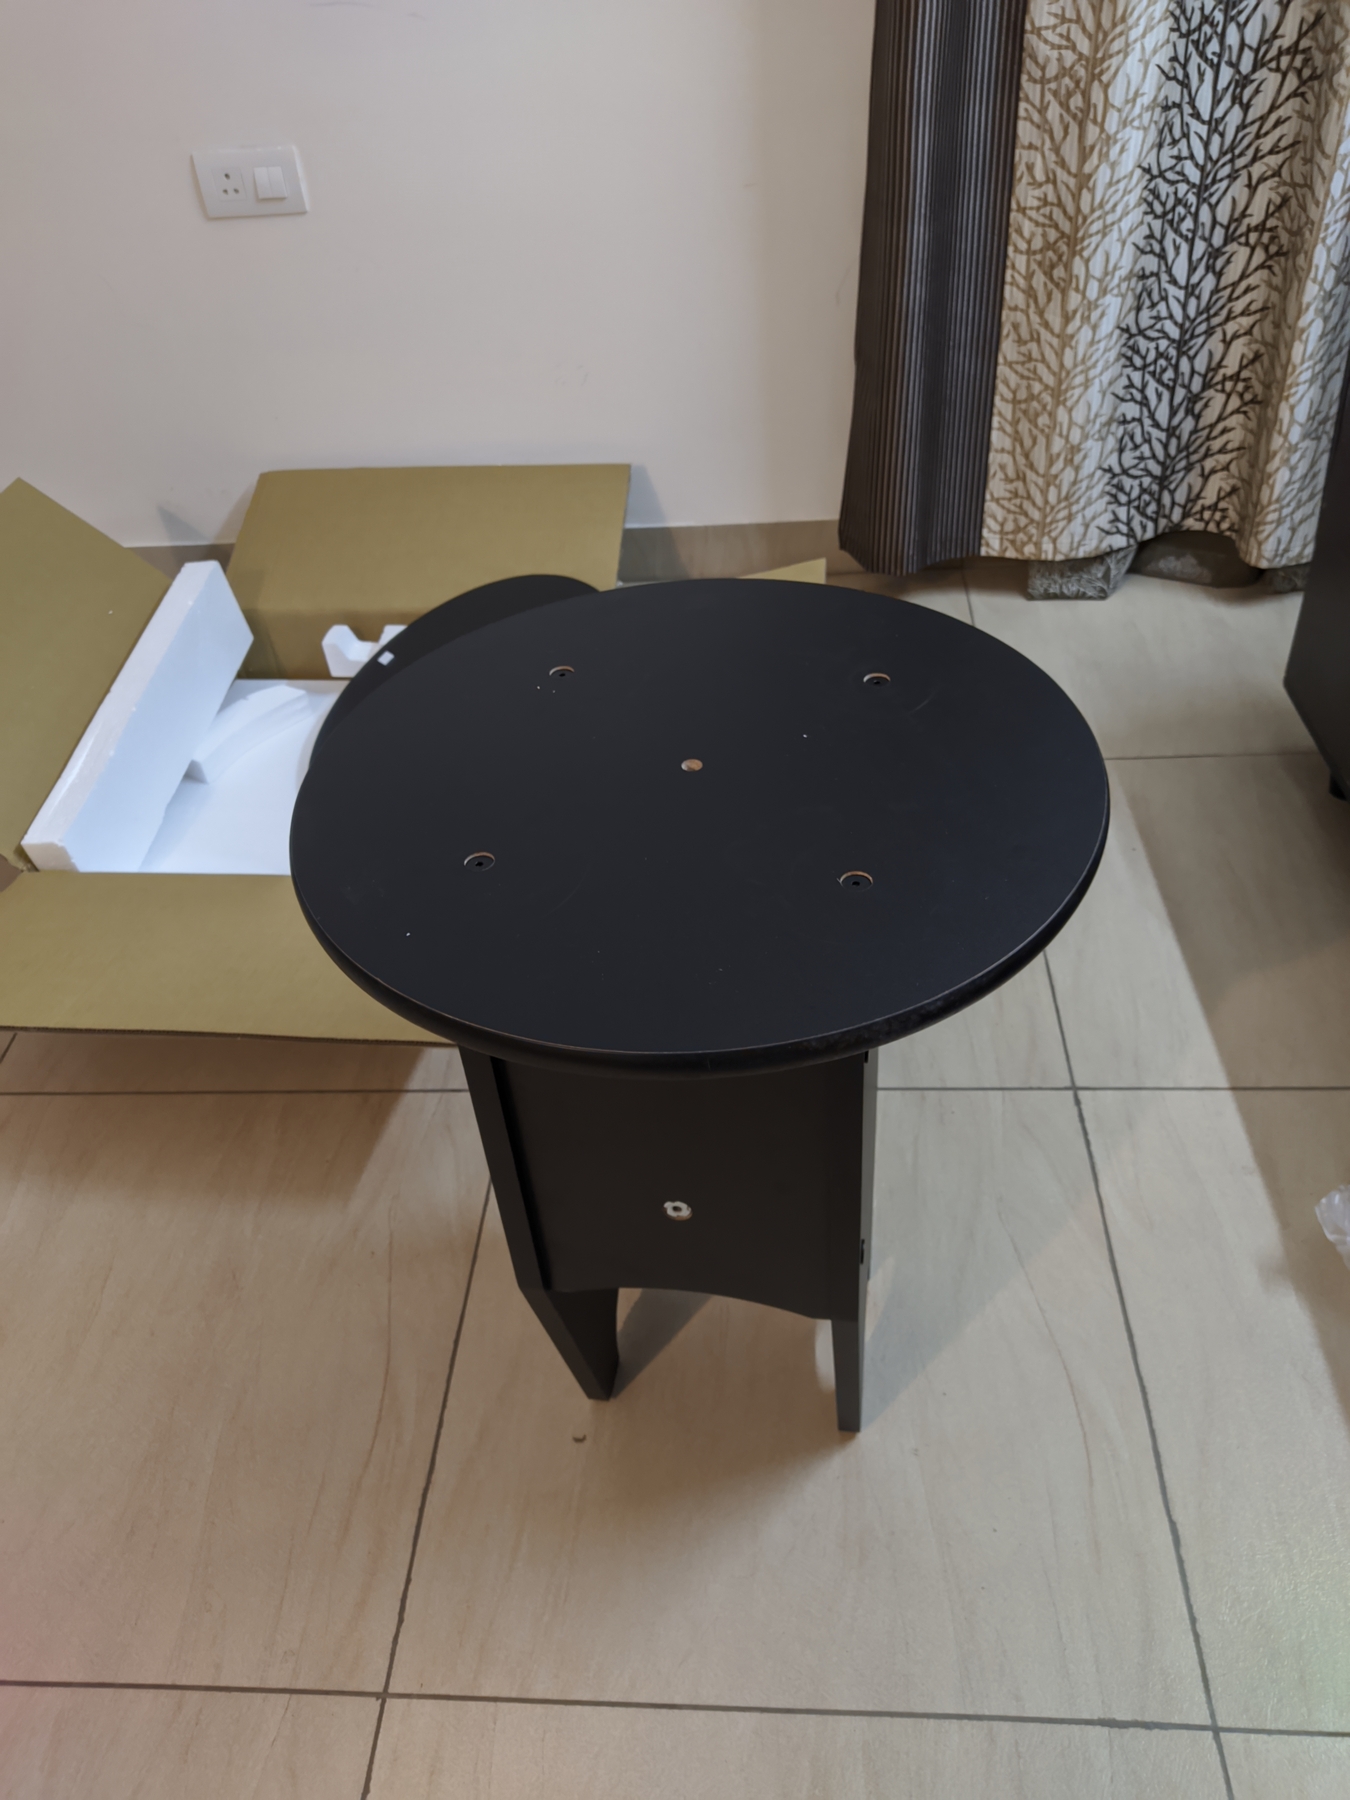
My Telescope After spending so much of the time reading up on types of telescopes, my conclusion was that a scope with high aperture and focal length was the way to go forward. This made me shorten the list to Dobsonians. But the Dobsonians aren t a very cheap telescope, whether manual or automatic. My final decision made me acquire a 6" Dobsonian Telescope. It is a Newtonian Reflecting Telescope with a 1200mm focal length and 150mm diameter. Another thing about this subject is that most of the stuff you do in Astronomy; right from the telescope selection, to installation, to star gazing; most of it is DIY, so your mileage may vary with the end result and experience. For me, installation wasn t very difficult. I was able to assemble the base Dobsonian mount and the scope in around 2 hours. But the installation manual, I had been provided with, was very brief. I ended up with one module in the mount wrongly fit, which I was able to fix later, with the help of online forums.
Dobsonian Mount
Dobsonian Mount
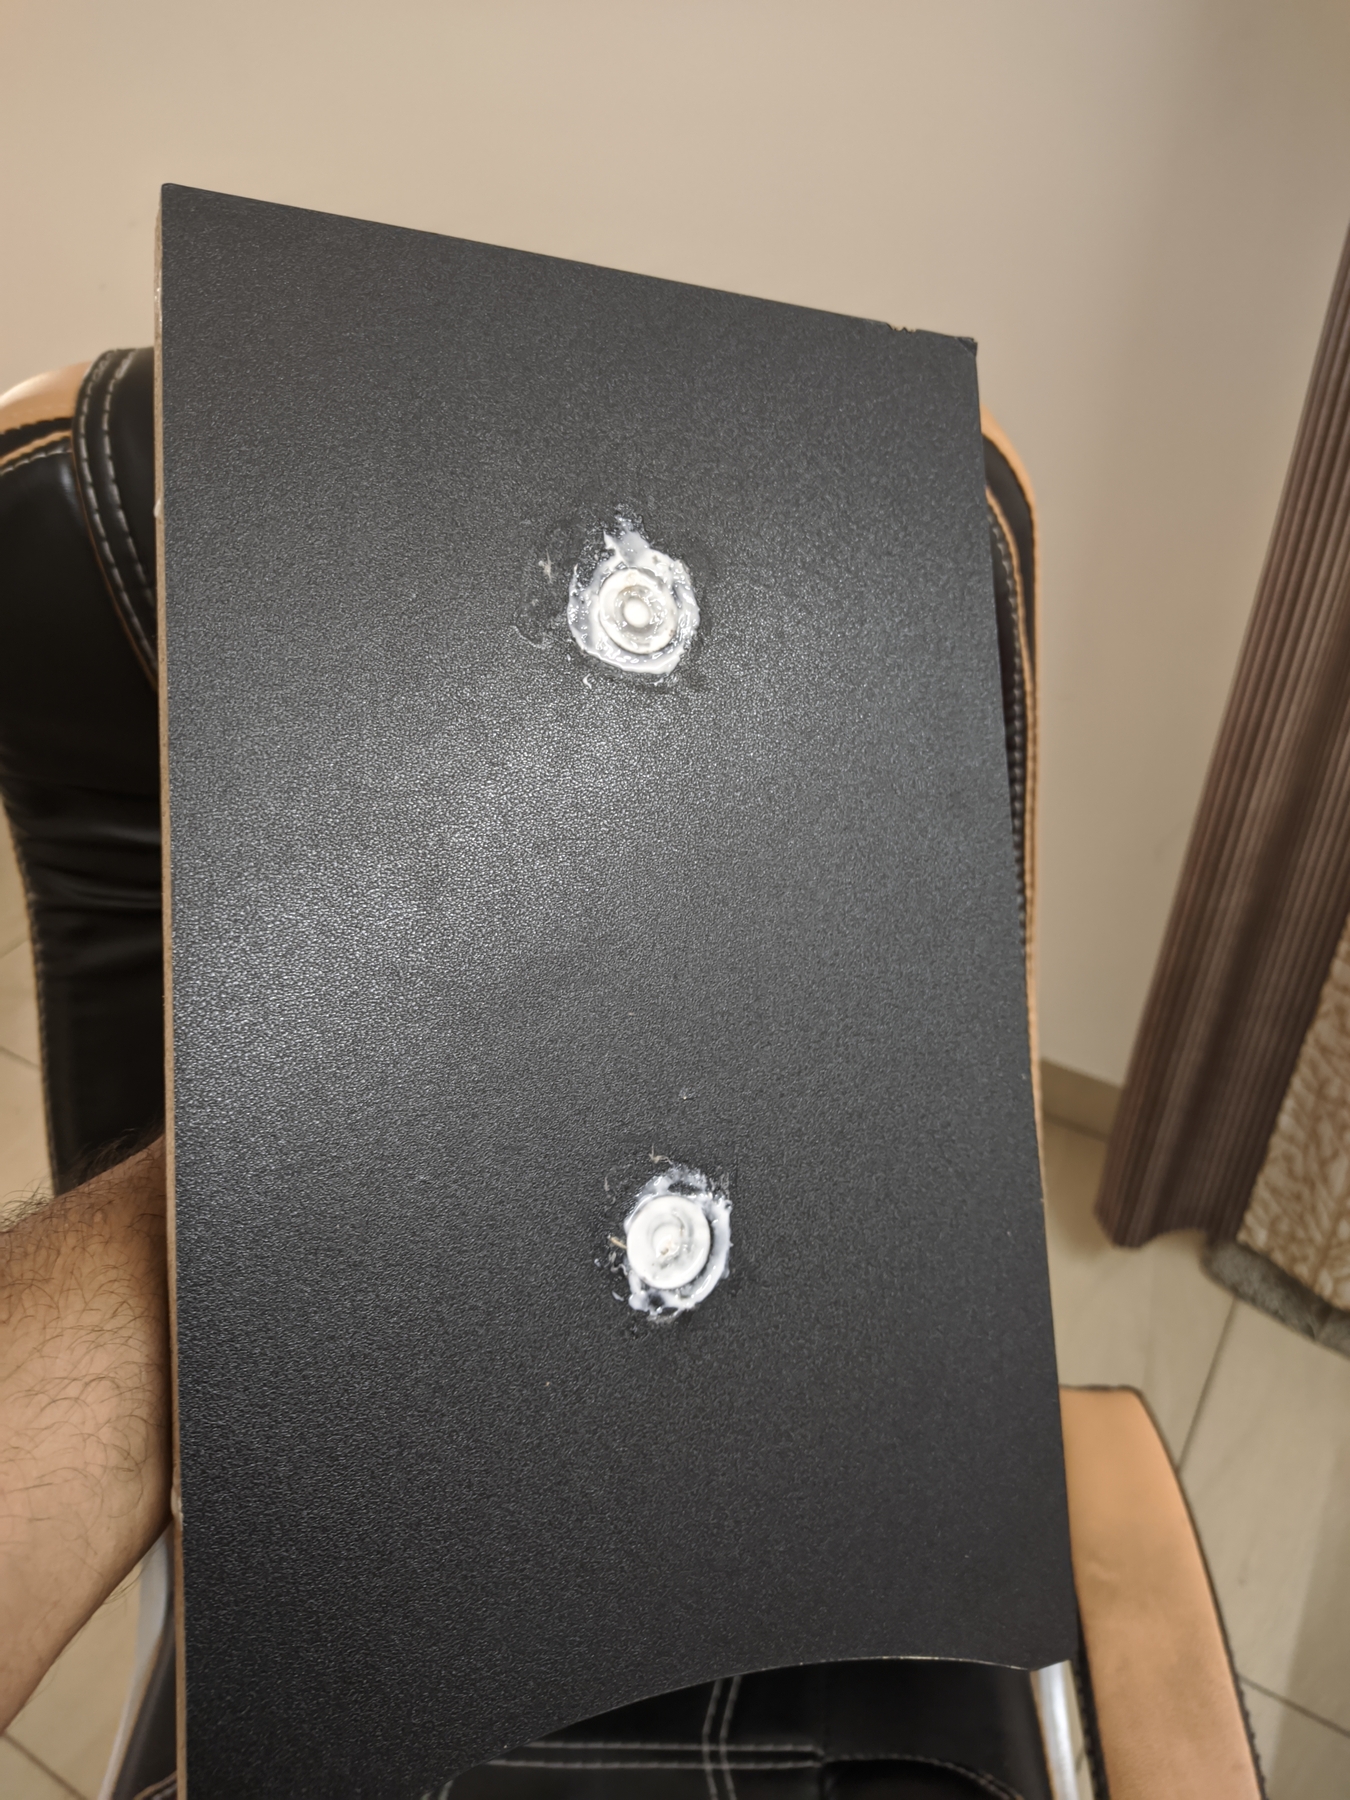
In this image you can see that the side facing out, where the handle will go, is wrong. If fit this way, the handle will not withstand any weight at all.
Correct Panel Side
Correct Panel Side
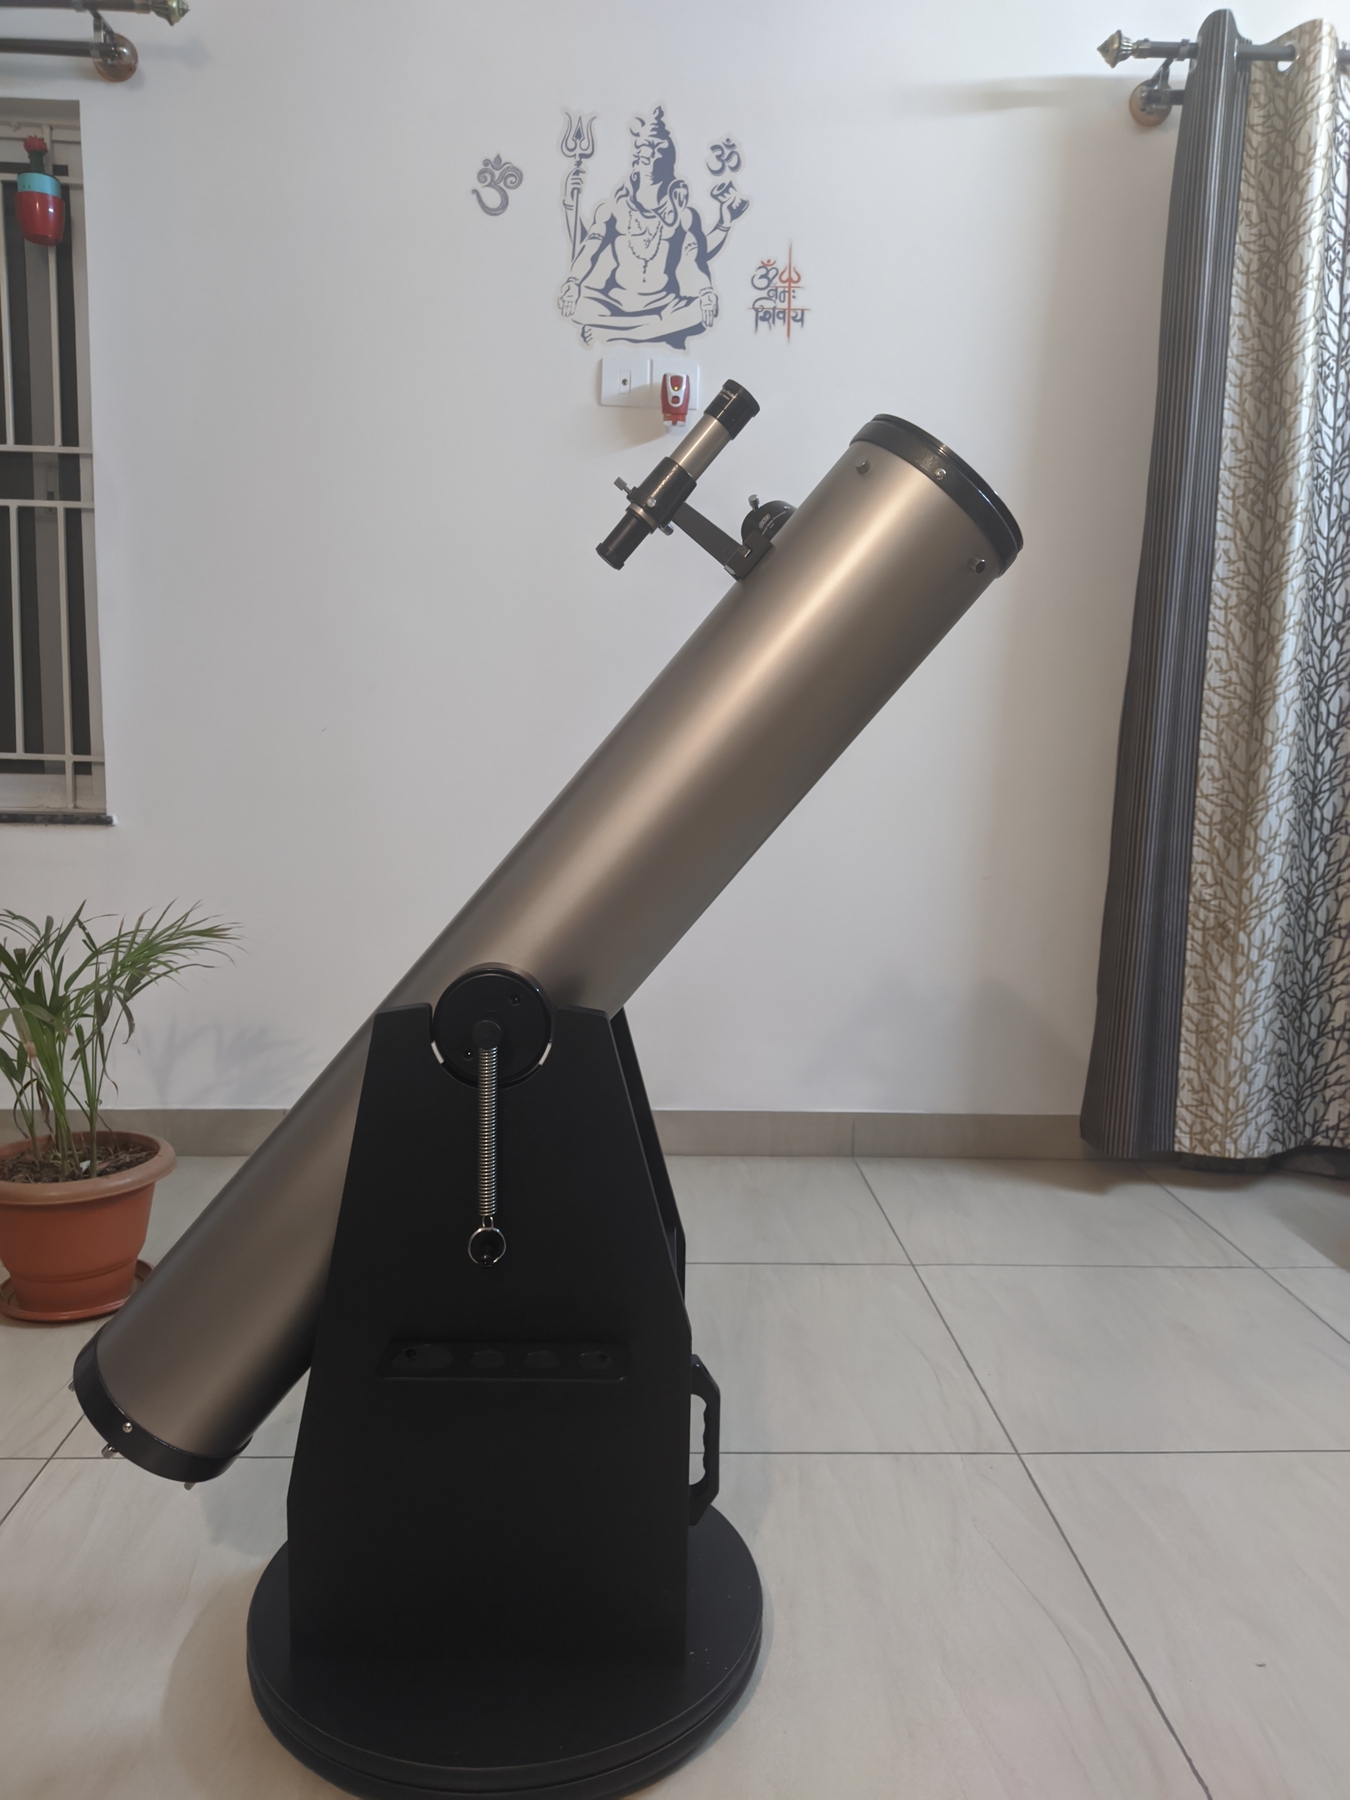
The right fix of the handle base board. In this image, the handle is on the other side that I m holding. Because the initial fit put in some damage to the engineered wood, I fixed it up by sealing with some adhesive. With that, this is what my final telescope looks like.
Final Telescope
Final Telescope

Clear Skies While the telescope was ready, the skies were not. For almost next 10 days, we had no clear skies at all. All I could do was wait. Wait so much that I had forgotten to check on the skies. Luckily, my wife noticed clear skies this week for a single day. Clear enough that we could try out our telescope for the very first time.
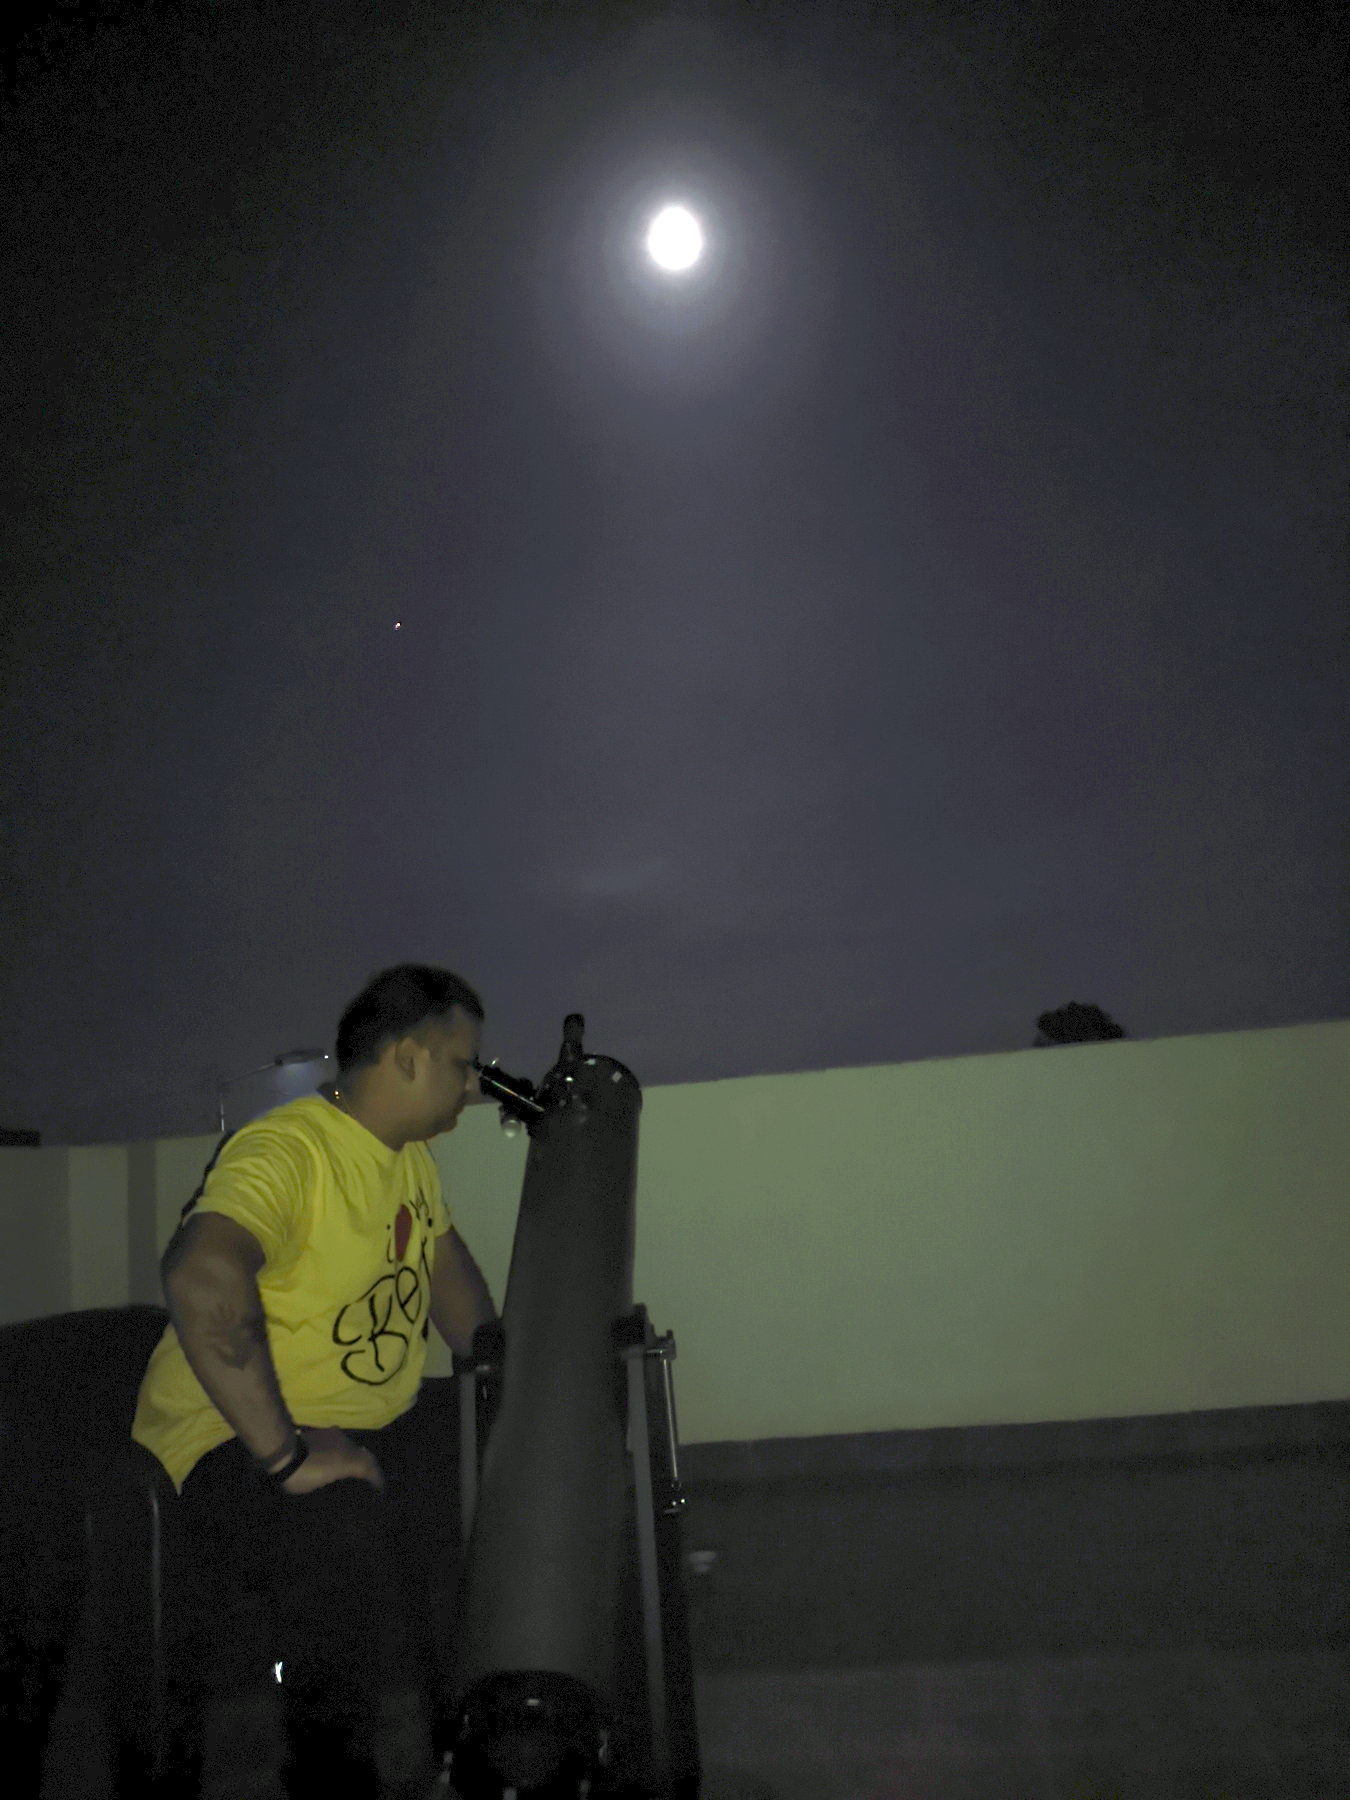
Me posing for a shot

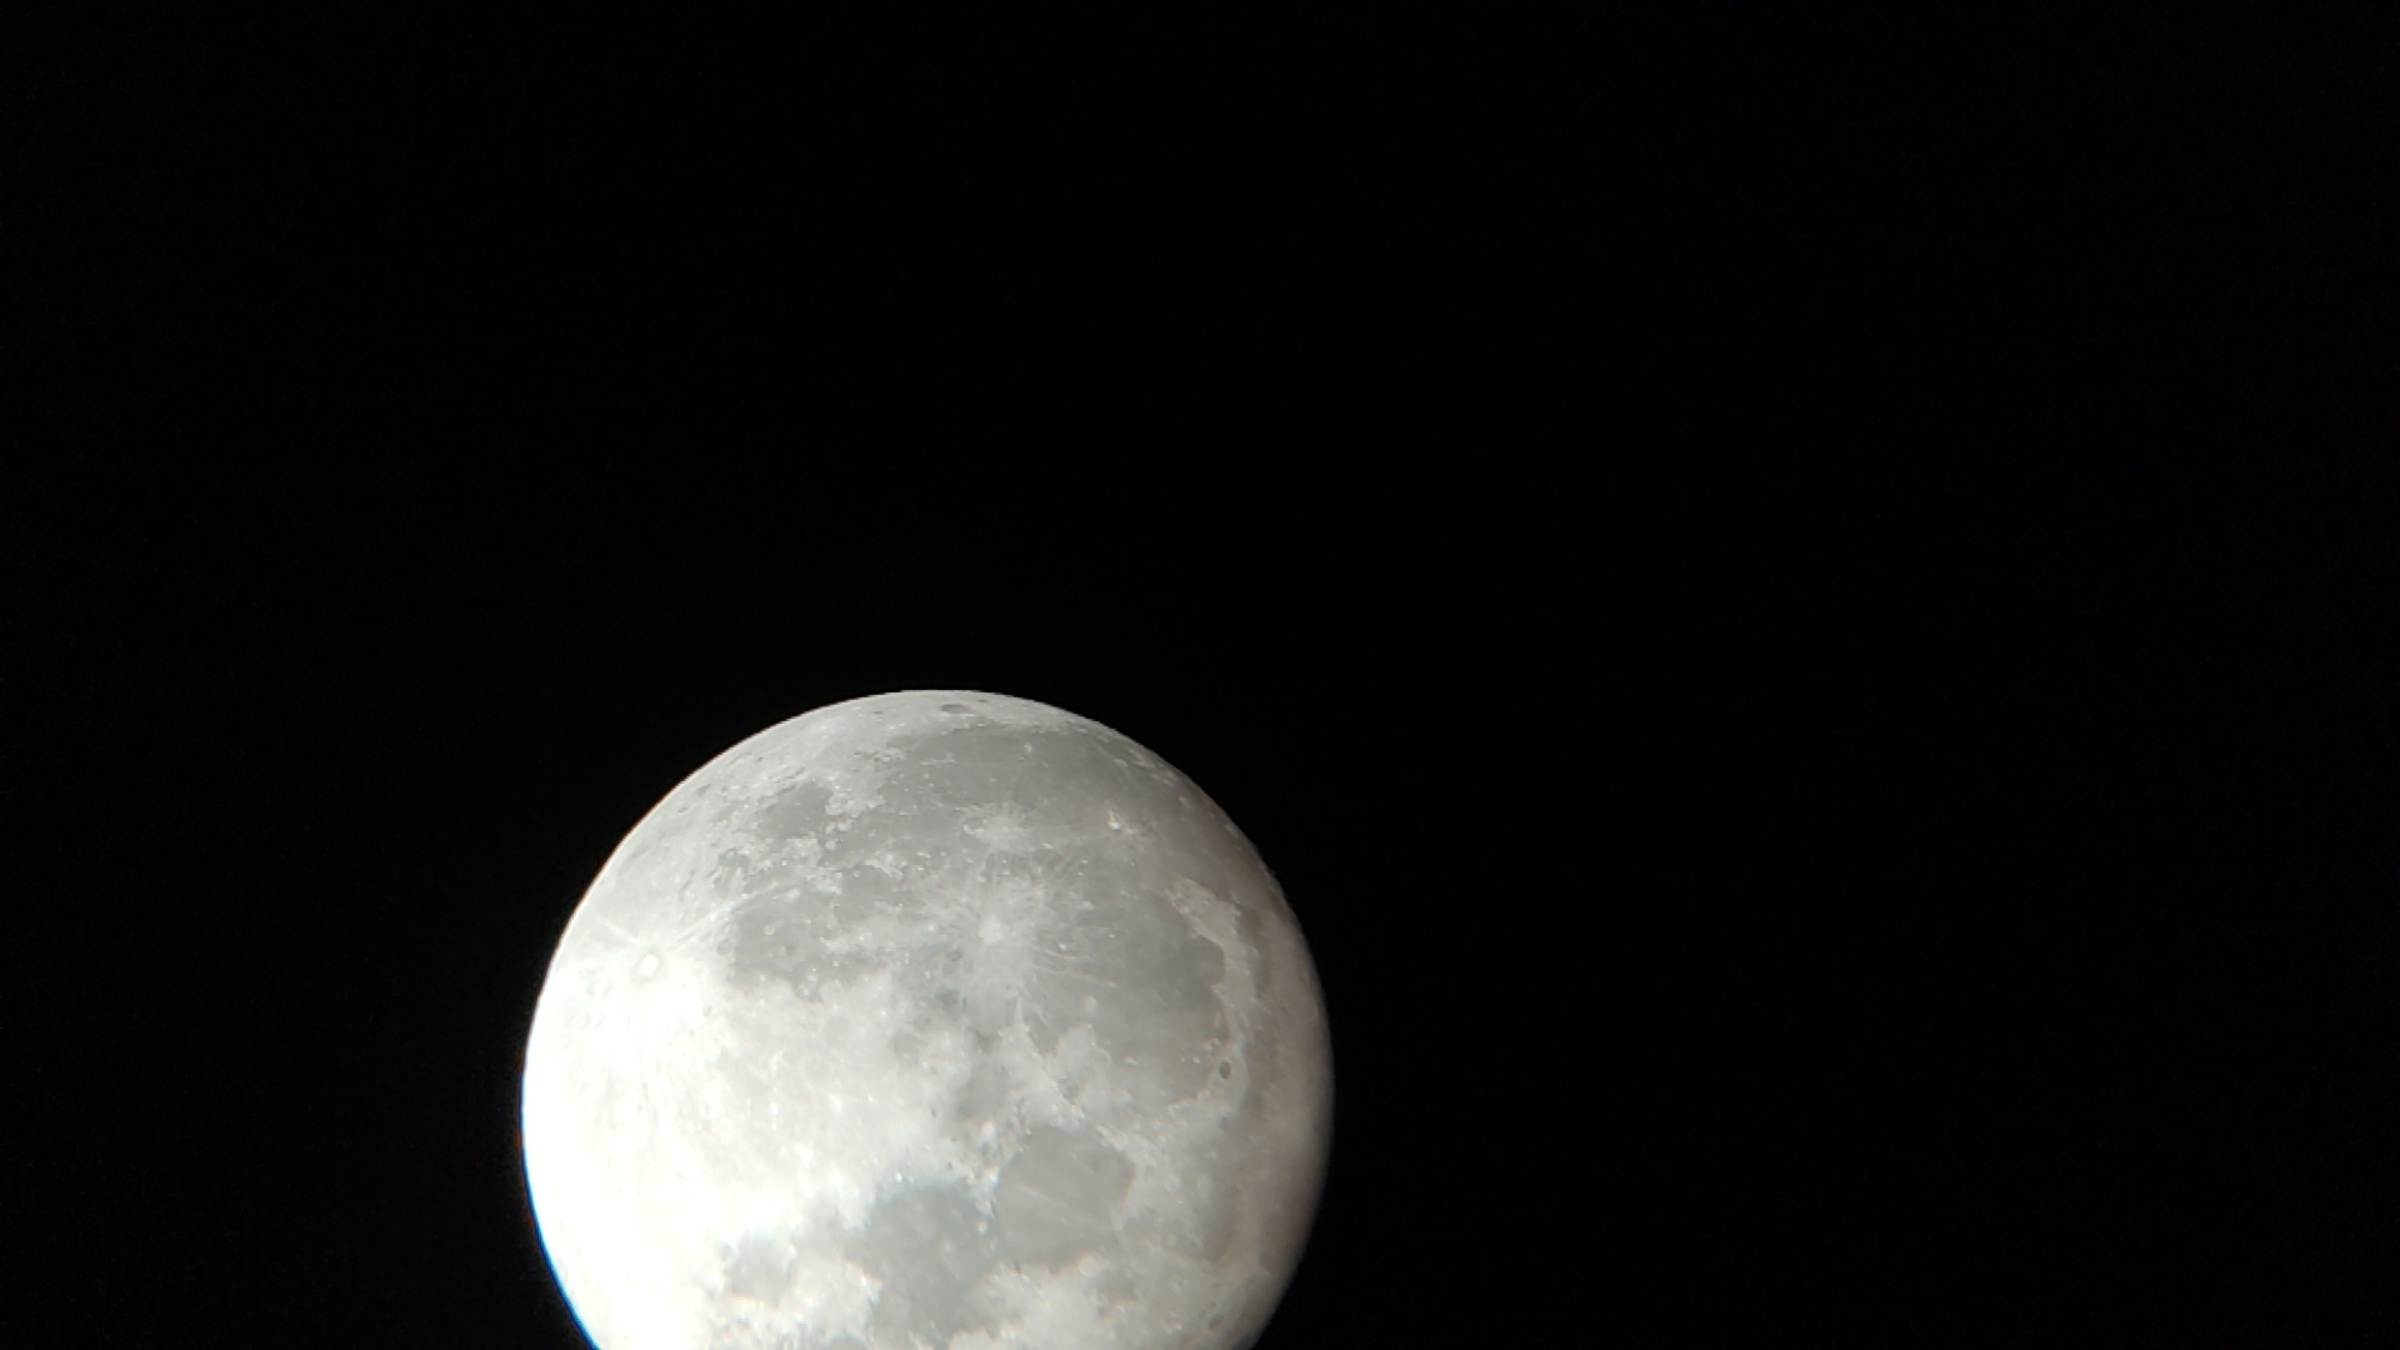
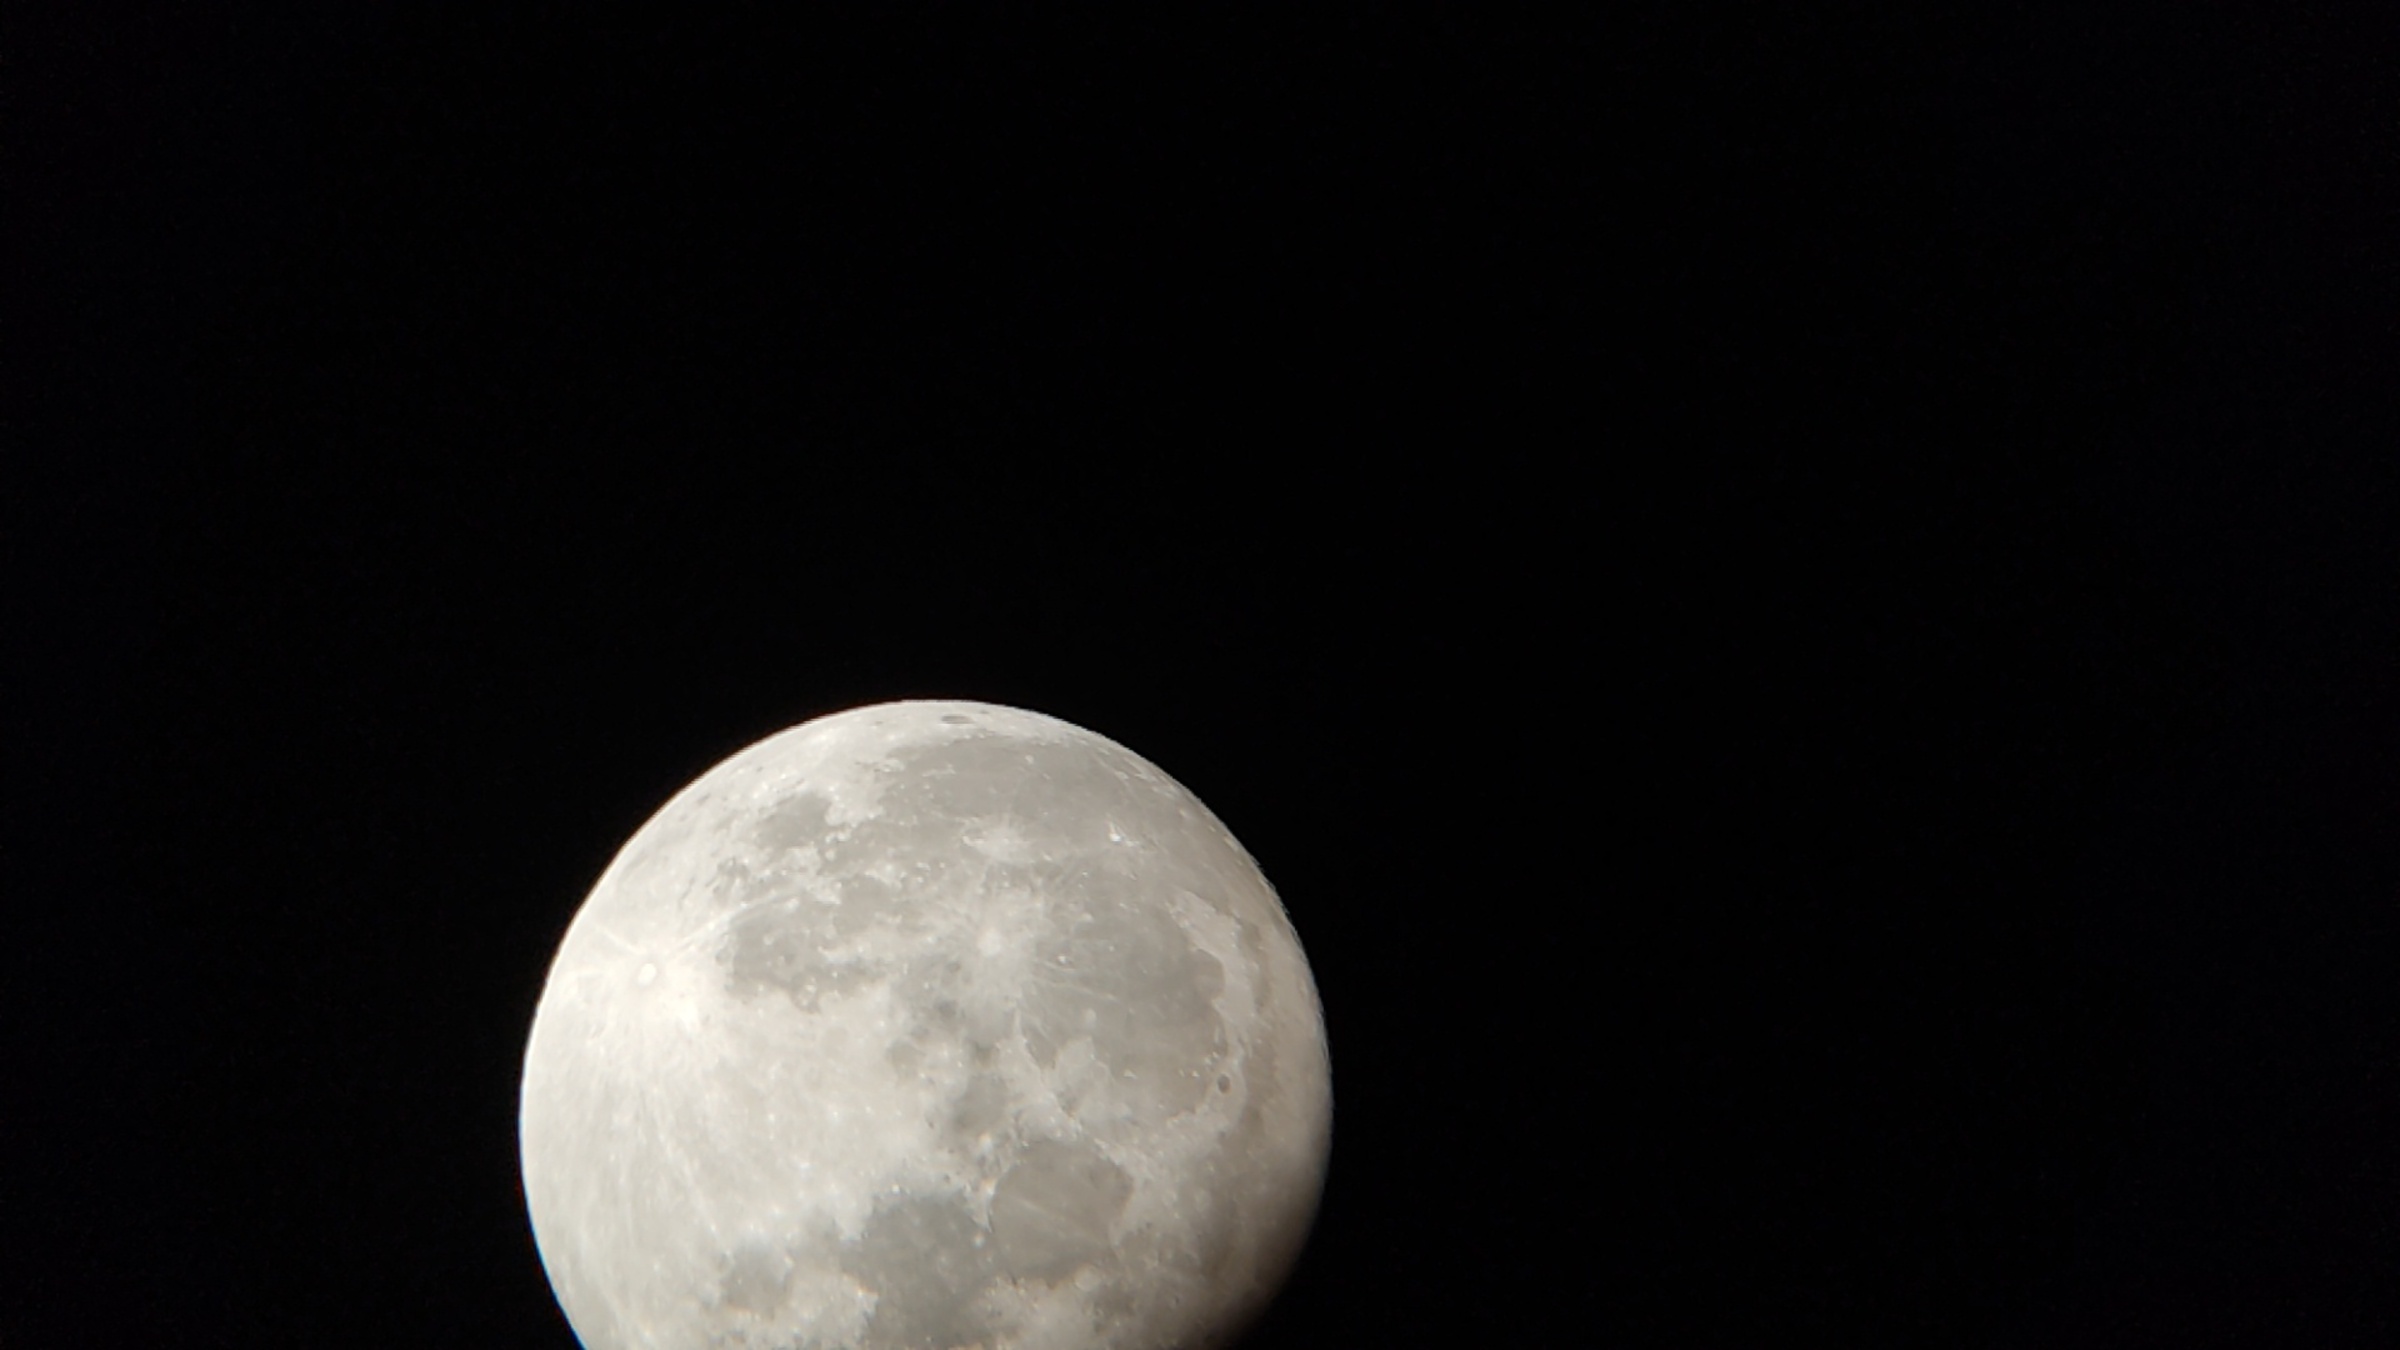
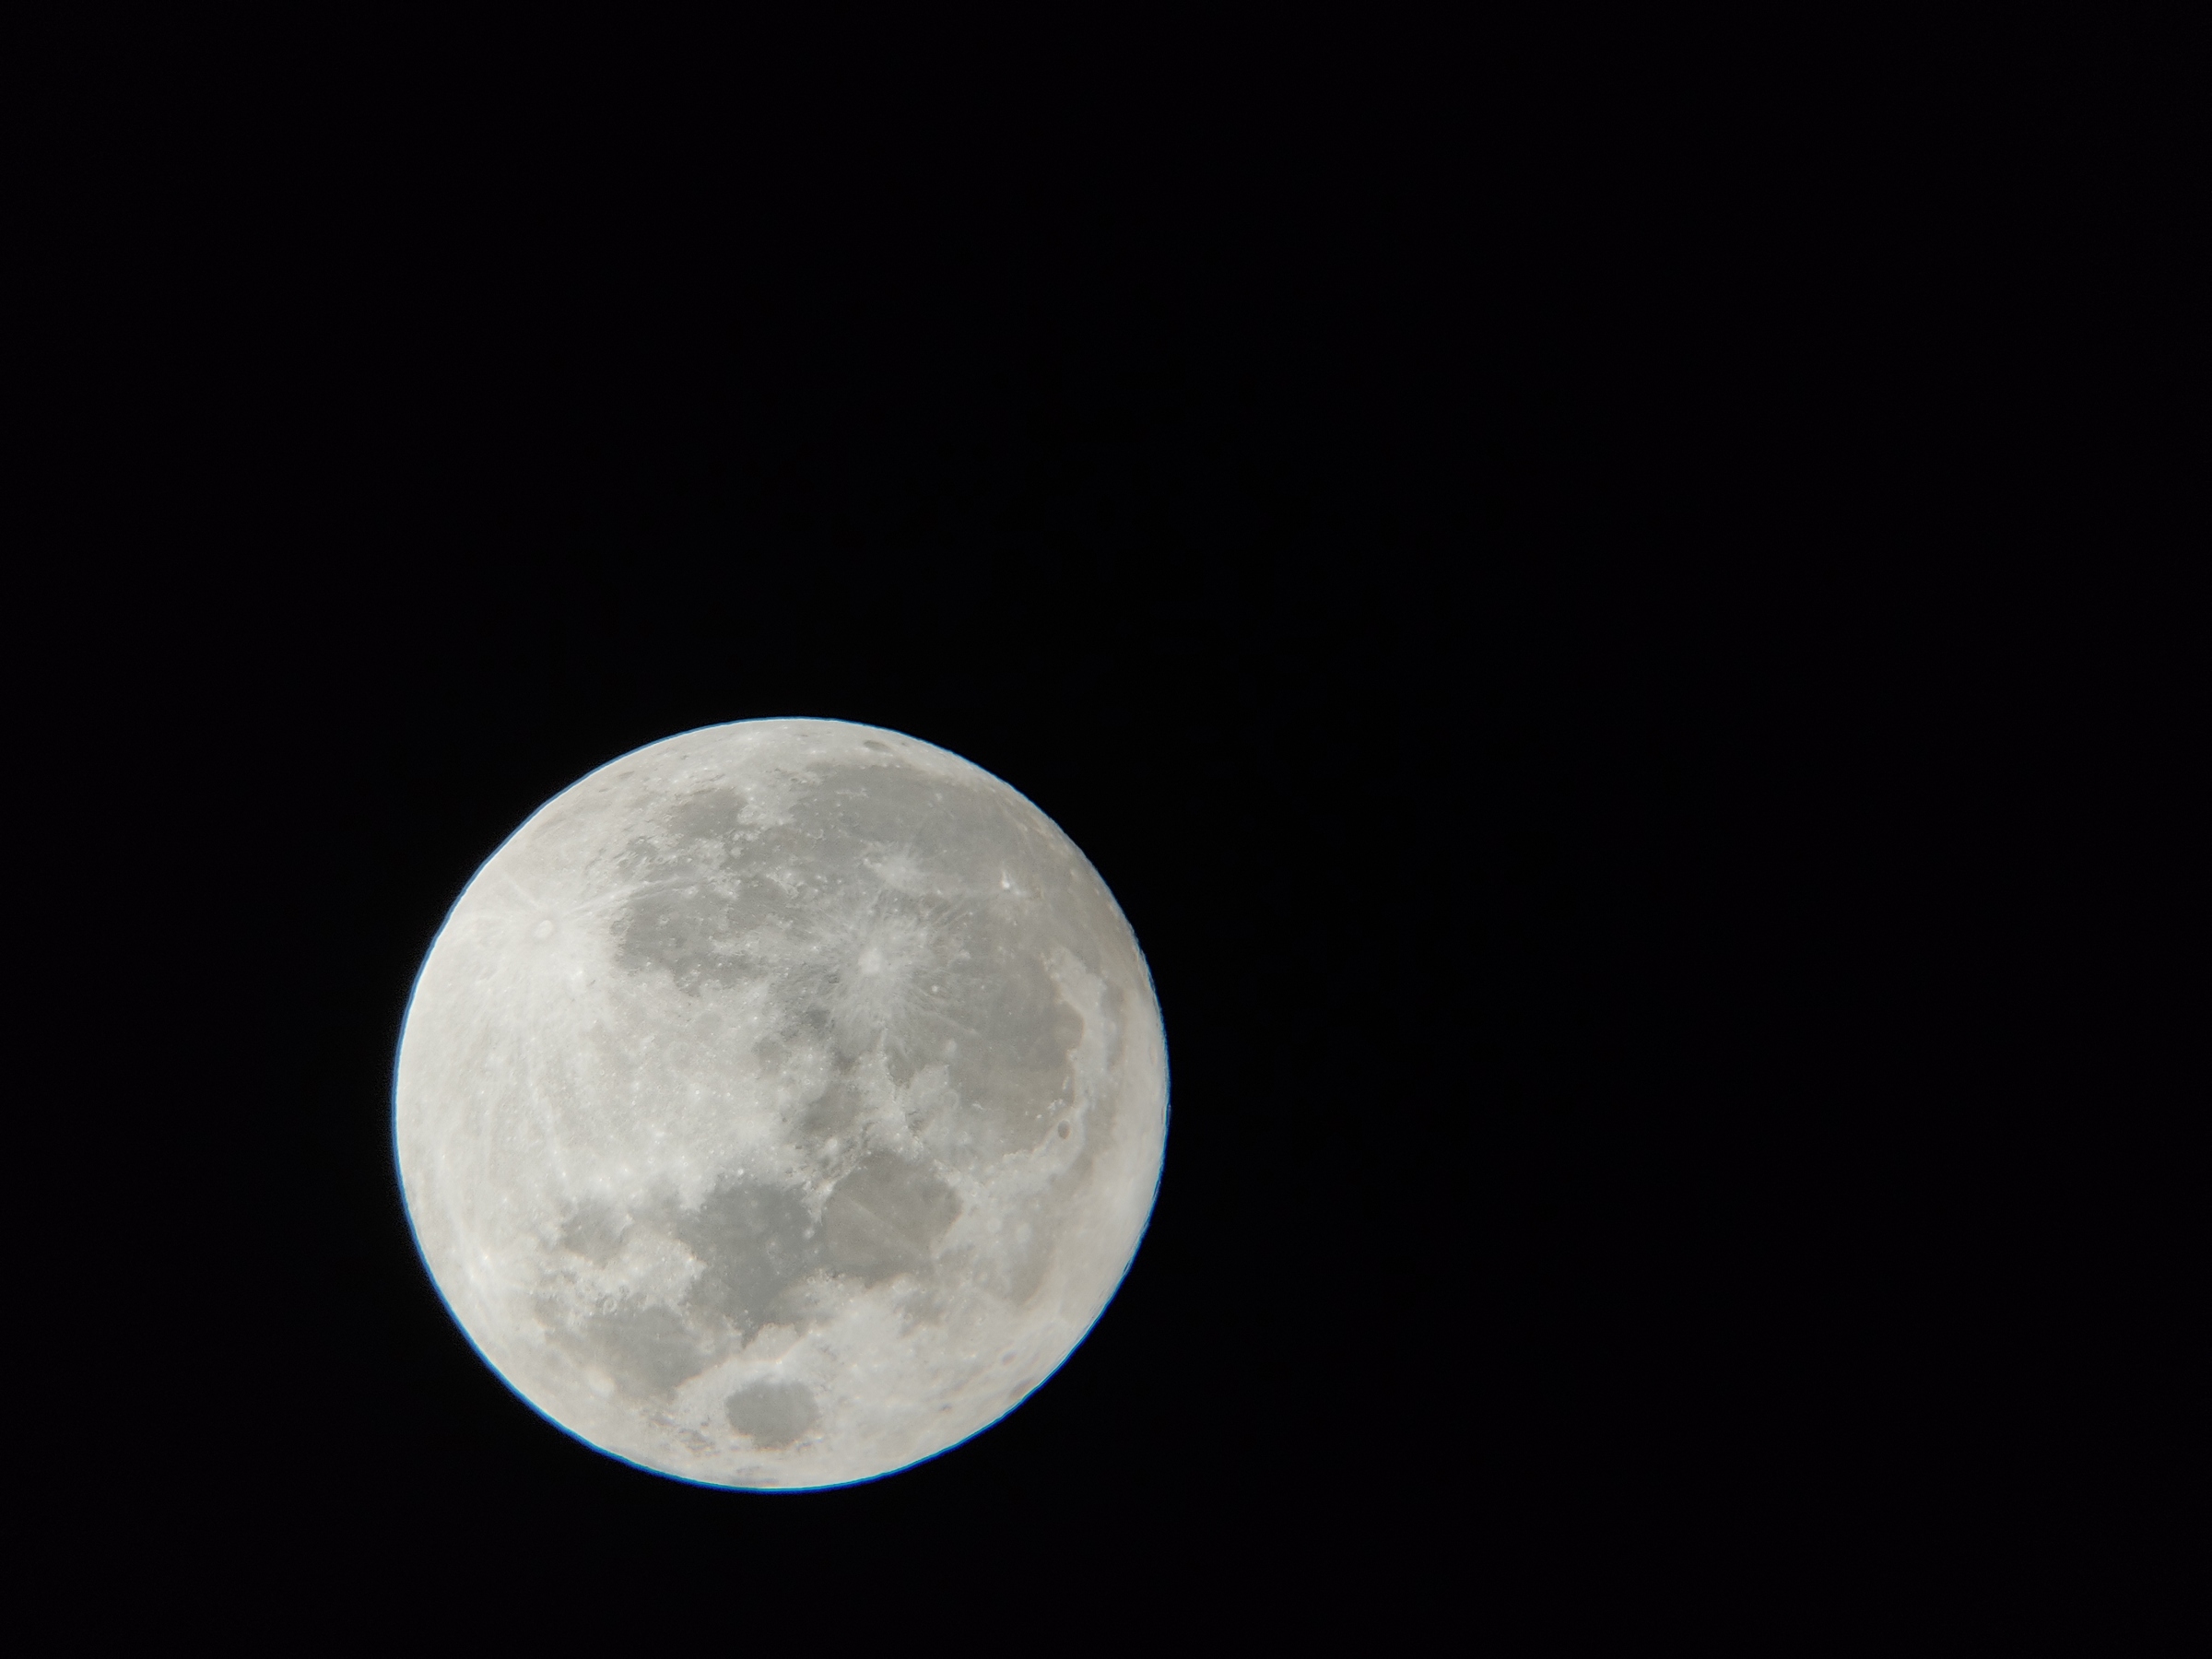
Telescope As I said earlier, in my opinion, it takes a lot of patience and perseverance on this subject. And most of the things here are DIY. To start with, we targeted the Moon. Because it is easy. I pointed the scope to the moon, then looked into the finder scope to center it, and then looked through the eyepiece. And blank. Nothing out there. Turns out, the finder scope and the viewer s angle weren t aligned. This is common and the first DIY step, when you plan to use your telescope for viewing. Since our first attempt was unplanned and just random because we luckily spotted that the skies were clear, we weren t prepared for this. Lucky enough, mapping the difference in the alignment, in the head, is not very difficult. After a couple of minutes, I could make out the point in the finder scope, where the object if projected, would show proper in the viewer. With that done, it was just mesmerizing to see the Moon, in a bit more detail, than what I ve seen all these years of my life.
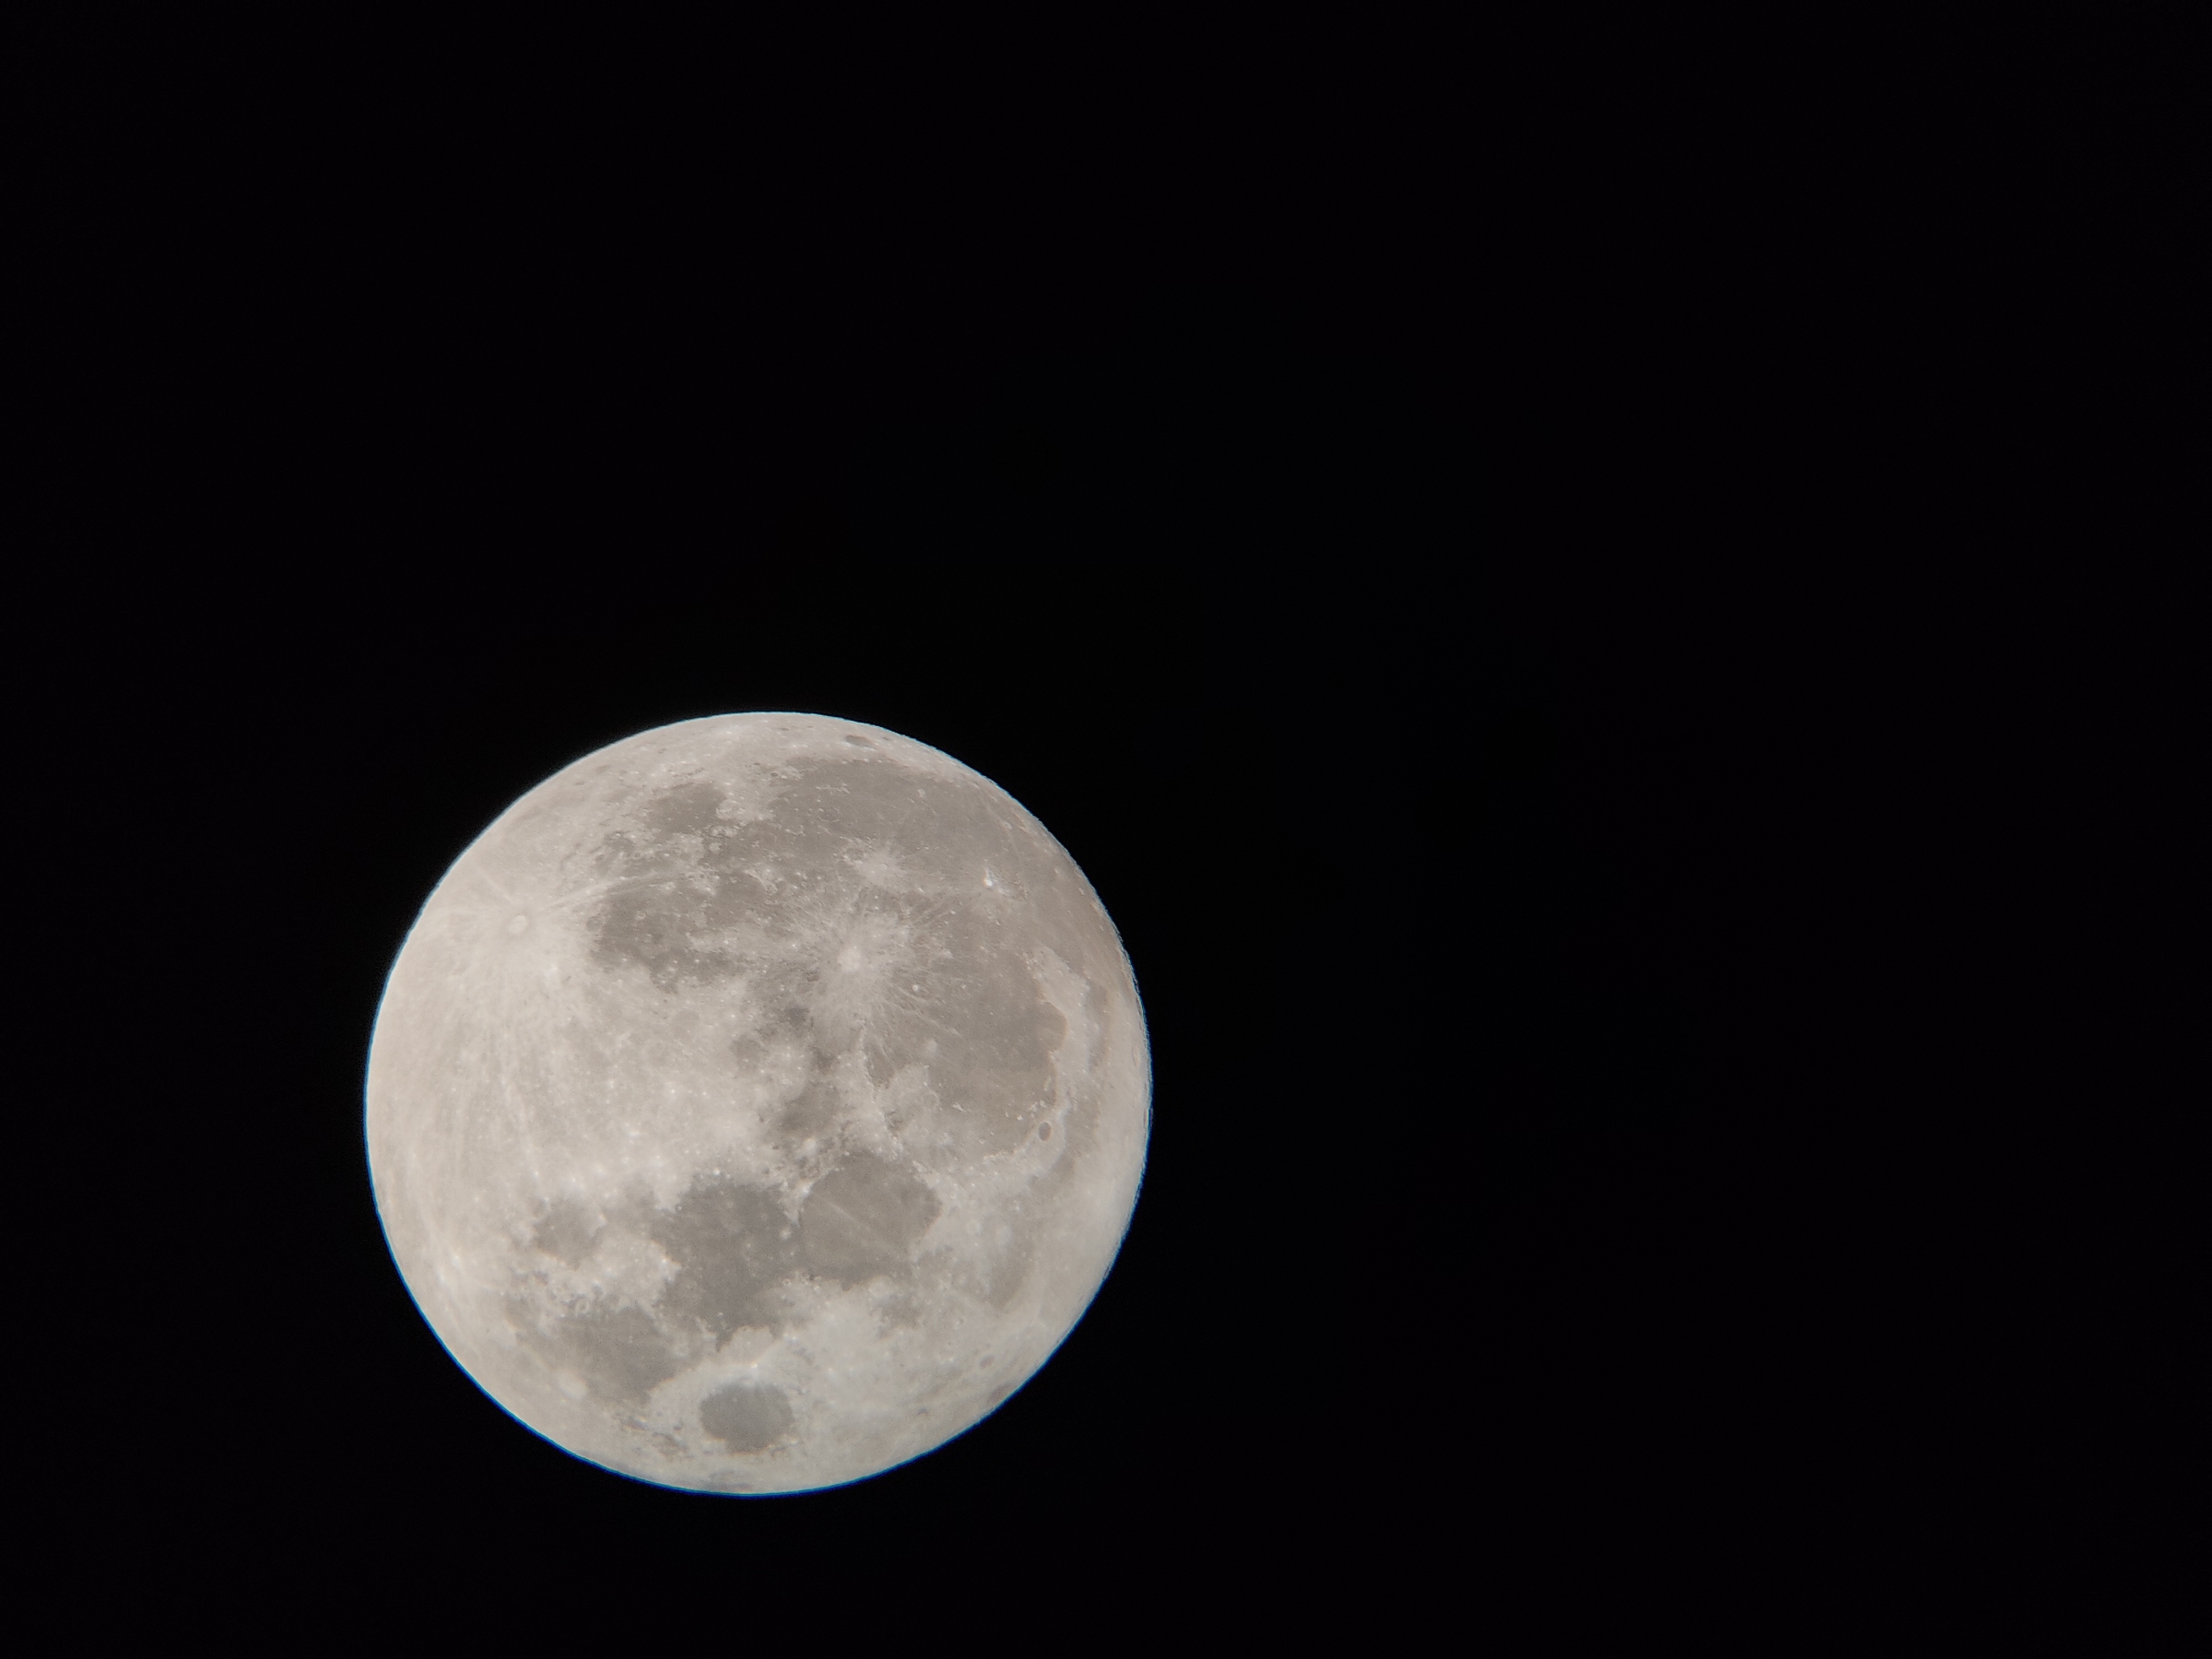
Moon
Moon
Moon
Moon
Moon
Moon
Moon
Moon
The images are not exactly what we saw with our eyes. The view was much more vivid than these pictures. But as a first timer, I really wanted to capture this first moment of a closer view of the Moon. In the whole process; that of ground work studying about telescopes, installation of the telescope, astronomy basics and many other things; the most difficult part in this entire journey, was to point my phone to the viewing eyepiece, to get a shot of the object. This requirement just introduced me to astrophotography. And then, Dobsonians aren t the best model for astrophotography, to what I ve learnt so far. Hopefully, I ll find my ways to do some DIY astrophotography with the tools I have. Or extend my arsenal over time. But overall, we ve been very pleased with the subject of Astronomy. It is a different feel altogether and we re glad to have forayed into it.

2 October 2020

Ian Jackson: Mailman vs DKIM - a novel solution

tl;dr: Do not configure Mailman to replace the mail domains in From: headers. Instead, try out my small new program which can make your Mailman transparent, so that DKIM signatures survive. Background and narrative DKIM NB: This explanation is going to be somewhat simplified. I am going to gloss over some details and make some slightly approximate statements. DKIM is a new anti-spoofing mechanism for Internet email, intended to help fight spam. DKIM, paired with the DMARC policy system, has been remarkably successful at stemming the flood of joe-job spams. As usually deployed, DKIM works like this: When a message is originally sent, the author's MUA sends it to the MTA for their From: domain for outward delivery. The From: domain mailserver calculates a cryptographic signature of the message, and puts the signature in the headers of the message. Obviously not the whole message can be signed, since at the very least additional headers need to be added in transit, and sometimes headers need to be modified too. The signing MTA gets to decide what parts of the message are covered by the signature: they nominate the header fields that are covered by the signature, and specify how to handle the body. A recipient MTA looks up the public key for the From: domain in the DNS, and checks the signature. If the signature doesn't match, depending on policy (originator's policy, in the DNS, and recipient's policy of course), typically the message will be treated as spam. The originating site has a lot of control over what happens in practice. They get to publish a formal (DMARC) policy in the DNS which advises recipients what they should do with mails claiming to be from their site. As mentioned, they can say which headers are covered by the signature - including the ability to sign the absence of a particular headers - so they can control which headers downstreams can get away with adding or modifying. And they can set a normalisation policy, which controls how precisely the message must match the one that they sent. Mailman Mailman is, of course, the extremely popular mailing list manager. There are a lot of things to like about it. I choose to run it myself not just because it's popular but also because it provides a relatively competent web UI and a relatively competent email (un)subscription interfaces, decent bounce handling, and a pretty good set of moderation and posting access controls. The Xen Project mailing lists also run on mailman. Recently we had some difficulties with messages sent by Citrix staff (including myself), to Xen mailing lists, being treated as spam. Recipient mail systems were saying the DKIM signatures were invalid. This was in fact true. Citrix has chosen a fairly strict DKIM policy; in particular, they have chosen "simple" normalisation - meaning that signed message headers must precisely match in syntax as well as in a semantic sense. Examining the the failing-DKIM messages showed that this was definitely a factor. Applying my Opinions about email My Bayesian priors tend to suggest that a mail problem involving corporate email is the fault of the corporate email. However in this case that doesn't seem true to me. My starting point is that I think mail systems should not not modify messages unnecessarily. None of the DKIM-breaking modifications made by Mailman seemed necessary to me. I have on previous occasions gone to corporate IT and requested quite firmly that things I felt were broken should be changed. But it seemed wrong to go to corporate IT and ask them to change their published DKIM/DMARC policy to accomodate a behaviour in Mailman which I didn't agree with myself. I felt that instead I shoud put (with my Xen Project hat on) my own house in order. Getting Mailman not to modify messages So, I needed our Mailman to stop modifying the headers. I needed it to not even reformat them. A brief look at the source code to Mailman showed that this was not going to be so easy. Mailman has a lot of features whose very purpose is to modify messages. Personally, as I say, I don't much like these features. I think the subject line tags, CC list manipulations, and so on, are a nuisance and not really Proper. But they are definitely part of why Mailman has become so popular and I can definitely see why the Mailman authors have done things this way. But these features mean Mailman has to disassemble incoming messages, and then reassemble them again on output. It is very difficult to do that and still faithfully reassemble the original headers byte-for-byte in the case where nothing actually wanted to modify them. There are existing bug reports[1] [2] [3] [4]; I can see why they are still open. Rejected approach: From:-mangling This situation is hardly unique to the Xen lists. Many other have struggled with it. The best that seems to have been come up with so far is to turn on a new Mailman feature which rewrites the From: header of the messages that go through it, to contain the list's domain name instead of the originator's. I think this is really pretty nasty. It breaks normal use of email, such as reply-to-author. It is having Mailman do additional mangling of the message in order to solve the problems caused by other undesirable manglings! Solution! As you can see, I asked myself: I want Mailman not modify messages at all; how can I get it to do that? Given the existing structure of Mailman - with a lot of message-modifying functionality - that would really mean adding a bypass mode. It would have to spot, presumably depending on config settings, that messages were not to be edited; and then, it would avoid disassembling and reassembling the message at at all, and bypass the message modification stages. The message would still have to be parsed of course - it's just that the copy send out ought to be pretty much the incoming message. When I put it to myself like that I had a thought: couldn't I implement this outside Mailman? What if I took a copy of every incoming message, and then post-process Mailman's output to restore the original? It turns out that this is quite easy and works rather well! outflank-mailman outflank-mailman is a 233-line script, plus documentation, installation instructions, etc. It is designed to run from your MTA, on all messages going into, and coming from, Mailman. On input, it saves a copy of the message in a sqlite database, and leaves a note in a new Outflank-Mailman-Id header. On output, it does some checks, finds the original message, and then combines the original incoming message with carefully-selected headers from the version that Mailman decided should be sent. This was deployed for the Xen Project lists on Tuesday morning and it seems to be working well so far. If you administer Mailman lists, and fancy some new software to address this problem, please do try it out. Matters arising - Mail filtering, DKIM Overall I think DKIM is a helpful contribution to the fight against spam (unlike SPF, which is fundamentally misdirected and also broken). Spam is an extremely serious problem; most receiving mail servers experience more attempts to deliver spam than real mail, by orders of magnitude. But DKIM is not without downsides. Inherent in the design of anything like DKIM is that arbitrary modification of messages by list servers is no longer possible. In principle it might be possible to design a system which tolerated modifications reasonable for mailing lists but it would be quite complicated and have to somehow not tolerate similar modifications in other contexts. So DKIM means that lists can no longer add those unsubscribe footers to mailing list messages. The "new way" (RFC2369, July 1998), to do this is with the List-Unsubscribe header. Hopefully a good MUA will be able to deal with unsubscription semiautomatically, and I think by now an adequate MUA should at least display these headers by default. Sender: There are implications for recipient-side filtering too. The "traditional" correct way to spot mailing list mail was to look for Resent-To:, which can be added without breaking DKIM; the "new" (RFC2919, March 2001) correct way is List-Id:, likewise fine. But during the initial deployment of outflank-mailman I discovered that many subscribers were detecting that a message was list traffic by looking at the Sender: header. I'm told that some mail systems (apparently Microsoft's included) make it inconvenient to filter on List-Id. Really, I think a mailing list ought not to be modifying Sender:. Given Sender:'s original definition and semantics, there might well be reasonable reasons for a mailing list posting to have different From: and and then the original Sender: ought not to be lost. And a mailing list's operation does not fit well into the original definition of Sender:. I suspect that list software likes to put in Sender mostly for historical reasons; notably, a long time ago it was not uncommon for broken mail systems to send bounces to the Sender: header rather than the envelope sender (SMTP MAIL FROM). DKIM makes this more of a problem. Unfortunately the DKIM specifications are vague about what headers one should sign, but they pretty much definitely include Sender: if it is present, and some materials encourage signing the absence of Sender:. The latter is Exim's default configuration when DKIM-signing is enabled. Franky there seems little excuse for systems to not readily support and encourage filtering on List-Id, 20 years later, but I don't want to make life hard for my users. For now we are running a compromise configuration: if there wasn't a Sender: in the original, take Mailman's added one. This will result in (i) misfiltering for some messages whose poster put in a Sender:, and (ii) DKIM failures for messages whose originating system signed the absence of a Sender:. I'm going to mine the db for some stats after it's been deployed for a week or so, to see which of these problems is worst and decide what to do about it. Mail routing For DKIM to work, messages being sent From: a particular mail domain must go through a system trusted by that domain, so they can be signed. Most users tend to do this anyway: their mail provider gives them an IMAP server and an authenticated SMTP submission server, and they configure those details in their MUA. The MUA has a notion of "accounts" and according to the user's selection for an outgoing message, connects to the authenticated submission service (usually using TLS over the global internet). Trad unix systems where messages are sent using the local sendmail or localhost SMTP submission (perhaps by automated systems, or perhaps by human users) are fine too. The smarthost can do the DKIM signing. But this solution is awkward for a user of a trad MUA in what I'll call "alias account" setups: where a user has an address at a mail domain belonging to different people to the system on which they run their MUA (perhaps even several such aliases for different hats). Traditionally this worked by the mail domain forwarding incoming the mail, and the user simply self-declaring their identity at the alias domain. Without DKIM there is nothing stopping anyone self-declaring their own From: line. If DKIM is to be enabled for such a user (preventing people forging mail as that user), the user will have to somehow arrange that their trad unix MUA's outbound mail stream goes via their mail alias provider. For a single-user sending unix system this can be done with tolerably complex configuration in an MTA like Exim. For shared systems this gets more awkward and might require some hairy shell scripting etc.
edited 2020-10-01 21:22 and 21:35 and -02 10:50 +0100 to fix typos and 21:28 to linkify "my small program" in the tl;dr


comment count unavailable comments

1 October 2020

Sylvain Beucler: Debian LTS and ELTS - September 2020

Debian LTS Logo Here is my transparent report for my work on the Debian Long Term Support (LTS) and Debian Extended Long Term Support (ELTS), which extend the security support for past Debian releases, as a paid contributor. In September, the monthly sponsored hours were split evenly among contributors depending on their max availability - I was assigned 19.75h for LTS (out of my 30 max; all done) and 20h for ELTS (out of my 20 max; all done). ELTS - Jessie LTS - Stretch Documentation/Scripts

Molly de Blanc: Free Software Activities September 2020

I haven t done one of these in a while, so let s see how it goes.

Debian The Community Team has been busy. We re planning a sprint to work on a bigger writing project and have some tough discussions that need to happen.
I personally have only worked on one incident, but we ve had a few others come in.
I m attempting to step down from the Outreach team, which is more work than I thought it would be. I had a very complicated relationship with the Outreach team. When no one else was there to take on making sure we did GSoC and Outreachy, I stepped up. It wasn t really what I wanted to be doing, but it s important. I m glad to have more time to focus on other things that feel more aligned with what I m trying to work on right now.

GNOME In addition to, you know, work, I joined the Code of Conduct Committee. Always a good time! Rosanna and I presented at GNOME Onboard Africa Virtual about the GNOME CoC. It was super fun!

Digital Autonomy Karen and I did an interview on FLOSS Weekly with Doc Searls and Dan Lynch. Super fun! I ve been doing some more writing, which I still hope to publish soon, and a lot of organization on it. I m also in the process of investigating some funding, as there are a few things we d like to do that come with price tags. Separately, I started working on a video to explain the Principles. I m excited!

Misc I started a call that meets every other week where we talk about Code of Conduct stuff. Good peeps. Into it.

Russ Allbery: Review: Harrow the Ninth

Review: Harrow the Ninth, by Tamsyn Muir
Series: The Locked Tomb #2
Publisher: Tor
Copyright: 2020
ISBN: 1-250-31320-1
Format: Kindle
Pages: 510
Harrow the Ninth is a direct sequel to Gideon the Ninth and under absolutely no circumstances should you start reading here. You would be so lost. If you plan on reading this series, read the books as closely together as you can so that you can remember the details of the previous book. You may still resort to re-reading or searching through parts of the previous book as you go. Muir is doing some complex structural work with Harrow the Ninth, so it's hard to know how much to say about it without spoiling some aspect of it for someone. I think it's safe to say this much: As advertised by the title, we do get a protagonist switch to Harrowhark. However, unlike Gideon the Ninth, it's not a single linear story. The storyline that picks up after the conclusion of Gideon is interwoven with apparent flashbacks retelling the story of the previous book from Harrowhark's perspective. Or at least it might have been the story of the previous book, except that Ortus is Harrowhark's cavalier, Gideon does not appear, and other divergences from the story we previously read become obvious early on. (You can see why memory of Gideon the Ninth is important.) Oh, and one of those storylines is written in the second person. Unlike some books that use this as a gimmick, this is for reasons that are eventually justified and partly explained in the story, but it's another example of the narrative complexity. Harrow the Ninth is dropping a lot of clues (and later revelations) in both story events and story structure, many of which are likely to upend reader expectations from the first book. I have rarely read a novel that is this good at fulfilling the tricky role of the second book of a trilogy. Gideon the Ninth was, at least on the surface, a highly entertaining, linear, and relatively straightforward escape room mystery, set against a dying-world SF background that was more hinted at than fleshed out. Harrow the Ninth revisits and reinterprets that book in ways that add significant depth without feeling artificial. Bits of scenery in the first book take on new meaning and intention. Characters we saw only in passing get a much larger role (and Abigail is worth the wait). And we get a whole ton of answers: about the God Emperor, about Lyctors, about the world, about Gideon and Harrowhark's own pasts and backgrounds, and about the locked tomb that is at the center of the Ninth House. But there is still more than enough for a third book, including a truly intriguing triple cliffhanger ending. Harrow the Ninth is both satisfying in its own right and raises new questions that I'm desperate to see answered in the third book. Also, to respond to my earlier self on setting, this world is not a Warhammer 40K universe, no matter how much it may have appeared in the glimpses we got in Gideon. The God Emperor appears directly in this book and was not at all what I was expecting, if perhaps even more disturbing. Muir is intentionally playing against type, drawing a sharp contrast between the God Emperor and the dramatic goth feel of the rest of the universe and many of the characters, and it's creepily effective and goes in a much different ethical direction than I had thought. (That said, I will warn that properly untangling the ethical dilemmas of this universe is clearly left to the third book.) I mentioned in my review of Gideon the Ninth that I was happy to see more SF pulling unapologetically from fanfic. I'm going to keep beating that drum in this review in part because I think the influence may be less obvious to the uninitiated. Harrow the Ninth is playing with voice, structure, memory, and chronology in ways that I suspect the average reader unfamiliar with fanfic may associate more with literary fiction, but they would be wrongly underestimating fanfic if they did so. If anything, the callouts to fanfic are even clearer. There are three classic fanfic alternate universe premises that appear in passing, the story relies on the reader's ability to hold a canonical narrative and an alternate narrative in mind simultaneously, and the genre inspiration was obvious enough to me that about halfway through the novel I correctly guessed one of the fanfic universes in which Muir has written. (I'm not naming it here since I think it's a bit of a spoiler.) And of course there's the irreverence. There are some structural reasons why the narrative voice isn't quite as good as Gideon the Ninth at the start, but rest assured that Muir makes up for that by the end of the book. My favorite scenes in the series so far happen at the end of Harrow the Ninth: world-building, revelations, crunchy metaphysics, and irreverent snark all woven beautifully together. Muir has her characters use Internet meme references like teenagers, which is a beautiful bit of characterization because they are teenagers. In a world that's heavy on viscera, skeletons, death, and horrific monsters, it's a much needed contrast and a central part of how the characters show defiance and courage. I don't think this will work for everyone, but it very much works for me. There's a Twitter meme reference late in the book that had me laughing out loud in delight. Harrow the Ninth is an almost perfect second book, in that if you liked Gideon the Ninth, you will probably love Harrow the Ninth and it will make you like Gideon the Ninth even more. It does have one major flaw, though: pacing. This was also my major complaint about Gideon, primarily around the ending. I think Harrow the Ninth is a bit better, but the problem has a different shape. The start of the book is a strong "what the hell is going on" experience, which is very effective, and the revelations are worth the build-up once they start happening. In between, though, the story drags on a bit too long. Harrow is sick and nauseated at the start of the book for rather longer than I wanted to read about, there is one too many Lyctor banquets than I think were necessary to establish the characters, and I think there's a touch too much wandering the halls. Muir also interwove two narrative threads and tried to bring them to a conclusion at the same time, but I think she had more material for one than the other. There are moments near the end of the book where one thread is producing all the payoff revelations the reader has been waiting for, and the other thread is following another interminable and rather uninteresting fight scene. You don't want your reader saying "argh, no" each time you cut away to the other scene. It's better than Gideon the Ninth, where the last fifth of the book is mostly a running battle that went on way longer than it needed to, but I still wish Muir had tightened the story throughout and balanced the two threads so that we could stay with the most interesting one when it mattered. That said, I mostly noticed the pacing issues in retrospect and in talking about them with a friend who was more annoyed than I was. In the moment, there was so much going on here, so many new things to think about, and so much added depth that I devoured Harrow the Ninth over the course of two days and then spent the next day talking to other people who had read it, trading theories about what happened and what will happen in the third book. It was the most enjoyable reading experience I've had so far this year. Gideon the Ninth was fun; Harrow the Ninth was both fun and on the verge of turning this series into something truly great. I can hardly wait for Alecto the Ninth (which doesn't yet have a release date, argh). As with Gideon the Ninth, content warning for lots and lots of gore, rather too detailed descriptions of people's skeletons, restructuring bits of the body that shouldn't be restructured, and more about bone than you ever wanted to know. Rating: 9 out of 10

Norbert Preining: Plasma 5.20 coming to Debian

The KDE Plasma desktop is soon getting an update to 5.20, and beta versions are out for testing.
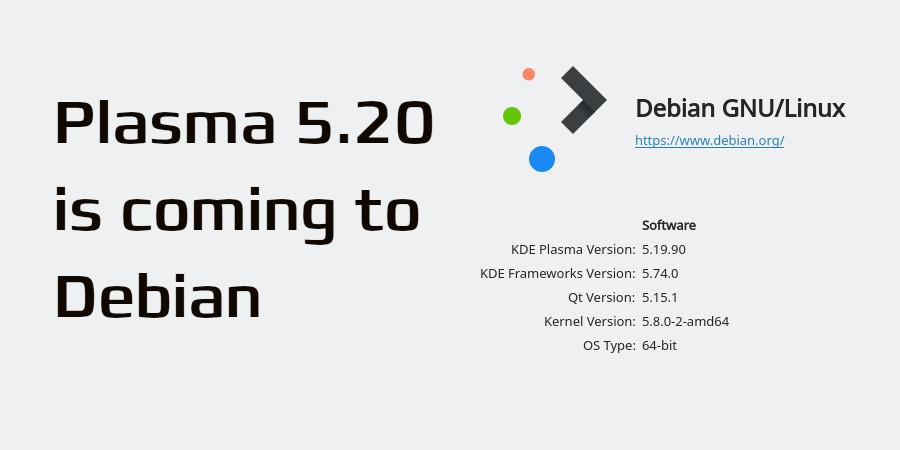
Plasma 5.20 is going to be one absolutely massive release! More features, more fixes for longstanding bugs, more improvements to the user interface!
There are lots of new features mentioned in the release announcement, I like in particular the ability that settings changed from the default can now be highlighted.
I have been providing builds of KDE related packages since quite some time now, see everything posted under the KDE tag. In the last days I have prepared Debian packages for Plasma 5.19.90 on OBS, for now only targeting Debian/experimental and amd64 architecture. These packages require Qt 5.15, which is only available in the experimental suite, and there is no way to simply update to Qt 5.15 since all Qt related packages need to be recompiled. So as long as Qt 5.15 doesn t hit unstable, I cannot really run these packages on my main machine, but I tried a clean Debian virtual machine installing only Plasma 5.19.90 and depending packages, plus some more for a pleasant desktop experience. This worked out quite well, the VM runs Plasma 5.19.90. Well, bottom line, as soon as we have Qt 5.15 in Debian/unstable, we are also ready for Plasma 5.20!

Jonathan Carter: Free Software Activities for 2020-09

This month I started working on ways to make hosting access easier for Debian Developers. I also did some work and planning for the MiniDebConf Online Gaming Edition that we ll likely announce within the next 1-2 days. Just a bunch of content that needs to be fixed and a registration bug then I think we ll be ready to send out the call for proposals. In the meantime, here s my package uploads and sponsoring for September: 2020-09-07: Upload package calamares (3.2.30-1) to Debian unstable. 2020-09-07: Upload package gnome-shell-extension-dash-to-panel (39-1) to Debian unstable. 2020-09-08: Upload package gnome-shell-extension-draw-on-your-screen (6.2-1) to Debian unstable. 2020-09-08: Sponsor package sqlobject (3.8.0+dfsg-2) for Debian unstable (Python team request). 2020-09-08: Sponsor package bidict (0.21.0-1) for Debian unstable (Python team request). 2020-09-11: Upload package catimg (2.7.0-1) to Debian unstable. 2020-09-16: Sponsor package gamemode (1.6-1) for Debian unstable (Games team request). 2020-09-21: Sponsor package qosmic (1.6.0-3) for Debian unstable (Debian Mentors / e-mail request). 2020-09-22: Upload package gnome-shell-extension-draw-on-your-screen (6.4-1) to Debian unstable. 2020-09-22: Upload package bundlewrap (4.2.0-1) to Debian unstable. 2020-09-25: Upload package gnome-shell-extension-draw-on-your-screen (7-1) to Debian unstable. 2020-09-27: Sponsor package libapache2-mod-python (3.5.0-1) for Debian unstable (Python team request). 2020-09-27: Sponsor package subliminal (2.1.0-1) for Debian unstable (Python team request).

30 September 2020

Utkarsh Gupta: FOSS Activites in September 2020

Here s my (twelfth) monthly update about the activities I ve done in the F/L/OSS world.

Debian
This was my 21st month of contributing to Debian. I became a DM in late March last year and a DD last Christmas! \o/ I ve been busy with my undergraduation stuff but I still squeezed out some time for the regular Debian work. Here are the following things I did in Debian this month:

Uploads and bug fixes:

Other $things:
  • Attended the Debian Ruby team meeting. Logs here.
  • Mentoring for newcomers.
  • FTP Trainee reviewing.
  • Moderation of -project mailing list.
  • Sponsored trace-cmd for Sudip, ruby-asset-sync for Nilesh, and mariadb-mysql-kbs for William.

RuboCop::Packaging - Helping the Debian Ruby team! \o/ This Google Summer of Code, I worked on writing a linter that could flag offenses for lines of code that are very troublesome for Debian maintainers while trying to package and maintain Ruby libraries and applications! Whilst the GSoC period is over, I ve been working on improving that tool and have extended that linter to now auto-correct these offenses by itself! \o/
You can now just use the -A flag and you re done! Boom! The ultimate game-changer! Here s a quick demo for this feature: A few quick updates on RuboCop::Packaging: I ve also spent a considerable amount of time in raising awareness about this and in more general sense, about downstream maintenance.
As a result, I raised a bunch of PRs which got really good response. I got all of the 20 PRs merged upstream, fixing these issues.

Debian (E)LTS
Debian Long Term Support (LTS) is a project to extend the lifetime of all Debian stable releases to (at least) 5 years. Debian LTS is not handled by the Debian security team, but by a separate group of volunteers and companies interested in making it a success. And Debian Extended LTS (ELTS) is its sister project, extending support to the Jessie release (+2 years after LTS support). This was my twelfth month as a Debian LTS and third month as a Debian ELTS paid contributor.
I was assigned 19.75 hours for LTS and 15.00 hours for ELTS and worked on the following things:
(for LTS, I over-worked for 11 hours last month on the survey so only had 8.75 hours this month!)

LTS CVE Fixes and Announcements:

ELTS CVE Fixes and Announcements:
  • Issued ELA 274-1, fixing CVE-2020-11984, for uwsgi.
    For Debian 8 Jessie, these problems have been fixed in version 2.0.7-1+deb8u3.
  • Issued ELA 275-1, fixing CVE-2020-14363, for libx11.
    For Debian 8 Jessie, these problems have been fixed in version 2:1.6.2-3+deb8u4.
  • Issued ELA 278-1, fixing CVE-2020-8184, for ruby-rack.
    For Debian 8 Jessie, these problems have been fixed in version 1.5.2-3+deb8u4.
  • Also worked on updating the version of clamAV from v0.101.5 to v0.102.4.
    This was a bit tricky package to work on since it involved an ABI/API change and was more or less a transition. Super thanks to Emilio for his invaluable help and him taking over the package, finishing, and uploading it in the end.

Other (E)LTS Work:
  • Front-desk duty from 31-08 to 06-09 and from 28-09 onward for both LTS and ELTS.
  • Triaged apache2, cryptsetup, nasm, node-bl, plinth, qemu, rsync, ruby-doorkeeper, and uwsgi.
  • Marked CVE-2020-15094/symfony as not-affected for Stretch.
  • Marked CVE-2020- 9490,11993 /apache2 as ignored for Stretch.
  • Marked CVE-2020-8244/node-bl as no-dsa for Stretch.
  • Marked CVE-2020-24978/nasm as no-dsa for Stretch.
  • Marked CVE-2020-25073/plinth as no-dsa for Stretch.
  • Marked CVE-2020-15094/symfony as not-affected for Jessie.
  • Marked CVE-2020-14382/cryptsetup as not-affected for Jessie.
  • Marked CVE-2020-14387/rsync as not-affected for Jessie.
  • Auto EOL ed ark, collabtive, linux, nasm, node-bl, and thunderbird for Jessie.
  • Use mktemp instead of tempfile in bin/auto-add-end-of-life.sh.
  • Attended the fifth LTS meeting. Logs here.
  • General discussion on LTS private and public mailing list.

Until next time.
:wq for today.

Chris Lamb: Free software activities in September 2020

Here is my monthly update covering what I have been doing in the free software world during September 2020 (previous month):

Reproducible Builds One of the original promises of open source software is that distributed peer review and transparency of process results in enhanced end-user security. However, whilst anyone may inspect the source code of free and open source software for malicious flaws, almost all software today is distributed as pre-compiled binaries. This allows nefarious third-parties to compromise systems by injecting malicious code into ostensibly secure software during the various compilation and distribution processes. The motivation behind the Reproducible Builds effort is to ensure no flaws have been introduced during this compilation process by promising identical results are always generated from a given source, thus allowing multiple third-parties to come to a consensus on whether a build was compromised. The project is proud to be a member project of the Software Freedom Conservancy. Conservancy acts as a corporate umbrella allowing projects to operate as non-profit initiatives without managing their own corporate structure. If you like the work of the Conservancy or the Reproducible Builds project, please consider becoming an official supporter. This month, I:

diffoscope I made the following changes to diffoscope, including preparing and uploading versions 159 and 160 to Debian:

Debian Lintian For Lintian, the static analysis tool for Debian packages, I uploaded versions 2.93.0, 2.94.0, 2.95.0 & 2.96.0 (not counting uploads to the backports repositories), as well as: Debian LTS This month I've worked 18 hours on Debian Long Term Support (LTS) and 12 hours on its sister Extended LTS project. You can find out more about the project via the following video:
Uploads Bugs filed

29 September 2020

Mike Gabriel: UBports: Packaging of Lomiri Operating Environment for Debian (part 03)

Before and during FOSDEM 2020, I agreed with the people (developers, supporters, managers) of the UBports Foundation to package the Unity8 Operating Environment for Debian. Since 27th Feb 2020, Unity8 has now become Lomiri. Recent Uploads to Debian related to Lomiri Over the past 4 months I worked on the following bits and pieces regarding Lomiri in Debian: The next two big projects / packages ahead are lomiri-ui-toolkit and qtmir. Credits Many big thanks go to Marius and Dalton for their work on the UBports project and being always available for questions, feedback, etc. Thanks to Ratchanan Srirattanamet for providing some of his time for debugging some non-thread safe unit tests (currently unsure, what package we actually looked at...). Thanks for Florian Leeber for being my point of contact for topcis regarding my cooperation with the UBports Foundation. Previous Posts about my Debian UBports Team Efforts

28 September 2020

Kentaro Hayashi: dnsZoneEntry: field should be removed when DD is retired

It is known that Debian Developer can setup *.debian.net. wiki.debian.org When Debian Developer had retired, actual DNS entry is removed, but dnsZoneEntry: field is kept on LDAP (db.debian.org) So you can not reuse *.debian.net if retired Debian Developer owns your prefered subdomain already. I've posted question about this current undocumented specification. lists.debian.org

Vincent Bernat: Syncing RIPE, ARIN and APNIC objects with a custom Ansible module

Internet is split into five regional Internet registry: AFRINIC, ARIN, APNIC, LACNIC and RIPE. Each RIR maintains an Internet Routing Registry. An IRR allows one to publish information about the routing of Internet number resources.1 Operators use this to determine the owner of an IP address and to construct and maintain routing filters. To ensure your routes are widely accepted, it is important to keep the prefixes you announce up-to-date in an IRR. There are two common tools to query this database: whois and bgpq4. The first one allows you to do a query with the WHOIS protocol:
$ whois -BrG 2a0a:e805:400::/40
[ ]
inet6num:       2a0a:e805:400::/40
netname:        FR-BLADE-CUSTOMERS-DE
country:        DE
geoloc:         50.1109 8.6821
admin-c:        BN2763-RIPE
tech-c:         BN2763-RIPE
status:         ASSIGNED
mnt-by:         fr-blade-1-mnt
remarks:        synced with cmdb
created:        2020-05-19T08:04:58Z
last-modified:  2020-05-19T08:04:58Z
source:         RIPE
route6:         2a0a:e805:400::/40
descr:          Blade IPv6 - AMS1
origin:         AS64476
mnt-by:         fr-blade-1-mnt
remarks:        synced with cmdb
created:        2019-10-01T08:19:34Z
last-modified:  2020-05-19T08:05:00Z
source:         RIPE
The second one allows you to build route filters using the information contained in the IRR database:
$ bgpq4 -6 -S RIPE -b AS64476
NN = [
    2a0a:e805::/40,
    2a0a:e805:100::/40,
    2a0a:e805:300::/40,
    2a0a:e805:400::/40,
    2a0a:e805:500::/40
];
There is no module available on Ansible Galaxy to manage these objects. Each IRR has different ways of being updated. Some RIRs propose an API but some don t. If we restrict ourselves to RIPE, ARIN and APNIC, the only common method to update objects is email updates, authenticated with a password or a GPG signature.2 Let s write a custom Ansible module for this purpose!

Notice I recommend that you read Writing a custom Ansible module as an introduction, as well as Syncing MySQL tables for a more instructive example.

Code The module takes a list of RPSL objects to synchronize and returns the body of an email update if a change is needed:
- name: prepare RIPE objects
  irr_sync:
    irr: RIPE
    mntner: fr-blade-1-mnt
    source: whois-ripe.txt
  register: irr

Prerequisites The source file should be a set of objects to sync using the RPSL language. This would be the same content you would send manually by email. All objects should be managed by the same maintainer, which is also provided as a parameter. Signing and sending the result is not the responsibility of this module. You need two additional tasks for this purpose:
- name: sign RIPE objects
  shell:
    cmd: gpg --batch --user noc@example.com --clearsign
    stdin: "  irr.objects  "
  register: signed
  check_mode: false
  changed_when: false
- name: update RIPE objects by email
  mail:
    subject: "NEW: update for RIPE"
    from: noc@example.com
    to: "auto-dbm@ripe.net"
    cc: noc@example.com
    host: smtp.example.com
    port: 25
    charset: us-ascii
    body: "  signed.stdout  "
You also need to authorize the PGP keys used to sign the updates by creating a key-cert object and adding it as a valid authentication method for the corresponding mntner object:
key-cert:  PGPKEY-A791AAAB
certif:    -----BEGIN PGP PUBLIC KEY BLOCK-----
certif:    
certif:    mQGNBF8TLY8BDADEwP3a6/vRhEERBIaPUAFnr23zKCNt5YhWRZyt50mKq1RmQBBY
[ ]
certif:    -----END PGP PUBLIC KEY BLOCK-----
mnt-by:    fr-blade-1-mnt
source:    RIPE
mntner:    fr-blade-1-mnt
[ ]
auth:      PGPKEY-A791AAAB
mnt-by:    fr-blade-1-mnt
source:    RIPE

Module definition Starting from the skeleton described in the previous article, we define the module:
module_args = dict(
    irr=dict(type='str', required=True),
    mntner=dict(type='str', required=True),
    source=dict(type='path', required=True),
)
result = dict(
    changed=False,
)
module = AnsibleModule(
    argument_spec=module_args,
    supports_check_mode=True
)

Getting existing objects To grab existing objects, we use the whois command to retrieve all the objects from the provided maintainer.
# Per-IRR variations:
# - whois server
whois =  
    'ARIN': 'rr.arin.net',
    'RIPE': 'whois.ripe.net',
    'APNIC': 'whois.apnic.net'
 
# - whois options
options =  
    'ARIN': ['-r'],
    'RIPE': ['-BrG'],
    'APNIC': ['-BrG']
 
# - objects excluded from synchronization
excluded = ["domain"]
if irr == "ARIN":
    # ARIN does not return these objects
    excluded.extend([
        "key-cert",
        "mntner",
    ])
# Grab existing objects
args = ["-h", whois[irr],
        "-s", irr,
        *options[irr],
        "-i", "mnt-by",
        module.params['mntner']]
proc = subprocess.run("whois", *args, capture_output=True)
if proc.returncode != 0:
    raise AnsibleError(
        f"unable to query whois:  args ")
output = proc.stdout.decode('ascii')
got = extract(output, excluded)
The first part of the code setup some IRR-specific constants: the server to query, the options to provide to the whois command and the objects to exclude from synchronization. The second part invokes the whois command, requesting all objects whose mnt-by field is the provided maintainer. Here is an example of output:
$ whois -h whois.ripe.net -s RIPE -BrG -i mnt-by fr-blade-1-mnt
[ ]
inet6num:       2a0a:e805:300::/40
netname:        FR-BLADE-CUSTOMERS-FR
country:        FR
geoloc:         48.8566 2.3522
admin-c:        BN2763-RIPE
tech-c:         BN2763-RIPE
status:         ASSIGNED
mnt-by:         fr-blade-1-mnt
remarks:        synced with cmdb
created:        2020-05-19T08:04:59Z
last-modified:  2020-05-19T08:04:59Z
source:         RIPE
[ ]
route6:         2a0a:e805:300::/40
descr:          Blade IPv6 - PA1
origin:         AS64476
mnt-by:         fr-blade-1-mnt
remarks:        synced with cmdb
created:        2019-10-01T08:19:34Z
last-modified:  2020-05-19T08:05:00Z
source:         RIPE
[ ]
The result is passed to the extract() function. It parses and normalizes the results into a dictionary mapping object names to objects. We store the result in the got variable.
def extract(raw, excluded):
    """Extract objects."""
    # First step, remove comments and unwanted lines
    objects = "\n".join([obj
                         for obj in raw.split("\n")
                         if not obj.startswith((
                                 "#",
                                 "%",
                         ))])
    # Second step, split objects
    objects = [RPSLObject(obj.strip())
               for obj in re.split(r"\n\n+", objects)
               if obj.strip()
               and not obj.startswith(
                   tuple(f" x :" for x in excluded))]
    # Last step, put objects in a dict
    objects =  repr(obj): obj
               for obj in objects 
    return objects
RPSLObject() is a class enabling normalization and comparison of objects. Look at the module code for more details.
>>> output="""
... inet6num:       2a0a:e805:300::/40
... [ ]
... """
>>> pprint( k: str(v) for k,v in extract(output, excluded=[]) )
 '<Object:inet6num:2a0a:e805:300::/40>':
   'inet6num:       2a0a:e805:300::/40\n'
   'netname:        FR-BLADE-CUSTOMERS-FR\n'
   'country:        FR\n'
   'geoloc:         48.8566 2.3522\n'
   'admin-c:        BN2763-RIPE\n'
   'tech-c:         BN2763-RIPE\n'
   'status:         ASSIGNED\n'
   'mnt-by:         fr-blade-1-mnt\n'
   'remarks:        synced with cmdb\n'
   'source:         RIPE',
 '<Object:route6:2a0a:e805:300::/40>':
   'route6:         2a0a:e805:300::/40\n'
   'descr:          Blade IPv6 - PA1\n'
   'origin:         AS64476\n'
   'mnt-by:         fr-blade-1-mnt\n'
   'remarks:        synced with cmdb\n'
   'source:         RIPE' 

Comparing with wanted objects Let s build the wanted dictionary using the same structure, thanks to the extract() function we can use verbatim:
with open(module.params['source']) as f:
    source = f.read()
wanted = extract(source, excluded)
The next step is to compare got and wanted to build the diff object:
if got != wanted:
    result['changed'] = True
    if module._diff:
        result['diff'] = [
            dict(before_header=k,
                 after_header=k,
                 before=str(got.get(k, "")),
                 after=str(wanted.get(k, "")))
            for k in set((*wanted.keys(), *got.keys()))
            if k not in wanted or k not in got or wanted[k] != got[k]]

Returning updates The module does not have a side effect. If there is a difference, we return the updates to send by email. We choose to include all wanted objects in the updates (contained in the source variable) and let the IRR ignore unmodified objects. We also append the objects to be deleted by adding a delete: attribute to each them them.
# We send all source objects and deleted objects.
deleted_mark = f" 'delete:':16 deleted by CMDB"
deleted = "\n\n".join([f" got[k].raw \n deleted_mark "
                       for k in got
                       if k not in wanted])
result['objects'] = f" source \n\n deleted "
module.exit_json(**result)

The complete code is available on GitHub. The module supports both --diff and --check flags. It does not return anything if no change is detected. It can work with APNIC, RIPE and ARIN. It is not perfect: it may not detect some changes,3 it is not able to modify objects not owned by the provided maintainer4 and some attributes cannot be modified, requiring to manually delete and recreate the updated object.5 However, this module should automate 95% of your needs.

  1. Other IRRs exist without being attached to a RIR. The most notable one is RADb.
  2. ARIN is phasing out this method in favor of IRR-online. RIPE has an API available, but email updates are still supported and not planned to be deprecated. APNIC plans to expose an API.
  3. For ARIN, we cannot query key-cert and mntner objects and therefore we cannot detect changes in them. It is also not possible to detect changes to the auth mechanisms of a mntner object.
  4. APNIC do not assign top-level objects to the maintainer associated with the owner.
  5. Changing the status of an inetnum object requires deleting and recreating the object.

27 September 2020

Iain R. Learmonth: Multicast IPTV

For almost a decade, I ve been very slowly making progress on a multicast IPTV system. Recently I ve made a significant leap forward in this project, and I wanted to write a little on the topic so I ll have something to look at when I pick this up next. I was aspiring to have a useable system by the end of today, but for a couple of reasons, it wasn t possible. When I started thinking about this project, it was still common to watch broadcast television. Over time the design of this system has been changing as new technologies have become available. Multicast IP is probably the only constant, although I m now looking at IPv6 rather than IPv4. Initially, I d been looking at DVB-T PCI cards. USB devices have become common and are available cheaply. There are also DVB-T hats available for the Raspberry Pi. I m now looking at a combination of Raspberry Pi hats and USB devices with one of each on a couple of Pis.
Two Raspberry Pis with DVB hats installed, TV antenna sockets showing Two Raspberry Pis with DVB hats installed, TV antenna sockets showing
The Raspberry Pi devices will run DVBlast, an open-source DVB demultiplexer and streaming server. Each of the tuners will be tuned to a different transponder giving me the ability to stream any combination of available channels simultaneously. This is everything that would be needed to watch TV on PCs on the home network with VLC. I ve not yet worked out if Kodi will accept multicast streams as a TV source, but I do know that Tvheadend will. Tvheadend can also act as a PVR to record programmes for later playback so is useful even if the multicast streams can be viewed directly. So how far did I get? I have built two Raspberry Pis in cases with the DVB-T hats on. They need to sit in the lounge as that s where the antenna comes down from the roof. There s no wired network connection in the lounge. I planned to use an OpenBSD box as a gateway, bridging the wireless network to a wired network. Two problems quickly emerged. The first being that the wireless card I had purchased only supported 2.4GHz, no 5GHz, and I have enough noise from neighbours that the throughput rate and packet loss are unacceptable. The second problem is that I had forgotten the problems with bridging wireless networks. To create a bridge, you need to be able to spoof the MAC addresses of wired devices on the wireless interface, but this can only be done when the wireless interface is in access point mode. So when I come back to this, I will have to look at routing rather than bridging to work around the MAC address issue, and I ll also be on the lookout for a cheap OpenBSD supported mini-PCIe wireless card that can do 5GHz.

Joachim Breitner: Learn Haskell on CodeWorld writing Sokoban

Two years ago, I held the CIS194 minicourse on Haskell at the University of Pennsylvania. In that installment of the course, I changed the first four weeks to teach the basics of Haskell using the online Haskell environment CodeWorld, and lead the students towards implementing the game Sokoban. As it is customary for CIS194, I put my lecture notes and exercises online, and this has been used as a learning resources by people from all over the world. But since I have left the University of Pennsylvania, I lost the ability to update the text, and as the CodeWorld API has evolved, some of the examples and exercises no longer work. Some recent complains about that, in bug reports against CodeWorld and in unrealistically flattering tweets ( Shame, this was the best Haskell course ever!!! ) motivated me to extract that material and turn it into an updated stand-alone tutorial that I can host myself. So if you feel like learning Haskell without worrying about local installation, and while creating a reasonably fun game, head over to https://haskell-via-sokoban.nomeata.de/ and get started! Improvements can now also be contributed at https://github.com/nomeata/haskell-via-sokoban. Credits go to Brent Yorgey, Richard Eisenberg and Noam Zilberstein, who held the previous installments of the course, and Chris Smith for creating the CodeWorld environment.

26 September 2020

Fran ois Marier: Repairing a corrupt ext4 root partition

I ran into filesystem corruption (ext4) on the root partition of my backup server which caused it to go into read-only mode. Since it's the root partition, it's not possible to unmount it and repair it while it's running. Normally I would boot from an Ubuntu live CD / USB stick, but in this case the machine is using the mipsel architecture and so that's not an option.

Repair using a USB enclosure I had to pull the shutdown the server and then pull the SSD drive out. I then moved it to an external USB enclosure and connected it to my laptop. I started with an automatic filesystem repair:
fsck.ext4 -pf /dev/sde2
which failed for some reason and so I moved to an interactive repair:
fsck.ext4 -f /dev/sde2
Once all of the errors were fixed, I ran a full surface scan to update the list of bad blocks:
fsck.ext4 -c /dev/sde2
Finally, I forced another check to make sure that everything was fixed at the filesystem level:
fsck.ext4 -f /dev/sde2

Fix invalid alternate GPT The other thing I noticed is this messge in my dmesg log:
scsi 8:0:0:0: Direct-Access     KINGSTON  SA400S37120     SBFK PQ: 0 ANSI: 6
sd 8:0:0:0: Attached scsi generic sg4 type 0
sd 8:0:0:0: [sde] 234441644 512-byte logical blocks: (120 GB/112 GiB)
sd 8:0:0:0: [sde] Write Protect is off
sd 8:0:0:0: [sde] Mode Sense: 31 00 00 00
sd 8:0:0:0: [sde] Write cache: enabled, read cache: enabled, doesn't support DPO or FUA
sd 8:0:0:0: [sde] Optimal transfer size 33553920 bytes
Alternate GPT is invalid, using primary GPT.
 sde: sde1 sde2
I therefore checked to see if the partition table looked fine and got the following:
$ fdisk -l /dev/sde
GPT PMBR size mismatch (234441643 != 234441647) will be corrected by write.
The backup GPT table is not on the end of the device. This problem will be corrected by write.
Disk /dev/sde: 111.8 GiB, 120034123776 bytes, 234441648 sectors
Disk model: KINGSTON SA400S3
Units: sectors of 1 * 512 = 512 bytes
Sector size (logical/physical): 512 bytes / 512 bytes
I/O size (minimum/optimal): 512 bytes / 512 bytes
Disklabel type: gpt
Disk identifier: 799CD830-526B-42CE-8EE7-8C94EF098D46
Device       Start       End   Sectors   Size Type
/dev/sde1     2048   8390655   8388608     4G Linux swap
/dev/sde2  8390656 234441614 226050959 107.8G Linux filesystem
It turns out that all I had to do, since only the backup / alternate GPT partition table was corrupt and the primary one was fine, was to re-write the partition table:
$ fdisk /dev/sde
Welcome to fdisk (util-linux 2.33.1).
Changes will remain in memory only, until you decide to write them.
Be careful before using the write command.
GPT PMBR size mismatch (234441643 != 234441647) will be corrected by write.
The backup GPT table is not on the end of the device. This problem will be corrected by write.
Command (m for help): w
The partition table has been altered.
Syncing disks.

Run SMART checks Since I still didn't know what caused the filesystem corruption in the first place, I decided to do one last check: SMART errors. I couldn't do this via the USB enclosure since the SMART commands aren't forwarded to the drive and so I popped the drive back into the backup server and booted it up. First, I checked whether any SMART errors had been reported using smartmontools:
smartctl -a /dev/sda
That didn't show any errors and so I kicked off an extended test:
smartctl -t long /dev/sda
which ran for 30 minutes and then passed without any errors. The mystery remains unsolved.

Dirk Eddelbuettel: #30: Easy, Reliable, Fast and Portable Linux and macOS Continuous Integration

Welcome to the 30th post in the rarified R recommendation resources series or R4 for short. The last post introduced BSPM. In the four weeks since, we have worked some more on BSPM to bring it to the point where it is ready for use with continuous integration. Building on this, it is now used inside the run.sh script that driven our CI use for many years (via the r-travis repo). Which we actually use right now on three different platforms: All three use the exact same script facilitating this, and run a matrix over Linux and macOS. You read this right: one CI setup that is portable and which you can take to your CI provider of choice. No lock-in or tie-in. Use what works, change at will. Or run on all three if you like burning extra cycles. This is already used by handful of my repos as well as by at least two repos of friends also deploying r-travis. How does it work? In a nutshell we are There are several customizations that are possible via environment variables We find this setup compelling. The scheme is simple: there really is just one shell script behind it which can also be downloaded and altered. The scheme is also portable as we can (as shown) rotate between CI provides. The scheme is also more flexible: in case of debugging needs one can simply run the script on a local Docker or VM instance. Lastly, the scheme moves away from single points of failure or breakage. Currently the script uses only BSPM as I had the hunch that it would a) work and b) be compelling. Adding support for RSPM would be equally easy, but I have no immediate need to do so. Adding BioConductor installation may be next. That is easy when BioConductor uses r-release; it may be little more challenging under r-devel to but it should work too. Stay tuned. In the meantime, if the above sounds compelling, give run.sh from r-travis a go! If you like this or other open-source work I do, you can now sponsor me at GitHub. For the first year, GitHub will match your contributions.

This post by Dirk Eddelbuettel originated on his Thinking inside the box blog. Please report excessive re-aggregation in third-party for-profit settings.

Next.

Previous.