Search Results: "tar"

15 October 2020

Dirk Eddelbuettel: dang 0.0.12: Two new functions

A new release of the dang package is now on CRAN, roughly one year after the last release. The dang package regroups a few functions of mine that had no other home as for example lsos() from a StackOverflow question from 2009 (!!) is one, this overbought/oversold price band plotter from an older blog post is another. More recently added were helpers for data.table to xts conversion and a git repo root finder. This release adds two functions. One was mentioned just days ago in a tweet by Nathan and is a reworked version of something Colin tweeted about a few weeks ago: a little data wrangling off the kewl rtweet to find maximally spammy accounts per search topic. In other words those who include more than N hashtags for given search term. The other is something I, if memory serves, picked up a while back on one of the lists: a base R function to identify non-ASCII characters in a file. It is a C function that is not directly exported by and hence no accessible, so we put it here (with credits, of course). I mentioned it yesterday when announcing tidyCpp as I this C function was the starting point for the new tidyCpp wrapper around some C API of R functions. The (very short) NEWS entry follows.

Changes in version 0.0.12 (2020-10-14)
  • New functions muteTweets and checkPackageAsciiCode.
  • Updated CI setup.

Courtesy of CRANberries, there is a comparison to the previous release. For questions or comments use the issue tracker off the GitHub repo. If you like this or other open-source work I do, you can now sponsor me at GitHub. For the first year, GitHub will match your contributions.

This post by Dirk Eddelbuettel originated on his Thinking inside the box blog. Please report excessive re-aggregation in third-party for-profit settings.

14 October 2020

Michael Stapelberg: distri: a Linux distribution to research fast package management

Over the last year or so I have worked on a research linux distribution in my spare time. It s not a distribution for researchers (like Scientific Linux), but my personal playground project to research linux distribution development, i.e. try out fresh ideas. This article focuses on the package format and its advantages, but there is more to distri, which I will cover in upcoming blog posts.

Motivation I was a Debian Developer for the 7 years from 2012 to 2019, but using the distribution often left me frustrated, ultimately resulting in me winding down my Debian work. Frequently, I was noticing a large gap between the actual speed of an operation (e.g. doing an update) and the possible speed based on back of the envelope calculations. I wrote more about this in my blog post Package managers are slow . To me, this observation means that either there is potential to optimize the package manager itself (e.g. apt), or what the system does is just too complex. While I remember seeing some low-hanging fruit , through my work on distri, I wanted to explore whether all the complexity we currently have in Linux distributions such as Debian or Fedora is inherent to the problem space. I have completed enough of the experiment to conclude that the complexity is not inherent: I can build a Linux distribution for general-enough purposes which is much less complex than existing ones. Those were low-hanging fruit from a user perspective. I m not saying that fixing them is easy in the technical sense; I know too little about apt s code base to make such a statement.

Key idea: packages are images, not archives One key idea is to switch from using archives to using images for package contents. Common package managers such as dpkg(1) use tar(1) archives with various compression algorithms. distri uses SquashFS images, a comparatively simple file system image format that I happen to be familiar with from my work on the gokrazy Raspberry Pi 3 Go platform. This idea is not novel: AppImage and snappy also use images, but only for individual, self-contained applications. distri however uses images for distribution packages with dependencies. In particular, there is no duplication of shared libraries in distri. A nice side effect of using read-only image files is that applications are immutable and can hence not be broken by accidental (or malicious!) modification.

Key idea: separate hierarchies Package contents are made available under a fully-qualified path. E.g., all files provided by package zsh-amd64-5.6.2-3 are available under /ro/zsh-amd64-5.6.2-3. The mountpoint /ro stands for read-only, which is short yet descriptive. Perhaps surprisingly, building software with custom prefix values of e.g. /ro/zsh-amd64-5.6.2-3 is widely supported, thanks to:
  1. Linux distributions, which build software with prefix set to /usr, whereas FreeBSD (and the autotools default), which build with prefix set to /usr/local.
  2. Enthusiast users in corporate or research environments, who install software into their home directories.
Because using a custom prefix is a common scenario, upstream awareness for prefix-correctness is generally high, and the rarely required patch will be quickly accepted.

Key idea: exchange directories Software packages often exchange data by placing or locating files in well-known directories. Here are just a few examples:
  • gcc(1) locates the libusb(3) headers via /usr/include
  • man(1) locates the nginx(1) manpage via /usr/share/man.
  • zsh(1) locates executable programs via PATH components such as /bin
In distri, these locations are called exchange directories and are provided via FUSE in /ro. Exchange directories come in two different flavors:
  1. global. The exchange directory, e.g. /ro/share, provides the union of the share sub directory of all packages in the package store.
    Global exchange directories are largely used for compatibility, see below.
  2. per-package. Useful for tight coupling: e.g. irssi(1) does not provide any ABI guarantees, so plugins such as irssi-robustirc can declare that they want e.g. /ro/irssi-amd64-1.1.1-1/out/lib/irssi/modules to be a per-package exchange directory and contain files from their lib/irssi/modules.

Search paths sometimes need to be fixed Programs which use exchange directories sometimes use search paths to access multiple exchange directories. In fact, the examples above were taken from gcc(1) s INCLUDEPATH, man(1) s MANPATH and zsh(1) s PATH. These are prominent ones, but more examples are easy to find: zsh(1) loads completion functions from its FPATH. Some search path values are derived from --datadir=/ro/share and require no further attention, but others might derive from e.g. --prefix=/ro/zsh-amd64-5.6.2-3/out and need to be pointed to an exchange directory via a specific command line flag.

FHS compatibility Global exchange directories are used to make distri provide enough of the Filesystem Hierarchy Standard (FHS) that third-party software largely just works. This includes a C development environment. I successfully ran a few programs from their binary packages such as Google Chrome, Spotify, or Microsoft s Visual Studio Code.

Fast package manager I previously wrote about how Linux distribution package managers are too slow. distri s package manager is extremely fast. Its main bottleneck is typically the network link, even at high speed links (I tested with a 100 Gbps link). Its speed comes largely from an architecture which allows the package manager to do less work. Specifically:
  1. Package images can be added atomically to the package store, so we can safely skip fsync(2) . Corruption will be cleaned up automatically, and durability is not important: if an interactive installation is interrupted, the user can just repeat it, as it will be fresh on their mind.
  2. Because all packages are co-installable thanks to separate hierarchies, there are no conflicts at the package store level, and no dependency resolution (an optimization problem requiring SAT solving) is required at all.
    In exchange directories, we resolve conflicts by selecting the package with the highest monotonically increasing distri revision number.
  3. distri proves that we can build a useful Linux distribution entirely without hooks and triggers. Not having to serialize hook execution allows us to download packages into the package store with maximum concurrency.
  4. Because we are using images instead of archives, we do not need to unpack anything. This means installing a package is really just writing its package image and metadata to the package store. Sequential writes are typically the fastest kind of storage usage pattern.
Fast installation also make other use-cases more bearable, such as creating disk images, be it for testing them in qemu(1) , booting them on real hardware from a USB drive, or for cloud providers such as Google Cloud.

Fast package builder Contrary to how distribution package builders are usually implemented, the distri package builder does not actually install any packages into the build environment. Instead, distri makes available a filtered view of the package store (only declared dependencies are available) at /ro in the build environment. This means that even for large dependency trees, setting up a build environment happens in a fraction of a second! Such a low latency really makes a difference in how comfortable it is to iterate on distribution packages.

Package stores In distri, package images are installed from a remote package store into the local system package store /roimg, which backs the /ro mount. A package store is implemented as a directory of package images and their associated metadata files. You can easily make available a package store by using distri export. To provide a mirror for your local network, you can periodically distri update from the package store you want to mirror, and then distri export your local copy. Special tooling (e.g. debmirror in Debian) is not required because distri install is atomic (and update uses install). Producing derivatives is easy: just add your own packages to a copy of the package store. The package store is intentionally kept simple to manage and distribute. Its files could be exchanged via peer-to-peer file systems, or synchronized from an offline medium.

distri s first release distri works well enough to demonstrate the ideas explained above. I have branched this state into branch jackherer, distri s first release code name. This way, I can keep experimenting in the distri repository without breaking your installation. From the branch contents, our autobuilder creates:
  1. disk images, which
  2. a package repository. Installations can pick up new packages with distri update.
  3. documentation for the release.
The project website can be found at https://distr1.org. The website is just the README for now, but we can improve that later. The repository can be found at https://github.com/distr1/distri

Project outlook Right now, distri is mainly a vehicle for my spare-time Linux distribution research. I don t recommend anyone use distri for anything but research, and there are no medium-term plans of that changing. At the very least, please contact me before basing anything serious on distri so that we can talk about limitations and expectations. I expect the distri project to live for as long as I have blog posts to publish, and we ll see what happens afterwards. Note that this is a hobby for me: I will continue to explore, at my own pace, parts that I find interesting. My hope is that established distributions might get a useful idea or two from distri.

There s more to come: subscribe to the distri feed I don t want to make this post too long, but there is much more! Please subscribe to the following URL in your feed reader to get all posts about distri: https://michael.stapelberg.ch/posts/tags/distri/feed.xml Next in my queue are articles about hermetic packages and good package maintainer experience (including declarative packaging).

Feedback or questions? I d love to discuss these ideas in case you re interested! Please send feedback to the distri mailing list so that everyone can participate!

Sven Hoexter: Nice Helper to Sanitize File Names - sanity.pl

One of the most awesome helpers I carry around in my ~/bin since the early '00s is the sanity.pl script written by Andreas Gohr. It just recently came back to use when I started to archive some awesome Corona enforced live session music with youtube-dl. Update: Francois Marier pointed out that Debian contains the detox package, which has a similar functionality.

Thomas Goirand: The Gnocchi package in Debian

This is a follow-up from the blog post of Russel as seen here: https://etbe.coker.com.au/2020/10/13/first-try-gnocchi-statsd/. There s a bunch of things he wrote which I unfortunately must say is inaccurate, and sometimes even completely wrong. It is my point of view that none of the reported bugs are helpful for anyone that understand Gnocchi and how to set it up. It s however a terrible experience that Russell had, and I do understand why (and why it s not his fault). I m very much open on how to fix this on the packaging level, though some things aren t IMO fixable. Here s the details. 1/ The daemon startups First of all, the most surprising thing is when Russell claimed that there s no startup scripts for the Gnocchi daemons. In fact, they all come with both systemd and sysv-rc support: # ls /lib/systemd/system/gnocchi-api.service
/lib/systemd/system/gnocchi-api.service
# /etc/init.d/gnocchi-api
/etc/init.d/gnocchi-api Russell then tried to start gnocchi-api without the good options that are set in the Debian scripts, and not surprisingly, this failed. Russell attempted to do what was in the upstream doc, which isn t adapted to what we have in Debian (the upstream doc is probably completely outdated, as Gnocchi is unfortunately not very well maintained upstream). The bug #972087 is therefore, IMO not valid. 2/ The database setup By default for all things OpenStack in Debian, there are some debconf helpers using dbconfig-common to help users setup database for their services. This is clearly for beginners, but that doesn t prevent from attempting to understand what you re doing. That is, more specifically for Gnocchi, there are 2 databases: one for Gnocchi itself, and one for the indexer, which not necessarily is using the same backend. The Debian package already setups one database, but one has to do it manually for the indexer one. I m sorry this isn t well enough documented. Now, if some package are supporting sqlite as a backend (since most things in OpenStack are using SQLAlchemy), it looks like Gnocchi doesn t right now. This is IMO a bug upstream, rather than a bug in the package. However, I don t think the Debian packages are to be blame here, as they simply offer a unified interface, and it s up to the users to know what they are doing. SQLite is anyway not a production ready backend. I m not sure if I should close #971996 without any action, or just try to disable the SQLite backend option of this package because it may be confusing. 3/ The metrics UUID Russell then thinks the UUID should be set by default. This is probably right in a single server setup, however, this wouldn t work setting-up a cluster, which is probably what most Gnocchi users will do. In this type of environment, the metrics UUID must be the same on the 3 servers, and setting-up a random (and therefore different) UUID on the 3 servers wouldn t work. So I m also tempted to just close #972092 without any action on my side. 4/ The coordination URL Since Gnocchi is supposed to be setup with more than one server, as in OpenStack, having an HA setup is very common, then a backend for the coordination (ie: sharing the workload) must be set. This is done by setting an URL that tooz understand. The best coordinator being Zookeeper, something like this should be set by hand: coordination_url=zookeeper://192.168.101.2:2181/ Here again, I don t think the Debian package is to be blamed for not providing the automation. I would however accept contributions to fix this and provide the choice using debconf, however, users would still need to understand what s going on, and setup something like Zookeeper (or redis, memcache, or any other backend supported by tooz) to act as coordinator. 5/ The Debconf interface cannot replace a good documentation and there s not so much I can do at my package maintainer level for this. Russell, I m really sorry for the bad user experience you had with Gnocchi. Now that you know a little big more about it, maybe you can have another go? Sure, the OpenStack telemetry system isn t an easy to understand beast, but it s IMO worth trying. And the recent versions can scale horizontally

Fran ois Marier: Making an Apache website available as a Tor Onion Service

As part of the #MoreOnionsPorFavor campaign, I decided to follow brave.com's lead and make my homepage available as a Tor onion service.

Tor daemon setup I started by installing the Tor daemon locally:
apt install tor
and then setting the following in /etc/tor/torrc:
SocksPort 0
SocksPolicy reject *
HiddenServiceDir /var/lib/tor/hidden_service/
HiddenServicePort 80 [2600:3c04::f03c:91ff:fe8c:61ac]:80
HiddenServicePort 443 [2600:3c04::f03c:91ff:fe8c:61ac]:443
HiddenServiceVersion 3
HiddenServiceNonAnonymousMode 1
HiddenServiceSingleHopMode 1
in order to create a version 3 onion service without actually running a Tor relay. Note that since I am making a public website available over Tor, I do not need the location of the website to be hidden and so I used the same settings as Cloudflare in their public Tor proxy. Also, I explicitly used the external IPv6 address of my server in the configuration in order to prevent localhost bypasses. After restarting the Tor daemon to reload the configuration file:
systemctl restart tor.service
I looked for the address of my onion service:
$ cat /var/lib/tor/hidden_service/hostname 
ixrdj3iwwhkuau5tby5jh3a536a2rdhpbdbu6ldhng43r47kim7a3lid.onion

Apache configuration Next, I enabled a few required Apache modules:
a2enmod mpm_event
a2enmod http2
a2enmod headers
and configured my Apache vhosts in /etc/apache2/sites-enabled/www.conf:
<VirtualHost *:443>
    ServerName fmarier.org
    ServerAlias ixrdj3iwwhkuau5tby5jh3a536a2rdhpbdbu6ldhng43r47kim7a3lid.onion
    Protocols h2, http/1.1
    Header set Onion-Location "http://ixrdj3iwwhkuau5tby5jh3a536a2rdhpbdbu6ldhng43r47kim7a3lid.onion% REQUEST_URI s"
    Header set alt-svc 'h2="ixrdj3iwwhkuau5tby5jh3a536a2rdhpbdbu6ldhng43r47kim7a3lid.onion:443"; ma=315360000; persist=1'
    Header add Strict-Transport-Security: "max-age=63072000"
    Include /etc/fmarier-org/www-common.include
    SSLEngine On
    SSLCertificateFile /etc/letsencrypt/live/fmarier.org/fullchain.pem
    SSLCertificateKeyFile /etc/letsencrypt/live/fmarier.org/privkey.pem
</VirtualHost>
<VirtualHost *:80>
    ServerName fmarier.org
    Redirect permanent / https://fmarier.org/
</VirtualHost>
<VirtualHost *:80>
    ServerName ixrdj3iwwhkuau5tby5jh3a536a2rdhpbdbu6ldhng43r47kim7a3lid.onion
    Include /etc/fmarier-org/www-common.include
</VirtualHost>
Note that /etc/fmarier-org/www-common.include contains all of the configuration options that are common to both the HTTP and the HTTPS sites (e.g. document root, caching headers, aliases, etc.). Finally, I restarted Apache:
apache2ctl configtest
systemctl restart apache2.service

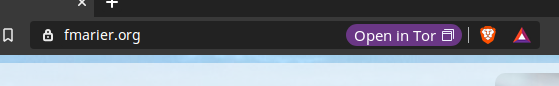
Testing In order to test that my website is correctly available at its .onion address, I opened the following URLs in a Brave Tor window: I also checked that the main URL (https://fmarier.org/) exposes a working Onion-Location header which triggers the display of a button in the URL bar (recently merged and available in Brave Nightly): Testing that the Alt-Svc is working required using the Tor Browser since that's not yet supported in Brave:
  1. Open https://fmarier.org.
  2. Wait 30 seconds.
  3. Reload the page.
On the server side, I saw the following:
2a0b:f4c2:2::1 - - [14/Oct/2020:02:42:20 +0000] "GET / HTTP/2.0" 200 2696 "-" "Mozilla/5.0 (Windows NT 10.0; rv:78.0) Gecko/20100101 Firefox/78.0"
2600:3c04::f03c:91ff:fe8c:61ac - - [14/Oct/2020:02:42:53 +0000] "GET / HTTP/2.0" 200 2696 "-" "Mozilla/5.0 (Windows NT 10.0; rv:78.0) Gecko/20100101 Firefox/78.0"
That first IP address is from a Tor exit node:
$ whois 2a0b:f4c2:2::1
...
inet6num:       2a0b:f4c2::/40
netname:        MK-TOR-EXIT
remarks:        -----------------------------------
remarks:        This network is used for Tor Exits.
remarks:        We do not have any logs at all.
remarks:        For more information please visit:
remarks:        https://www.torproject.org
which indicates that the first request was not using the .onion address. The second IP address is the one for my server:
$ dig +short -x 2600:3c04::f03c:91ff:fe8c:61ac
hafnarfjordur.fmarier.org.
which indicates that the second request to Apache came from the Tor relay running on my server, hence using the .onion address.

Dirk Eddelbuettel: tidyCpp 0.0.1: New package

A new package arrived on CRAN a few days ago. It offers a few headers files which wrap (parts) of the C API for R, but in a form that may be a little easier to use for C++ programmers. I have always liked how in Rcpp we offer good parts of the standalone R Math library in a namespace R::. While working recently with a particular C routine (for checking non-ASCII characters that will be part of the next version of the dang package which collecting various goodies in one place), I realized there may be value in collecting a few more such wrappers. So I started a few simple ones starting from simple examples. Currently we have five headers defines.h, globals.h, internals.h, math.h, and shield.h. The first four each correpond to an R header file of the same or similar name, and the last one brings a simple yet effective alternative to PROTECT and UNPROTECT from Rcpp (in a slightly simplified way). None of the headers are complete , for internals.h in particular a lot more could be added (as I noticed today when experimenting with another source file that may be converted). All of the headers can be accessed with a simple #include <tidyCpp> (which, following another C++ convention, does not have a .h or .hpp suffix). And a the package ships these headers, packages desiring to use them only need LinkingTo: tidyCpp. As usage examples, we (right now) have four files in the snippets/ directory of the package. Two of these, convolveExample.cpp and dimnamesExample.cpp both illustrate how one could change example code from Writing R Extensions. Then there are also a very simple defineExample.cpp and a shieldExample.cpp illustrating how much easier Shield() is compared to PROTECT and UNPROTECT. Finally, there is a nice vignette discussing the package motivation with two detailed side-by-side before and after examples that are the aforementioned convolution and dimnames examples. Over time, I expect to add more definitions and wrappers. Feedback would be welcome it seems to hit a nerve already as it currently has more stars than commits even though (prior to this post) I had yet to tweet or blog about it. Please post comments and suggestions at the GitHub repo. If you like this or other open-source work I do, you can now sponsor me at GitHub. For the first year, GitHub will match your contributions.

This post by Dirk Eddelbuettel originated on his Thinking inside the box blog. Please report excessive re-aggregation in third-party for-profit settings.

12 October 2020

Markus Koschany: My Free Software Activities in September 2020

Welcome to gambaru.de. Here is my monthly report (+ the first week in October) that covers what I have been doing for Debian. If you re interested in Java, Games and LTS topics, this might be interesting for you. Debian Games
warzone2100
Debian Java
pdfsam
Misc Debian LTS This was my 55. month as a paid contributor and I have been paid to work 31,75 hours on Debian LTS, a project started by Rapha l Hertzog. In that time I did the following: ELTS Extended Long Term Support (ELTS) is a project led by Freexian to further extend the lifetime of Debian releases. It is not an official Debian project but all Debian users benefit from it without cost. The current ELTS release is Debian 8 Jessie . This was my 28. month and I have been paid to work 15 hours on ELTS. Thanks for reading and see you next time.

Axel Beckert: Git related shell aliases I commonly use

Hope this might be an inspiration to use these or similar aliases as well.

Reproducible Builds: Restarting Reproducible Builds IRC meetings

The Reproducible Builds project intends to resume meeting regularly on IRC, starting today, Monday October 12th, at 18:00 UTC. Sadly, due to the unprecedented events in 2020, there will be no in-person Reproducible Builds event this year, but please join us on the #reproducible-builds channel on irc.oftc.net. An editable agenda is available. The cadence of these meetings will probably be every two weeks, although this will be discussed and decided on at the first meeting.

Russ Allbery: Review: Hand to Mouth

Review: Hand to Mouth, by Linda Tirado
Publisher: G.P. Putnam's Sons
Copyright: October 2014
ISBN: 0-698-17528-X
Format: Kindle
Pages: 194
The first time Linda Tirado came to the viral attention of the Internet was in 2013 when she responded to a forum question: "Why do poor people do things that seem so self-destructive?" Here are some excerpts from her virally popular five-page response, which is included in the first chapter:
I know how to cook. I had to take Home Ec. to graduate high school. Most people on my level didn't. Broccoli is intimidating. You have to have a working stove, and pots, and spices, and you'll have to do the dishes no matter how tired you are or they'll attract bugs. It is a huge new skill for a lot of people. That's not great, but it's true. And if you fuck it up, you could make your family sick. We have learned not to try too hard to be middle class. It never works out well and always makes you feel worse for having tried and failed yet again. Better not to try. It makes more sense to get food that you know will be palatable and cheap and that keeps well. Junk food is a pleasure that we are allowed to have; why would we give that up? We have very few of them.
and
I smoke. It's expensive. It's also the best option. You see, I am always, always exhausted. It's a stimulant. When I am too tired to walk one more step, I can smoke and go for another hour. When I am enraged and beaten down and incapable of accomplishing one more thing, I can smoke and I feel a little better, just for a minute. It is the only relaxation I am allowed. It is not a good decision, but it is the only one that I have access to. It is the only thing I have found that keeps me from collapsing or exploding.
This book is an expansion on that essay. It's an entry in a growing genre of examinations of what it means to be poor in the United States in the 21st century. Unlike most of those examinations, it isn't written by an outsider performing essentially anthropological field work. It's one of the rare books written by someone who is herself poor and had the combination of skill and viral fame required to get an opportunity to talk about it in her own words.
I haven't had it worse than anyone else, and actually, that's kind of the point. This is just what life is for roughly a third of the country. We all handle it in our own ways, but we all work in the same jobs, live in the same places, feel the same sense of never quite catching up. We're not any happier about the exploding welfare rolls than anyone else is, believe me. It's not like everyone grows up and dreams of working two essentially meaningless part-time jobs while collecting food stamps. It's just that there aren't many other options for a lot of people.
I didn't find this book back in 2014 when it was published. I found it in 2020 during Tirado's second round of Internet fame: when the police shot out her eye with "non-lethal" rounds while she was covering the George Floyd protests as a photojournalist. In characteristic fashion, she subsequently reached out to the other people who had been blinded by the police, used her temporary fame to organize crowdfunded support for others, and is planning on having "try again" tattooed over the scar. That will give you a feel for the style of this book. Tirado is blunt, opinionated, honest, and full speed ahead. It feels weird to call this book delightful since it's fundamentally about the degree to which the United States is failing a huge group of its citizens and making their lives miserable, but there is something so refreshing and clear-headed about Tirado's willingness to tell you the straight truth about her life. It's empathy delivered with the subtlety of a brick, but also with about as much self-pity as a brick. Tirado is not interested in making you feel sorry for her; she's interested in you paying attention.
I don't get much of my own time, and I am vicious about protecting it. For the most part, I am paid to pretend that I am inhuman, paid to cater to both the reasonable and unreasonable demands of the general public. So when I'm off work, feel free to go fuck yourself. The times that I am off work, awake, and not taking care of life's details are few and far between. It's the only time I have any autonomy. I do not choose to waste that precious time worrying about how you feel. Worrying about you is something they pay me for; I don't work for free.
If you've read other books on this topic (Emily Guendelsberger's On the Clock is still the best of those I've read), you probably won't get many new facts from Hand to Mouth. I think this book is less important for the policy specifics than it is for who is writing it (someone who is living that life and can be honest about it) and the depth of emotional specifics that Tirado brings to the description. If you have never been poor, you will learn the details of what life is like, but more significantly you'll get a feel for how Tirado feels about it, and while this is one individual perspective (as Tirado stresses, including the fact that, as a white person, there are other aspects of poverty she's not experienced), I think that perspective is incredibly valuable. That said, Hand to Mouth provides even more reinforcement of the importance of universal medical care, the absurdity of not including dental care in even some of the more progressive policy proposals, and the difficulties in the way of universal medical care even if we solve the basic coverage problem. Tirado has significant dental problems due to unrepaired damage from a car accident, and her account reinforces my belief that we woefully underestimate how important good dental care is to quality of life. But providing universal insurance or access is only the start of the problem.
There is a price point for good health in America, and I have rarely been able to meet it. I choose not to pursue treatment if it will cost me more than it will gain me, and my cost-benefit is done in more than dollars. I have to think of whether I can afford any potential treatment emotionally, financially, and timewise. I have to sort out whether I can afford to change my life enough to make any treatment worth it I've been told by more than one therapist that I'd be fine if I simply reduced the amount of stress in my life. It's true, albeit unhelpful. Doctors are fans of telling you to sleep and eat properly, as though that were a thing one can simply do.
That excerpt also illustrates one of the best qualities of this book. So much writing about "the poor" treats them as an abstract problem that the implicitly not-poor audience needs to solve, and this leads rather directly to the endless moralizing as "we" attempt to solve that problem by telling poor people what they need to do. Tirado is unremitting in fighting for her own agency. She has a shitty set of options, but within those options she makes her own decisions. She wants better options and more space in which to choose them, which I think is a much more productive way to frame the moral argument than the endless hand-wringing over how to help "those poor people." This is so much of why I support universal basic income. Just give people money. It's not all of the solution UBI doesn't solve the problem of universal medical care, and we desperately need to find a way to make work less awful but it's the most effective thing we can do immediately. Poor people are, if anything, much better at making consequential financial decisions than rich people because they have so much more practice. Bad decisions are less often due to bad decision-making than bad options and the balancing of objectives that those of us who are not poor don't understand. Hand to Mouth is short, clear, refreshing, bracing, and, as you might have noticed, very quotable. I think there are other books in this genre that offer more breadth or policy insight, but none that have the same feel of someone cutting through the bullshit of lazy beliefs and laying down some truth. If any of the above excerpts sound like the sort of book you would enjoy reading, pick this one up. Rating: 8 out of 10

11 October 2020

Mark Brown: Book club: JSON Web Tokens

This month for our book club Daniel, Lars, Vince and I read Hardcoded secrets, unverified tokens, and other common JWT mistakes which wasn t quite what we d thought when it was picked. We had been expecting an analysis of JSON web tokens themselves as several us had been working in the area and had noticed various talk about problems with the standard but instead the article is more a discussion of the use of semgrep to find and fix common issues, using issues with JWT as examples. We therefore started off with a bit of a discussion of JWT, concluding that the underlying specification was basically fine given the problem to be solved but that as with any security related technology there were plenty of potential pitfalls in implementation and that sadly many of the libraries implementing the specification make it far too easy to make mistakes such as those covered by the article through their interface design and defaults. For example interfaces that allow interchangable use of public keys and shared keys are error prone, as is is making it easy to access unauthenticated data from tokens without clearly flagging that it is unauthenticated. We agreed that the wide range of JWT implementations available and successfully interoperating with each other is a sign that JWT is getting something right in providing a specification that is clear and implementable. Moving on to semgrep we were all very enthusiastic about the technology, language independent semantic matching with a good set of rules for a range of languages available. Those of us who work on the Linux kernel were familiar with semantic matching and patching as implemented by Coccinelle which has been used quite successfully for years to both avoiding bad patterns in code and making tree wide changes, as demonstrated by the article it is a powerful technique. We were impressed by the multi-language support and approachability of semgrep, with tools like their web editor seeming particularly helpful for people getting started with the tool, especially in conjunction with the wide range of examples available. This was a good discussion (including the tangential discussions of quality problems we had all faced dealing with software over the years, depressing though those can be) and semgrep was a great tool to learn about, I know I m going to be using it for some of my projects.

10 October 2020

William (Bill) Blough: sudo reboot


Benjy: The best-laid plans of mice... Arthur: And men. Frankie: What? Arthur: Best-laid plans of mice and men. Benjy: What have men got to do with it? -- The Hitchhiker's Guide to the Galaxy TV series
Last year, my intent had been to post monthy updates with details of the F/LOSS contributions I had made during the previous month. I wanted to do this as a way to summarize and reflect on what I had done, and also to hopefully motivate me to do more. Fast forward, and it's been over a year since my last blog post. So much for those plans. I won't go into specific detail about the F/LOSS contributions I've made in the past year. This isn't meant to be a "catch-up" post, per se. It's more of an acknowledgement that I didn't do what I set out to do, as well as something of a reset to enable me to continue blogging (or not) as I see fit. So, to summarize those contributions: All in all, I'm pretty happy with the contributions I've made in the past year. Historically, my F/LOSS activity had been somewhat sporadic, sometimes with months passing in between contributions. But looking through my notes from the past year, it appears that I made contributions every single month, with no skipped months. Of course, I would have liked to have done more, but I consider the improvement in consistency to be a solid win. As for the blog, well... Judging by the most recent year-long gap (as well as the gaps before that), I'm not likely to start regularly writing posts anytime soon. But then again, if sporadic F/LOSS contribtutions can turn into regular F/LOSS contributions, then maybe sporadic blog posts can turn into regular blog posts, too. Time will tell.

9 October 2020

Bits from Debian: Salsa CI now includes i386 build support

Salsa CI pipeline with i386 build support Salsa CI aims at improving the Debian packaging lifecycle by delivering Continuous Integration fully compatible with Debian packaging. The main Salsa CI's project is the pipeline, that builds packages and run different tests after every git push to Salsa. The pipeline makes it possible to have a quick and early feedback about any issues the new changes may have created or solved, without the need to upload to the archive. All of the pipeline jobs run on amd64 architecture, but the Salsa CI Team has recently added support to build packages also on i386 architecture. This work started during the Salsa CI Sprint at DebConf20 after the "Where is Salsa CI right now" talk, and required different changes at the core of pipeline to make it possible. For more details, this is the related merge request: https://salsa.debian.org/salsa-ci-team/pipeline/-/merge_requests/256 If you have any questions, you can contact the Salsa CI Team at the #salsaci channel on irc.oftc.net

Yves-Alexis Perez: Airplane pilot

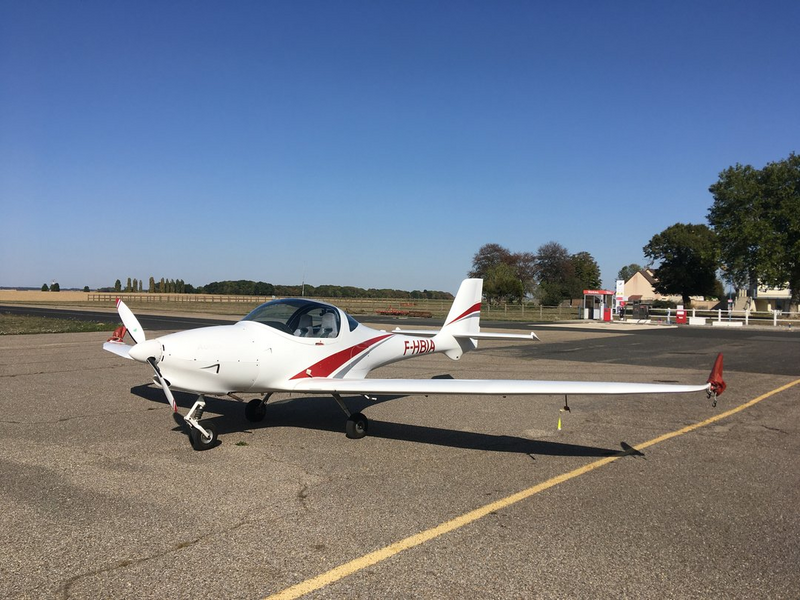
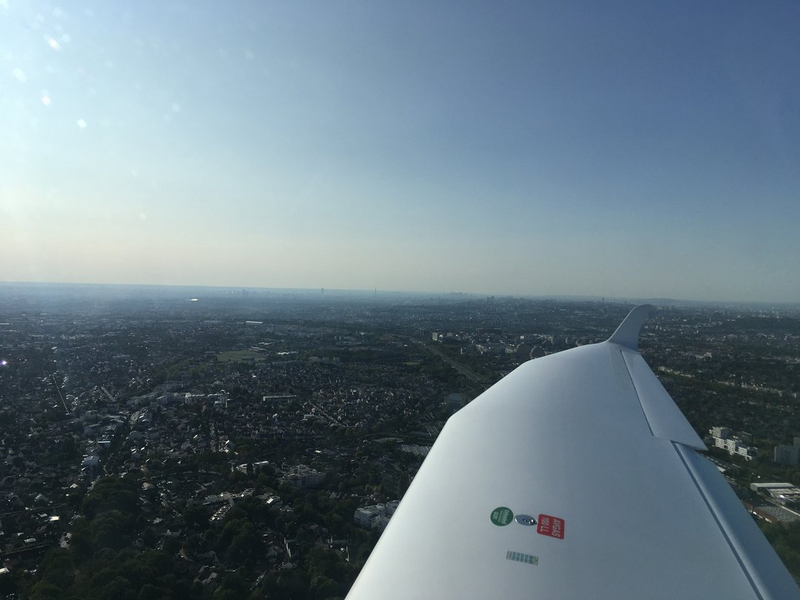
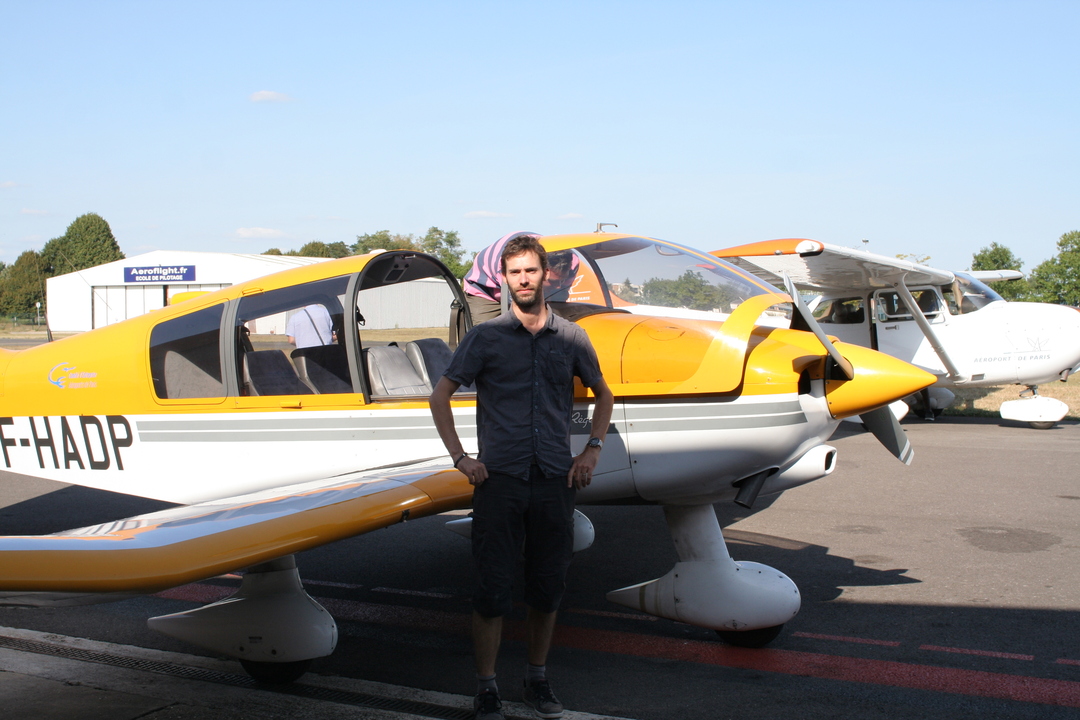
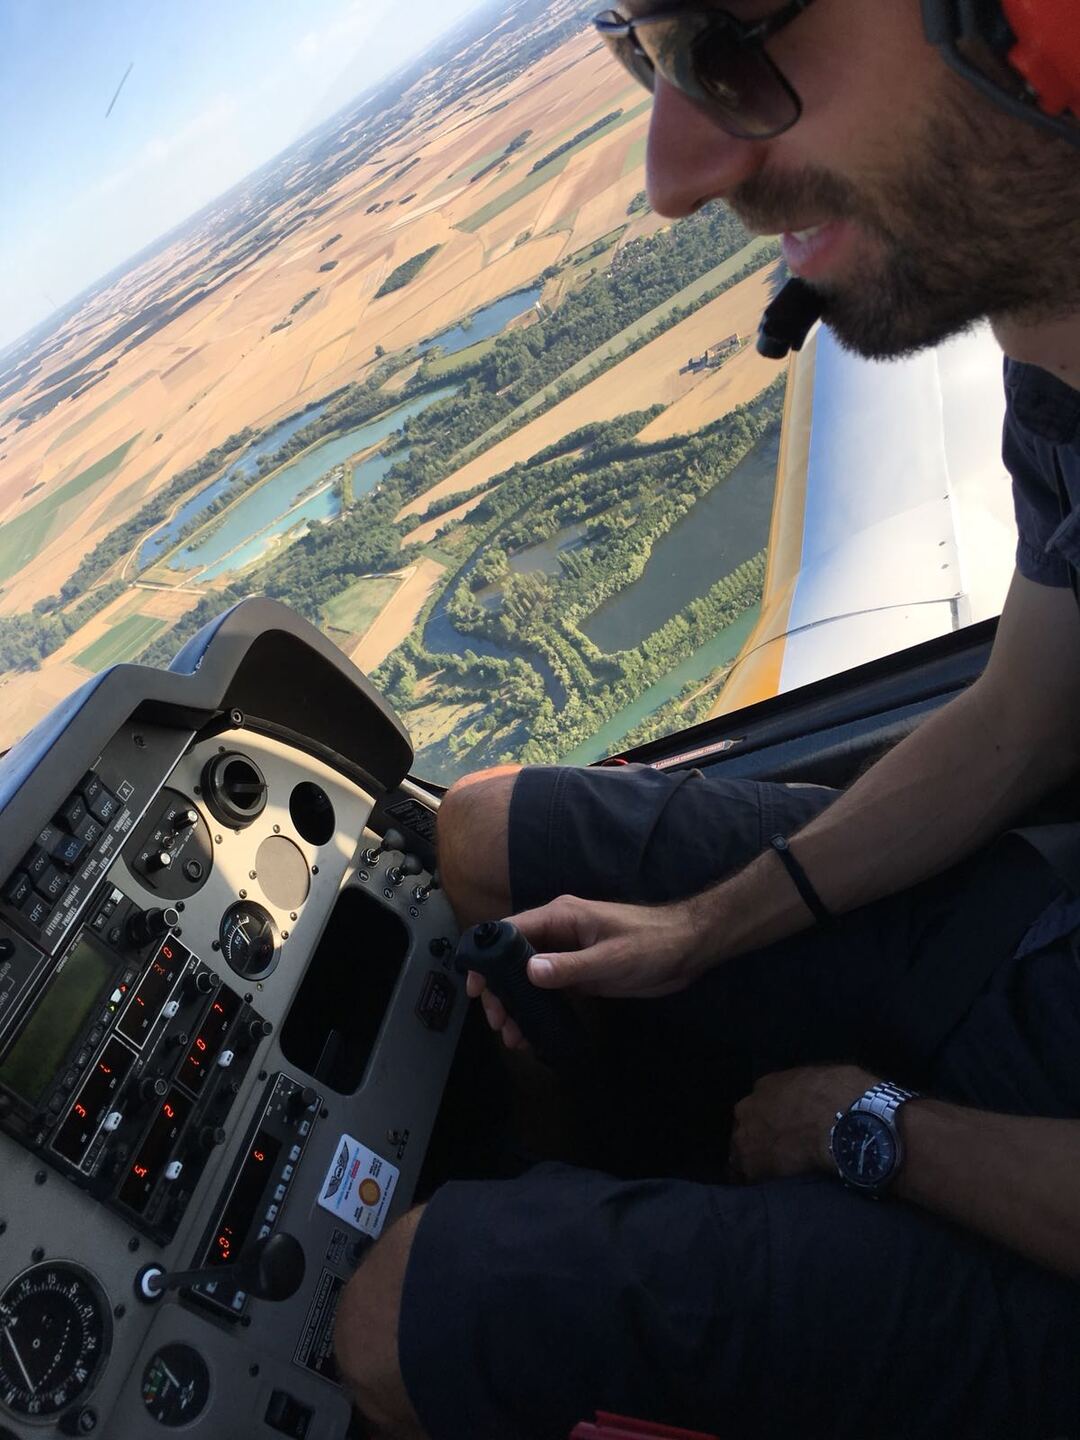
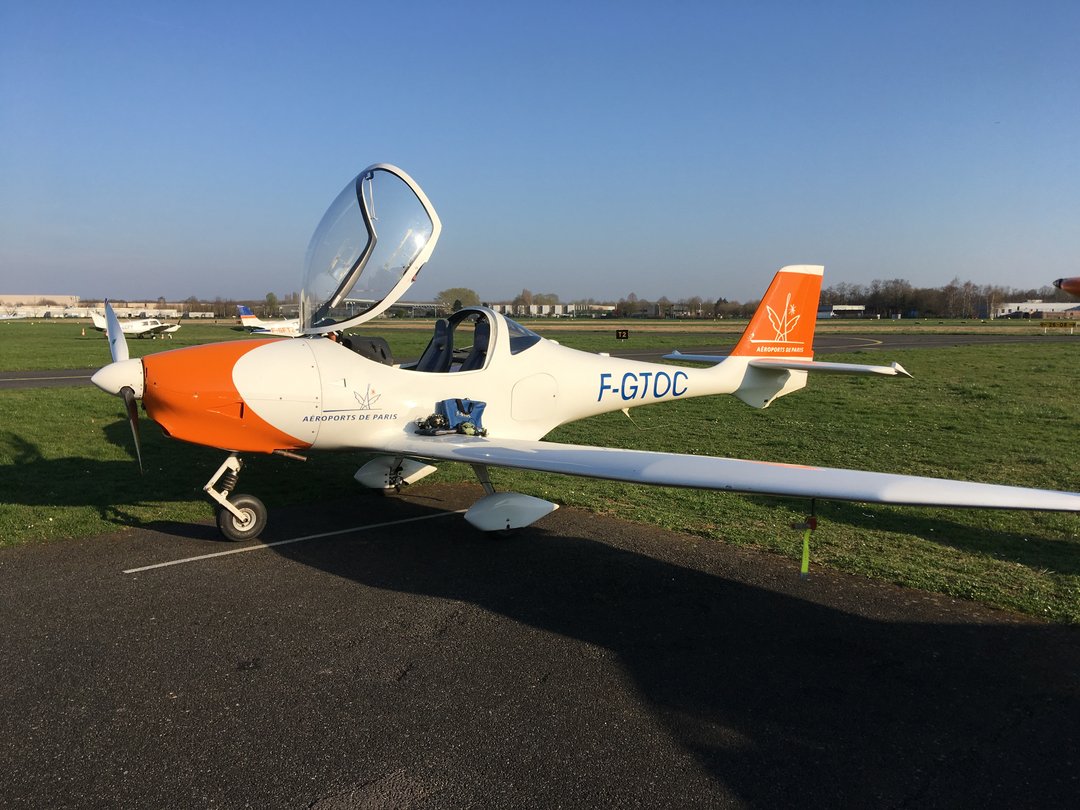
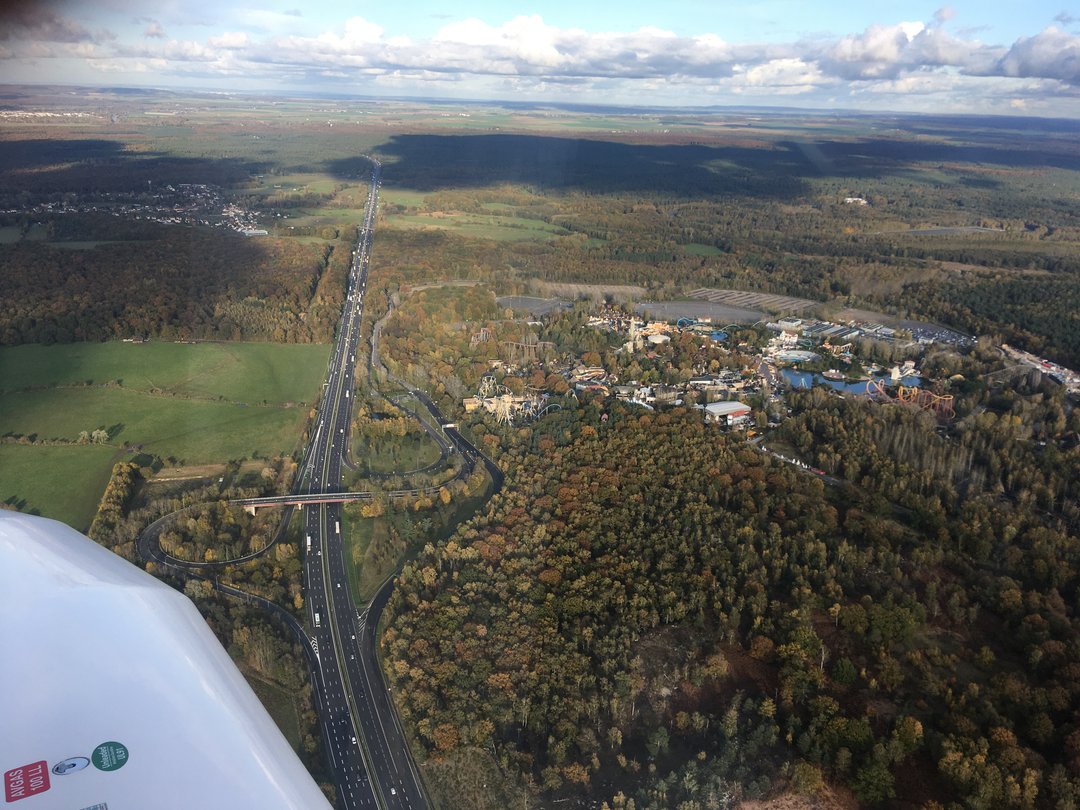
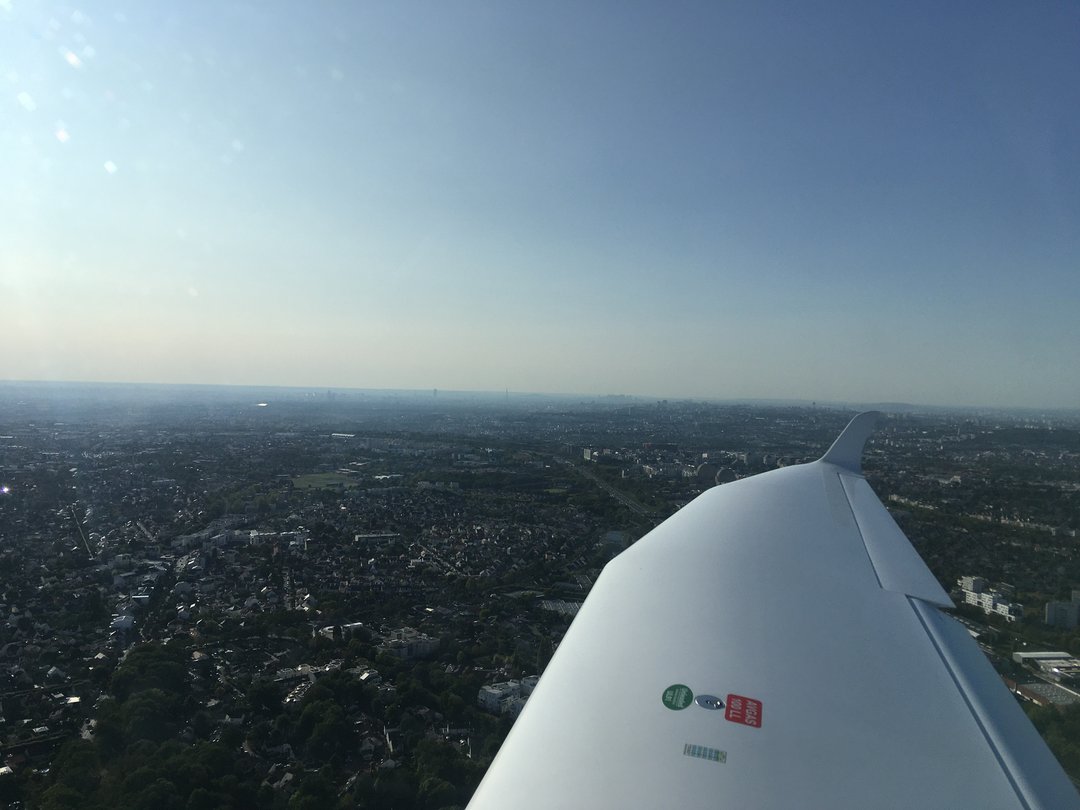
So, a bit more thank 18 months ago, I started a new adventure. After a few flights with a friend of mine in a Robin DR400 and Jodel aircrafts, I enlisted in a local flight club at the Lognes airfield (LFPL), and started a Pilot Private License training. A PPL is an international flight license for non commercial operations. Associated with a qualification like the SEP (Single Engine Piston), it enables you to fly basically anywhere in the world (or at least anywhere where French is spoken by the air traffic controllers) with passengers, under Visual Flight Rules (VFR).
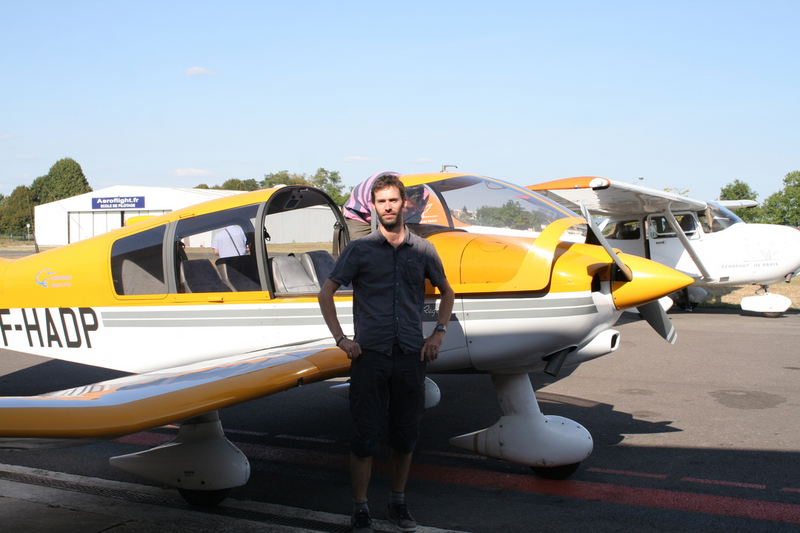
A bit like with cars, training has two parts, theoretical and practical, both validated in a test. You don't have to pass the theoretical test before starting the practical training, and it's actually recommended to do both in parallel, especially since nowadays most of the theoretical training is done online (you still have to do 10h of in-person courses before taking the test).
So in March 2019 I started both trainings. Theoretical training is divided in various domains, like regulations, flight mechanics, meteorology, human factors etc. and you can obviously train in parallel. Practical is more sequential and starts with basic flight training (turns, climbs, descents), then take-off, then landing configuration, then landing itself. All of that obviously with a flight instructor sitting next to you (you're on the left seat but the FI is the pilot in command ). You then start doing circuit patterns, meaning you take off, do a circuit around the airfield, then land on the runway you just took off. Usually you actually don't do a complete landing but rather touch and go, and do it again in order to have more and more landing training.

Once you know how to take-off, do a pattern and land when everything is OK, you start practicing (still with your flight instructor aboard) various failures: especially engine failures at take off, but also flaps failure and stuff like that, all that while still doing patterns and practicing landings. At one point, the flight instructor deems you ready: he exits the plane, and you start your first solo flight: engine tests, take off, one pattern, landing.

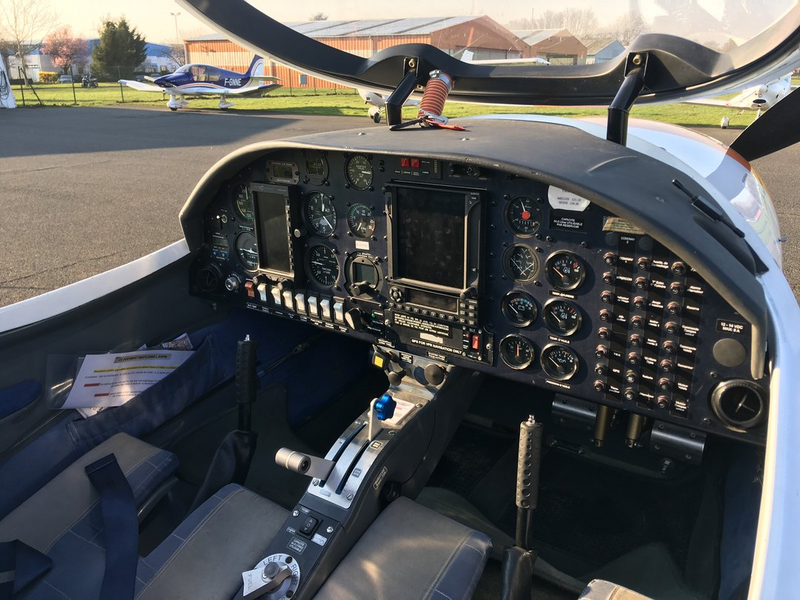
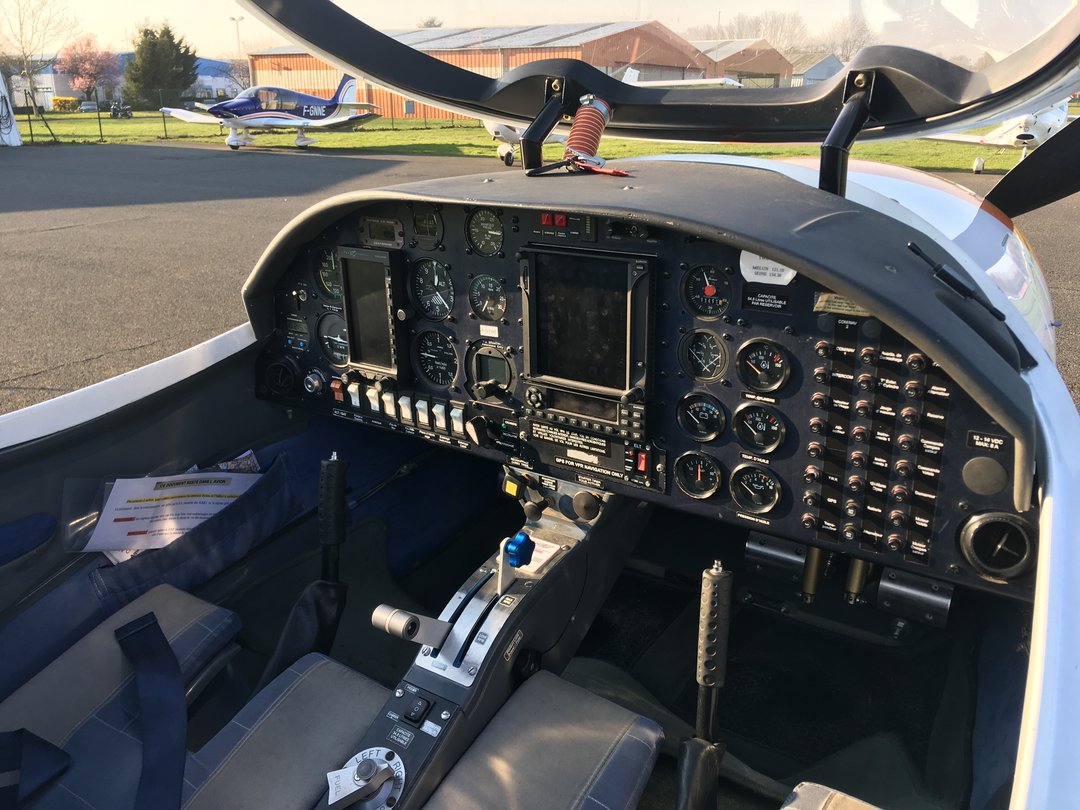
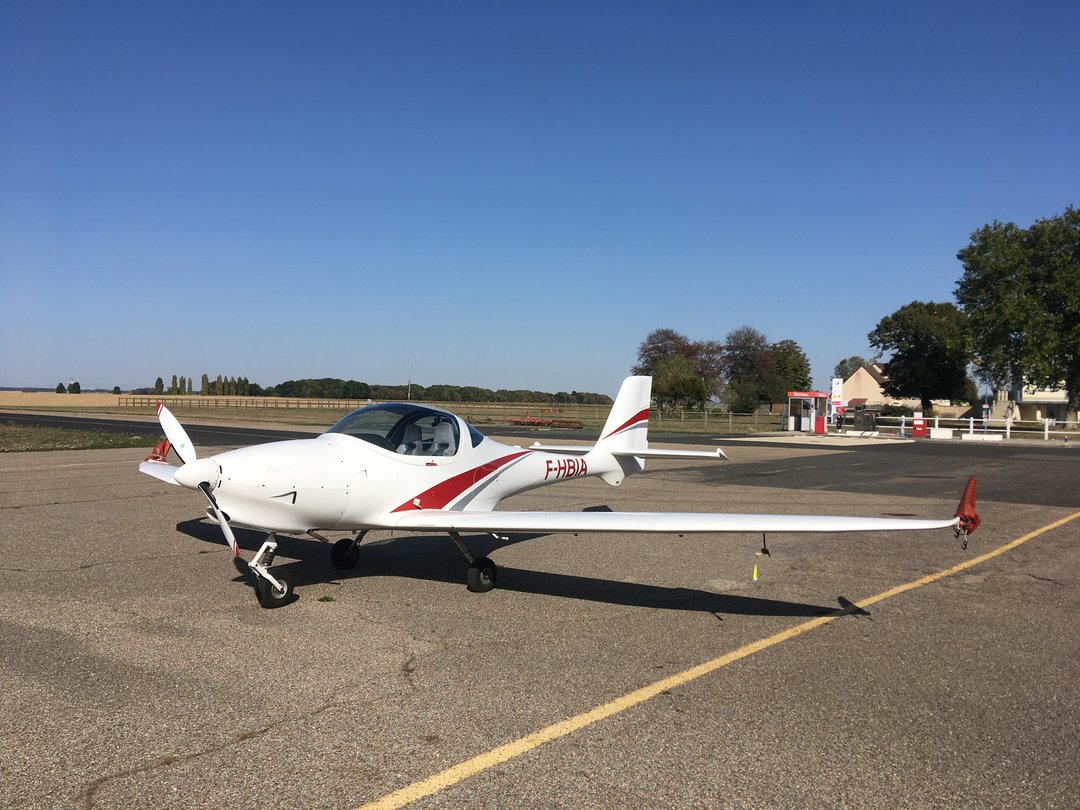
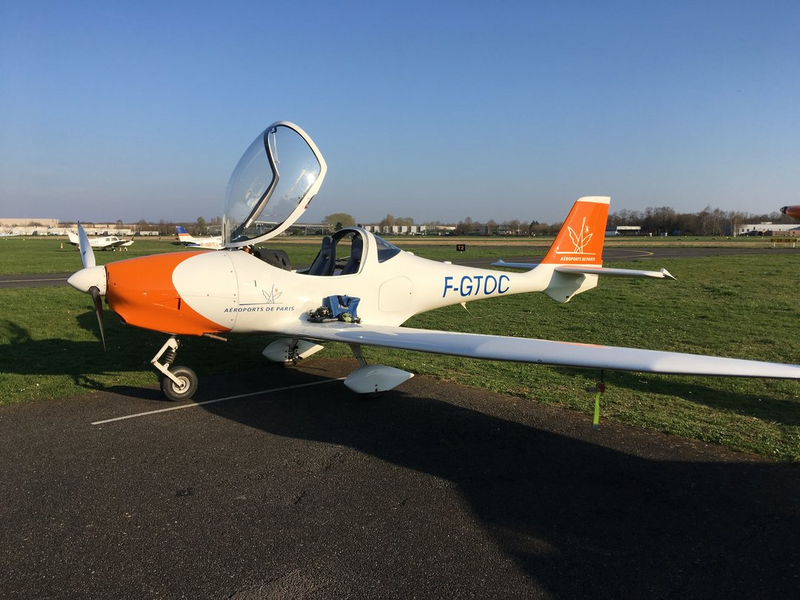
For me practical training was done in an Aquila AT-01/A210, which is a small 2-seater. It's really light (it can actually be used as an ultralight), empty weight is a bit above 500kg and max weight is 750. It doesn't go really fast (it cruises at around 100 knots, 185 km/h) but it's nice to fly. As it's really lightweight the wind really shakes it though and it can be a bit hard to land because it really glides very well (with a lift-to-drag ratio at 14). I tried to fly a lot in the beginning, so the basic flight training was done in about 6 months and 23 flight hours. At that point my instructor stepped out of the plane and I did my first solo flight. Everything actually went just fine, because we did repeat a lot before that, so it wasn't even that scary. I guess I will remember my whole life, as people said, but it was pretty uneventful, although the controller did scold me a little because when taxiing back to the parking I misunderstood the instructions and didn't stop where asked (no runway incursion though).
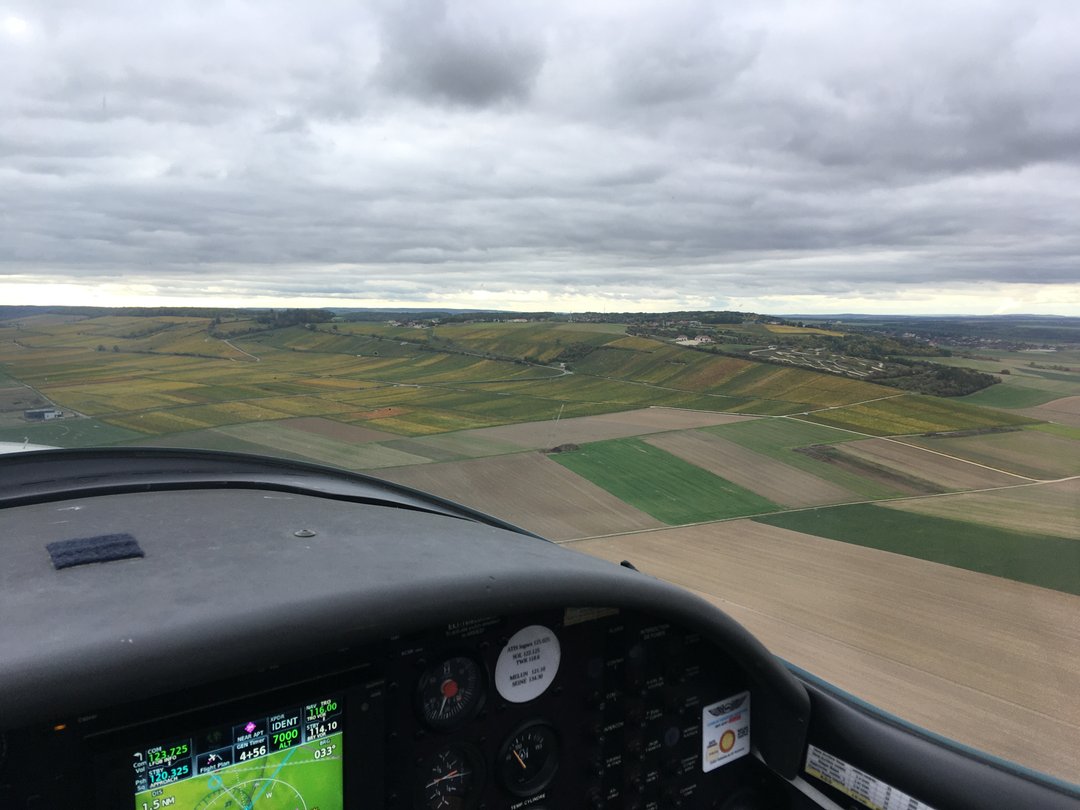
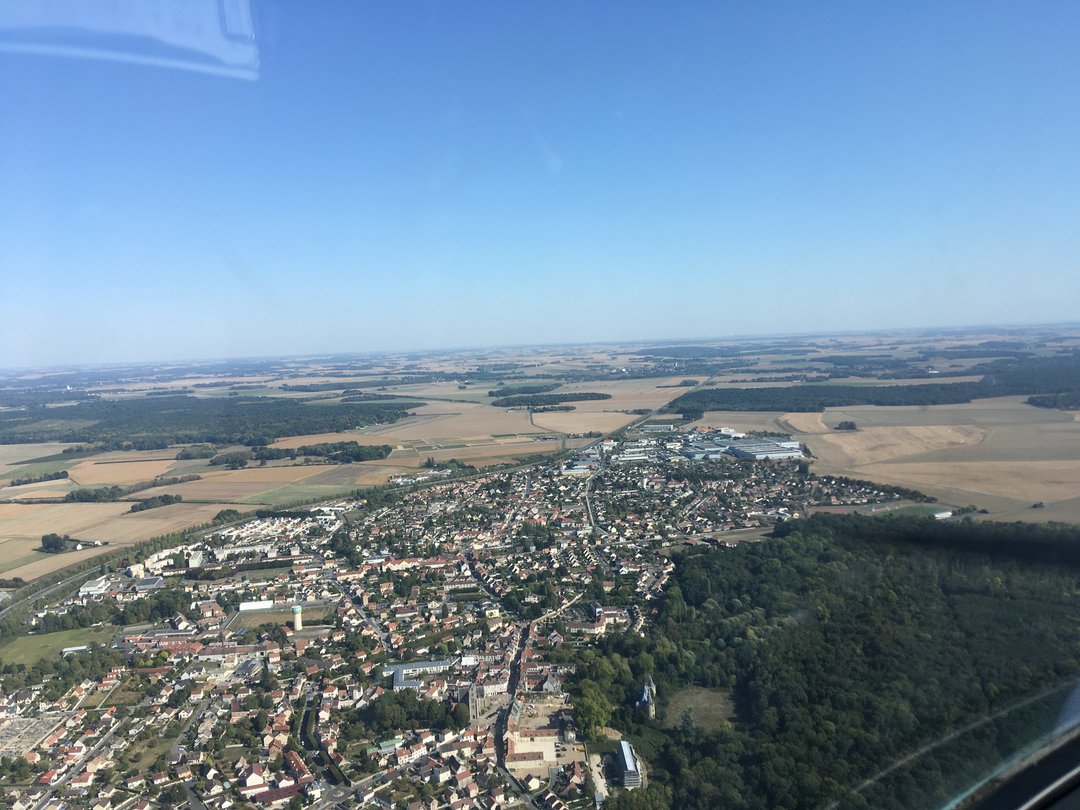
After the first solo flight, you keep practicing patterns and solo flights every once in a while, and start doing cross-country flights: you're not restricted to the local airfields (LFPL, LFAI, LFPK) but start planning trips to more remote airports, about 30-40 minutes away (for me it was Moret/LFPU, Troyes/LFQB, Pontoise/LFPT). Cross country flights requires you to plan the route (draw it on the map, and write a navigation log so you know what to do when in flight), but also check the weather, relevant information, especially NOTAMs - Notice To Air Men (I hope someone rename those Notice to Air Crews at one point), estimate the fuel needed etc. For me, flight preparation time was between once and twice the flight time. Early flight preparation is completed on the day by last-minute checks, especially for weather. During the briefing (with the flight instructor at first, but for the test with the flight examiner and later with yourself) you check in turn every bit of information to decide if you're GO or not for the flight. As a lot of things in aviation, safety is really paramount here.
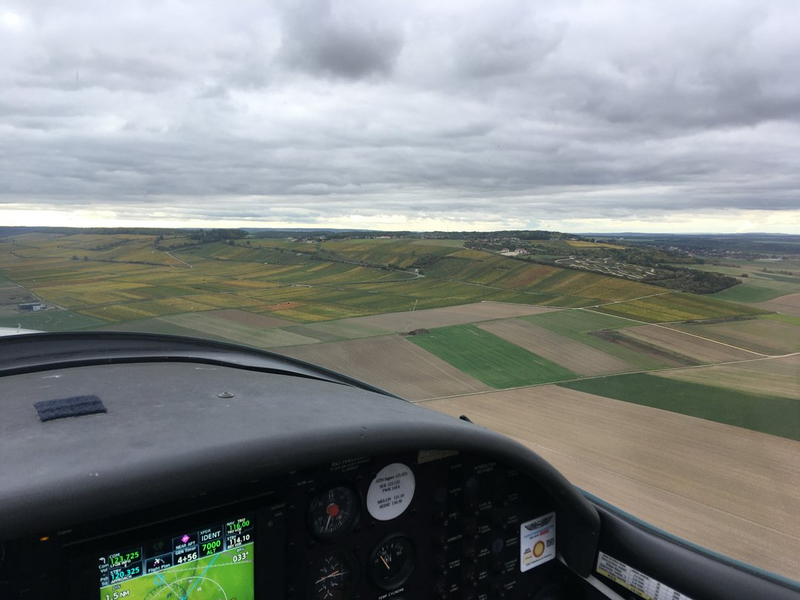
Once you've practiced cross country flight a bit, you start learning what to do in case of failures during a non-local flights, for example an engine failure in a middle of nowhere, when you have to chose a proper field to land, or a radio failure. And again when you're ready for it (and in case of my local club, once you pass your theoretical exam) you go for cross-country solo flights (of the 10h of solo flight required for taking the test, 5h should be done in cross-country flights). I went again to Troyes (LFQB), then Dijon-Darois (LFGI) and did a three-legs flight to Chalons-Ecury (LFQK) and Pont sur Yonne (LFGO).

And just after that, when I was starting to feel ready for the test, COVID-19 lockdown happened, grounding everyone for a few months. Even after it was over, I felt a bit rusty and had to take some more training. I finally took the test in the beginning of summer, but the first attempt wasn't good enough: I was really stressed, and maybe not completely ready actually. So a bit more training during summer, and finally in September I took the final test part, which was successful this time.

After some paperwork, a new, shiny, Pilot Private License arrived at my door.
And now that I can fly basically when I want, the autumn is finally here with bad weather all day long, so actually planning real flights is a bit tricky. For now I'm still flying solo on familiar trips, but at some point I should be able to bring a passenger with me (on the Aquila) and at some point migrate to a four-seaters like the DR400, ubiquitous in France.
Jonathan Dowland: New Bike

I grew up riding bikes with my friends, but I didn't keep it up once I went to University. A couple of my friends persevered and are really good riders, even building careers on their love of riding. I bought a mountain bike in 2006 (a sort of "first pay cheque" treat after changing roles) but didn't really ride it all that often until this year. Once Lockdown began, I started going for early morning rides in order to get some fresh air and exercise. Once I'd got into doing that I decided it was finally time to buy a new bike. I knew I wanted something more like a "hybrid" than a mountain bike but apart from that I was clueless. I couldn't even name the top manufacturers. Ross Burton a friend from the Debian community suggested I take a look at Cotic, a small UK-based manufacturer based in the peak district. Specifically their Escapade gravel bike. (A gravel bike, it turns out, is kind-of like a hybrid.)
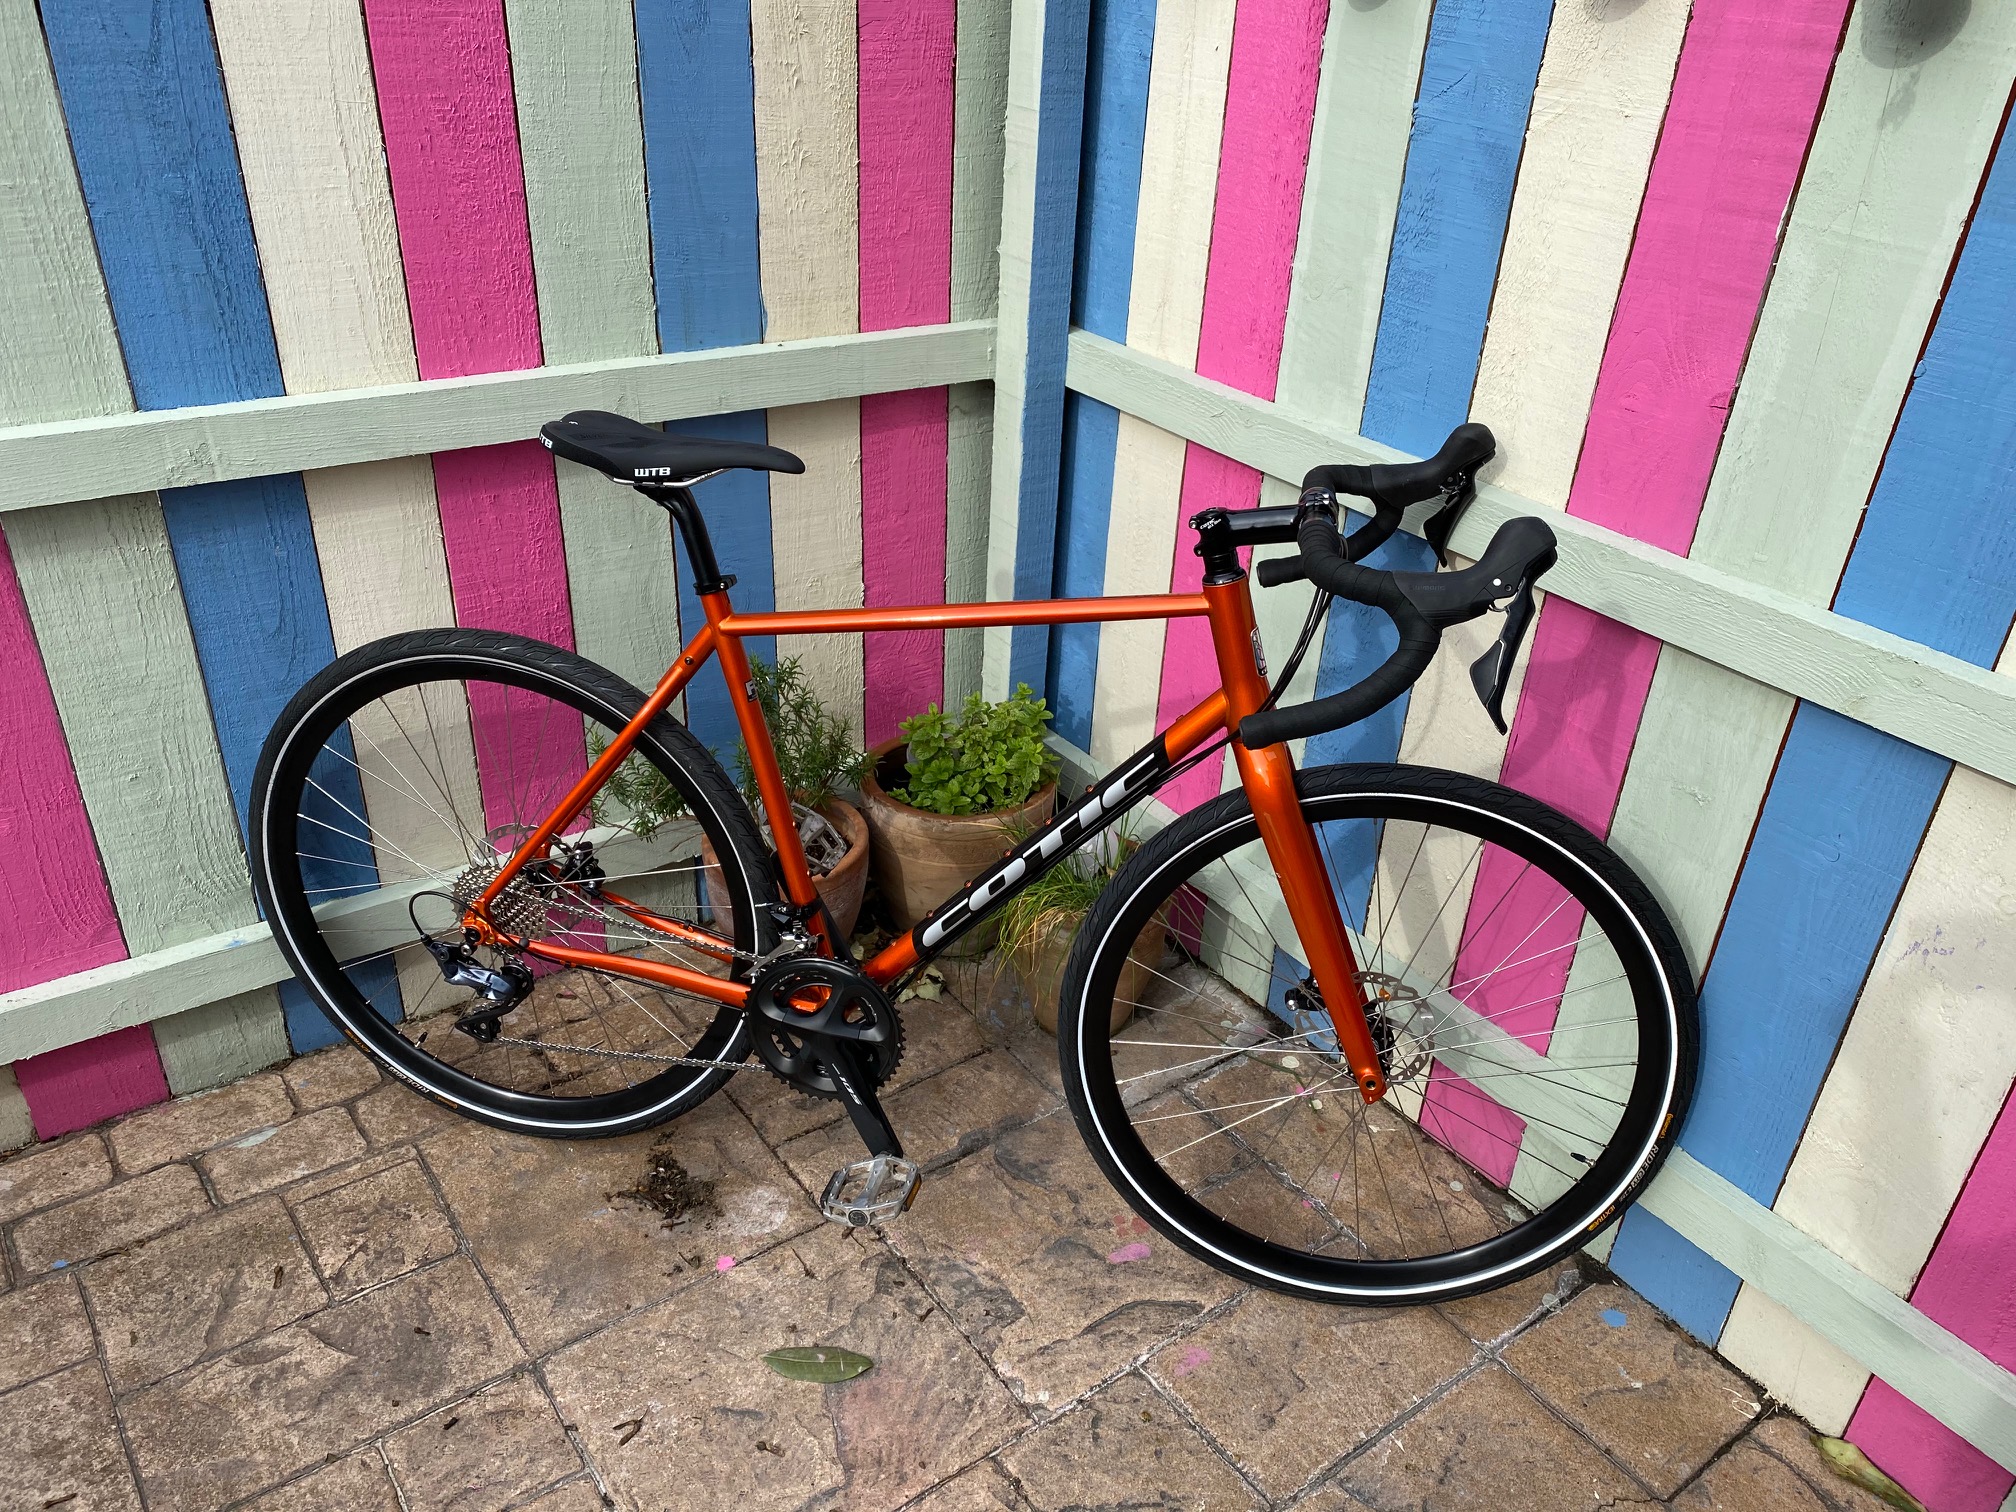
My new Cotic Escapade My new Cotic Escapade
I did some due diligence, looked at some other options, put together a spreadsheet etc but the Escapade was the clear winner. During the project I arranged to have a socially distant cup of tea with my childhood friend Dan, now a professional bike mechanic, who by coincidence arrived on his own Cotic Escapade. It definitely seemed to tick all the boxes. I just needed to agonise over the colour choices: Metallic Orange (a Cotic staple) or a Grey with some subtle purple undertones. I was leaning towards the Grey, but ended up plumping for the Orange. I could just cover it under Red Hat UK s cycle to work scheme. I m very pleased our HR dept is continuing to support the scheme, in these times when they also forbid me from travelling to the office. And so here we are. I m very pleased with it! Perhaps I'll write more about riding, or post some pictures, going forward.

8 October 2020

Molly de Blanc: COVID and Reflections on Jessica Flanigan

One of the points Flanigan makes in her piece Seat Belt Mandates and Paternalism is that we re conditioned to use seat belts from a very early age. It s a thing we internalize and build into our understanding of the world. People feel bad when they don t wear a seat belt.(1) They re unsettled. They feel unsafe. They feel like they re doing something wrong. Masks have started to fit into this model as well. Not wearing a mask feels wrong. An acquaintance shared a story of crying after realizing they had left the house without a mask. For some people, mask wearing has been deeply internalized. We have regular COVID tests at NYU. Every other week I spit into a tube and then am told whether I am safe or sick. This allows me to hang out with my friends more confident than I would feel otherwise. This allows me to be closer to people than I would be otherwise. It also means that if I got sick, I would know, even if I was asymptomatic. If this happened, I would need to tell my friends. I would trace the places I ve been, the people I ve seen, and admit to them that I got sick. I would feel shame because something I did put me in that position. There were (are?) calls to market mask wearing and COVID protection with the same techniques we use around sex: wear protection, get tested, think before you act, ask consent before touching, be honest and open with the people around you about your risk factors. This is effective, at least among a swath of the population, but COVID has effectively become another STD. It s a socially transmitted disease that we have tabooified into creating shame in people who have it. The problem with this is, of course, that COVID isn t treatable in the same way syphilis and chlamydia are. Still, I would ask whether people don t report, or get tested, or even wear masks, because of shame? In some communities, wearing a mask is a sign that you re sick. It s stigmatizing.(2) I think talking about COVID the way we talk about sex is not the right approach because, in my experience, the ways I learned about sex were everything from factually wrong to deeply harmful. If what we re doing doesn t work, what does? (1) Yes, I know not everyone. (2) Many men who don t wear masks cite it as feeling emasculating, rather than stigmatizing.

Dirk Eddelbuettel: littler 0.3.12: Exciting updates

max-heap image The thirteenth release of littler as a CRAN package became available today (after a three day rest at CRAN for no real reason), following in the fourteen-ish year history as a package started by Jeff in 2006, and joined by me a few weeks later. littler is the first command-line interface for R as it predates Rscript. It allows for piping as well for shebang scripting via #!, uses command-line arguments more consistently and still starts faster. It also always loaded the methods package which Rscript only started to do in recent years. littler lives on Linux and Unix, has its difficulties on macOS due to yet-another-braindeadedness there (who ever thought case-insensitive filesystems as a default where a good idea?) and simply does not exist on Windows (yet the build system could be extended see RInside for an existence proof, and volunteers are welcome!). See the FAQ vignette on how to add it to your PATH. A few examples are highlighted at the Github repo, as well as in the examples vignette. This release brings five new example scripts and command wrappers: A number of commands were also extended or updated (see below for more). We have a new and very slick documentation website once again utilising Material for MkDocs. Last but not least the two included vignettes now use minidown and the fabulous water css theme which reduced the file sizes of the two vignettes from, respectively, 884kb and 873kb to 47kb and 15kb. Yes, that is correct. That alone brought the package file size down from 641kb to 116kb. Incredible. The NEWS file entry is below.

Changes in littler version 0.3.12 (2020-10-04)
  • Changes in examples
    • Updates to scripts tt.r, cos.r, cow.r, c4r.r, com.r
    • New script installDeps.r to install dependencies
    • Several updates tp script check.r
    • New script installBSPM.r and installRSPM.r for binary package installation (Dirk and I aki in #81)
    • New script cranIncoming.r to check in Incoming
    • New script urlUpdate.r validates URLs as R does
  • Changes in package
    • Travis CI now uses BSPM
    • A package documentation website was added
    • Vignettes now use minidown resulting in much reduced filesizes: from over 800kb to under 50kb (Dirk in #83)

My CRANberries provides a comparison to the previous release. Full details for the littler release are provided as usual at the ChangeLog page, and now also on the new package docs website. The code is available via the GitHub repo, from tarballs and now of course also from its CRAN page and via install.packages("littler"). Binary packages are available directly in Debian as well as soon via Ubuntu binaries at CRAN thanks to the tireless Michael Rutter. Comments and suggestions are welcome at the GitHub repo. If you like this or other open-source work I do, you can now sponsor me at GitHub. For the first year, GitHub will match your contributions.

This post by Dirk Eddelbuettel originated on his Thinking inside the box blog. Please report excessive re-aggregation in third-party for-profit settings.

6 October 2020

Iustin Pop: Late report for Nationalpark Bike Marathon 2020

I don t have to mention that 2020 is a special year, so all the normal race plan was out the window, and I was very happy and fortunate to be able to do even one race. And only delayed 3 weeks to write this race report :/ So, here s the story

Preparing for the race Because it was a special year, and everything was crazy, I actually managed to do more sports than usual, at least up to end of July. So my fitness, and even body weight, was relatively fine, so I subscribed to the mid-distance race (official numbers: 78km distance, 1570 meters altitude), and then off it went to a proper summer vacation in a hotel, even. And while I did do some bike rides during that vacation, from then on my training regime went just off? I did train, I did ride, I did get significant PRs, but it didn t click anymore. Plus, due to well, actually not sure what, work or coffee or something my sleep regime also got completely ruined On top of that, I didn t think about the fact that the race was going to be mid-September, and that high up in the mountains, the weather could have be bad enough (I mean, in 2018 the weather was really bad even in August ) such that I d need to seriously think about clothing.

Race week I arrive in Scuol two days before the race, very tired (I think I got only 6 hours of sleep the night before), and definitely not in a good shape. I was feeling bad enough that I was not quite sure I was going to race. At least weather was OK, such that normal summer clothing would suffice. But the race info was mentioning dangerous segments, to be very careful, etc. etc. so I was quite anxious. Note 1: my wife says, this was not the first time, and likely not the last time that two days before the race I feel like quitting. And as I m currently on-and-off reading the interesting The Brave Athlete: Calm the Fuck Down and Rise to the Occasion book (by Lesley Paterson and Simon Marshall; it s an interesting book, not sure if I recommend it or not), I am beginning to think that this is my reaction to races where I have overshot my usual distance. Or, in general, races where I fear the altitude gain. Not quite sure, but I think it is indeed the actual cause. So I spend Thursday evening feeling unwell, and thinking I ll see how Friday goes. Friday comes, and having slept reasonably well entire night, I pick up my race number, then I take another nap in the afternoon - in total, I ve slept around 13 hours that day. So I felt much better, and was looking forward to the race. Saturday morning comes, I manage to wake up early, and get ready in time; almost didn t panic at all that I m going to be late. Note 2: my wife also says that this is the usual way I behave. Hence, it must be most of it a mental issue, rather than real physical one

Race I reach the train station in time, I get on the train, and by the time the train reached Zernez, I fully calm down. There was am entire hour wait though before the race, and it was quite chilly. Of course I didn t bring anything beside what I was wearing, relying on temperature getting better later in the day. During the wait, there were two interesting things happening. First, we actually got there (in Zernez) before the first people from the long distance passed by, both men and women. Seeing them pass by was cool, thinking they already had ~1 200m altitude in just 30-ish kilometres. The second thing was, as this was the middle and not the shortest distance, the people in the group looked differently than in previous years. More precisely, they were looking very fit, and I was feeling fat. Well, I am overweight, so it was expected, but I was feeling it even more than usual. I think only one or two in ten people were looking as fit as me or less And of course, the pictures post-race show me even less fit-looking than I thought. Ah, self-deception is a sweet thing And yes, we all had to wear masks, up until the last minute. It was interesting, but not actually annoying - and small enough price for being able to race! Then the race starts, and as opposed to many other years, it starts slow. I didn t feel that rush of people starting fast, it was reasonable?

First part of the race (good) Thus started the first part of the race, on a new route that I was unfamiliar with. There was not too much climbing, to be honest, and there was some tricky single-trail through the woods, with lots of the roots. I actually had to get off the bike and push it, since it was too difficult to pedal uphill on that path. Other than that, I was managing so far to adjust my efforts well enough that my usual problems related to climbing (lower back pain) didn t yet appear, even as the overall climbed meters were increasing. I was quite happy at that, and had lots of reserves. To my (pleasant) surprise, two positive things happened:
  • I was never alone, a sign that I wasn t too far back.
  • I was passing/being passed by people, both on climbs but also on descents! It s rare, but I did overtake a few people on a difficult trail downhill.
With all the back and forth, a few people became familiar (or at least their kit), and it was fun seeing who is better uphill vs. downhill.

And second part (not so good) I finally get to (around) S-chanf, on a very nice but small descent, and on flat roads, and start the normal route for the short race. Something was off though - I knew from past years that these last ~47km have around 700-800m altitude, but I had already done around 1000m. So the promised 1571m were likely to be off, by at least 100-150m. I set myself a new target of 1700m, and adjust my efforts based on that. And then, like clockwork on the 3:00:00 mark, the route exited the forest, the sun got out of the clouds, and the temperature started to increase from 16-17 C to 26 +, with peaks of 31 C. I m not joking: at 2:58:43, temp was 16 , at 3:00:00, it was 18 , at 3:05:45, it was 26 . Heat and climbing are my two nemeses, and after having a pretty good race for the first 3 hours and almost exactly 1200m of climbing, I started feeling quite miserable. Well, it was not all bad. There were some nice stretches of flat, where I knew I can pedal strongly and keep up with other people, until my chain dropped, so I had to stop, re-set it, and lose 2 minutes. Sigh. But, at least, I was familiar with this race, or so I thought. I completely mis-remembered the last ~20km as a two-punch climb, Guarda and Ftan, whereas it is actually a three-punch one: Guarda, Ardez, and only then Ftan. Doesn t help that Ardez has the nice ruins that I was remembering and which threw me off. The saddest part of the day was here, on one of the last climbs - not sure if to Guarda or to Arddez, where a guy overtakes me, and tells me he s glad he finally caught up with me, he almost got me five or six times (!), but I always managed to break off. Always, until now. Now, this was sad (I was huffing and puffing like a steam locomotive now), but also positive, as I never had that before. One good, one bad? And of course, it was more than 1 700m altitude, it was 1 816m. And the descent to Scuol shorter and it didn t end as usual with the small but sharp climb which I just love, due to Covid changes. But, I finished, and without any actual issues, and no dangerous segments as far as I saw. I was anxious for no good reason

Conclusion (or confusion?) So this race was interesting: three hours (to the minute) in which I went 43.5km, climbed 1200m, felt great, and was able to push and push. And then the second part, only ~32km, climbed only 600m, but which felt quite miserable. I don t know if it was mainly heat, mainly my body giving up after that much climbing (or time?), or both. But it s clear that I can t reliably race for more than around these numbers: 3 hours, ~1000+m altitude, in >20 C temperature. One thing that I managed to achieve though: except due to the technically complex trail at the beginning where I pushed the bike, I did not ever stop and push the bike uphill because I was too tired. Instead, I managed (badly) to do the switch sitting/standing as much as I could motivate myself, and thus continue pushing uphill. This is an achievement for me, since mentally it s oh so easy to stop and push the bike, so I was quite glad. As to the race results, they were quite atrocious:
  • age category (men), 38 out of 52 finishers, 4h54m, with first finisher doing 3h09m, so 50% slower (!)
  • overall (men), 138 out of 173 finishers, with first finisher 2h53m.
These results clearly don t align with my feeling of a good first half of the race, so either it was purely subjective, or maybe in this special year, only really strong people registered for the race, or something else One positive aspect though, compared to most other years, was the consistency of my placement (age and overall):
  • Zuoz: 38 / 141
  • S-Chanf: 39 / 141
  • Zernez: 39 / 141
  • Guarda: 38 / 138
  • Ftan: 38 / 138
  • ( next - whatever this is): 38 / 138
  • Finish: 38 / 138
So despite all my ranting above, and all the stats I m pulling out of my own race, it looks like my position in the race was fully settled in the really first part, and I didn t gain nor lose practically anything afterwards. I did dip one place but then gained it back (on the climb to Guarda, even). The split times (per-segment rankings) are a bit more variable, and show that I was actually fast on the climbs but losing speed on the descents, which I really don t understand anymore:
  • Zernez-Zuoz (unclear type): 38 / 141
  • Zuoz-S-Chanf (unclear type): 40 / 141
  • S-Chanf-Zernez (mostly downhill): 39 / 143
  • Zernez-Guarda (mostly uphill): 37 / 136
  • Guarda-Ftan (mostly uphill): 37 / 131
  • Ftan-Scuol (mostly downhill): 43 / 156
The difference at the end is striking. I m visually matching the map positions to km and then use VeloViewer for computing the altitude gain, but Zernez to Guarda is 420m altitude, and Guarda to Ftan is 200m altitude gain, and yet on both, I was faster than my final place, and by quite a few places on overall, only to lose that on the descent (Ftan-Scuol), and by a large margin. So, amongst all the confusion here, I think the story overall is:
  • indeed I was quite fit for me, so the climbs were better than my place in the race (if that makes sense).
  • however, I m not actually good at climbing nor fit (watts/kg), so I m still way back in the pack (oops!).
  • and I do suck at descending, both me (skills) and possible my bike setup as well (too high tyre pressure, etc.) so I lose even more time here
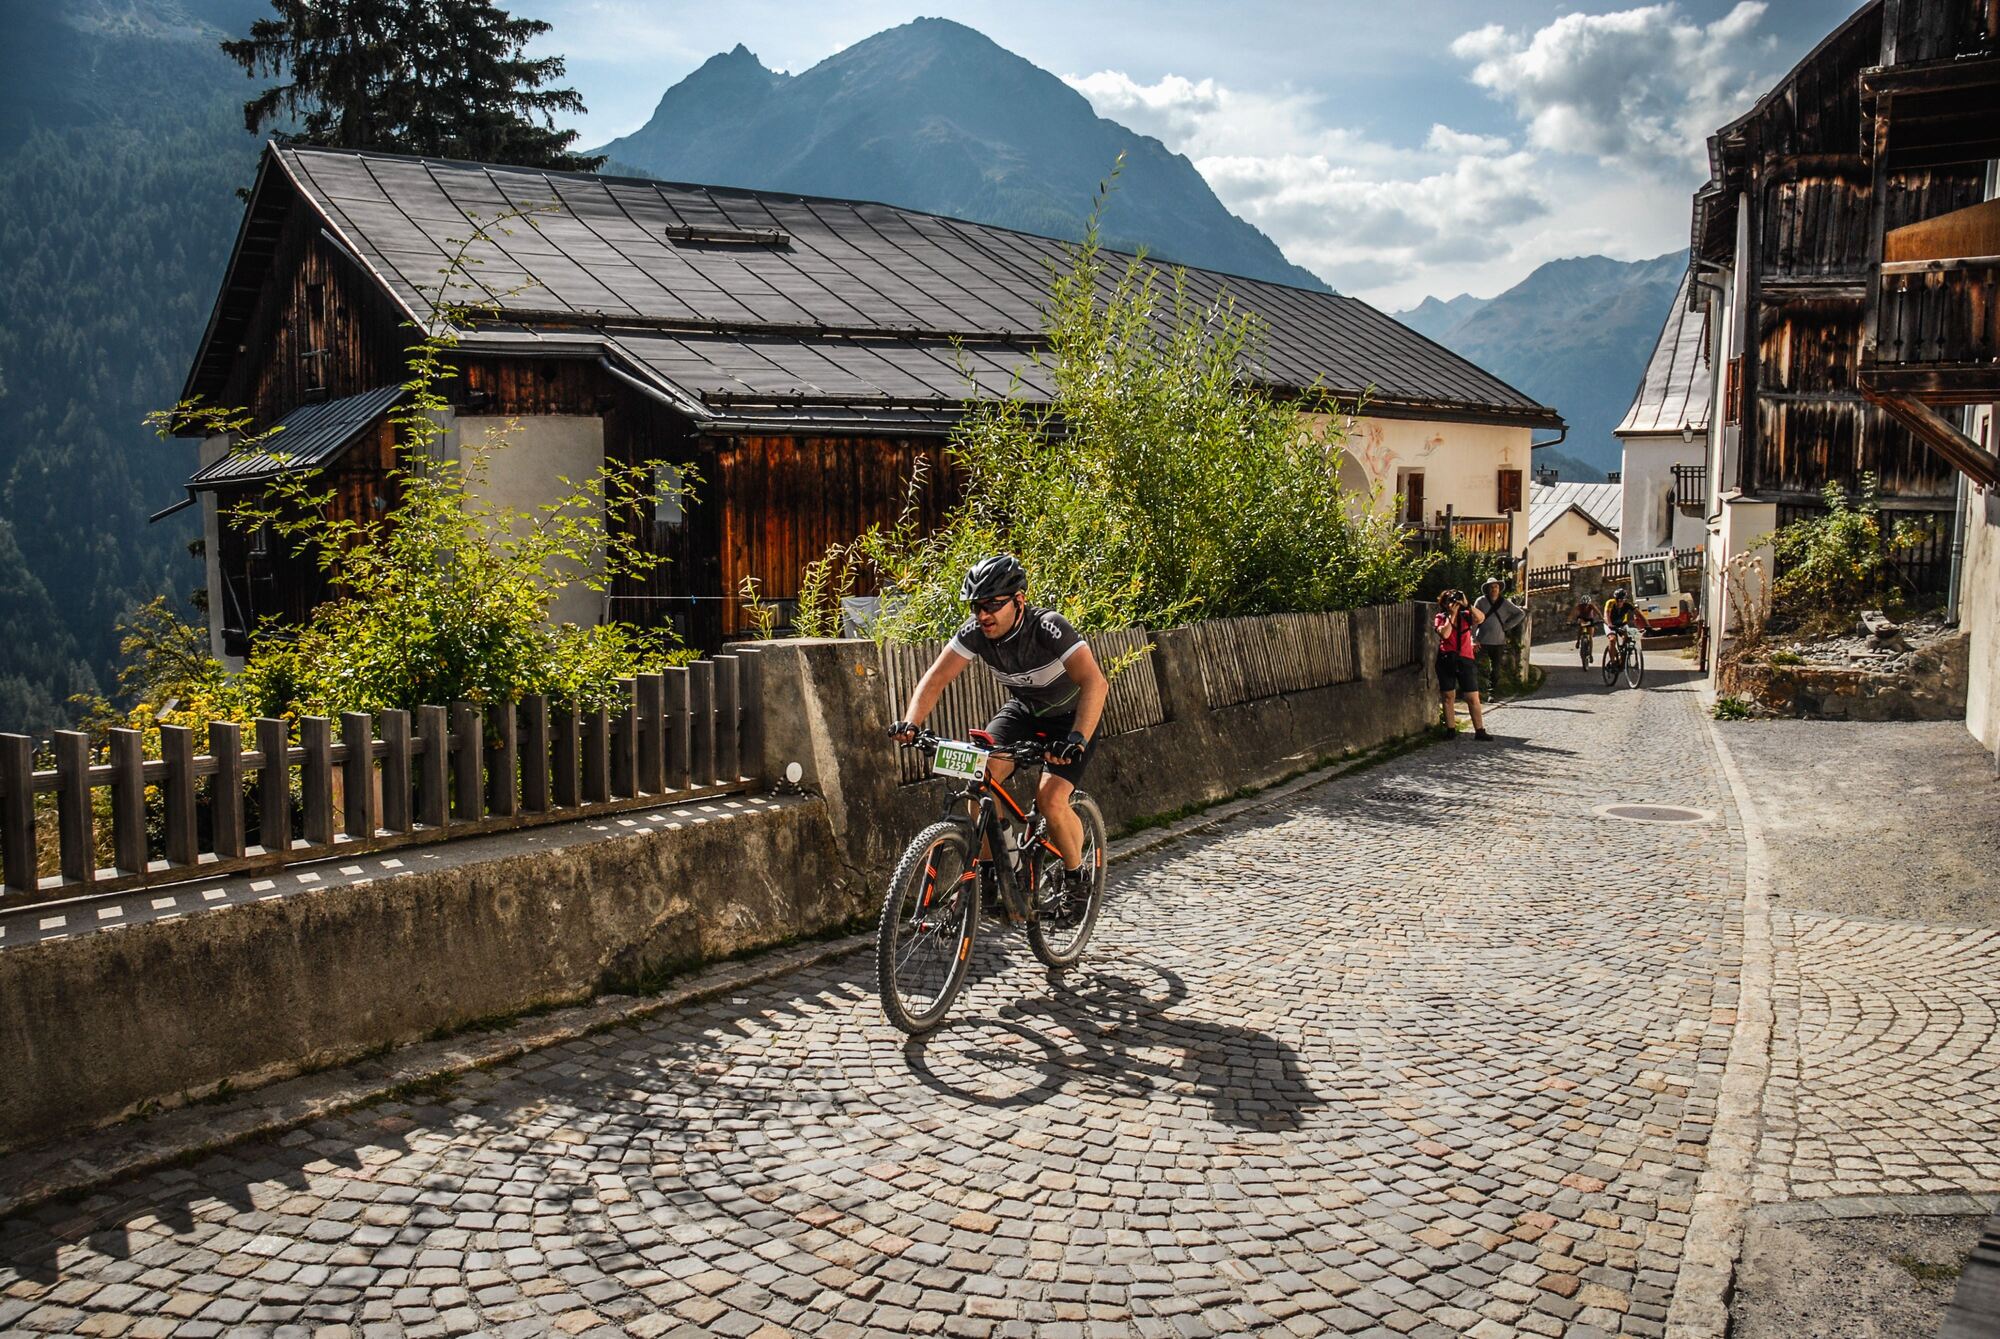
As usual, the final take-away points are: lose the extra weight that is not needed, get better skills, get better core to be better at climbing. I ll finish here with one pic, taken in Guarda (4 hours into the race, more or less):
Climbing in Guarda Climbing in Guarda
Until next year!

Thorsten Alteholz: My Debian Activities in September 2020

FTP master This month I accepted 278 packages and rejected 58. The overall number of packages that got accepted was 304. Debian LTS This was my seventy-fifth month that I did some work for the Debian LTS initiative, started by Raphael Hertzog at Freexian. This month my all in all workload has been 19.75h. During that time I did LTS uploads of: I also started to work on new issues of qemu but had to learn that most of the patches I found have not yet been approved by upstream. So I moved on to python3.5 and cimg. The latter is basically just a header file and I had to find its reverse dependencies to check whether all of them can still be built with the new cimg package. This is still WIP and I hope to upload new versions soon. Last but not least I did some days of frontdesk duties. Debian ELTS This month was the twenty seventh ELTS month. During my allocated time I uploaded: Like in LTS, I also started to work on qemu and encountered the same problems as in LTS above.
When building the new python packages for ELTS and LTS, I used the same VM and encountered memory problems that resulted in random tests failing. This was really annoying as I spent some time just chasing the wind. So up to now only the LTS package got an update and the ELTS one has to wait for October. Last but not least I did some days of frontdesk duties. Other stuff This month I only uploaded some packages to fix bugs:

5 October 2020

Reproducible Builds: Reproducible Builds in September 2020

Welcome to the September 2020 report from the Reproducible Builds project. In our monthly reports, we attempt to summarise the things that we have been up to over the past month, but if you are interested in contributing to the project, please visit our main website. This month, the Reproducible Builds project was pleased to announce a donation from Amateur Radio Digital Communications (ARDC) in support of its goals. ARDC s contribution will propel the Reproducible Builds project s efforts in ensuring the future health, security and sustainability of our increasingly digital society. Amateur Radio Digital Communications (ARDC) is a non-profit which was formed to further research and experimentation with digital communications using radio, with a goal of advancing the state of the art of amateur radio and to educate radio operators in these techniques. You can view the full announcement as well as more information about ARDC on their website.
In August s report, we announced that Jennifer Helsby (redshiftzero) launched a new reproduciblewheels.com website to address the lack of reproducibility of Python wheels . This month, Kushal Das posted a brief follow-up to provide an update on reproducible sources as well. The Threema privacy and security-oriented messaging application announced that within the next months , their apps will become fully open source, supporting reproducible builds :
This is to say that anyone will be able to independently review Threema s security and verify that the published source code corresponds to the downloaded app.
You can view the full announcement on Threema s website.

Events Sadly, due to the unprecedented events in 2020, there will be no in-person Reproducible Builds event this year. However, the Reproducible Builds project intends to resume meeting regularly on IRC, starting on Monday, October 12th at 18:00 UTC (full announcement). The cadence of these meetings will probably be every two weeks, although this will be discussed and decided on at the first meeting. (An editable agenda is available.) On 18th September, Bernhard M. Wiedemann gave a presentation in German titled Wie reproducible builds Software sicherer machen ( How reproducible builds make software more secure ) at the Internet Security Digital Days 2020 conference. (View video.) On Saturday 10th October, Morten Linderud will give a talk at Arch Conf Online 2020 on The State of Reproducible Builds in the Arch Linux distribution:
The previous year has seen great progress in Arch Linux to get reproducible builds in the hands of the users and developers. In this talk we will explore the current tooling that allows users to reproduce packages, the rebuilder software that has been written to check packages and the current issues in this space.
During the Reproducible Builds summit in Marrakesh, GNU Guix, NixOS and Debian were able to produce a bit-for-bit identical binary when building GNU Mes, despite using three different major versions of GCC. Since the summit, additional work resulted in a bit-for-bit identical Mes binary using tcc and this month, a fuller update was posted by the individuals involved.

Development work In openSUSE, Bernhard M. Wiedemann published his monthly Reproducible Builds status update.

Debian Chris Lamb uploaded a number of Debian packages to address reproducibility issues that he had previously provided patches for, including cfingerd (#831021), grap (#870573), splint (#924003) & schroot (#902804) Last month, an issue was identified where a large number of Debian .buildinfo build certificates had been tainted on the official Debian build servers, as these environments had files underneath the /usr/local/sbin directory to prevent the execution of system services during package builds. However, this month, Aurelien Jarno and Wouter Verhelst fixed this issue in varying ways, resulting in a special policy-rcd-declarative-deny-all package. Building on Chris Lamb s previous work on reproducible builds for Debian .ISO images, Roland Clobus announced his work in progress on making the Debian Live images reproducible. [ ] Lucas Nussbaum performed an archive-wide rebuild of packages to test enabling the reproducible=+fixfilepath Debian build flag by default. Enabling the fixfilepath feature will likely fix reproducibility issues in an estimated 500-700 packages. The test revealed only 33 packages (out of 30,000 in the archive) that fail to build with fixfilepath. Many of those will be fixed when the default LLVM/Clang version is upgraded. 79 reviews of Debian packages were added, 23 were updated and 17 were removed this month adding to our knowledge about identified issues. Chris Lamb added and categorised a number of new issue types, including packages that captures their build path via quicktest.h and absolute build directories in documentation generated by Doxygen , etc. Lastly, Lukas Puehringer s uploaded a new version of the in-toto to Debian which was sponsored by Holger Levsen. [ ]

diffoscope diffoscope is our in-depth and content-aware diff utility that can not only locate and diagnose reproducibility issues, it provides human-readable diffs of all kinds too. In September, Chris Lamb made the following changes to diffoscope, including preparing and uploading versions 159 and 160 to Debian:
  • New features:
    • Show ordering differences only in strings(1) output by applying the ordering check to all differences across the codebase. [ ]
  • Bug fixes:
    • Mark some PGP tests that they require pgpdump, and check that the associated binary is actually installed before attempting to run it. (#969753)
    • Don t raise exceptions when cleaning up after guestfs cleanup failure. [ ]
    • Ensure we check FALLBACK_FILE_EXTENSION_SUFFIX, otherwise we run pgpdump against all files that are recognised by file(1) as data. [ ]
  • Codebase improvements:
    • Add some documentation for the EXTERNAL_TOOLS dictionary. [ ]
    • Abstract out a variable we use a couple of times. [ ]
  • diffoscope.org website improvements:
    • Make the (long) demonstration GIF less prominent on the page. [ ]
In addition, Paul Spooren added support for automatically deploying Docker images. [ ]

Website and documentation This month, a number of updates to the main Reproducible Builds website and related documentation. Chris Lamb made the following changes: In addition, Holger Levsen re-added the documentation link to the top-level navigation [ ] and documented that the jekyll-polyglot package is required [ ]. Lastly, diffoscope.org and reproducible-builds.org were transferred to Software Freedom Conservancy. Many thanks to Brett Smith from Conservancy, J r my Bobbio (lunar) and Holger Levsen for their help with transferring and to Mattia Rizzolo for initiating this.

Upstream patches The Reproducible Builds project detects, dissects and attempts to fix as many currently-unreproducible packages as possible. We endeavour to send all of our patches upstream where appropriate. This month, we wrote a large number of these patches, including: Bernhard M. Wiedemann also reported issues in git2-rs, pyftpdlib, python-nbclient, python-pyzmq & python-sidpy.

Testing framework The Reproducible Builds project operates a Jenkins-based testing framework to power tests.reproducible-builds.org. This month, Holger Levsen made the following changes:
  • Debian:
    • Shorten the subject of nodes have gone offline notification emails. [ ]
    • Also track bugs that have been usertagged with usrmerge. [ ]
    • Drop abort-related codepaths as that functionality has been removed from Jenkins. [ ]
    • Update the frequency we update base images and status pages. [ ][ ][ ][ ]
  • Status summary view page:
    • Add support for monitoring systemctl status [ ] and the number of diffoscope processes [ ].
    • Show the total number of nodes [ ] and colourise critical disk space situations [ ].
    • Improve the visuals with respect to vertical space. [ ][ ]
  • Debian rebuilder prototype:
    • Resume building random packages again [ ] and update the frequency that packages are rebuilt. [ ][ ]
    • Use --no-respect-build-path parameter until sbuild 0.81 is available. [ ]
    • Treat the inability to locate some packages as a debrebuild problem, and not as a issue with the rebuilder itself. [ ]
  • Arch Linux:
    • Update various components to be compatible with Arch Linux s move to the xz compression format. [ ][ ][ ]
    • Allow scheduling of old packages to catch up on the backlog. [ ][ ][ ]
    • Improve formatting on the summary page. [ ][ ]
    • Update HTML pages once every hour, not every 30 minutes. [ ]
    • Use the Ubuntu (!) GPG keyserver to validate packages. [ ]
  • System health checks:
    • Highlight important bad conditions in colour. [ ][ ]
    • Add support for detecting more problems, including Jenkins shutdown issues [ ], failure to upgrade Arch Linux packages [ ], kernels with wrong permissions [ ], etc.
  • Misc:
    • Delete old schroot sessions after 2 days, not 3. [ ]
    • Use sudo to cleanup diffoscope schroot sessions. [ ]
In addition, stefan0xC fixed a query for unknown results in the handling of Arch Linux packages [ ] and Mattia Rizzolo updated the template that notifies maintainers by email of their newly-unreproducible packages to ensure that it did not get caught in junk/spam folders [ ]. Finally, build node maintenance was performed by Holger Levsen [ ][ ][ ][ ], Mattia Rizzolo [ ][ ] and Vagrant Cascadian [ ][ ][ ].
If you are interested in contributing to the Reproducible Builds project, please visit our Contribute page on our website. However, you can get in touch with us via:

Next.

Previous.