Search Results: "ag"

3 November 2007

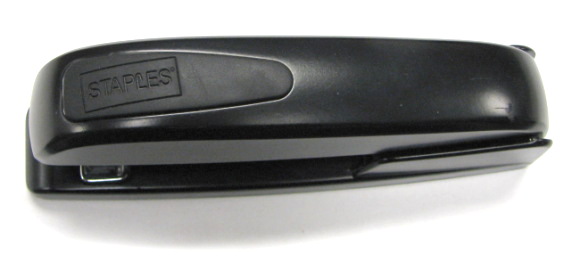
Benjamin Mako Hill: Accidentally Accurate

The label on this office product is correct, but for the wrong reason. /copyrighteous/images/stapler-small.jpg

2 November 2007

David Nusinow: Update On The Shiny

If you've been wondering what's up with compiz in Debian, Sean Finney has been doing a ton of work on the packages. He's posted a major update here.

Wouter Verhelst: Vim vs Emacs

John Goerzen blogs about his experience of using vim for about 8 months. Having been an emacs user a few years back, I understand both editors on a basic level, and can relate to some of the things he says. I have to disagree with one particular bit, though:
It starts faster. I'm not sure if that really was true even when I switched, but it certainly isn't true on any of my machines today. Both Vim and Emacs have had major version upgrades (v7 and v22, respectively) since I started using Vim. People seem to say that Emacs 22 feels faster, though I don't know if that's true. The startup times of the two, if they're different, are imperceptible.
Sorry, but that just isn't true. Using my very non-scientific method of measuring startup times ("click on the icon, watch the clock, and start counting until the editor is ready to use"), I can tell that gvim on my hardware takes less than a second to start, whereas emacs requires approximately 5 seconds to do the same. For reference, this is on my laptop, a 1.3Ghz PowerPC G4. In any case, I'm not a fan of either editor. There are things that vi does well, and there are things that emacs does well. On emacs' end, I like M-x gdb, I slightly prefer its M-x compile over vim's :make, and I just love psgml. I've also occasionally used gnus for news reading (never for mail, though). On vim's end, I find regex search & replace easier (as you mention in your blog post), and I prefer its syntax highlighting (I've seen emacs get confused because the first line in the output window started in the middle of a string. Such things will never happen to vim: if it gets confused once on a given file, it will always be confused on the same file. While annoying, at least you know it's there). All in all, I don't think it matters much. I've seen people who use an editor as an operating system, both in the vim and in the emacs camp, by having a ~/.vimrc or ~/.emacs that's larger than my collection of pictures[1]. I'm not one of them; to me, an editor that doesn't properly work in its defaults shouldn't exist. [1] okay, that's an exaggeration. Still.

MJ Ray: Problems with MyDNS on a Virtual Server

I moved secondary DNS for one of my customers to an OpenVZ virtual server on a completely different network to their main server (which is a very good idea). The secondary DNS is MyDNS with a customised way of sync'ing from the primary nameservers. MyDNS has been wonderful when I've used it. Using postgresql with a nice trigger to auto-update the serial whenever the zone is updated, it's reduced the most common mistake my customers make when managing their own DNS. So, I was struggling to figure out why MyDNS kept crashing with an out-of-memory error. It seems that it was hitting two limits in the virtual server config: dgramrcvbuf and Tcprcvbuf limits. Is there a smart way to figure out how big to set these, apart from trial-and-error?

Christian Perrier: We're now shadow upstream

A few weeks ago, I announced that Debian maintainers of shadow were about to take upstream development over. This has now happened and, after final cleaning work (90% by Nicolas Fran ois and 10% by /me), we released shadow 4.0.18.2 which is just a simple take-over of the package, with inclusion of the trivial patches we had in the Debian package. Immediately after, the Debian package was uploaded (release name "Vacherin", to continue our tradition of naming releases of the Debian package from French cheese names) and we're now officially in charge of this software which is used by several Linux distros. The main contact point for shadow maintenance is the pkg-shadow-devel mailing list on Alioth.

Wouter Verhelst: Beid updates

There've been some posts on Planet Grep about using the Belgian electronic ID card in Ubuntu, recently. As the one who's responsible for making that possible, I felt I had to comment. First, yes, it's possible to do crypto stuff with plain OpenSC rather than the belpic-patched versions; in fact, the tools required to sign plain text files aren't shipped anymore as part of belpic since (I believe) version 2.5.9, which is currently in Debian. However, if you're going to write your own software that somehow uses the eID, I strongly recommend you use the beid-patched versions, since they have support for a feature of which I can't remember the name currently but which means that you need to send your PIN to the card on every signature operation; plain OpenSC is not aware of this possiblity, so does not have support for it, may end up in a confused state when the card refuses to sign, and you may end up locking your card if you keep going on. You have been warned. Second, there is a README.Debian file in libbeidlibopensc2 which explains some of the idiosynchracies in the packaging, and tells you which packages you need and which ones you don't. If you're interested in using the eID, I suggest you read it. Finally, I'm currently working on packages of 2.6.0, which was released on 2007-08-30. They're mostly ready; I have a rather large changelog currently and a two-item TODO list—one of which reads "test&upload"; if all goes well, I should be able to upload them this weekend. Occasionally, this upload includes a small patch that was communicated to me through some mandriva developer which will make one of the aforementioned idiosynchracies—the fact that you have to install the -dev packages if you want to use the mozilla plugin—obsolete.

Jordi Mallach: Valencian children and foreign languages

Recently, GozRita unveiled the names of our two Falleretes majors for 2008's Falles festivities. All the free newspapers did some extensive coverage, with reports on who they are and what they do. Qu Valencia interviewed the little Fallera major, and then posted this:


Little Victoria learns Valencian So, Victoria Bl zquez speaks English and Valencian "nearly perfectly". Great! I think having newspapers treat Valencian as if it were just another foreign language that students are forced to learn is a great example of the dark future our language will face in just a few generations.

Ross Burton: Shame

(wow, three blog posts — albeit short ones — in one day) Some people appear to believe that having a letter in the Granuiad is sad and I should be shamed or something. Honestly, I thought the email was going to be in some online forum thingy, not actually printed, but can I help it if even my brief flippant replies are insightful? Anyway, you can't shame me with newspaper clippings, I've had a like-cures-like homeopathic treatment against that.

Russell Coker: Increasing Efficiency through Less Work

I have just read an interesting article titled Why Crunch Mode Doesn’t Work [1] which documents the research on efficiency vs amount of time spent working (and by inference amount of time spent on leisure activities and sleep). It shows that a 40 hour working week was chosen by people who run factories (such as Henry Ford) not due to being nice for the workers but due to the costs of inefficient work practices and errors that damage products and equipment. Now these results can only be an indication of what works best by today’s standards. The military research is good but only military organisations get to control workers to that degree (few organisations try to control how much sleep their workers get or are even legally permitted to do so), companies can only give their employees appropriate amounts of spare time to get enough sleep and hope for the best. Much of the research dates from 80+ years ago. I suspect that modern living conditions where every house has electric lights and entertainment devices such as a TV to encourage staying awake longer during the night will change things, as would ubiquitous personal transport by car. It could be that for modern factory workers the optimum amount of work is not 40 hours a week, it could be as little as 30 or as much as 50 (at a guess). Also the type of work being done certainly changes things. The article notes that mental tasks are affected more than physical tasks by lack of sleep (in terms of the consequences of being over-tired), but no mention is made about whether the optimum working hours change. If the optimum amount of work in a factory is 40 hours per week might the optimum for a highly intellectual task such as computer programming be less, perhaps 35 or 30? The next factor is the issue of team-work. In an assembly-line it’s impossible to have one person finish work early while the rest keep working, so the limit will be based on the worker who can handle the least hours. Determining which individuals will work more slowly when they work longer hours is possible (but it would be illegal to refuse to hire such people in many jurisdictions) and determining which individuals might be more likely to cause industrial accidents may be impossible. So it seems to me that the potential for each employee to work their optimal hours is much greater in the computer industry than in most sectors. I have heard a single anecdote of an employee who determined that their best efficiency came from 5 hours work a day and arranged with their manager to work 25 hours a week, apart from that I have not heard any reports of anyone trying to tailor the working hours to the worker. Some obvious differences in capacity for working long hours without losing productivity seem related to age and general health, obligations outside work (EG looking after children or sick relatives), and enjoyment of work (the greater the amount of work time that can be regarded as “fun” the less requirement there would be for recreation time outside work). It seems likely to me that parts of the computer industry that are closely related to free software development could have longer hours worked due to the overlap between recreation and paid work. If the amount of time spent working was to vary according to the capacity of each worker then the company structures for management and pay would need to change. Probably the first step towards this would be to try to pay employees according to the amount of work that they do, one problem with this is the fact that managers are traditionally considered to be superior to workers and therefore inherently worthy of more pay. As long as the pay of engineers is restricted to less than the pay of middle-managers the range between the lowest and highest salaries among programmers is going to be a factor of at most five or six, while the productivity difference between the least and most skilled programmers will be a factor of 20 for some boring work and more than 10,000 for more challenging work (assuming that the junior programmer can even understand the task). I don’t expect that a skillful programmer will get a salary of $10,000,000 any time soon (even though it would be a bargain compared to the number of junior programmers needed to do the same work), but a salary in excess of $250,000 would be reasonable. If pay was based on the quality and quantity of work done (which as the article mentions is difficult to assess) then workers would have an incentive to do what is necessary to improve their work - and with some guidance from HR could adjust their working hours accordingly. Another factor that needs to be considered is that ideally the number of working hours would vary according to the life situation of the worker. Having a child probably decreases the work capacity for the next 8 years or so. These are just some ideas, please read the article for the background research. I’m going to bed now. ;)

John Goerzen: A little more on Vim and Emacs file handling

Yesterday's post about switching back to Emacs saw quite a few comments from people (most of them useful, even). I learned a few things.

My biggest gripe about Vim was that for the file types I worked with most, its indentation and syntax highlighting was inferior to that of Emacs. I'd like to illustrate that with an example.

Let's consider one of those file types: XML containing DocBook markup.

Vim has a DocBook mode. It doesn't autodetect DocBook files, so I have this at the top of each one:

<!-- vim: set filetype=docbkxml shiftwidth=2 autoindent expandtab tw=77 : -->

Now, why should Vim need a separate DocBook mode? DocBook is just XML or SGML, and these things have a well-formed nature. Well, part of the reason is that /usr/share/vim/vim71/syntax/docbk.vim has a ton of lines like this:

syn keyword docbkKeyword chapter citation citerefentry citetitle city contained

Yes, they are hard-coding all the DocBook element names into the editing mode. It's probably used for completion, highlighting, maybe indentation. I'm not sure, really. I remember that editing these files without the DocBook mode was much more painful anyway, but that was 8 months ago and I can't quite remember why.

Now, what about Emacs? I don't know if Emacs even has a DocBook mode, mainly because I don't have to care. The Emacs psgml mode actually parses the DTD for your XML or SGML files. It knows exactly what the valid tags are from doing so. This means it has full functionality not just for DocBook, but for any XML or SGML file with a DTD.

Not only that, but it knows more about the files than Vim does. For instance, both Emacs and Vim can do completion of various things. Vim </ C-x C-o (ooo, sounds like Emacs!) can complete my closing tags. But it can't autocomplete my opening tags, and it certainly isn't aware

Not only can Emacs autocomplete opening and closing tags, but it knows exactly what tags are valid at a given place in the document (thanks to the DTD) and will only consider those tags for completion. Moreover, depending on how you have configured it, it could also insert spots for you to add any required attributes. So, for instance, if you're editing XHTML and autocompletion gives you an <img> tag, it would add src="" in it for you, as a reminder that src is required.

There are a host of other smart things that Emacs can do with XML or SGML documents. For instance, you can get a list of all tags valid at the current point with C-c C-t or Shift-RightClick -- useful if you've forgotten the name of a tag for a moment.

The difference isn't as great with everything. But it sure is noticable as I work with XML and Haskell files.

Andrew Pollock: [tech] sysnews for Gnome/KDE/X in general?

Dearest Lazyweb, I wouldn't mind something that put in-your-face announcements on the desktops of our users. Something exactly like sysnews would be ideal. If it were GNOME-centric, it'd pop up some sort of notification thingy down on the bottom, right-hand corner, on top of everything and require explicit dismissal, but in an ideal world, it'd be desktop environment agnostic. Anything like that already out there, or do I have to put my coding pants on? Love, and sloppy kisses Andrew Update libnotify-bin has a very promising looking notify-send -t 0. That might address the GNOME and KDE users, but I'm not sure how say FVWM2 users would fare.

Adam Rosi-Kessel: Catch-22 Poor Organization, and City Council Endorsements

I was quoted in a recent Needham Times article regarding my complaints with the T:
But Adam Rosi-Kessel, a Roslindale resident who takes the Needham Line to his job in the financial district, said 15- to 20-minute delays have kept him from getting to work before 9 a.m. since May. Now Rosi-Kessel, a lawyer who biked to work when he lived in Jamaica Plain, is thinking about trading in his Charlie Card again. It used to be, living here in Roslindale, the train was always the fastest way to get in, he said. Now, it s slowed down to the point where it s starting to get competitive with biking again.
I’m glad they got my biking quote. Here’s the part I don’t understand (emphasis added):
Massachusetts Bay Transportation Authority spokeswoman Lydia Rivera said Needham Line delays have been caused by construction work and speed restrictions on tracks that don t go anywhere near Needham. In order to maximize train use, the T often transfers trains between tracks, rather than leaving underused trains empty in the MBTA yard. The method helps the T get trains where they re needed most, but it also means a delay on one track can slow service on a seemingly unrelated track. It s a Catch-22, Rivera said.
I don’t think the T spokesperson knows what a “Catch-22″ is. I refer those interested to the Wikipedia article on the subject, but it is nicely summarized there as “heads I win, tails you lose.” The T’s problem is not a logical paradox, but some combination of inadequate resources and poor organization. Can someone please help them out? Also on Boston local topics: I’ve received several unattributed mailings lately related to the city council election that do not facially promote any particular candidate. Today’s mailing attacked Stephen Murphy for repeatedly trying (and failing) to win some other office or get some other job than City Councilor. The return address was 31 Milk Street, which is the address of many different businesses. A few days ago, I received another unattributed mailing bemoaning how long it has been since an at-large city councilor came from the Parkway Area (my neighborhood), but not mentioning any candidate in particular. My guess is these mailings are all meant to support John Connolly, a West Roxbury resident, attorney, and ostensibly good guy. I was feeling pretty happy about the possibility of Connolly replacing Murphy on the Council (I have to admit some unfair prejudice in that the only house in our neighborhood I’ve ever seen prominently posting a sign in support of Bush also features a Murphy billboard). But these questionable campaign tactics are giving me pause. Does anyone know anything more about this? In any case, here are my endorsements for next week’s election, notwithstanding the concern outlined above: (1) Felix Arroyo, (2) John Connolly, and (3) Sam Yoon. I have no pick for a fourth candidate. I’ll also throw in a vote for Matt Geary. I really wouldn’t want the socialists running the City, but a broader spectrum of political opinion within the council wouldn’t hurt. Incidentally, it is remarkably hard to find any information summarizing all of the candidates’ positions and records. It’s almost as if the election isn’t even happening. (A commenter properly points me to Brighton Centered as a good resource.) 11/3/07 Update: More discussion here. Technorati Tags: , , , , , , , , , , , ,

1 November 2007

Andrew McMillan: DAViCal and support for Apple's CalDAV client in OS 10.5

Quite a few people seem impressed with the new release of Leopard, and are now looking for a CalDAV server to use with their shiny new iCal app. Unfortunately it seems that Apple wrote this primarily to work with their own (free, open-source) calendar server, which has the side effect that it doesn't work with DAViCal. Part of the "doesn't work" is due to DAViCal not implementing some areas of the CalDAV specification, which is fair enough. Part of it is due to DAViCal not implementing some draft extensions to the CalDAV specification, which I can also understand, since it allows them to provide some useful features that those extensions are designed to support. There also seem to be some parts of the "doesn't work" which are due to a dependence on extensions beyond either of these cases, which is a little more disappointing - and quite a bit harder to implement. So far I have made some fixes to the first point, and some additions towards parts of the second, but as of today it still does not work. This is complicated by my not having access to a Mac. Things are looking up, however, because Tom Robinson has kindly agreed to loan me a Mac running Leopard from next week. In order to "clear the slate" for that, I will be releasing a 0.9.2 over the weekend with the various minor enhancements and fixes that have been applied over the last week. So although this upcoming release will let you add your DAViCal account to iCal 3, it still won't actually work with it. I'm hoping that ready access to the application will enable me to correct that fairly quickly. Also waiting in the wings (and which unfortunately won't be in 0.9.2 either) Maxime Delorme has been working on SyncML support, and is nearly ready with a patch, so we can look forward to that addition fairly soon also.

Steve Kemp: thinking everything's gonna be as sweet as pie

I'm in a position where I need to rebuild a Linux kernel for a number of distributions and architectures. Currently the distributions are: (For each distribution I need a collection of packages for both i386 and amd64.) I've written a couple of scripts to automate the process - first of all running "make menuconfig" within a debootstrap-derived chroot of each arch & distribution pair. Then later using those stored .config files to actually produce the packages via make-kpkg. This process, as you could imagine, takes several hours to complete. Then there's the testing ... I'm sure there must be other people with this kind of need but I was suprised to see nothing in my search attempts. ObRandom: I'm tempted to switch from song-lyrics to film names as post titles. Undecided as yet. I guess it doesn't really matter, just gives me a small amount of amusement. Even now.

Antti-Juhani Kaijanaho: 30

I was born on the 2nd of November in the year 1977, thirty years ago today, at 20:18 +0200. Argh. I’m scared. Does it always feel like you’re about to die? :)

Jeff Bailey: At the Ubuntu Devlopers' Summit in Boston - Getting Older

It's strange being here at UDS-Boston-2007. I realised that this would've been the next time I'd have seen my old coworkers *anyway*. Working remotely meant that I really was glad to go to these, and I still am.

I turned 32 a couple of days ago, which I was pleased to discover is 2^5. According to Wikipedia, it is also a Powerful Number. I like the sound of that. =)

Christian Perrier: A really clean pet package

About two weeks ago, I was claiming that my pet package is awfully clean!. It turned out to be slightly untrue as there was a pending Ubuntu patch. Despite what I claimed then, I finally integrated it without checking whether they now mention Debian in their release annoucements. Yesterday, the package migrated to testing. So, now, my pet package really has the cleanest packages.qa.debian.org page possible.

Russell Coker: Load Average

Other Unix systems apparently calculate the load average differently to Linux. According to the Wikipedia page about Load(computing) [1] most Unix systems calculate it based on the average number of processes that are using a CPU or available for scheduling on a CPU while Linux also includes the count of processes that are blocked on disk IO (uninterruptible sleep). There are three load average numbers, the first is for the past minute, the second is for the past 5 minutes, and the third is for the past 15 minutes. In most cases you will only be interested in the first number. What is a good load average depends on the hardware. For a system with a single CPU core a load average of 1 or greater from CPU use will indicate that some processes may perform badly due to lack of CPU time - although a long-running background process with a high “nice” value can increase the load average without interfering with system performance in most cases. As a general rule if you want snappy performance then the load average component from CPU use should be less than the number of CPU cores (not hyper-threads). For example a system with two dual-core CPUs can be expected to perform really well with a load average of 3.5 from CPU use but might perform badly with a load average of 5. The component of the load average that is due to disk IO is much more difficult to interpret in a sensible manner. A common situation is to have the load average increased by a NFS server with a network problem. A user accesses a file on the NFS server and gets no response (thus giving a load average of 1), they then open another session and use “ls” to inspect the state of the file - ls is blocked and gives a system load average of 2. A single user may launch 5 or more processes before they realise that they are not going to succeed. If there are 20 active users on a multi-user system then a load average of 100 from a single NFS server that has a network problem is not uncommon. While this is happening the system will perform very well for all tasks that don’t involve the NFS server, the processes that are blocked on disk IO can be paged out so they don’t use any RAM or CPU time. For regular disk IO you can have load average incremented by 1 for each non-RAID disk without any significant performance problems. For example if you have two users who each have a separate disk for their home directory (not uncommon with certain systems where performance is required and cooperation between users is low) then each could have a single process performing disk IO at maximum speed with no performance problems for the entire system. A system which has four CPU cores and two hard drives used for separate tasks could have a load average slightly below 6 and the performance for all operations would be quite good if there were four processes performing CPU intensive tasks and two processes doing disk intensive tasks on different disks. The same system with six CPU intensive programs would under-perform (each process would on average get 2/3 of a CPU), and if it had six disk intensive tasks that all use the same disk then performance would be terrible (especially if one of the six was an interactive task). The fact that a single load average number can either mean that the system is busy but performing well, under a bit of load, or totally overloaded means that the load average number is of limited utility in diagnosing performance problems. It is useful as a quick measure, if your server usually has a load average of 0.5 and it suddenly gets a load average of 10 then you know that something is wrong. Then the typical procedure for diagnosing it starts with either running “ps aux grep D” (to get a list of D state processes - processes that are blocked on disk IO) or running top to see the percentages of CPU time idle and in IO-wait states. Cpu(s): 15.0%us, 35.1%sy,  0.0%ni, 49.9%id,  0.0%wa,  0.0%hi,  0.0%si,  0.0%st   PID USER      PR  NI  VIRT  RES  SHR S %CPU %MEM    TIME+  COMMAND
7331 rjc      25  0  2868  640  312 R  100  0.0  0:21.57 gzip Above is a section of the output of top showing a system running gzip -9 < /dev/urandom > /dev/null. Gzip is using one CPU core (100% CPU means 100% of one core - a multi-threaded program can use more than one core and therefore more than 100% CPU) and the overall system statistics indicate 49.9% idle (the other core is almost entirely idle). Cpu(s):  1.3%us,  3.2%sy,  0.0%ni, 50.7%id, 44.4%wa,  0.0%hi,  0.3%si,  0.0%st   PID USER      PR  NI  VIRT  RES  SHR S %CPU %MEM    TIME+  COMMAND
7425 rjc      17  0  4036  872  588 R    4  0.1  0:00.20 find Above is a section of the output of top showing the same system running find /. The system is registering 44% IO wait and 50.7% idle. The IO wait is the percentage of time that CPU core is waiting on IO, so 44% of the total system CPU time (or 88% of one CPU core) is idle while the system is waiting for disk IO to complete. A common mistake is to think that if the IO was faster then more CPU time would be used, in this case with the find program using 4% of one CPU core if all the IO was instantaneous (EG in cache) then the command would complete 25 times faster with 100% CPU use. But if the disk IO performance was doubled (a realistic possibility given that the system has a pair of cheap SATA disks in a RAID-1) then find would probably use 8% of CPU time. Really the only use for load average is for getting an instant feel for whether there are any performance problems related to CPU use or disk IO. If you know what the normal number is then a significant change will stand out. Dr. Neil Gunther has written some interesting documentation on the topic [2], which goes into more technical detail including kernel algorithms used for calculating the load average. My aim in this post is to educate Unix operators as to the basics of the load average. His book The Practical Performance Analyst gives some useful insights into the field. One thing I learned from his book is the basics of queueing theory. One important aspect of this is that as the rate at which work arrives approaches the rate at which work can be done the queue length starts to increase exponentially, and if work keeps arriving at the same rate when the queue is full and the system can’t perform the work fast enough the queue will grow without end. This means that as the load average approaches the theoretical maximum the probability of the system dramatically increasing it’s load average increases. A machine that’s bottlenecked on disk IO for a task where there is a huge number of independent clients (such as a large web server) may have it’s load average jump from 3 to 100 in a matter of one minute. Of course this won’t mean that you actually need to be able to serve 30 times the normal load, merely slightly more than the normal load to keep the queues short. I recommend reading the book, he explains it much better than I do.

John Goerzen: So long, Vim. I'm returning to Emacs

I'd been using Emacs for quite awhile, and about 8 months ago I decided I would try using Vim. I'd only used vi for system emergency work, but knew a number of people that swore by it for regular work. So I decided I would learn Vim and use it for my regular work. I figure that with things like this, I don't get a real feel for how well they work unless I use them for all my work. So I haven't really opened Emacs at all in the past 8 months.

Yesterday I finally decided that Vim was not living up to my expectations and I'm in the process of switching back to Emacs. I thought I ought to write down why I'm doing that, for my own future reference... and since nobody has ever written about Emacs vs. Vim, I might as well post it where everyone can see it.

So here we are.

Original Reasons for Using Vim

It would lead to more comfortable typing. Lots of Vim users mention that you don't have to hold down keys while hitting other keys as much in Vim as in Emacs, and that the movement keys are all on the home row. That's true, but I didn't find it to be that big of an improvement, since Esc is a farther reach than anything in Emacs, and let me tell you, you're hitting Esc all the time in Vim. I found that removing the armrests from my chair made my hands happier than Vim ever did, and swapping Ctrl and CapsLock in Emacs will probably help there too.

It starts faster. I'm not sure if that really was true even when I switched, but it certainly isn't true on any of my machines today. Both Vim and Emacs have had major version upgrades (v7 and v22, respectively) since I started using Vim. People seem to say that Emacs 22 feels faster, though I don't know if that's true. The startup times of the two, if they're different, are imperceptible.

Vim would use less RAM. Frankly, these days, both Emacs and Vim are way down on the list of things that use up RAM. Heck, kmail has 141MB resident, and each of its two IMAP processes is using more than 30MB. Emacs in X right after start has 16MB resident, 10MB of which is shared, and 25MB VSS. gvim right after start has 8MB resident, 5MB of which is shared, and a 43MB VSS. Emacs tends to use fewer processes for things that vim. So they're not all that different, and Emacs could come out smaller in certain situations. But the difference is irrelevant on today's machines, and modern Gnome and KDE apps are many times larger than both of them.

It will make me more comfortable in rescue environments where I have only traditional vi available. Actually, the vi on AIX is so different from modern Vim that this didn't really help.

It would make me more productive. There are some editing commands that did, but as you'll see below, it was more than balanced out by other problems.

Things I Liked about Vim

The commands dt, dT, df, dF. Wonderful little things those. Emacs now has M-z (Zap), which is similar to df but can actually go to other lines (a nice addition). And there are easy ways to bind keys to the others as well, though that doesn't make it a pervasive convention like it is in Vim.

Antialiased fonts. It's crazy that Emacs doesn't have this yet. But not a showstopper; I still like good ole 10x20 just fine.

Regexp search-and-replace. Emacs actually has this now, and maybe it had it back then too. M-C-%. Apparently in Emacs22 the replacement expression can also have lisp code in it, which sounds really slick but I can't see myself using it regularly.

Annoying Things in Vim

Syntax highlighting. The syntax highlighting for most languages in Vim felt like it was about as smart as it was in Emacs about 10 years ago. Strings like "Hello!\"" (in languages where \" inserts a literal ") often confused it. Sometimes quotes within comments confused it. Sometimes it would be confused permanently. Other times, just until I scrolled around in the file or reloaded it.

Indentation. This is much more annoying than the syntax highlighting, really. In many languages -- and especially the two modes I've used most recently, XML and Haskell -- it really, really stinks. The indentation there isn't aware of syntax, or not very much. Sometimes it is smart enough to know that if an XML line starts with </ that it moves left and if it starts with an opening tag, that the next line moves right. But it's not smart enough to do this reliably. Not only that, but indentation is not handled with consistent configuration between languages. And even though Vim ships with a ton of language modes, the central docs only cover indentation for C.

I've asked Vim experts about this, and have tried all sorts of various tweaks, have read through Vim indentation mode source files, etc. There is just no way to get it anywhere near the intelligence of Emacs for most languages, short of writing my own mode, it appears. This is even worse because when using the backspace key in insert mode, for awhile it deletes individual spaces, and then all of a sudden deletes a big chunk of whitespace back to the beginning of the line. (And no, the insertion of Tab characters is disabled.) Indentation is my #1 complaint about Vim, and something that shows no progress towards being fixed any time soon.

And forget about anything like Emacs M-x reindent-region. This is a syntax-aware indenter. You can write out an entire source file with no indentation whatsoever, and it will indent the entire thing according to the indentation rules you've defined and the syntax of the language you're using. The best I've seen in Vim are commands that add or remove space at the beginning of every line in a region.

In short, Emacs seems to "understand" the file format on a much deeper level than Vim, and can automate things to a much better extent because of it.

Too many things disrupt the paste buffer. I can use Y or y to yank some text in Vim, and it's really, really easy to overwrite that buffer with other things. Yes, I know that I can yank it into a named buffer, but that's inconvenient and I don't usually know in advance that I'll have that need. In Emacs, only C-k and other "large area" commands disrupt it.

Vim doesn't like you having lots of files open at once. It's surprisingly convoluted to do this. If you use the basic documented command to edit another file, :e, it closes the file you're working on. The normal way to open multiple files at once is to use split windows. Well, I don't like split windows all that well, and often just want to make a quick change in one file -- in full screen -- and then go back to another. Even though I use set hidden in my ~/.vimrc, it still is annoying and more convoluted than it should be.

Vim can't create new top-level X windows. In Emacs, I can press C-x 5 2, and poof, I have a second Emacs window in X, and it's tied to the same editing session and Emacs process. Not a new process, with a different set of files, its own buffers, etc. The same process, same set of files. Just like a split window, but with a new top-level X window instead. gvim simply has no way to do that. This is also a large annoyance.

gqap stinks. This has burned me more than once. I'll be editing an XML document, and insert some text in the middle of a paragraph. Now I have a really wide line. So I type gqap to reformat the paragraph. My cursor is near the bottom of the screen, so I don't really see much past the current line. I then save the document and exit. Later I discover that vim considered the entire rest of the document part of the single paragraph, and removed all the different indentation levels at </para> and the like, so it's completely messed up. Emacs is smart enough to know what is a paragraph in XML mode, and M-q does the right thing. Oh, and Emacs reindent-region can fix the Vim gqap-induced mess.

Giacomo Catenazzi: Linux Kernel Driver DataBase

This weekend I finally finished the Linux Kernel Driver DataBase . Really I started this project in 2000, but in 2001 after some flames in the LKML (for CML2, the configuration engine used by my project) I put the project in a long hibernation. Now I had some time to finish it.

LKDDb is a database of hardware (and protocols), kernel configuration items and associated kernel driver files. Actually it has nearly 6000 entries (see the statistics). The database is generated automagically, quite fast: it take 2 minutes to scan the whole kernel source, and to interpret it. Unfortunately it is not complete and not accurate (I'm not sure if there is some black-list in kernel, but my scanner cannot distinguish the black-list with the supported hardware list).

Now I'm looking for some application of the database. In 2001 it seemed that there was some interest, but let see.

As a prototype, I dis-hibernate also the AutoKernConf, an automagical kernel configuration. The old version was a more powerful, so I need to forward-port some old features. BTW I changed an other time the project name: autoconfig was too similar to existing projects, kautoconfig, kernfig, kernautoconf were other names, but I like better the new name, and I can use the automagical word in the description ;-)

Do you see other uses of the database?

Next.

Previous.