Jonathan Dowland: Lush (and friends)

 The gig poster
 Nano Kino 7"
 Max mo 7"s
The gig poster
Nano Kino 7"
Max mo 7"s
 There's been a bunch of coverage of this attack on Microsoft's Secure Boot implementation, a lot of which has been somewhat confused or misleading. Here's my understanding of the situation.
 Almost exactly six years ago I bought one of these Fuloong 6064 mini
PCs. The machine has been working great ever since both collecting my
mail and acting as an IMAP server as well as providing public services
-- it's also
keyserver.siccegge.de. However jessie
is supposed to be the last Debian release supporting the hardware and
the system's rather slow and lacks memory. This is especially
noticeable with IMAP spam filter training and mail indexing. Therefore
I'm looking for some nice replacement -- preferably non-x86 again (no
technical reasons). My requirements are pretty simple:
123 files changed, 1674 insertions(+), 3205 deletions(-)More than 1500 lines less build system code. Quite impressive, eh? This also includes about 200 lines of less code in debian/, as that switched from prehistoric debhelper stuff to modern dh (compat level 9, almost ready for 10). The annoying Tale of Targets vs Files Talking about CMake: I don t really love it. As you might know, CMake differentiates between targets and files. Targets can in some cases depend on files (generated by a command in the same directory), but overall files are not really targets. You also cannot have a target with the same name as a file you are generating in a custom command, you have to rename your target (make is OK with the generated stuff, but ninja complains about cycles because your custom target and your custom command have the same name). Byproducts for the (time) win One interesting thing about CMake and Ninja are byproducts. In our tree, we are building C++ files. We also have .pot templates depending on them, and .mo files depending on the templates (we have multiple domains, and merge the per-domain .pot with the all-domain .po file during the build to get a per-domain .mo). Now, if we just let them depend naively, changing a C++ file causes the .pot file to be regenerated which in turns causes us to build .mo files for every freaking language in the package. Even if nothing changed. Byproducts solve this problem. Instead of just building the .pot file, we also create a stamp file (AKA the witness) and write the .pot file (without a header) into a temporary name and only copy it to its final name if the content changed. The .pot file is declared as a byproduct of the command. The command doing the .pot->.mo step still depends on the .pot file (the byproduct), but as that only changes now if strings change, the .mo files only get rebuild if I change a translatable string. We still need to ensure that that the .pot file is actually built before we try to use it the solution here is to specify a custom target depending on the witness and then have the target containing the .mo build commands depend on that target. Now if you use make, you might now this trick already. In make, the byproducts remain undeclared, though, while in CMake we can now actually express them, and they are used by the Ninja generator and the Ninja build tool if you chose that over make (try it out, it s fast). Further Work Some command names are hardcoded, I should find_program() them. Also cross-building the package does not yet work successfully, but it only requires a tiny amount of patches in debhelper and/or cmake. I also tried building the package on a Fedora docker image (with dpkg installed, it s available in the Fedora sources). While I could eventually get the programs build and most of the integration test suite to pass, there are some minor issues to fix, mostly in the documentation building and GTest department: Fedora ships its docbook stylesheets in a different location, and ships GTest as a pre-compiled library, and not a source tree. I have not yet tested building on exotic platforms like macOS, or even a BSD. Please do and report back. In Debian, CMake is not up-to.date enough on the non-Linux platforms to build APT due to test suite failures, I hope those can be fixed/disabled soon (it appears to be a timing issue AFAICT). I hope that we eventually get some non-Debian backends for APT. I d love that.

UsePAM yes
ChallengeResponseAuthentication yes
AuthenticationMethods publickey,keyboard-interactive
This forces all authentication to pass two verification methods in ssh: publickey and keyboard-interactive. All users will have to supply a public key and then also pass keyboard-interactive auth. Normally keyboard-interactive auth prompts for a password, but we can change /etc/pam.d/sshd on this. I added this line at the very top of /etc/pam.d/sshd:
auth [success=done new_authtok_reqd=done ignore=ignore default=bad] pam_google_authenticator.soThis basically makes Google Authenticator both necessary and sufficient for keyboard-interactive in ssh. That is, whenever the system wants to use keyboard-interactive, rather than prompt for a password, it instead prompts for a token. Note that any user that has not set up google-authenticator already will be completely unable to ssh into their account. Enhancement 1, variant 2: Allowing automated processes to root On many of my systems, I have ~root/.ssh/authorized_keys set up to permit certain systems to run locked-down commands for things like backups. These are automated commands, and the above configuration will break them because I m not going to be typing in codes at 3AM. If you are very restrictive about what you put in root s authorized_keys, you can exempt the root user from the 2FA requirement in ssh by adding this to sshd_config:
Match User root
  AuthenticationMethods publickey
This says that the only way to access the root account via ssh is to use the authorized_keys file, and no 2FA will be required in this scenario. Enhancement 1, variant 2: Allowing non-pubkey auth On some multiuser systems, some users may still want to use password auth rather than publickey auth. There are a few ways we can support that:
AuthenticationMethods publickey,keyboard-interactive keyboard-interactiveThis means that to authenticate, you need to pass either publickey and then keyboard-interactive auth, or just keyboard-interactive auth. Then in /etc/pam.d/sshd, you put this:
auth required pam_google_authenticator.soAs a sub-variant for option 1, you can add nullok to here to permit auth from people that do not have a Google Authenticator configuration. Or for option 2, change required to sufficient . You should not add nullok in combination with sufficient, because that could let people without a Google Authenticator config authenticate completely without a password at all. Enhancement 2: Configuring su A lot of other tutorials stop with ssh (and maybe gdm) but forget about the other ways we authenticate or change users on a system. su and sudo are the two most important ones. If your root password is compromised, you don t want anybody to be able to su to that account without having to supply a token. So you can set up google-authenticator for root. Then, edit /etc/pam.d/su and insert this line after the pam_rootok.so line:
auth required pam_google_authenticator.so nullokThe reason you put this after pam_rootok.so is because you want to be able to su from root to any account without having to input a token. We add nullok to the end of this, because you may want to su to accounts that don t have tokens. Just make sure to configure tokens for the root account first. Enhancement 3: Configuring sudo This one is similar to su, but a little different. This lets you, say, secure the root password for sudo. Normally, you might sudo from your user account to root (if so configured). You might have sudo configured to require you to enter in your own password (rather than root s), or to just permit you to do whatever you want as root without a password. Our first step, as always, is to configure PAM. What we do here depends on your desired behavior: do you want to require someone to supply both a password and a token, or just a token, or require a token? If you want to require a token, put this at the top of /etc/pam.d/sudo:
auth [success=done new_authtok_reqd=done ignore=ignore default=bad] pam_google_authenticator.soIf you want to require a token and a password, change the bracketed string to required , and if you want a token or a password, change it to sufficient . As before, if you want to permit people without a configured token to proceed, add nullok , but do not use that with sufficient or the bracketed example here. Now here comes the fun part. By default, if a user is required to supply a password to sudo, they are required to supply their own password. That does not help us here, because a user logged in to the system can read the ~/.google_authenticator file and easily then supply tokens for themselves. What you want to do is require them to supply root s password. Here s how I set that up in sudoers:
Defaults:jgoerzen rootpw
jgoerzen ALL=(ALL) ALL
So now, with the combination of this and the PAM configuration above, I can sudo to the root user without knowing its password but only if I can supply root s token. Pretty slick, eh? Further reading In addition to the basic tutorials referenced above, consider:
 Hi,
I am in two minds of what to write about Doha. My job has been vastly simplified by a friend when he shared with me https://www.youtube.com/watch?v=LdrAd-44LW0 . That video is more relevant and more closer to the truth than whatever I can share. As can be seen it is funny but more sad the way Qatarians are trying to figure out how things will be and as can be seen it seems to heading towards a real estate bubble . They would have to let go of the Sharia if they are thinking of wealthy westerners coming to stay put. I am just sad to know that many of my country-men are stuck there and although I hope the best for them, I dread it may turn out the way it has turned out for many people of Indians, and especially from Kerala in Saudi Arabia. I would touch about the Kerala situation probably in another blog post as this time is exclusively for legal aspects which were discussed in Debconf.
A bit of backgrounder here, one part of my family is lawyers which means I have somewhat notion of law as practiced in our land. As probably everybody knows, India was ruled by the British for around 150 odd years. One of the things that they gave while leaving was/is the IPC (Indian Penal Code) and is practiced with the common law concept. The concept means precedence of any judgement goes quite some way in framing rulings and law of the land as time goes on besides the lobbying and the politics which happens in any democracy.
Free software would not have been there without the GPL The General Public License. And the license is as much a legal document as it s something that the developers can work without becoming deranged, as it is one of the more simpler licenses to work with.
My own understanding of the legal, ethical and moral issues around me were framed by two-three different TV shows, books (fiction and non-fiction alike) apart from what little news I heard in family. One was M*A*S*H* (with Alan Alda and his frailness, anarchism, humanism, civil rights), the Practise and Boston Legal which does lay bare the many grey areas that lawyers have to deal with ( The Practice also influenced a lot of civil rights understanding and First amendment, but as it is a TV show, how much of it is actually practiced for lawyers and how much moral dilemma they are can only be guessed at.) . In books it is artists like John Grisham, Michael Connelly as well as Perry Mason Agatha Christie. In non-fiction look at the treasures under bombayhighcourt e-books corner and series of Hamlyn Lectures. I would have to warn that all of the above are major time-sinks but rewarding in their own way. Also haven t read all of them as time and interests are constrained but do know they are good for understanding bit of our history. I do crave for a meetup kind of scenario when non-lawyers can read and discuss about facets of law .
All that understanding was vastly amplified by Groklaw.net which made non-lawyers at the very least be able to decipher and understand what is going on in the free software world. After PJ (Pamela Jones) closed it in 2013 due to total surveillance by the Free World (i.e. the United States of America, NSA) we have been thirsty. We do get occasionally somewhat mildly interesting articles in lwn.net or arstechnica.net but nowhere the sheer brilliance of groklaw.
So, it was a sheer stroke of luck that I met Mr. Bradley M. Kuhn who works with Karen Sandler on Software Conservancy. While I wanted to be there for his presentation, it was just one of those days which doesn t go as planned. However, as we met socially and over e-mail there were two basic questions which I asked him which also imbibes why we need to fight for software freedom in the court of law. Below is a re-wording of what he shared .
Q1. why do people think that GPL still needs to be challenged in the court of law while there are gpl-violations which has been more or less successfully defended in the court of law ?
Bradley Kuhn the GPL violations is basically a violation of one or more clauses of the GPL license and not the GPL license as a whole and my effort during my lifetime would be to make/have such precedents that the GPL is held as a valid license in the court of law.
Q2. Let s say IF GPL is held to be valid in the court of law, would FSF benefit monetarily, at least to my mind it might be so, as more people and comapnies could be convinced to use strong copyleft licenses such as GPLv3 or AGPLv3 .
Bradley Kuhn It may or may not. It is possible that even after winning, that people and especially companies may go for weak copyleft licenses if it suits them. The only benefit would probably would be to those people who are already using GPLv3 as the law could be used to protect them as well. Although we would want and welcome companies who would use strong copyleft license such as the GPL, the future is in future and hence uncertain. Both possibilities co-exist.
While Bradley didn t say it, I would add further here it probably would mean also moving from being a more offensive mode (which GPL-violations is based upon where a violation occurs and somebody either from the victim s side or a by-stander notices the violation, brings it to the notice of the victim and the GPL-volations team.) to perhaps it being defended by the DMCA people themselves, once GPL is held as a valid license in the eyes of law. Although should you use the DMCA or not is a matter of choice, personal belief system as well as your legal recourses.
I have to share that the FSF and the GPL-violations team are probably very discerning when they take up the fight as most of the work done by them is pro-bono (i.e. they don t make a single penny/paisa from the work done therein.) and hence in view of scarce resources, it makes sense to go only for the biggest violators in the hopes that you can either make them agree to compensate and agree to the terms of license of any software/hardware combination or sue them and take a bigger share of the reward/compensation awarded by the Court to help the defendant and maybe some of the proceeds donated by the defendant and people like you and me to make sure that Conservancy and the GPL-violations team is still around to help the next time something similar happens.

Bradley Kuhn presenting at #Debconf 16


 A couple of quick wins
There are a couple of little fixes and improvements on which I m not going to spend too much time on, but which I list for completeness anyway just in case they come in handy for a similar project of yours:
svgo optimizer (saves 8KB).
<link rel="preload" href="foo.css" as="style" onload="this.rel='stylesheet'">, see also filamentgroup/loadCSS.
We switched from WebSockets to the EventSource API because the former is not compatible with HTTP/2, whereas the latter is. This removes a round trip and some custom code for WebSocket reconnecting, because EventSource does that for you.
The progress bar animation used to animate the background-position property. It turns out that browsers can only animate the position, scale, rotation and opacity properties smoothly, because such animations can be off-loaded to the GPU. Hence, we have re-implemented the progress bar animation using the position property.
The biggest win for improving client-side latency from the Chrome address bar was introducing Service Workers (see commit 7f31aef402cb782056e290a797f224171f4af270). Our Service Worker caches static assets and a placeholder results page. The placeholder page is presented immediately when you start a search (e.g. from the address bar), making the first response immediate, i.e. rendered within 100ms. Having assets and the result page out of the way, the first round trip is used for actually doing the search, removing all unnecessary overhead.
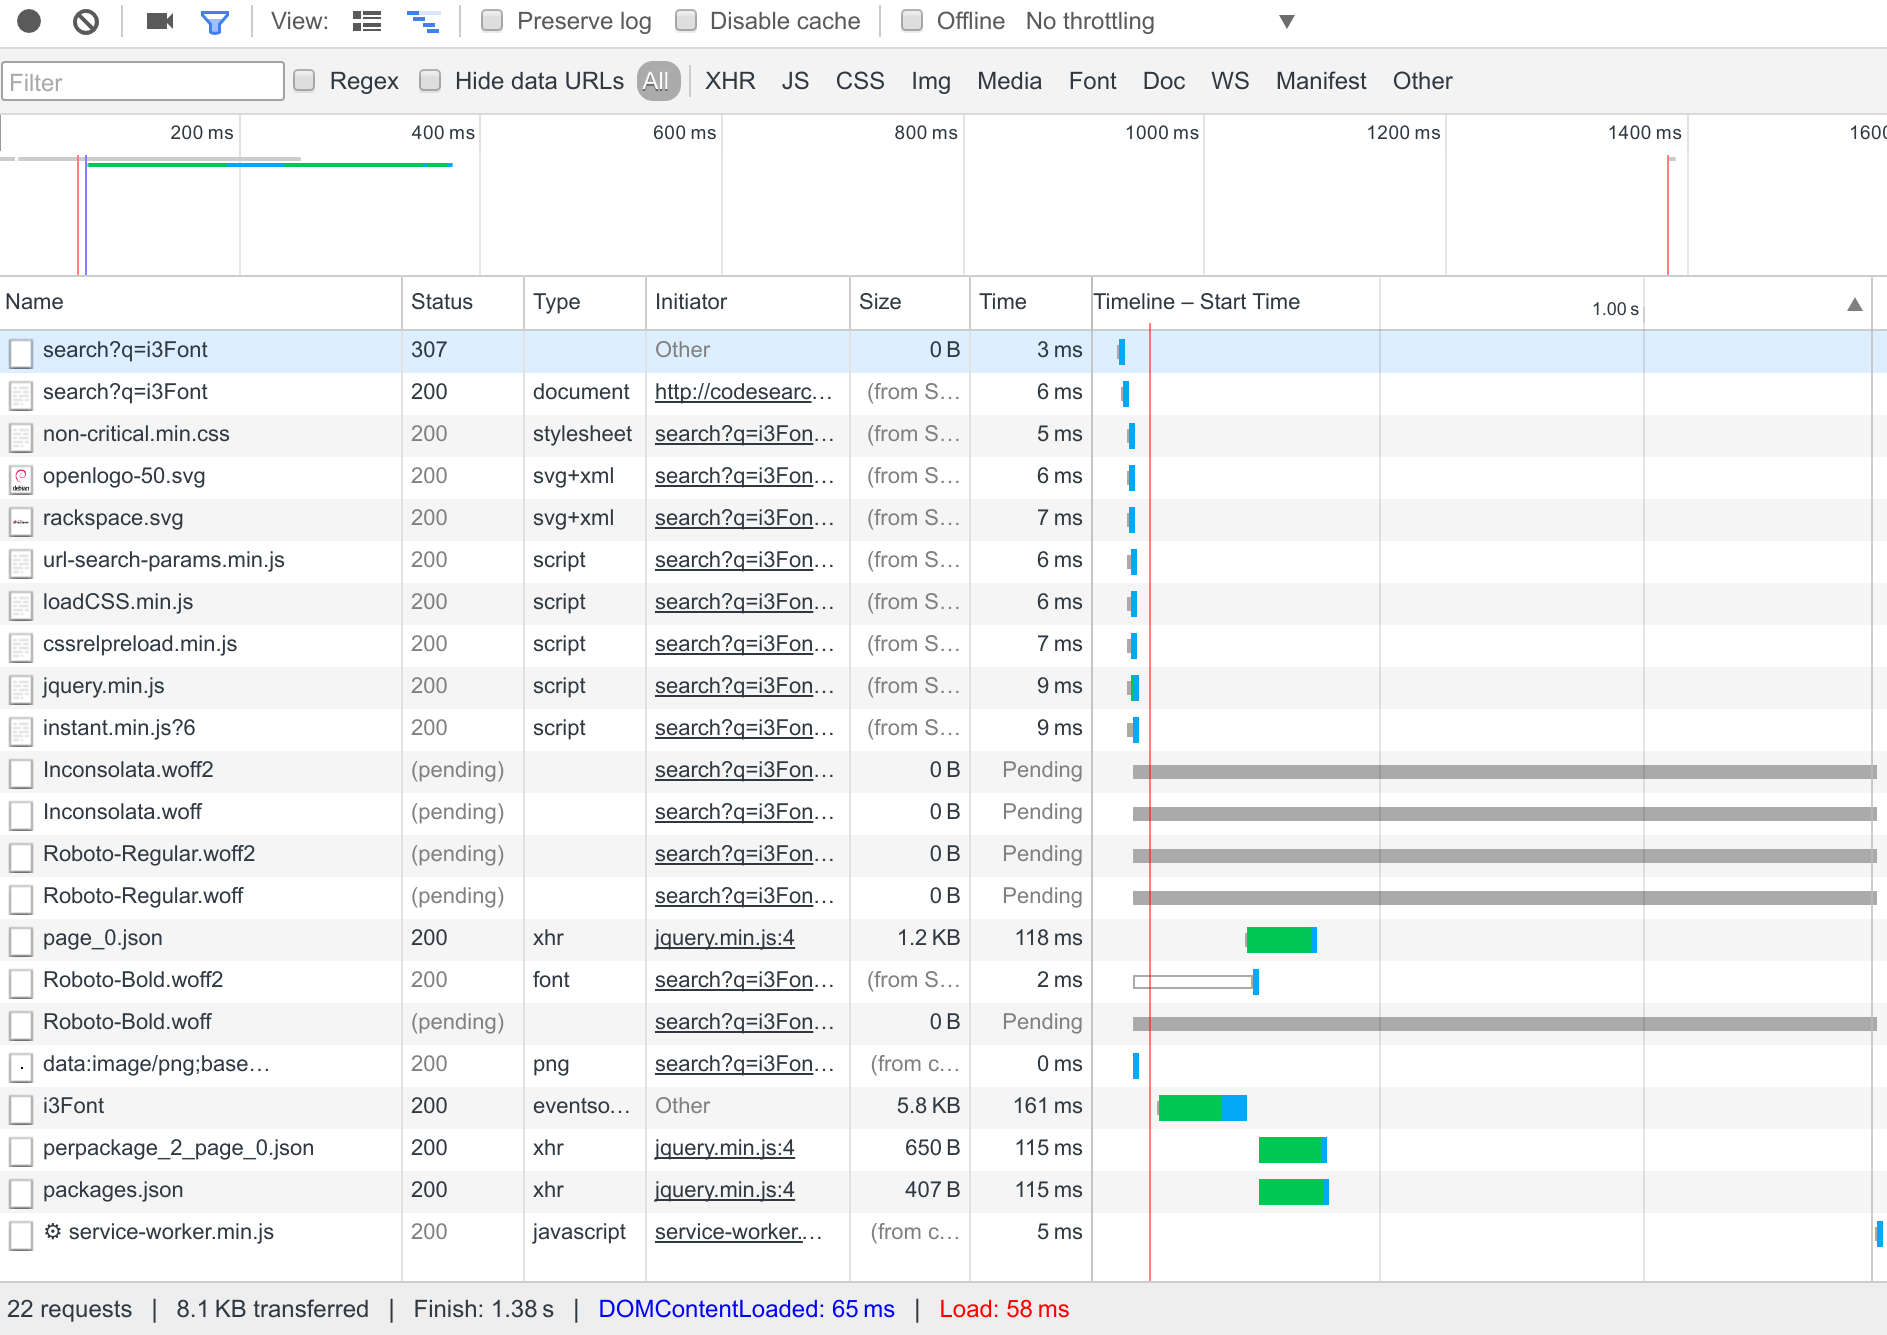
With all of these improvements in place, rendering latency goes down from half a second to well under 100 ms, and this is what the Chrome network inspector looks like:

 The second release of littler as a CRAN package is now available, following in the now more than ten-year history as a package started by Jeff in the summer of 2006, and joined by me a few weeks later.
littler is the first command-line interface for R and predates
Rscript. It is still faster, and in my very biased eyes better as it allows for piping as well shebang scripting via #!, uses command-line arguments more consistently and still starts faster. It prefers to live on Linux and Unix, has its difficulties on the OS X due yet-another-braindeadedness there (who ever thought case-insensitive filesystems where a good idea?) and simply does not exist on Windows (yet -- the build system could be extended -- see RInside for an existence proof, and volunteers welcome!).
This release brings us fixes and enhancements from three other contributors, a couple new example scripts, more robust builds, extended documentation and more -- see below for details.
The NEWS file entry is below.
Changes in littler version 0.3.1 (2016-08-06)Full details for the littler release are provided as usual at the ChangeLog page. The code is available via the GitHub repo, from tarballs off my littler page and the local directory here -- and now of course all from its CRAN page and via
- Changes in examples
install2.rnow passes on extra options past--toR CMD INSTALL(PR #37 by Steven Pav)- Added
rcc.rto runrcmdcheck::rcmdcheck()- Added (still simple)
render.rto render (R)markdown- Several examples now support the
-xor--usageflag to show extended help.- Changes in build system
- The
AM_LDFLAGSvariable is now set and used too (PR #38 by Mattias Ellert)- Three more directories, used when an explicit installation directory is set, are excluded (also #38 by Mattias)
- Travis CI is now driven via
run.shfrom our fork, and deploys all packages as .deb binaries using our PPA where needed- Changes in package
- SystemRequirements now mentions the need for
libR, i.e. an R built with a shared library so that we can embed R.- The docopt and rcmdcheck packages are now suggested, and added to the Travis installation.
- A new helper function
r()is now provided and exported so that the package can be imported (closes #40).- URL and BugReports links were added to DESCRIPTION.
- Changes in documentation
- The help output for
installGithub.rwas corrected (PR #39 by Brandon Bertelsen)
install.packages("littler"). Binary packages are available directly in Debian as well as soon via Ubuntu binaries at CRAN thanks to the tireless Michael Rutter. will probably have new
Comments and suggestions are welcome at the GitHub repo.
This post by Dirk Eddelbuettel originated on his Thinking inside the box blog. Please report excessive re-aggregation in third-party for-profit settings.
 I maintain Debian packages for several projects which are hosted on
GitHub. I have a master packaging branch containing both upstream s
code, and my
debian/ subdirectory containing the packaging control
files. When upstream makes a new release, I simply merge their
release tag into master: git merge 1.2.3 (after reviewing the
diff!).
Packaging things for Debian turns out to be a great way to find small
bugs that need to be fixed, and I end up forwarding a lot of patches
upstream. Since the projects are on GitHub, that means forking the
repo and submitting pull requests. So I end up with three remotes:
originupstreamforkgit push -u fork fix-gcc-6. However, it is
also useful to have a command that pushes everything to the places it
should be: pushes bugfix branches to fork, my master packaging
branch to origin, and definitely doesn t try to push anything to
upstream (recently an upstream project gave me push access because I
was sending so many patches, and then got a bit annoyed when I pushed
a series of Debian release tags to their GitHub repo by mistake).
I spent quite a lot of time reading git-config(1) and git-push(1),
and came to the conclusion that there is no combination of git
settings and a push command that do the right thing in all cases.
Candidates, and why they re insufficient:
git push --allremote.pushDefault and branch.*.pushRemote configuration options. The problem is that git push --all pushes to only one remote, and it selects it by looking at the current branch. If I ran this command for all remotes, it would push everything everywhere.git push <remote> : for each remotefork and upstream remotes have upstream s master branch, and the origin remote has my packaging branch.git push-all, which does the
right thing. As you will see from the description at the top of the
script, it uses remote.pushDefault and branch.*.pushRemote to
determine where it should push, falling back to pushing to the remote
the branch is tracking. If won t push something when all three of
these are unspecified, and more generally, it won t create new remote
branches except in the case where the branch-specific setting
branch.*.pushRemote has been specified. Magit
makes it easy to set remote.pushDefault and branch.*.pushRemote.
I have this in my ~/.mrconfig:
git_push = git push-all
mr push to ensure that all of my work has
been sent where it needs to be (see
myrepos).
#!/usr/bin/perl
# git-push-all -- intelligently push most branches
# Copyright (C) 2016 Sean Whitton
#
# This program is free software: you can redistribute it and/or modify
# it under the terms of the GNU General Public License as published by
# the Free Software Foundation, either version 3 of the License, or (at
# your option) any later version.
#
# This program is distributed in the hope that it will be useful, but
# WITHOUT ANY WARRANTY; without even the implied warranty of
# MERCHANTABILITY or FITNESS FOR A PARTICULAR PURPOSE.  See the GNU
# General Public License for more details.
#
# You should have received a copy of the GNU General Public License
# along with this program.  If not, see <http://www.gnu.org/licenses/>.
# Prerequisites:
# The Git::Wrapper, Config::GitLike, and List::MoreUtils perl
# libraries.  On a Debian system,
#     apt-get install libgit-wrapper-perl libconfig-gitlike-perl \
#         liblist-moreutils-perl
# Description:
# This script will try to push all your branches to the places they
# should be pushed, with --follow-tags.  Specifically, for each branch,
#
# 1. If branch.pushRemote is set, push it there
#
# 2. Otherwise, if remote.pushDefault is set, push it there
#
# 3. Otherwise, if it is tracking a remote branch, push it there
#
# 4. Otherwise, exit non-zero.
#
# If a branch is tracking a remote that you cannot push to, be sure to
# set at least one of branch.pushRemote and remote.pushDefault.
use strict;
use warnings;
no warnings "experimental::smartmatch";
use Git::Wrapper;
use Config::GitLike;
use List::MoreUtils qw  uniq apply  ;
my $git = Git::Wrapper->new(".");
my $config = Config::GitLike->new( confname => 'config' );
$config->load_file('.git/config');
my @branches = apply   s/[ \*]//g   $git->branch;
my @allBranches = apply   s/[ \*]//g   $git->branch(  all => 1  );
my $pushDefault = $config->get( key => "remote.pushDefault" );
my %pushes;
foreach my $branch ( @branches )
    my $pushRemote = $config->get( key => "branch.$branch.pushRemote" );
    my $tracking = $config->get( key => "branch.$branch.remote" );
    if ( defined $pushRemote )
        print "I: pushing $branch to $pushRemote (its pushRemote)\n";
        push @  $pushes $pushRemote   , $branch;
    # don't push unless it already exists on the remote: this script
    # avoids creating branches
      elsif ( defined $pushDefault
              && "remotes/$pushDefault/$branch" ~~ @allBranches )
        print "I: pushing $branch to $pushDefault (the remote.pushDefault)\n";
        push @  $pushes $pushDefault   , $branch;
      elsif ( !defined $pushDefault && defined $tracking )
        print "I: pushing $branch to $tracking (probably to its tracking branch)\n";
        push @  $pushes $tracking   , $branch;
      else
        die "E: couldn't find anywhere to push $branch";


foreach my $remote ( keys %pushes )
    my @branches = @  $pushes $remote   ;
    system "git push --follow-tags $remote @branches";
    exit 1 if ( $? != 0 );
 It didn't drop packets at random, though. Some traffic would be
deterministically dropped, such as the parallel A/AAAA DNS lookups generated by
the glibc DNS stub resolver. For instance, in the following
tcpdump output:
[1] 17:31:46.989073 IP [My IP].50775 > 75.75.75.75.53: 53571+ A? www.comcast6.net. (34)
[2] 17:31:46.989102 IP [My IP].50775 > 75.75.75.75.53: 14987+ AAAA? www.comcast6.net. (34)
[3] 17:31:47.020423 IP 75.75.75.75.53 > [My IP].50775: 53571 2/0/0 CNAME comcast6.g.comcast.net., [ ]
[4] 17:31:51.993680 IP [My IP].50775 > 75.75.75.75.53: 53571+ A? www.comcast6.net. (34)
[5] 17:31:52.025138 IP 75.75.75.75.53 > [My IP].50775: 53571 2/0/0 CNAME comcast6.g.comcast.net., [ ]
[6] 17:31:52.025282 IP [My IP].50775 > 75.75.75.75.53: 14987+ AAAA? www.comcast6.net. (34)
[7] 17:31:52.056550 IP 75.75.75.75.53 > [My IP].50775: 14987 2/0/0 CNAME comcast6.g.comcast.net., [ ]
[1] and [2] are the A and AAAA queries being initiated in parallel.
Note that they both use the same 4-tuple of (Source IP, Destination IP, Source
Port, Destination Port), but with different DNS IDs. Packet [3] is the
response to packet [1]. The response to packet [2] never arrives, and five
seconds later, the glibc stub resolver times out and retries in single-request
mode, which performs the A and AAAA queries sequentially. Packets [4] and
[5] are the type A query and response, and packets [6] and [7] are the
AAAA query and response.
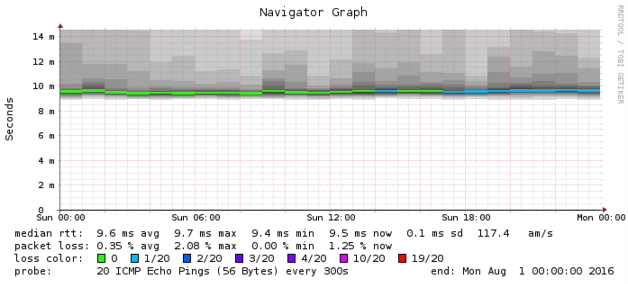
The Arris SB6190 running firmware 9.1.93N would consistently interfere with
these parallel DNS requests, but only when operating in its degraded mode. It
also didn't matter whether glibc was configured to use an IPv4 or IPv6
nameserver, or which nameserver was being used. Power cycling the modem would
fix the issue for a few days.
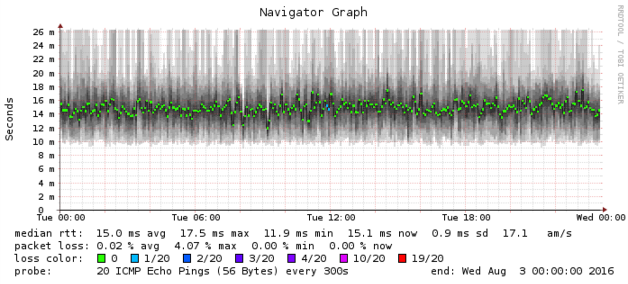
My ISP offered to downgrade the firmware on the Arris SB6190 to version 9.1.93K.
This firmware version doesn't go into a degraded mode after a few days, but it
does exhibit higher latency, and more jitter:
 It seemed unlikely that Arris would fix the firmware issues in the SB6190 before
the end of my 30-day return window, so I returned the SB6190 and purchased a
Netgear CM600. This modem appears to be based on the Broadcom BCM3384 and
looking at an older release of the CM600 firmware source reveals that the
device runs the open source eCos embedded operating system.
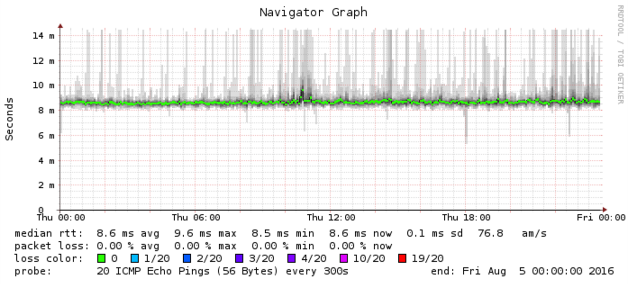
The Netgear CM600 so far hasn't exhibited any of the issues I found with the
Arris SB6190 modem. Here is a SmokePing graph for the CM600, which shows median
latency about 1 ms lower than the Arris modem:
 It's not clear which company is to blame for the problems in the Arris modem.
Looking at the DOCSIS drivers in the SB6190 firmware source reveals copyright
statements from ARRIS Group, Texas Instruments, and Intel. However, I would
recommend avoiding cable modems produced by Arris in particular, and cable
modems based on the Intel Puma SoC in general.
 For a few years I did not attempt any serious task on the Amazon cloud. It
took me a bit of time to get back my automatisms and adapt myself to the
changes. In particular, the cheapest instances,
t2.nano, are only
accessible via virtual private clouds (VPC), and it was a bit difficult for
me to find how to create a simple one. Perhaps this is because all AWS
accounts created after March 18, 2013, automatically have a default VPC, and
everybody else who needed their own simple VPC have created it a long time
ago already. In the end, this was not complicated at all. This is probably
why I could not find a tutorial.
In brief, one needs first to create a VPC. If it is just for spawning an
instance from time to time, the IP range does not matter much. Default VPCs
are using 172.31.0.0/16, so let's do the same.
CIDR_BLOCK=172.31.0.0/16
aws ec2 create-vpc --cidr-block $CIDR_BLOCK
VPC. The same pattern will be repeated for each
command creating something. One can also find the VPC's identifier with the
command aws ec2 describe-vpcs.
VPC=vpc-XXXXXXXX
SUBNET. In order that the instances receive a public IP
address like in default VPCs and like in the usual behaviour of the VPC-less
Cloud, one needs to set the attribute MapPublicIpOnLaunch.
aws ec2 create-subnet --vpc-id $VPC --cidr-block $CIDR_BLOCK
SUBNET=subnet-XXXXXXXX
aws ec2 modify-subnet-attribute --subnet-id $SUBNET --map-public-ip-on-launch
GATEWAY) and attach it to
the VPC.
aws ec2 create-internet-gateway
GATEWAY=igw-XXXXXXXX
aws ec2 attach-internet-gateway --internet-gateway-id $GATEWAY --vpc-id $VPC
describe-route-tables. Then, create a default route to
the gateway.
aws ec2 describe-route-tables
ROUTETABLE=rtb-XXXXXXXX
aws ec2 create-route --route-table-id $ROUTETABLE --destination-cidr-block 0.0.0.0/0 --gateway-id $GATEWAY
aws ec2 describe-security-groups
SECURITY_GROUP=sg-XXXXXXXX
aws ec2 authorize-security-group-ingress --group-id $SECURITY_GROUP --protocol tcp --port 22 --cidr 0.0.0.0/0
/etc/apt/sources.list):
  deb  tor+http://vwakviie2ienjx6t.onion/debian          jessie            main
  deb  tor+http://vwakviie2ienjx6t.onion/debian          jessie-updates    main
  deb  tor+http://sgvtcaew4bxjd7ln.onion/debian-security jessie/updates    main
deb tor+http://sdscoq7snqtznauu.onion/torproject.org jessie main
 This is a repost and update of my retirement letter sent privately to Debian last month, July 10, 2016. At that time I received many notes of appreciation and good wishes which I treasure. Now, I d like to say goodbye to the broader Debian community and, as well, indicate which of the cleanup items have since been addressed in strikethrough style and with annotations. Also, I d like to stay in touch with many of you, so I have added some comments oriented towards those of you who are interested in doing that after the letter.
When in 1995, on a tip from a friend, I installed Debian on my 386 at work and was enthralled with the results, I could not have foreseen that two years later, friends I had made on channel #debian would nudge me to become a Debian developer. Nor when that happened did I have any idea that twenty years later, I d consider Debian to be like family, the greatest free software community in the world, and would still be promoting it and helping people with it whenever I could. Debian quietly, unexpectedly became a part of what defines me. My priorities in life have changed over that time, though. I have shifted my attention to things that are more important to me in life, such as my family, my health and well-being physically and spiritually, and bringing all I can to bear on the task of preserving our local wilderness areas and trails. In the latter area, I m now bringing all of what Debian has helped shaped me to be to the table, launching some ambitious projects I hope will bear fruit in the coming years, and make a measurable contribution to help us hang onto our precious natural preserves where I live. Unfortunately, as I ve poured more time and energy into these things, I ve increasingly not been giving my packages the care they need. Nor do I have any roles or goals now for any of the Debian projects I was previously involved in. So, after much careful deliberation, and as much as it pains me to say it, it s time to retire as a Debian developer. It has been a great privilege to work with you, and to meet many of you in New York at Debconf 10. I plan to be around online, and will continue to take an interest in Debian, lending a hand when I can. Thanks for all of the fun times, for all that I ve learned, and for the privilege to make awesome things with you. I ll treasure this forever. So much for the soppy bits.Now, business. These things remain to clean up upon my departure, and I d appreciate help from QA, and anyone else who can lend a hand. My packages are effectively orphaned, but I haven t the time to do any of the cleanup myself, so please speak up if you can help.
There are also some Alioth projects / lists that are defunct that I ll need to talk to the Alioth admins about cleaning up in the coming days. One of these is <debian-eeepc-devel@lists.alioth.debian.org> and since it is still listed as the maintainer of eeepc-acpi-scripts, that needs to be sorted out before the list can be closed. Thanks again, and see you around!
- Debian Jr.
- O: junior-doc. The junior-doc package has been awaiting an overhaul by whoever revives the project since I gave it up years ago. I m still listed as maintainer and that should be changed to Debian Junior Maintainers <debianjr-maintainers@lists.alioth.debian.org> if they want it. Otherwise, it is orphaned.
I should also be dropped from Uploaders from debian-junior, the metapackages source.Fixed in git.- Tux Paint. This is a very special package that deserves to go to someone who will love it and care for it well. There are three source packages in all:
- O: tuxpaint
- O: tuxpaint-config
- O: tuxpaint-stamps
- O: xletters. This is a cute little typing practice game and needs a new maintainer.
XPilot is co-maintained by Phil Brooke <pjb@debian.org>, so he should replace me as Maintainer.Phil said he ll pick up xpilot-ng and will also look at xpilot-extra.
xpilot-ngO: xpilot-extra (recently removed from testing due to my neglect, and not co-maintained by Phil; it s unclear if anyone really uses this anymore)- GTypist is co-maintained by Daniel Leidert <dleidert@debian.org> and should replace me as Maintainer.
My ruby packages. A group of packages that I brought into Debian as dependencies of taskwarrior-web, which I never completed. Maybe they ll be useful in and of themselves, and maybe not. In any case, they are maintained by pkg-ruby-extras-maintainers, but I m the sole developer in Uploaders and should be removed:Fixed in git.
ruby-blockenspielruby-parseconfigruby-rack-flash3ruby-simple-navigationruby-sinatra-simple-navigationruby-term-ansicolorruby-versionomyDebian Live stuff: I am listed in Uploaders for live-manual(fixed in git)and debian-installer-launcher(fixed in git)and need to be removed.- O: eeepc-acpi-scripts. The defunct Debian EeePC project has just this one package. Recently, the mailing list was asked about its status, and it was recently NMU d. To my knowledge, nobody from the original team remains to take care of it, so it needs a new maintainer. I should be removed from Uploaders, and since the Debian Eee PC Team no longer exists, it should be removed as maintainer. It is effectively orphaned unless someone speaks up.
Ben


 Here is my monthly update covering a large part of what I have been doing in the free software world (previously):
Next.