Search Results: "ema"

26 January 2016

Michal Čihař: Weekly phpMyAdmin contributions 2016-W03

Last week consisted mostly of code fixes. For example the code for checking latest phpMyAdmin turned out to be buggy under some PHP configurations. But most work for last week is not yet public, you will see it in upcoming security releases. All handled issues:

Filed under: English phpMyAdmin 0 comments

25 January 2016

Antoine Beaupr : Internet in Cuba

A lot has been written about the Internet in Cuba over the years. I have read a few articles, from New York Times' happy support for Google's invasion of Cuba to RSF's dramatic and fairly outdated report about censorship in Cuba. Having written before about Internet censorship in Tunisia, I was curious to see if I could get a feel of what it is like over there, now that a new Castro is in power and the Obama administration has started restoring diplomatic ties with Cuba. With those political changes coming signifying the end of an embargo that has been called genocidal by the Cuban government, it is surprisingly difficult to get fresh information about the current state of affairs. This article aims to fill that gap in clarifying how the internet works in Cuba, what kind of censorship mechanisms are in place and how to work around them. It also digs more technically into the network architecture and performance. It is published in the hope of providing both Cubans and the rest of the world with a better understanding of their network and, if possible, Cubans ways to access the internet more cheaply or without censorship.

"Censorship" and workarounds Unfortunately, I have been connected to the internet only through the the Varadero airport and the WiFi of a "full included" resort near Jibacoa. I have to come to assume that this network is likely to be on a segregated, uncensored internet while the rest of the country suffers the wrath of the Internet censorship in Cuba I have seen documented elsewhere. Through my research, I couldn't find any sort of direct censorship. The Netalyzr tool couldn't find anything significantly wrong with the connection, other than the obvious performance problems related both to the overloaded uplinks of the Cuban internet. I ran an incomplete OONI probe as well, and it seems there was no obvious censorship detected there as well, at least according to folks in the helpful #ooni IRC channel. Tor also works fine, and could be a great way to avoid the global surveillance system described later in this article. Nevertheless, it still remains to be seen how the internet is censored in the "real" Cuban internet, outside of the tourist designated areas - hopefully future visitors or locals can expand on this using the tools mentioned above, using the regular internet. Usual care should be taken when using any workaround tools, mentioned in this post or not, as different regimes over the world have accused, detained, tortured and killed sometimes for the mere fact of using or distributing circumvention tools. For example, a Russian developer was arrested and detained in 2001 by United States' FBI for exposing vulnerabilities in the Adobe e-books copy protection mechanisms. Similarly, people distributing Tor and other tools have been arrested during the period prior to the revolution in Tunisia.

The Cuban captive portal There is, however, a more pernicious and yet very obvious censorship mechanism at work in Cuba: to get access to the internet, you have to go through what seems to be a state-wide captive portal, which I have seen both at the hotel and the airport. It is presumably deployed at all levels of the internet access points. To get credentials through that portal, you need a username and password which you get by buying a Nauta card. Those cards cost 2$CUC and get you an hour of basically unlimited internet access. That may not seem like a lot for a rich northern hotel party-goer, but for Cubans, it's a lot of money, given that the average monthly salary is around 20$CUC. The system is also pretty annoying to use, because it means you do not get continuous network access: every hour, you need to input a new card, which will obviously make streaming movies and other online activities annoying. It also makes hosting servers basically impossible. So while Cuba does not have, like China or Iran, a "great firewall", there is definitely a big restriction to going online in Cuba. Indeed, it seems to be how the government ensures that Cubans do not foment too much dissent online: keep the internet slow and inaccessible, and you won't get too many Arab spring / blogger revolutions.

Bypassing the Cuban captive portal The good news is that it is perfectly possible for Cubans (or at least for a tourist like me with resources outside of the country) to bypass the captive portal. Like many poorly implemented portals, the portal allows DNS traffic to go through, which makes it possible to access the global network for free by using a tool like iodine which tunnels IP traffic over DNS requests. Of course, the bandwidth and reliability of the connection you get through such a portal is pretty bad. I have regularly seen 80% packet loss and over two minutes of latency:
--- 10.0.0.1 ping statistics ---
163 packets transmitted, 31 received, 80% packet loss, time 162391ms
rtt min/avg/max/mdev = 133.700/2669.535/64188.027/11257.336 ms, pipe 65
Still, it allowed me to login to my home server through SSH using Mosh to workaround the reliability issues. Every once in a while, mosh would get stuck and keep on trying to send packets to probe the server, which would clog the connection even more. So I regularly had to restart the whole stack using these commands:
killall iodine # stop DNS tunnel
nmcli n off # turn off wifi to change MAC address
macchanger -A wlan0 # change MAC address
nmcli n on # turn wifi back on
sleep 3 # wait for wifi to settle
iodine-client-start # restart DNS tunnel
The Koumbit Wiki has good instructions on how to setup a DNS tunnel. I am wondering if such a public service could be of use for Cubans, although I am not sure how it could be deployed only for Cubans, and what kind of traffic it could support... The fact is that iodine does require a server to operate, and that server must be run on the outside of the censored perimeter, something that Cubans may not be able to afford in the first place. Another possible way to save money with the captive portal would be to write something that automates connecting and disconnecting from the portal. You would feed that program a list of credentials and it would connect to the portal only on demand, and disconnect as soon as no traffic goes through. There are details on the implementation of the captive portal below that may help future endeavours in that field.

Private information revealed to the captive portal It should be mentioned, however, that the captive portal has a significant amount of information on clients, which is a direct threat to the online privacy of Cuban internet users. Of course the unique identifiers issued with the Nauta cards can be correlated with your identity, right from the start. For example, I had to give my room number to get a Nauta card issued. Then the central portal also knows which access point you are connected to. For example, the central portal I was connected to Wifi_Memories_Jibacoa which, for anyone that cares to research, will give them a location of about 20 square meters where I was located when connected (there is only one access point in the whole hotel). Finally, the central portal also knows my MAC address, a unique identifier for the computer I am using which also reveals which brand of computer I am using (Mac, Lenovo, etc). While this address can be changed, very few people know that, let alone how. This led me to question whether I would be allowed back in Cuba (or even allowed out!) after publishing this blog post, as it is obvious that I can be easily identified based on the time this article was published, my name and other details. Hopefully the Cuban government will either not notice or not care, but this can be a tricky situation, obviously. I have heard that Cuban prisons are not the best hangout place in Cuba, to say the least...

Network configuration assessment This section is more technical and delves more deeply in the Cuban internet to analyze the quality and topology of the network, along with hints as to which hardware and providers are being used to support the Cuban government.

Line quality The internet is actually not so bad in the hotel. Again, this may be because of the very fact that I am in that hotel, and I get a privileged access to the new fiber line to Venezuela, the ALBA-1 link. The line speed I get is around 1mbps, according to speedtest, which selected a server from LIME in George Town, Cayman Islands:
[1034]anarcat@angela:cuba$ speedtest
Retrieving speedtest.net configuration...
Retrieving speedtest.net server list...
Testing from Empresa de Telecomunicaciones de Cuba (152.206.92.146)...
Selecting best server based on latency...
Hosted by LIME (George Town) [391.78 km]: 317.546 ms
Testing download speed........................................
Download: 1.01 Mbits/s
Testing upload speed..................................................
Upload: 1.00 Mbits/s
Latency to the rest of the world is of couse slow:
--- koumbit.org ping statistics ---
122 packets transmitted, 120 received, 1,64% packet loss, time 18731,6ms
rtt min/avg/max/sdev = 127,457/156,097/725,211/94,688 ms
--- google.com ping statistics ---
122 packets transmitted, 121 received, 0,82% packet loss, time 19371,4ms
rtt min/avg/max/sdev = 132,517/160,095/724,971/93,273 ms
--- redcta.org.ar ping statistics ---
122 packets transmitted, 120 received, 1,64% packet loss, time 40748,6ms
rtt min/avg/max/sdev = 303,035/339,572/965,092/97,503 ms
--- ccc.de ping statistics ---
122 packets transmitted, 72 received, 40,98% packet loss, time 19560,2ms
rtt min/avg/max/sdev = 244,266/271,670/594,104/61,933 ms
Interestingly, Koumbit is actually the closest host in the above test. It could be that Canadian hosts are less affected by bandwidth problems compared to US hosts because of the embargo.

Network topology The various traceroutes show a fairly odd network topology, but that is typical of what I would described as "colonized internet users", which have layers and layers of NAT and obscure routing that keep them from the real internet. Just like large corporations are implementing NAT in a large scale, Cuba seems to have layers and layers of private RFC 1918 IPv4 space. A typical traceroute starts with:
traceroute to koumbit.net (199.58.80.33), 30 hops max, 60 byte packets
 1  10.156.41.1 (10.156.41.1)  9.724 ms  9.472 ms  9.405 ms
 2  192.168.134.137 (192.168.134.137)  16.089 ms  15.612 ms  15.509 ms
 3  172.31.252.113 (172.31.252.113)  15.350 ms  15.805 ms  15.358 ms
 4  pos6-0-0-agu-cr-1.mpls.enet.cu (172.31.253.197)  15.286 ms  14.832 ms  14.405 ms
 5  172.31.252.29 (172.31.252.29)  13.734 ms  13.685 ms  14.485 ms
 6  200.0.16.130 (200.0.16.130)  14.428 ms  11.393 ms  10.977 ms
 7  200.0.16.74 (200.0.16.74)  10.738 ms  10.019 ms  10.326 ms
 8  ix-11-3-1-0.tcore1.TNK-Toronto.as6453.net (64.86.33.45)  108.577 ms  108.449 ms
Let's take this apart line by line:
 1  10.156.41.1 (10.156.41.1)  9.724 ms  9.472 ms  9.405 ms
This is my local gateway, probably the hotel's wifi router.
 2  192.168.134.137 (192.168.134.137)  16.089 ms  15.612 ms  15.509 ms
This is likely not very far from the local gateway, probably still in Cuba. It in one bit away from the captive portal IP address (see below) so it is very likely related to the captive portal implementation.
 3  172.31.252.113 (172.31.252.113)  15.350 ms  15.805 ms  15.358 ms
 4  pos6-0-0-agu-cr-1.mpls.enet.cu (172.31.253.197)  15.286 ms  14.832 ms  14.405 ms
 5  172.31.252.29 (172.31.252.29)  13.734 ms  13.685 ms  14.485 ms
All those are withing RFC 1918 space. Interestingly, the Cuban DNS servers resolve one of those private IPs as within Cuban space, on line #4. That line is interesting because it reveals the potential use of MPLS.
 6  200.0.16.130 (200.0.16.130)  14.428 ms  11.393 ms  10.977 ms
 7  200.0.16.74 (200.0.16.74)  10.738 ms  10.019 ms  10.326 ms
Those two lines are the only ones that actually reveal that the route belongs in Cuba at all. Both IPs are in a tiny (/24, or 256 IP addresses) network allocated to ETECSA, the state telco in Cuba:
inetnum:     200.0.16/24
status:      allocated
aut-num:     N/A
owner:       EMPRESA DE TELECOMUNICACIONES DE CUBA S.A. (IXP CUBA)
ownerid:     CU-CUBA-LACNIC
responsible: Rafael L pez Guerra
address:     Ave. Independencia y 19 Mayo, s/n,
address:     10600 - La Habana - CH
country:     CU
phone:       +53 7 574242 []
owner-c:     JOQ
tech-c:      JOQ
abuse-c:     JEM52
inetrev:     200.0.16/24
nserver:     NS1.NAP.ETECSA.NET
nsstat:      20160123 AA
nslastaa:    20160123
nserver:     NS2.NAP.ETECSA.NET
nsstat:      20160123 AA
nslastaa:    20160123
created:     20030512
changed:     20140610
Then the last hop:
 8  ix-11-3-1-0.tcore1.TNK-Toronto.as6453.net (64.86.33.45)  108.577 ms  108.449 ms  108.257 ms
...interestingly, lands directly in Toronto, in this case going later to Koumbit but that is the first hop that varies according to the destination, hops 1-7 being a common trunk to all external communications. It's also interesting that this shoves a good 90 milliseconds extra in latency, showing that a significant distance and number of equipment crossed. Yet a single hop is crossed, not showing the intermediate step of the Venezuelan link or any other links for that matter. Something obscure is going on there... Also interesting to note is the traceroute to the redirection host, which is only one hop away:
traceroute to 192.168.134.138 (192.168.134.138), 30 hops max, 60 byte packets
 1  192.168.134.138 (192.168.134.138)  6.027 ms  5.698 ms  5.596 ms
Even though it is not the gateway:
$ ip route
default via 10.156.41.1 dev wlan0  proto static  metric 1024
10.156.41.0/24 dev wlan0  proto kernel  scope link  src 10.156.41.4
169.254.0.0/16 dev wlan0  scope link  metric 1000
This means a very close coordination between the different access points and the captive portal system. Finally, note that there seems to be only three peers to the Cuban internet: Teleglobe, formerly Canadian, now owned by the Indian [[!wiki Tata group]], and Telef nica, the Spanish Telco that colonized most of Latin America's internet, all the way down to Argentina. This is confirmed by my traceroutes, which show traffic to Koumbit going through Tata and Google's going through Telef nica.

Captive portal implementation The captive portal is https://www.portal-wifi-temas.nauta.cu/ (not accessible outside of Cuba) and uses a self-signed certificate. The domain name resolves to 190.6.81.230 in the hotel. Accessing http://1.1.1.1/ gives you a status page which allows you to disconnect from the portal. It actually redirects you to https://192.168.134.138/logout.user. That is also a self-signed, but different certificate. That certificate actually reveals the implication of Gemtek which is a "world-leading provider of Wireless Broadband solutions, offering a wide range of solutions from residential to business". It is somewhat unclear if the implication of Gemtek here is deliberate or a misconfiguration on the part of Cuban officials, especially since the certificate is self-signed and was issued in 2002. It could be, however, a trace of the supposed involvement of China in the development of Cuba's networking systems, although Gemtek is based in Taiwan, and not in the China mainland. That IP, in turn, redirects you to the same portal but in a page that shows you the statistics:
https://www.portal-wifi-temas.nauta.cu/?mac=0024D1717D18&script=logout.user&remain_time=00%3A55%3A52&session_time=00%3A04%3A08&username=151003576287&clientip=10.156.41.21&nasid=Wifi_Memories_Jibacoa&r=ac%2Fpopup
Notice how you see the MAC address of the machine in the URL (randomized, this is not my MAC address), along with the remaining time, session time, client IP and the Wifi access point ESSID. There may be some potential in defrauding the session time there, I haven't tested it directly. Hitting Actualizar redirects you back to the IP address, which redirects you to the right URL on the portal. The "real" logout is at:
http://192.168.134.138/logout.user?cmd=logout
The login is performed against https://www.portal-wifi-temas.nauta.cu/index.php?r=ac/login with a referer of:
https://www.portal-wifi-temas.nauta.cu/?&nasid=Wifi_Memories_Jibacoa&nasip=192.168.134.138&clientip=10.156.41.21&mac=EC:55:F9:C5:F2:55&ourl=http%3a%2f%2fgoogle.ca%2f&sslport=443&lang=en-US%2cen%3bq%3d0.8&lanip=10.156.41.1
Again, notice the information revealed to the central portal.

Equipment and providers I ran Nmap probes against both the captive portal and the redirection host, in the hope of finding out how they were built and if they could reveal the source of the equipment used. The complete nmap probes are available in nmap, but it seems that the captive portal is running some embedded device. It is confusing because the probe for the captive portal responds as if it was the gateway, which blurs even more the distinction between the hotel's gateway and the captive portal. This raises the distinct possibility that all access points are actually captive portal that authenticate to another central server. The nmap traces do show three distinct hosts however:
  • the captive portal (www.portal-wifi-temas.nauta.cu, 190.6.81.230)
  • some redirection host (192.168.134.138)
  • the hotel's gateway (10.156.41.1)
They do have distinct signatures so the above may be just me misinterpreting traceroute and nmap results. Your comments may help in clarifying the above. Still, the three devices show up as running Linux, in the two last cases versions between 2.4.21 and 2.4.31. Now, to find out which version of Linux it is running is way more challenging, and it is possible it is just some custom Linux distribution. Indeed, the webserver shows up as G4200.GSI.2.22.0155 and the SSH server is running OpenSSH 3.0.2p1, which is basically prehistoric (2002!) which corroborates the idea that this is some Gemtek embedded device. The fact that those devices are running 14 years old software should be a concern to the people responsible for those networks. There is, for example, a remote root vulnerability that affects that specific version of OpenSSH, among many other vulnerabilities.

A note on Nauta card's security Finally, one can note that it is probably trivial to guess card UIDs. All cards i have here start with the prefix 15100, the following digits being 3576 or 4595, presumably depending on the "batch" that was sent to different hotels, which seems to be batches of 1000 cards. You can also correlate the UID with the date at which the card was issued. For example, 15100357XXX cards are all valid until 19/03/2017, and 151004595XXX cards are all valid until 23/03/2017. Here's the list of UIDs I have seen:
151004595313
151004595974
151003576287
151003576105
151003576097
The passwords, on the other hand, do seem fairly random (although my sample size is small). Interestingly, those passwords are also 12 digits long, which is about as strong as a seven-letter password (mixed uppercase and lowercase). If there are no rate-limiting provisions on that captive portal, it could be possible to guess those passwords, since you have free rein on accessing those routers. Depending on the performance of the routers, you could be lucky and find a working password for free...

Conclusion Clearly, Internet access in Cuba needs to be modernized. We can clearly see that Cuba years behind the rest of the Americas, if only through the percentage of the population with internet access, or download speeds. The existence of a centralized captive portal also enables a huge surveillance potential that should be a concern for any Cuban, or for that matter, anyone wishing to live in a free society. The answer, however, lies not in the liberalization of commerce and opening the doors to the US companies and their own systems of surveillance. It should be possible, and even desirable for Cubans to establish their own neutral network, a proposal I have made in the past even for here in Qu bec. This network could be used and improved by Cubans themselves, prioritizing local communities that would establish their own infrastructure according to their own needs. I have been impressed by this article about the El Paquete system - it shows great innovation and initiative from Cubans which are known for engaging in technology in a creative way. This should be leveraged by letting Cubans do what they want with their networks, not telling them what to do. The best the Googles of this world can do to help Cuba is not to colonize Cuba's technological landscape but to cleanup their own and make their own tools more easily accessible and shareable offline. It is something companies can do right now, something I detailed in a previous article.

24 January 2016

Wouter Verhelst: Playing with Letsencrypt

While I'm not convinced that encrypting everything by default is necessarily a good idea, it is certainly true that encryption has its uses. Unfortunately, for the longest time getting an SSL certificate from a CA was quite a hassle -- and then I'm not even mentioning the fact that it would cost money, too. In that light, the letsencrypt project is a useful alternative: rather than having to dabble with emails or webforms, letsencrypt does everything by way of a few scripts. Also, the letsencrypt CA is free to use, in contrast to many other certificate authorities. Of course, once you start scripting, it's easy to overdo it. When you go to the letsencrypt website and try to install their stuff, they point you to a "letsencrypt-auto" thing, which starts installing a python virtualenv and loads of other crap, just so we can talk to a server and get a certificate properly signed. I'm sure that makes sense for some people, and I'm also sure it makes some things significantly easier, but honestly, I think it's a bit overkill. Luckily, there is also a regular letsencrypt script that doesn't do all the virtualenv stuff, and which is already packaged for Debian, so installing that gets us rid of the overkill bits. It's not in stable, but it is an arch:all package. Unfortunately, not all dependencies are available in Jessie, but backporting it turned out to be not too complicated. Once the client is installed, you need to get it to obtain a certificate, and you need to have the certificate be activated for your webserver. By default, the letsencrypt client will update your server configuration for you, and run a temporary webserver, and do a whole lot of other things that I would rather not see it do. The good news, though, is that you can switch all that off. If you're willing to let it write a few files to your DocumentRoot, it can do the whole thing without any change to your system:
letsencrypt certonly -m <your mailaddress> --accept-tos --webroot -w \
    /path/to/DocumentRoot -d example.com -d www.example.com
In that command, the -m option (with mail address) and the --accept-tos option are only required the first time you ever run letsencrypt. Doing so creates an account for you at letsencrypt.org, without which you cannot get any certificates. The --accept-tos option specifies that you accept their terms of service, which you might want to read first before blindly accepting. If all goes well, letsencrypt will tell you that it wrote your account information and some certificates somewhere under /etc/letsencrypt. All that's left is to update your webserver configuration so that the certificates are actually used. No, I won't tell you how that's done -- if you need that information, it's probably better if you just use the apache or nginx plugin of letsencrypt, which updates your webserver's configuration automatically. But if you already know how to do so, and prefer to maintain your configuration by yourself, then it's good to know that it is at least possible. Since we specified two -d parameters, the certificate you get from the letsencrypt CA will have subjectAlternativeName fields, allowing you to use them for more than one domain name. I specified example.com and www.example.com as the valid names, but there is nothing in letsencrypt requiring that the domain names you specify share a suffix; so yes, it is certainly possible to have multiple domains on a single certificate, if you want that. Finally, you need to ensure that your certificates are renewed before they expire. The easiest way to do that is to add a cronjob, which runs letsencrypt again; only this time, you'll need slightly different options:
letsencrypt certonly --renew-by-default --webroot -w \
    /path/to/DocumentRoot -d domain.name.tld -d www.domain.name.tld
The --renew-by-default option tells letsencrypt that you want to renew your certificates, not create new ones. If you specify this, the old certificate will be revoked, and a new one will be generated, again with three months validity. The symlinks under /etc/letsencrypt/live will be updated, so if your webserver's configuration uses those as the path to your certificates, you don't need to update any configuration files (although you may need to restart your webserver). You'll also notice that the -m and --accept-tos options are not specified this time around; this is because those are only required when you want to create an account -- once that step has been taken, letsencrypt will read the necessary information from its configuration files (and creating a new account for every renewal is just silly). With that, you now have a working, browser-trusted, certificate. Update: fix mistake about installing on Jessie. It's possible (I've done so), but it's been a while and I forgot that I had to recompile several of letsencrypt's dependencies in order for it to be installable.

21 January 2016

Tanguy Ortolo: Removing sam2p from Debian

Issues with sam2p and removal I have been maintaining the Debian package of sam2p for some time. Unfortunately, the upstream development of that program is no longer active, and it is using an old custom build chain that no longer works with recent version of GCC. This package is currently failing to build from source, and while I have been able to patch some issues in the past, and it may still be possible to fix it again, this is not really sustainable. I am therefore considering to remove sam2p from Debian, unless someone has a very good reason to keep it and is able and willing to maintain it.Alternative sam2p is a raster image conversion tool that can convert PNG and JPEG to EPS and PDF while keeping their compression, which is mostly useful to use them in documents compiled with LaTeX. Fortunately, the same can be done with ImageMagick. If you want to convert to EPS, you have to specify that you want EPS 2 or 3, otherwise it would produce EPS level 1 which does not provide native raster compression:
% convert debian-openlogo-raster100.png \
          eps3:debian-openlogo-raster100.eps
% convert debian-openlogo-raster100.png \
          debian-openlogo-raster100.pdf
% ls -lh
1.7K debian-openlogo-raster100.png
6.0K debian-openlogo-raster100.eps
8.8K debian-openlogo-raster100.pdf
% convert photograph.jpg eps3:photograph.eps
% convert photograph.jpg photograph.pdf
% ls -lh
657K photograph.jpg
662K photograph.eps
664K photograph.pdf
% convert scanned-document.png eps3:scanned-document.eps
% convert scanned-document.png scanned-document.pdf
140K scanned-document.png
145K scanned-document.eps
150K scanned-document.pdf
This is a bit less efficient than sam2p, as convert seems to add some fixed overhead, but it does keep the appropriate compression algorithm. See this documentation page from ImageMagick for more information. Using appropriate formats As a reminder, when writing LaTeX documents, depending on your build chain, you can use:
photographs
JPEG or EPS (converted from JPEG with ImageMagick);
raster drawings, screenshots
PNG or EPS (converted from PNG with ImageMagick);
vector graphics
PDF or EPS (convertes from SVG with Inkscape).

Jonas Smedegaard: IT@school

Siri and I are on a journey through India and Nepal, with the aim of learning about needs of Debian derivatives, to improve Debian and encourage closer integration.

Distribution IT@school is a distribution originally based on Debian, later rebased on Ubuntu. Next release will possibly again be a direct derivative of Debian, or maybe even - time will tell - a Debian pure blend.

Aim is education As its name indicates, IT@school is targeted at schools: The system is used in 8th - 10th grades of most (or all?) public primary schools in Kerala, Together with KEK members Anto and Fayad, Siri and I met with former and current key participants in the project where we learned about its history and current status, and discussed some differences between Ubuntu and Debian. IT@school has a strong emphasis on the educational aspect, arguably setting it apart from Skolelinux/DebianEdu which emphasizes the technical aspect of relieving teachers from admin tasks. In the early years of deployment the project faced many hardware issues - e.g. in getting sound cards to work. This was seen not as problems but as beneficial learning for the teachers facing those issues. Kerala public school system has set the standard for other states in India, but sadly political support within the state has been weak in recent years. It is hoped that next election - this April - will bring a positive change.

School book IT@school is accompagnied by a school book written specifically for use of the included tools. No explicit license is applied to the book (which means it defaults to classic copyright). Possibly it will get Creative Commons licensed. If the school book gets a DFSG-free license, several collaboration opportunities emerge: Currently the book is drafted in LibreOffice but then - due to state procedures - finalized with PageMaker. Would be interesting to setup an alternate process using only Free tools - either with Scribus or XeLaTeX. An important detail here is to ensure that the process supports malayalam script.

Curriculum Work is in progress mapping FLOSS tools to the state curriculum. I recommended to share that work publicly with a Free license, to encourage comparisons across countries, and invite collaboration e.g. with Skolelunux/DebianEdu.

Blend for SBCs Some Kerala higher education schools (sorry, don't remember which) have bought some thousands of RaspberryPi2. I suggested to create a Debian Blend for SBCs (Single Board Computers) - we will see what comes of that idea

Blend for education I also suggested to make a Debian blend around IT@school distribution itself, with its strong focus on educational content - i.e. not just as addon to technical tools but the primary purpose pulling in tools as needed.

Russell Coker: Finding Storage Performance Problems

Here are some basic things to do when debugging storage performance problems on Linux. It s deliberately not an advanced guide, I might write about more advanced things in a later post. Disk Errors When a hard drive is failing it often has to read sectors several times to get the right data, this can dramatically reduce performance. As most hard drives aren t monitored properly (email or SMS alerts on errors) it s quite common for the first notification about an impending failure to be user complaints about performance. View your kernel message log with the dmesg command and look in /var/log/kern.log (or wherever your system is configured to store kernel logs) for messages about disk read errors, bus resetting, and anything else unusual related to the drives. If you use an advanced filesystem like BTRFS or ZFS there are system commands to get filesystem information about errors. For BTRFS you can run btrfs device stats MOUNTPOINT and for ZFS you can run zpool status . Most performance problems aren t caused by failing drives, but it s a good idea to eliminate that possibility before you continue your investigation. One other thing to look out for is a RAID array where one disk is noticeably slower than the others. For example if you have a RAID-5 or RAID-6 array every drive should have almost the same number of reads and writes, if one disk in the array is at 99% performance capacity and the other disks are at 5% then it s an indication of a failing disk. This can happen even if SMART etc don t report errors. Monitoring IO The iostat program in the Debian sysstat package tells you how much IO is going to each disk. If you have physical hard drives sda, sdb, and sdc you could run the command iostat -x 10 sda sdb sdc to tell you how much IO is going to each disk over 10 second periods. You can choose various durations but I find that 10 seconds is long enough to give results that are useful. By default iostat will give stats on all block devices including LVM volumes, but that usually gives too much data to analyse easily. The most useful things that iostat tells you are the %util (the percentage utilisation anything over 90% is a serious problem), the reads per second r/s , and the writes per second w/s . The parameters to iostat for block devices can be hard drives, partitions, LVM volumes, encrypted devices, or any other type of block device. After you have discovered which block devices are nearing their maximum load you can discover which of the partitions, RAID arrays, or swap devices on that disk are causing the load in question. The iotop program in Debian (package iotop) gives a display that s similar to that of top but for disk io. It generally isn t essential (you can run ps ax grep D to get most of that information), but it is handy. It will tell you which programs are causing IO on a busy filesystem. This can be good when you have a busy system and don t know why. It isn t very useful if you have a system that is used for one task, EG a database server that is known to be busy doing database stuff. It s generally a good idea to have sysstat and iotop installed on all systems. If a system is experiencing severe performance problems you might not want to wait for new packages to be installed. In Debian the sysstat package includes the sar utility which can give historical information on system load. One benefit of using sar for diagnosing performance problems is that it shows you the time of day that has the most load which is the easiest time to diagnose performance problems. Swap Use Swap use sometimes confuses people. In many cases swap use decreases overall disk use, this is the design of the Linux paging algorithms. So if you have a server that accesses a lot of data it might swap out some unused programs to make more space for cache. When you have multiple virtual machines on one system sharing the same disks it can be difficult to determine the best allocation for RAM. If one VM has some applications allocating a lot of RAM but not using it much then it might be best to give it less RAM and force those applications into swap so that another VM can cache all the data it accesses a lot. The important thing is not the amount of swap that is allocated but the amount of IO that goes to the swap partition. Any significant amount of disk IO going to a swap device is a serious problem that can be solved by adding more RAM. Reads vs Writes The ratio of reads to writes depends on the applications and the amount of RAM. Some applications can have most of their reads satisfied from cache. For example an ideal configuration of a mail server will have writes significantly outnumber reads (I ve seen ratios of 5:1 for writes to reads on real mail servers). Ideally a mail server will cache all new mail for at least an hour and as the most prolific users check their mail more frequently than that most mail will be downloaded before it leaves the cache. If you have a mail server with reads outnumbering writes then it needs more RAM. RAM is cheap nowadays so if you don t want to compete with Gmail it should be cheap to buy enough RAM to cache all recent mail. The ratio of reads to writes is important because it s one way of quickly determining if you have enough RAM and adding RAM is often the cheapest way of improving performance. Unbalanced IO One common performance problem on systems with multiple disks is having more load going to some disks than to others. This might not be a problem (EG having cron jobs run on disks that are under heavy load while the web server accesses data from lightly loaded disks). But you need to consider whether it s desirable to have some disks under more load than others. The simplest solution to this problem is to just have a single RAID array for all data storage. This is also the solution that gives you the maximum available disk space if you use RAID-5 or RAID-6. A more complex option is to use some SSDs for things that require performance and disks for things that don t. This can be done with the ZIL and L2ARC features of ZFS or by just creating a filesystem on SSD for the data that is most frequently accessed. What Did I Miss? I m sure that I missed something, please let me know of any other basic things to do or suggestions for a post on more advanced things.

18 January 2016

Russ Allbery: rra-c-util 5.10

Despite the name of the package, most of the changes in this release are actually to the Perl test infrastructure. I decided to finally standardize the versions of the modules embedded in wallet, but discovered the need to add an exclusion list so that I don't have to change the version of the schema module. (That currently drives database schema upgrades.) While doing that, I rediscovered that I have two versions of the module version check that shared a ton of code, so they've now been refactored into a module (and then debugged again, since I broke various things about the Automake integration). This release also fixes use of UNIX-specific path delimiters in my standard Perl docs/synopsis.t test, which fixed some failing tests in podlators. I would have been done with this somewhat sooner, but the Travis-CI tests for rra-c-util started failing in the IPv6 server test, and it took a lot of debugging to figure out why. It turned out that the environment allows creation of IPv6 sockets but not connecting to them, and my test for whether IPv6 was working didn't account for that. Now it does, so those tests are properly skipped when IPv6 is half-configured. You can get the latest version from the rra-c-util distribution page.

16 January 2016

Russ Allbery: podlators 4.05

Getting all the details right in a highly portable Perl core module that tries to support very old versions of Perl is tricky! And I clearly didn't do a good job of documenting previous decisions. This release reintroduces pod2man.PL and pod2text.PL generator scripts to get the right Perl invocation. I thought ExtUtils::MakeMaker and Module::Build now took care of this, but apparently they only take care of this on UNIX platforms, not on the non-UNIX platforms that require special execution logic. Thanks to a patch by Niko Tyni, this version of Pod::Man also falls back to non-utf8 behavior if the utf8 option is specified but the Encode module doesn't exist. This can help with some cross-build situations. I also finally figured out the problem with occasional test failures on random platforms: I was trying to clean up the temporary directory used by tests after each test, but the CPAN test systems run all the tests in parallel, so the tests were racing with each other. This release just leaves the temporary directory around and deletes it in make clean. You can get the latest version from the podlators distribution page.

14 January 2016

Sven Hoexter: call for trouble aka RM xchat

Well we want to freeze later this year so I started with the axing now. Maybe a bit premature like Mattia pointed out correctly in #debian-qa, because we've some maintained plugins for xchat around. cwirc a morse code via IRC plugin xchat-xsys system statistics output to a channel Update: There is a xsys plugin included with hexchat. xchat-guile GNU Scheme scripting plugin Update: Lionel agreed and created a RM bug. Thanks! I can survive without them, so I'd be fine with another three RM bugs. Now feel free to flame me, I promise to wear my finest asbestos underwear.

Lunar: Reproducible builds: week 37 in Stretch cycle

What happened in the reproducible builds effort between January 3rd and January 9th 2016:

Toolchain fixes David Bremner uploaded dh-elpa/0.0.18 which adds a --fix-autoload-date option (on by default) to take autoload dates from changelog. Lunar updated and sent the patch adding the generation of .buildinfo to dpkg.

Packages fixed The following packages have become reproducible due to changes in their build dependencies: aggressive-indent-mode, circe, company-mode, db4o, dh-elpa, editorconfig-emacs, expand-region-el, f-el, geiser, hyena, js2-mode, markdown-mode, mono-fuse, mysql-connector-net, openbve, regina-normal, sml-mode, vala-mode-el. The following packages became reproducible after getting fixed: Some uploads fixed some reproducibility issues, but not all of them: Patches submitted which have not made their way to the archive yet:
  • #809780 on flask-restful by Chris Lamb: implement support for SOURCE_DATE_EPOCH in the build system.
  • #810259 on avfs by Chris Lamb: implement support for SOURCE_DATE_EPOCH in the build system.
  • #810509 on apt by Mattia Rizzolo: ensure a stable file order is given to the linker.

reproducible.debian.net Add 2 more armhf build nodes provided by Vagrant Cascadian. This added 7 more armhf builder jobs. We now run around 900 tests of armhf packages each day. (h01ger) The footer of each page now indicates by which Jenkins jobs build it. (h01ger)

diffoscope development diffoscope 45 has been released on January 4th. It features huge memory improvements when comparing large files, several fixes of squashfs related issues that prevented comparing two Tails images, and improve the file list of tar and cpio archive to be more precise and consistent over time. It also fixes a typo that prevented the Mach-O to work (Rainer M ller), improves comparisons of ELF files when specified on the command line, and solves a few more encoding issues.

Package reviews 134 reviews have been removed, 30 added and 37 updated in the previous week. 20 new fail to build from source issues were reported by Chris Lamb and Chris West. prebuilder will now skip installing diffoscope to save time if the build results are identical. (Reiner Herrmann)

Elena 'valhalla' Grandi: Conservancy supporter, at last!

Conservancy supporter, at last!

Yesterday I've finally donated to become a Conservancy Supporter http://sfconservancy.org/supporter/.

The reasons to donate have already been explained many times both on Planet Debian http://planet.debian.org/ and elsewhere; a few weeks ago I wrote a post (in Italian) on the Ninux community blog https://blog.ninux.org/2015/12/03/causa-vmware-per-violazione-gpl-sponsor-ritirano-fondi-a-software-freedom-conservancy/ to spread the word about it.

So, why I haven't donated earlier?

Trying to donate via PayPal from Italy (and, it seems, from Europe in general) requires a PayPal account, which I don't have and don't want to have, so I contacted them to ask for bank transfer instructions.
The first instructions I received were too complex for my online-only bank account, so I asked my bank for help, there was an exchange of emails, further simpler instructions from their bank, a small donation to test everything and time passed.

Finally, the good news: it is possible to donate to Conservancy from Italy (and probably from elsewhere in EU) using a SEPA transfer with minimal commissions and usually available from the home banking websites, so that it doesn't require significantly more effort than using paypal.
You can contact Conservancy via e-mail mailto:accounting@sfconservancy.org to get the relevant payment data.

(Conservancy has an account in EUR which is then used to pay for expenses in EUR, so no currency conversion commission are involved.)

13 January 2016

Norbert Preining: Ian Buruma: Wages of Guilt

Since moving to Japan, I got more and more interested in history, especially the recent history of the 20th century. The book I just finished, Ian Buruma (Wiki, home page) Wages of Guilt Memories of War in Germany and Japan (Independent, NYRB), has been a revelation for me. As an Austrian living in Japan, I am experiencing the discrepancy between these two countries with respect to their treatment of war legacy practically daily, and many of my blog entries revolve around the topic of Japanese non-reconciliation.
Willy Brandt went down on his knees in the Warsaw ghetto, after a functioning democracy had been established in the Federal Republic of Germany, not before. But Japan, shielded from the evil world, has grown into an Oskar Matzerath: opportunistic, stunted, and haunted by demons, which it tries to ignore by burying them in the sand, like Oskar s drum.
Ian Buruma, Wages of Guilt, Clearing Up the Ruins
Buruma-Wages_of_Guilt The comparison of Germany and Japan with respect to their recent history as laid out in Buruma s book throws a spotlight on various aspects of the psychology of German and Japanese population, while at the same time not falling into the easy trap of explaining everything with difference in the guilt culture. A book of great depth and broad insights everyone having even the slightest interest in these topics should read.
This difference between (West) German and Japanese textbooks is not just a matter of detail; it shows a gap in perception.
Ian Buruma, Wages of Guilt, Romance of the Ruins
Only thinking about giving a halfway full account of this book is something impossible for me. The sheer amount of information, both on the German and Japanese side, is impressive. His incredible background (studies of Chinese literature and Japanese movie!) and long years as journalist, editor, etc, enriches the book with facets normally not available: In particular his knowledge of both the German and Japanese movie history, and the reflection of history in movies, were complete new aspects for me (see my recent post (in Japanese)). The book is comprised of four parts: The first with the chapters War Against the West and Romance of the Ruins; the second with the chapters Auschwitz, Hiroshima, and Nanking; the third with History on Trial, Textbook Resistance, and Memorials, Museums, and Monuments; and the last part with A Normal Country, Two Normal Towns, and Clearing Up the Ruins. Let us look at the chapters in turn: The boook somehow left me with a bleak impression of Japanese post-war times as well as Japanese future. Having read other books about the political ignorance in Japan (Norma Field s In the realm of a dying emperor, or the Chibana history), Buruma s characterization of Japanese politics is striking. He couldn t foresee the recent changes in legislation pushed through by the Abe government actually breaking the constitution, or the rewriting of history currently going on with respect to comfort women and Nanking. But reading his statement about Article Nine of the constitution and looking at the changes in political attitude, I am scared about where Japan is heading to:
The Nanking Massacre, for leftists and many liberals too, is the main symbol of Japanese militarism, supported by the imperial (and imperialist) cult. Which is why it is a keystone of postwar pacifism. Article Nine of the constitution is necessary to avoid another Nanking Massacre. The nationalist right takes the opposite view. To restore the true identity of Japan, the emperor must be reinstated as a religious head of state, and Article Nine must be revised to make Japan a legitimate military power again. For this reason, the Nanking Massacre, or any other example of extreme Japanese aggression, has to be ignored, softened, or denied.
Ian Buruma, Wages of Guilt, Nanking
While there are signs of resistance in the streets of Japan (Okinawa and the Hanako bay, the demonstrations against secrecy law and reversion of the constitution), we are still to see a change influenced by the people in a country ruled and distributed by oligarchs. I don t think there will be another Nanking Massacre in the near future, but Buruma s books shows that we are heading back to a nationalistic regime similar to pre-war times, just covered with a democratic veil to distract critics.
I close with several other quotes from the book that caught my attention: In the preface and introduction:
[ ] mainstream conservatives made a deliberate attempt to distract people s attention from war and politics by concentrating on economic growth.
The curious thing was that much of what attracted Japanese to Germany before the war Prussian authoritarianism, romantic nationalism, pseudo-scientific racialism had lingered in Japan while becoming distinctly unfashionable in Germany.
In Romance of the Ruins:
The point of all this is that Ikeda s promise of riches was the final stage of what came to be known as the reverse course, the turn away from a leftist, pacifist, neutral Japan a Japan that would never again be involved in any wars, that would resist any form of imperialism, that had, in short, turned its back for good on its bloody past. The Double Your Incomes policy was a deliberate ploy to draw public attention away from constitutional issues.
In Hiroshima:
The citizens of Hiroshima were indeed victims, primarily of their own military rulers. But when a local group of peace activists petitioned the city of Hiroshima in 1987 to incorporate the history of Japanese aggression into the Peace Memorial Museum, the request was turned down. The petition for an Aggressors Corner was prompted by junior high school students from Osaka, who had embarrassed Peace Museum officials by asking for an explanation about Japanese responsibility for the war.
The history of the war, or indeed any history, is indeed not what the Hiroshima spirit is about. This is why Auschwitz is the only comparison that is officially condoned. Anything else is too controversial, too much part of the flow of history .
In Nanking, by the governmental pseudo-historian Tanaka:
Unlike in Europe or China, writes Tanaka, you won t find one instance of planned, systematic murder in the entire history of Japan. This is because the Japanese have a different sense of values from the Chinese or the Westerners.
In History on Trial:
In 1950, Becker wrote that few things have done more to hinder true historical self-knowledge in Germany than the war crimes trials. He stuck to this belief. Becker must be taken seriously, for he is not a right-wing apologist for the Nazi past, but an eminent liberal.
There never were any Japanese war crimes trials, nor is there a Japanese Ludwigsburg. This is partly because there was no exact equivalent of the Holocaust. Even though the behavior of Japanese troops was often barbarous, and the psychological consequences of State Shinto and emperor worship were frequently as hysterical as Nazism, Japanese atrocities were part of a military campaign, not a planned genocide of a people that included the country s own citizens. And besides, those aspects of the war that were most revolting and furthest removed from actual combat, such as the medical experiments on human guinea pigs (known as logs ) carried out by Unit 731 in Manchuria, were passed over during the Tokyo trial. The knowledge compiled by the doctors of Unit 731 of freezing experiments, injection of deadly diseases, vivisections, among other things was considered so valuable by the Americans in 1945 that the doctors responsible were allowed to go free in exchange for their data.
Some Japanese have suggested that they should have conducted their own war crimes trials. The historian Hata Ikuhiko thought the Japanese leaders should have been tried according to existing Japanese laws, either in military or in civil courts. The Japanese judges, he believed, might well have been more severe than the Allied tribunal in Tokyo. And the consequences would have been healthier. If found guilty, the spirits of the defendants would not have ended up being enshrined at Yasukuni. The Tokyo trial, he said, purified the crimes of the accused and turned them into martyrs. If they had been tried in domestic courts, there is a good chance the real criminals would have been flushed out.
After it was over, the Nippon Times pointed out the flaws of the trial, but added that the Japanese people must ponder over why it is that there has been such a discrepancy between what they thought and what the rest of the world accepted almost as common knowledge. This is at the root of the tragedy which Japan brought upon herself.
Emperor Hirohito was not Hitler; Hitler was no mere Shrine. But the lethal consequences of the emperor-worshipping system of irresponsibilities did emerge during the Tokyo trial. The savagery of Japanese troops was legitimized, if not driven, by an ideology that did not include a Final Solution but was as racialist as Hider s National Socialism. The Japanese were the Asian Herrenvolk, descended from the gods.
Emperor Hirohito, the shadowy figure who changed after the war from navy uniforms to gray suits, was not personally comparable to Hitler, but his psychological role was remarkably similar.
In fact, MacArthur behaved like a traditional Japanese strongman (and was admired for doing so by many Japanese), using the imperial symbol to enhance his own power. As a result, he hurt the chances of a working Japanese democracy and seriously distorted history. For to keep the emperor in place (he could at least have been made to resign), Hirohito s past had to be freed from any blemish; the symbol had to be, so to speak, cleansed from what had been done in its name.
In Memorials, Museums, and Monuments:
If one disregards, for a moment, the differences in style between Shinto and Christianity, the Yasukuni Shrine, with its relics, its sacred ground, its bronze paeans to noble sacrifice, is not so very different from many European memorials after World War I. By and large, World War II memorials in Europe and the United States (though not the Soviet Union) no longer glorify the sacrifice of the fallen soldier. The sacrificial cult and the romantic elevation of war to a higher spiritual plane no longer seemed appropriate after Auschwitz. The Christian knight, bearing the cross of king and country, was not resurrected. But in Japan, where the war was still truly a war (not a Holocaust), and the symbolism still redolent of religious exultation, such shrines as Yasukuni still carry the torch of nineteenth-century nationalism. Hence the image of the nation owing its restoration to the sacrifice of fallen soldiers.
In A Normal Country:
The mayor received a letter from a Shinto priest in which the priest pointed out that it was un-Japanese to demand any more moral responsibility from the emperor than he had already taken. Had the emperor not demonstrated his deep sorrow every year, on the anniversary of Japan s surrender? Besides, he wrote, it was wrong to have spoken about the emperor in such a manner, even as the entire nation was deeply worried about his health. Then he came to the main point: It is a common error among Christians and people with Western inclinations, including so-called intellectuals, to fail to grasp that Western societies and Japanese society are based on fundamentally different religious concepts . . . Forgetting this premise, they attempt to place a Western structure on a Japanese foundation. I think this kind of mistake explains the demand for the emperor to bear full responsibility.
In Two Normal Towns:
The bust of the man caught my attention, but not because it was in any way unusual; such busts of prominent local figures can be seen everywhere in Japan. This one, however, was particularly grandiose. Smiling across the yard, with a look of deep satisfaction over his many achievements, was Hatazawa Kyoichi. His various functions and titles were inscribed below his bust. He had been an important provincial bureaucrat, a pillar of the sumo wrestling establishment, a member of various Olympic committees, and the recipient of some of the highest honors in Japan. The song engraved on the smooth stone was composed in praise of his rich life. There was just one small gap in Hatazawa s life story as related on his monument: the years from 1941 to 1945 were missing. Yet he had not been idle then, for he was the man in charge of labor at the Hanaoka mines.
In Clearing Up the Ruins:
But the question in American minds was understandable: could one trust a nation whose official spokesmen still refused to admit that their country had been responsible for starting a war? In these Japanese evasions there was something of the petulant child, stamping its foot, shouting that it had done nothing wrong, because everybody did it.
Japan seems at times not so much a nation of twelve-year-olds, to repeat General MacArthur s phrase, as a nation of people longing to be twelve-year-olds, or even younger, to be at that golden age when everything was secure and responsibility and conformity were not yet required.
For General MacArthur was right: in 1945, the Japanese people were political children. Until then, they had been forced into a position of complete submission to a state run by authoritarian bureaucrats and military men, and to a religious cult whose high priest was also formally chief of the armed forces and supreme monarch of the empire.
I saw Jew S ss that same year, at a screening for students of the film academy in Berlin. This showing, too, was followed by a discussion. The students, mostly from western Germany, but some from the east, were in their early twenties. They were dressed in the international uniform of jeans, anoraks, and work shirts. The professor was a man in his forties, a 68er named Karsten Witte. He began the discussion by saying that he wanted the students to concentrate on the aesthetics of the film more than the story. To describe the propaganda, he said, would simply be banal: We all know the what, so let s talk about the how. I thought of my fellow students at the film school in Tokyo more than fifteen years before. How many of them knew the what of the Japanese war in Asia.

Keith Packard: auto-calendar

Automatic Calendar Management Notmuch + Calypso One of the big features of outlook/exchange in my world is automatically merging of incoming calendar updates from email. This makes my calendar actually useful in knowing what meetings people have asked me to attend. As I'm not willing to otherwise tolerate outlook, I decided to try and provide that in my preferred environment; notmuch and calypso. Identifying calendar updates The first trick is how to identify incoming messages with calendar updates. I'd love to be able to search for specific mime content types, but I haven't been able to construct such a search. Failing that, I'm just looking for messages containing the string 'text/calendar':
notmuch search --output=messages tag:inbox AND text/calendar
Next, I want to skip over previously scanned calendar updates, so I'll plan on tagging messages that have been scanned with the 'calendar' tag and skip those:
notmuch search --output=messages tag:inbox AND text/calendar AND not tag:calendar
jq sed for json With the messages containing likely calendar entries identified, the remaining task is to extract the MIME section containing the actual calendar data. Notmuch can generate json for the message, leaving us only needing to parse the json and extract the relevant section. I found the 'jq' tool in the archive, which looks like a rather complicated parsing and reformatting tool for json data. It took a while to understand, but I managed to generate a command string that takes a notmuch message and pulls out the content for all text/calendar elements:
jq -r '..  select(."content-type"? == "text/calendar")   .content'
This is a recursive walk over the data structure. It looks for structures with "content-type": "text/calendar" and dumps their "content" elements in raw text form. Putting it all together Here's the complete script:
#!/bin/bash
SEARCH="tag:inbox AND not tag:calendar AND text/calendar"
TMP= mktemp 
trap "rm -r $TMP" 0 1 15
notmuch search --output=messages $SEARCH   while read message; do
    notmuch show --format=json $message   
        jq -r '..   select(."content-type"? == "text/calendar")   .content' > $TMP
    if [ -s $TMP ]; then
        calypso --import private/calendar $TMP && notmuch tag +calendar $message
    else
        notmuch tag +calendar $message
    fi
done
I'd love to fix calypso's --import operation to talk to the local calypso daemon with the database loaded; the current mechanism actually loads the entire database into a new process and then applies the new data to that. With my calendar often containing hundreds of entries, that takes a while.

Rapha&#235;l Hertzog: Freexian s report about Debian Long Term Support, December 2015

A Debian LTS logoLike each month, here comes a report about the work of paid contributors to Debian LTS. Individual reports In December, 113.50 work hours have been dispatched among 9 paid contributors. Their reports are available: Evolution of the situation We lost our first silver sponsor (Gandi.net, they prefer to give the same amount of money to Debian directly) and another sponsor reduced his sponsorship level. While this won t show in the hours dispatched in January, we will do a small jump backwards in February (unless we get new sponsors replacing those in the next 3 weeks). This is a bit unfortunate as we are rather looking at reinforcing the amount of sponsorship we get as we approach Wheezy LTS and we will need more support to properly support virtualization related packages and other packages that were formerly excluded from Squeeze LTS. Can you convince your company and help us reach our second goal? In terms of security updates waiting to be handled, the situation is close to last month. It looks like that having about 20 packages needing an update is the normal situation and that we can t really get further down given the time required to process some updates (sometimes we wait until the upstream authors provides a patch, and so on). Thanks to our sponsors We got one new bronze sponsor but he s not listed (he did not fill the form where we request their permission to be listed).

2 comments Liked this article? Click here. My blog is Flattr-enabled.

Rhonda D'Vine: 2016 Resolutions

People these days often do think about what worked well in the last year that they are proud of, what didn't work so well and what they plan to change the coming year. For me a fair amount of the resolutions were about my name. One of them was getting rid of my old name from the Debian Project Participants page. Actually, I started with it on new year's eve already:
DatePackageVersion
Dec 31abook0.6.1-1
Jan 01tworld1.3.2-1
Jan 01blosxom2.1.2-2
Jan 02netris0.52-10
Jan 03t-prot3.4-4
Jan 04rungetty1.2-16
Jan 05tworld1.3.2-2
Jan 06tetrinet0.11+CVS20070911-2
Jan 07xblast-tnt-musics20050106-3
Jan 08xblast-tnt-sounds20040429-3
Jan 09xblast-tnt-levels20050106-3
Jan 10xblast-tnt-images20050106-3
Jan 11tetradraw2.0.3-9
Jan 12ldapvi1.7-10
So far I've done a fair amount of my job. There are eight source package left to get tweaked. Those might be a bit more difficult and require more attention though. What I also did during those efforts: Convert all packages to source format 3.0 (quilt), and use a dh style debian/rules file. The latter enabled the packages to build reproducible too, which is also an added benefit. So this is a win situation on many levels. One of the most prominent reasons why I didn't convert to a dh style debian/rules file yet was that I considered it making easy things easy and difficult things difficult. Finding out what to override and how to do that was something I was unable to figure out, and speaking with people didn't help me there neither. Only recently someone told me that there is dh binary --no-act to figure out what would be called, and then you just prefix it with override_ in debian/rules to get to where you want to go. This worked extremely well for me.
I'm personally still not a big fan of source format 3.0 (quilt) with respect to that it insists on patches to be applied and leaves them that way after building the source package, which makes it difficult to deal with when having upstream source in the VCS too, but I managed to find my way around so many things in the past that I can live with that. The benefit of not having to repack upstream source if it isn't in .gz form is a far bigger benefit. So, I hope to stay productive and be able to get the remaining package also adjusted and fixed. Guess that's doable until the end of the month, and getting rid of all reproducible build bugreports against my packages along that lines. I will check those packages that carry my name already too after my old name is gone from the overview page.

/debian permanent link Comments: 5 Flattr this

12 January 2016

Gunnar Wolf: Readying up for the second "Embedded Linux" diploma course

I am happy to share here a project I was a part of during last year, that ended up being a complete success and now stands to be repeated: The diploma course on embedded Linux, taught at Facultad de Ingenier a, UNAM, where I'm teaching my regular classes as well. Back in November, we held the graduation for our first 10 students. This photo shows only seven, as the remaining three have already relocated to Guadalajara, where they were hired by Continental, a company that promoted the creation of this specialization program. After this first excercise, we went over the program and made some adequations; future generations will have a shorter and more focused program (240 instead of 288 hours, leaving out several topics that were not deemed related to the topic or were thoroughly understood by students to begin with); we intend to start the semester-long course in early February. I will soon update here with the full program and promotional material, as soon as I receive it. update (01-19): You can download the promotional information, or go to an (unofficial) URL with the full information. We are close to starting the program, so hurry! I am specially glad that this course is taught by people I admire and recognize, and a very interesting mix between long-time academic and stemming from my free-software-related friends: From the academic side, Facultad de Ingenier a's professors Laura Sandoval, Karen S enz and Oscar Valdez, and from the free-software side, Sandino Araico, Iv n Chavero, C sar Y ez and Gabriel Salda a (and myself on both camps, of course )
AttachmentSize
OT401_nota.jpg75.82 KB
Linux Embebido - Folleto.pdf455.32 KB

11 January 2016

Norbert Preining: 10 years TeX Live in Debian

I recently dug through my history of involvement with TeX (Live), and found out that in January there are a lot of anniversaries I should celebrate: 14 years ago I started building binaries for TeX Live, 11 years ago I proposed the packaging TeX Live for Debian, 10 years ago the TeX Live packages entered Debian. There are other things to celebrate next year (2017), namely the 10 year anniversary of the (not so new anymore) infrastructure in short tlmgr of TeX Live packaging, but this will come later. In this blog post I want to concentrate on my involvement in TeX Live and Debian. TeX Live/Debian Those of you not interested in boring and melancholic look-back onto history can safely skip reading this one. For those a bit interested in the history of TeX in Debian, please read on. Debian releases and TeX systems The TeX system of choice has been for long years teTeX, curated by Thomas Esser. Digging through the Debian Archive and combining it with changelog entries as well as personal experiences since I joined Debian, here is a time line of TeX in Debian, all to my best knowledge.
Date Version Name teTeX/TeX Live Maintainers
1993-96 <1 ? ? Christoph Martin
6/1996 1.1 Buzz ?
12/1996 1.2 Rec ?
6/1997 1.3 Bo teTeX 0.4
7/1998 2.0 Ham teTeX 0.9
3/1999 2.1 Slink teTeX 0.9.9N
8/2000 2.2 Potato teTeX 1.0
7/2002 3.0 Woody teTeX 1.0
6/2005 3.1 Sarge teTeX 2.0 Atsuhito Kohda
4/2007 4.0 Etch teTeX 3.0, TeX Live 2005 Frank K ster, NP
2/2009 5.0 Lenny TeX Live 2007 NP
2/2011 6.0 Squeeze TeX Live 2009
5/2013 7.0 Whezzy TeX Live 2012
4/2015 8.0 Jessie TeX Live 2014
??? ??? Stretch TeX Live 2015
The history of TeX in Debian is thus split more or less in 10 years teTeX, and 10 years TeX Live. While I cannot check back to the origins, my guesses are that already in the very first releases (te)TeX was included. The first release I can confirm (via the Debian archive) shipping teTeX is the release Bo (June 1997). Maintainership during the first 10 years showed some fluctuation: The first years/releases (till about 2002) were dominated by Christoph Martin with Adrian Bunk and few others, who did most packaging work on teTeX version 1. After this Atsuhito Kohda with help from Hilmar Preusse and some people brought teTeX up to version 2, and from 2004 to 2007 Frank K ster, again with help of Hilmar Preusse and some other, took over most of the work on teTeX. Other names appearing throughout the changelog are (incomplete list) Julian Gilbey, Ralf Stubner, LaMont Jones, and C.M Connelly (and many more bug-reporters and fixers). Looking at the above table I have to mention the incredible amount of work that both Atsuhito Kohda and Frank K ster have put into the teTeX packages, and many of their contributions have been carried over into the TeX Live packages. While there haven t been many releases during their maintainership, their work has inspired and supported the packaging of TeX Live to a huge extend. Start of TeX Live I got involved in TeX Live back in 2002 when I started building binaries for the alpha-linux architecture. I can t remember when I first had the idea to package TeX Live for Debian, but here is a time line from my first email to the Debian Developers mailing list concerning TeX Live, to the first accepted upload:
Date Subject/Link Comment
2005-01-11 binaries for different architectures in debian packages The first question concerning packaging TeX Live, about including pre-built binaries
2005-01-25 Debian-TeXlive Proposal II A better proposal, but still including pre-built binaries
2005-05-17 Proposal for a tex-base package Proposal for tex-base, later tex-common, as basis for both teTeX and TeX live packages
2015-06-10 Bug#312897: ITP: texlive ITP bug for TeX Live
2005-09-17 Re: Take over of texinfo/info packages Taking over texinfo which was somehow orphaned started here
2005-11-28 Re: texlive-basic_2005-1_i386.changes REJECTED My answer to the rejection by ftp-master of the first upload. This email sparked a long discussion about packaging and helped improve the naming of packages (but not really the packaging itself).
2006-01-12 Upload of TeX Live 2005-1 to Debian The first successful upload
2006-01-22 Accepted texlive-base 2005-1 (source all) TeX Live packages accepted into Debian/experimental
One can see from the first emails that at that time I didn t have any idea about Debian packaging and proposed to ship the binaries built within the TeX Live system on Debian. What followed was first a long discussion about whether there is any need for just another TeX system. The then maintainer Frank K ster took a clear stance in favor of including TeX Live, and after several rounds of proposals, tests, rejections and improvements, the first successful upload of TeX Live packages to Debian/experimental happened on 12 January 2006, so exactly 10 years ago. Packaging Right from the beginning I used a meta-packaging approach. That is, instead of working directly with the source packages, I wrote (Perl) scripts that generated the source packages from a set of directives. There were several reasons why I choose to introduce this extra layer: Till now I am not 100% sure whether it was the best idea, but the scripts remain in place till now, only adapted to the new packaging paradigm in TeX Live (without xml) and adding new functionality. This allows me to just kick off one script that does do all the work, including building .orig.tar.gz, source packages, binary packages. For those interested to follow the frantic activity during the first years, there is a file CHANGES.packaging which for the years from 2005 to 2011 documents very extensively the changes I made in these years. I don t want to count the hours the went into all this  Development over the years TeX Live 2005 was just another TeX system but not the preferred one in Debian Etch and beyond. But then in May 2006, Thomas Esser announced the end of development of teTeX, which cleared the path for TeX Live as main TeX system in Debian (and the world!). The next release of Debian, Lenny (1/2009), already carried only TeX Live. Unfortunately it was only TeX Live 2007 and not 2008, mostly due to me having been involved in rewriting the upstream infrastructure based on Debian package files instead of the notorious xml files. This took quite a lot of attention and time from Debian away to upstream development, but this will be discussed in a different post. Similarly, the release of TeX Live included in Debian Squeeze (released 2/2011) was only TeX Live 2009 (instead of 2010), but since then (Wheezy and Jessie) the releases of TeX Live in Debian were always the latest released ones. Current status Since about 2013 I am trying to keep a regular schedule of new TeX Live packages every month. These helps me to keep up with the changes in upstream packaging and reduces the load of packaging a new release of TeX Live. It also bring to users of unstable and testing a very up-to-date TeX system, where packages at most lack 1 month of behind the TeX Live net updates. Future As most of the readers here know, besides caring for TeX (Live) and related packages in Debian, I am also responsible for the TeX Live Manager (tlmgr) and most of upstream s infrastructure including network distribution. Thus, my (spare, outside work) time needs to be distributed between all these projects (and some others) which leaves less and less time for Debian packaging. Fortunately the packaging is in a state that making regular updates once a month is less of a burden, since most steps are automatized. What is still a bit of a struggle is adapting the binary package (src:texlive-bin) to new releases. But also this has become simpler due to less invasive changes over the years. All in all, I don t have many plans for TeX Live in Debian besides keeping the current system running as it is. Search for and advise to future maintainers and collaborators I would be more than happy if new collaborators appear, with fresh ideas and some spare time. Unfortunately, my experience over these 10 years with people showing up and proposing changes (anyone remembers the guy proposing a complete rewrite in ML or so?) is that nobody really wants to invest time and energy, but search for quick solutions. This is not something that will work with a package like TeX Live, sized of several gigabyte (the biggest in the Debian archive), and complicated inner workings. I advise everyone being interested in helping to package TeX Live for Debian, to first install normal TeX Live from TUG, get used to what actions happen during updates (format rebuilds, hyphenation patters, map file updates). One does not need to have a perfect understanding of what exactly happens down there in the guts (I didn t have in the beginning, either), but if you want to help packaging and never heard about what format dumps or map files are, then this might be a slight obstacle. Conclusion TeX Live is the only TeX system in wide use across lots of architectures and operating systems, and the only comparable system, MikTeX, is Windows specific (also there are traces of ports to Unix). Backed by all the big user groups of TeX, TeX Live will remain the prime choice for the foreseeable future, and thus also TeX Live in Debian.

Vincent Fourmond: Ghost in the machine: faint remanence of screen contents across reboots in a Macbook pro retina

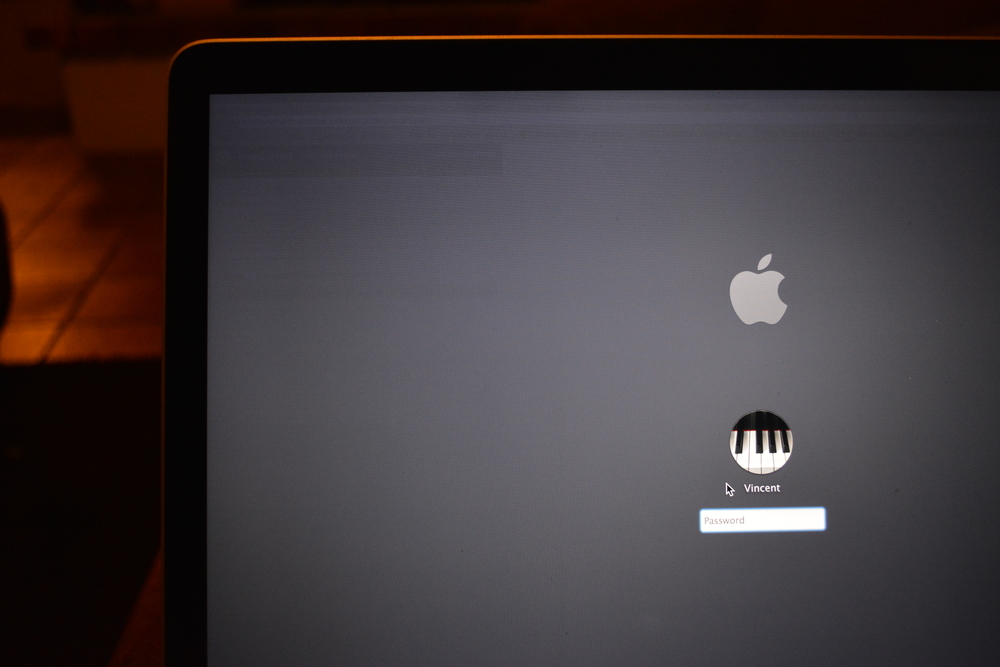
As was noted a few times before, I happen to own a Macbook Pro Retina laptop I mostly use under Linux. I had noticed from time to time weird mixes between two screens, i.e. I would be looking at a website, but, in some areas with uniform colors, I would see faint traces of other windows currently opened on another screen. These faint traces would not show up in a screenshot. It never really bothered me, and I attributed that to a weird specificity of the mac hardware (they often do that) that was not well handled by the nouveau driver, so I had simply dismissed that. Until, one day, I switch off the computer, switch back on, boot to MacOS and see this as a boot screen:
Here is a close-up view of the top-left corner of the screen:
If you look carefully, you can still see the contents of the page I was browsing just before switching off the computer ! So this problem is not Linux-specific, it also affects MacOS... To be honest, I don't have a clue about what's happening here, but it has to be a serious hardware malfunction. How can two video memory regions be composed upon display without the computer asking explicitly for it ? Why does that problem survives a reboot ? I mean, someone switches on my computer and can see the last thing I did on it ? I could actually read the address line without difficulty, although you'll have to take my word for it, since the picture does not show it that well. That's scary...

10 January 2016

Juliana Louback: NLP: Viterbi Named-Entity Tagger

During my MSc program, I was lucky to squeeze into Michael Collin s NLP class. We used his Coursera course as part of the program, which I d highly recommend. Recently I decided to review my NLP studies and I believe the best way to learn or relearn a subject is to teach it. This is one in a series of 4 posts with a walk-through of the algorithms we implemented during the course. I ll provide links to my code hosted on Github. Disclaimer: Before taking this NLP course, the only thing I knew about Python was that it s the one without curly brackets . I learned Python on the go while implementing these algorithms. So if I did anything against Python code conventions or flat-out heinous, I apologize and thank you in advance for your understanding. Feel free to write and let me know.

The Concept To quote Wikipedia, Named-entity recognition (I ve always known it as tagging) is a subtask of information extraction that seeks to locate and classify elements in text into predefined categories such as the names of persons, organizations, locations, expressions of times, quanitites, monetary values, percentages, etc. For example, the algorithm receives as input some text Bill Gates founded Microsoft in 1975. and outputs Bill Gates[person] founded Microsoft[organization] in 1975[date]. Off the top of my head, some useful applications are document matching (ex. a document containing Gates[person] may not be on the same topic as one containing gates[object]) and query searches. I m sure there are lots more, if you check out Collin s Coursera course he may discuss this in greater depth.

The Requirements Development data: The file ner_dev.dat provided by prof. Michael Collins has a series of sentences separated by an empty line, one word per line. Training data: The file ner_train.dat provided by prof. Michael Collins has a series of sentences separated by an empty line, one word and tag per line, speparated by a space. Word-tag count data: The file ner.counts has the format [count] [type of tag] [label] [word]. The tags used are RARE, O, I-MISC, I-PER, I-ORG, I-LOC, B-MISC, B-PER, B-ORG, B-LOC. The tag O means it s not an NE. This file is generated by count_freqs.py, a script provided by prof. Michael Collins. Run count_freqs.py on the training data ner_train.dat

The Algorithm Python code: viterbi.py Usage: python viterbi.py ner.counts ngram.counts [input_file] > [output_file] Summary: The Viterbi algorithm finds the maximum probability path for a series of observations, based on emission and transition probabilities. In a Markov Process, emission is the probability of an output given a state and transition is the probability of transitioning to the state given the previous states. In our case, the emission parameter e(x y) = the probability of the word being x given you attributed tag y. If your training data had 100 counts of person tags, one of which is the word London (I know a guy who named his kid London), e( London person ) = 0.01. Now with 50 counts of location tags, 5 of which are London , e( London location ) = 0.1 which clearly trumps 0.01. The transition parameter q(yi yi-1, yi-2) = the probability of putting tag y in position i given it s two previous tags. This is calculated by Count(trigram)/Count(bigram). For each word in the development data, he Viterbi algorithm will associate a score for a word-tag combo based on the emission and transition parameters it obtained from the training data. It does this for every possible tag and sees which is more likely. Clearly this won t be 100% correct as natural language is unpredictable, but you should get pretty high accuracy. Optional Preprocessing Re-label words in training data with frequency < 5 as RARE - This isn t required, but useful. Re-run count_freqs.py if used. Python code: label_rare.py Usage: python label_rare.py [input_file] Pseudocode:
  1. Uses Python Counter to obtain word counts in [input_file]; removes all word-count pairs with count < 5, store remaining pairs in a dictionary named rare_words.
  2. Iterates through each line in [input file], checks if word is in rare words dictionary, if so, replaces word with RARE.
Step 1. Get Count(y) and Count(x~y) Python code: emission_counts.py Pseudocode:
  1. Iterate through each line in ner.counts file and store each word-label-count combo in a dictionary count_xy and update the dictionary of count_y. For example count_xy[Peter][I-PER] returns the number of times the word Peter was labeled I-PER in the training data and count_y[I-PER] the total number of I-PER tags. The dictionary count_y contains 8 items, one for each label ( RARE , O, I-MISC, I-PER, I-ORG, I-LOC, B-MISC, B-PER, B-ORG, B-LOC);
  2. Return count_xy, count_y
Step 2. Get bigram and trigram counts Python code: transition_counts.py Pseudocode:
  1. Iterate through each line in the n-gram_counts file
  2. If the line contains 2-GRAM add an item to the bigram_counts dictionary using the bigram (two space-separated labels following the tag type 2-gram ) as key, count as value. This dictionary will contain Count(yi-2,yi-1).
  3. If the line contains 3-GRAM , add an item to the trigram_counts dictionary using the trigram as key, count as value. This dictionary will contain Count(yi-2, yi-1, yi).
  4. Return dictionaries of bigram and trigram counts.
Step 3. Viterbi (For each line in the [input_file]):
  1. If the word was seen in training data (present in the count_xy dictionary), for each of the possible labels for the word:
  2. Calculate emission = count_xy[word][label] / float(count_y[label]
  3. Calculate transition = trigram_counts[trigram])/float(bigram_counts[bigram] Note: yi-2 = *, yi-1 = * for the first round
  4. Set probability = emission x transition
  5. Update max(probability) and arg max if needed. 2 If the word was not seen in the training data:
  6. Calculate emission = count xy[RARE][label] / float(count y[label].
  7. Calculate q(yi yi-1, yi-2) = trigram counts[trigram])/float(bigram counts[bigram]. Note: yi-2 = , yi-1 = for the first round
  8. Set probability = emission transition
  9. Update max(probability) if needed, arg max = RARE
  10. Write arg max and log(max(probability)) to output file.
  11. Update yi-2, yi-1.
  12. Update yi-2, yi-1.
Evaluation Prof. Michael Collins provided an evaluation script eval_ne_tagger.py to verify the output of your Viterbi implementation. Usage: python eval_ne_tagger.py ner_dev.key [output_file]

Scott Kitterman: Debian LTS Work December 2015

This was my eighth month as a Freexian sponsored LTS contributor. I was assigned 8 hours for the month of December. It s also the month in which I (re)learned an important lesson.

I decided to take another run at backporting the security fixes for Quassel. Unlike the first time, I was successful at getting the fixes backported. Then I ran into another problem: the changes took advantage of new features in c++11 such as std::function. I made an attempt to change things away from c++11 with my limited c++ foo and after running head first into a brick wall several times finally consulted with the upstream author of the original fixes. He let me know that while the problematic code is in fact present in the quassel versions in squeeze and wheezy, it s not actually possible to trigger the security issue and that the CVEs should not actually apply to those versions. That s my report of a singularly unproductive and unpleasant 8 hours. Next time I ask upstream first if there s any doubt. I shouldn t assume they only care about current/recent releases.

Next.

Previous.