Search Results: "cas"

22 August 2016

Satyam Zode: Google Summer of Code 2016 : Final Report

Project Title : Improving diffoscope tool and reproducibility of Debian packages Project details This project aims to improve diffoscope tool and fix Debian packages which are unreproducible in Reproducible builds testing framework. diffoscope recursively unpack archives of many kinds and transform various binary formats into more human readable form to compare them. As a part of this project I worked on argument completion feature and ignoring .buildinfo feature. This project is a part of Reproducible Builds effort Mentor and Co-Mentor Project Discussion Project Implementation Challenges and Work Left Future work Acknowledgement I would like to express my deepest gratitude to Lunar for mentoring me throughout Google Summer of Code program and for being cool. Lunar s deep knowledge regarding diffoscope and Python skills helped me a lot throughout the project and we literally had great discussions. I would also like to thank Debaian community and Google for giving me this opportunity. Special thanks to Reproducible Builds folks for all the guidance!

Vincent Sanders: Down the rabbit hole

My descent began with a user reporting a bug and I fear I am still on my way down.

Like Alice I headed down the hole. https://commons.wikimedia.org/wiki/File:Rabbit_burrow_entrance.jpg
The bug was simple enough, a windows bitmap file caused NetSurf to crash. Pretty quickly this was tracked down to the libnsbmp library attempting to decode the file. As to why we have a heavily used library for bitmaps? I am afraid they are part of every icon file and many websites still have favicons using that format.

Some time with a hex editor and the file format specification soon showed that the image in question was malformed and had a bad offset header entry. So I was faced with two issues, firstly that the decoder crashed when presented with badly encoded data and secondly that it failed to deal with incorrect header data.

This is typical of bug reports from real users, the obvious issues have already been encountered by the developers and unit tests formed to prevent them, what remains is harder to produce. After a debugging session with Valgrind and electric fence I discovered the crash was actually caused by running off the front of an allocated block due to an incorrect bounds check. Fixing the bounds check was simple enough as was working round the bad header value and after adding a unit test for the issue I almost moved on.

Almost...

american fuzzy lop are almost as cute as cats https://commons.wikimedia.org/wiki/File:Rabbit_american_fuzzy_lop_buck_white.jpg
We already used the bitmap test suite of images to check the library decode which was giving us a good 75% or so line coverage (I long ago added coverage testing to our CI system) but I wondered if there was a test set that might increase the coverage and perhaps exercise some more of the bounds checking code. A bit of searching turned up the american fuzzy lop (AFL) projects synthetic corpora of bmp and ico images.

After checking with the AFL authors that the images were usable in our project I added them to our test corpus and discovered a whole heap of trouble. After fixing more bounds checks and signed issues I finally had a library I was pretty sure was solid with over 85% test coverage.

Then I had the idea of actually running AFL on the library. I had been avoiding this because my previous experimentation with other fuzzing utilities had been utter frustration and very poor return on investment of time. Following the quick start guide looked straightforward enough so I thought I would spend a short amount of time and maybe I would learn a useful tool.

I downloaded the AFL source and built it with a simple make which was an encouraging start. The library was compiled in debug mode with AFL instrumentation simply by changing the compiler and linker environment variables.

$ LD=afl-gcc CC=afl-gcc AFL_HARDEN=1 make VARIANT=debug test
afl-cc 2.32b by <lcamtuf@google.com>
COMPILE: src/libnsbmp.c
afl-cc 2.32b by <lcamtuf@google.com>
afl-as 2.32b by <lcamtuf@google.com>
[+] Instrumented 751 locations (64-bit, hardened mode, ratio 100%).
AR: build-x86_64-linux-gnu-x86_64-linux-gnu-debug-lib-static/libnsbmp.a
COMPILE: test/decode_bmp.c
afl-cc 2.32b by <lcamtuf@google.com>
afl-as 2.32b by <lcamtuf@google.com>
[+] Instrumented 52 locations (64-bit, hardened mode, ratio 100%).
LINK: build-x86_64-linux-gnu-x86_64-linux-gnu-debug-lib-static/test_decode_bmp
afl-cc 2.32b by <lcamtuf@google.com>
COMPILE: test/decode_ico.c
afl-cc 2.32b by <lcamtuf@google.com>
afl-as 2.32b by <lcamtuf@google.com>
[+] Instrumented 65 locations (64-bit, hardened mode, ratio 100%).
LINK: build-x86_64-linux-gnu-x86_64-linux-gnu-debug-lib-static/test_decode_ico
afl-cc 2.32b by <lcamtuf@google.com>
Test bitmap decode
Tests:606 Pass:606 Error:0
Test icon decode
Tests:392 Pass:392 Error:0
TEST: Testing complete

I stuffed the AFL build directory on the end of my PATH, created a directory for the output and ran afl-fuzz

afl-fuzz -i test/bmp -o findings_dir -- ./build-x86_64-linux-gnu-x86_64-linux-gnu-debug-lib-static/test_decode_bmp @@ /dev/null

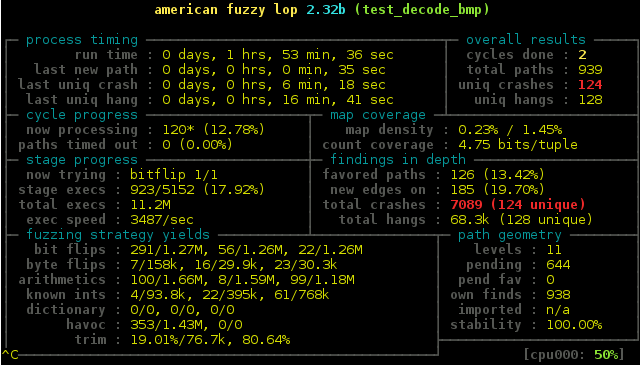
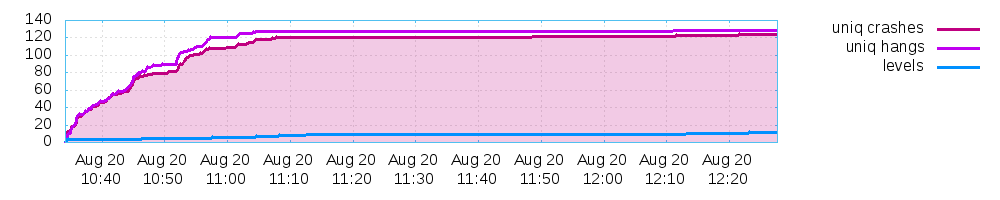
The result was immediate and not a little worrying, within seconds there were crashes and lots of them! Over the next couple of hours I watched as the unique crash total climbed into the triple digits.

I was forced to abort the run at this point as, despite clear warnings in the AFL documentation of the demands of the tool, my laptop was clearly not cut out to do this kind of work and had become distressingly hot.

AFL has a visualisation tool so you can see what kind of progress it is making which produced a graph that showed just how fast it managed to produce crashes and how much the return plateaus after just a few cycles. Although it was finding a new unique crash every ten minutes or so when aborted.

I dove in to analyse the crashes and it immediately became obvious the main issue was caused when the test tool attempted allocations of absurdly large bitmaps. The browser itself uses a heuristic to determine the maximum image size based on used memory and several other values. I simply applied an upper bound of 48 megabytes per decoded image which fits easily within the fuzzers default heap limit of 50 megabytes.

The main source of "hangs" also came from large allocations so once the test was fixed afl-fuzz was re-run with a timeout parameter set to 100ms. This time after several minutes no crashes and only a single hang were found which came as a great relief, at which point my laptop had a hard shutdown due to thermal event!

Once the laptop cooled down I spooled up a more appropriate system to perform this kind of work a 24way 2.1GHz Xeon system. A Debian Jessie guest vm with 20 processors and 20 gigabytes of memory was created and the build replicated and instrumented.

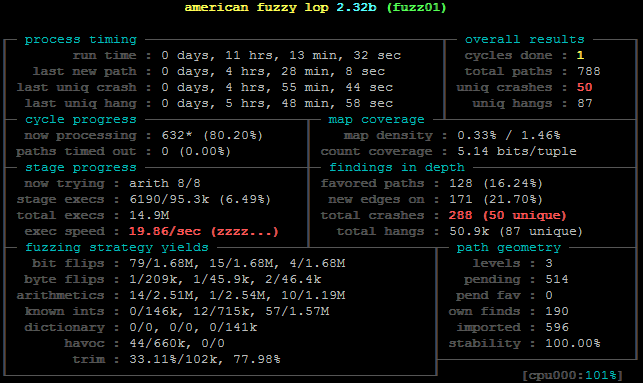
AFL master node display
To fully utilise this system the next test run would utilise AFL in parallel mode. In this mode there is a single "master" running all the deterministic checks and many "secondary" instances performing random tweaks.

If I have one tiny annoyance with AFL, it is that breeding and feeding a herd of rabbits by hand is annoying and something I would like to see a convenience utility for.

The warren was left overnight with 19 instances and by morning had generated crashes again. This time though the crashes actually appeared to be real failures.

$ afl-whatsup sync_dir/
Summary stats
=============

Fuzzers alive : 19
Total run time : 5 days, 12 hours
Total execs : 214 million
Cumulative speed : 8317 execs/sec
Pending paths : 0 faves, 542 total
Pending per fuzzer : 0 faves, 28 total (on average)
Crashes found : 554 locally unique

All the crashing test cases are available and a simple file command immediately showed that all the crashing test files had one thing in common the height of the image was -2147483648 This seemingly odd number is actually meaningful to a programmer, it is the largest negative number which can be stored in a 32bit integer (INT32_MIN) I immediately examined the source code that processes the height in the image header.

if ((width <= 0)   (height == 0))          
return BMP_DATA_ERROR;
if (height < 0)
bmp->reversed = true;
height = -height;

The bug is where the height is made a positive number and results in height being set to 0 after the existing check for zero and results in a crash later in execution. A simple fix was applied and test case added removing the crash and any possible future failure due to this.

Another AFL run has been started and after a few hours has yet to find a crash or non false positive hang so it looks like if there are any more crashes to find they are much harder to uncover.

Main lessons learned are:
I will of course be debugging any new crashes that occur and perhaps turning my sights to all the projects other unit tested libraries. I will also be investigating the generation of our own custom test corpus from AFL to replace the demo set, this will hopefully increase our unit test coverage even further.

Overall this has been my first successful use of a fuzzing tool and a very positive experience. I would wholeheartedly recommend using AFL to find errors and perhaps even integrate as part of a CI system.

Michal &#268;iha&#345;: Continuous integration on multiple platforms

Over the weekend I've played with continuous integration for Gammu to make it run on more platforms. I had to remember many things from the Windows world on the way and the solution is not yet complete, but the basic build is working, the only problematic part are external dependencies. First of all we already have Linux builds on Travis CI. These cover compilation with both GCC and Clang compilers, hopefully covering most of the possible problems. Recently I've added OS X builds on Travis CI, what was pretty much painless and worked out of the box. The next major architecture to support is Windows. Once I've discovered AppVeyor I thought it might be the way to go. The have free plans for open-source projects (though it has only one parallel build compared to four provided by Travis CI). As our build system is cross platform based on CMake, it should work pretty much out of the box, right? Well almost, tweaking the basics took some time (unfortunately there is no CMake support on AppVeyor, so you have to script it a bit). The most painful things on the way: You can check our current appveyor.yml in case you're going to try something similar. Current build results are on AppVeyor. As a nice side effect, we now have up to date Windows binaries for Gammu.

Filed under: Debian English Gammu 0 comments

Zlatan Todori : When you wake up with a feeling

I woke up at 5am. Somehow made myself to soon go back to sleep again. Woke up at 6am. Such is the life of jet-lag. Or I am just getting old for it. But the truth wouldn't be complete with only those assertion. I woke inspired and tired and the same time. Tired because I am doing very time consumable things. Also in the same time very emotional things. AND at the exact same time things that inspire me. On paper, I am technical leader of Purism. In reality, I have insanely good relations with my CEO for such a short time. So good that I for months were not leading the technical shift only, but also I overtook operations (getting orders and delivering them while working with our assembly line to automate most of the tasks in this field). I was playing also as first line of technical support (forums, IRC and email). Actually I was pretty much the only line of support for few months. I was doing some website changes: change some wording, updating bunch of plugins and making it sure all works, resolved (hopefully) Tor and Cloudflare issues for it, annoying caching system for forums, stopped forum spam and so on. I worked on better messaging for Purism public relations. I thought my team to use keys for signing and encryption. I interviewed (and read all mails) for people that were interested in working or helping Purism. In process of doing all that, I maybe wasn't the most speedy person for all our users needs but I hope they understand and forgive me. I was doing all that while I was researching and developing tablets (which ended up not being the most successful campaign but we now do have them as product). I was doing all that while seeing (and resolving) that our kernel builds were failing. Worked on pushing touchpad (not so good but we are still working on) patches upstream (and they ended being upstreamed). While seeing repos being down because of our host. Repos being down because of broken sync with Debian. Repos being down because of our key mis-management. Metadata not working well. PureBrowser getting broken all the time. Tor browser out of date. No real ISO updates. Wrong sources.list entries and so on. And the hardest part on work was, I was doing all this with very limited scope and even more limited resources. So what kept me on, what is pushing me forward and what am I doing? One philosophy - Free software. Let me not explain it as a technical debt. Let me explain it as social movement. In age, where people are "bombed" by media, by all-time lying politicians (which use fear of non-existent threats/terror as model to control population), in age where proprietary corporations are selling your freedom so you can gain temporary convenience the term Free software is like Giordano Bruno in age of Inquisitions. Free software does not only preserve your Freedom to software source usage but it preserves your Freedom to think and think out of the box and not being punished for that. It preserves the Freedom to live - to choose what and when to do, without having the negative impact on your or others people lives. The Freedom to be transparent and to share. Because not only ideas grow with sharing, but we, as human beings, grow as we share. The Freedom to say "NO". NO. I somehow learnt, and personally think, that the Freedom to say NO is the most important Freedom in our lives. No I will not obey some artificially created master that think they can plan and choose my life decision. No I will not negotiate my Freedom for your convenience (also, such Freedom is anyway not real and it is matter of time where you will be blown away by such illusion). No I will not accept your credit because it has STRINGS attached to it which you either don't present or you blur it in mountain of superficial wording. No I will not implant a chip inside me for sake of your research or my convenience. No I will not have social account on media where majority of people are. No, I will not have pacemaker which is a blackbox with proprietary (buggy) software and it harvesting my data without me being able to look at it. Yin-Yang. Yes, I want to collaborate on making world better place for us all. I don't agree with most of people, but that doesn't make them my enemies (although media would like us to feel and think like that). I will try to preserve everyones Freedom as much as I can. Yes I will share with my community and friends. Yes I want to learn from better than I am. Yes I want to have awesome mentors. Yes, I will try to be awesome mentor. Yes, I choose to care and not ignore facts and actions done by me and other people. Yes, I have the right to be imperfect and do mistakes as long as I will aknowledge and work on them. Bugfixing ourselves as humans is the most important task in our lives. As in software, it is very time consumable but also as in software, it is improvement and incredible satisfaction to see better version of yourself, getting more and more features (even if that sometimes means actually getting read of other/bad features). This all is blending with my work at Purism. I spend a lot of time thinking about projects, development and future. I must do that in order not to make grave mistakes. Failing hardware and software is not grave mistake. Serious, but not grave. Grave is if we betray ourselves and our community in pursue for Freedom. We are trying to unify many things - we want to give you security, privacy and FREEDOM with convenience. So I am pushing myself out of comfort zones and also out of conventional and sometimes even my standard way of thinking. I have seen that non-existing infrastructure for PureOS is hurting is a lot but I needed to cope with it to the time where I will be able to say: not anymore, we are starting to build our own infrastructure. I was coping with Cloudflare being assholes to Tor users but now we also shifting away from them. I came to team where people didn't properly understand what and why are we building this. Came to very small and not that efficient team. Now, we employed a dedicated and hard working person on operations (Goran) which I trust. We have dedicated support person (Mladen) which tries hard to work with people. A very creative visual mastermind (Francois). We have a capable Debian Developer (Matthias Klumpp) working on PureOS new infra. We have a capable and dedicated sysadmins (Theo and Stelio) which we didn't even have in past. We are trying to LEVEL UP Free software and unify them in convenient solution which is lead by Joey Hess. We have a hard-working PureOS developer (Hema) who is coping with current non-existent PureOS infra. We have GNOME Boards of Directors person (Jeff) who is trying to light up our image in world (working with James, to try bring some lights into our shadows caused by infinite supply chain delays). We have created Advisory Board for Freedom, Privacy and Security which I don't want to name now as we are preparing to announce soon that (and trust me, we have good people in here). But, the most important thing here is not that they are all capable or cool people. It is the core value in all of them - they care about Freedom and I trust them on their paths. The trust is always important but in Purism it is essential for our work. I built the workflow without time management (everyone spends their time every single day as they see it fit as long as the work gets done). And we don't create insane short deadlines because everyone else thinks it is important (and rarely something is more important than our time freedom). So the trust is built out of knowledge and the knowledge I have about them and their works is because we freely share with no strings attached. Because of them, and other good people from our community I have the energy to sacrifice my entire time for Purism. It is not white and black: CEO and me don't always agree, some members of my team don't always agree with me or I with them, some people in community are very rude, impolite and don't respect our work but even with disagreement everyone in Purism finds agreement at the end (we use facts in our judgments) and all the people who just try to disturb my and mine teams work aren't as efficient as all the lovely words of people who believe in us, who send us words of support and who share ideas and their thoughts with us. There is no more satisfaction for me than reading a personal mail giving us kudos for the work and their understanding of underlaying amount of work and issues. While we are limited with resources we had an occasional outcry from community to help us. Now I want to help them to help me (you see the Freedom of sharing here?). PureOS has now a wiki. It will be a community wiki which is endorsed by Purism as company. Yes you read it right, Purism considers its community part of company (you don't need to get paycheck to be Purism member). That is why a call upon contributors (technical but mostly non-technical too) to help us make PureOS wiki the best resource on net for our needs. Write tutorials for others, gather and put info on wiki, create an ideas page and vote on them so we can see what community wants to see, chat with us so we all understand what, why and how are we working on things. Make it as transparent as possible. Everyone interested please get in touch with our teams by either poking us online (IRC, social accounts) or via emails (our personal or [hr, pr, feedback]@puri.sm. To finish this writing (as it is 8am here and I still want to rest a bit because I will have meetings for 6 hours straight today) - I wanted to share some personal insight into few things from my point of view. I wanted to say despite all the troubles and people who tried to make our time even harder (and it is already hard by all the limitation which come naturally today with our kind of work), we still create products, we still ship them, we still improved step by step, we still hired and we are still building. Keeping all that together and making progress is for me a milestone greater than just creating a technical product. I just hope we will continue and improve our pace so we can start progressing towards my personal great goal - integrate and cooperate with most of FLOSS ecosystem. P.S. yes, I also (finally!) became an official Debian Developer - still didn't have time to sit and properly think and cry (as every good men) about it.

21 August 2016

Cyril Brulebois: Freelance Debian consultant: running DEBAMAX

Executive summary Since October 2015, I've been running a FLOSS consulting company, specialized on Debian, called DEBAMAX. DEBAMAX logo Longer version Everything started two years ago. Back then I blogged about one of the biggest changes in my life: trying to find the right balance between volunteer work as a Debian Developer, and entrepreneurship as a Freelance Debian consultant. Big change because it meant giving up the comfort of the salaried world, and figuring out whether working this way would be sufficient to earn a living I experimented for a while under a simplified status. It comes with a number of limitations but that s a huge win compared to France s heavy company-related administrativia. Here s what it looked like, everything being done online: A number of things became quite clear after a few months: Thankfully I was eligible to being accompanied by the local Chamber of Commerce and Industry (CCI Rennes), which provides teaching sessions for new entrepreneurs, coaching, and meeting opportunities (accountants, lawyers, insurance companies, ). Summer in France is traditionally rather quiet (read: almost everybody is on vacation), so DEBAMAX officially started operating in October 2015. Besides different administrative and accounting duties, running this company doesn't change the way I've been working since July 2014, so everything is fine! As before, I won't be writing much about it through my personal blog, except for an occasional update every other year; if you want to follow what's happening with DEBAMAX:
David Moreno: WIP: Perl bindings for Facebook Messenger

A couple of weeks ago I started looking into wrapping the Facebook Messenger API into Perl. Since all the calls are extremely simple using a REST API, I thought it could be easier and simpler even, to provide a small framework to hook bots using PSGI/Plack. So I started putting some things together and with a very simple interface you could do a lot:
use strict;
use warnings;
use Facebook::Messenger::Bot;
my $bot = Facebook::Messenger::Bot->new( 
    access_token   => '...',
    app_secret     => '...',
    verify_token   => '...'
 );
$bot->register_hook_for('message', sub  
    my $bot = shift;
    my $message = shift;
    my $res = $bot->deliver( 
        recipient => $message->sender,
        message =>   text => "You said: " . $message->text()  
     );
    ...
 );
$bot->spin();
You can hook a script like that as a .psgi file and plug it in to whatever you want. Once you have some more decent user flow and whatnot, you can build something like:


using a simple script like this one. The work is not finished and not yet CPAN-ready but I m posting this in case someone wants to join me in this mini-project or have suggestions, the work in progress is here. Thanks!

20 August 2016

Daniel Stender: Collected notes from Python packaging

Here are some collected notes on some particular problems from packaging Python stuff for Debian, and more are coming up like this in the future. Some of the issues discussed here might be rather simple and even benign for the experienced packager, but maybe this is be helpful for people coming across the same issues for the first time, wondering what's going wrong. But some of the things discussed aren't easy. Here are the notes for this posting, there is no particular order. UnicodeDecoreError on open() in Python 3 running in non-UTF-8 environments I've came across this problem again recently packaging httpbin 0.5.0. The build breaks the following way e.g. trying to build with sbuild in a chroot, that's the first run of setup.py with the default Python 3 interpreter:
I: pybuild base:184: python3.5 setup.py clean 
Traceback (most recent call last):
  File "setup.py", line 5, in <module>
    os.path.join(os.path.dirname(__file__), 'README.rst')).read()
  File "/usr/lib/python3.5/encodings/ascii.py", line 26, in decode
    return codecs.ascii_decode(input, self.errors)[0]
UnicodeDecodeError: 'ascii' codec can't decode byte 0xe2 in position 2386: ordinal not in range(128)
E: pybuild pybuild:274: clean: plugin distutils failed with: exit code=1: python3.5 setup.py clean 
One comes across UnicodeDecodeError-s quite oftenly on different occasions, mostly related to Python 2 packaging (like here). Here it's the case that in setup.py the long_description is tried to be read from the opened UTF-8 encoded file README.rst:
long_description = open(
    os.path.join(os.path.dirname(__file__), 'README.rst')).read()
This is a problem for Python 3.5 (and other Python 3 versions) when setup.py is executed by an interpreter run in a non-UTF-8 environment1:
$ LANG=C.UTF-8 python3.5 setup.py clean
running clean
$ LANG=C python3.5 setup.py clean
Traceback (most recent call last):
  File "setup.py", line 5, in <module>
    os.path.join(os.path.dirname(__file__), 'README.rst')).read()
  File "/usr/lib/python3.5/encodings/ascii.py", line 26, in decode
    return codecs.ascii_decode(input, self.errors)[0]
UnicodeDecodeError: 'ascii' codec can't decode byte 0xe2 in position 2386: ordinal not in range(128)
$ LANG=C python2.7 setup.py clean
running clean
The reason for this error is, the default encoding for file object returned by open() e.g. in Python 3.5 is platform dependent, so that read() fails on that when there's a mismatch:
>>> readme = open('README.rst')
>>> readme
<_io.TextIOWrapper name='README.rst' mode='r' encoding='ANSI_X3.4-1968'>
Non-UTF-8 build environments because $LANG isn't particularly set at all or set to C are common or even default in Debian packaging, like in the continuous integration resp. test building for reproducible builds the primary environment features that (see here). That's also true for the base system of the sbuild environment:
$ schroot -d / -c unstable-amd64-sbuild -u root
(unstable-amd64-sbuild)root@varuna:/# locale
LANG=
LANGUAGE=
LC_CTYPE="POSIX"
LC_NUMERIC="POSIX"
LC_TIME="POSIX"
LC_COLLATE="POSIX"
LC_MONETARY="POSIX"
LC_MESSAGES="POSIX"
LC_PAPER="POSIX"
LC_NAME="POSIX"
LC_ADDRESS="POSIX"
LC_TELEPHONE="POSIX"
LC_MEASUREMENT="POSIX"
LC_IDENTIFICATION="POSIX"
LC_ALL=
A problem like this is solved mostly elegant by installing some workaround in debian/rules. A quick and easy fix is to add export LC_ALL=C.UTF-8 here, which supersedes the locale settings of the build environment. $LC_ALL is commonly used to change the existing locale settings, it overrides all other locale variables with the same value (see here). C.UTF-8 is an UTF-8 locale which is available by default in a base system, it could be used without installing the locales package (or worse, the huge locales-all package):
(unstable-amd64-sbuild)root@varuna:/# locale -a
C
C.UTF-8
POSIX
This problem ideally should be taken care of upstream. In Python 3, the default open() is io.open(), for which the specific encoding could be given, so that the UnicodeDecodeError disappears. Python 2 uses os.open() for open(), which doesn't support that, but has io.open(), too. A fix which works for both Python branches goes like this:
import io
long_description = io.open(
    os.path.join(os.path.dirname(__file__), 'README.rst'), encoding='utf-8').read()
non-deterministic order of requirements in egg-info/requires.txt This problem appeared in prospector/0.11.7-5 in the reproducible builds test builds, that was the first package of Prospector running on Python 32. It was revealed that there were differences in the sorting order of the [with_everything] dependencies resp. requirements in prospector-0.11.7.egg-info/requires.txt if the package was build on varying systems:
$ debbindiff b1/prospector_0.11.7-5_amd64.changes b2/prospector_0.11.7-5_amd64.changes 
 ... 
  prospector_0.11.7-5_all.deb
      file list
      @@ -1,3 +1,3 @@
       -rw-r--r--   0        0        0        4 2016-04-01 20:01:56.000000 debian-binary
      --rw-r--r--   0        0        0     4343 2016-04-01 20:01:56.000000 control.tar.gz
      +-rw-r--r--   0        0        0     4344 2016-04-01 20:01:56.000000 control.tar.gz
       -rw-r--r--   0        0        0    74512 2016-04-01 20:01:56.000000 data.tar.xz
      control.tar.gz
          control.tar
              ./md5sums
                  md5sums
                  Files in package differ
      data.tar.xz
          data.tar
              ./usr/share/prospector/prospector-0.11.7.egg-info/requires.txt
              @@ -1,12 +1,12 @@
               
               [with_everything]
              +pyroma>=1.6,<2.0
               frosted>=1.4.1
               vulture>=0.6
              -pyroma>=1.6,<2.0
Reproducible builds folks recognized this to be a toolchain problem and set up the issue randonmness_in_python_setuptools_requires.txt to cover this. Plus, a wishlist bug against python-setuptools was filed to fix this. The patch which was provided by Chris Lamb adds sorting of dependencies in requires.txt for Setuptools by adding sorted() (stdlib) to _write_requirements() in command/egg_info.py:
--- a/setuptools/command/egg_info.py
+++ b/setuptools/command/egg_info.py
@@ -406,7 +406,7 @@ def warn_depends_obsolete(cmd, basename, filename):
 def _write_requirements(stream, reqs):
     lines = yield_lines(reqs or ())
     append_cr = lambda line: line + '\n'
-    lines = map(append_cr, lines)
+    lines = map(append_cr, sorted(lines))
     stream.writelines(lines)
O.k. In the toolchain, nothing sorts these requirements alphanumerically to make differences disappear, but what is the reason for these differences in the Prospector packages, though? The problem is somewhat subtle. In setup.py, [with_everything] is a dictionary entry of _OPTIONAL (which is used for extras_require) that is created by a list comprehension out of the other values in that dictionary. The code goes like this:
_OPTIONAL =  
    'with_frosted': ('frosted>=1.4.1',),
    'with_vulture': ('vulture>=0.6',),
    'with_pyroma': ('pyroma>=1.6,<2.0',),
    'with_pep257': (),  # note: this is no longer optional, so this option will be removed in a future release
 
_OPTIONAL['with_everything'] = [req for req_list in _OPTIONAL.values() for req in req_list]
The result, the new _OPTIONAL dictionary including the key with_everything (which w/o further sorting is the source of the list of requirements requires.txt) e.g. looks like this (code snipped run through in my IPython):
In [3]: _OPTIONAL
Out[3]: 
 'with_everything': ['vulture>=0.6', 'pyroma>=1.6,<2.0', 'frosted>=1.4.1'],
 'with_vulture': ('vulture>=0.6',),
 'with_pyroma': ('pyroma>=1.6,<2.0',),
 'with_frosted': ('frosted>=1.4.1',),
 'with_pep257': () 
That list comprehension iterates over the other dictionary entries to gather the value of with_everything, and Python programmers know that of course dictionaries are not indexed and therefore the order of the key-value pairs isn't fixed, but is determined by certain conditions. That's the source for the non-determinism of this Debian package revision of Prospector. This problem has been fixed by a patch, which just presorts the list of requirements before it gets added to _OPTIONAL:
@@ -76,8 +76,8 @@
     'with_pyroma': ('pyroma>=1.6,<2.0',),
     'with_pep257': (),  # note: this is no longer optional, so this option will be removed in a future release
  
-_OPTIONAL['with_everything'] = [req for req_list in _OPTIONAL.values() for req in req_list]
-
+with_everything = [req for req_list in _OPTIONAL.values() for req in req_list]
+_OPTIONAL['with_everything'] = sorted(with_everything)
In comparison to the list method sort(), the function sorted() does not change iterables in-place, but returns a new object. Both could be used. As a side note, egg-info/requires.txt isn't even needed, but that's another issue.

  1. As an alternative to prefixing LC_ALL, env -i could be used to get an empty environment.
  2. 0.11.7-4 already but this package revision was in experimental due to the switch to Python 3 and therefore not tested by reproducible builds continuous integration.

Russell Coker: Basics of Backups

I ve recently had some discussions about backups with people who aren t computer experts, so I decided to blog about this for the benefit of everyone. Note that this post will deliberately avoid issues that require great knowledge of computers. I have written other posts that will benefit experts. Essential Requirements Everything that matters must be stored in at least 3 places. Every storage device will die eventually. Every backup will die eventually. If you have 2 backups then you are covered for the primary storage failing and the first backup failing. Note that I m not saying only have 2 backups (I have many more) but 2 is the bare minimum. Backups must be in multiple places. One way of losing data is if your house burns down, if that happens all backup devices stored there will be destroyed. You must have backups off-site. A good option is to have backup devices stored by trusted people (friends and relatives are often good options). It must not be possible for one event to wipe out all backups. Some people use cloud backups, there are many ways of doing this with Dropbox, Google Drive, etc. Some of these even have free options for small amounts of storage, for example Google Drive appears to have 15G of free storage which is more than enough for all your best photos and all your financial records. The downside to cloud backups is that a computer criminal who gets access to your PC can wipe it and the backups. Cloud backup can be a part of a sensible backup strategy but it can t be relied on (also see the paragraph about having at least 2 backups). Backup Devices USB flash sticks are cheap and easy to use. The quality of some of those devices isn t too good, but the low price and small size means that you can buy more of them. It would be quite easy to buy 10 USB sticks for multiple copies of data. Stores that sell office-supplies sell USB attached hard drives which are quite affordable now. It s easy to buy a couple of those for backup use. The cheapest option for backing up moderate amounts of data is to get a USB-SATA device. This connects to the PC by USB and has a cradle to accept a SATA hard drive. That allows you to buy cheap SATA disks for backups and even use older disks as backups. With choosing backup devices consider the environment that they will be stored in. If you want to store a backup in the glove box of your car (which could be good when travelling) then a SD card or USB flash device would be a good choice because they are resistant to physical damage. Note that if you have no other options for off-site storage then the glove box of your car will probably survive if your house burns down. Multiple Backups It s not uncommon for data corruption or mistakes to be discovered some time after it happens. Also in recent times there is a variety of malware that encrypts files and then demands a ransom payment for the decryption key. To address these problems you should have older backups stored. It s not uncommon in a corporate environment to have backups every day stored for a week, backups every week stored for a month, and monthly backups stored for some years. For a home use scenario it s more common to make backups every week or so and take backups to store off-site when it s convenient. Offsite Backups One common form of off-site backup is to store backup devices at work. If you work in an office then you will probably have some space in a desk drawer for personal items. If you don t work in an office but have a locker at work then that s good for storage too, if there is high humidity then SD cards will survive better than hard drives. Make sure that you encrypt all data you store in such places or make sure that it s not the secret data! Banks have a variety of ways of storing items. Bank safe deposit boxes can be used for anything that fits and can fit hard drives. If you have a mortgage your bank might give you free storage of papers as part of the service (Commonwealth Bank of Australia used to offer that). A few USB sticks or SD cards in an envelope could fit the papers criteria. An accounting firm may also store documents for free for you. If you put a backup on USB or SD storage in your waller then that can also be a good offsite backup. For most people losing data from disk is more common than losing their wallet. A modern mobile phone can also be used for backing up data while travelling. For a few years I ve been doing that. But note that you have to encrypt all data stored on a phone so an attacker who compromises your phone can t steal it. In a typical phone configuration the mass storage area is much less protected than application data. Also note that customs and border control agents for some countries can compel you to provide the keys for encrypted data. A friend suggested burying a backup device in a sealed plastic container filled with dessicant. That would survive your house burning down and in theory should work. I don t know of anyone who s tried it. Testing On occasion you should try to read the data from your backups and compare it to the original data. It sometimes happens that backups are discovered to be useless after years of operation. Secret Data Before starting a backup it s worth considering which of the data is secret and which isn t. Data that is secret needs to be treated differently and a mixture of secret and less secret data needs to be treated as if it s all secret. One category of secret data is financial data. If your accountant provides document storage then they can store that, generally your accountant will have all of your secret financial data anyway. Passwords need to be kept secret but they are also very small. So making a written or printed copy of the passwords is part of a good backup strategy. There are options for backing up paper that don t apply to data. One category of data that is not secret is photos. Photos of holidays, friends, etc are generally not that secret and they can also comprise a large portion of the data volume that needs to be backed up. Apparently some people have a backup strategy for such photos that involves downloading from Facebook to restore, that will help with some problems but it s not adequate overall. But any data that is on Facebook isn t that secret and can be stored off-site without encryption. Backup Corruption With the amounts of data that are used nowadays the probability of data corruption is increasing. If you use any compression program with the data that is backed up (even data that can t be compressed such as JPEGs) then errors will be detected when you extract the data. So if you have backup ZIP files on 2 hard drives and one of them gets corrupt you will easily be able to determine which one has the correct data. Failing Systems update 2016-08-22 When a system starts to fail it may limp along for years and work reasonably well, or it may totally fail soon. At the first sign of trouble you should immediately make a full backup to separate media. Use different media to your regular backups in case the data is corrupt so you don t overwrite good backups with bad ones. One traditional sign of problems has been hard drives that make unusual sounds. Modern drives are fairly quiet so this might not be loud enough to notice. Another sign is hard drives that take unusually large amounts of time to read data. If a drive has some problems it might read a sector hundreds or even thousands of times until it gets the data which dramatically reduces system performance. There are lots of other performance problems that can occur (system overheating, software misconfiguration, and others), most of which are correlated with potential data loss. A modern SSD storage device (as used in a lot of the recent laptops) doesn t tend to go slow when it nears the end of it s life. It is more likely to just randomly fail entirely and then work again after a reboot. There are many causes of systems randomly hanging or crashing (of which overheating is common), but they are all correlated with data loss so a good backup is a good idea. When in doubt make a backup. Any Suggestions? If you have any other ideas for backups by typical home users then please leave a comment. Don t comment on expert issues though, I have other posts for that.

19 August 2016

Zlatan Todori : Defcon24

I went to Defcon24 as Purism representative. It was (as usual) held in Las Vegas, the city of sin. In the same module as with DebConf, here we go with good, bad and ugly. Good Badges are really cool. You can find good hackers here and there (but very small number compared to total number). Some talks are good and workshop + village idea looks good (although I didn't manage to attend any workshop as there was place for 1100 and there were 22000 attendees). The movie night idea is cool and Arcade space (where you can play old arcade games, relax and hack and also listen to some cool music) is really lovely. Also you have a camp/village for kids learning things such as electronics, soldering etc but you need to pay attention that they don't see too much of twisted folks that also gather on this con. And that's it. Oh, yea, Dark Tangent appears actually to be cool dude. Bad One does not simply hold a so-called hacker conference in Las Vegas. Having a conference inside hotel/casino where you mix with gamblers and casino workes (for good or for bad) is simply not in hacker spirit and certainly brings all kind of people to the same place. Also, there were simply not enough space for 22000 Defcon attendees, and you don't get proud of having on average ONLY 40min lines. You get proud if you don't have lines! Organization is not the strongest part of Defcon. Huge majority of attendees are not hackers. They are script kiddies, hacker wannabes, comic con people, few totally lost souls etc etc. That simply brings the quality of a conference down. Yes it is cool to have mix of many diverse people but not for the sake of just having people. Ugly They lack Code of Conduct (everyone knows I am not in favor of any writens rules how people should behave but after Defcon I clearly see need for it). Actually, tbh, they do have it but no one gives a damn about it. And you should report to Goons, more about them below. Sexism is huge here. I remember and hear about stories of sexual harassment in IT industry, but Debian somehow mitigated that before me entering its domains, so I never experienced it. The sheer number of sexist behavior on Defcon is tremendous. It appears to me that those people had lonely childhood and now they act as a spoiled 6 year old: they're spoiled, they need to yell to show their point, they have low and stupid sexist jokes and they simply think that is cool. Majority of Goons (their coordinators or whatever) are simply idiots. I don't know do they feel they have some superpowers, or are drunk or just stupid but yelling on people, throwing low jokes on people, more yelling, cursing all the time, more yelling - simply doesn't work for me. So now you can see the irony of CoC on Defcon. They even like to say, hey we are old farts, let us our con be as we want it to be. So no real diversity there. Either it is their way, and god forsaken if you try to change something for better and make them stop cursing or throwing sexist jokes ("squeeze, people. together, touch each other, trust me it will feel good"), or highway. Also it appears that to huge number of vocal people, word "fuck" has some fetish meaning. Either it needs to show how "fucking awesome this con or they are" or to "fucking tell few things about random fucking stuff". Thank you, but no thank you. So what did I do during con. I attended few talks, had some discussion with people, went to one party (great DJs, again people doing stupid things, like breaking invertory to name just one of them) and had so much time (read "I was bored") that I bought domain, brough up server on which I configured nginx and cp'ed this blog to blog.zlatan.tech (yes, recently I added letsencrypt because it is, let me be in Defcon mood, FUCKING AWESOME GRRR UGH) and now I even made .onion domain for it. What can boredom do to people, right? So the ultimate question is - would I go again to Defcon. I am strongly leaning to no, but in my nature is to give second chance and now I have more experience (and I also have thick skin so I guess I can play calm for one more round).

18 August 2016

Zlatan Todori : DebConf16 - new age in Debian community gathering

DebConf16 Finally got some time to write this blog post. DebConf for me is always something special, a family gathering of weird combination of geeks (or is weird a default geek state?). To be honest, I finally can compare Debian as hacker conference to other so-called hacker conferences. With that hat on, I can say that Debian is by far the most organized and highest quality conference. Maybe I am biased, but I don't care too much about that. I simply love Debian and that is no secret. So lets dive into my view on DebConf16 which was held in Cape Town, South Africa. Cape Town This was the first time we had conference on African continent (and I now see for the first time DebConf bid for Asia, which leaves only Australia and beautiful Pacific islands to start a bid). Cape Town by itself, is pretty much Europe-like city. That was kinda a bum for me on first day, especially as we were hosted at University of Cape Town (which is quite beautiful uni) and the surrounding neighborhood was very European. Almost right after the first day I was fine because I started exploring the huge city. Cape Town is really huge, it has by stats ~4mil people, and unofficially it has ~6mil. Certainly a lot to explore and I hope one day to be back there (I actually hope as soon as possible). The good, bad and ugly I will start with bad and ugly as I want to finish with good notes. Racism down there is still HUGE. You don't have signs on the road saying that, but there is clearly separation between white and black people. The houses near uni all had fences on walls (most of them even electrical ones with sharp blades on it) with bars on windows. That just bring tensions and certainly doesn't improve anything. To be honest, if someone wants to break in they still can do easily so the fences maybe need to bring intimidation but they actually only bring tension (my personal view). Also many houses have sign of Armed Force Response (something in those lines) where in case someone would start breaking in, armed forces would come to protect the home. Also compared to workforce, white appear to hold most of profit/big business positions and fields, while black are street workers, bar workers etc etc. On the street you can feel from time to time the tension between people. Going out to bars also showed the separation - they were either almost exclusively white or exclusively black. Very sad state to see. Sharing love and mixing is something that pushes us forward and here I saw clear blockades for such things. The bad part of Cape Town is, and this is not only special to Cape Town but to almost all major cities, is that small crime is on wide scale. Pickpocketing here is something you must pay attention to it. To me, personally, nothing happened but I heard a lot of stories from my friends on whom were such activities attempted (although I am not sure did the criminals succeed). Enough of bad as my blog post will not change this and it is a topic for debate and active involvement which I can't unfortunately do at this moment. THE GOOD! There are so many great local people I met! As I mentioned, I want to visit that city again and again and again. If you don't fear of those bad things, this city has great local cuisine, a lot of great people, awesome art soul and they dance with heart (I guess when you live in rough times, you try to use free time at your best). There were difference between white and black bars/clubs - white were almost like standard European, a lot of drinking and not much dancing, and black were a lot of dancing and not much drinking (maybe the economical power has something to do with it but I certainly felt more love in black bars). Cape Town has awesome mountain, the Table Mountain. I went on hiking with my friends, and I must say (again to myself) - do the damn hiking as much as possible. After every hike I feel so inspired, that I will start thinking that I hate myself for not doing it more often! The view from Table mountain is just majestic (you can even see the Cape of Good Hope). The WOW moments are just firing up in you. Now lets transfer to DebConf itself. As always, organization was on quite high level. I loved the badge design, it had a map and nice amount of information on it. The place we stayed was kinda not that good but if you take it into account that those a old student dorms (in we all were in female student dorm :D ) it is pretty fancy by its own account. Talks were near which is always good. The general layout of talks and front desk position was perfect in my opinion. All in one place basically. Wine and Cheese this year was kinda funny story because of the cheese restrictions but Cheese cabal managed to pull out things. It was actually very well organized. Met some new people during the party/ceremony which always makes me grow as a person. Cultural mix on DebConf is just fantastic. Not only you learn a lot about Debian, hacking on it, but sheer cultural diversity makes this small con such a vibrant place and home to a lot. Debian Dinner happened in Aquarium were I had nice dinner and chat with my old friends. Aquarium by itself is a thing where you can visit and see a lot of strange creatures that live on this third rock from Sun. Speaking of old friends - I love that I Apollo again rejoined us (by missing the DebConf15), seeing Joel again (and he finally visited Banja Luka as aftermath!), mbiebl, ah, moray, Milan, santiago and tons of others. Of course we always miss a few such as zack and vorlon this year (but they had pretty okay-ish reasons I would say). Speaking of new friends, I made few local friends which makes me happy and at least one Indian/Hindu friend. Why did I mention this separately - well we had an accident during Group Photo (btw, where is our Lithuanian, German based nowdays, photographer?!) where 3 laptops of our GSoC students were stolen :( . I was luckily enough to, on behalf of Purism, donate Librem11 prototype to one of them, which ended up being the Indian friend. She is working on real time communications which is of interest also to Purism for our future projects. Regarding Debian Day Trip, Joel and me opted out and we went on our own adventure through Cape Town in pursue of meeting and talking to local people, finding out interesting things which proved to be a great decision. We found about their first Thursday of month festival and we found about Mama Africa restaurant. That restaurant is going into special memories (me playing drums with local band must always be a special memory, right?!). Huh, to be honest writing about DebConf would probably need a book by itself and I always try to keep my posts as short as possible so I will try to stop here (maybe I write few bits in future more about it but hardly). Now the notes. Although I saw the racial segregation, I also saw the hope. These things need time. I come from country that is torn apart in nationalism and religious hate so I understand this issues is hard and deep on so many levels. While the tensions are high, I see people try to talk about it, try to find solution and I feel it is slowly transforming into open society, where we will realize that there is only one race on this planet and it is called - HUMAN RACE. We are all earthlings, and as sooner we realize that, sooner we will be on path to really build society up and not fake things that actually are enslaving our minds. I just want in the end to say thank you DebConf, thank you Debian and everyone could learn from this community as a model (which can be improved!) for future societies.

17 August 2016

Michal &#268;iha&#345;: Revoking old PGP key

It has been already six years since I've moved to using RSA4096 PGP key. For various reasons, the old DSA key was still kept valid till today. This is no longer true and it has been revoked now. The revoked key is DC3552E836E75604 and new one is 9C27B31342B7511D. In case you've signed the old one and not the new one (quite unlikely if you did not sign it more than six years ago), there has been migration document, where you can verify my new key being signed by the old one.

Filed under: Debian English 0 comments

16 August 2016

Lars Wirzenius: 20 years ago I became a Debian developer

Today it is 23 years ago since Ian Murdock published his intention to develop a new Linux distribution, Debian. It also about 20 years since I became a Debian developer and made my first package upload. In the time since: It's been a good twenty years. And the fun ain't over yet.

15 August 2016

Shirish Agarwal: The road to TOR

Happy Independence Day to all. I had been looking forward to this day so I can use to share with my brothers and sisters what little I know about TOR . Independence means so many things to many people. For me, it means having freedom, valuing it and using it to benefit not just to ourselves but to people at large. And for that to happen, at least on the web, it has to rise above censorship if we are to get there at all. I am 40 years old, and if I can t read whatever I want to read without asking the state-military-Corporate trinity than be damned with that. Debconf was instrumental as I was able to understand and share many of the privacy concerns that we all have. This blog post is partly a tribute to being part of a community and being part of Debconf16. So, in that search for privacy couple of years ago, I came across TOR . TOR stands for The Onion Router project. Explaining tor is simple. Let us take the standard way in which we approach the website using a browser or any other means. a. We type out a site name, say debian.org in the URL/URI bar .
b. Now the first thing the browser would do is look into its DNS Cache to see if the name/URL has been used before. If it is something like debian.org which has been used before and is *fresh* and there is content already it would serve the content from the cache there itself.
c. In case, if it s not or the content is stale or something, it would generate a DNS lookup through the various routing tables till the DNS IP Address is found and information relayed to the browser.
d. The browser takes the IP Address and opens a TCP connection to the server, you have the handshake happen and after that it s business as usual.
e. In case if it doesn t work, you could get errors like Could not connect to server xyz or some special errors with error codes. This is a much simplified version of what happens or goes through normally with most/all of the browsers. One good way to see how the whole thing happens is to use traceroute and use the whois service. For e.g. [$] traceroute debian.org and then [$] whois 5.153.231.4 grep inetnum
inetnum: 5.153.231.0 - 5.153.231.255
Just using whois IP Address gives much more. I just shared a short version because I find it interesting that Debian has booked all 255 possible IP Addresses but speculating on that would be probably be a job for a different day. Now the difference when using TOR are two things a. The conversation is encrypted (somewhat like using https but encrypted through the relays)
b. The conversation is relayed over 2-3 relays and it will give a somewhat different identification to the DNS server at the other end.
c. It is only at the end-points that the conversation will be in plain text. For e.g. the TOR connection I m using atm is from me France (relay) Switzerland (relay) Germany (relay) WordPress.com . So wordpress thinks that all the connection is happening via Germany while I m here in India. It would also tells that I m running MS-Windows some version and a different browser while I m from somewhere in India, on Debian, using another browser altogether There are various motivations for doing that. For myself, I m just a private person and do not need or want that any other person/s or even the State should be looking over my shoulder as to what I m doing. And the argument that we need to spy on citizens because Terrorists are there doesn t hold water over me. There are many ways in which they can pass messages even without tor or web. The Government-Corporate-Military just get more powerful if and when they know what common people think, do, eat etc. So the question is how does you install tor if you a private sort of person . If you are on a Debian machine, you are one step closer to doing that. So the first thing that you need to do is install the following $ sudo aptitude install ooniprobe python-certifi tor tor-geoipdb torsocks torbrowser-launcher Once the above is done, then run torbrowser-launcher. This is how it would work out the first time it is run [$] torbrowser-launcher Tor Browser Launcher
By Micah Lee, licensed under MIT
version 0.2.6
https://github.com/micahflee/torbrowser-launcher
Creating GnuPG homedir /home/shirish/.local/share/torbrowser/gnupg_homedir
Downloading and installing Tor Browser for the first time.
Downloading https://dist.torproject.org/torbrowser/update_2/release/Linux_x86_64-gcc3/x/en-US
Latest version: 6.0.3
Downloading https://dist.torproject.org/torbrowser/6.0.3/tor-browser-linux64-6.0.3_en-US.tar.xz.asc
Downloading https://dist.torproject.org/torbrowser/6.0.3/tor-browser-linux64-6.0.3_en-US.tar.xz
Verifying signature
Extracting tor-browser-linux64-6.0.3_en-US.tar.xz
Running /home/shirish/.local/share/torbrowser/tbb/x86_64/tor-browser_en-US/start-tor-browser.desktop
Launching './Browser/start-tor-browser --detach'...
As can be seen above, you basically download the tor browser remotely from the website. Obviously, for this port 80 needs to be opened. One of the more interesting things is that it tells you where it installs the browser. /home/shirish/.local/share/torbrowser/tbb/x86_64/tor-browser_en-US/Browser/start-tor-browser and then detaches. The first time the TOR browser actually runs it looks something similar to this
Torbrowser picture

Torbrowser picture

Additionally it would give you 4 choices. Depending on your need for safety, security and convenience you make a choice and live with it. Now the only thing remaining to do is have an alias for your torbrowser. So I made [$] alias tor tor=/home/shirish/.local/share/torbrowser/tbb/x86_64/tor-browser_en-US/Browser/start-tor-browser It is suggested that you do not use the same usernames on the onion network. Also apart from the regular URL addresses such as flossexperiences.wordpress.com you will also see sites such as https://www.abc12defgh3ijkl.onion.to (fictional address) Now there would be others who would want to use the same/similar settings say as there are in their Mozilla Firefox installation. To do that do the following steps a. First close down both Torbrowser and Mozilla Firefox .
b. Open your file browser and go to where your mozilla profile details are. In typical Debian installations it is at ~/.mozilla/firefox/5r7t1r92.default In the next tab, navigate to ~/.local/share/torbrowser/tbb/x86_64/tor-browser_en-US/Browser/TorBrowser/Data/Browser/profile.default c. Now copy the following files over from your mozilla profile to your tor browser profile and you can resume where you left off.
    cert8.db
    chromeappsstore.sqlite
    content-prefs.sqlite
    cookies.sqlite
    formhistory.sqlite
    key3.db
    logins.json (Firefox 32 and above)
    mimeTypes.rdf
    permissions.sqlite
    persdict.dat
    places.sqlite
    signons3.txt (if exists)
    webappsstore.sqlite
and the following folders/directories
    bookmarkbackups
    chrome (if it exists)
    searchplugins (if it exists)
Once the above is done, fire up your torbrowser with the alias shared. This is usually put it in your .bashrc file or depending on whatever terminal interpreter you use, wherever the config file will be. Welcome to the world of TOR. Now, after a time if you benefit from tor and would like to give back to the tor community, you should look up tor bridges and relay. As the blog post has become long enough, I would end it now and hopefully we can talk about tor bridges and relay some other day.
Filed under: Miscellenous Tagged: #anonymity, #Debconf16, #debian, #tor, #torbrowser, GNU, Linux, Privacy

Russ Allbery: Review: Winds of Fate

Review: Winds of Fate, by Mercedes Lackey
Series: Mage Winds #1
Publisher: DAW
Copyright: 1991
Printing: July 1992
ISBN: 0-88677-516-7
Format: Mass market
Pages: 460
As a kid working my way through nearly everything in the children's section of the library, I always loved book series, since it meant I could find a lot more of something I liked. But children's book series tended to be linear, with a well-defined order. When I moved into the adult SF section, I encountered a new type of series: one that moves backwards and forwards in time to fill in a broader story. I mention that here because Winds of Fate, although well into the linked series that make up Valdemar, was one of the first Valdemar books I read. (I think it was the first, but my memory is hazy.) Therefore, in my brain, this is where the story of Valdemar "begins": with Elspeth, a country that has other abilities but has forgotten about magic, a rich world full of various approaches to magic, and very pushy magic horses. Talia's story, and particularly Vanyel's, were always backstory, the events that laid the groundwork for Elspeth's story. (I didn't encounter Tarma and Kethry until somewhat later.) Read now in context, this is obviously not the case. The Mage Winds trilogy, of which this is the first book, are clearly sequels to the Arrows of the Queen trilogy. Valdemar was victorious in the first round of war with Ancar, but the Heralds have slowly (and with great difficulty) become aware of their weakness against magic and their surprising lack of it. Elspeth has grown into the role of heir, but she's also one of the few who find it easy to talk about and think about magic (perhaps due to her long association with Kerowyn, who came into Valdemar from the outside world in By the Sword). She therefore takes on the mission of finding an Adept who can return to Valdemar, solve the mystery of whatever is keeping magic out of the kingdom, and start training mages for the kingdom again. Meanwhile, we get the first viewpoint character from the Tayledras: the elf-inspired mages who work to cleanse the Pelagiris forests from magic left over from a long-ago war. They appeared briefly in Vanyel's story, since his aunt was friends with a farther-north tribe of them and Valdemar of the time had contact with mages. Darkwind and his people are far to the south, up against the rim of the Dhorisha crater. Something has gone horribly wrong with Heartstone of the k'Sheyna, his tribe: it cracked when being drained, killing most of the experienced mages including Darkwind's mother, and now it is subtly wrong, twisting and undermining the normal flow of magic inside their Vale. In the aftermath of that catastrophe, Darkwind has forsworn magic and become a scout, putting him sharply at odds with his father. And it's a matter of time before less savory magic users in the area realize how vulnerable k'Sheyna is. Up to this point in the Valdemar series, Lackey primarily did localized world-building to support the stories and characters she was writing about. Valdemar and its Heralds and Companions have been one of the few shared elements, and only rarely did the external magic-using world encounter them. Here, we get the first extended contact between the fairly naive Heralds and experienced mages who understand how they and their Companions fit into the broader system of magic. We also finally get the origin of the Dhorisha Plains and the Tayledras and Shin'a'in, and a much better sense of the broader history of this world. And Need, which started as Kethry's soul-bonded sword and then became Kerowyn's, joins the story in a much more active way. The world-building is a definite feature if you like this sort of thing. It doesn't withstand too much thinking about the typical sword and sorcery lack of technology, but for retroactive coherence constructed from originally scattered stories, it's pretty fun. (I suspect part of why I like the Valdemar world-building is that it feels a lot like large shared universe world-building in comics.) And Need is the high point of the story: she brings a much-needed cynical stubbornness to the cast and is my favorite character in this book. What is not a feature, unfortunately, is the characterization. Darkwind is okay but a largely unremarkable here, more another instance of the troubled but ethical Tayledras type than a clearly defined character. But Elspeth is just infuriating, repeatedly making decisions and taking hard positions that seem entirely unwarranted by the recorded events of the book. This is made worse by how frequently she's shown to be correct in ways that seem like authorial cheating. At times, it feels like she's the heroine by authorial fiat, not because she's doing a particularly good job. I can muster some sympathy for not wanting to follow the plan of the Companions when it became clear they were acting entirely out of character and actively intervening, but she expresses that with petulant, childish insistence rather than reasoned argument. And she suddenly decides Skif is in love with her and treating her like a fragile princess on the basis of absolutely no action that occurs on camera in this book so far as I can tell, and proceeds to treat him like dirt for large sections of the book. That Skif then lives down to this suddenly negative impression doesn't help. This book also has quite a lot of the U-shaped story arc in which everything gets worse and more horrific and more hopeless for the heroes over the course of the book until it turns into torture, and only then do they manage to claw their way back out. I've come to dislike this way of building tension. It's undeniably effective, but the parts of the story near the bottom of the U are difficult and painful reading. I prefer a bit more evenly-spread hurt/comfort storytelling in my popcorn fantasy reading. Winds of Fate is, sadly, not a very good book. Most of the characterization is intensely irritating, the writing is a bit uneven, and the middle section of the book is rather painful to read. For me, though, that's balanced by the world-building and the sense of broadened scope, by Need's abrasive decisiveness, and by some really entertaining reactions to the combination of Elspeth, Need, and her Companion walking naive into the broader world. I still have a fond spot in my heart for it, but I'm hoping the remaining books of the trilogy are better. Rating: 6 out of 10

14 August 2016

Reproducible builds folks: Reproducible Builds: week 68 in Stretch cycle

What happened in the Reproducible Builds effort between Sunday August 7 and Saturday August 13 2016: GSoC and Outreachy updates Reproducible work in other projects Thomas Schmitt scdbackup@gmx.net implemented a new -as mkisofs option:
--set_all_file_dates timestring
Set mtime, atime, and ctime of all files and directories to  the
given time.
Valid  timestring  formats  are:  'Nov  8  14:51:13  CET  2007',
110814512007.13, 2007110814511300. See also --modification-date=
and man xorriso, Examples of input timestrings.
This  action  stays  delayed until mkisofs emulation ends. Up to
then it  can  be  revoked  by  --set_all_file_dates  with  empty
timestring.   In  any  case  files  which get into the ISO after
mkisofs emulation ended will not  be  affected,  unless  another
mkisofs emulation applies --set_all_file_date again.
LEDE developer Jonas Gorski submitted a patch to fix build times in their kernel:
kernel: allow reproducable builds
Similar how we fix the file times in the filesystems, fix the build time
of the kernel, and make the build number static. This should allow the
kernel build to be reproducable when combined with setting the
KERNEL\_BUILD\_USER and \_DOMAIN in case of different machines.
The reproducability only applies to non-initramfs kernels, those still
require additional changes.
Signed-off-by: Jonas Gorski <jonas.gorski@gmail.com>
Packages reviewed and fixed, and bugs filed Patches have been submitted by: Package reviews 28 reviews have been added, 4 have been updated and 7 have been removed in this week, adding to our knowledge about identified issues. Issue types have been added/updated: Weekly QA work FTBFS bugs have been reported by: diffoscope development strip-nondeterminism development tests.reproducible-builds.org Misc. Chris started to ping old bugs with patches and no maintainer reaction so far. This week's edition was written by Chris Lamb and Holger Levsen and reviewed by a bunch of Reproducible Builds folks on IRC.

Steinar H. Gunderson: Linear interpolation, source alignment, and Debian's embedding policy

At some point back when the dinosaurs roamed the Earth and I was in high school, I borrowed my first digital signal processing book from a friend. I later went on to an engineering education and master's thesis about DSP, but the very basics of DSP never stop to fascinate me. Today, I wanted to write something about one of them and how it affects audio processing in Nageru (and finally, how Debian's policies put me in a bit of a bind on this issue). DSP texts tend to obscure profound truths with large amounts of maths, so I'll try to present a somewhat less general result that doesn't require going into the mathematical details. That rule is: Adding a signal to weighted, delayed copies of itself is a filtering operation. (It's simple, but ignoring it will have sinister effects, as we'll see later.) Let's see exactly what that means with a motivating example. Let's say that I have a signal where I want to get rid of (or rather, reduce) high frequencies. The simplest way I can think of is to add every neighboring sample; that is, set yn = xn + xn-1. For each sample, we add the previous sample, ie., the signal as it was one sample ago. (We ignore what happens at the edges; the common convention is to assume signals extend out to infinity with zeros.) What effect will this have? We can figure it out with some trigonometry, but let's just demonstrate it by plotting instead: We assume 48 kHz sample rate (which means that our one-sample delay is 20.83 s) and a 22 kHz note (definitely treble!), and plot the signal with one-sample delay (the x axis is sample number): Filtered 22 kHz As you can see, the resulting signal is a new signal of the same frequency (which is always true; linear filtering can never create new frequencies, just boost or dampen existing ones), but with much lower amplitude. The signal and the delayed version of it end up cancelling each other mostly out. Also note that there signal has changed phase; the resulting signal has been a bit delayed compared to the original. Now let's look at a 50 Hz signal (turn on your bass face). We need to zoom out a bit to see full 50 Hz cycles: Filtered 50 Hz The original signal and the delayed one overlap almost exactly! For a lower frequency, the one-sample delay means almost nothing (since the waveform is varying so slowly), and thus, in this case, the resulting signal is amplified, not dampened. (The signal has changed phase here, too actually exactly as much in terms of real time but we don't really see it, because we've zoomed out.) Real signals are not pure sines, but they can be seen as sums of many sines (another fundamental DSP result), and since filtering is a linear operation, it affects those sines independently. In other words, we now have a very simple filter that will amplify low frequencies and dampen high frequencies (and delay the entire signal a little bit). We can do this for all frequencies from 0 to 24000 Hz; let's ask Octave to do it for us: Frequency plot for simple filter (Of course, in a real filter, we'd probably multiply the result with 0.5 to leave the bass untouched instead of boosting it, but it doesn't really change anything. A real filter would have a lot more coefficients, though, and they wouldn't all be the same!) Let's now turn to a problem that will at first seem different: Combining audio from multiple different time sources. For instance, when mixing video, you could have input from two different cameras or sounds card and would want to combine them (say, a source playing music and then some audience sound from a camera). However, unless you are lucky enough to have a professional-grade setup where everything runs off the same clock (and separate clock source cables run to every device), they won't be in sync; sample clocks are good, but they are not perfect, and they have e.g. some temperature variance. Say we have really good clocks and they only differ by 0.01%; this means that after an hour of streaming, we have 360 ms delay, completely ruining lip sync! This means we'll need to resample at least one of the sources to match the other; that is, play one of them faster or slower than it came in originally. There are two problems here: How do you determine how much to resample the signals, and how do we resample them? The former is a difficult problem in its own right; about every algorithm not backed in solid control theory is doomed to fail in one way or another, and when they fail, it's extremely annoying to listen to. Nageru follows a 2012 paper by Fons Adriaensen; GStreamer does well, something else. It fails pretty badly in a number of cases; see e.g. this 2015 master's thesis that tries to patch it up. However, let's ignore this part of the problem for now and focus on the resampling. So let's look at the case where we've determined we have a signal and need to play it 0.01% faster (or slower); in a real situation, this number would vary a bit (clocks are not even consistently wrong). This means that at some point, we want to output sample number 3000 and that corresponds to input sample number 3000.3, ie., we need to figure out what's between two input samples. As with so many other things, there's a way to do this that's simple, obvious and wrong, namely linear interpolation. The basis of linear interpolation is to look at the two neighboring samples and weigh them according to the position we want. If we need sample 3000.3, we calculate y = 0.7 x3000 + 0.3 x3001 (don't switch the two coefficients!), or, if we want to save one multiplication and get better numerical behavior, we can use the equivalent y = x3000 + 0.3 (x3001 - x3000). And if we need sample 5000.5, we take y = 0.5 x5000 + 0.5 x5001. And after a while, we'll be back on integer samples; output sample 10001 corresponds to x10000 exactly. By now, I guess it should be obvious what's going on: We're creating a filter! Linear interpolation will inevitably result in high frequencies being dampened; and even worse, we are creating a time-varying filter, which means that the amount of dampening will vary over time. This manifests itself as a kind of high-frequency flutter , where the amount of flutter depends on the relative resampling frequencies. There's also cubic resampling (which can mean any of several different algorithms), but it only really reduces the problem, it doesn't really solve it. The proper way of interpolating depends a lot on exactly what you want (e.g., whether you intend to change the rate quickly or not); this paper lays out a bunch of them, and was the paper that originally made me understand why linear interpolation is so bad. Nageru outsources this problem to zita-resampler, again by Fons Adriaensen; it yields extremely high-quality resampling under controlled delay, through a relatively common technique known as polyphase filters. Unfortunately, doing this kind of calculations takes CPU. Not a lot of CPU, but Nageru runs in rather CPU-challenged environments (ultraportable laptops where the GPU wants most of the TDP, and the CPU has to go down to the lowest frequency), and it is moving in a direction where it needs to resample many more channels (more on the later), so every bit of CPU helps. So I coded up an SSE optimization of the inner loop for a particular common case (stereo signals) and sent it in for upstream inclusion. (It made the code 2.7 times as fast without any structural changes or reducing precision, which is pretty much what you can expect from SSE.) Unfortunately, after a productive discussion, suddenly upstream went silent. I tried pinging, pinging again, and after half a year pinging again, but to no avail. I filed the patch in Debian's BTS, but the maintainer understandably is reluctant to carry a delta against upstream. I also can't embed a copy; Debian policy would dictate that I build against the system's zita-resampler. I could work around it by rewriting zita-resampler until it looks nothing like the original, which might be a good idea anyway if I wanted to squeeze out the last drops of speed; there are AVX optimizations to be had in addition to SSE, and the structure as-is isn't ideal for SSE optimizations (although some of the changes I have in mind would have to be offset against increased L1 cache footprint, so careful benchmarking would be needed). But in a sense, it feels like just working around a policy that's there for good reason. So like I said, I'm in a bit of a bind. Maybe I should just buy a faster laptop. Oh, and how does GStreamer solve this? Well, it doesn't use linear interpolation. It does something even worse it uses nearest neighbor. Gah. Update: I was asked to clarify that this is about the audio resampling done by the GStreamer audio sink to sync signals, not in the audioresample element, which solves a related but different problem (static sample rate conversion). The audioresample element supports a number of different resampling methods; I haven't evaluated them.
David Moreno: I quit

I just recently quit my job at the startup company I had been working in for almost five years. In startup terms, such long time might be a whole lifetime, but in my case, I grew liking it more and more as the years came, I had evolved from being just another engineer, to lead a team of seven great developers, with decision-making tasks and strategy planning for our technical infrastructure. It s been such a great long teaching journey that I m nothing but pleased with my own performance, learned lessons and skills and all I provided and was provided by the project. Leaving a city like New York is not an easy task. You have it all there, you start making a life and suddenly, before you know it, you already have a bunch of ties to the place, people, leases, important dates, all kinds of shit. Seriously, all kinds of crazy ass shit start to fill up your baggage. You wake up everyday to get into the subway and commute surrounded by all of this people that are just like you: so similar yet so immensely different. No, leaving the city is not an easy task, it s not something to take lightly. You know how people just say my cycle has ended in this place as an euphemism not to end in bad terms with anyone? Well, ending a cycle is indeed a reality, I got to a point where I felt like I needed to head into a different direction, take on new challenges and overall, peace out and hope the best to everyone, specially to myself. This was me, on my last day at work, last Friday of June: (Some) people seem to be anxious to know what I m doing next, and my answer is, go mind your own fucking business. However, life is short and I would love to do any of the following: Decisions, decisions For the time being, I m chilling with my people, friends and family in beautiful Mexico City. I ve been doing so for the entire month of July and I couldn t be more content. August will see my 28th birthday and as I approach thirty, I believe I need to continue moving forward. This stupid world is a tiny place and our lives are short, I for one, will definitively try to take the bull by the horns. Thanks for reading, more updates soon. Peace.

13 August 2016

Russ Allbery: git-pbuilder 1.42

A minor update to my glue script for building software with pdebuild and git-buildpackage. (Yes, still needs to get rewritten in Python.) This release stops using the old backport location for oldstable builds since oldstable is now wheezy, which merged the backports archive into the regular archive location. The old location is still there for squeeze just in case anyone needs it. It also adds a new environment variable, GIT_PBUILDER_PDEBUILDOPTIONS, that can be used to pass options directly to pdebuild. Previously, there was only a way to pass options to the builder, via pdebuild, but not to configure pdebuild itself. There are some times when that's useful, such as to pass --use-pdebuild-internal. This was based on a patch from Rafa D ugo cki. You can get the latest version of git-pbuilder from my scripts page.

Russell Coker: SSD and M.2

The Need for Speed One of my clients has an important server running ZFS. They need to have a filesystem that detects corruption, while regular RAID is good for the case where a disk gives read errors it doesn t cover the case where a disk returns bad data and claims it to be good (which I ve witnessed in BTRFS and ZFS systems). BTRFS is good for the case of a single disk or a RAID-1 array but I believe that the RAID-5 code for BTRFS is not sufficiently tested for business use. ZFS doesn t perform very well due to the checksums on data and metadata requiring multiple writes for a single change which also causes more fragmentation. This isn t a criticism of ZFS, it s just an engineering trade-off for the data integrity features. ZFS supports read-caching on a SSD (the L2ARC) and write-back caching (ZIL). To get the best benefit of L2ARC and ZIL you need fast SSD storage. So now with my client investigating 10 gigabit Ethernet I have to investigate SSD. For some time SSDs have been in the same price range as hard drives, starting at prices well below $100. Now there are some SSDs on sale for as little as $50. One issue with SATA for server use is that SATA 3.0 (which was released in 2009 and is most commonly used nowadays) is limited to 600MB/s. That isn t nearly adequate if you want to serve files over 10 gigabit Ethernet. SATA 3.2 was released in 2013 and supports 1969MB/s but I doubt that there s much hardware supporting that. See the SATA Wikipedia page for more information. Another problem with SATA is getting the devices physically installed. My client has a new Dell server that has plenty of spare PCIe slots but no spare SATA connectors or SATA power connectors. I could have removed the DVD drive (as I did for some tests before deploying the server) but that s ugly and only gives 1 device while you need 2 devices in a RAID-1 configuration for ZIL. M.2 M.2 is a new standard for expansion cards, it supports SATA and PCIe interfaces (and USB but that isn t useful at this time). The wikipedia page for M.2 is interesting to read for background knowledge but isn t helpful if you are about to buy hardware. The first M.2 card I bought had a SATA interface, then I was unable to find a local company that could sell a SATA M.2 host adapter. So I bought a M.2 to SATA adapter which made it work like a regular 2.5 SATA device. That s working well in one of my home PCs but isn t what I wanted. Apparently systems that have a M.2 socket on the motherboard will usually take either SATA or NVMe devices. The most important thing I learned is to buy the SSD storage device and the host adapter from the same place then you are entitled to a refund if they don t work together. The alternative to the SATA (AHCI) interface on an M.2 device is known as NVMe (Non-Volatile Memory Express), see the Wikipedia page for NVMe for details. NVMe not only gives a higher throughput but it gives more command queues and more commands per queue which should give significant performance benefits for a device with multiple banks of NVRAM. This is what you want for server use. Eventually I got a M.2 NVMe device and a PCIe card for it. A quick test showed sustained transfer speeds of around 1500MB/s which should permit saturating a 10 gigabit Ethernet link in some situations. One annoyance is that the M.2 devices have a different naming convention to regular hard drives. I have devices /dev/nvme0n1 and /dev/nvme1n1, apparently that is to support multiple storage devices on one NVMe interface. Partitions have device names like /dev/nvme0n1p1 and /dev/nvme0n1p2. Power Use I recently upgraded my Thinkpad T420 from a 320G hard drive to a 500G SSD which made it faster but also surprisingly quieter you never realise how noisy hard drives are until they go away. My laptop seemed to feel cooler, but that might be my imagination. The i5-2520M CPU in my Thinkpad has a TDP of 35W but uses a lot less than that as I almost never have 4 cores in use. The z7k320 320G hard drive is listed as having 0.8W low power idle and 1.8W for read-write, maybe Linux wasn t putting it in the low power idle mode. The Samsung 500G 850 EVO SSD is listed as taking 0.4W when idle and up to 3.5W when active (which would not be sustained for long on a laptop). If my CPU is taking an average of 10W then replacing the hard drive with a SSD might have reduced the power use of the non-screen part by 10%, but I doubt that I could notice such a small difference. I ve read some articles about power use on the net which can be summarised as SSDs can draw more power than laptop hard drives but if you do the same amount of work then the SSD will be idle most of the time and not use much power . I wonder if the SSD being slightly thicker than the HDD it replaced has affected the airflow inside my Thinkpad. From reading some of the reviews it seems that there are M.2 storage devices drawing over 7W! That s going to create some cooling issues on desktop PCs but should be OK in a server. For laptop use they will hopefully release M.2 devices designed for low power consumption. The Future M.2 is an ideal format for laptops due to being much smaller and lighter than 2.5 SSDs. Spinning media doesn t belong in a modern laptop and using a SATA SSD is an ugly hack when compared to M.2 support on the motherboard. Intel has released the X99 chipset with M.2 support (see the Wikipedia page for Intel X99) so it should be commonly available on desktops in the near future. For most desktop systems an M.2 device would provide all the storage that is needed (or 2*M.2 in a RAID-1 configuration for a workstation). That would give all the benefits of reduced noise and increased performance that regular SSDs provide, but with better performance and fewer cables inside the PC. For a corporate desktop PC I think the ideal design would have only M.2 internal storage and no support for 3.5 disks or a DVD drive. That would allow a design that is much smaller than a current SFF PC.

David Moreno: Disable Nginx logging

This is something that is specified clearly on the Nginx manual, but it s nice to have it as a quick reference. The access_log and error_log directives on Nginx are on separate modules (HTTP Log and Core modules respectively) and they don t behave the same way when all you want is to disable all logging on your server (in our case, we serve a gazillion static files and perform a lot of reverse proxying and we re not interested on tracking that). It s a common misconception that you can set error_log to off, because that s how you disable access_log (if you do that, the server will still log to the file $nginx_path/off). Instead, you have to set error_log to log to the always mighty black hole /dev/null using the highest level for logging (which triggers the fewest events), crit:
http  
  server  
    # ...
    access_log off;
    error_log /dev/null crit;
    # ...
   
  #...
 
If you re the possessor of the blingest of bling-bling, you can disable all logging (not only for a server block), by putting error_log on the root of the configuration and access_log within your http block and make sure you don t override that on any of the inner blocks. And you re good to go.

Next.

Previous.