Search Results: "tar"

14 December 2020

Jonathan Dowland: git rebasing and lab books

For my PhD work, I've been working on preparing an experimental branch of StrIoT for merging down to the main branch. This has been a long-lived branch (a year!) within which I've been exploring some ideas. Some of the code I want to keep, and some I don't. The history of the experimental branch is consequently messy. Looking it over and considering what a reviewer needs to see, there's a lot of things that are irrelevant and potentially distracting. And so, I've been going through an iterative process of steadily whittling down the history to the stuff that matters: some strings of commits are dropped, others squashed together, and others re-ordered. The resulting branch is a historic fiction. This is common practice. Joey Hess ruminated about it 5 years ago in "our beautiful fake histories", pointing out that the real history is also useful, and perhaps worth preserving. After a recent conversation with my supervisor I realised the situation was analagous to writing a research paper (or a thesis): the process of getting to the conclusion which the thesis documents is messy, with false starts, wrong directions, and plenty of roads-not-travelled. The eventual write-up focusses on the path that lead to the conclusion, and a lot of the side-quest stuff disappears. The "true history" then, is captured elsewhere: in lab books, diaries and the like, and these have their own value. So do my messy exploratory branches, before they've been cleaned up for merging.

Vincent Fourmond: Version 3.0 of QSoas is out

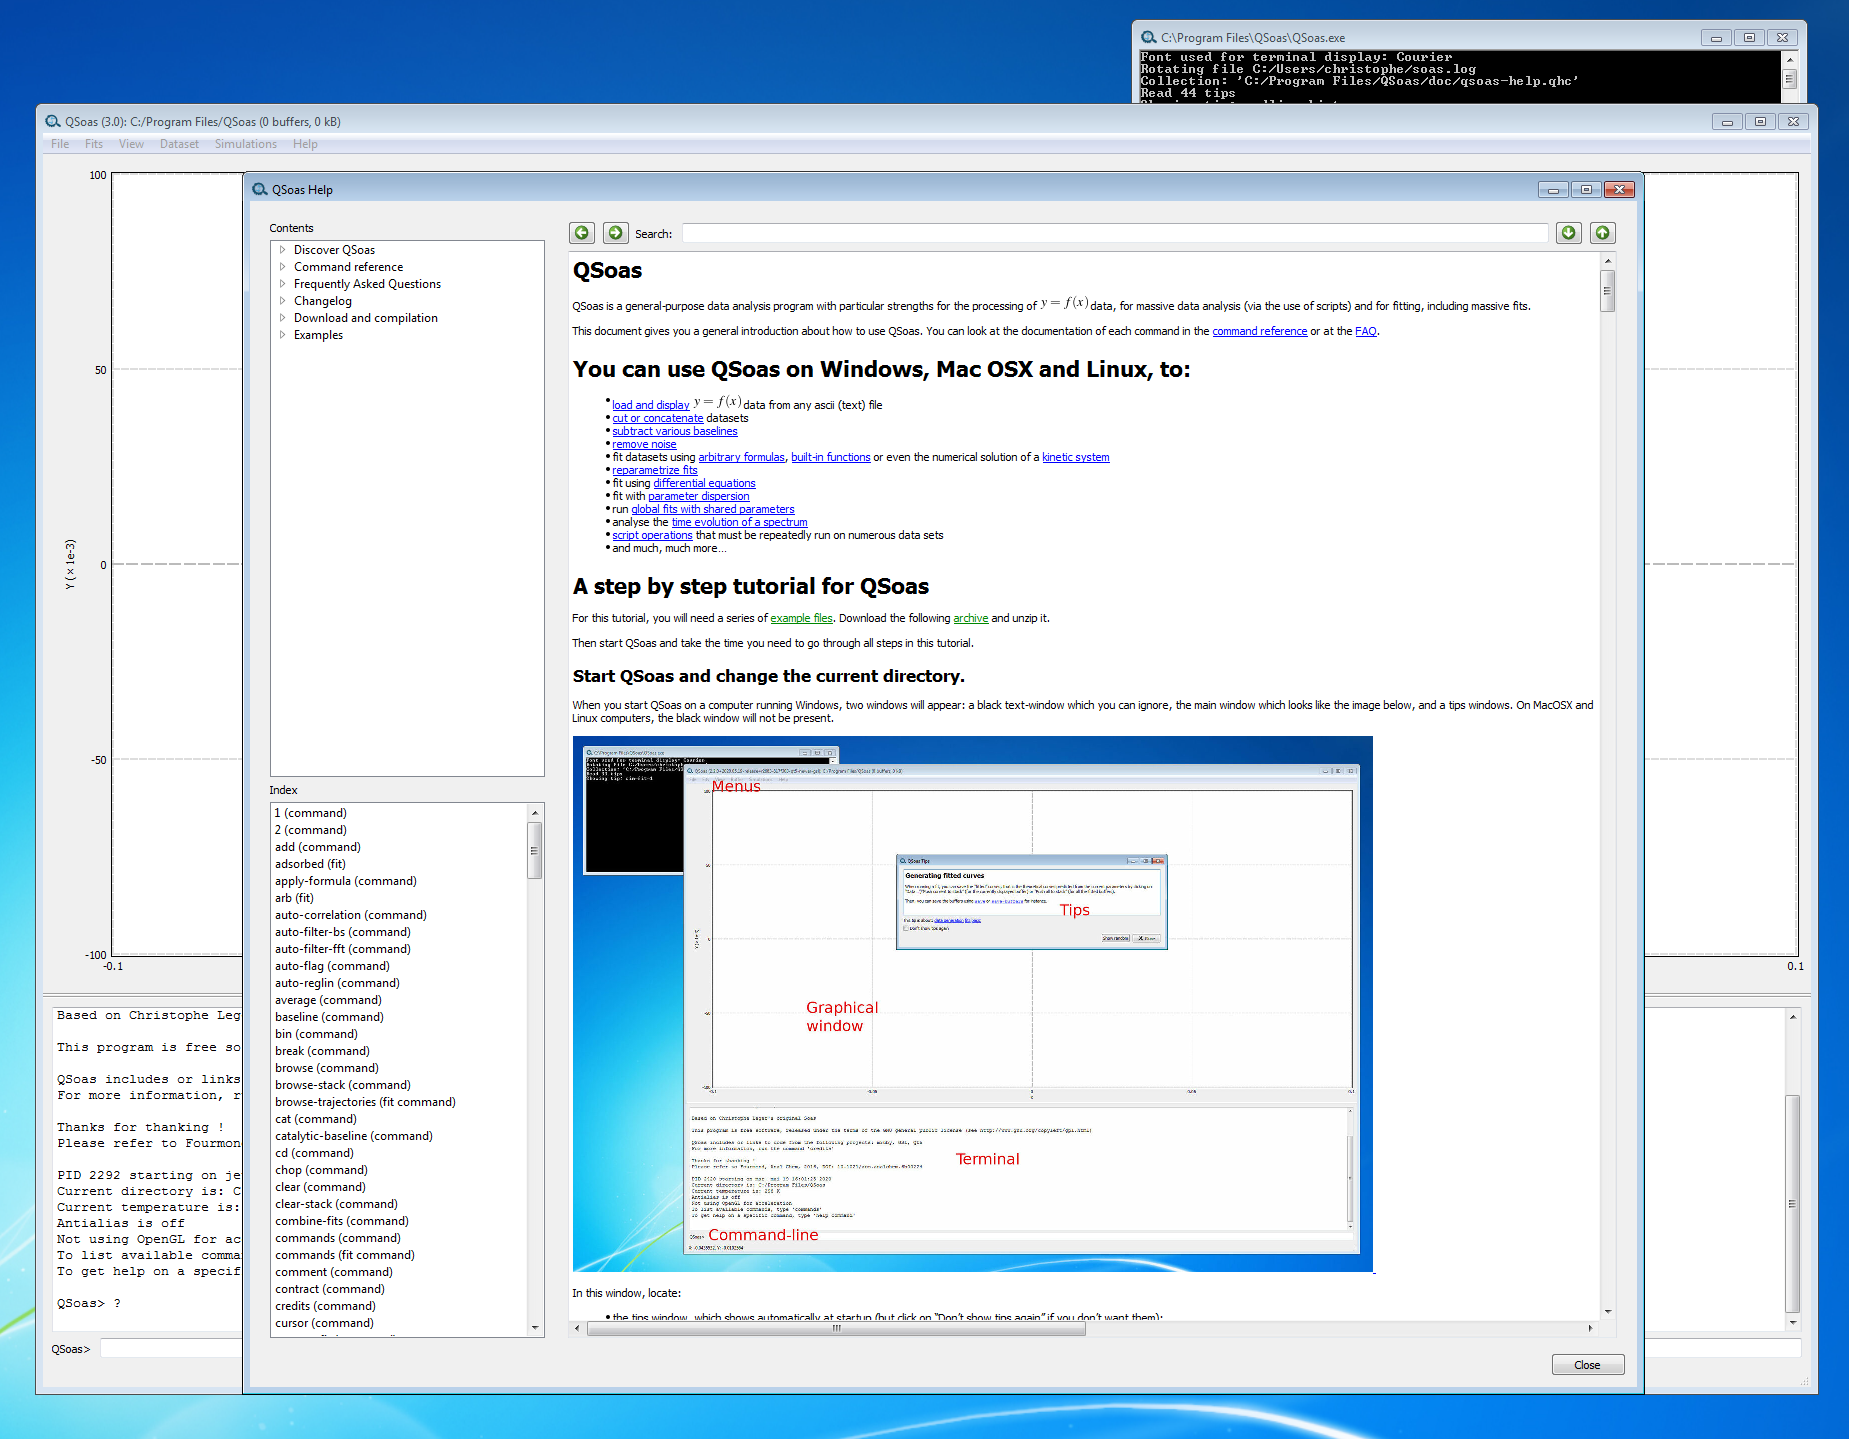
After almost two years of development, version 3.0 of QSoas is finally out ! It brings in a number of new features. An expert mode for fitting Undoubtedly the most important feature in the new version is a complete upgrade of the fit system, which now features an expert mode, turned on by using the /expert=true option with the fit commands. The expert mode features a command prompt that looks like the normal command prompt, in which it is possible: The latter feature is very important when running fits with many parameters. In that case, there are a number of local minima, and it is necessary to try a number of different starting parameters to really find the best parameters. The new parameter space exploration feature makes it much easier than before, with an interface that allows easily finding the best parameters tried so far and reuse them.
A new documentation system Another very important update is the inclusion of a new, offline, documentation system. The documentation features browsing via table of contents, a command index and text search. It also features the possibility to copy commands from the help to the command prompt, or even run them directly. To top it all, it comes with a series of startup tips that might teach you a thing or two about QSoas (try hitting Show random to learn new tricks !).
Many other features For the full list of changes, please see the changelog. Apart from the changes described above, these are my favorites:
To get the new version, you can just download the source code from the downloads page, where you can also purchase precompiled versions for Windows and MacOS. You can also clone the source from the GitHub repository. About QSoasQSoas is a powerful open source data analysis program that focuses on flexibility and powerful fitting capacities. It is released under the GNU General Public License. It is described in Fourmond, Anal. Chem., 2016, 88 (10), pp 5050 5052. Current version is 3.0. You can download its source code there (or clone from the GitHub repository) and compile it yourself, or buy precompiled versions for MacOS and Windows there.

Kunal Mehta: Starting a new job

Last week I officially joined the Site Reliability Engineering team at the Wikimedia Foundation. I'll be working with the Service Operations team, which "...takes care of public and user-visible services." I'm glad to be back at the WMF; I had originally started working there in 2013 but recently took a break to finish school. SRE will be my ninth distinct team at the WMF, and I'm looking forward to even more adventures. As part of transitioning into my new role, I have unsubscribed myself from most MediaWiki bug mail and Gerrit notifications. Once I get more situated I'll put out a more detailed request for new maintainers for the components that need them. I'll continue taking care of maintenance as needed until then. P.S.: I created a new userbox about Rust on mediawiki.org.

Russ Allbery: remctl 3.17

remctl is a simple GSS-API-based RPC system designed to be as trivial to deploy as possible for sites already using Kerberos. I owe various people deeper reviews of remctl feature changes, but alas this release is not that. This is a bit of a stopgap maintenance release primarily to fix a testing problem on Debian that booted remctl out of testing. The basic problem is that a lot of test machinery assumes that every system will have an IPv4 address available, but this is not necessarily true on modern systems. This release only fixes the tests that don't use Kerberos. The tests that require Kerberos have much deeper assumptions that the IPv4 loopback will be available, and will require later work (hampered by the fact that I personally don't have such an environment readily available that also has access to a KDC and need to construct something in Docker or some similar container system). This release also adds support for PHP 8 in anticipation of a possible Debian migration (some minor C source cleanup was required, nothing major), fixes some Python build system problems, and incorporates the changes from rra-c-util 8.4. For future releases, I am considering removing the language bindings from the remctl distribution and distributing them separately as stand-alone tarballs. The primary reason for this is to more easily upload those packages to the respective repositories for those languages (particularly Perl and Python; I don't know how the Ruby and PHP ones work and would need to find out), thus making them available to tools like cpanm and pip as long as the C libraries were already installed. The cost is that someone who wants the C libraries and the extensions will have to download multiple tarballs, and someone (not me) will have to create separate Red hat spec files for the various language bindings. If this would cause problems for you, let me know. It's not likely to happen soon since it would require some major reworking of my web page publication software, but once I finish the prerequisites, I'm likely to adopt this approach unless there are objections. You can get the latest release from the remctl distribution page.

13 December 2020

Jan Wagner: Monitoring Plugins 2.3 released

While our last release has matured for quite a little time, there raised demands within our community for a new release. The development has settled this fall and @sni was already using master for a while in production, so we thought about to release. Anyway Debian Freeze is coming, let's cut a new upstream release! The last question was: Who should cut the release? The last releases was done by @JeremyHolger, but these days everybody is short on time. Fortunately Holger has documented the whole release process very well, so I jumped on the band wagon and slipped into the release wizard role.
Surprisingly it seems I was able to fix all faults I've done in the release process (beside using the 2.2 link in the release announcement mail) and kicked the release of monitoring-plugins 2.3 successfully. Grab the new Monitoring Plugins release while it's hot (and give the new check_curl a try)!
Hopefully monitoring-plugins 2.3 will hit Debian experimental soon.

Russ Allbery: Review: Because Internet

Review: Because Internet, by Gretchen McCulloch
Publisher: Riverhead Books
Copyright: 2019
ISBN: 0-7352-1095-0
Format: Kindle
Pages: 276
If you're familiar with linguistics as a field of scientific study (as opposed to the tool-based fields of grammar or writing advice), you'll be familiar with the dichotomy between written and spoken language. We may spend more time thinking about written language since it is central to most types of education and carries much of the intellectual and social weight of society. Linguists, however, see spoken language as more fundamental, since speech is wired into our brains and universal in human societies. Written language is a recent and somewhat artificial invention. One also learns from linguistics that spoken language does not follow many of the rules of written language that we painstakingly memorized in school. In casual speech, people split infinitives, speak in partial and run-on sentences, ignore nit-picking pronoun case rules, and rarely notice or care about the difference between less and fewer. Spoken language does have rules, but they're more subtle and nuanced than the grammar rules we learn in school. (I think the real fun of linguistics is separating the rules that native speakers follow effortlessly from the artificial rules used as education markers.) This is, in part, because nearly all spoken language is informal, whereas nearly all written language is formal. Enter the Internet, and enter this book. For the first time in human history we have both an explosion of informal writing and easy availability of that writing to linguists for study. Informal writing is not entirely new, of course. We've had personal letters for nearly as long as we've had writing, not to mention private notes, diaries, and other writing intended for tiny audiences. But consider who wrote private letters and, on top of that historical filter, whose private letters were preserved for linguistic research. Until relatively recently, only the upper classes were literate and had access to the infrastructure to write and send letters. Someone's letters or private notes were unlikely to be preserved unless they were someone famous and important, and thus often well-educated and more likely to take a more formal tone in writing. If you compare this to the Internet-driven blizzard of work and personal email, SMS conversations, chatrooms, and social media posts, the difference is obvious in both volume and level of informality. We're all on the Internet, we all read and write with a frequency that would be staggering to the average person from even fifty years ago, and while one may take a bit of additional care with a tricky email to one's manager, the SMS message to one's friend is as informal of a use of language as a conversation over coffee. Gretchen McCulloch is a professional linguist and Because Internet is about exactly this phenomenon: the new conventions of informal writing, how it has changed and evolved, and the new subtleties and shortcuts we've invented to make written communication easier. That goes beyond words and grammar to encompass punctuation, emoji and emoticons, memes and reaction gifs, and even the subtleties of timing, whitespace, and the construction of virtual places via our choices in how and where we write. This topic is my catnip, so it's not surprising I love this book. I've been heavily involved with online communities that communicate in writing since 1993 (making me, in McCulloch's classification, an Old Internet Person; each wave of introduction to the Internet has its own conventions that can be in conflict with later waves). I've now spent more than half my life carrying out most of my social activity and most of my closest friendships primarily in writing, so I found a lot of satisfaction in a linguistic study that takes that seriously rather than treating it as a curiosity. But, even better, I was amazed at how much I didn't know, in part because I am from a specific wave. I have a deep intuition for the Usenet conventions, but not as good of an understanding of the ones from AIM and LiveJournal one wave later (the Full Internet People). And I had a lot to learn about the conventions of the Instagram and Snapchat cluster (the Post Internet People, who have never known life without the Internet). One of the things that struck me while reading this book is how most of the language innovations that McCulloch describes are addressing the old complaint that written communication is inferior to face-to-face conversation because it lacks emotional nuance. My knee-jerk reply is that, no, written communication is full of emotional nuance and the complainer is just bad at reading it, but that's somewhat unfair. A better statement of the problem is that there is not a standardized language for emotional nuance in written communication, in part because it's so new in human history. Most humans are extremely good at reading facial expressions and body language for emotional cues, and those physical expressions are largely subconscious, reliable, and similar among different people (particularly within a culture; one can get in trouble with body language variations across cultures). This is not true of writing. With friends I've talked to over chat for twenty-five years, I can read volumes about their emotional state in a couple of short lines of text. But with strangers, despite decades of Internet communications, I will still misread cues and misinterpret simple intentions. The other standard response to this complaint is that it is possible to put extensive emotional nuance into formal writing. Just get better at writing! This is true, but unhelpful. There's a reason why we give book contracts to people who are very good at investing formal writing with emotional nuance. It's difficult, time-consuming, and requires a great deal of practice. That may be appropriate for formal, paid writing, but it won't do for informal writing, which by definition needs to be as effortless as possible. It's therefore unsurprising that once millions of people were using the Internet regularly for informal writing, they started adding new mechanisms, shortcuts, and conventions for emotional nuance. The standardization is growing, but conventions still vary widely between waves of Internet users. One of the most fascinating parts of this book for me was McCulloch's explanation of why periods (and, to a lesser extent, capital letters) in short chat messages are perceived by younger users as harsh or passive-aggressive. I still have the formal writing mindset of treating proper capitalization and punctuation as a point of pride, but McCulloch makes an excellent argument for letting go of my biases and understanding how and why language is changing. The realization I had while reading this is that many of the changes that look like sloppiness or laziness to someone trained in formal writing have the effect of giving language greater dynamic range. If one always uses periods uniformly, the period becomes meaningless except as a sentence boundary (which is redundant with newlines in most short informal chat messages). If one normally doesn't use it, and then suddenly starts using it, the period can carry semantic weight. It can convey a snippy tone of voice, a note of annoyance, or other subtle shades of meaning. I still use periods in most of my Slack messages because habits are hard to break, but I'm remembering to leave them off some of the time and paying more attention to what emotional weight they're carrying when present. Because Internet is therefore the rare book that meets the bar of changing my day-to-day behavior. "lol" is another excellent example that McCulloch spends some time on. It started life as LOL, an abbreviation for "laughing out loud," and that's still how it's stuck in my head. But, as McCulloch explains, it no longer means that to newer waves of Internet users. It now carries a far more complicated and nuanced meaning that has very little to do with physical laughter and that doesn't easily translate to a single word or sentence. I went from being mildly irritated by and mildly superior towards the ubiquitous "lol" to realizing that it's a fascinating new word that carries primarily emotional nuance and that I don't understand well enough to read or use properly (yet). One more example of the type of analysis McCulloch brings to this book: emoji. The tendency when talking about emoji is to treat them as rebuses (pictures that stand in for a word, or at least a specific concept). They are sometimes used that way, but McCulloch argues that they more often function in the same role that gestures play in informal speech, including the gestures that have no simple name and no independent meaning outside of the context of the words being said at the same time. This seems obvious in retrospect, but before reading Because Internet I had never thought about what a gesture is, what function it plays in speech, and how that could be translated into informal written communication. If you're as interested in this area as I am, this is great stuff. I'd seen several mentions of this book go past on Twitter and kept holding off because I had lots of things to read and was worried it would only cover the superficial things I already knew as a long-time Internet user who has listened to a few lectures on linguistics. That was not the case at all. I learned so much from this book and had a delightful time reading it. If you're also interested in these topics, recommended. Rating: 9 out of 10

12 December 2020

Russell Coker: Electromagnetic Space Launch

The G-Force Wikipedia page says that humans can survive 20G horizontally eyes in for up to 10 seconds and 10G for 1 minute. An accelerator of 14G for 10 seconds (well below the level that s unsafe) gives a speed of mach 4 and an acceleration distance of just under 7km. Launching a 100 metric ton spacecraft in that way would require 14MW at the end of the launch path plus some extra for the weight of the part that contains magnets which would be retrieved by parachute. 14MW is a small fraction of the power used by a train or tram network and brown-outs of the transit network is something that they deal with so such a launch could be powered by diverting power from a transit network. The Rocky Mountains in the US peak at 4.4KM above sea level, so a magnetic launch that starts 2.6KM below sea level and extends the height of the Rocky Mountains would do. A speed of mach 4 vertically would get a height of 96Km if we disregard drag, that s almost 1/4 of the orbital altitude of the ISS. This seems like a more practical way to launch humans into space than a space elevator. The Mass Driver page on Wikipedia documents some of the past research on launching satellites that way, with shorter launch hardware and significantly higher G forces.

Junichi Uekawa: Added multiple windows and a camera angle.

Added multiple windows and a camera angle. Maybe when I am talking and slides haven't started I want to show my face. I probably have a terminal and presentation to show off. So added a way to toggle between the sources. here.

11 December 2020

Evgeni Golov: systemd + SELinux =

Okay, getting a title that will ensure clicks for this post was easy. Now comes the hard part: content! When you deploy The Foreman, you want a secure setup by default. That's why we ship (and enable) a SELinux policy which allows you to run the involved daemons in confined mode. We have recently switched our default Ruby application server from Passenger (running via mod_passenger inside Apache httpd) to Puma (running standalone and Apache just being a reverse proxy). While doing so, we initially deployed Puma listening on localhost:3000 and while localhost is pretty safe, a local user could still turn out evil and talk directly to Puma, pretending to be authenticated by Apache (think Kerberos or X.509 cert auth). Obviously, this is not optimal, so the next task was to switch Puma to listen on an UNIX socket and only allow Apache to talk to said socket. This doesn't sound overly complicated, and indeed it wasn't. The most time/thought was spent on doing that in a way that doesn't break existing setups and still allows binding to a TCP socket for setups where users explicitly want that. We also made a change to the SELinux policy to properly label the newly created socket and allow httpd to access it. The whole change was carefully tested on CentOS 7 and worked like a charm. So we merged it, and it broke. Only on CentOS 8, but broken is broken, right? This is the start of my Thanksgiving story "learn how to debug SELinux issues" ;) From the logs of our integration test I knew the issue was Apache not being able to talk to that new socket (we archive sos reports as part of the tests, and those clearly had it in the auditd logs). But I also knew we did prepare our policy for that change, so either our preparation was not sufficient or the policy wasn't properly loaded. The same sos report also contained the output of semanage fcontext --list which stated that all regular files called /run/foreman.sock would get the foreman_var_run_t type assigned. Wait a moment, all regular files?! A socket is not a regular file! Let's quickly make that truly all files. That clearly changed the semanage fcontext --list output, but the socket was still created as var_run_t?! It was time to actually boot a CentOS 8 VM and try more things out. Interestingly, you actually can't add a rule for /run/something, as /run is an alias (equivalency in SELinux speak) for /var/run:
# semanage fcontext --add -t foreman_var_run_t /run/foreman.sock
ValueError: File spec /run/foreman.sock conflicts with equivalency rule '/run /var/run'; Try adding '/var/run/foreman.sock' instead
I have no idea how the list output in the report got that /run rule, but okay, let's match /var/run/foreman.sock. Did that solve the issue? Of course not! And you knew it, as I didn't get to the juciest part of the headline yet: systemd! We use systemd to create the socket, as it is both convenient and useful (no more clients connecting before Rails has finished booting). But why is it wrongly labeling our freshly created socket?! A quick check with touch shows that the policy is correct now, the touched file gets the right type assigned. So it must be something with systemd A bit of poking (and good guesswork based on prior experience with a similar issue in Puppet: PUP-2169 and PUP-10548) led to the realization that a systemctl daemon-reexec after adding the file context rule "fixes" the issue. Moving the poking to Google, you quickly end up at systemd issue #9997 which is fixed in v245, but that's in no EL release yet. And indeed, the issue seems fixed on my Fedora 33 with systemd 246, but I still need it to work on CentOS 7 and 8 Well, maybe that reexec isn't that bad after all? At least the socket is now properly labeled and httpd can connect to it on CentOS 8. Btw, no idea why the connection worked on CentOS 7, as there the socket was also wrongly labeled, but SELinux didn't deny httpd to open it. Big shout out to lzap and ewoud for helping me with this beast!

Markus Koschany: My Free Software Activities in November 2020

Welcome to gambaru.de. Here is my monthly report (+ the first week in December) that covers what I have been doing for Debian. If you re interested in Java, Games and LTS topics, this might be interesting for you. Debian Games
Debian Java Misc Debian LTS This was my 57. month as a paid contributor and I have been paid to work 12 hours on Debian LTS, a project started by Rapha l Hertzog. In that time I did the following: ELTS Extended Long Term Support (ELTS) is a project led by Freexian to further extend the lifetime of Debian releases. It is not an official Debian project but all Debian users benefit from it without cost. The current ELTS release is Debian 8 Jessie . This was my 30. month and I have been paid to work 15 hours on ELTS. Thanks for reading and see you next time.

10 December 2020

John Goerzen: How the Attention Economy Hurts You via Social Media Sites like Facebook

There is a whole science to manipulating our attention. And because there is a lot of money to be made by doing this well, it means we all encounter attempts to manipulate what we pay attention to each day. What is this, and how is it harmful? This post will be the first on a series on the topic. Why is attention so important? When people use Facebook, they use it for free. Facebook generally doesn t even try to sell them anything, yet has billions in revenues. What, then, is Facebook s product? Well, really, it s you. Or, more specifically, your attention. Facebook sells your attention to advertisers. Everything they do is in service to that. They want you to spend more time on the site so they can show you more ads. (I should say here that I m using Facebook as an example, but this applies to other social media companies too.) Seeking to maximize attention So if your attention is so important to their profit, it follows naturally that they would seek ways to get people to spend more time on their site. And they do. They track all sorts of metrics, including engagement (if you click like , comment, share, or otherwise interact with content). They know which sorts of things are likely to capture your (and I mean you in specific!) attention and show you that. Your neighbor may have different interests and Facebook judges different things are likely to capture their attention. Manipulating your attention Attention turning into money isn t unique for social media. In fact, in the article If It Bleeds, It Leads: Understanding Fear-Based Media, Psychology Today writes:
In previous decades, the journalistic mission was to report the news as it actually happened, with fairness, balance, and integrity. However, capitalistic motives associated with journalism have forced much of today s television news to look to the spectacular, the stirring, and the controversial as news stories. It s no longer a race to break the story first or get the facts right. Instead, it s to acquire good ratings in order to get advertisers, so that profits soar. News programming uses a hierarchy of if it bleeds, it leads. Fear-based news programming has two aims. The first is to grab the viewer s attention. In the news media, this is called the teaser. The second aim is to persuade the viewer that the solution for reducing the identified fear will be in the news story. If a teaser asks, What s in your tap water that YOU need to know about? a viewer will likely tune in to get the up-to-date information to ensure safety.
You ve probably seen fear-based messages a lot on Facebook. They will highlight messages to liberals about being afraid of what Trump is doing, and to conservatives about being afraid of what Biden is doing. They may or may not even intentionally be doing this; it is their algorithm predicts that those would maximize time and engagement for certain people, so that s what they see. Fear leads to controversy It s not just fear, though. Social media also loves controversy. There s nothing that makes people really want to stay on Facebook like anger. See something controversial and you ll see hundreds or thousands of people are there arguing about it and in the process, giving Facebook their attention. A quick Internet search will show you numerous articles on how marketing companes can leverage controvery to get attention and engagement with their campaigns. Consequences of maximizing fear and controversy What does it mean to society at large and to you personally that large companies make a lot of money by maximizing fear and controversy? The most obvious way is it leads to less common ground. If the posts and reactions that show common ground are never seen because they don t drive engagement, it poisons the well; left and right hate each other with ever more vigor a profitable outcome to Facebook, but a poisonous one to all of us. I have had several friendships lost because I a liberal in agreement with these friends on political matters still talk to Trump voters. On the other side, we ve seen people storm the Michigan statehouse with weapons. How did that level of disagreement and even fear behind it get so firmly embedded in our society? Surely the fact that social media shows us things designed to stimulate fear and anger must play a role. What does it do to our ability to have empathy for, and understand, others? The Facebook groups I ve been in for like-minded people have largely been flooded with memes calling the President rump and other things clearly designed to make people angry or fearful. It s a worthless experience, and not just that, but it s a harmful experience. When our major media TV and social networks all are optimizing for fear, anger, and controvesry, we have a society beholden to fear, anger, and controvesy. In my next installment, I m going to talk about what to do about this, including the decentralized social networks of the Fediverse that are specifically designed to put you back in charge of your attention. Update 2020-12-16: There are two followup articles for this: how to join the Fediverse and non-creepy technology purchasing and gifting guides. The latter references the FSF s page on software manipulation towards addiction, which is particularly relevant to this topic.

Jonathan Carter: CentOS Stream, or Debian?

It s the end of CentOS as we know it Earlier this week, the CentOS project announced the shift to CentOS stream. In a nutshell, this means that they will discontinue being a close clone of RHEL along with security updates, and instead it will serve as a development branch of RHEL. As you can probably imagine (or gleam from the comments in that post I referenced), a lot of people are unhappy about this. One particular quote got my attention this morning while catching up on this week s edition of Linux Weekly News, under the distributions quotes section:

I have been doing this for 17 years and CentOS is basically my life s work. This was (for me personally) a heart wrenching decision. However, i see no other decision as a possibility. If there was, it would have been made.Johnny Hughes
I feel really sorry for this person and can empathize, I ve been in similar situations in my life before where I ve poured all my love and energy into something and then due to some corporate or organisational decisions (and usually poor ones), the project got discontinued and all that work that went into it vanishes into the ether. Also, 17 years is really long to be contributing to any one project so I can imagine that this must have been especially gutting.

Throw me a freakin bone here I m also somewhat skeptical of how successful CentOS Stream will really be in any form of a community project. It seems that Red Hat is expecting that volunteers should contribute to their product development for free, and then when these contributors actually want to use that resulting product, they re expected to pay a corporate subscription fee to do so. This seems like a very lop-sided relationship to me, and I m not sure it will be sustainable in the long term. In Red Hat s announcement of CentOS Stream, they kind of throw the community a bone by saying In the first half of 2021, we plan to introduce low- or no-cost programs for a variety of use cases - it seems likely that this will just be for experimental purposes similar to the Windows Insider program and won t be of much use for production users at all. Red Hat does point out that their Universal Base Image (UBI) is free to use and that users could just use that on any system in a container, but this doesn t add much comfort to the individuals and organisations who have contributed huge amounts of time and effort to CentOS over the years who rely on a stable, general-purpose Linux system that can be installed on bare metal.

Way forward for CentOS users Where to from here? I suppose CentOS users could start coughing up for RHEL subscriptions. For many CentOS use cases that won t make much sense. They could move to another distribution, or fork/restart CentOS. The latter is already happening. One of the original founders of the CentOS project, Gregory Kurtzer, is now working on Rocky Linux, which aims to be a new free system built from the RHEL sources. Some people from Red Hat and Canonical are often a bit surprised or skeptical when I point out to them that binary licenses are also important. This whole saga is yet another data point, but it proves that yet again. If Red Hat had from the beginning released RHEL with free sources and unobfuscated patches, then none of this would ve been necessary in the first place. And while I wish Rocky Linux all the success it aims to achieve, I do not think that working for free on a system that ultimately supports Red Hat s selfish eco-system is really productive or helpful. The fact is, Debian is already a free enterprise-scale system already used by huge organisations like Google and many others, which has stable releases, LTS support and ELTS offerings from external organisations if someone really needs it. And while RHEL clones have come and gone through the years, Debian s mission and contract to its users is something that stays consistent and I believe Debian and its ideals will be around for as long as people need Unixy operating systems to run anywhere (i.e. a very long time). While we sometimes fall short of some of our technical goals in Debian, and while we don t always agree on everything, we do tend to make great long-term progress, and usually in the right direction. We ve proved that our method of building a system together is sustainable, that we can do so reliably and timely and that we can collectively support it. From there on it can only get even better when we join forces and work together, because when either individuals or organisations contribute to Debian, they can use the end result for both private or commercial purposes without having to pay any fee or be encumbered by legal gotchas. Don t get caught by greedy corporate motivations that will result in you losing years of your life s work for absolutely no good reason. Make your time and effort count and either contribute to Debian or give your employees time to do so on company time. Many already do and reap the rewards of this, and don t look back. While Debian is a very container and virtualization friendly system, we ve managed to remain a good general-purpose operating system that manages to span use cases so vast that I d have to use a blog post longer than this one just to cover them. And while learning a whole new set of package build chain, package manager and new organisational culture and so on can be uhm, really rocky at the start, I d say that it s a good investment with Debian and unlikely to be time that you ll ever felt was wasted. As Debian project leader, I m personally available to help answer any questions that someone might have if they are interested in coming over to Debian. Feel free to mail leader_AT_debian.org (replace _AT_ with @) or find me on the oftc IRC network with the nick highvoltage. I believe that together, we can make Debian the de facto free enterprise system, and that it would be to the benefit of all its corporate users, instead of tilting all the benefit to just one or two corporations who certainly don t have your best interests in mind.

9 December 2020

Shirish Agarwal: Farm Laws and Too much Democracy

Issues with Farm Laws While I have written about the farm laws a bit sometime back. The issue is still in the nation s eye and that is due to the policies which have been done. I have been reading up on it quite a bit and also have been seeing what has been happening in here and now. The problems are with the three bills themselves which I have shared as below Click to access farmers-produce-trade-and-commerce-promotion-and-facilation-bill.pdf Click to access farmers-empowerment-and-protection-bill.pdf Click to access essential-commodities-bill-2020.pdf Biggest issue with the laws While there are many issues with the laws themselves but for me the biggest issue is that the fundamental right of the farmer to get justice via civil courts has been railroaded. From the laws itself. Standard disclaimer not a lawyer, please consult one for any issues per-se.

Farmers-produce-trade-and-commerce (promotion and facilitation-bill) 2020 Page 4 Chapter 3 Section 8 (1)8. (1) In case of any dispute arising out of a transaction between the farmer and a trader under section 4, the parties may seek a mutually acceptable solution through conciliation by filing an application to the Sub-Divisional Magistrate who shall refer such dispute to a Conciliation Board to be appointed by him for facilitating the binding settlement of the dispute. (2) Every Board of Conciliation appointed by the Sub-Divisional Magistrate under sub-section (1), shall consist of a chairperson and such members not less than two and not more than four, as the Sub-Divisional Magistrate may deem fit.10 (5) If the parties to the transaction under sub-section (1) are unable to resolve the dispute within thirty days in the manner set out under this section, they may approach the Sub-Divisional Magistrate concerned who shall be the Sub-Divisional Authority for settlement of such dispute. (8) Any party aggrieved by the order of the Sub-Divisional Authority may prefer an appeal before the Appellate Authority (Collector or Additional Collector nominated by the Collector) within thirty days of such order who shall dispose of the appeal within thirty days from the date of filing of such appeal. 10. (1) Any person aggrieved by an order under section 9 may, prefer an appeal within sixty days from the date of such order, to an officer not below the rank of Joint Secretary to the Government of India to be nominated by the Central Government for this purpose: Page 6 of the bill. 13. No suit, prosecution or other legal proceedings shall lie against the Central Government or the State Government, or any officer of the Central Government or the State Government or any other person in respect of anything which is in good faith done or intended to be done under this Act or of any rules or orders made thereunder. Page 7 of the bill, 15. No civil court shall have jurisdiction to entertain any suit or proceedings in respect of any matter, the cognizance of which can be taken and disposed of by any authority empowered by or under this Act or the rules made thereunder. Now the same laws have been reiterated for the farmers (Empowerment and Protection) Agreement on Price Assurance and Farm Services Bill, 2020. The problem is that too much power is being put into the hands of the executive. All the three, whether it is SDM (Sub-Divisional Magistrate) , the Appellate Authority or the Government Secretary directly are subservient to the whims and fancies of the Central Govt. They after all get their salaries from the Govt. itself. So there will be no independent oversight to any injustices done to the farmer. The third bill i.e. the Essential Commodities Bill, 2020 does away with stock limits on traders and big players like Adani and Ambani. This means that both these players can take and keep produce at their end thereby forcing consumers like you and me who at the retail end would have to pay higher prices for fruits and vegetables while from the producer they will take at the lowest price possible. While I have shared is just one of the points. That is the reason why even the Supreme Court bar association which almost never takes part in politics has been forced to take sides with the farmers. In many ways, one is forced to remember the Emergency  Update 11/12/20 Came across this article on the wire which tells how everybody s rights, not just the farmer s rights are being shod over. I think it depicts correctly the signs of time to come. While arguing on SM, also came to know about Article 300 (1), thanks to Sachin Kumar which shows multiple instances where Government was sued because somebody was working in official capacity and did mistakes, malafide or otherwise and it was the state who was made to pay. FWIW, today farmers from Maharashtra, my state arrived at Delhi border where they were also kept at bay. I did come across an infographic which shows how the various states have fared. Most tellingly, is the state of Bihar. It was in 2006 (one of the most backward states) where APMC was taken off. While others have tried to paint a flattering picture of Bihar, they have failed to share that in the interim 15 odd years, there hasn t been any sort of infrastructure created for farmers which is the reason it is still the lowest earner. These are the last available figures we have about the farmer s income. From 2014 to 2020 there hasn t been any update.
Situation Assessment Survey of Agricultural Household 2013 Copyright GOI,
This concludes just one portion of the bill. I will take other parts of the bill. I may dwell on some other parts as and when I have the time. A cartoon which depicts the current issue
I stand with farmers Copyright Sanitary Panels
Too much democracy Amitabh Kant Yesterday, the Niti Aayog chief Amitabh Kant remarked that we are too much of a democracy at an event called for Atmanirbhar Bharat which is basically a coinage for import substitution. Whether this is desirable or not I have argued and if needed will re-argue the same later as well. What is and was interesting were the gentleman s context, the media reactions and our overall Democracy Index which has been going downhill for quite some years. Now the gentleman who is the Niti Aayog chief and who is supposed to have the ear of the Prime Minister had opined it in an event organized by Swarajya Magazine (a far-right magazine) known to be Islamophobic and all things undemocratic. It has been a target of defundthehate campaign and with good reason. But that s a different story altogether. His full statement was as below

Tough reforms are very difficult in the Indian context, as we are too much of a democracy but the government has shown courage and determination in pushing such reforms across sectors, including mining, coal, labour and agriculture. Niti Aayog chief. The upper quotation remarks and the statement has been from the article in Indian Express which I have linked to. I have archived it as a pdf just in case the link goes dead. Yesterday, after the statement became viraled, tweets of media houses which shared the tweet suddenly become unavailable. Seems too much democracy, became too little democracy all of a sudden. I think Mr. Amitabh Kant didn t visualize as the opposition as well as most people who are on Twitter to share their opinion on the same. Few examples
Too much Democracy copyright Satish Acharya
Too much democracy Illustration and Copyright Alok
Sterlite protest 13 dead, 100 injured Copyright Business Standard too much democracy
Erosion of Democracy V-dem institute Copyright The Hindu Web Team
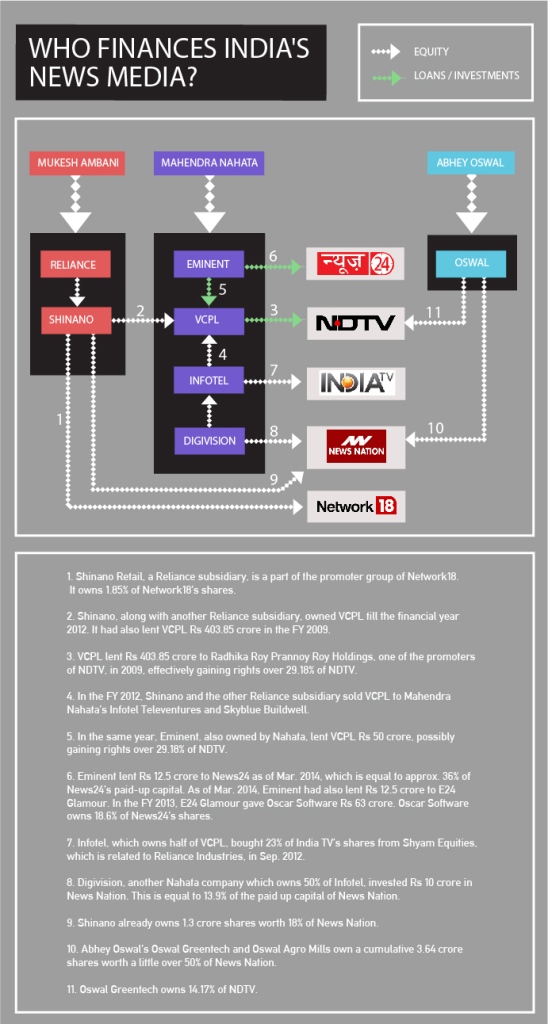
The last one requires a bit more information. This comes from V-Dem Institute which is an independent research institute based out of Department of Political Science, University of Gothenburg, Sweden. I am gonna leave the methods they use for another day as the blog post itself has become rather big/large. Apart from that is the Economists own Democracy Index -2019 Click to access democracy-index-2019.pdf Now for many people, both the V-Dem report and the Economist Index are some sort of attack against India. Doesn t matter that in V-Dem 200+ countries have been taken a variety of indicators and data or the Economist which has data from 150+- countries. Somehow India is supposed to be bigger than all these countries, they do think that other countries data specifically our neighbor China or any other neighbor, those are all accurate. How the dissonance is, has to be gauged from statements of various people. Update 11/12/20 Sadly, the newest V-Dem report marks India as getting into authoritarianism. Gag on Press and Media owners I had shared about the gag on the press especially with respect to western media or reports or anything. This news made its way to straitstimes which normally covers a wide-range of stories covering East Asia vis-a-vis India/South-East Asia. What has also been a big worry that most of the media has been in the hands of a few people. Caravan ran a story on the same in 2016, it has been four years, god only knows what the current situation might be. Any wonder that there is dearth of investigative journalism in India.
India media ownership 2016 Copyright Caravan
Incidentally, a reporter called Akarshan Uppal, who is a reporter on a channel called IBN24 had showecased just few days back how Adani has got land which was shot down for land change use in 2017 to 2020 around 100 acres. There seem to be very less details as to how the land was acquired, whose land it was etc. etc. The reporter was supposedly following a story on drugs on which he was attacked and is now lying in hospital.
Akarshan Uppal Reporter, IBN24 Copyright IBN24
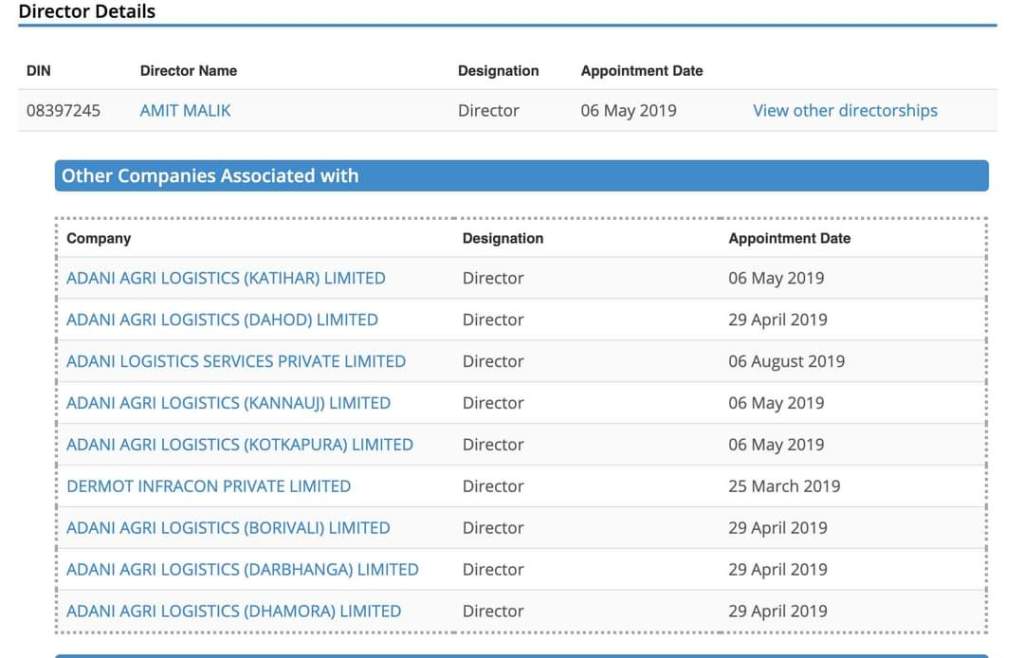
While it would take a whole article/blog post to talk about either Adani or Ambani, in the recent case, the land that has been taken over by Adani is 100 acres and there are private rail lines. And all of this was secret till few days back. The place where these massive godowns/silos have been made are Panipat s Jondhan Kalan and Naultha villages in Haryana. This is Adani AgiLogistics. Almost 7 odd companies have registered and come up in the last couple of years. As can be seen, almost all have come up within the last 2-3 years. Seems to be a lot of coincidence, isn t it?
Personal Anecdote on Data Collection and child marriages in India.

Around 1995 -96 when Internet had started to become a thing in India, there had been quite a few non-profits which were working on various issues. One of those which I initially came in contact with and which I found to be a bit absurd was non-profit which was working in the field of women against Violence. Now it is and was not the concept or the idea which was absurd to me, it was what these women were doing. Instead of the traditional ways in which you counsel women and try and figure out issues, these women were collecting data points from newspapers and magazines. This was way way before data science became a thing in India. They had their own structure where a story about violence against women which would be above the fold would be 5 points, the one below 2.5 points, in inner pages, it would be less and less. Patriarchy at that time was so strong, even today is but at that time it was such, that it felt a waste of time. I did consult them but never said that but did privately feel the above. In hindsight, they were doing the right thing and yet even today crimes against women goes unreported and is suppressed by both State and Central Governments as well as NCRB (National Crime Records Bureau). Interestingly, just few days back, the case against M.J. Akbar by Priya Ramani had taken a back seat and the defamation case by M.J. Akbar was taken forward. Even then, Priya Ramani s counsel s arguments were such that the court wound up in half an hour when they were expecting to do a whole day hearing. The next hearing would be happening today which I will look at in few hours from now. Why Priya Ramani was singled out rather than other tweets may probably be because she is an NRI and most NRI s usually do not want to be part of the bureaucratic Indian court system. This is also the reason that most companies from outside India especially those who are into startups prefer to change ownership, IPR etc. to their own or any country outside India which does make a loss to the exchequer. But this again is a story for another day. At the end, while I did not want to end on a negative note, it seems in many ways status-quo remains. For e.g. 2 years back, a BJP candidate (part of the ruling dispensation) had made a controversy saying that if they win the police won t interfere in child marriages. This is and was in Rajasthan where they have been trying to eradicate it forever. Till date, neither the NHRC (National Human Rights Commission) nor NCW (National Commission for Women) has taken cognizance of the statement. This is our state of democracy.

8 December 2020

Russell Coker: Links December 2020

Business Insider has an informative article about the way that Google users can get locked out with no apparent reason and no recourse [1]. Something to share with clients when they consider putting everything in the cloud . Vice has an interestoing article about people jailbreaking used Teslas after Tesla has stolen software licenses that were bought with the car [2]. The Atlantic has an interesting article titled This Article Won t Change Your Mind [3]. It s one of many on the topic of echo chambers but has some interesting points that others don t seem to cover, such as regarding the benefits of groups when not everyone agrees. Inequality.org has lots of useful information about global inequality [4]. Jeffrey Goldberg has an insightful interview with Barack Obama for the Atlantic about the future course of American politics and a retrospective on his term in office [5]. A Game Designer s Analysis Of QAnon is an insightful Medium article comparing QAnon to an augmented reality game [6]. This is one of the best analysis of QAnon operations that I ve seen. Decrypting Rita is one of the most interesting web comics I ve read [7]. It makes good use of side scrolling and different layers to tell multiple stories at once. PC Mag has an article about the new features in Chrome 87 to reduce CPU use [8]. On my laptop I have 1/3 of all CPU time being used when it is idle, the majority of which is from Chrome. As the CPU has 2 cores this means the equivalent of 1 core running about 66% of the time just for background tabs. I have over 100 tabs open which I admit is a lot. But it means that the active tabs (as opposed to the plain HTML or PDF ones) are averaging more than 1% CPU time on an i7 which seems obviously unreasonable. So Chrome 87 doesn t seem to live up to Google s claims. The movie Bad President starring Stormy Daniels as herself is out [9]. Poe s Law is passe. Interesting summary of Parler, seems that it was designed by the Russians [10]. Wired has an interesting article about Indistinguishability Obfuscation, how to encrypt the operation of a program [11]. Joerg Jaspert wrote an interesting blog post about the difficulties packagine Rust and Go for Debian [12]. I think that the problem is many modern languages aren t designed well for library updates. This isn t just a problem for Debian, it s a problem for any long term support of software that doesn t involve transferring a complete archive of everything and it s a problem for any disconnected development (remote sites and sites dealing with serious security. Having an automatic system for downloading libraries is fine. But there should be an easy way of getting the same source via an archive format (zip will do as any archive can be converted to any other easily enough) and with version numbers.

5 December 2020

Andrew Cater: And the last few architectures are getting done - Debian 10.7 edging ever closer

And we're through the live images as far as we can reasonably go. There remain a couple of MIPS architectures to build and IBM s390x - we have no hardware to test these.It's now 23:30 UTC - so that's 12 1/2 hours since we started and Sledge has another couple of hours to wait before the last images can be signed and the image release can be pushed.Thanks so much to Sledge, RattusRattus, Isy, Schweer and jlsantos - who came back to us after a significant internet outage local to them in California - to those who popped by - hi Kibi and Manty - and to all who labour behind the scenes to make each release "just work"Here's to the next one - in another couple of months, I'm guessing.

Thorsten Alteholz: My Debian Activities in November 2020

FTP master Unfortunately a day only has 24h. As the freeze is approaching, I had to concentrate a bit more on keeping my packages in shape. So this month I only accepted nine packages. The good news, I rejected no package. The overall number of packages that got accepted was 328. Debian LTS This was my seventy-seventh month that I did some work for the Debian LTS initiative, started by Raphael Hertzog at Freexian. This month my all in all workload has been 22.75h. During that time I did LTS uploads of: I also started to work on x11vnc and slirp. Last but not least I did some days of frontdesk duties. Debian ELTS This month was the twenty ninth ELTS month. During my allocated time I uploaded: Unfortunately I also had to give back some hours. Last but not least I did some days of frontdesk duties. Other stuff This month I uploaded new upstream versions of: I fixed one or two bugs in: I improved packaging of: and there have been even some new packages: As it is again this time of the year, I would also like to draw some attention to the Debian Med Advent Calendar. Like the past years, the Debian Med team starts a bug squashing event from the December 1st to 24th. Every bug that is closed will be registered in the calendar. So instead of taking something from the calendar, this special one will be filled and at Christmas hopefully every Debian Med related bug is closed. Don t hesitate, start to squash :-). The announcement on the mailing list can be found here.

Joachim Breitner: Named goals in Coq

TL;DR: Some mildly tricky tricks allow you to select subgoals by name, like in Isabelle. This leads to more readable proofs, and proofs that are more robust against changes.

The need for case names Consider the following Coq proof, right out of the respected Software Foundations book, Chapter Inductively Defined Propositions (and slightly simplified):
Lemma star_app: forall T (s1 s2 : list T) (re : reg_exp T),
  s1 =~ Star re ->
  s2 =~ Star re ->
  s1 ++ s2 =~ Star re.
Proof.
  intros T s1 s2 re H1.
  remember (Star re) as re'.
   generalize dependent s2.
  induction H1.
  - (* MEmpty *) discriminate.
  - (* MChar *) discriminate.
  - (* MApp *) discriminate.
  - (* MUnionL *) discriminate.
  - (* MUnionR *) discriminate.
  - (* MStar0 *)
    injection Heqre' as Heqre''. intros s H. apply H.
  - (* MStarApp *)
    injection Heqre' as Heqre''.
    intros s3 H1. rewrite <- app_assoc.
    apply MStarApp.
    + apply H1_.
    + apply IHexp_match2.
      * rewrite Heqre''. reflexivity.
      * apply H1.
Qed.
This is a very typical example for a proof by induction over an inductively defined relation (in this case, the relations s =~ re which indicates that the string s matches the regular expression re): After some preparation, the invocation of a tactic like induction (could also be inversion or others) creates a number of new goals, one of for each rule of the relation. Then the modern(!) Coq user uses proof bullets to focus the goals, one after another, in order, to solve them. We can see from this example that proof bullets (which were a big improvement) are not quite satisfactory, and the author of this proof felt the need to annotate each subproof with the case it corresponds to. But these are mere comments! This is unsatisfactory, as there is nothing keeping them correct as my proof changes. And anyone who came to Coq from Isabelle is just flabbergasted that the state of art in Coq is still at that level So, wouldn t it be great if
  • I could focus goals by their name (e.g. MEmpty)
  • Focus them in any order (so that refactoring of my data types do not break my proofs)
  • This even worked when simultaneously inducting over or inverting multiple relations?

Simulating named goals in Coq Well, with a few tricks we can! It just takes three simple steps:
  1. I load a small file full of hacks (explained below):
    Require Import NamedCases.
  2. This allows me to prefix the type of the constructors of the inductive relations (i.e. the rules of the relation) with case <name>, , as follows:
    Reserved Notation "s =~ re" (at level 80).
    Inductive exp_match  T  : list T -> reg_exp T -> Prop :=
        MEmpty:
        case empty,
        [] =~ EmptyStr
        MChar:
        case char,
        forall x,
        [x] =~ (Char x)
        MApp:
        case app,
        forall s1 re1 s2 re2
        (H1 : s1 =~ re1)
        (H2 : s2 =~ re2),
        (s1 ++ s2) =~ (App re1 re2)
        MUnionL:
        case union_l,
        forall s1 re1 re2
        (H1 : s1 =~ re1),
        s1 =~ (Union re1 re2)
        MUnionR:
        case union_r,
        forall re1 s2 re2
        (H2 : s2 =~ re2),
        s2 =~ (Union re1 re2)
        MStar0:
        case star0,
        forall re,
        [] =~ (Star re)
        MStarApp:
        case star_app,
        forall s1 s2 re
        (H1 : s1 =~ re)
        (H2 : s2 =~ (Star re)),
        (s1 ++ s2) =~ (Star re)
      where "s =~ re" := (exp_match s re).
    This is the definition from the Software Foundations book; only the case <name>, lines are added.
  3. Now I can change the proof: After the induction tactic I use ; name_cases to name the cases, and then I can use the relatively new named goal focusing feature ([name]: , which I suggested two years ago, and was implemented by Th o Zimmermann) to focus a specific case:
    Lemma star_app2: forall T (s1 s2 : list T) (re : reg_exp T),
      s1 =~ Star re ->
      s2 =~ Star re ->
      s1 ++ s2 =~ Star re.
    Proof.
      intros T s1 s2 re H1.
      remember (Star re) as re'.
       generalize dependent s2.
      induction H1; name_cases.
      [empty]:  
         discriminate.
       
      [char]:  
         discriminate.
       
      [app]:  
         discriminate.
       
      [unionL]:  
         discriminate.
       
      [unionR]:  
        discriminate.
       
      [star0]:  
        injection Heqre' as Heqre''. intros s H. apply H.
       
      [starApp]:  
        injection Heqre' as Heqre''.
        intros s3 H1. rewrite <- app_assoc.
        apply MStarApp; clear_names.
        + apply H1_.
        + apply IHexp_match2.
          * rewrite Heqre''. reflexivity.
          * apply H1.
        
    Qed.
    The comments have turned into actual names!
Goal focusing is now just much more reliable. For example, let me try to discharge the boring cases by using ; try discriminate after the induction. This means there are suddenly only two goals left. With bullets, the first bullet would now suddenly focus a different goal, and my proof script would likely fail somewhere. With named goals, I get a helpful error message No such goal: empty and I can t even enter the first subproof. So let me delete these goals and, just to show off, focus the remaining goals in the wrong order:
Lemma star_app: forall T (s1 s2 : list T) (re : reg_exp T),
  s1 =~ Star re ->
  s2 =~ Star re ->
  s1 ++ s2 =~ Star re.
Proof.
  intros T s1 s2 re H1.
  remember (Star re) as re'.
   generalize dependent s2.
  induction H1; name_cases; try discriminate.
  [starApp]:  
    injection Heqre' as Heqre''.
    intros s3 H1. rewrite <- app_assoc.
    apply MStarApp; clear_names.
    + apply H1_.
    + apply IHexp_match2.
      * rewrite Heqre''. reflexivity.
      * apply H1.
    
  [star0]:  
    injection Heqre' as Heqre''. intros s H. apply H.
   
Qed.
I did not explain the clear_names tactic yet that I had to use after apply MStarApp. What I am showing here is a hack, and it shows these case names are extra hypothesis (of a trivially true type CaseName), and this tactic gets rid of it.

Even better than Isabelle The above even works when there are multiple inductions/inversions involved. To give an example, let s introduce another inductive predicate, and begin proving a lemma that one can do by induction on one and inversion on the other predicate.
Inductive Palindrome  T  : list T -> Prop :=
  EmptyPalin:
  case emptyP,
  Palindrome []
  SingletonPalin:
  case singletonP,
  forall x,
  Palindrome [x]
  GrowPalin:
  case growP,
  forall l x,
  Palindrome l -> Palindrome ([x] ++ l ++ [x])
.
Lemma palindrome_star_of_two:
  forall T (s : list T) x y,
  Palindrome s -> s =~ Star (App (Char x) (Char y)) ->
  s = [] \/ x = y.
Proof.
  intros T s x y HPalin HRe.
  induction HPalin; inversion HRe; name_cases.
At this point we have four open goals. Can you tell why there are four, and which ones they are? Luckily, Show Existentials will tell us their names (and Coq 8.13 will just show them in the proof state window). These names not only help us focus the goal in a reliable way; they even assist us in understanding what goal we have to deal with. For example, the last goal arose from the GrowP rule and the StarApp rule. Neat!
  [emptyP_star0]:  
    left. reflexivity.
   
  [emptyP_starApp]:  
     left. reflexivity.
   
  [singletonP_starApp]:  
    inversion HRe; clear HRe.
    inversion H5; clear H5.
    inversion H10; clear H10.
    inversion H11; clear H11.
    subst.
    inversion H3.
   
 [growP_starApp]:  
    admit. (* I did not complete the proof *)
  

Under the hood (the hack) The above actually works, but it works with a hack, and I wish that Coq s induction tactic would just do the right thing here. I hope eventually this will be the case, and this section will just be curiosity but until, it may actually be helpful.
  1. The trick1 is to leave markers in the proof state. We use a dedicate type CaseName, and a hypothesis name : CaseName indicates that this goal arose from the that case.
    Inductive CaseName := CaseNameI.
    With this, we can write StarApp: forall (starApp : CaseName), to name this case.
  2. For a little bit of polish, we can introduce notation for that:
    Notation "'case' x , t" := (forall  x : CaseName , t) (at level 200).
    This allows us to use the syntax you saw above.
  3. To easily discharge these CaseName assumptions when using the introduction forms, I wrote these tactics:
    Ltac clear_names := try exact CaseNameI.
    Ltac named_constructor  := constructor; [ exact CaseNameI   idtac .. ].
    Ltac named_econstructor := econstructor; [ exact CaseNameI   idtac .. ].
  4. Finally I wrote the tactic name_cases. What it does is relatively simple:
    For each subgoal: Take all hypotheses of type CaseName, concatenate their names, change the name of the current goal to that, and clear these hypotheses
    Unfortunately, my grasp of Coq tactic programming is rather rudimentary, and the only way I manged to solve this is a horrible monster of Ltac2, including hand-rolled imperative implementations of string concatenation and a little nested Ltac1 tactic within. You have been warned:
    From Ltac2 Require Import Ltac2.
    From Ltac2 Require Option.
    Set Default Proof Mode "Classic".
    Ltac name_cases := ltac2:(
      (* Horribly manual string manipulations. Does this mean I should
         go to the Ocaml level?
      *)
      let strcpy s1 s2 o :=
        let rec go := fun n =>
          match Int.lt n (String.length s2) with
            true => String.set s1 (Int.add o n) (String.get s2 n); go (Int.add n 1)
            false => ()
          end
        in go 0
      in
      let concat := fun s1 s2 =>
        let l := Int.add (Int.add (String.length s1) (String.length s2)) 1 in
        let s := String.make l (Char.of_int 95) in
        strcpy s s1 0;
        strcpy s s2 (Int.add (String.length s1) 1);
        s
      in
      Control.enter (let rec go () :=
        lazy_match! goal with
          [ h1 : CaseName, h2 : CaseName  - _ ] =>
          (* Multiple case names? Combine them (and recurse) *)
          let h := concat (Ident.to_string h1) (Ident.to_string h2) in
          Std.clear [h1; h2];
          let h := Option.get (Ident.of_string h) in
          assert ($h := CaseNameI);
          go ()
          [ _ : CaseName  - _ ] =>
          (* A single case name? Set current goal name accordingly. *)
          ltac1:(
            (* How to do this in ltac2? *)
            lazymatch goal with
              [ H : CaseName  - _ ] => refine ?[H]; clear H
            end
          )
          [  - _ ] =>
          Control.backtrack_tactic_failure "Did not find any CaseName hypotheses"
        end
      in go)
    ).
    If someone feels like re-implementing this in a way that is more presentable, I ll be happy to update this code (and learn something along the way
That s all it takes!

Conclusion With some mild hackery, we can get named cases in Coq, which I find indispensable in managing larger, evolving proofs. I wonder why this style is not more common, and available out of the box, but maybe it is just not known well enough? Maybe this blog post can help a bit here.

  1. I have vague recollections of seeing at least parts of this trick on some blog some years ago, and I do not claim originality here.

Junichi Uekawa: Learning WebAudio.

Learning WebAudio. I wanted to make a multi-track recorder before but I couldn't. This morning I am starting with single track audio recording and play back. here is audio record code.

4 December 2020

Russell Coker: ZFS 2.0.0 Released

Version 2.0 of ZFS has been released, it s now known as OpenZFS and has a unified release for Linux and BSD which is nice. One new feature is persistent L2ARC (which means that when you use SSD or NVMe to cache hard drives that cache will remain after a reboot) is an obvious feature that was needed for a long time. The Zstd compression invented by Facebook is the best way of compressing things nowadays, it s generally faster while giving better compression than all other compression algorithms and it s nice to have that in the filesystem. The PAM module for encrypted home directories is interesting, I haven t had a need for directory level encryption as block device encryption has worked well for my needs. But there are good use cases for directory encryption. I just did a quick test of OpenZFS on a VM, the one thing it doesn t do is let me remove a block device accidentally added to a zpool. If you have a zpool with a RAID-Z array and mistakenly add a new disk as a separate device instead of replacing a part of the RAID-Z then you can t remove it. There are patches to allow such removal but they didn t appear to get in to the OpenZFS 2.0.0 release. For my use ZFS on Linux 0.8.5 has been working fairly well and apart from the inability to remove a mistakenly added device I haven t had any problems with it. So I have no immediate plans to upgrade existing servers. But if I was about to install a new ZFS server I d definitely use the latest version. People keep asking about license issues. I m pretty sure that Oracle lawyers have known about sites like zfsonlinux.org for years, the fact that they have decided not to do anything about it seems like clear evidence that it s OK for me to keep using that code.

Dirk Eddelbuettel: #31: Test your R package against bleeding-edge gcc

Welcome to the 31th post in the rapturously rampant R recommendations series, or R4 for short. This post will once again feature Docker for use with R. Earlier this week, I received a note from CRAN about how my RcppTOML package was no longer building with the (as of right now of course unreleased) version 11 of the GNU C++ compiler, i.e. g++-11. And very kindly even included a hint about the likely fix (which was of course correct). CRAN, and one of its maintainers in particular, is extremely forward-looking in terms of toolchain changes. A year ago we were asked to updated possible use of global variables in C code as gcc-10 tightened the rules. This changes is a C++ one, and a fairly simple one of simply being more explicit with include headers. Previous g++ release had done the same. The question now was about the least painful way to get g++-11 onto my machine, with the least amount of side-effects. Regular readers of this blog will know where this is headed, but even use of Docker requires binaries. A look at g++-11 within packages.debian.org comes up empty. No Debian means no Ubuntu. But there is a PPA for Ubuntu with toolchain builds we have used before. And voil there we have it: within the PPA for Ubuntu Toolchain repository is the volatile packages PPA with both g++-10 and g++-11. Here Ubuntu 20.10 works with g++-10, but g++-11 requires Ubuntu 21.04. Docker containers are there for either. So with the preliminaries sorted out, the key steps are fairly straightforward: And that is it! RcppTOML is fairly minimal and could be a member of the tinyverse so no other dependencies are needed if your package has any you could just use the standard steps to install from source, or binary (including using RSPM or bspm). You can see the resulting Dockerfile which contains a minimal amount of extra stuff to deal with some environment variables and related settings. Nothing critical, but it smoothes the experience somewhat. This container is now built (under label rocker/r-edge with tags latest and gcc-11), and you can download it from Docker Hub. With that the proof of the (now fixed and uploaded) package building becomes as easy as
edd@rob:~/git/rcpptoml(master)$ docker run --rm -ti -v $PWD:/mnt -w /mnt rocker/r-edge:gcc-11 g++ --version
g++ (Ubuntu 11-20201128-0ubuntu2) 11.0.0 20201128 (experimental) [master revision fb6b29c85c4:a331ca6194a:e87559d202d90e614315203f38f9aa2f5881d36e]
Copyright (C) 2020 Free Software Foundation, Inc.
This is free software; see the source for copying conditions.  There is NO
warranty; not even for MERCHANTABILITY or FITNESS FOR A PARTICULAR PURPOSE.

edd@rob:~/git/rcpptoml(master)$ 
edd@rob:~/git/rcpptoml(master)$ docker run --rm -ti -v $PWD:/mnt -w /mnt rocker/r-edge:gcc-11 R CMD INSTALL RcppTOML_0.1.7.tar.gz
* installing to library  /usr/local/lib/R/site-library 
* installing *source* package  RcppTOML  ...
** using staged installation
** libs
g++ -std=gnu++11 -I"/usr/share/R/include" -DNDEBUG -I../inst/include/ -DCPPTOML_USE_MAP -I'/usr/lib/R/site-library/Rcpp/include'    -fpic  -g -O2 -fdebug-prefix-map=/build/r-base-Fuvi9C/r-base-4.0.3=. -fstack-protector-strong -Wformat -Werror=format-security -Wdate-time -D_FORTIFY_SOURCE=2 -g  -c RcppExports.cpp -o RcppExports.o
g++ -std=gnu++11 -I"/usr/share/R/include" -DNDEBUG -I../inst/include/ -DCPPTOML_USE_MAP -I'/usr/lib/R/site-library/Rcpp/include'    -fpic  -g -O2 -fdebug-prefix-map=/build/r-base-Fuvi9C/r-base-4.0.3=. -fstack-protector-strong -Wformat -Werror=format-security -Wdate-time -D_FORTIFY_SOURCE=2 -g  -c parse.cpp -o parse.o
g++ -std=gnu++11 -shared -L/usr/lib/R/lib -Wl,-Bsymbolic-functions -Wl,-z,relro -o RcppTOML.so RcppExports.o parse.o -L/usr/lib/R/lib -lR
installing to /usr/local/lib/R/site-library/00LOCK-RcppTOML/00new/RcppTOML/libs
** R
** inst
** byte-compile and prepare package for lazy loading
** help
*** installing help indices
** building package indices
** testing if installed package can be loaded from temporary location
** checking absolute paths in shared objects and dynamic libraries
** testing if installed package can be loaded from final location
** testing if installed package keeps a record of temporary installation path
* DONE (RcppTOML)
edd@rob:~/git/rcpptoml(master)$ 
I hope both the availability of such a base container with gcc-11 (and g++-11 and gfortran-11) as well as a recipe for building similar containers with newer clang version will help other developers. If you like this or other open-source work I do, you can sponsor me at GitHub.

This post by Dirk Eddelbuettel originated on his Thinking inside the box blog. Please report excessive re-aggregation in third-party for-profit settings.

Next.

Previous.