Search Results: "cas"

7 September 2016

Julian Andres Klode: New software: sicherboot

Fork me on GitHub Today, I wrote sicherboot, a tool to integrate systemd-boot into a Linux distribution in an entirely new way: With secure boot support. To be precise: The use case here is to only run trusted code which then unmounts an otherwise fully encrypted disk, as in my setup: screenshot-from-2016-09-06-04-09-52 If you want, sicherboot automatically creates db, KEK, and PK keys, and puts the public keys on your EFI System Partition (ESP) together with the KeyTool tool, so you can enroll the keys in UEFI. You can of course also use other keys, you just need to drop a db.crt and a db.key file into /etc/sicherboot/keys. It would be nice if sicherboot could enroll the keys directly in Linux, but there seems to be a bug in efitools preventing that at the moment. For some background: The Platform Key (PK) signs the Key Exchange Key (KEK) which signs the database key (db). The db key is the one signing binaries. sicherboot also handles installing new kernels to your ESP. For this, it combines the kernel with its initramfs into one executable UEFI image, and then signs that. Combined with a fully encrypted disk setup, this assures that only you can run UEFI binaries on the system, and attackers cannot boot any other operating system or modify parts of your operating system (except for, well, any block of your encrypted data, as XTS does not authenticate the data; but then you do have to know which blocks are which which is somewhat hard). sicherboot integrates with various parts of Debian: It can work together by dracut via an evil hack (diverting dracut s kernel/postinst.d config file, so we can run sicherboot after running dracut), it should support initramfs-tools (untested), and it also integrates with systemd upgrades via triggers on the /usr/lib/systemd/boot/efi directory. Currently sicherboot only supports Debian-style setups with /boot/vmlinuz-<version> and /boot/initrd.img-<version> files, it cannot automatically create combined boot images from or install boot loader entries for other naming schemes yet. Fixing that should be trivial though, with a configuration setting and some eval magic (or string substitution). Future planned features include: (1) support for multiple ESP partitions, so you can have a fallback partition on a different drive (think RAID type situation, keep one ESP on each drive, so you can remove a failing one); and (2) a tool to create a self-contained rescue disk image from a directory (which will act as initramfs) and a kernel (falling back to a vmlinuz file ) It might also be interesting to add support for other bootloaders and setups, so you could automatically sign a grub cryptodisk image for example. Not sure how much sense that makes. I published the source at https://github.com/julian-klode/sicherboot (MIT licensed) and uploaded the package to Debian, it should enter the NEW queue soon (or be in NEW by the time you read this). Give it a try, and let me know what you think.
Filed under: Debian, sicherboot

Reproducible builds folks: Reproducible Builds: week 71 in Stretch cycle

What happened in the Reproducible Builds effort between Sunday August 28 and Saturday September 3 2016: Media coverage Antonio Terceiro blogged about testing build reprodubility with debrepro . GSoC and Outreachy updates The next round is being planned now: see their page with a timeline and participating organizations listing. Maybe you want to participate this time? Then please reach out to us as soon as possible! Packages reviewed and fixed, and bugs filed The following packages have addressed reproducibility issues in other packages: The following updated packages have become reproducible in our current test setup after being fixed: The following updated packages appear to be reproducible now, for reasons we were not able to figure out yet. (Relevant changelogs did not mention reproducible builds.) The following 4 packages were not changed, but have become reproducible due to changes in their build-dependencies: Some uploads have addressed some reproducibility issues, but not all of them: Patches submitted that have not made their way to the archive yet: Reviews of unreproducible packages 706 package reviews have been added, 22 have been updated and 16 have been removed in this week, adding to our knowledge about identified issues. 5 issue types have been added: 1 issue type has been updated: Weekly QA work FTBFS bugs have been reported by: diffoscope development diffoscope development on the next version (60) continued in git, taking in contributions from: strip-nondeterminism development Mattia Rizzolo uploaded strip-nondeterminism 0.023-2~bpo8+1 to jessie-backports. A new version of strip-nondeterminism 0.024-1 was uploaded to unstable by Chris Lamb. It included contributions from: Holger added jobs on jenkins.debian.net to run testsuites on every commit. There is one job for the master branch and one for the other branches. disorderfs development Holger added jobs on jenkins.debian.net to run testsuites on every commit. There is one job for the master branch and one for the other branches. tests.reproducible-builds.org Debian: We now vary the GECOS records of the two build users. Thanks to Paul Wise for providing the patch. Misc. This week's edition was written by Ximin Luo, Holger Levsen & Chris Lamb and reviewed by a bunch of Reproducible Builds folks on IRC.

6 September 2016

Markus Koschany: My Free Software Activities in August 2016

Welcome to gambaru.de. Here is my monthly report that covers what I have been doing for Debian. If you re interested in Android, Java, Games and LTS topics, this might be interesting for you. Debian Android Debian Games Debian Java Debian LTS This was my seventh month as a paid contributor and I have been paid to work 14,75 hours on Debian LTS, a project started by Rapha l Hertzog. In that time I did the following: Non-maintainer uploads QA

5 September 2016

Chris Lamb: How to write your first Lintian check

Lintian's humble description of "Debian package checker" belies its importance within the Debian GNU/Linux project. An extensive static analysis tool, it's not only used by the vast majority of developers, falling foul of some of its checks even cause uploads to be automatically rejected by the archive maintenance software. As you may have read in my recent monthly report, I've recently been hacking on Lintian itself. In particular:

However, this rest of this post will go through the steps needed to start contributing yourself. To demonstrate this I will be walking through submitting a patch for bug #831864 which warns about Python packages that ship .coverage files generated by Coverage.py.
Getting started First, let's obtain the Lintian sources and create a branch for our work:
$ git clone https://anonscm.debian.org/git/lintian/lintian.git
[ ]
$ cd lintian
$ git checkout -b warn-about-dotcoverage-files
Switched to a new branch 'warn-about-dotcoverage-files'
The most interesting files are under checks/*:
$ ls -l checks/   head -n 9
total 1356
-rw-r--r-- 1 lamby lamby  6393 Jul 29 14:19 apache2.desc
-rw-r--r-- 1 lamby lamby  8619 Jul 29 14:19 apache2.pm
-rw-r--r-- 1 lamby lamby  1956 Jul 29 14:19 application-not-library.desc
-rw-r--r-- 1 lamby lamby  3285 Jul 29 14:19 application-not-library.pm
-rw-r--r-- 1 lamby lamby   544 Jul 29 14:19 automake.desc
-rw-r--r-- 1 lamby lamby  1354 Jul 29 14:19 automake.pm
-rw-r--r-- 1 lamby lamby 19506 Jul 29 14:19 binaries.desc
-rw-r--r-- 1 lamby lamby 25204 Jul 29 14:19 binaries.pm
-rw-r--r-- 1 lamby lamby 15641 Aug 24 21:42 changelog-file.desc
-rw-r--r-- 1 lamby lamby 19606 Jul 29 14:19 changelog-file.pm
Note that the files are in pairs; a foo.desc file that contains description of the tags and a sibling foo.pm Perl module that actually performs the checks.

Let's add our new tag before we go any further. After poking around, it looks like files. pm,desc would be most appropriate, so we'll add our new tag definition to files.desc:
Tag: package-contains-python-coverage-file
Severity: normal
Certainty: certain
Info: The package contains a file that looks like output from the Python
 coverage.py tool.  These are generated by python ,3 -coverage during a test
 run, noting which parts of the code have been executed.  They can then be
 subsequently analyzed to identify code that could have been executed but was
 not.
 .
 As they are are unlikely to be of utility to end-users, these files should
 be removed from the package.
The Severity and Certainty fields are documented in the manual. Note the convention of using double spaces after full stops in the Info section.

Extending the testsuite Lintian has many moving parts based on regular expressions and other subtle logic, so it's especially important to provide tests in order to handle edge cases and to catch any regressions in the future. We create tests by combining a tiny Debian package that will deliberately violate our check, along with some metadata and the expected output of running Lintian against this package. The tests themselves are stored under t/tests. There may be an existing test that it would be more appropriate to extend, but I've gone with creating a new directory called files-python-coverage:
$ mkdir -p t/tests/files-python-coverage
$ cd t/tests/files-python-coverage
First, we create a simple package, installing dummy file to trigger the check:
$ mkdir -p debian/debian
$ touch debian/.coverage
$ echo ".coverage /usr/share/files-python-coverage" > debian/debian/install
Note that we do not need a debian/rules file as long as we do not deviate from a "skeleton" debhelper style. We then add the aforementioned metadata to t/tests/files-python-coverage/desc:
Testname: files-python-coverage
Sequence: 6000
Version: 1.0
Description: Check for Python .coverage files
Test-For:
 package-contains-python-coverage-file
and the expected warning to t/tests/files-python-coverage/tags:
$ echo "W: files-python-coverage: package-contains-python-coverage-file" \
      "usr/share/files-python-coverage/.coverage" > tags

When we run the testsuite, it should fail because we don't emit the check yet:
$ cd $(git rev-parse --show-toplevel)
$ debian/rules runtests onlyrun=tag:package-contains-python-coverage-file
[ ]
--- t/tests/files-python-coverage/tags
+++ debian/test-out/tests/files-python-coverage/tags.files-python-coverage
@@ -1 +0,0 @@
-W: files-python-coverage: package-contains-python-coverage-file usr/share/files-python-coverage/.coverage
fail tests::files-python-coverage: output differs!
Failed tests (1)
    tests::files-python-coverage
debian/rules:48: recipe for target 'runtests' failed
make: *** [runtests] Error 1
$ echo $?
1
Specifying onlyrun= means we only run the tests that are designed to trigger this tag rather than the whole testsuite. This is controlled by the Test-For key in our desc file, not by scanning the tags files. This recipe for creating a testcase could be used when submitting a regular bug against Lintian providing a failing testcase not only clarifies misunderstandings resulting from the use of natural language, it also makes it easier, quicker and safer to correct the offending code itself.

Emitting the tag Now, let's actually implement the check:
             tag 'package-installs-python-egg', $file;
          
+        # ---------------- .coverage (coverage.py output)
+        if ($file->basename eq ".coverage")  
+            tag 'package-contains-python-coverage-file', $file;
+         
         # ---------------- /usr/lib/site-python
Our testsuite now passes:
$ debian/rules runtests onlyrun=tag:package-contains-python-coverage-file
private/generate-profiles.pl
.... running tests ....
mkdir -p "debian/test-out"
t/runtests -k -j 9 t "debian/test-out" tag:package-contains-python-coverage-file
ENV[PATH]=[..]
pass tests::files-python-coverage
if [ "tag:package-contains-python-coverage-file" = "" ]; then touch runtests; fi
$ echo $?
0

Submitting the patch Lastly, we create a patch for submission to the bug tracking system:
$ git commit -a -m "c/files: Warn about Python packages which ship" \
      "coverage.py information. (Closes: #831864)"
$ git format-patch HEAD~
0001-c-files-Warn-about-Python-packages-which-ship-covera.patch
and we finally attach it to the existing bug:
To: 831864@bugs.debian.org
Cc: 831864-submitter@bugs.debian.org
Bcc: control@bugs.debian.org
tags 831864 + patch
thanks
Patch attached.
/lamby

Summary I hope this post will encourage at some extra contributions towards this important tool. (Be aware that I'm not a Lintian maintainer, so not only should you not treat anything here as gospel and expect this post may be edited over time if clarifications arise.)

Rapha&#235;l Hertzog: My Free Software Activities in August 2016

My monthly report covers a large part of what I have been doing in the free software world. I write it for my donators (thanks to them!) but also for the wider Debian community because it can give ideas to newcomers and it s one of the best ways to find volunteers to work with me on projects that matter to me. This months is rather light since I was away in vacation for two weeks. Kali related work The new pkg-security team is working full steam and I reviewed/sponsored many packages during the month: polenum, accheck, braa, t50, ncrack, websploit. I filed bug #834515 against sbuild since sbuild-createchroot was no longer usable for kali-rolling due to the embedded dash. That misfeature has been reverted and implemented through an explicit option. I brought the attention of ftpmasters on #832163 since we had unexpected packages in the standard section (they have been discovered in the Kali live ISO while we did not want them). I uploaded two fontconfig NMU to finally push to Debian a somewhat cleaner fix for the problem of various captions being displayed as squares after a font upgrade (see #828037 and #835142). I tested (twice) a live-build patch from Adrian Gibanel Lopez implementing EFI boot with grub and merged it into the official git repository (see #731709). I filed bug #835983 on python-pypdf2 since it has an invalid dependency forbidding co-installation with python-pypdf. I orphaned splint since its maintainer was missing in action (MIA) and immediately made a QA upload to fix the RC bug which kicked it out of testing (this package is a build dependency of a Kali package). django-jsonfield I wrote a patch to make python-django-jsonfield compatible with Django 1.10 (#828668) and I committed that patch in the upstream repository. Distro Tracker I made some changes to make the codebase compatible with Django 1.10 (and added Django 1.10 to the tox test matrix). I added a Debian Maintainer Dashboard link next to people s name on request of Lucas Nussbaum (#830548). I made a preliminary review of Paul Wise s patch to add multiarch hints (#833623) and improved the handling of the mailbot when it gets MIME Headers referencing an unknown charset (like cp-850 , Python only knows of cp850 ) I also helped Peter Palfrader to enabled a .onion address for tracker.debian.org, see onion.debian.org for the full list of services available over Tor. Misc stuff I updated my letsencrypt.sh salt formula to work with the latest version of letsencrypt.sh (0.2.0) I merged updated translations for the Debian Administrator s Handbook from weblate.org and uploaded a new version to Debian. Thanks See you next month for a new summary of my activities.

No comment Liked this article? Click here. My blog is Flattr-enabled.

Dirk Eddelbuettel: Rcpp 0.12.7: More updates

The seventh update in the 0.12.* series of Rcpp just arrived on the CRAN network for GNU R as well as in Debian. This 0.12.7 release follows the 0.12.0 release from late July, the 0.12.1 release in September, the 0.12.2 release in November, the 0.12.3 release in January, the 0.12.4 release in March, the 0.12.5 release in May, and the 0.12.6 release in July --- making it the eleventh release at the steady bi-montly release frequency. Keeping with the established pattern, this is again more of a maintenance release which addresses small bugs, nuisances or documentation issues without adding any major new features. One issue that got to a few people was our casual use of NORET in the definition of Rcpp::stop(). We had (ahem) overlooked that NORET is only defined by R 3.2.0 or later, and several folks trying to build on older releases of R (why?) got bitten. Well, at least we have a new record for most frequently reported bug ... Kidding aside, this is now fixed. Rcpp has become the most popular way of enhancing GNU R with C or C++ code. As of today, 759 packages on CRAN depend on Rcpp for making analytical code go faster and further. That is up by well over fifty packages since the last release in mid-July! We are once again fortunate to have a number of pull request, from first-timers to regulars. James "coatless" Balamuta in particular relentlessly pushed for better documentation and cleanup of numerous dangling issue tickets. Artem Klevtsov also contributed again. Qiang, Kevin and I also got some changes in for the Rcpp Core team. More details are again below.
Changes in Rcpp version 0.12.7 (2016-09-04)
  • Changes in Rcpp API:
    • The NORET macro is now defined if it was not already defined by R itself (Kevin fixing issue #512).
    • Environment functions get() & find() now accept a Symbol (James Balamuta in #513 addressing issue #326).
    • Several uses of Rf_eval were replaced by the preferred Rcpp::Rcpp_eval (Qiang in PR #523 closing #498).
    • Improved Autogeneration Warning for RcppExports (James Balamuta in #528 addressing issue #526).
    • Fixed invalid C++ prefix identifiers in auto-generated code (James Balamuta in #528 and #531 addressing issue #387; Simon Dirmeier in #548).
    • String constructors now set default UTF-8 encoding (Qiang Kou in #529 fixing #263).
    • Add variadic variants of the RCPP_RETURN_VECTOR and RCPP_RETURN_MATRIX macro when C++11 compiler used (Artem Klevtsov in #537 fixing #38).
  • Changes in Rcpp build system
    • Travis CI is now driven via run.sh from our fork, and deploys all packages as .deb binaries using our PPA where needed (Dirk in #540 addressing issue #517).
  • Changes in Rcpp unit tests
    • New unit tests for random number generators the R namespace which call the standalone Rmath library. (James Balamuta in #514 addressing issue #28).
  • Changes in Rcpp Examples:
    • Examples that used cxxfunction() from the inline package have been rewritten to use either sourceCpp() or cppFunction() (James Balamuta in #541, #535, #534, and #532 addressing issue #56).
Thanks to CRANberries, you can also look at a diff to the previous release. As always, even fuller details are on the Rcpp Changelog page and the Rcpp page which also leads to the downloads page, the browseable doxygen docs and zip files of doxygen output for the standard formats. A local directory has source and documentation too. Questions, comments etc should go to the rcpp-devel mailing list off the R-Forge page.

This post by Dirk Eddelbuettel originated on his Thinking inside the box blog. Please report excessive re-aggregation in third-party for-profit settings.

4 September 2016

Iustin Pop: Usefulness of real-time data during cycling

Wow, a mouthful of a title, for a much simpler post. Up until earlier this year, I had only one sport GPS device, and that was a watch. Made sense, as my "main" sport was running (not that I did it very consistently). Upgraded over a few generations of Garmins, I mainly used it to record my track and statistics (pace, heart rate, etc.) The newest generation of watch and heart rate monitor even give more statistics (left-right leg balance, ground contact time, so on). Most of this data can be looked at while running, but only as an exception; after all, it's very hard to run with one hand up in front of your face. The other useful features guided workouts and alerts during normal runs I've used, but not consistently. So when I started biking a bit more seriously, I wondered whether it would make sense to buy a bike computer. The feature intersection between watch and bike GPS is quite large, so clearly this is a "want" not a "need" by far. Reading forum posts showed the same question repeated multiple times What convinced me to nevertheless buy such a bike GPS were the mapping/routing features. A bike GPS with good routing features, or even just maps on which tracks can be overlayed, can certainly ease the discovery of new routes. After a few months of use, my most useful feature is one that I didn't expect. While the mapping is useful and I do use it, the one that actually is significantly better than my watch is the large display with data fields that I can trivially check almost continuously on road biking, and during technically easy climbing sections for mountain biking. My setup looks like this: It's a 9-field setup; the Edge 1000 can go to 10, but I like "headline" field. The watch can only go to four, and is basically not usable during rides, unless one would use a quick-release kit for mounting on the handle bar. This setup allowed me to learn much better my physical capabilities, why I sometimes run out of energy, and how the terrain affects me. Random things that I learned: Seeing all this data only after the ride is less useful since you don't remember exactly how you felt during specific points in the ride. But as real-time data, one can easily see/feel the correlation between how the body feels and what data says. One thing that would be also useful would be real-time power data (3 sec average, not instantaneous) to correlate even better with the body state. I now use heart rate and cadence as a proxy for that, but being able to see actual power numbers would increase the usefulness of the data even more. Unfortunately, none of these makes the climbs easier. But at least it allows me to understand why one climb feels hard and another easy (relatively speaking). I wonder if, and how this could be applied to running; maybe with smart glasses? Conclusion: yes, I do recommend a bike computer with a large display (to be able to see many fields at once). Just in case one has disposable income at hand and doesn't know which hobby to spend it on ;-)

Steinar H. Gunderson: Multitrack audio in Nageru 1.4.0

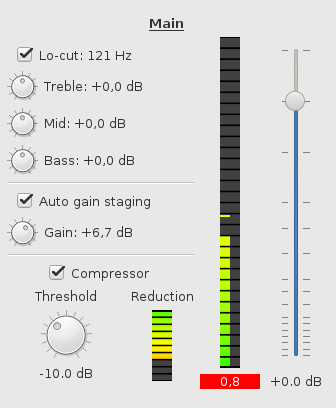
Even though the Chess Olympiad takes some attention right now, development on Nageru (my live video mixer) has continued steadily throughout since the 1.3.0 release. I wanted to take a little time to talk about the upcoming 1.4.0 release, and why things are as they are; writing down things often make them a bit clearer. Every major release of Nageru has had a specific primary focus: 1.0.0 was about just getting everything to work, 1.1.0 was about NVIDIA support for more oomph, 1.2.0 was about stabilization and polish (and added support for Blackmagic's PCI cards as a nice little bonus), and 1.3.0 was about x264 integration. For 1.4.0, I wanted to work on multitrack audio and mixing. Audio has always been a clear focus for Nageru, and for good reason; video is 90% about audio, and it's sorely neglected in most amateur productions (not to mention that processing tools are nearly non-existant in most free or cheap software video mixers). Right from the get-go, it's had a chain with proper leveling, compressors and most importantly visual monitoring, so that you know when things are not as they should be. However, it was also written with an assumption that there would be a single audio input source (one of the cameras), and that's going to change. Single-input is less of a showstopper than one'd think at first; you can work around it by buying a mixer, plug everything into that and then feed that signal into the computer. However, there are a few downsides: If you want camera audio, you'll need to pull more cable from each camera (or have SDI de-embedders). Your mixer is likely to require an extra power supply, and that means yet more cable (any decent USB video card can power over USB, so why shouldn't your audio?). You'll need to buy and transport yet another device. And so on. (If you already have a PA mixer, of course you can use it, but just reusing the PA mix as a stream mix rarely gives the best results, and mixing on an aux bus gives very little flexibility.) So for 1.4.0, I wanted something to get essentially the processing equivalent of a mid-range mixer. But even though my education is in DSP, my experience with mixers is rather limited, so I did the only reasonable thing and went over to a friend who's also an (award-winning) audio engineer. (It turns out that everything on a mixer is the way it is for a pretty good reason, tuned through 50+ years of collective audio experience. If you just try to make up something on your own without understanding what's going on, you have a 0.001% chance of stumbling upon some genius new way of doing things by accident, and a significantly larger chance than that of messing things up.) After some back and forth, we figured out a reasonable set of basic tools that would be useful in the right hands, and not too confusing for a beginner. So let's have a look at the new controls you get: Nageru expanded audio control view There's one set of these controls for each bus. (This is the expanded view; there's also a compact view that has only the meters and the fader, which is what you'll typically want to use during the run itself the expanded view is for setup and tweaking.) A bus in Nageru is a pair of channels (left/right), sourced from a video capture or ALSA card. The channel mapping is flexible; my USB sound card has 18 channels, for instance, and you can use that to make several buses. Each bus has a name (here I named it very creatively Main , but in a real setting you might want something like Blue microphone or Speaker PC ), which is just for convenience; it doesn't mean much. The most important parts of the mix are given the most screen estate, so even though the way through the signal chain is left-to-right top-to-bottom, I'll go over it in the opposite direction. By far the most important part is the audio level, so the fader naturally is very prominent. (Note that the scale is nonlinear; you want more resolution in the most important area.) Changing a fader with the mouse or keyboard is possible, and probably most people will be doing that, but Nageru will also support USB faders. These usually speak MIDI, for historical reasons, and there are some UI challenges when they're all so different, but you can get really small ones if you want to get that tactile feel without blowing up your budget or getting a bigger backpack. Then there's the meter to the left of that. Nageru already has R128 level meters in the mastering section (not shown here, but generally unchanged from 1.3.0), and those are kept as-is, but for each bus, you don't want to know loudness; you want to know recording levels, so you want a peak meter, not a loudness meter. In particular, you don't want the bus to send clipped data to the master (which would happen if you set it too high); Nageru can handle this situation pretty well (unlike most digital mixers, it mixes in full 32-bit floating-point so there's no internal clipping, and there's a limiter on the master by default), but it's still not a good place to be in, so you can see that being marked in red in this example. The meter doubles as an input peak check during setup; if you turn off all the effects and set the fader to neutral, you can see if the input hits peak or not, and then adjust it down. (Also, you can see here that I only have audio in the left channel; I'd better check my connections, or perhaps just use mono, by setting the right channel on the bus mapping to the same input as the left one.) The compressor (now moved from the mastering section to each bus) should be well-known for those using 1.3.0, but in this view, it also has a reduction meter, so that you can see whether it kicks in or not. Most casual users would want to just leave the gain staging and compressor settings alone, but a skilled audio engineer will know how to adjust these to each speaker's antics (some speak at a pretty even volume and thus can get a bit of headroom, while some are much more variable and need tighter settings). Finally (or, well, first), there's the EQ section. The lo-cut is again well-known from 1.3.0 (the cutoff frequency is the same across all buses), but there's now also a simple three-band EQ per bus. Simply ask the speaker to talk normally for a bit, and tweak the controls until it sounds good. People have different voices and different ways of holding the microphone, and if you have a reasonable ear, you can use the EQ to your advantage to make them sound a little more even on the stream. Either that, or just put it in neutral, and the entire EQ code will be bypassed. The code is making pretty good progress; all the DSP stuff is done (save for some optimizations I want to do in zita-resampler, now that the discussion flow is started again), and in theory, one could use it already as-is. However, there's a fair amount of gnarly support code that still needs to be written: In particular, I need to do some refactoring to support ALSA hotplug (you don't want your entire stream to go down just because an USB soundcard dropped out for a split second), and similarly some serialization of saving/loading bus mappings. It's not exactly rocket science, but all the code still needs to be written, and there are a number of corner cases to think of. If you want to peek, the code is in the multichannel_audio branch, but beware; I rebase/squash it pretty frequently, so if you pull from it, expect frequent git breakage.

3 September 2016

Iustin Pop: Nationalpark Bike Marathon 2016

Nationalpark Bike Marathon 2016 report: gravity rules! "Marathon" is a bit of a misnomer, since I did the short route, not the medium nor the long one. But hey, it's the official name! Setup This race has four possible lengths: "Valader" which is full round-trip Scuol-Scuol (137km/4'026m), "Jauer" (Fuldera-Scuol, 103km/2'934m), "Livignasco" (Livigno-Scuol, 66km/1'871m) and "Put r" (S-chanf to Scuol, 47Km/1'051m). After many debates, I settled on the Livignasco route, as that was what I was reasonably confident to be able to do. The only problem was that this route (and all the longer ones, of course) were going over Pass Chaschauna, which is a quite hard climb. My bike shop person, who did the full length a number of times, just said when hearing the route I was planning: "Chaschauna is a bitch " Bad language, proper characterisation. The route choice also impacts the logistics: except for the full route, the question is where to sleep the night before? One can sleep either at the start place, or sleep in Scuol itself and take the official shuttle to the start place, but this means waking up much earlier. I decided to sleep in Livigno, as with a 7:45 start this would allow me to sleep until ~6:30, have a quick breakfast and be in time for the race. Problem #1 So on Friday (26th) I drove to Scuol, picked up my start number, and then drove over to Livigno and checked in to the hotel. Speaking of picking up the start number, I saw this at the start area: While picking up my start number: the race is so fast that an STI is needed as pacer?? An STI needed as pacer? How fast are these people, I wondered? Day of the race My plan to have a relaxing sleep until relatively late failed. I went to sleep with difficulties: late dinner due to my late arrival in Livigno, and then I was stressed enough about not missing the race that at 05:05 I already woke up, and was checking the clock every five minutes. Finally at 05:30 I gave up and got out of bed, with only about 6 hours of sleep. Problem #2. The other problem was that I na vely thought the hotel will have breakfast from 07:00 or even 07:30. Hah, as if this was Switzerland. The hotel had breakfast from 08:00, no reason to hurry, right? So I had a poor man's breakfast in the room, some energy bars and an ice tea. Problem #3. At least I had time to grab this picture from the hotel room: Good morning Livigno! Not bad. On to the race! But before that, remember to fill my hydration pack with 3L of water, and put it in my not-so-light backpack. Of course I had tools and some spare parts with me, what if something happens? Problem #4, over-planning. The race The setup at the start was pretty easy. Wait near the start until 07:45, then go. For me, not too in front, of course: Ready for the start! Pass Chaschauna About 3 kilometres of easy/flat road, and then it starts. Pass Chaschauna, killing your legs softly Already climbing  on foot! But not everybody. But at least the pictures were nice! The climb is hard, but the view is worth it! Still climbing So high already! Good legs :) Looking back: it's been a loong way up I can see the top!  and the remaining steep meters to climb :( The climb is difficult. It was around 22% for most of the time, and very few people were able to bike up. Not only the absolute meters were the problem, but also the fact that the ground was quite loose, and pushing the bike, or rather climbing up while pushing the bike, was difficult to do in bike shoes with cleats. Proper hiking shoes would have been much more adequate. Maybe this is why despite the effort, some people biked as much as possible? I was careful not to over-exert myself and walked almost all the way up. Hence the pictures But at last, reached the top of the pass, and was very happy to be done with it. The GPX file from my Garmin says it took only 4 minutes (1.2km) after the race start to actually start climbing (it was not obvious we were climbing so early), and then 1h:20m/8Km to get from 1'817m altitude to the highest point at 2'658m. 8Km in 1h:20m, faster than walking pace but quite slower than running pace (on flat terrain, of course). At the top of the pass I was quite happy: Finally at the top! Clipping in and Go! Smilling and happy! And then the descent started: I wonder how steep it will be going down This was an easy section :/ All the way leading to the race I kept thinking only about climbing Chaschauna, and not about going down on it. It was quite an experience, which I won't forget soon. The trail was already well travelled, which means that besides the loose ground in form of large clumps of dried earth, there was a layer of fine, somewhat moist earth, about 3-5 centimetres deep, which made the downhill "interesting". Coupled with what was a much steeper trail than going up I saw most of the time ~33% it's no surprise that many, or even most, of the people were walking their bikes down. The GPX track says that the trail goes 319m down in 1Km (so a 31.9% over one entire kilometre), then another 130m over the next 1.4Km (9.28%), and then (not sure if this is the pass per se or after) another longer segment of ~260m over 3Km (8.56%). The first steep segment needs lots of skill and concentration, the others are normal gradients. But at least things go fast. What took uphill took ~40 minutes for the last 450m up, downhill it took only 15 minutes! Falling I was able, thanks to recent training, to bike down the trail, or at least I thought so. So on the steep segment I was struggling to bike down and keep control of my bike, putting one leg down on some sections but in general being "on the bike", being hit by the dirt I was throwing in the air despite the mud-guards, being careful but at the same time enjoying this difficult section. That is, right up to the point where I got, I think, too comfortable. After the second-to-last curve, the rear wheel slides, I lose balance and fall in the (thankfully soft) dirt a bit more forcefully than I should have, the bike also sliding along in the dirt. No damage to myself, just some trivial scratches; the bike seems a bit shaken (fork was turned 180 , full of dirt, etc.). I get again on the bike and I continue down; however, something seems off: the rear brake level doesn't have a return anymore, I have to push it to go back. Still usable, but strange. So I continue the other two segment of this descent, and over these ~4-5Km I feel the brake issue going worse and worse: it's actually hard to push the brake lever back, and even pressing it doesn't seem to have much effect. And then the realisation dawns on my: I have hydraulic brakes, and the worsening thing leads me to think my brake hose has been punctured (by what? I fell in loose dirt) and I'm losing the brake fluid with every press. Now, on flat road, biking with only the front brake is tricky but doable. On an MTB course, having only one brake is not a smart thing . Not easy, not smart, and definitely dangerous. It also felt very strange to not have both brakes, and then I realised how much I work with the brakes in unison. I knew that there are repair posts in the race, but I didn't know if they can fix such things (and doing a brake fluid refill how complicated is it, how much time does it take?). Anyway, I resolved to try and continue if the terrain allows until I reach the first repair post, and stop if it gets too steep. It would be pretty sad to have to abort the race after only 10Km, right? The terrain did cooperate: up and down, so I was able to bleed speed easily, and even though through forest, the visibility was good enough that I could plan ahead. It was strangely lonely at this time: I was going slowly and thus not reaching from behind anyone, but also not being reached by riders from behind. I did enjoy it a bit, the quietness of the forest, just interrupted by the squeaking of my front brake And then I finally see the sign for "Repair: 1Km". Yaaay! maybe I don't have to quit the race. And then, about 100m further on, another sign: "Danger! Steep descent". Uh-oh tantalisingly close Let's go slow. And yes, here I was overtaken by 3-4 other cyclists. This was the single moment in the race where I did have a moment of real fear: at one point, I was going down with the remaining brake as pressed as I could without compromising stability, and I was still gaining speed. Not smart, and as I was debating how to fall to stop my descent, the terrain started to get less steep, and I finally reached the repair station, at kilometre 21. Difficult repairs There was another person being serviced for a flat rear tire, so I wait in line and discuss with him my problem. Upon hearing I only had the front brake, he said: "Wow, how did you manage to descend this last segment?" "Well, slowly ". My turn came up, I explain my problem and my theory, and the repair guy gives me one look, the bike one look, but doesn't look at the brake hose. Instead, he looks once at the brake lever, sees that another cable guide on my handle bar was bent during the fall and actually was mechanically interfering with the brake lever, unbends that thing, and says "here you go". I was stunned. 15 seconds of looking at the problem without stress, and the problem was solved. I could have done this myself if I took the time to look and think, and not hurry. And I could have enjoyed all the downhill on the pass, with two functioning brakes. Some lessons have to be learned the hard way, and this was one. I got off easy though, as I didn't have a real accident while biking with only one brake. And they say you get wiser as you get older Anyway, brake repaired, I stopped at the Sanit r tent to have my scratches disinfected, and onwards. The following few kilometres until S-chanf I enjoyed very much. S-chanf And then, 2 hours 10 minutes into the race, I exit the forest trail, reach S-chanf, and start climbing and descending and climbing and descending. In the sun, which now (after 10 AM) is not that light anymore. The initial climb at S-chanf, while not much, took away my remaining short-term reserves. The route is 50m ascent, then down and then another 50m ascent, and after a bit of flat another 75m ascent I was getting tired, despite eating energy bars and drinking water (and juice at stops). This goes one for an entire hour, during which I cover about 23Km, so not a bad speed everything considered. But getting more and more tired. There were also some very nice segments, along the river, in the shade of the forest. Some fast downhill, some fast flat. I got overtaken by quite a few real racers, that were going so fast I couldn't keep up with them as in I didn't dare ride that fast even when I had the energy. Clearly they were from the longer segments, and boy were they fast! A number of couples (or pairs?) one woman one man, a number of bigger groups, all going as if they had E-bikes or super-powers, not just biking along tired like me Last climb And then, the last big climb: half an hour of going about 300m up (absolute values, so cumulative number would probably be higher), in the sun, over about 6Km, so only 5% average gradient. But I was tired and even resorted to walking on some portions At least I could take some pictures again: Much later, climbing again. Or have pictures taken: A bit of a smile left. Yes, that's a smile, not a grimace! Nice views: Look, nice castle! Stopping for a picture, and not because I was *dead tired* :) At one point, in a bit of a shade, I stop to catch my breath. Somebody else stopped as well and, seeing as I was checking my GPS, asks: I got overtaken by a lot of cyclists here, although many of them were from S-chanf route (based on the number colour). Sad The thing is, besides the climbing and the sun, this and the previous part was a very nice route: through small towns, high above the valley, beautiful landscapes, etc. Just enjoying it was hard, since I wasn't a) trained well enough and b) prepared well enough. Last segment, last downhill In any case, after that hard half hour, it's flat (or rather said, average gradient zero): Flat route, good pavement. Can catch my breath, and take a another picture. Good road, good views, but I'm on the last virtual bar of my battery, so the remaining 15Km I do in 40 minutes, also "eating" the last ascent meters still about 300 left, I think, but up/down/up/down, so you could reuse kinetic energy to gain potential one. The only question I had now was, the route was at this moment about 400m higher (in absolute altitude) than the finish point, so when do we lose that altitude? The answer was a very very nice answer: in the last 5Km, for an average gradient of 8%, just perfect. I was tired however, so I couldn't really enjoy or go fast here, but it was a good feeling. Finish! And then, entering Scuol, not really believing I'm near the finish, that I will be able to actually stop and relax. My finish picture doesn't do justice to how happy I was at that moment: At the finish, happy happy happy! However, after passing the finish line, it was a bit weird. I just stop now? What next? So weird to just walk, not push pedals, and not go up. Or down. The funny thing here was that I thought I didn't use much of my water (hydration pack) during the race. But soon after finishing, I drank the equivalent of about two glasses (let's say 0.5L) and it was over. So I did manage to drink 2.5L during the race, plus the sport drinks at the stops. Time for stats: my Garmin says 67.07Km, 4h:29m, average speed 15.0kph (hah), 1'615m elevation gain. Official numbers say 66Km, 1'871m elevation, and thus 14.22kph. Ranking-wise: Sigh, could have done better. I was aiming for somewhere around last 33%, not last 25% :-P First classed was ~66% faster than me Going to the train station was hard as in difficult to move my legs. Took one nice picture of Scuol though, so was able to think a bit: After the race: Scuol is not so bad And then the long way back to Livigno. Took me 4 h to bike to Scuol, and about 3 hours to go back via public transport. At least I ate a sandwich in the meantime. Then reached Livigno, which was also looking nice: Took me almost as long by public transport as by bike, but finally back in Livigno. Also nice! Then got on my bike, which at this point was magically light and easy to ride (it seems I was at least partially recovered), rode to the hotel, packed my stuff, and drove home. On the highway I had my first real meal for that day, but I was quite tired so didn't feel like the achievement it should have been Lessons The biggest takeaway from this race was the huge learning experience I got. The race was itself awesome, but the learning even more so. First, for this particular race, it's much better to sleep in Scuol and (if not doing the whole route) take the shuttle to the actual start. Yes, one has to wake up earlier, but you have assured breakfast via the organisers (++++!), and after the race you don't have to get even more tired by taking the train and the bus and Second, I need better logistics: I don't need to carry that heavy load (spare tube, pump, tools, jacket in case it's cold) when the race is well organised. The water in the hydration pack was useful, but carrying it up Chaschauna was a pain. Not sure what I'll do next; it's possible to survive only on water/drinks from the food posts (basically 2.5-2.8L is equivalent to only 4 750ml bottles, and there were I think about 6 stops?), but the hydration pack is so easy to use Keeping one's head cool and not stress about things also would help: had I looked at my brake lever in peace, I could have solved it myself, and not ride ~10Km with only one brake. Also, losing some weight (as in losing fat, not having a lighter bike) would definitely help. I could stand to lose 5Kg easily, probably 10Kg, and that would bring me more in line with other people in the race (at least looking at the pictures). And hey, my Watts/Kg would improve magically! And last but most important, I need better training. Training on how to use my energy, training longer rides so that my body gets used to it and doesn't bonk after 3 hours, training training training. Which I like, but the problem is time to do it Also, in case anybody wonders: yes, I do recommend this race! It was definitely fun, and the route itself is very nice, nicer than the pictures here show. Closing words: gravity rules. Up or down, it's hard and punishing. Still: Ride on!

1 September 2016

Thadeu Lima de Souza Cascardo: GNU libc and Linux

Some time ago, I built a static program that I wanted to run on an Android tablet. What was my surprise when I saw a message saying "FATAL: kernel too old". After some investigation, it turns out that GNU libc may assume some Linux features are present during build time. This means that given a minimum Linux version, that built libc might only work on that version or newer. Since 2014, GNU libc itself requires 2.6.32 as the minimum. Previously, it was 2.6.16, changed in 2012. Debian, as of 2015, builds it with a required minimum Linux version of 3.2. To give an idea about the history of these kernel releases, we have: So, at least for GNU libc upstream, it would appear that not many devices would stop being supported, though the situation would not be as good for binary versions of Debian. However, I have a small list of devices that might show otherwise. Many Android devices have been shipped with Linux 3.4, but I encountered at least one using Linux 3.0. So, even though many new devices ship with newer versions of Linux, it's still possible to find some new and older devices using versions older than 3.2, and even versions older than 2.6.32 may be found. Another interesting note is that, without a few patches, it's not possible to build Linux 2.6.32 with GCC 5 and newer. For that and many other reasons, it's important that we update. For bug fixes, and so we can make progress and use better software are some of the other reasons. So, it's imperative that we have devices support upstream. Otherwise, the task of doing updates with forward porting becomes daunting. And that's the current state for many devices, which is why I have been trying to use new software with older versions of Linux. But as time passes, I realize how hard a task this is, as most new software these days, even a building block like GNU libc, requires ever new versions of Linux. For now, most gadgets I have support Linux 3.4 or newer. But not long ahead, that support will be dropped as well. And that means there will be no more updates for those devices. It's a consequence of both targeting time-to-market and programmed obsolescence as business practices. Upstream support is no priority, and maintenance is only that required until the next model is available on the stores. This is one more reason why we need to have more operating systems available for those devices. Systems that are designed to last more than a couple of years. As I said, upstream support is imperative, but as a step forward, I still believe we can provide the GNU experience to lots of devices out there.

31 August 2016

Enrico Zini: Links for September 2016

A Few Useful Mental Tools from Richard Feynman [archive]
These tricks show Feynman taking the method of thought he learned in pure science and applying it to the more mundane topics most of us have to deal with every day.
Pasta [archive]
A comprehensive introduction to pasta, to keep at hand in case I meet someone who has little familiarity with it.
MPTP: One Designer Drug and Serendipity [archive]
Abstract: Through an unlikely series of coincidences and fortunate accidents, the development of Parkinson s disease in several illicit drug users was traced to their use of a meperidine analog contaminated with 1-methyl-4-phenyl-1,2,3,6-tetrahydropyridine (MPTP). The discovery of a chemical capable of producing animal models of the disease has revitalized research efforts and resulted in important new information. The serendipitous finding also prompted consideration of what changes seem advisable if designer drugs are to be dealt with more efficaciously.
The Debunking Handbook: now freely available for download
The Debunking Handbook, a guide to debunking misinformation, is now freely available to download. Although there is a great deal of psychological research on misinformation, there's no summary of the literature that offers practical guidelines on the most effective ways of reducing the influence of myths.
Faulty neon light jams radio appliances [archive]
An apparent interference source began plaguing wireless vehicle key fobs, cell phones, and other wireless electronics. Key fob owners found they could not open or start their vehicles remotely until their vehicles were towed at least a block away, nor were they able to call for help on their cell phones when problems occurred
Calvin & Muad'Dib
Calvin & Hobbes with text taken from Frank Herbert's Dune. It's been around since 2013 and I consistently found it moving and deep.
When Birds Attack - Bike Helmet Hacks [archive]
Australian magpies attacking cyclists has propted several creative adaptations, including attaching an afro wig to the bike helmet.

Chris Lamb: Free software activities in August 2016

Here is my monthly update covering what I have been doing in the free software world (previously):

Reproducible builds

Whilst anyone can inspect the source code of free software for malicious flaws, most Linux distributions provide binary (or "compiled") packages to end users. The motivation behind the Reproducible Builds effort is to allow verification that no flaws have been introduced either maliciously and accidentally during this compilation process by promising identical binary packages are always generated from a given source.

Diffoscope diffoscope is our "diff on steroids" that will not only recursively unpack archives but will transform binary formats into human-readable forms in order to compare them:
  • Added a command-line interface to the try.diffoscope.org web service.
  • Added a JSON comparator.
  • In the HTML output, highlight lines when hovering to make it easier to visually track.
  • Ensure that we pass str types to our Difference class, otherwise we can't be sure we can render them later.
  • Testsuite improvements:
    • Generate test coverage reports.
    • Add tests for Haskell and GitIndex comparators.
    • Completely refactored all of the comparator tests, extracting out commonly-used routines.
    • Confirm rendering of text and HTML presenters when checking non-existing files.
    • Dropped a squashfs test as it was simply too unreliable and/or has too many requirements to satisfy.
  • A large number of miscellaneous cleanups, including:
    • Reworking the comparator setup/preference internals by dynamically importing classes via a single list.
    • Split exceptions out into dedicated diffoscope.exc module.
    • Tidying the PROVIDERS dict in diffoscope/__init__.py.
    • Use html.escape over xml.sax.saxutils.escape, cgi.escape, etc.
    • Removing hard-coding of manual page targets names in debian/rules.
    • Specify all string format arguments as logging function parameters, not using interpolation.
    • Tidying imports, correcting indentation levels and drop unnecessary whitespace.

disorderfs disorderfs is our FUSE filesystem that deliberately introduces nondeterminism in system calls such as readdir(3).
  • Added a testsuite to prevent regressions. (f124965)
  • Added a --sort-dirents=yes no option for forcing deterministic ordering. (2aae325)

Other
  • Improved strip-nondeterminism, our tool to remove specific nondeterministic information after a build:
    • Match more styles of Java .properties files.
    • Remove hyphen from "non-determinism" and "non-deterministic" throughout package for consistency.
  • Improvements to our testing infrastucture:
    • Improve the top-level navigation so that we can always get back to "home" of a package.
    • Give expandable elements cursor: pointer CSS styling to highlight they are clickable.
    • Drop various trailing underlined whitespaces after links.
    • Explicitly log that build was successful or not.
    • Various code-quality improvements, including prefering str.format over concatentation.
  • Miscellaneous updates to our filter-packages internal tool:
    • Add --random=N and --url options.
    • Add support for --show=comments.
    • Correct ordering so that --show-version runs after --filter-ftbfs.
    • Rename --show-ftbfs to --filter-ftbfs and --show-version to --show=version.
  • Created a proof-of-concept reproducible-utils package to contain commonly-used snippets aimed at developers wishing to make their packages reproducible.


I also submitted 92 patches to fix specific reproducibility issues in advi, amora-server, apt-cacher-ng, ara, argyll, audiotools, bam, bedtools, binutils-m68hc1x, botan1.10, broccoli, congress, cookiecutter, dacs, dapl, dateutils, ddd, dicom3tools, dispcalgui, dnssec-trigger, echoping, eekboek, emacspeak, eyed3, fdroidserver, flashrom, fntsample, forkstat, gkrellm, gkrellm, gnunet-gtk, handbrake, hardinfo, ircd-irc2, ircd-ircu, jack-audio-connection-kit, jpy, kxmlgui, libbson, libdc0, libdevel-cover-perl, libfm, libpam-ldap, libquvi, librep, lilyterm, mozvoikko, mp4h, mp4v2, myghty, n2n, nagios-nrpe, nikwi, nmh, nsnake, openhackware, pd-pdstring, phpab, phpdox, phpldapadmin, pixelmed-codec, pleiades, pybit, pygtksourceview, pyicu, python-attrs, python-gflags, quvi, radare2, rc, rest2web, roaraudio, rt-extension-customfieldsonupdate, ruby-compass, ruby-pg, sheepdog, tf5, ttf-tiresias, ttf-tiresias, tuxpaint, tuxpaint-config, twitter-bootstrap3, udpcast, uhub, valknut, varnish, vips, vit, wims, winswitch, wmweather+ & xshisen.

Debian GNU/Linux
Debian LTS

This month I have been paid to work 15 hours on Debian Long Term Support (LTS). In that time I did the following:
  • "Frontdesk" duties, triaging CVEs, etc.
  • Authored the patch & issued DLA 596-1 for extplorer, a web-based file manager, fixing an archive traversal exploit.
  • Issued DLA 598-1 for suckless-tools, fixing a segmentation fault in the slock screen locking tool.
  • Issued DLA 599-1 for cracklib2, a pro-active password checker library, fixing a stack-based buffer overflow when parsing large GECOS fields.
  • Improved the find-work internal tool adding optional colour highlighting and migrating it to Python 3.
  • Wrote an lts-missing-uploads tool to find mistakes where there was no correponding package in the archive after an announcement.
  • Added optional colour highlighting to the lts-cve-triage tool.

Uploads
  • redis 2:3.2.3-1 New upstream release, move to the DEP-5 debian/copyright format, ensure that we are running as root in LSB initscripts and add a README.Source regarding our local copies of redis.conf and sentinel.conf.
  • python-django:
    • 1:1.10-1 New upstream release.
    • 1:1.10-2 Fix test failures due to mishandled upstream translation updates.

  • gunicorn:
    • 19.6.0-2 Reload logrotate in the postrotate action to avoid processes writing to the old files and move to DEP-5 debian/copyright format.
    • 19.6.0-3 Drop our /usr/sbin/gunicorn ,3 -debian and related Debian-specific machinery to be more like upstream.
    • 19.6.0-4 Drop "template" systemd .service files and point towards examples and documentation instead.

  • adminer:
    • 4.2.5-1 Take over package maintenance, completely overhauling the packaging with a new upstream version, move to virtual-mysql-server to support MariaDB, updating package names of dependencies and fix the outdated Apache configuration.
    • 4.2.5-2 Correct the php5 package names.


FTP Team As a Debian FTP assistant I ACCEPTed 90 packages: android-platform-external-jsilver, android-platform-frameworks-data-binding, camlpdf, consolation, dfwinreg, diffoscope, django-restricted-resource, django-testproject, django-testscenarios, gitlab-ci-multi-runner, gnome-shell-extension-taskbar, golang-github-flynn-archive-go-shlex, golang-github-jamesclonk-vultr, golang-github-weppos-dnsimple-go, golang-golang-x-time, google-android-ndk-installer, haskell-expiring-cache-map, haskell-hclip, haskell-hdbc-session, haskell-microlens-ghc, haskell-names-th, haskell-persistable-record, haskell-should-not-typecheck, haskell-soap, haskell-soap-tls, haskell-th-reify-compat, haskell-with-location, haskell-wreq, kbtin, libclipboard-perl, libgtk3-simplelist-perl, libjs-jquery-selectize.js, liblemon, libplack-middleware-header-perl, libreoffice, libreswan, libtest-deep-json-perl, libtest-timer-perl, linux, linux-signed, live-tasks, llvm-toolchain-3.8, llvm-toolchain-snapshot, lua-luv, lua-torch-image, lua-torch-nn, magic-wormhole, mini-buildd, ncbi-vdb, node-ast-util, node-es6-module-transpiler, node-es6-promise, node-inline-source-map, node-number-is-nan, node-object-assign, nvidia-graphics-drivers, openhft-chronicle-bytes, openhft-chronicle-core, openhft-chronicle-network, openhft-chronicle-threads, openhft-chronicle-wire, pycodestyle, python-aptly, python-atomicwrites, python-click-log, python-django-casclient, python-git-os-job, python-hypothesis, python-nosehtmloutput, python-overpy, python-parsel, python-prov, python-py, python-schema, python-tackerclient, python-tornado, pyvo, r-cran-cairo, r-cran-mi, r-cran-rcppgsl, r-cran-sem, ruby-curses, ruby-fog-rackspace, ruby-mixlib-archive, ruby-tzinfo-data, salt-formula-swift, scapy3k, self-destructing-cookies, trollius-redis & websploit.

29 August 2016

Michal &#268;iha&#345;: Improving phpMyAdmin Docker container

Since I've created the phpMyAdmin container for Docker I've always felt strange about using PHP's built in web server there. It really made it poor choice for any production setup and probably was causing lot of problems users saw with this container. During the weekend, I've changed it to use more complex setup with Supervisor, nginx and PHP FPM. As building this container is one of my first experiences with Docker (together with Weblate container), it was not as straightforward as I'd hope for, but in the end is seems to be working just fine. While touching the code, I've also improved testing of the Docker container to tests all supported setups and to better report in case of test fails. The nice side effect of this is that the PHP code is no longer being executed under root in the container, so that should make it more sane for production use as well (honestly I never liked this approach that almost everything is executed as root in Docker containers).

Filed under: Debian English phpMyAdmin 4 comments

Gergely Nagy: Recruitment mistakes: part 3

It has been a while that I have been contacted by a recruiter, and the last few ones were fairly decent conversations, where they made an effort to research me first, and even if they did not get everything right, they still listened, and we had a productive talk. But four days ago, I had another recruiter reach out to me, from a company I know oh so well: one I ranted about before: Google. Apparently, their recruiters still do carpet-bombing style outreach. My first thought was "what took them so long?" - it has been five years since my last contact with a Google recruiter. I almost started missing them. Almost. To think that Google is now powerful enough to read my mind, is scary. Yet, I believe, this is not the case; rather, it's just another embarrassing mistake.To make my case, let me quote the full e-mail I was sent, with the name of the sender redacted, and my comments - which I'm also sending to the recruiter:
Hi Gergely,
Hi!
How are you? Hope you're well.
Thank you, I'm fine, just back from vacation, and I was thrilled to read your e-mail. Although, I did find it surprising too, and considering past events, I thought it to be spam first.
My name is XXX and I am recruiting for the Google Engineering team. I have just found your details on Github...
I'm happy that you found me through GitHub, but I'm curious why you mailed me at my debian.org address then? That address is not on my GitHub profile, and even though I have some code signed with that address, that's not what I use normally. My GitHub profile also links to a page I created especially for recruiters, which I don't think you have read - but more on that below.
...and your experience with software development combined with your open source contributions is particularly relevant to Google
Which part of my recent contributions are relevant to Google? For the past few months, the vast majority (over 90%) of my open source work has been on keyboard firmware. If Google is developing a keyboard, then this may be relevant, otherwise, I find it doubtful.Some of my past OSS contributions may be more relevant, but that's in the past, and it would take some digging to see those from GitHub. And if you did that kind of digging, you would have found the page on my site for recruiters, and would not have e-mailed me at my Debian address, either.
We are always interested in talking to top engineers with your mix of skills and I was wondering if you are at all open to exploring roles with Google in EMEA.
To make things short, my stance is the same as it was five years ago, when I wrote - and I quote - "So, here's a public request: do not email me ever again about job opportunities within Google. I do not wish to work for Google. Not now, not tomorrow, not ever."This still stands. Please do not ever e-mail me about job opportunities within Google. I do not wish to work for Google, not now, not tomorrow, not five years from now, not ever. This will not change. Many things may change, this however, will not.But even if I ignore this, let me ask you mix of skills are you exactly interested in? Keyboard firmware hacking, mixed with Emacs Lisp, some Clojure, and hacking on Hy (which, if you have explored my GitHub profile, will surely know) from time to time? Or is it my Debian Developer hat that got your interest? If so, why didn't you say so? Not that it would change anything, but I'm curious.Is it my participation in 24pullrequests? Or my participation in GSoC in years past?Nevertheless, my list of conditions I mentioned above, apply. Is Google able to fulfill all my requirements, and the preferences too? Last time I heard, working for Google required one to relocate, which I clearly said on that page, I'm not willing to do.
The teams I recruit for are responsible for Google's planet-scale systems. Just to give you more of an idea, some of the projects we work on that might be of interest to you would include:
  • MapReduce
  • App Engine
  • Mesa
  • Maglev
And how would these be interesting to me, considering my recent OSS work? (Hint: none of them interest me, not a bit. Ok perhaps MapReduce, a little.)
I think you could be a great fit here, where you can develop a great career and at the same time you will be part of the most mission critical team, designing and developing systems which run Google Search, Gmail, YouTube, Google+ and many more as you can imagine.
My career is already developing fine, thank you, I do not need Google to do that. I am already working on things I consider important and interesting, if I wanted to change, I would. But I certainly would not consider a company which I had asked numerous times NOT to contact me about opportunities. If you can't respect this wish, and forget about this in mere five years, why would I trust you to keep any other promises you make now?
Thank you so much for your time and I look forward to hearing from you.
I wish you had spent as much time researching me - or even half that - as I have spent replying to you. I suppose this is not the reply you were expecting, or looking for, but this is the only one I'll ever give to anyone from Google.And here, at the end, if you read this far, I'm asking you, and everyone at Google to never contact me about job opportunities. I will not work for Google. Not now, not tomorrow, not five years from now, not ever. Please do not e-mail me again, and do not reply to this e-mail either. I'm not interested in neither apologies, nor promises that you won't contact me - just simply don't do it.Thank you.

Russell Coker: Monitoring of Monitoring

I was recently asked to get data from a computer that controlled security cameras after a crime had been committed. Due to the potential issues I refused to collect the computer and insisted on performing the work at the office of the company in question. Hard drives are vulnerable to damage from vibration and there is always a risk involved in moving hard drives or systems containing them. A hard drive with evidence of a crime provides additional potential complications. So I wanted to stay within view of the man who commissioned the work just so there could be no misunderstanding. The system had a single IDE disk. The fact that it had an IDE disk is an indication of the age of the system. One of the benefits of SATA over IDE is that swapping disks is much easier, SATA is designed for hot-swap and even systems that don t support hot-swap will have less risk of mechanical damage when changing disks if SATA is used instead of IDE. For an appliance type system where a disk might be expected to be changed by someone who s not a sysadmin SATA provides more benefits over IDE than for some other use cases. I connected the IDE disk to a USB-IDE device so I could read it from my laptop. But the disk just made repeated buzzing sounds while failing to spin up. This is an indication that the drive was probably experiencing stiction which is where the heads stick to the platters and the drive motor isn t strong enough to pull them off. In some cases hitting a drive will get it working again, but I m certainly not going to hit a drive that might be subject to legal action! I recommended referring the drive to a data recovery company. The probability of getting useful data from the disk in question seems very low. It could be that the drive had stiction for months or years. If the drive is recovered it might turn out to have data from years ago and not the recent data that is desired. It is possible that the drive only got stiction after being turned off, but I ll probably never know. Doing it Properly Ever since RAID was introduced there was never an excuse for having a single disk on it s own with important data. Linux Software RAID didn t support online rebuild when 10G was a large disk. But since the late 90 s it has worked well and there s no reason not to use it. The probability of a single IDE disk surviving long enough on it s own to capture useful security data is not particularly good. Even with 2 disks in a RAID-1 configuration there is a chance of data loss. Many years ago I ran a server at my parents house with 2 disks in a RAID-1 and both disks had errors on one hot summer. I wrote a program that s like ddrescue but which would read from the second disk if the first gave a read error and ended up not losing any important data AFAIK. BTRFS has some potential benefits for recovering from such situations but I don t recommend deploying BTRFS in embedded systems any time soon. Monitoring is a requirement for reliable operation. For desktop systems you can get by without specific monitoring, but that is because you are effectively relying on the user monitoring it themself. Since I started using mon (which is very easy to setup) I ve had it notify me of some problems with my laptop that I wouldn t have otherwise noticed. I think that ideally for desktop systems you should have monitoring of disk space, temperature, and certain critical daemons that need to be running but which the user wouldn t immediately notice if they crashed (such as cron and syslogd). There are some companies that provide 3G SIMs for embedded/IoT applications with rates that are significantly cheaper than any of the usual phone/tablet plans if you use small amounts of data or SMS. For a reliable CCTV system the best thing to do would be to have a monitoring contract and have the monitoring system trigger an event if there s a problem with the hard drive etc and also if the system fails to send a I m OK message for a certain period of time. I don t know if people are selling CCTV systems without monitoring to compete on price or if companies are cancelling monitoring contracts to save money. But whichever is happening it s significantly reducing the value derived from monitoring.

28 August 2016

Reproducible builds folks: Reproducible builds: week 70 in Stretch cycle

What happened in the Reproducible Builds effort between Sunday August 21 and Saturday August 27 2016: GSoC and Outreachy updates Packages reviewed and fixed, and bugs filed Reviews of unreproducible packages 10 package reviews have been added and 6 have been updated this week, adding to our knowledge about identified issues. A large number of issue types have been updated: Weekly QA work 29 FTBFS bugs have been reported by: diffoscope development Holger also created another test job for diffoscope on jenkins.debian.net, so that now also all commits to branches other than master are being tested. strip-nondeterminism development strip-nondeterminism 0.023-1 was uploaded by Chris Lamb:
 * Support Android .apk files with the JAR normalizer.
 * handlers/png.pm: Drop unused Archive::Zip import
 * Remove hyphen from non-determinism and non-deterministic.
 * javaproperties.pm: Match more styles of .properties and loosen filename matching.
 * Improve tests:
   - Make fixture runner generic to all normalizer types.
   - Replace (single) pearregistry test with a fixture.
   - Set a canonical time for fixture tests.
   - Add gzip testcase fixture.
   - Replace t/javadoc.t with fixture
   - Replace t/ar.t with a fixture.
   - t/javaproperties: move pom.properties and version.properties tests to fixtures
   - t/fixtures.t: move to using subtests
   - t/fixtures.t: Explicitly test that we can find a normalizer
   - t/fixtures.t: Don't run normalizer if we didn't find one.
strip-nondeterminism 0.023-2 uploaded by Mattia Rizzolo to allow stderr in autopkgtest. disorderfs development tests.reproducible-builds.org Debian: Somewhat related to reproducible builds there has been a first Debian jenkins team maintainance meeting on the #debian-qa IRC channel, to discuss current issues with the setup and to start the work of migrating jenkins.debian.net to jenkins.debian.org. The next meeting will take place on September 28th 2016 at 19 UTC. Misc. This week's edition was written by Chris Lamb and Holger Levsen and reviewed by a bunch of Reproducible Builds folks on IRC.

27 August 2016

Arturo Borrero Gonz lez: Why conntrackd in Debian is better with systemd


There has been some discussion [0] around my decision to drop sysvinit support in the conntrackd package in Debian [1] (version 1:1.4.4-2).

The rationale I used for such a movement was sent to the debian-devel [2] mailing list, and here it is:


Lots of people have talked to me with both support and disagreement with the change.

Before reading the rest of this blogpost, please note that I'm not interested in the 'systemd vs sysvinit' war, and starting now I will focus mainly on the subject of building a firewall cluster with netfilter technology and the reasons why I think sysvinit here is irrelevant.

I started working with firewall clusters by the time of Debian Squeeze. By then, I used only sysvinit, because it was the Debian default init system and because I did not dive so much in the internals of the firewall cluster itself.

By then, the conntrackd debian package included support for sysvinit by means of two files (the two files that I dropped in 1:1.4.4-2) :


Using both files, you could start/stop conntrackd, and nothing more (for example, a proper status check was not implemented).

The conntrackd daemon is used in HA firewall clusters to replicate connection states between nodes of the cluster, so flow states are known in all nodes and they can properly perform stateful firewalling.

When you build HA clusters, there are 2 basic states of the cluster you may check and adjust: failover and failback.

With conntrackd, the failover situation is straight forward: the other node has the state information already from the dying node.
The failback situation is different: depending on the configuration of both the cluster and conntrackd, the new node may ask for a complete synchronisation to the other node when it become alive again (at boot time, for example) . This is the case if you are building a multi-master firewall cluster (i.e: both nodes are seeing traffic and filtering at the same time).

Asking for a complete synchronisation is done by means of a new instance of conntrackd, which communicates using a UNIX socket to the main conntrackd daemon (the one which is actually communicating with the other node). A failback boot procedure may look like this:

  1. system boots
  2. firewall ruleset loading
  3. networking up
  4. conntrackd up (main sync daemon: using 'conntrackd -d'; UNIX socket is opened)
  5. request sync with other node (using conntrackd -n' which uses the UNIX socket opened in step 4)

In both sysvinit and systemd cases, the step 5 may be implemented using another dummy service which performs the required operations and that depends on the main service representing the step 4.

The point here is that steps 4 and 5 suffer a very bad race condition: the conntrackd daemon may open the UNIX socket (step 4) *after* the we try to use it (step 5).

As you could probably imagine, this is the worst possible scenario: as one of the nodes of the cluster is missing important flow state information the stateful firewall will drop packets and all the network monitoring alarms will start to ring... Ironically, just after a failback operation, when all of our cluster is supposed to be up an running.

To avoid the race conditions, some typical hacks could be implemented:


After a bit of research, I found that the last point could be implemented very easily using libsystemd, so the daemon inform of its internal state to systemd [4].

The solution is elegant, simple and offers more direct benefits:

So the clear winner for conntrackd is to go with systemd, using an unit service file of Type=notify. Using sysvinit is prone to the described race condition. No serious firewall cluster with this architecture would use sysvinit.

It's obvious to me that systemd is a better technology than sysvinit. The sysvinit approach has been OK for a while, and for me it was fascinating when I started developing init scripts and learning how things worked.
But now we have systemd. It's the default in Debian. It's far better.

Conclusions: yes, I will probably reintroduce sysvinit files just to avoid any flamewar.


[0] https://lists.debian.org/debian-devel/2016/08/msg00448.html
[1] https://tracker.debian.org/pkg/conntrack-tools
[2] https://lists.debian.org/debian-devel/2016/08/msg00456.html
[3] https://sources.debian.net/src/systemd/231-4/debian/systemd.NEWS/
[4] http://git.netfilter.org/conntrack-tools/tree/src/systemd.c

26 August 2016

Michal &#268;iha&#345;: CI coverage from Windows, Linux and OSX

Once I got CI working on multiple platforms the obvious next step was to be able to aggregate coverage reports across them. This should not be that hard, right? Well I've spent couple of hours on that during last few days. On Linux and OSX it was pretty much straightforward. Both GCC and Clang do support coverage, so it's just matter of configuring them properly and collect the coverage reports. I've used own solution for that in past and that was really far from working well (somehow I never managed to get coverage fully uploaded to Codecov). Fortunately there exists CMake script called CMake-codecov which does all needed work and works out of the box on GCC and Clang (even on OSX). Well it works on Travis only once you update the compilers and install llvm-cov tool. The Windows part on AppVeyor was much harder for me. This can be heavily accounted to lack of my experience with Windows and especially development on Windows in past ten years (probably even more). First challenge was to find something what can generate code coverage there. After lot of googling I've settled down on OpenCppCoverage what seems to be the only free solution I was able to find. The good thing is that it can generate coverage in Cobertura format that Codecov undestands. There are also bad things that I've learned. First of all it's quite hard to integrate this with CTest. There is no support for wrapping test calls in custom commands, so I've misused the memory checks for that purpose. I've written small python script which pretends the valgrind interface and does call OpenCppCoverage in the background. Now I had around 800 coverage files (one for each test case) and we need to deal with them somehow. The Codeconv command line client doesn't deal wit this out of the box so the obvious choice was to merge them before upload. There even seems to be script doing that, but unfortunately trying that on our coverage data make it nowhere near completion within hour, so that's not really good choice. Second thing I've tried was merging binary coverage in OpenCppCoverage and then exporting to Cobertura format. Obviously Gammu is special project as all I got from this attempt was crashing OpenCppCoverage (it did merge some of the coverages, but it failed in the end without indicating any error). In the end I've settled down to uploading files in chunks to Codecov. This seems to work quite okay, though is a bit slow, mostly due to way how Codecov bash uploader prepares data to upload (but this will be hopefully fixed soon). Anyway the goal has been reached, both Windows and Linux code shows in coverage reports.

Filed under: Debian English Gammu 0 comments

25 August 2016

Alessio Treglia: The Breath of Time

For centuries man has hunted, he brought the animals to pasture, cultivated fields and sailed the seas without any kind of tool to measure time. Back then, the time was not measured, but only estimated with vague approximation and its pace was enough to dictate the steps of the day and the life of man. Subsequently, for many centuries, hourglasses accompanied the civilization with the slow flow of their sand grains. About hourglasses, Ernst Junger writes in Das Sanduhrbuch 1954 (no English translation): This small mountain, formed by all the moments lost that fell on each other, it could be understood as a comforting sign that the time disappears but does not fade. It grows in depth . For the philosophers of ancient Greece, the time was just a way to measure how things move in everyday life and in any case there was a clear distinction between quantitative time (Kronos) and qualitative time (Kair s). According to Parmenides, time is guise, because its existence <Read More [by Fabio Marzocca]>

Joerg Jaspert: New gnupg-agent in Debian

In case you just upgraded to the latest gnupg-agent and used gnupg-agent as your ssh-agent you may find that ssh refuses to work with a simple but not helpful sign_and_send_pubkey: signing failed: agent refused operation This seems to come from systemd starting the agent, no longer a script at the start of the X session. And so it ends up with either no or an unusable tty. A simple
gpg-connect-agent updatestartuptty /bye
updates that and voila, ssh agent functionality is back in. Note: This assumes you have enable-ssh-support in your ~/.gnupg/gpg-agent.conf

Next.

Previous.