To start off, let me say it again: I hate light pollution. I really, really hate it. I love the night sky where you look up and see thousands of stars, and constellations besides Ursa Major. As somebody said once, You haven t lived until you ve seen your shadow by the light of the Milky Way .
But, ahem, I live in a large city, and despite my attempts using star trackers, special filters, etc. you simply can t escape it. So, whenever we go on vacation in the mountains, I m trying to think if I can do a bit of astro-photography (not that I m good at it).
Which bring me to our recent vacation up in the mountains. I was looking forward to it, until in the week before, when the weather prognosis was switching between snow, rain and overcast for the entire week. No actual day or night with clear skies, so I didn t take a tripod, I didn t take a wide lens, and put night photography out of my mind.
Vacation itself was good, especially the quietness of the place, so I usually went to be early-ish and didn t look outside. The weather was as forecasted - no new snow (but there was enough up in the mountains), but heavy clouds all the time, and the sun only showed itself for a few minutes at a time.
One night I was up a bit longer than usual, working on the laptop and being very annoyed by a buzzing sound. At first I thought maybe I was imagining it, but from time to time it was stopping briefly, so it was a real noise; I started hunting for the source. Not my laptop, not the fridge, not the TV but it was getting stronger near the window. I open the door to the balcony, and bam! Very loud noise, from the hotel nearby, where at midnight the pool was being cleaned. I look at the people doing the work, trying to estimate how long it ll be until they finish, but it was looking like a long time.
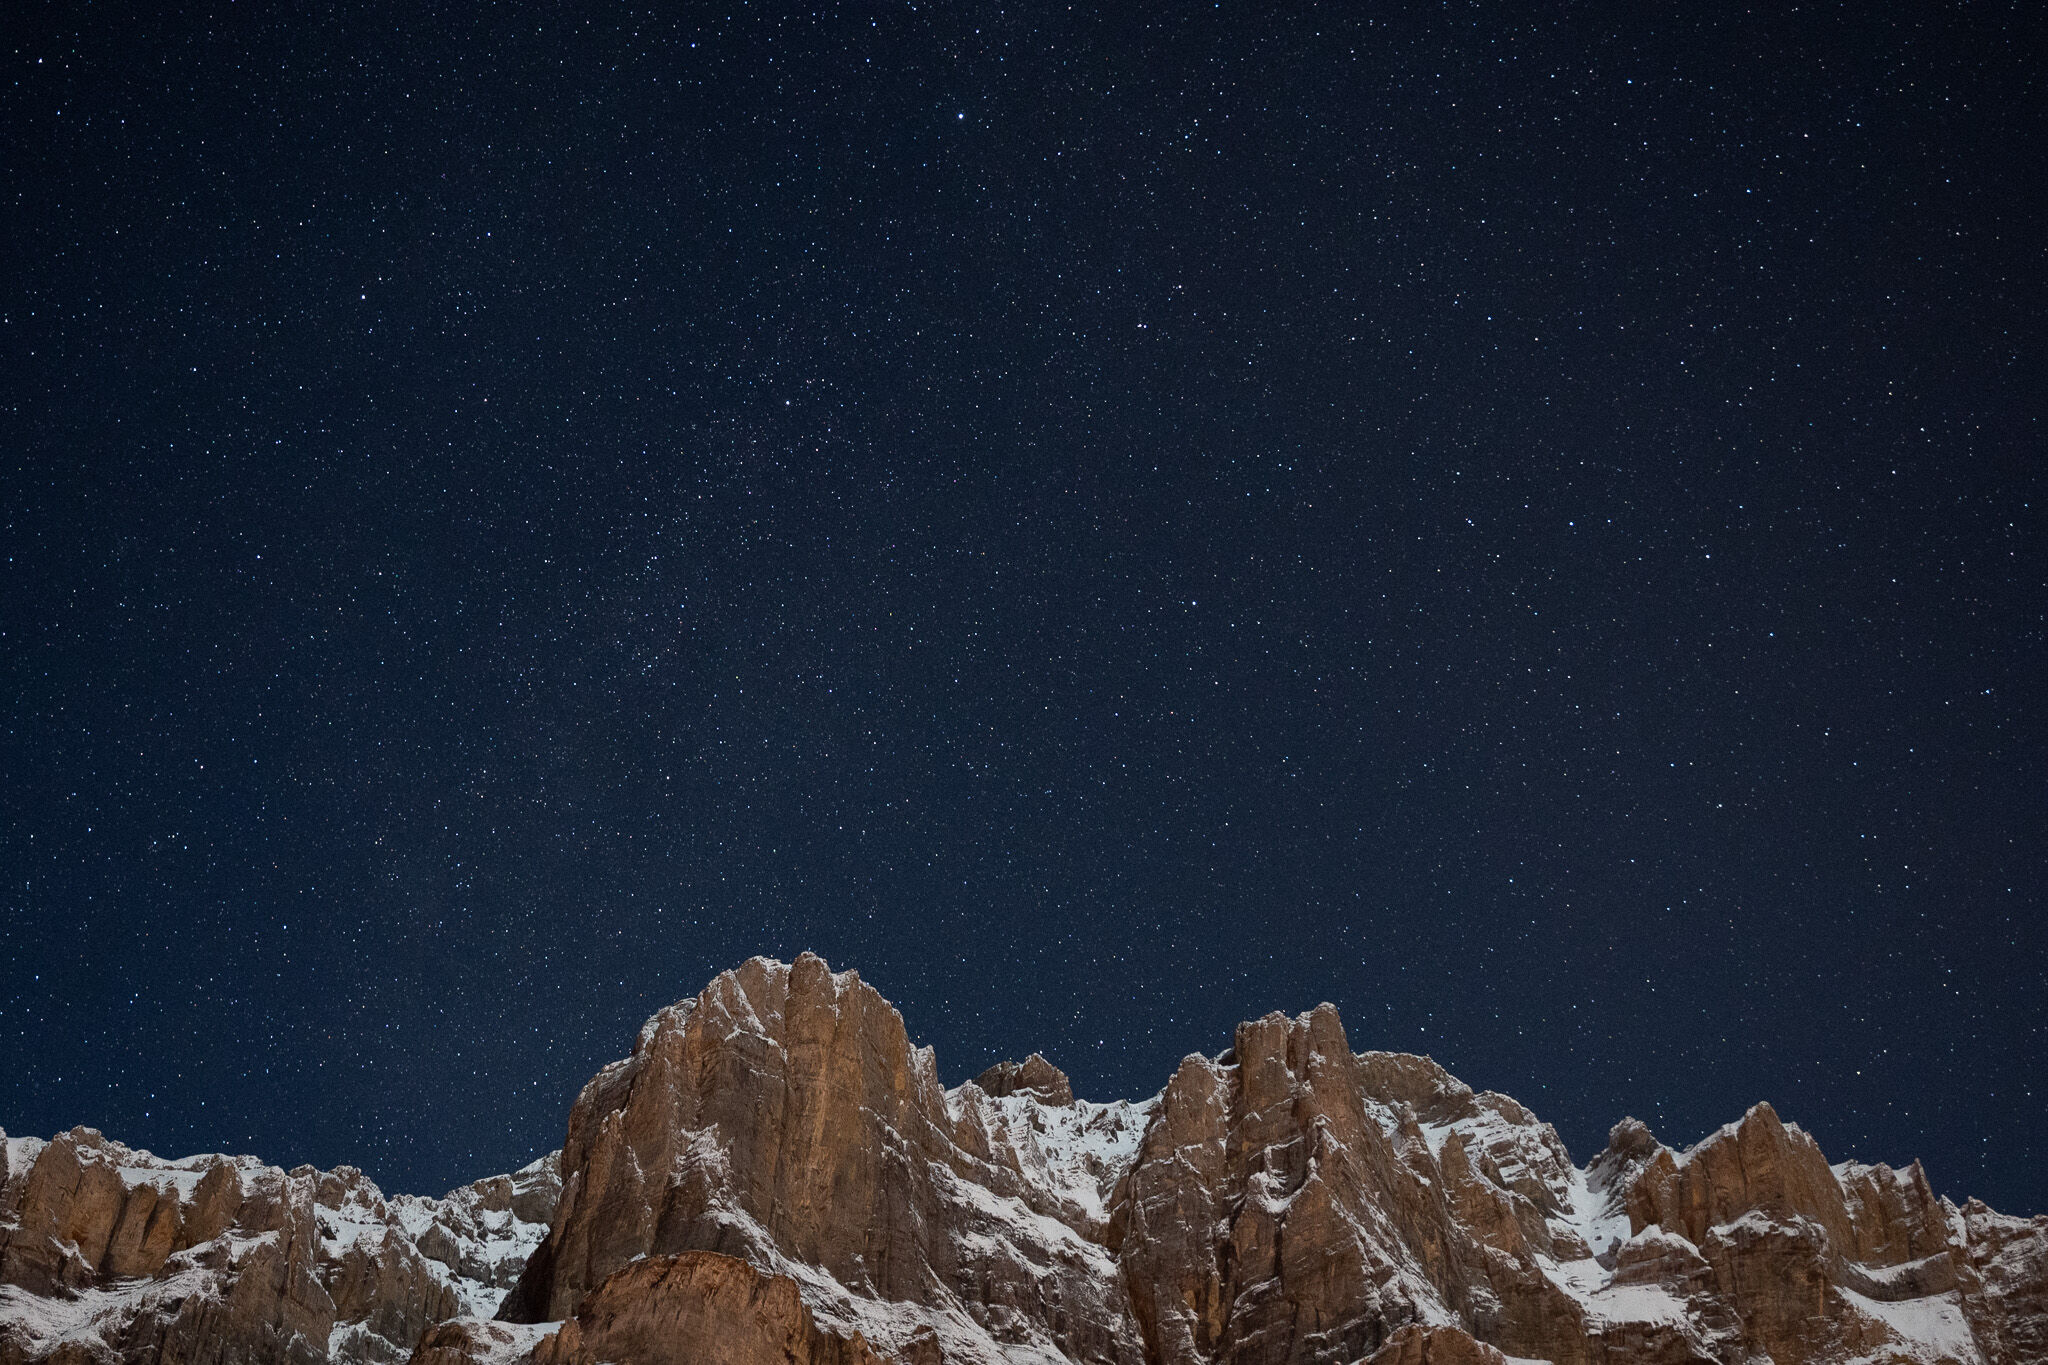
Fortunately with the door closed the noise was not bad enough to impact my sleep, so I debate getting angry or just resigned, and since it was late, I just sigh, roll my eyes not metaphorically, but actually roll my eyes and look up, and I can t believe my eyes. Completely clear sky, no trace of clouds anywhere, and stars. Lots of starts. I sit there, looking at the sky and enjoying the view, and I think to myself that it won t look that nice on the camera, for sure. Especially without a real trip, and without a fast lens.
Nevertheless, I grab my camera and just for kicks take one handheld picture. To my surprise (and almost disbelief), blurry pixels aside, the photo does look like what I was seeing, so I grab my tiny tripod that I carried along, and (with only a 24-70 zoom lens), grab a photo. And another, and another and then I realise that if I can make the composition work, and find a good shutter speed, this can turn out a good picture.
I didn t have a remote release, the tripod was not very stable and it cannot point the camera upwards (it s basically an emergency tripod), so it was quite sub-optimal; still, I try multiple shots (different compositions, different shutter speeds); they look on the camera screen and on the phone pretty good, so just for safety I take a few more, and, very happy, go to bed.
Coming back from vacation, on the large monitor, it turns out that the first 28 out of the 30 pictures were either blurry or not well focused (as I was focusing manually), and the 29th was almost OK but still not very good. Only the last, the really last picture, was technically good and also composition-wise OK. Luck? Foresight? Don t know, but it was worth deleting 28 pictures to get this one. One of my best night shots, despite being so unprepared
Stars! Lots of stars! And mountains
Of course, compared to other people s pictures, this is not special. But for me, it will be a keepsake of how a real night sky should look like.
If you want to zoom in, higher resolution on flickr.
Technically, the challenges for the picture were two-fold:
fighting the shutter speed; the light was not the problem, but rather the tripod and lack of remote release: a short shutter speed will magnify tripod issues/movement from the release (although I was using delayed release on the camera), but will prevent star trails, and a long shutter speed will do the exact opposite; in the end, at the focal length I was using, I settled on a 5 second shutter speed.
composition: due to the presence of the mountains (which I couldn t avoid by tilting the camera fully up), this was for me a difficult thing, since it s more on the artistic side, which is very subjective; in the end, this turned out fine (I think), but mostly because I took pictures from many different perspectives.
Next time when travelling by car, I ll surely take a proper tripod
Until next time, clear and dark skies
And a new version of digest is now on CRAN will go to Debian shortly.
digest creates hash digests of arbitrary R objects (using the md5, sha-1, sha-256, sha-512, crc32, xxhash32, xxhash64, murmur32, spookyhash, and blake3 algorithms) permitting easy comparison of R language objects. It is a fairly widely-used package (currently listed at 896k monthly downloads, 279 direct reverse dependencies and 8057 indirect reverse dependencies, or just under half of CRAN) as many tasks may involve caching of objects for which it provides convenient general-purpose hash key generation.
This release brings two nice contributed updates. Dirk Schumacher added support for blake3 (though we could probably push this a little harder for performance, help welcome). Winston Chang benchmarked and tuned some of the key base R parts of the package. Last but not least I flipped the vignette to the lovely minidown, updated the Travis CI setup using bspm (as previously blogged about in r4 #30), and added a package website using Matertial for MkDocs.
My CRANberries provides the usual summary of changes to the previous version.
For questions or comments use the issue tracker off the GitHub repo.
If you like this or other open-source work I do, you can now sponsor me at GitHub. For the first year, GitHub will match your contributions.
It's a bit of a long shot, but maybe someone on Planet Debian or
elsewhere can help us reach the right people at Apple.
Starting with iOS 14, something apparently changed on the way
USB tethering (also called Personal Hotspot) is set up, which broke
it for people using Linux. The driver in use is ipheth, developped
in 2009 and
included in the Linux kernel in
2010.
The kernel driver negotiates over USB with the iOS device in
order to setup the link. The protocol used by both parties to
communicate don't really seemed documented publicly, and it seems
the protocol has evolved over time and iOS versions, and the Linux
driver hasn't been kept up to date. On macOS and Windows the driver
apparently comes with iTunes, and Apple engineers obviously know
how to communicate with iOS devices, so iOS 14 is supported just
fine.
There's an open
bug on libimobildevice (the set of userlands tools used to
communicate with iOS devices, although the update should be done in
the
kernel), with some debugging and communication logs between
Windows and an iOS device, but so far no real progress has been
done. The link is enabled, the host gets an IP from the device, can
ping the device IP and can even resolve name using the device DNS
resolver, but IP forwarding seems disabled, no packet goes farther
than the device itself.
That means a lot of people upgrading to iOS 14 will suddenly
lose USB tethering. While Wi-Fi and Bluetooth connection sharing
still works, it's still suboptimal, so it'd be nice to fix the
kernel driver and support the latest protocol used in iOS 14.
If someone knows the right contact (or the right way to contact
them) at Apple so we can have access to some kind of documentation
on the protocol and the state machine to use, please reach us
(either to the libimobile device bug or to my email address
below).
Thanks!
Mexico was one of the first countries in the world to set up a
national population registry in the late 1850s, as part of the
church-state separation that was for long years one of the national
sources of pride.
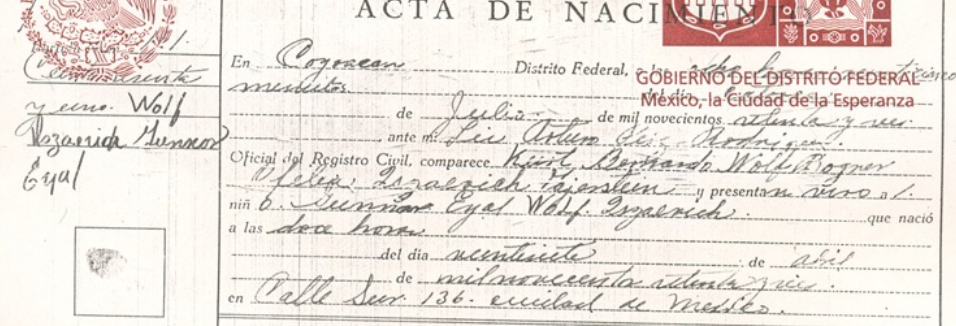
Forty four years ago, when I was born, keeping track of the population
was still mostly a manual task. When my parents registered me, my data
was stored in page 161 of book 22, year 1976, of the 20th Civil
Registration office in Mexico City. Faithful to the legal tradition,
everything is handwritten and specified in full. Because, why would
they write 1976.04.27 (or even 27 de abril de 1976) when they
could spell out d a veintisiete de abril de mil novecientos setenta y
seis? Numbers seem to appear only for addresses.
So, the State had record of a child being born, and we knew where to
look if we came to need this information. But, many years later, a
very sensible tecnification happened: all records (after a certain
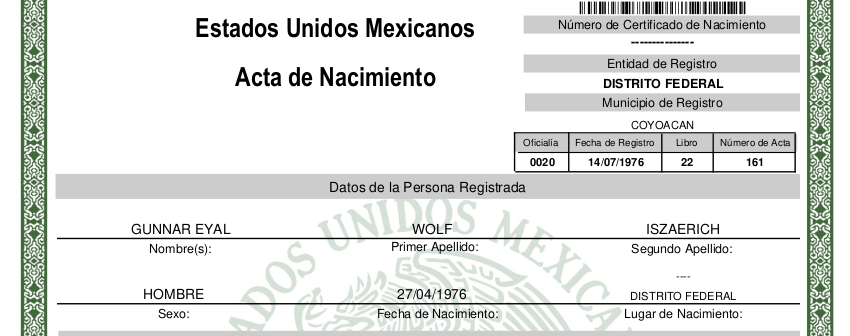
date, I guess) were digitized. Great news! I can now get my birth
certificate without moving from my desk, paying a quite reasonable fee
(~US$4). What s there not to like?
Digitally certified and all! So great! But But Oh, there s a
problem.
Of course Making sense of the handwriting as you can see is
somewhat prone to failure. And I cannot blame anybody for failing to
understand the details of my record.
So, my mother s first family name is Iszaevich. It was digitized as
Iszaerich. Fortunately, they do acknowledge some errors could have
made it into the process, and there is a process to report and
correct
errors.
What s there not to like?
Oh That they do their best to emulate a public office using online
tools. I followed some links in that link to get the address to
contact and yesterday night sent them the needed documents. Quite
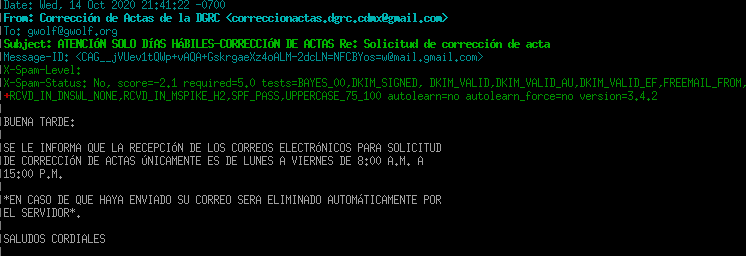
immediately, I got an answer that I must share with the world:
Yes, the mailing contact is in the @gmail.com domain. I could care
about them not using a @ .gob.mx address, but I ll let it slip. The
mail I got says (uppercase and all):
GOOD EVENING,
WE INFORM YOU THAT THE RECEPTION OF E-MAILS FOR REQUESTING
CORRECTIONS IN CERTIFICATES IS ONLY ACTIVE MONDAY THROUGH FRIDAY,
8:00 TO 15:00.
*IN CASE YOU SENT A MAIL OUTSIDE THE WORKING HOURS, IT WILL BE
AUTOMATICALLY DELETED BY THE SERVER*
CORDIAL GREETINGS,
I would only be half-surprised if they were paying the salary of
somebody to spend the wee hours of the night receiving and deleting
mails from their GMail account.
A new release of the dang package is now on CRAN, roughly one year after the last release. The dang package regroups a few functions of mine that had no other home as for example lsos() from a StackOverflow question from 2009 (!!) is one, this overbought/oversold price band plotter from an older blog post is another. More recently added were helpers for data.table to xts conversion and a git repo root finder.
This release adds two functions. One was mentioned just days ago in a tweet by Nathan and is a reworked version of something Colin tweeted about a few weeks ago: a little data wrangling off the kewl rtweet to find maximally spammy accounts per search topic. In other words those who include more than N hashtags for given search term. The other is something I, if memory serves, picked up a while back on one of the lists: a base R function to identify non-ASCII characters in a file. It is a C function that is not directly exported by and hence no accessible, so we put it here (with credits, of course). I mentioned it yesterday when announcing tidyCpp as I this C function was the starting point for the new tidyCpp wrapper around some C API of R functions.
The (very short) NEWS entry follows.
Changes in version 0.0.12 (2020-10-14)
New functions muteTweets and checkPackageAsciiCode.
Over the last year or so I have worked on a research linux distribution in my
spare time. It s not a distribution for researchers (like Scientific
Linux), but my personal
playground project to research linux distribution development, i.e. try out
fresh ideas.
This article focuses on the package format and its advantages, but there is
more to distri, which I will cover in upcoming blog posts.
Motivation
I was a Debian Developer for the 7 years from 2012 to 2019, but using the
distribution often left me frustrated, ultimately resulting in me winding down
my Debian work.
Frequently, I was noticing a large gap between the actual speed of an operation
(e.g. doing an update) and the possible speed based on back of the envelope
calculations. I wrote more about this in my blog post Package managers are
slow .
To me, this observation means that either there is potential to optimize the
package manager itself (e.g. apt), or what the system does is just too
complex. While I remember seeing some low-hanging fruit , through my work on
distri, I wanted to explore whether all the complexity we currently have in
Linux distributions such as Debian or Fedora is inherent to the problem space.
I have completed enough of the experiment to conclude that the complexity is not
inherent: I can build a Linux distribution for general-enough purposes which is
much less complex than existing ones.
Those were low-hanging fruit from a user perspective. I m not saying that
fixing them is easy in the technical sense; I know too little about apt s code
base to make such a statement.
Key idea: packages are images, not archives
One key idea is to switch from using archives to using images for package
contents. Common package managers such as dpkg(1)
use tar(1)
archives with various compression
algorithms.
distri uses SquashFS images, a
comparatively simple file system image format that I happen to be familiar with
from my work on the gokrazy Raspberry Pi 3 Go platform.
This idea is not novel: AppImage and
snappy also use
images, but only for individual, self-contained applications. distri however
uses images for distribution packages with dependencies. In particular, there is
no duplication of shared libraries in distri.
A nice side effect of using read-only image files is that applications are
immutable and can hence not be broken by accidental (or malicious!)
modification.
Key idea: separate hierarchies
Package contents are made available under a fully-qualified path. E.g., all
files provided by package zsh-amd64-5.6.2-3 are available under
/ro/zsh-amd64-5.6.2-3. The mountpoint /ro stands for read-only, which is
short yet descriptive.
Perhaps surprisingly, building software with custom prefix values of
e.g. /ro/zsh-amd64-5.6.2-3 is widely supported, thanks to:
Linux distributions, which build software with prefix set to /usr,
whereas FreeBSD (and the autotools default), which build with prefix set to
/usr/local.
Enthusiast users in corporate or research environments, who install software
into their home directories.
Because using a custom prefix is a common scenario, upstream awareness for
prefix-correctness is generally high, and the rarely required patch will be
quickly accepted.
Key idea: exchange directories
Software packages often exchange data by placing or locating files in well-known
directories. Here are just a few examples:
zsh(1)
locates executable programs via PATH components such as /bin
In distri, these locations are called exchange directories and are provided
via FUSE in /ro.
Exchange directories come in two different flavors:
global. The exchange directory, e.g. /ro/share, provides the union of the
share sub directory of all packages in the package store.
Global exchange directories are largely used for compatibility, see
below.
per-package. Useful for tight coupling: e.g. irssi(1)
does not provide any ABI guarantees, so plugins such as irssi-robustirc
can declare that they want
e.g. /ro/irssi-amd64-1.1.1-1/out/lib/irssi/modules to be a per-package
exchange directory and contain files from their lib/irssi/modules.
Search paths sometimes need to be fixed
Programs which use exchange directories sometimes use search paths to access
multiple exchange directories. In fact, the examples above were taken from gcc(1)
s INCLUDEPATH, man(1)
s MANPATH and zsh(1)
s PATH. These are
prominent ones, but more examples are easy to find: zsh(1)
loads completion functions from its FPATH.
Some search path values are derived from --datadir=/ro/share and require no
further attention, but others might derive from
e.g. --prefix=/ro/zsh-amd64-5.6.2-3/out and need to be pointed to an exchange
directory via a specific command line flag.
FHS compatibility
Global exchange directories are used to make distri provide enough of the
Filesystem Hierarchy Standard
(FHS) that
third-party software largely just works. This includes a C development
environment.
I successfully ran a few programs from their binary packages such as Google
Chrome, Spotify, or Microsoft s Visual Studio Code.
Fast package manager
I previously wrote about how Linux distribution package managers are too slow.
distri s package manager is extremely fast. Its main bottleneck is typically the network link, even at high speed links (I tested with a 100 Gbps link).
Its speed comes largely from an architecture which allows the package manager to
do less work. Specifically:
Package images can be added atomically to the package store, so we can safely
skip fsync(2)
. Corruption will be cleaned up
automatically, and durability is not important: if an interactive
installation is interrupted, the user can just repeat it, as it will be fresh
on their mind.
Because all packages are co-installable thanks to separate hierarchies, there
are no conflicts at the package store level, and no dependency resolution (an
optimization problem requiring SAT
solving) is required at all.
In exchange directories, we resolve conflicts by selecting the package with the
highest monotonically increasing distri revision number.
distri proves that we can build a useful Linux distribution entirely without
hooks and triggers. Not having to
serialize hook execution allows us to download packages into the package
store with maximum concurrency.
Because we are using images instead of archives, we do not need to unpack
anything. This means installing a package is really just writing its package
image and metadata to the package store. Sequential writes are typically the
fastest kind of storage usage pattern.
Fast installation also make other use-cases more bearable, such as creating disk
images, be it for testing them in qemu(1)
, booting
them on real hardware from a USB drive, or for cloud providers such as Google
Cloud.
Fast package builder
Contrary to how distribution package builders are usually implemented, the
distri package builder does not actually install any packages into the build
environment.
Instead, distri makes available a filtered view of the package store (only
declared dependencies are available) at /ro in the build environment.
This means that even for large dependency trees, setting up a build environment
happens in a fraction of a second! Such a low latency really makes a difference
in how comfortable it is to iterate on distribution packages.
Package stores
In distri, package images are installed from a remote package store into the
local system package store /roimg, which backs the /ro mount.
A package store is implemented as a directory of package images and their
associated metadata files.
You can easily make available a package store by using distri export.
To provide a mirror for your local network, you can periodically distri update
from the package store you want to mirror, and then distri export your local
copy. Special tooling (e.g. debmirror in Debian) is not required because
distri install is atomic (and update uses install).
Producing derivatives is easy: just add your own packages to a copy of the
package store.
The package store is intentionally kept simple to manage and distribute. Its
files could be exchanged via peer-to-peer file systems, or synchronized from an
offline medium.
distri s first release
distri works well enough to demonstrate the ideas explained above. I have
branched this state into branch
jackherer, distri s first
release code name. This way, I can keep experimenting in the distri repository
without breaking your installation.
From the branch contents, our autobuilder creates:
Project outlook
Right now, distri is mainly a vehicle for my spare-time Linux distribution
research. I don t recommend anyone use distri for anything but research, and
there are no medium-term plans of that changing. At the very least, please
contact me before basing anything serious on distri so that we can talk about
limitations and expectations.
I expect the distri project to live for as long as I have blog posts to publish,
and we ll see what happens afterwards. Note that this is a hobby for me: I will
continue to explore, at my own pace, parts that I find interesting.
My hope is that established distributions might get a useful idea or two from
distri.
There s more to come: subscribe to the distri feed
I don t want to make this post too long, but there is much more!
Please subscribe to the following URL in your feed reader to get all posts about
distri:
https://michael.stapelberg.ch/posts/tags/distri/feed.xml
Next in my queue are articles about hermetic packages and good package
maintainer experience (including declarative packaging).
Feedback or questions?
I d love to discuss these ideas in case you re interested!
Please send feedback to the distri mailing
list so that everyone can participate!
This is a follow-up from the blog post of Russel as seen here: https://etbe.coker.com.au/2020/10/13/first-try-gnocchi-statsd/. There s a bunch of things he wrote which I unfortunately must say is inaccurate, and sometimes even completely wrong. It is my point of view that none of the reported bugs are helpful for anyone that understand Gnocchi and how to set it up. It s however a terrible experience that Russell had, and I do understand why (and why it s not his fault). I m very much open on how to fix this on the packaging level, though some things aren t IMO fixable. Here s the details.
1/ The daemon startups
First of all, the most surprising thing is when Russell claimed that there s no startup scripts for the Gnocchi daemons. In fact, they all come with both systemd and sysv-rc support:
# ls /lib/systemd/system/gnocchi-api.service /lib/systemd/system/gnocchi-api.service # /etc/init.d/gnocchi-api /etc/init.d/gnocchi-api
Russell then tried to start gnocchi-api without the good options that are set in the Debian scripts, and not surprisingly, this failed. Russell attempted to do what was in the upstream doc, which isn t adapted to what we have in Debian (the upstream doc is probably completely outdated, as Gnocchi is unfortunately not very well maintained upstream).
The bug #972087 is therefore, IMO not valid.
2/ The database setup
By default for all things OpenStack in Debian, there are some debconf helpers using dbconfig-common to help users setup database for their services. This is clearly for beginners, but that doesn t prevent from attempting to understand what you re doing. That is, more specifically for Gnocchi, there are 2 databases: one for Gnocchi itself, and one for the indexer, which not necessarily is using the same backend. The Debian package already setups one database, but one has to do it manually for the indexer one. I m sorry this isn t well enough documented.
Now, if some package are supporting sqlite as a backend (since most things in OpenStack are using SQLAlchemy), it looks like Gnocchi doesn t right now. This is IMO a bug upstream, rather than a bug in the package. However, I don t think the Debian packages are to be blame here, as they simply offer a unified interface, and it s up to the users to know what they are doing. SQLite is anyway not a production ready backend. I m not sure if I should close #971996 without any action, or just try to disable the SQLite backend option of this package because it may be confusing.
3/ The metrics UUID
Russell then thinks the UUID should be set by default. This is probably right in a single server setup, however, this wouldn t work setting-up a cluster, which is probably what most Gnocchi users will do. In this type of environment, the metrics UUID must be the same on the 3 servers, and setting-up a random (and therefore different) UUID on the 3 servers wouldn t work. So I m also tempted to just close #972092 without any action on my side.
4/ The coordination URL
Since Gnocchi is supposed to be setup with more than one server, as in OpenStack, having an HA setup is very common, then a backend for the coordination (ie: sharing the workload) must be set. This is done by setting an URL that tooz understand. The best coordinator being Zookeeper, something like this should be set by hand:
coordination_url=zookeeper://192.168.101.2:2181/
Here again, I don t think the Debian package is to be blamed for not providing the automation. I would however accept contributions to fix this and provide the choice using debconf, however, users would still need to understand what s going on, and setup something like Zookeeper (or redis, memcache, or any other backend supported by tooz) to act as coordinator.
5/ The Debconf interface cannot replace a good documentation
and there s not so much I can do at my package maintainer level for this.
Russell, I m really sorry for the bad user experience you had with Gnocchi. Now that you know a little big more about it, maybe you can have another go? Sure, the OpenStack telemetry system isn t an easy to understand beast, but it s IMO worth trying. And the recent versions can scale horizontally
A new package arrived on CRAN a few days ago. It offers a few headers files which wrap (parts) of the C API for R, but in a form that may be a little easier to use for C++ programmers. I have always liked how in Rcpp we offer good parts of the standalone R Math library in a namespace R::. While working recently with a particular C routine (for checking non-ASCII characters that will be part of the next version of the dang package which collecting various goodies in one place), I realized there may be value in collecting a few more such wrappers. So I started a few simple ones starting from simple examples.
Currently we have five headers defines.h, globals.h, internals.h, math.h, and shield.h. The first four each correpond to an R header file of the same or similar name, and the last one brings a simple yet effective alternative to PROTECT and UNPROTECT from Rcpp (in a slightly simplified way). None of the headers are complete , for internals.h in particular a lot more could be added (as I noticed today when experimenting with another source file that may be converted). All of the headers can be accessed with a simple #include <tidyCpp> (which, following another C++ convention, does not have a .h or .hpp suffix). And a the package ships these headers, packages desiring to use them only need LinkingTo: tidyCpp.
As usage examples, we (right now) have four files in the snippets/ directory of the package. Two of these, convolveExample.cpp and dimnamesExample.cpp both illustrate how one could change example code from Writing R Extensions. Then there are also a very simple defineExample.cpp and a shieldExample.cpp illustrating how much easier Shield() is compared to PROTECT and UNPROTECT.
Finally, there is a nice vignette discussing the package motivation with two detailed side-by-side before and after examples that are the aforementioned convolution and dimnames examples.
Over time, I expect to add more definitions and wrappers. Feedback would be welcome it seems to hit a nerve already as it currently has more stars than commits even though (prior to this post) I had yet to tweet or blog about it. Please post comments and suggestions at the GitHub repo.
If you like this or other open-source work I do, you can now sponsor me at GitHub. For the first year, GitHub will match your contributions.
The Reproducible Builds project intends to resume meeting regularly on IRC, starting today, Monday October 12th, at 18:00 UTC.
Sadly, due to the unprecedented events in 2020, there will be no in-person Reproducible Builds event this year, but please join us on the #reproducible-builds channel on irc.oftc.net. An editable agenda is available. The cadence of these meetings will probably be every two weeks, although this will be discussed and decided on at the first meeting.
The first time Linda Tirado came to the viral attention of the Internet
was in 2013 when she responded to a forum question: "Why do poor people do
things that seem so self-destructive?" Here are some excerpts from her
virally popular five-page response, which is included in the first
chapter:
I know how to cook. I had to take Home Ec. to graduate high school.
Most people on my level didn't. Broccoli is intimidating. You have
to have a working stove, and pots, and spices, and you'll have to do
the dishes no matter how tired you are or they'll attract bugs. It is
a huge new skill for a lot of people. That's not great, but it's
true. And if you fuck it up, you could make your family sick. We
have learned not to try too hard to be middle class. It never works
out well and always makes you feel worse for having tried and failed
yet again. Better not to try. It makes more sense to get food that
you know will be palatable and cheap and that keeps well. Junk food
is a pleasure that we are allowed to have; why would we give that up?
We have very few of them.
and
I smoke. It's expensive. It's also the best option. You see, I am
always, always exhausted. It's a stimulant. When I am too tired to
walk one more step, I can smoke and go for another hour. When I am
enraged and beaten down and incapable of accomplishing one more thing,
I can smoke and I feel a little better, just for a minute. It is the
only relaxation I am allowed. It is not a good decision, but it is
the only one that I have access to. It is the only thing I have found
that keeps me from collapsing or exploding.
This book is an expansion on that essay. It's an entry in a growing genre
of examinations of what it means to be poor in the United States in the
21st century. Unlike most of those examinations, it isn't written by an
outsider performing essentially anthropological field work. It's one of
the rare books written by someone who is herself poor and had the
combination of skill and viral fame required to get an opportunity to talk
about it in her own words.
I haven't had it worse than anyone else, and actually, that's kind of
the point. This is just what life is for roughly a third of the
country. We all handle it in our own ways, but we all work in the
same jobs, live in the same places, feel the same sense of never quite
catching up. We're not any happier about the exploding welfare rolls
than anyone else is, believe me. It's not like everyone grows up and
dreams of working two essentially meaningless part-time jobs while
collecting food stamps. It's just that there aren't many other
options for a lot of people.
I didn't find this book back in 2014 when it was published. I found it in
2020 during Tirado's second round of Internet fame: when the police shot
out her eye with "non-lethal" rounds while she was covering the George
Floyd protests as a photojournalist. In characteristic fashion, she
subsequently reached out to the other people who had been blinded by the
police, used her temporary fame to organize crowdfunded support for
others, and is planning on having "try again" tattooed over the scar.
That will give you a feel for the style of this book. Tirado is blunt,
opinionated, honest, and full speed ahead. It feels weird to call this
book delightful since it's fundamentally about the degree to which the
United States is failing a huge group of its citizens and making their
lives miserable, but there is something so refreshing and clear-headed
about Tirado's willingness to tell you the straight truth about her life.
It's empathy delivered with the subtlety of a brick, but also with about
as much self-pity as a brick. Tirado is not interested in making you feel
sorry for her; she's interested in you paying attention.
I don't get much of my own time, and I am vicious about protecting
it. For the most part, I am paid to pretend that I am inhuman, paid
to cater to both the reasonable and unreasonable demands of the
general public. So when I'm off work, feel free to go fuck yourself.
The times that I am off work, awake, and not taking care of life's
details are few and far between. It's the only time I have any
autonomy. I do not choose to waste that precious time worrying about
how you feel. Worrying about you is something they pay me for; I
don't work for free.
If you've read other books on this topic (Emily Guendelsberger's
On the Clock is still the best of those
I've read), you probably won't get many new facts from Hand to
Mouth. I think this book is less important for the policy specifics than
it is for who is writing it (someone who is living that life and can be
honest about it) and the depth of emotional specifics that Tirado brings
to the description. If you have never been poor, you will learn the
details of what life is like, but more significantly you'll get a feel for
how Tirado feels about it, and while this is one individual perspective
(as Tirado stresses, including the fact that, as a white person, there are
other aspects of poverty she's not experienced), I think that perspective
is incredibly valuable.
That said, Hand to Mouth provides even more reinforcement of the
importance of universal medical care, the absurdity of not including
dental care in even some of the more progressive policy proposals, and the
difficulties in the way of universal medical care even if we solve the
basic coverage problem. Tirado has significant dental problems due to
unrepaired damage from a car accident, and her account reinforces my
belief that we woefully underestimate how important good dental care is to
quality of life. But providing universal insurance or access is only the
start of the problem.
There is a price point for good health in America, and I have rarely
been able to meet it. I choose not to pursue treatment if it will
cost me more than it will gain me, and my cost-benefit is done in more
than dollars. I have to think of whether I can afford any potential
treatment emotionally, financially, and timewise. I have to sort out
whether I can afford to change my life enough to make any treatment
worth it I've been told by more than one therapist that I'd be fine
if I simply reduced the amount of stress in my life. It's true,
albeit unhelpful. Doctors are fans of telling you to sleep and eat
properly, as though that were a thing one can simply do.
That excerpt also illustrates one of the best qualities of this book. So
much writing about "the poor" treats them as an abstract problem that the
implicitly not-poor audience needs to solve, and this leads rather
directly to the endless moralizing as "we" attempt to solve that problem
by telling poor people what they need to do. Tirado is unremitting in
fighting for her own agency. She has a shitty set of options, but within
those options she makes her own decisions. She wants better options and
more space in which to choose them, which I think is a much more
productive way to frame the moral argument than the endless hand-wringing
over how to help "those poor people."
This is so much of why I support universal basic income. Just give people
money. It's not all of the solution UBI doesn't solve the problem of
universal medical care, and we desperately need to find a way to make work
less awful but it's the most effective thing we can do immediately.
Poor people are, if anything, much better at making consequential
financial decisions than rich people because they have so much more
practice. Bad decisions are less often due to bad decision-making than
bad options and the balancing of objectives that those of us who are not
poor don't understand.
Hand to Mouth is short, clear, refreshing, bracing, and, as you
might have noticed, very quotable. I think there are other books in this
genre that offer more breadth or policy insight, but none that have the
same feel of someone cutting through the bullshit of lazy beliefs and
laying down some truth. If any of the above excerpts sound like the sort
of book you would enjoy reading, pick this one up.
Rating: 8 out of 10
Benjy: The best-laid plans of mice...
Arthur: And men.
Frankie: What?
Arthur: Best-laid plans of mice and men.
Benjy: What have men got to do with it?
-- The Hitchhiker's Guide to the Galaxy TV series
Last year, my intent had been to post monthy updates with details of the F/LOSS
contributions I had made during the previous month. I wanted to do this as a
way to summarize and reflect on what I had done, and also to hopefully
motivate me to do more.
Fast forward, and it's been over a year since my last blog post. So much for
those plans.
I won't go into specific detail about the F/LOSS contributions I've made in the
past year. This isn't meant to be a "catch-up" post, per se. It's more of an
acknowledgement that I didn't do what I set out to do, as well as something
of a reset to enable me to continue blogging (or not) as I see fit.
So, to summarize those contributions:
As expected, most of my contributions were to projects that I regularly
contribute to, like Debian, Apache Axis2/C, or PasswordSafe.
There were also some one-off contributions to projects that I use but am not
actively involved in, such as log4cxx or PyKAN.
There was also a third category of contributions that are a bit of a special
case. I made some pseudonymous contributions to a F/LOSS project that I did
not want to tie to my public identity. I hope to write more about that
situation in a future post.
All in all, I'm pretty happy with the contributions I've made in the
past year. Historically, my F/LOSS activity had been somewhat sporadic,
sometimes with months passing in between contributions. But looking through
my notes from the past year, it appears that I made contributions every single
month, with no skipped months. Of course, I would have liked to have done more,
but I consider the improvement in consistency to be a solid win.
As for the blog, well... Judging by the most recent year-long gap (as well as
the gaps before that), I'm not likely to start regularly writing posts anytime
soon. But then again, if sporadic F/LOSS contribtutions can turn into
regular F/LOSS contributions, then maybe sporadic blog posts can turn into
regular blog posts, too. Time will tell.
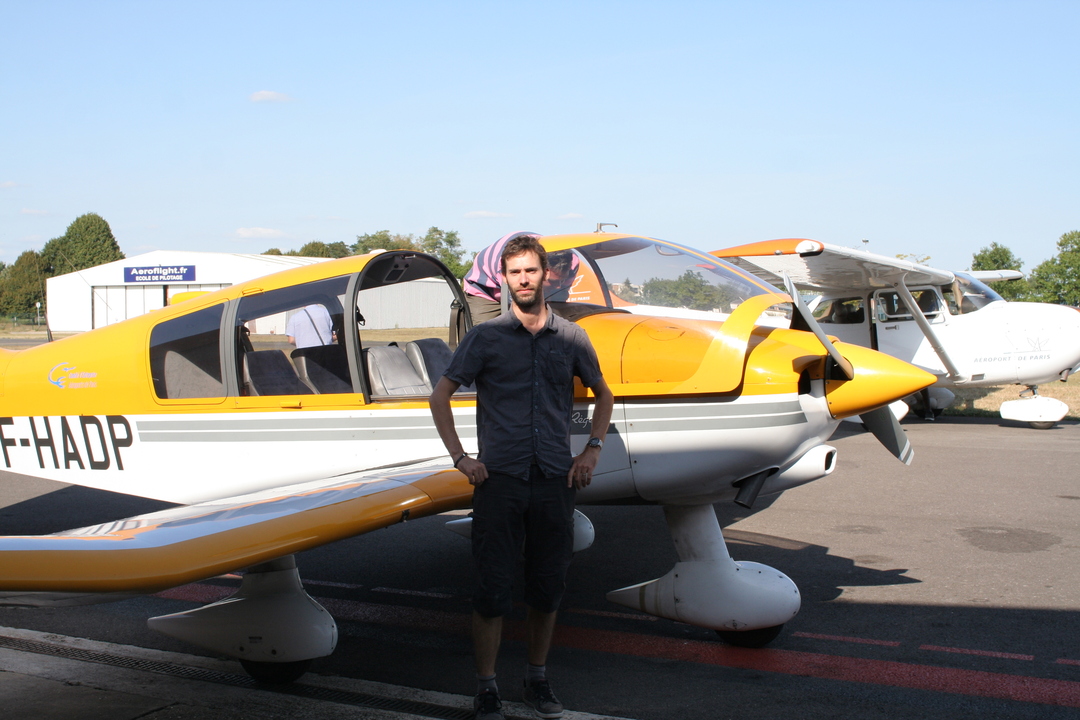
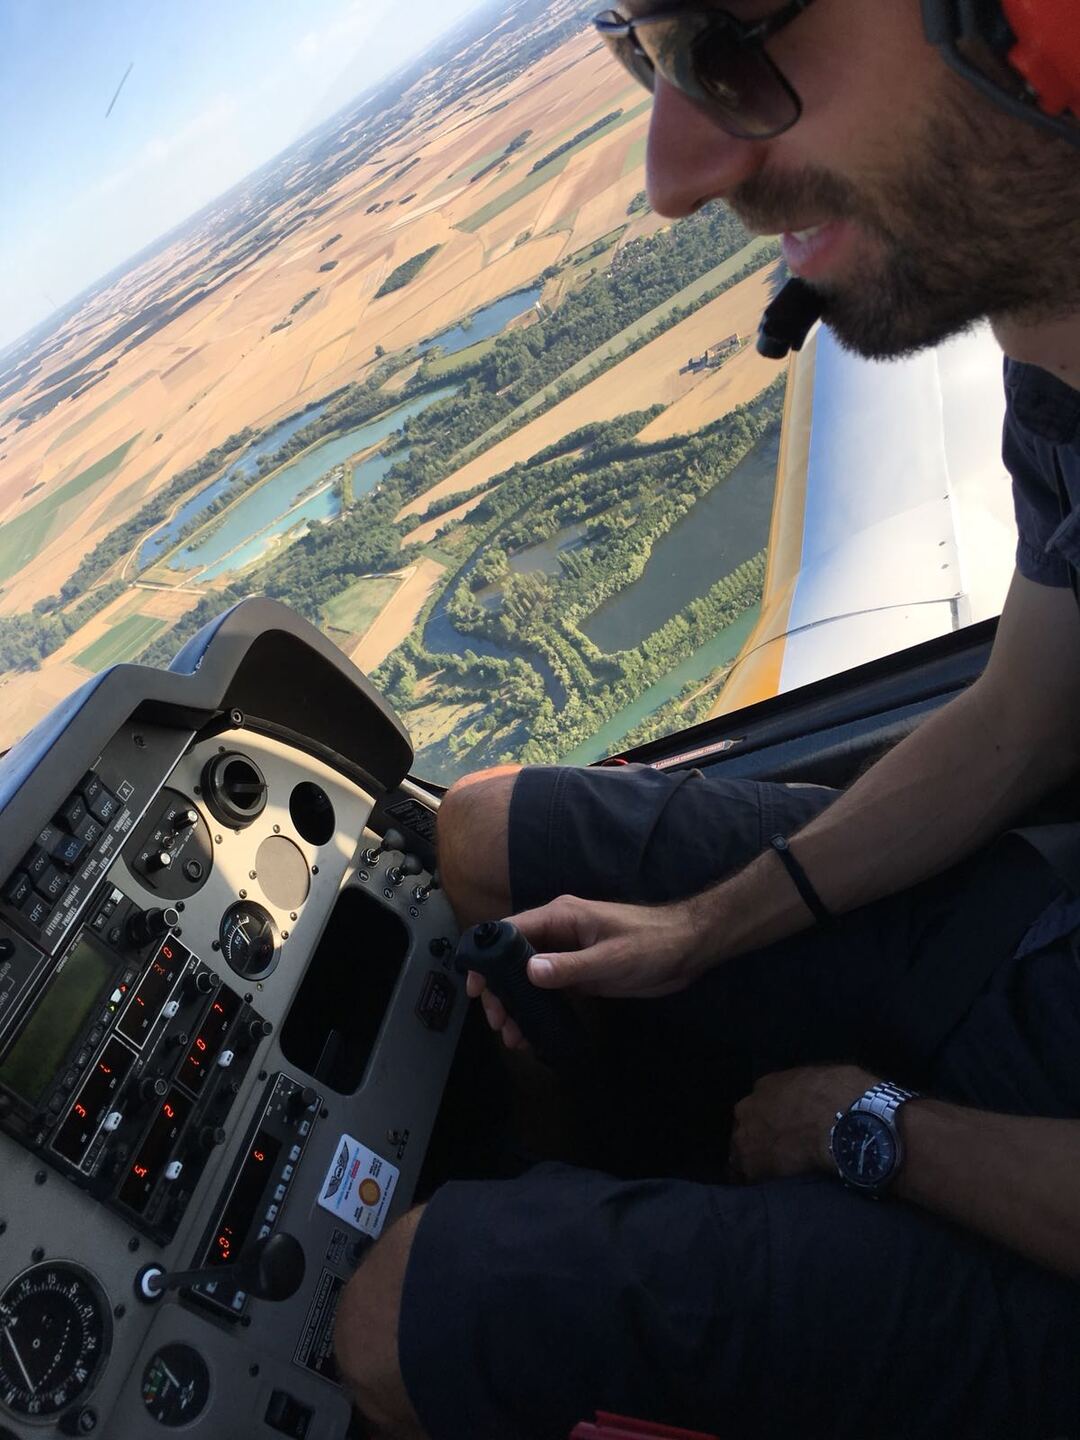
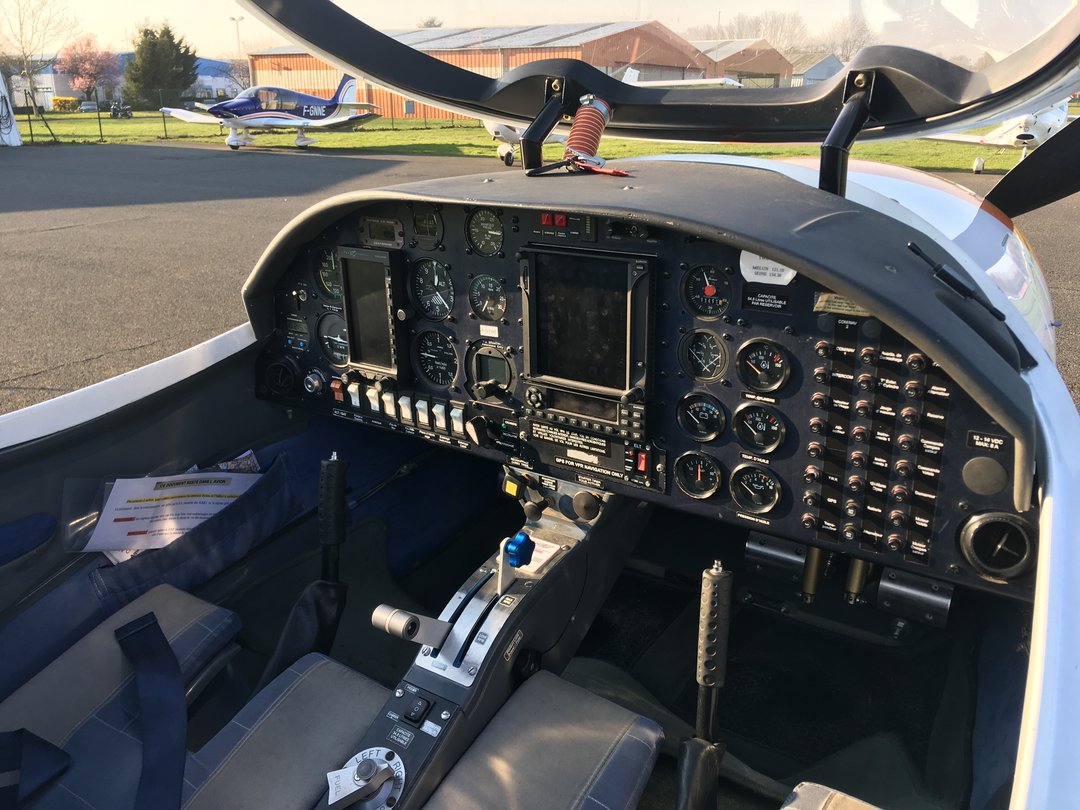
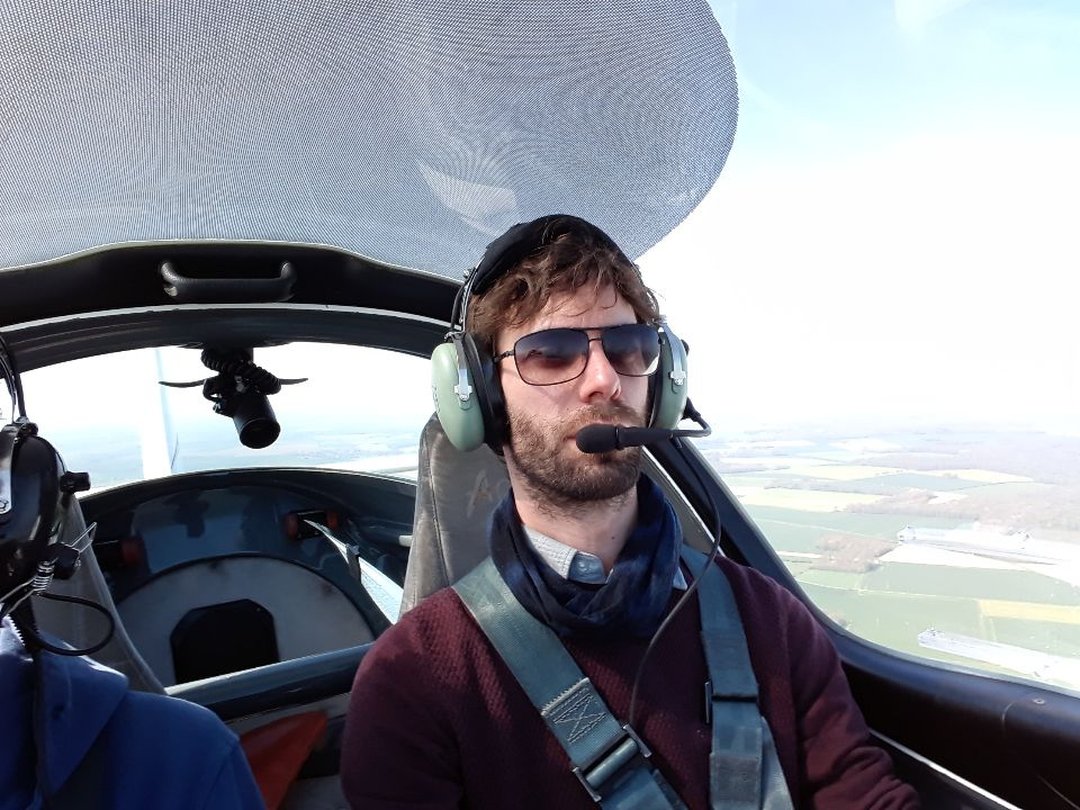
So, a bit more thank 18 months ago, I started a new adventure.
After a few flights with a friend of mine in a Robin DR400 and
Jodel aircrafts, I enlisted in a local flight club at the Lognes
airfield (LFPL), and started a Pilot Private License training. A
PPL is an international flight license for non commercial
operations. Associated with a qualification like the SEP (Single
Engine Piston), it enables you to fly basically anywhere in the
world (or at least anywhere where French is spoken by the air
traffic controllers) with passengers, under Visual Flight Rules
(VFR).
A bit like with cars, training has two parts, theoretical and
practical, both validated in a test. You don't have to pass the
theoretical test before starting the practical training, and it's
actually recommended to do both in parallel, especially since
nowadays most of the theoretical training is done online (you still
have to do 10h of in-person courses before taking the test).
So in March 2019 I started both trainings. Theoretical training is
divided in various domains, like regulations, flight mechanics,
meteorology, human factors etc. and you can obviously train in
parallel. Practical is more sequential and starts with basic flight
training (turns, climbs, descents), then take-off, then landing
configuration, then landing itself. All of that obviously with a
flight instructor sitting next to you (you're on the left seat but
the FI is the pilot in command ). You then start doing circuit
patterns, meaning you take off, do a circuit around the airfield,
then land on the runway you just took off. Usually you actually
don't do a complete landing but rather touch and go, and do it
again in order to have more and more landing training.
Once you know how to take-off, do a pattern and land when
everything is OK, you start practicing (still with your flight
instructor aboard) various failures: especially engine failures at
take off, but also flaps failure and stuff like that, all that
while still doing patterns and practicing landings. At one point,
the flight instructor deems you ready: he exits the plane, and you
start your first solo flight: engine tests, take off, one pattern,
landing.
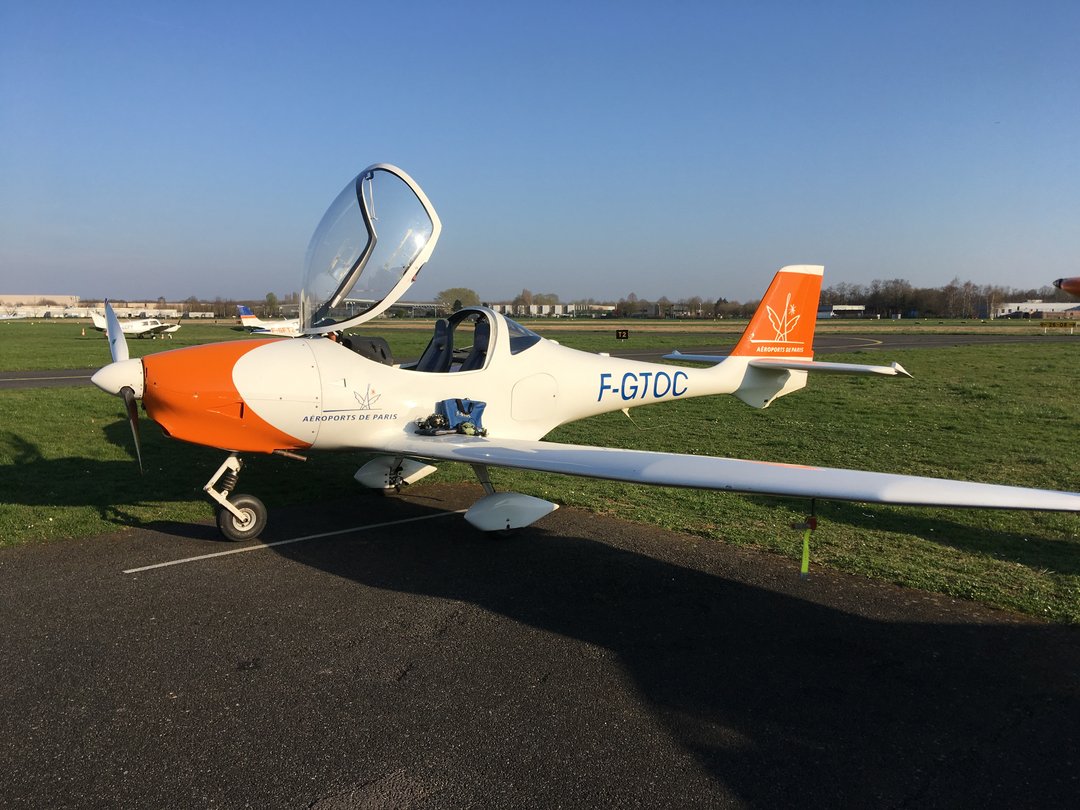
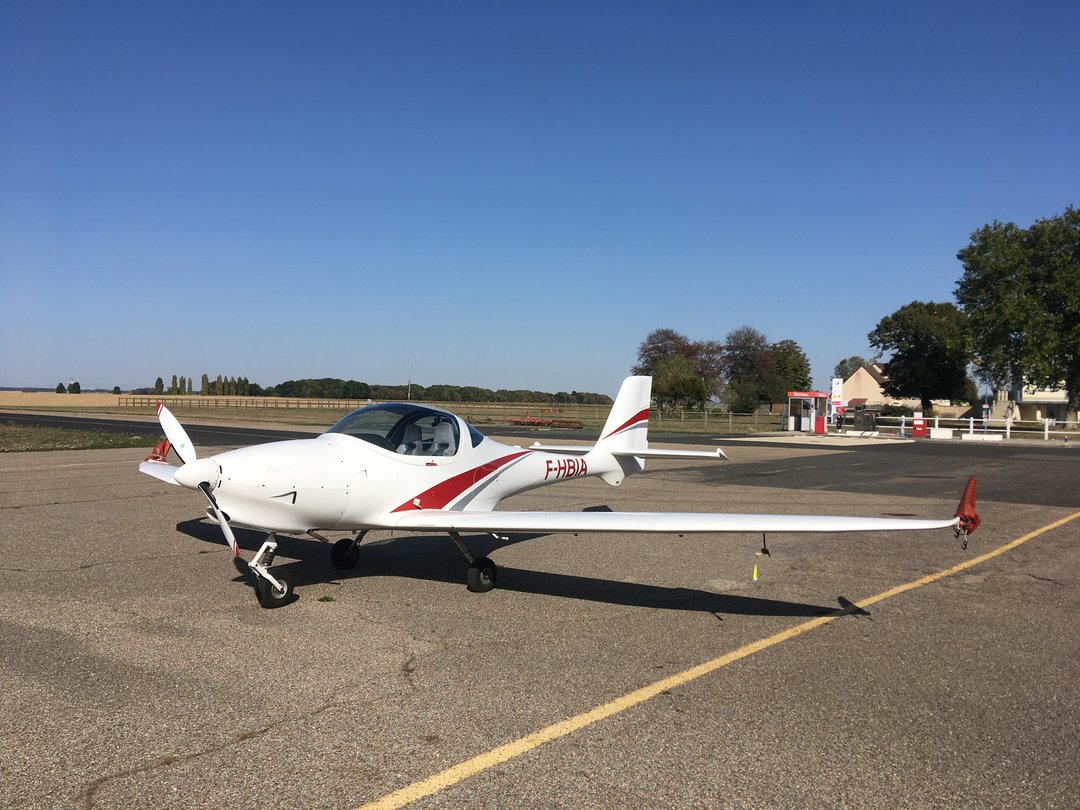
For me practical training was done in an Aquila AT-01/A210, which
is a small 2-seater. It's really light (it can actually be used as
an ultralight), empty weight is a bit above 500kg and max weight is
750. It doesn't go really fast (it cruises at around 100 knots, 185
km/h) but it's nice to fly. As it's really lightweight the wind
really shakes it though and it can be a bit hard to land because it
really glides very well (with a lift-to-drag ratio at 14). I tried
to fly a lot in the beginning, so the basic flight training was
done in about 6 months and 23 flight hours. At that point my
instructor stepped out of the plane and I did my first solo flight.
Everything actually went just fine, because we did repeat a lot
before that, so it wasn't even that scary. I guess I will remember
my whole life, as people said, but it was pretty uneventful,
although the controller did scold me a little because when taxiing
back to the parking I misunderstood the instructions and didn't
stop where asked (no runway incursion though).
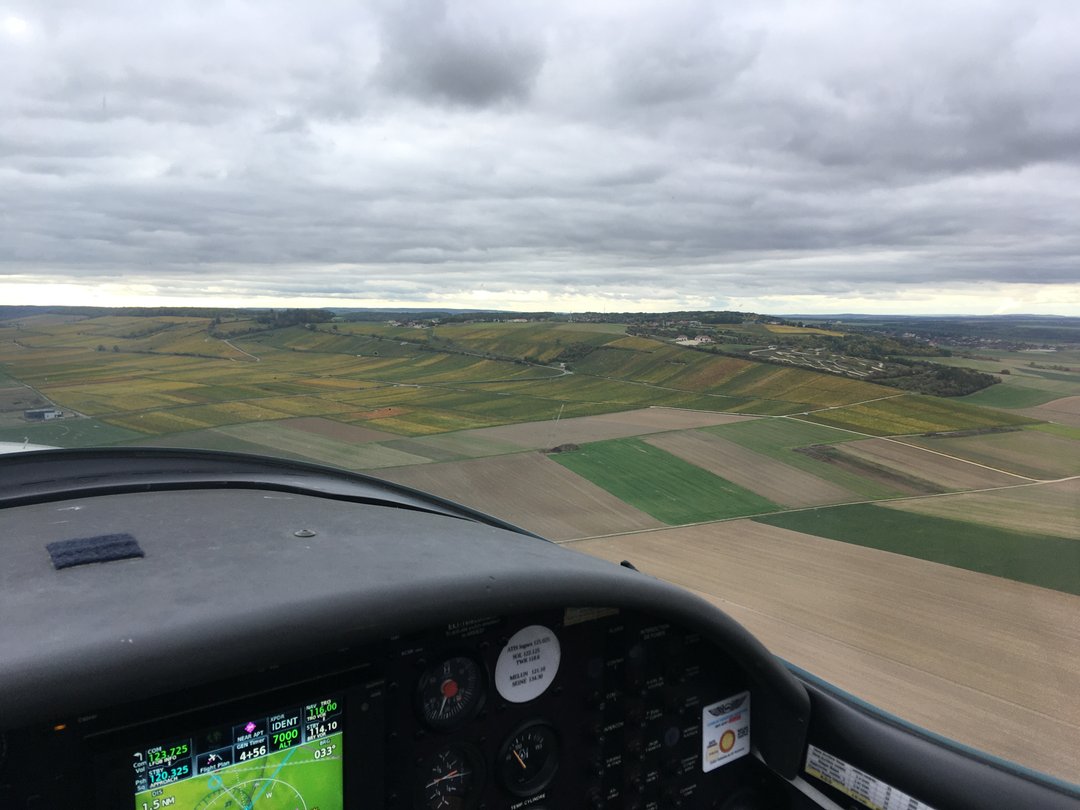
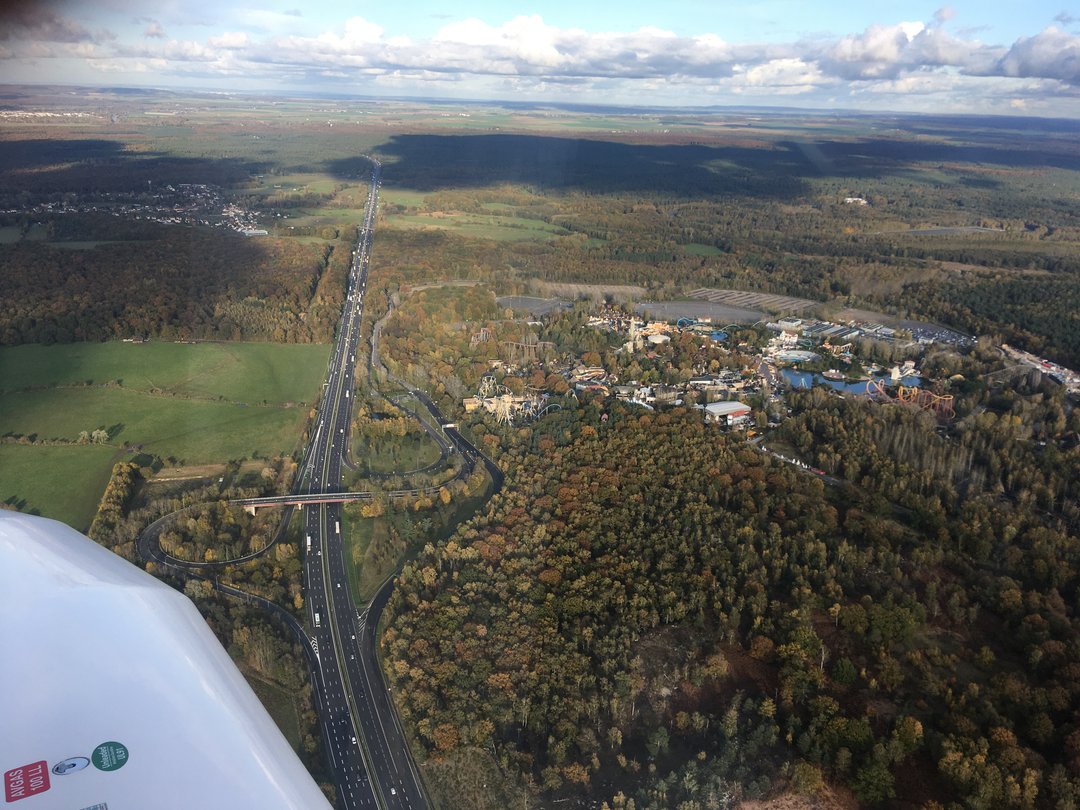
After the first solo flight, you keep practicing patterns and solo
flights every once in a while, and start doing cross-country
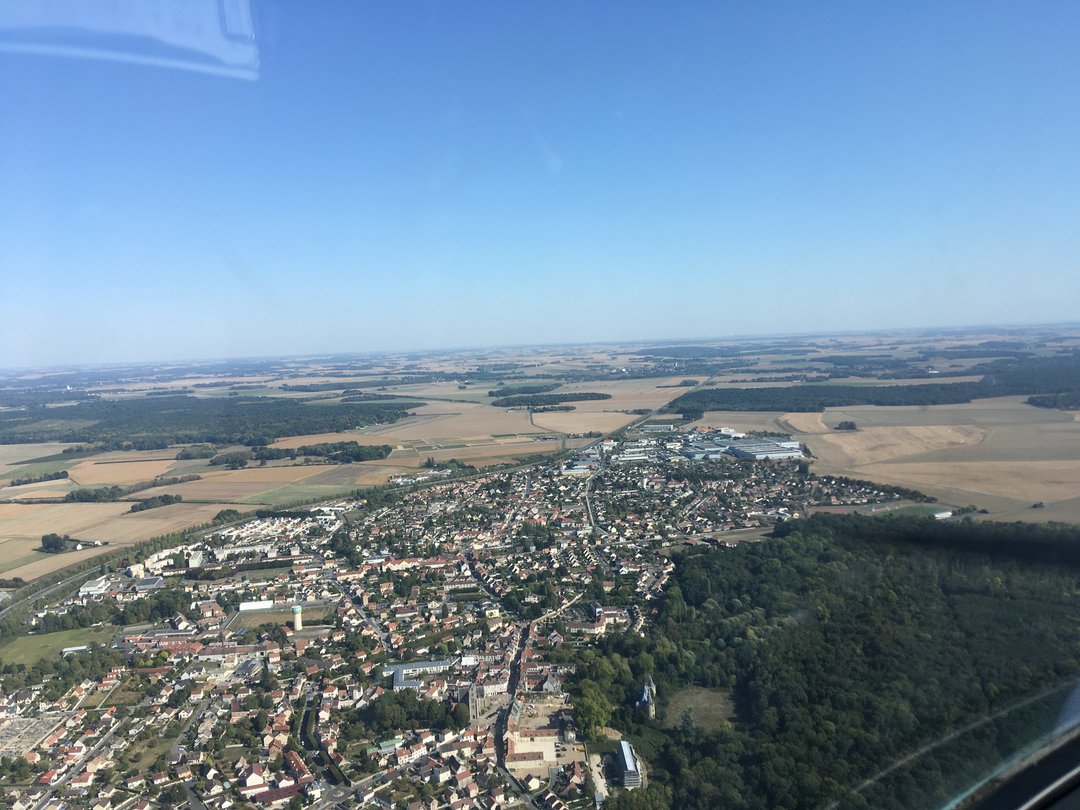
flights: you're not restricted to the local airfields (LFPL, LFAI,
LFPK) but start planning trips to more remote airports, about 30-40
minutes away (for me it was Moret/LFPU, Troyes/LFQB,
Pontoise/LFPT). Cross country flights requires you to plan the
route (draw it on the map, and write a navigation log so you know
what to do when in flight), but also check the weather, relevant
information, especially NOTAMs - Notice To Air Men (I hope someone
rename those Notice to Air Crews at one point), estimate the fuel
needed etc. For me, flight preparation time was between once and
twice the flight time. Early flight preparation is completed on the
day by last-minute checks, especially for weather. During the
briefing (with the flight instructor at first, but for the test
with the flight examiner and later with yourself) you check in turn
every bit of information to decide if you're GO or not for the
flight. As a lot of things in aviation, safety is really paramount
here.
Once you've practiced cross country flight a bit, you start
learning what to do in case of failures during a non-local flights,
for example an engine failure in a middle of nowhere, when you have
to chose a proper field to land, or a radio failure. And again when
you're ready for it (and in case of my local club, once you pass
your theoretical exam) you go for cross-country solo flights (of
the 10h of solo flight required for taking the test, 5h should be
done in cross-country flights). I went again to Troyes (LFQB), then
Dijon-Darois (LFGI) and did a three-legs flight to Chalons-Ecury
(LFQK) and Pont sur Yonne (LFGO).
And just after that, when I was starting to feel ready for the
test, COVID-19 lockdown happened, grounding everyone for a few
months. Even after it was over, I felt a bit rusty and had to take
some more training. I finally took the test in the beginning of
summer, but the first attempt wasn't good enough: I was really
stressed, and maybe not completely ready actually. So a bit more
training during summer, and finally in September I took the final
test part, which was successful this time.
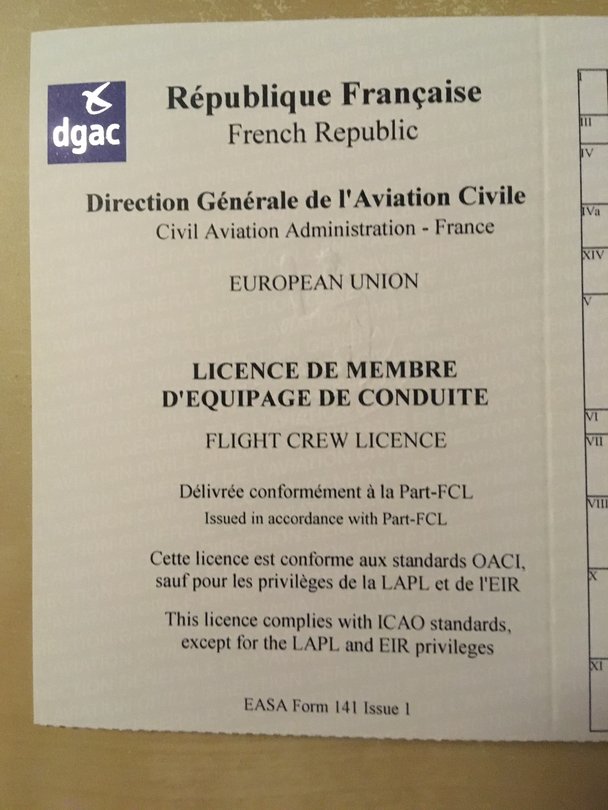
After some paperwork, a new, shiny, Pilot Private License arrived
at my door.
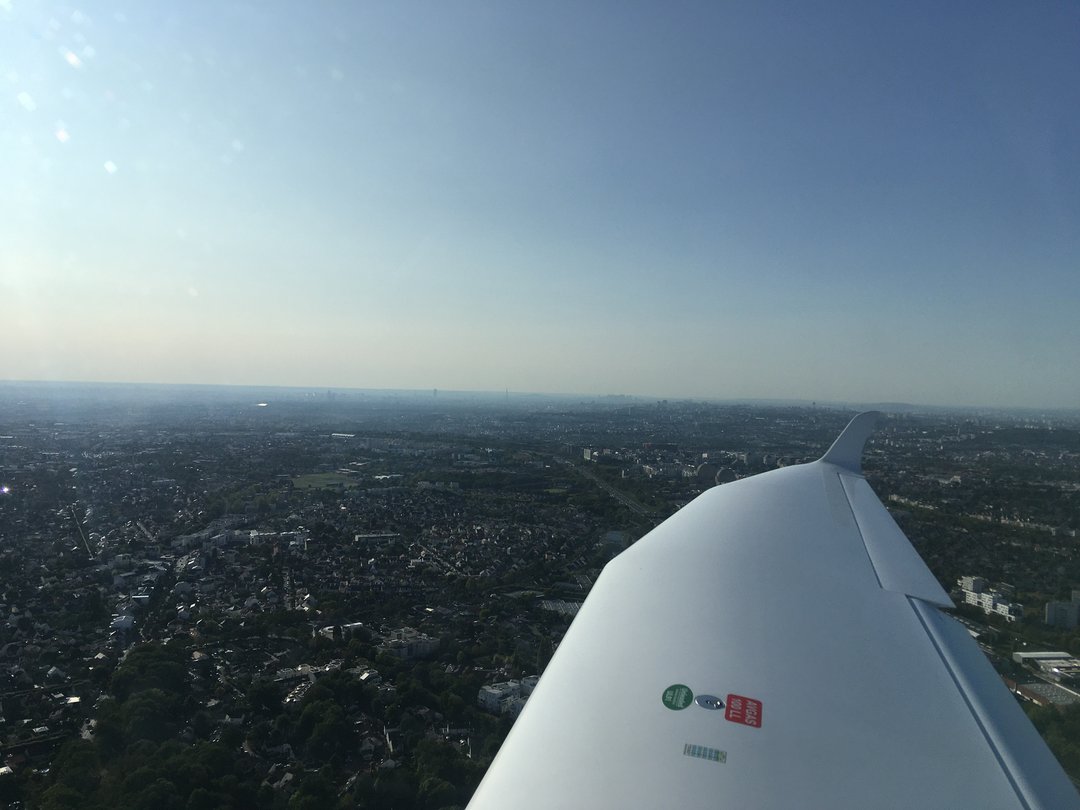
And now that I can fly basically when I want, the autumn is finally
here with bad weather all day long, so actually planning real
flights is a bit tricky. For now I'm still flying solo on familiar
trips, but at some point I should be able to bring a passenger with
me (on the Aquila) and at some point migrate to a four-seaters like
the DR400, ubiquitous in France.
A new RcppSimdJson release arrived on CRAN yesterday bringing along the simdjson 0.5.0 release that happened a few weeks.
RcppSimdJson wraps the fantastic and genuinely impressive simdjson library by Daniel Lemire and collaborators. Via very clever algorithmic engineering to obtain largely branch-free code, coupled with modern C++ and newer compiler instructions, it results in parsing gigabytes of JSON parsed per second which is quite mindboggling. The best-case performance is faster than CPU speed as use of parallel SIMD instructions and careful branch avoidance can lead to less than one cpu cycle per byte parsed; see the video of the talk by Daniel Lemire at QCon (also voted best talk).
Beside the upstream update, not too much happened to our package itself since 0.1.1 though Brandon did help one user to seriously speed up his JSON processing. The (this time very short) NEWS entry follows.
The thirteenth release of littler as a CRAN package became available today (after a three day rest at CRAN for no real reason), following in the fourteen-ish year history as a package started by Jeff in 2006, and joined by me a few weeks later.
littler is the first command-line interface for R as it predates Rscript. It allows for piping as well for shebang scripting via #!, uses command-line arguments more consistently and still starts faster. It also always loaded the methods package which Rscript only started to do in recent years.
littler lives on Linux and Unix, has its difficulties on macOS due to yet-another-braindeadedness there (who ever thought case-insensitive filesystems as a default where a good idea?) and simply does not exist on Windows (yet the build system could be extended see RInside for an existence proof, and volunteers are welcome!). See the FAQ vignette on how to add it to your PATH.
A few examples are highlighted at the Github repo, as well as in the examples vignette.
This release brings five new example scripts and command wrappers:
installDeps.r installs all dependencies of package (directory or tarball)
installRSPM.r relies on RSPM to install binary packages
installBSPM.r relies on BSPM to install binary packages (esp. on Linux)
cranIncomimg.r checks the incoming queue for one or more packages
urlUpdates.r checks and/or updates stale URLs leading to redirects
A number of commands were also extended or updated (see below for more). We have a new and very slick documentation website once again utilising Material for MkDocs. Last but not least the two included vignettes now use minidown and the fabulous water css theme which reduced the file sizes of the two vignettes from, respectively, 884kb and 873kb to 47kb and 15kb. Yes, that is correct. That alone brought the package file size down from 641kb to 116kb. Incredible.
The NEWS file entry is below.
Changes in littler version 0.3.12 (2020-10-04)
Changes in examples
Updates to scripts tt.r, cos.r, cow.r, c4r.r, com.r
New script installDeps.r to install dependencies
Several updates tp script check.r
New script installBSPM.r and installRSPM.r for binary package installation (Dirk and I aki in #81)
New script cranIncoming.r to check in Incoming
New script urlUpdate.r validates URLs as R does
Changes in package
Travis CI now uses BSPM
A package documentation website was added
Vignettes now use minidown resulting in much reduced filesizes: from over 800kb to under 50kb (Dirk in #83)
Here is the first QSoas quiz ! I recently measured several identical spectra in a row to evaluate the noise of the setup, and so I wanted to average all the spectra and also determine the standard deviation in the absorbances. Averaging the spectra can simply be done taking advantage of the average command:
QSoas> load Spectrum*.dat /flags=spectra
QSoas> average flagged:spectra
However, average does not provide means to make standard deviations, it just takes the average of all but the X column. I wanted to add this feature, but I realized there are already at least two distinct ways to do that...
One that relies simply on average and on apply-formula, and which requires that you remember how to compute standard deviations.
One that is a little more involved, that requires more data manipulation (take a look at contract for instance) and relies on the fact that you can use statistics in apply-formula (and in particular you can use y_stddev to refer to the standard deviation of \(y\)), but which does not require you to know exactly how to compute standard deviations.
To help you, I've added the result in Average.dat. The figure below shows a zoom on the data superimposed to the average (bonus points to find how to display this light red area that corresponds to the standard deviation !).
I will post the answer later. In the meantime, feel free to post your own solutions or attempts, hacks, and so on !
About QSoasQSoas is a powerful open source data analysis program that focuses on flexibility and powerful fitting capacities. It is released under the GNU General Public License. It is described in Fourmond, Anal. Chem., 2016, 88 (10), pp 5050 5052. Current version is 2.2. You can download its source code or buy precompiled versions for MacOS and Windows there.
Welcome to the September 2020 report from the Reproducible Builds project. In our monthly reports, we attempt to summarise the things that we have been up to over the past month, but if you are interested in contributing to the project, please visit our main website.
This month, the Reproducible Builds project was pleased to announce a donation from Amateur Radio Digital Communications (ARDC) in support of its goals. ARDC s contribution will propel the Reproducible Builds project s efforts in ensuring the future health, security and sustainability of our increasingly digital society. Amateur Radio Digital Communications (ARDC) is a non-profit which was formed to further research and experimentation with digital communications using radio, with a goal of advancing the state of the art of amateur radio and to educate radio operators in these techniques. You can view the full announcement as well as more information about ARDC on their website.
In August s report, we announced that Jennifer Helsby (redshiftzero) launched a new reproduciblewheels.com website to address the lack of reproducibility of Python wheels . This month, Kushal Das posted a brief follow-up to provide an update on reproducible sources as well.
The Threema privacy and security-oriented messaging application announced that within the next months , their apps will become fully open source, supporting reproducible builds :
This is to say that anyone will be able to independently review Threema s security and verify that the published source code corresponds to the downloaded app.
The previous year has seen great progress in Arch Linux to get reproducible builds in the hands of the users and developers. In this talk we will explore the current tooling that allows users to reproduce packages, the rebuilder software that has been written to check packages and the current issues in this space.
During the Reproducible Builds summit in Marrakesh, GNU Guix, NixOS and Debian were able to produce a bit-for-bit identical binary when building GNU Mes, despite using three different major versions of GCC. Since the summit, additional work resulted in a bit-for-bit identical Mes binary using tcc and this month, a fuller update was posted by the individuals involved.
diffoscopediffoscope is our in-depth and content-aware diff utility that can not only locate and diagnose reproducibility issues, it provides human-readable diffs of all kinds too.
In September, Chris Lamb made the following changes to diffoscope, including preparing and uploading versions 159 and 160 to Debian:
New features:
Show ordering differences only in strings(1) output by applying the ordering check to all differences across the codebase. []
Bug fixes:
Mark some PGP tests that they require pgpdump, and check that the associated binary is actually installed before attempting to run it. (#969753)
Don t raise exceptions when cleaning up after guestfs cleanup failure. []
Ensure we check FALLBACK_FILE_EXTENSION_SUFFIX, otherwise we run pgpdump against all files that are recognised by file(1) as data. []
Codebase improvements:
Add some documentation for the EXTERNAL_TOOLS dictionary. []
Abstract out a variable we use a couple of times. []
Improve the documentation on how to signup to Salsa. []
Add some more links to academic papers. []
Also include the general news in our RSS feed [] and drop including weekly reports from the RSS feed (they are never shown now that we have over 10 items) [].
Update ordering and location of various news and links to tarballs, etc. [][][]
In addition, Holger Levsen re-added the documentation link to the top-level navigation [] and documented that the jekyll-polyglot package is required []. Lastly, diffoscope.org and reproducible-builds.org were transferred to Software Freedom Conservancy. Many thanks to Brett Smith from Conservancy, J r my Bobbio (lunar) and Holger Levsen for their help with transferring and to Mattia Rizzolo for initiating this.
Upstream patches
The Reproducible Builds project detects, dissects and attempts to fix as many currently-unreproducible packages as possible. We endeavour to send all of our patches upstream where appropriate. This month, we wrote a large number of these patches, including:
Testing framework
The Reproducible Builds project operates a Jenkins-based testing framework to power tests.reproducible-builds.org. This month, Holger Levsen made the following changes:
Highlight important bad conditions in colour. [][]
Add support for detecting more problems, including Jenkins shutdown issues [], failure to upgrade Arch Linux packages [], kernels with wrong permissions [], etc.
Misc:
Delete old schroot sessions after 2 days, not 3. []
In addition, stefan0xC fixed a query for unknown results in the handling of Arch Linux packages [] and Mattia Rizzolo updated the template that notifies maintainers by email of their newly-unreproducible packages to ensure that it did not get caught in junk/spam folders []. Finally, build node maintenance was performed by Holger Levsen [][][][], Mattia Rizzolo [][] and Vagrant Cascadian [][][].
If you are interested in contributing to the Reproducible Builds project, please visit our Contribute page on our website. However, you can get in touch with us via:
As normal, probably of direct interest only to California residents and
apologies to everyone else since my hand-rolled blog software doesn't do
cut tags. I'm only going to cover propositions, since the state-wide
elections aren't very interesting and I both don't have strong opinions
about the local elections and would guess that almost no one cares.
See the voter guide for the full
details on each proposition.
Propositions 16 through 19 were put on the ballot by the legislature and
thus were written as well as our regular laws. The remaining propositions
are initiatives, which means I default to voting against them because
they're usually poorly-written crap.
Proposition 14: NO. I reluctantly supported the original
proposition to fund stem cell research with state bonds because it was in
the middle of the George W. Bush administration and his weird obsession
with ending stem cell research. It seemed worth the cost to maintain the
research, and I don't regret doing this. But since then we've reached a
compromise on ongoing research, and this proposition looks a lot more like
pork spending than investment.
I am in favor of government support of basic research, but I think that's
best done by a single grant institution that can pursue a coherent agenda.
The federal government, when sane, does a decent job of this, and the
California agency created by the previous proposition looks dodgy. The
support for this proposition also comes primarily from research
institutions that benefit from it. On top of that, there are way higher
priorities right now for public investment than a very specific and
limited type of medical research that isn't even the most important type
of medical research to do right now. There is nothing magic about stem
cells other than the fact that they make a certain type of Republican lose
their minds. It's time to stop funding this specific research specially
and roll it into general basic research funding.
Proposition 15: YES. Yes to anything that repeals Proposition 13
in whole or in part. Repealing it for commercial and industrial real
estate is a good first step. A rare exception in my general rule to vote
against initiatives.
Proposition 16: YES. Reverses a bad law to outlaw affirmative
action in California. I am in favor of actual reparations, so I am of
course in favor of this, which is far, far more mild.
Proposition 17: YES. Restores voting rights to felons after
completion of their sentence. I think it's inexcusable that any US
citizen cannot vote, including people who are currently incarcerated, so
of course I'm in favor of this more mild measure. (You may notice a
theme.) When we say everyone should be able to vote, that should mean
literally everyone.
Proposition 18: YES. Allows 17-year-olds to vote in California
(but not federal) elections in some specific circumstances. I'm generally
in favor of lowering the voting age, and this seems inoffensive. (And the
arguments against it are stupid.)
Proposition 19: YES. This is a complicated legislative
compromise around property tax that strengthens property tax limits for
seniors moving within California while removing exemptions against
increases for inherited real estate not used as a primary home. Some
progressives are opposed to this because it doesn't go far enough and
increases exemptions for seniors. I agree that those exemptions aren't
needed and shouldn't be added, but closing the inheritance loophole is
huge and worth this compromise. It's a tepid improvement for the somewhat
better, but it's still worth approving (and was written by the
legislature, so it's somewhat better written than the typical initiative).
Proposition 20: NO. Another pile of "anyone who has ever
committed a crime deserves to be treated as subhuman" bullshit. Typical
harsher sentences and harsher parole nonsense. No to everything like
this, always.
Proposition 21: YES. This is my other exception of voting for an
initiative, and that's because the California state legislature is
completely incapable of dealing with any housing problem.
This is a proposition that overhauls an ill-conceived state-wide
restriction on how rent control can be handled. The problem with rent
control is that a sane solution to housing problems in this state requires
both rent control and massive new construction, and we only get the former
and not the latter because the NIMBYism is endemic. (There's a pile of
NIMBY crap on my local ballot this year.) I would much rather be
approving those things together, because either of them alone makes things
worse for a lot of people. So yes, the opponents of this proposition are
right: it will make the housing crisis worse, because everyone refuses to
deal with the supply side.
That said, we need rent control as part of a humane solution, and the
current state-wide rules are bad. For example, they disallow rent control
on every property newer than a certain date that's forever fixed. This
initiative replaces that with a much saner 15-year rolling window for
maximizing profit, which is a better balance.
I hate voting for this because the legislature should have done their job
and passed comprehensive housing reform. But since they didn't, this is
part of what they should have passed, and I'll vote for it. Particularly
since it's opposed by all the huge commercial landlords.
Proposition 22: NO. The "exclude Uber and Lyft from labor law"
proposition, which is just as bullshit as it sounds. They're spending all
of their venture capital spamming the crap out of everyone in the state to
try to get this passed by lying about it. Just stunningly evil companies.
If your business model requires exploiting labor, get a better business
model.
Proposition 23: NO. So, this is another mess. It appears to be
part of some unionization fight between dialysis clinic employees and the
for-profit dialysis clinics. I hate everything about this situation,
starting from the fact that we have such a thing as for-profit dialysis
clinics, which is a crime against humanity.
But this proposition requires some very dodgy things, such as having a
doctor on staff at every clinic for... reasons? This is very reminiscent
of the bullshit laws about abortion clinics, which are designed to make it
more expensive to operate a clinic for no justifiable reason. I'm happy
to believe there is a bit more justification here, but this sort of
regulation is tricky and should be done by the legislature in a normal
law-making process. Medical regulation by initiative is just a horrible
idea in every way. So while I am doubtless politically on the side of the
proponents of the proposition, this is the wrong tool. Take it to the
legislature.
Proposition 24: NO. A deceptively-written supposed consumer
privacy law written by tech companies that actually weakens consumer
privacy in some critical ways that are profitable for them. No thanks,
without even getting to the point that this sort of thing shouldn't be
done by initiative.
Proposition 25: YES. Yes, we should eliminate cash bail, which
is essentially imprisoning people for being poor. No, this doesn't create
a system of government profiling; judges already set bail and can revoke
bail for flight risks. (This is not legislation by initiative; the state
government already passed this law, but we have a dumb law that lets
people oppose legislative action via initiative, so we have to vote to
approve the law that our representatives already passed and that should
have already gone into effect.)
I was assigned 16 hours of work by Freexian's Debian LTS initiative
and carried over 9.75 hours from August. I only worked 8.25 hours
this month, and will return excess hours to the pool.
I attended and participated in the LTS team meeting on the 24th.
I updated linux-4.19 to include the changes in the buster point
release, and issued
DLA-2385-1.
I began work on an update to the linux (Linux 4.9 kernel) package.
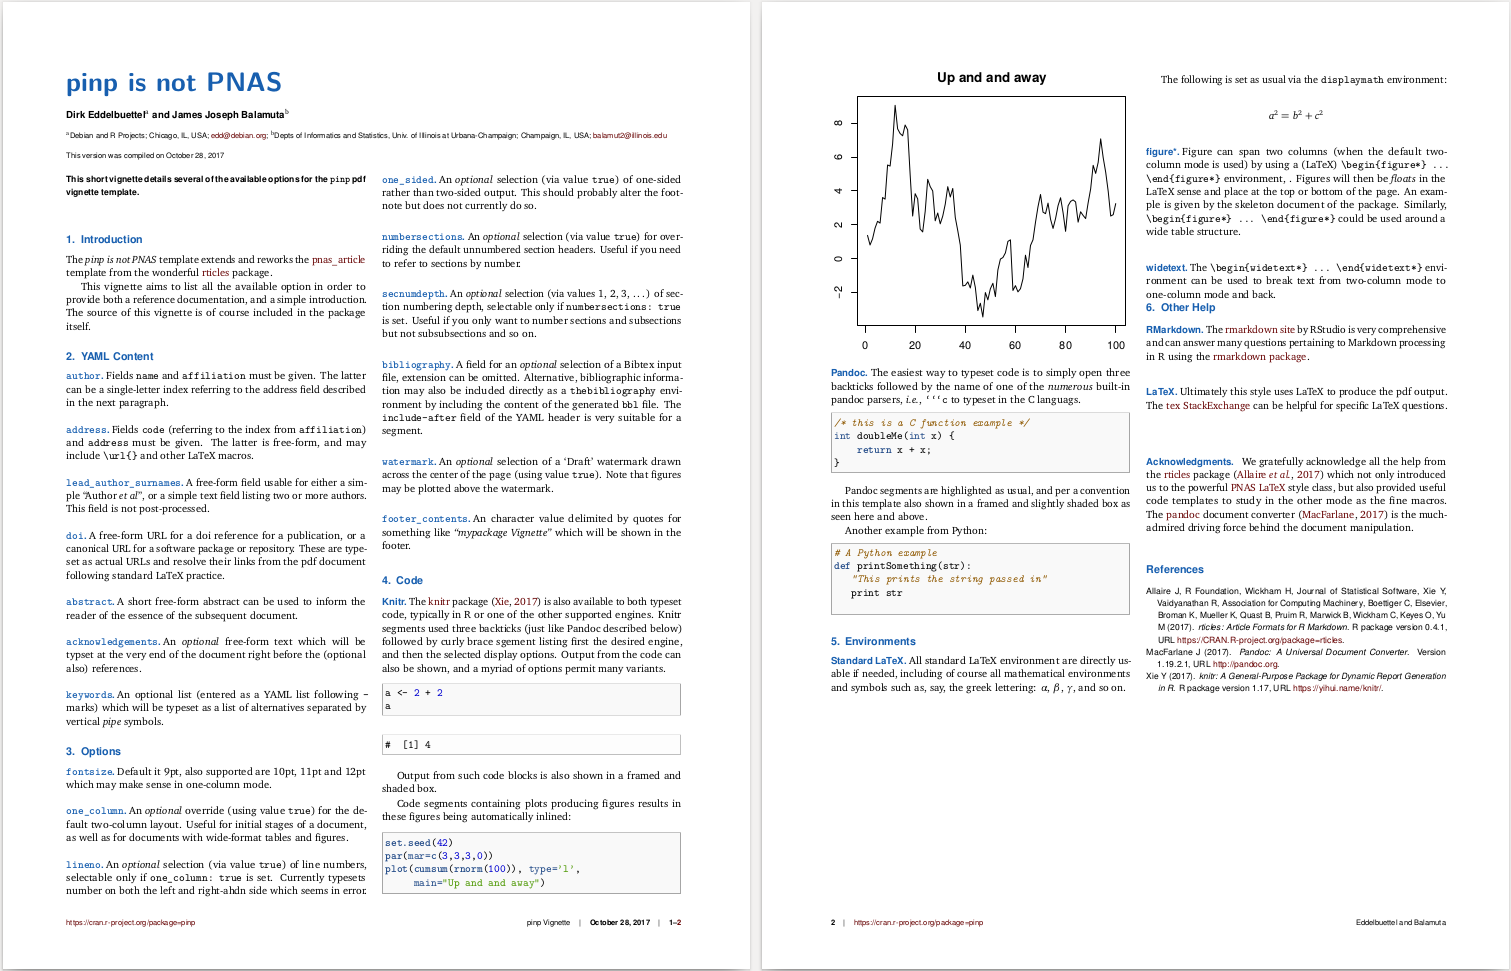
A new version of our pinp package arrived on CRAN two days ago, roughly one year after the previous release. The pinp package allows for snazzier one or two column Markdown-based pdf vignettes, and is now used by a few packages. A screenshot of the package vignette can be seen below. Additional screenshots are at the pinp page.
This release adds another option for a customized date YAML variable suitable for e.g. a published at date thanks to Ilya Kashnitsky, has some tweaks to the README.md as well as support for pandoc columns mode (as a small extension of code from the nice repo by Grant McDermott).
The NEWS entry for this release follows.
Changes in pinp version 0.0.10 (2020-10-01)
New document_date YAML variable to optionally set a 'Published at' or alike date (Ilya Kashnitsky in #85).
Recently I've been writing a couple of simple compilers, which take input in a particular format and generate assembly language output. This output can then be piped through gcc to generate a native executable.
Public examples include this trivial math compiler and my brainfuck compiler.
Of course there's always the nagging thought that relying upon gcc (or nasm) is a bit of a cheat. So I wondered how hard is it to write an assembler? Something that would take assembly-language program and generate a native (ELF) binary?
And the answer is "It isn't hard, it is just tedious".
I found some code to generate an ELF binary, and after that assembling simple instructions was pretty simple. I remember from my assembly-language days that the encoding of instructions can be pretty much handled by tables, but I've not yet gone into that.
(Specifically there are instructions like "add rax, rcx", and the encoding specifies the source/destination registers - with different forms for various sized immediates.)
Anyway I hacked up a simple assembler, it can compile a.out from this input:
.hello   DB "Hello, world\n"
.goodbye DB "Goodbye, world\n"
        mov rdx, 13        ;; write this many characters
        mov rcx, hello     ;; starting at the string
        mov rbx, 1         ;; output is STDOUT
        mov rax, 4         ;; sys_write
        int 0x80           ;; syscall
        mov rdx, 15        ;; write this many characters
        mov rcx, goodbye   ;; starting at the string
        mov rax, 4         ;; sys_write
        mov rbx, 1         ;; output is STDOUT
        int 0x80           ;; syscall
        xor rbx, rbx       ;; exit-code is 0
        xor rax, rax       ;; syscall will be 1 - so set to xero, then increase
        inc rax            ;;
        int 0x80           ;; syscall
The obvious omission is support for "JMP", "JMP_NZ", etc. That's painful because jumps are encoded with relative offsets. For the moment if you want to jump:
        push foo     ; "jmp foo" - indirectly.
        ret
:bar
        nop          ; Nothing happens
        mov rbx,33   ; first syscall argument: exit code
        mov rax,1    ; system call number (sys_exit)
        int 0x80     ; call kernel
:foo
        push bar     ; "jmp bar" - indirectly.
        ret
I'll update to add some more instructions, and see if I can use it to handle the output I generate from a couple of other tools. If so that's a win, if not then it was a fun learning experience:
 Stars! Lots of stars! And mountains
 And a new version of
 It's a bit of a long shot, but maybe someone on Planet Debian or
elsewhere can help us reach the right people at Apple.
Starting with iOS 14, something apparently changed on the way
USB tethering (also called Personal Hotspot) is set up, which broke
it for people using Linux. The driver in use is ipheth, developped
in
 Mexico was one of the first countries in the world to set up a
national population registry in the late 1850s, as part of the
church-state separation that was for long years one of the national
sources of pride.
Forty four years ago, when I was born, keeping track of the population
was still mostly a manual task. When my parents registered me, my data
was stored in page 161 of book 22, year 1976, of the 20th Civil
Registration office in Mexico City. Faithful to the legal tradition,
everything is handwritten and specified in full. Because, why would
they write 1976.04.27 (or even 27 de abril de 1976) when they
could spell out d a veintisiete de abril de mil novecientos setenta y
seis? Numbers seem to appear only for addresses.
 So, the State had record of a child being born, and we knew where to
look if we came to need this information. But, many years later, a
very sensible tecnification happened: all records (after a certain
date, I guess) were digitized. Great news! I can now get my birth
certificate without moving from my desk, paying a quite reasonable fee
(~US$4). What s there not to like?
 Digitally certified and all! So great! But But Oh, there s a
problem.
Of course Making sense of the handwriting as you can see is
somewhat prone to failure. And I cannot blame anybody for failing to
understand the details of my record.
So, my mother s first family name is Iszaevich. It was digitized as
Iszaerich. Fortunately, they do acknowledge some errors could have
made it into the process, and
 Yes, the mailing contact is in the
 This is a follow-up from the blog post of Russel as seen here:

 The thirteenth release of




 I was assigned 16 hours of work by Freexian's Debian LTS initiative
and carried over 9.75 hours from August. I only worked 8.25 hours
this month, and will return excess hours to the pool.
I attended and participated in the LTS team meeting on the 24th.
I updated linux-4.19 to include the changes in the buster point
release, and issued
 This release adds another option for a customized date YAML variable suitable for e.g. a published at date thanks to
 Recently I've been writing a couple of simple compilers, which take input in a particular format and generate assembly language output. This output can then be piped through