Search Results: "ron"

28 June 2017

Steve Kemp: Yet more linux security module craziness ..

I've recently been looking at linux security modules. My first two experiments helped me learn:
My First module - whitelist_lsm.c
This looked for the presence of an xattr, and if present allowed execution of binaries. I learned about the Kernel build-system, and how to write a simple LSM.
My second module - hashcheck_lsm.c
This looked for the presence of a "known-good" SHA1 hash xattr, and if it matched the actual hash of the file on-disk allowed execution. I learned how to hash the contents of a file, from kernel-space.
Both allowed me to learn things, but both were a little pointless. They were not fine-grained enough to allow different things to be done by different users. (i.e. If you allowed "alice" to run "wget" you'd also allow www-data to do the same.) So, assuming you wanted to do your security job more neatly what would you want? You'd want to allow/deny execution of commands based upon: So your local users could run "bad" commands, but "www-data" (post-compromise) couldn't. Obviously you don't want to have to recompile your kernel to change the rules of who can execute what. So you think to yourself "I'll write those rules down in a file". But of course reading a file from kernel-space is tricky. And parsing any list of rules, in a file, from kernel-space would prone to buffer-related problems. So I had a crazy idea: Calling userspace? Every time a command is to be executed? Crazy. But it just might work. One problem I had with this approach is that userspace might not even be available, when you're booting. So I setup a flag to enable this stuff:
# echo 1 >/proc/sys/kernel/can-exec/enabled
Now the kernel will invoke the following on every command:
/sbin/can-exec $UID $PATH
Because the kernel waits for this command to complete - as it reads the exit-code - you cannot execute any child-processes from it as you'd end up in recursive hell, but you can certainly read files, write to syslog, etc. My initial implementionation was as basic as this:
int main( int argc, char *argv[] )
 
...
  // Get the UID + Program
  int uid = atoi( argv[1] );
  char *prg = argv[2];
  // syslog
  openlog ("can-exec", LOG_CONS   LOG_PID   LOG_NDELAY, LOG_LOCAL1);
  syslog (LOG_NOTICE, "UID:%d CMD:%s", uid, prg );
  // root can do all.
  if ( uid == 0 )
    return 0;
  // nobody
  if ( uid == 65534 )  
    if ( ( strcmp( prg , "/bin/sh" ) == 0 )  
         ( strcmp( prg , "/usr/bin/id" ) == 0 ) )  
      fprintf(stderr, "Allowing 'nobody' access to shell/id\n" );
      return 0;
     
   
  fprintf(stderr, "Denied\n" );
  return -1;
 
Although the UIDs are hard-code it actually worked! Yay! I updated the code to convert the UID to a username, then check executables via the file /etc/can-exec/$USERNAME.conf, and this also worked. I don't expect anybody to actually use this code, but I do think I've reached a point where I can pretend I've written a useful (or non-pointless) LSM at last. That means I can stop.

27 June 2017

Colin Watson: New address book

I ve had a kludgy mess of electronic address books for most of two decades, and have got rather fed up with it. My stack consisted of: The biggest practical problem with this was that I had the address book that was most convenient for me to add things to (Google Contacts) and the one I used when sending email, and no sensible way to merge them or move things between them. I also wasn t especially comfortable with having all my contact information in a proprietary web service. My goals for a replacement address book system were: I think I have all this now! New stack The obvious basic technology to use is CardDAV: it s fairly complex, admittedly, but lots of software supports it and one of my goals was not having to write my own thing. This meant I needed a CardDAV server, some way to sync the database to and from both Android and the system where I run mutt, and whatever query glue was necessary to get mutt to understand vCards. There are lots of different alternatives here, and if anything the problem was an embarrassment of choice. In the end I just decided to go for things that looked roughly the right shape for me and tried not to spend too much time in analysis paralysis. CardDAV server I went with Xandikos for the server, largely because I know Jelmer and have generally had pretty good experiences with their software, but also because using Git for history of the backend storage seems like something my future self will thank me for. It isn t packaged in stretch, but it s in Debian unstable, so I installed it from there. Rather than the standalone mode suggested on the web page, I decided to set it up in what felt like a more robust way using WSGI. I installed uwsgi, uwsgi-plugin-python3, and libapache2-mod-proxy-uwsgi, and created the following file in /etc/uwsgi/apps-available/xandikos.ini which I then symlinked into /etc/uwsgi/apps-enabled/xandikos.ini:
[uwsgi]
socket = 127.0.0.1:8801
uid = xandikos
gid = xandikos
umask = 022
master = true
cheaper = 2
processes = 4
plugin = python3
module = xandikos.wsgi:app
env = XANDIKOSPATH=/srv/xandikos/collections
The port number was arbitrary, as was the path. You need to create the xandikos user and group first (adduser --system --group --no-create-home --disabled-login xandikos). I created /srv/xandikos owned by xandikos:xandikos and mode 0700, and I recommend setting a umask as shown above since uwsgi s default umask is 000 (!). You should also run sudo -u xandikos xandikos -d /srv/xandikos/collections --autocreate and then Ctrl-c it after a short time (I think it would be nicer if there were a way to ask the WSGI wrapper to do this). For Apache setup, I kept it reasonably simple: I ran a2enmod proxy_uwsgi, used htpasswd to create /etc/apache2/xandikos.passwd with a username and password for myself, added a virtual host in /etc/apache2/sites-available/xandikos.conf, and enabled it with a2ensite xandikos:
<VirtualHost *:443>
        ServerName xandikos.example.org
        ServerAdmin me@example.org
        ErrorLog /var/log/apache2/xandikos-error.log
        TransferLog /var/log/apache2/xandikos-access.log
        <Location />
                ProxyPass "uwsgi://127.0.0.1:8801/"
                AuthType Basic
                AuthName "Xandikos"
                AuthBasicProvider file
                AuthUserFile "/etc/apache2/xandikos.passwd"
                Require valid-user
        </Location>
</VirtualHost>
Then service apache2 reload, set the new virtual host up with Let s Encrypt, reloaded again, and off we go. Android integration I installed DAVdroid from the Play Store: it cost a few pounds, but I was OK with that since it s GPLv3 and I m happy to help fund free software. I created two accounts, one for my existing Google Contacts database (and in fact calendaring as well, although I don t intend to switch over to self-hosting that just yet), and one for the new Xandikos instance. The Google setup was a bit fiddly because I have two-step verification turned on so I had to create an app-specific password. The Xandikos setup was straightforward: base URL, username, password, and done. Since I didn t completely trust the new setup yet, I followed what seemed like the most robust option from the DAVdroid contacts syncing documentation, and used the stock contacts app to export my Google Contacts account to a .vcf file and then import that into the appropriate DAVdroid account (which showed up automatically). This seemed straightforward and everything got pushed to Xandikos. There are some weird delays in syncing contacts that I don t entirely understand, but it all seems to get there in the end. mutt integration First off I needed to sync the contacts. (In fact I happen to run mutt on the same system where I run Xandikos at the moment, but I don t want to rely on that, and going through the CardDAV server means that I don t have to poke holes for myself using filesystem permissions.) I used vdirsyncer for this. In ~/.vdirsyncer/config:
[general]
status_path = "~/.vdirsyncer/status/"
[pair contacts]
a = "contacts_local"
b = "contacts_remote"
collections = ["from a", "from b"]
[storage contacts_local]
type = "filesystem"
path = "~/.contacts/"
fileext = ".vcf"
[storage contacts_remote]
type = "carddav"
url = "<Xandikos base URL>"
username = "<my username>"
password = "<my password>"
Running vdirsyncer discover and vdirsyncer sync then synced everything into ~/.contacts/. I added an hourly crontab entry to run vdirsyncer -v WARNING sync. Next, I needed a command-line address book tool based on this. khard looked about right and is in stretch, so I installed that. In ~/.config/khard/khard.conf (this is mostly just the example configuration, but I preferred to sort by first name since not all my contacts have neat first/last names):
[addressbooks]
[[contacts]]
path = ~/.contacts/<UUID of my contacts collection>/
[general]
debug = no
default_action = list
editor = vim
merge_editor = vimdiff
[contact table]
# display names by first or last name: first_name / last_name
display = first_name
# group by address book: yes / no
group_by_addressbook = no
# reverse table ordering: yes / no
reverse = no
# append nicknames to name column: yes / no
show_nicknames = no
# show uid table column: yes / no
show_uids = yes
# sort by first or last name: first_name / last_name
sort = first_name
[vcard]
# extend contacts with your own private objects
# these objects are stored with a leading "X-" before the object name in the vcard files
# every object label may only contain letters, digits and the - character
# example:
#   private_objects = Jabber, Skype, Twitter
private_objects = Jabber, Skype, Twitter
# preferred vcard version: 3.0 / 4.0
preferred_version = 3.0
# Look into source vcf files to speed up search queries: yes / no
search_in_source_files = no
# skip unparsable vcard files: yes / no
skip_unparsable = no
Now khard list shows all my contacts. So far so good. Apparently there are some awkward vCard compatibility issues with creating or modifying contacts from the khard end. I ve tried adding one address from ~/.mutt/aliases using khard and it seems to at least minimally work for me, but I haven t explored this very much yet. I had to install python3-vobject 0.9.4.1-1 from experimental to fix eventable/vobject#39 saving certain vCard files. Finally, mutt integration. I already had set query_command="lbdbq '%s'" in ~/.muttrc, and I wanted to keep that in place since I still wanted to use LDAP querying as well. I had to write a very small amount of code for this (perhaps I should contribute this to lbdb upstream?), in ~/.lbdb/modules/m_khard:
#! /bin/sh
m_khard_query ()  
    khard email --parsable --remove-first-line --search-in-source-files "$1"
 
My full ~/.lbdb/rc now reads as follows (you probably won t want the LDAP stuff, but I ve included it here for completeness):
MODULES_PATH="$MODULES_PATH $HOME/.lbdb/modules"
METHODS='m_muttalias m_khard m_ldap'
LDAP_NICKS='debian canonical'
Next steps I ve deleted one account from Google Contacts just to make sure that everything still works (e.g. I can still search for it when composing a new message), but I haven t yet deleted everything. I won t be adding anything new there though. I need to push everything from ~/.mutt/aliases into the new system. This is only about 30 contacts so shouldn t take too long. Overall this feels like a big improvement! It wasn t a trivial amount of setup for just me, but it means I have both better usability for myself and more independence from proprietary services, and I think I can add extra users with much less effort if I need to. Postscript A day later and I ve consolidated all my accounts from Google Contacts and ~/.mutt/aliases into the new system, with the exception of one group that I had defined as a mutt alias and need to work out what to do with. This all went smoothly. I ve filed the new lbdb module as #866178, and the python3-vobject bug as #866181.

26 June 2017

Alexander Wirt: Stretch Backports available

With the release of stretch we are pleased to open the doors for stretch-backports and jessie-backports-sloppy. \o/ As usual with a new release we will change a few things for the backports service.

What to upload where As a reminder, uploads to a release-backports pocket are to be taken from release + 1, uploads to a release-backports-sloppy pocket are to be taken from release + 2. Which means:
Source Distribution Backports Distribution Sloppy Distribution
buster stretch-backports jessie-backports-sloppy
stretch jessie-backports -

Deprecation of LTS support for backports We started supporting backports as long as there is LTS support as an experiment. Unfortunately it didn t worked, most maintainers didn t wanted to support oldoldstable-backports (squeeze) for the lifetime of LTS. So things started to rot in squeeze and most packages didn t received updates. After long discussions we decided to deprecate LTS support for backports. From now on squeeze-backports(-sloppy) is closed and will not receive any updates. Expect it to get removed from the mirrors and moved to archive in the near future.

BSA handling We - the backports team - didn t scale well in processing BSA requests. To get things better in the future we decided to change the process a little bit. If you upload a package which fixes security problems please fill out the BSA template and create a ticket in the rt tracker (see https://backports.debian.org/Contribute/#index3h2 for details).

Stretching the rules From time to time its necessary to not follow the backports rules, like a package needs to be in testing or a version needs to be in Debian. If you think you have one of those cases, please talk to us on the list before upload the package.

Thanks Thanks have to go out to all people making backports possible, and that includes up front the backporters themself who do upload the packages, track and update them on a regular basis, but also the buildd team making the autobuilding possible and the ftp masters for creating the suites in the first place. We wish you a happy stretch :) Alex, on behalf of the Backports Team

Jonathan Dowland: Coming in from the cold

I've been using a Mac day-to-day since around 2014, initially as a refreshing break from the disappointment I felt with GNOME3, but since then a few coincidences have kept me on the platform. Something happened earlier in the year that made me start to think about a move back to Linux on the desktop. My next work hardware refresh is due in March next year, which gives me about nine months to "un-plumb" myself from the Mac ecosystem. From the top of my head, here's the things I'm going to have to address: I think that's probably it: not a big list! Notably, I'm not locked into iTunes, which I avoid where possible; Apple's Photo app (formerly iPhoto) which is a bit of a disaster; nor Time Machine, which is excellent, but I have a backup system for other things in place that I can use.

25 June 2017

Andreas Bombe: PDP-8/e Replicated Introduction

I am creating a replica of the DEC PDP-8/e architecture in an FPGA from schematics of the original hardware. So how did I end up with a project like this? The story begins with me wanting to have a computer with one of those front panels that have many, many lights where you can really see, in real time, what the computer is doing while it is executing code. Not because I am nostalgic for a prior experience with any of those I was born a bit too late for that and my first computer as a kid was a Commodore 64. Now, the front panel era ended around 40 years ago with the advent of microprocessors and computers of that age and older that are complete and working are hard to find and not cheap. And even if you do, there s the issue of weight, size (complete systems with peripherals fill at least a rack) and power consumption. So what to do build myself a small one with modern technology of course. While there s many computer architectures of that era to choose from, the various PDP machines by DEC are significant and well known (and documented) due to their large numbers. The most important are probably the 12 bit PDP-8, the 16 bit PDP-11 and the 36 bit PDP-10. While the PDP-11 is enticing because of the possibility to run UNIX I wanted to start with something simpler, so I chose the PDP-8.
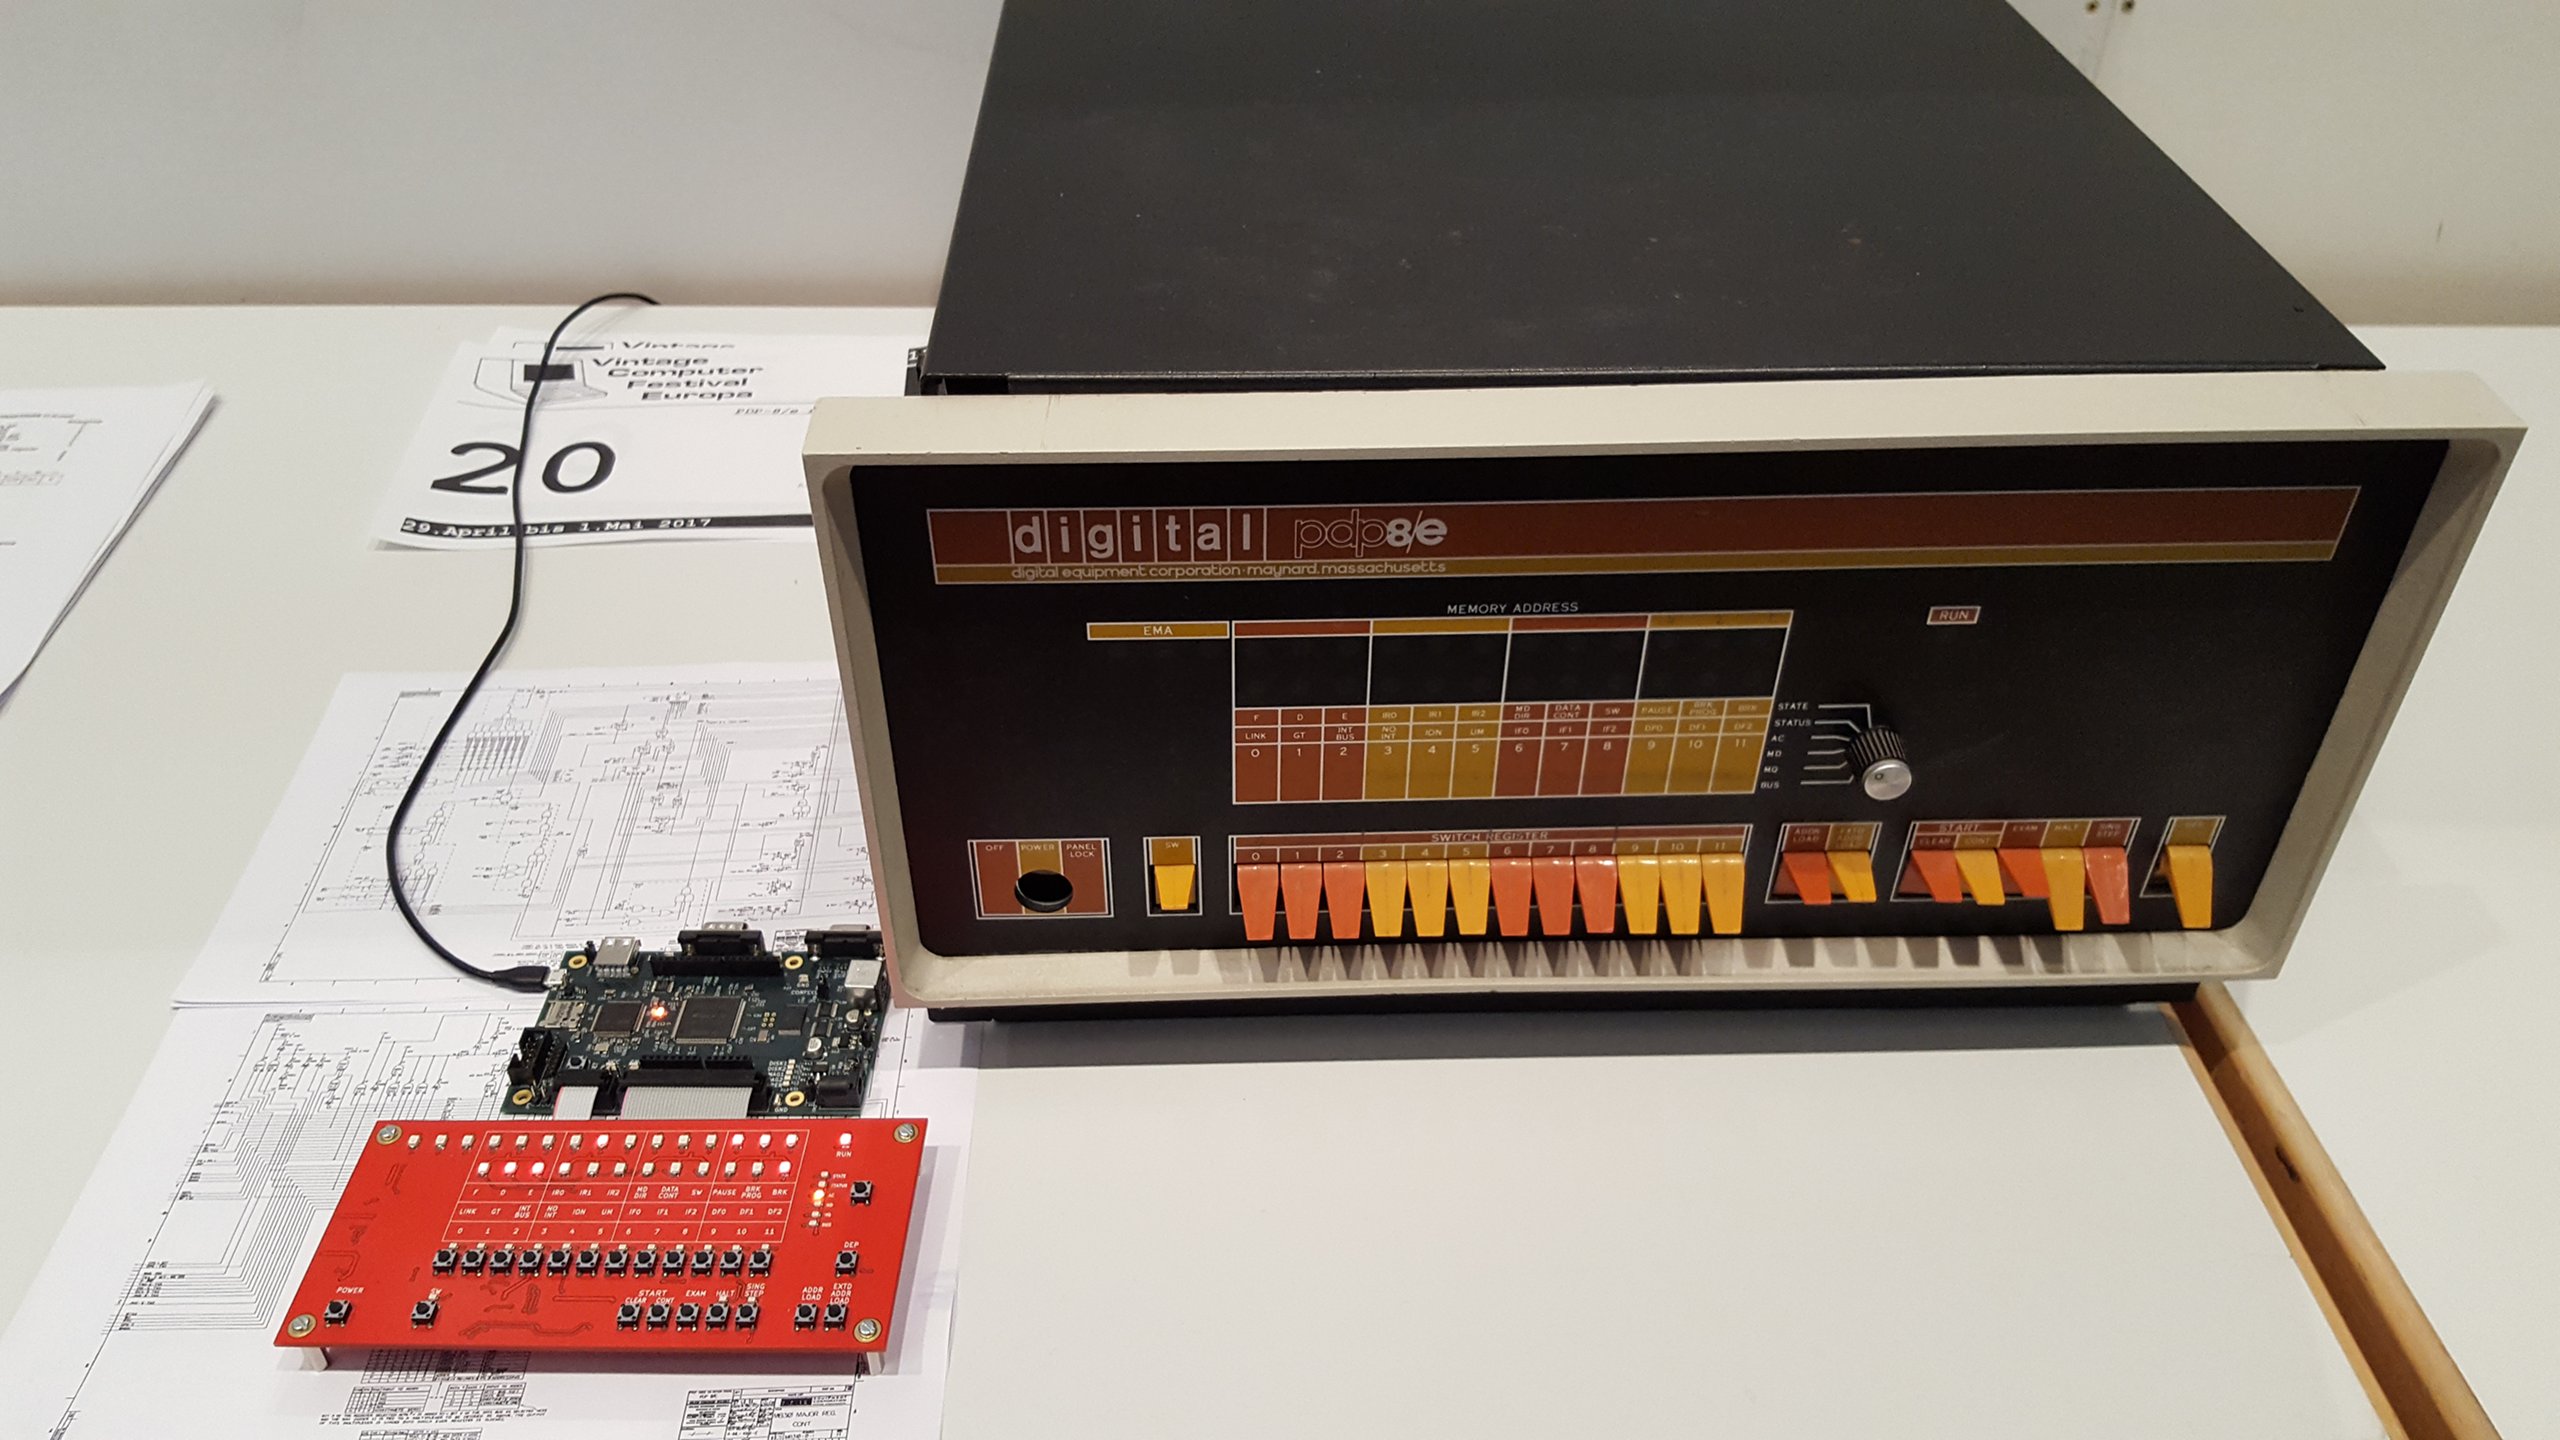
My implementation on display next to a real PDP-8/e at VCFe 18.0

The Original DEC started the PDP-8 line of computers programmed data processors designed as low cost machines in 1965. It is a quite minimalist 12 bit architecture based on the earlier PDP-5, and by minimalist I mean seriously minimal. If you are familiar with early 8 bit microprocessors like the 6502 or 8080 you will find them luxuriously equipped in comparison. The PDP-8 base architecture has a program counter (PC) and an accumulator (AC)1. That s it. There are no pointer or index registers2. There is no stack. It has addition and AND instructions but subtractions and OR operations have to be manually coded. The optional Extended Arithmetic Element adds the MQ register but that s really it for visible registers. The Wikipedia page on the PDP-8 has a good detailed description. Regarding technology, the PDP-8 series has been in production long enough to get the whole range of implementations from discrete transistor logic to microprocessors. The 8/e which I target was right in the middle, implemented in TTL logic where each IC contains multiple logic elements. This allowed the CPU itself (including timing generator) to fit on three large circuit boards plugged into a backplane. Complete systems would have at least another board for the front panel and multiple boards for the core memory, then additional boards for whatever options and peripherals were desired.

Design Choices and Comparisons I m not the only one who had the idea to build something like that, of course. Among the other modern PDP-8 implementations with a front panel, probably the most prominent project is the Spare Time Gizmos SBC6120 which is a PDP-8 single board computer built around the Harris/Intersil HD-6120 microprocessor, which implementes the PDP-8 architecture, combined with a nice front panel. Another is the PiDP-8/I, which is another nice front panel (modeled after the 8/i which has even more lights) driven by the simh simulator running under Linux on a Raspberry Pi. My goal is to get front panel lights that appear exactly like the real ones in operation. This necessitates driving the lights at full speed as they change with every instruction or even within instructions for some display selections. For example, if you run a tight loop that does nothing but increment AC while displaying that register, it would appear that all lights are lit at equal but less than full brightness. The reason is that the loop runs at such a high speed that even the most significant bit, which is blinking the slowest, is too fast to see flicker. Hence they are all effectively 50% on, just at different frequencies, and appear to be constantly light at the same brightness. This is where the other projects lack what I am looking for. The PiDP-8/I is a multiplexed display which updates at something like 30 Hz or 60 Hz, taking whatever value is current in the simulation software at the time. All the states the lights took inbetween are lost and consequently there is flickering where there shouldn t be. On the SBC6120 at least the address lines appear to update at full speed as these are the actual RAM address lines. However the used 6120 microprocessor does not have required data for the indicator display externally available. Instead, the SBC6120 runs an interrupt at 30 Hz to trap into its firmware/monitor program which then reads the current state and writes it to the front panel display, which is essentially just another peripheral. A different considerable problem with the SBC6120 is its use of the 6100 microprocessor family ICs, which are themselves long out of production and not trivial (or cheaply) to come by. Given that the way to go is to drive all lights in step with every cycle3, this can be done by a software running on a dedicated microcontroller which is how I started or by implementing a real CPU with all the needed outputs in an FPGA which is the project I am writing about. In the next post I give an overview of the hardware I built so far and some of the features that are yet to be implemented.

  1. With an associated link bit which is a little different from a carry bit in that it is treated as a thirteenth bit, i.e. it will be flipped rather than set when a carry occurs. [return]
  2. Although there are 8 specially treated memory addresses that will pre-increment when used in indirect addressing. [return]
  3. Basic cycles on the PDP-8/e are 1.4 s for memory modifying cycles and fast cycles of 1.2 s for everything else. Instructions can be one to three cycles long. [return]

Steinar H. Gunderson: Frame queue management in Nageru 1.6.1

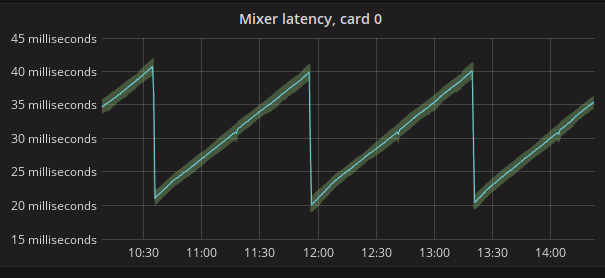
Nageru 1.6.1 is on its way, and what was intended to only be a release centered around monitoring improvements (more specifically a full set of native Prometheus] metrics) actually ended up getting a fairly substantial change to how Nageru manages its frame queues. To understand what's changing and why, it's useful to first understand the history of Nageru's queue management. Nageru 1.0.0 started out with a fairly simple scheme, but with some basics that are still relevant today: One of the input cards was deemed the master card, and whenever it delivers a frame, the master clock ticks and an output frame is produced. (There are some subtleties about dropped frames and/or the master card changing frame rates, but I'm going to ignore them, since they're not important to the discussion.) To this end, every card keeps a preallocated frame queue; when a card delivers a frame, it's put into the queue, and when the master clock ticks, it tries picking out one frame from each of the other card's queues to mix together. Note that mix here could be as simple as picking one input and throwing all the other ones away; the queueing algorithm doesn't care, it just feeds all of them to the theme and lets that run whatever GPU code it needs to match the user's preferences. The only thing that really keeps the queues bounded is that the frames in them are preallocated (in GPU memory), so if one queue gets longer than 16 frames, Nageru starts dropping it. But is 16 the right number? There are two conflicting demands here, ignoring memory usage: The 1.0.0 scheme does about as well as one could possibly hope in never dropping frames, but unfortunately, it can be pretty poor at latency. For instance, if your master card runs at 50 Hz and you have a 60 Hz card, the latter will eventually build up a delay of 16 * 16.7 ms = 266.7 ms clearly unacceptable, and rather unneeded. You could ask the user to specify a queue length, but the user probably doesn't know, and also shouldn't really have to care more knobs to twiddle are a bad thing, and even more so knobs the user is expected to twiddle. Thus, Nageru 1.2.0 introduced queue autotuning; it keeps a running estimate on how big the queue needs to be to avoid underruns, simply based on experience. If we've been dropping frames on a queue and then there's an underrun, the safe queue length is increased by one, and if the queue has been having excess frames for more than a thousand successive master clock ticks, we reduce it by one again. Whenever the queue has more than this safe number, we drop frames. This was simple, effective and largely fixed the problem. However, when adding metrics, I noticed a peculiar effect: Not all of my devices have equally good clocks. In particular, when setting up for 1080p50, my output card's internal clock (which assumes the role of the master clock when using HDMI/SDI output) seems to tick at about 49.9998 Hz, and my simple home camcorder delivers frames at about 49.9995 Hz. Over the course of an hour, this means it produces one more frame than you should have which should of course be dropped. Having an SDI setup with synchronized clocks (blackburst/tri-level) would of course fix this problem, but most people are not so lucky with their cameras, not to mention the price of PC graphics cards with SDI outputs! However, this happens very slowly, which means that for a significant amount of time, the two clocks will very nearly be in sync, and thus racing. Who ticks first is determined largely by luck in the jitter (normal is maybe 1ms, but occasionally, you'll see delayed delivery of as much as 10 ms), and this means that the 1000 frames estimate is likely to be thrown off, and the result is hundreds of dropped frames and underruns in that period. Once the clocks have diverged enough again, you're off the hook, but again, this isn't a good place to be. Thus, Nageru 1.6.1 change the algorithm around yet again, by incorporating more data to build an explicit jitter model. 1.5.0 was already timestamping each frame to be able to measure end-to-end latency precisely (now also exposed in Prometheus metrics), but from 1.6.1, they are actually used in the queueing algorithm. I ran several eight- to twelve-hour tests and simply stored all the event arrivals to a file, and then simulated a few different algorithms (including the old algorithm) to see how they fared in measures such as latency and number of drops/underruns. I won't go into the full details of the new queueing algorithm (see the commit if you're interested), but the gist is: Based on the last 5000 frames, it tries to estimate the maximum possible jitter for each input (ie., how late the frame could possibly be). Based on this as well as clock offsets, it determines whether it's really sure that there will be an input frame available on the next master tick even if it drops the queue, and then trims the queue to fit. The result is pretty satisfying; here's the end-to-end latency of my camera being sent through to the SDI output: As you can see, the latency goes up, up, up until Nageru figures it's now safe to drop a frame, and then does it in one clean drop event; no more hundreds on drops involved. There are very late frame arrivals involved in this run two extra frame drops, to be precise but the algorithm simply determines immediately that they are outliers, and drops them without letting them linger in the queue. (Immediate dropping is usually preferred to sticking around for a bit and then dropping it later, as it means you only get one disturbance event in your stream as opposed to two. Of course, you can only do it if you're reasonably sure it won't lead to more underruns later.) Nageru 1.6.1 will ship before Solskogen, as I intend to run it there :-) And there will probably be lovely premade Grafana dashboards from the Prometheus data. Although it would have been a lot nicer if Grafana were more packaging-friendly, so I could pick it up from stock Debian and run it on armhf. Hrmf. :-)

Shirish Agarwal: Dreams don t cost a penny, mumma s boy :)

This one I promise will be short  After the last two updates, I thought it was time for something positive to share. While I m doing the hard work (of physiotherapy which is gruelling), the only luxury I have nowadays is of falling on to dreams which are also rare. The dream I m going to share is totally unrealistic as my mum hates travel but I m sure many sons and daughters would identify with it. Almost all travel outside of relatives is because I dragged her onto it. In the dream, I am going to a Debconf, get bursary and the conference is being held somewhere in Europe, maybe Paris (2019 probably)  . I reach and attend the conference, present and generally have a great time sharing and learning from my peers. As we all do in these uncertain times, I too phone home every couple of days ensuring her that I m well and in best of health. The weather is mild like it was in South Africa and this time I had come packed with woollens so all was well. Just the day before the conference is to end, I call up mum and she tells about a specific hotel/hostel which I should check out. I am somewhat surprised that she knows of a specific hotel/hostel in a specific place but I accede to her request. I go there to find a small, quiet, quaint bed & breakfast place (dunno if Paris has such kind of places), something which my mum would like. Intuitively, I ask at the reception to look in the register. After seeing my passport, he too accedes to my request and shows me the logbook of all visitors registering to come in the last few days (for some reason privacy is not a concern then) . I am surprised to find my mother s name in the register and she had turned up just a day or two before. I again request the reception to be able to go to room abcd without being announced and have some sort of key (like for maintenance or laundry as an excuse) . The reception calls the manager and after looking copy of mother s passport and mine they somehow accede to the request with help located nearby just in case something goes wrong. I disguise my voice and announce as either Room service or Maintenance and we are both surprised and elated to see each other. After talking a while, I go back to the reception and register myself as her guest. The next week is a whirlwind as I come to know of hop-on, hop-off buses similar service in Paris as was in South Africa. I buy a small booklet and we go through all the museums. the vineyards or whatever it is that Paris has to offer. IIRC there is also a lock and key on a famous bridge. We also do that. She is constantly surprised at the different activities the city shows her and the mother-son bond becomes much better. I had shared the same dream with her and she laughed. In reality, she is happy and comfortable in the confines of her home. Still I hope some mother-daughter, son-father, son-mother or any combination of parent, sibling takes this entry and enrich each other by travelling together.
Filed under: Miscellenous Tagged: #dream, #mother, #planet-debian, travel

24 June 2017

Ingo Juergensmann: Upgrade to Debian Stretch - GlusterFS fails to mount

Before I upgrade from Jessie to Stretch everything worked as a charme with glusterfs in Debian. But after I upgraded the first VM to Debian Stretch I discovered that glusterfs-client was unable to mount the storage on Jessie servers. I got this in glusterfs log:
[2017-06-24 12:51:53.240389] I [MSGID: 100030] [glusterfsd.c:2454:main] 0-/usr/sbin/glusterfs: Started running /usr/sbin/glusterfs version 3.8.8 (args: /usr/sbin/glusterfs --read-only --fuse-mountopts=nodev,noexec --volfile-server=192.168.254.254 --volfile-id=/le --fuse-mountopts=nodev,noexec /etc/letsencrypt.sh/certs)
[2017-06-24 12:51:54.534826] E [mount.c:318:fuse_mount_sys] 0-glusterfs-fuse: ret = -1

[2017-06-24 12:51:54.534896] I [mount.c:365:gf_fuse_mount] 0-glusterfs-fuse: direct mount failed (Invalid argument) errno 22, retry to mount via fusermount
[2017-06-24 12:51:56.668254] I [MSGID: 101190] [event-epoll.c:628:event_dispatch_epoll_worker] 0-epoll: Started thread with index 1
[2017-06-24 12:51:56.671649] E [glusterfsd-mgmt.c:1590:mgmt_getspec_cbk] 0-glusterfs: failed to get the 'volume file' from server
[2017-06-24 12:51:56.671669] E [glusterfsd-mgmt.c:1690:mgmt_getspec_cbk] 0-mgmt: failed to fetch volume file (key:/le)
[2017-06-24 12:51:57.014502] W [glusterfsd.c:1327:cleanup_and_exit] (-->/usr/lib/x86_64-linux-gnu/libgfrpc.so.0(rpc_clnt_handle_reply+0x90) [0x7fbea36c4a20] -->/usr/sbin/glusterfs(mgmt_getspec_cbk+0x494) [0x55fbbaed06f4] -->/usr/sbin/glusterfs(cleanup_and_exit+0x54) [0x55fbbaeca444] ) 0-: received signum (0), shutting down
[2017-06-24 12:51:57.014564] I [fuse-bridge.c:5794:fini] 0-fuse: Unmounting '/etc/letsencrypt.sh/certs'.
[2017-06-24 16:44:45.501056] I [MSGID: 100030] [glusterfsd.c:2454:main] 0-/usr/sbin/glusterfs: Started running /usr/sbin/glusterfs version 3.8.8 (args: /usr/sbin/glusterfs --read-only --fuse-mountopts=nodev,noexec --volfile-server=192.168.254.254 --volfile-id=/le --fuse-mountopts=nodev,noexec /etc/letsencrypt.sh/certs)
[2017-06-24 16:44:45.504038] E [mount.c:318:fuse_mount_sys] 0-glusterfs-fuse: ret = -1

[2017-06-24 16:44:45.504084] I [mount.c:365:gf_fuse_mount] 0-glusterfs-fuse: direct mount failed (Invalid argument) errno 22, retry to mount via fusermount
After some searches on the Internet I found Debian #858495, but no solution for my problem. Some search results recommended to set "option rpc-auth-allow-insecure on", but this didn't help. In the end I joined #gluster on Freenode and got some hints there:
JoeJulian ij__: debian breaks apart ipv4 and ipv6. You'll need to remove the ipv6 ::1 address from localhost in /etc/hosts or recombine your ip stack (it's a sysctl thing)
JoeJulian It has to do with the decisions made by the debian distro designers. All debian versions should have that problem. (yes, server side).
Removing ::1 from /etc/hosts and from lo interface did the trick and I could mount glusterfs storage from Jessie servers in my Stretch VMs again. However, when I upgraded the glusterfs storages to Stretch as well, this "workaround" didn't work anymore. Some more searching on the Internet made me found this posting on glusterfs mailing list:
We had seen a similar issue and Rajesh has provided a detailed explanation on why at [1]. I'd suggest you to not to change glusterd.vol but execute "gluster volume set <volname> transport.address-family inet" to allow Gluster to listen on IPv4 by default.
Setting this option instantly fixed my issues with mounting glusterfs storages. So, whatever is wrong with glusterfs in Debian, it seems to have something to do with IPv4 and IPv6. When disabling IPv6 in glusterfs, it works. I added information to #858495.
Kategorie:

23 June 2017

Joachim Breitner: The perils of live demonstrations

Yesterday, I was giving a talk at the The South SF Bay Haskell User Group about how implementing lock-step simulation is trivial in Haskell and how Chris Smith and me are using this to make CodeWorld even more attractive to students. I gave the talk before, at Compose::Conference in New York City earlier this year, so I felt well prepared. On the flight to the West Coast I slightly extended the slides, and as I was too cheap to buy in-flight WiFi, I tested them only locally. So I arrived at the offices of Target1 in Sunnyvale, got on the WiFi, uploaded my slides, which are in fact one large interactive CodeWorld program, and tried to run it. But I got a type error Turns out that the API of CodeWorld was changed just the day before:
commit 054c811b494746ec7304c3d495675046727ab114
Author: Chris Smith <cdsmith@gmail.com>
Date:   Wed Jun 21 23:53:53 2017 +0000
    Change dilated to take one parameter.
    
    Function is nearly unused, so I'm not concerned about breakage.
    This new version better aligns with standard educational usage,
    in which "dilation" means uniform scaling.  Taken as a separate
    operation, it commutes with rotation, and preserves similarity
    of shapes, neither of which is true of scaling in general.
Ok, that was quick to fix, and the CodeWorld server started to compile my code, and compiled, and aborted. It turned out that my program, presumably the larges CodeWorld interaction out there, hit the time limit of the compiler. Luckily, Chris Smith just arrived at the venue, and he emergency-bumped the compiler time limit. The program compiled and I could start my presentation. Unfortunately, the biggest blunder was still awaiting for me. I came to the slide where two instances of pong are played over a simulated network, and my point was that the two instances are perfectly in sync. Unfortunately, they were not. I guess it did support my point that lock-step simulation can easily go wrong, but it really left me out in the rain there, and I could not explain it I did not modify this code since New York, and there it worked flawless2. In the end, I could save my face a bit by running the real pong game against an attendee over the network, and no desynchronisation could be observed there. Today I dug into it and it took me a while, and it turned out that the problem was not in CodeWorld, or the lock-step simulation code discussed in our paper about it, but in the code in my presentation that simulated the delayed network messages; in some instances it would deliver the UI events in different order to the two simulated players, and hence cause them do something different. Phew.

  1. Yes, the retail giant. Turns out that they have a small but enthusiastic Haskell-using group in their IT department.
  2. I hope the video is going to be online soon, then you can check for yourself.

Arturo Borrero Gonz lez: Backup router/switch configuration to a git repository

git Most routers/switches out there store their configuration in plain text, which is nice for backups. I m talking about Cisco, Juniper, HPE, etc. The configuration of our routers are being changed several times a day by the operators, and in this case we lacked some proper way of tracking these changes. Some of these routers come with their own mechanisms for doing backups, and depending on the model and version perhaps they include changes-tracking mechanisms as well. However, they mostly don t integrate well into our preferred version control system, which is git. After some internet searching, I found rancid, which is a suite for doing tasks like this. But it seemed rather complex and feature-full for what we required: simply fetch the plain text config and put it into a git repo. Worth noting that the most important drawback of not triggering the change-tracking from the router/switch is that we have to follow a polling approach: loggin into each device, get the plain text and the commit it to the repo (if changes detected). This can be hooked in cron, but as I said, we lost the sync behaviour and won t see any changes until the next cron is run. In most cases, we lost authorship information as well. But it was not important for us right now. In the future this is something that we will have to solve. Also, some routers/switches lack some basic SSH security improvements, like public-key authentication, so we end having to hard-code user/pass in our worker script. Since we have several devices of the same type, we just iterate over their names. For example, this is what we use for hp comware devices:
#!/bin/bash
# run this script by cron
USER="git"
PASSWORD="readonlyuser"
DEVICES="device1 device2 device3 device4"
FILE="flash:/startup.cfg"
GIT_DIR="myrepo"
GIT="/srv/git/$ GIT_DIR .git"
TMP_DIR="$(mktemp -d)"
if [ -z "$TMP_DIR" ] ; then
	echo "E: no temp dir created" >&2
	exit 1
fi
GIT_BIN="$(which git)"
if [ ! -x "$GIT_BIN" ] ; then
	echo "E: no git binary" >&2
	exit 1
fi
SCP_BIN="$(which scp)"
if [ ! -x "$SCP_BIN" ] ; then
	echo "E: no scp binary" >&2
	exit 1
fi
SSHPASS_BIN="$(which sshpass)"
if [ ! -x "$SSHPASS_BIN" ] ; then
	echo "E: no sshpass binary" >&2
	exit 1
fi
# clone git repo
cd $TMP_DIR
$GIT_BIN clone $GIT
cd $GIT_DIR
for device in $DEVICES; do
	mkdir -p $device
	cd $device
	# fetch cfg
	CONN="$ USER @$ device "
	$SSHPASS_BIN -p "$PASSWORD" $SCP_BIN $ CONN :$ FILE  .
	# commit
	$GIT_BIN add -A .
	$GIT_BIN commit -m "$ device : configuration change" \
		-m "A configuration change was detected" \
		--author="cron <cron@example.com>"
	$GIT_BIN push -f
	cd ..
done
# cleanup
rm -rf $TMP_DIR
You should create a read-only user git in the devices. And beware that each device model has the config file stored in a different place. For reference, in HP comware, the file to scp is flash:/startup.cfg. And you might try creating the user like this:
local-user git class manage
 password hash xxxxx
 service-type ssh
 authorization-attribute user-role security-audit
#
In Junos/Juniper, the file you should scp is /config/juniper.conf.gz and the script should gunzip the data before committing. For the read-only user, try is something like this:
system  
	[...]
	login  
		[...]
		class git  
			permissions maintenance;
			allow-commands scp.*;
		 
		user git  
			uid xxx;
			class git;
			authentication  
				encrypted-password "xxx";


The file to scp in HP procurve is /cfg/startup-config. And for the read-only user, try something like this:
aaa authorization group "git user" 1 match-command "scp.*" permit
aaa authentication local-user "git" group "git user" password sha1 "xxxxx"
What would be the ideal situation? Get the device controlled directly by git (i.e. commit > git hook > device update) or at least have the device to commit the changes by itself to git. I m open to suggestions :-)

22 June 2017

Dirk Eddelbuettel: RcppCCTZ 0.2.3 (and 0.2.2)

A new minor version 0.2.3 of RcppCCTZ is now on CRAN. RcppCCTZ uses Rcpp to bring CCTZ to R. CCTZ is a C++ library for translating between absolute and civil times using the rules of a time zone. In fact, it is two libraries. One for dealing with civil time: human-readable dates and times, and one for converting between between absolute and civil times via time zones. The RcppCCTZ page has a few usage examples and details. This version ensures that we set the TZDIR environment variable correctly on the old dreaded OS that does not come with proper timezone information---an issue which had come up while preparing the next (and awesome, trust me) release of nanotime. It also appears that I failed to blog about 0.2.2, another maintenance release, so changes for both are summarised next.

Changes in version 0.2.3 (2017-06-19)
  • On Windows, the TZDIR environment variable is now set in .onLoad()
  • Replaced init.c with registration code inside of RcppExports.cpp thanks to Rcpp 0.12.11.

Changes in version 0.2.2 (2017-04-20)
  • Synchronized with upstream CCTZ
  • The time_point object is instantiated explicitly for nanosecond use which appears to be required on macOS

We also have a diff to the previous version thanks to CRANberries. More details are at the RcppCCTZ page; code, issue tickets etc at the GitHub repository.

This post by Dirk Eddelbuettel originated on his Thinking inside the box blog. Please report excessive re-aggregation in third-party for-profit settings.

21 June 2017

Joey Hess: DIY professional grade solar panel installation

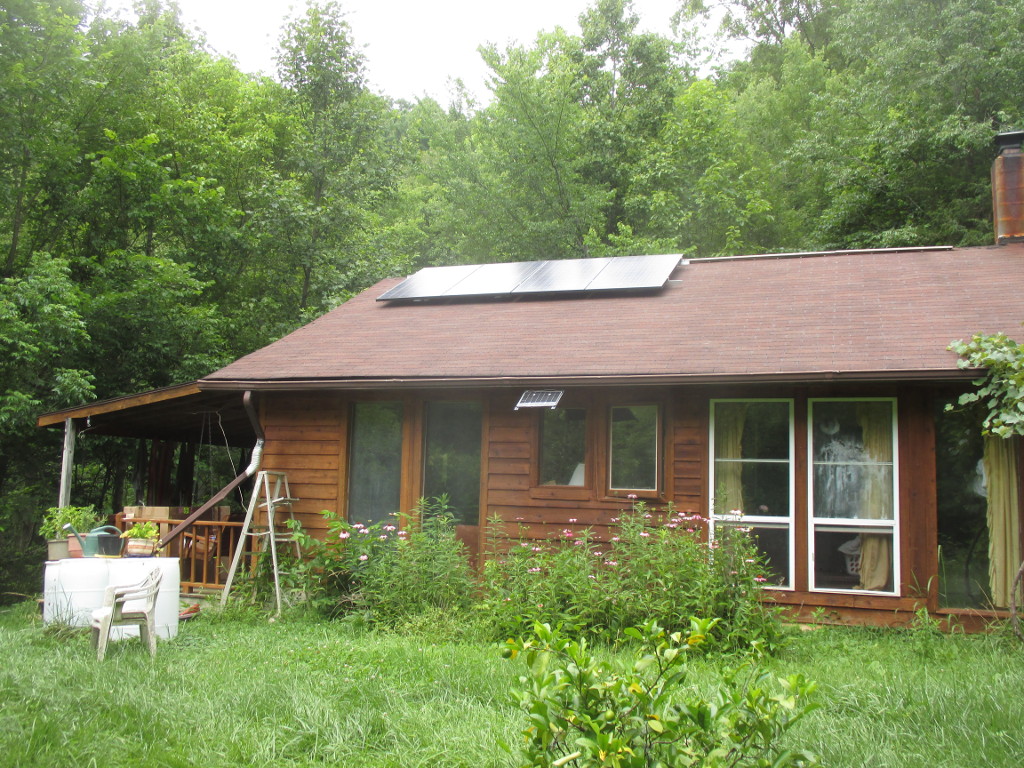
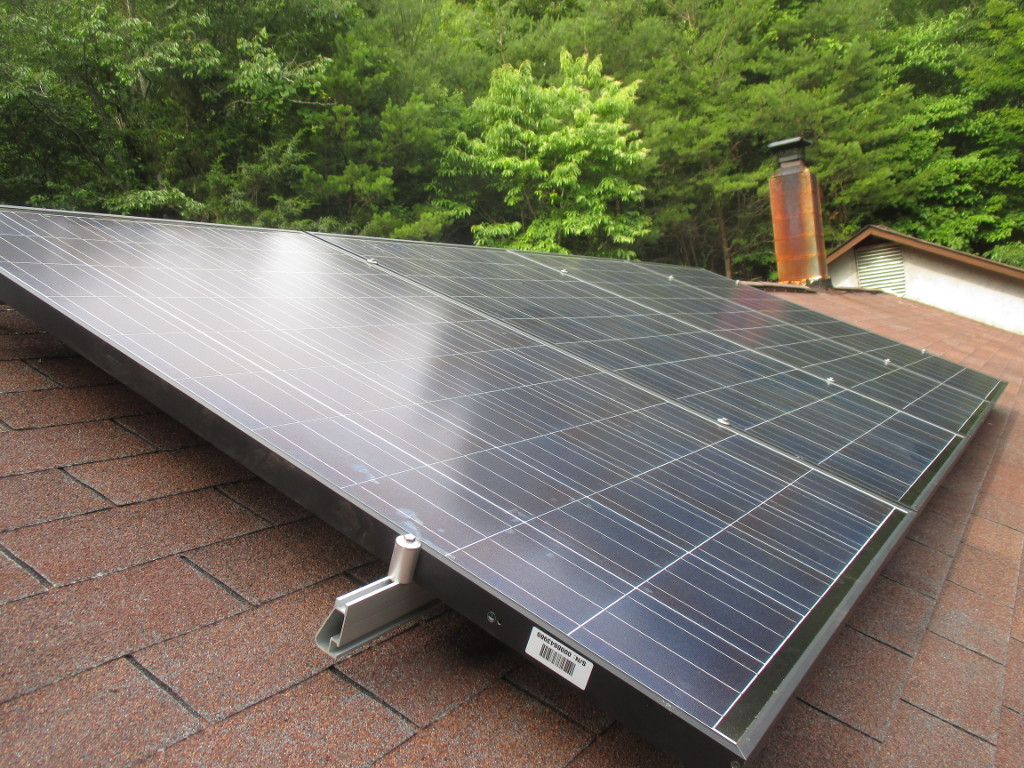
I've installed 1 kilowatt of solar panels on my roof, using professional grade eqipment. The four panels are Astronergy 260 watt panels, and they're mounted on IronRidge XR100 rails. Did it all myself, without help. house with 4 solar panels on roof I had three goals for this install:
  1. Cheap but sturdy. Total cost will be under $2500. It would probably cost at least twice as much to get a professional install, and the pros might not even want to do such a small install.
  2. Learn the roof mount system. I want to be able to add more panels, remove panels when working on the roof, and understand everything.
  3. Make every day a sunny day. With my current solar panels, I get around 10x as much power on a sunny day as a cloudy day, and I have plenty of power on sunny days. So 10x the PV capacity should be a good amount of power all the time.
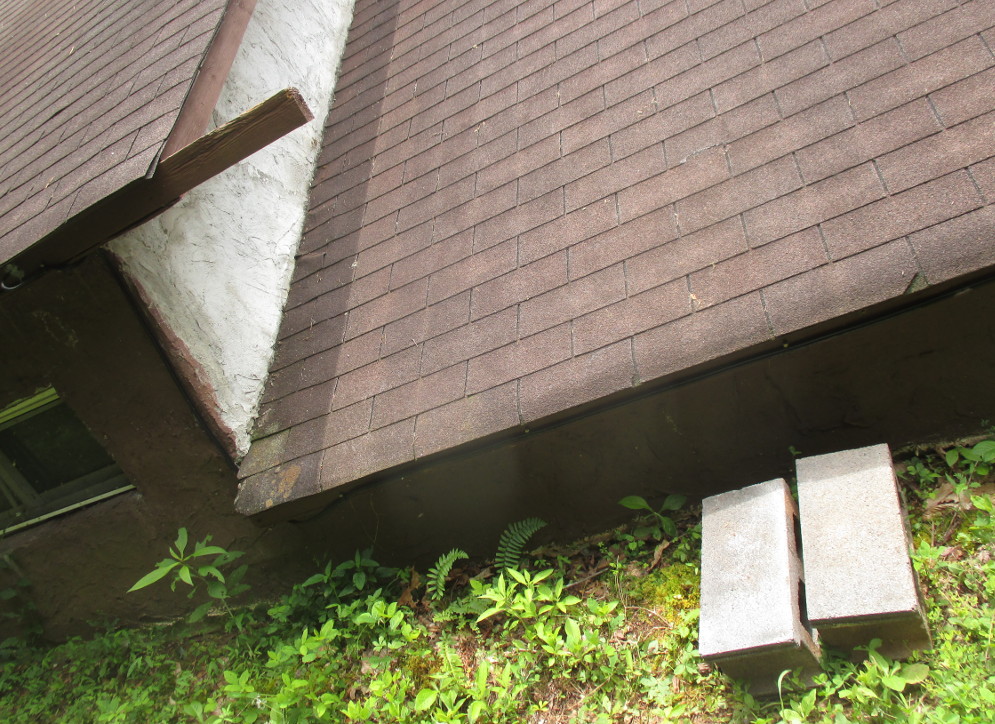
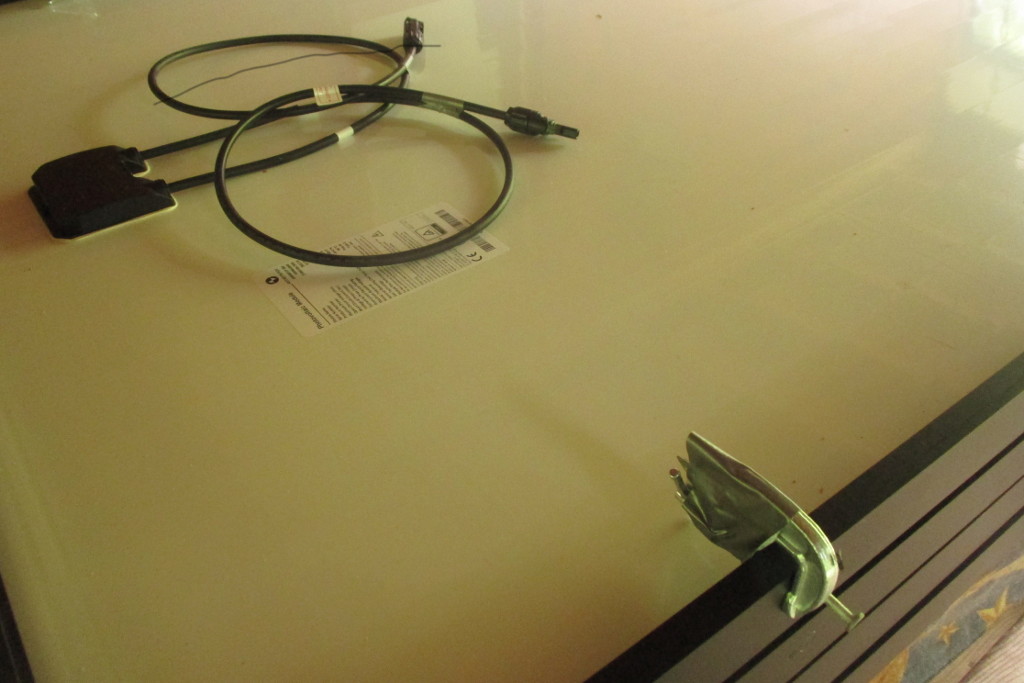
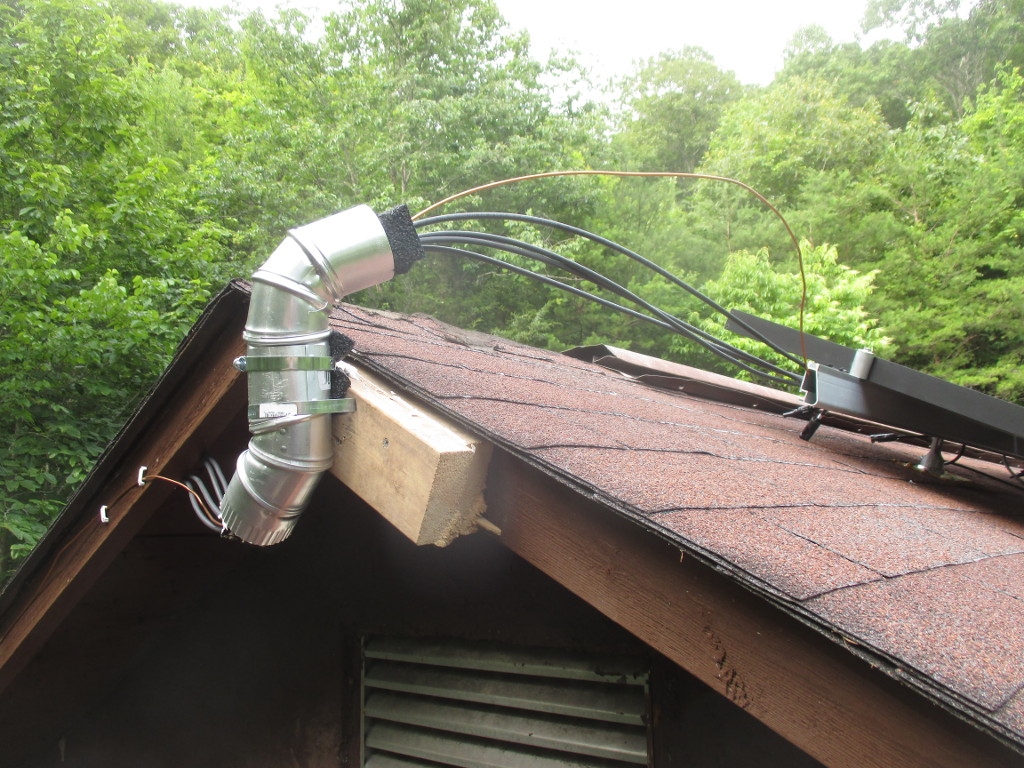
My main concerns were, would I be able to find the rafters when installing the rails, and would the 5x3 foot panels be too unweildly to get up on the roof by myself. I was able to find the rafters, without needing a stud finder, after I removed the roof's vent caps, which exposed the rafters. The shingles were on straight enough that I could follow the lines down and drilled into the rafter on the first try every time. And I got the rails on spaced well and straight, although I could have spaced the FlashFeet out better (oops). My drill ran out of juice half-way, and I had to hack it to recharge on solar power, but that's another story. Between the learning curve, a lot of careful measurement, not the greatest shoes for roofing, and waiting for recharging, it took two days to get the 8 FlashFeet installed and the rails mounted. Taking a break from that and swimming in the river, I realized I should have been wearing my water shoes on the roof all along. Super soft and nubbly, they make me feel like a gecko up there! After recovering from an (unrelated) achilles tendon strain, I got the panels installed today. Turns out they're not hard to handle on the roof by myself. Getting them up a ladder to the roof by yourself would normally be another story, but my house has a 2 foot step up from the back retaining wall to the roof, and even has a handy grip beam as you step up. roof next to the ground with a couple of cinderblock steps The last gotcha, which I luckily anticipated, is that panels will slide down off the rails before you can get them bolted down. This is where a second pair of hands would have been most useful. But, I macguyvered a solution, attaching temporary clamps before bringing a panel up, that stopped it sliding down while I was attaching it. clamp temporarily attached to side of panel I also finished the outside wiring today. Including the one hack of this install so far. Since the local hardware store didn't have a suitable conduit to bring the cables off the roof, I cobbled one together from pipe, with foam inserts to prevent chafing. some pipe with 5 wires running through it, attached to the side of the roof While I have 1 kilowatt of power on my roof now, I won't be able to use it until next week. After ordering the upgrade, I realized that my old PWM charge controller would be able to handle less than half the power, and to get even that I would have needed to mount the fuse box near the top of the roof and run down a large and expensive low-voltage high-amperage cable, around OO AWG size. Instead, I'll be upgrading to a MPPT controller, and running a single 150 volt cable to it. Then, since the MPPT controller can only handle 1 kilowatt when it's converting to 24 volts, not 12 volts, I'm gonna have to convert the entire house over from 12V DC to 24V DC, including changing all the light fixtures and rewiring the battery bank...

Vincent Bernat: IPv4 route lookup on Linux

TL;DR: With its implementation of IPv4 routing tables using LPC-tries, Linux offers good lookup performance (50 ns for a full view) and low memory usage (64 MiB for a full view).
During the lifetime of an IPv4 datagram inside the Linux kernel, one important step is the route lookup for the destination address through the fib_lookup() function. From essential information about the datagram (source and destination IP addresses, interfaces, firewall mark, ), this function should quickly provide a decision. Some possible options are: Since 2.6.39, Linux stores routes into a compressed prefix tree (commit 3630b7c050d9). In the past, a route cache was maintained but it has been removed1 in Linux 3.6.

Route lookup in a trie Looking up a route in a routing table is to find the most specific prefix matching the requested destination. Let s assume the following routing table:
$ ip route show scope global table 100
default via 203.0.113.5 dev out2
192.0.2.0/25
        nexthop via 203.0.113.7  dev out3 weight 1
        nexthop via 203.0.113.9  dev out4 weight 1
192.0.2.47 via 203.0.113.3 dev out1
192.0.2.48 via 203.0.113.3 dev out1
192.0.2.49 via 203.0.113.3 dev out1
192.0.2.50 via 203.0.113.3 dev out1
Here are some examples of lookups and the associated results:
Destination IP Next hop
192.0.2.49 203.0.113.3 via out1
192.0.2.50 203.0.113.3 via out1
192.0.2.51 203.0.113.7 via out3 or 203.0.113.9 via out4 (ECMP)
192.0.2.200 203.0.113.5 via out2
A common structure for route lookup is the trie, a tree structure where each node has its parent as prefix.

Lookup with a simple trie The following trie encodes the previous routing table: Simple routing trie For each node, the prefix is known by its path from the root node and the prefix length is the current depth. A lookup in such a trie is quite simple: at each step, fetch the nth bit of the IP address, where n is the current depth. If it is 0, continue with the first child. Otherwise, continue with the second. If a child is missing, backtrack until a routing entry is found. For example, when looking for 192.0.2.50, we will find the result in the corresponding leaf (at depth 32). However for 192.0.2.51, we will reach 192.0.2.50/31 but there is no second child. Therefore, we backtrack until the 192.0.2.0/25 routing entry. Adding and removing routes is quite easy. From a performance point of view, the lookup is done in constant time relative to the number of routes (due to maximum depth being capped to 32). Quagga is an example of routing software still using this simple approach.

Lookup with a path-compressed trie In the previous example, most nodes only have one child. This leads to a lot of unneeded bitwise comparisons and memory is also wasted on many nodes. To overcome this problem, we can use path compression: each node with only one child is removed (except if it also contains a routing entry). Each remaining node gets a new property telling how many input bits should be skipped. Such a trie is also known as a Patricia trie or a radix tree. Here is the path-compressed version of the previous trie: Patricia trie Since some bits have been ignored, on a match, a final check is executed to ensure all bits from the found entry are matching the input IP address. If not, we must act as if the entry wasn t found (and backtrack to find a matching prefix). The following figure shows two IP addresses matching the same leaf: Lookup in a Patricia trie The reduction on the average depth of the tree compensates the necessity to handle those false positives. The insertion and deletion of a routing entry is still easy enough. Many routing systems are using Patricia trees:

Lookup with a level-compressed trie In addition to path compression, level compression2 detects parts of the trie that are densily populated and replace them with a single node and an associated vector of 2k children. This node will handle k input bits instead of just one. For example, here is a level-compressed version our previous trie: Level-compressed trie Such a trie is called LC-trie or LPC-trie and offers higher lookup performances compared to a radix tree. An heuristic is used to decide how many bits a node should handle. On Linux, if the ratio of non-empty children to all children would be above 50% when the node handles an additional bit, the node gets this additional bit. On the other hand, if the current ratio is below 25%, the node loses the responsibility of one bit. Those values are not tunable. Insertion and deletion becomes more complex but lookup times are also improved.

Implementation in Linux The implementation for IPv4 in Linux exists since 2.6.13 (commit 19baf839ff4a) and is enabled by default since 2.6.39 (commit 3630b7c050d9). Here is the representation of our example routing table in memory3: Memory representation of a trie There are several structures involved: The trie can be retrieved through /proc/net/fib_trie:
$ cat /proc/net/fib_trie
Id 100:
  +-- 0.0.0.0/0 2 0 2
      -- 0.0.0.0
        /0 universe UNICAST
     +-- 192.0.2.0/26 2 0 1
         -- 192.0.2.0
           /25 universe UNICAST
         -- 192.0.2.47
           /32 universe UNICAST
        +-- 192.0.2.48/30 2 0 1
            -- 192.0.2.48
              /32 universe UNICAST
            -- 192.0.2.49
              /32 universe UNICAST
            -- 192.0.2.50
              /32 universe UNICAST
[...]
For internal nodes, the numbers after the prefix are:
  1. the number of bits handled by the node,
  2. the number of full children (they only handle one bit),
  3. the number of empty children.
Moreover, if the kernel was compiled with CONFIG_IP_FIB_TRIE_STATS, some interesting statistics are available in /proc/net/fib_triestat4:
$ cat /proc/net/fib_triestat
Basic info: size of leaf: 48 bytes, size of tnode: 40 bytes.
Id 100:
        Aver depth:     2.33
        Max depth:      3
        Leaves:         6
        Prefixes:       6
        Internal nodes: 3
          2: 3
        Pointers: 12
Null ptrs: 4
Total size: 1  kB
[...]
When a routing table is very dense, a node can handle many bits. For example, a densily populated routing table with 1 million entries packed in a /12 can have one internal node handling 20 bits. In this case, route lookup is essentially reduced to a lookup in a vector. The following graph shows the number of internal nodes used relative to the number of routes for different scenarios (routes extracted from an Internet full view, /32 routes spreaded over 4 different subnets with various densities). When routes are densily packed, the number of internal nodes are quite limited. Internal nodes and null pointers

Performance So how performant is a route lookup? The maximum depth stays low (about 6 for a full view), so a lookup should be quite fast. With the help of a small kernel module, we can accurately benchmark5 the fib_lookup() function: Maximum depth and lookup time The lookup time is loosely tied to the maximum depth. When the routing table is densily populated, the maximum depth is low and the lookup times are fast. When forwarding at 10 Gbps, the time budget for a packet would be about 50 ns. Since this is also the time needed for the route lookup alone in some cases, we wouldn t be able to forward at line rate with only one core. Nonetheless, the results are pretty good and they are expected to scale linearly with the number of cores. The measurements are done with a Linux kernel 4.11 from Debian unstable. I have gathered performance metrics accross kernel versions in Performance progression of IPv4 route lookup on Linux . Another interesting figure is the time it takes to insert all those routes into the kernel. Linux is also quite efficient in this area since you can insert 2 million routes in less than 10 seconds: Insertion time

Memory usage The memory usage is available directly in /proc/net/fib_triestat. The statistic provided doesn t account for the fib_info structures, but you should only have a handful of them (one for each possible next-hop). As you can see on the graph below, the memory use is linear with the number of routes inserted, whatever the shape of the routes is. Memory usage The results are quite good. With only 256 MiB, about 2 million routes can be stored!

Routing rules Unless configured without CONFIG_IP_MULTIPLE_TABLES, Linux supports several routing tables and has a system of configurable rules to select the table to use. These rules can be configured with ip rule. By default, there are three of them:
$ ip rule show
0:      from all lookup local
32766:  from all lookup main
32767:  from all lookup default
Linux will first lookup for a match in the local table. If it doesn t find one, it will lookup in the main table and at last resort, the default table.

Builtin tables The local table contains routes for local delivery:
$ ip route show table local
broadcast 127.0.0.0 dev lo proto kernel scope link src 127.0.0.1
local 127.0.0.0/8 dev lo proto kernel scope host src 127.0.0.1
local 127.0.0.1 dev lo proto kernel scope host src 127.0.0.1
broadcast 127.255.255.255 dev lo proto kernel scope link src 127.0.0.1
broadcast 192.168.117.0 dev eno1 proto kernel scope link src 192.168.117.55
local 192.168.117.55 dev eno1 proto kernel scope host src 192.168.117.55
broadcast 192.168.117.63 dev eno1 proto kernel scope link src 192.168.117.55
This table is populated automatically by the kernel when addresses are configured. Let s look at the three last lines. When the IP address 192.168.117.55 was configured on the eno1 interface, the kernel automatically added the appropriate routes:
  • a route for 192.168.117.55 for local unicast delivery to the IP address,
  • a route for 192.168.117.255 for broadcast delivery to the broadcast address,
  • a route for 192.168.117.0 for broadcast delivery to the network address.
When 127.0.0.1 was configured on the loopback interface, the same kind of routes were added to the local table. However, a loopback address receives a special treatment and the kernel also adds the whole subnet to the local table. As a result, you can ping any IP in 127.0.0.0/8:
$ ping -c1 127.42.42.42
PING 127.42.42.42 (127.42.42.42) 56(84) bytes of data.
64 bytes from 127.42.42.42: icmp_seq=1 ttl=64 time=0.039 ms
--- 127.42.42.42 ping statistics ---
1 packets transmitted, 1 received, 0% packet loss, time 0ms
rtt min/avg/max/mdev = 0.039/0.039/0.039/0.000 ms
The main table usually contains all the other routes:
$ ip route show table main
default via 192.168.117.1 dev eno1 proto static metric 100
192.168.117.0/26 dev eno1 proto kernel scope link src 192.168.117.55 metric 100
The default route has been configured by some DHCP daemon. The connected route (scope link) has been automatically added by the kernel (proto kernel) when configuring an IP address on the eno1 interface. The default table is empty and has little use. It has been kept when the current incarnation of advanced routing has been introduced in Linux 2.1.68 after a first tentative using classes in Linux 2.1.156.

Performance Since Linux 4.1 (commit 0ddcf43d5d4a), when the set of rules is left unmodified, the main and local tables are merged and the lookup is done with this single table (and the default table if not empty). Moreover, since Linux 3.0 (commit f4530fa574df), without specific rules, there is no performance hit when enabling the support for multiple routing tables. However, as soon as you add new rules, some CPU cycles will be spent for each datagram to evaluate them. Here is a couple of graphs demonstrating the impact of routing rules on lookup times: Routing rules impact on performance For some reason, the relation is linear when the number of rules is between 1 and 100 but the slope increases noticeably past this threshold. The second graph highlights the negative impact of the first rule (about 30 ns). A common use of rules is to create virtual routers: interfaces are segregated into domains and when a datagram enters through an interface from domain A, it should use routing table A:
# ip rule add iif vlan457 table 10
# ip rule add iif vlan457 blackhole
# ip rule add iif vlan458 table 20
# ip rule add iif vlan458 blackhole
The blackhole rules may be removed if you are sure there is a default route in each routing table. For example, we add a blackhole default with a high metric to not override a regular default route:
# ip route add blackhole default metric 9999 table 10
# ip route add blackhole default metric 9999 table 20
# ip rule add iif vlan457 table 10
# ip rule add iif vlan458 table 20
To reduce the impact on performance when many interface-specific rules are used, interfaces can be attached to VRF instances and a single rule can be used to select the appropriate table:
# ip link add vrf-A type vrf table 10
# ip link set dev vrf-A up
# ip link add vrf-B type vrf table 20
# ip link set dev vrf-B up
# ip link set dev vlan457 master vrf-A
# ip link set dev vlan458 master vrf-B
# ip rule show
0:      from all lookup local
1000:   from all lookup [l3mdev-table]
32766:  from all lookup main
32767:  from all lookup default
The special l3mdev-table rule was automatically added when configuring the first VRF interface. This rule will select the routing table associated to the VRF owning the input (or output) interface. VRF was introduced in Linux 4.3 (commit 193125dbd8eb), the performance was greatly enhanced in Linux 4.8 (commit 7889681f4a6c) and the special routing rule was also introduced in Linux 4.8 (commit 96c63fa7393d, commit 1aa6c4f6b8cd). You can find more details about it in the kernel documentation.

Conclusion The takeaways from this article are:
  • route lookup times hardly increase with the number of routes,
  • densily packed /32 routes lead to amazingly fast route lookups,
  • memory use is low (128 MiB par million routes),
  • no optimization is done on routing rules.

  1. The routing cache was subject to reasonably easy to launch denial of service attacks. It was also believed to not be efficient for high volume sites like Google but I have first-hand experience it was not the case for moderately high volume sites.
  2. IP-address lookup using LC-tries , IEEE Journal on Selected Areas in Communications, 17(6):1083-1092, June 1999.
  3. For internal nodes, the key_vector structure is embedded into a tnode structure. This structure contains information rarely used during lookup, notably the reference to the parent that is usually not needed for backtracking as Linux keeps the nearest candidate in a variable.
  4. One leaf can contain several routes (struct fib_alias is a list). The number of prefixes can therefore be greater than the number of leaves. The system also keeps statistics about the distribution of the internal nodes relative to the number of bits they handle. In our example, all the three internal nodes are handling 2 bits.
  5. The measurements are done in a virtual machine with one vCPU. The host is an Intel Core i5-4670K running at 3.7 GHz during the experiment (CPU governor was set to performance). The benchmark is single-threaded. It runs a warm-up phase, then executes about 100,000 timed iterations and keeps the median. Timings of individual runs are computed from the TSC.
  6. Fun fact: the documentation of this first tentative of more flexible routing is still available in today s kernel tree and explains the usage of the default class .

19 June 2017

Shirish Agarwal: Seizures, Vigo and bi-pedal motion

Dear all, an update is in order. While talking to physiotherapist couple of days before, came to know the correct term to what was I experiencing. I had experienced convulsive seizure , spasms being a part of it. Reading the wikipedia entry and the associated links/entries it seems I am and was very very lucky. The hospital or any hospital is a very bad bad place. I have seen all horror movies which people say are disturbing but have never been disturbed as much as I was in hospital. I couldn t help but hear people s screams and saw so many cases which turned critical. At times it was not easy to remain positive but dunno from where there was a will to live which pushed me and is still pushing me. One of the things that was painful for a long time were the almost constant stream of injections that were injected in me. It was almost an afterthought that the nurse put a Vigo in me. Similar to the Vigo injected in me. While the above medical device is similar, mine had a cross, the needle was much shorter and is injected into the vein. After that all injections are injected into that including common liquid which is salt,water and something commonly given to patients to stabilize first. I am not remembering the name atm. I also had a urine bag which was attached to my penis in a non-invasive manner. Both my grandfather and grandma used to cry when things went wrong while I didn t feel any pain but when the urine bag was disattached and attached again, so seems things have improved there. I was also very conscious of getting bed sores as both my grandpa and grandma had them when in hospital. As I had no strength I had to beg. plead do everything to make sure that every few hours I was turned from one side to other. I also had an air bag which is supposed to alleviate or relief this condition. Constant physiotherapy every day for a while slowly increased my strength and slowly both the vigo and feeding tube put inside my throat was removed. I have no remembrance as to when they had put the feeding tube as it was all rubber and felt bad when it came out. Further physiotherapy helped me crawl till the top of the bed, the bed was around 6 feet in length and and more than enough so I could turn both sides without falling over. Few days later I found I could also sit up using my legs as a lever and that gave confidence to the doctors to remove the air bed so I could crawl more easily. Couple of more days later I stood on my feet for the first time and it was like I had lead legs. Each step was painful but the sense and feeling of independence won over whatever pain was there. I had to endure wet wipes from nurses and ward boys in place of a shower everyday and while they were respectful always it felt humiliating. The first time I had a bath after 2 weeks or something, every part of my body cried and I felt like a weakling. I had thought I wouldn t be able to do justice to the physiotherapy session which was soon after but after the session was back to feeling normal. For a while I was doing the penguin waddle which while painful was also had humor in it. I did think of shooting the penguin waddle but decided against it as I was half-naked most of the time ( the hospital clothes never fit me properly) Cut to today and I was able to climb up and down the stairs on my own and circled my own block, slowly but was able to do it on my own by myself. While I always had a sense of wonderment for bi-pedal motion as well as all other means of transport, found much more respect of walking. I live near a fast food eating joint so I see lot of youngsters posing in different ways with their legs to show interest to their mates. And this I know happens both on the conscious and sub-conscious levels. To be able to see and discern that also put a sense of wonder in nature s creations. All in all, I m probabl6y around 40% independent and still 60% interdependent. I know I have to be patient with myself and those around me and explain to others what I m going through. For e.g. I still tend to spill things and still can t touch-type much. So, the road is long, I can only pray and hope best wishes for anybody who is my condition and do pray that nobody goes through what I went through, especiallly not children. I am also hoping that things like DxtER and range of non-invasive treatments make their way into India and the developing world at large. Anybody who is overweight and is either disgusted or doesn t like the gym route, would recommend doing sessions with a physiotherapist that you can trust. You have to trust that her judgement will push you a bit more and not more that the gains you make are toppled over. I still get dizziness spells while doing therapy but will to break it as I know dizziness doesn t help me. I hope my writings give strength and understanding to either somebody who is going through it, or relatives or/and caregivers so they know the mental status of the person who s going through it. Till later and sorry it became so long. Update I forgot to share this inspirational story from my city which I shared with a friend days ago. Add to that, she is from my city. What it doesn t share is that Triund is a magical place. I had visited once with a friend who had elf ears (he had put on elf ears) and it is kind of place which alchemist talks about, a place where imagination does turn wild and there is magic in the air.
Filed under: Miscellenous Tagged: #air bag, #bed sores, #convulsive epileptic seizure, #crawling, #horror, #humiliation, #nakedness, #penguin waddle, #physiotherapy, #planet-debian, #spilling things, #urine bag, #Vigo medical device

Vasudev Kamath: Update: - Shell pipelines with subprocess crate and use of Exec::shell function

In my previous post I used Exec::shell function from subprocess crate and passed it string generated by interpolating --author argument. This string was then run by the shell via Exec::shell. After publishing post I got ping on IRC by Jonas Smedegaard and Paul Wise that I should replace Exec::shell, as it might be prone to errors or vulnerabilities of shell injection attack. Indeed they were right, in hurry I did not completely read the function documentation which clearly mentions this fact.
When invoking this function, be careful not to interpolate arguments into the string run by the shell, such as Exec::shell(format!("sort ", filename)). Such code is prone to errors and, if filename comes from an untrusted source, to shell injection attacks. Instead, use Exec::cmd("sort").arg(filename).
Though I'm not directly taking input from untrusted source, its still possible that the string I got back from git log command might contain some oddly formatted string with characters of different encoding which could possibly break the Exec::shell , as I'm not sanitizing the shell command. When we use Exec::cmd and pass argument using .args chaining, the library takes care of creating safe command line. So I went in and modified the function to use Exec::cmd instead of Exec::shell. Below is updated function.
fn copyright_fromgit(repo: &str) -> Result<Vec<String>>  
    let tempdir = TempDir::new_in(".", "debcargo")?;
    Exec::cmd("git")
     .args(&["clone", "--bare", repo, tempdir.path().to_str().unwrap()])
     .stdout(subprocess::NullFile)
     .stderr(subprocess::NullFile)
     .popen()?;
    let author_process =  
        Exec::shell(OsStr::new("git log --format=\"%an <%ae>\"")).cwd(tempdir.path())  
        Exec::shell(OsStr::new("sort -u"))
     .capture()?;
    let authors = author_process.stdout_str().trim().to_string();
    let authors: Vec<&str> = authors.split('\n').collect();
    let mut notices: Vec<String> = Vec::new();
    for author in &authors  
        let author_string = format!("--author= ", author);
        let first =  
            Exec::cmd("/usr/bin/git")
             .args(&["log", "--format=%ad",
                    "--date=format:%Y",
                    "--reverse",
                    &author_string])
             .cwd(tempdir.path())   Exec::shell(OsStr::new("head -n1"))
         .capture()?;
        let latest =  
            Exec::cmd("/usr/bin/git")
             .args(&["log", "--format=%ad", "--date=format:%Y", &author_string])
             .cwd(tempdir.path())   Exec::shell("head -n1")
         .capture()?;
        let start = i32::from_str(first.stdout_str().trim())?;
        let end = i32::from_str(latest.stdout_str().trim())?;
        let cnotice = match start.cmp(&end)  
            Ordering::Equal => format!(" ,  ", start, author),
            _ => format!(" - ,  ", start, end, author),
         ;
        notices.push(cnotice);
     
    Ok(notices)
 
I still use Exec::shell for generating author list, this is not problematic as I'm not interpolating arguments to create command string.

18 June 2017

Simon Josefsson: OpenPGP smartcard under GNOME on Debian 9.0 Stretch

I installed Debian 9.0 Stretch on my Lenovo X201 laptop today. Installation went smooth, as usual. GnuPG/SSH with an OpenPGP smartcard I use a YubiKey NEO does not work out of the box with GNOME though. I wrote about how to fix OpenPGP smartcards under GNOME with Debian 8.0 Jessie earlier, and I thought I d do a similar blog post for Debian 9.0 Stretch . The situation is slightly different than before (e.g., GnuPG works better but SSH doesn t) so there is some progress. May I hope that Debian 10.0 Buster gets this right? Pointers to which package in Debian should have a bug report tracking this issue is welcome (or a pointer to an existing bug report). After first login, I attempt to use gpg --card-status to check if GnuPG can talk to the smartcard.
jas@latte:~$ gpg --card-status
gpg: error getting version from 'scdaemon': No SmartCard daemon
gpg: OpenPGP card not available: No SmartCard daemon
jas@latte:~$ 
This fails because scdaemon is not installed. Isn t a smartcard common enough so that this should be installed by default on a GNOME Desktop Debian installation? Anyway, install it as follows.
root@latte:~# apt-get install scdaemon
Then try again.
jas@latte:~$ gpg --card-status
gpg: selecting openpgp failed: No such device
gpg: OpenPGP card not available: No such device
jas@latte:~$ 
I believe scdaemon here attempts to use its internal CCID implementation, and I do not know why it does not work. At this point I often recall that want pcscd installed since I work with smartcards in general.
root@latte:~# apt-get install pcscd
Now gpg --card-status works!
jas@latte:~$ gpg --card-status
Reader ...........: Yubico Yubikey NEO CCID 00 00
Application ID ...: D2760001240102000006017403230000
Version ..........: 2.0
Manufacturer .....: Yubico
Serial number ....: 01740323
Name of cardholder: Simon Josefsson
Language prefs ...: sv
Sex ..............: male
URL of public key : https://josefsson.org/54265e8c.txt
Login data .......: jas
Signature PIN ....: not forced
Key attributes ...: rsa2048 rsa2048 rsa2048
Max. PIN lengths .: 127 127 127
PIN retry counter : 3 3 3
Signature counter : 8358
Signature key ....: 9941 5CE1 905D 0E55 A9F8  8026 860B 7FBB 32F8 119D
      created ....: 2014-06-22 19:19:04
Encryption key....: DC9F 9B7D 8831 692A A852  D95B 9535 162A 78EC D86B
      created ....: 2014-06-22 19:19:20
Authentication key: 2E08 856F 4B22 2148 A40A  3E45 AF66 08D7 36BA 8F9B
      created ....: 2014-06-22 19:19:41
General key info..: sub  rsa2048/860B7FBB32F8119D 2014-06-22 Simon Josefsson 
sec#  rsa3744/0664A76954265E8C  created: 2014-06-22  expires: 2017-09-04
ssb>  rsa2048/860B7FBB32F8119D  created: 2014-06-22  expires: 2017-09-04
                                card-no: 0006 01740323
ssb>  rsa2048/9535162A78ECD86B  created: 2014-06-22  expires: 2017-09-04
                                card-no: 0006 01740323
ssb>  rsa2048/AF6608D736BA8F9B  created: 2014-06-22  expires: 2017-09-04
                                card-no: 0006 01740323
jas@latte:~$ 
Using the key will not work though.
jas@latte:~$ echo foo gpg -a --sign
gpg: no default secret key: No secret key
gpg: signing failed: No secret key
jas@latte:~$ 
This is because the public key and the secret key stub are not available.
jas@latte:~$ gpg --list-keys
jas@latte:~$ gpg --list-secret-keys
jas@latte:~$ 
You need to import the key for this to work. I have some vague memory that gpg --card-status was supposed to do this, but I may be wrong.
jas@latte:~$ gpg --recv-keys 9AA9BDB11BB1B99A21285A330664A76954265E8C
gpg: failed to start the dirmngr '/usr/bin/dirmngr': No such file or directory
gpg: connecting dirmngr at '/run/user/1000/gnupg/S.dirmngr' failed: No such file or directory
gpg: keyserver receive failed: No dirmngr
jas@latte:~$ 
Surprisingly, dirmngr is also not shipped by default so it has to be installed manually.
root@latte:~# apt-get install dirmngr
Below I proceed to trust the clouds to find my key.
jas@latte:~$ gpg --recv-keys 9AA9BDB11BB1B99A21285A330664A76954265E8C
gpg: key 0664A76954265E8C: public key "Simon Josefsson " imported
gpg: no ultimately trusted keys found
gpg: Total number processed: 1
gpg:               imported: 1
jas@latte:~$ 
Now the public key and the secret key stub are available locally.
jas@latte:~$ gpg --list-keys
/home/jas/.gnupg/pubring.kbx
----------------------------
pub   rsa3744 2014-06-22 [SC] [expires: 2017-09-04]
      9AA9BDB11BB1B99A21285A330664A76954265E8C
uid           [ unknown] Simon Josefsson 
sub   rsa2048 2014-06-22 [S] [expires: 2017-09-04]
sub   rsa2048 2014-06-22 [E] [expires: 2017-09-04]
sub   rsa2048 2014-06-22 [A] [expires: 2017-09-04]
jas@latte:~$ gpg --list-secret-keys
/home/jas/.gnupg/pubring.kbx
----------------------------
sec#  rsa3744 2014-06-22 [SC] [expires: 2017-09-04]
      9AA9BDB11BB1B99A21285A330664A76954265E8C
uid           [ unknown] Simon Josefsson 
ssb>  rsa2048 2014-06-22 [S] [expires: 2017-09-04]
ssb>  rsa2048 2014-06-22 [E] [expires: 2017-09-04]
ssb>  rsa2048 2014-06-22 [A] [expires: 2017-09-04]
jas@latte:~$ 
I am now able to sign data with the smartcard, yay!
jas@latte:~$ echo foo gpg -a --sign
-----BEGIN PGP MESSAGE-----
owGbwMvMwMHYxl2/2+iH4FzG01xJDJFu3+XT8vO5OhmNWRgYORhkxRRZZjrGPJwQ
yxe68keDGkwxKxNIJQMXpwBMRJGd/a98NMPJQt6jaoyO9yUVlmS7s7qm+Kjwr53G
uq9wQ+z+/kOdk9w4Q39+SMvc+mEV72kuH9WaW9bVqj80jN77hUbfTn5mffu2/aVL
h/IneTfaOQaukHij/P8A0//Phg/maWbONUjjySrl+a3tP8ll6/oeCd8g/aeTlH79
i0naanjW4bjv9wnvGuN+LPHLmhUc2zvZdyK3xttN/roHvsdX3f53yTAxeInvXZmd
x7W0/hVPX33Y4nT877T/ak4L057IBSavaPVcf4yhglVI8XuGgaTP666Wuslbliy4
5W5eLasbd33Xd/W0hTINznuz0kJ4r1bLHZW9fvjLduMPq5rS2co9tvW8nX9rhZ/D
zycu/QA=
=I8rt
-----END PGP MESSAGE-----
jas@latte:~$ 
Encrypting to myself will not work smoothly though.
jas@latte:~$ echo foo gpg -a --encrypt -r simon@josefsson.org
gpg: 9535162A78ECD86B: There is no assurance this key belongs to the named user
sub  rsa2048/9535162A78ECD86B 2014-06-22 Simon Josefsson 
 Primary key fingerprint: 9AA9 BDB1 1BB1 B99A 2128  5A33 0664 A769 5426 5E8C
      Subkey fingerprint: DC9F 9B7D 8831 692A A852  D95B 9535 162A 78EC D86B
It is NOT certain that the key belongs to the person named
in the user ID.  If you *really* know what you are doing,
you may answer the next question with yes.
Use this key anyway? (y/N) 
gpg: signal Interrupt caught ... exiting
jas@latte:~$ 
The reason is that the newly imported key has unknown trust settings. I update the trust settings on my key to fix this, and encrypting now works without a prompt.
jas@latte:~$ gpg --edit-key 9AA9BDB11BB1B99A21285A330664A76954265E8C
gpg (GnuPG) 2.1.18; Copyright (C) 2017 Free Software Foundation, Inc.
This is free software: you are free to change and redistribute it.
There is NO WARRANTY, to the extent permitted by law.
Secret key is available.
pub  rsa3744/0664A76954265E8C
     created: 2014-06-22  expires: 2017-09-04  usage: SC  
     trust: unknown       validity: unknown
ssb  rsa2048/860B7FBB32F8119D
     created: 2014-06-22  expires: 2017-09-04  usage: S   
     card-no: 0006 01740323
ssb  rsa2048/9535162A78ECD86B
     created: 2014-06-22  expires: 2017-09-04  usage: E   
     card-no: 0006 01740323
ssb  rsa2048/AF6608D736BA8F9B
     created: 2014-06-22  expires: 2017-09-04  usage: A   
     card-no: 0006 01740323
[ unknown] (1). Simon Josefsson 
[ unknown] (2)  Simon Josefsson 
gpg> trust
pub  rsa3744/0664A76954265E8C
     created: 2014-06-22  expires: 2017-09-04  usage: SC  
     trust: unknown       validity: unknown
ssb  rsa2048/860B7FBB32F8119D
     created: 2014-06-22  expires: 2017-09-04  usage: S   
     card-no: 0006 01740323
ssb  rsa2048/9535162A78ECD86B
     created: 2014-06-22  expires: 2017-09-04  usage: E   
     card-no: 0006 01740323
ssb  rsa2048/AF6608D736BA8F9B
     created: 2014-06-22  expires: 2017-09-04  usage: A   
     card-no: 0006 01740323
[ unknown] (1). Simon Josefsson 
[ unknown] (2)  Simon Josefsson 
Please decide how far you trust this user to correctly verify other users' keys
(by looking at passports, checking fingerprints from different sources, etc.)
  1 = I don't know or won't say
  2 = I do NOT trust
  3 = I trust marginally
  4 = I trust fully
  5 = I trust ultimately
  m = back to the main menu
Your decision? 5
Do you really want to set this key to ultimate trust? (y/N) y
pub  rsa3744/0664A76954265E8C
     created: 2014-06-22  expires: 2017-09-04  usage: SC  
     trust: ultimate      validity: unknown
ssb  rsa2048/860B7FBB32F8119D
     created: 2014-06-22  expires: 2017-09-04  usage: S   
     card-no: 0006 01740323
ssb  rsa2048/9535162A78ECD86B
     created: 2014-06-22  expires: 2017-09-04  usage: E   
     card-no: 0006 01740323
ssb  rsa2048/AF6608D736BA8F9B
     created: 2014-06-22  expires: 2017-09-04  usage: A   
     card-no: 0006 01740323
[ unknown] (1). Simon Josefsson 
[ unknown] (2)  Simon Josefsson 
Please note that the shown key validity is not necessarily correct
unless you restart the program.
gpg> quit
jas@latte:~$ echo foo gpg -a --encrypt -r simon@josefsson.org
-----BEGIN PGP MESSAGE-----
hQEMA5U1Fip47NhrAQgArTvAykj/YRhWVuXb6nzeEigtlvKFSmGHmbNkJgF5+r1/
/hWENR72wsb1L0ROaLIjM3iIwNmyBURMiG+xV8ZE03VNbJdORW+S0fO6Ck4FaIj8
iL2/CXyp1obq1xCeYjdPf2nrz/P2Evu69s1K2/0i9y2KOK+0+u9fEGdAge8Gup6y
PWFDFkNj2YiVa383BqJ+kV51tfquw+T4y5MfVWBoHlhm46GgwjIxXiI+uBa655IM
EgwrONcZTbAWSV4/ShhR9ug9AzGIJgpu9x8k2i+yKcBsgAh/+d8v7joUaPRZlGIr
kim217hpA3/VLIFxTTkkm/BO1KWBlblxvVaL3RZDDNI5AVp0SASswqBqT3W5ew+K
nKdQ6UTMhEFe8xddsLjkI9+AzHfiuDCDxnxNgI1haI6obp9eeouGXUKG
=s6kt
-----END PGP MESSAGE-----
jas@latte:~$ 
So everything is fine, isn t it? Alas, not quite.
jas@latte:~$ ssh-add -L
The agent has no identities.
jas@latte:~$ 
Tracking this down, I now realize that GNOME s keyring is used for SSH but GnuPG s gpg-agent is used for GnuPG. GnuPG uses the environment variable GPG_AGENT_INFO to connect to an agent, and SSH uses the SSH_AUTH_SOCK environment variable to find its agent. The filenames used below leak the knowledge that gpg-agent is used for GnuPG but GNOME keyring is used for SSH.
jas@latte:~$ echo $GPG_AGENT_INFO 
/run/user/1000/gnupg/S.gpg-agent:0:1
jas@latte:~$ echo $SSH_AUTH_SOCK 
/run/user/1000/keyring/ssh
jas@latte:~$ 
Here the same recipe as in my previous blog post works. This time GNOME keyring only has to be disabled for SSH. Disabling GNOME keyring is not sufficient, you also need gpg-agent to start with enable-ssh-support. The simplest way to achieve that is to add a line in ~/.gnupg/gpg-agent.conf as follows. When you login, the script /etc/X11/Xsession.d/90gpg-agent will set the environment variables GPG_AGENT_INFO and SSH_AUTH_SOCK. The latter variable is only set if enable-ssh-support is mentioned in the gpg-agent configuration.
jas@latte:~$ mkdir ~/.config/autostart
jas@latte:~$ cp /etc/xdg/autostart/gnome-keyring-ssh.desktop ~/.config/autostart/
jas@latte:~$ echo 'Hidden=true' >> ~/.config/autostart/gnome-keyring-ssh.desktop 
jas@latte:~$ echo enable-ssh-support >> ~/.gnupg/gpg-agent.conf 
jas@latte:~$ 
Log out from GNOME and log in again. Now you should see ssh-add -L working.
jas@latte:~$ ssh-add -L
ssh-rsa AAAAB3NzaC1yc2EAAAADAQABAAABAQDFP+UOTZJ+OXydpmbKmdGOVoJJz8se7lMs139T+TNLryk3EEWF+GqbB4VgzxzrGjwAMSjeQkAMb7Sbn+VpbJf1JDPFBHoYJQmg6CX4kFRaGZT6DHbYjgia59WkdkEYTtB7KPkbFWleo/RZT2u3f8eTedrP7dhSX0azN0lDuu/wBrwedzSV+AiPr10rQaCTp1V8sKbhz5ryOXHQW0Gcps6JraRzMW+ooKFX3lPq0pZa7qL9F6sE4sDFvtOdbRJoZS1b88aZrENGx8KSrcMzARq9UBn1plsEG4/3BRv/BgHHaF+d97by52R0VVyIXpLlkdp1Uk4D9cQptgaH4UAyI1vr cardno:000601740323
jas@latte:~$ 
Topics for further discussion or research include 1) whether scdaemon, dirmngr and/or pcscd should be pre-installed on Debian desktop systems; 2) whether gpg --card-status should attempt to import the public key and secret key stub automatically; 3) why GNOME keyring is used by default for SSH rather than gpg-agent; 4) whether GNOME keyring should support smartcards, or if it is better to always use gpg-agent for GnuPG/SSH, 5) if something could/should be done to automatically infer the trust setting for a secret key. Enjoy!

16 June 2017

Bits from Debian: Upcoming Debian 9.0 Stretch!

Alt Stretch is coming on 2017-06-17 The Debian Release Team in coordination with several other teams are preparing the last bits needed for releasing Debian 9 Stretch. Please, be patient! Lots of steps are involved and some of them take some time, such as building the images, propagating the release through the mirror network, and rebuilding the Debian website so that "stable" points to Debian 9. Follow the live coverage of the release on https://micronews.debian.org or the @debian profile in your favorite social network! We'll spread the word about what's new in this version of Debian 9, how the release process is progressing during the weekend and facts about Debian and the wide community of volunteer contributors that make it possible.

14 June 2017

Antoine Beaupr : Alioth moving toward pagure

Since 2003, the Debian project has been running a server called Alioth to host source code version control systems. The server will hit the end of life of the Debian LTS release (Wheezy) next year; that deadline raised some questions regarding the plans for the server over the coming years. Naturally, that led to a discussion regarding possible replacements. In response, the current Alioth maintainer, Alexander Wirt, announced a sprint to migrate to pagure, a free-software "Git-centered forge" written in Python for the Fedora project, which LWN covered last year. Alioth currently runs FusionForge, previously known as GForge, which is the free-software fork of the SourceForge code base when that service closed its source in 2001. Alioth hosts source code repositories, mainly Git and Subversion (SVN) and, like other "forge" sites, also offers forums, issue trackers, and mailing list services. While other alternatives are still being evaluated, a consensus has emerged on a migration plan from FusionForage to a more modern and minimal platform based on pagure.

Why not GitLab? While this may come as a surprise to some who would expect Debian to use the more popular GitLab project, the discussion and decision actually took place a while back. During a lengthy debate last year, Debian contributors discussed the relative merits of different code-hosting platforms, following the initiative of Debian Developer "Pirate" Praveen Arimbrathodiyil to package GitLab for Debian. At that time, Praveen also got a public GitLab instance running for Debian (gitlab.debian.net), which was sponsored by GitLab B.V. the commercial entity behind the GitLab project. The sponsorship was originally offered in 2015 by the GitLab CEO, presumably to counter a possible move to GitHub, as there was a discussion about creating a GitHub Organization for Debian at the time. The deployment of a Debian-specific GitLab instance then raised the question of the overlap with the already existing git.debian.org service, which is backed by Alioth's FusionForge deployment. It then seemed natural that the new GitLab instance would replace Alioth. But when Praveen directly proposed to move to GitLab, Wirt stepped in and explained that a migration plan was already in progress. The plan then was to migrate to a simpler gitolite-based setup, a decision that was apparently made in corridor discussions surrounding the Alioth Git replacement BoF held during Debconf 2015. The first objection raised by Wirt against GitLab was its "huge number of dependencies". Another issue Wirt identified was the "open core / enterprise model", preferring a "real open source system", an opinion which seems shared by other participants on the mailing list. Wirt backed his concerns with an hypothetical example:
Debian needs feature X but it is already in the enterprise version. We make a patch and, for commercial reasons, it never gets merged (they already sell it in the enterprise version). Which means we will have to fork the software and keep those patches forever. Been there done that. For me, that isn't acceptable.
This concern was further deepened when GitLab's Director of Strategic Partnerships, Eliran Mesika, explained the company's stewardship policy that explains how GitLab decides which features end up in the proprietary version. Praveen pointed out that:
[...] basically it boils down to features that they consider important for organizations with less than 100 developers may get accepted. I see that as a red flag for a big community like debian.
Since there are over 600 Debian Developers, the community seems to fall within the needs of "enterprise" users. The features the Debian community may need are, by definition, appropriate only to the "Enterprise Edition" (GitLab EE), the non-free version, and are therefore unlikely to end up in the "Community Edition" (GitLab CE), the free-software version. Interestingly, Mesika asked for clarification on which features were missing, explaining that GitLab is actually open to adding features to GitLab CE. The response from Debian Developer Holger Levsen was categorical: "It's not about a specific patch. Free GitLab and we can talk again." But beyond the practical and ethical concerns, some specific features Debian needs are currently only in GitLab EE. For example, debian.org systems use LDAP for authentication, which would obviously be useful in a GitLab deployment; GitLab CE supports basic LDAP authentication, but advanced features, like group or SSH-key synchronization, are only available in GitLab EE. Wirt also expressed concern about the Contributor License Agreement that GitLab B.V. requires contributors to sign when they send patches, which forces users to allow the release of their code under a non-free license. The debate then went on going through a exhaustive inventory of different free-software alternatives:
  • GitLab, a Ruby-based GitHub replacement, dual-licensed MIT/Commercial
  • Gogs, Go, MIT
  • Gitblit, Java, Apache-licensed
  • Kallithea, in Python, also supports Mercurial, GPLv3
  • and finally, pagure, also written Python, GPLv2
A feature comparison between each project was created in the Debian wiki as well. In the end, however, Praveen gave up on replacing Alioth with GitLab because of the controversy and moved on to support the pagure migration, which resolved the discussion in July 2016. More recently, Wirt admitted in an IRC conversation that "on the technical side I like GitLab a lot more than pagure" and that "as a user, GitLab is much nicer than pagure and it has those nice CI [continuous integration] features". However, as he explained in his blog "GitLab is Opencore, [and] that it is not entirely opensource. I don't think we should use software licensed under such a model for one of our core services" which leaves pagure as the only stable candidate. Other candidates were excluded on technical grounds, according to Wirt: Gogs "doesn't scale well" and a quick security check didn't yield satisfactory results; "Gitblit is Java" and Kallithea doesn't have support for accessing repositories over SSH (although there is a pending pull request to add the feature). In an email interview, Sid Sijbrandij, CEO of GitLab, did say that "we want to make sure that our open source edition can be used by open source projects". He gave examples of features liberated following requests by the community, such as branded login pages for the VLC project and GitLab Pages after popular demand. He stressed that "There are no artificial limits in our open source edition and some organizations use it with more than 20.000 users." So if the concern of the Debian community is that features may be missing from GitLab CE, there is definitely an opening from GitLab to add those features. If, however, the concern is purely ethical, it's hard to see how an agreement could be reached. As Sijbrandij put it:
On the mailinglist it seemed that some Debian maintainers do not agree with our open core business model and demand that there is no proprietary version. We respect that position but we don't think we can compete with the purely proprietary software like GitHub with this model.

Working toward a pagure migration The issue of Alioth maintenance came up again last month when Boyuan Yang asked what would happen to Alioth when support for Debian LTS (Wheezy) ends next year. Wirt brought up the pagure migration proposal and the community tried to make a plan for the migration. One of the issues raised was the question of the non-Git repositories hosted on Alioth, as pagure, like GitLab, only supports Git. Indeed, Ben Hutchings calculated that while 90% (\~19,000) of the repositories currently on Alioth are Git, there are 2,400 SVN repositories and a handful of Mercurial, Bazaar (bzr), Darcs, Arch, and even CVS repositories. As part of an informal survey, however, most packaging teams explained they either had already migrated away from SVN to Git or were in the process of doing so. The largest CVS user, the web site team, also explained it was progressively migrating to Git. Mattia Rizzolo then proposed that older repository services like SVN could continue running even if FusionForge goes down, as FusionForge is, after all, just a web interface to manage those back-end services. Repository creation would be disabled, but older repositories would stay operational until they migrate to Git. This would, effectively, mean the end of non-Git repository support for new projects in the Debian community, at least officially. Another issue is the creation of a Debian package for pagure. Ironically, while Praveen and other Debian maintainers have been working for 5 years to package GitLab for Debian, pagure isn't packaged yet. Antonio Terceiro, another Debian Developer, explained this isn't actually a large problem for debian.org services: "note that DSA [Debian System Administrator team] does not need/want the service software itself packaged, only its dependencies". Indeed, for Debian-specific code bases like ci.debian.net or tracker.debian.org, it may not make sense to have the overhead of maintaining Debian packages since those tools have limited use outside of the Debian project directly. While Debian derivatives and other distributions could reuse them, what usually happens is that other distributions roll their own software, like Ubuntu did with the Launchpad project. Still, Paul Wise, a member of the DSA team, reasoned that it was better, in the long term, to have Debian packages for debian.org services:
Personally I'm leaning towards the feeling that all configuration, code and dependencies for Debian services should be packaged and subjected to the usual Debian QA activities but I acknowledge that the current archive setup (testing migration plus backporting etc) doesn't necessarily make this easy.
Wise did say that "DSA doesn't have any hard rules/policy written down, just evaluation on a case-by-case basis" which probably means that pagure packaging will not be a blocker for deployment. The last pending issue is the question of the mailing lists hosted on Alioth, as pagure doesn't offer mailing list management (nor does GitLab). In fact, there are three different mailing list services for the Debian project: Wirt, with his "list-master hat" on, explained that the main mailing list service is "not really suited as a self-service" and expressed concern at the idea of migrating the large number mailing lists hosted on Alioth. Indeed, there are around 1,400 lists on Alioth while the main service has a set of 300 lists selected by the list masters. No solution for those mailing lists was found at the time of this writing. In the end, it seems like the Debian project has chosen pagure, the simpler, less featureful, but also less controversial, solution and will use the same hosting software as their fellow Linux distribution, Fedora. Wirt is also considering using FreeIPA for account management on top of pagure. The plan is to migrate away from FusionForge one bit at a time, and pagure is the solution for the first step: the Git repositories. Lists, other repositories, and additional features of FusionForge will be dealt with later on, but Wirt expects a plan to come out of the upcoming sprint. It will also be interesting to see how the interoperability promises of pagure will play out in the Debian world. Even though the federation features of pagure are still at the early stages, one can already clone issues and pull requests as Git repositories, which allows for a crude federation mechanism. In any case, given the long history and the wide variety of workflows in the Debian project, it is unlikely that a single tool will solve all problems. Alioth itself has significant overlap with other Debian services; not only does it handle mailing lists and forums, but it also has its own issue tracker that overlaps with the Debian bug tracking system (BTS). This is just the way things are in Debian: it is an old project with lots of moving part. As Jonathan Dowland put it: "The nature of the project is loosely-coupled, some redundancy, lots of legacy cruft, and sadly more than one way to do it." Hopefully, pagure will not become part of that "legacy redundant cruft". But at this point, the focus is on keeping the services running in a simpler, more maintainable way. The discussions between Debian and GitLab are still going on as we speak, but given how controversial the "open core" model used by GitLab is for the Debian community, pagure does seem like a more logical alternative.
Note: this article first appeared in the Linux Weekly News.

Mike Gabriel: Ayatana Indicators

In the near future various upstream projects related to the Ubuntu desktop experience as we have known it so far may become only sporadically maintained or even fully unmaintained. Ubuntu will switch to the Gnome desktop environment with 18.04 LTS as its default desktop, maybe even earlier. The Application Indicators [1] brought into being by Canonical Ltd. will not be needed in Gnome (AFAIK) any more. We can expect the Application Indicator related projects become unmaintained upstream. (In fact I have recently been offered continuation of upstream maintenance of libdbusmenu). Historical Background This all started at Ubuntu Developer Summit 2012 when Canonical Ltd. announced Ubuntu to become the successor of Windows XP in business offices. The Unity Greeter received an Remote Login Service enhancement: since then it supports Remote Login to Windows Terminal Servers. The question came up, why Remote Login to Linux servers--maybe even Ubuntu machines--is not on the agenda. It turned out, that it wasn't even a discussable topic. At that time, I started looking into the Unity Greeter code, adding support for X2Go Logon into Unity Greeter. I never really stopped looking at the greeter code from time to time. Since then, it turned into some sort of a hobby... While looking into the Unity Greeter code over the past years and actually forking Unity Greeter as Arctica Greeter [2] in September 2015, I also started looking into the Application Indicators concept just recently. And I must say, the more I have been looking into it, the more I have started liking the concept behind Application Indicators. The basic idea is awesome. However, lately all indicators became more and more Ubuntu-centric and IMHO too polluted by code related to the just declared dead Ubuntu phablet project. Forking Application Indicators Saying all this, I recently forked Application Indicators as Ayatana Indicators. At the moment I represent upstream and Debian package maintainer in one person. Ideally, this is only temporary and more people join in. (I heard some Unity 7 maintainers think about switching to Ayatana Indicators for the now community maintained Unity 7). The goal is to provide Ayatana Indicators to all desktop environments generically, all that want to use them, either as default or optionally. Release-wise, the idea is to strictly differentiate between upstream and Debian downstream in the release cycles of the various related components. I hope, noone is too concerned about the choice of name, as the "Ayatana" word actually was first used for upstream efforts inside Ubuntu [3]. Using the Ayatana term for the indicator forks is meant as honouring the previously undertaken efforts. I have seen very good work, so far, while going through the indicators' code. The upstream code must not be distro-specific, but, of course, can be distro-aware. Contributions Welcome The Ayatana Indicators upstream project components are currently hosted on Github under the umbrella of the Arctica Project. Regarding Debian, first uploads have recently been accepted to Debian experimental. The Debian packages are maintained under the umbrella of the revived Ayatana Packagers team [4]. Meet you at the Ayatana Indicators BoF at DebConf 17 (hopefully) For DebConf 17 (yeah, I am going there, if all plans work out well!!!!) I have submitted a BoF on this topic (let's hope, it gets accepted...). I'd like to give a quick overview on the current status of above named efforts and reasonings behind my commitment to the work. Most of the time during that BoF I would like to get into discussion with desktop maintainers, possibly upstream developers, Ubuntu developers, etc. Anyone who sees an asset in the Indicators approach is welcome to share and contribute. References

Nicolas Dandrimont: DebConf 17 bursaries: update your status now!

TL;DR: if you applied for a DebConf 17 travel bursary, and you haven t accepted it yet, login to the DebConf website and update your status before June 20th or your bursary grant will be gone. *blows dust off the blog* As you might be aware, DebConf 17 is coming soon and it s gonna be the biggest DebConf in Montr al ever. Of course, what makes DebConf great is the people who come together to work on Debian, share their achievements, and help draft our cunning plans to take over the world. Also cheese. Lots and lots of cheese. To that end, the DebConf team had initially budgeted US$40,000 for travel grants ($30,000 for contributors, $10,000 for diversity and inclusion grants), allowing the bursaries team to bring people from all around the world who couldn t have made it to the conference. Our team of volunteers rated the 188 applications, we ve made a ranking (technically, two rankings : one on contribution grounds and one on D&I grounds), and we finally sent out a first round of grants last week. After the first round, the team made a new budget assessment, and thanks to the support of our outstanding sponsors, an extra $15,000 has been allocated for travel stipends during this week s team meeting, with the blessing of the DPL. We ve therefore been able to send a second round of grants today. Now, if you got a grant, you have two things to do : you need to accept your grant, and you need to update your requested amount. Both of those steps allow us to use our budget more wisely: having grants expire frees money up to get more people to the conference earlier. Having updated amounts gives us a better view of our overall budget. (You can only lower your requested amount, as we can t inflate our budget) Our system has sent mails to everyone, but it s easy enough to let that email slip (or to not receive it for some reason). It takes 30 seconds to look at the status of your request on the DebConf 17 website, and even less to do the few clicks needed for you to accept the grant. Please do so now! OK, it might take a few minutes if your SSO certificate has expired and you have to look up the docs to renew it. The deadline for the first round of travel grants (which went out last week) is June 20th. The deadline for the second round (which went out today) is June 24th. If somehow you can t login to the website before the deadline, the bursaries team has an email address you can use. We want to send out a third round of grants on June 25th, using the money people freed up: our current acceptance ratio is around 40%, and a lot of very strong applications have been deferred. We don t want them to wait up until July to get a definitive answer, so thanks for helping us! bient t Montr al !

Next.

Previous.