Search Results: "xam"

16 November 2014

Dirk Eddelbuettel: Introducing RcppAnnoy

A new package RcppAnnoy is now on CRAN. It wraps the small, fast, and lightweight C++ template header library Annoy written by Erik Bernhardsson for use at Spotify. While Annoy is setup for use by Python, RcppAnnoy offers the exact same functionality from R via Rcpp. A new page for RcppAnnoy provides some more detail, example code and further links. See a recent blog post by Erik for a performance comparison of different approximate nearest neighbours libraries for Python.

This post by Dirk Eddelbuettel originated on his Thinking inside the box blog. Please report excessive re-aggregation in third-party for-profit settings.

15 November 2014

Jo Shields: mono-project.com Linux packages an update

It s been pointed out to me that many people aren t aware of the current status of Linux packages on mono-project.com, so I m here s a summary: Stable packages Mono 3.10.0, MonoDevelop 5.5.0.227, NuGet 2.8.1 and F# 3.1.1.26 packages are available. Plus related bits. MonoDevelop on Linux does not currently include the F# addin (there are a lot of pieces to get in place for this to work). These are built for x86-64 CentOS 7, and should be compatible with RHEL 7, openSUSE 12.3, and derivatives. I haven t set up a SUSE 1-click install file yet, but I ll do it next week if someone reminds me. They are also built for Debian 7 on i386, x86-64, and IBM zSeries processors. The same packages ought to work on Ubuntu 12.04 and above, and any derivatives of Debian or Ubuntu. Due to ABI changes, you need to add a second compatibility extension repository for Ubuntu 12.04 or 12.10 to get anything to work, and a different compatibility extension repository for Debian derivatives with Apache 2.4 if you want the mod-mono ASP.NET Apache module (Debian 8+, Ubuntu 13.10+, and derivatives, will need this).
MonoDevelop 5.5 on Ubuntu 14.04

MonoDevelop 5.5 on Ubuntu 14.04

In general, see the install guide to get these going. Docker You may have seen Microsoft recently posting a guide to using ASP.NET 5 on Docker. Close inspection would show that this Docker image is based on our shiny new Xamarin Mono docker image, which is based on Debian 7.The full details are on Docker Hub, but the short version is docker pull mono:latest gets you an image with the very latest Mono.
directhex@desire:~$ docker pull mono:latest
Pulling repository mono
9da8fc8d2ff5: Download complete 
511136ea3c5a: Download complete 
f10807909bc5: Download complete 
f6fab3b798be: Download complete 
3c43ebb7883b: Download complete 
7a1f8e485667: Download complete 
a342319da8ea: Download complete 
3774d7ea06a6: Download complete 
directhex@desire:~$ docker run -i -t mono:latest mono --version 
Mono JIT compiler version 3.10.0 (tarball Wed Nov  5 12:50:04 UTC 2014)
Copyright (C) 2002-2014 Novell, Inc, Xamarin Inc and Contributors. www.mono-project.com
	TLS:           __thread
	SIGSEGV:       altstack
	Notifications: epoll
	Architecture:  amd64
	Disabled:      none
	Misc:          softdebug 
	LLVM:          supported, not enabled.
	GC:            sgen
The Dockerfiles are on GitHub.

14 November 2014

Richard Hartmann: Release Critical Bug report for Week 46

I know I promised better stats, but meh... Next week :( As you can see, there's been a bit of a mass-filing going on. and that pushed ys above Wheezy's count for week 46. My own personal favourite bug is, of course, this one. The UDD bugs interface currently knows about the following release critical bugs: How do we compare to the Squeeze release cycle?
Week Squeeze Wheezy Diff
43 284 (213+71) 468 (332+136) +184 (+119/+65)
44 261 (201+60) 408 (265+143) +147 (+64/+83)
45 261 (205+56) 425 (291+134) +164 (+86/+78)
46 271 (200+71) 401 (258+143) +130 (+58/+72)
47 283 (209+74) 366 (221+145) +83 (+12/+71)
48 256 (177+79) 378 (230+148) +122 (+53/+69)
49 256 (180+76) 360 (216+155) +104 (+36/+79)
50 204 (148+56) 339 (195+144) +135 (+47/+90)
51 178 (124+54) 323 (190+133) +145 (+66/+79)
52 115 (78+37) 289 (190+99) +174 (+112/+62)
1 93 (60+33) 287 (171+116) +194 (+111/+83)
2 82 (46+36) 271 (162+109) +189 (+116/+73)
3 25 (15+10) 249 (165+84) +224 (+150/+74)
4 14 (8+6) 244 (176+68) +230 (+168/+62)
5 2 (0+2) 224 (132+92) +222 (+132/+90)
6 release! 212 (129+83) +212 (+129/+83)
7 release+1 194 (128+66) +194 (+128/+66)
8 release+2 206 (144+62) +206 (+144/+62)
9 release+3 174 (105+69) +174 (+105/+69)
10 release+4 120 (72+48) +120 (+72/+48)
11 release+5 115 (74+41) +115 (+74/+41)
12 release+6 93 (47+46) +93 (+47/+46)
13 release+7 50 (24+26) +50 (+24/+26)
14 release+8 51 (32+19) +51 (+32/+19)
15 release+9 39 (32+7) +39 (+32/+7)
16 release+10 20 (12+8) +20 (+12/+8)
17 release+11 24 (19+5) +24 (+19/+5)
18 release+12 2 (2+0) +2 (+2/+0)
Graphical overview of bug stats thanks to azhag:

13 November 2014

Tanguy Ortolo: Re: About choice

This is a reply to Josselin Mouette's blog article About choice, since his blog does not seem to accept comments . Please note that this is not meant to be systemd-bashing, just a criticism base one a counter-example refutation of Josselin's implication that there is no use case better covered by SysV init: this is false, as there is at least one. And yes, there are probably many cases better covered by systemd, I am making no claims about that.A use case better covered by SysV init: encrypted block devices So, waiting for a use case better covered by SysV init? Rejoice, you will not die waiting, here is one: encrypted block devices. That case works just fine with SysV init, without any specific configuration, whereas systemd just sucks at it. There exist a way to make it work , but: If you know any better, I would be glad to try it. Believe me, I like the basic principles of systemd and I would be glad to have it working correctly on my system. Notes
  1. Well, it does accept comments, but marks them as span and does not show them, which is roughly equivalent.
  2. Installing an additional piece of software, Plymouth, is supposed to make systemd work correctly with encrypted block devices. Yes, this is additional configuration, as that piece of software does not come when you install systemd, and it is not even suggested so a regular user cannot guess it.
  3. Though I must say I hate the way it is pushed into the GNU/Linux desktop systems.

12 November 2014

Jonathan Wiltshire: A chilly week

It s finally become properly autumnal, in the real world and in Debian. One week ago, I announced (on behalf of the whole release team) that Debian 8 Jessie had successfully frozen on time. At 18:00 that evening we had 310 release critical bugs that is, the number that we must reduce to 0 before the release is ready. How does that number look now? Well, there are now 315 bugs affecting Jessie, at various stages of progression. That sounds like it s going in the wrong direction, but considering that over a hundred new bugs were filed just 8 hours after the freeze announcement, things are actually looking pretty good. Out of those 315 bugs, 91 have been fixed and the packages affected have already been unblocked by the release team. The fixed packages will migrate to Jessie in the next few days, if they continue to be bug-free. Thirty-four bugs are apparently fixed in unstable but are not cleared for migration yet. That means that the release team has not spotted the fix, or nobody has told us, or the fixed package is unsuitable for some other reason (like unrelated changes in the same upload). You can help by trying to find out which reason applies, and talking to us about it. Most likely nobody has asked us to unblock it yet. Speaking of unblocks, we currently have twenty-four requests that need to be looked at, and a further 20 which are awaiting more information from the maintainer. We already investigated and resolved 260 requests. Our response rate is currently pretty good, but it s unclear whether we can sustain it indefinitely. We all have day jobs, for example. One way you could help is to review the list of unchecked unblocks and gather up missing information, or look at the ones tagged moreinfo and see whether that s still the case (maybe the maintainer replied, but forgot to remove the tag). If you re confident, you might even try triaging some of the obvious requests and give some feedback to the maintainer, though the final decision will be made by a release team member. After all, the quicker this goes the sooner we can release and thaw up unstable again.
Footnote: the method used to determine RC bug counts last week and this week differ, and therefore so could the margin for error. Surprisingly enough, counting bugs is not an exact science. I m confident these numbers are close enough for broad comparison, even if they re out by one or two.
A chilly week is a post from: jwiltshire.org.uk Flattr

11 November 2014

Simon Josefsson: Dice Random Numbers

Generating data with entropy, or random number generation (RNG), is a well-known difficult problem. Many crypto algorithms and protocols assumes random data is available. There are many implementations out there, including /dev/random in the BSD and Linux kernels and API calls in crypto libraries such as GnuTLS or OpenSSL. How they work can be understood by reading the source code. The quality of the data depends on actual hardware and what entropy sources were available the RNG implementation itself is deterministic, it merely convert data with supposed entropy from a set of data sources and then generate an output stream. In some situations, like on virtualized environments or on small embedded systems, it is hard to find sources of sufficient quantity. Rarely are there any lower-bound estimates on how much entropy there is in the data you get. You can improve the RNG issue by using a separate hardware RNG, but there is deployment complexity in that, and from a theoretical point of view, the problem of trusting that you get good random data merely moved from one system to another. (There is more to say about hardware RNGs, I ll save that for another day.) For some purposes, the available solutions does not inspire enough confidence in me because of the high complexity. Complexity is often the enemy of security. In crypto discussions I have said, only half-jokingly, that about the only RNG process that I would trust is one that I can explain in simple words and implement myself with the help of pen and paper. Normally I use the example of rolling a normal six-sided dice (a D6) several times. I have been thinking about this process in more detail lately, and felt it was time to write it down, regardless of how silly it may seem. A dice with six sides produces a random number between 1 and 6. It is relatively straight forward to intuitively convinced yourself that it is not clearly biased: inspect that it looks symmetric and do some trial rolls. By repeatedly rolling the dice, you can generate how much data you need, time permitting. I do not understand enough thermodynamics physics to know how to estimate the amount of entropy of a physical process, so I need to resort to intuitive arguments. It would be easy to just assume that a dice produces 3 bits of entropy, because 2^3=6 which matches the number of possible outcomes. At least I find it easy to convince myself that 3 bits is the upper bound. I suspect that most dice have some form of defect, though, which leads to a very small bias that could be found with a large number of rolls. Thus I would propose that the amount of entropy of most D6 s are slightly below 3 bits on average. Further, to establish a lower bound, and intuitively, it seems easy to believe that if the entropy of particular D6 would be closer to 2 bits than to 3 bits, this would be noticeable fairly quickly by trial rolls. That assumes the dice does not have complex logic and machinery in it that would hide the patterns. With the tinfoil hat on, consider a dice with a power source and mechanics in it that allowed it to decide which number it would land on: it could generate seamingly-looking random pattern that still contained 0 bits of entropy. For example, suppose a D6 is built to produce the pattern 4, 1, 4, 2, 1, 3, 5, 6, 2, 3, 1, 3, 6, 3, 5, 6, 4, this would mean it produces 0 bits of entropy (compare the numbers with the decimals of sqrt(2)). Other factors may also influence the amount of entropy in the output, consider if you roll the dice by just dropping straight down from 1cm/1inch above the table. With this discussion as background, and for simplicity, going forward, I will assume that my D6 produces 3 bits of entropy on every roll. We need to figure out how many times we need to roll it. I usually find myself needing a 128-bit random number (16 bytes). Crypto algorithms and protocols typically use power-of-2 data sizes. 64 bits of entropy results in brute-force attacks requiring about 2^64 tests, and for many operations, this is feasible with today s computing power. Performing 2^128 operations does not seem possible with today s technology. To produce 128 bits of entropy using a D6 that produces 3 bits of entropy per roll, you need to perform ceil(128/3)=43 rolls. We also need to design an algorithm to convert the D6 output into the resulting 128-bit random number. While it would be nice from a theoretical point of view to let each and every bit of the D6 output influence each and every bit of the 128-bit random number, this becomes difficult to do with pen and paper. For simplicity, my process will be to write the binary representation of the D6 output on paper in 3-bit chunks and then read it up as 8-bit chunks. After 8 rolls, there are 24 bits available, which can be read up as 3 distinct 8-bit numbers. So let s do this for the D6 outputs of 3, 6, 1, 1, 2, 5, 4, 1:
3   6   1   1   2   5   4   1
011 111 001 001 010 101 010 001
01111100 10010101 01010001
124 0x7C 149 0x95 81 0x51
After 8 rolls, we have generated the 3 byte hex string 7C9551 . I repeat the process 5 more times, concatenating the strings, resulting in a hex string with 15 bytes of data. To get the last byte, I only need to roll the D6 three more times, where the two high bits of the last roll is used and the lowest bit is discarded. Let s say the last D6 outputs were 4, 2, 3, this would result in:
4   2   3
100 010 011
10001001
137 0x89
So the 16 bytes of random data is 7C9551..89 with .. replaced by the 5 pieces of 3-byte chunks of data. So what s the next step? Depends on what you want to use the random data for. For some purposes, such as generating a high-quality 128-bit AES key, I would be done. The key is right there. To generate a high-quality ECC private key, you need to generate somewhat more randomness (matching the ECC curve size) and do a couple of EC operations. To generate a high-quality RSA private key, unfortunately you will need much more randomness, at the point where it makes more sense to implement a PRNG seeded with a strong 128-bit seed generated using this process. The latter approach is the general solution: generate 128 bits of data using the dice approach, and then seed a CSPRNG of your choice to get large number of data quickly. These steps are somewhat technical, and you lose the pen-and-paper properties, but code to implement these parts are easier to verify compared to verifying that you get good quality entropy out of your RNG implementation. flattr this!

10 November 2014

Gustavo Noronha Silva: Yay, the left won! Or did it?

Originally published on politi.kov I have been asked by a bunch of friends from outside of Brazil for my opinion regarding the recent elections we had in Brazil, and it is a bit complicated to explain it without some background, so I decided to write this piece providing a bit of history so that people can understand my opinion. The elections this year were a rematch of our traditional polarization between the workers party (PT) and the social democracy party (PSDB), which has been going on since 1994. PT and PSDB used to be allies. In the 80s, when the dictatorship dropped the law that forbade more than 2 parties, the opposition party, MDB, began breaking up in several smaller ones. PSDB was founded by politicians and intelectuals who were inspired by Europe s social democracy and political systems. Parliamentarism, for instance, is one of the historical causes of the party. The workers party had a more grassroots origin, with union leaders, marxist intelectuals and marxist-inspired catholic priests being the main founders. They drew their inspiration from the USSR and Cuba, and were very close to social movements.
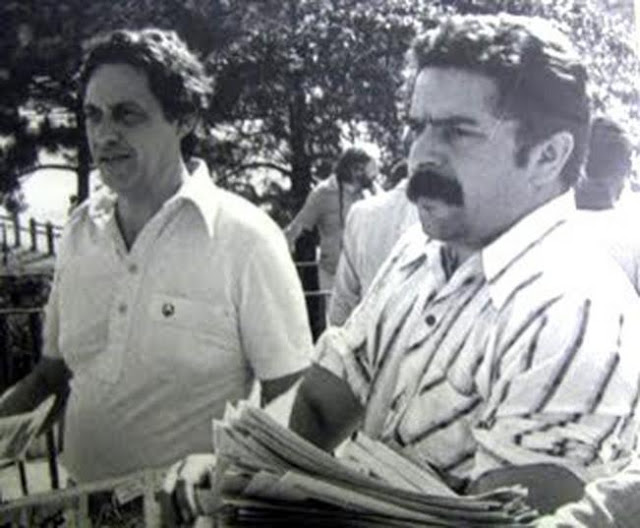
Lula and FHC campaigning together in 1981, by Cl vis Cranchi Sobrinho

Lula (PT) and FHC (PSDB) campaigning together in 1981, by Cl vis Cranchi Sobrinho

Some people have celebrated the reelection of Dilma Roussef as a victory of the left against the right. In my opinion that view is wrong for several reasons. First, because I disagree that PSDB and A cio Neves in particular are right-wing, both in terms of economics and social/moral issues. Second, because I believe Dilma s first government has taken a quite severe turn to the right in several topics that matter a lot to me. Since comparisons with PSDB s government during the 90s has been one of the main strategies of the campaign this year, I ll argue why I think it was actually a pretty good government with a lot of left in it. Unlike what happens in most other places, Brazil does not really have an actual right-wing party, economics-wise. Although we might see the birth of a couple in the near future, no current party is really against public health, education and social security being provided by the state as rights, or wants to decrease state size and lower taxes significantly. It should come as no surprise that even though it has undergone a lot of liberal reforms over the last 20 years, Brazil is still a very closed country, with very high import tariffs and a huge presence of the state in the economy. There is a certain consensus about all of that, with disagreements being essentially on implementation details, not goals. On the other hand, and contrary to popular belief, when it comes to social and moral issues we are a very conservative people. Ironically, the two parties which have been in power over the last 20 years are quite progressive, being historically proponents of diversity, minorities rights, reproductive rights. They have had to compromise on those causes to become viable alternatives, given the conservative nature of the majority of the voters. Despite their different origins and beliefs, both parties share socialist inclinations and were allies from the onset. That changed in 1992, when president Collor, who had been elected on a runoff against Lula (who PSDB supported), was impeached by Congress for corruption. With no formal political support and a chaotic situation in his hands, Itamar Franco, the vice president, called for a national union government to go through the last two years of his term. PSDB answered the call, but the workers party decided against being part of the government. Fernando Henrique Cardoso, a sociologist who was one of the leaders of PSDB was chosen to lead the Foreign Relations Ministry, but a few months later got nominated to the Economy. At the time, Brazil lived under hyperinflation of close to 1000% a year, and several stabilization plans had been attempted. Economy Ministers did not last very much in office at the time. FHC gathered a team of economists and sponsored their stabilization plan, which turned out to be highly successful: the Plano Real ( Real Plan ). In addition to introducing a new currency, something that was becoming pretty common to Brazilians by then, it also attacked the structural causes of inflation. Lula was counting on the failure of the Plano Real when he ran against FHC in 1994, but the plan succeeded, giving FHC two terms as president. During those two terms, FHC introduced several institutional changes that made Brazil a saner country. In addition to the hyperinflation, Brazil had lived a debt crises for decades and was still in default. FHC s team renegotiated the debts, reopened lines of credit, but most importantly, introduced reforms that made the Brazilian finances and financial system credible. The problem was not even that Brazil had a fiscal d ficit, it just did not have any control whatsoever of money supply and budget. Banks, regardless of whether they were private or public, had very little regulation and took advantage of the hyperinflation to hide monstrous holes in their balances. When inflation was gone and regulation became more strict, those became apparent, and it was pretty clear that the system would collapse if nothing was done. Some people like to say that FHC was a president who ruled for the rich and didn t care about the poor. I think the way the potential collapse of the banking system was handled is a great counter-example of that. The government passed laws that made the owners of the banks responsible for the financial problems, regardless of whether caused by mismanagement or fraud. If a bank went under, the central bank intervened and added enough money to protect the deposits, but that money was a loan that had to be repaid by the owners of the bank, and the owners properties were added as collateral to the loan. As a brazilian journalist once said, the people did not risk losing their deposits, the bankers did risk losing the banks, though. Today, we have a separate fund, filled with money from the banks, that does what the central bank did back then when required. Compare that to countries where the banking system was saved with tax payer money and executives kept getting huge bonuses regardless, while owners kept their profits. It is hard to find an initiative that is more focused on the public interest against the interest of the rich people who caused the problem. This legislation, called PROER, is still in place today, and it came along with solid regulation of the banking system. It should come as no surprise that Brazil went through the financial crisis of 2008 with not a single hiccup of the banking system and no fear of bank runs. Despite having been against PROER back in the day, Lula celebrated its existence in 2008, when it was clear it was one of the reasons we would not suffer much. He even advertised it as something that should be adopted by the US and Europe. It is also pretty common to hear that under FHC social questions were not a priority. I believe it is pretty simple to see that that was not the case both by inspecting the growth of social spending and the improvement of social indicators for the period, such as UN s human development index. One area in which people are particularly critical of the FHC government is the investment on higher education, and they are actually quite right. Brazil has free Federal universities and those did not get a lot of priority in the 90s. However, I would argue that while it is a matter of priorities, it is not one of education versus something else, but rather of what to invest on inside education. The reality is basic education was the priority. When FHC came to power, Brazil had a significant number of children who were not going to school at all. The goal was to make access to schools universal for young children, and that goal was reached. Every child has been going to school since the early 2000s, and that is a significant achievement which reaches the poorest. While the federal universities are attended essentially by the Brazilian elite, given the difficulty of passing the exams and the relative lack of quality of free public schools compared to private ones, which is still a reality to this day, investment on getting children to even go to school for the early years has a significant impact on the lives of the poorest. It is important to remember that getting every child to go to school is also what gave birth to one of the most celebrated programs from the Lula era: Bolsa Fam lia ( Family Allowance ) is a direct money transfer to poor families, particularly those who have children and has been an important contribution to lowering inequality and getting people out of extreme poverty. To get the money, the families need to ensure their children are 1) attending school and 2) getting vaccinated. That program comes from the FHC government, in which it was created with the name Bolsa Escola ( School Allowance ), in its turn inspired by a program of the same name by governor Cristovam Buarque, from PT. What Lula did, and he deserves a lot of credit for this, was to merge a series of smaller programs with Bolsa Escola, and then expand the program to ensure it got to more and more people. Interestingly, during the announcement of the program he credited the idea of doing that to a state governor from PSDB. You can see why I think these two should be allies again. When faced with all these arguments, people will eventually say that FHC was bad because he privatized companies and used orthodox economic policies. Well, if that is what it takes, then we ll have to take Lula down with him, because his first term was essentially a continuation of FHC s second term: orthodox economic policies to keep inflation down, along with privatization of several state-owned companies and banks. But Lula, whom I voted for and whose government I believe was a good one, is not my subject: Dilma is. On Lula s second term, Dilma gained a lot of power when other major leaders of PT went down for corruption. She became second in command and started leading several programs. A big believer in developmentalism, she started pushing for a bigger role of the state in the coordination of the productive sector, with a clear focus on growing the industrial base. One of the initiatives she sponsored was a sizable increase on the number and size of subsidized loans given out by the national development bank (BNDES). Brazil started an unnofficial national champions program, where the government elected a few big companies to get a huge amount of subsidized credit. The goal was for these selected firms to get big enough to be competitive on the global market. The criteria for the choices is completely opaque, if it even exists, and includes handing out milions in subsidized credit for Eike Batista, who became Brazil s richest enterpreneur for a while, and lost pretty much everything when it became clear the oil would not be pumping out of his camps after all, sinking with them a huge amount of public funds invested by BNDES. The way this policy was enacted, it is unclear how much it really costs in terms of public funds: the Brazilian treasury emits debt to capitalize, lends that money to BNDES with higher than market interest, and BNDES then lends it out to the big companies with a lower than market interest rate. Although it is obviously unsustainable, the problem does not yet show in the balance because the grace period for BNDES debt with the treasury is 2040. The fact that this has a cost and, perhaps more importantly, a huge opportunity cost is not clear because it is not part of the government budget. Why are we putting money in this rather than quadrupling Bolsa Fam lia, which studies show generates 1,78 reais in GDP for every 1 real invested? Worse, why are we not even updating Bolsa Fam lia enough to cover inflation? When Dilma got elected in 2010, the first signs were pretty bad. She was already seen as someone who did not care much for the environment, and on her first month in power she made good on that promise by pushing to get the Belo Monte Dam building started as soon as possible regardless of conditionalities being satisfied. To this day there are several issues with how the building of the dam is going: the handling of the indigenous people and the small city nearby are lacking, conditionalities are not met. Beyond Belo Monte, indigenous leaders are being assassinated, deforestation in the Amazon forest has increased by 122% in 2014 alone. Dilma s answer to people who question her on these kinds of issues is essentially: would you rather not have electric power? Her populist authoritarian nature and obsession with industry are also pretty evident when it comes to her policies in the energy area as a whole. She showed up in national tv on the eve of our independence day celebration to announce a reduction in electric tariffs, mainly for industry, but also for homes. Nobody really knew how. The following week she sent a fast-track project to Congress to automatically renew concessions of power grid operators, requiring those who accepted it to lower tariffs, instead of doing an auction, which was already necessary anyway because the concessions were up on 2015. There was no discussion with stakeholders, there was just a populist announcement and a great deal of rhethoric to paint anyone who opposed as being against the people. And now, everything went into the crapper because that represented a breach of contract that required indemnification, and we had a pretty bad drought that made power more expensive given the need to turn on the thermal generators. Combining the costs of the thermal generation, indemnity, and financial fallout that the grid operators suffered, we are already at 105 billion reais and counting, nobody knows how high the cost will reach. Any reduction in tariffs has long been invalidated. And the fact that industry has lowered production significantly ends up being good news, we would probably be under rationing already if that was not the case. You would expect someone who fought a dictatorship to be pretty good in terms of human and civil rights. What we see in reality is a lack of respect for those things. During the world cup, Dilma has put the army on the streets and has supported arbitrary behaviour from state polices throughout the country. They jailed a bunch of demonstrators preemptively. No shit. The would be demonstrators were kept in jail throghout the tournament under false accusations. Dilma s Minister of Justice said several times that the case against them was solid and that the arrests were legal, but it turned out the case simply did not exist. Just this week we had a number of executions orchestrated by policemen in the state of Par and there is zero reaction from the federal government. In the oil industry, Dilma has enacted a policy of subsidizing gas prices by using a fixed price that used to be lower than the international prices (it is no longer the case with the fall in international prices). That would not be a problem if Brazil was selfsufficient in oild and gas, which we are not: we had to import a significant amount of both. The implicit subsidy cost Petrobr s a huge amount of cash the more gas it sold, the bigger the losses. This lead not only to decreasing the company s market value (it is a state-controlled, but open company), but to reducing its capacity of investment as well. That is more problematic than it sounds because, with our current concession model, every single oil camp needs to have Petrobr s as a member of the consortium. Limiting the company s investment capacity limits the rate at which our pre-salt oil camps can be explored and thus the speed at which we can become selfsufficient. Chicken and egg anyone? To make things worse, Dilma has made policies that lowered taxes on car production, used to foster economic activity during the crisis in 2008-2010, essentially permanent. This lead to a significant increase in traffic and polution on Brazilian cities, while at the same time increasing the pressure on Petrobr s, which had to import more and more gas. Meanwhile, Brazilian cities suffer from a severe lack of mobility infrastructure. A recent study has shown that Brazil has spend almost twice as much subsidized money on pro-car policies than on pro-mass transit projects. Talk about good usage of public funds. One of the only remaining good news the government was still able to mention was the constant reduction in extreme poverty. Dilma was actually ellected promising to erradicate extreme poverty and changed the government s slogan to A rich country is a country with no poverty (Pa s rico pa s sem pobreza). Well, it turns out all of these policies caused inequality and extreme poverty both to stop falling as of 2013. And given the policies were actually deepened in 2014, I believe it is very likely we ll see an increase in both when we get the data for 2014, next year. Other than that, her policies ended up being a complete failure. Despite giving tax benefits to several sectors, investment has fallen, growth has fallen and inflation is quite high at 6,6% for the last 12 months. In terms of minorities, her government has been a severe set back, with the government going back on educational material against homophoby saying it would not do advertisement of sexual choice , and going back on a decree that allowed the public health system to perform abortions on the cases allowed by the law (essentially if the woman has been raped). Looking at Dilma s policies, I really can t see that much of the left, honestly. So why, you might ask, has this victory been deemed a victory of the left over the right? My explanation is the aura the workers party still manages to keep over itself. There s a notion that whatever PT does, it will still be more to the left than PSDB, which I think is just crazy. There is also a fair amount of idealizing Dilma just because she is Lula s proteg . People will forgive anything, provided it is the workers party doing it. Thankfully, the number of people aligned on the left that supported the candidate from PSDB this election tells me this is changing quite rapidly. Hopefully that leads to PT having to reinvent itself, and get in touch with the left again.

Matthias Klumpp: Introducing Limba a software installer experiment

As some of you already know, since the larger restructuring in PackageKit for the 1.0 release, I am rethinking Listaller, the 3rd-party application installer for Linux systems, as well. During the past weeks, I was playing around with a lot of different ideas and code, to make installations of 3rd-party software easily possible on Linux, but also working together with the distribution package manager. I now have come up with an experimental project, which might achieve this. Motivation Many of you know Lennart s famous blogpost on how we put together Linux distributions. And he makes a lot of good and valid points there (in fact, I agree with his reasoning there). The proposed solution, however, is not something which I am very excited about, at least not for the use-case of installing a simple application[1]. Leaving things like the exclusive dependency on technology like Btrfs aside, the solution outlined by Lennart basically bypasses the distribution itself, instead of working together with it. This results in a duplication of installed libraries, making it harder to overview which versions of which software component are actually running on the system. There is also a risk for security holes due to libraries not being updated. The security issues are worked around by a superior sandbox, which still needs to be implemented (but will definitively come soon, maybe next year). I wanted to explore a different approach of managing 3rd-party applications on Linux systems, which allows sharing as much code as possible between applications. Limba Glick2 and Listaller concepts mergedlimba-small In order to allow easy creation of software packages, as well as the ability to share software between different 3rd-party applications, I took heavy inspiration from Alexander Larssons Glick2 project, combining it with ideas from the application-directory based Listaller. The result is Limba (named after Limba tree, not the voodoo spirit I needed some name starting with li to keep the prefix used in Listaller, and for a tool like this the name didn t really matter ;-) ). Limba uses OverlayFS to combine an application with its dependencies before running it, as well as mount namespaces and shared subtrees. Except for OverlayFS, which just landed in the kernel recently, all other kernel features needed by Limba are available for years now (and many distributions ship with OverlayFS on older kernels as well). How does it work? In order to to achieve separation of software, each software component is located in a separate container (= package). A software component can be an application, like Kate or GEdit, but also be a single shared library (openssl) or even a full runtime (KDE Frameworks 5 parts, GNOME 3). Each of these software components can be identified via AppStream metadata, which is just a few bits of XML. A Limba package can declare a dependency on any other software component. In case that software is available in the distribution s repositories, the version found there can be used. Otherwise, another Limba package providing the software is required. Limba packages can be provided from software repositories (e.g. provided by the distributor), or be nested in other packages. For example, imagine the software Kate requires a version of the Qt5 libraries, >= 5.2. The downloadable package for Kate can be bundled with that dependency, by including the Qt5 5.2 Limba package in the Kate package. In case another software is installed later, which also requires the same version of Qt, the already installed version will be used. Since the software components are located in separate directories under /opt/software, an application will not automatically find its dependencies, or be able to locate its own files. Therefore, each application has to be run by a special tool, which merges the directory trees of the main application and it s dependencies together using OverlayFS. This has the nice sideeffect that the main application could override files from its dependencies, if necessary. The tool also sets up a new mount namespace, so if the application is compiled with a certain prefix, it does not need to be relocatable to find its data files. At installation time, to achieve better system integration, certain files (like e.g. the .desktop file) are split out of the installed directory tree, so the newly installed application achieves almost full system integration. AQNAY* Can I use Limba now? Limba is an experiment. I like it very much, but it might happen that I find some issues with it and kill it off again. So, if you feel adventurous, you can compile the source code and use the example Foobar application to play around with Limba. Before it can be used in production (if at all), some more time is needed. I will publish documentation on how to test the project soon. Doesn t OverlayFS have a maximum stacking depth? Oh yes it has! The How does it work explanation doesn t tell the whole truth in that regard (mainly to keep the section small). In fact, Limba will generate a runtime for the newly installed software, which is a directory with links to the actual individual software components the runtime consists of. The runtime is identified by an UUID. This runtime is then mounted together with the respective applications using OverlayFS. This works pretty great, and also results in no dependency-resolution to be done immediately before an application is started. Than dependency stuff gives me a headache Admittedly, allowing dependencies adds a whole lot of complexity. Other approaches, like the one outlined by Lennart work around that (and there are good reasons for doing that as well). In my opinion, the dependency-sharing and de-duplication of software components, as well as the ability to use the components which are packaged by your Linux distribution is worth the extra effort. Can you give an overview of future plans for Limba? Sure, so here is the stuff which currently works: These features are planned for the new future: Remember that Limba is an experiment, still ;-) XKCD 927 Technically, I am replacing one solution with another one here, so the situation does not change at all ;-). But indeed, some duplicate work is done due to more people working in this area now on similar questions. But I think this is a good thing, because the solutions worked on are fundamentally different approaches, and by exploring multiple ways of doing things, we will come up with something great in the end. (XKCD reference) Doesn t the use of OverlayFS have an impact on the performance of software running with Limba? I ran some synthetic benchmarks and didn t notice any problems even the startup speed of Limba applications is only a few milliseconds slower than the startup of the raw native application. However, I will still have to run further tests to give a definitive answer on this. How do you solve ABI compatibility issues? This approach requires software to keep their ABI stable. But since software can have strict dependencies on a specific version of a software (although I d discourage that), even people who are worried about this issue can be happy. We are getting much better at tracking unwanted ABI breaks, and larger projects offer stable API/ABI during a major release cycle. For smaller dependencies, there are, as explained above, stricter dependencies. In summary, I don t think ABI incompatibilities will be a problem with this approach at least not more than they have been in general. (The libuild facilities from Listaller to minimize dependencies will still be present im Limba, of course) You are wrong because of $X! Please leave a comment in this case! I d love to discuss new ideas and find the limits of the Limba concept that s why I am writing C code afterall, since what looks great on paper might not work in reality or have issues one hasn t thought about before. So any input is welcomed! Conclusion Last but not least I want to thank Alexander Larsson for writing Glick2, which Limba is heavily inspired from, and for his patient replies to my emails. If Limba turns out to be a good idea, you can expect a few more blog posts about it soon.
* Answered questions nobody asked yet [1]: Don t get me wrong, I would like to have these ideas implemented they offer great value. But I think for simple software deployment, the solution is an overkill.

9 November 2014

Erich Schubert: GR vote on init coupling

Overregulation is bad, and the project is suffering from the recent Anti-Systemd hate campaigning.
There is nothing balanced about the original GR proposal. It is bullshit from a policy point of view (it means we must remove software from Debian that would not work with other inits, such as gnome-journal, by policy).At the same time, it uses manipulative language like "freedom to select a different init system" (as if this would otherwise be impossible) and "accidentally locked in". It is exactly this type of language and behavior which has made Debian quite poisonous the last months.
In fact, the GR pretty much says "I don't trust my fellow maintainers to do the right thing, therefore I want a new hammer to force my opinion on them". This is unacceptable in my opinion, and the GR will only demotivate contributors. Every Debian developer (I'm not talking about systemd upstream, but about Debian developers!) I've met would accept a patch that adds support for sysvinit to a package that currently doesn't. The proposed GR will not improve sysvinit support. It is a hammer to kick out software where upstream doesn't want to support sysvinit, but it won't magically add sysvinit support anywhere.
What some supporters of the GR may not have realized - it may as well backfire on them. Some packages that don't yet work with systemd would violate policy then, too... - in my opinion, it is much better to make the support on a "as good as possible, given available upstream support and patches" basis, instead of a "must" basis. The lock-in may come even faster if we make init system support mandatory: it may be more viable to drop software to satisfy the GR than to add support for other inits - and since systemd is the current default, software that doesn't support systemd are good candidates to be dropped, aren't they? (Note that I do prefer to keep them, and have a policy that allows keeping them ...)
For these reasons I voted:
  1. Choice 4: GR not required
  2. Choice 3: Let maintainers do their work
  3. Choice 2: Recommended, but not mandatory
  4. Choice 5: No decision
  5. Choice 1: Ban packages that don't work with every init system
Fact is that Debian maintainers have always been trying hard to allow people to choose their favorite software. Until you give me an example where the Debian maintainer (not upstream) has refused to include sysvinit support, I will continue to trust my fellow DDs. I've been considering to place Choice 2 below "further discussion", but essentially this is a no-op GR anyway - in my opinion "should support other init systems" is present in default Debian policy already anyway...
Say no to the haters.
And no, I'm not being unfair. One of the most verbose haters going by various pseudonyms such as Gregory Smith (on Linux Kernel Mailing list), Brad Townshend (LKML) and John Garret (LKML) has come forward with his original alias - it is indeed MikeeUSA, a notorious anti-feminist troll (see his various youtube "songs", some of them include this pseudonym). It's easy to verify yourself.
He has not contributed anything to the open source community. His songs and "games" are not worth looking at, and I'm not aware of any project that has accepted any of his "contributions". Yet, he uses several sock puppets to spread his hate.
The anti-systemd "crowd" (if it acually is more than a few notorious trolls) has lost all its credibility in my opinion. They spread false information, use false names, and focus on hate instead of improving source code. And worse, they tolerate such trolling in their ranks.

Charles Plessy: Did we need a general resolution?

In 2009 I called for a general resolution regarding membership procedures in Debian, to block a change that, in my opinion, was going against our values. Results, even if they satisfied the majority came with a bitter feeling and it became questioned whether a better solution could have been reached without using a constraining procedure. I did not think so, but not to the point of not having doubts about it, and therefore, regrets. This year, we are again having a vote related to a change that some people think it goes against our values, and again the existence of this vote makes it hard to find compromises. Bitterness will win whatever the result is. For the avoidance of doubt, I have proposed the amendment number 3, stating that this general resolution should not have been started. I hope that this amendment will defeat the original proposition and will make people think twice before pressing Debian's alarm button next time. PS: amendment 3, that is amendment C, that is choice 4. If there was a need for an example that the procedure is complex, here it is...

Steve Kemp: How could you rationally fork Debian?

The topic of Debian forks has come up a lot recently, and as time goes on I've actually started considering the matter seriously: How would you fork Debian? The biggest stumbling block is that the Debian distribution contains thousands of packages, which are maintained by thousands of developers. A small team has virtually no hope of keeping up to date, importing changes, dealing with bug-reports, etc. Instead you have to pick your battle and decide what you care about. This is why Ubuntu split things into "main" and "universe". Because this way they didn't have to deal with bug reports - instead they could just say "Try again in six months. Stuff from that repository isn't supported. Sorry!" So if you were going to split the Debian project into "supported" and "unsupported" what would you use as the dividing line? I think the only sensible approach would be : On that basis you'd immediately drop the support burden of GNOME, KDE, Firefox, Xine, etc. All the big, complex, and user-friendly stuff would just get thrown away. What you'd end up with would be a Debian-Server fork, or derivative. Things you'd package and care about would include: Would that be a useful split? I suspect it would. It would also be manageable by a reasonably small team. That split would also mean if you were keen on dropping any particular init-system you'd not have an unduly difficult job - your server wouldn't be running GNOME, for example. Of course if you're thinking of integrating a kernel and server-only stuff then you might instead prefer a BSD-based distribution. But if you did that you'd miss out on Docker. Hrm.

8 November 2014

Gunnar Wolf: Collective pain

The following text is not mine. I'm copy-translating a text a dear friend of mine just wrote in Spanish, in Facebook. He writes far better than I do (much better than most people I have known). I am not also a great translator. If you can read Spanish, go read the original.
I hate my country. I want to get the hell out of here. This country stinks. Phrases that appear in talks between Mexicans since yesterday. On the network and outside of it. And to tell the truth, I would have put them between quotation marks if I had not thought them as well. At some point. Because that is the edtent of the pain. Enuogh to hate, to insult, to give up. But we talk and write without realizing that it might be the most terrible thing in all this mess. That the pain makes us give up and consent to play a role in the game that they, the executioners, would pleasedly look at from their tribunes, laughing at us while they hand each other the popcorn. That would be over the line. So lets not give them that joy. Because they surely don't realize we have the obligation to notice it from the very beginning and do something to avoid falling there: The root of the pain they caused us yesterday is because that's how the annihilation of hope feels like. The shout "Alive they were taken" they do not realize but we do is a shout of hope. A pronouncement for the possible goodness in the human being. A testimony of hope in the future. A bet for life. And with his cold address, the federal attorney yesterday wanted to finish the killing of our already aching hope. We cannot grant him that joy. They say it's the last thing that dies. I'd say it's the only thing that should not die. Ever. It finishes and everything finishes. There is no possible justice for the parents of the 43. Much less for the 43. Not even however much the official discourse wants to gets us dizzy with the propaganda saying "we will not rest until". Not even if the president quits that would bring back to their classrooms even one of those that by today are just ashes. And sadly, that's the excuse that man wields to not stop boarding his plane and travel wherever he pleases. The farthest from Mexico, the better. Lets not do the same. Lets remind the world this country is full of us, not of them. That the face of a persn is not the dirtyness on his forehead and cheeks, but the skin that's below, that feels and throbs. Lets show the world Mexico is more the verse than the blood, more the idea than the terror. And to them... Lets not give them the joy. To them, lets make them see that, however hard they try, there are things they will never take from us. Our love for this country, for example. The country, over all things.
- Antonio Malpica. After what appears to be the bitter and sadly expected end of a sad, terrible, unbelievable collective social rupture we have lived for ~50 days. And what comes next? How can it come? How can we expect it? I have no way to answer. We, the country's people, are broken.

Steve Kemp: Some brief notes on Docker

Docker is the well-known tool for building, distributing, and launching containers. I use it personally to run a chat-server, a graphite instance, and I distribute some of my applications with Dockerfiles too, to ease deployment. Here are some brief notes on things that might not be obvious. For a start when you create a container it is identified by a 64-byte ID. This ID is truncated and used as the hostname of the new guest - but if you ever care you can discover the full ID from within the guest:
~# awk -F/ ' print $NF ' /proc/self/cgroup
9d16624a313bf5bb9eb36f4490b5c2b7dff4f442c055e99b8c302edd1bf26036
Compare that with the hostname:
~# hostname
9d16624a313b
Assigning names to containers is useful, for example:
$ docker run -d -p 2222:22 --name=sshd skxskx/sshd
However note that names must be removed before they can be reused:
#!/bin/sh
# launch my ssh-container - removing the name first
docker rm  sshd   true
docker run --name=sshd -d -p 2222:22 skxskx/sshd
The obvious next step is to get the IP of the new container, and setup a hostname for it sshd.docker. Getting the IP is easy, via either the name of the ID:
~$ docker inspect --format '  .NetworkSettings.IPAddress  ' sshd
172.17.0.2
The only missing step is the ability to do that magically. You'd hope there would be a hook that you could run when a container has started - unfortunately there is no such thing. Instead you have two choices: I wrote a simple watcher to fire when events are created, which lets me do the job. But running a deamon just to watch for events seems like the wrong way to go. Instead I've switched to running via a wrapper dock-run:
$ dock-run --name=sshd -d -p 2222:22 skxskx/sshd
This invokes run-parts on the creation directory, if present, and that allows me to update DNS. So "sshd.docker.local" will point to the IP of the new image. The wrapper was two minutes work, but it does work, and if you like you can find it here. That concludes my notes on docker - although you can read articles I wrote on docker elsewhere.

7 November 2014

Richard Hartmann: Release Critical Bug report for Week 45

WE ARE FROZEN! Please note that Lucas hacked a "key packages" count into this list. If you have spare cycles, look at those first. I hope to have a (somewhat) random bug of the week thingie by next week which picks stalled bugs for increased exposure. As you can see, we are a bit worse than in the Squeeze cycle, but way ahead of Wheezy. Stats with proper diffs will also start next week. The UDD bugs interface currently knows about the following release critical bugs: How do we compare to the Squeeze release cycle?
Week Squeeze Wheezy Diff
43 284 (213+71) 468 (332+136) +184 (+119/+65)
44 261 (201+60) 408 (265+143) +147 (+64/+83)
45 261 (205+56) 425 (291+134) +164 (+86/+78)
46 271 (200+71) 401 (258+143) +130 (+58/+72)
47 283 (209+74) 366 (221+145) +83 (+12/+71)
48 256 (177+79) 378 (230+148) +122 (+53/+69)
49 256 (180+76) 360 (216+155) +104 (+36/+79)
50 204 (148+56) 339 (195+144) +135 (+47/+90)
51 178 (124+54) 323 (190+133) +145 (+66/+79)
52 115 (78+37) 289 (190+99) +174 (+112/+62)
1 93 (60+33) 287 (171+116) +194 (+111/+83)
2 82 (46+36) 271 (162+109) +189 (+116/+73)
3 25 (15+10) 249 (165+84) +224 (+150/+74)
4 14 (8+6) 244 (176+68) +230 (+168/+62)
5 2 (0+2) 224 (132+92) +222 (+132/+90)
6 release! 212 (129+83) +212 (+129/+83)
7 release+1 194 (128+66) +194 (+128/+66)
8 release+2 206 (144+62) +206 (+144/+62)
9 release+3 174 (105+69) +174 (+105/+69)
10 release+4 120 (72+48) +120 (+72/+48)
11 release+5 115 (74+41) +115 (+74/+41)
12 release+6 93 (47+46) +93 (+47/+46)
13 release+7 50 (24+26) +50 (+24/+26)
14 release+8 51 (32+19) +51 (+32/+19)
15 release+9 39 (32+7) +39 (+32/+7)
16 release+10 20 (12+8) +20 (+12/+8)
17 release+11 24 (19+5) +24 (+19/+5)
18 release+12 2 (2+0) +2 (+2/+0)
Graphical overview of bug stats thanks to azhag:

Riku Voipio: Adventures in setting up local lava service

Linaro uses LAVA as a tool to test variety of devices. So far I had not installed it myself, mostly due to assuming it to be enermously complex to set up. But thanks to Neil Williams work on packaging, installation has got a lot easier. Follow the Official Install Doc and Official install to debian Doc, roughly looking like: 1. Install Jessie into kvm

kvm -m 2048 -drive file=lava2.img,if=virtio -cdrom debian-testing-amd64-netinst.iso
2. Install lava-server

apt-get update; apt-get install -y postgresql nfs-kernel-server apache2
apt-get install lava-server
# answer debconf questions
a2dissite 000-default && a2ensite lava-server.conf
service apache2 reload
lava-server manage createsuperuser --username default --email=foo.bar@example.com
$EDITOR /etc/lava-dispatcher/lava-dispatcher.conf # make sure LAVA_SERVER_IP is right
That's the generic setup. Now you can point your browser to the IP address of the kvm machine, and log in with the default user and the password you made. 3 ... 1000 Each LAVA instance is site customized for the boards, network, serial ports, etc. In this example, I now add a single arndale board.

cp /usr/lib/python2.7/dist-packages/lava_dispatcher/default-config/lava-dispatcher/device-types/arndale.conf /etc/lava-dispatcher/device-types/
sudo /usr/share/lava-server/add_device.py -s arndale arndale-01 -t 7001
This generates us a almost usable config for the arndale. For site specifics I have usb-to-serial. Outside kvm, I provide access to serial ports using the following ser2net config:

7001:telnet:0:/dev/ttyUSB0:115200 8DATABITS NONE 1STOPBIT
7002:telnet:0:/dev/ttyUSB1:115200 8DATABITS NONE 1STOPBIT
TODO: make ser2net not run as root and ensure usb2serial devices always get same name.. For automatic power reset, I wanted something cheap, yet something that wouldn't require much soldering (I'm not a real embedded engineer.. I prefer software side ;) . Discussed with Hector, who hinted about prebuilt relay boxes. Chose one from Ebay, a kmtronic 8-port USB Relay. So now I have this cute boxed nonsense hack. The USB relay is driven with a short script, hard-reset-1

stty -F /dev/ttyACM0 9600
echo -e '\xFF\x01\x00' > /dev/ttyACM0
sleep 1
echo -e '\xFF\x01\x01' > /dev/ttyACM0
Sidenote: If you don't have or want automated power relay for lava, you can always replace this this script with something along "mpg123 puny_human_press_the_power_button_now.mp3" Both the serial port and reset script are on server with dns name aimless. So we take the /etc/lava-dispatcher/devices/arndale-01.conf that add_device.py created and make it look like:

device_type = arndale
hostname = arndale-01
connection_command = telnet aimless 7001
hard_reset_command = slogin lava@aimless -i /etc/lava-dispatcher/id_rsa /home/lava/hard-reset-1
Since in my case I'm only going to test with tftp/nfs boot, the arndale board needs only to be setup to have a u-boot bootloader ready on power-on. Now everything is ready for a test job. I have a locally built kernel and device tree, and I export the directory using the httpd available by default in debian.. Python!

cd out/
python -m SimpleHTTPServer
Go to the lava web server, select api->tokens and create a new token. Next we add the token and use it to submit a job

$ sudo apt-get install lava-tool
$ lava-tool auth-add http://default@lava-server/RPC2/
$ lava-tool submit-job http://default@lava-server/RPC2/ lava_test.json
submitted as job id: 1
$
The first job should now be visible in the lava web frontend, in the scheduler -> jobs part. If everything goes fine, the relay will click in a moment and the job will finish in a few minutes.

6 November 2014

Daniel Kahn Gillmor: GnuPG 2.1.0 in debian experimental

Today, i uploaded GnuPG 2.1.0 into debian's experimental suite. It's built for amd64 and i386 and powerpc already. You can monitor its progress on the buildds to see when it's available for your architecture. ChangesGnuPG 2.1 offers many new and interesting features, but one of the most important changes is the introduction of elliptic curve crypto (ECC). While GnuPG 2.1 discourages the creation of ECC keys by default, it's important that we have the ability to verify ECC signatures and to encrypt to ECC keys if other people are using this tech. It seems likely, for example, that Google's End-To-End Chrome OpenPGP extension will use ECC. GnuPG users who don't have this capability available won't be able to communicate with End-To-End users. There are many other architectural changes, including a move to more daemonized interactions with the outside world, including using dirmngr to talk to the keyservers, and relying more heavily on gpg-agent for secret key access. The gpg-agent change is a welcome one -- the agent now holds the secret key material entirely and never releases it -- as of 2.1 gpg2 never has any asymmetric secret key material in its process space at all. One other nice change for those of us with large keyrings is the new keybox format for public key material. This provides much faster indexed access to the public keyring. I've been using GnuPG 2.1.0 betas regularly for the last month, and i think that for the most part, they're ready for regular use. Timing for debian The timing between the debian freeze and the GnuPG upstream is unfortunate, but i don't think i'm prepared to push for this as a jessie transition yet, without more backup. I'm talking to other members of the GnuPG packaging team to see if they think this is worth even bringing to the attention of the release team, but i'm not pursuing it at the moment. If you really want to see this in debian jessie, please install the experimental package and let me know how it works for you. Long term migration concerns GnuPG upstream is now maintaining three branches concurrently: modern (2.1.x), stable (2.0.x), and classic (1.4.x). I think this is stretches the GnuPG upstream development team too thin, and we should do what we can to help them transition to supporting fewer releases concurrently. In the long-term, I'd ultimately like to see gnupg 2.1.x to replace all use of gpg 1.4.x and gpg 2.0.x in debian, but unlikely to to happen right now. In particular, the following two bugs make it impossible to use my current, common monkeysphere workflow: And GnuPG 2.1.0 drops support for the older, known-weak OpenPGPv3 key formats. This is an important step for simplification, but there are a few people who probably still need to use v3 keys for obscure/janky reasons, or have data encrypted to a v3 key that they need to be able to decrypt. Those people will want to have GnuPG 1.4 around. Call for testing Anyway, if you use debian testing or unstable, and you are interested in these features, i invite you to install gnupg2 and its friends from experimental. If you want to be sensibly conservative, i recommend backing up ~/.gnupg before trying to use it:

cp -aT .gnupg .gnupg.bak
sudo apt install -t experimental gnupg2 gnupg-agent dirmngr gpgsm gpgv2 scdaemon
If you find issues, please file them via the debian BTS as usual. I (or other members of the pkg-gnupg team) will help you triage them to upstream as needed. Tags: ecc, experimental, gnupg

Matthias Klumpp: The state of AppStream/GNOME-Software in Debian Jessie

or Why do I not see any update notifications on my brand-new Debian Jessie installation?? This is a short explanation of the status quo, and also explains the no update notifications issue in a slightly more detailed way, since I am already getting bug reports for that. As you might know, GNOME provides GNOME-Software for installation of applications via PackageKit. In order to work properly, GNOME-Software needs AppStream metadata, which is not yet available in Debian. There was a GSoC student working on the necessary code for that, but the code is not yet ready and doesn t produce good results yet. Therefore, I postponed AppStream integration to Jessie+1, with an option to include some metadata for GNOME and KDE to use via a normal .deb package. Then, GNOME was updated to 3.14. GNOME 3.14 moved lots of stuff into GNOME-Software, including the support for update-notifications (which have been in g-s-d before). GNOME-Software is also the only thing which can edit the application groups in GNOME-Shell, at least currently. So obviously, there was no a much stronger motivation to support GNOME-Software in Jessie. The appstream-glib library, which GNOME-Software uses exclusively to read AppStream metadata, didn t support the DEP-11 metadata format which Debian uses in place of the original AppSTream XML for a while, but does so in it s current development branch. So that component had to be packaged first. Later, GNOME-Software was uploaded to the archive as well, but still lacked the required metadata. That data was provided by me as a .deb package later, locally generated using the current code by my SoC student (the data isn t great, but better than nothing). So far with the good news. But there are multiple issues at time. First of all, the appstream-data package didn t pass NEW so far, due to it s complex copyright situation (nothing we can t resolve, since app-install-data, which appstream-data would replace, is in Debian as well). Also, GNOME-Software is exclusively using offline-updates (more information also on [1] and [2]) at time. This isn t always working at the moment, since I haven t had the time to test it properly and I didn t expect it to be used in Debian Jessie as well[3]. Furthermore, the offline-updates feature requires systemd (which isn t an issue in itself, I am quite fine with that, but people not using it will get unexpected results, unless someone does the work to implement offline-updates with sysvinit). Since we are in freeze at time, and obviously this stuff is not ready yet, GNOME is currently without update notifications and without a way to change the shell application groups. So, how can we fix this? One way would of course be to patch notification support back into g-s-d, if the new layout there allows doing that. But that would not give us the other features GNOME-Software provides, like application-group-editing. Implementing that differently and patching it to make it work would be more or at least the same amount of work like making GNOME-Software run properly. I therefore prefer getting GNOME-Software to run, at least with basic functionality. That would likely mean hiding things like the offline-update functionality, and using online-updates with GNOME-PackageKit instead. Obviously, this approach has it s own issues, like doing most of the work post-freeze, which kind of defeats the purpose of the freeze and would need some close coordination with the release-team. So, this is the status quo at time. It is kind of unfortunate that GNOME moved crucial functionality into a new component which requires additional integration work by the distributors so quickly, but that s something which isn t worth to talk about. We need a way forward to bring update-notifications back, and there is currently work going on to do that. For all Debian users: Please be patient while we resolve the situation, and sorry for the inconvenience. For all developers: If you would like to help, please contact me or Laurent Bigonville, there are some tasks which could use some help.
As a small remark: If you are using KDE, you are lucky Apper provides the notification support like it always did, and thanks to improvements in aptcc and PackageKit, it even is a bit faster now. For the Xfce and <other_desktop> people, you need to check if your desktop provides integration with PackageKit for update-checking. At least Xfce doesn t, but after GNOME-PackageKit removed support for it (which was moved to gnome-settings-daemon and now to GNOME-Software) nobody stepped up to implement it yet (so if you want to do it it s not super-complicated, but knowledge of C and GTK+ is needed). - [3]: It looks like dpkg tries to ask a debconf question for some reason, or an external tool like apt-listchanges is interfering with the process, which must run completely unsupervised. There is some debugging needed to resolve these Debian-specific issues.

Dirk Eddelbuettel: A Software Carpentry workshop at Northwestern

On Friday October 31, 2014, and Saturday November 1, 2014, around thirty-five graduate students and faculty members attended a Software Carpentry workshop. Attendees came primarily from the Economics department and the Kellogg School of Management, which was also the host and sponsor providing an excellent venue with the Allen Center on the (main) Evanston campus of Northwestern University. The focus of the two-day workshop was an introduction, and practical initiation, to working effectively at the shell, getting introduced and familiar with the git revision control system, as well as a thorough introduction to working and programming in R---from the basics all the way to advanced graphing as well as creating reproducible research documents. The idea of the workshop had come out of discussion during our R/Finance 2014 conference. Bob McDonald of Northwestern, one of this year's keynote speakers, and I were discussing various topic related to open source and good programming practice --- as well as the lack of a thorough introduction to either for graduate students and researcher. And once I mentioned and explained Software Carpentry, Bob was rather intrigued. And just a few months later we were hosting a workshop (along with outstanding support from Jackie Milhans from Research Computing at Northwestern). We were extremely fortunate in that Karthik Ram and Ramnath Vaidyanathan were able to come to Chicago and act as lead instructors, giving me an opportunity to get my feet wet. The workshop began with a session on shell and automation, which was followed by three session focusing on R: a core introduction, a session focused on function, and to end the day, a session on the split-apply-combine approach to data transformation and analysis. The second day started with two concentrated session on git and the git workflow. In the afternoon, one session on visualization with R as well as a capstone-alike session on reproducible research rounded out the second day.

Things that worked The experience of the instructors showed, as the material was presented and an effective manner. The selection of topics, as well as the pace were seen by most students to be appropriate and just right. Karthik and Ramnath both did an outstanding job. No students experienced any real difficulties installing software, or using the supplied information. Participants were roughly split between Windows and OS X laptops, and had generally no problem with bash, git, or R via RStudio. The overall Software Carpentry setup, the lesson layout, the focus on hands-on exercises along with instruction, the use of the electronic noteboard provided by etherpad and, of course, the tried-and-tested material worked very well.

Things that could have worked better Even more breaks for exercises could have been added. Students had difficulty staying on pace in some of the exercise: once someone fell behind even for a small error (maybe a typo) it was sometimes hard to catch up. That is a general problem for hands-on classes. I feel I could have done better with the scope of my two session. Even more cohesion among the topics could have been achieved via a single continually used example dataset and analysis.

Acknowledgments Robert McDonald from Kellogg, and Jackie Milhans from Research Computing IT, were superb hosts and organizers. Their help in preparing for the workshop was tremendous, and the pick of venue was excellent, and allowed for a stress-free two days of classes. We could not have done this without Karthik and Ramnath, so a very big Thank You to both of them. Last but not least the Software Carpentry 'head office' was always ready to help Bob, Jackie and myself during the earlier planning stage, so another big Thank You! to Greg and Arliss.

Lisandro Dami&aacute;n Nicanor P&eacute;rez Meyer: Early announce: Qt4 removal in Jessie+1

We the Debian Qt/KDE Team want to early-announce [maintainer warning] our decision to remove Qt4 from Jessie+1. This warning is mostly targeted at upstreams.

Qt4 has been deprecated since Qt5's first release on December 19th 2012, that means almost two years ago!

So far we had bugfixes-only releases, but upstream has announced that they will end this support on august 2015. This already means we will have to do a special effort from that point on for Jessie in case RC bugs appears, so having it in Jessie+1 is simply a non-go.

Some of us where involved in various Qt4 to Qt5 migrations [0] and we know for sure that porting stuff from Qt4 to Qt5 is much much easier and less painful than it was from Qt3 to Qt4.

We also understand that there is still a lot of software still using Qt4. In order to easy the transition time we have provided Wheezy backports for Qt5.

Don't forget to take a look at the C++ API change page [1] whenever you start porting your application.

[0] http://perezmeyer.blogspot.com.ar/2014/03/porting-qt-4-apps-to-qt-5-example-with.html
[1] http://qt-project.org/doc/qt-5.0/qtdoc/sourcebreaks.html

[maintainer warning] **Remember the freeze** and do not upload packages ported to Qt5 to unstable. The best thing you can do now is to ask your upstream if the code can be compiled against Qt5 and, why not, try it yourself.

Our first priority now is to release Jessie, and this is why this is an early announce.

2 November 2014

Steve Kemp: IPv6 only server

I enjoy the tilde.club site/community, and since I've just setup an IPv6-only host I was looking to do something similar. Unfortunately my (working) code to clone github repositories into per-user directories fails - because github isn't accessible over IPv6. That's a shame. Oddly enough chromium, the browser packaged for wheezy, doesn't want to display IPv6-only websites either. For example this site fail to load http://ipv6.steve.org.uk/. In the meantime I've got a server setup which is only accessible over IPv6 and I'm a little smug. (http://ipv6.website/). (Yes it is true that I've used all the IPv4 addreses allocated to my VLAN. That's just a coincidence. Ssh!)

Next.

Previous.