Search Results: "pm"

6 June 2025

Reproducible Builds: Reproducible Builds in May 2025
Welcome to our 5th report from the Reproducible Builds project in 2025! Our monthly reports outline what we ve been up to over the past month, and highlight items of news from elsewhere in the increasingly-important area of software supply-chain security. If you are interested in contributing to the Reproducible Builds project, please do visit the Contribute page on our website. In this report:
  1. Security audit of Reproducible Builds tools published
  2. When good pseudorandom numbers go bad
  3. Academic articles
  4. Distribution work
  5. diffoscope and disorderfs
  6. Website updates
  7. Reproducibility testing framework
  8. Upstream patches

Security audit of Reproducible Builds tools published The Open Technology Fund s (OTF) security partner Security Research Labs recently an conducted audit of some specific parts of tools developed by Reproducible Builds. This form of security audit, sometimes called a whitebox audit, is a form testing in which auditors have complete knowledge of the item being tested. They auditors assessed the various codebases for resilience against hacking, with key areas including differential report formats in diffoscope, common client web attacks, command injection, privilege management, hidden modifications in the build process and attack vectors that might enable denials of service. The audit focused on three core Reproducible Builds tools: diffoscope, a Python application that unpacks archives of files and directories and transforms their binary formats into human-readable form in order to compare them; strip-nondeterminism, a Perl program that improves reproducibility by stripping out non-deterministic information such as timestamps or other elements introduced during packaging; and reprotest, a Python application that builds source code multiple times in various environments in order to to test reproducibility. OTF s announcement contains more of an overview of the audit, and the full 24-page report is available in PDF form as well.

When good pseudorandom numbers go bad Danielle Navarro published an interesting and amusing article on their blog on When good pseudorandom numbers go bad. Danielle sets the stage as follows:
[Colleagues] approached me to talk about a reproducibility issue they d been having with some R code. They d been running simulations that rely on generating samples from a multivariate normal distribution, and despite doing the prudent thing and using set.seed() to control the state of the random number generator (RNG), the results were not computationally reproducible. The same code, executed on different machines, would produce different random numbers. The numbers weren t just a little bit different in the way that we ve all wearily learned to expect when you try to force computers to do mathematics. They were painfully, brutally, catastrophically, irreproducible different. Somewhere, somehow, something broke.
Thanks to David Wheeler for posting about this article on our mailing list

Academic articles There were two scholarly articles published this month that related to reproducibility: Daniel Hugenroth and Alastair R. Beresford of the University of Cambridge in the United Kingdom and Mario Lins and Ren Mayrhofer of Johannes Kepler University in Linz, Austria published an article titled Attestable builds: compiling verifiable binaries on untrusted systems using trusted execution environments. In their paper, they:
present attestable builds, a new paradigm to provide strong source-to-binary correspondence in software artifacts. We tackle the challenge of opaque build pipelines that disconnect the trust between source code, which can be understood and audited, and the final binary artifact, which is difficult to inspect. Our system uses modern trusted execution environments (TEEs) and sandboxed build containers to provide strong guarantees that a given artifact was correctly built from a specific source code snapshot. As such it complements existing approaches like reproducible builds which typically require time-intensive modifications to existing build configurations and dependencies, and require independent parties to continuously build and verify artifacts.
The authors compare attestable builds with reproducible builds by noting an attestable build requires only minimal changes to an existing project, and offers nearly instantaneous verification of the correspondence between a given binary and the source code and build pipeline used to construct it , and proceed by determining that t he overhead (42 seconds start-up latency and 14% increase in build duration) is small in comparison to the overall build time.
Timo Pohl, Pavel Nov k, Marc Ohm and Michael Meier have published a paper called Towards Reproducibility for Software Packages in Scripting Language Ecosystems. The authors note that past research into Reproducible Builds has focused primarily on compiled languages and their ecosystems, with a further emphasis on Linux distribution packages:
However, the popular scripting language ecosystems potentially face unique issues given the systematic difference in distributed artifacts. This Systemization of Knowledge (SoK) [paper] provides an overview of existing research, aiming to highlight future directions, as well as chances to transfer existing knowledge from compiled language ecosystems. To that end, we work out key aspects in current research, systematize identified challenges for software reproducibility, and map them between the ecosystems.
Ultimately, the three authors find that the literature is sparse , focusing on few individual problems and ecosystems, and therefore identify space for more critical research.

Distribution work In Debian this month:
Hans-Christoph Steiner of the F-Droid catalogue of open source applications for the Android platform published a blog post on Making reproducible builds visible. Noting that Reproducible builds are essential in order to have trustworthy software , Hans also mentions that F-Droid has been delivering reproducible builds since 2015 . However:
There is now a Reproducibility Status link for each app on f-droid.org, listed on every app s page. Our verification server shows or based on its build results, where means our rebuilder reproduced the same APK file and means it did not. The IzzyOnDroid repository has developed a more elaborate system of badges which displays a for each rebuilder. Additionally, there is a sketch of a five-level graph to represent some aspects about which processes were run.
Hans compares the approach with projects such as Arch Linux and Debian that provide developer-facing tools to give feedback about reproducible builds, but do not display information about reproducible builds in the user-facing interfaces like the package management GUIs.
Arnout Engelen of the NixOS project has been working on reproducing the minimal installation ISO image. This month, Arnout has successfully reproduced the build of the minimal image for the 25.05 release without relying on the binary cache. Work on also reproducing the graphical installer image is ongoing.
In openSUSE news, Bernhard M. Wiedemann posted another monthly update for their work there.
Lastly in Fedora news, Jelle van der Waa opened issues tracking reproducible issues in Haskell documentation, Qt6 recording the host kernel and R packages recording the current date. The R packages can be made reproducible with packaging changes in Fedora.

diffoscope & disorderfs diffoscope is our in-depth and content-aware diff utility that can locate and diagnose reproducibility issues. This month, Chris Lamb made the following changes, including preparing and uploading versions 295, 296 and 297 to Debian:
  • Don t rely on zipdetails --walk argument being available, and only add that argument on newer versions after we test for that. [ ]
  • Review and merge support for NuGet packages from Omair Majid. [ ]
  • Update copyright years. [ ]
  • Merge support for an lzma comparator from Will Hollywood. [ ][ ]
Chris also merged an impressive changeset from Siva Mahadevan to make disorderfs more portable, especially on FreeBSD. disorderfs is our FUSE-based filesystem that deliberately introduces non-determinism into directory system calls in order to flush out reproducibility issues [ ]. This was then uploaded to Debian as version 0.6.0-1. Lastly, Vagrant Cascadian updated diffoscope in GNU Guix to version 296 [ ][ ] and 297 [ ][ ], and disorderfs to version 0.6.0 [ ][ ].

Website updates Once again, there were a number of improvements made to our website this month including:
Reproducibility testing framework The Reproducible Builds project operates a comprehensive testing framework running primarily at tests.reproducible-builds.org in order to check packages and other artifacts for reproducibility. However, Holger Levsen posted to our mailing list this month in order to bring a wider awareness to funding issues faced by the Oregon State University (OSU) Open Source Lab (OSL). As mentioned on OSL s public post, recent changes in university funding makes our current funding model no longer sustainable [and that] unless we secure $250,000 in committed funds, the OSL will shut down later this year . As Holger notes in his post to our mailing list, the Reproducible Builds project relies on hardware nodes hosted there. Nevertheless, Lance Albertson of OSL posted an update to the funding situation later in the month with broadly positive news.
Separate to this, there were various changes to the Jenkins setup this month, which is used as the backend driver of for both tests.reproducible-builds.org and reproduce.debian.net, including:
  • Migrating the central jenkins.debian.net server AMD Opteron to Intel Haswell CPUs. Thanks to IONOS for hosting this server since 2012.
  • After testing it for almost ten years, the i386 architecture has been dropped from tests.reproducible-builds.org. This is because that, with the upcoming release of Debian trixie, i386 is no longer supported as a regular architecture there will be no official kernel and no Debian installer for i386 systems. As a result, a large number of nodes hosted by Infomaniak have been retooled from i386 to amd64.
  • Another node, ionos17-amd64.debian.net, which is used for verifying packages for all.reproduce.debian.net (hosted by IONOS) has had its memory increased from 40 to 64GB, and the number of cores doubled to 32 as well. In addition, two nodes generously hosted by OSUOSL have had their memory doubled to 16GB.
  • Lastly, we have been granted access to more riscv64 architecture boards, so now we have seven such nodes, all with 16GB memory and 4 cores that are verifying packages for riscv64.reproduce.debian.net. Many thanks to PLCT Lab, ISCAS for providing those.

Outside of this, a number of smaller changes were also made by Holger Levsen:
  • reproduce.debian.net-related:
    • Only use two workers for the ppc64el architecture due to RAM size. [ ]
    • Monitor nginx_request and nginx_status with the Munin monitoring system. [ ][ ]
    • Detect various variants of network and memory errors. [ ][ ][ ][ ]
    • Add a prominent link to reproducible-builds.org. [ ]
    • Add a rebuilderd-cache-cleanup.service and run it daily via timer. [ ][ ][ ][ ][ ]
    • Be more verbose what sources are being downloaded. [ ]
    • Correctly deal with packages with an epoch in their version [ ] and deal with binNMUs versions with an epoch as well [ ][ ].
    • Document how to reschedule all other errors on all archs. [ ]
    • Misc documentation improvements. [ ][ ][ ][ ]
    • Include the $HOSTNAME variable in the rebuilderd logfiles. [ ]
    • Install the equivs package on all worker nodes. [ ][ ]
  • Jenkins nodes:
    • Permit the sudo tool to fix up permission issues. [ ][ ]
    • Document how to manage diskspace with OpenStack. [ ]
    • Ignore a number of spurious monitoring errors on riscv64, FreeBSD, etc.. [ ][ ][ ][ ]
    • Install ntpsec-ntpdate (instead of ntpdate) as the former is available on Debian trixie and bookworm. [ ][ ]
    • Use the same SSH ControlPath for all nodes. [ ]
    • Make sure the munin user uses the same SSH config as the jenkins user. [ ]
  • tests.reproducible-builds.org-related:
    • Disable testing of the i386 architecture. [ ][ ][ ][ ][ ]
    • Document the current disk usage. [ ][ ]
    • Address some image placement now that we only test three architectures. [ ]
    • Keep track of build performance. [ ]
  • Misc:
    • Fix a (harmless) typo in the multiarch_versionskew script. [ ]
In addition, Jochen Sprickerhof made a series of changes related to reproduce.debian.net:
  • Add out of memory detection to the statistics page. [ ]
  • Reverse the sorting order on the statistics page. [ ][ ][ ][ ]
  • Improve the spacing between statistics groups. [ ]
  • Update a (hard-coded) line number in error message detection pertaining to a debrebuild line number. [ ]
  • Support Debian unstable in the rebuilder-debian.sh script. [ ] ]
  • Rely on rebuildctl to sync only arch-specific packages. [ ][ ]

Upstream patches The Reproducible Builds project detects, dissects and attempts to fix as many currently-unreproducible packages as possible. This month, we wrote a large number of such patches, including:

Finally, if you are interested in contributing to the Reproducible Builds project, please visit our Contribute page on our website. However, you can get in touch with us via:

1 June 2025

Guido G nther: Free Software Activities May 2025

Another short status update of what happened on my side last month. Larger blocks besides the Phosh 0.47 release are on screen keyboard and cell broadcast improvements, work on separate volume streams, the switch of phoc to wlroots 0.19.0 and effort to make Phosh work on Debian's upcoming stable release (Trixie) out of the box. Trixie will ship with Phosh 0.46, if you want to try out 0.47 you can fetch it from Debian's experimental suite. See below for details on the above and more: phosh phoc phosh-mobile-settings phosh-osk-stub / stevia phosh-tour phosh-osk-data pfs xdg-desktop-portal-phosh phrog phosh-debs meta-phosh feedbackd feedbackd-device-themes gmobile GNOME calls Debian ModemManager osmo-cbc gsm-cell-testing mobile-broadband-provider-info Cellbroadcastd phosh-site pipewire wireplumber python-dbusmock Bugs Reviews This is not code by me but reviews on other peoples code. The list is (as usual) slightly incomplete. Thanks for the contributions! Help Development If you want to support my work see donations. Comments? Join the Fediverse thread

Emmanuel Kasper: ARM64 desktop as daily driver

I have bought myself an expensive ARM64 workstation, the System 76 Thelio Astra that I intend to use as my main desktop computer for the next 15 years, running Debian. The box is basically a server motherboard repurposed in a good desktop chassis. In Europe it seems you can order similar ready systems here. The hardware is well supported by Debian 12 and Debian testing.I had some initial issues with graphics, due to the board being designed for a server use, but I am solving these as we go. Annoyances I got so far:
  • When you power on the machine using the power supply switch, you have to wait for the BMC to finished its startup sequence, before the front power button does anything. As starting the BMC can take 90 seconds, I thought initially the machine was dead on arrival.
  • The default graphical output is redirected to the BMC Serial over LAN, which means if you want to install Debian using an attached display you need to force the output on the attached display passing console=tty0 as an installer parameter.
  • Finally the Xorg Nouveau driver does not work with the Nvidia A400 GPU I got with the machine. After passing nodemodeset as a kernel parameter, I can force Xorg to use an unaccelerated framebuffer, which at least displays something. I passed this parameter to the installer, so that I could install in graphical mode. The driver from Nvidia works, but I d like very much to get Nouveau running.
Ugly point
  • A server mother board we said. This mean there is NO suspend to RAM, you have to power off if you don t want to keep the machine on all the time. As the boot sequence is long (server board again) I am pondering setting a startup time in the UEFI firmware to turn the box on at specific usage time.
Good points
  • The firmware of the machine is a standard EFI, which means you can use the debian arm64 installer on an USB stick straight away, without any kind of device tree / bootloader fiddling.
  • The 3 Nics, Wifi, bluetooth were all recognized on first boot.
  • I was afraid the machine would be loud. However it is quiet, you hear the humming of a fan, but it is quieter than most desktops I owned, from the Atari TT to an all in one Lenovo M92z I used for 10 years. I am certainly not a hardware and cooling specialist, but meseems the quietness comes from slow rotating but very large fans.
  • Due the clean design of Linux and Debian, thousands of packages working correctly on ARM64, starting with the Gnome desktop environment and Firefox.
  • The documentation from system76 is fine, their Ubuntu 20.04 setup guide was helpful to understand the needed parameters mentioned above.
Update: The display is working correctly with the nouveau driver after installing the non-free Nvidia firmware. See the Debian wiki.

30 May 2025

Russell Coker: Service Setup Difficulties

Marco wrote a blog post opposing hyperscale systems which included We want to use an hyperscaler cloud because our developers do not want to operate a scalable and redundant database just means that you need to hire competent developers and/or system administrators. [1]. I previously wrote a blog post Why Clusters Usually Don t Work [2] and I believe that all the points there are valid today and possibly exacerbated by clusters getting less direct use as clustering is increasingly being done by hyperscale providers. Take a basic need, a MySQL or PostgreSQL database for example. You want it to run and basically do the job and to have good recovery options. You could set it up locally, run backups, test the backups, have a recovery plan for failures, maybe have a hot-spare server if it s really important, have tests for backups and hot-spare server, etc. Then you could have documentation for this so if the person who set it up isn t available when there s a problem they will be able to find out what to do. But the hyperscale option is to just select a database in your provider and have all this just work. If the person who set it up isn t available for recovery in the event of failure the company can just put out a job advert for person with experience on cloud company X and have them just immediately go to work on it. I don t like hyperscale providers as they are all monopolistic companies that do anti-competitive actions. Google should be broken up, Android development and the Play Store should be separated from Gmail etc which should be separated from search and adverts, and all of them should be separated from the GCP cloud service. Amazon should be broken up, running the Amazon store should be separated from selling items on the store, which should be separated from running a video on demand platform, and all of them should be separated from the AWS cloud. Microsoft should be broken up, OS development should be separated from application development all of that should be separated from cloud services (Teams and Office 365), and everything else should be separate from the Azure cloud system. But the cloud providers offer real benefits at small scale. Running a MySQL or PostgreSQL database for local services is easy, it s a simple apt command to install it and then it basically works. Doing backup and recovery isn t so easy. One could say just hire competent people but if you do hire competent people do you want them running MySQL databases etc or have them just click on the create mysql database option on a cloud control panel and then move on to more important things? The FreedomBox project is a great project for installing and managing home/personal services [3]. But it s not about running things like database servers, it s for a high level running mail servers and other things for the user not for the developer. The Debian packaging of Open Stack looks interesting [4], it s a complete setup for running your own hyper scale cloud service. For medium and large organisations running Open Stack could be a good approach. But for small organisations it s cheaper and easier to just use a cloud service to run things. The issue of when to run things in-house and when to put them in the cloud is very complex. I think that if the organisation is going to spend less money on cloud services than on the salary of one sysadmin then it s probably best to have things in the cloud. When cloud costs start to exceed the salary of one person who manages systems then having them spend the extra time and effort to run things locally starts making more sense. There is also an opportunity cost in having a good sysadmin work on the backups for all the different systems instead of letting the cloud provider just do it. Another possibility of course is to run things in-house on low end hardware and just deal with the occasional downtime to save money. Knowingly choosing less reliability to save money can be quite reasonable as long as you have considered the options and all the responsible people are involved in the discussion. The one situation that I strongly oppose is having hyper scale services setup by people who don t understand them. Running a database server on a cloud service because you don t want to spend the time managing it is a reasonable choice in many situations. Running a database server on a cloud service because you don t understand how to setup a database server is never a good choice. While the cloud services are quite resilient there are still ways of breaking the overall system if you don t understand it. Also while it is quite possible for someone to know how to develop for databases including avoiding SQL injection etc but be unable to setup a database server that s probably not going to be common, probably if someone can t set it up (a generally easy task) then they can t do the hard tasks of making it secure.

29 May 2025

Arthur Diniz: Bringing Kubernetes Back to Debian

I ve been part of the Debian Project since 2019, when I attended DebConf held in Curitiba, Brazil. That event sparked my interest in the community, packaging, and how Debian works as a distribution. In the early years of my involvement, I contributed to various teams such as the Python, Golang and Cloud teams, packaging dependencies and maintaining various tools. However, I soon felt the need to focus on packaging software I truly enjoyed, tools I was passionate about using and maintaining. That s when I turned my attention to Kubernetes within Debian.

A Broken Ecosystem The Kubernetes packaging situation in Debian had been problematic for some time. Given its large codebase and complex dependency tree, the initial packaging approach involved vendorizing all dependencies. While this allowed a somewhat functional package to be published, it introduced several long-term issues, especially security concerns. Vendorized packages bundle third-party dependencies directly into the source tarball. When vulnerabilities arise in those dependencies, it becomes difficult for Debian s security team to patch and rebuild affected packages system-wide. This approach broke Debian s best practices, and it eventually led to the abandonment of the Kubernetes source package, which had stalled at version 1.20.5. Due to this abandonment, critical bugs emerged and the package was removed from Debian s testing channel, as we can see in the package tracker.

New Debian Kubernetes Team Around this time, I became a Debian Maintainer (DM), with permissions to upload certain packages. I saw an opportunity to both contribute more deeply to Debian and to fix Kubernetes packaging. In early 2024, just before DebConf Busan in South Korea, I founded the Debian Kubernetes Team. The mission of the team was to repackage Kubernetes in a maintainable, security-conscious, and Debian-compliant way. At DebConf, I shared our progress with the broader community and received great feedback and more visibility, along with people interested in contributing to the team. Our first tasks was to migrate existing Kubernetes-related tools such as kubectx, kubernetes-split-yaml and kubetail into a dedicated namespace on Salsa, Debian s GitLab instance. Many of these tools were stored across different teams (like the Go team), and consolidating them helped us organize development and focus our efforts.

De-vendorizing Kubernetes Our main goal was to un-vendorize Kubernetes and bring it up-to-date with upstream releases. This meant:
  • Removing the vendor directory and all embedded third-party code.
  • Trimming the build scope to focus solely on building kubectl, Kubernetes CLI.
  • Using Files-Excluded in debian/copyright to cleanly drop unneeded files during source imports.
  • Rebuilding the dependency tree, ensuring all Go modules were separately packaged in Debian.
We used uscan, a standard Debian packaging tool that fetches upstream tarballs and prepares them accordingly. The Files-Excluded directive in our debian/copyright file instructed uscan to automatically remove unnecessary files during the repackaging process:
$ uscan
Newest version of kubernetes on remote site is 1.32.3, specified download version is 1.32.3
Successfully repacked ../v1.32.3 as ../kubernetes_1.32.3+ds.orig.tar.gz, deleting 30616 files from it.
The results were dramatic. By comparing the original upstream tarball with our repackaged version, we can see that our approach reduced the tarball size by over 75%:
$ du -h upstream-v1.32.3.tar.gz kubernetes_1.32.3+ds.orig.tar.gz
14M	upstream-v1.32.3.tar.gz
3.2M	kubernetes_1.32.3+ds.orig.tar.gz
This significant reduction wasn t just about saving space. By removing over 30,000 files, we simplified the package, making it more maintainable. Each dependency could now be properly tracked, updated, and patched independently, resolving the security concerns that had plagued the previous packaging approach.

Dependency Graph To give you an idea of the complexity involved in packaging Kubernetes for Debian, the image below is a dependency graph generated with debtree, visualizing all the Go modules and other dependencies required to build the kubectl binary. kubectl-depgraph This web of nodes and edges represents every module and its relationship during the compilation process of kubectl. Each box is a Debian package, and the lines connecting them show how deeply intertwined the ecosystem is. What might look like a mess of blue spaghetti is actually a clear demonstration of the vast and interconnected upstream world that tools like kubectl rely on. But more importantly, this graph is a testament to the effort that went into making kubectl build entirely using Debian-packaged dependencies only, no vendoring, no downloading from the internet, no proprietary blobs.
Upstream Version 1.32.3 and Beyond After nearly two years of work, we successfully uploaded version 1.32.3+ds of kubectl to Debian unstable. kubernetes/-/merge_requests/1 The new package also includes:
  • Zsh, Fish, and Bash completions installed automatically
  • Man pages and metadata for improved discoverability
  • Full integration with kind and docker for testing purposes

Integration Testing with Autopkgtest To ensure the reliability of kubectl in real-world scenarios, we developed a new autopkgtest suite that runs integration tests using real Kubernetes clusters created via Kind. Autopkgtest is a Debian tool used to run automated tests on binary packages. These tests are executed after the package is built but before it s accepted into the Debian archive, helping catch regressions and integration issues early in the packaging pipeline. Our test workflow validates kubectl by performing the following steps:
  • Installing Kind and Docker as test dependencies.
  • Spinning up two local Kubernetes clusters.
  • Switching between cluster contexts to ensure multi-cluster support.
  • Deploying and scaling a sample nginx application using kubectl.
  • Cleaning up the entire test environment to avoid side effects.
  • debian/tests/kubectl.sh

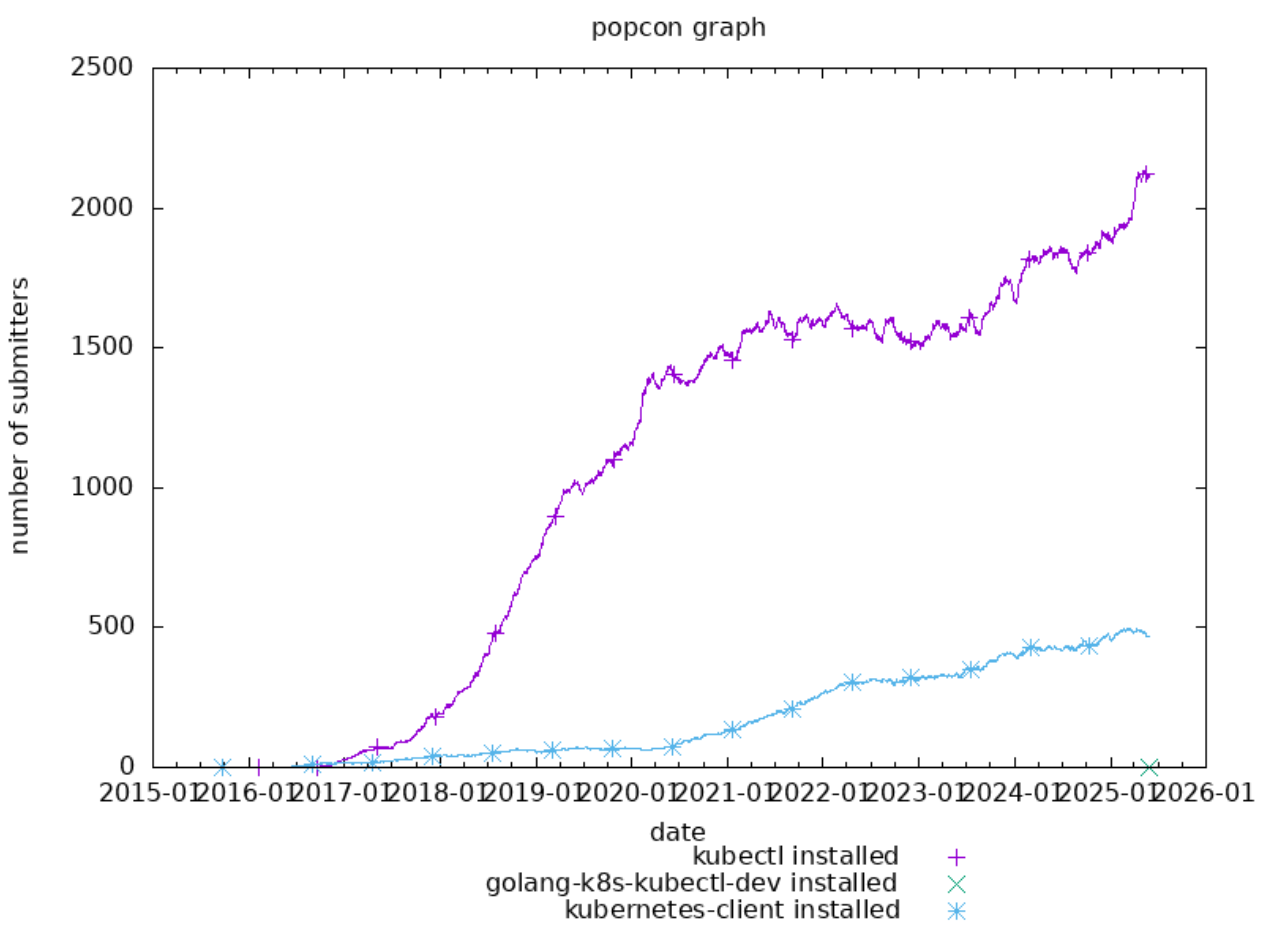
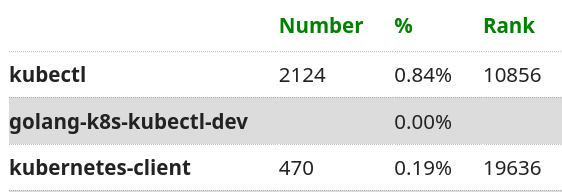
Popcon: Measuring Adoption To measure real-world usage, we rely on data from Debian s popularity contest (popcon), which gives insight into how many users have each binary installed. popcon-graph popcon-table Here s what the data tells us:
  • kubectl (new binary): Already installed on 2,124 systems.
  • golang-k8s-kubectl-dev: This is the Go development package (a library), useful for other packages and developers who want to interact with Kubernetes programmatically.
  • kubernetes-client: The legacy package that kubectl is replacing. We expect this number to decrease in future releases as more systems transition to the new package.
Although the popcon data shows activity for kubectl before the official Debian upload date, it s important to note that those numbers represent users who had it installed from upstream source-lists, not from the Debian repositories. This distinction underscores a demand that existed even before the package was available in Debian proper, and it validates the importance of bringing it into the archive.
Also worth mentioning: this number is not the real total number of installations, since users can choose not to participate in the popularity contest. So the actual adoption is likely higher than what popcon reflects.

Community and Documentation The team also maintains a dedicated wiki page which documents:
  • Maintained tools and packages
  • Contribution guidelines
  • Our roadmap for the upcoming Debian releases
https://debian-kubernetes.org

Looking Ahead to Debian 13 (Trixie) The next stable release of Debian will ship with kubectl version 1.32.3, built from a clean, de-vendorized source. This version includes nearly all the latest upstream features, and will be the first time in years that Debian users can rely on an up-to-date, policy-compliant kubectl directly from the archive. By comparing with upstream, our Debian package even delivers more out of the box, including shell completions, which the upstream still requires users to generate manually. In 2025, the Debian Kubernetes team will continue expanding our packaging efforts for the Kubernetes ecosystem. Our roadmap includes:
  • kubelet: The primary node agent that runs on each node. This will enable Debian users to create fully functional Kubernetes nodes without relying on external packages.
  • kubeadm: A tool for creating Kubernetes clusters. With kubeadm in Debian, users will then be able to bootstrap minimum viable clusters directly from the official repositories.
  • helm: The package manager for Kubernetes that helps manage applications through Kubernetes YAML files defined as charts.
  • kompose: A conversion tool that helps users familiar with docker-compose move to Kubernetes by translating Docker Compose files into Kubernetes resources.

Final Thoughts This journey was only possible thanks to the amazing support of the debian-devel-br community and the collective effort of contributors who stepped up to package missing dependencies, fix bugs, and test new versions. Special thanks to:
  • Carlos Henrique Melara (@charles)
  • Guilherme Puida (@puida)
  • Jo o Pedro Nobrega (@jnpf)
  • Lucas Kanashiro (@kanashiro)
  • Matheus Polkorny (@polkorny)
  • Samuel Henrique (@samueloph)
  • Sergio Cipriano (@cipriano)
  • Sergio Durigan Junior (@sergiodj)
I look forward to continuing this work, bringing more Kubernetes tools into Debian and improving the developer experience for everyone.

Arthur Diniz: Bringing Kubernetes Back to Debian

I ve been part of the Debian Project since 2019, when I attended DebConf held in Curitiba, Brazil. That event sparked my interest in the community, packaging, and how Debian works as a distribution. In the early years of my involvement, I contributed to various teams such as the Python, Golang and Cloud teams, packaging dependencies and maintaining various tools. However, I soon felt the need to focus on packaging software I truly enjoyed, tools I was passionate about using and maintaining. That s when I turned my attention to Kubernetes within Debian.

A Broken Ecosystem The Kubernetes packaging situation in Debian had been problematic for some time. Given its large codebase and complex dependency tree, the initial packaging approach involved vendorizing all dependencies. While this allowed a somewhat functional package to be published, it introduced several long-term issues, especially security concerns. Vendorized packages bundle third-party dependencies directly into the source tarball. When vulnerabilities arise in those dependencies, it becomes difficult for Debian s security team to patch and rebuild affected packages system-wide. This approach broke Debian s best practices, and it eventually led to the abandonment of the Kubernetes source package, which had stalled at version 1.20.5. Due to this abandonment, critical bugs emerged and the package was removed from Debian s testing channel, as we can see in the package tracker.

New Debian Kubernetes Team Around this time, I became a Debian Maintainer (DM), with permissions to upload certain packages. I saw an opportunity to both contribute more deeply to Debian and to fix Kubernetes packaging. In early 2024, just before DebConf Busan in South Korea, I founded the Debian Kubernetes Team. The mission of the team was to repackage Kubernetes in a maintainable, security-conscious, and Debian-compliant way. At DebConf, I shared our progress with the broader community and received great feedback and more visibility, along with people interested in contributing to the team. Our first tasks was to migrate existing Kubernetes-related tools such as kubectx, kubernetes-split-yaml and kubetail into a dedicated namespace on Salsa, Debian s GitLab instance. Many of these tools were stored across different teams (like the Go team), and consolidating them helped us organize development and focus our efforts.

De-vendorizing Kubernetes Our main goal was to un-vendorize Kubernetes and bring it up-to-date with upstream releases. This meant:
  • Removing the vendor directory and all embedded third-party code.
  • Trimming the build scope to focus solely on building kubectl, Kubernetes CLI.
  • Using Files-Excluded in debian/copyright to cleanly drop unneeded files during source imports.
  • Rebuilding the dependency tree, ensuring all Go modules were separately packaged in Debian.
We used uscan, a standard Debian packaging tool that fetches upstream tarballs and prepares them accordingly. The Files-Excluded directive in our debian/copyright file instructed uscan to automatically remove unnecessary files during the repackaging process:
$ uscan
Newest version of kubernetes on remote site is 1.32.3, specified download version is 1.32.3
Successfully repacked ../v1.32.3 as ../kubernetes_1.32.3+ds.orig.tar.gz, deleting 30616 files from it.
The results were dramatic. By comparing the original upstream tarball with our repackaged version, we can see that our approach reduced the tarball size by over 75%:
$ du -h upstream-v1.32.3.tar.gz kubernetes_1.32.3+ds.orig.tar.gz
14M	upstream-v1.32.3.tar.gz
3.2M	kubernetes_1.32.3+ds.orig.tar.gz
This significant reduction wasn t just about saving space. By removing over 30,000 files, we simplified the package, making it more maintainable. Each dependency could now be properly tracked, updated, and patched independently, resolving the security concerns that had plagued the previous packaging approach.

Dependency Graph To give you an idea of the complexity involved in packaging Kubernetes for Debian, the image below is a dependency graph generated with debtree, visualizing all the Go modules and other dependencies required to build the kubectl binary. kubectl-depgraph This web of nodes and edges represents every module and its relationship during the compilation process of kubectl. Each box is a Debian package, and the lines connecting them show how deeply intertwined the ecosystem is. What might look like a mess of blue spaghetti is actually a clear demonstration of the vast and interconnected upstream world that tools like kubectl rely on. But more importantly, this graph is a testament to the effort that went into making kubectl build entirely using Debian-packaged dependencies only, no vendoring, no downloading from the internet, no proprietary blobs.
Upstream Version 1.32.3 and Beyond After nearly two years of work, we successfully uploaded version 1.32.3+ds of kubectl to Debian unstable. kubernetes/-/merge_requests/1 The new package also includes:
  • Zsh, Fish, and Bash completions installed automatically
  • Man pages and metadata for improved discoverability
  • Full integration with kind and docker for testing purposes

Integration Testing with Autopkgtest To ensure the reliability of kubectl in real-world scenarios, we developed a new autopkgtest suite that runs integration tests using real Kubernetes clusters created via Kind. Autopkgtest is a Debian tool used to run automated tests on binary packages. These tests are executed after the package is built but before it s accepted into the Debian archive, helping catch regressions and integration issues early in the packaging pipeline. Our test workflow validates kubectl by performing the following steps:
  • Installing Kind and Docker as test dependencies.
  • Spinning up two local Kubernetes clusters.
  • Switching between cluster contexts to ensure multi-cluster support.
  • Deploying and scaling a sample nginx application using kubectl.
  • Cleaning up the entire test environment to avoid side effects.
  • debian/tests/kubectl.sh

Popcon: Measuring Adoption To measure real-world usage, we rely on data from Debian s popularity contest (popcon), which gives insight into how many users have each binary installed. popcon-graph popcon-table Here s what the data tells us:
  • kubectl (new binary): Already installed on 2,124 systems.
  • golang-k8s-kubectl-dev: This is the Go development package (a library), useful for other packages and developers who want to interact with Kubernetes programmatically.
  • kubernetes-client: The legacy package that kubectl is replacing. We expect this number to decrease in future releases as more systems transition to the new package.
Although the popcon data shows activity for kubectl before the official Debian upload date, it s important to note that those numbers represent users who had it installed from upstream source-lists, not from the Debian repositories. This distinction underscores a demand that existed even before the package was available in Debian proper, and it validates the importance of bringing it into the archive.
Also worth mentioning: this number is not the real total number of installations, since users can choose not to participate in the popularity contest. So the actual adoption is likely higher than what popcon reflects.

Community and Documentation The team also maintains a dedicated wiki page which documents:
  • Maintained tools and packages
  • Contribution guidelines
  • Our roadmap for the upcoming Debian releases
https://debian-kubernetes.org

Looking Ahead to Debian 13 (Trixie) The next stable release of Debian will ship with kubectl version 1.32.3, built from a clean, de-vendorized source. This version includes nearly all the latest upstream features, and will be the first time in years that Debian users can rely on an up-to-date, policy-compliant kubectl directly from the archive. By comparing with upstream, our Debian package even delivers more out of the box, including shell completions, which the upstream still requires users to generate manually. In 2025, the Debian Kubernetes team will continue expanding our packaging efforts for the Kubernetes ecosystem. Our roadmap includes:
  • kubelet: The primary node agent that runs on each node. This will enable Debian users to create fully functional Kubernetes nodes without relying on external packages.
  • kubeadm: A tool for creating Kubernetes clusters. With kubeadm in Debian, users will then be able to bootstrap minimum viable clusters directly from the official repositories.
  • helm: The package manager for Kubernetes that helps manage applications through Kubernetes YAML files defined as charts.
  • kompose: A conversion tool that helps users familiar with docker-compose move to Kubernetes by translating Docker Compose files into Kubernetes resources.

Final Thoughts This journey was only possible thanks to the amazing support of the debian-devel-br community and the collective effort of contributors who stepped up to package missing dependencies, fix bugs, and test new versions. Special thanks to:
  • Carlos Henrique Melara (@charles)
  • Guilherme Puida (@puida)
  • Jo o Pedro Nobrega (@jnpf)
  • Lucas Kanashiro (@kanashiro)
  • Matheus Polkorny (@polkorny)
  • Samuel Henrique (@samueloph)
  • Sergio Cipriano (@cipriano)
  • Sergio Durigan Junior (@sergiodj)
I look forward to continuing this work, bringing more Kubernetes tools into Debian and improving the developer experience for everyone.

26 May 2025

Otto Kek l inen: Creating Debian packages from upstream Git

Featured image of post Creating Debian packages from upstream GitIn this post, I demonstrate the optimal workflow for creating new Debian packages in 2025, preserving the upstream git history. The motivation for this is to lower the barrier for sharing improvements to and from upstream, and to improve software provenance and supply-chain security by making it easy to inspect every change at any level using standard git tooling. Key elements of this workflow include: To make the instructions so concrete that anyone can repeat all the steps themselves on a real package, I demonstrate the steps by packaging the command-line tool Entr. It is written in C, has very few dependencies, and its final Debian source package structure is simple, yet exemplifies all the important parts that go into a complete Debian package:
  1. Creating a new packaging repository and publishing it under your personal namespace on salsa.debian.org.
  2. Using dh_make to create the initial Debian packaging.
  3. Posting the first draft of the Debian packaging as a Merge Request (MR) and using Salsa CI to verify Debian packaging quality.
  4. Running local builds efficiently and iterating on the packaging process.

Create new Debian packaging repository from the existing upstream project git repository First, create a new empty directory, then clone the upstream Git repository inside it:
shell
mkdir debian-entr
cd debian-entr
git clone --origin upstreamvcs --branch master \
 --single-branch https://github.com/eradman/entr.git
Using a clean directory makes it easier to inspect the build artifacts of a Debian package, which will be output in the parent directory of the Debian source directory. The extra parameters given to git clone lay the foundation for the Debian packaging git repository structure where the upstream git remote name is upstreamvcs. Only the upstream main branch is tracked to avoid cluttering git history with upstream development branches that are irrelevant for packaging in Debian. Next, enter the git repository directory and list the git tags. Pick the latest upstream release tag as the commit to start the branch upstream/latest. This latest refers to the upstream release, not the upstream development branch. Immediately after, branch off the debian/latest branch, which will have the actual Debian packaging files in the debian/ subdirectory.
shell
cd entr
git tag # shows the latest upstream release tag was '5.6'
git checkout -b upstream/latest 5.6
git checkout -b debian/latest
%% init:   'gitGraph':   'mainBranchName': 'master'      %%
gitGraph:
checkout master
commit id: "Upstream 5.6 release" tag: "5.6"
branch upstream/latest
checkout upstream/latest
commit id: "New upstream version 5.6" tag: "upstream/5.6"
branch debian/latest
checkout debian/latest
commit id: "Initial Debian packaging"
commit id: "Additional change 1"
commit id: "Additional change 2"
commit id: "Additional change 3"
At this point, the repository is structured according to DEP-14 conventions, ensuring a clear separation between upstream and Debian packaging changes, but there are no Debian changes yet. Next, add the Salsa repository as a new remote which called origin, the same as the default remote name in git.
shell
git remote add origin git@salsa.debian.org:otto/entr-demo.git
git push --set-upstream origin debian/latest
This is an important preparation step to later be able to create a Merge Request on Salsa that targets the debian/latest branch, which does not yet have any debian/ directory.

Launch a Debian Sid (unstable) container to run builds in To ensure that all packaging tools are of the latest versions, run everything inside a fresh Sid container. This has two benefits: you are guaranteed to have the most up-to-date toolchain, and your host system stays clean without getting polluted by various extra packages. Additionally, this approach works even if your host system is not Debian/Ubuntu.
shell
cd ..
podman run --interactive --tty --rm --shm-size=1G --cap-add SYS_PTRACE \
 --env='DEB*' --volume=$PWD:/tmp/test --workdir=/tmp/test debian:sid bash
Note that the container should be started from the parent directory of the git repository, not inside it. The --volume parameter will loop-mount the current directory inside the container. Thus all files created and modified are on the host system, and will persist after the container shuts down. Once inside the container, install the basic dependencies:
shell
apt update -q && apt install -q --yes git-buildpackage dpkg-dev dh-make

Automate creating the debian/ files with dh-make To create the files needed for the actual Debian packaging, use dh_make:
shell
# dh_make --packagename entr_5.6 --single --createorig
Maintainer Name : Otto Kek l inen
Email-Address : otto@debian.org
Date : Sat, 15 Feb 2025 01:17:51 +0000
Package Name : entr
Version : 5.6
License : blank
Package Type : single
Are the details correct? [Y/n/q]

Done. Please edit the files in the debian/ subdirectory now.
Due to how dh_make works, the package name and version need to be written as a single underscore separated string. In this case, you should choose --single to specify that the package type is a single binary package. Other options would be --library for library packages (see libgda5 sources as an example) or --indep (see dns-root-data sources as an example). The --createorig will create a mock upstream release tarball (entr_5.6.orig.tar.xz) from the current release directory, which is necessary due to historical reasons and how dh_make worked before git repositories became common and Debian source packages were based off upstream release tarballs (e.g. *.tar.gz). At this stage, a debian/ directory has been created with template files, and you can start modifying the files and iterating towards actual working packaging.
shell
git add debian/
git commit -a -m "Initial Debian packaging"

Review the files The full list of files after the above steps with dh_make would be:
 -- entr
   -- LICENSE
   -- Makefile.bsd
   -- Makefile.linux
   -- Makefile.linux-compat
   -- Makefile.macos
   -- NEWS
   -- README.md
   -- configure
   -- data.h
   -- debian
     -- README.Debian
     -- README.source
     -- changelog
     -- control
     -- copyright
     -- gbp.conf
     -- entr-docs.docs
     -- entr.cron.d.ex
     -- entr.doc-base.ex
     -- manpage.1.ex
     -- manpage.md.ex
     -- manpage.sgml.ex
     -- manpage.xml.ex
     -- postinst.ex
     -- postrm.ex
     -- preinst.ex
     -- prerm.ex
     -- rules
     -- salsa-ci.yml.ex
     -- source
       -- format
     -- upstream
       -- metadata.ex
     -- watch.ex
   -- entr.1
   -- entr.c
   -- missing
     -- compat.h
     -- kqueue_inotify.c
     -- strlcpy.c
     -- sys
     -- event.h
   -- status.c
   -- status.h
   -- system_test.sh
 -- entr_5.6.orig.tar.xz
You can browse these files in the demo repository. The mandatory files in the debian/ directory are:
  • changelog,
  • control,
  • copyright,
  • and rules.
All the other files have been created for convenience so the packager has template files to work from. The files with the suffix .ex are example files that won t have any effect until their content is adjusted and the suffix removed. For detailed explanations of the purpose of each file in the debian/ subdirectory, see the following resources:
  • The Debian Policy Manual: Describes the structure of the operating system, the package archive and requirements for packages to be included in the Debian archive.
  • The Developer s Reference: A collection of best practices and process descriptions Debian packagers are expected to follow while interacting with one another.
  • Debhelper man pages: Detailed information of how the Debian package build system works, and how the contents of the various files in debian/ affect the end result.
As Entr, the package used in this example, is a real package that already exists in the Debian archive, you may want to browse the actual Debian packaging source at https://salsa.debian.org/debian/entr/-/tree/debian/latest/debian for reference. Most of these files have standardized formatting conventions to make collaboration easier. To automatically format the files following the most popular conventions, simply run wrap-and-sort -vast or debputy reformat --style=black.

Identify build dependencies The most common reason for builds to fail is missing dependencies. The easiest way to identify which Debian package ships the required dependency is using apt-file. If, for example, a build fails complaining that pcre2posix.h cannot be found or that libcre2-posix.so is missing, you can use these commands:
shell
$ apt install -q --yes apt-file && apt-file update
$ apt-file search pcre2posix.h
libpcre2-dev: /usr/include/pcre2posix.h
$ apt-file search libpcre2-posix.so
libpcre2-dev: /usr/lib/x86_64-linux-gnu/libpcre2-posix.so
libpcre2-posix3: /usr/lib/x86_64-linux-gnu/libpcre2-posix.so.3
libpcre2-posix3: /usr/lib/x86_64-linux-gnu/libpcre2-posix.so.3.0.6
The output above implies that the debian/control should be extended to define a Build-Depends: libpcre2-dev relationship. There is also dpkg-depcheck that uses strace to trace the files the build process tries to access, and lists what Debian packages those files belong to. Example usage:
shell
dpkg-depcheck -b debian/rules build

Build the Debian sources to generate the .deb package After the first pass of refining the contents of the files in debian/, test the build by running dpkg-buildpackage inside the container:
shell
dpkg-buildpackage -uc -us -b
The options -uc -us will skip signing the resulting Debian source package and other build artifacts. The -b option will skip creating a source package and only build the (binary) *.deb packages. The output is very verbose and gives a large amount of context about what is happening during the build to make debugging build failures easier. In the build log of entr you will see for example the line dh binary --buildsystem=makefile. This and other dh commands can also be run manually if there is a need to quickly repeat only a part of the build while debugging build failures. To see what files were generated or modified by the build simply run git status --ignored:
shell
$ git status --ignored
On branch debian/latest

Untracked files:
 (use "git add <file>..." to include in what will be committed)
 debian/debhelper-build-stamp
 debian/entr.debhelper.log
 debian/entr.substvars
 debian/files

Ignored files:
 (use "git add -f <file>..." to include in what will be committed)
 Makefile
 compat.c
 compat.o
 debian/.debhelper/
 debian/entr/
 entr
 entr.o
 status.o
Re-running dpkg-buildpackage will include running the command dh clean, which assuming it is configured correctly in the debian/rules file will reset the source directory to the original pristine state. The same can of course also be done with regular git commands git reset --hard; git clean -fdx. To avoid accidentally committing unnecessary build artifacts in git, a debian/.gitignore can be useful and it would typically include all four files listed as untracked above. After a successful build you would have the following files:
shell
 -- entr
   -- LICENSE
   -- Makefile -> Makefile.linux
   -- Makefile.bsd
   -- Makefile.linux
   -- Makefile.linux-compat
   -- Makefile.macos
   -- NEWS
   -- README.md
   -- compat.c
   -- compat.o
   -- configure
   -- data.h
   -- debian
     -- README.source.md
     -- changelog
     -- control
     -- copyright
     -- debhelper-build-stamp
     -- docs
     -- entr
       -- DEBIAN
         -- control
         -- md5sums
       -- usr
       -- bin
         -- entr
       -- share
       -- doc
         -- entr
         -- NEWS.gz
         -- README.md
         -- changelog.Debian.gz
         -- copyright
       -- man
       -- man1
       -- entr.1.gz
     -- entr.debhelper.log
     -- entr.substvars
     -- files
     -- gbp.conf
     -- patches
       -- PR149-expand-aliases-in-system-test-script.patch
       -- series
       -- system-test-skip-no-tty.patch
       -- system-test-with-system-binary.patch
     -- rules
     -- salsa-ci.yml
     -- source
       -- format
     -- tests
       -- control
     -- upstream
       -- metadata
       -- signing-key.asc
     -- watch
   -- entr
   -- entr.1
   -- entr.c
   -- entr.o
   -- missing
     -- compat.h
     -- kqueue_inotify.c
     -- strlcpy.c
     -- sys
     -- event.h
   -- status.c
   -- status.h
   -- status.o
   -- system_test.sh
 -- entr-dbgsym_5.6-1_amd64.deb
 -- entr_5.6-1.debian.tar.xz
 -- entr_5.6-1.dsc
 -- entr_5.6-1_amd64.buildinfo
 -- entr_5.6-1_amd64.changes
 -- entr_5.6-1_amd64.deb
 -- entr_5.6.orig.tar.xz
The contents of debian/entr are essentially what goes into the resulting entr_5.6-1_amd64.deb package. Familiarizing yourself with the majority of the files in the original upstream source as well as all the resulting build artifacts is time consuming, but it is a necessary investment to get high-quality Debian packages. There are also tools such as Debcraft that automate generating the build artifacts in separate output directories for each build, thus making it easy to compare the changes to correlate what change in the Debian packaging led to what change in the resulting build artifacts.

Re-run the initial import with git-buildpackage When upstreams publish releases as tarballs, they should also be imported for optimal software supply-chain security, in particular if upstream also publishes cryptographic signatures that can be used to verify the authenticity of the tarballs. To achieve this, the files debian/watch, debian/upstream/signing-key.asc, and debian/gbp.conf need to be present with the correct options. In the gbp.conf file, ensure you have the correct options based on:
  1. Does upstream release tarballs? If so, enforce pristine-tar = True.
  2. Does upstream sign the tarballs? If so, configure explicit signature checking with upstream-signatures = on.
  3. Does upstream have a git repository, and does it have release git tags? If so, configure the release git tag format, e.g. upstream-vcs-tag = %(version%~%.)s.
To validate that the above files are working correctly, run gbp import-orig with the current version explicitly defined:
shell
$ gbp import-orig --uscan --upstream-version 5.6
gbp:info: Launching uscan...
gpgv: Signature made 7. Aug 2024 07.43.27 PDT
gpgv: using RSA key 519151D83E83D40A232B4D615C418B8631BC7C26
gpgv: Good signature from "Eric Radman <ericshane@eradman.com>"
gbp:info: Using uscan downloaded tarball ../entr_5.6.orig.tar.gz
gbp:info: Importing '../entr_5.6.orig.tar.gz' to branch 'upstream/latest'...
gbp:info: Source package is entr
gbp:info: Upstream version is 5.6
gbp:info: Replacing upstream source on 'debian/latest'
gbp:info: Running Postimport hook
gbp:info: Successfully imported version 5.6 of ../entr_5.6.orig.tar.gz
As the original packaging was done based on the upstream release git tag, the above command will fetch the tarball release, create the pristine-tar branch, and store the tarball delta on it. This command will also attempt to create the tag upstream/5.6 on the upstream/latest branch.

Import new upstream versions in the future Forking the upstream git repository, creating the initial packaging, and creating the DEP-14 branch structure are all one-off work needed only when creating the initial packaging. Going forward, to import new upstream releases, one would simply run git fetch upstreamvcs; gbp import-orig --uscan, which fetches the upstream git tags, checks for new upstream tarballs, and automatically downloads, verifies, and imports the new version. See the galera-4-demo example in the Debian source packages in git explained post as a demo you can try running yourself and examine in detail. You can also try running gbp import-orig --uscan without specifying a version. It would fetch it, as it will notice there is now Entr version 5.7 available, and import it.

Build using git-buildpackage From this stage onwards you should build the package using gbp buildpackage, which will do a more comprehensive build.
shell
gbp buildpackage -uc -us
The git-buildpackage build also includes running Lintian to find potential Debian policy violations in the sources or in the resulting .deb binary packages. Many Debian Developers run lintian -EviIL +pedantic after every build to check that there are no new nags, and to validate that changes intended to previous Lintian nags were correct.

Open a Merge Request on Salsa for Debian packaging review Getting everything perfectly right takes a lot of effort, and may require reaching out to an experienced Debian Developers for review and guidance. Thus, you should aim to publish your initial packaging work on Salsa, Debian s GitLab instance, for review and feedback as early as possible. For somebody to be able to easily see what you have done, you should rename your debian/latest branch to another name, for example next/debian/latest, and open a Merge Request that targets the debian/latest branch on your Salsa fork, which still has only the unmodified upstream files. If you have followed the workflow in this post so far, you can simply run:
  1. git checkout -b next/debian/latest
  2. git push --set-upstream origin next/debian/latest
  3. Open in a browser the URL visible in the git remote response
  4. Write the Merge Request description in case the default text from your commit is not enough
  5. Mark the MR as Draft using the checkbox
  6. Publish the MR and request feedback
Once a Merge Request exists, discussion regarding what additional changes are needed can be conducted as MR comments. With an MR, you can easily iterate on the contents of next/debian/latest, rebase, force push, and request re-review as many times as you want. While at it, make sure the Settings > CI/CD page has under CI/CD configuration file the value debian/salsa-ci.yml so that the CI can run and give you immediate automated feedback. For an example of an initial packaging Merge Request, see https://salsa.debian.org/otto/entr-demo/-/merge_requests/1.

Open a Merge Request / Pull Request to fix upstream code Due to the high quality requirements in Debian, it is fairly common that while doing the initial Debian packaging of an open source project, issues are found that stem from the upstream source code. While it is possible to carry extra patches in Debian, it is not good practice to deviate too much from upstream code with custom Debian patches. Instead, the Debian packager should try to get the fixes applied directly upstream. Using git-buildpackage patch queues is the most convenient way to make modifications to the upstream source code so that they automatically convert into Debian patches (stored at debian/patches), and can also easily be submitted upstream as any regular git commit (and rebased and resubmitted many times over). First, decide if you want to work out of the upstream development branch and later cherry-pick to the Debian packaging branch, or work out of the Debian packaging branch and cherry-pick to an upstream branch. The example below starts from the upstream development branch and then cherry-picks the commit into the git-buildpackage patch queue:
shell
git checkout -b bugfix-branch master
nano entr.c
make
./entr # verify change works as expected
git commit -a -m "Commit title" -m "Commit body"
git push # submit upstream
gbp pq import --force --time-machine=10
git cherry-pick <commit id>
git commit --amend # extend commit message with DEP-3 metadata
gbp buildpackage -uc -us -b
./entr # verify change works as expected
gbp pq export --drop --commit
git commit --amend # Write commit message along lines "Add patch to .."
The example below starts by making the fix on a git-buildpackage patch queue branch, and then cherry-picking it onto the upstream development branch:
shell
gbp pq import --force --time-machine=10
nano entr.c
git commit -a -m "Commit title" -m "Commit body"
gbp buildpackage -uc -us -b
./entr # verify change works as expected
gbp pq export --drop --commit
git commit --amend # Write commit message along lines "Add patch to .."
git checkout -b bugfix-branch master
git cherry-pick <commit id>
git commit --amend # prepare commit message for upstream submission
git push # submit upstream
The key git-buildpackage commands to enter and exit the patch-queue mode are:
shell
gbp pq import --force --time-machine=10
gbp pq export --drop --commit
%% init:   'gitGraph':   'mainBranchName': 'debian/latest'      %%
gitGraph
checkout debian/latest
commit id: "Initial packaging"
branch patch-queue/debian/latest
checkout patch-queue/debian/latest
commit id: "Delete debian/patches/..."
commit id: "Patch 1 title"
commit id: "Patch 2 title"
commit id: "Patch 3 title"
These can be run at any time, regardless if any debian/patches existed prior, or if existing patches applied cleanly or not, or if there were old patch queue branches around. Note that the extra -b in gbp buildpackage -uc -us -b instructs to build only binary packages, avoiding any nags from dpkg-source that there are modifications in the upstream sources while building in the patches-applied mode.

Programming-language specific dh-make alternatives As each programming language has its specific way of building the source code, and many other conventions regarding the file layout and more, Debian has multiple custom tools to create new Debian source packages for specific programming languages. Notably, Python does not have its own tool, but there is an dh_make --python option for Python support directly in dh_make itself. The list is not complete and many more tools exist. For some languages, there are even competing options, such as for Go there is in addition to dh-make-golang also Gophian. When learning Debian packaging, there is no need to learn these tools upfront. Being aware that they exist is enough, and one can learn them only if and when one starts to package a project in a new programming language.

The difference between source git repository vs source packages vs binary packages As seen in earlier example, running gbp buildpackage on the Entr packaging repository above will result in several files:
entr_5.6-1_amd64.changes
entr_5.6-1_amd64.deb
entr_5.6-1.debian.tar.xz
entr_5.6-1.dsc
entr_5.6.orig.tar.gz
entr_5.6.orig.tar.gz.asc
The entr_5.6-1_amd64.deb is the binary package, which can be installed on a Debian/Ubuntu system. The rest of the files constitute the source package. To do a source-only build, run gbp buildpackage -S and note the files produced:
entr_5.6-1_source.changes
entr_5.6-1.debian.tar.xz
entr_5.6-1.dsc
entr_5.6.orig.tar.gz
entr_5.6.orig.tar.gz.asc
The source package files can be used to build the binary .deb for amd64, or any architecture that the package supports. It is important to grasp that the Debian source package is the preferred form to be able to build the binary packages on various Debian build systems, and the Debian source package is not the same thing as the Debian packaging git repository contents.
flowchart LR
git[Git repository<br>branch debian/latest] --> gbp buildpackage -S  src[Source Package<br>.dsc + .tar.xz]
src --> dpkg-buildpackage  bin[Binary Packages<br>.deb]
If the package is large and complex, the build could result in multiple binary packages. One set of package definition files in debian/ will however only ever result in a single source package.

Option to repackage source packages with Files-Excluded lists in the debian/copyright file Some upstream projects may include binary files in their release, or other undesirable content that needs to be omitted from the source package in Debian. The easiest way to filter them out is by adding to the debian/copyright file a Files-Excluded field listing the undesired files. The debian/copyright file is read by uscan, which will repackage the upstream sources on-the-fly when importing new upstream releases. For a real-life example, see the debian/copyright files in the Godot package that lists:
debian
Files-Excluded: platform/android/java/gradle/wrapper/gradle-wrapper.jar
The resulting repackaged upstream source tarball, as well as the upstream version component, will have an extra +ds to signify that it is not the true original upstream source but has been modified by Debian:
godot_4.3+ds.orig.tar.xz
godot_4.3+ds-1_amd64.deb

Creating one Debian source package from multiple upstream source packages also possible In some rare cases the upstream project may be split across multiple git repositories or the upstream release may consist of multiple components each in their own separate tarball. Usually these are very large projects that get some benefits from releasing components separately. If in Debian these are deemed to go into a single source package, it is technically possible using the component system in git-buildpackage and uscan. For an example see the gbp.conf and watch files in the node-cacache package. Using this type of structure should be a last resort, as it creates complexity and inter-dependencies that are bound to cause issues later on. It is usually better to work with upstream and champion universal best practices with clear releases and version schemes.

When not to start the Debian packaging repository as a fork of the upstream one Not all upstreams use Git for version control. It is by far the most popular, but there are still some that use e.g. Subversion or Mercurial. Who knows maybe in the future some new version control systems will start to compete with Git. There are also projects that use Git in massive monorepos and with complex submodule setups that invalidate the basic assumptions required to map an upstream Git repository into a Debian packaging repository. In those cases one can t use a debian/latest branch on a clone of the upstream git repository as the starting point for the Debian packaging, but one must revert the traditional way of starting from an upstream release tarball with gbp import-orig package-1.0.tar.gz.

Conclusion Created in August 1993, Debian is one of the oldest Linux distributions. In the 32 years since inception, the .deb packaging format and the tooling to work with it have evolved several generations. In the past 10 years, more and more Debian Developers have converged on certain core practices evidenced by https://trends.debian.net/, but there is still a lot of variance in workflows even for identical tasks. Hopefully, you find this post useful in giving practical guidance on how exactly to do the most common things when packaging software for Debian. Happy packaging!

25 May 2025

Iustin Pop: Corydalis v2025.21.0 - new features!

I just released yesterday a new version of Corydalis (https://demo.corydalis.io, https://github.com/iustin/corydalis). To me personally, it s a major improvement, since the native (my own) image viewer finally gets zooming, panning, gesture handling, etc. This is table-stakes for an image viewer, but oh well, it took me a long time to implement it, because of multiple things: lack of time, the JS library I was using for gestures was pretty old and unmaintained and it caused more trouble than was helping, etc. The feature is not perfect, and on the demo site there s already a bug since all images are smaller than the screen, and this I didn t test , so double-click to zoom doesn t work: says Already at minimum zoom , but zooming otherwise (+/- on the keyboard, mouse wheel, gesture) works. End-to-end, the major development for this release was done over around two weeks, which is pretty short: I extensively used Claude Sonnet and Grok to unblock myself. Not to write code per se - although there is code written 1:1 by LLMs, but most of the code is weirdly wrong, and I have to either correct it or just use it as a starter and rewrite most of it. But to discuss and unblock, and learn about new things, the current LLMs are very good at. And yet, sometimes even what they re good at, fails hard. I asked for ideas to simplify a piece of code, and it went nowhere, even if there were significant rewrite possibilities. I spent the brain cycles on it, reverse engineered my own code, then simplified. I ll have to write a separate blog post on this In any case, this (zooming) was the last major feature I was missing. There are image viewer libraries, but most of them slow, compared to the bare-bones (well, now not so much anymore) viewer that I use as main viewer. From now on, it will me minor incremental features, mostly around Exif management/handling, etc. Or, well, internal cleanups: extend test coverage, remove use of JQuery in the frontend, etc., there are tons of things to do. Fun fact: I managed to discover a Safari iOS bug. Or at least I think it s a bug, so reported it and curious what ll come out of it. Finally, I still couldn t fix the GitHub actions bug where the git describe doesn t see the just pushed tag, sigh, so the demo site still lists Corydalis v2024.12.0-133-g00edf63 as the version .

Otto Kek l inen: New Debian package creation from upstream git repository

Featured image of post New Debian package creation from upstream git repositoryIn this post, I demonstrate the optimal workflow for creating new Debian packages in 2025, preserving the upstream git history. The motivation for this is to lower the barrier for sharing improvements to and from upstream, and to improve software provenance and supply-chain security by making it easy to inspect every change at any level using standard git tooling. Key elements of this workflow include: To make the instructions so concrete that anyone can repeat all the steps themselves on a real package, I demonstrate the steps by packaging the command-line tool Entr. It is written in C, has very few dependencies, and its final Debian source package structure is simple, yet exemplifies all the important parts that go into a complete Debian package:
  1. Creating a new packaging repository and publishing it under your personal namespace on salsa.debian.org.
  2. Using dh_make to create the initial Debian packaging.
  3. Posting the first draft of the Debian packaging as a Merge Request (MR) and using Salsa CI to verify Debian packaging quality.
  4. Running local builds efficiently and iterating on the packaging process.

Create new Debian packaging repository from the existing upstream project git repository First, create a new empty directory, then clone the upstream Git repository inside it:
shell
mkdir debian-entr
cd debian-entr
git clone --origin upstreamvcs --branch master \
 --single-branch https://github.com/eradman/entr.git
Using a clean directory makes it easier to inspect the build artifacts of a Debian package, which will be output in the parent directory of the Debian source directory. The extra parameters given to git clone lay the foundation for the Debian packaging git repository structure where the upstream git remote name is upstreamvcs. Only the upstream main branch is tracked to avoid cluttering git history with upstream development branches that are irrelevant for packaging in Debian. Next, enter the git repository directory and list the git tags. Pick the latest upstream release tag as the commit to start the branch upstream/latest. This latest refers to the upstream release, not the upstream development branch. Immediately after, branch off the debian/latest branch, which will have the actual Debian packaging files in the debian/ subdirectory.
shell
cd entr
git tag # shows the latest upstream release tag was '5.6'
git checkout -b upstream/latest 5.6
git checkout -b debian/latest
%% init:   'gitGraph':   'mainBranchName': 'master'      %%
gitGraph:
checkout master
commit id: "Upstream 5.6 release" tag: "5.6"
branch upstream/latest
checkout upstream/latest
commit id: "New upstream version 5.6" tag: "upstream/5.6"
branch debian/latest
checkout debian/latest
commit id: "Initial Debian packaging"
commit id: "Additional change 1"
commit id: "Additional change 2"
commit id: "Additional change 3"
At this point, the repository is structured according to DEP-14 conventions, ensuring a clear separation between upstream and Debian packaging changes, but there are no Debian changes yet. Next, add the Salsa repository as a new remote which called origin, the same as the default remote name in git.
shell
git remote add origin git@salsa.debian.org:otto/entr-demo.git
git push --set-upstream origin debian/latest
This is an important preparation step to later be able to create a Merge Request on Salsa that targets the debian/latest branch, which does not yet have any debian/ directory.

Launch a Debian Sid (unstable) container to run builds in To ensure that all packaging tools are of the latest versions, run everything inside a fresh Sid container. This has two benefits: you are guaranteed to have the most up-to-date toolchain, and your host system stays clean without getting polluted by various extra packages. Additionally, this approach works even if your host system is not Debian/Ubuntu.
shell
cd ..
podman run --interactive --tty --rm --shm-size=1G --cap-add SYS_PTRACE \
 --env='DEB*' --volume=$PWD:/tmp/test --workdir=/tmp/test debian:sid bash
Note that the container should be started from the parent directory of the git repository, not inside it. The --volume parameter will loop-mount the current directory inside the container. Thus all files created and modified are on the host system, and will persist after the container shuts down. Once inside the container, install the basic dependencies:
shell
apt update -q && apt install -q --yes git-buildpackage dpkg-dev dh-make

Automate creating the debian/ files with dh-make To create the files needed for the actual Debian packaging, use dh_make:
shell
# dh_make --packagename entr_5.6 --single --createorig
Maintainer Name : Otto Kek l inen
Email-Address : otto@debian.org
Date : Sat, 15 Feb 2025 01:17:51 +0000
Package Name : entr
Version : 5.6
License : blank
Package Type : single
Are the details correct? [Y/n/q]

Done. Please edit the files in the debian/ subdirectory now.
Due to how dh_make works, the package name and version need to be written as a single underscore separated string. In this case, you should choose --single to specify that the package type is a single binary package. Other options would be --library for library packages (see libgda5 sources as an example) or --indep (see dns-root-data sources as an example). The --createorig will create a mock upstream release tarball (entr_5.6.orig.tar.xz) from the current release directory, which is necessary due to historical reasons and how dh_make worked before git repositories became common and Debian source packages were based off upstream release tarballs (e.g. *.tar.gz). At this stage, a debian/ directory has been created with template files, and you can start modifying the files and iterating towards actual working packaging.
shell
git add debian/
git commit -a -m "Initial Debian packaging"

Review the files The full list of files after the above steps with dh_make would be:
 -- entr
   -- LICENSE
   -- Makefile.bsd
   -- Makefile.linux
   -- Makefile.linux-compat
   -- Makefile.macos
   -- NEWS
   -- README.md
   -- configure
   -- data.h
   -- debian
     -- README.Debian
     -- README.source
     -- changelog
     -- control
     -- copyright
     -- gbp.conf
     -- entr-docs.docs
     -- entr.cron.d.ex
     -- entr.doc-base.ex
     -- manpage.1.ex
     -- manpage.md.ex
     -- manpage.sgml.ex
     -- manpage.xml.ex
     -- postinst.ex
     -- postrm.ex
     -- preinst.ex
     -- prerm.ex
     -- rules
     -- salsa-ci.yml.ex
     -- source
       -- format
     -- upstream
       -- metadata.ex
     -- watch.ex
   -- entr.1
   -- entr.c
   -- missing
     -- compat.h
     -- kqueue_inotify.c
     -- strlcpy.c
     -- sys
     -- event.h
   -- status.c
   -- status.h
   -- system_test.sh
 -- entr_5.6.orig.tar.xz
You can browse these files in the demo repository. The mandatory files in the debian/ directory are:
  • changelog,
  • control,
  • copyright,
  • and rules.
All the other files have been created for convenience so the packager has template files to work from. The files with the suffix .ex are example files that won t have any effect until their content is adjusted and the suffix removed. For detailed explanations of the purpose of each file in the debian/ subdirectory, see the following resources:
  • The Debian Policy Manual: Describes the structure of the operating system, the package archive and requirements for packages to be included in the Debian archive.
  • The Developer s Reference: A collection of best practices and process descriptions Debian packagers are expected to follow while interacting with one another.
  • Debhelper man pages: Detailed information of how the Debian package build system works, and how the contents of the various files in debian/ affect the end result.
As Entr, the package used in this example, is a real package that already exists in the Debian archive, you may want to browse the actual Debian packaging source at https://salsa.debian.org/debian/entr/-/tree/debian/latest/debian for reference. Most of these files have standardized formatting conventions to make collaboration easier. To automatically format the files following the most popular conventions, simply run wrap-and-sort -vast or debputy reformat --style=black.

Identify build dependencies The most common reason for builds to fail is missing dependencies. The easiest way to identify which Debian package ships the required dependency is using apt-file. If, for example, a build fails complaining that pcre2posix.h cannot be found or that libcre2-posix.so is missing, you can use these commands:
shell
$ apt install -q --yes apt-file && apt-file update
$ apt-file search pcre2posix.h
libpcre2-dev: /usr/include/pcre2posix.h
$ apt-file search libpcre2-posix.so
libpcre2-dev: /usr/lib/x86_64-linux-gnu/libpcre2-posix.so
libpcre2-posix3: /usr/lib/x86_64-linux-gnu/libpcre2-posix.so.3
libpcre2-posix3: /usr/lib/x86_64-linux-gnu/libpcre2-posix.so.3.0.6
The output above implies that the debian/control should be extended to define a Build-Depends: libpcre2-dev relationship. There is also dpkg-depcheck that uses strace to trace the files the build process tries to access, and lists what Debian packages those files belong to. Example usage:
shell
dpkg-depcheck -b debian/rules build

Build the Debian sources to generate the .deb package After the first pass of refining the contents of the files in debian/, test the build by running dpkg-buildpackage inside the container:
shell
dpkg-buildpackage -uc -us -b
The options -uc -us will skip signing the resulting Debian source package and other build artifacts. The -b option will skip creating a source package and only build the (binary) *.deb packages. The output is very verbose and gives a large amount of context about what is happening during the build to make debugging build failures easier. In the build log of entr you will see for example the line dh binary --buildsystem=makefile. This and other dh commands can also be run manually if there is a need to quickly repeat only a part of the build while debugging build failures. To see what files were generated or modified by the build simply run git status --ignored:
shell
$ git status --ignored
On branch debian/latest

Untracked files:
 (use "git add <file>..." to include in what will be committed)
 debian/debhelper-build-stamp
 debian/entr.debhelper.log
 debian/entr.substvars
 debian/files

Ignored files:
 (use "git add -f <file>..." to include in what will be committed)
 Makefile
 compat.c
 compat.o
 debian/.debhelper/
 debian/entr/
 entr
 entr.o
 status.o
Re-running dpkg-buildpackage will include running the command dh clean, which assuming it is configured correctly in the debian/rules file will reset the source directory to the original pristine state. The same can of course also be done with regular git commands git reset --hard; git clean -fdx. To avoid accidentally committing unnecessary build artifacts in git, a debian/.gitignore can be useful and it would typically include all four files listed as untracked above. After a successful build you would have the following files:
shell
 -- entr
   -- LICENSE
   -- Makefile -> Makefile.linux
   -- Makefile.bsd
   -- Makefile.linux
   -- Makefile.linux-compat
   -- Makefile.macos
   -- NEWS
   -- README.md
   -- compat.c
   -- compat.o
   -- configure
   -- data.h
   -- debian
     -- README.source.md
     -- changelog
     -- control
     -- copyright
     -- debhelper-build-stamp
     -- docs
     -- entr
       -- DEBIAN
         -- control
         -- md5sums
       -- usr
       -- bin
         -- entr
       -- share
       -- doc
         -- entr
         -- NEWS.gz
         -- README.md
         -- changelog.Debian.gz
         -- copyright
       -- man
       -- man1
       -- entr.1.gz
     -- entr.debhelper.log
     -- entr.substvars
     -- files
     -- gbp.conf
     -- patches
       -- PR149-expand-aliases-in-system-test-script.patch
       -- series
       -- system-test-skip-no-tty.patch
       -- system-test-with-system-binary.patch
     -- rules
     -- salsa-ci.yml
     -- source
       -- format
     -- tests
       -- control
     -- upstream
       -- metadata
       -- signing-key.asc
     -- watch
   -- entr
   -- entr.1
   -- entr.c
   -- entr.o
   -- missing
     -- compat.h
     -- kqueue_inotify.c
     -- strlcpy.c
     -- sys
     -- event.h
   -- status.c
   -- status.h
   -- status.o
   -- system_test.sh
 -- entr-dbgsym_5.6-1_amd64.deb
 -- entr_5.6-1.debian.tar.xz
 -- entr_5.6-1.dsc
 -- entr_5.6-1_amd64.buildinfo
 -- entr_5.6-1_amd64.changes
 -- entr_5.6-1_amd64.deb
 -- entr_5.6.orig.tar.xz
The contents of debian/entr are essentially what goes into the resulting entr_5.6-1_amd64.deb package. Familiarizing yourself with the majority of the files in the original upstream source as well as all the resulting build artifacts is time consuming, but it is a necessary investment to get high-quality Debian packages. There are also tools such as Debcraft that automate generating the build artifacts in separate output directories for each build, thus making it easy to compare the changes to correlate what change in the Debian packaging led to what change in the resulting build artifacts.

Re-run the initial import with git-buildpackage When upstreams publish releases as tarballs, they should also be imported for optimal software supply-chain security, in particular if upstream also publishes cryptographic signatures that can be used to verify the authenticity of the tarballs. To achieve this, the files debian/watch, debian/upstream/signing-key.asc, and debian/gbp.conf need to be present with the correct options. In the gbp.conf file, ensure you have the correct options based on:
  1. Does upstream release tarballs? If so, enforce pristine-tar = True.
  2. Does upstream sign the tarballs? If so, configure explicit signature checking with upstream-signatures = on.
  3. Does upstream have a git repository, and does it have release git tags? If so, configure the release git tag format, e.g. upstream-vcs-tag = %(version%~%.)s.
To validate that the above files are working correctly, run gbp import-orig with the current version explicitly defined:
shell
$ gbp import-orig --uscan --upstream-version 5.6
gbp:info: Launching uscan...
gpgv: Signature made 7. Aug 2024 07.43.27 PDT
gpgv: using RSA key 519151D83E83D40A232B4D615C418B8631BC7C26
gpgv: Good signature from "Eric Radman <ericshane@eradman.com>"
gbp:info: Using uscan downloaded tarball ../entr_5.6.orig.tar.gz
gbp:info: Importing '../entr_5.6.orig.tar.gz' to branch 'upstream/latest'...
gbp:info: Source package is entr
gbp:info: Upstream version is 5.6
gbp:info: Replacing upstream source on 'debian/latest'
gbp:info: Running Postimport hook
gbp:info: Successfully imported version 5.6 of ../entr_5.6.orig.tar.gz
As the original packaging was done based on the upstream release git tag, the above command will fetch the tarball release, create the pristine-tar branch, and store the tarball delta on it. This command will also attempt to create the tag upstream/5.6 on the upstream/latest branch.

Import new upstream versions in the future Forking the upstream git repository, creating the initial packaging, and creating the DEP-14 branch structure are all one-off work needed only when creating the initial packaging. Going forward, to import new upstream releases, one would simply run git fetch upstreamvcs; gbp import-orig --uscan, which fetches the upstream git tags, checks for new upstream tarballs, and automatically downloads, verifies, and imports the new version. See the galera-4-demo example in the Debian source packages in git explained post as a demo you can try running yourself and examine in detail. You can also try running gbp import-orig --uscan without specifying a version. It would fetch it, as it will notice there is now Entr version 5.7 available, and import it.

Build using git-buildpackage From this stage onwards you should build the package using gbp buildpackage, which will do a more comprehensive build.
shell
gbp buildpackage -uc -us
The git-buildpackage build also includes running Lintian to find potential Debian policy violations in the sources or in the resulting .deb binary packages. Many Debian Developers run lintian -EviIL +pedantic after every build to check that there are no new nags, and to validate that changes intended to previous Lintian nags were correct.

Open a Merge Request on Salsa for Debian packaging review Getting everything perfectly right takes a lot of effort, and may require reaching out to an experienced Debian Developers for review and guidance. Thus, you should aim to publish your initial packaging work on Salsa, Debian s GitLab instance, for review and feedback as early as possible. For somebody to be able to easily see what you have done, you should rename your debian/latest branch to another name, for example next/debian/latest, and open a Merge Request that targets the debian/latest branch on your Salsa fork, which still has only the unmodified upstream files. If you have followed the workflow in this post so far, you can simply run:
  1. git checkout -b next/debian/latest
  2. git push --set-upstream origin next/debian/latest
  3. Open in a browser the URL visible in the git remote response
  4. Write the Merge Request description in case the default text from your commit is not enough
  5. Mark the MR as Draft using the checkbox
  6. Publish the MR and request feedback
Once a Merge Request exists, discussion regarding what additional changes are needed can be conducted as MR comments. With an MR, you can easily iterate on the contents of next/debian/latest, rebase, force push, and request re-review as many times as you want. While at it, make sure the Settings > CI/CD page has under CI/CD configuration file the value debian/salsa-ci.yml so that the CI can run and give you immediate automated feedback. For an example of an initial packaging Merge Request, see https://salsa.debian.org/otto/entr-demo/-/merge_requests/1.

Open a Merge Request / Pull Request to fix upstream code Due to the high quality requirements in Debian, it is fairly common that while doing the initial Debian packaging of an open source project, issues are found that stem from the upstream source code. While it is possible to carry extra patches in Debian, it is not good practice to deviate too much from upstream code with custom Debian patches. Instead, the Debian packager should try to get the fixes applied directly upstream. Using git-buildpackage patch queues is the most convenient way to make modifications to the upstream source code so that they automatically convert into Debian patches (stored at debian/patches), and can also easily be submitted upstream as any regular git commit (and rebased and resubmitted many times over). First, decide if you want to work out of the upstream development branch and later cherry-pick to the Debian packaging branch, or work out of the Debian packaging branch and cherry-pick to an upstream branch. The example below starts from the upstream development branch and then cherry-picks the commit into the git-buildpackage patch queue:
shell
git checkout -b bugfix-branch master
nano entr.c
make
./entr # verify change works as expected
git commit -a -m "Commit title" -m "Commit body"
git push # submit upstream
gbp pq import --force --time-machine=10
git cherry-pick <commit id>
git commit --amend # extend commit message with DEP-3 metadata
gbp buildpackage -uc -us -b
./entr # verify change works as expected
gbp pq export --drop --commit
git commit --amend # Write commit message along lines "Add patch to .."
The example below starts by making the fix on a git-buildpackage patch queue branch, and then cherry-picking it onto the upstream development branch:
shell
gbp pq import --force --time-machine=10
nano entr.c
git commit -a -m "Commit title" -m "Commit body"
gbp buildpackage -uc -us -b
./entr # verify change works as expected
gbp pq export --drop --commit
git commit --amend # Write commit message along lines "Add patch to .."
git checkout -b bugfix-branch master
git cherry-pick <commit id>
git commit --amend # prepare commit message for upstream submission
git push # submit upstream
The key git-buildpackage commands to enter and exit the patch-queue mode are:
shell
gbp pq import --force --time-machine=10
gbp pq export --drop --commit
%% init:   'gitGraph':   'mainBranchName': 'debian/latest'      %%
gitGraph
checkout debian/latest
commit id: "Initial packaging"
branch patch-queue/debian/latest
checkout patch-queue/debian/latest
commit id: "Delete debian/patches/..."
commit id: "Patch 1 title"
commit id: "Patch 2 title"
commit id: "Patch 3 title"
These can be run at any time, regardless if any debian/patches existed prior, or if existing patches applied cleanly or not, or if there were old patch queue branches around. Note that the extra -b in gbp buildpackage -uc -us -b instructs to build only binary packages, avoiding any nags from dpkg-source that there are modifications in the upstream sources while building in the patches-applied mode.

Programming-language specific dh-make alternatives As each programming language has its specific way of building the source code, and many other conventions regarding the file layout and more, Debian has multiple custom tools to create new Debian source packages for specific programming languages. Notably, Python does not have its own tool, but there is an dh_make --python option for Python support directly in dh_make itself. The list is not complete and many more tools exist. For some languages, there are even competing options, such as for Go there is in addition to dh-make-golang also Gophian. When learning Debian packaging, there is no need to learn these tools upfront. Being aware that they exist is enough, and one can learn them only if and when one starts to package a project in a new programming language.

The difference between source git repository vs source packages vs binary packages As seen in earlier example, running gbp buildpackage on the Entr packaging repository above will result in several files:
entr_5.6-1_amd64.changes
entr_5.6-1_amd64.deb
entr_5.6-1.debian.tar.xz
entr_5.6-1.dsc
entr_5.6.orig.tar.gz
entr_5.6.orig.tar.gz.asc
The entr_5.6-1_amd64.deb is the binary package, which can be installed on a Debian/Ubuntu system. The rest of the files constitute the source package. To do a source-only build, run gbp buildpackage -S and note the files produced:
entr_5.6-1_source.changes
entr_5.6-1.debian.tar.xz
entr_5.6-1.dsc
entr_5.6.orig.tar.gz
entr_5.6.orig.tar.gz.asc
The source package files can be used to build the binary .deb for amd64, or any architecture that the package supports. It is important to grasp that the Debian source package is the preferred form to be able to build the binary packages on various Debian build systems, and the Debian source package is not the same thing as the Debian packaging git repository contents.
flowchart LR
git[Git repository<br>branch debian/latest] --> gbp buildpackage -S  src[Source Package<br>.dsc + .tar.xz]
src --> dpkg-buildpackage  bin[Binary Packages<br>.deb]
If the package is large and complex, the build could result in multiple binary packages. One set of package definition files in debian/ will however only ever result in a single source package.

Option to repackage source packages with Files-Excluded lists in the debian/copyright file Some upstream projects may include binary files in their release, or other undesirable content that needs to be omitted from the source package in Debian. The easiest way to filter them out is by adding to the debian/copyright file a Files-Excluded field listing the undesired files. The debian/copyright file is read by uscan, which will repackage the upstream sources on-the-fly when importing new upstream releases. For a real-life example, see the debian/copyright files in the Godot package that lists:
debian
Files-Excluded: platform/android/java/gradle/wrapper/gradle-wrapper.jar
The resulting repackaged upstream source tarball, as well as the upstream version component, will have an extra +ds to signify that it is not the true original upstream source but has been modified by Debian:
godot_4.3+ds.orig.tar.xz
godot_4.3+ds-1_amd64.deb

Creating one Debian source package from multiple upstream source packages also possible In some rare cases the upstream project may be split across multiple git repositories or the upstream release may consist of multiple components each in their own separate tarball. Usually these are very large projects that get some benefits from releasing components separately. If in Debian these are deemed to go into a single source package, it is technically possible using the component system in git-buildpackage and uscan. For an example see the gbp.conf and watch files in the node-cacache package. Using this type of structure should be a last resort, as it creates complexity and inter-dependencies that are bound to cause issues later on. It is usually better to work with upstream and champion universal best practices with clear releases and version schemes.

When not to start the Debian packaging repository as a fork of the upstream one Not all upstreams use Git for version control. It is by far the most popular, but there are still some that use e.g. Subversion or Mercurial. Who knows maybe in the future some new version control systems will start to compete with Git. There are also projects that use Git in massive monorepos and with complex submodule setups that invalidate the basic assumptions required to map an upstream Git repository into a Debian packaging repository. In those cases one can t use a debian/latest branch on a clone of the upstream git repository as the starting point for the Debian packaging, but one must revert the traditional way of starting from an upstream release tarball with gbp import-orig package-1.0.tar.gz.

Conclusion Created in August 1993, Debian is one of the oldest Linux distributions. In the 32 years since inception, the .deb packaging format and the tooling to work with it have evolved several generations. In the past 10 years, more and more Debian Developers have converged on certain core practices evidenced by https://trends.debian.net/, but there is still a lot of variance in workflows even for identical tasks. Hopefully, you find this post useful in giving practical guidance on how exactly to do the most common things when packaging software for Debian. Happy packaging!

22 May 2025

Dirk Eddelbuettel: RcppArmadillo 14.4.3-1 on CRAN: Small Upstream Bug Fix

armadillo image Armadillo is a powerful and expressive C++ template library for linear algebra and scientific computing. It aims towards a good balance between speed and ease of use, has a syntax deliberately close to Matlab, and is useful for algorithm development directly in C++, or quick conversion of research code into production environments. RcppArmadillo integrates this library with the R environment and language and is widely used by (currently) 1251 other packages on CRAN, downloaded 39.8 million times (per the partial logs from the cloud mirrors of CRAN), and the CSDA paper (preprint / vignette) by Conrad and myself has been cited 628 times according to Google Scholar. Conrad released a minor bugfix version yesterday which addresses corner cases with non-finite values in sparse matrices. And despite conference traveling, I managed to wrap this up and ship it to CRAN where it appeared yesterday. The changes since the last CRAN release are summarised below.

Changes in RcppArmadillo version 14.4.3-1 (2025-05-21)
  • Upgraded to Armadillo release 14.4.3 (Filtered Espresso)
    • Fix for several corner cases involving handling of non-finite elements by sparse matrices

Courtesy of my CRANberries, there is a diffstat report relative to previous release. More detailed information is on the RcppArmadillo page. Questions, comments etc should go to the rcpp-devel mailing list off the Rcpp R-Forge page.

This post by Dirk Eddelbuettel originated on his Thinking inside the box blog. If you like this or other open-source work I do, you can sponsor me at GitHub.

19 May 2025

Melissa Wen: A Look at the Latest Linux KMS Color API Developments on AMD and Intel

This week, I reviewed the last available version of the Linux KMS Color API. Specifically, I explored the proposed API by Harry Wentland and Alex Hung (AMD), their implementation for the AMD display driver and tracked the parallel efforts of Uma Shankar and Chaitanya Kumar Borah (Intel) in bringing this plane color management to life. With this API in place, compositors will be able to provide better HDR support and advanced color management for Linux users. To get a hands-on feel for the API s potential, I developed a fork of drm_info compatible with the new color properties. This allowed me to visualize the display hardware color management capabilities being exposed. If you re curious and want to peek behind the curtain, you can find my exploratory work on the drm_info/kms_color branch. The README there will guide you through the simple compilation and installation process. Note: You will need to update libdrm to match the proposed API. You can find an updated version in my personal repository here. To avoid potential conflicts with your official libdrm installation, you can compile and install it in a local directory. Then, use the following command: export LD_LIBRARY_PATH="/usr/local/lib/" In this post, I invite you to familiarize yourself with the new API that is about to be released. You can start doing as I did below: just deploy a custom kernel with the necessary patches and visualize the interface with the help of drm_info. Or, better yet, if you are a userspace developer, you can start developing user cases by experimenting with it. The more eyes the better.

KMS Color API on AMD The great news is that AMD s driver implementation for plane color operations is being developed right alongside their Linux KMS Color API proposal, so it s easy to apply to your kernel branch and check it out. You can find details of their progress in the AMD s series. I just needed to compile a custom kernel with this series applied, intentionally leaving out the AMD_PRIVATE_COLOR flag. The AMD_PRIVATE_COLOR flag guards driver-specific color plane properties, which experimentally expose hardware capabilities while we don t have the generic KMS plane color management interface available. If you don t know or don t remember the details of AMD driver specific color properties, you can learn more about this work in my blog posts [1] [2] [3]. As driver-specific color properties and KMS colorops are redundant, the driver only advertises one of them, as you can see in AMD workaround patch 24. So, with the custom kernel image ready, I installed it on a system powered by AMD DCN3 hardware (i.e. my Steam Deck). Using my custom drm_info, I could clearly see the Plane Color Pipeline with eight color operations as below:
 "COLOR_PIPELINE" (atomic): enum  Bypass, Color Pipeline 258  = Bypass
     Bypass
     Color Pipeline 258
         Color Operation 258
             "TYPE" (immutable): enum  1D Curve, 1D LUT, 3x4 Matrix, Multiplier, 3D LUT  = 1D Curve
             "BYPASS" (atomic): range [0, 1] = 1
             "CURVE_1D_TYPE" (atomic): enum  sRGB EOTF, PQ 125 EOTF, BT.2020 Inverse OETF  = sRGB EOTF
         Color Operation 263
             "TYPE" (immutable): enum  1D Curve, 1D LUT, 3x4 Matrix, Multiplier, 3D LUT  = Multiplier
             "BYPASS" (atomic): range [0, 1] = 1
             "MULTIPLIER" (atomic): range [0, UINT64_MAX] = 0
         Color Operation 268
             "TYPE" (immutable): enum  1D Curve, 1D LUT, 3x4 Matrix, Multiplier, 3D LUT  = 3x4 Matrix
             "BYPASS" (atomic): range [0, 1] = 1
             "DATA" (atomic): blob = 0
         Color Operation 273
             "TYPE" (immutable): enum  1D Curve, 1D LUT, 3x4 Matrix, Multiplier, 3D LUT  = 1D Curve
             "BYPASS" (atomic): range [0, 1] = 1
             "CURVE_1D_TYPE" (atomic): enum  sRGB Inverse EOTF, PQ 125 Inverse EOTF, BT.2020 OETF  = sRGB Inverse EOTF
         Color Operation 278
             "TYPE" (immutable): enum  1D Curve, 1D LUT, 3x4 Matrix, Multiplier, 3D LUT  = 1D LUT
             "BYPASS" (atomic): range [0, 1] = 1
             "SIZE" (atomic, immutable): range [0, UINT32_MAX] = 4096
             "LUT1D_INTERPOLATION" (immutable): enum  Linear  = Linear
             "DATA" (atomic): blob = 0
         Color Operation 285
             "TYPE" (immutable): enum  1D Curve, 1D LUT, 3x4 Matrix, Multiplier, 3D LUT  = 3D LUT
             "BYPASS" (atomic): range [0, 1] = 1
             "SIZE" (atomic, immutable): range [0, UINT32_MAX] = 17
             "LUT3D_INTERPOLATION" (immutable): enum  Tetrahedral  = Tetrahedral
             "DATA" (atomic): blob = 0
         Color Operation 292
             "TYPE" (immutable): enum  1D Curve, 1D LUT, 3x4 Matrix, Multiplier, 3D LUT  = 1D Curve
             "BYPASS" (atomic): range [0, 1] = 1
             "CURVE_1D_TYPE" (atomic): enum  sRGB EOTF, PQ 125 EOTF, BT.2020 Inverse OETF  = sRGB EOTF
         Color Operation 297
             "TYPE" (immutable): enum  1D Curve, 1D LUT, 3x4 Matrix, Multiplier, 3D LUT  = 1D LUT
             "BYPASS" (atomic): range [0, 1] = 1
             "SIZE" (atomic, immutable): range [0, UINT32_MAX] = 4096
             "LUT1D_INTERPOLATION" (immutable): enum  Linear  = Linear
             "DATA" (atomic): blob = 0
Note that Gamescope is currently using AMD driver-specific color properties implemented by me, Autumn Ashton and Harry Wentland. It doesn t use this KMS Color API, and therefore COLOR_PIPELINE is set to Bypass. Once the API is accepted upstream, all users of the driver-specific API (including Gamescope) should switch to the KMS generic API, as this will be the official plane color management interface of the Linux kernel.

KMS Color API on Intel On the Intel side, the driver implementation available upstream was built upon an earlier iteration of the API. This meant I had to apply a few tweaks to bring it in line with the latest specifications. You can explore their latest work here. For a more simplified handling, combining the V9 of the Linux Color API, Intel s contributions, and my necessary adjustments, check out my dedicated branch. I then compiled a kernel from this integrated branch and deployed it on a system featuring Intel TigerLake GT2 graphics. Running my custom drm_info revealed a Plane Color Pipeline with three color operations as follows:
 "COLOR_PIPELINE" (atomic): enum  Bypass, Color Pipeline 480  = Bypass
     Bypass
     Color Pipeline 480
         Color Operation 480
             "TYPE" (immutable): enum  1D Curve, 1D LUT, 3x4 Matrix, 1D LUT Mult Seg, 3x3 Matrix, Multiplier, 3D LUT  = 1D LUT Mult Seg
             "BYPASS" (atomic): range [0, 1] = 1
             "HW_CAPS" (atomic, immutable): blob = 484
             "DATA" (atomic): blob = 0
         Color Operation 487
             "TYPE" (immutable): enum  1D Curve, 1D LUT, 3x4 Matrix, 1D LUT Mult Seg, 3x3 Matrix, Multiplier, 3D LUT  = 3x3 Matrix
             "BYPASS" (atomic): range [0, 1] = 1
             "DATA" (atomic): blob = 0
         Color Operation 492
             "TYPE" (immutable): enum  1D Curve, 1D LUT, 3x4 Matrix, 1D LUT Mult Seg, 3x3 Matrix, Multiplier, 3D LUT  = 1D LUT Mult Seg
             "BYPASS" (atomic): range [0, 1] = 1
             "HW_CAPS" (atomic, immutable): blob = 496
             "DATA" (atomic): blob = 0
Observe that Intel s approach introduces additional properties like HW_CAPS at the color operation level, along with two new color operation types: 1D LUT with Multiple Segments and 3x3 Matrix. It s important to remember that this implementation is based on an earlier stage of the KMS Color API and is awaiting review.

A Shout-Out to Those Who Made This Happen I m impressed by the solid implementation and clear direction of the V9 of the KMS Color API. It aligns with the many insightful discussions we ve had over the past years. A huge thank you to Harry Wentland and Alex Hung for their dedication in bringing this to fruition! Beyond their efforts, I deeply appreciate Uma and Chaitanya s commitment to updating Intel s driver implementation to align with the freshest version of the KMS Color API. The collaborative spirit of the AMD and Intel developers in sharing their color pipeline work upstream is invaluable. We re now gaining a much clearer picture of the color capabilities embedded in modern display hardware, all thanks to their hard work, comprehensive documentation, and engaging discussions. Finally, thanks all the userspace developers, color science experts, and kernel developers from various vendors who actively participate in the upstream discussions, meetings, workshops, each iteration of this API and the crucial code review process. I m happy to be part of the final stages of this long kernel journey, but I know that when it comes to colors, one step is completed for new challenges to be unlocked. Looking forward to meeting you in this year Linux Display Next hackfest, organized by AMD in Toronto, to further discuss HDR, advanced color management, and other display trends.

13 May 2025

Ben Hutchings: Report for Debian BSP near Leuven in April 2025

On 26th and 27th April we held a Debian bug-squashing party near Leuven, Belgium. Several longstanding and new Debian contributors gathered to work through some of the highest priority bugs affecting the upcoming release of Debian 13 trixie . We were hosted by the Familia community centre in Tildonk. As this venue currently does not have an Internet connection, we brought a mobile hotspot and a local Debian mirror. In attendance were: The new contributors were variously using Arch, Fedora, and Ubuntu, and the DDs spent some some time setting them up with Debian dvelopment environments. The bugs we worked on included:
12 May 2025

Reproducible Builds: Reproducible Builds in April 2025

Welcome to our fourth report from the Reproducible Builds project in 2025. These monthly reports outline what we ve been up to over the past month, and highlight items of news from elsewhere in the increasingly-important area of software supply-chain security. Lastly, if you are interested in contributing to the Reproducible Builds project, please visit our Contribute page on our website. Table of contents:
  1. reproduce.debian.net
  2. Fifty Years of Open Source Software Supply Chain Security
  3. 4th CHAINS Software Supply Chain Workshop
  4. Mailing list updates
  5. Canonicalization for Unreproducible Builds in Java
  6. OSS Rebuild adds new TUI features
  7. Distribution roundup
  8. diffoscope & strip-nondeterminism
  9. Website updates
  10. Reproducibility testing framework
  11. Upstream patches

reproduce.debian.net The last few months have seen the introduction, development and deployment of reproduce.debian.net. In technical terms, this is an instance of rebuilderd, our server designed monitor the official package repositories of Linux distributions and attempt to reproduce the observed results there. This month, however, we are pleased to announce that reproduce.debian.net now tests all the Debian trixie architectures except s390x and mips64el. The ppc64el architecture was added through the generous support of Oregon State University Open Source Laboratory (OSUOSL), and we can support the armel architecture thanks to CodeThink.

Fifty Years of Open Source Software Supply Chain Security Russ Cox has published a must-read article in ACM Queue on Fifty Years of Open Source Software Supply Chain Security. Subtitled, For decades, software reuse was only a lofty goal. Now it s very real. , Russ article goes on to outline the history and original goals of software supply-chain security in the US military in the early 1970s, all the way to the XZ Utils backdoor of 2024. Through that lens, Russ explores the problem and how it has changed, and hasn t changed, over time. He concludes as follows:
We are all struggling with a massive shift that has happened in the past 10 or 20 years in the software industry. For decades, software reuse was only a lofty goal. Now it s very real. Modern programming environments such as Go, Node and Rust have made it trivial to reuse work by others, but our instincts about responsible behaviors have not yet adapted to this new reality. We all have more work to do.

4th CHAINS Software Supply Chain Workshop Convened as part of the CHAINS research project at the KTH Royal Institute of Technology in Stockholm, Sweden, the 4th CHAINS Software Supply Chain Workshop occurred during April. During the workshop, there were a number of relevant workshops, including: The full listing of the agenda is available on the workshop s website.

Mailing list updates On our mailing list this month:
  • Luca DiMaio of Chainguard posted to the list reporting that they had successfully implemented reproducible filesystem images with both ext4 and an EFI system partition. They go on to list the various methods, and the thread generated at least fifteen replies.
  • David Wheeler announced that the OpenSSF is building a glossary of sorts in order that they consistently use the same meaning for the same term and, moreover, that they have drafted a definition for reproducible build . The thread generated a significant number of replies on the definition, leading to a potential update to the Reproducible Build s own definition.
  • Lastly, kpcyrd posted to the list with a timely reminder and update on their repro-env tool. As first reported in our July 2023 report, kpcyrd mentions that:
    My initial interest in reproducible builds was how do I distribute pre-compiled binaries on GitHub without people raising security concerns about them . I ve cycled back to this original problem about 5 years later and built a tool that is meant to address this. [ ]

Canonicalization for Unreproducible Builds in Java Aman Sharma, Benoit Baudry and Martin Monperrus have published a new scholarly study related to reproducible builds within Java. Titled Canonicalization for Unreproducible Builds in Java, the article s abstract is as follows:
[ ] Achieving reproducibility at scale remains difficult, especially in Java, due to a range of non-deterministic factors and caveats in the build process. In this work, we focus on reproducibility in Java-based software, archetypal of enterprise applications. We introduce a conceptual framework for reproducible builds, we analyze a large dataset from Reproducible Central and we develop a novel taxonomy of six root causes of unreproducibility. We study actionable mitigations: artifact and bytecode canonicalization using OSS-Rebuild and jNorm respectively. Finally, we present Chains-Rebuild, a tool that raises reproducibility success from 9.48% to 26.89% on 12,283 unreproducible artifacts. To sum up, our contributions are the first large-scale taxonomy of build unreproducibility causes in Java, a publicly available dataset of unreproducible builds, and Chains-Rebuild, a canonicalization tool for mitigating unreproducible builds in Java.
A full PDF of their article is available from arXiv.

OSS Rebuild adds new TUI features OSS Rebuild aims to automate rebuilding upstream language packages (e.g. from PyPI, crates.io and npm registries) and publish signed attestations and build definitions for public use. OSS Rebuild ships a text-based user interface (TUI) for viewing, launching, and debugging rebuilds. While previously requiring ownership of a full instance of OSS Rebuild s hosted infrastructure, the TUI now supports a fully local mode of build execution and artifact storage. Thanks to Giacomo Benedetti for his usage feedback and work to extend the local-only development toolkit. Another feature added to the TUI was an experimental chatbot integration that provides interactive feedback on rebuild failure root causes and suggests fixes.

Distribution roundup In Debian this month:
  • Roland Clobus posted another status report on reproducible ISO images on our mailing list this month, with the summary that all live images build reproducibly from the online Debian archive .
  • Debian developer Simon Josefsson published another two reproducibility-related blog posts this month, the first on the topic of Verified Reproducible Tarballs. Simon sardonically challenges the reader as follows: Do you want a supply-chain challenge for the Easter weekend? Pick some well-known software and try to re-create the official release tarballs from the corresponding Git checkout. Is anyone able to reproduce anything these days? After that, they also published a blog post on Building Debian in a GitLab Pipeline using their multi-stage rebuild approach.
  • Roland also posted to our mailing list to highlight that there is now another tool in Debian that generates reproducible output, equivs . This is a tool to create trivial Debian packages that might Depend on other packages. As Roland writes, building the [equivs] package has been reproducible for a while, [but] now the output of the [tool] has become reproducible as well .
  • Lastly, 9 reviews of Debian packages were added, 10 were updated and 10 were removed this month adding to our extensive knowledge about identified issues.
The IzzyOnDroid Android APK repository made more progress in April. Thanks to funding by NLnet and Mobifree, the project was also to put more time into their tooling. For instance, developers can now easily run their own verification builder in less than 5 minutes . This currently supports Debian-based systems, but support for RPM-based systems is incoming.
  • The rbuilder_setup tool can now setup the entire framework within less than five minutes. The process is configurable, too, so everything from just the basics to verify builds up to a fully-fledged RB environment is also possible.
  • This tool works on Debian, RedHat and Arch Linux, as well as their derivates. The project has received successful reports from Debian, Ubuntu, Fedora and some Arch Linux derivates so far.
  • Documentation on how to work with reproducible builds (making apps reproducible, debugging unreproducible packages, etc) is available in the project s wiki page.
  • Future work is also in the pipeline, including documentation, guidelines and helpers for debugging.
NixOS defined an Outreachy project for improving build reproducibility. In the application phase, NixOS saw some strong candidates providing contributions, both on the NixOS side and upstream: guider-le-ecit analyzed a libpinyin issue. Tessy James fixed an issue in arandr and helped analyze one in libvlc that led to a proposed upstream fix. Finally, 3pleX fixed an issue which was accepted in upstream kitty, one in upstream maturin, one in upstream python-sip and one in the Nix packaging of python-libbytesize. Sadly, the funding for this internship fell through, so NixOS were forced to abandon their search. Lastly, in openSUSE news, Bernhard M. Wiedemann posted another monthly update for their work there.

diffoscope & strip-nondeterminism diffoscope is our in-depth and content-aware diff utility that can locate and diagnose reproducibility issues. This month, Chris Lamb made the following changes, including preparing and uploading a number of versions to Debian:
  • Use the --walk argument over the potentially dangerous alternative --scan when calling out to zipdetails(1). [ ]
  • Correct a longstanding issue where many >-based version tests used in conditional fixtures were broken. This was used to ensure that specific tests were only run when the version on the system was newer than a particular number. Thanks to Colin Watson for the report (Debian bug #1102658) [ ]
  • Address a long-hidden issue in the test_versions testsuite as well, where we weren t actually testing the greater-than comparisons mentioned above, as it was masked by the tests for equality. [ ]
  • Update copyright years. [ ]
In strip-nondeterminism, however, Holger Levsen updated the Continuous Integration (CI) configuration in order to use the standard Debian pipelines via debian/salsa-ci.yml instead of using .gitlab-ci.yml. [ ]

Website updates Once again, there were a number of improvements made to our website this month including:
  • Aman Sharma added OSS-Rebuild s stabilize tool to the Tools page. [ ][ ]
  • Chris Lamb added a configure.ac (GNU Autotools) example for using SOURCE_DATE_EPOCH. [ ]. Chris also updated the SOURCE_DATE_EPOCH snippet and move the archive metadata to a more suitable location. [ ]
  • Denis Carikli added GNU Boot to our ever-evolving Projects page.

Reproducibility testing framework The Reproducible Builds project operates a comprehensive testing framework running primarily at tests.reproducible-builds.org in order to check packages and other artifacts for reproducibility. In April, a number of changes were made by Holger Levsen, including:
  • reproduce.debian.net-related:
    • Add armel.reproduce.debian.net to support the armel architecture. [ ][ ]
    • Add a new ARM node, codethink05. [ ][ ]
    • Add ppc64el.reproduce.debian.net to support testing of the ppc64el architecture. [ ][ ][ ]
    • Improve the reproduce.debian.net front page. [ ][ ]
    • Make various changes to the ppc64el nodes. [ ][ ]9[ ][ ]
    • Make various changes to the arm64 and armhf nodes. [ ][ ][ ][ ]
    • Various changes related to the rebuilderd-worker entry point. [ ][ ][ ]
    • Create and deploy a pkgsync script. [ ][ ][ ][ ][ ][ ][ ][ ]
    • Fix the monitoring of the riscv64 architecture. [ ][ ]
    • Make a number of changes related to starting the rebuilderd service. [ ][ ][ ][ ]
  • Backup-related:
    • Backup the rebuilder databases every week. [ ][ ][ ][ ]
    • Improve the node health checks. [ ][ ]
  • Misc:
    • Re-use existing connections to the SSH proxy node on the riscv64 nodes. [ ][ ]
    • Node maintenance. [ ][ ][ ]
In addition:
  • Jochen Sprickerhof fixed the risvc64 host names [ ] and requested access to all the rebuilderd nodes [ ].
  • Mattia Rizzolo updated the self-serve rebuild scheduling tool, replacing the deprecated SSO -style authentication with OpenIDC which authenticates against salsa.debian.org. [ ][ ][ ]
  • Roland Clobus updated the configuration for the osuosl3 node to designate 4 workers for bigger builds. [ ]

Upstream patches The Reproducible Builds project detects, dissects and attempts to fix as many currently-unreproducible packages as possible. We endeavour to send all of our patches upstream where appropriate. This month, we wrote a large number of such patches, including:

Finally, if you are interested in contributing to the Reproducible Builds project, please visit our Contribute page on our website. However, you can get in touch with us via:

11 May 2025

Bits from Debian: Bits from the DPL

Dear Debian community, This is bits from the DPL for April. End of 10 I am sure I was speaking in the interest of the whole project when joining the "End of 10" campaign. Here is what I wrote to the initiators:
Hi Joseph and all drivers of the "End of 10" campaign, On behalf of the entire Debian project, I would like to say that we proudly join your great campaign. We stand with you in promoting Free Software, defending users' freedoms, and protecting our planet by avoiding unnecessary hardware waste. Thank you for leading this important initiative.
Andreas Tille Debian Project Leader
I have some goals I would like to share with you for my second term. Ftpmaster delegation This splits up into tasks that can be done before and after Trixie release. Before Trixie: 1. Reducing Barriers to DFSG Compliance Checks Back in 2002, Debian established a way to distribute cryptographic software in the main archive, whereas such software had previously been restricted to the non-US archive. One result of this arrangement which influences our workflow is that all packages uploaded to the NEW queue must remain on the server that hosts it. This requirement means that members of the ftpmaster team must log in to that specific machine, where they are limited to a restricted set of tools for reviewing uploaded code. This setup may act as a barrier to participation--particularly for contributors who might otherwise assist with reviewing packages for DFSG compliance. I believe it is time to reassess this limitation and work toward removing such hurdles. In October last year, we had some initial contact with SPI's legal counsel, who noted that US regulations around cryptography have been relaxed somewhat in recent years (as of 2021). This suggests it may now be possible to revisit and potentially revise the conditions under which we manage cryptographic software in the NEW queue. I plan to investigate this further. If you have expertise in software or export control law and are interested in helping with this topic, please get in touch with me. The ultimate goal is to make it easier for more people to contribute to ensuring that code in the NEW queue complies with the DFSG. 2. Discussing Alternatives My chances to reach out to other distributions remained limited. However, regarding the processing of new software, I learned that OpenSUSE uses a Git-based workflow that requires five "LGTM" approvals from a group of trusted developers. As far as I know, Fedora follows a similar approach. Inspired by this, a recent community initiative--the Gateway to NEW project--enables peer review of new packages for DFSG compliance before they enter the NEW queue. This effort allows anyone to contribute by reviewing packages and flagging potential issues in advance via Git. I particularly appreciate that the DFSG review is coupled with CI, allowing for both license and technical evaluation. While this process currently results in some duplication of work--since final reviews are still performed by the ftpmaster team--it offers a valuable opportunity to catch issues early and improve the overall quality of uploads. If the community sees long-term value in this approach, it could serve as a basis for evolving our workflows. Integrating it more closely into DAK could streamline the process, and we've recently seen that merge requests reflecting community suggestions can be accepted promptly. For now, I would like to gather opinions about how such initiatives could best complement the current NEW processing, and whether greater consensus on trusted peer review could help reduce the burden on the team doing DFSG compliance checks. Submitting packages for review and automated testing before uploading can improve quality and encourage broader participation in safeguarding Debian's Free Software principles. My explicit thanks go out to the Gateway to NEW team for their valuable and forward-looking contribution to Debian. 3. Documenting Critical Workflows Past ftpmaster trainees have told me that understanding the full set of ftpmaster workflows can be quite difficult. While there is some useful documentation thanks in particular to Sean Whitton for his work on documenting NEW processing rules many other important tasks carried out by the ftpmaster team remain undocumented or only partially so. Comprehensive and accessible documentation would greatly benefit current and future team members, especially those onboarding or assisting in specific workflows. It would also help ensure continuity and transparency in how critical parts of the archive are managed. If such documentation already exists and I have simply overlooked it, I would be happy to be corrected. Otherwise, I believe this is an area where we need to improve significantly. Volunteers with a talent for writing technical documentation are warmly invited to contact me--I'd be happy to help establish connections with ftpmaster team members who are willing to share their knowledge so that it can be written down and preserved. Once Trixie is released (hopefully before DebConf): 4. Split of the Ftpmaster Team into DFSG and Archive Teams As discussed during the "Meet the ftpteam" BoF at DebConf24, I would like to propose a structural refinement of the current Ftpmaster team by introducing two different delegated teams:
  1. DFSG Team
  2. Archive Team (responsible for DAK maintenance and process tooling, including releases)
(Alternative name suggestions are, of course, welcome.) The primary task of the DFSG team would be the processing of the NEW queue and ensuring that packages comply with the DFSG. The Archive team would focus on maintaining DAK and handling the technical aspects of archive management. I am aware that, in the recent past, the ftpmaster team has decided not to actively seek new members. While I respect the autonomy of each team, the resulting lack of a recruitment pipeline has led to some friction and concern within the wider community, including myself. As Debian Project Leader, it is my responsibility to ensure the long-term sustainability and resilience of our project, which includes fostering an environment where new contributors can join and existing teams remain effective and well-supported. Therefore, even if the current team does not prioritize recruitment, I will actively seek and encourage new contributors for both teams, with the aim of supporting openness and collaboration. This proposal is not intended as criticism of the current team's dedication or achievements--on the contrary, I am grateful for the hard work and commitment shown, often under challenging circumstances. My intention is to help address the structural issues that have made onboarding and specialization difficult and to ensure that both teams are well-supported for the future. I also believe that both teams should regularly inform the Debian community about the policies and procedures they apply. I welcome any suggestions for a more detailed description of the tasks involved, as well as feedback on how best to implement this change in a way that supports collaboration and transparency. My intention with this proposal is to foster a more open and effective working environment, and I am committed to working with all involved to ensure that any changes are made collaboratively and with respect for the important work already being done. I'm aware that the ideas outlined above touch on core parts of how Debian operates and involve responsibilities across multiple teams. These are not small changes, and implementing them will require thoughtful discussion and collaboration. To move this forward, I've registered a dedicated BoF for DebConf. To make the most of that opportunity, I'm looking for volunteers who feel committed to improving our workflows and processes. With your help, we can prepare concrete and sensible proposals in advance--so the limited time of the BoF can be used effectively for decision-making and consensus-building. In short: I need your help to bring these changes to life. From my experience in my last term, I know that when it truly matters, the Debian community comes together--and I trust that spirit will guide us again. Please also note: we had a "Call for volunteers" five years ago, and much of what was written there still holds true today. I've been told that the response back then was overwhelming--but that training such a large number of volunteers didn't scale well. This time, I hope we can find a more sustainable approach: training a few dedicated people first, and then enabling them to pass on their knowledge. This will also be a topic at the DebCamp sprint. Dealing with Dormant Packages Debian was founded on the principle that each piece of software should be maintained by someone with expertise in it--typically a single, responsible maintainer. This model formed the historical foundation of Debian's packaging system and helped establish high standards of quality and accountability. However, as the project has grown and the number of packages has expanded, this model no longer scales well in all areas. Team maintenance has since emerged as a practical complement, allowing multiple contributors to share responsibility and reduce bottlenecks--depending on each team's internal policy. While working on the Bug of the Day initiative, I observed a significant number of packages that have not been updated in a long time. In the case of team-maintained packages, addressing this is often straightforward: team uploads can be made, or the team can be asked whether the package should be removed. We've also identified many packages that would fit well under the umbrella of active teams, such as language teams like Debian Perl and Debian Python, or blends like Debian Games and Debian Multimedia. Often, no one has taken action--not because of disagreement, but simply due to inattention or a lack of initiative. In addition, we've found several packages that probably should be removed entirely. In those cases, we've filed bugs with pre-removal warnings, which can later be escalated to removal requests. When a package is still formally maintained by an individual, but shows signs of neglect (e.g., no uploads for years, unfixed RC bugs, failing autopkgtests), we currently have three main tools:
  1. The MIA process, which handles inactive or unreachable maintainers.
  2. Package Salvaging, which allows contributors to take over maintenance if conditions are met.
  3. Non-Maintainer Uploads (NMUs), which are limited to specific, well-defined fixes (which do not include things like migration to Salsa).
These mechanisms are important and valuable, but they don't always allow us to react swiftly or comprehensively enough. Our tools for identifying packages that are effectively unmaintained are relatively weak, and the thresholds for taking action are often high. The Package Salvage team is currently trialing a process we've provisionally called "Intend to NMU" (ITN). The name is admittedly questionable--some have suggested alternatives like "Intent to Orphan"--and discussion about this is ongoing on debian-devel. The mechanism is intended for situations where packages appear inactive but aren't yet formally orphaned, introducing a clear 21-day notice period before NMUs, similar in spirit to the existing ITS process. The discussion has sparked suggestions for expanding NMU rules. While it is crucial not to undermine the autonomy of maintainers who remain actively involved, we also must not allow a strict interpretation of this autonomy to block needed improvements to obviously neglected packages. To be clear: I do not propose to change the rights of maintainers who are clearly active and invested in their packages. That model has served us well. However, we must also be honest that, in some cases, maintainers stop contributing--quietly and without transition plans. In those situations, we need more agile and scalable procedures to uphold Debian's high standards. To that end, I've registered a BoF session for DebConf25 to discuss potential improvements in how we handle dormant packages. These discussions will be prepared during a sprint at DebCamp, where I hope to work with others on concrete ideas. Among the topics I want to revisit is my proposal from last November on debian-devel, titled "Barriers between packages and other people". While the thread prompted substantial discussion, it understandably didn't lead to consensus. I intend to ensure the various viewpoints are fairly summarised--ideally by someone with a more neutral stance than myself--and, if possible, work toward a formal proposal during the DebCamp sprint to present at the DebConf BoF. My hope is that we can agree on mechanisms that allow us to act more effectively in situations where formerly very active volunteers have, for whatever reason, moved on. That way, we can protect both Debian's quality and its collaborative spirit. Building Sustainable Funding for Debian Debian incurs ongoing expenses to support its infrastructure--particularly hardware maintenance and upgrades--as well as to fund in-person meetings like sprints and mini-DebConfs. These investments are essential to our continued success: they enable productive collaboration and ensure the robustness of the operating system we provide to users and derivative distributions around the world. While DebConf benefits from generous sponsorship, and we regularly receive donated hardware, there is still considerable room to grow our financial base--especially to support less visible but equally critical activities. One key goal is to establish a more constant and predictable stream of income, helping Debian plan ahead and respond more flexibly to emerging needs. This presents an excellent opportunity for contributors who may not be involved in packaging or technical development. Many of us in Debian are engineers first--and fundraising is not something we've been trained to do. But just like technical work, building sustainable funding requires expertise and long-term engagement. If you're someone who's passionate about Free Software and has experience with fundraising, donor outreach, sponsorship acquisition, or nonprofit development strategy, we would deeply value your help. Supporting Debian doesn't have to mean writing code. Helping us build a steady and reliable financial foundation is just as important--and could make a lasting impact. Kind regards Andreas. PS: In April I also planted my 5000th tree and while this is off-topic here I'm proud to share this information with my fellow Debian friends.

9 May 2025

Uwe Kleine-K nig: The Linux kernel's PGP Web of Trust

The Linux kernel's development process makes use of PGP. The most relevant part here is that subsystem maintainers are supposed to use signed tags in their pull requests to Linus Torvalds. As the concept of keyservers is considered broken, Konstantin Ryabitsev maintains a collection of relevant keys in a git repository. As of today (at commit a0bc65fb27f5033beddf9d1ad97d67c353849be2) there are 602 valid keys tracked in that repository. The requirement for a key to be added there is that there must be at least one trust path from Linus Torvalds' key to this key of length at most 5 within that keyring. Occasionally it happens that a key loses its trust paths because someone in these paths replaced their key, or keys expired. Currently this affects 2 keys. However there is a problem on the horizon: GnuPG 2.4.x started to reject third-party key signatures using the SHA-1 hash algorithm. In general that's good, SHA-1 isn't considered secure any more for more than 20 years. This doesn't directly affect the kernel-pgpkeys repo, because the trust path checking doesn't rely on GnuPG trusting the signatures; there is a dedicated tool that parses the keyring contents and currently accepts signatures using SHA-1. Also signatures are not thrown away usually, but there are exceptions: Recently Theodore Ts'o asked to update his certificate. When Konstantin imported the updated certificate GnuPG's "cleaning" was applied which dropped all SHA-1 signatures. So Theodore Ts'o's key lost 168 signatures, among them one by Linus Torvalds on his primary UID. That made me wonder what would be the effect on the web of trust if all SHA-1 signatures were dropped. Here are the facts: If you attend Embedded Recipes 2025 next week, there is an opportunity to improve the situation: Together with Ahmad Fatoum I'm organizing a keysigning session. If you want to participate, send your public key to er2025-keysigning@baylibre.com before 2025-05-12 08:00 UTC.

5 May 2025

Ravi Dwivedi: A visit to Paris

After attending the 2024 LibreOffice conference in Luxembourg, I visited Paris in October 2024. If you are wondering whether I needed another visa to cross the border into France I didn t! Further, they are both also EU members, which means you don t need to go through customs either. Thus, crossing the Luxembourg-France border is no different from crossing Indian state borders - like going from Rajasthan to Uttar Pradesh. I took a TGV train from Luxembourg Central Station, which was within walking distance from my hostel. The train took only 2 hours and 20 minutes to cover the 300 km distance to Paris. It departed from Luxembourg at 10:00 AM and reached Paris at 12:20 PM. The ride was smooth and comfortable, arriving on time. It gave me an opportunity to see the countryside of France. I booked the train ticket online a couple of days prior through the Omio website.
A train standing on a platform TGV train I rode from Luxembourg to Paris
I planned the first day with my friend Joenio, whom I met upon arriving in Paris Gare de l Est station, along with his wife Mari. We went to my hostel (which was within walking distance from the station) to store my luggage, but we were informed that we needed to wait for a couple of hours before I could check in. Consequently, we went to an Italian restaurant nearby for lunch, where I ordered pasta. My hostel was unbelievably cheap by French standards (25 euros per night) that Joenio was shocked when he learned about it.
Pasta on a plate topped with Ricotta cheese Pasta I had in Paris
Walking in the city, I noticed it had separate cycling tracks and wide footpaths, just like Luxembourg. The traffic was also organized. For instance, there were traffic lights even for pedestrian crossings, unlike India, where crossing roads can be a nightmare. Car drivers stopping for pedestrians is a big improvement over what I am used to in India. The weather was also pleasant. It was a bit on the cooler side - around 15 degrees Celsius - and I had to wear a jacket.
A cycling track in Paris A cycling track in Paris
After lunch, we returned to my hostel for my check-in at around 3 o clock. Then, we went to the Luxembourg Museum (Mus e du Luxembourg in French) as Joenio had booked tickets for an exhibition of paintings by the Brazilian painter Tarsila do Amaral. To reach there, we took a subway train from Gare du Nord station. The Paris subway charges 2.15 euros irrespective of the distance (or number of stations) traveled, as opposed to other metro systems I have used. We reached the museum at around 4 o clock. I found the paintings beautiful, but I would have appreciated them much more if the descriptions were in English.
A building wit trees on the left and right side of it and sky in the background. People can be seen in front of the building. Luxembourg Museum
Afterward, we went to a beautiful garden just behind the museum. It served as a great spot to relax and take pictures. Following this, we walked to the Pantheon - a well-known attraction in the city. It is a church built a couple of centuries ago. It has a dome-shaped structure at the top, recognizable from far away.
A building with a garden in front it and people sitting closer to us. Sky can be seen in the background. A shot of the park near to the Luxembourg Museum
A building with a dome shaped structure on top. Closer to camera, roads can be seen. In the background is blue colored cloudy sky. Pantheon, one of the attractions of Paris.
Then we went to Notre Dame after having evening snacks and coffee at a nearby bakery. The Notre Dame was just over a kilometer from the Pantheon, so we took a walk. We also crossed the beautiful Seine river. On the way, I sampled a cr pe, a signature dish of France. The shop was named Cr perie and had many varieties of Cr pe. I took the one with eggs and Emmental cheese. It was savory and delicious.
Photo with Joenio and Mari Photo with Joenio and Mari
Notre Dame, another tourist attraction of Paris. Notre Dame, another tourist attraction of Paris.
By the time we reached Notre Dame, it was 07:30 PM. I learned from Joenio that Notre Dame was closed and being renovated due to a fire a couple of years ago, so we just sat around and clicked photos. It is a catholic cathedral built in French Gothic architecture (I read that on Wikipedia ;)). I read on Wikipedia that it is located on an island named le de la Cit and I didn t even realize we are on an island. At night, we visited the most well-known attraction of Paris, The Eiffel Tower. We again took the subway, alighting at the Bir-Hakeim station, followed by a short walk. We reached the Eiffel Tower at 9 o clock. It was lit bright yellow. There was not much to do there, so we just clicked photos and hung out. After that, I came back to my hostel.
The Eiffel Tower lit with bright yellow My photo with Eiffel Tower in the background
Next day, I roamed around the city by walking mostly. France is known for its bakeries, so I checked out a couple of local bakeries. I had espresso a couple of times and sampled croissant, pain au chocolat and lemon meringue tartlet.
Items from left to right are: Chocolate Twist, Sugar briochette, Pain au Chocolat, Croissant with almonds, Croissant, Croissant with chocolate hazlenut filling.Items at a bakery in Paris Items at a bakery in Paris. Items from left to right are: Chocolate Twist, Sugar briochette, Pain au Chocolat, Croissant with almonds, Croissant, Croissant with chocolate hazlenut filling.
Here are some random shots:
The Paris subway The Paris subway
Inside a Paris metro train Inside a Paris subway
A random building and road in Paris A random building and road in Paris
A shot near Seine river A shot near Seine river
A view of Seine river A view of Seine river
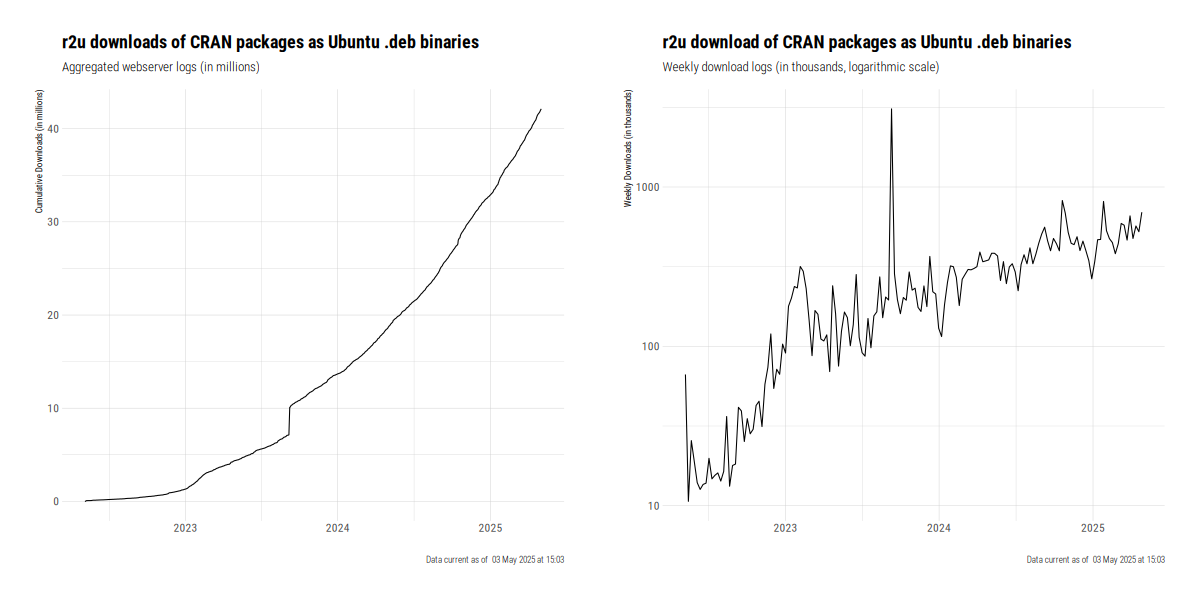
On the third day, I had my flight for India. Thus, I checked out of the hostel early in the morning, took an RR train from Gare du Nord station to reach the airport. It costs 11.8 euros. I heard some of my friends had bad experiences in France. Thus, I had the impression that I would not feel welcomed. Furthermore, I have encountered language problems in my previous Europe trip to Albania and Kosovo. Likewise, I learned a couple of French words, like how to say thank you and good morning, which went a long way. However, I didn t have bad experiences in Paris, except for one instance in which I asked my hostel s reception about my misplaced watch and the person at the reception asked me to be polite by being rude. She said, Excuse me! You don t know how to say Good Morning? Overall, I enjoyed my time in Paris and would like to thank Joenio and Mari for joining me. I would also like to thank Sophie, who gave me a map of Paris. Let s end this post here. I ll meet you in the next one! Credits: Thanks to contrapunctus for reviewing this post before publishing

4 May 2025

Dirk Eddelbuettel: #47: r2u at its Third Birthday

Welcome to post 47 in the $R^4 series! r2u provides Ubuntu binaries for all CRAN packages for the R system. It started three years ago, and offers for Linux users on Ubuntu what windows and macOS users already experience: fast, easy and reliable installation of binary packages. But by integrating with the system package manager (which is something that cannot be done on those other operating systems) we can fully and completely integrate it with underlying system. External libraries are resolved as shared libraries and handled by the system package manager. This offers fully automatic installation both at the initial installation and all subsequent upgrades. R users just say, e.g., install.packages("sf") and spatial libraries proj, gdal, geotiff (as well as several others) are automatically installed as dependencies in the correct versions. And they remain installed along with sf as the system manager now knows of the dependency. Work on r2u began as a quick weekend experiment in March 2022, and by May 4 a first release was marked in the NEWS file after a few brave alpha testers kicked tires quite happily. This makes today the third anniversary of that first release, and marks a good time to review where we are. This short post does this, and stresses three aspects: overall usage, current versions, and new developments.

Steadily Growing Usage at 42 Million Packages Shipped r2u ships from two sites. Its main repository is at the University of Illinois campus providing ample and heavily redundant bandwidth. We remain very grateful for the sponsorship from Atlas. It also still ships from my own server though that may be discontinued or could be spotty as it is on retail fiber connectivity. As we have access to the both sets of server logs, we can tabulate and chart usage. As of yesterday, total downloads were north of 42 million with current weekly averages around 500 thousand. These are quite staggering numbers for what started as a small hobby project, and are quite humbling. Usage is driven by deployment in continuous integration (as for example the Ubuntu-use at GitHub makes this both an easy and obvious choice), cloud computing (as it is easy to spin up Ubuntu instances, it is as easy to add r2u via four simple commands or one short script), explorative use (for example on Google Colab) or of course in general laptop, desktop, or server settings.

Current Versions Since r2u began, we added two Ubuntu LTS releases, three annual R releases as well as multiple BioConductor releases. BioConductor support is on a best-efforts basis motivated primarily to support the CRAN packages having dependencies. It has grown to around 500 packages and includes the top-250 by usage. Right now, current versions R 4.5.0 and BioConductor 3.21, both released last month, are supported.

New Development: arm64 A recent change is the support of the arm64 platform. As discussed in the introductory post, it is a popular and increasingly common CPU choice seen anywhere from the Raspberry Pi 5 and it Cortex CPU to in-house cloud computing platforms (called, respectively, Graviton at AWS and Axiom at GCS), general server use via Ampere CPUs, Cortex-based laptops that start to appears and last but not least on the popular M1 to M4-based macOS machines. (For macOS, one key appeal is in use of lighterweight Docker use as these M1 to M4 cpus can run arm64-based containers without a translation layer making it an attractive choice.) This is currently supported only for the noble aka 24.04 release. GitHub Actions, where we compile these packages, now also supports jammy aka 22.04 but it may not be worth it to expand there as the current latest release is available. We have not yet added BioConductor support but may do so. Drop us a line (maybe via an issue) if this of interest. With the provision of arm64 binaries, we also started to make heavier use of GitHub Actions. The BioConductor 3.21 release binaries were also created there. This makes the provision more transparent as well as the configuration repo as well as the two builder repos (arm64, bioc) are public, as is of course the main r2u repo.

Summing Up This short post summarised the current state of r2u along with some recent news. If you are curious, head over to the r2u site and try it, for example in a rocker/r2u container.

This post by Dirk Eddelbuettel originated on his Thinking inside the box blog. If you like this or other open-source work I do, you can now sponsor me at GitHub.

3 May 2025

Russ Allbery: Review: Paper Soldiers

Review: Paper Soldiers, by Saleha Mohsin
Publisher: Portfolio
Copyright: 2024
ISBN: 0-593-53912-5
Format: Kindle
Pages: 250
The subtitle of Paper Soldiers is "How the Weaponization of the Dollar Changed the World Order," which may give you the impression that this book is about US use of the dollar system for political purposes such as sanctions. Do not be fooled like I was; this subtitle is, at best, deceptive. Coverage of the weaponization of the dollar is superficial and limited to a few chapters. This book is, instead, a history of the strong dollar policy told via a collection of hagiographies of US Treasury Secretaries and written with all of the skeptical cynicism of a poleaxed fawn. There is going to be some grumbling about the state of journalism in this review. Per the author's note, Saleha Mohsin is the Bloomberg News beat reporter for the US Department of the Treasury. That is, sadly, exactly what this book reads like: routine beat reporting. Mohsin asked current and former Treasury officials what they were thinking at various points in history and then wrote down their answers without, so far as I can tell, considering any contradictory evidence or wondering whether they were telling the truth. Paper Soldiers does contain extensive notes (those plus the index fill about forty pages), so I guess you could do the cross-checking yourself, although apparently most of the interviews for this book were "on background" and are therefore unattributed. (Is this weird? I feel like this is weird.) Mohsin adds a bit of utterly conventional and uncritical economic framing and casts the whole project in the sort of slightly breathless and dramatized prose style that infests routine news stories in the US. I find this style of book unbelievably frustrating because it represents such a wasted opportunity. To me, the point of book-length journalism is precisely to not write in this style. When you're trying to crank out two or three articles a week covering current events, I understand why there isn't always space or time to go deep into background, skepticism, and contrary opinions. But when you expand that material into a book, surely the whole point is to take the time to do some real reporting. Dig into what people told you, see if they're lying, talk to the people who disagree with them, question the conventional assumptions, and show your work on the page so that the reader is smarter after finishing your book than they were before they started. International political economics is not a sequence of objective facts. It's a set of decisions made in pursuit of economic and political theories that are disputed and arguable, and I think you owe the reader some sense of the argument and, ideally, some defensible position on the merits that is more than a transcription of your interviews. This is... not that.
It's a power loop that the United States still enjoys today: trust in America's dollar (and its democratic government) allows for cheap debt financing, which buys health care built on the most advanced research and development and inventions like airplanes and the iPhone. All of this is propelled by free market innovation and the superpowered strength to keep the nation safe from foreign threats. That investment boosts the nation's economic, military, and technological prowess, making its economy (and the dollar) even more attractive.
Let me be precise about my criticism. I am not saying that every contention in the above excerpt is wrong. Some of them are probably correct; more of them are at least arguable. This book is strictly about the era after Bretton Woods, so using airplanes as an example invention is a bizarre choice, but sure, whatever, I get the point. My criticism is that paragraphs like this, as written in this book, are not introductions to deeper discussions that question or defend that model of economic and political power. They are simple assertions that stand entirely unsupported. Mohsin routinely writes paragraphs like the above as if they are self-evident, and then immediately moves on to the next anecdote about Treasury dollar policy. Take, for example, the role of the US dollar as the world's reserve currency, which roughly means that most international transactions are conducted in dollars and numerous countries and organizations around the world hold large deposits in dollars instead of in their native currency. The conventional wisdom holds that this is a great boon to the US economy, but there are also substantive critiques and questions about that conventional wisdom. You would never know that from this book; Mohsin asserts the conventional wisdom about reserve currencies without so much as a hint that anyone might disagree. For example, one common argument, repeated several times by Mohsin, is that the US can only get away with the amount of deficit spending and cheap borrowing that it does because the dollar is the world's reserve currency. Consider two other countries whose currencies are clearly not the international reserve currency: Japan and the United Kingdom. The current US debt to GDP ratio is about 125% and the current interest rate on US 10-year bonds is about 4.2%. The current Japanese debt to GDP ratio is about 260% and the current interest rate on Japanese 10-year bonds is about 1.2%. The current UK debt to GDP ratio is 160% and the current interest rate on UK 10-year bonds is 4.5%. Are you seeing the dramatic effects of the role of the dollar as reserve currency? Me either. Again, I am not saying that this is a decisive counter-argument. I am not an economist; I'm just some random guy on the Internet who finds macroeconomics interesting and reads a few newsletters. I know the Japanese bond market is unusual in ways I'm not accounting for. There may well be compelling arguments for why reserve currency status matters immensely for US borrowing capacity. My point is not that Mohsin is wrong; my point is that you have to convince me and she doesn't even try. Nowhere in this book is a serious effort to view conventional wisdom with skepticism or confront it with opposing arguments. Instead, this book is full of blithe assertions that happen to support the narrative the author was fed by a bunch of former Treasury officials and does not appear to question in any way. I want books like this to increase my understanding of the world. To do that, they need to show me multiple sides of debates and teach me how to evaluate evidence, not simply reinforce a superficial conventional wisdom. It doesn't help that whatever fact-checking process this book went through left some glaring errors. For example, on the Plaza Accord:
With their central banks working in concert, enough dollars were purchased on the open market to weaken the currency, making American goods more affordable for foreign buyers.
I don't know what happened after the Plaza Accord (I read books like this to find out!), but clearly it wasn't that. This is utter nonsense. Buying dollars on the open market would increase the value of the dollar, not weaken it; this is basic supply and demand that you learn in the first week of a college economics class. This is the type of error that makes me question all the other claims in the book that I can't easily check. Mohsin does offer a more credible explanation of the importance of a reserve currency late in the book, although it's not clear to me that she realizes it: The widespread use of the US dollar gives US government sanctions vast international reach, allowing the US to punish and coerce its enemies through the threat of denying them access to the international financial system. Now we're getting somewhere! This is a more believable argument than a small and possibly imaginary effect on government borrowing costs. It is clear why a bellicose US government, particularly one led by advocates of a unitary executive theory that elevates the US president to a status of near-emperor, want to turn the dollar into a weapon of international control. It's much less obvious how comfortable the rest of the world should be with that concentration of power. This would be a fascinating topic for a journalistic non-fiction book. Some reporter should dive deep into the mechanics of sanctions and ask serious questions about the moral, practical, and diplomatic consequences of this aggressive wielding of US power. One could give it a title like Paper Soldiers that reflected the use of banks and paper currency as foot soldiers enforcing imperious dictates on the rest of the world. Alas, apart from a brief section in which the US scared other countries away from questioning the dollar, Mohsin does not tug at this thread. Maybe someone should write that book someday. As you will have gathered by now, I think this is a bad book and I do not recommend that you read it. Its worst flaw is one that it shares with far too much mainstream US print and TV journalism: the utter credulity of the author. I have the old-fashioned belief that a journalist should be more than a transcriptionist for powerful people. They should be skeptical, they should assume public figures may be lying, they should look for ulterior motives, and they should try to bring the reader closer to some objective truths about the world, wherever they may lie. I have no solution for this degradation of journalism. I'm not even sure that it's a change. There were always reporters eager to transcribe the voice of power into the newspaper, and if we remember the history of journalism differently, that may be because we have elevated the rare exceptions and forgotten the average. But after watching too many journalists I once respected start parroting every piece of nonsense someone tells them, from NFTs to UFOs to the existential threat of AI, I've concluded that the least I can do as a reader is to stop rewarding reporters who cannot approach powerful subjects with skepticism, suspicion, and critical research. I failed in this case, but perhaps I can serve as a warning to others. Rating: 3 out of 10

2 May 2025

Ben Hutchings: FOSS activity in April 2025

I also co-organised a Debian BSP (Bug-Squashing Party) last weekend, for which I will post a separate report later.

1 May 2025

Jonathan McDowell: Local Voice Assistant Step 2: Speech to Text and back

Having setup an ATOM Echo Voice Satellite and hooked it up to Home Assistant we now need to actually do something with the captured audio. Home Assistant largely deals with voice assistants using the Wyoming Protocol, which describes itself as essentially JSONL + PCM audio. It works nicely in terms of meaning everything can exist as separate modules that then just communicate over network sockets, and there are a whole bunch of Python implementations of the pieces necessary. The first bit I looked at was speech to text; how do I get what I say to the voice satellite into something that Home Assistant can try and parse? There is a nice self contained speech recognition tool called whisper.cpp, which is a low dependency implementation of inference using OpenAI s Whisper model. This is wrapped up for Wyoming as part of wyoming-whisper-cpp. Here we get into something that unfortunately seems common in this space; the repo contains a forked copy of whisper.cpp with enough differences that I couldn t trivially make it work with regular whisper.cpp. That means missing out on new development, and potential improvements (the fork appears to be at v1.5.4, upstream is up to v1.7.5 at the time of writing). However it was possible to get up and running easily enough. [I note there is a Wyoming Whisper API client that can use the whisper.cpp server, and that might be a cleaner way to go in the future, especially if whisper.cpp ends up in Debian.] I stated previously I wanted all of this to be as clean an installed on Debian stable as possible. Given most of this isn t packaged, that s meant I ve packaged things up as I go. I m not at the stage anything is suitable for upload to Debian proper, but equally I ve tried to make them a reasonable starting point. No pre-built binaries available, just Salsa git repos. https://salsa.debian.org/noodles/wyoming-whisper-cpp in this case. You need python3-wyoming from trixie if you re building for bookworm, but it doesn t need rebuilt. You need a Whisper model that s been converts to ggml format; they can be found on Hugging Face. I ve ended up using the base.en model. I found small.en gave more accurate results, but took a little longer, when doing random testing, but it doesn t seem to make much of a difference for voice control rather than plain transcribing. [One of the open questions about uploading this to Debian is around the use of a prebuilt AI model. I don t know what the right answer is here, and whether the voice infrastructure could ever be part of Debian proper, but the current discussion on the interpretation of the DFSG on AI models is very relevant.] I run this in the same container as my Home Assistant install, using a systemd unit file dropped in /etc/systemd/system/wyoming-whisper-cpp.service:
[Unit]
Description=Wyoming whisper.cpp server
After=network.target
[Service]
Type=simple
DynamicUser=yes
ExecStart=wyoming-whisper-cpp --uri tcp://localhost:10030 --model base.en
MemoryDenyWriteExecute=false
ProtectControlGroups=true
PrivateDevices=false
ProtectKernelTunables=true
ProtectSystem=true
RestrictRealtime=true
RestrictNamespaces=true
[Install]
WantedBy=multi-user.target
It needs the Wyoming Protocol integration enabled in Home Assistant; you can Add Entry and enter localhost + 10030 for host + port and it ll get added. Then in the Voice Assistant configuration there ll be a whisper.cpp option available. Text to speech turns out to be weirdly harder. The right answer is something like Wyoming Piper, but that turns out to be hard on bookworm. I ll come back to that in a future post. For now I took the easy option and used the built in Google Translate option in Home Assistant. That needed an extra stanza in configuration.yaml that wasn t entirely obvious:
media_source:
With this, and the ATOM voice satellite, I could now do basic voice control of my Home Assistant setup, with everything except the text-to-speech piece happening locally! Things such as Hey Jarvis, turn on the study light work out of the box. I haven t yet got into defining my own phrases, partly because I know some of the things I want ( What time is it? ) are already added in later Home Assistant versions than the one I m running. Overall I found this initially complicated to setup given my self-imposed constraints about actually understanding the building blocks and compiling them myself, but I ve been pretty impressed with the work that s gone into it all. Next step, running a voice satellite on a Debian box.

Next.

Previous.