Here s my monthly but brief update about the activities I ve done in the FOSS world.
Debian
Whilst I didn t get a chance to do much, here are still a few things that I worked on:
Leading the DebConf Bursary team along with PEB.
This took most of my Debian time this month but we ve been able to wrap that work now.
Got back to all the tickets on Zammad, too.
Assisted a few folks in getting their patches submitted via Salsa.
Mentoring for newcomers.
Moderation of -project mailing list.
Ubuntu
I joined Canonical to work on Ubuntu full-time back in February 2021.
Whilst I can t give a full, detailed list of things I did, here s a quick TL;DR of what I did:
Continued to push for infrastructure improvements:
[LTS] Emilio pointed out that the gst-plugins-ugly1.0 binaries were still not fully released, so I ran dcut migrate to fully release them. The DLA had gone out earlier.
[ELTS] Did some more work on ruby-rack - a lot of new CVEs have opened up and, whilst I made some progress, Santiago let me know that ruby-rack is no longer supported and so it ll be removed from the ela-needed list.
[E/LTS] Set up the security-tracker and a few other things on the new machine, and debugged the git repository size madness. Sent a summary here.
[E/LTS] Monitored discussions on mailing lists, IRC, and all the documentation updates.
The diffoscope maintainers are pleased to announce the release of diffoscope
version 323. This version includes the following changes:
[ Chris Lamb ]
* Debian adds an extra "Flags:" line in the output of ocamlobjinfo via a
  patch, so adjust how we test OCaml to ensure cross-distribution
  compatibility. (Closes: reproducible-builds/diffoscope#430)
* Update copyright years.
[ Michael Daniels ]
* Fix tests when using zipdetails version >= 4.006.
The Linux local root exploit of today s news is PACKET_EDIT_MEME.c [CVE-2026-46331] which is also known as pedit COW.
This vulnerability has been fixed as of linux 7.1~rc7, but also fixed in trixies 6.12.94-1 as well as testing/unstable 7.0.13-1. If you run an older or different kernel you might want to mitigate the vulnerability until you can update and reboot affected systems.
The vulnerability can be mitigated by unloading and blocking the act_pedit module, linux-vulnerability-mitigation as of 20260629-1 (uploaded to sid, trixie-fastforward-backports and people.debian.org/~daniel) does that automatically for you.
While watching a YouTube video I saw an advert for the Plaud AI Note Taker [1]. The Plaud device looks pretty good for what it does, taking notes and managing them, using some sort of LLM function to manage the notes. The devices all cost about $300 which is an amount that doesn t seem unreasonable for someone who s in a lot of meetings. One of the models is the NotePin that seems comparable to the Humane AI Pin I previously blogged about [2].
The business model for Plaud is based on only allowing 5 hours per month of free transcriptions, then charging $16.25/month for 20 hours per month and $33.33/month for unlimited use. That s quite expensive for any serious use.
The number of people in the market for an audio recording system that automatically transcribes things may be greater than the number of people in the market for all the stuff that the Humane AI Pin did, but it still may not be enough to run a profitable business when competing with apps on mobile phones.
While the product does look decent it seems that they are making the same mistakes as the original Humane developers did, of wanting to lock it down as a subscription based service which reduces the usability of the device. If they had sold an Android hand-held computer with their own app pre-loaded and allowed the user to install a different app then it would have been much more usable. If they had sold Android devices designed for the note taking market and allowed people to choose their own apps to install then their products would have a much longer life expectancy.
The majority of Android devices in use are probably out of support but still working while the Humane AI pin can t be used any more and at some time in the not too distant future the Plaud devices will also become unusable. People who buy devices like the Plaud seem to be unaware of the history of such things and the expected future for them. But possibly some people just consider $300 for a year of use to be an acceptable price. If someone wanted to purchase a new high end phone every year and sell their previous one they would probably have a net cost of about $500/year.
Maybe I should look for work with a company with an implausible AI based business plan. It would be fun developing such a device if you weren t emotionally invested in the project. Just develop new technology, earn a heap of money, play with fun computers, and move on to the next thing when it collapses. Just like all the Internet companies about 25 years ago.
After getting a HP Z4 G4 tower server/workstation to house my Intel Battlemage GPU [1] I ve been playing around with some GPU stuff. For years I ve been just buying GPUs based on the resolution and price and not bothering about anything else due to lack of ability to measure what cards are doing. The nvidia-smi program is really good for NVidia/CUDA setups but I hadn t been aware of anything similar for AMD cards. As I prefer AMD cards for my workstations due to driver issues with NVidia that was a problem for me.
I ve recently discovered that the program nvtop (Debian package nvtop) shows the GPU use of multiple GPU types, for me it s worked on AMD and Intel discrete GPUs and shows some information on Intel integrated GPUs, I don t have others convenient for testing at the moment. Currently BOINC has the Einstein@Home [2] project running on the HP Z4 G4 and it s using between 66% and 100% of GPU compute power and 1.6G of GPU RAM. Using 100% GPU compute power allegedly takes 62W of power out of the 190W quoted TDP. I presume that the power use reported by nvtop is very inaccurate.
A friend installed a LLM on that system and the libraries used for the LLM were sufficient that BOINC just started using the GPU.
On my workstation running an AMD [Radeon RX 460/560D / Pro 450/455/460/555/555X/560/560X] (actually R560) with 4G of GPU RAM I have mpv taking 1G of GPU RAM to play a FullHD video expanded to a full screen window on my 5120*2160 display. I also have about 2G used by the kwin_wayland process (the Wayland server for KDE). That doesn t leave enough GPU RAM to allow Einstein@Home to use the GPU. When playing the FullHD video in question (which is 1.2G for 42 minutes about 500KB/s) at 1.5* speed (a common playback speed I use) that takes about 30% of the compute power on my GPU.
I had installed the rocm-opencl-icd package on my workstation (with a 5120*2160 monitor) and restarted boinc-client.service which is all that s needed to allow BOINC to use an AMD GPU. Then the screen started flickering as the Einstein process repeatedly core dumped which I initially assumed to be it s reaction to not having enough GPU RAM available. On every core dump the screen flickered so it went through a process of dozens of screen flickers until it had caused a sufficient number of core dumps and BOINC gave up running that job.
Another annoyance is that the boincmgr program (the graphical program for managing BOINC systems) launches two webkit processes that each use about 400M of GPU RAM, so even if other things weren t using all my GPU RAM the boincmgr process would stop the BOINC jobs from using the GPU. I shut down some of the programs that were using GPU RAM until there was 2G free and the BOINC process kept crashing so it seems that there is some other issue.
On another system with a 4K monitor there were Chrome and Chromium GPU process taking 1.1G and 500M of GPU RAM respectively and the KWin Wayland process was taking 1G of GPU RAM. So that s well over half the GPU RAM for just browsers and Wayland. With programs like Kitty (terminal emulator) and Nheko (Matrix client) taking over 100M of GPU RAM it seems that 4G is the bare minimum for GPU RAM with modern software and a 4K or similar display.
I also noticed the kscreenlocker_greet process taking 440M of GPU RAM. I wonder if a hostile web server could make a web browser take more GPU RAM and starve the screenlocker of GPU RAM, could that allow forcing a screen lock operation to fail?
It seems that 4G is the minimum for modern systems, which isn t necessarily a problem as GPUs that are capable of driving 4K displays tend to have no less than 4G. My local computer store has new GPUs with 4G starting at $120 but 12G seems to be the next option up which starts at about $400.
Ebay currently has a selection of AMD GPUs with 8G of RAM under $200. I ve had some problems with the GPU in my workstation crashing as described in my previous post where I thought it was driver issues [3]. I now believe that there are hardware issues and will look into buying one of the cards with 8G.
Further Investigation
I need to determine which of the AMD GPUs that are currently going cheap on ebay are best. While my current PC has support for 150W PCIe power I d rather something less power hungry than that. I have occasional issues of mpv reporting that my system is too slow for a video so slightly more compute power on the GPU would be good, but I think that every available option has significantly more compute power.
I need to find out what the relationship is between screen resolution and GPU memory. If I get an 8K display or an array of 4*4K displays (which is quite plausible as 27 4K displays go for $230 each) will I find 16G of GPU RAM as limiting as I find 4G now?
The nvtop program tracks PCIe data transfers for AMD GPUs, I haven t yet seen more than 25MB/s and I need to do more tests to see what the maximum is. Running on an Intel Battlemage card nvtop doesn t report PCIe data transfer speed which is a missing feature in either the driver or the program. I need to find out where the problem is and report a bug if someone hasn t already done so.
The GPU RAM use of some applications seems excessive. 440M for a lockscreen? 100M+ for a terminal emulator? 320M for Thunderbird?
I previously wrote about the
upcoming UEFI
CA rollover. Well, it's happened now - the old Microsoft UEFI
CA from 2011 expired yesterday:
Third Party Marketplace Root (used for signing option ROMs and other software)
  Subject: C=US, ST=Washington, L=Redmond, O=Microsoft Corporation, CN=Microsoft Corporation UEFI CA 2011
  Validity
    Not Before: Jun 27 21:22:45 2011 GMT
    Not After : Jun 27 21:32:45 2026 GMT
It's dead - it's not coming back...
The world doesn't seem to have ended yesterday, so I guess we did
ok? :-)
How did we do?
After a lot of prodding behind the scenes, Debian and many other
distributions managed to get new shim binaries dual-signed with both
the old and new CAs. The members of the shim-review team did a
sterling job with reviews in the last few weeks. Since I started
pushing people in May, we've had 21 reviews accepted successfully -
see here
for the list. Great stuff! Microsoft have also been working quickly -
many of those shim submissions were accepted and signed by Microsoft
very quickly too, with a turnaround time of less than 1 day in some
cases.
Not all of those signed shims have been published and used by the
distros involved yet, but expect to see them in the wild in the coming
weeks and months.
These binaries should be good for people to use for the foreseeable
future, until either we need to do another CA rollover or (sadly, more
likely) we find an issue in shim that necessitates a new release.
What's next?
We already have one of our new dual-signed shim
binaries in place in Debian, in unstable and testing (Forky) right
now. In a couple of weeks from now, we'll be rolling out very similar
new dual-signed shim binaries in the next point releases for Debian 12
(bookworm) and Debian 13 (trixie). We'll also be
upgrading fwupd in both those point releases, to make DB
and KEK updates work better.
For more information about these updates,
see https://wiki.debian.org/SecureBoot/CAChanges. For
your own safety, validate that your systems are updated when
possible. If you don't, they may fail to boot in future.
I had intended that the next release of onak, my OpenPGP keyserver, would be 0.7.0, and include OpenPGP v6 support (RFC9580). However events conspired to make a 0.6.5 release a really good idea.
Firstly, I threw an LLM at the code base and asked it to review it. This isn t intended to be a post about LLMs, but there s a considerable amount of pressure at work to be AI native . I m very much an AI sceptic, so I figured throwing it at a code base I know well might be an interesting exercise. It did find a bunch of embarrassing mistakes, but I don t think there was anything earth shattering that a human reviewer wouldn t have pulled me on. The problem is with a hobby project with a single user there s no actual review of my work.
I also enabled GitHub s security scanning. It mostly complained about format strings, and those were easy enough to fix up.
Next I threw AFLplusplus at the code. I d previously tried American Fuzzy Lop, but not in some time. AFL++ found a whole bunch of places I should really have checked available buffer lengths and wasn t doing so. It really is an incredibly easy tool to get up and running.
valgrind is also a tool I ve used before, and rate highly. Thankfully it didn t find anything in my testing this time.
Finally I threw a few more automated tests into the mix and discovered something has changed around dynamic linking such that the libonak symbols in the dynamic key database backends were using private copies, rather than the main binary. This caused problems with seeing the correct configuration settings in some instances.
All in all this release is not my proudest moment; a bunch of the issues fixed should never have made it to a release.
(Also, just to explicitly state it, all the actual code in this release was artisanly crafted by me, in vim. The only involvement of an LLM was for a review pass.)
Available locally or via GitHub.
0.6.5 - 27th June 2026
Lots of fixes/improvements around length checking
Added extra basic tests for maxpaths/sixdegrees/CGI
Correctly end transactions in the stacked backend
Ensure the file backend avoids stale key data on updates
Fix decoding of v2/3 signature creation times
Fix EdDSA signature parsing when r < 249 bits long
Fix migration of bools from old to new config style
Fix parsing of new config details for DB parameters
Fix problems with linking + dynamic backends
Fix RSA-SHA2-384 signature checking
Fix sixdegrees parsing of keyids with high bit set
The Folded Sky is a far-future space opera and a fairly direct
sequel to Ancestral Night, but with a
different protagonist. You do not need to have a vivid memory of the
previous book to read this one. It is somewhere around Elizabeth Bear's
31st (!) novel, depending on how one counts and what one includes.
Sunyata Song is an archinformist, which is sort of an archaeologist, sort
of a librarian, and sort of a historian. She recovers, decodes, and
organizes information so that it can be preserved and made usefully
available. As the book opens, she is, after an exceedingly long white
space journey in an actively hostile ship with a (to Sunya at least) an
atavistically off-putting crew, reaching her goal: a vast artifact that I
won't describe further to avoid any spoilers for Ancestral Night.
She is eager to get to work, an eagerness that is both heightened and made
more anxious by the discovery that her academic rival and abusive ex has
arrived before her. The pirate attack doesn't help, nor (at least at
first) does the surprise appearance of her wife and kids.
The opening of this book is a lot of infodumping mixed with nearly
stream-of-consciousness emotional dumping. The style shift in this series
continues to surprise me; previously, Elizabeth Bear books avoided reader
hand-holding to the point of bafflement if you weren't paying close
attention. Not here. The Folded Sky takes the shift perhaps too
far, and I almost stalled out at the start of this book when Sunya's
near-constant self-conscious litany and analysis of fears and concerns
started feeling like whining.
The book picks up considerably after the attempted murder.
About a third of the way through, The Folded Sky feels like it's
settling into a recognizable subgenre of murder mystery except set in the
far future with fascinating technology and aliens. There has been an
attempted murder on a closed station besieged by pirates. There is a law
enforcement officer present, but they don't have a lot of investigative
experience. For various reasons, Sunya decides to start poking around
while being conscious she has no idea what she's doing. The bumbling
detective is a common trope, so I thought that was where the story was
headed.
It is, sort of. There is a mystery and Sunya is involved in solving it.
But that's only a small fraction of what's going on, and by the end of the
book the plot has shifted firmly back to the genre of space opera, with a
side note of family... drama is the wrong word. Whatever one would call a
story about raising a rebellious teenager while trying very hard to not
turn conflicts into actual drama.
I am fascinated by the characterization of this book. Sunya is something
of an emotional mess, but Bear doesn't use that fact in the ways that I
would normally expect. Similar to Ancestral Night, I finished this
book thinking that The Folded Sky is primarily an examination of
rightminding, but a more subtle one than the previous novel.
Rightminding is a central technology of the White Space series, and I
suspect its intended thematic core. Humans in this civilization are
equipped with near-universal implants that allow conscious manipulation of
one's neurotransmitters and thus emotional state, either by the wearer or
by a helpful nearby AI. The fox, the implant used to accomplish this,
comes with some other features such as sensory recordings and the ability
to load ayatanas (James White style
personality recordings to provide some bit of necessary expertise), but
rightminding is its primary and most frequently-used function. It is the
critical technology that allowed humans to break out of cycles of endless
war and join the other peaceful inhabitants of the galaxy in a shared
civilization.
The name is (intentionally, I assume) Orwellian because Bear knows that
many readers, particularly those from the US who have been steeped in
simplistic libertarian ideas, will find the idea profoundly creepy. (This
was a major plot point in Grail.) This
book is not the argument for the technology, though; Bear dealt with that
in Ancestral Night. This book is a look at its practical messiness
for a person who needs a lot of psychological support.
Sunya is anxious, prone to catastrophizing, hates surprises, has some
PTSD-style symptoms around space habitats due to earlier trauma, and is
also dealing with the unwelcome reappearance of her ex-girlfriend who
stole her work. Her first-person narration tends towards insecurity and
anxiety spirals, and in another book this might signal an unreliable
narrator. In this book, though, there are no dramatic emotional
revelations or backstory twists the way there were in Ancestral
Night, and the resolution of her troubled relationship with her daughter
only partly hinges on plot developments. Instead, Sunya muddles through,
with a lot of self-analysis, help from her fox, and a great deal of
support from her wife.
This makes it sounds like the emotional mess at the start of the book is
left unresolved at the end, but that's not true at all. The muddling
through works! Sunya keeps doing things that I thought were foreshadowing
some catastrophe, but she knows herself better than the reader does. Bear
largely avoids the sudden ruptures that are normally used to resolve
emotional problems in fiction. Instead, Sunya spends a lot of time and
energy working on her thinking and her relationships while trying to be
ethical and useful, and those efforts slowly bear fruit.
I'm worried this makes the book sound boring; rest assured that it isn't.
This emotional subplot is only an undercurrent in the novel, and the main
plot has enough weird science, alien aliens, and space opera drama to
satisfy my page-turning desires.
I'm focusing on the emotional arc in this review because I find it so
unusual and so oddly compelling, particularly in retrospect. This is not
how one normally does emotional development in a novel. Sunya's fox and
rightminding aren't even the focus except when the pirates express their
typical libertarian disgust for the idea. Rightminding is an entirely
normal part of Sunya's life that she relies on. It doesn't solve all of
her problems, but it gives her a foundation from which to tackle them in
the slow and frustrating and inconsistent way that is required outside of
novels, via a long series of small decisions to be the person she wants to
be.
I think The Folded Sky will be more hit and miss for readers than the
other books of this series. Sunya was, for me at least, a much harder
character to like early in the book, and it takes quite a while for the
plot to get going. But this is one of those books that I've not stopped
thinking about since I finished it. I think it makes a fascinating pair
with Ancestral Night. The first book makes the philosophical
argument for rightminding, and this book shows the practical reality with
all of its messiness. The Synarche has some significant flaws (including
the status of AIs, which is another interesting subplot), but it's a
workable system.
It feels rare to read a science fiction novel that shows this level of
messiness without pairing it with an argument for radical change, and as
frustrating as it was to read in places, I am intrigued by the overall
effect. Sometimes acknowledging problems and working on them within an
existing framework works.
Followed by a book tentatively titled Shipwreck Star that does not
yet have a release date.
Rating: 7 out of 10
Please consider supporting my work in Debian and elsewhere through Liberapay.
Some months ago I started working on a small experiment: a specialised LLM assistant for Debian maintainers preparing proposed updates for stable and oldstable.
The aim is not to replace review by the Stable Release Managers, nor to automate away maintainer judgement. It is meant to be a pre-advice tool: something maintainers can use while they are still preparing a proposed update, before sending it to other people to review.
If you ve uploaded to stable before you may have some experience with our acceptance criteria. Does the version sort correctly? Is the changelog clear enough? Is the delta focused? Are the patches documented? Are the right bugs or CVEs mentioned? Are they of sufficient severity? What is the risk to users of stable? Is there an ABI change hiding in the diff?
These are the sort of checks where a structured first pass can be useful, provided it is treated as advice rather than authority.
To explain what the tool does, what could be more appropriate in an AI age than to ask it?
Describe yourself and your abilities and limitations for a blog post.
It answers:
I m Debian Stable Update Adviser, a specialised ChatGPT assistant for Debian maintainers preparing proposed updates for Debian stable and oldstable.
My main job is to review a single .debdiff and give practical, policy-aware feedback before a maintainer submits or uploads a proposed update. I focus on whether the update appears suitable for Debian stable or oldstable, especially under the Stable Release Managers expectations for minimal, targeted, low-risk changes.
I can inspect a debdiff for Debian changelog quality, including suite, version, bug references, CVE mentions, and rationale. I can check version correctness using Debian dpkg version semantics. I can review packaging changes under debian/, such as patches, maintscripts, symbols files, conffiles, Build-Depends, autopkgtests, and control metadata. I can also group upstream source changes into behavioural and non-behavioural categories, and flag areas that may carry regression risk.
My reports are intended to be concise and useful to maintainers. A typical review includes a quick summary, behavioural and non-behavioural change breakdown, mechanical policy checks, risk assessment, stable-policy checklist, acceptance likelihood, rationale, maintainer advice, and a clear conclusion.
My limitations are important. I cannot prove that a package builds, that tests pass, that the bug is fully fixed, or that the Stable Release Managers will accept the upload. I also do not replace maintainer judgment, archive review, autopkgtest results, reproducibility checks, or real-world upgrade testing. I can only review the provided debdiff and point out likely issues, risks, and improvements.
I also do not proceed without a valid debdiff. The whole point of my review is to assess the actual proposed delta, not to speculate from package names or bug descriptions alone.
In short, I act as a focused pre-review assistant for Debian stable and oldstable proposed updates: useful for catching policy, versioning, changelog, packaging, and regression-risk issues early, but not a substitute for the Debian review process itself.
That last point is an important one. This is not an oracle, and it is not part of the Debian archive machinery. It is a checklist with some language-model assistance, aimed at reading a debdiff and pointing out things that might be worth another look.
I know that commercial AI and LLM tools are not universally welcome in Debian. That is understandable. Debian depends on transparency, human responsibility, licensing clarity, and technical correctness. LLMs have obvious problems in all of those areas. They can be wrong, and worse, they can be wrong in a fluent and plausible way. They are impossible to reproduce and their training is opaque.
But I see this as a useful first pass for a maintainer who is unused to working in stable, and would benefit from a virtual mentor giving their proposal a quick check and reassurance. Perhaps they don t have a more experienced co-maintainer to ask. Perhaps they are conscious that stable reviews are presently a two-man effort and want to avoid adding round trips to that load. Perhaps they just need some reassurance.
So despite my reservations I am today opening the adviser up for general use, and I m interested in feedback about how it responds to real world proposals in various states. Most of the examples I have tested with already had a green light, so the value added by the adviser is limited. I would especially be interested in seeing a transcript alongside the submitted debdiff.
Try it out
I would dearly love to build this in a more Debian-ish environment, but for now I m limited in resources and skill to do that (help is welcome). Until that s a reality, you can try out the ChatGPT implementation: Debian Stable Update Adviser
Platform Decay is the eighth book in the Murderbot science fiction
series. You absolutely should not start here, but you also don't need to
remember the specifics of the previous books.
As the story opens, Murderbot and a friend (the identity of whom is a
spoiler for previous books) are infiltrating a Corporation Rim torus, a
massive space station that encircles a mined-out planet. (Like most
science fiction megastructures, this is more space than the plot really
requires.) Murderbot's mission is to exfiltrate some of Dr. Mensah's
family members who have become entangled in corporate shenanigans. The
corporates are eager to get revenge for the events of
System Collapse, not to mention the
other times Preservation Station has upended corporate plans. Murderbot's
job is to stop them.
The group, in addition to one of Dr. Mensah's partners, includes an older
woman and a young child. Murderbot is analytical and of course not at all
emotional about children, which is reliably a good time. Also, the older
woman is gruff, stubborn, and thoroughly enjoyable.
There are, of course, complications that lead to picking up more children
and going through rather more of the torus than Murderbot wanted to
explore. Each section of the torus is run by a different corporation and
has a different constructed environment and visual aesthetic, so there are
a lot of opportunities for fights, daring escapes, and incidental trouble.
Also, well:
So I had installed a mental health module. I know, I was surprised I
did it too.
After the events of System Collapse, University Medical decided
that Murderbot needed a bit more metal health support.
The only reason I agreed to it was that the mental health module
didn't actually try to adjust my processing or core programming or
anything; it just monitored my organic neural tissue. When my neural
tissue started to generate weird chemicals and whatever, it would ping
me to "check in with my emotional state." Seriously, I could have
coded that myself.
(I told Dr. Bharadwaj that, and she said, "Would you have ever coded
that yourself?" which was totally unfair and also correct. I would
never have done that.)
Speaking as someone whose neural tissue sometimes generates weird
chemicals and whatever, I sympathize.
The specific form this module takes is periodic "emotion check"
parentheticals throughout the narration, which I found utterly delightful.
I ran that through risk assessment and it produced the equivalent of a
shrug.
(Emotion check: Shrug sigil right back at you, you piece of shit.)
This is otherwise an extended action movie sort of a book, much like
several of the early novellas. There are no major political or
interpersonal developments here and the usual cast (apart from Murderbot)
is mostly absent. Instead, we get an extended, dangerous journey through a
corporation-controlled habitat, mixed with Murderbot trying to interact
with humans in a way that minimizes its annoyance while being hopefully
reassuring. It's competence porn with awkward but surprisingly heartfelt
emotional bonding, not that Murderbot in any way wants to bond or would
appreciate that description.
I doubt this will be anyone's favorite entry into the series since there
are none of the big reveals or major leaps of character development there
have been in the past few books. But, like all Murderbot books, the
narrative tone is wonderful and all of the small asides and little moments
of character interaction are an utter delight. If you've gotten this far
in the series, you know what I mean and you'll be as happy to read more of
it as I was. There is a part of me that is hoping for some major plot
development, and I always want to see more of ART (who has no significant
role in this book), but Wells has the narrative style down so perfectly
that I would read and enjoy a book about Murderbot doing just about
anything.
If you're this far in the series, you probably don't need a review, and
since this is an action-heavy adventure rather than a character growth
novel, I don't have a lot more to add. There's a new short Murderbot novel
out and you want to read it. Recommended to everyone who enjoys the
series.
Rating: 8 out of 10
A new small package of mine just hit CRAN. The tl package wraps the (also
very new) rspdlite package
(announced last
week) to offer a lightweight and consistent logging interface from
both R and C++ that is also tiny, fast, capable thanks to rspdlite.
The rspdlite
announcement is a good place to get a first glimpse at that package;
the upstream spdlite
repo has all the details (for the C++ side of things). With tl we follow the same idea
that our spdl package
introduced: a simple consistent interface via just the tl::
prefix and the appropropriate logging level. In other words
tl::debug("Alert -- foo is at ' '", foo) will work from
both R and C++ (given a variable foo, and in the case of
C++ an extra semicolon). Just give it a try, and see how it goes. The
package is still young and small.
The NEWS entry for this release is also very simple and just
announces that we have a release. More details are in the ChangeLog
and the GitHub
repo.
The seL4 organisation on GitHub uses
git-repo to manage
multiple source repositories, and so there are a large number of
projects to get your head around when figuring out the ecosystem.
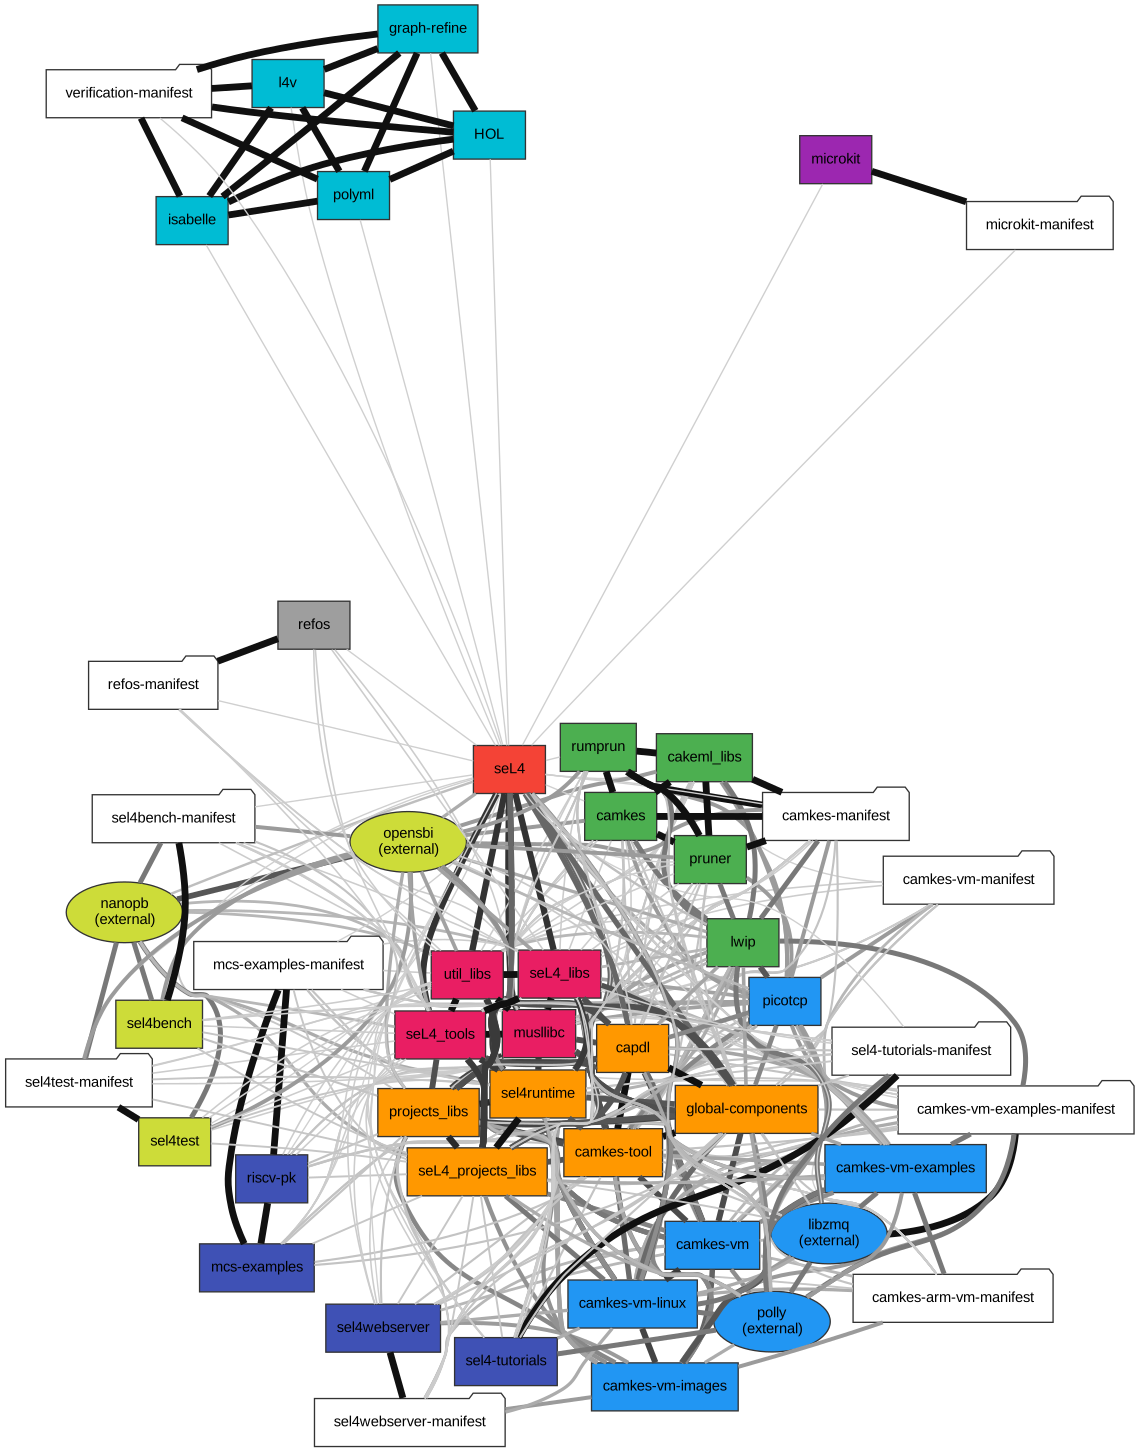
As an experiment, I have taken the various manifest files across the
org, and constructed a graph based on how frequently each pair of
repositories is mentioned in a manifest together. See below:
[This may render badly when syndicated outside of my blog; and also
on small screens. And probably large screens. I ve attempted to make
sure there s a non-JS fallback
on my site with JS enabled, if you hover over a node, it should
highlight connected nodes.]
The colouring of the nodes is mostly manual; I experimented with graph
clustering algorithms but have not found a satisfactory result so far.
Still, some clusters are obvious:
Kernel the seL4 microkernel proper. This often but not
always co-exists with the main cluster of core libraries, but it
is pulled away slightly by the verification and microkit
manifests.
Verification the verification repositories (l4v, HOL,
graph-refine, polyml, isabelle) form a very distinct group.
These are connected only to the seL4 microkernel itself, which is
the only component formally verified.
Microkit microkit is a newer operating system framework
that does not use CAmkES, so stands apart from the rest of the
pack. I chose to scope this work to the seL4 org, so the LionsOS
ecosystem and sDDF which are maintained by Trustworthy Systems are
not shown. Also not linked is rust-sel4, because this modern
world isn t using git-repo in the main to manage its repositories.
RefOS I d not come across refos before, but it appears to
be an example OS from 2021 built on the seL4 kernel.
It s quite hard to pull apart the CAmkES framework and the core
libraries; there are definitely some which are more associated with VM
management, but the overall shape of this co-occurence data is a messy
ball in the middle with some outliers in orbit. One observation is
that camkes is correctly identified as more peripheral than
camkes-tool, which contains the actual core CAmkES code.
Reflecting on this approach, in hindsight I m surprised that using
co-occurences worked as well as it did there was no attempt to
actually inspect the code and find direct mentions of other code
e.g. library header dependencies. As the newer microkit effort
largely eschews git-repo, better results might be found by actually
taking that more detailed approach, so that graph edges could
represent real dependencies between two packages. Additionally, this
could allow diving into the various libraries held in the different
libs repos, to get a more granular graph of relationships between
them.
However, I think I spent more time on making it possible to render
graphviz graphs easily on my blog than actually gaining any insight
into the codebase!
Armadillo is a powerful
and expressive C++ template library for linear algebra and scientific
computing. It aims towards a good balance between speed and ease of use,
has a syntax deliberately close to Matlab, and is useful for algorithm
development directly in C++, or quick conversion of research code into
production environments. RcppArmadillo
integrates this library with the R environment and language and is
widely used by (currently) 1282 other packages on CRAN, downloaded 47.1 million
times (per the partial logs from the cloud mirrors of CRAN), and the CSDA paper (preprint
/ vignette) by Conrad and myself has been cited 697 times according
to Google Scholar.
This versions updates to the 15.4.0 upstream Armadillo release made on
Thursday. We had run a complete reverse-dependency check leading up to
it, asserting there were no issues with packages dependent on it. As it
sometimes goes with that many packages involved, one CRAN package reported one test
failure. And it turned out to be both unrelated and pre-existing. But
sorting this out over one round of email delayed things by a day. And
then I went cycling
for a good cause so this announcement post comes a little later than
usual. The package has also been updated for Debian, built for r2u, and by now also at
CRAN for the different binary
releases.
All changes since the last CRAN release follow.
Changes in
RcppArmadillo version 15.4.0-1 (2026-06-17)
Upgraded to Armadillo release 15.4.0 (Medium Roast Agave)
Added fill::nan, fill::pos_inf,
fill::neg_inf as optional fill forms for the
Mat class
Added .push_back() for appending elements to
vectors
Faster handling of find() within
.elem()
Faster element-wise min() and
max()
Faster conv_to when element types of input and
output objects are the same
Following up on my previous post, I have released the
debvulns CLI. This utility uses
the same parsing logic as the debsecan-mcp server but exposes the
functionality directly via the command line.
Why a new CLI?
While Debian's native debsecan utility exists, it lacks modern output formats
like JSON and CSV, and fails to expose a significant amount of metadata
available in the Debian Security Team's daily snapshot.
Additionally, running a persistent Model Context Protocol (MCP) server
introduces context window overhead. The manifests and tool descriptions required
by the protocol consume tokens even when idle. For debsecan-mcp, the MCP
Inspector utility shows an
overhead of roughly 150 tokens.
By contrast, an LLM can parse a standard CLI help menu on-demand without
permanently draining the context window. Integrating the CLI into a persistent
agent workflow can be achieved via a skill file, allowing the LLM to leverage the
tool without repeated discovery overhead.
What else is NEW?
During testing, I observed discrepancies between the output of debsecan-mcp/debvulns
and native debsecan. Debugging with an LLM revealed a bug in the version
comparison logic
that caused debvulns to underreport vulnerabilities. This has been resolved.
The current interface supports structured formatting and customizable data backends:
By allowing users to override data sources with local snapshots of the Debian
Security Tracker and EPSS feeds, debvulns can run natively in airgapped
environments.
What Next?
The next step is building a Prometheus exporter for this vulnerability data to
streamline scanning and monitoring across data center infrastructure. Stay tuned.
In what is hopefully the conclusion of my hunt for a cheap tower server supporting REBAR [1] I have just bought a HP Z4 G4 with W-2125 CPU for $320.
Hardware
One interesting thing is that it has an adaptor from SATA power to 8 pin PCIe power. According to Wikipedia the 8 pin connector provides 150W at 12V [2]. According to Wikipedia SATA power cables include 3 12V pins each of which can deliver 1.5A [3] which is 54W. The system as I received it had a single SATA power plug connected so potentially 150W could be drawn from a connector designed for 54W. The first thing I did was to connect a second SATA power connector on the same cable so I could have connectors designed for a total of 108W supplying potentially 150W (and definitely more than 75W).
I found two versions of the specs for this system, this version seems to match what I bought as it references W-21xx CPUs [4] while this version matches what I would rather have with a W-22xx CPU [5]. The URL naming scheme implies that there are potentially at least a few other variants out there. So much for the buy name brand and you can buy two systems with the same model and have them work the same benefit you hope to get. Why don t they just name them G4.1 , G4.2 , etc?
It seems that W-21xx and W-22xx CPUs are incompatible, so the W-2295 scoring 30,804 multithread and 2,634 single thread on passmark that I hoped to get isn t an option [6].
The system is well designed for space efficiency, both it and the Z640 are 17cm wide but the Z4G4 allows my to close the lid with the Intel Battlemage card installed which doesn t come close to fitting in a Z640. It has 8 DIMM sockets and with the ready availability of 32G DIMMS that allows 256G of RAM which is the maximum the motherboard supports. That compares well to the Z640 that only has 4 DIMM slots and the Z6G4 which only has 6.
The system supports a maximum RAM speed of DDR4-2666 which is better than the DDR4-2400 of the Z640 but less than the DDR4-2933 of the Z6G4.
The NVMe sockets on the motherboard are a convenient feature. Most systems I run need at most two NVMe devices so this saves a PCIe slot which is important when dealing with GPUs that take 2+ slots. Also for systems that don t really need NVMe I can use some of the small NVMe devices that I have no other use for. 128G NVMe devices aren t even worth selling and 256G will be of little use in the near future. So when I move to gen4 Z servers I can use up some of them without wasting slots.
Using the lesser socket LGA2066 in the Z4G4 is a minor annoyance, but for a single socket system 18 cores is probably enough.
The BIOS has an option for single-socket NUMA, which is basically locking cores in a single CPU to specific RAM channels. I enabled it but it did nothing presumably because I only have 2 DIMMs. When I get more DIMMs I ll do some tests of that and compare it with NUMA on my Z840.
Variants
There are many different variants of the Z4G4 and the only way to recognise them is by the CPU not by any part number or serial number AFAIK. The first difference is between server grade CPUs (the W-2xxx CPUs) and desktop grade CPUs (the i7 and i9 CPUs). The systems with i7 and i9 CPUs don t support ECC RAM which makes them less reliable, gives smaller limits for RAM
The below table compares the Z640 which is my current desktop PC with the Z4G4, Z6G4, and Z8G4 systems. For the latter 3 I have included multiple options for the parts that differ in different models in the same name series. The Z4G4 I have is an early one which only supports W-21xx CPUs which means a maximum RAM speed of 2666 and the best possible CPU would only be 15% faster than my Z640. I can only use this for ML stuff as it s the only system I have with REBAR support (which works well).
Z640 (1 socket)
Z4G4
Z6G4 (1 socket)
Z8G4
DIMM slots
4
8
6
24
Max DDR4 speed
2400
2666/2933
2666/2933
2666/2933
Max DIMM size
32G
64G
64G
64G/128G
System Max Ram
128G
512G
192G/384G
1.5T/3T
CPU Socket
LGA2011-3
LGA2066
LGA3647
LGA3647
Best CPU
E5-2699A v4
W-2195/W-2295
Platinum 8180/W-3275
Platinum 8180/8280
Motherboard NVMe
0
2
2
?
Conclusion
In my previous blog post I concluded that the next step up for me would be DDR5 systems [10]. But now some of the LGA3647 systems are appealing. The Z8G4 would be a decent upgrade from my current Z840 build server and should be affordable long before any two socket DDR5 system becomes affordable.
The Z4G4 doesn t have any potential for useful upgrades. But for me it was a good cheap way to house a GPU that had already damaged the motherboard of one good system. If the Z4G4 has a PCIe slot break the way my Z840 did then it wouldn t bother me a lot. It was annoying to discover how limited this variant of the Z4G4 is after buying it, but at that price I can t complain.
A Z6G4 could be a nice workstation if I found one at a really low price. The only reason I d seek one out is if I had a need for a desktop workstation with REBAR support, which seems unlikely.
The Problem
In 2019 I blogged about getting a 4K monitor because of my vision being inadequate for a 2560*1440 monitor [1]. Now I m using a 40 5120*2160 monitor [2] and still trying to find the correct balance between how much I want to see on the screen and what I am physically capable of seeing on screen.
Currently Kitty is my terminal emulator of choice [3]. What I most like about it is the feature of having multiple terminal windows in a single OS window, so instead of having 9 or 16 different xterm instances running all with possible alignment issues I have a single window for all terminals which can be brought to the foreground. The impending 6.7 release of KDE (my favourite Linux desktop environment) [4] includes the feature of per-screen virtual desktops which might be the feature I need to make multiple monitors usable for me. One of the factors stopping me from using multiple monitors in the past was the issue of not getting the alignment of dozens of xterms right if a monitor goes to sleep mode and is regarded as disconnected, moving a few Kitty windows is much easier than moving dozens of xterms (also a tiling window manager isn t my style).
I ve just decided that the Terminus font (my favourite out of the monospaced fonts in Debian) is too small for me at 9.0 point. But then I tried 10.0 which looked really ugly and an experiment showed that 10.5 looked good.
What I ve Learned
This is the best explanation I ve seen of how ridiculous the whole font point thing is [5]. It doesn t and won t ever correlate to pixels. So what we ideally want to do is set the size on screen to match the actual pixel size of the font. I can t find any software to interrogate a font file and find out what sizes it supports. The web page for the Terminus font says that it supports 6 12, 8 14, 8 16, 10 18, 10 20, 11 22, 12 24, 14 28 and 16 32 [6]. So the question is how to get a terminal program that uses one of those.
Kitty doesn t and won t support specifying font size by pixel. I tried some other terminal programs, I started with the Debian Wiki page TerminalEmulator [7] which wasn t very helpful, I added some new entries to that page. There doesn t seem to be another option for a terminal emulator with multiple terminals in one OS window that can arrange them automatically. I didn t even get to the stage of checking whether other terminal emulators supported font size in pixels.
The lcdf-typetools package contains the program otfinfo which gives some interesting information on fonts but nothing about the font sizes in pixels.
Sites like Coding Font to compare fonts [8] can never work properly as the fonts will always be slightly different sizes as the same point size doesn t mean the same display size.
The Current Situation
On my 5120*2160 monitor with 9 Kitty terminal sessions with 9.0 point font they each have 277*50 characters. With 10 point it s 237*46 but fuzzy and unpleasant to read. With 10.5 point it s 208*43 which isn t as good as I m used to but is still almost 4.5* as many characters as the original 80*25 standard for terminals.
Some time before 2019 I had a 4*4 array of terminal windows that were 100*25 or 120*25. That left some space at the right and bottom so I could open another 8 or 9 terminals that were partially obscured if I needed to. By 2019 before getting a 4K monitor I had a 3*3 array of terminal windows as my standard desktop and a larger monitor that did 4K resolution allowed me to have 16+ terminals again. Now with Kitty I routinely have 9 terminals in a 3*3 array and I can easily open more if I need them and have them resize appropriately.
This situation works reasonably well, but the element of just trying different sizes in 0.5 point increments until I find something that looks good is unpleasant. I should be able to specify the next largest increment of the bitmaps in the font and just have it look good.
Conclusion
It would be good if more people tested the terminal emulators in Debian and added information to the wiki page about them. The current page is useful but needs more information to support the variety of features that people find important.
We need some tools to provide information on fonts in Debian, such as the sizes of bitmapped fonts.
The whole point size thing is just wrong and would ideally go away. The vast majority of font use nowadays is for things that will probably never end up on a printed page so trying to map it to a physical size in fractions of an inch makes no sense. But that s just one of many horrible things used for backwards compatibility that aren t going to go away any time soon. Really everything involving inches should go away.
systemd. Yes, in full lowercase. If there was ever a technology to cause
controversy in the Linux world, this is it. Since its inception in 2010,
systemd s goals were set quite high: to replace the vital part in every
Linux system that takes care of the system boot process. It quickly reached
maturity, allowing it to be adopted as the main init system in most major
distributions just five years later. Despite describing events that
happened over a decade ago, systemd adoption still raises the temperature
in any Linux-related discussion.
David Both s comprehensive book tackles the what, why, and how issues
surrounding systemd. Carefully divided into 16 chapters, going from the
basics and some of the technical and political history behind the project
to the different subsystems and aspects covered by systemd, its almost 450
pages can scare people away. But the text is written in a very clear,
tutorial-like fashion, and while it can be read sequentially,
cover-to-cover, readers can also pick a single aspect and jump straight to
the relevant chapter.
A frequent criticism of the systemd project is that it aims to basically
rewrite all of a Linux system, and just looking at this book s index shows
there is some truth to it. The first chapter is an introduction to the
systemd project and a brief overview of its history (including the
controversies around it), and the following four chapters deal with
understanding and controlling the system boot process.
That leaves ten chapters to cover different aspects or subprojects of
systemd, such as time and date issues (synchronization, time
specifications, and controlling repetitive tasks), understanding and
leveraging the system journal that strongly departs from the old syslog
system, network configuration and firewall management, system health and
performance debugging all aspects that in the traditional Unix philosophy
were managed by independent programs. And I can identify several systemd
subprojects not covered by this book!
We long-time Unix and Linux administrators took pride in how highly
performant and stable systems were supported by the simplicity of our
tools; systemd critics point out this massive project has absorbed dozens
of individual tools, yielding corporate control over vast swaths of vital
system tooling. Truth is, as a sysadmin myself, systemd is today one of my
greatest allies.
I appreciate how the author evaluates every component independently,
including his personal evaluation of each even acknowledging when he
prefers working with the traditional programs.
If I had to note one criticism: given the many console captures, having a
maximum width below 70 characters means several lines are unnaturally cut
short (and continued with odd indentations). There is probably no right
way to solve this, but it does affect the reading experience.
Through work, I have paid license to windsurf
(recently renamed to "devin"), an application for LLM-based (aka,
"Agentic") development.
I hadn't been using it that much, but in an effort to more clearly
understand how this whole AI development thing works, I decided to give
it a closer look recently.
My conclusions:
In its current form, this whole LLM wave is problematic for multiple
reasons. But ignoring that, and looking at the technology only, I can
say that:
it is a paradigm shift;
it is, at the technological level, a positive evolution;
and it is a threat to free software.
Problems
Lest someone (incorrectly) assume that I am arguing in favour of the
current state of affairs with regards to LLMs, let me state this first.
The way LLMs are built today is highly parasitic. Websites are
downloaded in whole, at unsustainable rates, regardless of the consent
of the people who made the original content. The result is predictable:
servers get overloaded, server administrators attempt to implement
various mitigations. Some of these mitigations work; some do, for a
while; some are entirely useless. In actual fact, the mitigations are an
arms race -- if too many people implement the same mitigation, then the
people who try to build yet another LLM so they can extract rent will
just try to work around the mitigation, eventually they will succeed,
and you'll just have to come up with another mitigation. It's a bit like
spam; you introduce regex-based spam filters, they introduce spelling
mistakes, you introduce bayesian filters, they add a large batch of
markov chain-generated semi-nonsense words made invisible by markup, you
add filters to block emails with such markup, they move the text into an
image. We have working mitigations today, but eventually we'll run out
of ideas.
LLMs glob up everything they can while ignoring the license of the
source material. The people who push those LLMs claim that pushing the
source material through the machine learning algorithms makes the output
of the algorithm distinct enough from the source material that the
license no longer applies; I'm not so sure that this is true. I guess
the New York Times v OpenAI
lawsuit
will teach us some of the answer to that question here, but even so
the ethical questions about "is it OK to bring down another server just
so we can download the internet for another for-pay LLM" are still
open. And regardless of what the law states, my opinion on "you're using
my copyleft code to generate code under a different license" is not
something you might like if you agree with the rent seekers' opinion on
the subject.
That all being said and true, the technology works. You can have a
"conversation" with an LLM that resembles a human one. If you pass it
some data, you can use plain english to ask it questions about that
data, which is a lot easier than to ask it about that in a formal way.
You can request it to generate some code, and it will generate something
that looks like what you need and that will be mostly correct for like
95% of the time.
Now, yes, 95% of the time is not 100% of the time, and no, you can't ask
it to "write me a piece of software that implements this 300-page
requirements document and get back to me when you're done", because it
will fail, and you won't know where it has failed, and you'll take it
into production and expect everything to be fine because it won't and
this one minor logic bug will cause half your servers to spin and
consume credits with your infrastructure provider with nothing to show
for it.
But that doesn't mean you can't use an LLM to build a large piece of
software. It just means you have to understand the LLMs limitations and
strenghts, and use them correctly.
Here's what an LLM is good at:
Generating plausible text
Interpreting text to figure out what a plausible meaning or summary of
that text is
Giving vague indications as to what the probable context of a given
body of text is.
It turns out that that's enough to use the LLM to build a reliable piece
of software, provided you do it right.
Paradigm shift
An LLM can generate text by the truckful. The generated text could be
code. Given a good enough LLM, the generated text might even run and do
something useful.
You can try to blindly run the code, and if it doesn't run correctly,
you can paste the error message to the LLM, and it can tell you what
went wrong and how you could possibly fix it. This creates a feedback
loop: you ask it for an amount of code, you run the code, you receive an
error, you tell it that the code is problematic and give it the error
message, it makes changes to the code, now you have something that at
least no longer fails at startup.
If you ask it to add tests to make sure that your code acts as per your
specification, now you get an error if and when the code doesn't act
as per your specification. Or, well, at least not as per the part of the
specification that was correctly turned into a unit test by the LLM.
LLMs have a context window, so if the error message is pasted in the
same conversation as where the code was generated, it is able to reuse
the earlier prompts to refine how it should interpret the error message
that you received.
You can't really paste the source code of an entire application into the
prompt of your LLM, that would quickly overrun its context window. But
LLMs also allow you to provide some form of background information --
a document, say -- on which you ask it to reason. It will interpret that
document, but doing so uses less of the LLMs context window. So
providing the LLM with your application's source code as background
information can help it understand better how your code interacts. This
is especially helpful if you only provide the LLM the background
information relevant to the actual question.
So now if you are able to:
Create background context with your application's source code
Have the LLM generate a first draft of your requested change, plus the
tests to make sure it works
Compile (if applicable) the generated code (and tests) and run said
tests
Return any error messages to the LLM with a request to correct the
error
Then the combination of "getting it 95% right off the bat" and the above
feedback loop means you can generate syntactically correct code, that
probably does what you need, in minutes.
I say "probably" for a reason. There are going to be cases where you
specify a request without a number of details (because they are
implied), and the LLM will get most of those details right but just not
implement the one bit because it's an automaton and it doesn't think. Or
you will ask it to make sure that two bits of the application look
exactly the same, without specifying that they must act the same, now
and in the future, and it will just generate the same block of code
twice and then in a future change it will change one but not the other.
But if you review the changes, and you have experience as a
programmer, you will be able to spot most cases where the LLM got it
wrong. And so it's possible, if not necessarily easy at first, to
use an LLM to generate mostly correct code.
There are certain places where "mostly correct" code is not desireable.
But equally, there are also cases where, "mostly correct" is good
enough.
After all, most of the software you run today -- the bits of it that
weren't, yet, generated by an LLM -- is only "mostly correct", too,
because to err is human and we all make mistakes. If not, there wouldn't
be any CVEs and your software would never do anything wrong.
Now, doing the feedback loop described above is certainly something you
could do manually. You could open an account on one of the LLM websites,
upload the source code of your application, ask it to generate some new
feature, download the newly generated feature, run it, and then
copy/paste any error messages back into the LLM.
But that's a lot of manual work of the type that computers are pretty
good at. So that's what the "windsurf" tool helps you with: you run it
inside your IDE -- either a VSCode-based tool that you download from
their website which comes with their product preinstalled, or a separate
JetBrains plugin that you can install. You can then open your entire
relevant codebase in a workspace in your IDE. You then ask the LLM,
through the IDE, to generate a new feature in your codebase, and to also
generate the test while it's at it. It will use a mixture of LLM
interpretation and non-LLM functionality to scoop out the relevant bits
of your codebase to send to the LLM as background information, will send
it your prompt, will download the generated code and patch or create
files, will compile (if required) and run the newly generated code and
tests, and will refine the generated code if the tests produce any
errors. All mostly automatic; by default, running anything requires
explicit confirmation. You can turn that off completely (probably not a
good idea), or you can give it a whitelist of things that you don't want
to confirm (perhaps OK), and the tool also passes standing instructions
to the LLM to never generate any command that deletes a file (which,
like with any LLM, can be overridden, but it requires you to be very
stubborn and to use more credits than you'd probably like).
All this put together means you can build something without writing any
piece of code, provided you do it right.
A technically positive evolution
Don't go and say, "here's a 300-page document, read it and write
whatever the document says". It will get it wrong, it will write a
massive test suite that it will only run at the end, it will choke
itself up trying to interpret the massive amount of failures it
encounters, it will fill up its context window and it will start to
forget some of the requirements. That won't work.
But what you can do -- what I did, in fact -- is this.
First, create an empty workspace. Don't put any code in it.
Then, tell the LLM to generate a backend framework using technology X
and a frontend framework using technology Y that initially only says
"hello, world". Also add tests to it, and run the tests.
It will do that. You'll not get much, but it will work.
Then, ask it to add some UI elements. A login page, perhaps. A
navigation bar. Small things. Most of it doesn't have to be functional
-- but tests must be there for the bits that are, and have it run the
tests and evaluate the results.
Rinse, repeat, until you have a working application.
Importantly, in between the steps, you should also run the application
yourself and see if the change was implemented correctly. Sometimes it
won't be. Sometimes there will be a subtle bug -- I at one point had a
the application hang after a few minutes. Sometimes you tell it that
there's a subtle bug, and it will discover it more quickly than you
could, and it will fix it, and in implementing the fix it will uncover
another bug, and then you have to fix that one -- the fix it came up
with for the hang was to move something to an async process on the
server, which caused the application to start spinning while trying to
create hundreds of async jobs (this is when I realized that the hang was
a deadlock due to some part of the codebase doing something that
indirectly triggered itself). Sometimes it will try to fix the bug you
tell it about, and you'll see that it's going off on a tangent that has
nothing to do with what you're seeing. It's important to keep an eye on
what it's doing, so you can guide it back on track when that happens --
when I told it about the hang, it started investigating the part of the
code which sends out emails, thinking that it could hang while waiting
for sendmail to finish, but the hang was happening when the
application was idle, not when it was sending out emails, and only
when I told it about it happening when it was idle did it find the
deadlock.
So it's not a fully automatic process, and it needs to be guided by
someone who knows what they're doing. But if that is the case, you can
come up with something that works. I spent evenings and breaks for about
a week, and I managed to create a working application which, had I
written it by hand, would have taken me a few months of full-time work
to come up with. And I now have a side project, fully complete and
working, that I had been thinking about doing for more than a decade,
but never got around to actually doing, because of all the work that
would be involved and I just didn't see myself having the time for.
It's not perfect code. But it's mostly good enough, and it will perform
the job it needs to. And it looks far slicker than most of the side
projects I've done in the past, because in the past I would prioritize
between implementing new features or making something look slick, and I
would decide that the new feature was more important because it's only
for me and there's only me and nobody cares if it looks good or not and
I don't have three weeks to come up with something that looks better.
But here, I found myself sometimes spending 10 minutes writing a prompt
with instructions on making things look better. Because what's 10
minutes when you just spent an hour writing down and refining
specifications for functionality and tests?
There are a number of other things in which an LLM can help a
programmer.
For instance.
I received a bug report recently in a project I'm paid to
maintain that I couldn't make heads
or tails of. I opened the source code in my windsurf IDE, pasted the bug
report in the prompt, and then requested the tool to analyze the source
code and the associated logs and tell me how the described behavior
could be happening. It turned out that I had overlooked something, but
with the help of the tool, I found the bug in minutes.
I was trying to understand a particular part of a large
codebase that I didn't really grasp very well.
I loaded the codebase in the tool, and asked it to explain to me how a
particular action is performed by the code. I requested specific
functions and line numbers. I now have a far better understanding of how
the code works, and will be able to write that patch that I've been
wanting to write for years -- without using the LLM.
I have been struggling for, literally, years with understanding why
another tool that I
maintain was
misbehaving in a particular way but only in Firefox. I opened the
codebase in Firefox, explained the buggy behavior in plain English, and
asked it to explain how this could be happening. It picked up some
obscure corner case behavior of ffmpeg and mp4 containers that I was not
aware of and that perfectly explained why things were misbehaving in the
way that they were.
At the same time, there are limitations. Giving an LLM a codebase that
was originally generated by an LLM (either the same one or another one)
seems to work well. Giving it a codebase that was written by a human and
expecting it to correctly update it seems to be more error-prone. I did
one or two of those as a trial, and it is more problematic than
anything.
An LLM is also not intelligent, notwithstanding the popular term of
"Artificial Intelligence". On multiple occasions, I've asked it to write
a test case for some code that was not set up to do so; and rather than
suggesting a refactor is required, it would instead copy the code that
needed to be tested and then test the copy, rather than the original.
The tool has made multiple similar errors. I have sometimes people
describe agentic coding as "similar to interacting with junior
programmers", but that is not the case. A junior programmer will either
fill in the gaps in your specifications, or ask for clarification when
something seems off. The LLM will not do that; it will do what you ask,
exactly that and nothing more. If you missed a corner case in your
specification, then all bets are off.
I remember learning about programming language generations in college.
A first-generation language is "machine code", a second-generation
language is "assembler", a third-generation language is any high-level
language such as C, Perl, or Pascal. I've forgotten what set a
3rd-generation language apart from a 4th-generation language. But I
remember the definition they gave me for a 5th-generation language: "you
tell the computer what to do, and it will do it". At the time, I thought
it was ridiculous. Nobody could ever write something like that.
But it's here.
And it's a threat to free software.
A threat to free software?
Yes.
There is the obvious part where most of the well-known LLMs are non-free
software. I mean, there
are
some "open source" LLM models. The windsurf tool that I used doesn't allow
you to use them (directly), but they're there. There are also open
source applications that implement what the
windsurf editor does. So it's definitely possible to work like this
without resorting to non-free software and non-free services, even
though the non-free LLMs might be a bit ahead of the curve of the free
ones. But that's not what I mean.
And there is also the obvious thing which I mentioned earlier in this
post, which is that the people who try to build LLMs are doing it in
unethical, disgusting ways, causing downtimes and disregarding licenses
for whatever they can get their grubby hands on. Ideally we wouldn't be
in that situation, and ideally this wouldn't be a problem, but we are
where we are.
And there's the obvious thing where the OSI sold itself out and declared
that a machine learning program can be open source even when the very
things it was built from -- the training data -- is not available.
That's a major issue that the free software community needs to fight
against, but there's not really anything that that is a threat to free
software. You just build your own, free software, LLM, and you're done.
The actual threat is in funding and developer support.
Most large businesses do not care about free-as-in-freedom software.
They like the free-as-in-beer part, and they appreciate that the
free-as-in-freedom bits can make the software more customizable. They
are (mostly) happy to do sponsorships of the free-as-in-freedom projects
that they use if that means their free-as-in-beer usage of the software
gets improved.
But why would you care about all that when you can just generate the
code you need, rather than interacting with an open source community
that may or may not care about your business's interests?
Where to go from here
Although I think the moral and environmental issues with LLMs are real
and problematic, given the experiments I did I am not convinced that the
concept of interacting with a computer system in natural language and
to use it to generate code is necessarily deficient. There are pitfalls,
but they can be managed. It is possible to use such a system to create
throwaway, proof-of-concept type "good enough" code bases. It can be
used to interpret code bases and to understand bug reports.
I believe that the major issue with LLMs has to do with that saying
about hammers and nails:
If all you have is a hammer, then everything looks like a nail.
LLMs are an outgrowth of machine learning, pushed by large corporations.
These large corporations have a lot of money. If all you have is money,
then every problem can be fixed by throwing more money at it. The
initial language models were promising but not (yet) good enough, and it
seemed that one way in which they could be improved was to increase the
scale of the statistics: throw more hardware (and thus money) at it, and
rather than improving the efficiency of the models, just scale up.
Scaling up is something that megacorporations are very good at. It's
only a money problem, after all. Does that mean that "scaling up"
is the only way to improve the models, though? I'm not convinced.
Some hardware, such as most modern Apple and Samsung devices, ship with
accelerator hardware for machine learning algorithms. There are some
models that are small enough to be able to run on these devices. I don't
see why it should not be possible to create a small(er) language model
that can do some useful part of the above-described use cases; if not
locally, then at least on a server that one can run on-prem rather than
requiring that you pay rent to one of the LLM companies.
The Software Freedom Conservancy has
published an aspirational statement on machine learning-assisted
programming
that, I think, gets a lot right. It's not quite a definition, but it's
something to keep in mind.
Perhaps that's the way forward?
More questions than answers at this point, anyway.

 I previously wrote about the
upcoming
 I had intended that the next release of onak, my OpenPGP keyserver, would be 0.7.0, and include OpenPGP v6 support (
 A new small package of mine just hit
 [This may render badly when syndicated outside of my blog; and also
on small screens. And probably large screens. I ve attempted to make
sure there s a

 Following up on my previous

 Through work, I have paid license to
 looking for last. I realized it's gone. what's my replacement?