Search Results: "ana"

3 January 2026

Benjamin Mako Hill: Effects of Algorithmic Flagging on Fairness: Quasi-experimental Evidence from Wikipedia

Note: I have not published blog posts about my academic papers over the past few years. To ensure that my blog contains a more comprehensive record of my published papers and to surface these for folks who missed them, I will be periodically (re)publishing blog posts about some older published projects. This particular post is closely based on a previously published post by Nate TeBlunthuis from the Community Data Science Blog. Many online platforms are adopting AI and machine learning as a tool to maintain order and high-quality information in the face of massive influxes of user-generated content. Of course, AI algorithms can be inaccurate, biased, or unfair. How do signals from AI predictions shape the fairness of online content moderation? How can we measure an algorithmic flagging system s effects? In our paper published at CSCW, Nate TeBlunthuis, together with myself and Aaron Halfaker, analyzed the RCFilters system: an add-on to Wikipedia that highlights and filters edits that a machine learning algorithm called ORES identifies as likely to be damaging to Wikipedia. This system has been deployed on large Wikipedia language editions and is similar to other algorithmic flagging systems that are becoming increasingly widespread. Our work measures the causal effect of being flagged in the RCFilters user interface.

Screenshot of Wikipedia edit metadata on Special:RecentChanges with RCFilters enabled. Highlighted edits with a colored circle to the left side of other metadata are flagged by ORES. Different circle and highlight colors (white, yellow, orange, and red in the figure) correspond to different levels of confidence that the edit is damaging. RCFilters does not specifically flag edits by new accounts or unregistered editors, but does support filtering changes by editor types.
Our work takes advantage of the fact that RCFilters, like many algorithmic flagging systems, create discontinuities in the relationship between the probability that a moderator should take action and whether a moderator actually does. This happens because the output of machine learning systems like ORES is typically a continuous score (in RCFilters, an estimated probability that a Wikipedia edit is damaging), while the flags (in RCFilters, the yellow, orange, or red highlights) are either on or off and are triggered when the score crosses some arbitrary threshold. As a result, edits slightly above the threshold are both more visible to moderators and appear more likely to be damaging than edits slightly below. Even though edits on either side of the threshold have virtually the same likelihood of truly being damaging, the flagged edits are substantially more likely to be reverted. This fact lets us use a method called regression discontinuity to make causal estimates of the effect of being flagged in RCFilters.
Charts showing the probability that an edit will be reverted as a function of ORES scores in the neighborhood of the discontinuous threshold that triggers the RCfilters flag. The jump in the increase in reversion chances is larger for registered editors compared to unregistered editors at both thresholds.
To understand how this system may affect the fairness of Wikipedia moderation, we estimate the effects of flagging on edits on different groups of editors. Comparing the magnitude of these estimates lets us measure how flagging is associated with several different definitions of fairness. Surprisingly, we found evidence that these flags improved fairness for categories of editors that have been widely perceived as troublesome particularly unregistered (anonymous) editors. This occurred because flagging has a much stronger effect on edits by the registered than on edits by the unregistered. We believe that our results are driven by the fact that algorithmic flags are especially helpful for finding damage that can t be easily detected otherwise. Wikipedia moderators can see the editor s registration status in the recent changes, watchlists, and edit history. Because unregistered editors are often troublesome, Wikipedia moderators attention is often focused on their contributions, with or without algorithmic flags. Algorithmic flags make damage by registered editors (in addition to unregistered editors) much more detectable to moderators and so help moderators focus on damage overall, not just damage by suspicious editors. As a result, the algorithmic flagging system decreases the bias that moderators have against unregistered editors. This finding is particularly surprising because the ORES algorithm we analyzed was itself demonstrably biased against unregistered editors (i.e., the algorithm tended to greatly overestimate the probability that edits by these editors were damaging). Despite the fact that the algorithms were biased, their introduction could still lead to less biased outcomes overall. Our work shows that although it is important to design predictive algorithms to avoid such biases, it is equally important to study fairness at the level of the broader sociotechnical system. Since we first published a preprint of our paper, a follow-up piece by Leijie Wang and Haiyi Zhu replicated much of our work and showed that differences between different Wikipedia communities may be another important factor driving the effect of the system. Overall, this work suggests that social signals and social context can interact with algorithmic signals, and together these can influence behavior in important and unexpected ways.

The full citation for the paper is: TeBlunthuis, Nathan, Benjamin Mako Hill, and Aaron Halfaker. 2021. Effects of Algorithmic Flagging on Fairness: Quasi-Experimental Evidence from Wikipedia. Proceedings of the ACM on Human-Computer Interaction 5 (CSCW): 56:1-56:27. https://doi.org/10.1145/3449130.

We have also released replication materials for the paper, including all the data and code used to conduct the analysis and compile the paper itself.

Emmanuel Kasper: Storing GPG private keys on a dedicated device

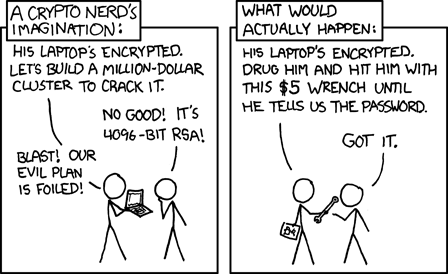
The limits of cryptography Since this blog post is about security and cryptography, it makes sense to start with this XKCD reminder about the value of encryption: xkcd crypt wrench. There is a similar, complementary discussion in this article: crypto can help but cannot safeguard against all actors. Public Key encryption 101 GPG, the most widely used tool for end to end email encryption and signing software releases, is based on public key cryptography. In public key cryptography you have a private key, to keep very private and a public key you share to the world. If you use SSH with key authentication you know already the concept:
$ ls -1 .ssh/id_rsa*
.ssh/id_rsa
.ssh/id_rsa.pub
Here id_rsa is the private key and id_rsa.pub the public key. GPG private key on a hardware token I would like to store the private part of my GPG key on a hardware token. This provides extra security compared to storing the private key on a hard disk: as the private key stays on the device, you need physical access to the device to do anything with the private key. It also eases the usage of the private key on different computers, as you just have to take the hardware token with you without creating multiple copies of the precious private key. That is the basic, some people explains the topic better than me. The hardware token I chose is a YubiKey because I already use such a dongle for two factor authentication on salsa, the Debian gitlab forge. Some terminology Understanding GPG and even worse hardware tokens, is like sailing in an endless sea of acronyms and recommendation practices. Let us navigate: First the generic name of a GPG hardware token is an OpenPGP smart card. Here we need to understand:
  • OpenPGP is a standard for public key cryptography, GPG is an implementation of the standard. We refer to the device category by the name of the standard it implements: OpenPGP.
  • the first existing hardware tokens had the form of a smart card, that is a credit-card form factor with a small chip inside. Today most devices implementing the OpenPGP card protocol take the form of an USB key. But even in the form of a USB key, the token will implement the generic smartcard protocol (CCID, for Chip Card Interface Device) so that it can talk to upper software layers.
Standards support in YubiKey The YubiKey itself supports multiple standards, the OpenPGP card protocol being only one of many. This is what my YubiKey supports:
$ ykman info   awk '/Applications/,0'
Applications
Yubico OTP  	Enabled
FIDO U2F    	Disabled
FIDO2       	Disabled
OATH        	Enabled
PIV         	Disabled
OpenPGP     	Enabled
YubiHSM Auth	Disabled
Since I already threw 5 acronyms on the paragraph above, I will not go in details into what OATH and PIV are. What is important for us here, is that we have OpenPGP enabled on the device, more important we can verify that GPG sees a card with:
gpg --card-status   grep -E '(Application type Manufacturer)'
Application type .: OpenPGP
Manufacturer .....: Yubico
Next steps Now with this basic understanding, you can follow the Debian Keyring maintainer guide for key creation good practises, and the Debian Wiki smart card article on how to move the private keys to the YubiKey. Although the article is for a different device, I also found the topic is even more better described in the NitroKey documentation. XKCD License: https://xkcd.com/license.html You can also comment this post via Mastodon

Louis-Philippe V ronneau: 2025 A Musical Retrospective

2026 already! The winter weather here has really been beautiful and I always enjoy this time of year. Writing this yearly musical retrospective has now become a beloved tradition of mine1 and I enjoy retracing the year's various events through albums I listened to and concerts I went to. Albums In 2025, I added 141 new albums to my collection, around 60% more than last year's haul. I think this might have been too much? I feel like I didn't have time to properly enjoy all of them and as such, I decided to slow down my acquisition spree sometimes in early December, around the time I normally do the complete opposite. This year again, I bought the vast majority of my music on Bandcamp. Most of the other albums I bought as CDs and ripped them. Concerts In 2025, I went to the following 25 (!!) concerts: Although I haven't touched metalfinder's code in a good while, my instance still works very well and I get the occasional match when a big-name artist in my collection comes in town. Most the venues that advertise on Bandsintown are tied to Ticketmaster though, which means most underground artists (i.e. most of the music I listen to) end up playing elsewhere. As such, shout out again to the Gancio project and to the folks running the Montreal instance. It continues to be a smash hit and most of the interesting concerts end up being advertised there. See you all in 2026!

  1. see the 2022, 2023 and 2024 entries

1 January 2026

Russ Allbery: 2025 Book Reading in Review

In 2025, I finished and reviewed 32 books, not counting another five books I've finished but not yet reviewed and which will therefore roll over to 2026. This was not a great reading year, although not my worst reading year since I started keeping track. I'm not entirely sure why, although part of the explanation was that I hit a bad stretch of books in spring of 2025 and got into a bit of a reading slump. Mostly, though, I shifted a lot of reading this year to short non-fiction (newsletters and doom-scrolling) and spent rather more time than I intended watching YouTube videos, and sadly each hour in the day can only be allocated one way. This year felt a bit like a holding pattern. I have some hopes of being more proactive and intentional in 2026. I'm still working on finding a good balance between all of my hobbies and the enjoyment of mindless entertainment. The best book I read this year was also the last book I reviewed (and yes, I snuck the review under the wire for that reason): Bethany Jacobs's This Brutal Moon, the conclusion of the Kindom Trilogy that started with These Burning Stars. I thought the first two books of the series were interesting but flawed, but the conclusion blew me away and improved the entire trilogy in retrospect. Like all books I rate 10 out of 10, I'm sure a large part of my reaction is idiosyncratic, but two friends of mine also loved the conclusion so it's not just me. The stand-out non-fiction book of the year was Rory Stewart's Politics on the Edge. I have a lot of disagreements with Stewart's political positions (the more I listen to him, the more disagreements I find), but he is an excellent memoirist who skewers the banality, superficiality, and contempt for competence that has become so prevailing in centrist and right-wing politics. It's hard not to read this book and despair of electoralism and the current structures of governments, but it's bracing to know that even some people I disagree with believe in the value of expertise. I also finished Suzanne Palmer's excellent Finder Chronicles series, reading The Scavenger Door and Ghostdrift. This series is some of the best science fiction I've read in a long time and I'm sad it is over (at least for now). Palmer has a new, unrelated book coming in 2026 (Ode to the Half-Broken), and I'm looking forward to reading that. This year, I experimented with re-reading books I had already reviewed for the first time since I started writing reviews. After my reading slump, I felt like revisiting something I knew I liked, and therefore re-read C.J. Cherryh's Cyteen and Regenesis. Cyteen mostly held up, but Regenesis was worse than I had remembered. I experimented with a way to add on to my previous reviews, but I didn't like the results and the whole process of re-reading and re-reviewing annoyed me. I'm counting this as a failed experiment, which means I've still not solved the problem of how to revisit series that I read long enough ago that I want to re-read them before picking up the new book. (You may have noticed that I've not read the new Jacqueline Carey Kushiel novel, for example.) You may have also noticed that I didn't start a new series re-read, or continue my semi-in-progress re-reads of Mercedes Lackey or David Eddings. I have tentative plans to kick off a new series re-read in 2026, but I'm not ready to commit to that yet. As always, I have no firm numeric goals for the next year, but I hope to avoid another reading slump and drag my reading attention back from lower-quality and mostly-depressing material in 2026. The full analysis includes some additional personal reading statistics, probably only of interest to me.

Russ Allbery: Review: This Brutal Moon

Review: This Brutal Moon, by Bethany Jacobs
Series: Kindom Trilogy #3
Publisher: Orbit
Copyright: December 2025
ISBN: 0-316-46373-6
Format: Kindle
Pages: 497
This Brutal Moon is a science fiction thriller with bits of cyberpunk and space opera. It concludes the trilogy begun with These Burning Stars. The three books tell one story in three volumes, and ideally you would read all three in close succession. There is a massive twist in the first book that I am still not trying to spoil, so please forgive some vague description. At the conclusion of These Burning Stars, Jacobs had moved a lot of pieces into position, but it was not yet clear to me where the plot was going, or even if it would come to a solid ending in three volumes as promised by the series title. It does. This Brutal Moon opens with some of the political maneuvering that characterized These Burning Stars, but once things start happening, the reader gets all of the action they could wish for and then some. I am pleased to report that, at least as far as I'm concerned, Jacobs nails the ending. Not only is it deeply satisfying, the characterization in this book is so good, and adds so smoothly to the characterization of the previous books, that I saw the whole series in a new light. I thought this was one of the best science fiction series finales I've ever read. Take that with a grain of salt, since some of those reasons are specific to me and the mood I was in when I read it, but this is fantastic stuff. There is a lot of action at the climax of this book, split across at least four vantage points and linked in a grand strategy with chaotic surprises. I kept all of the pieces straight and understood how they were linked thanks to Jacobs's clear narration, which is impressive given the number of pieces in motion. That's not the heart of this book, though. The action climax is payoff for the readers who want to see some ass-kicking, and it does contain some moving and memorable moments, but it relies on some questionable villain behavior and a convenient plot device introduced only in this volume. The action-thriller payoff is competent but not, I think, outstanding. What put this book into a category of its own were the characters, and specifically how Jacobs assembles sweeping political consequences from characters who, each alone, would never have brought about such a thing, and in some cases had little desire for it. Looking back on the trilogy, I think Jacobs has captured, among all of the violence and action-movie combat and space-opera politics, the understanding that political upheaval is a relay race. The people who have the personalities to start it don't have the personality required to nurture it or supply it, and those who can end it are yet again different. This series is a fascinating catalog of political actors the instigator, the idealist, the pragmatist, the soldier, the one who supports her friends, and several varieties and intensities of leaders and it respects all of them without anointing any of them as the One True Revolutionary. The characters are larger than life, yes, and this series isn't going to win awards for gritty realism, but it's saying something satisfyingly complex about where we find courage and how a cause is pushed forward by different people with different skills and emotions at different points in time. Sometimes accidentally, and often in entirely unexpected ways. As before, the main story is interwoven with flashbacks. This time, we finally see the full story of the destruction of the moon of Jeve. The reader has known about this since the first volume, but Jacobs has a few more secrets to show (including, I will admit, setting up a plot device) and some pointed commentary on resource extraction economies. I think this part of the book was a bit obviously constructed, although the characterization was great and the visible junction points of the plot didn't stop me from enjoying the thrill when the pieces came together. But the best part of this book was the fact there was 10% of it left after the climax. Jacobs wrote an actual denouement, and it was everything I wanted and then some. We get proper story conclusions for each of the characters, several powerful emotional gut punches, some remarkably subtle and thoughtful discussion of political construction for a series that tended more towards space-opera action, and a conclusion for the primary series relationship that may not be to every reader's taste but was utterly, perfectly, beautifully correct for mine. I spent a whole lot of the last fifty pages of this book trying not to cry, in the best way. The character evolution over the course of this series is simply superb. Each character ages like fine wine, developing more depth, more nuance, but without merging. They become more themselves, which is an impressive feat across at least four very different major characters. You can see the vulnerabilities and know what put them there, you can see the strengths they developed to compensate, and you can see why they need the support the other characters provide. And each of them is so delightfully different. This was so good. This was so precisely the type of story that I was in the mood for, with just the type of tenderness for its characters that I wanted, that I am certain I am not objective about it. It will be one of those books where other people will complain about flaws that I didn't see or didn't care about because it was doing the things I wanted from it so perfectly. It's so good that it elevated the entire trilogy; the journey was so worth the ending. I'm afraid this review will be less than helpful because it's mostly nonspecific raving. This series is such a spoiler minefield that I'd need a full spoiler review to be specific, but my reaction is so driven by emotion that I'm not sure that would help if the characters didn't strike you the way that they struck me. I think the best advice I can offer is to say that if you liked the emotional tone of the end of These Burning Stars (not the big plot twist, the character reaction to the political goal that you learn drove the plot), stick with the series, because that's a sign of the questions Jacobs is asking. If you didn't like the characters at the end (not the middle) of the first novel, bail out, because you're going to get a lot more of that. Highly, highly recommended, and the best thing I've read all year, with the caveats that you should read the content notes, and that some people are going to bounce off this series because it's too intense and melodramatic. That intensity will not let up, so if that's not what you're in the mood for, wait on this trilogy until you are. Content notes: Graphic violence, torture, mentions of off-screen child sexual assault, a graphic corpse, and a whole lot of trauma. One somewhat grumbly postscript: This is the sort of book where I need to not read other people's reviews because I'll get too defensive of it (it's just a book I liked!). But there is one bit of review commentary I've seen about the trilogy that annoys me enough I have to mention it. Other reviewers seem to be latching on to the Jeveni (an ethnic group in the trilogy) as Space Jews and then having various feelings about that. I can see some parallels, I'm not going to say that it's completely wrong, but I also beg people to read about a fictional oppressed ethnic and religious minority and not immediately think "oh, they must be stand-ins for Jews." That's kind of weird? And people from the US, in particular, perhaps should not read a story about an ethnic group enslaved due to their productive skill and economic value and think "they must be analogous to Jews, there are no other possible parallels here." There are a lot of other comparisons that can be made, including to the commonalities between the methods many different oppressed minorities have used to survive and preserve their culture. Rating: 10 out of 10

31 December 2025

Sergio Cipriano: Zero-Code Instrumentation of an Envoy TCP Proxy using eBPF

Zero-Code Instrumentation of an Envoy TCP Proxy using eBPF I recently had to debug an Envoy Network Load Balancer, and the options Envoy provides just weren't enough. We were seeing a small number of HTTP 499 errors caused by latency somewhere in our cloud, but it wasn't clear what the bottleneck was. As a result, each team had to set up additional instrumentation to catch latency spikes and figure out what was going on. My team is responsible for the LBaaS product (Load Balancer as a Service) and, of course, we are the first suspects when this kind of problem appear. Before going for the current solution, I read a lot of Envoy's documentation. It is possible to enable access logs for Envoy, but they don't provide the information required for this debug. This is an example of the output:
[2025-12-08T20:44:49.918Z] "- - -" 0 - 78 223 1 - "-" "-" "-" "-" "172.18.0.2:8080"
I won't go into detail about the line above, since it's not possible to trace the request using access logs alone. Envoy also has OpenTelemetry tracing, which is perfect for understanding sources of latency. Unfortunatly, it is only available for Application Load Balancers. Most of the HTTP 499 were happening every 10 minutes, so we managed to get some of the requests with tcpdump, Wireshark and using http headers to filter the requests. This approach helped us reproduce and track down the problem, but it wasn't a great solution. We clearly needed better tools to catch this kind of issue the next time it happened. Therefore, I decided to try out OpenTelemetry eBPF Instrumentation, also referred to as OBI. I saw the announcement of Grafana Beyla before it was renamed to OBI, but I didn't have the time or a strong reason to try it out until now. Even then, I really liked the idea, and the possibility of using eBPF to solve this instrumentation problem had been in the back of my mind. OBI promises zero-code automatic instrumentation for Linux services using eBPF, so I put together a minimal setup to see how well it works.

Reproducible setup I used the following tools: Setting up a TCP Proxy with Envoy was straightforward:
static_resources:
  listeners:
  - name: go_server_listener
    address:
      socket_address:
        address: 0.0.0.0
        port_value: 8000
    filter_chains:
    - filters:
      - name: envoy.filters.network.tcp_proxy
        typed_config:
          "@type": type.googleapis.com/envoy.extensions.filters.network.tcp_proxy.v3.TcpProxy
          stat_prefix: go_server_tcp
          cluster: go_server_cluster
  clusters:
  - name: go_server_cluster
    connect_timeout: 1s
    type: LOGICAL_DNS
    load_assignment:
      cluster_name: go_server_cluster
      endpoints:
      - lb_endpoints:
        - endpoint:
            address:
              socket_address:
                address: target-backend
                port_value: 8080
This is the simplest Envoy TCP proxy configuration: a listener on port 8000 forwarding traffic to a backend running on port 8080. For the backend, I used a basic Go HTTP server:
package main

import (
    "fmt"
    "net/http"
)

func main()  
    http.Handle("/", http.FileServer(http.Dir(".")))

    server := http.Server Addr: ":8080" 

    fmt.Println("Starting server on :8080")
    panic(server.ListenAndServe())
 
Finally, I wrapped everything together with Docker Compose:
services:
  autoinstrumenter:
    image: otel/ebpf-instrument:main
    pid: "service:envoy"
    privileged: true
    environment:
      OTEL_EBPF_TRACE_PRINTER: text
      OTEL_EBPF_OPEN_PORT: 8000

  envoy:
    image: envoyproxy/envoy:v1.33-latest
    ports:
      - 8000:8000
    volumes:
      - ./envoy.yaml:/etc/envoy/envoy.yaml 
    depends_on:
      - target-backend
  
  target-backend:
    image: golang:1.22-alpine
    command: go run /app/backend.go
    volumes:
      - ./backend.go:/app/backend.go:ro
    expose:
      - 8080
OBI should output traces to the standard output similar to this when a HTTP request is made to Envoy:
2025-12-08 20:44:49.12884449 (305.572 s[305.572 s]) HTTPClient 200 GET /(/) [172.18.0.3 as envoy:36832]->[172.18.0.2 as localhost:8080] contentLen:78B responseLen:0B svc=[envoy generic] traceparent=[00-529458a2be271956134872668dc5ee47-6dba451ec8935e3e[06c7f817e6a5dae2]-01]
2025-12-08 20:44:49.12884449 (1.260901ms[366.65 s]) HTTP 200 GET /(/) [172.18.0.1 as 172.18.0.1:36282]->[172.18.0.3 as envoy:8000] contentLen:78B responseLen:223B svc=[envoy generic] traceparent=[00-529458a2be271956134872668dc5ee47-06c7f817e6a5dae2[0000000000000000]-01]
This is exactly what we needed, with zero-code. The above trace shows:
  • 2025-12-08 20:44:49.12884449: time of the trace.
  • (1.260901ms[366.65 s]): total response time for the request, with the actual internal execution time of the request (not counting the request enqueuing time).
  • HTTP 200 GET /: protocol, response code, HTTP method, and URL path.
  • [172.18.0.1 as 172.18.0.1:36282]->[172.18.0.3 as envoy:8000]: source and destination host:port. The initial request originates from my machine through the gateway (172.18.0.1), hits the Envoy (172.23.0.3), the proxy then forwards it to the backend application (172.23.0.2).
  • contentLen:78B: HTTP Content-Length. I used curl and the default request size for it is 78B.
  • responseLen:223B: Size of the response body.
  • svc=[envoy generic]: traced service.
  • traceparent: ids to trace the parent request. We can see that the Envoy makes a request to the target and this request has the other one as parent.
Let's add one more Envoy to show that it's also possible to track multiple services.
  envoy1:
    image: envoyproxy/envoy:v1.33-latest
    ports:
      - 9000:9000
    volumes:
      - ./envoy1.yaml:/etc/envoy/envoy.yaml
    depends_on:
      - envoy
The new Envoy will listen on port 9000 and forward the request to the other Envoy listening on port 8000. Now we just need to change OBI open port variable to look at a range:
OTEL_EBPF_OPEN_PORT: 8000-9000
And change the pid field of the autoinstrumenter service to use the host's PID namespace inside the container:
pid: host
This is the output I got after one curl:
2025-12-09 12:28:05.12912285 (2.202041ms[1.524713ms]) HTTP 200 GET /(/) [172.19.0.1 as 172.19.0.1:59030]->[172.19.0.5 as envoy:9000] contentLen:78B responseLen:223B svc=[envoy generic] traceparent=[00-69977bee0c2964b8fe53cdd16f8a9d19-856c9f700e73bf0d[0000000000000000]-01]
2025-12-09 12:28:05.12912285 (1.389336ms[1.389336ms]) HTTPClient 200 GET /(/) [172.19.0.5 as envoy:59806]->[172.19.0.4 as localhost:8000] contentLen:78B responseLen:0B svc=[envoy generic] traceparent=[00-69977bee0c2964b8fe53cdd16f8a9d19-caa7f1ad1c68fa77[856c9f700e73bf0d]-01]
2025-12-09 12:28:05.12912285 (1.5431ms[848.574 s]) HTTP 200 GET /(/) [172.19.0.5 as 172.19.0.5:59806]->[172.19.0.4 as envoy:8000] contentLen:78B responseLen:223B svc=[envoy generic] traceparent=[00-69977bee0c2964b8fe53cdd16f8a9d19-cbca9d64d3d26b40[caa7f1ad1c68fa77]-01]
2025-12-09 12:28:05.12912285 (690.217 s[690.217 s]) HTTPClient 200 GET /(/) [172.19.0.4 as envoy:34256]->[172.19.0.3 as localhost:8080] contentLen:78B responseLen:0B svc=[envoy generic] traceparent=[00-69977bee0c2964b8fe53cdd16f8a9d19-5502f7760ed77b5b[cbca9d64d3d26b40]-01]
2025-12-09 12:28:05.12912285 (267.9 s[238.737 s]) HTTP 200 GET /(/) [172.19.0.4 as 172.19.0.4:34256]->[172.19.0.3 as backend:8080] contentLen:0B responseLen:0B svc=[backend go] traceparent=[00-69977bee0c2964b8fe53cdd16f8a9d19-ac05c7ebe26f2530[5502f7760ed77b5b]-01]
Each log line represents a span belonging to the same trace (69977bee0c2964b8fe53cdd16f8a9d19). For readability, I ordered the spans by their traceparent relationship, showing the request's path as it moves through the system: from the client-facing Envoy, through the internal Envoy hop, and finally to the Go backend. You can see both server-side (HTTP) and client-side (HTTPClient) spans at each hop, along with per-span latency, source and destination addresses, and response sizes, making it easy to pinpoint where time is spent along the request chain. The log lines are helpful, but we need better ways to visualize the traces and the metrics generated by OBI. I'll share another setup that more closely reflects what we actually use.

Production setup I'll be using the following tools this time: The goal of this setup is to mirror an environment similar to what I used in production. This time, I've omitted the load balancer and shifted the emphasis to observability instead. setup diagram I will run three HTTP servers on port 8080: two inside Incus containers and one on the host machine. The OBI process will export metrics and traces to an OpenTelemetry Collector, which will forward traces to Jaeger and expose a metrics endpoint for Prometheus to scrape. Grafana will also be added to visualize the collected metrics using dashboards. The aim of this approach is to instrument only one of the HTTP servers while ignoring the others. This simulates an environment with hundreds of Incus containers, where the objective is to debug a single container without being overwhelmed by excessive and irrelevant telemetry data from the rest of the system. OBI can filter metrics and traces based on attribute values, but I was not able to filter by process PID. This is where the OBI Collector comes into play, it allows me to use a processor to filter telemetry data by the PID of the process being instrumented. These are the steps to reproduce this setup:
  1. Create the incus containers.
$ incus launch images:debian/trixie server01
Launching server01
$ incus launch images:debian/trixie server02
Launching server02
  1. Start the HTTP server on each container.
$ apt install python3 --update -y
$ tee /etc/systemd/system/server.service > /dev/null <<'EOF'
[Unit]
Description=Python HTTP server
After=network.target
[Service]
User=root
Group=root
Type=simple
ExecStart=/usr/bin/python3 -m http.server 8080
Restart=always
StandardOutput=journal
StandardError=journal
[Install]
WantedBy=multi-user.target
EOF
$ systemctl start server.service
  1. Start the HTTP server on the host.
$ python3 -m http.server 8080
  1. Start the Docker compose.
services:
  autoinstrumenter:
    image: otel/ebpf-instrument:main
    pid: host
    privileged: true
    environment:
      OTEL_EBPF_CONFIG_PATH: /etc/obi/obi.yml 
    volumes:
      - ./obi.yml:/etc/obi/obi.yml

  otel-collector:
    image: otel/opentelemetry-collector-contrib:0.98.0
    command: ["--config=/etc/otel-collector-config.yml"]
    volumes:
      - ./otel-collector-config.yml:/etc/otel-collector-config.yml
    ports:
      - "4318:4318" # Otel Receiver
      - "8889:8889" # Prometheus Scrape
    depends_on:
      - autoinstrumenter
      - jaeger
      - prometheus

  prometheus:
    image: prom/prometheus
    volumes:
      - ./prometheus.yml:/etc/prometheus/prometheus.yml
    ports:
      - "9090:9090" # Prometheus UI

  grafana:
    image: grafana/grafana
    restart: always
    environment:
      - GF_SECURITY_ADMIN_USER=admin
      - GF_SECURITY_ADMIN_PASSWORD=RandomString123!
    volumes:
      - ./grafana-ds.yml:/etc/grafana/provisioning/datasources/datasource.yml
    ports:
      - "3000:3000" # Grafana UI

  jaeger:
    image: jaegertracing/all-in-one
    container_name: jaeger
    ports:
      - "16686:16686" # Jaeger UI
      - "4317:4317"  # Jaeger OTLP/gRPC Collector
Here's what the configuration files look like:
  • obi.yml:
log_level: INFO
trace_printer: text

discovery:
  instrument:
    - open_ports: 8080

otel_metrics_export:
  endpoint: http://otel-collector:4318
otel_traces_export:
  endpoint: http://otel-collector:4318
  • prometheus.yml:
global:
  scrape_interval: 5s

scrape_configs:
  - job_name: 'otel-collector'
    static_configs:
      - targets: ['otel-collector:8889']
  • grafana-ds.yml:
apiVersion: 1

datasources:
  - name: Prometheus
    type: prometheus
    access: proxy
    url: http://prometheus:9090
    isDefault: true
  • otel-collector-config.yml:
receivers:
  otlp:
    protocols:
      http:
        endpoint: otel-collector:4318

exporters:
  otlp/jaeger:
    endpoint: jaeger:4317
    tls:
      insecure: true

  prometheus:
    endpoint: 0.0.0.0:8889
    namespace: default

service:
  pipelines:
    traces:
      receivers: [otlp]
      exporters: [otlp/jaeger]

    metrics:
      receivers: [otlp] 
      exporters: [prometheus]
We're almost there, the OpenTelemetry Collector is just missing a processor. To create the processor filter, we can look at the OBI logs to find the PID of the HTTP server being instrumented:
autoinstrumenter-1    time=2025-12-30T19:57:17.593Z level=INFO msg="instrumenting process" component=discover.traceAttacher cmd=/usr/bin/python3.13 pid=297514 ino=460310 type=python service=""
autoinstrumenter-1    time=2025-12-30T19:57:18.320Z level=INFO msg="instrumenting process" component=discover.traceAttacher cmd=/usr/bin/python3.13 pid=310288 ino=722998 type=python service=""
autoinstrumenter-1    time=2025-12-30T19:57:18.512Z level=INFO msg="instrumenting process" component=discover.traceAttacher cmd=/usr/bin/python3.13 pid=315183 ino=2888480 type=python service=""
Which can also be obtained using standard GNU/Linux utilities:
$ cat /sys/fs/cgroup/lxc.payload.server01/system.slice/server.service/cgroup.procs 
297514
$ cat /sys/fs/cgroup/lxc.payload.server02/system.slice/server.service/cgroup.procs 
310288
$ ps -aux   grep http.server
USER         PID %CPU %MEM    VSZ   RSS TTY      STAT START   TIME COMMAND
1000000   297514  0.0  0.1  32120 14856 ?        Ss   16:03   0:00 /usr/bin/python3 -m http.server 8080
1000000   310288  0.0  0.1  32120 10616 ?        Ss   16:09   0:00 /usr/bin/python3 -m http.server 8080
cipriano  315183  0.0  0.1 103476 11480 pts/3    S+   16:17   0:00 python -m http.server 8080
If we search for the PID in the OpenTelemetry Collector endpoint where Prometheus metrics are exposed, we can find the attribute values to filter on.
$ curl http://localhost:8889/metrics   rg 297514
default_target_info host_id="148f400ad3ea",host_name="148f400ad3ea",instance="148f400ad3ea:297514",job="python3.13",os_type="linux",service_instance_id="148f400ad3ea:297514",service_name="python3.13",telemetry_sdk_language="python",telemetry_sdk_name="opentelemetry-ebpf-instrumentation",telemetry_sdk_version="main"  1
Now we just need to add the processor to the collector configuration:
processors: # <--- NEW BLOCK
  filter/host_id:
    traces:
      span:
        - 'resource.attributes["service.instance.id"] == "148f400ad3ea:297514"'

service:
  pipelines:
    traces:
      receivers: [otlp]
      processors: [filter/host_id] # <--- NEW LINE
      exporters: [otlp/jaeger]

    metrics:
      receivers: [otlp] 
      processors:  # <--- NEW BLOCK
        - filter/host_id
      exporters: [prometheus]
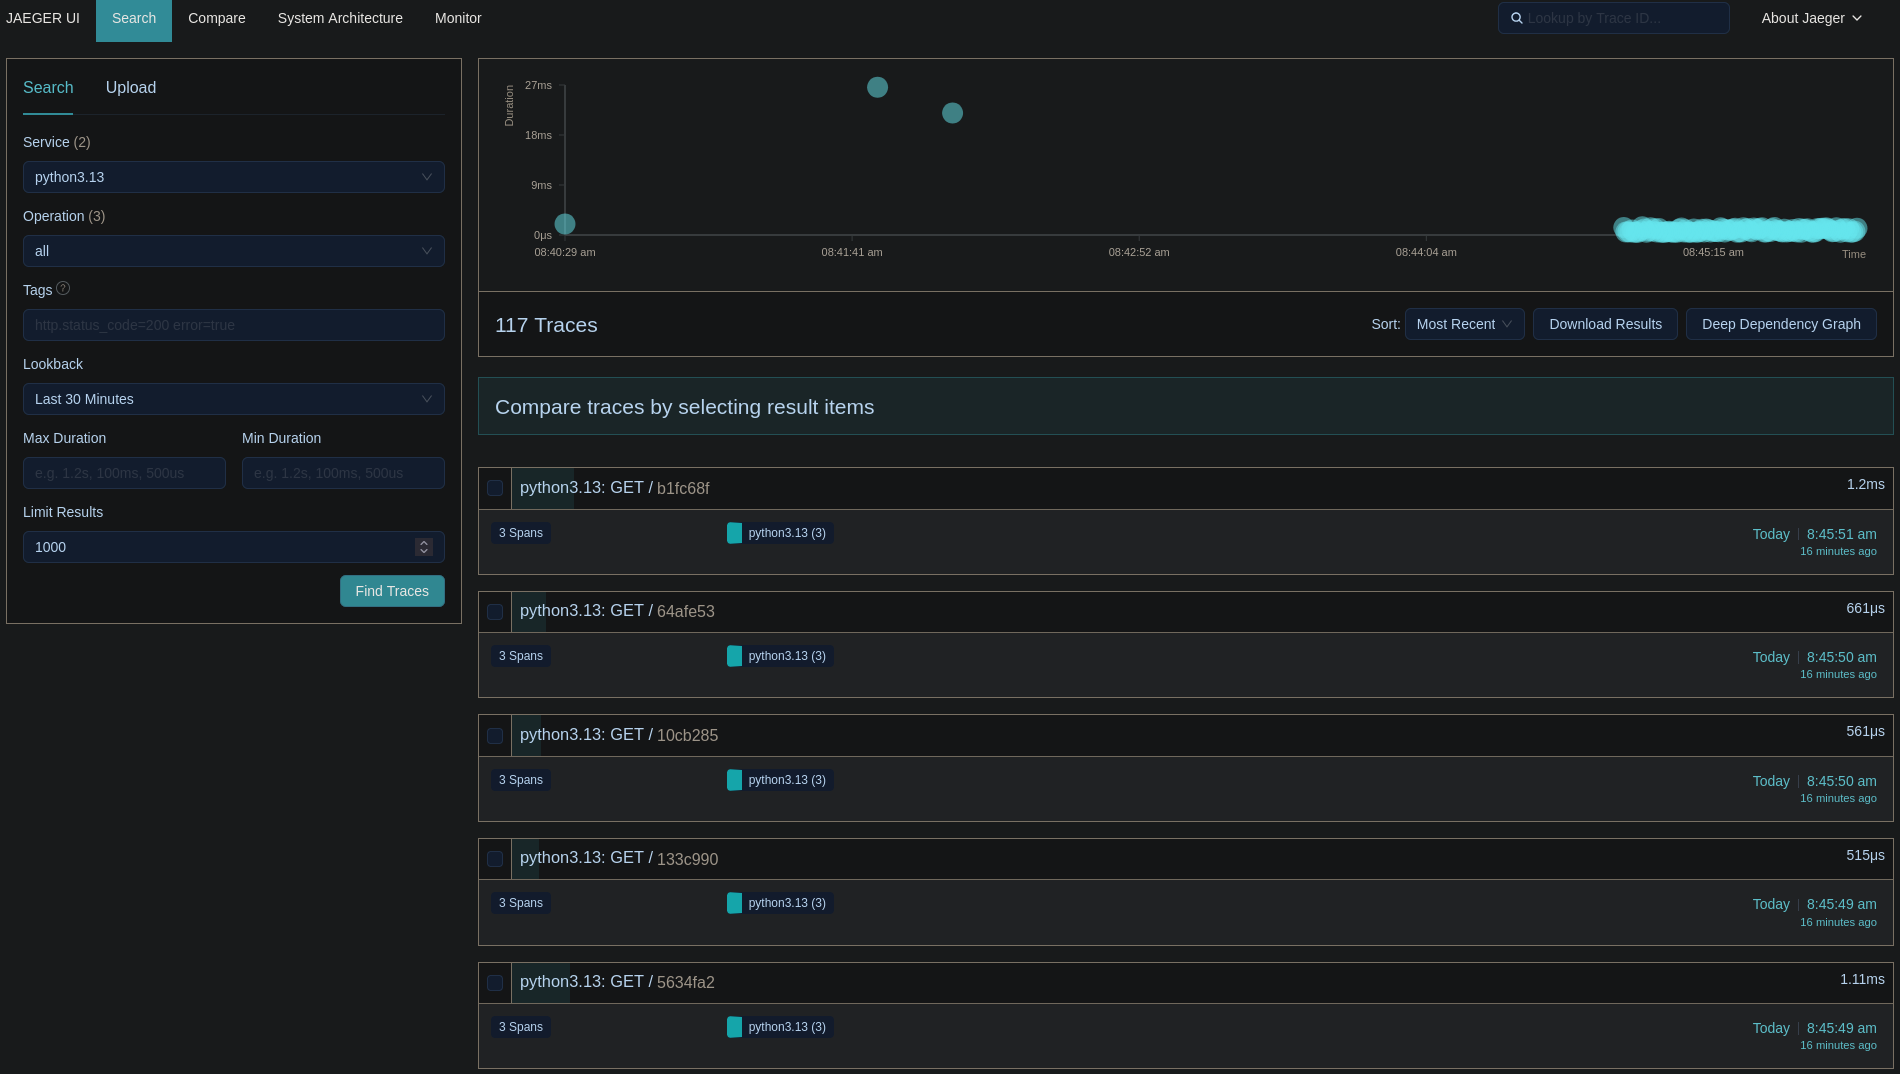
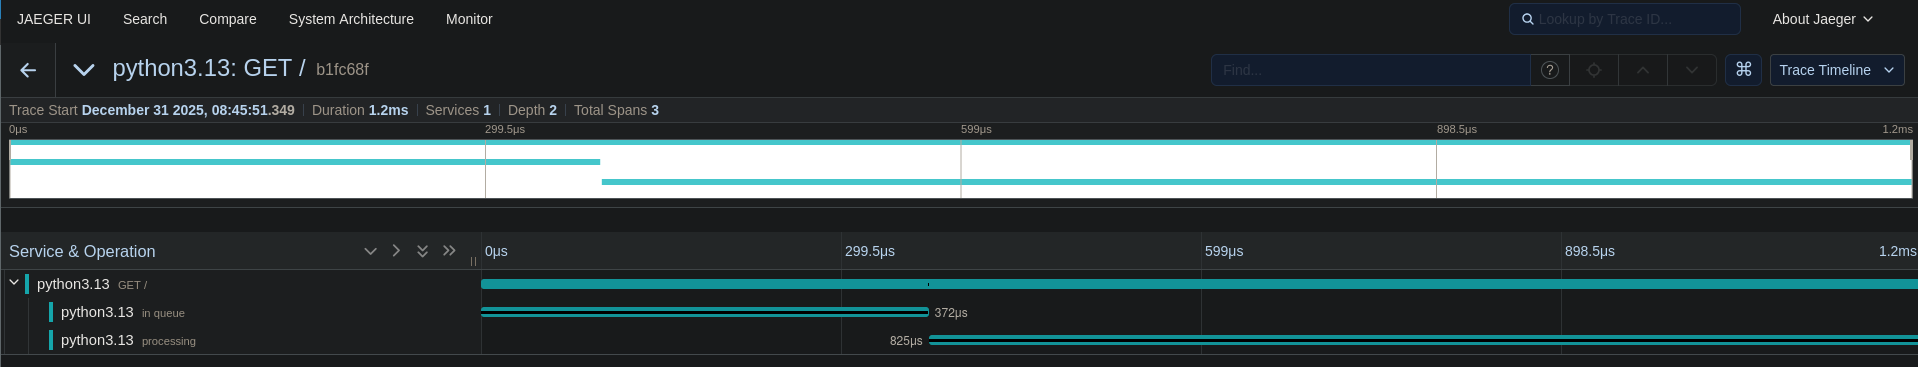
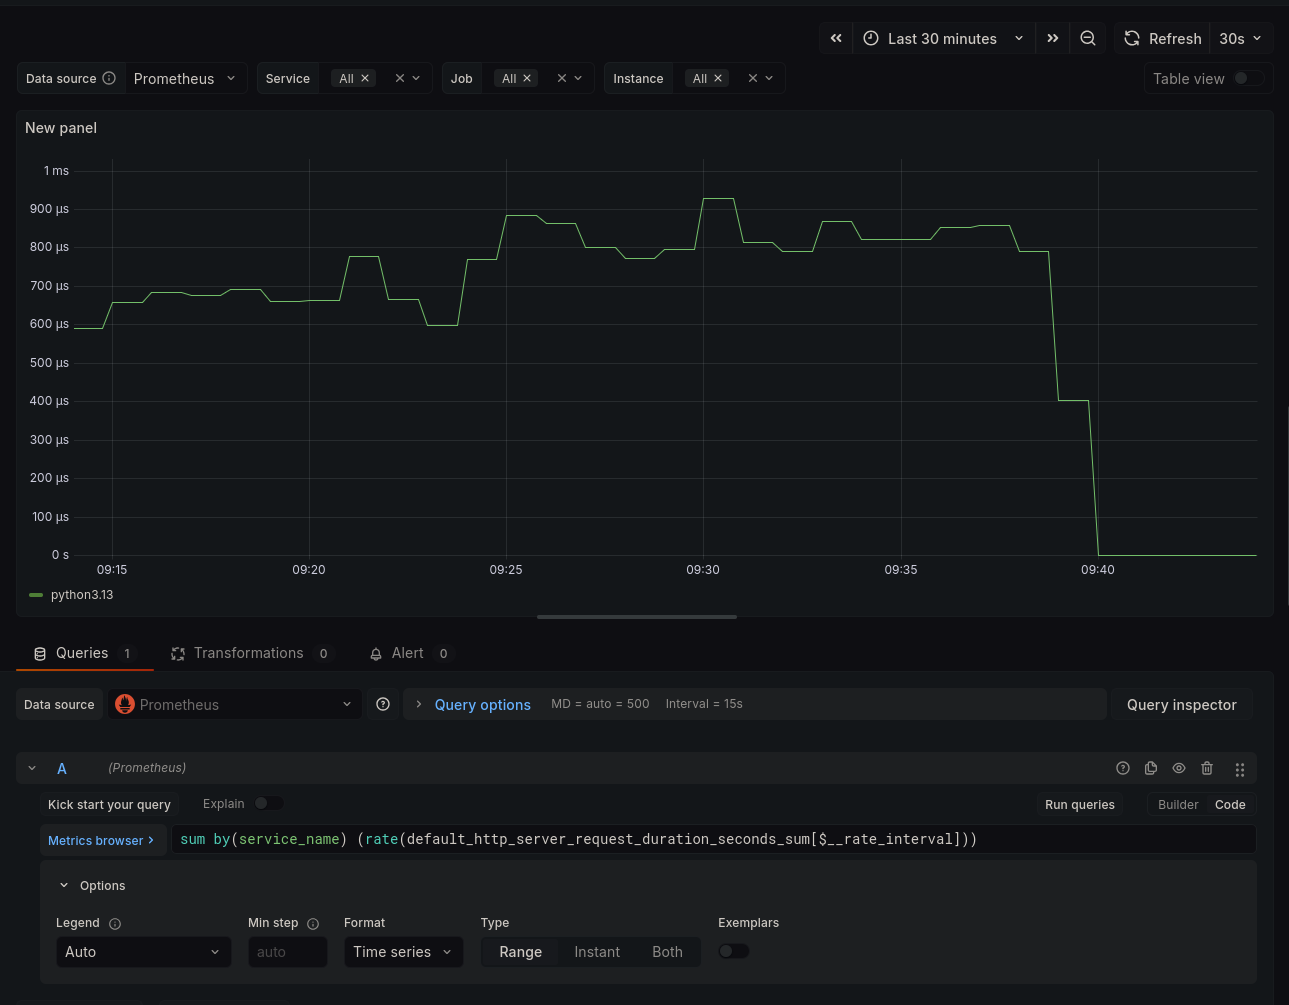
That's it! The processor will handle the filtering for us, and we'll only see traces and metrics from the HTTP server running in the server01 container. Below are some screenshots from Jaeger and Grafana: jaeger search will all traces one jaeger trace grafana request duration panel

Closing Notes I am still amazed at how powerful OBI can be. For those curious about the debug, we found out that a service responsible for the network orchestration of the Envoy containers was running netplan apply every 10 minutes because of a bug. Netplan apply causes interfaces to go down temporarily and this made the latency go above 500ms which caused the 499s.

Ravi Dwivedi: Transit through Kuala Lumpur

In my last post, Badri and I reached Kuala Lumpur - the capital of Malaysia - on the 7th of December 2024. We stayed in Bukit Bintang, the entertainment district of the city. Our accommodation was pre-booked at Manor by Mingle , a hostel where I had stayed for a couple of nights in a dormitory room earlier in February 2024. We paid 4937 rupees (the payment was online, so we paid in Indian rupees) for 3 nights for a private room. From the Terminal Bersepadu Selatan (TBS) bus station, we took the metro to the Plaza Rakyat LRT station, which was around 500 meters from the hostel. Upon arriving at the hostel, we presented our passports at their request, followed by a 20 ringgit (400 rupee) deposit which would be refunded once we returned the room keys at checkout.
Outside view of the hostel Manor by Mingle Manor by Mingle - the hostel where we stayed at during our KL transit. Photo by Ravi Dwivedi. Released under the CC-BY-SA 4.0.
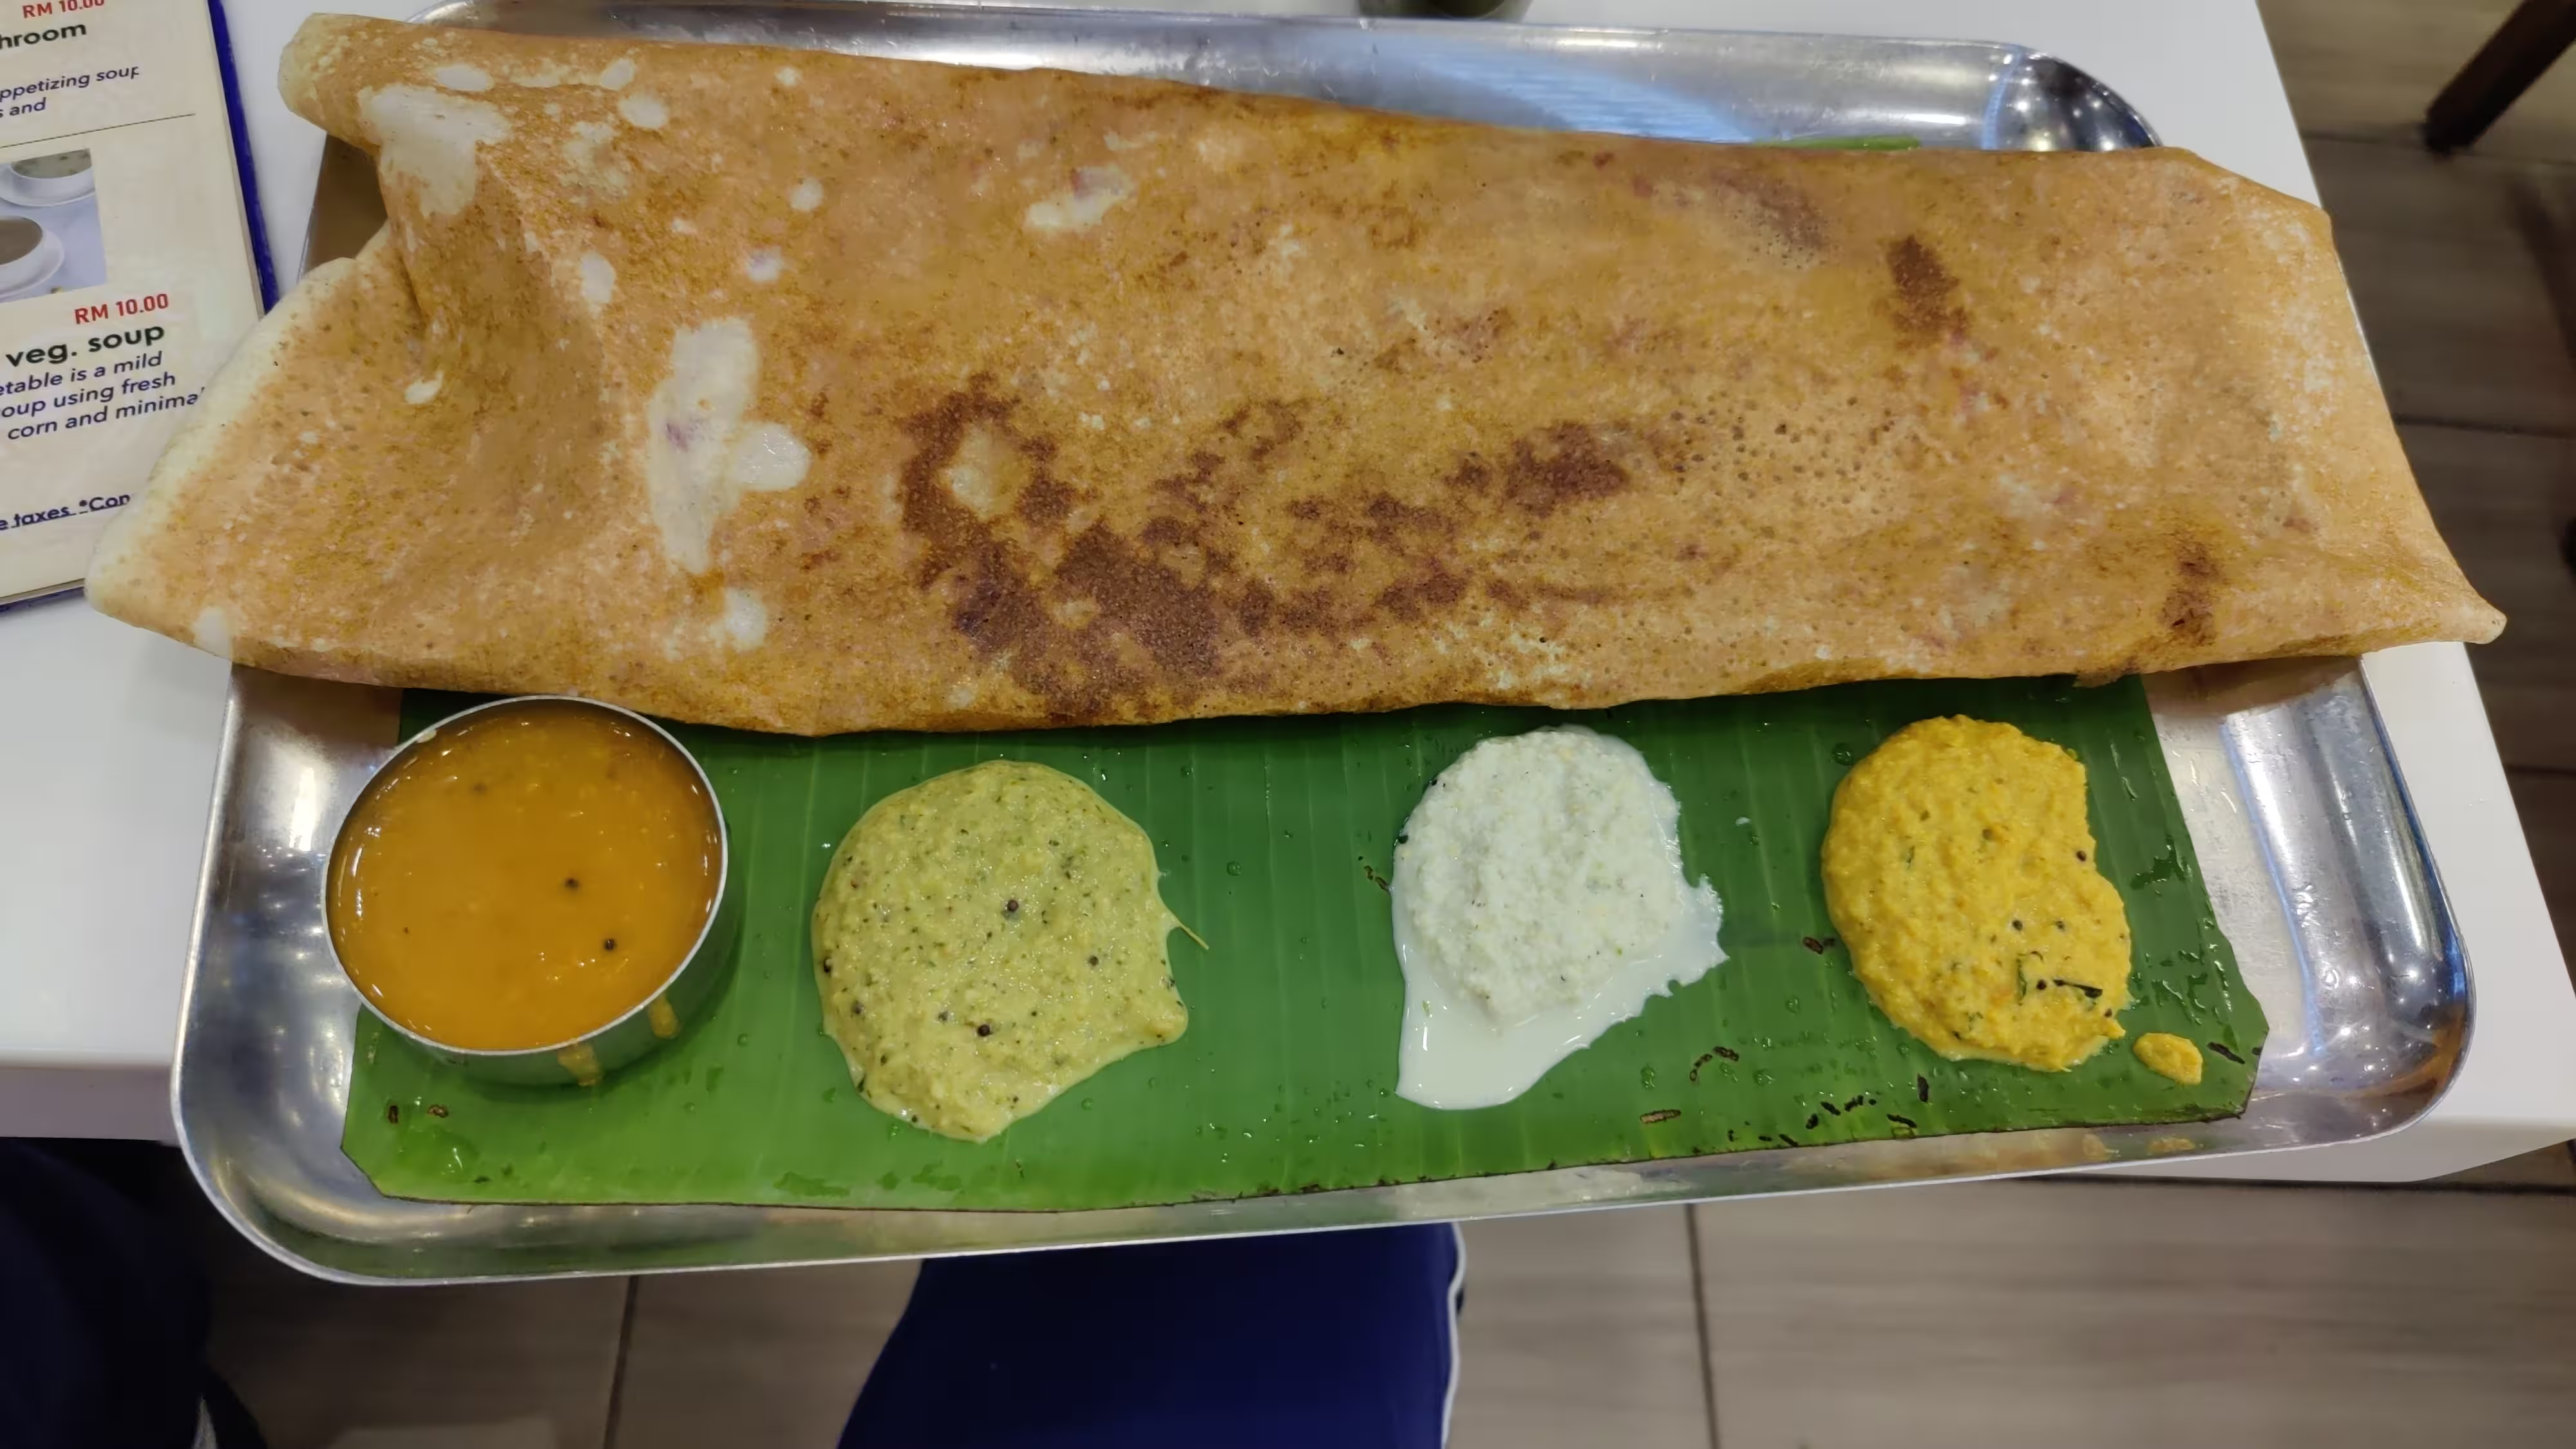
Our room was upstairs and it had a bunk bed. I had seen bunk beds in dormitories before, but this was my first time seeing a bunk bed in a private room. The room did not have any toilets, so we had to use shared toilets. Unusually, the hostel was equipped with a pool. It also had a washing machine with dryers - this was one of the reasons we chose this hostel, because we were traveling light and hadn t packed too many clothes. The machine and dryer cost 10 ringgits (200 rupees) per use, and we only used it once. The hostel provided complimentary breakfast, which included coffee. Outside of breakfast hours, there was also a paid coffee machine. During our stay, we visited a gurdwara - a place of worship for Sikhs - which was within walking distance from our hostel. The name of the gurdwara was Gurdwara Sahib Mainduab. However, it wasn t as lively as I had thought. The gurdwara was locked from the inside, and we had to knock on the gate and call for someone to open it. A man opened the gate and invited us in. The gurdwara was small, and there was only one other visitor - a man worshipping upstairs. We went upstairs briefly, then settled down on the first floor. We had some conversations with the person downstairs who kindly made chai for us. They mentioned that the langar (community meal) is organized on every Friday, which was unlike the gurdwaras I have been to where the langar is served every day. We were there for an hour before we left. We also went to Adyar Ananda Bhavan (a restaurant chain) near our hostel to try the chain in Malaysia. The chain is famous in Southern India and also known by its short name A2B. We ordered
A dosa Dosa served at Adyar Ananda Bhavan. Photo by Ravi Dwivedi. Released under the CC-BY-SA 4.0.
All this came down to around 33 ringgits (including taxes), i.e. around 660 rupees. We also purchased some snacks such as murukku from there for our trip. We had planned a day trip to Malacca, but had to cancel it due to rain. We didn t do a lot in Kuala Lumpur, and it ended up acting as a transit point for us to other destinations: flights from Kuala Lumpur were cheaper than Singapore, and in one case a flight via Kuala Lumpur was even cheaper than a direct flight! We paid 15,000 rupees in total for the following three flights:
  1. Kuala Lumpur to Brunei,
  2. Brunei to Kuala Lumpur, and
  3. Kuala Lumpur to Ho Chi Minh City (Vietnam).
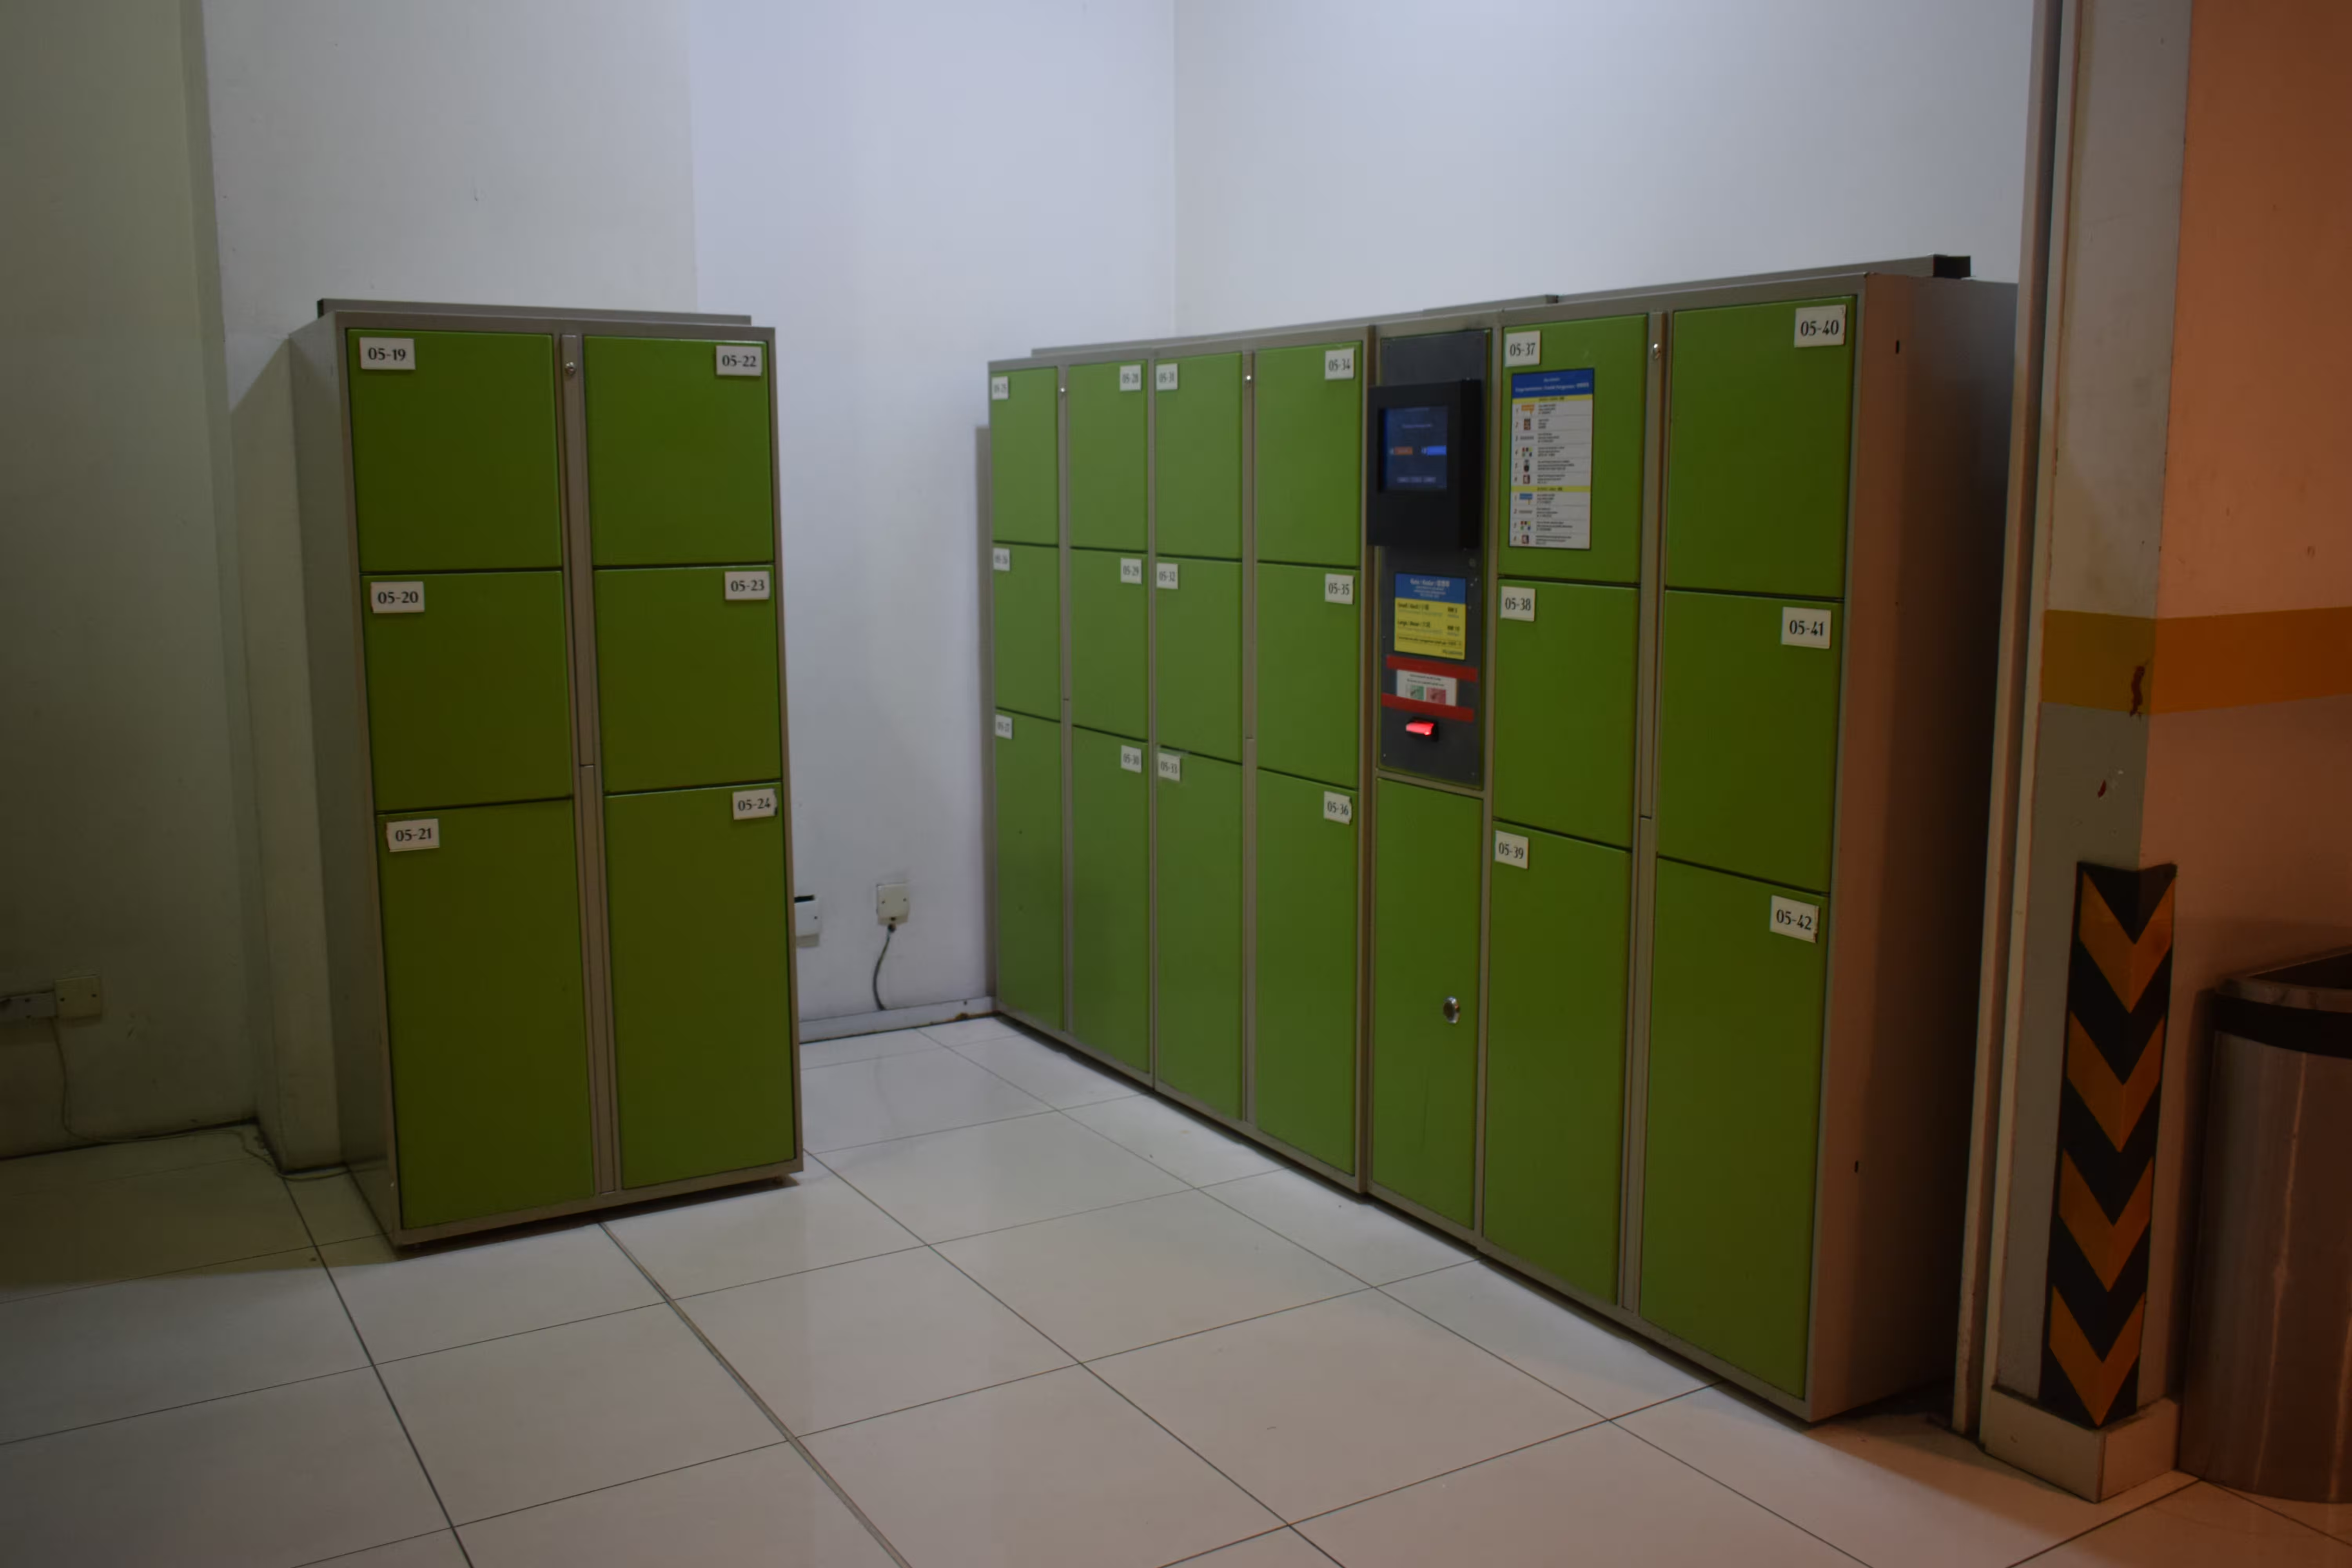
These were all AirAsia flights. The cheap tickets, however, did not include any checked-in luggage, and the cabin luggage weight limit was 7 kg. We also bought quite some stuff in Kuala Lumpur and Singapore, leading to an increase in the weight of our luggage. We estimated that it would be cheaper for us to take only essential items such as clothes, cameras, and laptops, and to leave behind souvenirs and other non-essentials in lockers at the TBS bus stand in Kuala Lumpur, than to pay more for check-in luggage. It would take 140 ringgits for us to add a checked-in bag from Kuala Lumpur to Bandar Seri Begawan and back, while the cost for lockers was 55 ringgits at the rate of 5 ringgits every six hours. We had seen these lockers when we alighted at the bus stand while coming from Johor Bahru. There might have been lockers in the airport itself as well, which would have been more convenient as we were planning to fly back in soon, but we weren t sure about finding lockers at the airport and we didn t want to waste time looking. We had an early morning flight for Brunei on the 10th of December. We checked out from our hostel on the night of the 9th of December, and left for TBS to take a bus to the airport. We took a metro from the nearest metro station to TBS. Upon reaching there, we put our luggage in the lockers. The lockers were automated and there was no staff there to guide us.
Lockers at TBS bus station Lockers at TBS bus station. Photo by Ravi Dwivedi. Released under the CC-BY-SA 4.0.
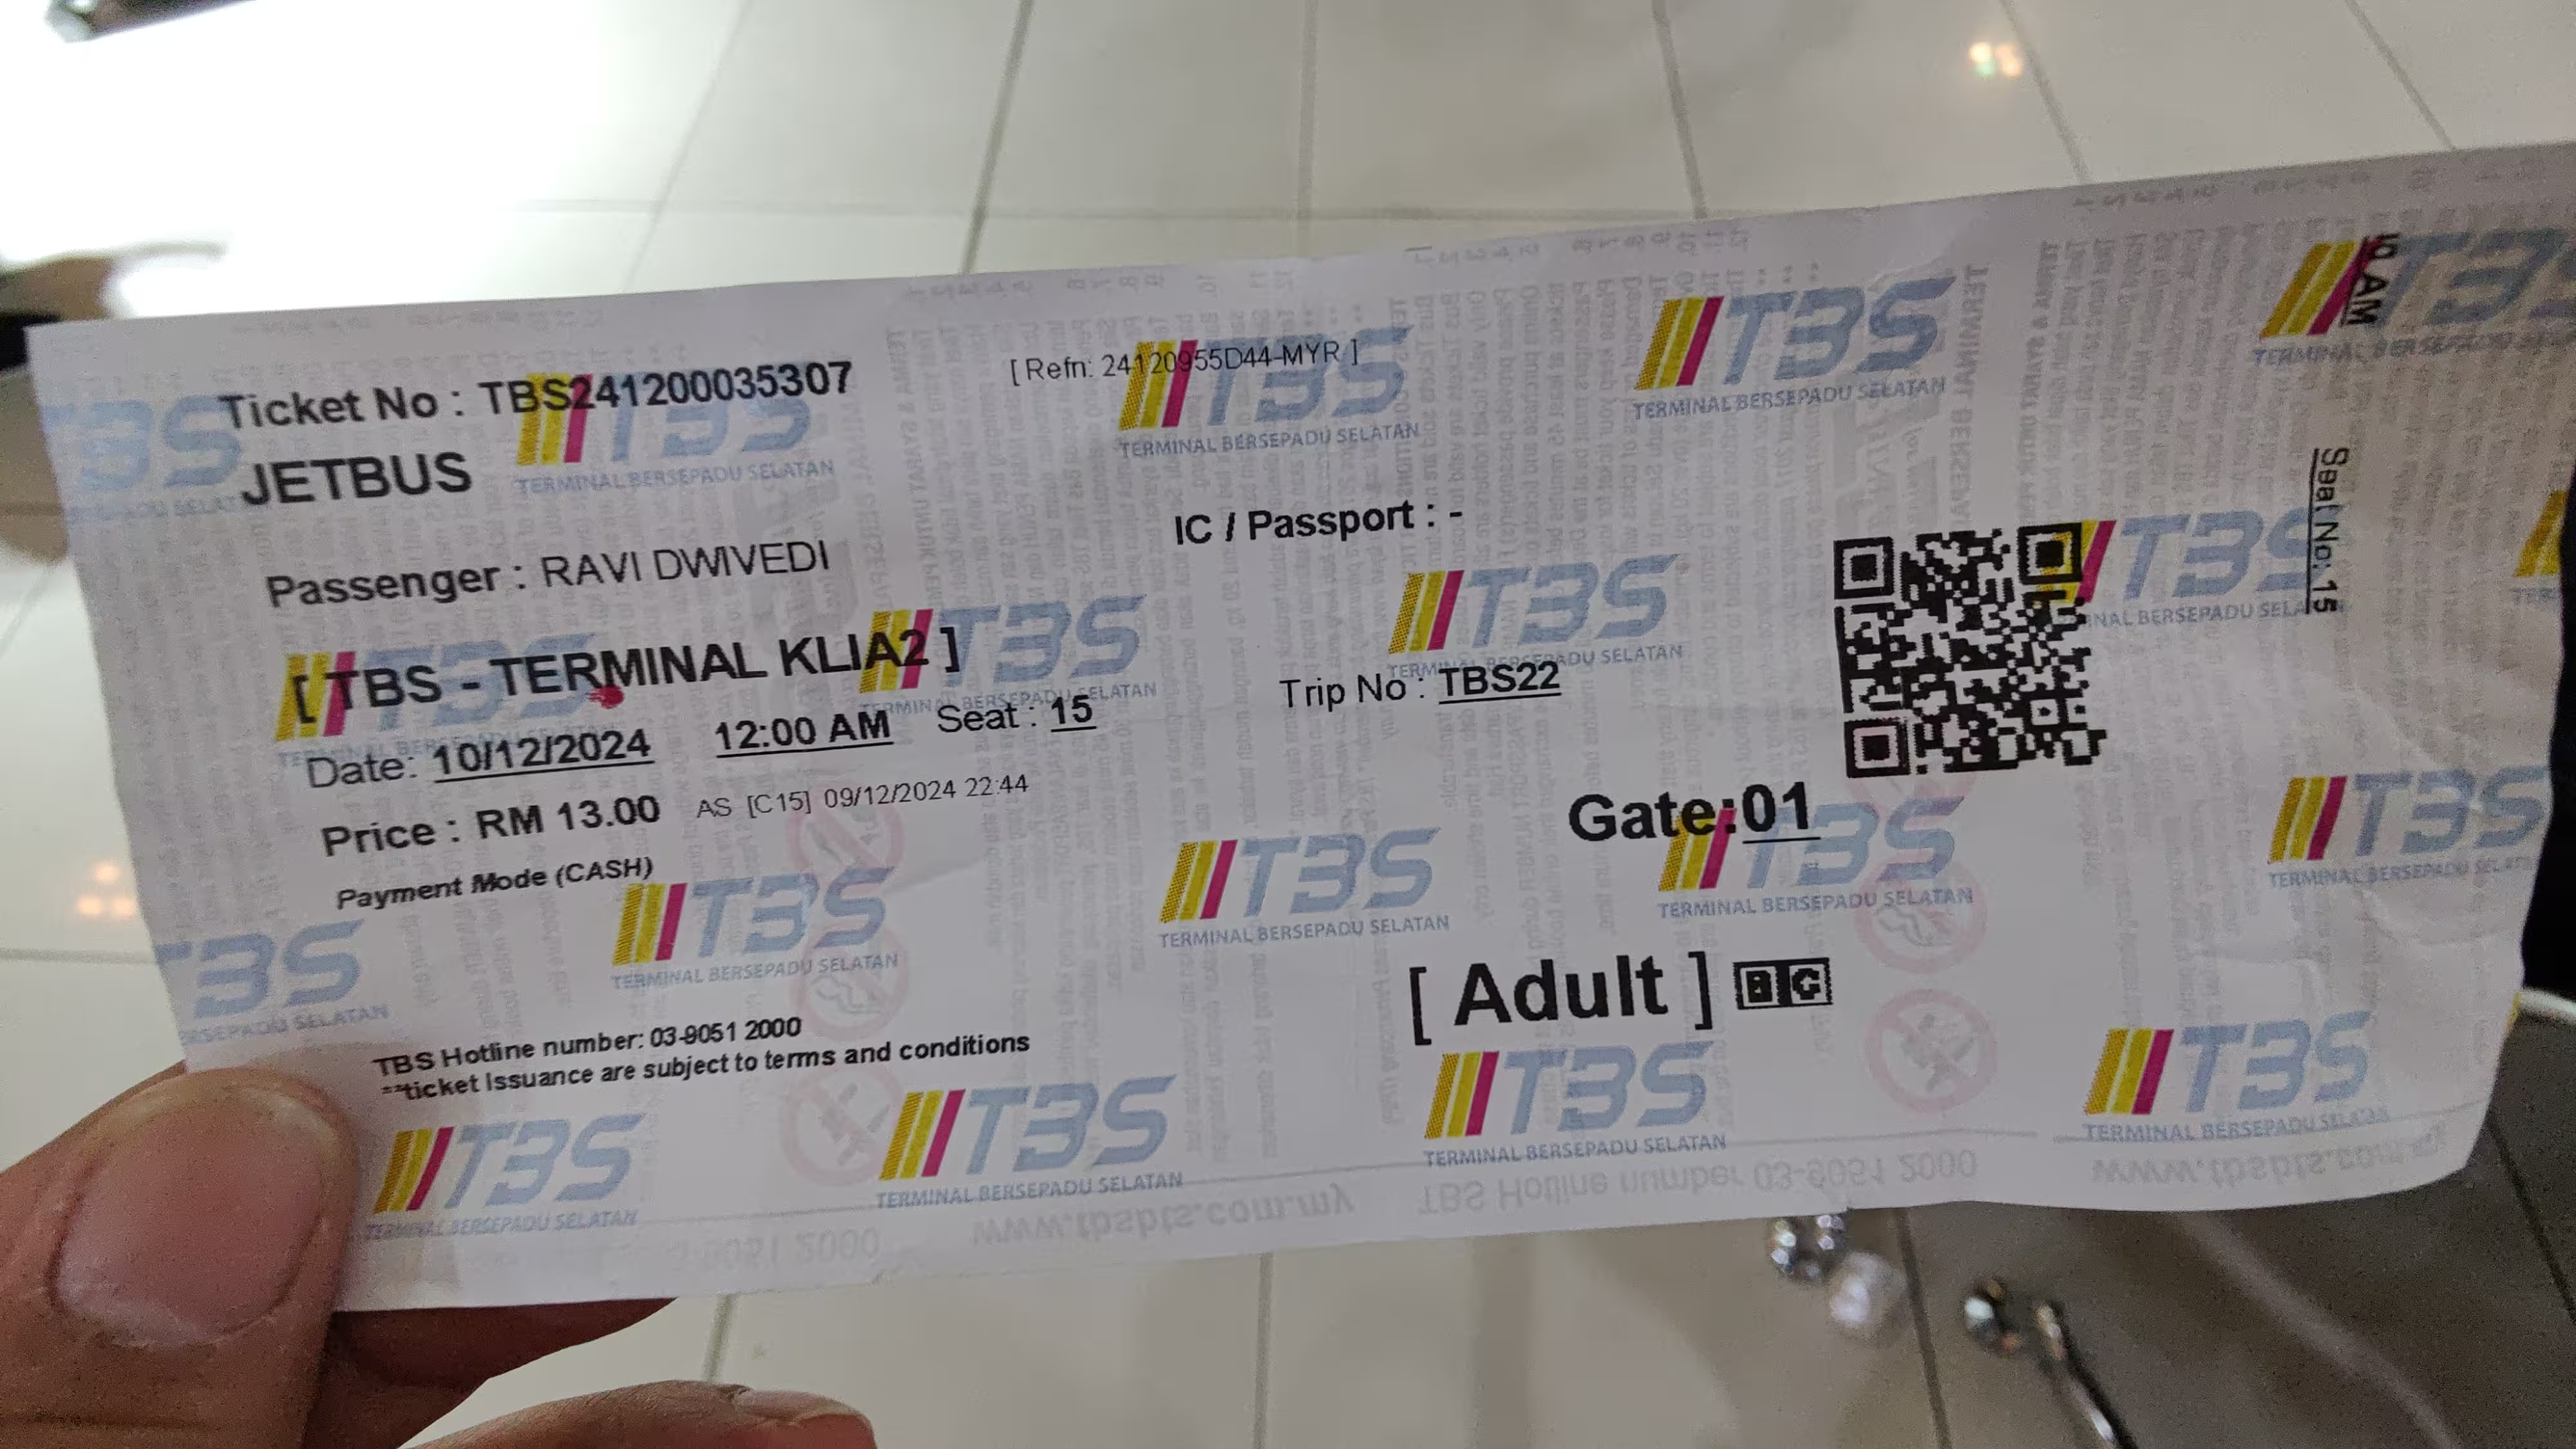
We bought a ticket for the airport bus from a counter at TBS for 26 ringgits for both of us. In order to give us tickets, the person at the counter asked for our passports, and we handed it over to them promptly. Since paying in cash did not provide any extra anonymity, I would advise others to book these buses online. In Malaysia, you also need a boarding pass for buses. The bus terminal had kiosks for getting these printed, but they were broken and we had to go to a counter to obtain them. The boarding pass mentioned our gate number and other details such as our names and departure time of the bus. The company was Jet Bus.
My boarding pass for the bus to the airport in Kuala Lumpur My boarding pass for the bus to the airport in Kuala Lumpur. Photo by Ravi Dwivedi. Released under the CC-BY-SA 4.0.
To go to our boarding gate, we had to scan our boarding pass to let the AFC gates open. Then we went downstairs, leading into the waiting area. It had departure boards listing the bus timings and their respective gates. We boarded our bus around 10 minutes before the departure time - 00:00 hours. It departed at its scheduled time and took 45 minutes to reach KL Airport Terminal 2, where we alighted. We reached 6 hours before our flight s departure time of 06:30. We stopped at a convenience store at the airport to have some snacks. Then we weighed our bags at a weighing machine to check whether we were within the weight limit. It turned out that we were. We went to an AirAsia counter to get our boarding passes. The lady at our counter checked our Brunei visas carefully and looked for any Brunei stamps on the passports to verify whether we had used that visa in the past. However, she didn t weigh our bags to check whether they were within the limit, and gave us our boarding passes. We had more than 4 hours to go before our flight. This was the downside of booking an early morning flight - we weren t able to get a full night s sleep. A couple of hours before our flight time, we were hanging around our boarding gate. The place was crowded, so there were no seats available. There were no charging points. There was a Burger King outlet there which had some seating space and charging points. As we were hungry, we ordered two cups of cappuccino coffee (15.9 ringgits) and one large french fries (8.9 ringgits) from Burger King. The total amount was 24 ringgits. When it was time to board the flight, we went to the waiting area for our boarding gates. Soon, we boarded the plane. It took 2.5 hours to reach the Brunei International Airport in the capital city of Bandar Seri Begawan.
View of Kuala Lumpur from the aeroplane View of Kuala Lumpur from the aeroplane. Photo by Ravi Dwivedi. Released under the CC-BY-SA 4.0.
Stay tuned for our experiences in Brunei! Credits: Thanks to Badri, Benson and Contrapunctus for reviewing the draft.

Petter Reinholdtsen: Some of my 2025 free software activities

I guess it is about time I posted a new summary of the free software and open culture activites and projects I have been involved in the last year. The days have been so packed the last year that I have failed with my intention to post at least one blog post per month, so this summary became rather long. I am sorry about this. This year was the year I got tired of the lack of new releases of the multimedia related libraries published via Xiph, and I decided to wrap up the current state and make the releases myself. In a burst of activity early this year, I collected and tested patches, coordinated with other developers and finally made new tarballs and release announcement for theora, and new tarball releases for liboggz, kate and fishsound. This upstreamed several patches accumulated in Debian and other Linux distributions for the last 15 years or so. To change the world and the future, it is important to start with the kids, and one such avenue of change have been created by the current president of FSF Europe, Matthias Kirschner. He wrote a book for children, Ada & Zangemann, and I have been involved in its translation framework for the entire year. The source code has been transformed to Docbook and I have been conducting and coordinating translations into Norwegian Bokm l and Nynorsk, as well as preparing paper editions of the book and an animation movie with Norwegian voices. The Bokm l edition is very close to ready, and will be available early in 2026, and the movie release will follow shortly after this. I intend announce this on my blog and elsewhere when this happen. Please get in touch if you want to help spread the word about this book in Norwegian. I hope we can get the author to Norway when making the Norwegian releases. This year I continued a push for the system I made a few years ago to improve hardware dongle handling on Linux. The Isenkram system use hardware mapping information provided by relevant packages using the AppStream system to propose which Linux distribution packages to install on a given machine to support dongles like cameras, finger print readers, smart card readers, LEGO controllers, ECC memory and other hardware. I have followed up on the list of packages providing such mapping, either to get it into Debian or to upstream the necessary metadata. I am not sure if we are at a point where package maintainers on their own add such information to their packages, but there are Debian lintian reports suggesting it and I have send patches to all packages I am aware of that should include such mappings. Most of the patches are included in Debian now, only 27 was left the last time I checked. As part of my involvement with Debian, I continued my push to get all orphaned packages without a version control repository migrated to git. I am not sure how many packages I went through, but it was in the range of 200-300 packages. In addition to this I updated, sponsored, pushed maintainers for updates upstreamed patches for and fixed RC issues with battery-stats, bs1770gain, isenkram, libonvif, mfiutil, opensnitch, simplescreenrecorder, vlc-plugin-bittorrent and wakeonlan. I've also followed up LEGO related packages, dahdi support for Asterisk, llama.cpp and whisper.cpp in particular for the AMD GPU I was donated by AMD, as well as tried yet again to convince the upstream developers of the photogrammetric workstion e-foto to get their program into a state that could be included in Debian. As I do not buy into the story that it is great to expose oneself to the whims of and priorities of commercial entities to have access to cultural expressions like films and music, I still maintain a huge collection of movies. For this to work well, I have ended up as part of the people maintaining lsdvd upstream and wrapped up a new release fixing several crash bugs caused by DVDs with intentionally broken metadata, and introduced code to list a DVD ID in the lsdvd output. Related to this, I have also worked some add-ons for my main video and music player, and took over upstream maintenance of the Invidious add-on, which sadly stopped working for non-authenticated users when web scrapers made it impossible for Invidious installations to provide a open API, as well as contributed to the NRK and projector control add-ons. As part of my involvement in the Norwegian archiving community and standardisation work, we organised a Noark 5 workshop this spring discussing how to decide what to keep and what to delete in digital archives. We finally managed to apply for Noark 5 certification for the free software archive API Nikita, as well as worked to test and improve the performance of Nikita together with people on my day job at the university. Manufacturing using Free Software is still a focus for me, and I have continued my involved with the LinuxCNC community, organising a developer gathering this summer with the help and sponsoring from the initial start in 2023 from NUUG Foundation and sponsoring from Debian and Redpill-Linpro. We plan to repeat the event also in 2026, but this time NUUG Foundation have told us they do not want a role, so we have found another friendly organisation to handle the money. A popular machine controller with LinuxCNC is the MESA set of electronics, which is centred around a FPGA which now can be programmed using only Free Software. We discussed during this summers gathering how hard it would be to compile the current FPGA source using a Free Software tool chain, and I started looking into this, locating tools to transform the VHDL source into something the Yosys tool chain can handle. Still lot to do there, and I hope to get further next year. An important part of Free Software manufacturing is the ability to design parts and create programs that can be passed to machines making parts, also known as CAD/CAM. The most prominent project for this is FreeCAD, and I have been both pushing to get opencamlib integrated with it in Debian as well as fixing bugs in the handling of Fanuc controlled machines, do make it easier to generate instructions for machines I have access to. I expect to also continue this also next year. This year the UN conference Internet Governance Forum (IGF) was held in Norway, and I tried my best to get a stand for the Norwegian Unix Users Group (NUUG) there. Sadly the effort failed, due to lack of interest with the NUUG Board, but I was happy to see several members at least attend some of the activities related to IGF. Sadly to participate at IGF one need to hand over quite private information, so I decided not to participate in any of the closed forum events myself. Related to NUUG I have been a member of the election board proposing board member candidates to the general assembly, and been part of the program committee of the "Big Tech m vekk" (Big Tech must go away) festival organised by Attac in concert with NUUG and EFN. I've also assisted the Norwegian open TV channel Frikanalen with access to their machines located in a machine room at the university. Related to the University, I have become involved in a small team of students working to build and program robots for the Robocup@Home competition. For 2026 we also plan to use the new features of FreeCAD to make parts for the open hardware robot arm OpenArm. This is also the group that will handle the money for the LinuxCNC gathering in 2026. Also related to the university I was looking into the Linux security auditing system Falco earlier this year, making improvements to the detection rules. This activity is on hold at the moment, and do not expect to continue with this in 2026. I will most likely have to cut down a bit on my free software and open culture activities going forward, as NUUG Foundation, who have funded one day a week for such activities for several years no, sadly have decided they do not want to continue doing this. I am very grateful for their contributions over the years, both with freeing up time for me and supporting several events and projects where I have been involved or taken the initiative on. Now they are reorganizing with more focus on paperwork and applications. As usual, if you use Bitcoin and want to show your support of my activities, please send Bitcoin donations to my address 15oWEoG9dUPovwmUL9KWAnYRtNJEkP1u1b.

Freexian Collaborators: How files are stored by Debusine (by Stefano Rivera)

Debusine is a tool designed for Debian developers and Operating System developers in general. This post describes how Debusine stores and manages files. Debusine has been designed to run a network of workers that can perform various tasks that consume and produce artifacts . The artifact itself is a collection of files structured into an ontology of artifact types. This generic architecture should be suited to many sorts of build & CI problems. We have implemented artifacts to support building a Debian-like distribution, but the foundations of Debusine aim to be more general than that. For example a package build task takes a debian:source-package as input and produces some debian:binary-packages and a debian:package-build-log as output. This generalized approach is quite different to traditional Debian APT archive implementations, which typically required having the archive contents on the filesystem. Traditionally, most Debian distribution management tasks happen within bespoke applications that cannot share much common infrastructure.

File Stores Debusine s files themselves are stored by the File Store layer. There can be multiple file stores configured, with different policies. Local storage is useful as the initial destination for uploads to Debusine, but it has to be backed up manually and might not scale to sufficiently large volumes of data. Remote storage such as S3 is also available. It is possible to serve a file from any store, with policies for which one to prefer for downloads and uploads. Administrators can set policies for which file stores to use at the scope level, as well as policies for populating and draining stores of files.

Artifacts As mentioned above, files are collected into Artifacts. They combine:
  • a set of files with names (including potentially parent directories)
  • a category, e.g. debian:source-package
  • key-value data in a schema specified by the category and stored as a JSON-encoded dictionary.
Within the stores, files are content-addressed: a file with a given SHA-256 digest is only stored once in any given store, and may be retrieved by that digest. When a new artifact is created, its files are uploaded to Debusine as needed. Some of the files may already be present in the Debusine instance. In that case, if the file is already part of the artifact s workspace, then the client will not need to re-upload the file. But if not, it must be reuploaded to avoid users obtaining unauthorized access to existing file contents in another private workspace or multi-tenant scope. Because the content-addressing makes storing duplicates cheap, it s common to have artifacts that overlap files. For example a debian:upload will contain some of the same files as the related debian:source-package as well as the .changes file. Looking at the debusine.debian.net instance that we run, we can see a content-addressing savings of 629 GiB across our (currently) 2 TiB file store. This is somewhat inflated by the Debian Archive import, that did not need to bother to share artifacts between suites. But it still shows reasonable real-world savings.

APT Repository Representation Unlike a traditional Debian APT repository management tool, the source package and binary packages are not stored directly in the pool of an APT repository on disk on the debusine server. Instead we abstract the repository into a debian:suite collection within the Debusine database. The collection contains the artifacts that make up the APT repository. To ensure that it can be safely represented as a valid URL structure (or files on disk) the suite collection maintains an index of the pool filenames of its artifacts. Suite collections can combine into a debian:archive collection that shares a common file pool. Debusine collections can keep an historical record of when things were added and removed. This, combined with the database-backed collection-driven repository representation makes it very easy to provide APT-consumable snapshot views to every point in a repository s history.

Expiry While a published distribution probably wants to keep the full history of all its package builds, we don t need to retain all of the output of all QA tasks that were run. Artifacts can have an expiration delay or inherit one from their workspace. Once this delay has expired, artifacts which are not being held in any collection are eligible to be automatically cleaned up. QA work that is done in a workspace that has automatic artifact expiry, and isn t publishing the results to an APT suite, will safely automatically expire.

Daily Vacuum A daily vacuum task handles all of the file periodic maintenance for file stores. It does some cleanup of working areas, a scan for unreferenced & missing files, and enforces file store policies. The policy work could be copying files for backup or moving files between stores to keep them within size limits (e.g. from a local upload store into a general cloud store).

In Conclusion Debusine provides abstractions for low-level file storage and object collections. This allows storage to be scalable beyond a single filesystem and highly available. Using content-addressed storage minimizes data duplication within a Debusine instance. For Debian distributions, storing the archive metadata entirely in a database made providing built-in snapshot support easy in Debusine.

kpcyrd: 2025 wrapped

Same as last year, this is a summary of what I ve been up to throughout the year. See also the recap/retrospection published by my friends (antiz, jvoisin, orhun). Thanks to everybody who has been part of my human experience, past or present. Especially those who ve been closest.

28 December 2025

Balasankar 'Balu' C: Granting Namespace-Specific Access in GKE Clusters

Heyo, In production Kubernetes environments, access control becomes critical when multiple services share the same cluster. I recently faced this exact scenario: a GKE cluster hosting multiple services across different namespaces, where a new team needed access to maintain and debug their service-but only their service. The requirement was straightforward yet specific: grant external users the ability to exec into pods, view logs, and forward ports, but restrict this access to a single namespace within a single GKE cluster. No access to other clusters in the Google Cloud project, and no access to other namespaces.

The Solution Achieving this granular access control requires combining Google Cloud IAM with Kubernetes RBAC (Role-Based Access Control). Here s how to implement it:

Step 1: Tag Your GKE Cluster First, apply a unique tag to your GKE cluster. This tag will serve as the identifier for IAM policies.

Step 2: Grant IAM Access via Tags Add an IAM policy binding that grants users access to resources with your specific tag. The Kubernetes Engine Viewer role (roles/container.viewer) provides sufficient base permissions without granting excessive access.

Step 3: Create a Kubernetes ClusterRole Define a ClusterRole that specifies the exact permissions needed:
apiVersion: rbac.authorization.k8s.io/v1
kind: ClusterRole
metadata:
  name: custom-access-role
rules:
  - apiGroups: [""]
    resources: ["pods", "pods/exec", "pods/attach", "pods/portforward", "pods/log"]
    verbs: ["get", "list", "watch", "create"]
Note: While you could use a namespace-scoped Role, a ClusterRole offers better reusability if you need similar permissions for other namespaces later.

Step 4: Bind the Role to Users Create a RoleBinding to connect the role to specific users and namespaces:
apiVersion: rbac.authorization.k8s.io/v1
kind: RoleBinding
metadata:
  name: custom-rolebinding
  namespace: my-namespace
subjects:
  - kind: User
    name: myuser@gmail.com
    apiGroup: rbac.authorization.k8s.io
roleRef:
  kind: ClusterRole
  name: custom-access-role
  apiGroup: rbac.authorization.k8s.io
Apply both configurations using kubectl apply -f <filename>.

How It Works This approach creates a two-layer security model:
  • GCP IAM controls which clusters users can access using resource tags
  • Kubernetes RBAC controls what users can do within the cluster and limits their scope to specific namespaces
The result is a secure, maintainable solution that grants teams the access they need without compromising the security of other services in your cluster.

25 December 2025

Russ Allbery: Review: Machine

Review: Machine, by Elizabeth Bear
Series: White Space #2
Publisher: Saga Press
Copyright: October 2020
ISBN: 1-5344-0303-5
Format: Kindle
Pages: 485
Machine is a far-future space opera. It is a loose sequel to Ancestral Night, but you do not have to remember the first book to enjoy this book and they have only a couple of secondary characters in common. There are passing spoilers for Ancestral Night in the story, though, if you care. Dr. Brookllyn Jens is a rescue paramedic on Synarche Medical Vessel I Race To Seek the Living. That means she goes into dangerous situations to get you out of them, patches you up enough to not die, and brings you to doctors who can do the slower and more time-consuming work. She was previously a cop (well, Judiciary, which in this universe is mostly the same thing) and then found that medicine, and specifically the flagship Synarche hospital Core General, was the institution in all the universe that she believed in the most. As Machine opens, Jens is boarding the Big Rock Candy Mountain, a generation ship launched from Earth during the bad era before right-minding and joining the Synarche, back when it looked like humanity on Earth wouldn't survive. Big Rock Candy Mountain was discovered by accident in the wrong place, going faster than it was supposed to be going and not responding to hails. The Synarche ship that first discovered and docked with it is also mysteriously silent. It's the job of Jens and her colleagues to get on board, see if anyone is still alive, and rescue them if possible. What they find is a corpse and a disturbingly servile early AI guarding a whole lot of people frozen in primitive cryobeds, along with odd artificial machinery that seems to be controlled by the AI. Or possibly controlling the AI. Jens assumes her job will be complete once she gets the cryobeds and the AI back to Core General where both the humans and the AI can be treated by appropriate doctors. Jens is very wrong. Machine is Elizabeth Bear's version of a James White Sector General novel. If one reads this book without any prior knowledge, the way that I did, you may not realize this until the characters make it to Core General, but then it becomes obvious to anyone who has read White's series. Most of the standard Sector General elements are here: A vast space station with rings at different gravity levels and atmospheres, a baffling array of species, and the ability to load other people's personalities into your head to treat other species at the cost of discomfort and body dysmorphia. There's a gruff supervisor, a fragile alien doctor, and a whole lot of idealistic and well-meaning people working around complex interspecies differences. Sadly, Bear does drop White's entertainingly oversimplified species classification codes; this is the correct call for suspension of disbelief, but I kind of missed them. I thoroughly enjoy the idea of the Sector General series, so I was delighted by an updated version that drops the sexism and the doctor/nurse hierarchy and adds AIs, doctors for AIs, and a more complicated political structure. The hospital is even run by a sentient tree, which is an inspired choice. Bear, of course, doesn't settle for a relatively simple James White problem-solving plot. There are interlocking, layered problems here, medical and political, immediate and structural, that unwind in ways that I found satisfyingly twisty. As with Ancestral Night, Bear has some complex points to make about morality. I think that aspect of the story was a bit less convincing than Ancestral Night, in part because some of the characters use rather bizarre tactics (although I will grant they are the sort of bizarre tactics that I could imagine would be used by well-meaning people using who didn't think through all of the possible consequences). I enjoyed the ethical dilemmas here, but they didn't grab me the way that Ancestral Night did. The setting, though, is even better: An interspecies hospital was a brilliant setting when James White used it, and it continues to be a brilliant setting in Bear's hands. It's also worth mentioning that Jens has a chronic inflammatory disease and uses an exoskeleton for mobility, and (as much as I can judge while not being disabled myself) everything about this aspect of the character was excellent. It's rare to see characters with meaningful disabilities in far-future science fiction. When present at all, they're usually treated like Geordi's sight: something little different than the differential abilities of the various aliens, or even a backdoor advantage. Jens has a true, meaningful disability that she has to manage and that causes a constant cognitive drain, and the treatment of her assistive device is complex and nuanced in a way that I found thoughtful and satisfying. The one structural complaint that I will make is that Jens is an astonishingly talkative first-person protagonist, particularly for an Elizabeth Bear novel. This is still better than being inscrutable, but she is prone to such extended philosophical digressions or infodumps in the middle of a scene that I found myself wishing she'd get on with it already in a few places. This provides good characterization, in the sense that the reader certainly gets inside Jens's head, but I think Bear didn't get the balance quite right. That complaint aside, this was very fun, and I am certainly going to keep reading this series. Recommended, particularly if you like James White, or want to see why other people do.
The most important thing in the universe is not, it turns out, a single, objective truth. It's not a hospital whose ideals you love, that treats all comers. It's not a lover; it's not a job. It's not friends and teammates. It's not even a child that rarely writes me back, and to be honest I probably earned that. I could have been there for her. I didn't know how to be there for anybody, though. Not even for me. The most important thing in the universe, it turns out, is a complex of subjective and individual approximations. Of tries and fails. Of ideals, and things we do to try to get close to those ideals. It's who we are when nobody is looking.
Followed by The Folded Sky. Rating: 8 out of 10

22 December 2025

Jonathan McDowell: NanoKVM: I like it

I bought a NanoKVM. I d heard some of the stories about how terrible it was beforehand, and some I didn t learn about until afterwards, but at 52, including VAT + P&P, that seemed like an excellent bargain for something I was planning to use in my home network environment. Let s cover the bad press first. apalrd did a video, entitled NanoKVM: The S stands for Security (Armen Barsegyan has a write up recommending a PiKVM instead that lists the objections raised in the video). Matej Kova i wrote an article about the hidden microphone on a Chinese NanoKVM. Various other places have picked up both of these and still seem to be running with them, 10 months later. Next, let me explain where I m coming from here. I have over 2 decades of experience with terrible out-of-band access devices. I still wince when I think of the Sun Opteron servers that shipped with an iLOM that needed a 32-bit Windows browser in order to access it (IIRC some 32 bit binary JNI blob). It was a 64 bit x86 server from a company who, at the time, still had a major non-Windows OS. Sheesh. I do not assume these devices are fit for exposure to the public internet, even if they come from reputable vendors. Add into that the fact the NanoKVM is very much based on a development board (the LicheeRV Nano), and I felt I knew what I was getting into here. And, as a TL;DR, I am perfectly happy with my purchase. Sipeed have actually dealt with a bunch of apalrd s concerns (GitHub ticket), which I consider to be an impressive level of support for this price point. Equally the microphone is explained by the fact this is a 52 device based on a development board. You re giving it USB + HDMI access to a host on your network, if you re worried about the microphone then you re concentrating on the wrong bit here. I started out by hooking the NanoKVM up to my Raspberry Pi classic, which I use as a serial console / network boot tool for working on random bits of hardware. That meant the NanoKVM had no access to the outside world (the Pi is not configured to route, or NAT, for the test network interface), and I could observe what went on. As it happens you can do an SSH port forward of port 80 with this sort of setup and it all works fine - no need for the NanoKVM to have any external access, and it copes happily with being accessed as http://localhost:8000/ (though you do need to choose MJPEG as the video mode, more forwarding or enabling HTTPS is needed for an H.264 WebRTC session). IPv6 is enabled in the kernel. My test setup doesn t have a router advertisements configured, but I could connect to the web application over the v6 link-local address that came up automatically. My device reports:
Image version:              v1.4.1
Application version:        2.2.9
That s recent, but the GitHub releases page has 2.3.0 listed as more recent. Out of the box it s listening on TCP port 80. SSH is not running, but there s a toggle to turn it on and the web interface offers a web based shell (with no extra authentication over the normal login). On first use I was asked to set a username + password. Default access, as you d expect from port 80, is HTTP, but there s a toggle to enable HTTPS. It generates a self signed certificate - for me it had the CN localhost but that might have been due to my use of port forwarding. Enabling HTTPS does not disable HTTP, but HTTP just redirects to the HTTPS URL. As others have discussed it does a bunch of DNS lookups, primarily for NTP servers but also for cdn.sipeed.com. The DNS servers are hard coded:
~ # cat /etc/resolv.conf
nameserver 192.168.0.1
nameserver 8.8.4.4
nameserver 8.8.8.8
nameserver 114.114.114.114
nameserver 119.29.29.29
nameserver 223.5.5.5
This is actually restored on boot from /boot/resolv.conf, so if you want changes to persist you can just edit that file. NTP is configured with a standard set of pool.ntp.org services in /etc/ntp.conf (this does not get restored on reboot, so can just be edited in place). I had dnsmasq on the Pi setup to hand out DNS + NTP servers, but both were ignored (though actually udhcpc does write the DNS details to /etc/resolv.conf.dhcp). My assumption is the lookup to cdn.sipeed.com is for firmware updates (as I bought the NanoKVM cube it came fully installed, so no need for a .so download to make things work); when working DNS was provided I witness attempts to connect to HTTPS. I ve not bothered digging further into this. I did go grab the latest.zip being served from the URL, which turned out to be v2.2.9, matching what I have installed, not the latest on GitHub. I note there s an iptables setup (with nftables underneath) that s not fully realised - it seems to be trying to allow inbound HTTP + WebRTC, as well as outbound SSH, but everything is default accept so none of it gets hit. Setting up a default deny outbound and tweaking a little should provide a bit more reassurance it s not going to try and connect out somewhere it shouldn t. It looks like updates focus solely on the KVM application, so I wanted to take a look at the underlying OS. This is buildroot based:
~ # cat /etc/os-release
NAME=Buildroot
VERSION=-g98d17d2c0-dirty
ID=buildroot
VERSION_ID=2023.11.2
PRETTY_NAME="Buildroot 2023.11.2"
The kernel reports itself as 5.10.4-tag-. Somewhat ancient, but actually an LTS kernel. Except we re now up to 5.10.247, so it obviously hasn t been updated in some time. TBH, this is what I expect (and fear) from embedded devices. They end up with some ancient base OS revision and a kernel with a bunch of hacks that mean it s not easily updated. I get that the margins on this stuff are tiny, but I do wish folk would spend more time upstreaming. Or at least updating to the latest LTS point release for their kernel. The SSH client/daemon is full-fat OpenSSH:
~ # sshd -V
OpenSSH_9.6p1, OpenSSL 3.1.4 24 Oct 2023
There are a number of CVEs fixed in later OpenSSL 3.1 versions, though at present nothing that looks too concerning from the server side. Yes, the image has tcpdump + aircrack installed. I m a little surprised at aircrack (the device has no WiFi and even though I know there s a variant that does, it s not a standard debug tool the way tcpdump is), but there s a copy of GNU Chess in there too, so it s obvious this is just a kitchen-sink image. FWIW it looks like the buildroot config is here. Sadly the UART that I believe the bootloader/kernel are talking to is not exposed externally - the UART pin headers are for UART1 + 2, and I d have to open up the device to get to UART0. I ve not yet done this (but doing so would also allow access to the SD card, which would make trying to compile + test my own kernel easier). In terms of actual functionality it did what I d expect. 1080p HDMI capture was fine. I d have gone for a lower resolution, but I think that would have required tweaking on the client side. It looks like the 2.3.0 release allows EDID tweaking, so I might have to investigate that. The keyboard defaults to a US layout, which caused some problems with the symbol until I reconfigured the target machine not to expect a GB layout. There s also the potential to share out images via USB. I copied a Debian trixie netinst image to /data on the NanoKVM and was able to select it in the web interface and have it appear on the target machine easily. There s also the option to fetch direct from a URL in the web interface, but I was still testing without routable network access, so didn t try that. There s plenty of room for images:
~ # df -h
Filesystem                Size      Used Available Use% Mounted on
/dev/mmcblk0p2            7.6G    823.3M      6.4G  11% /
devtmpfs                 77.7M         0     77.7M   0% /dev
tmpfs                    79.0M         0     79.0M   0% /dev/shm
tmpfs                    79.0M     30.2M     48.8M  38% /tmp
tmpfs                    79.0M    124.0K     78.9M   0% /run
/dev/mmcblk0p1           16.0M     11.5M      4.5M  72% /boot
/dev/mmcblk0p3           22.2G    160.0K     22.2G   0% /data
The NanoKVM also appears as an RNDIS USB network device, with udhcpd running on the interface. IP forwarding is not enabled, and there s no masquerading rules setup, so this doesn t give the target host access to the management LAN by default. I guess it could be useful for copying things over to the target host, as a more flexible approach than a virtual disk image. One thing to note is this makes for a bunch of devices over the composite USB interface. There are 3 HID devices (keyboard, absolute mouse, relative mouse), the RNDIS interface, and the USB mass storage. I had a few occasions where the keyboard input got stuck after I d been playing about with big data copies over the network and using the USB mass storage emulation. There is a HID-only mode (no network/mass storage) to try and help with this, and a restart of the NanoKVM generally brought things back, but something to watch out for. Again I see that the 2.3.0 application update mentions resetting the USB hardware on a HID reset, which might well help. As I stated at the start, I m happy with this purchase. Would I leave it exposed to the internet without suitable firewalling? No, but then I wouldn t do so for any KVM. I wanted a lightweight KVM suitable for use in my home network, something unlikely to see heavy use but that would save me hooking up an actual monitor + keyboard when things were misbehaving. So far everything I ve seen says I ve got my money s worth from it.

Hellen Chemtai: Overcoming Challenges in OpenQA Images Testing: My Internship Journey

Hello there  . Today will be an in depth review on my work with the Debian OpenQA images testing team. I will highlight the struggles that I have had so far during my Outreachy internship. The OpenQA images testing team uses OpenQA to automatically install images e.g. Gnome Images. The images are then tested using tests written in Perl. My current tasks include speech install and capture all audio. I am also installing Live Gnome image to Windows using BalenaEtcher then testing it. A set of similar tasks will also be collaborated on. While working on tasks, I have to go through the guides. I also learn how Perl works so as to edit and create tests. For every change made, I have to re-run the job in developer mode. I have to create needles that have matches and click co-ordinates. I have been stuck on some of these instances:
  1. During installation, my job would not process a second HDD I had added. Roland Clobus , one of my mentors from the team gave me a variable to work with. The solution was adding NUMDISKS=2 as part of the command.
  2. While working on a file, one of the needles would only work after file edits. Afterwards it would fail to assert_and_click . What kept bugging me was why it was passing after the first instance then failing after. The solution was adding a wait_still_screen to the code. This would ensure any screen changes loaded first before clicking happened.
  3. I was stuck on finding the keys that would be needed for a context menu. I added button => right in the assert_and_click code.
  4. Windows 11 installation was constantly failing. Roland pointed out he was working on it so I had to use Windows 10.
  5. Windows 10 Virtual Machine does not connect to the internet because of update restrictions. I had to switch to Linux Virtual Machine for a download job.
When I get stuck, at times I seek guidance from the mentors. I still look for solutions in the documentation. Here are some of the documentation that have helped me get through some of these challenges.
  1. Installation and creating tests guide https://salsa.debian.org/qa/openqa/openqa-tests-debian/-/tree/debian/documentation . These guides help in installation and creating of tests.
  2. OpenQA official documentation https://open.qa/docs/ . This documentation is very comprehensive. I used it recently to read about PUBLISH_HDD_n to save the updated version of a HDD_n I am using.
  3. OpenQA test API documentation https://open.qa/api/testapi/ . This documentation shows me which parameters to use. I have used it recently to find how to right click on a mouse and special characters.
  4. OpenQA variables file in Gitlab https://salsa.debian.org/qa/openqa/openqa-tests-debian/-/blob/debian/VARIABLES.md . This has explanations of the most commonly used variables .
  5. OpenQA repository in Gitlab https://salsa.debian.org/qa/openqa/openqa-tests-debian . I go through the Perl tests. Understand how they work . Then integrate my tests using the a similar manner so that it would look uniform.
  6. OpenQa tests https://openqa.debian.net/tests. I use these tests to find machine settings. I also find test sequences and the assets I would need to create similar tests. I used it recently to look at how graphical login was being implemented then shutdown.
The list above are the documentation that are supposed to be used for these tests and finding solutions. If I don t find anything within these, I then ask Roland for help. I try to go through the autoinst documentation that are from the links provided in the Gitlab README.md file : https://salsa.debian.org/qa/openqa/openqa-tests-debian/-/blob/debian/README.md . They are also comprehensive but are very technical . In general, I get challenges but there is always a means to solve them through documentation provided. The mentors are also very helpful whenever we get challenges. I have gained team contribution skills , upgraded my git skills, learned Perl and how to test using OpenQA. I am still polishing on how to make my needles better. My current progress is thus good. We learn one day at a time.

C.J. Collier: I m learning about perlguts today.


im-learning-about-perlguts-today.png


## 0.23	2025-12-20
commit be15aa25dea40aea66a8534143fb81b29d2e6c08
Author: C.J. Collier 
Date:   Sat Dec 20 22:40:44 2025 +0000
    Fixes C-level test infrastructure and adds more test cases for upb_to_sv conversions.
    
    - **Makefile.PL:**
        - Allow  extra_src  in  c_test_config.json  to be an array.
        - Add ASan flags to CCFLAGS and LDDLFLAGS for better debugging.
        - Corrected echo newlines in  test_c  target.
    - **c_test_config.json:**
        - Added missing type test files to  deps  and  extra_src  for  convert/sv_to_upb  and  convert/upb_to_sv  test runners.
    - **t/c/convert/upb_to_sv.c:**
        - Fixed a double free of  test_pool .
        - Added missing includes for type test headers.
        - Updated test plan counts.
    - **t/c/convert/sv_to_upb.c:**
        - Added missing includes for type test headers.
        - Updated test plan counts.
        - Corrected Perl interpreter initialization.
    - **t/c/convert/types/**:
        - Added missing  test_util.h  include in new type test headers.
        - Completed the set of  upb_to_sv  test cases for all scalar types by adding optional and repeated tests for  sfixed32 ,  sfixed64 ,  sint32 , and  sint64 , and adding repeated tests to the remaining scalar type files.
    - **Documentation:**
        - Updated  01-xs-testing.md  with more debugging tips, including ASan usage and checking for double frees and typos.
        - Updated  xs_learnings.md  with details from the recent segfault.
        - Updated  llm-plan-execution-instructions.md  to emphasize debugging steps.
## 0.22	2025-12-19
commit 2c171d9a5027e0150eae629729c9104e7f6b9d2b
Author: C.J. Collier 
Date:   Fri Dec 19 23:41:02 2025 +0000
    feat(perl,testing): Initialize C test framework and build system
    
    This commit sets up the foundation for the C-level tests and the build system for the Perl Protobuf module:
    
    1.  **Makefile.PL Enhancements:**
        *   Integrates  Devel::PPPort  to generate  ppport.h  for better portability.
        *   Object files now retain their path structure (e.g.,  xs/convert/sv_to_upb.o ) instead of being flattened, improving build clarity.
        *   The  MY::postamble  is significantly revamped to dynamically generate build rules for all C tests located in  t/c/  based on the  t/c/c_test_config.json  file.
        *   C tests are linked against  libprotobuf_common.a  and use  ExtUtils::Embed  flags.
        *   Added  JSON::MaybeXS  to  PREREQ_PM .
        *   The  test  target now also depends on the  test_c  target.
    
    2.  **C Test Infrastructure ( t/c/ ):
        *   Introduced  t/c/c_test_config.json  to configure individual C test builds, specifying dependencies and extra source files.
        *   Created  t/c/convert/test_util.c  and  .h  for shared test functions like loading descriptors.
        *   Initial  t/c/convert/upb_to_sv.c  and  t/c/convert/sv_to_upb.c  test runners.
        *   Basic  t/c/integration/030_protobuf_coro.c  for Coro safety testing on core utils using  libcoro .
        *   Basic  t/c/integration/035_croak_test.c  for testing exception handling.
        *   Basic  t/c/integration/050_convert.c  for integration testing conversions.
    
    3.  **Test Proto:** Updated  t/data/test.proto  with more field types for conversion testing and regenerated  test_descriptor.bin .
    
    4.  **XS Test Harness ( t/c/upb-perl-test.h ):** Added  like_n  macro for length-aware regex matching.
    
    5.  **Documentation:** Updated architecture and plan documents to reflect the C test structure.
    6.  **ERRSV Testing:** Note that the C tests ( t/c/ ) will primarily check *if* a  croak  occurs (i.e., that the exception path is taken), but will not assert on the string content of  ERRSV . Reliably testing  $@  content requires the full Perl test environment with  Test::More , which will be done in the  .t  files when testing the Perl API.
    
    This provides a solid base for developing and testing the XS and C components of the module.
## 0.21	2025-12-18
commit a8b6b6100b2cf29c6df1358adddb291537d979bc
Author: C.J. Collier 
Date:   Thu Dec 18 04:20:47 2025 +0000
    test(C): Add integration tests for Milestone 2 components
    
    - Created t/c/integration/030_protobuf.c to test interactions
      between obj_cache, arena, and utils.
    - Added this test to t/c/c_test_config.json.
    - Verified that all C tests for Milestones 2 and 3 pass,
      including the libcoro-based stress test.
## 0.20	2025-12-18
commit 0fcad68680b1f700a83972a7c1c48bf3a6958695
Author: C.J. Collier 
Date:   Thu Dec 18 04:14:04 2025 +0000
    docs(plan): Add guideline review reminders to milestones
    
    - Added a "[ ] REFRESH: Review all documents in @perl/doc/guidelines/**"
      checklist item to the start of each component implementation
      milestone (C and Perl layers).
    - This excludes Integration Test milestones.
## 0.19	2025-12-18
commit 987126c4b09fcdf06967a98fa3adb63d7de59a34
Author: C.J. Collier 
Date:   Thu Dec 18 04:05:53 2025 +0000
    docs(plan): Add C-level and Perl-level Coro tests to milestones
    
    - Added checklist items for  libcoro -based C tests
      (e.g.,  t/c/integration/050_convert_coro.c ) to all C layer
      integration milestones (050 through 220).
    - Updated  030_Integration_Protobuf.md  to standardise checklist
      items for the existing  030_protobuf_coro.c  test.
    - Removed the single  xt/author/coro-safe.t  item from
       010_Build.md .
    - Added checklist items for Perl-level  Coro  tests
      (e.g.,  xt/coro/240_arena.t ) to each Perl layer
      integration milestone (240 through 400).
    - Created  perl/t/c/c_test_config.json  to manage C test
      configurations externally.
    - Updated  perl/doc/architecture/testing/01-xs-testing.md  to describe
      both C-level  libcoro  and Perl-level  Coro  testing strategies.
## 0.18	2025-12-18
commit 6095a5a610401a6035a81429d0ccb9884d53687b
Author: C.J. Collier 
Date:   Thu Dec 18 02:34:31 2025 +0000
    added coro testing to c layer milestones
## 0.17	2025-12-18
commit cc0aae78b1f7f675fc8a1e99aa876c0764ea1cce
Author: C.J. Collier 
Date:   Thu Dec 18 02:26:59 2025 +0000
    docs(plan): Refine test coverage checklist items for SMARTness
    
    - Updated the "Tests provide full coverage" checklist items in
      C layer plan files (020, 040, 060, 080, 100, 120, 140, 160, 180, 200)
      to explicitly mention testing all public functions in the
      corresponding header files.
    - Expanded placeholder checklists in 140, 160, 180, 200.
    - Updated the "Tests provide full coverage" and "Add coverage checks"
      checklist items in Perl layer plan files (230, 250, 270, 290, 310, 330,
      350, 370, 390) to be more specific about the scope of testing
      and the use of  Test::TestCoverage .
    - Expanded Well-Known Types milestone (350) to detail each type.
## 0.16	2025-12-18
commit e4b601f14e3817a17b0f4a38698d981dd4cb2818
Author: C.J. Collier 
Date:   Thu Dec 18 02:07:35 2025 +0000
    docs(plan): Full refactoring of C and Perl plan files
    
    - Split both ProtobufPlan-C.md and ProtobufPlan-Perl.md into
      per-milestone files under the  perl/doc/plan/  directory.
    - Introduced Integration Test milestones after each component
      milestone in both C and Perl plans.
    - Numbered milestone files sequentially (e.g., 010_Build.md,
      230_Perl_Arena.md).
    - Updated main ProtobufPlan-C.md and ProtobufPlan-Perl.md to
      act as Tables of Contents.
    - Ensured consistent naming for integration test files
      (e.g.,  t/c/integration/030_protobuf.c ,  t/integration/260_descriptor_pool.t ).
    - Added architecture review steps to the end of all milestones.
    - Moved Coro safety test to C layer Milestone 1.
    - Updated Makefile.PL to support new test structure and added Coro.
    - Moved and split t/c/convert.c into t/c/convert/*.c.
    - Moved other t/c/*.c tests into t/c/protobuf/*.c.
    - Deleted old t/c/convert.c.
## 0.15	2025-12-17
commit 649cbacf03abb5e7293e3038bb451c0406e9d0ce
Author: C.J. Collier 
Date:   Wed Dec 17 23:51:22 2025 +0000
    docs(plan): Refactor and reset ProtobufPlan.md
    
    - Split the plan into ProtobufPlan-C.md and ProtobufPlan-Perl.md.
    - Reorganized milestones to clearly separate C layer and Perl layer development.
    - Added more granular checkboxes for each component:
      - C Layer: Create test, Test coverage, Implement, Tests pass.
      - Perl Layer: Create test, Test coverage, Implement Module/XS, Tests pass, C-Layer adjustments.
    - Reset all checkboxes to  [ ]  to prepare for a full audit.
    - Updated status in architecture/api and architecture/core documents to "Not Started".
    
    feat(obj_cache): Add unregister function and enhance tests
    
    - Added  protobuf_unregister_object  to  xs/protobuf/obj_cache.c .
    - Updated  xs/protobuf/obj_cache.h  with the new function declaration.
    - Expanded tests in  t/c/protobuf_obj_cache.c  to cover unregistering,
      overwriting keys, and unregistering non-existent keys.
    - Corrected the test plan count in  t/c/protobuf_obj_cache.c  to 17.
## 0.14	2025-12-17
commit 40b6ad14ca32cf16958d490bb575962f88d868a1
Author: C.J. Collier 
Date:   Wed Dec 17 23:18:27 2025 +0000
    feat(arena): Complete C layer for Arena wrapper
    
    This commit finalizes the C-level implementation for the Protobuf::Arena wrapper.
    
    - Adds  PerlUpb_Arena_Destroy  for proper cleanup from Perl's DEMOLISH.
    - Enhances error checking in  PerlUpb_Arena_Get .
    - Expands C-level tests in  t/c/protobuf_arena.c  to cover memory allocation
      on the arena and lifecycle through  PerlUpb_Arena_Destroy .
    - Corrects embedded Perl initialization in the C test.
    
    docs(plan): Refactor ProtobufPlan.md
    
    - Restructures the development plan to clearly separate "C Layer" and
      "Perl Layer" tasks within each milestone.
    - This aligns the plan with the "C-First Implementation Strategy" and improves progress tracking.
## 0.13	2025-12-17
commit c1e566c25f62d0ae9f195a6df43b895682652c71
Author: C.J. Collier 
Date:   Wed Dec 17 22:00:40 2025 +0000
    refactor(perl): Rename C tests and enhance Makefile.PL
    
    - Renamed test files in  t/c/  to better match the  xs  module structure:
        -  01-cache.c  ->  protobuf_obj_cache.c 
        -  02-arena.c  ->  protobuf_arena.c 
        -  03-utils.c  ->  protobuf_utils.c 
        -  04-convert.c  ->  convert.c 
        -  load_test.c  ->  upb_descriptor_load.c 
    - Updated  perl/Makefile.PL  to reflect the new test names in  MY::postamble 's  $c_test_config .
    - Refactored the  $c_test_config  generation in  Makefile.PL  to reduce repetition by using a default flags hash and common dependencies array.
    - Added a  fail()  macro to  perl/t/c/upb-perl-test.h  for consistency.
    - Modified  t/c/upb_descriptor_load.c  to use the  t/c/upb-perl-test.h  macros, making its output consistent with other C tests.
    - Added a skeleton for  t/c/convert.c  to test the conversion functions.
    - Updated documentation in  ProtobufPlan.md  and  architecture/testing/01-xs-testing.md  to reflect new test names.
## 0.12	2025-12-17
commit d8cb5dd415c6c129e71cd452f78e29de398a82c9
Author: C.J. Collier 
Date:   Wed Dec 17 20:47:38 2025 +0000
    feat(perl): Refactor XS code into subdirectories
    
    This commit reorganizes the C code in the  perl/xs/  directory into subdirectories, mirroring the structure of the Python UPB extension. This enhances modularity and maintainability.
    
    - Created subdirectories for each major component:  convert ,  descriptor ,  descriptor_containers ,  descriptor_pool ,  extension_dict ,  map ,  message ,  protobuf ,  repeated , and  unknown_fields .
    - Created skeleton  .h  and  .c  files within each subdirectory to house the component-specific logic.
    - Updated top-level component headers (e.g.,  perl/xs/descriptor.h ) to include the new sub-headers.
    - Updated top-level component source files (e.g.,  perl/xs/descriptor.c ) to include their main header and added stub initialization functions (e.g.,  PerlUpb_InitDescriptor ).
    - Moved code from the original  perl/xs/protobuf.c  to new files in  perl/xs/protobuf/  (arena, obj_cache, utils).
    - Moved code from the original  perl/xs/convert.c  to new files in  perl/xs/convert/  (upb_to_sv, sv_to_upb).
    - Updated  perl/Makefile.PL  to use a glob ( xs/*/*.c ) to find the new C source files in the subdirectories.
    - Added  perl/doc/architecture/core/07-xs-file-organization.md  to document the new structure.
    - Updated  perl/doc/ProtobufPlan.md  and other architecture documents to reference the new organization.
    - Corrected self-referential includes in the newly created .c files.
    
    This restructuring provides a solid foundation for further development and makes it easier to port logic from the Python implementation.
## 0.11	2025-12-17
commit cdedcd13ded4511b0464f5d3bdd72ce6d34e73fc
Author: C.J. Collier 
Date:   Wed Dec 17 19:57:52 2025 +0000
    feat(perl): Implement C-first testing and core XS infrastructure
    
    This commit introduces a significant refactoring of the Perl XS extension, adopting a C-first development approach to ensure a robust foundation.
    
    Key changes include:
    
    -   **C-Level Testing Framework:** Established a C-level testing system in  t/c/  with a dedicated Makefile, using an embedded Perl interpreter. Initial tests cover the object cache ( 01-cache.c ), arena wrapper ( 02-arena.c ), and utility functions ( 03-utils.c ).
    -   **Core XS Infrastructure:**
        -   Implemented a global object cache ( xs/protobuf.c ) to manage Perl wrappers for UPB objects, using weak references.
        -   Created an  upb_Arena  wrapper ( xs/protobuf.c ).
        -   Consolidated common XS helper functions into  xs/protobuf.h  and  xs/protobuf.c .
    -   **Makefile.PL Enhancements:** Updated to support building and linking C tests, incorporating flags from  ExtUtils::Embed , and handling both  .c  and  .cc  source files.
    -   **XS File Reorganization:** Restructured XS files to mirror the Python UPB extension's layout (e.g.,  message.c ,  descriptor.c ). Removed older, monolithic  .xs  files.
    -   **Typemap Expansion:** Added extensive typemap entries in  perl/typemap  to handle conversions between Perl objects and various  const upb_*Def*  pointers.
    -   **Descriptor Tests:** Added a new test suite  t/02-descriptor.t  to validate descriptor loading and accessor methods.
    -   **Documentation:** Updated development plans and guidelines ( ProtobufPlan.md ,  xs_learnings.md , etc.) to reflect the C-first strategy, new testing methods, and lessons learned.
    -   **Build Cleanup:** Removed  ppport.h  from  .gitignore  as it's no longer used, due to  -DPERL_NO_PPPORT  being set in  Makefile.PL .
    
    This C-first approach allows for more isolated and reliable testing of the core logic interacting with the UPB library before higher-level Perl APIs are built upon it.
## 0.10	2025-12-17
commit 1ef20ade24603573905cb0376670945f1ab5d829
Author: C.J. Collier 
Date:   Wed Dec 17 07:08:29 2025 +0000
    feat(perl): Implement C-level tests and core XS utils
    
    This commit introduces a C-level testing framework for the XS layer and implements key components:
    
    1.  **C-Level Tests ( t/c/ )**:
        *   Added  t/c/Makefile  to build standalone C tests.
        *   Created  t/c/upb-perl-test.h  with macros for TAP-compliant C tests ( plan ,  ok ,  is ,  is_string ,  diag ).
        *   Implemented  t/c/01-cache.c  to test the object cache.
        *   Implemented  t/c/02-arena.c  to test  Protobuf::Arena  wrappers.
        *   Implemented  t/c/03-utils.c  to test string utility functions.
        *   Corrected include paths and diagnostic messages in C tests.
    
    2.  **XS Object Cache ( xs/protobuf.c )**:
        *   Switched to using stringified pointers ( %p ) as hash keys for stability.
        *   Fixed a critical double-free bug in  PerlUpb_ObjCache_Delete  by removing an extra  SvREFCNT_dec  on the lookup key.
    
    3.  **XS Arena Wrapper ( xs/protobuf.c )**:
        *   Corrected  PerlUpb_Arena_New  to use  newSVrv  and  PTR2IV  for opaque object wrapping.
        *   Corrected  PerlUpb_Arena_Get  to safely unwrap the arena pointer.
    
    4.  **Makefile.PL ( perl/Makefile.PL )**:
        *   Added  -Ixs  to  INC  to allow C tests to find  t/c/upb-perl-test.h  and  xs/protobuf.h .
        *   Added  LIBS  to link  libprotobuf_common.a  into the main  Protobuf.so .
        *   Added C test targets  01-cache ,  02-arena ,  03-utils  to the test config in  MY::postamble .
    
    5.  **Protobuf.pm ( perl/lib/Protobuf.pm )**:
        *   Added  use XSLoader;  to load the compiled XS code.
    
    6.  **New files  xs/util.h **:
        *   Added initial type conversion function.
    
    These changes establish a foundation for testing the C-level interface with UPB and fix crucial bugs in the object cache implementation.
## 0.09	2025-12-17
commit 07d61652b032b32790ca2d3848243f9d75ea98f4
Author: C.J. Collier 
Date:   Wed Dec 17 04:53:34 2025 +0000
    feat(perl): Build system and C cache test for Perl XS
    
    This commit introduces the foundational pieces for the Perl XS implementation, focusing on the build system and a C-level test for the object cache.
    
    -   **Makefile.PL:**
        -   Refactored C test compilation rules in  MY::postamble  to use a hash ( $c_test_config ) for better organization and test-specific flags.
        -   Integrated  ExtUtils::Embed  to provide necessary compiler and linker flags for embedding the Perl interpreter, specifically for the  t/c/01-cache.c  test.
        -   Correctly constructs the path to the versioned Perl library ( libperl.so.X.Y.Z ) using  $Config archlib  and  $Config libperl  to ensure portability.
        -   Removed  VERSION_FROM  and  ABSTRACT_FROM  to avoid dependency on  .pm  files for now.
    
    -   **C Cache Test (t/c/01-cache.c):**
        -   Added a C test to exercise the object cache functions implemented in  xs/protobuf.c .
        -   Includes tests for adding, getting, deleting, and weak reference behavior.
    
    -   **XS Cache Implementation (xs/protobuf.c, xs/protobuf.h):**
        -   Implemented  PerlUpb_ObjCache_Init ,  PerlUpb_ObjCache_Add ,  PerlUpb_ObjCache_Get ,  PerlUpb_ObjCache_Delete , and  PerlUpb_ObjCache_Destroy .
        -   Uses a Perl hash ( HV* ) for the cache.
        -   Keys are string representations of the C pointers, created using  snprintf  with  "%llx" .
        -   Values are weak references ( sv_rvweaken ) to the Perl objects ( SV* ).
        -    PerlUpb_ObjCache_Get  now correctly returns an incremented reference to the original SV, not a copy.
        -    PerlUpb_ObjCache_Destroy  now clears the hash before decrementing its refcount.
    
    -   **t/c/upb-perl-test.h:**
        -   Updated  is_sv  to perform direct pointer comparison ( got == expected ).
    
    -   **Minor:** Added  util.h  (currently empty), updated  typemap .
    
    These changes establish a working C-level test environment for the XS components.
## 0.08	2025-12-17
commit d131fd22ea3ed8158acb9b0b1fe6efd856dc380e
Author: C.J. Collier 
Date:   Wed Dec 17 02:57:48 2025 +0000
    feat(perl): Update docs and core XS files
    
    - Explicitly add TDD cycle to ProtobufPlan.md.
    - Clarify mirroring of Python implementation in upb-interfacing.md for both C and Perl layers.
    - Branch and adapt python/protobuf.h and python/protobuf.c to perl/xs/protobuf.h and perl/xs/protobuf.c, including the object cache implementation. Removed old cache.* files.
    - Create initial C test for the object cache in t/c/01-cache.c.
## 0.07	2025-12-17
commit 56fd6862732c423736a2f9a9fb1a2816fc59e9b0
Author: C.J. Collier 
Date:   Wed Dec 17 01:09:18 2025 +0000
    feat(perl): Align Perl UPB architecture docs with Python
    
    Updates the Perl Protobuf architecture documents to more closely align with the design and implementation strategies used in the Python UPB extension.
    
    Key changes:
    
    -   **Object Caching:** Mandates a global, per-interpreter cache using weak references for all UPB-derived objects, mirroring Python's  PyUpb_ObjCache .
    -   **Descriptor Containers:** Introduces a new document outlining the plan to use generic XS container types (Sequence, ByNameMap, ByNumberMap) with vtables to handle collections of descriptors, similar to Python's  descriptor_containers.c .
    -   **Testing:** Adds a note to the testing strategy to port relevant test cases from the Python implementation to ensure feature parity.
## 0.06	2025-12-17
commit 6009ce6ab64eccce5c48729128e5adf3ef98e9ae
Author: C.J. Collier 
Date:   Wed Dec 17 00:28:20 2025 +0000
    feat(perl): Implement object caching and fix build
    
    This commit introduces several key improvements to the Perl XS build system and core functionality:
    
    1.  **Object Caching:**
        *   Introduces  xs/protobuf.c  and  xs/protobuf.h  to implement a caching mechanism ( protobuf_c_to_perl_obj ) for wrapping UPB C pointers into Perl objects. This uses a hash and weak references to ensure object identity and prevent memory leaks.
        *   Updates the  typemap  to use  protobuf_c_to_perl_obj  for  upb_MessageDef *  output, ensuring descriptor objects are cached.
        *   Corrected  sv_weaken  to the correct  sv_rvweaken  function.
    
    2.  **Makefile.PL Enhancements:**
        *   Switched to using the Bazel-generated UPB descriptor sources from  bazel-bin/src/google/protobuf/_virtual_imports/descriptor_proto/google/protobuf/ .
        *   Updated  INC  paths to correctly locate the generated headers.
        *   Refactored  MY::dynamic_lib  to ensure the static library  libprotobuf_common.a  is correctly linked into each generated  .so  module, resolving undefined symbol errors.
        *   Overrode  MY::test  to use  prove -b -j$(nproc) t/*.t xt/*.t  for running tests.
        *   Cleaned up  LIBS  and  LDDLFLAGS  usage.
    
    3.  **Documentation:**
        *   Updated  ProtobufPlan.md  to reflect the current status and design decisions.
        *   Reorganized architecture documents into subdirectories.
        *   Added  object-caching.md  and  c-perl-interface.md .
        *   Updated  llm-guidance.md  with notes on  upb/upb.h  and  sv_rvweaken .
    
    4.  **Testing:**
        *   Fixed  xt/03-moo_immutable.t  to skip tests if no Moo modules are found.
    
    This resolves the build issues and makes the core test suite pass.
## 0.05	2025-12-16
commit 177d2f3b2608b9d9c415994e076a77d8560423b8
Author: C.J. Collier 
Date:   Tue Dec 16 19:51:36 2025 +0000
    Refactor: Rename namespace to Protobuf, build system and doc updates
    
    This commit refactors the primary namespace from  ProtoBuf  to  Protobuf 
    to align with the style guide. This involves renaming files, directories,
    and updating package names within all Perl and XS files.
    
    **Namespace Changes:**
    
    *   Renamed  perl/lib/ProtoBuf  to  perl/lib/Protobuf .
    *   Moved and updated  ProtoBuf.pm  to  Protobuf.pm .
    *   Moved and updated  ProtoBuf::Descriptor  to  Protobuf::Descriptor  (.pm & .xs).
    *   Removed other  ProtoBuf::*  stubs (Arena, DescriptorPool, Message).
    *   Updated  MODULE  and  PACKAGE  in  Descriptor.xs .
    *   Updated  NAME ,  *_FROM  in  perl/Makefile.PL .
    *   Replaced  ProtoBuf  with  Protobuf  throughout  perl/typemap .
    *   Updated namespaces in test files  t/01-load-protobuf-descriptor.t  and  t/02-descriptor.t .
    *   Updated namespaces in all documentation files under  perl/doc/ .
    *   Updated paths in  perl/.gitignore .
    
    **Build System Enhancements (Makefile.PL):**
    
    *   Included  xs/*.c  files in the common object files list.
    *   Added  -I.  to the  INC  paths.
    *   Switched from  MYEXTLIB  to  LIBS => ['-L$(CURDIR) -lprotobuf_common']  for linking.
    *   Removed custom keys passed to  WriteMakefile  for postamble.
    *    MY::postamble  now sources variables directly from the main script scope.
    *   Added  all :: $ common_lib  dependency in  MY::postamble .
    *   Added  t/c/load_test.c  compilation rule in  MY::postamble .
    *   Updated  clean  target to include  blib .
    *   Added more modules to  TEST_REQUIRES .
    *   Removed the explicit  PM  and  XS  keys from  WriteMakefile , relying on  XSMULTI => 1 .
    
    **New Files:**
    
    *    perl/lib/Protobuf.pm 
    *    perl/lib/Protobuf/Descriptor.pm 
    *    perl/lib/Protobuf/Descriptor.xs 
    *    perl/t/01-load-protobuf-descriptor.t 
    *    perl/t/02-descriptor.t 
    *    perl/t/c/load_test.c : Standalone C test for UPB.
    *    perl/xs/types.c  &  perl/xs/types.h : For Perl/C type conversions.
    *    perl/doc/architecture/upb-interfacing.md 
    *    perl/xt/03-moo_immutable.t : Test for Moo immutability.
    
    **Deletions:**
    
    *   Old test files:  t/00_load.t ,  t/01_basic.t ,  t/02_serialize.t ,  t/03_message.t ,  t/04_descriptor_pool.t ,  t/05_arena.t ,  t/05_message.t .
    *   Removed  lib/ProtoBuf.xs  as it's not needed with  XSMULTI .
    
    **Other:**
    
    *   Updated  test_descriptor.bin  (binary change).
    *   Significant content updates to markdown documentation files in  perl/doc/architecture  and  perl/doc/internal  reflecting the new architecture and learnings.
## 0.04	2025-12-14
commit 92de5d482c8deb9af228f4b5ce31715d3664d6ee
Author: C.J. Collier 
Date:   Sun Dec 14 21:28:19 2025 +0000
    feat(perl): Implement Message object creation and fix lifecycles
    
    This commit introduces the basic structure for  ProtoBuf::Message  object
    creation, linking it with  ProtoBuf::Descriptor  and  ProtoBuf::DescriptorPool ,
    and crucially resolves a SEGV by fixing object lifecycle management.
    
    Key Changes:
    
    1.  ** ProtoBuf::Descriptor :** Added  _pool  attribute to hold a strong
        reference to the parent  ProtoBuf::DescriptorPool . This is essential to
        prevent the pool and its C  upb_DefPool  from being garbage collected
        while a descriptor is still in use.
    
    2.  ** ProtoBuf::DescriptorPool :**
        *    find_message_by_name : Now passes the  $self  (the pool object) to the
             ProtoBuf::Descriptor  constructor to establish the lifecycle link.
        *   XSUB  pb_dp_find_message_by_name : Updated to accept the pool  SV*  and
            store it in the descriptor's  _pool  attribute.
        *   XSUB  _load_serialized_descriptor_set : Renamed to avoid clashing with the
            Perl method name. The Perl wrapper now correctly calls this internal XSUB.
        *    DEMOLISH : Made safer by checking for attribute existence.
    
    3.  ** ProtoBuf::Message :**
        *   Implemented using Moo with lazy builders for  _upb_arena  and
             _upb_message .
        *    _descriptor  is a required argument to  new() .
        *   XS functions added for creating the arena ( pb_msg_create_arena ) and
            the  upb_Message  ( pb_msg_create_upb_message ).
        *    pb_msg_create_upb_message  now extracts the  upb_MessageDef*  from the
            descriptor and uses  upb_MessageDef_MiniTable()  to get the minitable
            for  upb_Message_New() .
        *    DEMOLISH : Added to free the message's arena.
    
    4.  ** Makefile.PL :**
        *   Added  -g  to  CCFLAGS  for debugging symbols.
        *   Added Perl CORE include path to  MY::postamble 's  base_flags .
    
    5.  **Tests:**
        *    t/04_descriptor_pool.t : Updated to check the structure of the
            returned  ProtoBuf::Descriptor .
        *    t/05_message.t : Now uses a descriptor obtained from a real pool to
            test  ProtoBuf::Message->new() .
    
    6.  **Documentation:**
        *   Updated  ProtobufPlan.md  to reflect progress.
        *   Updated several files in  doc/architecture/  to match the current
            implementation details, especially regarding arena management and object
            lifecycles.
        *   Added  doc/internal/development_cycle.md  and  doc/internal/xs_learnings.md .
    
    With these changes, the SEGV is resolved, and message objects can be successfully
    created from descriptors.
## 0.03	2025-12-14
commit 6537ad23e93680c2385e1b571d84ed8dbe2f68e8
Author: C.J. Collier 
Date:   Sun Dec 14 20:23:41 2025 +0000
    Refactor(perl): Object-Oriented DescriptorPool with Moo
    
    This commit refactors the  ProtoBuf::DescriptorPool  to be fully object-oriented using Moo, and resolves several issues related to XS, typemaps, and test data.
    
    Key Changes:
    
    1.  **Moo Object:**  ProtoBuf::DescriptorPool.pm  now uses  Moo  to define the class. The  upb_DefPool  pointer is stored as a lazy attribute  _upb_defpool .
    2.  **XS Lifecycle:**  DescriptorPool.xs  now has  pb_dp_create_pool  called by the Moo builder and  pb_dp_free_pool  called from  DEMOLISH  to manage the  upb_DefPool  lifecycle per object.
    3.  **Typemap:** The  perl/typemap  file has been significantly updated to handle the conversion between the  ProtoBuf::DescriptorPool  Perl object and the  upb_DefPool *  C pointer. This includes:
        *   Mapping  upb_DefPool *  to  T_PTR .
        *   An  INPUT  section for  ProtoBuf::DescriptorPool  to extract the pointer from the object's hash, triggering the lazy builder if needed via  call_method .
        *   An  OUTPUT  section for  upb_DefPool *  to convert the pointer back to a Perl integer, used by the builder.
    4.  **Method Renaming:**  add_file_descriptor_set_binary  is now  load_serialized_descriptor_set .
    5.  **Test Data:**
        *   Added  perl/t/data/test.proto  with a sample message and enum.
        *   Generated  perl/t/data/test_descriptor.bin  using  protoc .
        *   Removed  t/data/  from  .gitignore  to ensure test data is versioned.
    6.  **Test Update:**  t/04_descriptor_pool.t  is updated to use the new OO interface, load the generated descriptor set, and check for message definitions.
    7.  **Build Fixes:**
        *   Corrected  #include  paths in  DescriptorPool.xs  to be relative to the  upb/  directory (e.g.,  upb/wire/decode.h ).
        *   Added  -I../upb  to  CCFLAGS  in  Makefile.PL .
        *   Reordered  INC  paths in  Makefile.PL  to prioritize local headers.
    
    **Note:** While tests now pass in some environments, a SEGV issue persists in  make test  runs, indicating a potential memory or lifecycle issue within the XS layer that needs further investigation.
## 0.02	2025-12-14
commit 6c9a6f1a5f774dae176beff02219f504ea3a6e07
Author: C.J. Collier 
Date:   Sun Dec 14 20:13:09 2025 +0000
    Fix(perl): Correct UPB build integration and generated file handling
    
    This commit resolves several issues to achieve a successful build of the Perl extension:
    
    1.  **Use Bazel Generated Files:** Switched from compiling UPB's stage0 descriptor.upb.c to using the Bazel-generated  descriptor.upb.c  and  descriptor.upb_minitable.c  located in  bazel-bin/src/google/protobuf/_virtual_imports/descriptor_proto/google/protobuf/ .
    2.  **Updated Include Paths:** Added the  bazel-bin  path to  INC  in  WriteMakefile  and to  base_flags  in  MY::postamble  to ensure the generated headers are found during both XS and static library compilation.
    3.  **Removed Stage0:** Removed references to  UPB_STAGE0_DIR  and no longer include headers or source files from  upb/reflection/stage0/ .
    4.  **-fPIC:** Explicitly added  -fPIC  to  CCFLAGS  in  WriteMakefile  and ensured  $(CCFLAGS)  is used in the custom compilation rules in  MY::postamble . This guarantees all object files in the static library are compiled with position-independent code, resolving linker errors when creating the shared objects for the XS modules.
    5.  **Refined UPB Sources:** Used  File::Find  to recursively find UPB C sources, excluding  /conformance/  and  /reflection/stage0/  to avoid conflicts and unnecessary compilations.
    6.  **Arena Constructor:** Modified  ProtoBuf::Arena::pb_arena_new  XSUB to accept the class name argument passed from Perl, making it a proper constructor.
    7.  **.gitignore:** Added patterns to  perl/.gitignore  to ignore generated C files from XS ( lib/*.c ,  lib/ProtoBuf/*.c ), the copied  src_google_protobuf_descriptor.pb.cc , and the  t/data  directory.
    8.  **Build Documentation:** Updated  perl/doc/architecture/upb-build-integration.md  to reflect the new build process, including the Bazel prerequisite, include paths,  -fPIC  usage, and  File::Find .
    
    Build Steps:
    1.   bazel build //src/google/protobuf:descriptor_upb_proto  (from repo root)
    2.   cd perl 
    3.   perl Makefile.PL 
    4.   make 
    5.   make test  (Currently has expected failures due to missing test data implementation).
## 0.01	2025-12-14
commit 3e237e8a26442558c94075766e0d4456daaeb71d
Author: C.J. Collier 
Date:   Sun Dec 14 19:34:28 2025 +0000
    feat(perl): Initialize Perl extension scaffold and build system
    
    This commit introduces the  perl/  directory, laying the groundwork for the Perl Protocol Buffers extension. It includes the essential build files, linters, formatter configurations, and a vendored Devel::PPPort for XS portability.
    
    Key components added:
    
    *   ** Makefile.PL **: The core  ExtUtils::MakeMaker  build script. It's configured to:
        *   Build a static library ( libprotobuf_common.a ) from UPB, UTF8_Range, and generated protobuf C/C++ sources.
        *   Utilize  XSMULTI => 1  to create separate shared objects for  ProtoBuf ,  ProtoBuf::Arena , and  ProtoBuf::DescriptorPool .
        *   Link each XS module against the common static library.
        *   Define custom compilation rules in  MY::postamble  to handle C vs. C++ flags and build the static library.
        *   Set up include paths for the project root, UPB, and other dependencies.
    
    *   **XS Stubs ( .xs  files)**:
        *    lib/ProtoBuf.xs : Placeholder for the main module's XS functions.
        *    lib/ProtoBuf/Arena.xs : XS interface for  upb_Arena  management.
        *    lib/ProtoBuf/DescriptorPool.xs : XS interface for  upb_DefPool  management.
    
    *   **Perl Module Stubs ( .pm  files)**:
        *    lib/ProtoBuf.pm : Main module, loads XS.
        *    lib/ProtoBuf/Arena.pm : Perl class for Arenas.
        *    lib/ProtoBuf/DescriptorPool.pm : Perl class for Descriptor Pools.
        *    lib/ProtoBuf/Message.pm : Base class for messages (TBD).
    
    *   **Configuration Files**:
        *    .gitignore : Ignores build artifacts, editor files, etc.
        *    .perlcriticrc : Configures Perl::Critic for static analysis.
        *    .perltidyrc : Configures perltidy for code formatting.
    
    *   ** Devel::PPPort **: Vendored version 3.72 to generate  ppport.h  for XS compatibility across different Perl versions.
    
    *   ** typemap **: Custom typemap for XS argument/result conversion.
    
    *   **Documentation ( doc/ )**: Initial architecture and plan documents.
    
    This provides a solid foundation for developing the UPB-based Perl extension.

21 December 2025

Ian Jackson: Debian s git transition

tl;dr: There is a Debian git transition plan. It s going OK so far but we need help, especially with outreach and updating Debian s documentation. Goals of the Debian git transition project
  1. Everyone who interacts with Debian source code should be able to do so entirely in git.
That means, more specifically:
  1. All examination and edits to the source should be performed via normal git operations.
  2. Source code should be transferred and exchanged as git data, not tarballs. git should be the canonical form everywhere.
  3. Upstream git histories should be re-published, traceably, as part of formal git releases published by Debian.
  4. No-one should have to learn about Debian Source Packages, which are bizarre, and have been obsoleted by modern version control.
This is very ambitious, but we have come a long way! Achievements so far, and current status We have come a very long way. But, there is still much to do - especially, the git transition team needs your help with adoption, developer outreach, and developer documentation overhaul. We ve made big strides towards goals 1 and 4. Goal 2 is partially achieved: we currently have dual running. Goal 3 is within our reach but depends on widespread adoption of tag2upload (and/or dgit push). Downstreams and users can obtain the source code of any Debian package in git form. (dgit clone, 2013). They can then work with this source code completely in git, including building binaries, merging new versions, even automatically (eg Raspbian, 2016), and all without having to deal with source packages at all (eg Wikimedia 2025). A Debian maintainer can maintain their own package entirely in git. They can obtain upstream source code from git, and do their packaging work in git (git-buildpackage, 2006). Every Debian maintainer can (and should!) release their package from git reliably and in a standard form (dgit push, 2013; tag2upload, 2025). This is not only more principled, but also more convenient, and with better UX, than pre-dgit tooling like dput. Indeed a Debian maintainer can now often release their changes to Debian, from git, using only git branches (so no tarballs). Releasing to Debian can be simply pushing a signed tag (tag2upload, 2025). A Debian maintainer can maintain a stack of changes to upstream source code in git (gbp pq 2009). They can even maintain such a delta series as a rebasing git branch, directly buildable, and use normal git rebase style operations to edit their changes, (git-dpm, 2010; git-debrebase, 2018) An authorised Debian developer can do a modest update to any package in Debian, even one maintained by someone else, working entirely in git in a standard and convenient way (dgit, 2013). Debian contributors can share their work-in-progress on git forges and collaborate using merge requests, git based code review, and so on. (Alioth, 2003; Salsa, 2018.) Core engineering principle The Debian git transition project is based on one core engineering principle: Every Debian Source Package can be losslessly converted to and from git. In order to transition away from Debian Source Packages, we need to gateway between the old dsc approach, and the new git approach. This gateway obviously needs to be bidirectional: source packages uploaded with legacy tooling like dput need to be imported into a canonical git representation; and of course git branches prepared by developers need to be converted to source packages for the benefit of legacy downstream systems (such as the Debian Archive and apt source). This bidirectional gateway is implemented in src:dgit, and is allowing us to gradually replace dsc-based parts of the Debian system with git-based ones. Correspondence between dsc and git A faithful bidirectional gateway must define an invariant: The canonical git tree, corresponding to a .dsc, is the tree resulting from dpkg-source -x. This canonical form is sometimes called the dgit view . It s sometimes not the same as the maintainer s git branch, because many maintainers are still working with patches-unapplied git branches. More on this below. (For 3.0 (quilt) .dscs, the canonical git tree doesn t include the quilt .pc directory.) Patches-applied vs patches-unapplied The canonical git format is patches applied . That is: If Debian has modified the upstream source code, a normal git clone of the canonical branch gives the modified source tree, ready for reading and building. Many Debian maintainers keep their packages in a different git branch format, where the changes made by Debian, to the upstream source code, are in actual patch files in a debian/patches/ subdirectory. Patches-applied has a number of important advantages over patches-unapplied: The downside is that, with the (bizarre) 3.0 (quilt) source format, the patch files files in debian/patches/ must somehow be kept up to date. Nowadays though, tools like git-debrebase and git-dpm (and dgit for NMUs) make it very easy to work with patches-applied git branches. git-debrebase can deal very ergonomically even with big patch stacks. (For smaller packages which usually have no patches, plain git merge with an upstream git branch, and a much simpler dsc format, sidesteps the problem entirely.) Prioritising Debian s users (and other outsiders) We want everyone to be able to share and modify the software that they interact with. That means we should make source code truly accessible, on the user s terms. Many of Debian s processes assume everyone is an insider. It s okay that there are Debian insiders and that people feel part of something that they worked hard to become involved with. But lack of perspective can lead to software which fails to uphold our values. Our source code practices in particular, our determination to share properly (and systematically) are a key part of what makes Debian worthwhile at all. Like Debian s installer, we want our source code to be useable by Debian outsiders. This is why we have chosen to privilege a git branch format which is more familiar to the world at large, even if it s less popular in Debian. Consequences, some of which are annoying The requirement that the conversion be bidirectional, lossless, and context-free can be inconvenient. For example, we cannot support .gitattributes which modify files during git checkin and checkout. .gitattributes cause the meaning of a git tree to depend on the context, in possibly arbitrary ways, so the conversion from git to source package wouldn t be stable. And, worse, some source packages might not to be representable in git at all. Another example: Maintainers often have existing git branches for their packages, generated with pre-dgit tooling which is less careful and less principled than ours. That can result in discrepancies between git and dsc, which need to be resolved before a proper git-based upload can succeed. That some maintainers use patches-unapplied, and some patches-unapplied, means that there has to be some kind of conversion to a standard git representation. Choosing the less-popular patches-applied format as the canonical form, means that many packages need their git representation converted. It also means that user- and outsider-facing branches from browse,git .dgit.d.o and dgit clone are not always compatible with maintainer branches on Salsa. User-contributed changes need cherry-picking rather than merging, or conversion back to the maintainer format. The good news is that dgit can automate much of this, and the manual parts are usually easy git operations. Distributing the source code as git Our source code management should be normal, modern, and based on git. That means the Debian Archive is obsolete and needs to be replaced with a set of git repositories. The replacement repository for source code formally released to Debian is *.dgit.debian.org. This contains all the git objects for every git-based upload since 2013, including the signed tag for each released package version. The plan is that it will contain a git view of every uploaded Debian package, by centrally importing all legacy uploads into git. Tracking the relevant git data, when changes are made in the legacy Archive Currently, many critical source code management tasks are done by changes to the legacy Debian Archive, which works entirely with dsc files (and the associated tarballs etc). The contents of the Archive are therefore still an important source of truth. But, the Archive s architecture means it cannot sensibly directly contain git data. To track changes made in the Archive, we added the Dgit: field to the .dsc of a git-based upload (2013). This declares which git commit this package was converted from. and where those git objects can be obtained. Thus, given a Debian Source Package from a git-based upload, it is possible for the new git tooling to obtain the equivalent git objects. If the user is going to work in git, there is no need for any tarballs to be downloaded: the git data could be obtained from the depository using the git protocol. The signed tags, available from the git depository, have standardised metdata which gives traceability back to the uploading Debian contributor. Why *.dgit.debian.org is not Salsa We need a git depository - a formal, reliable and permanent git repository of source code actually released to Debian. Git forges like Gitlab can be very convenient. But Gitlab is not sufficiently secure, and too full of bugs, to be the principal and only archive of all our source code. (The open core business model of the Gitlab corporation, and the constant-churn development approach, are critical underlying problems.) Our git depository lacks forge features like Merge Requests. But: The dgit git depository outlasted Alioth and it may well outlast Salsa. We need both a good forge, and the *.dgit.debian.org formal git depository. Roadmap In progress Right now we are quite focused on tag2upload. We are working hard on eliminating the remaining issues that we feel need to be addressed before declaring the service out of beta. Future Technology Whole-archive dsc importer Currently, the git depository only has git data for git-based package updates (tag2upload and dgit push). Legacy dput-based uploads are not currently present there. This means that the git-based and legacy uploads must be resolved client-side, by dgit clone. We will want to start importing legacy uploads to git. Then downstreams and users will be able to get the source code for any package simply with git clone, even if the maintainer is using legacy upload tools like dput. Support for git-based uploads to security.debian.org Security patching is a task which would particularly benefit from better and more formal use of git. git-based approaches to applying and backporting security patches are much more convenient than messing about with actual patch files. Currently, one can use git to help prepare a security upload, but it often involves starting with a dsc import (which lacks the proper git history) or figuring out a package maintainer s unstandardised git usage conventions on Salsa. And it is not possible to properly perform the security release as git. Internal Debian consumers switch to getting source from git Buildds, QA work such as lintian checks, and so on, could be simpler if they don t need to deal with source packages. And since git is actually the canonical form, we want them to use it directly. Problems for the distant future For decades, Debian has been built around source packages. Replacing them is a long and complex process. Certainly source packages are going to continue to be supported for the foreseeable future. There are no doubt going to be unanticipated problems. There are also foreseeable issues: for example, perhaps there are packages that work very badly when represented in git. We think we can rise to these challenges as they come up. Mindshare and adoption - please help! We and our users are very pleased with our technology. It is convenient and highly dependable. dgit in particular is superb, even if we say so ourselves. As technologists, we have been very focused on building good software, but it seems we have fallen short in the marketing department. A rant about publishing the source code git is the preferred form for modification. Our upstreams are overwhelmingly using git. We are overwhelmingly using git. It is a scandal that for many packages, Debian does not properly, formally and officially publish the git history. Properly publishing the source code as git means publishing it in a way that means that anyone can automatically and reliably obtain and build the exact source code corresponding to the binaries. The test is: could you use that to build a derivative? Putting a package in git on Salsa is often a good idea, but it is not sufficient. No standard branch structure git on Salsa is enforced, nor should it be (so it can t be automatically and reliably obtained), the tree is not in a standard form (so it can t be automatically built), and is not necessarily identical to the source package. So Vcs-Git fields, and git from Salsa, will never be sufficient to make a derivative. Debian is not publishing the source code! The time has come for proper publication of source code by Debian to no longer be a minority sport. Every maintainer of a package whose upstream is using git (which is nearly all packages nowadays) should be basing their work on upstream git, and properly publishing that via tag2upload or dgit. And it s not even difficult! The modern git-based tooling provides a far superior upload experience. A common misunderstanding dgit push is not an alternative to gbp pq or quilt. Nor is tag2upload. These upload tools complement your existing git workflow. They replace and improve source package building/signing and the subsequent dput. If you are using one of the usual git layouts on salsa, and your package is in good shape, you can adopt tag2upload and/or dgit push right away. git-debrebase is distinct and does provides an alternative way to manage your git packaging, do your upstream rebases, etc. Documentation Debian s documentation all needs to be updated, including particularly instructions for packaging, to recommend use of git-first workflows. Debian should not be importing git-using upstreams release tarballs into git. (Debian outsiders who discover this practice are typically horrified.) We should use only upstream git, work only in git, and properly release (and publish) in git form. We, the git transition team, are experts in the technology, and can provide good suggestions. But we do not have the bandwidth to also engage in the massive campaigns of education and documentation updates that are necessary especially given that (as with any programme for change) many people will be sceptical or even hostile. So we would greatly appreciate help with writing and outreach. Personnel We consider ourselves the Debian git transition team. Currently we are: We wear the following hats related to the git transition: You can contact us: We do most of our heavy-duty development on Salsa. Thanks Particular thanks are due to Joey Hess, who, in the now-famous design session in Vaumarcus in 2013, helped invent dgit. Since then we have had a lot of support: most recently political support to help get tag2upload deployed, but also, over the years, helpful bug reports and kind words from our users, as well as translations and code contributions. Many other people have contributed more generally to support for working with Debian source code in git. We particularly want to mention Guido G nther (git-buildpackage); and of course Alexander Wirt, Joerg Jaspert, Thomas Goirand and Antonio Terceiro (Salsa administrators); and before them the Alioth administrators.

comment count unavailable comments

Russell Coker: Links December 2025

Russ Allbery wrote an interesting review of Politics on the Edge, by Rory Stewart who sems like one of the few conservative politicians I could respect and possibly even like [1]. It has some good insights about the problems with our current political environment. The NY Times has an amusing article about the attempt to sell the solution to the CIA s encrypted artwork [2]. Wired has an interesting article about computer face recognition systems failing on people with facial disabilities or scars [3]. This is a major accessibility issue potentially violating disability legislation and a demonstration of the problems of fully automating systems when there should be a human in the loop. The October 2025 report from the Debian Reproducible Builds team is particularly interesting [4]. kpcyrd forwarded a fascinating tidbit regarding so-called ninja and samurai build ordering, that uses data structures in which the pointer values returned from malloc are used to determine some order of execution LOL Louis Rossmann made an insightful youtube video about the moral case for piracy of software and media [5]. Louis Rossman made an insightful video about the way that Hyundai is circumventing Right to Repair laws to make repairs needlessly expensive [6]. Korean cars aren t much good nowadays. Their prices keep increasing and the quality doesn t. Brian Krebs wrote an interesting article about how Google is taking legal action against SMS phishing crime groups [7]. We need more of this! Josh Griffiths wrote an informative blog post about how YouTube is awful [8]. I really should investigate Peertube. Louis Rossman made an informative YouTube video about Right to Repair and the US military, if even the US military is getting ripped off by this it s a bigger problem than most people realise [9]. He also asks the rhetorical question of whether politicians are bought or whether it s a subscription model . Brian Krebs wrote an informative article about the US plans to ban TP Link devices, OpenWRT seems like a good option [10]. Brian Krebs wrote an informative article about free streaming Android TV boxes that act as hidden residential VPN proxies [11]. Also the free streaming violates copyright law. Bruce Schneier and Nathan E. Sanders wrote an interesting article about ways that AI is being used to strengthen democracy [12]. Cory Doctorow wrote an insightful article about the incentives for making shitty goods and services and why we need legislation to protect consumers [13]. Linus Tech Tips has an interesting interview with Linus Torvalds [14]. Interesting video about the Kowloon Walled City [15]. It would be nice if a government deliberately created a hive city like that, the only example I know of is the Alaskan town in a single building. David Brin wrote an insightful set of 3 blog posts about a Democratic American deal that could improve the situation there [16].

19 December 2025

Otto Kek l inen: Backtesting trailing stop-loss strategies with Python and market data

Featured image of post Backtesting trailing stop-loss strategies with Python and market dataIn January 2024 I wrote about the insanity of the Magnificent Seven dominating the MSCI World Index, and I wondered how long the number can continue to go up? It has continued to surge upward at an accelerating pace, which makes me worry that a crash is likely closer. As a software professional, I decided to analyze whether using stop-loss orders could reliably automate avoiding deep drawdowns. As everyone with some savings in the stock market (hopefully) knows, the stock market eventually experiences crashes. It is just a matter of when and how deep the crash will be. Staying on the sidelines for years is not a good investment strategy, as inflation will erode the value of your savings. Assuming the current true inflation rate is around 7%, a restaurant dinner that costs 20 euros today will cost 24.50 euros in three years. Savings of 1000 euros today would drop in purchasing power from 50 dinners to only 40 dinners in three years. Hence, if you intend to retain the value of your hard-earned savings, they need to be invested in something that grows in value. Most people try to beat inflation by buying shares in stable companies, directly or via broad market ETFs. These historically grow faster than inflation during normal years, but likely drop in value during recessions.

What is a trailing stop-loss order? What if you could buy stocks to benefit from their value increasing without having to worry about a potential crash? All modern online stock brokers have a feature called stop-loss, where you can enter a price at which your stocks automatically get sold if they drop down to that price. A trailing stop-loss order is similar, but instead of a fixed price, you enter a margin (e.g. 10%). If the stock price rises, the stop-loss price will trail upwards by that margin. For example, if you buy a share at 100 euros and it has risen to 110 euros, you can set a 10% trailing stop-loss order which automatically sells it if the price drops 10% from the peak of 110 euros, at 99 euros. Thus, no matter what happens, you only lost 1 euro. And if the stock price continues to rise to 150 euros, the trailing stop-loss would automatically readjust to 150 euros minus 10%, which is 135 euros (150-15=135). If the price dropped to 135 euros, you would lock in a gain of 35 euros, which is not the peak price of 150 euros, but still better than whatever the price fell down to as a result of a large crash. In the simple case above, it obviously makes sense in theory, but it might not make sense in practice. Prices constantly oscillate, so you don t want a margin that is too small, otherwise you exit too early. Conversely, having a large margin may result in too large a drawdown before exiting. If markets crash rapidly, it might be that nobody buys your stocks at the stop-loss price, and shares have to be sold at an even lower price. Also, what will you do once the position is sold? The reason you invested in the stock market was to avoid holding cash, so would you buy the same stock back when the crash bottoms? But how will you know when the bottom has been reached?

Backtesting stock market strategies with Python, YFinance, Pandas and Lightweight Charts I am not a professional investor, and nobody should take investment advice from me. However, I know what backtesting is and how to leverage open source software. So, I wrote a Python script to test if the trading strategy of using trailing stop-loss orders with specific margin values would have worked for a particular stock. First you need to have data. YFinance is a handy Python library that can be used to download the historic price data for any stock ticker on Yahoo.com. Then you need to manipulate the data. Pandas is the Python data analysis library with advanced data structures for working with relational or labeled data. Finally, to visualize the results, I used Lightweight Charts, which is a fast, interactive library for rendering financial charts, allowing you to plot the stock price, the trailing stop-loss line, and the points where trades would have occurred. I really like how the zoom is implemented in Lightweight Charts, which makes drilling into the data points feel effortless. The full solution is not polished enough to be published for others to use, but you can piece together your own by reusing some of the key snippets. To avoid re-downloading the same data repeatedly, I implemented a small caching wrapper that saves the data locally (as Parquet files):
python
CACHE_DIR.mkdir(parents=True, exist_ok=True)
end_date = datetime.today().strftime("%Y-%m-%d")
cache_file = CACHE_DIR / f" TICKER - START_DATE -- end_date .parquet"

if cache_file.is_file():
 dataframe = pandas.read_parquet(cache_file)
 print(f"Loaded price data from cache:  cache_file ")
else:
 dataframe = yfinance.download(
 TICKER,
 start=START_DATE,
 end=end_date,
 progress=False,
 auto_adjust=False
 )

 dataframe.to_parquet(cache_file)
 print(f"Fetched new price data from Yahoo Finance and cached to:  cache_file ")
The dataframe is a Pandas object with a powerful API. For example, to print a snippet from the beginning and the end of the dataframe to see what the data looks like, you can use:
python
print("First 5 rows of the raw data:")
print(df.head())
print("Last 5 rows of the raw data:")
print(df.tail())
Example output:
First 5 rows of the raw data
Price Adj Close Close High Low Open Volume
Ticker BNP.PA BNP.PA BNP.PA BNP.PA BNP.PA BNP.PA
Date
2014-01-02 29.956285 55.540001 56.910000 55.349998 56.700001 316552
2014-01-03 30.031801 55.680000 55.990002 55.290001 55.580002 210044
2014-01-06 30.080338 55.770000 56.230000 55.529999 55.560001 185142
2014-01-07 30.943321 57.369999 57.619999 55.790001 55.880001 370397
2014-01-08 31.385597 58.189999 59.209999 57.750000 57.790001 489940
Last 5 rows of the raw data
Price Adj Close Close High Low Open Volume
Ticker BNP.PA BNP.PA BNP.PA BNP.PA BNP.PA BNP.PA
Date
2025-12-11 78.669998 78.669998 78.919998 76.900002 76.919998 357918
2025-12-12 78.089996 78.089996 80.269997 78.089996 79.470001 280477
2025-12-15 79.080002 79.080002 79.449997 78.559998 78.559998 233852
2025-12-16 78.860001 78.860001 79.980003 78.809998 79.430000 283057
2025-12-17 80.080002 80.080002 80.150002 79.080002 79.199997 262818
Adding new columns to the dataframe is easy. For example, I used a custom function to calculate the Relative Strength Index (RSI). To add a new column RSI with a value for every row based on the price from that row, only one line of code is needed, without custom loops:
python
df["RSI"] = compute_rsi(df["price"], period=14)
After manipulating the data, the series can be converted into an array structure and printed as JSON into a placeholder in an HTML template:
python
 baseline_series = [
  "time": ts, "value": val 
 for ts, val in df_plot[["timestamp", BASELINE_LABEL]].itertuples(index=False)
 ]

 baseline_json = json.dumps(baseline_series)
 template = jinja2.Template("template.html")
 rendered_html = template.render(
 title=title,
 heading=heading,
 description=description_html,
 ...
 baseline_json=baseline_json,
 ...
 )

 with open("report.html", "w", encoding="utf-8") as f:
 f.write(rendered_html)
 print("Report generated!")
In the HTML template, the marker variable in Jinja syntax gets replaced with the actual JSON:
html
<!DOCTYPE html>
<html lang="en">
<head>
 <meta charset="UTF-8">
 <title>  title  </title>
 ...
</head>
<body>
 <h1>  heading  </h1>
 <div id="chart"></div>
 <script>
 // Ensure the DOM is ready before we initialise the chart
 document.addEventListener('DOMContentLoaded', () =>  
 // Parse the JSON data passed from Python
 const baselineData =   baseline_json   safe  ;
 const strategyData =   strategy_json   safe  ;
 const markersData =   markers_json   safe  ;

 // Create the chart
 const chart = LightweightCharts.createChart(document.getElementById('chart'),  
 width: document.getElementById('chart').clientWidth,
 height: 500,
 layout:  
 background:   color: "#222"  ,
 textColor: "#ccc"
  ,
 grid:  
 vertLines:   color: "#555"  ,
 horzLines:   color: "#555"  
  
  );

 // Add baseline series
 const baselineSeries = chart.addLineSeries( 
 title: '  baseline_label  ',
 lastValueVisible: false,
 priceLineVisible: false,
 priceLineWidth: 1
  );
 baselineSeries.setData(baselineData);

 baselineSeries.priceScale().applyOptions( 
 entireTextOnly: true
  );

 // Add strategy series
 const strategySeries = chart.addLineSeries( 
 title: '  strategy_label  ',
 lastValueVisible: false,
 priceLineVisible: false,
 color: '#FF6D00'
  );
 strategySeries.setData(strategyData);

 // Add buy/sell markers to the strategy series
 strategySeries.setMarkers(markersData);

 // Fit the chart to show the full data range (full zoom)
 chart.timeScale().fitContent();
  )
 </script>
</body>
</html>
There are also Python libraries built specifically for backtesting investment strategies, such as Backtrader and Zipline, but they do not seem to be actively maintained, and probably have too many features and complexity compared to what I needed for doing this simple test. The screenshot below shows an example of backtesting a strategy on the Waste Management Inc stock from January 2015 to December 2025. The baseline Buy and hold scenario is shown as the blue line and it fully tracks the stock price, while the orange line shows how the strategy would have performed, with markers for the sells and buys along the way. Backtest run example

Results I experimented with multiple strategies and tested them with various parameters, but I don t think I found a strategy that was consistently and clearly better than just buy-and-hold. It basically boils down to the fact that I was not able to find any way to calculate when the crash has bottomed based on historical data. You can only know in hindsight that the price has stopped dropping and is on a steady path to recovery, but at that point it is already too late to buy in. In my testing, most strategies underperformed buy-and-hold because they sold when the crash started, but bought back after it recovered at a slightly higher price. In particular when using narrow margins and selling on a 3-6% drawdown the strategy performed very badly, as those small dips tend to recover in a few days. Essentially, the strategy was repeating the pattern of selling 100 stocks at a 6% discount, then being able to buy back only 94 shares the next day, then again selling 94 shares at a 6% discount, and only being able to buy back maybe 90 shares after recovery, and so forth, never catching up to the buy-and-hold. The strategy worked better in large market crashes as they tended to last longer, and there were higher chances of buying back the shares while the price was still low. For example, in the 2020 crash selling at a 20% drawdown was a good strategy, as the stock I tested dropped nearly 50% and remained low for several weeks; thus, the strategy bought back the stocks while the price was still low and had not yet started to climb significantly. But that was just a lucky incident, as the delta between the trailing stop-loss margin of 20% and total crash of 50% was large enough. If the crash had been only 25%, the strategy would have missed the rebound and ended up buying back the stocks at a slightly higher price. Also, note that the simulation assumes that the trade itself is too small to affect the price formation. We should keep in mind that in reality, if many people have stop-loss orders in place, a large price drop would trigger all of them, creating a flood of sell orders, which in turn would affect the price and drive it lower even faster and deeper. Luckily, it seems that stop-loss orders are generally not a good strategy, and we don t need to fear that too many people will be using them.

Conclusion Even though using a trailing stop-loss strategy does not seem to help in getting consistently higher returns based on my backtesting, I would still say it is useful in protecting from the downside of stock investing. It can act as a kind of insurance policy to considerably decrease the chances of losing big while increasing the chances of losing a little bit. If you are risk-averse, which I think I probably am, this tradeoff can make sense. I d rather miss out on an initial 50% loss and an overall 3% gain on recovery than have to sit through weeks or months with a 50% loss before the price recovers to prior levels. Most notably, the trailing stop-loss strategy works best if used only once. If it is repeated multiple times, the small losses in gains will compound into big losses overall. Thus, I think I might actually put this automation in place at least on the stocks in my portfolio that have had the highest gains. If they keep going up, I will ride along, but once the crash happens, I will be out of those particular stocks permanently. Do you have a favorite open source investment tool or are you aware of any strategy that actually works? Comment below!

18 December 2025

Dirk Eddelbuettel: dang 0.0.17: New Features, Plus Maintenance

dang image A new release of my mixed collection of things package dang package arrived at CRAN earlier today. The dang package regroups a few functions of mine that had no other home as for example lsos() from a StackOverflow question from 2009 (!!), the overbought/oversold price band plotter from an older blog post, the market monitor blogged about as well as the checkCRANStatus() function tweeted about by Tim Taylor. And more so take a look. This release retires two functions: the social media site nobody ever visits anymore shut down its API too, so no way to mute posts by a given handle. Similarly, the (never official) ability by Google to supply financial data is no more, so the function to access data this way is gone too. But we also have two new ones: one that helps with CRAN entries for ORCiD ids, and another little helper to re-order microbenchmark results by summary column (defaulting to the median). Other than the usual updates to continuous integrations, as well as a switch to Authors@R which will result in CRAN nagging me less about this, and another argument update. The detailed NEWS entry follows.
Changes in version 0.0.17 (2025-12-18)
  • Added new funtion reorderMicrobenchmarkResults with alias rmr
  • Use tolower on email argument to checkCRANStatus
  • Added new function cranORCIDs bootstrapped from two emails by Kurt Hornik
  • Switched to using Authors@R in DESCRIPTION and added ORCIDs where available
  • Switched to r-ci action with included bootstrap step; updated updated the checkout action (twice); added (commented-out) log accessor
  • Removed googleFinanceData as the (unofficial) API access point no longer works
  • Removed muteTweeters because the API was turned off

Via my CRANberries, there is a comparison to the previous release. For questions or comments use the the issue tracker at the GitHub repo.

This post by Dirk Eddelbuettel originated on his Thinking inside the box blog. If you like this or other open-source work I do, you can sponsor me at GitHub.

Colin Watson: Preparing a transition in Debusine
We announced a public beta of Debusine repositories recently (Freexian blog, debian-devel-announce). One thing I m very keen on is being able to use these to prepare transitions : changes to multiple packages that need to be prepared together in order to land in testing. As I said in my DebConf25 talk:
We have distribution-wide CI in unstable, but there s only one of it and it s shared between all of us. As a result it s very possible to get into tangles when multiple people are working on related things at the same time, and we only avoid that as much as we do by careful coordination such as transition bugs. Experimental helps, but again, there s only one of it and setting up another one is far from trivial. So, what we want is a system where you can run experiments on possible Debian changes at a large scale without a high setup cost and without fear of breaking things for other people. And then, if it all works, push the whole lot into Debian.
Time to practice what I preach. Setup The setup process is documented on the Debian wiki. You need to decide whether you re working on a short-lived experiment, in which case you ll run the create-experiment workflow and your workspace will expire after 60 days of inactivity, or something that you expect to keep around for longer, in which case you ll run the create-repository workflow. Either one of those will create a new workspace for you. Then, in that workspace, you run debusine archive suite create for whichever suites you want to use. For the case of a transition that you plan to land in unstable, you ll most likely use create-experiment and then create a single suite with the pattern sid-<name>. The situation I was dealing with here was moving to Pylint 4. Tests showed that we needed this as part of adding Python 3.14 as a supported Python version, and I knew that I was going to need newer upstream versions of the astroid and pylint packages. However, I wasn t quite sure what the fallout of a new major version of pylint was going to be. Fortunately, the Debian Python ecosystem has pretty good autopkgtest coverage, so I thought I d see what Debusine said about it. I created an experiment called cjwatson-pylint (resulting in https://debusine.debian.net/debian/developers-cjwatson-pylint/ - I m not making that a proper link since it will expire in a couple of months) and a sid-pylint suite in it. Iteration From this starting point, the basic cycle involved uploading each package like this for each package I d prepared:
$ dput -O debusine_workspace=developers-cjwatson-pylint \
       -O debusine_workflow=publish-to-sid-pylint \
       debusine.debian.net foo.changes
I could have made a new dput-ng profile to cut down on typing, but it wasn t worth it here. Then I looked at the workflow results, figured out which other packages I needed to fix based on those, and repeated until the whole set looked coherent. Debusine automatically built each upload against whatever else was currently in the repository, as you d expect. I should probably have used version numbers with tilde suffixes (e.g. 4.0.2-1~test1) in case I needed to correct anything, but fortunately that was mostly unnecessary. I did at least run initial test-builds locally of just the individual packages I was directly changing to make sure that they weren t too egregiously broken, just because I usually find it quicker to iterate that way. I didn t take screenshots as I was going along, but here s what the list of top-level workflows in my workspace looked like by the end: Workflows You can see that not all of the workflows are successful. This is because we currently just show everything in every workflow; we don t consider whether a task was retried and succeeded on the second try, or whether there s now a newer version of a reverse-dependency so tests of the older version should be disregarded, and so on. More fundamentally, you have to look through each individual workflow, which is a bit of a pain: we plan to add a dashboard that shows you the current state of a suite as a whole rather than the current workflow-oriented view, but we haven t started on that yet. Drilling down into one of these workflows, it looks something like this: astroid workflow This was the first package I uploaded. The first pass of failures told me about pylint (expected), pylint-flask (an obvious consequence), and python-sphinx-autodoc2 and sphinx-autoapi (surprises). The slightly odd pattern of failures and errors is because I retried a few things, and we sometimes report retries in a slightly strange way, especially when there are workflows involved that might not be able to resolve their input parameters any more. The next level was: pylint workflow Again, there were some retries involved here, and also some cases where packages were already failing in unstable so the failures weren t the fault of my change; for now I had to go through and analyze these by hand, but we ll soon have regression tracking to compare with reference runs and show you where things have got better or worse. After excluding those, that left pytest-pylint (not caused by my changes, but I fixed it anyway in unstable to clear out some noise) and spyder. I d seen people talking about spyder on #debian-python recently, so after a bit of conversation there I sponsored a rope upload by Aeliton Silva, upgraded python-lsp-server, and patched spyder. All those went into my repository too, exposing a couple more tests I d forgotten in spyder. Once I was satisfied with the results, I uploaded everything to unstable. The next day, I looked through the tracker as usual starting from astroid, and while there are some test failures showing up right now it looks as though they should all clear out as pieces migrate to testing. Success! Conclusions We still have some way to go before this is a completely smooth experience that I d be prepared to say that every developer can and should be using; there are all sorts of fit-and-finish issues that I can easily see here. Still, I do think we re at the point where a tolerant developer can use this to deal with the common case of a mid-sized transition, and get more out of it than they put in. Without Debusine, either I d have had to put much more effort into searching for and testing reverse-dependencies myself, or (more likely, let s face it) I d have just dumped things into unstable and sorted them out afterwards, resulting in potentially delaying other people s work. This way, everything was done with as little disruption as possible. This works best when the packages likely to be involved have reasonably good autopkgtest coverage (even if the tests themselves are relatively basic). This is an increasingly good bet in Debian, but we have plans to add installability comparisons (similar to how Debian s testing suite works) as well as optional rebuild testing. If this has got you interested, please try it out for yourself and let us know how it goes!
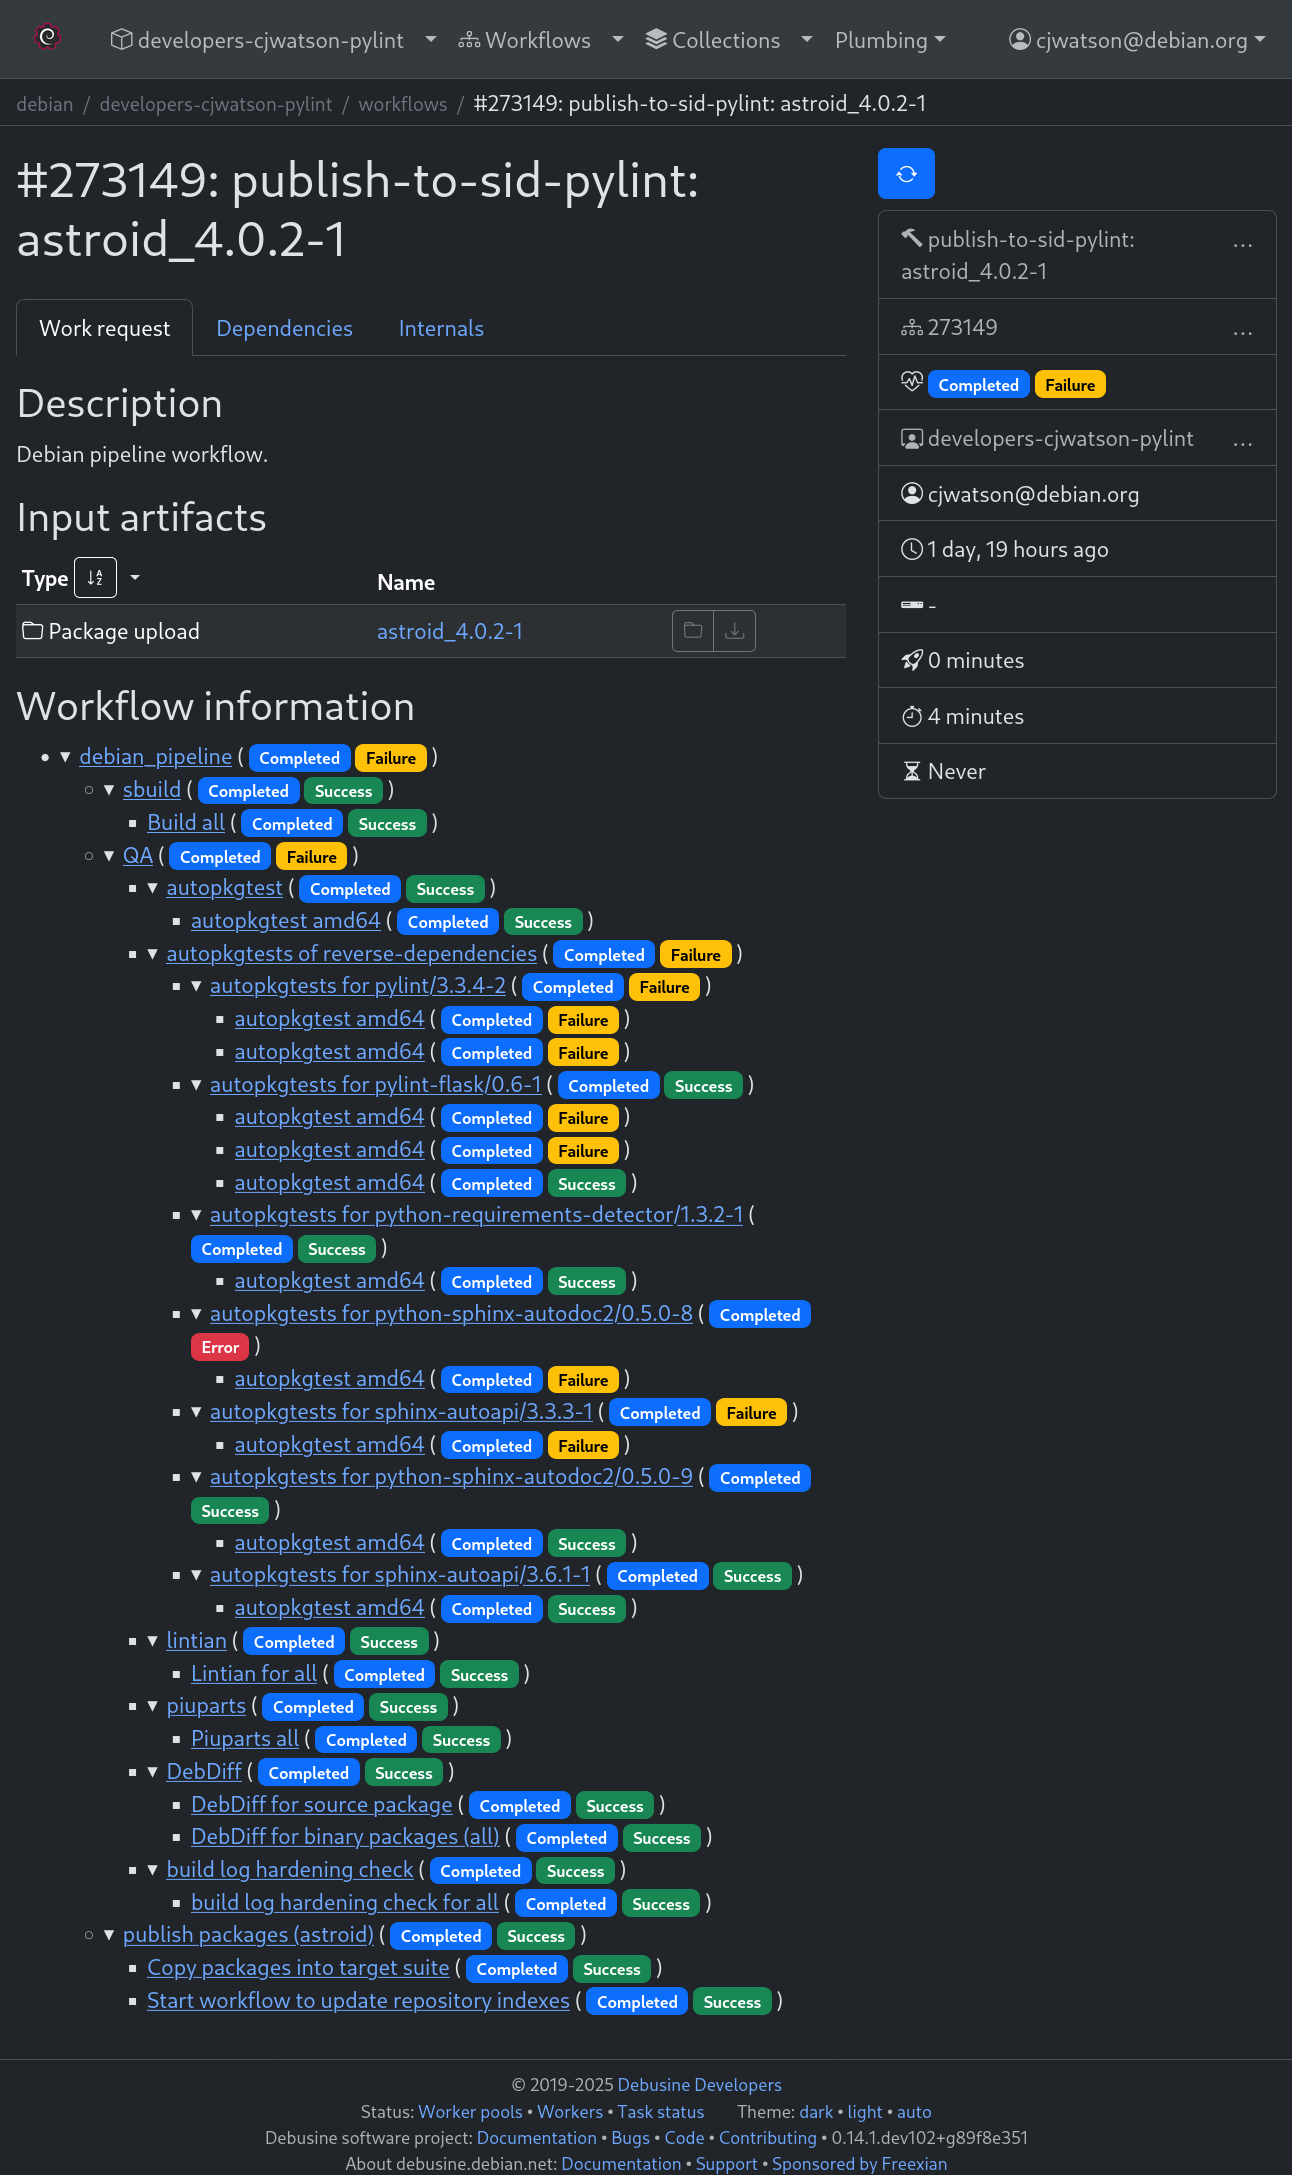
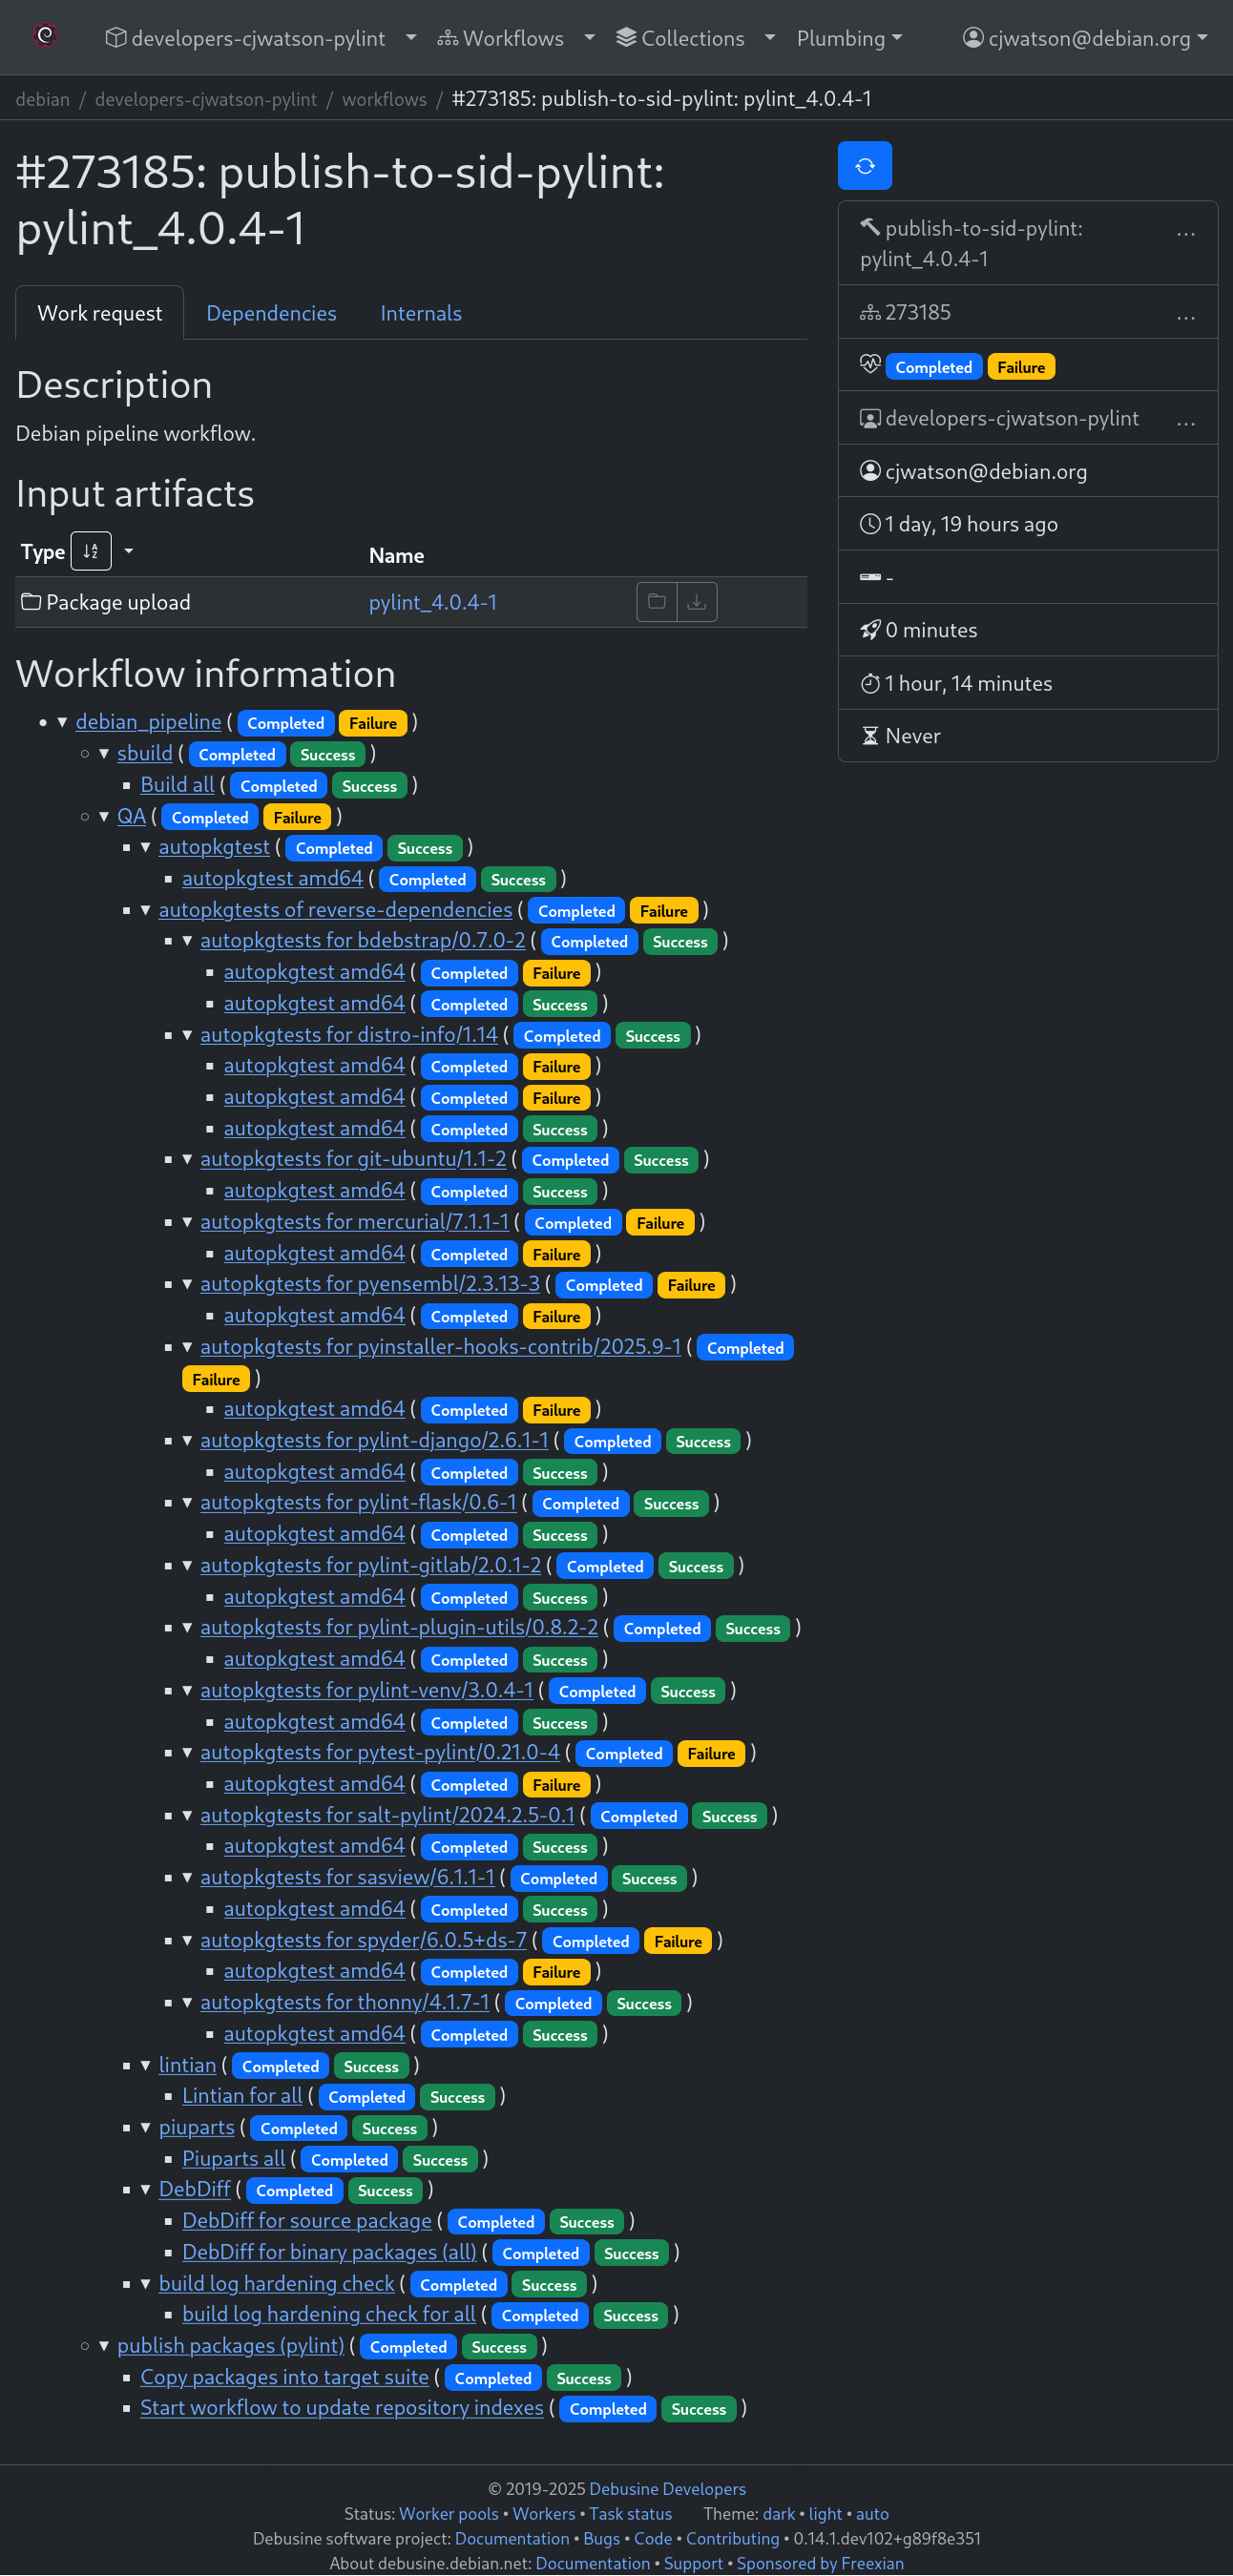
Next.

Previous.