Search Results: "ag"

1 April 2008

Andrew Pollock: [tech] On peering

Simon Rumble says the ABC should peer with all Australian ISPs. The fact of the matter is communication links don't grow on trees. The cost to the ABC would be prohibitive, I'd imagine. If the ABC has private WAN links around the country, and they were under-utilised, the most sensible thing to do would be to peer at each of the PIPE peering locations, where as I understand it, most ISPs worth their salt have a connection. That said, because WAN links don't grow on trees either, the ABC is probably not forking out for more capacity than it needs. Given the never ending budget cuts that the ABC has to endure, I doubt dishing up Internet content at low costs for the downloaders is their first priority. But yes, it would be nice if Australian content providers all peered.

Manoj Srivastava: Manoj: Migrating to Git

I have been using Arch to package my Debian packages since 2003; which means that Arch has had a good long run as my SCM of choice. I have been using CVS for a few years before I moved to arch, and the migration took me about six months, since it involved a while new philosophy of packaging; I am hoping that migrating to git would not involve such a major paradigm shift, and thus be less disruptive and time consuming. What follows is a narrative of my efforts to get educated about Git. This article is meant to be an annotated, selective, organized set of links to information about Git. How does it differ from the myriad of other link collections about Git proliferating on the web? Well, the value add is in the annotations and the organization: while not quite a narrative of my exploration, this is an idealized version of what I think my discovery process should have been, to be most effective. Staging the information is important; google finds one lots of information that is incomprehensible to someone just coming to Git. This selection of links is actually selective; I have included only pointers to resources that fed me information at the level that I could handle at that stage, and I have eliminated links to information that was not new at that point. I have tried to select the best (in terms of information and clarity) of breed for each kind of information source I have come across so far. There is a caveat: while still a beginner, though I am able to better judge now what is confusing to a beginner than I shall be when I have become more familiar with the system, I am still enough of a novice not to trust my judgement on what really is best practice. I can fix the latter as I gain experience, but then I ll need to be careful not to overload on complexity too early in the learning curve. On the down side, this selection is subjective, and probably shall be even in the long term: I include what appealed to me, and will probably miss loads of pointers to information that I have not yet come across. However, I hope this will make it easier for other people to reach the same goal: use git for their version control needs. Have fun.

Gustavo R. Montesino: libgda3 3.0.2-3

Earlier today I've just made my first package upload to the Debian archives (and no, this isn't an April 1st. joke :P). It was a debian revision of libgda3, with the following changes:

Now the bad news: The building still fails in ia64... and I have no idea way. Below is an excerpt from the full build log:
        
Writing ch18.html for chapter
I/O error : No such file or directory
runtime error: file file:///usr/share/xml/docbook/stylesheet/nwalsh/html/chunker.xsl line 202 element document
xsltDocumentElem: unable to save to ch18.html

I'm not sure when I'll have time to try debugging this, so any help would be greatly appreciated.

Sune Vuorela: fpo.mail.dk take 2

Hej! Jeg har nu ndret ops tningen i min mailserver, s dan at den p mails sendt med smtp auth skriver en mindre detaljeret Recieved:-header. Kort og godt har jeg fjernet forekomsten af: (scrooge.local) [77.75.167.214] i Recieved:. (Det er navnet p maskinen - og den ip min internetudbyder sender mig ud igennem[1]) Nu stryger al mail lige igennem fpo.mail.dk. Det er lige f r man skulle overveje om postmesteren p fpo.mail.dk havde et defekt anti-spam-setup - noget med at melde tempor r fejl hvis en ip i en Recieved-headers var fundet p en blackliste. Umiddelbart lyder det i hvert fald defekt i mine rer. Hvis du kender postmesteren p fpo.mail.dk, s prik lige venligst til ham og bed ham fikse sit setup. Til de exim-interesserede har jeg brugt f lgende konfigurationselement i main-delen:

received_header_text = "Received: \
$ if !def:sender_host_authenticated $ if def:sender_rcvhost from $sender_rcvhost\n\t \
$ if def:sender_ident from $sender_ident \
$ if def:sender_helo_name (helo=$sender_helo_name)\n\t \
by $primary_hostname \
$ if def:received_protocol with $received_protocol \
$ if def:tls_cipher ($tls_cipher)\n\t \
(Exim $version_number)\n\t\
id $message_id\
$ if def:received_for \n\tfor $received_for "
[1] Jeg bor p kollegie og deler offentlig ip med 287 andre mennesker. Det g r at den ip-adresse altid er p mindst en eller to blacklister. At v re p blacklister er ogs sj ldent en midlertidig tilstand.

MJ Ray: Blog Updates

First of all, you can't do All Fool's Day pranks on global web sites because of time zones: if you do, you'll be pranking either early or late somewhere and so you're the fool. Now, I've been a bit quiet recently because I've been moving dozens of Wordpress blogs over to one Wordpress MU install. Clearly the right way to do it. They're all on different domains and we want their names to have www, which needed the following small change...
 
--- wpmu-settings.php
+++ wpmu-settings.php
@@ -6,8 +6,8 @@ if( $current_site && $current_blog )
 $wpmuBaseTablePrefix = $table_prefix;
 $domain = addslashes( $_SERVER['HTTP_HOST'] );
-if( substr( $domain, 0, 4 ) == 'www.' )
-       $domain = substr( $domain, 4 );
+if( substr( $domain, 0, 4 ) != 'www.' )
+       $domain = 'www.'.$domain;
 if( strpos( $domain, ':' ) )  
        if( substr( $domain, -3 ) == ':80' )  
                $domain = substr( $domain, 0, -3 );
I could have sworn I changed something else in that file, but I don't see what. Oops. I guess I'll run a check against the release tarball before merging the next upgrade from upstream. If anyone wants to hire someone to move blogs to Wordpress MU, you how where to find me. It's pretty enjoyable once you get into the routine, even if this project overran. I'm looking at changing my own blogs too. I'm looking at Chronicle but maybe with more email-like input files.

Benjamin Mako Hill: Geek Shall Inherit the Earth Talk

I wrote an essay several years ago called The Geek Shall Inherit the Earth: My Story of Unlearning. It's buried on my website but still manages to attract a consistent stream of readers. It's essentially the story of how I became a geek, about school, ADD, and free software. It is by far the most personal thing I've ever published. That said, several people have told me that it's influenced them deeply -- changed their views, politics and attitudes in important ways. In December, my friend Marcell asked me to give a version of the talk as part of his G33koskop series. I was hesitant to give such a personal talk but I did it anyway. I've finally got around to cleaning up the recording and have posted it online. You can download and listen to the talk here in Ogg Vorbis or here in MP3).

Erich Schubert: Ubuntu to rename top level directories

The usability experts of Ubuntu have finally started to handle the single most mentioned usability issue with Linux: the top level directory names.Quoting Finn C. Tional from the Ubuntu Usability Group:
It's one of the mysteries of Unix that the directory named "usr" is not for user data, and the directory named "etc" while looking like random stuff thrown together stores all the important config files. [...] This is probably the single most confusing hurdle for new Unix users. [...] We need to finally tackle this, before people are too used to these odd directory names.
Therefore, they propose the following renaming scheme:
/bin      /system/executables
/boot     /system/boot
/dev      /system/devices
/etc      /system/config
/lib      /system/libraries
/home     /users
/media    /storage
/mnt      /storage
/proc     /system/processes
/root     /users/Administrator
/sbin     /system/executables/admin
/tmp      /system/temporary
/usr      /system/applications
They'll include a patch for the GNU C library as well as for AppArmor to redirect the old path names to the new ones. Given the existing filename matching already done by AppArmor the overhead is expected to be neglible at least for AppArmor enabled systems. SELinux enabled systems will remain unchanged, since the user won't be allowed to see anything potentially irritating in the root directory anyway, but will be confined to his user directory.Since there are a dozen applications that will need changes to accomodate the new naming scheme, expect these changes only to be included with Ubuntu 10.4 (also lovingly named Ubuntu X) scheduled for April 2010.Other distributions are expected to follow up with these changes in 2011.P.S. Yeah, the Ubuntu folks really need to think this throuh some more. Russel pointed out that "My System" is even easier to understand; after all this is not about someone elses system or some systematic error or whatever. I figure he's right. How about "My Computer" than this lowercase (pessimistic?) "system" directory they're proposing there!

Philipp Kern: Pervasive Privacy on Weblogs?

Is there any Free Software out there supporting pervasive privacy in weblogs? What does it take for decent support of privacy:
  • Not leaking that postings exist at all. This means that there should be some plausible deniability (configurable, though) that no new posts exist. No message that you are not allowed to view it.
  • Pervasive integration: next entry and previous entry links must not refer to the private entry, possibly leaking the post's title through the permalink. If the software integrates a search engine it must not search in entries the user is not allowed to look at. (Or display excerpts, FWIW.)
  • If possible integrate with the comments feature to allow both authenticated comments and post filters. OpenID integration is a big plus here. Passwords should be supported, too.
  • Allow the use of groups (filters) to limit certain posts to certain groups of friends.
  • Support tokenized RSS/Atom feeds without HTTP authentication. (I.e. generate a secret per-user token which authenticates the feed request and then display the restricted view on the posts.)
I tried the Privacy plugin for Movable Type 4, but it failed. It has some nice ideas like OpenID support, but it is not pervasive at all, leaking posts all over the place. So is there anything out there satisfying at least some of the criteria or do I need to learn Perl and to hack this into Movable Type? (The general point of "not posting private stuff you really don't want to leak" should not be reiterated, though. It is my own server and it boils down to trust anyway.)

Joerg Jaspert: Sick

In case you wonder why NEW is growing, why I’m less responsive on IRC and don’t get around to do the usual amount of work - I’m sick. :( In the last few weeks I was very busy with stuff for $work, enough to even keep me working on it during the easter holidays. Now, where that is over - I feel horrible. I don’t want to eat (just makes it worse if I do), don’t even want to drink milk. Bah. It started somewhere during last weekend, where it felt like I’m getting a cold. Went to work yesterday and got sent home after being there for some 4 hours. Today I went to work again - and got sent home by my boss, with a comment like Go to the doctor and don’t get back to work this week. Oh well, so now I’m on my way back home (takes slightly more than an hour by train), from there to the Doc and then into bed. I’ll try and do NEW and some other stuff thats waiting for me tomorrow again. Maybe even late today, using my laptop. Don’t know. Yesterday I mostly slept and did nothing. :()

Kartik Mistry: Just finished


* … I just finished installation of Ubuntu 10.

Neil Williams: Updating Emdebian docs

I've updated two of the Emdebian pages today, after some feedback on the list. I'm interested in feedback on the current Emdebian website because I'm aware that the site isn't that friendly to new users. (Note: feedback on the textual content of the site, not the structure or layout.) The updated wiki pages are the start of a longer process to review the website itself.

http://wiki.debian.org/EmdebianQuickStart

http://wiki.debian.org/EmdebianRootfs.

31 March 2008

Benjamin Mako Hill: Proven Wrong!

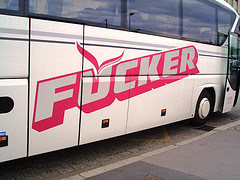
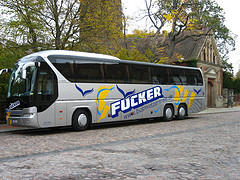
Yesterday I speculated that Lamers Bus Lines was the most disproportionately photographed, unintentionally insulting, bus line name on the Internet. Apparently not. Several readers pointed out that, while a Flickr search for lamers bus returns 81 photographs, a search for f cker bus and fucker bus return a combined 84 photos not unlike these. With Lamers, PUTA, F cker, SCAT, and the SLUT, I'm beginning to wonder if something very fundamentally wrong with the way human society is choosing the names for its mass transit systems.

Cyril Brulebois: Lufthansa machines landed!

As outlined some days ago, patience is a requirement. That said, I'm glad that all things come to (s)he who waits, Lufthansa hardware finally landed! Ganneff, already very busy with his well-known DAM and ftpmaster hats, managed to also handle shipping some hardware donated by the Lufthansa some months ago. pkg-games was promised a powerful box, look: Pentium 4 (2400 MHz, 1024 MB); we will finally be able to try and provide backports in a semi-automated fashion, so as to ease stable users' life, when it comes to installing bleeding-edge versions of their favourite games! Thank you for making this possible and keeping everyone posted about the status of that hardware donation. Hopefully, it'll be possible to also communicate through bits of the DAMs , as suggested some weeks ago on debian-newmaint@. Yay for communication! \o/

Steve Kemp: I don't shut up, I grow up

Recently I took stock of my Javascript programming efforts, with the intention of simplifying things. To date I've put together three sites which make use of Javascript:
debian-administration.org
There isn't very much javascript in use upon this site, and you might be forgiven for thinking there was none at all if you don't have an account, or don't login. There's a tagging system which is starting to creak under the sheer number of different tags, and several back-end parts of the site make use of AJAX calls. Most of the script lives in a single file common.js which I cobbled via a process of trial and error, augmented with a little copy & paste coding. It works. But I knew I could do better ..
ctrl-alt-date
This was my first attempt to make a site be truely dynamic and "pretty". It has succeeded in that respect, although the lack of members makes the site itself essentially a failure. This time round I decided that I'd utterly refuse to write my own Javascript. So instead I used script.aculo.us (damn I hate those ugly URLS). This library made it almost too easy to add flash. I liked it a lot. Having said that though the sheer scope of the library and the way it didn't fit in the way that I coded made it painful to use at times. It works, and it works well. Like it? Yes. Love it no?
mail-scanning.com
This site has a fair amount of javascript upon it, but that isn't obvious unless you're actually a user. The only piece that I can recall is the real-time count of spam caught upon the front-page. (Realtime stats are cool!) Most of the code here is the simple kind, reverting back to the way I worked on the Debian Administration site; we're talking about basic effects such as:
  • show/hide a div
  • make an AJAX request every now and again.
  • Do a bit of auto-completion.
To get more of a feel for whats out there I wrote this initially with my own code, then later migrated it to jQuery. Quite frankly jQuery rocks. The way it works is a little strange at first, but it is so natural after a while. As an example:
// find the div called "foo" - hide it.
$("#foo").hide()
I'm liking this library a lot recently, but only time will tell if I use it more.
In conclusion I filed #473125: ITP jQuery failing to see the existing ITP already present. Once the package makes it through the NEW queue I will update it to follow the skeletal javascript-policy. I disagree about the naming scheme suggested by that policy primarily because we already have packages of several of the "big" javascript libraries, such as scriptalicious, and see no gain in renaming them. But otherwise the policy is sane enough; following it will cause no harm at the very least. ObQuote: Stand By Me

Eric Warmenhoven: Rewriting as a learning tool

So a year and a half ago, I mentioned I was trying to learn Haskell, and I still am. It’s been going much more slowly than I hoped, since I haven’t really spent any time on it. I never write anything new anymore! So I decided to rewrite something I had previously written myself, need be damned. So I chose the RSS aggregator I wrote, harsh. harsh hasn’t changed in eleven months (and that change was just about making the location of its configuration file configurable), but I still remembered how it worked pretty closely; at least enough that I didn’t have to really go searching through its code too much. That’s probably also a function of how small harsh is; in terms of lines of code (excluding blank lines):
  config.c: 139
  cookie.c: 221
 display.c: 709
    feed.c: 577
    list.c: 96
    list.h: 16
    main.c: 96
    main.h: 84
     md5.c: 360
     md5.h: 76
     rss.c: 120
     xml.c: 276
     xml.h: 17
     total: 2787
It uses expat to parse the HTML, libnbio for socket management (which is available in Debian), and ncurses for the UI. It doesn’t have any sort of threading (libnbio does a good job of making sure that, other than DNS lookups, there’s never anything going on long enough to prevent responsiveness). About its only feature is that it will use my cookies.txt file, so that I can see my LiveJournal friends’ protected entries. I originally wrote harsh in about a day or two. It was really easy because of the 2800 lines, about 850 of them had been written in some of my other projects (list.c/h and xml.c/h) or are standard (md5.c/h). I was also really familiar with the three helper libraries from writing grim (my IM client) and stark (a tool for viewing GnuCash data files). As a learning exercise, rewriting harsh in Haskell was excellent. It’s incredibly small, does a lot of standard things (like networking and console UI), and doesn’t do a lot of non-standard things (like an AIM client does). I got to play with the Haskell light-weight threads and STM; I learned how to create a Debian Haskell package; I learned how to use ghci as a debugger with breakpoints; and I’m much more comfortable with monads and with the language in general. It did take me significantly longer to write than the C version, though that’s more due to me having to learn not just the language but some libraries along the way (like HTTP, Vty, and HaXml). I still think that it would take me just as long to write the Haskell version as the C version, but I’m still much more comfortable with C, and imperative programming in general. From a code size perspective, the Haskell version is about one-sixth the size (excluding comments):
Config.lhs: 53
  Feed.lhs: 144
 Harsh.lhs: 272
  Util.lhs: 26
     total: 495
However, that’s not a very fair comparison. In the C version, md5.c/h are included in the total count, when really they should be considered a standard library (and on the Haskell side, I used Data.Hash.MD5 from MissingH). On the C side, I did all of the HTTP request and response processing myself (which is what more than half of feed.c is about), while on the Haskell side I left that to an HTTP client library. Excluding all those things though, the Haskell version is still about one-fourth the size. Anyway, I put the Haskell version of harsh up here. If any Haskell hackers out there could take a look at it and let me know what I’m doing wrong or oddly, I’d appreciate it.

Junichi Uekawa: duplicate ssh-agents.

duplicate ssh-agents. I have ssh-agent start in .xsession, but apparently somebody else also starts it up and I have two distinct ssh-agents. Hmmm.

Lior Kaplan: Where did the numbers go ? (major bug in OO.org 2.4.0)


About two months after the Israeli government stopped the support for openoffice.org localization, we hit a major bug (actaully - a regression) with version 2.4.0 effecting Hebrew users. In version 2.4.0 numbers written in Microsoft Word documents are shown as Hindu numbers instead of Arabic numbers. There’s a big confusion in the terms, as the number used in Arabic are the Hindu numbers and the number used in Latin languages are the Arabic numbers. Anyway, this means that, the facto, Openoffice.org 2.4.0 can’t show properly Microsoft Word documents which were written in Hebrew. I can’t start to describe how much interoperability problems that causes in Israel. Which such behavior I can’t recommend OO.org to people, and organizations already moved to previous versions of OO.org can’t upgrade to 2.4.0 and must stay with 2.3.1. This is also a problem as most Linux distributions (Debian, Ubuntu, Fedora) intend to include 2.4.0 for their stable release. With all the RTL related bugs, OO.org was still usable. But this bug absolutely changes things. I hope it will be fixed for 2.4.1 and won’t be delayed for version 3.0. I wish I could say this is an April’s fools post, but that bug is a reality… Please vote for this bug.

Lucas Nussbaum: Jabber clients and OS usage stats (4)

After 2005, 2006 and 2007, I did it again. Here are my yearly stats about Jabber clients! 1244 users were online on the Apinc Jabber server when I ran the poll, and 1163 clients answered. Telepathy doesn’t seem to answer to jabber:iq:version, and it seems that a bug prevents Gajim from answering in some obscure cases (even when the “send info about OS” option is enabled). Systems: Clients:

Mirco Bauer: Monsoon Hacking Weekend + Monday Evening Hack

This weekend I did a hack session with Alan McGovern on Monson. You don't know what Monsoon is? It's the sexy GTK# driven bittorrent client based on the MonoTorrent library developed by Alan McGovern. I created debian packages for Monsoon and wasn't happy with some features and/or bugs so I thought I can contribute some love to it. First thing I implemented was persistency of file priorities for torrents, so when you restart Monsoon it will restore all priorities. I also reported some bugs to Alan in MonoTorrent, like it was ignoring "do not download" flags, so it kept downloading all files of a torrent and the download progress of files were not correctly restored when it was resuming the torrent. He found and fixed the issues right away, great service smile.png
Then I implemented auto-start of torrents that were running when Monsoon is closed.
Monsoon will also now not flood your console with lots of debug stuff, as I added a -d / --debug parameter for that, which made my terminal unresponsible without it when downloading big torrents (~1000 files). And this evening, I replaced the usage of Gnome.IconEntry and Gnome.IconSelection with Gtk.FileChooserDialog + a preview widget. Alan asked for this, as he wanted to drop the GNOME# dependency for memory usage reasons. Allright, enough love for today! Now am hungry.... PS: We have now an IRC channel for Monsoon: #monsoon on GIMPnet, if you are interested, please join!

Lars Wirzenius: Progress bars everywhere!

As I get older, and more impatient, I find myself wanting every program to give more or less accurate estimates of the remaining time until it has completed whatever it is doing. This applies to command line utilities as well. In fact, since most of my time is spent on the command line, it applies particularly to command line utilities. The thing I, as a user, want to know is how long I will still have to wait. I don't particularly care whether the program has completed 97.12765% of its job, I want to know whether it will still take seconds, minutes, hours, or longer to complete. Not remaining file counts. Not remaining byte counts. Time. I'm interested in the entire task. If each file takes 0.1 seconds to process, that's fine, but I don't want to estimate myself that with fourteen thousand remaining files it's going to to take around 25 minutes more. It doesn't have to be completely accurate; a reasonably good estimate is fine. It can fluctuate: when downloading over the Internet, transfer speeds sometimes vary. That's fine. Just give me the current estimate using the average recent speed. For various reasons, I often deal with large files, in the multi-gigabyte range. Copying them with cp seems to be pretty effective, but it's annoying to have to set up something like "watch du -sh source.file target.file" to be able to track progress. I could use "rsync --progress", but that only works well for a single file. Otherwise it reports remaining time for each file separately. I realize that rsync has a particularly difficult job for estimating the remaining time, since it is dependent on the contents of the files at either end. But it could try. Because of these, I tend to like Nautilus for copying files. It has a pretty good indicator for remaining time. Unfortunately, that isn't always practical to use, either, since I don't always copy file so that the local host is at least one end of the transfer, and I often really want rsync. One of the nice lesser-known utilities is pv (in Debian and Ubuntu in the package of the same name). It allows one to construct pipelines that estimate current remaining time. For example, I use this to fill a filesystem's empty space with zeroes:
pv -petrb -s "$ guess k" /dev/zero > temp
(where guess is the free space in kilobytes). Sometimes the pipelines need to be somewhat contrived to fit pv in. This can also make them slower than straightforward ones would be. But it's often nicer to get some progress reporting than to optimize for speed, at least for stuff that you have to actually wait for in real time.

Next.

Previous.