Search Results: "pm"

5 December 2013

Matthew Palmer: The easy bit of software development

I m sure this isn t an original thought of mine, but it just popped into my head and I think it s something of a fundamental truth that all software developers need to keep in mind:
Writing software is easy. The hard part is writing software that works.
All too often, we get so caught up in the rush of building something that we forget that it has to work and, all too often, we fail in some fundamental fashion, whether it s doesn t satisfy the user s needs or you just broke my $FEATURE! (which is the context I was thinking of).

3 December 2013

Antoine Beaupr : Announcing a prettier noping

I have implemented really pretty histograms in the venerable ping software, something I never thought could be improved, until I discovered prettyping.sh, something that was just begging for improvements. Which are now done. But first some history... First, in 1983 (!), there was ping and network operators rejoiced, as they could see if a host was down or not, and have all sorts of geeky statistics:
PING koumbit.net (209.44.112.66): 48 data bytes
56 bytes from 209.44.112.66: icmp_seq=0 ttl=52 time=25.076 ms
56 bytes from 209.44.112.66: icmp_seq=1 ttl=52 time=24.006 ms
56 bytes from 209.44.112.66: icmp_seq=2 ttl=52 time=24.106 ms
^C--- koumbit.net ping statistics ---
3 packets transmitted, 3 packets received, 0% packet loss
round-trip min/avg/max/stddev = 24.006/24.396/25.076/0.483 ms
Then, in 2006, there was noping, and things were, well, not much better, but we had colors, and there was some rejoicing. noping before Then, in october 2013, there was prettyping.sh, and things got really flashy and "oh wow, you can do that?" There was much rejoicing. prettyping animation Then, tonight, I learned ncurses and there was much headaches. But then, I reimplemented prettyping in noping, and I am so happy that I wrote this blog post: noping now Unless you haven't figured out how cool this is, let me break it down for you:
  1. it supports IPv4 and IPv6
  2. it allows you to track multiple hosts at the same time, and compare them
  3. this allows you to easily track down failure points in a network, something for which you usually need smokeping (needs a webserver) or mtr (doesn't have colors)
  4. it allows you to track a lot (the last minute at least) of history by default
  5. it is visually easy to track, even from a distance
You may know of that hack that can make "ping" ring a bell when it receives a packet? This is better: you can see the packets latency (or when they are just dropped!) from a distance, using an intuitive color code. The code is up for review here:
git clone -b prettyping git://src.anarc.at/liboping
Thanks to the well architectured noping, the patches were not that complicated to implemented. I have contacted upstream to get those changes merged, and hopefully this will be in your favorite Debian distribution soon. Rejoice!

2 December 2013

Tim Retout: Questhub.io

At the London Perl Workshop last Saturday, one of the lightning talks was about Questhub.io, formerly known as "play-perl.org". It's social gamification for your task list, or something like that. Buzzword-tastic! But most importantly, there seems to be a nice community of programming types to procrastinate with you on your quests. This means I can finally get to work refuting lamby's prediction about gamification of Debian development! Tasks are referred to as "Quests", and are pursued in themed "Realms", for that World of Warcraft feeling. For example, there's a "Perl" realm, and a "Lisp" realm, and a "Haskell" realm, but also non-programming realms like "Fitness" and "Japanese". Of course, part of me now wants to construct a federated version which can be self-hosted. :) Another downside of questhub currently is the lack of SSL support - your session cookies are sent in plain text. I hope this changes soon.

30 November 2013

Russell Coker: Links November 2013

Shanley wrote an insightful article about microagressions and management [1]. It s interesting to read that and think of past work experiences, even the best managers do it. Bill Stone gave an inspiring TED talk about exploring huge caves, autonamous probes to explore underground lakes (which can be used on Europa) and building a refuelling station on the Moon [2]. Simon Lewis gave an interesting TED talk about consciousness and the technology needed to help him recover from injuries sustained in a serious car crash [3]. Paul Wayper wrote an interesting article about reforming the patent system [4]. He also notes that the patent system is claimed to be protecting the mythical home inventor when it s really about patent trolls (and ex-inventors who work for them). This is similar to the way that ex-musicians work for organisations that promote extreme copyright legislation. Amanda Palmer gave an interesting TED talk about asking for donations/assistance, and the interactions between musicians and the audience [5]. Some part of this are NSFW. Hans Rakers wrote a useful post about how to solve a Dovecot problem with too many files open [6]. His solution was for a Red Hat based system, for Debian you can do the same but by editing /etc/init.d/dovecot. The use of the /proc/N/limits file was interesting, I ve never had a cause to deliberately use that file before. Krebs on Security has an interesting article about Android malware being used to defeat SMS systems to prevent bank fraud [7]. Apparently an infected PC will instruct the user to install an Android app to complete the process. Rick Falkvinge wrote an interesting article about how to apply basic economics terminology to so-called Intellectual Property [8]. Matthew Garrett wrote an interesting post about the way that Ubuntu gets a better result than Debian and Fedora because it has clear fixed goals [9]. He states that many people regard Fedora as a playground to produce a range of niche derivatives , probably a large portion of the Fedora and Debian developers consider this a feature not a bug. Ming Thein wrote an interesting article about the demise of the DSLR [10]. Bruce Schneier wrote an interesting post on the detention of David Miranda by the British authorities [11]. It s mostly speculation as to why they would do such a thing (which seems to go against their own best interests) and whether the NSA even knows which documents Edward Snowden copied. Jaclyn Friedman wrote an interesting article on Mens Rights Movements (MRAs) and how they are bad for MEN as well as for women [12]. Rodney S. Tucker wrote an insightful article for the IEEE about the NBN [13]. Basically the Liberal party are going to spend most of the tax money needed for a full NBN but get a significantly less than the full benefit. Lauren Drell wrote an interesting article for Mashable about TellSpec, a portable spectrometer that communicates with an Android phone to analyse food for allergens [14]. I guess this will stop schools from banning phones. Katie McDonough wrote an interesting article for Salon about the Pope s statements about the problems with unchecked capitalism [15]. His ideas are really nothing new to anyone who has read the Bible and read the news. It seems to me that the most newsworthy part of this is that most Christian leaders don t make similar statements. Daniel Leidert wrote an interesting post about power saving when running Debian on a HP Microserver [16]. Most of it is relevant to other AMD64 hardware too, I ll have to investigate the PCIE ASPM and spin down options on some of my systems that are mostly idle.

29 November 2013

Keith Packard: Black Friday 2013

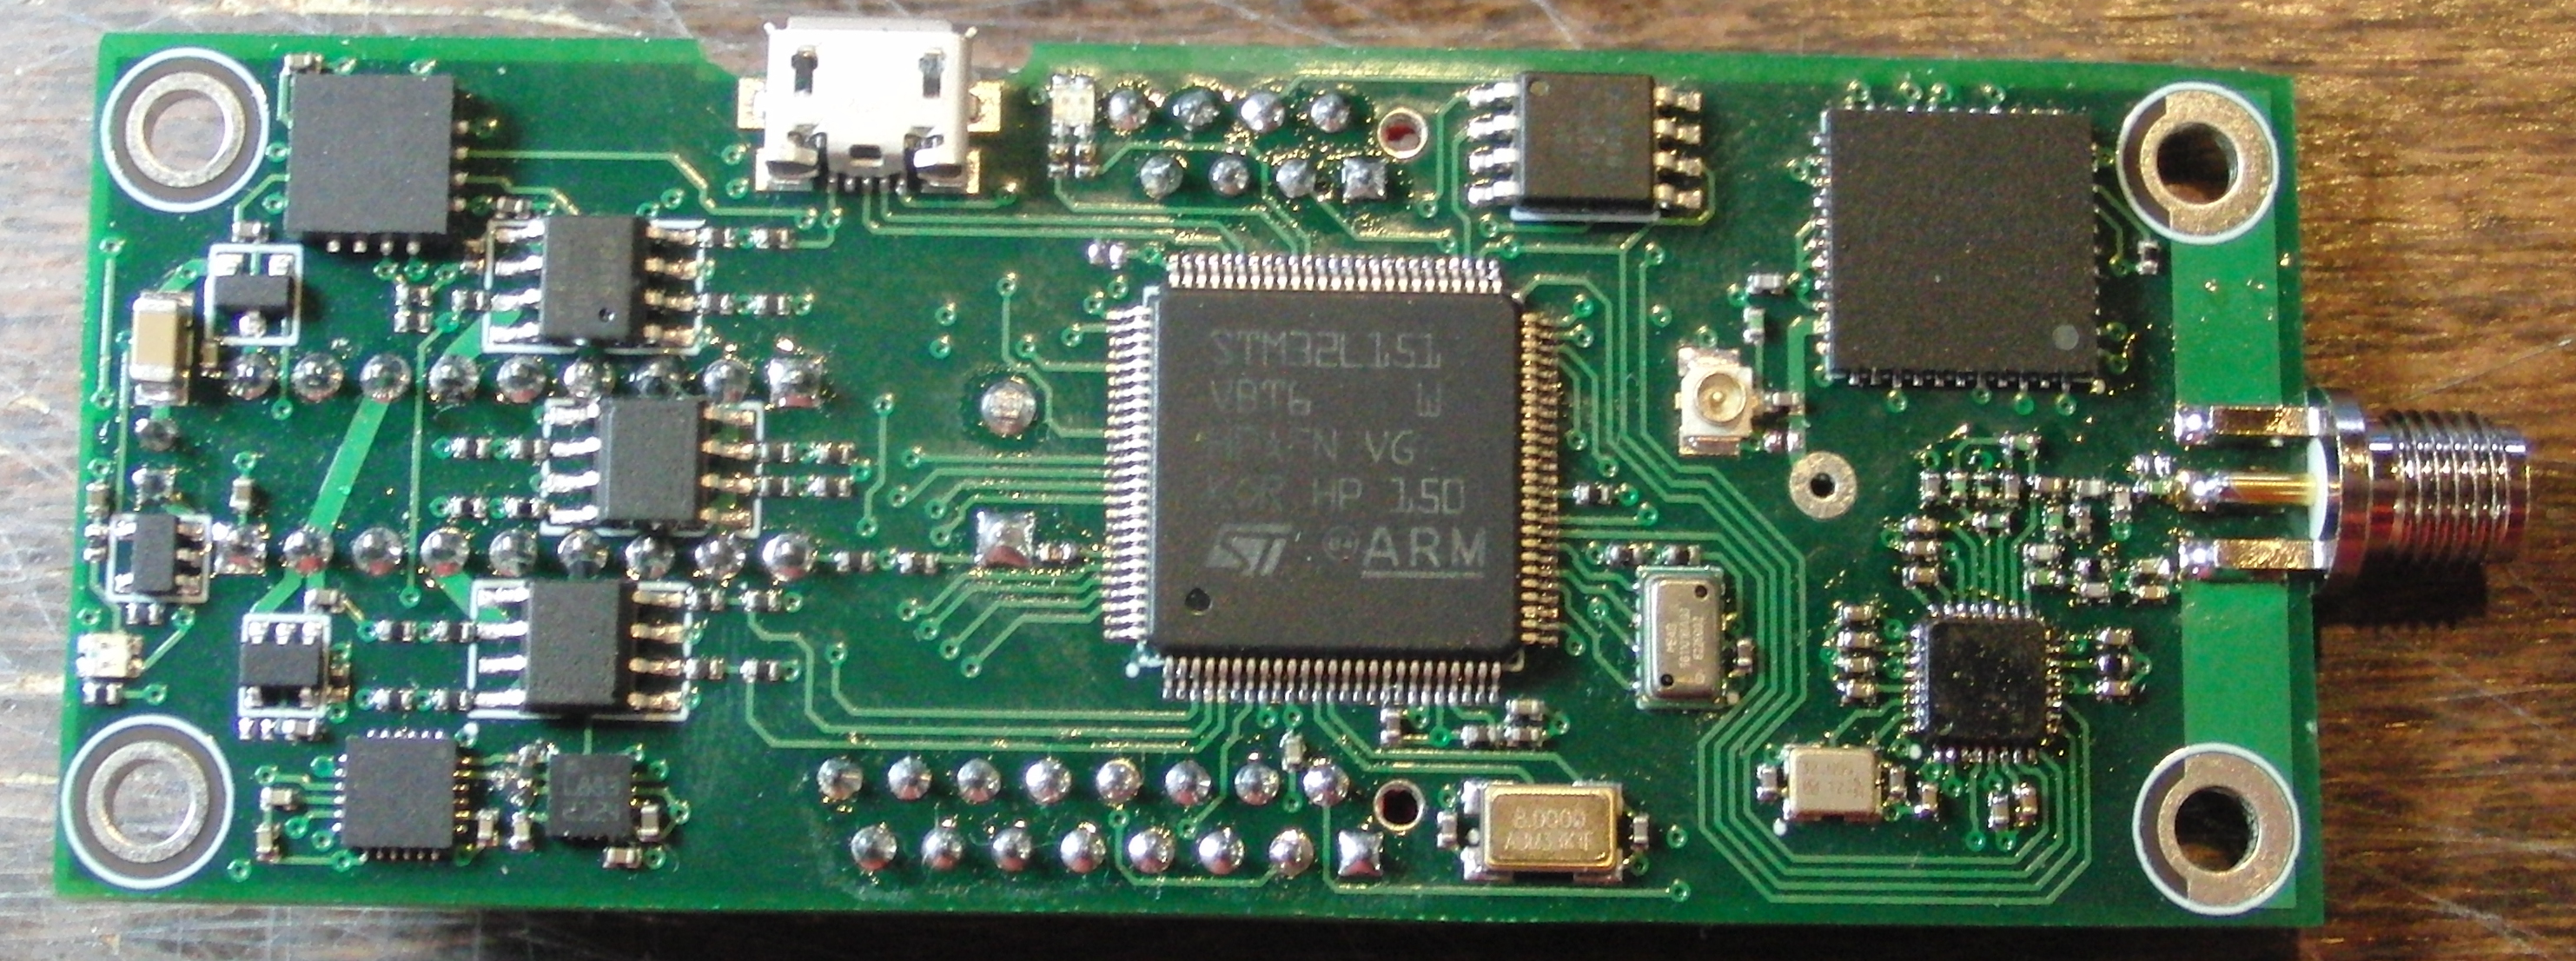
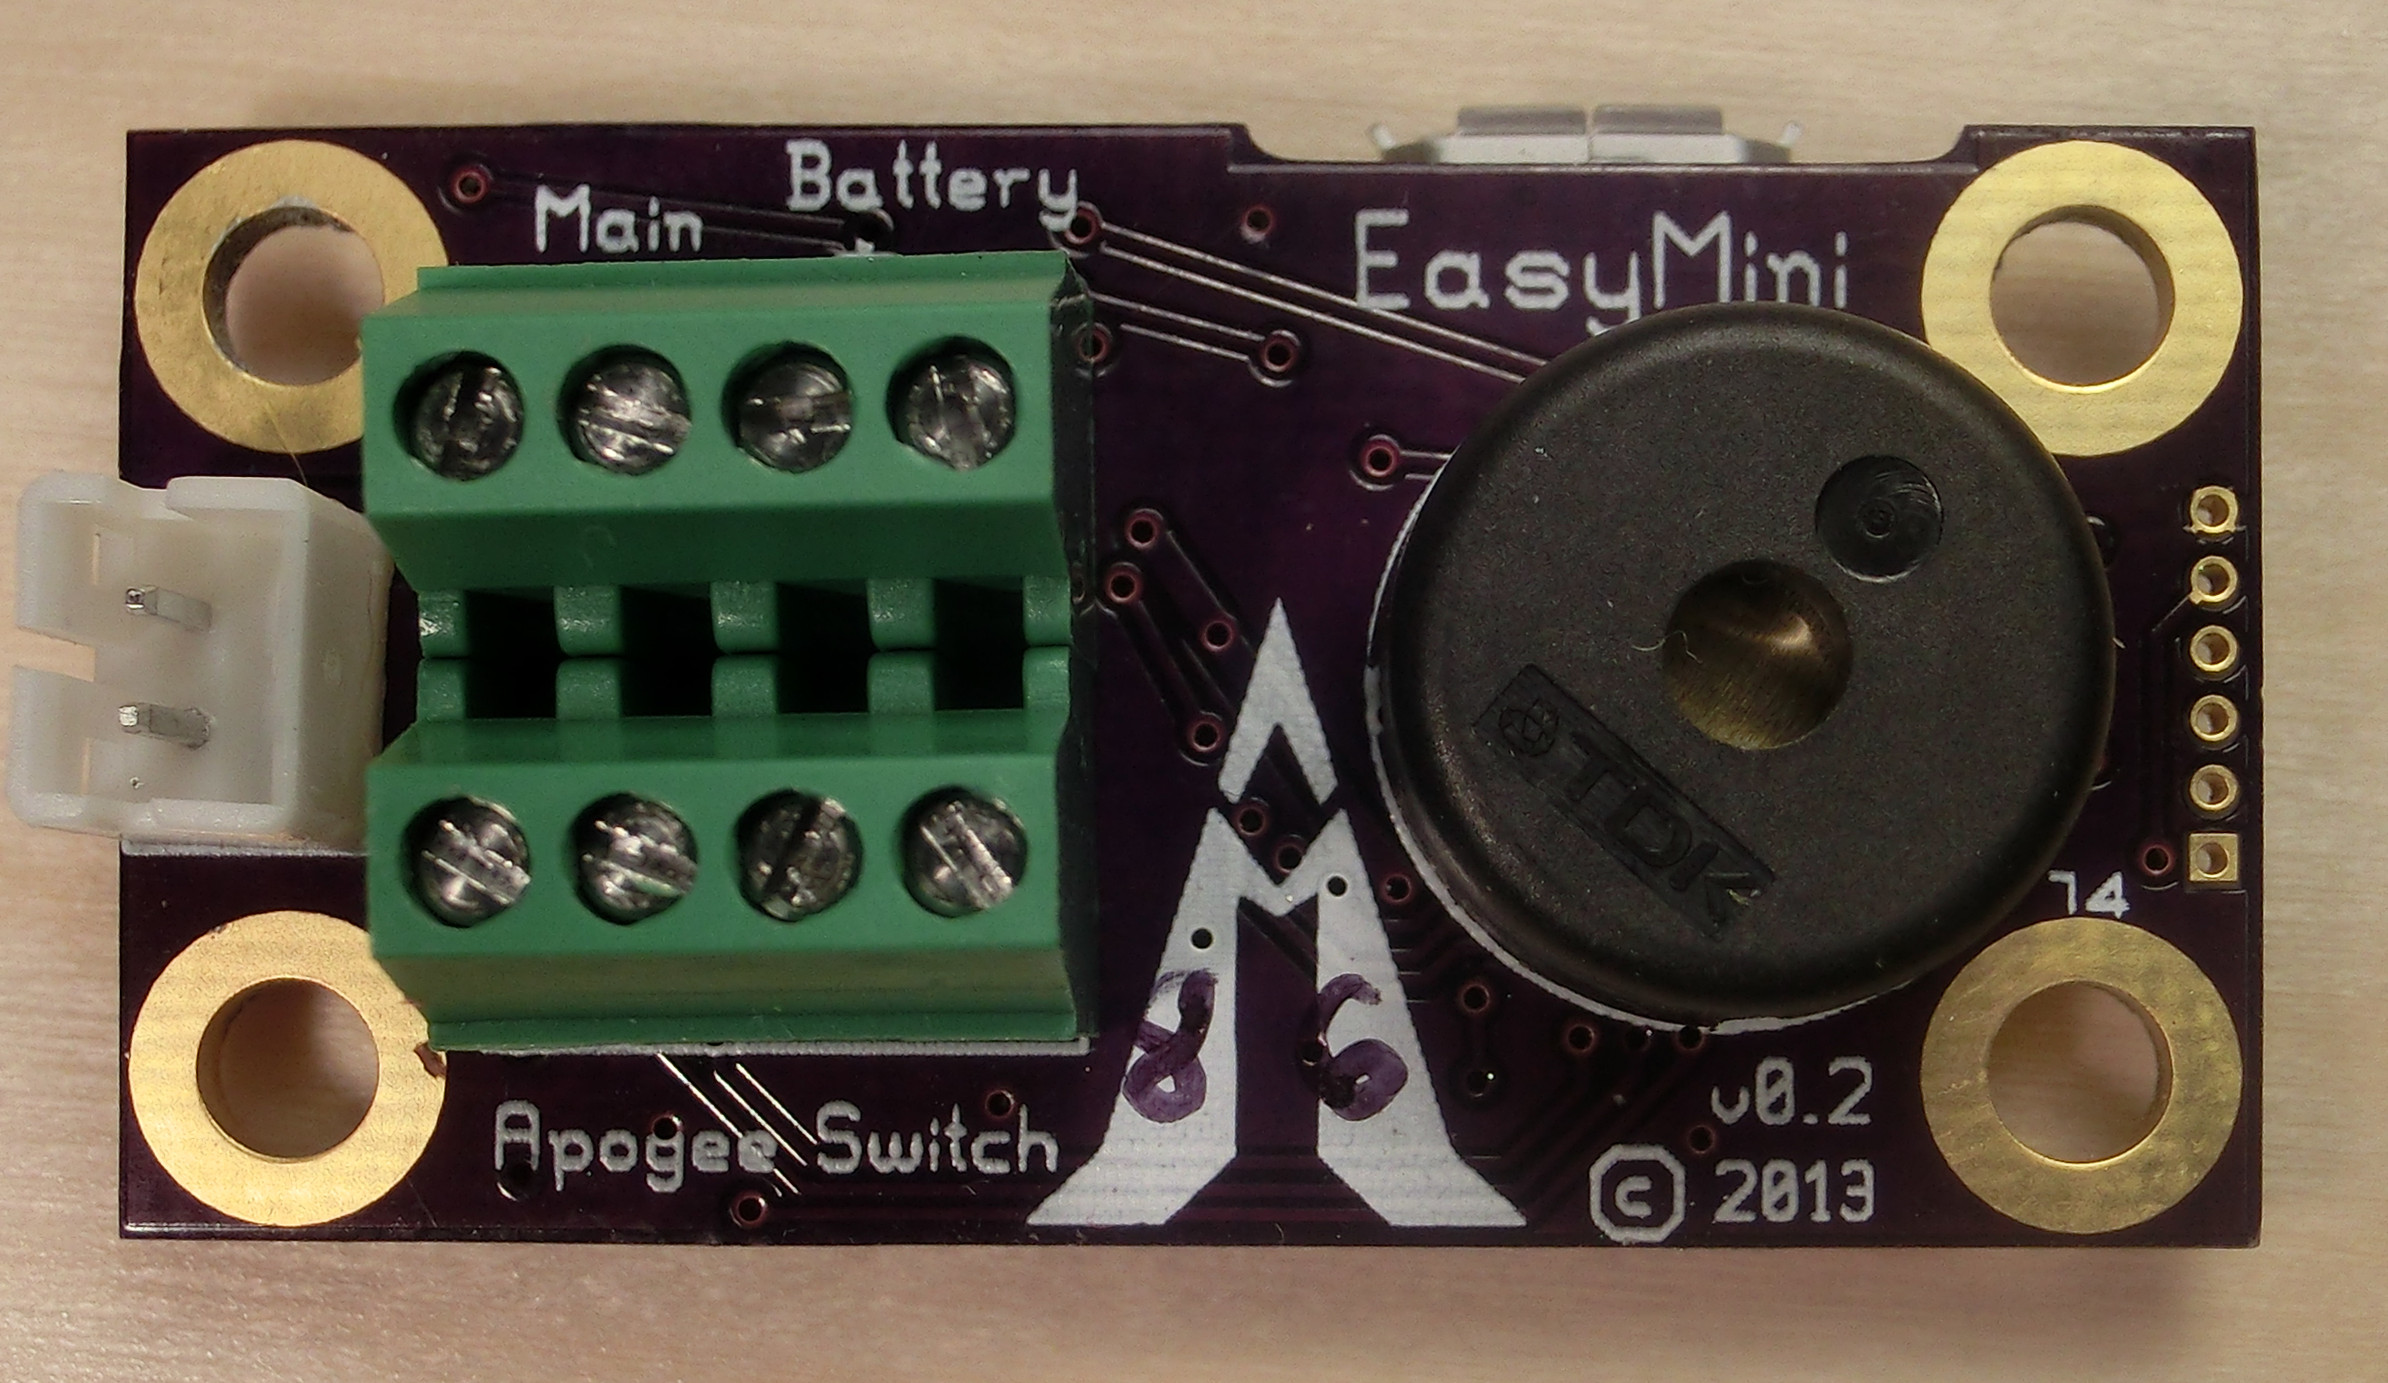
Back on Black (Friday) Event Altus Metrum is pleased to announce our Back on Black (Friday) event! For the first time since the Black Forest fire in June, we re re-opening our web store this weekend with a host of new and classic Altus Metrum products, including a special pre-order discount on our latest-and-greatest flight computer design, TeleMega. This weekend only, Friday, 29 November 2013 through Monday, 2 December, 2013, the first 40 TeleMega direct orders placed through our web store will receive a special $50 pre-order discount (regular $400, now only $350!). TeleMega is an advanced flight computer with 9-axis IMU, 6 pyro channels, uBlox Max 7Q GPS and 40mW telemetry system. We designed TeleMega to be the ideal flight computer for sustainers and other complex projects. TeleMega production is currently in process, and we expect to be ready to ship in mid-December. Pre-order now and we won t charge you until we ship. Learn more about TeleMega at: http://altusmetrum.org/TeleMega/ We are also pleased to announce that TeleBT is back in stock. Priced at $150, TeleBT is our latest ground station that connects to your laptop over USB or your Android device over BlueTooth. Learn more about TeleBT at http://altusmetrum.org/TeleBT/ Another new product we re thrilled to announce is EasyMini! Priced at only $80, EasyMini is a two-channel flight computer with built-in data logging and USB data download. Like our more advanced flight computers, EasyMini is loaded with sophisticated electronics and firmware, designed to be very simple to use yet capable enough for high performance airframes. Perfect as a first flight computer, EasyMini is also great as a backup deployment controller in complext projects. Learn more about EasyMini at: http://altusmetrum.org/EasyMini/ Also in stock for immediate shipment is MicroPeak, our 1.9 gram recording altimeter available for $50. The MicroPeak USB adapter, also $50, has been improved to make data downloading a snap. Read more about these at: http://altusmetrum.org/MicroPeak http://altusmetrum.org/MicroPeakUSB You can learn more about these and all our other Altus Metrum products at http://altusmetrum.org. The special discount on TeleMega pre-orders is available only on orders placed directly through Bdale s web store at http://shop.gag.com Thank you all for your support of Altus Metrum during 2013. It s been a rough year, but we re having a great time updating our existing products and designing new stuff! We look forward to returning products like TeleMetrum and TeleMini to the market soon, and plan to introduce even more new products soon.

28 November 2013

Debian Med: Bits from Debian Med team (by Andreas Tille)

Some of these bits are a bit outdated but there is no point in hiding this information just because it is old. FOSDEM talkAndreas Tille had a talk at FOSDEM which is also Video recorded. A quite similar but updated talk was held at DebConf 13 (see below). Jabber interview by reporter from IndiaThere was an interesting interview between Rajeev Nair and Andreas Tille at So, 17.02.2013 Rajeev Nair is Business head of an health care journal in India held via jabber. Since this might serve as some nice FAQ about Debian Med here is a complete log of this interview (permission to publish it was granted). Article about Debian MedAs a consequence of the interview above the Debian Med team has assembled an article which was originally intended to be published in the Health Cafe journal but somehow this never happened. So we ended up with a nice article targeting at interested readers about Free Software in medicine with not necessarily informatics background. Since the article is considered to be of good quality and has consumed some time of several team members we are seeking for ideas for relevant places where to publish it. It is available as PDFas well as in SVN. Yearly sprint of Debian Med teamThis year we had our third sprint of the Debian Med team and all participants consider it a great success again. The sprint was in end of February and the individual reports are linked from the according wiki page. Since Andreas Tille was able to prove the nice effect of having face to face meetings in Debian teams in the team metrics graphs presented in his talks at DebConf (see below) we will keep on with this good tradition. The next sprint is scheduled for Friday 31st January until Sunday 2nd February in Stonehaven near Aberdeen. If you are interested to meet the people behind Debian Med and want to join us in developing packages which are helpful in health care and bioinformatics you are invited to join us. DebConf 13 in VaumarcusAndreas Tille had two talks with specific influence to Debian Med development(Debian Med as a success story for other Blends, How to attract new developers for your team (MoM, SoB). For those who want to read a full (and lengthy) report about DebConf 13 by Andreas Tille this is online in this blog article. Codefest of the Open Bioinformatics FoundationIvo Maintz and Steffen M ller organised the Codefest of the Open Bioinformatics Foundation in Berlin. About 40 contributors from all over the world attended, connecting the Debian community strongly with upstream. The event triggered a joint paper of participants to Sprints, Codefests and Hackathons alike, presented at the Nettab conference on Semantic, Social, and Mobile Applications for Bioinformatics and Biomedical Laboratories in Venice. Reupload unattended packagesAndreas Tille has mentored the GSoC student Emmanouil Kiagias and as a byproduct some Blends metadata were now kept in UDD. This has inspired some new tools and one of this was an UDD query to return all packages in the interest of the Blend ordered by date when they were uploaded. It has shown that there were packages hanging around in the package pool since five years. So some effort was done to check those packages which were not necessarily "buggy" according to BTS entries and so we were able to fix the following issues in about 20-30 packages: Since it was impressive how many things that deserve fixing are hidden in such long unattended packages it is recommended also to other teams to spend some time into these. The UDD query can be easily tweaked for a team maintainer address. Debian Med Bug Squashing Advent Calendar 2013The Debian Med team will again do the Bug Squashing Advent Calendar. Feel free to join us in our bug squashing effort where we close bugs while other people are opening doors. :-) Kind regards and see you at Debian Med sprint
Andreas.

27 November 2013

Steinar H. Gunderson: Stockfish

The open-source chess program Stockfish recently climbed to the top of the TCEC rating lists. Even though it does not seem likely to win the actual TCEC tournament (it is 15.5 11.5 down in the 48-game superfinal against Komodo, a closed-source commercial program, after winning 4, losing 8 and drawing 15), this is a tremendeous achievement. This is not only because it is highly unusual that the strongest chess program is open-source (it's naturally hard to keep a competitive edge when everybody can see your secrets!), but also because it is a mere 9000 lines of C++ code. (This is without a GUI; it interfaces through a standardized protocol known as UCI.) In comparison, Crafty, a far weaker open-source program, is about four times that, GNU Chess is above 40000, and I seem to recall that the Deep Blue program was something like 65000 lines (in addition to, of course, all the code for the ASIC chess chips it contained, and stood for the majority of its chess strength!). So, the development team is really to be commended. It should also be said that TCEC is testing the latest beta versions of most of these engines and while Stockfish is developed in the open, on GitHub, the latest versions of e.g. Komodo and Houdini are private. (This is probably one of the reasons why Stockfish is slightly lower on e.g. the CCRL list, which also computes chess program rating lists by playing games between them.) Now, why does anyone care? Only a very small handful of players would be able to score even a draw against any of these programs in a 10-game match, so does it really matter which one we choose? Or is this some obscure pissing contest? The answer, of course, is that these engines are not primarily useful for competitive play; they are useful for analysis. Almost any player, right down from beginners to the very top players, can benefit from having someone stronger than them look at their games (or others' games!) and say where things went wrong. (Somehow analyzing losses always seem more instructive than analyzing wins. Nobody ever got better by winning, as the saying goes.) And the better a program is at playing chess, the more likely is its analysis to be correct. Of course, for the weaker players, a chess coach is likely to produce much more understandable guidance ( this creates a weak square on c7 is much more palatable than after these 18 moves here, white is 0.48 pawns stronger than you, so this was a bad move , and engines produce the latter sort of output), but they are always available, incredibly strong, and cost much less than a coach. :-) They also add a lot to the otherwise quite hard-to-comprehend activity of watching high-level human players; while the computers do not understand every kind of position equally well, they at least provide some sort of objective verdict on which player has the upper hand, something which can be really hard to discern unless you have very strong players around for commentary. So, in trying to improve my skills a bit, I've been analyzing my games with engines for a while, and recently I've switched from Rybka to Stockfish. (Rybka, a closed-source program, used to be the clear leader of the pack, but after a huge amount of drama involving accusations of who has copied code from who, it seems no longer to be actively developed, and Stockfish is now somewhat stronger.) This, unfortunately, brings me to the things I don't like too much about Stockfish; it seems to behave more erratically than Rybka did in interactive analysis mode. Its score jumps a lot more around when I move something (worse at remember the analysis from the previous position?), and sometimes, it changes its mind a lot when I move back and forth between moves maybe the huge selectivity that makes chess engines so strong these days also make them behave less usefully when only looking at a move for a few seconds. So, even though Stockfish is a fantastic chess engine, and will only get better in the future, maybe I'll go back to Rybka at some point. But then again, maybe I should then check out Komodo or any of the other engines out there or maybe talk to someone who actually knows chess, that would help a lot, too =)

26 November 2013

Daniel Pocock: Real-time streaming market data with free software

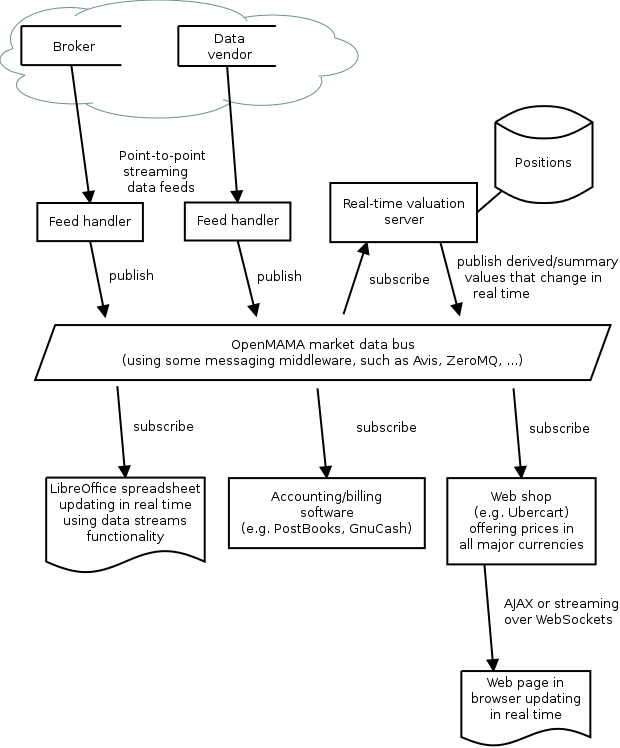
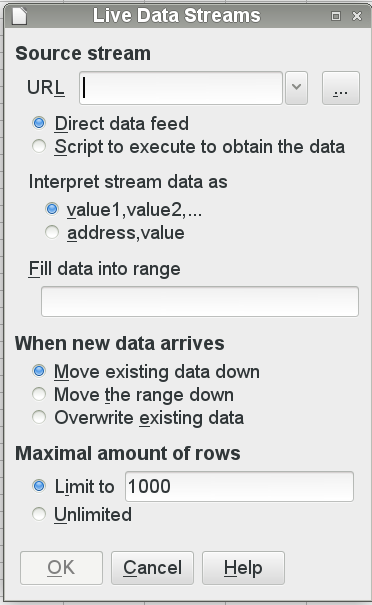
Here is an overview of the real-time market data architecture based on OpenMAMA: All these components may be running on a single host or they may be distributed across different servers and workstations in a LAN. The OpenMAMA market data bus ties them together. External data sources These are external sources of data. These could be currency trading firms, stock brokers, bullion dealers or even Bitcoin exchanges. Some exchanges don't provide data services directly to the general public and they distribute their price data through third-party data vendors such as Reuters and Bloomberg. Feed handlers The feed handlers manage the connections to external data sources. These are typically daemon processes that implement the wire protocols used by the external vendors for transmitting data over the public internet or a leased line. They typically use a point-to-point topology such as TCP connections. The feed handlers publish the data into the market data bus. In practice, the feed handler may be a proprietary application provided by the data vendor or it may simply be a Python script that fetches exchange rates from a URL every five minutes. OpenMAMA The market data bus is a distributed framework that is accessible to all of the local servers and workstations in the LAN. At the lowest level a messaging middleware solution is used to transport the data. The Avis Event Router is a free middleware. There is upcoming support for Apache QPID as well. Some commcercial middleware is supported too - here is the full list OpenMAMA does not provide a daemon or server process of its own. It is a set of libraries that operate on top of the middleware transport. In very general terms, the OpenMAMA libraries let applications publish messages (such as price ticks) or subscribe to receive the messages published by other applications. Spreadsheet application (for example, LibreOffice) LibreOffice is introducing a new data import feature for streaming time series data. This appears to provide a useful integration point for OpenMAMA and discussion is taking place in the development community. The spreadsheet can operate in various ways. A simple application may simply poll the currency prices when the spreadsheet is opened or refreshed. A more demanding application may see the spreadsheet come alive, recalculating all cells on every tick from the data vendor (several times per second). This latter scenario is more common in dealing rooms and hedge funds. Accounting/billing software There are many free accounting applications today, including PostBooks and GnuCash and some more heavyweight solutions like Adempiere and OpenERP. In a world where credit cards and the world wide web have made international trade an everyday activity, many people are using this software to track expenses and accounts in more than one currency. For example, a British business may be paying some suppliers in Euros and a Canadian may be charging some customers in US dollars. A Swiss person may be keeping some of their savings in gold bullion in the vault of one of their world reknowned Swiss banks. A common requirement for all of these users is the balance sheet. Using real-time market data sources, the balance sheet can be refreshed at any time from the live market prices. A home user may just find it convenient that they can open the balance sheet and always see their net worth immediately without having to manually cut and paste the currency prices from a web page. A business user operating in a competitive industry with low margins may be checking the balance sheet several times per day to ensure they remain solvent and profitable. Web shops Many web shops now offer the customers the convenience of viewing prices in their own currency. It is important to make sure these prices are accurate, especially when dealing with volatile currencies or when the products have a low profit margin. The web application server can receive the market data price ticks just like any other application in the network. Using this data, it can insert live prices into the pages as they are generated. If the currencies are particularly volatile, the web application could stream the prices to the browser using WebSockets and a JavaScript client embedded in the page would update the price field in real time. In fact, this web-based streaming price update mechanism is exactly how many online financial trading services offer live market prices to their customers. Real-time valuation server In a large organisation there may be many users looking at the same values. For example, in a trading desk, many users may need to see the desk's overall position in each market. In a busy web shop, many concurrent users may need to see the prices of common products. Rather than recalculating these values for each user in parallel, a common solution involves setting up a server to receive raw values (such as currency prices) from the data feed, calculate values needed by local users and then broadcast those values over the market data bus. How applications can integrate with real-time market data Here are some steps for getting started:

25 November 2013

Steve McIntyre: Mini-Debconf in Cambridge, November 14-17 2013

Phew, we did it! We successfuly ran our mini-conf last weekend. We welcomed roughly 60 people to the ARM offices in Cambridge over the 4 days. We started off with two days of sprint time, set aside for focussed hacking. We had a selection of ARM development boards on hand that people were playing with, plus a number of other people working on various other projects. The sprint sessions also saw some lively discussions on a couple of topics: the status of the ARM ports in Debian and automated system testing. Saturday and Sunday saw us move over to the more traditional style of conference session. Two full days of talks covered a wide range of topics: system testing to git tools, Debian ftp team work to bootstrapping the new arm64 port, improving ways of tracking and crediting Debian contributions to dealing with the new world of UEFI. Several volunteers from the DebConf video team were on hand too, so our talks were streamed live and recorded too - look out for them online soon! The mini-conf went well and feedback from attendees was universally positive, so we're already planning to run another similar event next year and maybe even apply to host a full DebConf in Cambridge soon too. :-) Many more details about the conference are in the debconf wiki at https://wiki.debconf.org/wiki/Miniconf-UK/2013 . Thanks to the sponsors who helped to make it all happen: ARM, Boston, Open@Citrix/Xen and Codethink/Baserock. 2013-11-25 UPDATE: Videos are now online at http://meetings-archive.debian.net/pub/debian-meetings/2013/mini-debconf-cambridge/ in various formats.

24 November 2013

Christian Perrier: Less IRC...

Over last months, I notice I'm not that active on IRC. Still, my always connected IRSSI client was constantly connected to 12+ channels. I just decided to reduce this to channels where I'm still (loosely) active and maybe less likely to miss highlights (or answer then 3 days later). So, I'll stick to the following: And that's all. So, well, if you want to catch me, you know where to go. But, really, mail is much more preferrable to reach me out nowadays.

Petter Reinholdtsen: New chrpath release 0.15

After many years break from the package and a vain hope that development would be continued by someone else, I finally pulled my acts together this morning and wrapped up a new release of chrpath, the command line tool to modify the rpath and runpath of already compiled ELF programs. The update was triggered by the persistence of Isha Vishnoi at IBM, which needed a new config.guess file to get support for the ppc64le architecture (powerpc 64-bit Little Endian) he is working on. I checked the Debian, Ubuntu and Fedora packages for interesting patches (failed to find the source from OpenSUSE and Mandriva packages), and found quite a few nice fixes. These are the release notes: New in 0.15 released 2013-11-24: You can download the new version 0.15 from alioth. Please let us know via the Alioth project if something is wrong with the new release. The test suite did not discover any old errors, so if you find a new one, please also include a testsuite check.

22 November 2013

Iustin Pop: Z rich at night

Last weekend I realised that one of the advantages of winter is that it gets dark quite early - so I took a short walk through Z rich at night to take a set of pictures. I usually only shoot handheld at night, which has its limitations, and this time I took a tripod with me. It's a very cheap tripod which I have for many years now and I don't really use - and the test was to see if it's actually usable for long exposures. The results can be seen on my Smugmug gallery. Some of the pictures I really like, but that's not the main point - I learned a lot in just an hour or so. First, the tripod worked. Well, it's cheap and plasticky, so "mirror delay 3" was absolutely needed, but with that the pictures got out reasonably sharp, even at 30s exposure. Second, I forgot my cable release at home, even though I explicitly wanted to take it, so "mirror delay 3" became my remote release. Logistics aside, the most interesting thing was that in the dark, the enemy is light, and not darkness. In the city, the contrast between darkness and strong lights results in a large dynamic range requirement, and - to me - that was a surprising realisation. As an example, in this picture, I had to use f/22 to get the desired exposure time, as the light was too strong. Another surprising realisation was that, if you're shooting with 30s exposure time, a person passing in front of the camera (but not staying in the same place) will leave no trace. At shorter exposures, or when the person has a low transversal speed, then it will show, but otherwise, you don't have to care too much . Something that I knew but it was not nice to be reminded of is how "broken" auto white balance is in presence of artificial lighting (basically low temperature). Add the fact that in a non-trivial scene you have multiple lights with different temperatures makes any night scene interesting - I had to manually fix white balance for the entire album, and I don't think I got it right. And finally - light pollution. The sky above Z rich was cloudy, and the clouds were glowing orange/reddish. I can't wait to get somewhere a bit far from civilisation with a nice, dark sky

Vincent Sanders: Error analysis is the sweet spot for improvement

Although Don Norman was discussing designers attitude to user errors I assert the same is true for programmers when we use static program analysis tools.

The errors, or rather defects in the jargon, that a static analysis tools produce can be considered low cost well formed bug reports available very early in the development process.

When I say low cost it is because they can be found by a machine without a user or fellow developer wasting their time finding them. Well formed comes because the machine can describe exactly how it came to the logical deduction leading to the defect.
IntroductionStatic analysis is in general terms using the computer to examine a program for logic errors beyond those of pure syntax before it is executed. Examining a running program for defects is known as dynamic program analysis and while a powerful tool in its own right is not the topic of discussion.

This analysis has historically been confined to compiled languages as their compilers already had the Abstract Syntax Tree (AST) of the code available for analysis. As an example the C language (released in 1972) had the lint tool (released in 1979) based on the PCC compiler.

Practical early compilers (I am generalising here as the 19070s were a time of white hot innovation in computing and examples of just about any innovation in the field could probably be found) were pretty primitive and produced executables which were less good than hand written assembler output. Due to practical constraints the progress of optimising compilers was not as rapid as might be desired so static analysis was largely used as an external process.

Before progressing I ought to explain why I just mixed the concept of an optimising compiler and static analysis. The act of optimisation within those compilers requires program analysis, from which they can generate defect reports which we all know and love as compiler warnings, also explaining why many warnings only appear at higher optimisation levels where deeper analysis is required.

The attentive reader may now enquire as to why we would need external analysis tools when our compilers already perform the task. The answer stems from the issue that a compiler is trying to reconcile many desirable traits including:
The slow progress in creating optimising compilers initially centred around the problem of getting the compiled output in a reasonable time to allow for a practical edit-compile-run-debug cycle although the issues more recently have moved more towards the compiler implementation costs.

Because the output generation time is still a significant factor compilers limit the level of static analysis performed to that strictly required to produce good output. In standard operation optimising compilers do not do the extended analysis necessary to find all the defects that might be detectable.

An example: compiling one 200,000 line C program with the clang (v3.3) compiler producing x86 instruction binaries at optimisation level 2 takes 70 seconds but using the clang based scan-build static analysis tool took 517 seconds or more than seven times as long.
Using static analysis
As already described warnings are a by-product of an optimising compilers analysis and most good programmers will endeavour to remove all warnings from a project. Thus almost all programmers are already using static analysis to some degree.

The external analysis tools available can produce many more defect reports than the compiler alone as long as the developer is prepared to wait for the output. Because of this delay static analysis is often done outside the usual developers cycle and often integrated into a projects Continuous Integration (CI) system.

The resulting defects are usually presented as annotated source code with a numbered list of logical steps which shows how the defect can present. For example the steps might highlight where a line of code allocates memory from the heap and then an exit path where no reference to the allocated memory is kept resulting in a resource leak.

Once the analysis has been performed and a list of defects generated the main problem with this technology rears its ugly head, that of so called "false positives". The analysis is fundamentally an undecidable problem (it is a variation of the halting problem) and relies on algorithms to generate approximate solutions. Because of this some of the identified defects are erroneous.

The level of erroneous defect reports varies depending on the codebase being analysed and how good the analysis tool being used is. It is not uncommon to see false positive rates, even with the best tools, in excess of 10%

Good tools allow for this and provide ways to supply additional context through model files or hints in the source code to suppress the incorrect defect reports. This is analogous to using asserts to explicitly constrain variable values or a type cast to suppress a type warning.

Even once the false positives have been dealt with there comes the problem of defects which while they may be theoretically possible take so many steps to achieve that their probability is remote at best. These defects are often better categorized as a missing constraint and the better analysis tools generate fewer than the more naive implementations.

An issue with some defect reports is that often defects will appear in a small number of modules within programs, generally where the developers already know the code is of poor quality, thus not adding useful knowledge about a project.

As with all code quality tools static analysis can be helpful but is not a panacea code may be completely defect free but still fail to function correctly.
Defect DensityA term that is often used as a metric for code quality is the defect density. This is nothing more than the ratio of defect to thousands of lines of code e.g. a defect density of 0.9 means that there is approximately one defect found in every 1100 lines of code.

The often quoted industry average defect density value is 1, as with all software metrics this can be a useful indicator but should not be used without understanding.

The value will be affected by improvements in the tool as well as how lines of code are counted so is exceptionally susceptible to gaming and long term trends must be treated with scepticism.
Practical examplesI have integrated two distinct static analysis tools into the development workflow for the NetSurf project which I shall present as case studies. These examples show a good open source solution and a commercial offering highlighting the issues with each.

Several other solutions, both open source and commercial, exist many of which have been examined and discarded as either impractical or proving less useful than those selected. However the investigation was not comprehensive and only considered what was practical for the project at the time.
clangThe clang project is a frontend to the LLVM project providing an optimising compiler for the C, C++ and objective C languages. As part of this project the compiler has been enhanced to run a collection of "checkers" which implement various methods of analysis on the code being compiled.

The "scan-build" tool is provided to make the using these features straightforward. This tool generates defect reports as a series of html files which show the analysis results.


NetSurf CI system scan-build overview
Because the scan-build takes in excess of eight minutes on powerful hardware the NetSurf developers are not going to run this tool themselves as a matter of course. To get the useful output without the downsides it was decided to integrate the scan into the CI system code quality checks.

NetSurf CI system scan-build result list
Whenever a git commit happens to the mainline branch and the standard check build completes successfully on all target architectures the scan is performed and the results are published as a list of defects.

The list is accessible directly through the CI interface and also incorporates a trend graph showing how many defects were detected in each build.

A scan-build report showing an extremely unlikely path to a defect
Each defect listed has a detail link which reveals the full analysis and logic necessary to cause the defect to occur.

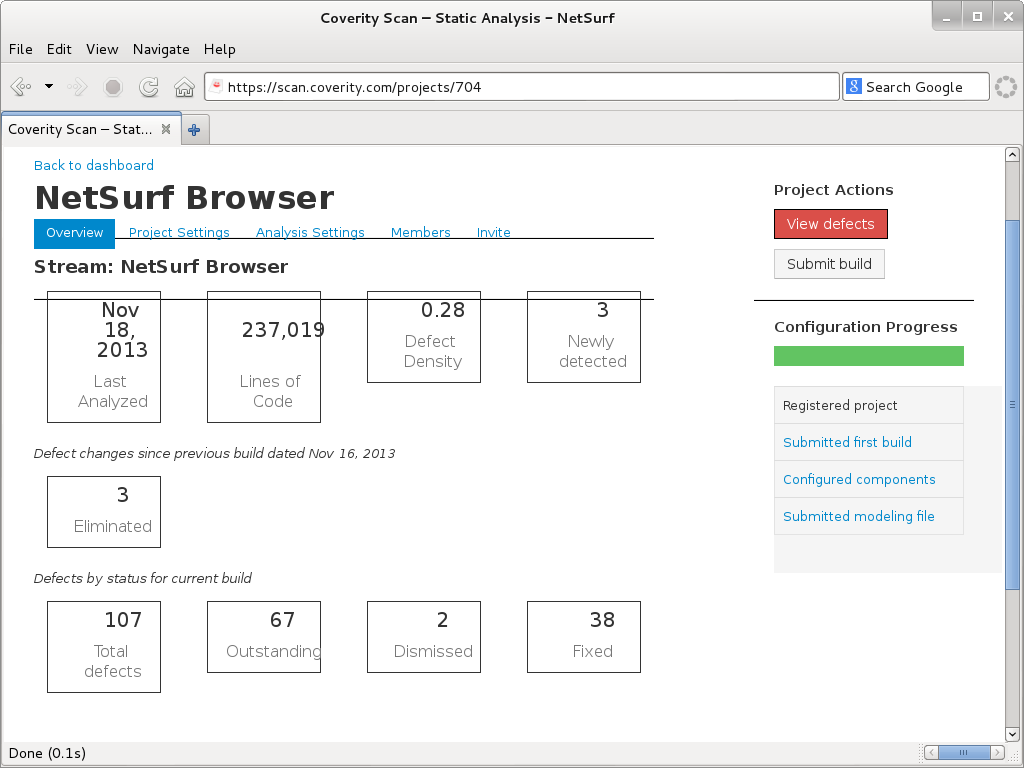
Unfortunately even NetSurf which is a relatively small piece of software (around 200,000 lines of code at time of writing) causes 107 defects to be emitted by scan-build.

All but 25 of the defects are however "Dead Store" where the code has a value assigned but is never checked. These errors are simply not interesting to the developers and are occurring in code generated by a tool.

Of the remaining defects identified the majority are false positives and several (like the example in the image above) are simply improbable requiring a large number of steps to reach.

This shows up the main problem with the scan-build tool in that there is no way to suppress certain checks, mark defects as erroneous or avoid false positives using a model file. This reduces the usefulness of these builds because the developers all need to remember that this list of defects is not relevant.

Most of the NetSurf developers know that the project currently has 107 outstanding issues and if a code change or tool improvement were to change that value we have to manually work through the defect list one by one to check what had changed.
CoverityThe coverity SAVE tool is a commercial offering from a company founded in the Computer Systems Laboratory at Stanford University in Palo Alto, California. The results of the original novel research has produced a good solution which improved on analysis tools previously available.

Coverity Interface showing summary of NetSurf analysis. Layout issues are a NetSurf bug
The company hosts a gratis service for open source projects, they even provide scans for the Linux kernel so project size does not appear to be an issue.

The challenges faced integrating the coverity tool into the build process differed from clang however the issue of execution time remained and the CI service was used.

The coverity scanning tool is a binary executable which collects data on the build which is then submitted to the coverity service to be analysed. This tool obviously relies upon the developer running the executable to trust coverity to some degree.

A basic examination of the binary was performed and determined the executable was not establishing network connections or performing and observably undesirable behaviour. From this investigation the decision was made that running the tool inside a sandbox environment on a CI build slave was safe. The CI system also submits the collected results in a compressed form directly to the coverity scan service.

Care must be taken to only submit builds according to the services Acceptable Use Policy which limits the submission frequency of NetSurf scans to every other day. To ensure the project stays within the rules the build performed by the CI system is manually controlled and confined to a subset of NetSurf developers.

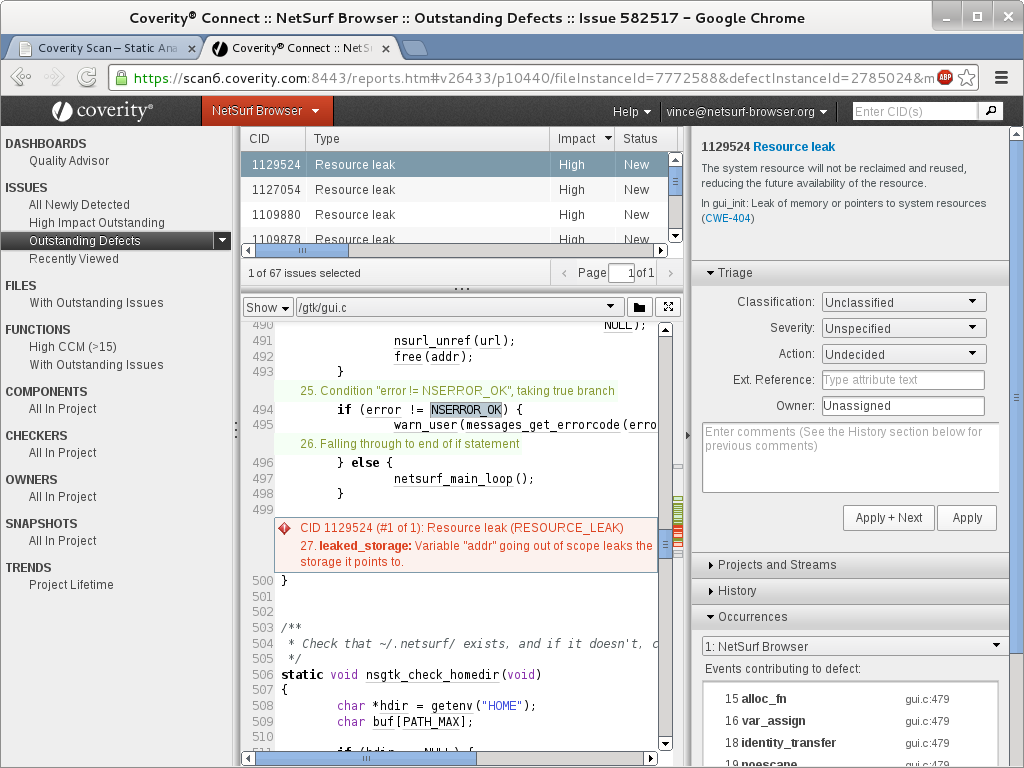
Coverity connect defect management console for NetSurfThe results are presented using the coverity connect web technology based defect management tool. Access to the coverity connect interface is controlled by a user management system which precludes publicly publishing the results within the CI system.

Unfortunately NetSurf itself does not currently have good enough JavaScript DOM bindings to support this interface so another browser must be used to view it.

Despite the drawbacks the quality of the analysis results is greatly superior to the clang solution. The false positive rate is very low while finding many real issues which had not been previously detected.

The analysis can be enhanced by use of collection configuration and modelling files which remove intended constructions from consideration reducing the false positive rate to very low levels. The ability to easily and persistently suppress false positives through the web interface is also available.

The false positive management capabilities coupled with a user interface that makes understanding the defect path simple make this solution very practical and indeed the NetSurf developers have removed over 50 actual issues within a relatively short period since the introduction of the tool.

Not all of those defects could be considered serious but they had the effect of encouraging deeper inspection of some very dubious smelling source.
ConclusionsThe principle conclusions of implementing and using static analysis have been:

When I started looking at this technology I was somewhat dubious about its usefulness but I have definitely changed my mind. It is a useful addition to any non-trivial project and the return on time and effort should be repaid handsomely in all but already perfect code (if you believe you have such code I have a bridge to sell you).

Russ Allbery: Review: The Pathway to Awesomeness

Review: The Pathway to Awesomeness, by Mark Forster
Publisher: Hyperink
Copyright: October 2013
ASIN: B00FXGXMPQ
Format: Kindle
Pages: 97
Mark Forster is probably my favorite time management (or, if you prefer, attention management) writer. The place to start with Forster if you're not familiar with him is Do It Tomorrow, not here. Unlike the other books by him I've reviewed, this is just an edited collection of blog posts presented in a convenient ebook form, without even an ISBN number. But if you've read his books (at least the ones that aren't out of print and cost a fortune), this is a convenient way to not have to trawl back through his blog and read the articles in a more convenient fashion. For me, it was also an easy way to give him a bit of money for his blog. Unless you have a similar motive, I don't think the content to price ratio is worth it. But I think everything is still up at Get Everything Done in case anything here strikes your fancy. As with most blog compilations, The Pathway to Awesomeness (I really hate that title) is composed of a whole bunch of fairly short articles, rarely more than three pages each, vaguely collected by topic. The first few are rather general and focused on the normal self-help platitudes that try to build up your sense that you're in control of your own life. But Forster doesn't take too long to get to what he's best at: short ideas, mental tools, interesting tricks, and simple techniques. Even more so than his books, due to the nature of this collection, there's a huge variety here, which means you can probably find something that strikes a chord no matter what attention management problem you've been running into. That's one of the main reasons why I prefer his writing: he tries to provide a giant toolbox instead of a single, streamlined System For Everyone. The other thing I like about Forster is that he is much more blunt than many authors about the biggest problem I have with attention management: trying to do more than anyone could possibly do given the available time. There are some more essays here about that, and several of them are quite good. I think my favorite is the short essay in which he points out how often people decide to do some task for a particular reason, and then get so engrossed in the performance of that task that they forget the original reason, risking sinking far more energy into that task than is actually warranted. Like a lot of Forster's observations, it's obvious in retrospect, but he has a way of phrasing those observation so that they shake the right thing loose in my head and let me re-evaluate something I was doing. Regular readers of Forster's blog know that he loves playing around with different simple to-do list management systems. Unfortunately, none of those are here, so don't pick this up expecting a collection of articles about Superfocus, Autofocus, etc. It makes sense given the topic of this collection, which is more general advice rather than systems, but this collection is so short that I wish he'd added a section on system development. I would have enjoyed reading a collection of all of his miniature systems together in one place and showing how he tweaked and changed them over time, particularly if he'd added some discussion of why he made each change and what goals he was trying to meet with each system. Ah well. If you aren't already familiar with Forster, there's no point in this, but if you are, I got a few new tidbits out of it and will probably skim through it a few more times. Buying it is mostly an exercise in putting money in the tip jar, and his writing is much less polished here (and more prone to cliches), but I still enjoyed reading through it. Rating: 7 out of 10

21 November 2013

Steve McIntyre: Mini-Debconf in Cambridge, November 14-17 2013

Phew, we did it! We successfuly ran our mini-conf last weekend. We welcomed roughly 60 people to the ARM offices in Cambridge over the 4 days. We started off with two days of sprint time, set aside for focussed hacking. We had a selection of ARM development boards on hand that people were playing with, plus a number of other people working on various other projects. The sprint sessions also saw some lively discussions on a couple of topics: the status of the ARM ports in Debian and automated system testing. Saturday and Sunday saw us move over to the more traditional style of conference session. Two full days of talks covered a wide range of topics: system testing to git tools, Debian ftp team work to bootstrapping the new arm64 port, improving ways of tracking and crediting Debian contributions to dealing with the new world of UEFI. Several volunteers from the DebConf video team were on hand too, so our talks were streamed live and recorded too - look out for them online soon! The mini-conf went well and feedback from attendees was universally positive, so we're already planning to run another similar event next year and maybe even apply to host a full DebConf in Cambridge soon too. :-) Many more details about the conference are in the debconf wiki at https://wiki.debconf.org/wiki/Miniconf-UK/2013 . Thanks to the sponsors who helped to make it all happen: ARM, Boston, Open@Citrix/Xen and Codethink/Baserock.

20 November 2013

Matt Zimmerman: Scaling Human Systems: Management

This is part 6 in a series on organizational design and growth.
The change from a business that the owner-entrepreneur can run with helpers to a business that requires management is a sweeping change. [...] One can compare the two kinds of business to two different kinds of organism: the insect, which is held together by a tough, hard skin, and the vertebrate animal, which has a skeleton. Land animals that are supported by a hard skin cannot grow beyond a few inches in size. To be larger, animals must have a skeleton. Yet the skeleton has not evolved out of the hard skin of the insect; for it is a different organ with different antecedents. Similarly, management becomes necessary when an organization reaches a certain size and complexity. But management, while it replaces the hard-skin structure of the owner-entrepreneur, is not its successor. It is, rather, its replacement. Peter Drucker
What it means Management is the art of enabling people to cooperate in achieving shared goals. I ve written elsewhere about what management is not. Management is a multifaceted discipline which is centered on people and the environment in which they work. Why it s important In very small organizations, management can be comparatively easy, and happen somewhat automatically, especially between people who have worked together before. But as organizations grow, management becomes a first-class concern, requiring dedicated practice and a higher degree of skill. Without due attention to management, coordination becomes excessively difficult, working systems are outgrown and become strained, and much of the important work described in this series just won t happen. Management is part of the infrastructure of the organization, and specifically the part which enables it to adapt and change as it grows. Old Status Quo People generally just do stuff , meaning there is little conscious understanding of the system in which people are working. If explicit managers exist, their jobs are poorly understood. Managers themselves may be confused or uncertain about what their purpose is, particularly if they are in such a role for the first time. The organization itself has probably developed more through accretion than deliberate design. New Status Quo People work within systems which help coordinate their work. These systems are consciously designed, explicitly communicated, and changed as often as necessary. Managers guide and coordinate the development and continuous improvement of these systems. The role of managers in the organization is broadly understood, and managers receive the training, support and coaching they need to be successful. Behaviors that help Obstacles that stand in our way

18 November 2013

Daniel Pocock: $75,000 to explore free software during maternity leave?

A number of countries offer women various social benefits during maternity leave. A new scheme in Australia promises to give virtually all women one hundred percent of their salary (capped at a whopping $12,500 per month) and extend maternity leave to 6 months. Some believe it has been funded by abolishing fibre-to-the-home, but that is another topic... This is a dramatic upgrade - in both cash and time - from the existing scheme where women have 18 weeks leave at the minimum wage. In Australia, the "minimum wage" figure is a fantasy, well below the real cost of living. In practice, the existing scheme and economic pressure force many women back into their job in less than 18 weeks. The new scheme with a one hundred percent salary replacement eliminates much of that pressure. Many European countries offer women some payment that pays the real cost of living, for example, EUR 2,400 per month in France. That is more than the minimum wage in Australia, enough to cover food, clothing and rent in most French cities. Australia's new system, in comparison, will give women on high salaries enough cash to immediately hire a nanny and other discretionary expenses that will maintain their lifestyle as much as they can within reason while dealing with a new baby. The cap is 300% higher than in France and it is 100% wage replacement, whereas many European schemes only give women a percentage of their salary. For this reason, many people have described it as the "Rolls Royce" of maternity pay. Just who are the women in these higher salary brackets? It is hardly any surprise that many of them are in IT and engineering professions. The upper salary range of the new maternity leave scheme appears to squarely match with the cashflows of female software developers, web designers, project managers and potentially many other professionals with a background in science or engineering. Many women worry about being out of the workforce for too long and the potential impact on their skills and professional networks. In computing jobs, technology can change a lot in 6 months. There are many men and women who enjoy computing in their free time as much as in their job. For female developers with this time out of the office, the world's most comfortable maternity leave scheme could be an opportunity to spend a little time exploring the free software world. Just to be clear, I'm not suggesting that women should be reaching for the laptop when they first go into labor and getting plugged in to the web before the umbilical cord has been severed. Some people find technology to be a rewarding pursuit throughout their whole life, while others simply see it as a job. For those who find free software interesting, some may simply pursue something creative that has no relation to the IT projects in their job, some may bring some new experiences back to their job. Others may choose to reconsider their career, performing free software development work on a freelance basis rather than going back to an office environment. The "Rolls Royce" maternity pay scheme could provide a comfortable buffer for them as they evaluate their next steps and make such decisions.

16 November 2013

Lars Wirzenius: Debian: developing it wrong

This is an essay form of a talk I have given today at the Cambridge Mini-debconf. The talk was videoed, so will presumably show up in the Debconf video archive eventually. Abstract Debian has a long and illustrious history. However, some of the things we do perhaps no longer make as much sense as they used to do. It's a new millennium, and we might find better ways of doing things. Things that used to be difficult might now be easy, if we dare look at things from a fresh perspective. I have been doing that at work, for the Baserock project, and this talk is a compilation of observations based on what I've learnt, concentrating on things that affect the development workflow of package maintainers. Introduction and background I have been a Debian developer since August, 1996 (modulo a couple of retirements), and have used it a little bit longer. I have done a variety of things for Debian, from maintaining PGP 2 packages to writing piuparts to blathering excessively on the mailing lists. My day job is to develop the Baserock system at Codethink. Baserock is a set of tools and workflows for developing embedded and appliance Linux systems. If you squint, it looks a bit like a source-based Linux distribution. I have worked on Baserock since September, 2011. Some of Baserock's design has been influenced by my experience with Debian. With Baserock I have the chance to fix all the things that are wrong in Debian, and this talk is me giving back to Debian by pointing out some the things I feel should be fixed. I don't have solutions for these problems: this is a bug report, not a patch. It's also perhaps a bit of a rant. I am specifically concentrating here on technical and tooling issues that affect the development process of Debian. I excluding social issues. I am also not trying to get Debian to switch to Baserock. Baserock is targeting embedded and appliance systems, and makes simplifying assumptions based on those targets, which Debian does not get to do. I am pointing out problems, and I am outlining solutions as implemented in Baserock, when I think the concept carries over well to Debian. Build tools should be intelligent, packaging should be dumb In Debian, the fundamental tool for compiling the upstream code and assembling a binary package is dpkg-buildpackage. It uses debian/rules, which is a Makefile with targets with specific names and semantics. By executing the right targets in the right order, dpkg-buildpackage tells the source package to build the binary package. On the one hand, this is a nice design, because it abstracts away the large variety of upstream build systems into one API for dpkg-buildpackage to use. On the other hand, it puts all the intelligence for how packages are built into the packages. Making packaging intelligent, rather than the build tool, means packagers need to do more work, and there's more work to do when, say, the Debian policy changes, or when there are other changes that affect a large number of packages. If packaging is intelligent, then every package needs changes. If the build tool is intelligent, then you change the build tool and re-build everything. In Baserock we put as much intelligence as we can into the Morph tool, which drives the build process. It turns out that today, unlike in 1995, most upstream projects use one of a handful well-known build systems: autotools, cpan, cmake, Python distutils, etc. With just a little extra logic in Morph we avoid having any delta against upstream in Baserock. This doesn't work for quite all upstream projects, of course, but we've spent the 2% (two, not twenty) of effort that solves 80% of the problem. In recent years, the dh approach to packaging has made a lot of packages be able to have only a minimal, 3-line debian/rules file. This is excellent. Wouldn't it be nice if even that wasn't needed? It'd save thousands of files in source packages across the archive, at least. It would be easy to: if the file is missing, have dpkg-buildpackage assume the 3-line version by default. Getting rid of a single file is, of course, not a particularly big win. The big win is the change in mindset: rather than dealing with all new issues in development by adding yet more fields to debian/control and more optional, competing tooling outside the core toolset, if you improve the tools everyone uses, then everyone's packages gets better. The goal should, in my opinion, be that for the large number of packages where upstream uses a well-known, well-behaved build system, and uses it in a reasonably sensible way, the Debian source package should not require anything added to make the package build. There will still be a need to add some stuff, such as the debian/copyright file, to make a good Debian package, but just getting the package to build should require nothing extra. (Side note: wouldn't it be nice if there was a well-known, widely used way to mark up copyright information so that debian/copyright could be constructed and updated automatically?) Configuration file handling on upgrades: add ucf to dpkg already In the 1990s, dpkg had excellent handling of configuration files and merging local changes with changes from the new package version, but it was excellent only because it tried to do that at all, and mostly nothing else did. It hasn't changed much, since, and it's not excellent on any absolute scale. We have the ucf tool, which can do a better job, but requires to be added to each package wanting to use it. Why don't we make dpkg smarter, instead? If ucf is not not good enough to be merged wholesale into dpkg, let's write something better. Making every package maintainer use ucf manually is just wasteful. This is not the kind of thing that should be done for each package separately: the package manager should be smart so that packaging can be stupid. The goal should be that dpkg is smart enough in its configuration file handling that having the package do it is a very rare special case. Clean building shouldn't be hard The basic tool for building a package is dpkg-buildpackage. It is ever so slightly cumbersome to use, so there are some wrappers, most importantly debuild. However, if you're making a build intended to be uploaded to the Debian archive, you should be doing a clean build. This means having to learn, configure, and use yet more tools. A clean build is important: security updates, development, debugging, quality control, porting, and user support become more difficult if we don't know how a package was built, and can't reproduce the build. It gets harder to keep build dependencies correct, making it harder for everyone to build things. Luckily, Debian has solved the clean build problem. Unluckily, it has solved it multiple times, creating the problem of having to choose the clean building approach you want to use. The default way of building is not clean, so then you have to remember to use the non-standard way. You also get to spend time maintaining the clean build environments yourself, since that doesn't seem to be fully automated. None of this is hard, as such, but it's extra friction in the development workflow. The primary approaches for clean building in Debian seem to be pbuilder, cowbuilder, and sbuild. I happen to use pbuilder myself, because it's what's been around the longest, but I make no claim of having made an informed choice. That is part of the problem here: why should I have to spend the effort to become informed to make a choice well? Why is the default way of building not clean? Don't say performance: Morph sets up a clean staging area in seconds, and does not offer you a choice of not doing so. It's a chroot, with everything but the build tree hardlinked from cached, unpacked build dependencies, and protected using read-only bind mounts. What's more, this approach avoids having to maintain the pbuilder base tarballs or sbuild chroots manually. It's all automatic, and up to date, for every build. Furthermore, the staging area contains only the specified build dependencies, and not anything else, meaning a build fails if a build dependency is missing, rather than succeeding because it happens to be in the default set of packages the build tool installs. Mass building shouldn't be hard Suppose you want to try out a large-scale change in Debian. It might be trying out a new version of GCC, or using llvm's clang as the default C compiler, or updating glibc, or doing a large library transition such as a new version of GTK+, or trying a new dpkg version, or even something more exploratory such as changing the default optimisation flags for all packages to see what breaks. All of these will require you to at least rebuild all affected packages. Ideally you'd test the built packages as well, but let's concentrate on the building for now. Here's what you do. You make the changes you want to try out, and build those packages. You create a dedicated APT repository, and upload your packages there. You configure your build environment to favour that APT repository. You make a list of all reverse build dependencies of the packages you changed. You write a script to build all of those, preferably so that if you change A, and rebuild B, then you also rebuild C which build depends on B. Each rebuilt package you also upload to your APT repository. You keep track of the build log, and success or failure, of each build. The people in Debian who do this kind of stuff regularly presumably have tools for doing it. It shouldn't be a rare, special thing, though. If my package has reverse build dependencies, I should at least consider testing building when I'm making changes. Otherwise, it might take years until the reverse build dependencies are rebuilt, and the problem is only found then, making it harder to fix. To be fair, building a lot of packages takes a lot of resources. It's not feasible to rebuild everything in Debian every time there's any change to, say, eglibc. However, it's feasible to do it, for large subsets of the archive, without huge hardware investments. One VCS to rule them all In 1995 there was really only one relevant version control system: CVS. It was not a great tool. In 2000, another contender existed: Subversion. It fixed some problems in CVS, but still wasn't a great tool. In 2005, there was a great upheaval and distributed version control systems started to become mainstream. There were a large handful of them. In 2010, it was becoming pretty clear that git had won. It's ugly, but it's powerful. I'm not going to debate the relative merits of different version control systems. Until recently, I was a Bazaar boy, and all of my personal projects were kept in Bazaar. (I have recently switched everything to git.) There are, however, strong benefits from everyone using the same system. Developers don't need to learn a dozen version control systems. Tools that operate on many repositories are easier to write and maintain. Workflows become simpler if one system can be assumed. Debian has a strong historical tendency to choose every option. This is sometimes a good thing, and sometimes a bad thing. For keeping source packages in version control I believe it is to be a bad thing. The status quo is that a Debian source package may not be in version control at all, or it might be in any version control system. This is acceptable when everyone only ever needs to maintain their own packages. However, in a distribution the size of Debian, that is not the case. NMUs, security support, archive wide transitions, and other situations arise when I might need to change yours, or you might need to change mine. We try to work around this by having a complicated source package format, using quilt to maintain patches to upstream semi-manually in a debian/patches directory. This is an awkward workflow. It's a workflow that trips up those that are not used to it. (I know quilt is a patch management system, not a version control system. I think git does it much better anyway.) It would be oh so much easier if everyone kept their source packages in the same, real version control system. I don't even care what it is, as long as it is powerful enough to handle the use cases we have. Imagine a world where every Debian source package is kept, for argument's sake, git, and everyone also uses the same layout and roughly the same workflow to maintain it. What would this mean? It would mean that if you want to inspect the history of your package, you know how to do that. If you want to merge in some bugfix from upstream code, you know how to do that, without having to figure out which of the several source package formats are in use. It would make feasible the development of more powerful, more higher level tooling. For example, it would allow Debian to have what we call system branches in Baserock. In Debian we have stable, testing, unstable, and experimental. We may get something like Ubuntu's PPAs, or perhaps an improved version of those. These are very poor versions of system branches, just like quilt is a poor way to manage patches and deltas against upstream. For example, you can upload an experimental version of gccto experimental, but then nobody else can upload another experimental version. You can set up your own PPA for this, but you'll still be affected by all the uploads to unstable while you're working. A Baserock system branch is a branch of the entire system, or the entire distribution in the case of Debian. It is isolated from other system branches. In branch in an individual repository is a well-known concept. A system branch is conceptually like branching every repository in the distribution at once. The actual implementation is more efficient, of course. This would be possible to implement without standardising on one version control system, but it would be much harder to implement, and would have to live with the lowest common denominator for features. CVS and Subversion, for example, don't really to merges, where Bazaar, Mercurial, and git do. Possible does not mean feasible. Any work you do in a system branch is isolated. Your work doesn't affect others, and theirs doesn't affect yours, until a merge happens. This is a simple, but very powerful tool. Cheap system branches, and powerful merging, makes it possible to do experiments safely, with little fuss. Combine that with being able to build everything cleanly and quickly, and get into a situation where there's no need to have make technical decisions based on arguments on mailing lists, and instead they can be done by choosing by looking at working code. I don't know how this could be implemented in Debian, but think about it. If Debian could have this, it might many archive-scale changes easier. debian/rules clean: really? One of the silliest things we require of packages is that they have a debian/rules clean rule that cleans up after a build perfectly so that we can do repeated builds in the same source tree. Let's just use git clean -fdx instead. This is a problem that is superbly well suited for automation. There is no point whatsover making packagers do any manual work for this. Large scale semi-mechanical changes require too much effort About a decade ago, we decided to follow a new version of the Filesystem Hierarchy Standard and transition from /usr/doc to /usr/share/doc. This was an almost entirely mechanical change: in many cases, a mere rebuild would fix it, and in almost every other case it was just a minor tweak to the packaging. A one-line change. It took us seven years to do this. Seven years. Think about it. In a recent discussion about building R binary data files from source at package build time it was suggested that we take 2-3 release cycles to get this done. That's four to six years. Think about it. These are not isolated cases. Every time we need to make a change that affects more than a small handful of packages, it becomes a major undertaking. Most of the time all the people involved in this are agreeable to the change, and welcome it. The change takes long because it requires co-ordinating a large number of people. Sometimes people are just busy. Sometimes they've left the project, but haven't properly orphaned their packages. Waiting for a timeout for answers about packages drags the process longer. Mechanical changes, or semi-mechanical ones, which are very easy and very quick to do should not take years. They should take an evening, no more. There's no end of changes we might want to do like this. In 2005 and 2006 I filed a few hundred bugs from failed piuparts runs. They're still being fixed, even when the fix is simple, such as adding a postrm script to remove, when the package is purged, a configuration file created by postinst, or starting the service with invoke-rc.d rather than running an init.d script directly. Mostly one-line changes. There's more mechanical changes that might happen. For example, changing the value of the VCS-Browser field when the Debian version control server changes domain names. It's not just about simple, mechanical changes, either. Transitions of important library packages, for example, which require changes to reverse dependencies due to a changed API are another source of pain. What should be a few evenings of build fixes can drag out to months of co-ordination. This is caused partly by technical issues, and partly due to social issues. The main social issue is that we have quite a strong ownership of packages, and NMUs are to be done carefully, and only in some cases. This is both good and bad, and I won't discuss that aspect now. The technical issues are that our tools are primarily intended for maintaining individual packages, rather than all of them together, making it harder to make even simple changes in large number of packages. In addition to easy mass building and system branches, as outlined above, large-scale changes would require testing tools so that you don't build the new package versions, but also test things automatically. Essentially, CI at the distribution level. Conclusion I've listed above a small variety of problems I see in the Debian development processes and tools. They're not the important part of this talk. The important part is that it we, the Debian developers, should look at our tools, and workflows, critically, and improve them when we can. Even small improvements are very useful, when they affect each of our twenty thousand source packages. The important change I argue for here is one in mindset, rather than any specific problem in any tool. We need a mindset of constant, incremental improvement for our tools.

15 November 2013

Rudy Godoy: New GPG Key 65F80A4D

A bit late but I ve created a new 4096 RSA GPG key. I ve published a transition document as well. I hope I can meet fellow Debian developers soon to get my new key signed. So, if you are in town (Arequipa, Peru) drop me an email!

Next.

Previous.