Search Results: "ron"

1 September 2017

Russ Allbery: Review: Regeneration

Review: Regeneration, by Julie E. Czerneda
Series: Species Imperative #3
Publisher: DAW
Copyright: 2006
ISBN: 0-7564-0345-6
Format: Hardcover
Pages: 543
This is the third book of the Species Imperative trilogy, and this is the type of trilogy that's telling a single story in three books. You don't want to read this out of order, and I'll have to be cautious about aspects of the plot to not spoil the earlier books. Mac is still recovering from the effects of the first two books of the series, but she's primarily worried about a deeply injured friend. Worse, that friend is struggling to explain or process what's happened, and the gaps in her memory and her very ability to explain may point at frightening, lingering risks to humanity. As much as she wants to, Mac can't give her friend all of her focus, since she's also integral to the team trying to understand the broader implications of the events of Migration. Worse, some of the non-human species have their own contrary interpretations that, if acted on, Mac believes would be desperately risky for humanity and all the other species reachable through the transects. That set of competing priorities and motivations eventually sort themselves out into a tense and rewarding multi-species story, but they get off to an awkward start. The first 150 pages of Regeneration are long on worry, uncertainty, dread, and cryptic conversations, and short on enjoyable reading. Czerneda's recaps of the previous books are appreciated, but they weren't very smoothly integrated into the story. (I renew my occasional request for series authors to include a simple plot summary of the previous books as a prefix, without trying to weave it into the fiction.) I was looking forward to this book after the excellent previous volumes, but struggled to get into the story. That does change. It takes a bit too long, with a bit too much nameless dread, a bit too much of an irritating subplot between Fourteen and Oversight that I didn't think added anything to the book, and not enough of Mac barreling forward doing sensible things. But once Mac gets back into space, with a destination and a job and a collection of suspicious (or arrogant) humans and almost-incomprehensible aliens to juggle, Czerneda hits her stride. Czerneda doesn't entirely avoid Planet of the Hats problems with her aliens, but I think she does better than most of science fiction. Alien species in this series do tend to be a bit all of a type, and Mac does figure them out by drawing conclusions from biology, but those conclusions are unobvious and based on Mac's mix of biological and human social intuition. They refreshingly aren't as simple as biology completely shaping culture. (Czerneda's touch is more subtle than James White's Sector General, for example.) And Mac has a practical, determined, and selfless approach that's deeply likable and admirable. It's fun as a reader to watch her win people over by just being competent, thoughtful, observant, and unrelentingly ethical. But the best part of this book, by far, are the Sinzi. They first appeared in the second book, Migration, and seemed to follow the common SF trope of a wise elder alien race that can bring some order to the universe and that humanity can learn from. They, or more precisely the one Sinzi who appeared in Migration, was very good at that role. But Czerneda had something far more interesting planned, and in Regeneration they become truly alien in their own right, with their own nearly incomprehensible way of viewing the universe. There are so many ways that this twist can go wrong, and Czerneda avoids all of them. She doesn't undermine their gravitas, nor does she elevate them to the level of Arisians or other semi-angelic wise mentors of other series. Czerneda makes them different in profound ways that are both advantage and disadvantage, pulls that difference into the plot as a complicating element, and has Mac stumble yet again into a role that is accidentally far more influential than she intends. Mac is the perfect character to do that to: she has just the right mix of embarrassment, ethics, seat-of-the-pants blunt negotiation skills, and a strong moral compass. Given a lever and a place to stand, one can believe that Mac can move the world, and the Sinzi are an absolutely fascinating lever. There are also three separate, highly differentiated Sinzi in this story, with different goals, life experience, personalities, and levels of gravitas. Czerneda's aliens are good in general, but her focus is usually more on biology than individual differentiation. The Sinzi here combine the best of both types of character building. I think the ending of Regeneration didn't entirely work. After all the intense effort the characters put into understanding the complexity of the universe over the course of the series, the denouement has a mopping-up feel and a moral clarity that felt a bit too easy. But the climax has everything I was hoping for, there's a lot more of Mac being Mac, and I loved every moment of the Sinzi twist. Now I want a whole new series exploring the implications of the Sinzi's view of the universe on the whole history of galactic politics that sat underneath this story. But I'll settle for moments of revelation that sent shivers down my spine. This is a bit of an uneven book that falls short of its potential, but I'll remember it for a long time. Add it on to a deeply rewarding series, and I will recommend the whole package unreservedly. The Species Imperative is excellent science fiction that should be better-known than it is. I still think the romance subplot was unfortunate, and occasionally the aliens get too cartoony (Fourteen, in particular, goes a bit too far in that direction), but Czerneda never lingers too long on those elements. And the whole work is some of the best writing about working scientific research and small-group politics that I've read. Highly recommended, but read the whole series in order. Rating: 9 out of 10

Dirk Eddelbuettel: RcppAnnoy 0.0.9

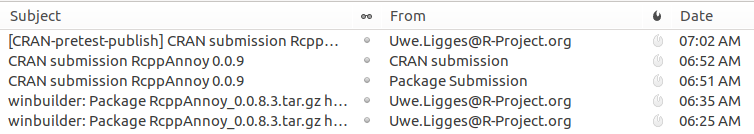
An new version 0.0.9 of RcppAnnoy, our Rcpp-based R integration of the nifty Annoy library by Erik, is now on CRAN. Annoy is a small and lightweight C++ template header library for very fast approximate nearest neighbours. This release corrects an issue for Windows users discovered by GitHub user 'khoran' who later also suggested the fix of binary mode. It upgrades to Annoy release 1.9.1 and brings its new Manhattan distance to RcppAnnoy. A number of unit tests were added as well, and we updated some packaging internals such as symbol registration. And I presume I had a good streak emailing with Uwe's robots as the package made it onto CRAN rather smoothly within ten minutes of submission:
RcppAnnou to CRAN
Changes in this version are summarized here:

Changes in version 0.0.9 (2017-08-31)
  • Synchronized with Annoy upstream version 1.9.1
  • Minor updates in calls and tests as required by annoy 1.9.1
  • New Manhattan distance modules along with unit test code
  • Additional unit tests from upstream test code carried over
  • Binary mode is used for save (as suggested by @khoran in #21)
  • A new file init.c was added with calls to R_registerRoutines() and R_useDynamicSymbols()
  • Symbol registration is enabled in useDynLib

Courtesy of CRANberries, there is also a diffstat report for this release.

This post by Dirk Eddelbuettel originated on his Thinking inside the box blog. Please report excessive re-aggregation in third-party for-profit settings.

31 August 2017

Paul Wise: FLOSS Activities August 2017

Changes

Issues

Review

Administration
  • myrepos: get commit/admin access from joeyh at DebConf17, add commit/admin access for other patch submitters, apply my stack of patches
  • Debian: fix weird log file issues, redirect hardware donor, cleaned up a weird dir, fix some OOB info, ask for TLS on meetings-archive.d.n, check an I/O error, restart broken stunnels, powercycle 1 borked machine,
  • Debian mentors: lintian/security updates & reboot
  • Debian wiki: remove some stray cache files, whitelist 3 email domains, whitelist some email addresses, disable 1 spammer account, disable 1 accounts with bouncing email,
  • Debian QA: apply patch to fix PTS watch file errors, deploy changes
  • Debian derivatives census: run scripts for Purism, remove some noise from logs, trigger a recheck, merge fix by Unit193, deploy changes
  • Openmoko: security updates, reboots, enable unattended-upgrades

Communication
  • Attended DebConf17 and provided some input in BoFs
  • Sent Misc Dev News #44
  • Invite Google gLinux (on IRC) to the Debian derivatives census
  • Welcome Sven Haardiek (of GreenboneOS) to the Debian derivatives census
  • Inquire about the status of Canaima

Sponsors The samba bug report was sponsored by my employer. All other work was done on a volunteer basis.

Chris Lamb: Free software activities in August 2017

Here is my monthly update covering what I have been doing in the free software world in August 2017 (previous month):
Reproducible builds

Whilst anyone can inspect the source code of free software for malicious flaws, most software is distributed pre-compiled to end users. The motivation behind the Reproducible Builds effort is to allow verification that no flaws have been introduced either maliciously or accidentally during this compilation process by promising identical results are always generated from a given source, thus allowing multiple third-parties to come to a consensus on whether a build was compromised. I have generously been awarded a grant from the Core Infrastructure Initiative to fund my work in this area. This month I:
  • Presented a status update at Debconf17 in Montr al, Canada alongside Holger Levsen, Maria Glukhova, Steven Chamberlain, Vagrant Cascadian, Valerie Young and Ximin Luo.
  • I worked on the following issues upstream:
    • glib2.0: Please make the output of gio-querymodules reproducible. (...)
    • gcab: Please make the output reproducible. (...)
    • gtk+2.0: Please make the immodules.cache files reproducible. (...)
    • desktop-file-utils: Please make the output reproducible. (...)
  • Within Debian:
  • Categorised a large number of packages and issues in the Reproducible Builds "notes" repository.
  • Worked on publishing our weekly reports. (#118, #119, #120, #121 & #122)

I also made the following changes to our tooling:
diffoscope

diffoscope is our in-depth and content-aware diff utility that can locate and diagnose reproducibility issues.

  • Use name attribute over path to avoid leaking comparison full path in output. (commit)
  • Add missing skip_unless_module_exists import. (commit)
  • Tidy diffoscope.progress and the XML comparator (commit, commit)

disorderfs

disorderfs is our FUSE-based filesystem that deliberately introduces non-determinism into directory system calls in order to flush out reproducibility issues.

  • Add a simple autopkgtest smoke test. (commit)


Debian
Patches contributed
  • openssh: Quote the IP address in ssh-keygen -f suggestions. (#872643)
  • libgfshare:
    • SIGSEGV if /dev/urandom is not accessible. (#873047)
    • Add bindnow hardening. (#872740)
    • Support nodoc build profile. (#872739)
  • devscripts:
  • memcached: Add hardening to systemd .service file. (#871610)
  • googler: Tidy long and short package descriptions. (#872461)
  • gnome-split: Homepage points to domain-parked website. (#873037)

Uploads
  • python-django 1:1.11.4-1 New upstream release.
  • redis:
    • 4:4.0.1-3 Drop yet more non-deterministic tests.
    • 4:4.0.1-4 Tighten systemd/seccomp hardening.
    • 4:4.0.1-5 Drop even more tests with timing issues.
    • 4:4.0.1-6 Don't install completions to /usr/share/bash-completion/completions/debian/bash_completion/.
    • 4:4.0.1-7 Don't let sentinel integration tests fail the build as they use too many timers to be meaningful. (#872075)
  • python-gflags 1.5.1-3 If SOURCE_DATE_EPOCH is set, either use that as a source of current dates or the UTC-version of the file's modification time (#836004), don't call update-alternatives --remove in postrm. update debian/watch/Homepage & refresh/tidy the packaging.
  • bfs 1.1.1-1 New upstream release, tidy autopkgtest & patches, organising the latter with Pq-Topic.
  • python-daiquiri 1.2.2-1 New upstream release, tidy autopkgtests & update travis.yml from travis.debian.net.
  • aptfs 2:0.10-2 Add upstream signing key, refer to /usr/share/common-licenses/GPL-3 in debian/copyright & tidy autopkgtests.
  • adminer 4.3.1-2 Add a simple autopkgtest & don't install the Selenium-based tests in the binary package.
  • zoneminder (1.30.4+dfsg-2) Prevent build failures with GCC 7 (#853717) & correct example /etc/fstab entries in README.Debian (#858673).

Finally, I reviewed and sponsored uploads of astral, inflection, more-itertools, trollius-redis & wolfssl.

Debian LTS

This month I have been paid to work 18 hours on Debian Long Term Support (LTS). In that time I did the following:
  • "Frontdesk" duties, triaging CVEs, etc.
  • Issued DLA 1049-1 for libsndfile preventing a remote denial of service attack.
  • Issued DLA 1052-1 against subversion to correct an arbitrary code execution vulnerability.
  • Issued DLA 1054-1 for the libgxps XML Paper Specification library to prevent a remote denial of service attack.
  • Issued DLA 1056-1 for cvs to prevent a command injection vulnerability.
  • Issued DLA 1059-1 for the strongswan VPN software to close a denial of service attack.

Debian bugs filed
  • wget: Please hash the hostname in ~/.wget-hsts files. (#870813)
  • debian-policy: Clarify whether mailing lists in Maintainers/Uploaders may be moderated. (#871534)
  • git-buildpackage: "pq export" discards text within square brackets. (#872354)
  • qa.debian.org: Escape HTML in debcheck before outputting. (#872646)
  • pristine-tar: Enable multithreaded compression in pristine-xz. (#873229)
  • tryton-meta: Please combine tryton-modules-* into a single source package with multiple binaries. (#873042)
  • azure-cli:
  • fwupd-tests: Don't ship test files to generic /usr/share/installed-tests dir. (#872458)
  • libvorbis: Maintainer fields points to a moderated mailing list. (#871258)
  • rmlint-gui: Ship a rmlint-gui binary. (#872162)
  • template-glib: debian/copyright references online source without quotation. (#873619)

FTP Team

As a Debian FTP assistant I ACCEPTed 147 packages: abiword, adacgi, adasockets, ahven, animal-sniffer, astral, astroidmail, at-at-clojure, audacious, backdoor-factory, bdfproxy, binutils, blag-fortune, bluez-qt, cheshire-clojure, core-match-clojure, core-memoize-clojure, cypari2, data-priority-map-clojure, debian-edu, debian-multimedia, deepin-gettext-tools, dehydrated-hook-ddns-tsig, diceware, dtksettings, emacs-ivy, farbfeld, gcc-7-cross-ports, git-lfs, glewlwyd, gnome-recipes, gnome-shell-extension-tilix-dropdown, gnupg2, golang-github-aliyun-aliyun-oss-go-sdk, golang-github-approvals-go-approval-tests, golang-github-cheekybits-is, golang-github-chzyer-readline, golang-github-denverdino-aliyungo, golang-github-glendc-gopher-json, golang-github-gophercloud-gophercloud, golang-github-hashicorp-go-rootcerts, golang-github-matryer-try, golang-github-opentracing-contrib-go-stdlib, golang-github-opentracing-opentracing-go, golang-github-tdewolff-buffer, golang-github-tdewolff-minify, golang-github-tdewolff-parse, golang-github-tdewolff-strconv, golang-github-tdewolff-test, golang-gopkg-go-playground-validator.v8, gprbuild, gsl, gtts, hunspell-dz, hyperlink, importmagic, inflection, insighttoolkit4, isa-support, jaraco.itertools, java-classpath-clojure, java-jmx-clojure, jellyfish1, lazymap-clojure, libblockdev, libbytesize, libconfig-zomg-perl, libdazzle, libglvnd, libjs-emojify, libjwt, libmysofa, libundead, linux, lua-mode, math-combinatorics-clojure, math-numeric-tower-clojure, mediagoblin, medley-clojure, more-itertools, mozjs52, openssh-ssh1, org-mode, oysttyer, pcscada, pgsphere, poppler, puppetdb, py3status, pycryptodome, pysha3, python-cliapp, python-coloredlogs, python-consul, python-deprecation, python-django-celery-results, python-dropbox, python-fswrap, python-hbmqtt, python-intbitset, python-meshio, python-parameterized, python-pgpy, python-py-zipkin, python-pymeasure, python-thriftpy, python-tinyrpc, python-udatetime, python-wither, python-xapp, pythonqt, r-cran-bit, r-cran-bit64, r-cran-blob, r-cran-lmertest, r-cran-quantmod, r-cran-ttr, racket-mode, restorecond, rss-bridge, ruby-declarative, ruby-declarative-option, ruby-errbase, ruby-google-api-client, ruby-rash-alt, ruby-representable, ruby-test-xml, ruby-uber, sambamba, semodule-utils, shimdandy, sjacket-clojure, soapysdr, stencil-clojure, swath, template-glib, tools-analyzer-jvm-clojure, tools-namespace-clojure, uim, util-linux, vim-airline, vim-airline-themes, volume-key, wget2, xchat, xfce4-eyes-plugin & xorg-gtest. I additionally filed 6 RC bugs against packages that had incomplete debian/copyright files against: gnome-recipes, golang-1.9, libdazzle, poppler, python-py-zipkin & template-glib.

30 August 2017

Dirk Eddelbuettel: RcppArmadillo 0.7.960.1.2

armadillo image A second fix-up release is needed following on the recent bi-monthly RcppArmadillo release as well as the initial follow-up as it turns out that OS X / macOS is so darn special that it needs an entire separate treatment for OpenMP. Namely to turn it off entirely... Armadillo is a powerful and expressive C++ template library for linear algebra aiming towards a good balance between speed and ease of use with a syntax deliberately close to a Matlab. RcppArmadillo integrates this library with the R environment and language--and is widely used by (currently) 384 other packages on CRAN---an increase of 54 since the CRAN release in June!

Changes in RcppArmadillo version 0.7.960.1.2 (2017-08-29)
  • On macOS, OpenMP support is now turned off (#170).
  • The package is now compiling under the C++11 standard (#170).
  • The vignette dependency is correctly set (James and Dirk in #168 and #169)

Courtesy of CRANberries, there is a diffstat report. More detailed information is on the RcppArmadillo page. Questions, comments etc should go to the rcpp-devel mailing list off the R-Forge page.

This post by Dirk Eddelbuettel originated on his Thinking inside the box blog. Please report excessive re-aggregation in third-party for-profit settings.

29 August 2017

Colin Watson: env chdir

I was recently asked to sort things out so that snap builds on Launchpad could themselves install snaps as build-dependencies. To make this work we need to start doing builds in LXD containers rather than in chroots. As a result I ve been doing some quite extensive refactoring of launchpad-buildd: it previously had the assumption that it was going to use a chroot for everything baked into lots of untested helper shell scripts, and I ve been rewriting those in Python with unit tests and with a single Backend abstraction that isolates the high-level logic from the details of where each build is being performed. This is all interesting work in its own right, but it s not what I want to talk about here. While I was doing all this refactoring, I ran across a couple of methods I wrote a while back which looked something like this:
def chroot(self, args, echo=False):
    """Run a command in the chroot.
    :param args: the command and arguments to run.
    """
    args = set_personality(
        args, self.options.arch, series=self.options.series)
    if echo:
        print("Running in chroot: %s" %
              ' '.join("'%s'" % arg for arg in args))
        sys.stdout.flush()
    subprocess.check_call([
        "/usr/bin/sudo", "/usr/sbin/chroot", self.chroot_path] + args)
def run_build_command(self, args, env=None, echo=False):
    """Run a build command in the chroot.
    This is unpleasant because we need to run it in /build under sudo
    chroot, and there's no way to do this without either a helper
    program in the chroot or unpleasant quoting.  We go for the
    unpleasant quoting.
    :param args: the command and arguments to run.
    :param env: dictionary of additional environment variables to set.
    """
    args = [shell_escape(arg) for arg in args]
    if env:
        args = ["env"] + [
            "%s=%s" % (key, shell_escape(value))
            for key, value in env.items()] + args
    command = "cd /build && %s" % " ".join(args)
    self.chroot(["/bin/sh", "-c", command], echo=echo)
(I ve already replaced the chroot method with a call to Backend.run, but it s easier to see what I m talking about in the original form.) One thing to notice about this code is that it uses several adverbial commands: that is, commands that run another command in a different way. For example, sudo runs another command as another user, while chroot runs another command with a different root directory, and env runs another command with different environment variables set. These commands chain neatly, and they also have the useful property that they take the subsidiary command and its arguments as a list of arguments. coreutils has several other commands that behave this way, and adverbio is another useful example. By contrast, su -c is something you might call a quasi-adverbial command: it does modify the behaviour of another command, but it takes it as a single argument which it then passes to sh -c. Every time you have something that s passed to a shell like this, you need a corresponding layer of shell quoting to escape any shell metacharacters that should be interpreted literally. This is often cumbersome and is easy to get wrong. My Python implementation is as follows, and I wouldn t be totally surprised to discover that it contained a bug:
import re
non_meta_re = re.compile(r'^[a-zA-Z0-9+,./:=@_-]+$')
def shell_escape(arg):
    if non_meta_re.match(arg):
        return arg
    else:
        return "'%s'" % arg.replace("'", "'\\''")
Python >= 3.3 has shlex.quote, which is an improvement and we should probably use that instead, but it s still another thing to forget to call. This is why process-spawning libraries such as Python s subprocess, Perl s system and open, and my own libpipeline for C encourage programmers to use a list syntax and to avoid involving the shell entirely wherever possible. One thing that the standard Unix tools don t let you do in an adverbial way is to change your working directory, and I ve run into this annoying limitation several times. This means that it s difficult to chain that operation together with other adverbs, for example to run a command in a particular working directory inside a chroot. The workaround I used above was to invoke a shell that runs cd /build && ..., but that s another command that s only quasi-adverbial, since the extra shell means an extra layer of shell quoting. (Ian Jackson rightly observes that you can in fact write the necessary adverb as something like sh -ec 'cd "$1"; shift; exec "$@"' chdir. I think that s a bit uglier than I ideally want to use in production code, but you might reasonably think that it s worth it to avoid the extra layer of shell quoting.) I therefore decided that this was a feature that belonged in coreutils, and after a bit of mailing list discussion we felt it was best implemented as a new option to env(1). I sent a patch for this which has been accepted. This means that we have a new composable adverb, env --chdir=NEWDIR, which will allow the run_build_command method above to be rewritten as something like this:
def run_build_command(self, args, env=None, echo=False):
    """Run a build command in the chroot.
    :param args: the command and arguments to run.
    :param env: dictionary of additional environment variables to set.
    """
    env_args = ["env", "--chdir=/build"]
    if env:
        for key, value in env.items():
            env_args.append("%s=%s" % (key, value))
    self.chroot(env_args + args, echo=echo)
The env --chdir option will be in coreutils 8.28. We won t be able to use it in launchpad-buildd until that s available in all Ubuntu series we might want to build for, so in this particular application that s going to take a few years; but other applications may well be able to make use of it sooner.

Carl Chenet: Send scheduled messages to both Twitter and Mastodon with the Remindr bot

Do you need to send messages to both Twitter and Mastodon? Use the Remindr bot! Remindr is written in Python, released under the GPLv3 license. 1. How to install Remindr Install Remindr from PyPI:
# pip3 install remindr
2. How to configure Remindr First, start by writing a messages.txt file with the following content:
o en Send scheduled messages to both Twitter and Mastodon with the Remindr bot https://carlchenet.com/send-scheduled-messages-to-both-twitter-and-mastodon-with-the-remindr-bot #remindr #twitter #mastodon
x en Follow Carl Chenet for great news about Free Software! https://carlchenet.com #freesoftware
The first field only indicates if the line is the next one to be considered by Remindr, the o indicates the next line to be sent, x means it won t. The second field is the 2-letters code language your content is using, in my example en or fr. Next content on the line will compose the body of your messages to Mastodon and Twitter. You need to configure the Mastodon and the Twitter credentials in order to allow Remindr to send the messages. First you need to generate the credentials. For Twitter, you need to manually create an app on apps.twitter.com. For Mastodon, just launch the following command:
$ register_remindr_app
Some information will be asked by the command. At the end, two files are created, remindr_usercred.txt and remindr_clientcred.txt. You re going to need them for the Remindr configuration above. For the Remindr configuration, here is a complete configuration using the
[mastodon]
instance_url=https://mastodon.social
user_credentials=remindr_usercred.txt
client_credentials=remindr_clientcred.txt
[twitter]
consumer_key=a6lv2gZxkvk6UbQ30N4vFmlwP
consumer_secret=j4VxM2slv0Ud4rbgZeGbBzPG1zoauBGLiUMOX0MGF6nsjcyn4a
access_token=1234567897-Npq5fYybhacYxnTqb42Kbb3A0bKgmB3wm2hGczB
access_token_secret=HU1sjUif010DkcQ3SmUAdObAST14dZvZpuuWxGAV0xFnC
[image]
path_to_image=/home/chaica/blog-carl-chenet.png
[entrylist]
path_to_list=/etc/remindr/messages.txt
Your configuration is complete! Now we have to check if everything is fine.

Read the full documentation on Readthedocs.

3. How to use Remindr Now let s try your configuration by launching Remindr the first time by-hand:
$ remindr -c /etc/remindr/remindr.ini
The messages should appear on both Twitter and Mastodon. 4. How to schedule the Remindr execution The easiest way is to use you user crontab. Just add the following line in your crontab file, editing it with crontab -e
00 10 * * * remindr -c /etc/remindr/remindr.ini
From now on, your message will be sent every day at 10:00AM. Going further with Remindr and finally You can help me developing tools for Mastodon and other social networks by donating anything through Liberaypay (also possible with cryptocurrencies). Any contribution will be appreciated. That s a big factor motivation
Donate You also may follow my account @carlchenet on Mastodon

27 August 2017

Carl Chenet: The Importance of Choosing the Correct Mastodon Instance

Remember, Mastodon is a new decentralized social network, based on a free software which is rapidly gaining users (already there is more than 1.5 million accounts). As I ve created my account in June, I was a fast addict and I ve already created several tools for this network, Feed2toot, Remindr and Boost (mostly written in Python).

Now, with all this experience I have to stress out the importance of choosing the correct Mastodon instance.

Some technical reminders on how Mastodon works

First, let s quickly clarify something about the decentralized part. In Mastodon, decentralization is made through a federation of dedicated servers, called instances , each one with a complete independent administration. Your user account is created on one specific instance. You have two choices:

  • Create your own instance. Which requires advanced technical knowledge.
  • Create your user account on a public instance. Which is the easiest and fastest way to start using Mastodon.

You can move your user account from one instance to another, but you have to follow a special procedure which can be quite long, considering your own interest for technical manipulation and the total amount of your followers you ll have to warn about your change. As such, you ll have to create another account on a new instance and import three lists: the one with your followers, the one with the accounts you have blocked, and the one with the account you have muted.

From this working process, several technical and human factors will interest us.

A good technical administration for instance

As a social network, Mastodon is truly decentralized, with more than 1.5 million users on more than 2350 existing instances. As such, the most common usage is to create an account on an open instance. To create its own instance is way too difficult for the average user. Yet, using an open instance creates a strong dependence on the technical administrator of the chosen instance.

The technical administrator will have to deal with several obligations to ensure its service continuity, with high-quality hardware and regular back-ups. All of these have a price, either in money and in time. Regarding the time factor, it would be better to choose an administration team over an individual, as life events can change quite fast everyone s interests. As such, Framasoft, a French association dedicated to promoting the Free software use, offers its own Mastodon instance named: Framapiaf. The creator of the mastodon project, also offers a quite solid instance, Mastodon.social (see below).

Regarding the money factor, many instance administrators with a large number of users are currently asking for donation via Patreon, as hosting an instance server or renting one cost money.

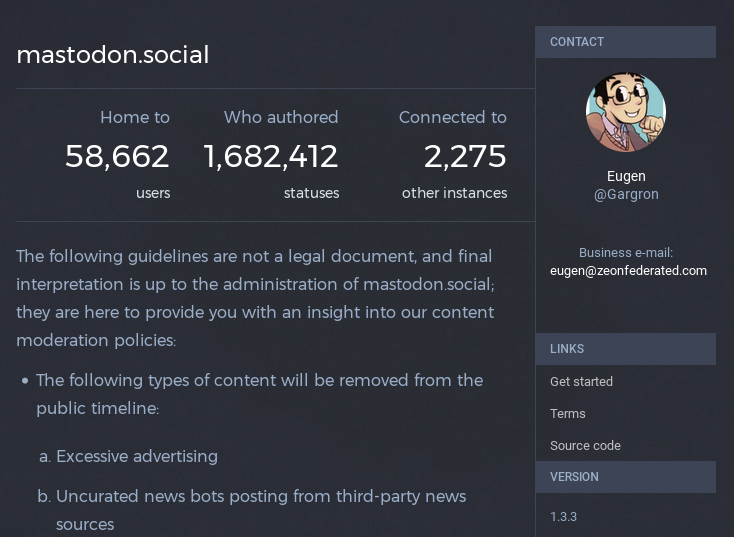
Mastodon.social, the first instance of the Mastodon network

The Ideological Trend Of Your Instance

If anybody could have guessed the previous technical points since the recent registration explosion on the Mastodon social network, the following point took almost everyone by surprise. Little by little, different instances show their culture , their protest action, and their propaganda on this social network.

As the instance administrator has all the powers over its instance, he or she can block the instance of interacting with some other instances, or ban its instance s users from any interaction with other instances users.

With everyone having in mind the main advantages to have federalized instance from, this partial independence of some instances from the federation was a huge surprise. One of the most recent example was when the Unixcorn.xyz instance administrator banned its users from reading Aeris account, which was on its own instance. It was a cataclysm with several consequences, which I ve named the #AerisGate as it shows the different views on moderation and on its reception by various Mastodon users.

If you don t manage your own instance, when you ll have to choose the one where to create your account, make sure that the content you plan to toot is within the rules and compatible with the ideology of said instance s administrator. Yes, I know, it may seem surprising but, as stated above, by entering a public instance you become dependent on someone else s infrastructure, who may have an ideological way to conceive its Mastodon hosting service. As such, if you re a nazi, for example, don t open your Mastodon account on a far-left LGBT instance. Your account wouldn t stay open for long.

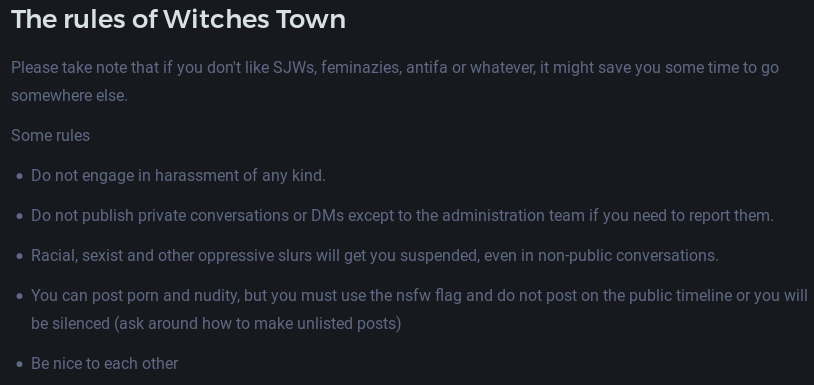
The moderation rules are described in the about/more page of the instance, and may contain ideological elements.

To ease the process for newcomers, it is now possible to use a great tool to select what instance should be the best to host your account.

Remember that, as stated above, Mastodon is decentralized, and as such there is no central authority which can be reached in case you have a conflict with your instance administrator. And nobody can force said administrator to follow its own rules, or not to change them on the fly. Think Twice Before Creating Your Account

If you want to create an account on an instance you don t control, you need to check two elements: the availability of the instance hosting service in the long run, often linked to the administrator or the administration group of said instance, and the ideological orientation of your instance. With these two elements checked, you ll be able to let your Mastodon account growth peacefully, without fearing an outage of your instance, or simple your account blocked one morning because it doesn t align with your instance s ideological line.

in Conclusion

To help me get involved in free software and writing articles for this blog, please consider a donation through my Liberapay page, even if it s only a few cents per week. My contact Bitcoin and Monero are also available on this page. Follow me on Mastodon Translated from French to English by St phanie Chaptal.

Evgeni Golov: starting the correct Chromium profile when opening links from IRC

I am using Chromium/Chrome as my main browser and I also use its profile/people feature to separate my work profile (bookmarks, cookies, etc) from my private one. However, Chromium always opens links in the last window (and by that profile) that was in foreground last. And that is pretty much not what I want. Especially if I open a link from IRC and it might lead to some shady rick-roll page. Thankfully, getting the list of available Chromium profiles is pretty easy and so is displaying a few buttons using Python. To do so I wrote cadmium, which scans the available Chromium profiles and allows to start either of them, or Chromium's Incognito Mode. On machines with SELinux it can even launch Chromium in the SELinux sandbox. No more links opened in the wrong profile. Yay!

Holger Levsen: 20170827-coreboot-build-environment

setting up a coreboot build environment, including an Ada compiler So without much explaination, this is how lynxis told me how to setup a coreboot build environment, which contains an Ada compiler which is needed to build the free graphics initialisation for Intel cards (=so no binary VGA bios blob is needed). The Ada compiler is build automatically by default if it's build depends are installed:
sudo apt install build-essential bison flex zlib1g-dev ncurses-dev gnat
git clone --recursive https://review.coreboot.org/p/coreboot.git
cd coreboot/
git submodule update --init --checkout 3rdparty/blobs   # for the x230 this only contains microcode updates
make iasl CPUS=$(nproc)
make gnumake CPUS=$(nproc)
make crossgcc-i386 CPUS=$(nproc)
coreboot is then build as usual:
make menuconfig
make
That's it. (I've just left out the steps to choose the coreboot revision and validating it, as well as choosing a configurationwith make menuconfig as this is better documented elsewhere.)

25 August 2017

Steve Kemp: Interesting times debugging puppet

I recently upgraded a bunch of systems from Jessie to Stretch, and as a result of that one of my hosts has started showing me a lot of noise in an hourly cron-email:
Command line is not complete. Try option "help"
I've been ignoring these emails for the past while, but today I sat down to track down the source. It was obviously coming from facter, the system that puppet uses to gather information about hosts. Running facter -debug made that apparent:
 root@smaug ~ # facter --debug
 Found no suitable resolves of 1 for ec2_metadata
 value for ec2_metadata is still nil
 value for netmask_git is still nil
 value for ipaddress6_lo is still nil
 value for macaddress_lo is still nil
 value for ipaddress_master is still nil
 value for ipaddress6_master is still nil
 Command line is not complete. Try option "help"
 value for netmask_master is still nil
 value for ipaddress_skx_mail is still nil
 ..
There we see the issue, and it is obviously relating to our master interface. To cut a long-story short /usr/lib/ruby/vendor_ruby/facter/util/ip.rb contains some code which eventually runs this:
 ip link show $interface
That works on all other interfaces I have:
  $ ip link show git
  6: git: <BROADCAST,MULTICAST,UP,LOWER_UP> mtu 1500 qdisc pfifo_fast state UNKNOWN mode DEFAULT group default qlen 1000
But not on master:
  $ ip link show master
  Command line is not complete. Try option "help"
I ninja-edited the code from this:
  ethbond = regex.match(%x /sbin/ip link show '# interface ' )
to:
  ethbond = regex.match(%x /sbin/ip link show dev '# interface ' )
And suddenly puppet-runs without any errors. I'm not 100% sure if this is a bug bug, but it is something of a surprise anyway.
This host runs KVM guests, one of the guests is a puppet-master, with a local name master. Hence the name of the interface. Similarly the interface git is associated with the KVM guest behind git.steve.org.uk.

Reproducible builds folks: Reproducible Builds: Weekly report #121

Here's what happened in the Reproducible Builds effort between Sunday August 13 and Saturday August 19 2017: Reproducible Builds finally mandated by Debian Policy "Packages should build reproducibly" was merged into Debian policy! The added text is as follows and has been included into debian-policy 4.1.0.0:
Reproducibility
---------------
Packages should build reproducibly, which for the purposes of this
document [#]_ means that given
- a version of a source package unpacked at a given path;
- a set of versions of installed build dependencies;
- a set of environment variable values;
- a build architecture; and
- a host architecture,
repeatedly building the source package for the build architecture on
any machine of the host architecture with those versions of the build
dependencies installed and exactly those environment variable values
set will produce bit-for-bit identical binary packages.
It is recommended that packages produce bit-for-bit identical binaries
even if most environment variables and build paths are varied.  It is
intended for this stricter standard to replace the above when it is
easier for packages to meet it.
.. [#]
   This is Debian's precisification of the  reproducible-builds.org
   definition  _.
Reproducible work in other projects Bernhard M. Wiedemann's reproducibleopensuse scripts now work on Debian buster on the openSUSE Build Service with the latest versions of osc and obs-build. Toolchain development and fixes #872514 was opened on devscripts by Chris Lamb to add a reproducible-check program to report on the reproducibility status of installed packages. Packages reviewed and fixed, and bugs filed Upstream reports: Debian reports: Debian non-maintainer uploads: Reviews of unreproducible packages 47 package reviews have been added, 58 have been updated and 39 have been removed in this week, adding to our knowledge about identified issues. 4 issue types have been updated: Weekly QA work During our reproducibility testing, FTBFS bugs have been detected and reported by: diffoscope development Development continued in git, including the following contributions: disorderfs development Development continued in git, including the following contributions: reprotest development Development continued in git, including the following contributions: tests.reproducible-builds.org Mattia fixed the script which creates the HTML representation of our database scheme to not append .html twice to the filename. Misc. This week's edition was written by Ximin Luo, Chris Lamb and Holger Levsen & reviewed by a bunch of Reproducible Builds folks on IRC & the mailing lists.

23 August 2017

Antoine Beaupr : The supposed decline of copyleft

At DebConf17, John Sullivan, the executive director of the FSF, gave a talk on the supposed decline of the use of copyleft licenses use free-software projects. In his presentation, Sullivan questioned the notion that permissive licenses, like the BSD or MIT licenses, are gaining ground at the expense of the traditionally dominant copyleft licenses from the FSF. While there does seem to be a rise in the use of permissive licenses, in general, there are several possible explanations for the phenomenon.

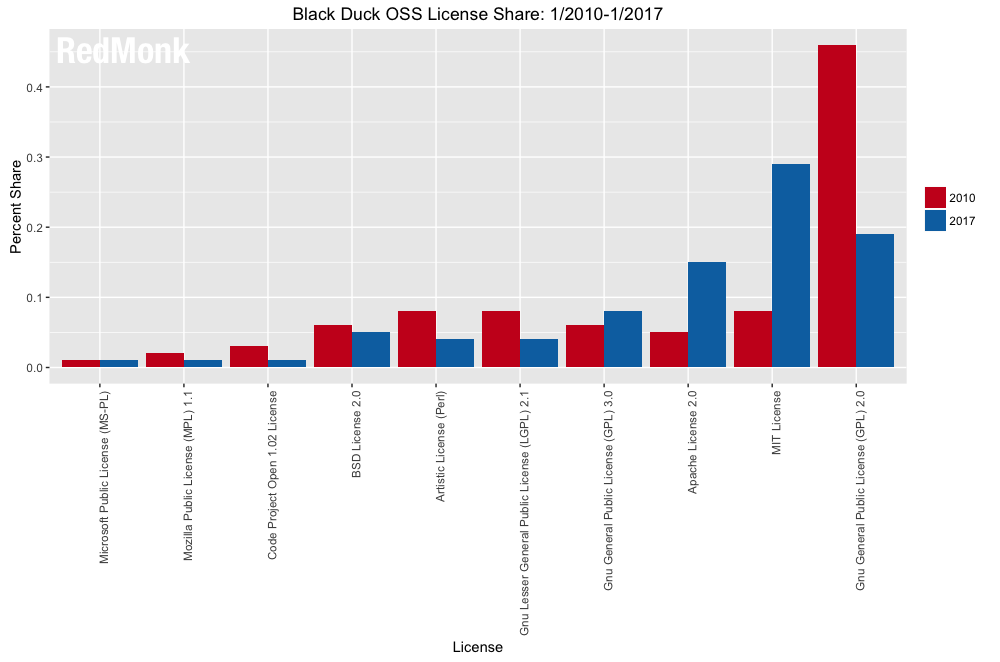
When the rumor mill starts Sullivan gave a recent example of the claim of the decline of copyleft in an article on Opensource.com by Jono Bacon from February 2017 that showed a histogram of license usage between 2010 and 2017 (seen below).
[Black Duck   histogram]
From that, Bacon elaborates possible reasons for the apparent decline of the GPL. The graphic used in the article was actually generated by Stephen O'Grady in a January article, The State Of Open Source Licensing, which said:
In Black Duck's sample, the most popular variant of the GPL version 2 is less than half as popular as it was (46% to 19%). Over the same span, the permissive MIT has gone from 8% share to 29%, while its permissive cousin the Apache License 2.0 jumped from 5% to 15%.
Sullivan, however, argued that the methodology used to create both articles was problematic. Neither contains original research: the graphs actually come from the Black Duck Software "KnowledgeBase" data, which was partly created from the old Ohloh web site now known as Open Hub. To show one problem with the data, Sullivan mentioned two free-software projects, GNU Bash and GNU Emacs, that had been showcased on the front page of Ohloh.net in 2012. On the site, Bash was (and still is) listed as GPLv2+, whereas it changed to GPLv3 in 2011. He also claimed that "Emacs was listed as licensed under GPLv3-only, which is a license Emacs has never had in its history", although I wasn't able to verify that information from the Internet archive. Basically, according to Sullivan, "the two projects featured on the front page of a site that was using [the Black Duck] data set were wrong". This, in turn, seriously brings into question the quality of the data:
I reported this problem and we'll continue to do that but when someone is not sharing the data set that they're using for other people to evaluate it and we see glimpses of it which are incorrect, that should give us a lot of hesitation about accepting any conclusion that comes out of it.
Reproducible observations are necessary to the establishment of solid theories in science. Sullivan didn't try to contact Black Duck to get access to the database, because he assumed (rightly, as it turned out) that he would need to "pay for the data under terms that forbid you to share that information with anybody else". So I wrote Black Duck myself to confirm this information. In an email interview, Patrick Carey from Black Duck confirmed its data set is proprietary. He believes, however, that through a "combination of human and automated techniques", Black Duck is "highly confident at the accuracy and completeness of the data in the KnowledgeBase". He did point out, however, that "the way we track the data may not necessarily be optimal for answering the question on license use trend" as "that would entail examination of new open source projects coming into existence each year and the licenses used by them". In other words, even according to Black Duck, its database may not be useful to establish the conclusions drawn by those articles. Carey did agree with those conclusions intuitively, however, saying that "there seems to be a shift toward Apache and MIT licenses in new projects, though I don't have data to back that up". He suggested that "an effective way to answer the trend question would be to analyze the new projects on GitHub over the last 5-10 years." Carey also suggested that "GitHub has become so dominant over the recent years that just looking at projects on GitHub would give you a reasonable sampling from which to draw conclusions".
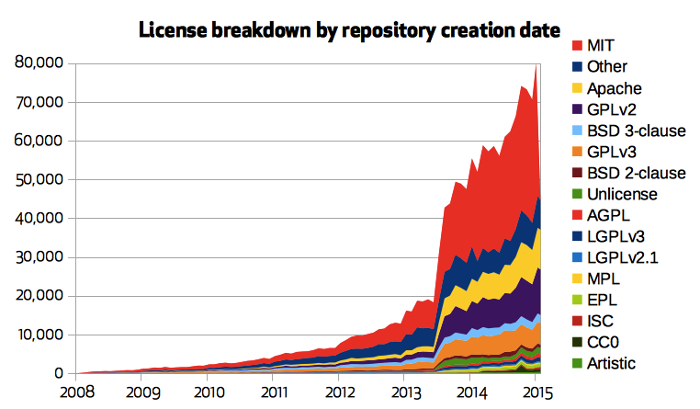
[GitHub   graph]
Indeed, GitHub published a report in 2015 that also seems to confirm MIT's popularity (45%), surpassing copyleft licenses (24%). The data is, however, not without its own limitations. For example, in the above graph going back to the inception of GitHub in 2008, we see a rather abnormal spike in 2013, which seems to correlate with the launch of the choosealicense.com site, described by GitHub as "our first pass at making open source licensing on GitHub easier". In his talk, Sullivan was critical of the initial version of the site which he described as biased toward permissive licenses. Because the GitHub project creation page links to the site, Sullivan explained that the site's bias could have actually influenced GitHub users' license choices. Following a talk from Sullivan at FOSDEM 2016, GitHub addressed the problem later that year by rewording parts of the front page to be more accurate, but that any change in license choice obviously doesn't show in the report produced in 2015 and won't affect choices users have already made. Therefore, there can be reasonable doubts that GitHub's subset of software projects may not actually be that representative of the larger free-software community.

In search of solid evidence So it seems we are missing good, reproducible results to confirm or dispel these claims. Sullivan explained that it is a difficult problem, if only in the way you select which projects to analyze: the impact of a MIT-licensed personal wiki will obviously be vastly different from, say, a GPL-licensed C compiler or kernel. We may want to distinguish between active and inactive projects. Then there is the problem of code duplication, both across publication platforms (a project may be published on GitHub and SourceForge for example) but also across projects (code may be copy-pasted between projects). We should think about how to evaluate the license of a given project: different files in the same code base regularly have different licenses often none at all. This is why having a clear, documented and publicly available data set and methodology is critical. Without this, the assumptions made are not clear and it is unreasonable to draw certain conclusions from the results. It turns out that some researchers did that kind of open research in 2016 in a paper called "The Debsources Dataset: Two Decades of Free and Open Source Software" [PDF] by Matthieu Caneill, Daniel M. Germ n, and Stefano Zacchiroli. The Debsources data set is the complete Debian source code that covers a large history of the Debian project and therefore includes thousands of free-software projects of different origins. According to the paper:
The long history of Debian creates a perfect subject to evaluate how FOSS licenses use has evolved over time, and the popularity of licenses currently in use.
Sullivan argued that the Debsources data set is interesting because of its quality: every package in Debian has been reviewed by multiple humans, including the original packager, but also by the FTP masters to ensure that the distribution can legally redistribute the software. The existence of a package in Debian provides a minimal "proof of use": unmaintained packages get removed from Debian on a regular basis and the mere fact that a piece of software gets packaged in Debian means at least some users found it important enough to work on packaging it. Debian packagers make specific efforts to avoid code duplication between packages in order to ease security maintenance. The data set covers a period longer than Black Duck's or GitHub's, as it goes all the way back to the Hamm 2.0 release in 1998. The data and how to reproduce it are freely available under a CC BY-SA 4.0 license.
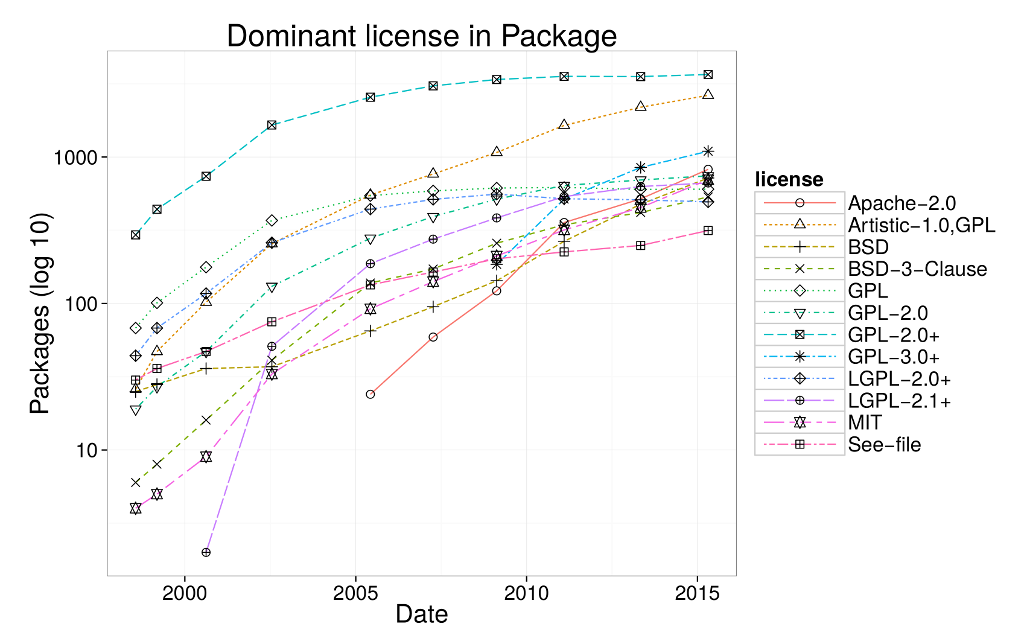
[Debsource   graph]
Sullivan presented the above graph from the research paper that showed the evolution of software license use in the Debian archive. Whereas previous graphs showed statistics in percentages, this one showed actual absolute numbers, where we can't actually distinguish a decline in copyleft licenses. To quote the paper again:
The top license is, once again, GPL-2.0+, followed by: Artistic-1.0/GPL dual-licensing (the licensing choice of Perl and most Perl libraries), GPL-3.0+, and Apache-2.0.
Indeed, looking at the graph, at most do we see a rise of the Apache and MIT licenses and no decline of the GPL per se, although its adoption does seem to slow down in recent years. We should also mention the possibility that Debian's data set has the opposite bias: toward GPL software. The Debian project is culturally quite different from the GitHub community and even the larger free-software ecosystem, naturally, which could explain the disparity in the results. We can only hope a similar analysis can be performed on the much larger Software Heritage data set eventually, which may give more representative results. The paper acknowledges this problem:
Debian is likely representative of enterprise use of FOSS as a base operating system, where stable, long-term and seldomly updated software products are desirable. Conversely Debian is unlikely representative of more dynamic FOSS environments (e.g., modern Web-development with micro libraries) where users, who are usually developers themselves, expect to receive library updates on a daily basis.
The Debsources research also shares methodology limitations with Black Duck: while Debian packages are reviewed before uploading and we can rely on the copyright information provided by Debian maintainers, the research also relies on automated tools (specifically FOSSology) to retrieve license information. Sullivan also warned against "ascribing reason to numbers": people may have different reasons for choosing a particular license. Developers may choose the MIT license because it has fewer words, for compatibility reasons, or simply because "their lawyers told them to". It may not imply an actual deliberate philosophical or ideological choice. Finally, he brought up the theory that the rise of non-copyleft licenses isn't necessarily at the detriment of the GPL. He explained that, even if there is an actual decline, it may not be much of a problem if there is an overall growth of free software to the detriment of proprietary software. He reminded the audience that non-copyleft licenses are still free software, according to the FSF and the Debian Free Software Guidelines, so their rise is still a positive outcome. Even if the GPL is a better tool to accomplish the goal of a free-software world, we can all acknowledge that the conversion of proprietary software to more permissive and certainly simpler licenses is definitely heading in the right direction.
[I would like to thank the DebConf organizers for providing meals for me during the conference.] Note: this article first appeared in the Linux Weekly News.

22 August 2017

John Goerzen: The Eclipse

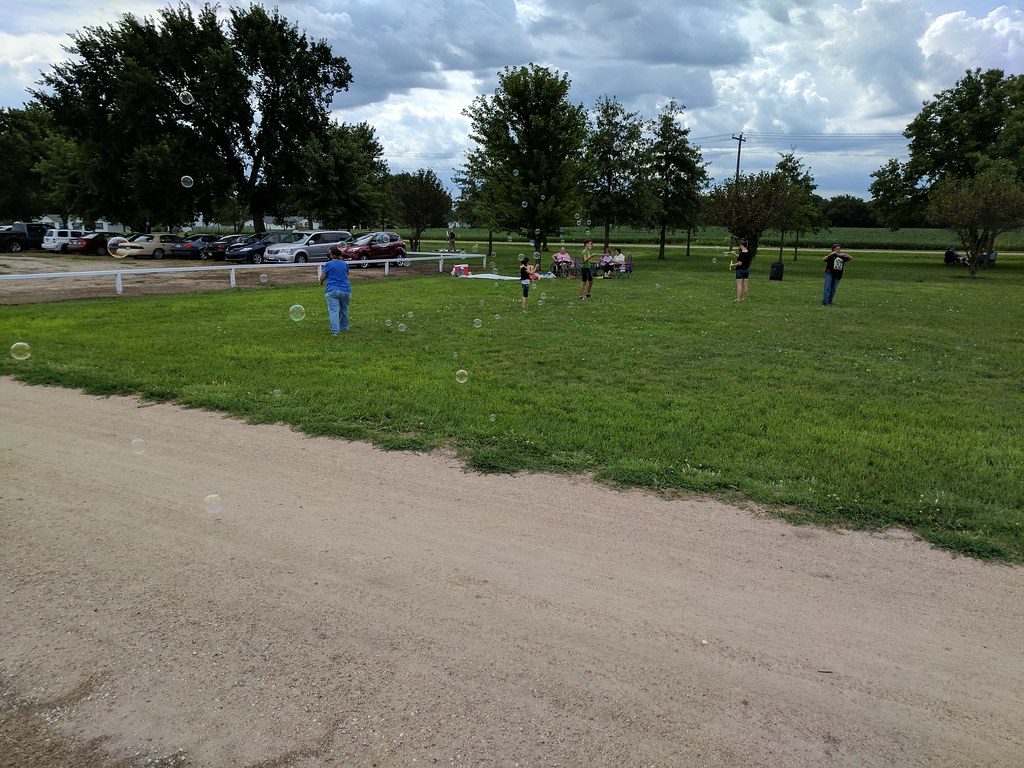
Highway US-81 in northern Kansas and southern Nebraska is normally a pleasant, sleepy sort of drive. It was upgraded to a 4-lane road not too long ago, but as far as 4-lane roads go, its traffic is typically light. For drives from Kansas to South Dakota, it makes a pleasant route. Yesterday was eclipse day. I strongly suspect that highway 81 had more traffic that day than it ever has before, or ever will again. For nearly the entire 3-hour drive to Geneva, NE, it was packed though mostly still moving at a good speed. And for our entire drive back, highway 81 and every other southbound road we used was so full it felt like rush hour in Dallas. (Well, not quite. Traffic was still moving.) I believe scenes like this were played out across the continent. I ve been taking a lot of photos, and writing about our new baby Martha lately. Now it s time to write a bit about some more adventures with Jacob and Oliver they re now in third and fifth grades in school. We had been planning to fly, and airports I called were either full, or were planning to park planes in the grass, or even shut down some runways to use for parking. The airport in the little town of Beatrice, NE (which I had visited twice before) was even going to have a temporary FAA control tower. At the last minute, due to some storm activity near home at departure time, we unloaded the plane and drove instead. The atmosphere at the fairgrounds in Geneva was festive. One family had brought bubbles for their kids and extras to share. IMG_20170821_113229 I had bought the boys a book about the eclipse, which they were reading before and during the event. They were both great, safe users of their eclipse glasses. IMG_20170821_124809 Jacob caught a toad, and played with it for awhile. He wanted to bring it home with us, but I convinced him to let me take a picture of him with his toad friend instead. IMG_20170821_124553 While we were waiting for totality, a number of buses from the local school district arrived. So by the time the big moment arrived, we could hear the distant roar of delight and applause from the school children gathered at the far end of the field, plus all the excitement nearby. Both boys were absolutely ecstatic to be witnessing it (and so was I!) Wow! Awesome! And simple cackles of delight were heard. On the drive home, they both kept talking about how amazing it was, and it was once in a lifetime. We enjoyed our eclipse neighbors the woman from San Antonio next to us, the surprise discovery of another family from just a few miles from us parked two cars down, even running into relatives at a restaurant on the way home. The applause from all around when it started and when it ended. And the feeling, which is hard to describe, of awe and amazement at the wonders of our world and our universe. There are many problems with the world right now, but somehow there s something right about people coming together from all over to enjoy it.

Sven Hoexter: whois databases and registration spam

Lately I experienced some new kind of spam, at least new to myself. Seems that spammer abuse registration input fields that do not implement strong enough validation, and echo back several values from the registration process in some kind of welcome mail. Basically filling the spam message in name and surname fields. So far I found a bunch of those originating from the following AS: AS49453, AS50896, AS200557 and AS61440. The first three belong to something identifying itself as "QUALITYNETWORK". The last one, AS61440, seems to be involved only partially with some networks being delegated to "Atomohost". To block them it's helpful to query the public radb service whois.radb.net for all networks belonging to the specific AS like this:
whois -h whois.radb.net -- '-i origin AS50896'
Another bunch of batch capable whois services are provided by Team Cymru. They've some examples at the end of https://www.team-cymru.org/IP-ASN-mapping.html. In this specific case the spam was for "www.robotas.ru" which is currently terminated at CloudFlare and redirects via JS document.location to "http://link31.net/b494d/ooo/", which in turn redirects via JS window.location to "http://revizor-online.ga/" which is again hosted at CloudFlare. The page at the end plays some strange youtube video - currently at around 1900 plays, so not that widely spread. In the end an interesting indicator about spam campaign success.

20 August 2017

Dirk Eddelbuettel: RcppArmadillo 0.7.960.1.1

armadillo image On the heels of the very recent bi-monthly RcppArmadillo release comes a quick bug-fix release 0.7.960.1.1 which just got onto CRAN (and I will ship a build to Debian in a moment). There were three distinct issues I addressed in three quick pull requests: Armadillo is a powerful and expressive C++ template library for linear algebra aiming towards a good balance between speed and ease of use with a syntax deliberately close to a Matlab. RcppArmadillo integrates this library with the R environment and language--and is widely used by (currently) 382 other packages on CRAN---an increase of 52 since the CRAN release in June! Changes in this release relative to the previous CRAN release are as follows:

Changes in RcppArmadillo version 0.7.960.1.1 (2017-08-20)
  • Added improved check for inherited S4 matrix classes (#162 fixing #161)
  • Changed fastLm C++ function to fastLm_impl to not clash with R method (#164 fixing #163)
  • Added OpenMP check for configure (#166 fixing #165)

Courtesy of CRANberries, there is a diffstat report. More detailed information is on the RcppArmadillo page. Questions, comments etc should go to the rcpp-devel mailing list off the R-Forge page.

This post by Dirk Eddelbuettel originated on his Thinking inside the box blog. Please report excessive re-aggregation in third-party for-profit settings.

Joachim Breitner: Compose Conference talk video online

Three months ago, I gave a talk at the Compose::Conference in New York about how Chris Smith and I added the ability to create networked multi-user programs to the educational Haskell programming environment CodeWorld, and finally the recording of the talk is available on YouTube (and is being discussed on reddit): It was the talk where I got the most positive feedback afterwards, and I think this is partly due to how I created the presentation: Instead of showing static slides, I programmed the complete visual display from scratch as an interaction within the CodeWorld environment, including all transitions, an working embedded game of Pong and a simulated multi-player environments with adjustable message delays. I have put the code for the presentation online. Chris and I have written about this for ICFP'17, and thanks to open access I can actually share the paper freely with you and under a CC license. If you come to Oxford you can see me perform a shorter version of this talk again.

Vincent Bernat: IPv6 route lookup on Linux

TL;DR: With its implementation of IPv6 routing tables using radix trees, Linux offers subpar performance (450 ns for a full view 40,000 routes) compared to IPv4 (50 ns for a full view 500,000 routes) but fair memory usage (20 MiB for a full view).
In a previous article, we had a look at IPv4 route lookup on Linux. Let s see how different IPv6 is.

Lookup trie implementation Looking up a prefix in a routing table comes down to find the most specific entry matching the requested destination. A common structure for this task is the trie, a tree structure where each node has its parent as prefix. With IPv4, Linux uses a level-compressed trie (or LPC-trie), providing good performances with low memory usage. For IPv6, Linux uses a more classic radix tree (or Patricia trie). There are three reasons for not sharing:
  • The IPv6 implementation (introduced in Linux 2.1.8, 1996) predates the IPv4 implementation based on LPC-tries (in Linux 2.6.13, commit 19baf839ff4a).
  • The feature set is different. Notably, IPv6 supports source-specific routing1 (since Linux 2.1.120, 1998).
  • The IPv4 address space is denser than the IPv6 address space. Level-compression is therefore quite efficient with IPv4. This may not be the case with IPv6.
The trie in the below illustration encodes 6 prefixes: Radix tree For more in-depth explanation on the different ways to encode a routing table into a trie and a better understanding of radix trees, see the explanations for IPv4. The following figure shows the in-memory representation of the previous radix tree. Each node corresponds to a struct fib6_node. When a node has the RTN_RTINFO flag set, it embeds a pointer to a struct rt6_info containing information about the next-hop. Memory representation of a routing table The fib6_lookup_1() function walks the radix tree in two steps:
  1. walking down the tree to locate the potential candidate, and
  2. checking the candidate and, if needed, backtracking until a match.
Here is a slightly simplified version without source-specific routing:
static struct fib6_node *fib6_lookup_1(struct fib6_node *root,
                                       struct in6_addr  *addr)
 
    struct fib6_node *fn;
    __be32 dir;
    /* Step 1: locate potential candidate */
    fn = root;
    for (;;)  
        struct fib6_node *next;
        dir = addr_bit_set(addr, fn->fn_bit);
        next = dir ? fn->right : fn->left;
        if (next)  
            fn = next;
            continue;
         
        break;
     
    /* Step 2: check prefix and backtrack if needed */
    while (fn)  
        if (fn->fn_flags & RTN_RTINFO)  
            struct rt6key *key;
            key = fn->leaf->rt6i_dst;
            if (ipv6_prefix_equal(&key->addr, addr, key->plen))  
                if (fn->fn_flags & RTN_RTINFO)
                    return fn;
             
         
        if (fn->fn_flags & RTN_ROOT)
            break;
        fn = fn->parent;
     
    return NULL;
 

Caching While IPv4 lost its route cache in Linux 3.6 (commit 5e9965c15ba8), IPv6 still has a caching mechanism. However cache entries are directly put in the radix tree instead of a distinct structure. Since Linux 2.1.30 (1997) and until Linux 4.2 (commit 45e4fd26683c), almost any successful route lookup inserts a cache entry in the radix tree. For example, a router forwarding a ping between 2001:db8:1::1 and 2001:db8:3::1 would get those two cache entries:
$ ip -6 route show cache
2001:db8:1::1 dev r2-r1  metric 0
    cache
2001:db8:3::1 via 2001:db8:2::2 dev r2-r3  metric 0
    cache
These entries are cleaned up by the ip6_dst_gc() function controlled by the following parameters:
$ sysctl -a   grep -F net.ipv6.route
net.ipv6.route.gc_elasticity = 9
net.ipv6.route.gc_interval = 30
net.ipv6.route.gc_min_interval = 0
net.ipv6.route.gc_min_interval_ms = 500
net.ipv6.route.gc_thresh = 1024
net.ipv6.route.gc_timeout = 60
net.ipv6.route.max_size = 4096
net.ipv6.route.mtu_expires = 600
The garbage collector is triggered at most every 500 ms when there are more than 1024 entries or at least every 30 seconds. The garbage collection won t run for more than 60 seconds, except if there are more than 4096 routes. When running, it will first delete entries older than 30 seconds. If the number of cache entries is still greater than 4096, it will continue to delete more recent entries (but no more recent than 512 jiffies, which is the value of gc_elasticity) after a 500 ms pause. Starting from Linux 4.2 (commit 45e4fd26683c), only a PMTU exception would create a cache entry. A router doesn t have to handle those exceptions, so only hosts would get cache entries. And they should be pretty rare. Martin KaFai Lau explains:
Out of all IPv6 RTF_CACHE routes that are created, the percentage that has a different MTU is very small. In one of our end-user facing proxy server, only 1k out of 80k RTF_CACHE routes have a smaller MTU. For our DC traffic, there is no MTU exception.
Here is how a cache entry with a PMTU exception looks like:
$ ip -6 route show cache
2001:db8:1::50 via 2001:db8:1::13 dev out6  metric 0
    cache  expires 573sec mtu 1400 pref medium

Performance We consider three distinct scenarios:
Excerpt of an Internet full view
In this scenario, Linux acts as an edge router attached to the default-free zone. Currently, the size of such a routing table is a little bit above 40,000 routes.
/48 prefixes spread linearly with different densities
Linux acts as a core router inside a datacenter. Each customer or rack gets one or several /48 networks, which need to be routed around. With a density of 1, /48 subnets are contiguous.
/128 prefixes spread randomly in a fixed /108 subnet
Linux acts as a leaf router for a /64 subnet with hosts getting their IP using autoconfiguration. It is assumed all hosts share the same OUI and therefore, the first 40 bits are fixed. In this scenario, neighbor reachability information for the /64 subnet are converted into routes by some external process and redistributed among other routers sharing the same subnet2.

Route lookup performance With the help of a small kernel module, we can accurately benchmark3 the ip6_route_output_flags() function and correlate the results with the radix tree size: Maximum depth and lookup time Getting meaningful results is challenging due to the size of the address space. None of the scenarios have a fallback route and we only measure time for successful hits4. For the full view scenario, only the range from 2400::/16 to 2a06::/16 is scanned (it contains more than half of the routes). For the /128 scenario, the whole /108 subnet is scanned. For the /48 scenario, the range from the first /48 to the last one is scanned. For each range, 5000 addresses are picked semi-randomly. This operation is repeated until we get 5000 hits or until 1 million tests have been executed. The relation between the maximum depth and the lookup time is incomplete and I can t explain the difference of performance between the different densities of the /48 scenario. We can extract two important performance points:
  • With a full view, the lookup time is 450 ns. This is almost ten times the budget for forwarding at 10 Gbps which is about 50 ns.
  • With an almost empty routing table, the lookup time is 150 ns. This is still over the time budget for forwarding at 10 Gbps.
With IPv4, the lookup time for an almost empty table was 20 ns while the lookup time for a full view (500,000 routes) was a bit above 50 ns. How to explain such a difference? First, the maximum depth of the IPv4 LPC-trie with 500,000 routes was 6, while the maximum depth of the IPv6 radix tree for 40,000 routes is 40. Second, while both IPv4 s fib_lookup() and IPv6 s ip6_route_output_flags() functions have a fixed cost implied by the evaluation of routing rules, IPv4 has several optimizations when the rules are left unmodified5. Those optimizations are removed on the first modification. If we cancel those optimizations, the lookup time for IPv4 is impacted by about 30 ns. This still leaves a 100 ns difference with IPv6 to be explained. Let s compare how time is spent in each lookup function. Here is a CPU flamegraph for IPv4 s fib_lookup(): IPv4 route lookup flamegraph Only 50% of the time is spent in the actual route lookup. The remaining time is spent evaluating the routing rules (about 30 ns). This ratio is dependent on the number of routes we inserted (only 1000 in this example). It should be noted the fib_table_lookup() function is executed twice: once with the local routing table and once with the main routing table. The equivalent flamegraph for IPv6 s ip6_route_output_flags() is depicted below: IPv6 route lookup flamegraph Here is an approximate breakdown on the time spent:
  • 50% is spent in the route lookup in the main table,
  • 15% is spent in handling locking (IPv4 is using the more efficient RCU mechanism),
  • 5% is spent in the route lookup of the local table,
  • most of the remaining is spent in routing rule evaluation (about 100 ns)6.
Why does the evaluation of routing rules is less efficient with IPv6? Again, I don t have a definitive answer.

History The following graph shows the performance progression of route lookups through Linux history: IPv6 route lookup performance progression All kernels are compiled with GCC 4.9 (from Debian Jessie). This version is able to compile older kernels as well as current ones. The kernel configuration is the default one with CONFIG_SMP, CONFIG_IPV6, CONFIG_IPV6_MULTIPLE_TABLES and CONFIG_IPV6_SUBTREES options enabled. Some other unrelated options are enabled to be able to boot them in a virtual machine and run the benchmark. There are three notable performance changes:
  • In Linux 3.1, Eric Dumazet delays a bit the copy of route metrics to fix the undesirable sharing of route-specific metrics by all cache entries (commit 21efcfa0ff27). Each cache entry now gets its own metrics, which explains the performance hit for the non-/128 scenarios.
  • In Linux 3.9, Yoshifuji Hideaki removes the reference to the neighbor entry in struct rt6_info (commit 887c95cc1da5). This should have lead to a performance increase. The small regression may be due to cache-related issues.
  • In Linux 4.2, Martin KaFai Lau prevents the creation of cache entries for most route lookups. The most sensible performance improvement comes with commit 4b32b5ad31a6. The second one is from commit 45e4fd26683c, which effectively removes creation of cache entries, except for PMTU exceptions.

Insertion performance Another interesting performance-related metric is the insertion time. Linux is able to insert a full view in less than two seconds. For some reason, the insertion time is not linear above 50,000 routes and climbs very fast to 60 seconds for 500,000 routes. Insertion time Despite its more complex insertion logic, the IPv4 subsystem is able to insert 2 million routes in less than 10 seconds.

Memory usage Radix tree nodes (struct fib6_node) and routing information (struct rt6_info) are allocated with the slab allocator7. It is therefore possible to extract the information from /proc/slabinfo when the kernel is booted with the slab_nomerge flag:
# sed -ne 2p -e '/^ip6_dst/p' -e '/^fib6_nodes/p' /proc/slabinfo   cut -f1 -d:
   name            <active_objs> <num_objs> <objsize> <objperslab> <pagesperslab>
fib6_nodes         76101  76104     64   63    1
ip6_dst_cache      40090  40090    384   10    1
In the above example, the used memory is 76104 64+40090 384 bytes (about 20 MiB). The number of struct rt6_info matches the number of routes while the number of nodes is roughly twice the number of routes: Nodes The memory usage is therefore quite predictable and reasonable, as even a small single-board computer can support several full views (20 MiB for each): Memory usage The LPC-trie used for IPv4 is more efficient: when 512 MiB of memory is needed for IPv6 to store 1 million routes, only 128 MiB are needed for IPv4. The difference is mainly due to the size of struct rt6_info (336 bytes) compared to the size of IPv4 s struct fib_alias (48 bytes): IPv4 puts most information about next-hops in struct fib_info structures that are shared with many entries.

Conclusion The takeaways from this article are:
  • upgrade to Linux 4.2 or more recent to avoid excessive caching,
  • route lookups are noticeably slower compared to IPv4 (by an order of magnitude),
  • CONFIG_IPV6_MULTIPLE_TABLES option incurs a fixed penalty of 100 ns by lookup,
  • memory usage is fair (20 MiB for 40,000 routes).
Compared to IPv4, IPv6 in Linux doesn t foster the same interest, notably in term of optimizations. Hopefully, things are changing as its adoption and use at scale are increasing.

  1. For a given destination prefix, it s possible to attach source-specific prefixes:
    ip -6 route add 2001:db8:1::/64 \
      from 2001:db8:3::/64 \
      via fe80::1 \
      dev eth0
    
    Lookup is first done on the destination address, then on the source address.
  2. This is quite different of the classic scenario where Linux acts as a gateway for a /64 subnet. In this case, the neighbor subsystem stores the reachability information for each host and the routing table only contains a single /64 prefix.
  3. The measurements are done in a virtual machine with one vCPU and no neighbors. The host is an Intel Core i5-4670K running at 3.7 GHz during the experiment (CPU governor set to performance). The benchmark is single-threaded. Many lookups are performed and the result reported is the median value. Timings of individual runs are computed from the TSC.
  4. Most of the packets in the network are expected to be routed to a destination. However, this also means the backtracking code path is not used in the /128 and /48 scenarios. Having a fallback route gives far different results and make it difficult to ensure we explore the address space correctly.
  5. The exact same optimizations could be applied for IPv6. Nobody did it yet.
  6. Compiling out table support effectively removes those last 100 ns.
  7. There is also per-CPU pointers allocated directly (4 bytes per entry per CPU on a 64-bit architecture). We ignore this detail.

Dirk Eddelbuettel: #10: Compacting your Shared Libraries, After The Build

Welcome to the tenth post in the rarely ranting R recommendations series, or R4 for short. A few days ago we showed how to tell the linker to strip shared libraries. As discussed in the post, there are two options. One can either set up ~/.R/Makevars by passing the strip-debug option to the linker. Alternatively, one can adjust src/Makevars in the package itself with a bit a Makefile magic. Of course, there is a third way: just run strip --strip-debug over all the shared libraries after the build. As the path is standardized, and the shell does proper globbing, we can just do
$ strip --strip-debug /usr/local/lib/R/site-library/*/libs/*.so
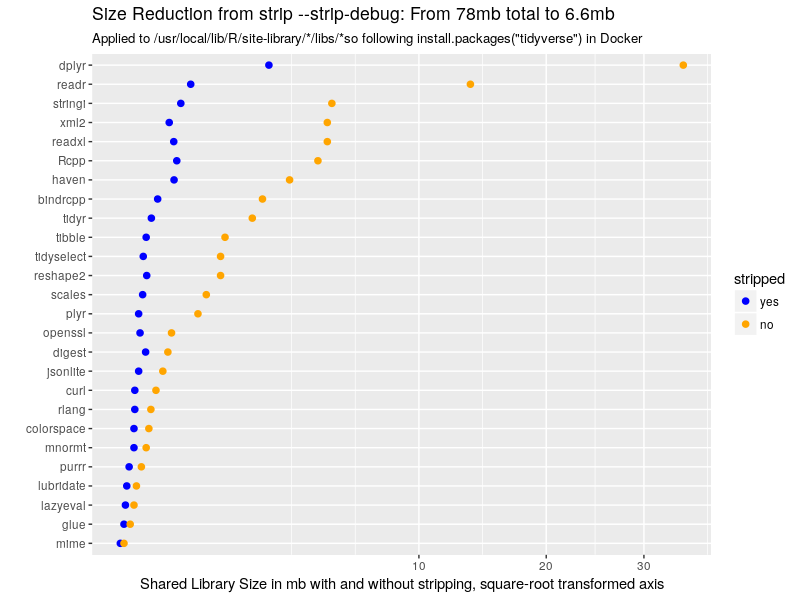
using a double-wildcard to get all packages (in that R package directory) and all their shared libraries. Users on macOS probably want .dylib on the end, users on Windows want another computer as usual (just kidding: use .dll). Either may have to adjust the path which is left as an exercise to the reader. The impact can be Yuge as illustrated in the following dotplot:
This illustration is in response to a mailing list post. Last week, someone claimed on r-help that tidyverse would not install on Ubuntu 17.04. And this is of course patently false as many of us build and test on Ubuntu and related Linux systems, Travis runs on it, CRAN tests them etc pp. That poor user had somehow messed up their default gcc version. Anyway: I fired up a Docker container, installed r-base-core plus three required -dev packages (for xml2, openssl, and curl) and ran a single install.packages("tidyverse"). In a nutshell, following the launch of Docker for an Ubuntu 17.04 container, it was just
$ apt-get update
$ apt-get install r-base libcurl4-openssl-dev libssl-dev libxml2-dev
$ apt-get install mg          # a tiny editor
$ mg /etc/R/Rprofile.site     # to add a default CRAN repo
$ R -e 'install.packages("tidyverse")'
which not only worked (as expected) but also installed a whopping fifty-one packages (!!) of which twenty-six contain a shared library. A useful little trick is to run du with proper options to total, summarize, and use human units which reveals that these libraries occupy seventy-eight megabytes:
root@de443801b3fc:/# du -csh /usr/local/lib/R/site-library/*/libs/*so
4.3M    /usr/local/lib/R/site-library/Rcpp/libs/Rcpp.so
2.3M    /usr/local/lib/R/site-library/bindrcpp/libs/bindrcpp.so
144K    /usr/local/lib/R/site-library/colorspace/libs/colorspace.so
204K    /usr/local/lib/R/site-library/curl/libs/curl.so
328K    /usr/local/lib/R/site-library/digest/libs/digest.so
33M     /usr/local/lib/R/site-library/dplyr/libs/dplyr.so
36K     /usr/local/lib/R/site-library/glue/libs/glue.so
3.2M    /usr/local/lib/R/site-library/haven/libs/haven.so
272K    /usr/local/lib/R/site-library/jsonlite/libs/jsonlite.so
52K     /usr/local/lib/R/site-library/lazyeval/libs/lazyeval.so
64K     /usr/local/lib/R/site-library/lubridate/libs/lubridate.so
16K     /usr/local/lib/R/site-library/mime/libs/mime.so
124K    /usr/local/lib/R/site-library/mnormt/libs/mnormt.so
372K    /usr/local/lib/R/site-library/openssl/libs/openssl.so
772K    /usr/local/lib/R/site-library/plyr/libs/plyr.so
92K     /usr/local/lib/R/site-library/purrr/libs/purrr.so
13M     /usr/local/lib/R/site-library/readr/libs/readr.so
4.7M    /usr/local/lib/R/site-library/readxl/libs/readxl.so
1.2M    /usr/local/lib/R/site-library/reshape2/libs/reshape2.so
160K    /usr/local/lib/R/site-library/rlang/libs/rlang.so
928K    /usr/local/lib/R/site-library/scales/libs/scales.so
4.9M    /usr/local/lib/R/site-library/stringi/libs/stringi.so
1.3M    /usr/local/lib/R/site-library/tibble/libs/tibble.so
2.0M    /usr/local/lib/R/site-library/tidyr/libs/tidyr.so
1.2M    /usr/local/lib/R/site-library/tidyselect/libs/tidyselect.so
4.7M    /usr/local/lib/R/site-library/xml2/libs/xml2.so
78M     total
root@de443801b3fc:/# 
Looks like dplyr wins this one at thirty-three megabytes just for its shared library. But with a single stroke of strip we can reduce all this down a lot:
root@de443801b3fc:/# strip --strip-debug /usr/local/lib/R/site-library/*/libs/*so
root@de443801b3fc:/# du -csh /usr/local/lib/R/site-library/*/libs/*so
440K    /usr/local/lib/R/site-library/Rcpp/libs/Rcpp.so
220K    /usr/local/lib/R/site-library/bindrcpp/libs/bindrcpp.so
52K     /usr/local/lib/R/site-library/colorspace/libs/colorspace.so
56K     /usr/local/lib/R/site-library/curl/libs/curl.so
120K    /usr/local/lib/R/site-library/digest/libs/digest.so
2.5M    /usr/local/lib/R/site-library/dplyr/libs/dplyr.so
16K     /usr/local/lib/R/site-library/glue/libs/glue.so
404K    /usr/local/lib/R/site-library/haven/libs/haven.so
76K     /usr/local/lib/R/site-library/jsonlite/libs/jsonlite.so
20K     /usr/local/lib/R/site-library/lazyeval/libs/lazyeval.so
24K     /usr/local/lib/R/site-library/lubridate/libs/lubridate.so
8.0K    /usr/local/lib/R/site-library/mime/libs/mime.so
52K     /usr/local/lib/R/site-library/mnormt/libs/mnormt.so
84K     /usr/local/lib/R/site-library/openssl/libs/openssl.so
76K     /usr/local/lib/R/site-library/plyr/libs/plyr.so
32K     /usr/local/lib/R/site-library/purrr/libs/purrr.so
648K    /usr/local/lib/R/site-library/readr/libs/readr.so
400K    /usr/local/lib/R/site-library/readxl/libs/readxl.so
128K    /usr/local/lib/R/site-library/reshape2/libs/reshape2.so
56K     /usr/local/lib/R/site-library/rlang/libs/rlang.so
100K    /usr/local/lib/R/site-library/scales/libs/scales.so
496K    /usr/local/lib/R/site-library/stringi/libs/stringi.so
124K    /usr/local/lib/R/site-library/tibble/libs/tibble.so
164K    /usr/local/lib/R/site-library/tidyr/libs/tidyr.so
104K    /usr/local/lib/R/site-library/tidyselect/libs/tidyselect.so
344K    /usr/local/lib/R/site-library/xml2/libs/xml2.so
6.6M    total
root@de443801b3fc:/#
Down to six point six megabytes. Not bad for one command. The chart visualizes the respective reductions. Clearly, C++ packages (and their template use) lead to more debugging symbols than plain old C code. But once stripped, the size differences are not that large. And just to be plain, what we showed previously in post #9 does the same, only already at installation stage. The effects are not cumulative.

This post by Dirk Eddelbuettel originated on his Thinking inside the box blog. Please report excessive re-aggregation in third-party for-profit settings.

19 August 2017

Sean Whitton: Debian Policy call for participation -- August 2017

At the Debian Policy BoF at DebConf17, Solveig suggested that we could post summaries of recent activity in policy bugs to Planet Debian, as a kind of call for participation. Russ Allbery had written a script to generate such a summary some time ago, but it couldn t handle the usertags the policy team uses to progress bugs through the policy changes process. Today I enhanced the script to handle usertags and I m pleased to be able to post a summary of our bugs. Consensus has been reached and help is needed to write a patch #172436 BROWSER and sensible-browser standardization #273093 document interactions of multiple clashing package diversions #299007 Transitioning perms of /usr/local #314808 Web applications should use /usr/share/package, not /usr/share/doc/ #425523 Describe error unwind when unpacking a package fails #452393 Clarify difference between required and important priorities #476810 Please clarify 12.5, Copyright information #484673 file permissions for files potentially including credential informa #491318 init scripts should support start/stop/restart/force-reload - why #556015 Clarify requirements for linked doc directories #568313 Suggestion: forbid the use of dpkg-statoverride when uid and gid ar #578597 Recommend usage of dpkg-buildflags to initialize CFLAGS and al. #582109 document triggers where appropriate #587279 Clarify restrictions on main to non-free dependencies #587991 perl-policy: /etc/perl missing from Module Path #592610 Clarify when Conflicts + Replaces et al are appropriate #613046 please update example in 4.9.1 (debian/rules and DEB_BUILD_OPTIONS) #614807 Please document autobuilder-imposed build-dependency alternative re #616462 clarify wording of parenthetical in section 2.2.1 #628515 recommending verbose build logs #661928 recipe for determining shlib package name #664257 document Architecture name definitions #682347 mark editor virtual package name as obsolete #683222 say explicitly that debian/changelog is required in source packages #685506 copyright-format: new Files-Excluded field #685746 debian-policy Consider clarifying the use of recommends #688251 Built-Using description too aggressive #757760 please document build profiles #759316 Document the use of /etc/default for cron jobs #761219 document versioned Provides #767839 Linking documentation of arch:any package to arch:all #770440 policy should mention systemd timers #773557 Avoid unsafe RPATH/RUNPATH #780725 PATH used for building is not specified #793499 The Installed-Size algorithm is out-of-date #810381 Update wording of 5.6.26 VCS-* fields to recommend encryption #823256 Update maintscript arguments with dpkg >= 1.18.5 #833401 virtual packages: dbus-session-bus, dbus-default-session-bus #835451 Building as root should be discouraged #838777 Policy 11.8.4 for x-window-manager needs update for freedesktop menus #845715 Please document that packages are not allowed to write outside thei #853779 Clarify requirements about update-rc.d and invoke-rc.d usage in mai Wording proposed, awaiting review from anyone and/or seconds by DDs #542288 Versions for native packages, NMU s, and binary only uploads #582109 document triggers where appropriate #630174 forbid installation into /lib64 #645696 [copyright-format] clearer definitions and more consistent License: #648271 11.8.3 Packages providing a terminal emulator says xterm passes - #649530 [copyright-format] clearer definitions and more consistent License: #662998 stripping static libraries #732445 debian-policy should encourage verification of upstream cryptograph #737796 copyright-format: support Files: paragraph with both abbreviated na #756835 Extension of the syntax of the Packages-List field. #786470 [copyright-format] Add an optional License-Grant field #835451 Building as root should be discouraged #844431 Packages should be reproducible #845255 Include best practices for packaging database applications #850729 Documenting special version number suffixes Merged for the next release #587279 Clarify restrictions on main to non-free dependencies #616462 clarify wording of parenthetical in section 2.2.1 #732445 debian-policy should encourage verification of upstream cryptograph #844431 Packages should be reproducible

Next.

Previous.