In a prior post,
I gave an overview of the OpenStack CI system and how jobs were
started. In that I said
(It is a gross oversimplification, but for the purposes of OpenStack
CI, Jenkins is pretty much used as a glorified ssh/scp wrapper. Zuul
Version 3, under development, is working to remove the need for
Jenkins to be involved at all).
Well some recent security issues with Jenkins and other changes has
led to a roll-out of what is being called Zuul 2.5, which has indeed
removed Jenkins and makes extensive use of Ansible as the basis for
running CI tests in OpenStack. Since I already had the diagram, it
seems worth updating it for the new reality.
OpenStack CI Overview
While previous post was really focused on the image-building
components of the OpenStack CI system, overview is the same but more
focused on the launchers that run the tests.
The process starts when a developer uploads their code to
gerrit via the git-review tool. There is no further action
required on their behalf and the developer simply waits for
results of their jobs.
Gerrit provides a JSON-encoded "fire-hose" output of everything
happening to it. New reviews, votes, updates and more all get sent
out over this pipe. Zuul is the overall scheduler
that subscribes itself to this information and is responsible for
managing the CI jobs appropriate for each change.
Zuul has a configuration
that tells it what jobs to run for what projects. Zuul can do lots
of interesting things, but for the purposes of this discussion we
just consider that it puts the jobs it wants run into gearman
for a launcher to consume. gearman is a
job-server; as they explain it "[gearman] provides a generic
application framework to farm out work to other machines or
processes that are better suited to do the work". Zuul puts into
gearman basically a tuple (job-name,node-type) for each
job it wants run, specifying the unique job name to run and what
type of node it should be run on.
A group of Zuul launchers
are subscribed to gearman as workers. It is these Zuul
launchers that will consume the job requests from the queue and
actually get the tests running. However, a launcher needs two
things to be able to run a job a job definition (what to actually
do) and a worker node (somewhere to do it).
The first part what to do is provided by job-definitions
stored in external YAML files. The Zuul launcher knows how to
process these files (with some help from Jenkins Job Builder, which
despite the name is not outputting XML files for Jenkins to
consume, but is being used to help parse templates and macros
within the generically defined job definitions). Each Zuul
launcher gets these definitions pushed to it constantly by Puppet,
thus each launcher knows about all the jobs it can run
automatically. Of course Zuul also knows about these same job
definitions; this is the job-name part of the tuple we said it
put into gearman.
The second part somewhere to run the test takes some more
explaining. To the next point...
Several cloud companies donate capacity in their clouds for
OpenStack to run CI tests. Overall, this capacity is managed by a
customized management tool called nodepool
(you can see the details of this capacity at any given time by
checking the nodepool configuration).
Nodepool watches the gearman queue and sees what requests are
coming out of Zuul. It looks at node-type of jobs in the queue
(i.e. what platform the job has requested to run on) and decides
what types of nodes need to start and which cloud providers have
capacity to satisfy demand.
Nodepool will start fresh virtual machines (from images built daily
as described in the prior post), monitor their start-up and, when
they're ready, put a new "assignment job" back into gearman with
the details of the fresh node. One of the active Zuul launchers
will pick up this assignment job and register the new node to
itself.
At this point, the Zuul launcher has what it needs to actually get
jobs started. With an fresh node registered to it and waiting for
something to do, the Zuul launcher can advertise its ability to
consume one of the waiting jobs from the gearman queue. For
example, if a ubuntu-trusty node is provided to the Zuul
launcher, the launcher can now consume from gearman any job it
knows about that is intended to run on an ubuntu-trusty node
type. If you're looking at the launcher code
this is driven by the NodeWorker class you can see this being
created in response to an assignment via
LaunchServer.assignNode.
To actually run the job where the "job hits the metal" as it were
the Zuul launcher will dynamically construct an Ansible playbook to run. This
playbook is a concatenation of common setup and teardown operations
along with the actual test scripts the jobs wants to run. Using
Ansible to run the job means all the flexibility an orchestration
tool provides is now available to the launcher. For example, there
is a custom console streamer
library that allows us to live-stream the console output for the
job over a plain TCP connection, and there is the possibility to
use projects like ARA
for visualisation of CI runs. In the future, Ansible will allow
for better coordination when running multiple-node testing jobs
after all, this is what orchestration tools such as Ansible are
made for! While the Ansible run can be fairly heavyweight
(especially when you're talking about launching thousands of jobs
an hour), the system scales horizontally with more launchers able
to consume more work easily.
When checking your job results on logs.openstack.org you will
see a _zuul_ansible directory now which contains copies of the
inventory, playbooks and other related files that the launcher used
to do the test run.
Eventually, the test will finish. The Zuul launcher will put the
result back into gearman, which Zuul will consume (log copying
is interesting but a topic for another day). The testing node will
be released back to nodepool, which destroys it and starts all over
again nodes are not reused and also have no sensitive details on
them, as they are essentially publicly accessible. Zuul will wait
for the results of all jobs for the change and post the result back
to Gerrit; it either gives a positive vote or the dreaded negative
vote if required jobs failed (it also handles merges to git, but
that is also a topic for another day).
Work will continue within OpenStack Infrastructure to further enhance
Zuul; including better support for multi-node jobs and "in-project"
job definitions (similar to the https://travis-ci.org/ model);
for full details see the spec.
texlive-bin/2016.20160513.41080-3 has been uploaded to unstable,
featuring support for FORCE_SOURCE_DATE. See the last post
for details on it.
doxygen/1.4.4-1 has been uploaded to unstable, fixing #822197
(upstream bug), which caused
some generated html file to contain unreproducible memory addresses of Python
objects used at build time.
debhelper/9.20160618 has been uploaded to unstable, fixing #824490,
which instructs ant to not save the username of the build user in the
generated files. Original patch by Emmanuel Bourg.
epydoc/3.0.1+dfsg-13 and 3.0.1+dfsg-14 have been uploaded by Kenneth J.
Pronovici which fixes nondeterministic ordering issues in generated
documentation and removes memory addresses. Original patches (#825968
and #827416) by Sascha Steinbiss.
With this upload of texlive-bin we decided to stop keeping our patched fork of
as most of the patches for SOURCE_DATE_EPOCH support had been integrated
upstream already, and the last one (making FORCE_SOURCE_DATE default to 1)
had been refused. So, we are now going to let the archive be rebuilt against
unstable's texlive-bin and see how many packages will become unreproducible
with this change; once enough data will be collected we will ponder whether
FORCE_SOURCE_DATE should be exported by helper tools (such as debhelper) or
manually exported by every package that needs it.
(For those wondering: we still recommend to follow SOURCE_DATE_EPOCH always
and don't recommend other projects to implement FORCE_SOURCE_DATE )
With the drop of texlive-bin we now have only three modified packages in our
experimental repository.
Reproducible work in other projects
Ed Maste sent a patch to have
ELF Tool Chain's elfcopy support SOURCE_DATE_EPOCH.
Ed Maste changed
FreeBSD's ar(1) to have a reproducible output by default when invoked with -s.
Ed Maste merged changes
from NetBSD's makefs to FreeBSD's to add a command line option for setting the
timestamp.
Holger Levsen spent some time thinking and documenting how to store package notes
and issues in a multi-distribution friendly manner, so that we can share
these issues and notes between reproducible efforts across different projects.
Thoughts we had about this topic
during the Athens meeting last December are included in the updated README.
Uploads with reproducibility fixes that currently fail to build:
ruby2.3/2.3.1-3 by Christian Hofstaedtler, avoids unreproducible rbconfig.rb files by always using bash for building.
Patches submitted that have not made their way to the archive yet:
#827109 against asciijump by Reiner Herrmann: sort source files for deterministic linking order.
#827112 against boswars by Reiner Herrmann: sort source files for deterministic linking order.
#827114 against overgod by Reiner Herrmann: use C locale for sorting source files.
#827115 against netpbm by Alexis Bienven e: honour SOURCE_DATE_EPOCH while generating output.
#827124 against funguloids by Reiner Herrmann: use C locale for sorting files.
#827145 against scummvm by Reiner Herrmann: don't embed extra fields in zip archive and build with proper host architecture.
#827150 against netpanzer by Reiner Herrmann: sort source files for deterministic linking order.
#827172 against reaver by Alexis Bienven e: sort object files for deterministic linking order.
#827187 against latex2html by Alexis Bienven e: iterate deterministic over Perl hashes; honour SOURCE_DATE_EPOCH for output; strip username from output; sort index keys.
#827313 against cherrypy3 by Sascha Steinbiss: prevent memory addresses in output.
#827361 against matplotlib by Alexis Bienven e: honour SOURCE_DATE_EPOCH in output and sort keys while iterating over dict.
#827382 against dwarfutils by Reiner Herrmann: fix array size, which caused memory from outside a table to be embedded into output.
#827384 against skytools3 by Sascha Steinbiss: use stable sorting order and remove timestamps from documentation.
#827419 against ldaptor by Sascha Steinbiss: sort list of input files and prevent home directory from leaking into documentation.
#827546 against git-buildpackage by Sascha Steinbiss: replace timestamps in documentation with changelog date; prevent temporary paths in documentation.
#827572 against xprobe by Reiner Herrmann: sort list of object files in static library archives.
Package reviews
36 reviews have been added, 12 have been updated and 31 have been removed in this week.
17 FTBFS bugs have been reported by Chris Lamb, Santiago Vila and Dominic Hargreaves.
diffoscope development
Satyam worked on argument completion (#826711) for diffoscope.
strip-nondeterminism development
Mattia Rizzolo uploaded strip-nondeterminism 0.019-1~bpo8+1 to
jessie-backports.
reprotest development
Ceridwen filed an Intent To Package (ITP) bug for reprotest as #827293.
tests.reproducible-builds.org
Mattia Rizzolo uploaded pbuilder 0.225 to unstable, providing built-in
support for eatmydata. We're planning to use it in armhf and i386 builders
where we don't build in tmpfs, to increase the build speed some more.
Valery Young reworked the appearance of the package page, hopefully making them more
intuitive and usable. In the process she changed the script generating them
to use a real templating system, thus improving
maintenance for the future.
Holger adjusted the scheduler to reschedule packages in state 'depwait' after
two days instead of three.
Mattia added the bug title next to the bug numbers in the notes.
Misc.
This week's edition was written by Mattia Rizzolo, Reiner Herrmann, Ed Maste and Holger Levsen and reviewed by a bunch of Reproducible builds folks on IRC.
I'm back from the GTK hackfest in Toronto, Canada and mostly recovered from
jetlag, so it's time to write up my notes on what we discussed there.
Despite the hackfest's title, I was mainly there to talk about non-GUI
parts of the stack, and technologies that fit more closely in what could
be seen as the freedesktop.org platform than they do in GNOME. In particular,
I'm interested in Flatpak as a way to deploy self-contained "apps" in a
freedesktop-based, sandboxed runtime environment layered over
the Universal Operating System and
its many derivatives,
with both binary and source compatibility with other GNU/Linux distributions.
I'm mainly only writing about discussions I was directly involved in:
lots of what sounded like good discussion about the actual graphics toolkit
went over my head completely :-)
More notes, mostly from Matthias
Clasen, are available on the GNOME wiki.
In no particular order:
Thinking with portals
We spent some time discussing Flatpak's portals, mostly on Tuesday.
These are the components that expose a subset of desktop functionality
as D-Bus services that can be used by contained applications: they are
part of the security boundary between a contained app and the rest of the
desktop session. Android's intents are a similar concept seen elsewhere.
While the portals are primarily designed for Flatpak, there's no real
reason why they couldn't be used by other app-containment solutions
such as Canonical's Snap.
One major topic of discussion was their overall design and layout. Most
portals will consist of a UX-independent part in Flatpak itself, together
with a UX-specific implementation of any user interaction the portal
needs. For example, the portal for file selection has a D-Bus service
in Flatpak, which interacts with some UX-specific service that will
pop up a standard UX-specific "Open" dialog for GNOME and probably
other GTK environments, that dialog is in (a branch of) GTK.
A design principle that was reiterated in this discussion is that
the UX-independent part should do as much as possible, with the
UX-specific part only carrying out the user interactions that need
to comply with a particular UX design (in the GTK case, GNOME's design).
This minimizes the amount of work that needs to be redone for other
desktop or embedded environments, while still ensuring that the other
environments can have their chosen UX design. In particular, it's
important that, as much as possible, the security- and performance-sensitive
work (such as data transport and authentication) is shared between all
environments.
The aim is for portals to get the user's permission to carry out actions,
while keeping it as implicit as possible, avoiding an "are you sure?" step
where feasible. For example, if an application asks to open a file,
the user's permission is implicitly given by them selecting the file
in the file-chooser dialog and pressing OK: if they do not want this
application to open a file at all, they can deny permission by cancelling.
Similarly, if an application asks to stream webcam data, the UX we expect
is for GNOME's Cheese app (or a similar non-GNOME app) to appear, open
the webcam to provide a preview window so they can see what they are about
to send, but not actually start sending the
stream to the requesting app until the user has pressed a "Start" button.
When defining the API "contracts" to be provided by applications in that
situation, we will need to be clear about whether the provider is expected
to obtain confirmation like this: in most cases I would anticipate that
it is.
One security trade-off here is that we have to have a small amount of
trust in the providing app. For example, continuing the example of Cheese
as a webcam provider, Cheese could (and perhaps should) be a contained
app itself, whether via something like Flatpak, an LSM like AppArmor
or both. If Cheese is compromised somehow, then whenever it is running, it
would be technically possible for it to open the webcam, stream video and
send it to a hostile third-party application. We concluded that this is an
acceptable trade-off: each application needs to be trusted with the privileges
that it needs to do its job, and we should not put up barriers that are easy
to circumvent or otherwise serve no purpose.
The main (only?) portal so far is the file chooser, in which the contained
application asks the wider system to show an "Open..." dialog, and if the user
selects a file, it is returned to the contained application through a FUSE
filesystem, the document portal. The reference implementation of the UX for
this is in GTK, and is basically a GtkFileChooserDialog. The intention is
that other environments such as KDE will substitute their own equivalent.
Other planned portals include:
image capture (scanner/camera)
opening a specified URI
this needs design feedback on how it should work for non-http(s)
sharing content, for example on social networks (like Android's Sharing menu)
proxying joystick/gamepad input (perhaps via Wayland or FUSE, or perhaps
by modifying libraries like SDL with a new input source)
network proxies (GProxyResolver) and availability (GNetworkMonitor)
contacts/address book, probably vCard-based
notifications, probably based on freedesktop.org Notifications
video streaming (perhaps using Pinot, analogous to PulseAudio but for video)
Environment variables
GNOME on Wayland currently has a problem with environment variables:
there are some traditional ways to set environment variables for X11
sessions or login shells using shell script fragments (/etc/X11/Xsession.d,
/etc/X11/xinit/xinitrc.d, /etc/profile.d), but these do not apply to
Wayland, or to noninteractive login environments like cron and
systemd --user. We are also keen to avoid requiring a Turing-complete shell
language during session startup, because it's difficult to reason about
and potentially rather inefficient.
Some uses of environment variables can be dismissed as unnecessary or even
unwanted, similar to the statement in Debian Policy 9.9: "A program must not
depend on environment variables to get reasonable defaults." However,
there are two common situations where environment variables can be necessary
for proper OS integration: search-paths like $PATH, $XDG_DATA_DIRS and
$PYTHONPATH (particularly necessary for things like Flatpak), and
optionally-loaded modules like $GTK_MODULES and $QT_ACCESSIBILITY
where a package influences the configuration of another package.
There is a stopgap solution in GNOME's gdm display manager,
/usr/share/gdm/env.d, but this is gdm-specific and
insufficiently expressive to provide the functionality needed by
Flatpak: "set XDG_DATA_DIRS to its specified default value if unset,
then add a couple of extra paths".
pam_env comes closer PAM is run at every transition from "no user logged
in" to "user can execute arbitrary code as themselves" but it doesn't
support .d fragments, which are required if we want distribution packages
to be able to extend search paths. pam_env also turns off per-user
configuration by default, citing security concerns.
I'll write more about this when I have a concrete proposal for how to solve it.
I think the best solution is probably a PAM module similar to pam_env but
supporting .d directories, either by modifying pam_env directly or
out-of-tree, combined with clarifying what the security concerns for
per-user configuration are and how they can be avoided.
Relocatable binary packages
On Windows and OS X, various GLib APIs automatically discover where the
application binary is located and use search paths relative to that;
for example, if C:\myprefix\bin\app.exe is running, GLib might put
C:\myprefix\share into the result of g_get_system_data_dirs(),
so that the application can ask to load app/data.xml from the data
directories and get C:\myprefix\share\app\data.xml. We would like
to be able to do the same on Linux, for example so that the apps in a
Flatpak or Snap package can be constructed from RPM or dpkg packages without
needing to be recompiled for a different --prefix, and so that other
third-party software packages like the games on Steam and gog.com can
easily locate their own resources.
Relatedly, there are currently no well-defined semantics for what happens
when a .desktop file or a D-Bus .service file has Exec=./bin/foo.
The meaning of Exec=foo is well-defined (it searches $PATH) and the
meaning of Exec=/opt/whatever/bin/foo is obvious. When this came up in
D-Bus previously, my assertion was that the meaning should be the same as
in .desktop files, whatever that is.
We agreed to propose that the meaning of a non-absolute path in a .desktop
or .service file should be interpreted relative to the directory
where the .desktop or .service file was found: for example, if
/opt/whatever/share/applications/foo.desktop says Exec=../../bin/foo,
then /opt/whatever/bin/foo would be the right thing to execute.
While preparing a mail to the freedesktop and D-Bus mailing lists proposing
this, I found that I had
proposed the same thingalmost 2 years ago...
this time I hope I can actually make it happen!
Flatpak and OSTree bug fixing
On the way to the hackfest, and while the discussion moved to topics that I
didn't have useful input on, I spent some time fixing up the Debian packaging
for Flatpak and its dependencies. In particular, I did my first upload
as a co-maintainer of bubblewrap,
uploaded ostree to unstable (with the known limitation that the grub, dracut
and systemd integration is missing for now
since I haven't been able to test it yet), got
most of the way through packaging Flatpak 0.6.5 (which I'll upload soon),
cherry-picked the right patches to make ostree compile on Debian 8 in an effort
to make backports trivial, and spent some time disentangling
a flatpak test failure
which was breaking the Debian package's installed-tests.
I'm still looking into
ostree test failures on little-endian MIPS,
which I was able to reproduce on a Debian porterbox just before the end of the
hackfest.
OSTree + Debian
I also had some useful conversations with developers from
Endless, who recently opened up a version of their
OSTree build scripts
for public access. Hopefully that information brings me a bit closer to
being able to publish a walkthrough for
how to deploy a simple Debian derivative using OSTree
(help with that is very welcome of course!).
GTK life-cycle and versioning
The life-cycle of GTK releases has already been
mentioned here and elsewhere, and there are some interesting responses
in the comments on my earlier blog post.
It's important to note that what we
discussed at the hackfest is only a proposal: a hackfest discussion between
a subset of the GTK maintainers and a small number of other GTK users
(I am in the latter category)
doesn't, and shouldn't, set policy for all of GTK or for all of GNOME. I
believe the intention is that the GTK maintainers will discuss the proposals
further at GUADEC, and make a decision after that.
As I said before, I hope that being more realistic about API and ABI
guarantees can avoid GTK going too far towards either of the possible
extremes: either becoming unable to advance because it's too constrained
by compatibility, or breaking applications because it isn't constrained
enough. The current situation, where it is meant to be compatible within
the GTK 3 branch but in practice applications still sometimes break,
doesn't seem ideal for anyone, and I hope we can do better in future.
Acknowledgements
Thanks to everyone involved, particularly:
Matthias Clasen, who organised the hackfest and took a lot of notes
Allison Lortie, who provided on-site cat-herding and led us to some
excellent restaurants
Red Hat Inc., who provided the venue (a conference room
in their Toronto office), snacks, a lot of coffee, and several participants
my employers Collabora Ltd., who sponsored my travel and accomodation
This year a significant number of students are working on RTC-related projects as part of Google Summer of Code, under the umbrella of the Debian Project. You may have already encountered some of them blogging on Planet or participating in mailing lists and IRC.
WebRTC plugins for popular CMS and web frameworks
There are already a range of pseudo-WebRTC plugins available for CMS and blogging platforms like WordPress, unfortunately, many of them are either not releasing all their source code, locking users into their own servers or requiring the users to download potentially untrustworthy browser plugins (also without any source code) to use them.
Mesut is making plugins for genuinely free WebRTC with open standards like SIP. He has recently created the WPCall plugin for WordPress, based on the highly successful DruCall plugin for WebRTC in Drupal.
Keerthana has started creating a similar plugin for MediaWiki.
What is great about these plugins is that they don't require any browser plugins and they work with any server-side SIP infrastructure that you choose. Whether you are routing calls into a call center or simply using them on a personal blog, they are quick and convenient to install. Hopefully they will be made available as packages, like the DruCall packages for Debian and Ubuntu, enabling even faster installation with all dependencies.
Would you like to try running these plugins yourself and provide feedback to the students? Would you like to help deploy them for online communities using Drupal, WordPress or MediaWiki to power their web sites? Please come and discuss them with us in the Free-RTC mailing list.
You can read more about how to run your own SIP proxy for WebRTC in the RTC Quick Start Guide.
Finding all the phone numbers and ham radio callsigns in old emails
Do you have phone numbers and other contact details such as ham radio callsigns in old emails? Would you like a quick way to data-mine your inbox to find them and help migrate them to your address book?
Jaminy is working on Python scripts to do just that. Her project takes some inspiration from the Telify plugin for Firefox, which detects phone numbers in web pages and converts them to hyperlinks for click-to-dial. The popular libphonenumber from Google, used to format numbers on Android phones, is being used to help normalize any numbers found. If you would like to test the code against your own mailbox and address book, please make contact in the #debian-data channel on IRC.
A truly peer-to-peer alternative to SIP, XMPP and WebRTC
The team at Savoir Faire Linux has been busy building the Ring softphone, a truly peer-to-peer solution based on the OpenDHT distribution hash table technology.
Several students (Simon, Olivier, Nicolas and Alok) are actively collaborating on this project, some of them have been fortunate enough to participate at SFL's offices in Montreal, Canada. These GSoC projects have also provided a great opportunity to raise Debian's profile in Montreal ahead of DebConf17 next year.
Linux Desktop Telepathy framework and reSIProcate
Another group of students, Mateus, Udit and Balram have been busy working on C++ projects involving the Telepathy framework and the reSIProcate SIP stack. Telepathy is the framework behind popular softphones such as GNOME Empathy that are installed by default on the GNU/Linux desktop.
I previously wrote about starting a new SIP-based connection manager for Telepathy based on reSIProcate. Using reSIProcate means more comprehensive support for all the features of SIP, better NAT traversal, IPv6 support, NAPTR support and TLS support. The combined impact of all these features is much greater connectivity and much greater convenience.
The students are extending that work, completing the buddy list functionality, improving error handling and looking at interaction with XMPP.
Streamlining provisioning of SIP accounts
Currently there is some manual effort for each user to take the SIP account settings from their Internet Telephony Service Provider (ITSP) and transpose these into the account settings required by their softphone.
Pranav has been working to close that gap, creating a JAR that can be embedded in Java softphones such as Jitsi, Lumicall and CSipSimple to automate as much of the provisioning process as possible. ITSPs are encouraged to test this client against their services and will be able to add details specific to their service through Github pull requests.
The project also hopes to provide streamlined provisioning mechanisms for privately operated SIP PBXes, such as the Asterisk and FreeSWITCH servers used in small businesses.
Improving SIP support in Apache Camel and the Jitsi softphone
Apache Camel's SIP component and the widely known Jitsi softphone both use the JAIN SIP library for Java.
Nik has been looking at issues faced by SIP users in both projects, adding support for the MESSAGE method in camel-sip and looking at why users sometimes see multiple password prompts for SIP accounts in Jitsi.
If you are trying either of these projects, you are very welcome to come and discuss them on the mailing lists, Camel users and Jitsi users.
GSoC students at DebConf16 and DebConf17 and other events
Many of us have been lucky to meet GSoC students attending DebConf, FOSDEM and other events in the past. From this year, Google now expects the students to complete GSoC before they become eligible for any travel assistance. Some of the students will still be at DebConf16 next month, assisted by the regular travel budget and the diversity funding initiative. Nik and Mesut were already able to travel to Vienna for the recent MiniDebConf / LinuxWochen.at
As mentioned earlier, several of the students and the mentors at Savoir Faire Linux are based in Montreal, Canada, the destination for DebConf17 next year and it is great to see the momentum already building for an event that promises to be very big.
Explore the world of Free Real-Time Communications (RTC)
If you are interesting in knowing more about the Free RTC topic, you may find the following resources helpful:
Try Lumicall and Ring apps for Android with your freinds
RTC mentoring team 2016
We have been very fortunate to build a large team of mentors around the RTC-themed projects for 2016. Many of them are first time GSoC mentors and/or new to the Debian community. Some have successfully completed GSoC as students in the past. Each of them brings unique experience and leadership in their domain.
Helping GSoC projects in 2016 and beyond
Not everybody wants to commit to being a dedicated mentor for a GSoC student. In fact, there are many ways to help without being a mentor and many benefits of doing so.
Simply looking out for potential applicants for future rounds of GSoC and referring them to the debian-outreach mailing list or an existing mentor helps ensure we can identify talented students early and design projects around their capabilities and interests.
Testing the projects on an ad-hoc basis, greeting the students at DebConf and reading over the student wikis to find out where they are and introduce them to other developers in their area are all possible ways to help the projects succeed and foster long term engagement.
Google gives Debian a USD $500 grant for each student who completes a project successfully this year. If all 2016 students pass, that is over $10,000 to support Debian's mission.
Here is a small update for last week s work:
1. Templates
tests.reproducible-builds.org now has a templating system, instead of writing HTML in python files We are using mustache with pystache. So far, only the html for the package pages have been converted.
2. Navigation improvements on package pages
While converting the package pages to using mustache I also rearranged the navigation bar, adding sections and hover text. Navigation improvements inspired by Gerts Wollney s email requests. Please check out the changes and provide feedback: tests.reproducible-builds.org/<your-favorite-package>
3. Began converting script from bash to python
Before converting the rest of the site to mustache, I spent a day digging into the last unconverted bash script (all other html producing scripts are python). I ve never written or read that much bash, yet another learning opportunity I have to admit it s a bit less intuitive than python
Up next:
Finish converting package set script, create more mustache templates, more site improvements! Then fly to South Africa.
As some of the world knows full well by now, I've been noodling with Go
for a few years, working through its pros, its cons, and thinking a lot
about how humans use code to express thoughts and ideas. Go's got a lot of
neat use cases, suited to particular problems, and used in the right place,
you can see some clear massive wins.
I've started writing Debian tooling in Go, because it's a pretty natural fit.
Go's fairly tight, and overhead shouldn't be taken up by your operating system.
After a while, I wound up hitting the usual blockers, and started to build up
abstractions. They became pretty darn useful, so, this blog post is announcing
(a still incomplete, year old and perhaps API changing) Debian package for Go.
The Go importable name is pault.ag/go/debian. This contains a lot of utilities
for dealing with Debian packages, and will become an edited down "toolbelt"
for working with or on Debian packages.
Module Overview
Currently, the package contains 4 major sub packages. They're a changelog
parser, a control file parser, deb file format parser, dependency parser
and a version parser. Together, these are a set of powerful building blocks
which can be used together to create higher order systems with reliable
understandings of the world.
changelog
The first (and perhaps most incomplete and least tested) is a changelog file
parser.. This provides the
programmer with the ability to pull out the suite being targeted in the
changelog, when each upload was, and the version for each. For example, let's
look at how we can pull when all the uploads of Docker to sid took place:
funcmain()resp,err:=http.Get("http://metadata.ftp-master.debian.org/changelogs/main/d/docker.io/unstable_changelog")iferr!=nilpanic(err)allEntries,err:=changelog.Parse(resp.Body)iferr!=nilpanic(err)for_,entry:=rangeallEntriesfmt.Printf("Version %s was uploaded on %s\n",entry.Version,entry.When)
The output of which looks like:
Version 1.8.3~ds1-2 was uploaded on 2015-11-04 00:09:02 -0800 -0800
Version 1.8.3~ds1-1 was uploaded on 2015-10-29 19:40:51 -0700 -0700
Version 1.8.2~ds1-2 was uploaded on 2015-10-29 07:23:10 -0700 -0700
Version 1.8.2~ds1-1 was uploaded on 2015-10-28 14:21:00 -0700 -0700
Version 1.7.1~dfsg1-1 was uploaded on 2015-08-26 10:13:48 -0700 -0700
Version 1.6.2~dfsg1-2 was uploaded on 2015-07-01 07:45:19 -0600 -0600
Version 1.6.2~dfsg1-1 was uploaded on 2015-05-21 00:47:43 -0600 -0600
Version 1.6.1+dfsg1-2 was uploaded on 2015-05-10 13:02:54 -0400 EDT
Version 1.6.1+dfsg1-1 was uploaded on 2015-05-08 17:57:10 -0600 -0600
Version 1.6.0+dfsg1-1 was uploaded on 2015-05-05 15:10:49 -0600 -0600
Version 1.6.0+dfsg1-1~exp1 was uploaded on 2015-04-16 18:00:21 -0600 -0600
Version 1.6.0~rc7~dfsg1-1~exp1 was uploaded on 2015-04-15 19:35:46 -0600 -0600
Version 1.6.0~rc4~dfsg1-1 was uploaded on 2015-04-06 17:11:33 -0600 -0600
Version 1.5.0~dfsg1-1 was uploaded on 2015-03-10 22:58:49 -0600 -0600
Version 1.3.3~dfsg1-2 was uploaded on 2015-01-03 00:11:47 -0700 -0700
Version 1.3.3~dfsg1-1 was uploaded on 2014-12-18 21:54:12 -0700 -0700
Version 1.3.2~dfsg1-1 was uploaded on 2014-11-24 19:14:28 -0500 EST
Version 1.3.1~dfsg1-2 was uploaded on 2014-11-07 13:11:34 -0700 -0700
Version 1.3.1~dfsg1-1 was uploaded on 2014-11-03 08:26:29 -0700 -0700
Version 1.3.0~dfsg1-1 was uploaded on 2014-10-17 00:56:07 -0600 -0600
Version 1.2.0~dfsg1-2 was uploaded on 2014-10-09 00:08:11 +0000 +0000
Version 1.2.0~dfsg1-1 was uploaded on 2014-09-13 11:43:17 -0600 -0600
Version 1.0.0~dfsg1-1 was uploaded on 2014-06-13 21:04:53 -0400 EDT
Version 0.11.1~dfsg1-1 was uploaded on 2014-05-09 17:30:45 -0400 EDT
Version 0.9.1~dfsg1-2 was uploaded on 2014-04-08 23:19:08 -0400 EDT
Version 0.9.1~dfsg1-1 was uploaded on 2014-04-03 21:38:30 -0400 EDT
Version 0.9.0+dfsg1-1 was uploaded on 2014-03-11 22:24:31 -0400 EDT
Version 0.8.1+dfsg1-1 was uploaded on 2014-02-25 20:56:31 -0500 EST
Version 0.8.0+dfsg1-2 was uploaded on 2014-02-15 17:51:58 -0500 EST
Version 0.8.0+dfsg1-1 was uploaded on 2014-02-10 20:41:10 -0500 EST
Version 0.7.6+dfsg1-1 was uploaded on 2014-01-22 22:50:47 -0500 EST
Version 0.7.1+dfsg1-1 was uploaded on 2014-01-15 20:22:34 -0500 EST
Version 0.6.7+dfsg1-3 was uploaded on 2014-01-09 20:10:20 -0500 EST
Version 0.6.7+dfsg1-2 was uploaded on 2014-01-08 19:14:02 -0500 EST
Version 0.6.7+dfsg1-1 was uploaded on 2014-01-07 21:06:10 -0500 EST
control
Next is one of the most complex, and one of the oldest parts of go-debian,
which is the control file parser
(otherwise sometimes known as deb822). This module was inspired by the way
that the json module works in Go, allowing for files to be defined in code
with a struct. This tends to be a bit more declarative, but also winds up
putting logic into struct tags, which can be a nasty anti-pattern if used too
much.
The first primitive in this module is the concept of a Paragraph, a struct
containing two values, the order of keys seen, and a map of string to string.
All higher order functions dealing with control files will go through this
type, which is a helpful interchange format to be aware of. All parsing of
meaning from the Control file happens when the Paragraph is unpacked into
a struct using reflection.
The idea behind this strategy that you define your struct, and let the Control
parser handle unpacking the data from the IO into your container, letting you
maintain type safety, since you never have to read and cast, the conversion
will handle this, and return an Unmarshaling error in the event of failure.
Additionally, Structs that define an anonymous member of control.Paragraph
will have the raw Paragraph struct of the underlying file, allowing the
programmer to handle dynamic tags (such as X-Foo), or at least, letting
them survive the round-trip through go.
The default decoder
contains an argument, the ability to verify the input control file using an
OpenPGP keyring, which is exposed to the programmer through the
(*Decoder).Signer() function. If the passed argument is nil, it will not
check the input file signature (at all!), and if it has been passed, any
signed data must be found or an error will fall out of the NewDecoder call.
On the way out, the opposite happens, where the struct is introspected,
turned into a control.Paragraph, and then written out to the io.Writer.
Here's a quick (and VERY dirty) example showing the basics of reading and
writing Debian Control files with go-debian.
packagemainimport("fmt""io""net/http""strings""pault.ag/go/debian/control")typeAllowedPackagestructPackagestringFingerprintstringfunc(a*AllowedPackage)UnmarshalControl(instring)errorin=strings.TrimSpace(in)chunks:=strings.SplitN(in," ",2)iflen(chunks)!=2returnfmt.Errorf("Syntax sucks: '%s'",in)a.Package=chunks[0]a.Fingerprint=chunks[1][1:len(chunks[1])-1]returnniltypeDMUAstructFingerprintstringUidstringAllowedPackages[]AllowedPackage control:"Allow" delim:"," funcmain()resp,err:=http.Get("http://metadata.ftp-master.debian.org/dm.txt")iferr!=nilpanic(err)decoder,err:=control.NewDecoder(resp.Body,nil)iferr!=nilpanic(err)fordmua:=DMUAiferr:=decoder.Decode(&dmua);err!=niliferr==io.EOFbreakpanic(err)fmt.Printf("The DM %s is allowed to upload:\n",dmua.Uid)for_,allowedPackage:=rangedmua.AllowedPackagesfmt.Printf(" %s [granted by %s]\n",allowedPackage.Package,allowedPackage.Fingerprint)
Output (truncated!) looks a bit like:
...
The DM Allison Randal <allison@lohutok.net> is allowed to upload:
   parrot [granted by A4F455C3414B10563FCC9244AFA51BD6CDE573CB]
...
The DM Benjamin Barenblat <bbaren@mit.edu> is allowed to upload:
   boogie [granted by 3224C4469D7DF8F3D6F41A02BBC756DDBE595F6B]
   dafny [granted by 3224C4469D7DF8F3D6F41A02BBC756DDBE595F6B]
   transmission-remote-gtk [granted by 3224C4469D7DF8F3D6F41A02BBC756DDBE595F6B]
   urweb [granted by 3224C4469D7DF8F3D6F41A02BBC756DDBE595F6B]
...
The DM     <aelmahmoudy@sabily.org> is allowed to upload:
   covered [granted by 41352A3B4726ACC590940097F0A98A4C4CD6E3D2]
   dico [granted by 6ADD5093AC6D1072C9129000B1CCD97290267086]
   drawtiming [granted by 41352A3B4726ACC590940097F0A98A4C4CD6E3D2]
   fonts-hosny-amiri [granted by BD838A2BAAF9E3408BD9646833BE1A0A8C2ED8FF]
   ...
...
deb
Next up, we've got the deb module. This contains code to handle reading
Debian 2.0 .deb files. It contains a wrapper that will parse the control
member, and provide the data member through the
archive/tar interface.
Here's an example of how to read a .deb file, access some metadata, and
iterate over the tar archive, and print the filenames of each of the
entries.
dependency
The dependency package provides an interface to parse and compute
dependencies. This package is a bit odd in that, well, there's no other
library that does this. The issue is that there are actually two different
parsers that compute our Dependency lines, one in Perl (as part of dpkg-dev)
and another in C (in dpkg).
To date, this has resulted in me filing
threedifferentbugs.
I also found a broken package in the
archive,
which actually resulted in another bug being (totally accidentally)
already fixed.
I hope to continue to run the archive through my parser in hopes of finding
more bugs! This package is a bit complex, but it basically just returns what
amounts to be an AST
for our Dependency lines. I'm positive there are bugs, so file them!
funcmain()dep,err:=dependency.Parse("foo bar, baz, foobar [amd64] bazfoo [!sparc], fnord:armhf [gnu-linux-sparc]")iferr!=nilpanic(err)anySparc,err:=dependency.ParseArch("sparc")iferr!=nilpanic(err)for_,possi:=rangedep.GetPossibilities(*anySparc)fmt.Printf("%s (%s)\n",possi.Name,possi.Arch)
Gives the output:
foo (<nil>)
baz (<nil>)
fnord (armhf)
version
Right off the bat, I'd like to thank
Michael Stapelberg for letting me graft this
out of dcs and into the go-debian package.
This was nearly entirely his work (with a one or two line function I added
later), and was amazingly helpful to have. Thank you!
This module implements Debian version comparisons and parsing, allowing for
sorting in lists, checking to see if it's native or not, and letting the
programmer to implement smart(er!) logic based on upstream (or Debian)
version numbers.
This module is extremely easy to use and very straightforward, and not worth
writing an example for.
Final thoughts
This is more of a "Yeah, OK, this has been useful enough to me at this point
that I'm going to support this" rather than a "It's stable!" or even
"It's alive!" post. Hopefully folks can report bugs and help iterate on
this module until we have some really clean building blocks to build
solid higher level systems on top of. Being able to have multiple libraries
interoperate by relying on go-debian will be a massive ease.
I'm in need of more documentation, and to finalize some parts of the older
sub package APIs, but I'm hoping to be at a "1.0" real soon now.
The last few months have been a bit of a crazy period of ups and downs, with a
tempest of events beneath the apparent and deceivingly calm surface waters of
being unemployed (still at it).
The daily grind
Chief activities are, of course, those related to the daily grind of
job-hunting, sending applications, and preparing and attending interviews.
It is demoralising when one searches for many days or weeks without seeing
anything suitable for one's skills or interests, or other more general life
expectations. And it takes a lot of time and effort to put one's best in the
applications for positions that one is really, really, interested in. And
even for the ones which are meh, for a variety of reasons (e.g. one is not
very suitable for what the offer demands).
After that, not being invited to interviews (or doing very badly at them) is
bad, of course, but quick and not very painful. A swift, merciful end to the
process.
But it's all the more draining when waiting for many weeks when not a few
months with the uncertainty of not knowing if one is going to be lucky enough
to be summoned for an interview; harbouring some hope one has to appear
enthusiastic in the interviews, after all , while trying to keep it contained
lest it grows too much ; then in the interview hearing good words and some
praises, and feeling the impression that one will fit in, that one did nicely
and that chances are good letting the hope grow again ; start to think about
life changes that the job will require to make a quick decision should the
offer finally arrives ; perhaps make some choices and compromises based on the
uncertain result; then wait for a week or two after the interview to know the
result...
... only to end up being unsuccessful.
All the effort and hopes finally get squashed with a cold, short email or
automatic response, or more often than not, complete radio silence from
prospective employers, as an end to a multi-month-long process. An emotional
roller coaster [1], which
happened to me several times in the last few months.
All in a day's work
The months of preparing and waiting for a new job often imply an impasse that
puts many other things that one cares about on hold, and one makes plans that
will never come to pass.
All in a day's (half-year's?) work of an unemployed poor soul.
But not all is bad.
This period was also a busy time doing some plans about life, mid- and
long-term; the usual and some really unusual! family events; visits to and
from friends, old and new; attending nice little local Debian gatherings or the
bigger gathering of Debian
SunCamp2016, and other
work for side projects or for other events that will happen soon...
And amidst all that, I managed to get some work done on aptitude.
Two pictures worth (less than) a thousand bugs
To be precise, worth 709 bugs 488 bugs in the first graph, plus 221 in the
second.
In 2015-11-15 (link to the post Work on aptitude):
In 2016-06-18:
Numbers
The BTS numbers for aptitude right now are:
221 (259 if counting all merged bugs independently)
1 Release Critical (but it is an artificial bug to keep it from migrating to
testing)
43 (55 unmerged) with severity Important or Normal
160 (182 unmerged) with severity Minor or Wishlist
17 (21 unmerged) marked as Forwarded or Pending
Highlights
Beyond graphs and stats, I am specially happy about two achievements in the last
year:
To have aptitude working today, first and foremost
Apart from the abandon that suffered in previous years, I mean
specifically the critical step of getting it through the troubles of the
last summer, with the GCC-5/C++11 transition in parallel with a
transition of the Boost library (explained in more detail in Work on
aptitude).
Without that, possibly aptitude would not have survived until today.
Improvements to the suggestions of the resolver
In the version 0.8, there were a lot of changes related with improving
the order of the suggestions from the resolver, when it finds conflicts
or other problems with the planned actions.
Historically, but specially in the last few years, there have been many
complaints about the nonsensical or dangerous suggestions from the
resolver. The first solution offered by the resolver was very often
regarded as highly undesirable (for example, removal of many packages),
and preferable solutions like upgrades of one or only a handful of
packages being offered only after many removals; and keeps only
offered as last resort.
Perhaps these changes don't get a lot of attention, given that in the first case
it's just to keep working (with few people realising that it could have
collapsed on the spot, if left unattended), and the second can probably go
unnoticed because it just works or it started to work more smoothly
doesn't get as much immediate attention as it suddenly broke! .
Still, I wanted to mention them, because I am quite proud of those.
Thanks
Even if I put a lot of work on aptitude in the last year, the results of the
graph and numbers have not been solely achieved by me.
Special thanks go to Axel Beckert (abe /
XTaran) and the apt team, David
Kalnischkies and Julian Andres Klode who, despite the claim in that page, does
not mostly work python-aptanymore... but also in the main tools.
They help with fixing some of the issues directly, or changing things in apt
that benefit aptitude, testing changes, triaging bugs or commenting on them,
patiently explaining to me why something in libapt doesn't do what I think it
does, and good company in general.
Not the least, for holding impromptu BTS group therapy / support meetings, for
those cases when prolonged exposure to BTS activity starts to induce very bad
feelings.
Thanks also to people who sent their translation updates, notified about
corrections, sent or tested patches, submitted bugs, or tried to help in other
ways. Change logs for details.
Notes
[1] ^ It's even an example in
the Cambridge Dictionaries Online website, for the entry of roller
coaster:
He was on an emotional roller coaster for a while when he lost his job.
I should probably document the purple server I hacked together in Perl and mentioned in my last post. In short it allows you to centralise notifications. Send "alerts" to it, and when they are triggered they will be routed from that central location. There is only a primitive notifier included, which sends data to the console, but there are sample stubs for sending by email/pushover, and escalation.
In brief you create alerts by sending a JSON object via HTTP-POST. These objects contain a bunch of fields, but the two most important are:
id
A human-name for the alert. e.g. "disk-space", "heartbeat", or "unread-mail".
raise
When to raise the alert. e.g. "now", "+5m", "1466006086".
When an update is received any existing alert has its values updated, which
makes heartbeat alerts trivial. Send a message with:
"id": "heartbeat",
"raise": "+5m",
..
The existing alert will be updated each time such a new event is submitted,
which means that the time at which that alert will raise will be pushed back
by five minutes. If you send this every 60 seconds then you'll get informed
of an outage five minutes after your server explodes (because the "+5m"
will have been turned into an absolute time, and that time will eventually
become in the past - triggering a notification).
Alerts are keyed on the source IP which sent the submission and
the id field, meaning you can send the same update from multiple
hosts without causing any problems.
Notifications can be viewed in a reasonably pretty Web UI, so you can
clear raised-alerts, see the pending ones, and suppress further notifications
on something that has been raised. (By default notifications are issued
every sixty seconds, until the alert is cleared. There is support for
only raising an alert once, which is useful for services you might deliver
events via, such as pushover which will repeat themselves.)
Anyway this is a fun project, which is a significantly simplified and
less scalable version of a project which is open-sourced already and
used at Bytemark.
Author: ceridwen
The first, very-alpha release of reprotest is now out at
PyPi. It should hit
Debian experimental later this week. While it only builds on an
existing system (as I'm still working on support for virtualization),
it can now check its own reproducibility, which it does in its own
tests, both using setuptools and debuild. Unfortunately, setuptools
seems to generate file-order-dependent binaries, meaning python
setup.py bdist creates unreproducible binaries. With debuild,
reprotest probably would be reproducible with the modified
packages
from the Reproducible Builds project, though I haven't tested that
yet. It tests 'captures_environment', 'fileordering' (renamed from
'filesystem'), 'home', 'kernel', 'locales', 'path', 'time',
'timezone', and 'umask'. The other variations require superuser
privileges and modifications that would be unsafe to make to a running
system, so they will only be enabled in the containers.
The next major part of the project is integrating autopkgtests's
container management system into reprotest. For the curious,
autopkgtest is composed of a main program, adt-run, which then calls
other command-line programs, adt-virt-chroot, adt-virt-lxd,
adt-virt-schroot, adt-virt-null, adt-virt-schroot, and
adt-virt-qemu, that communicate with the containers. (The
autopkgtest maintainer has since renamed the programs, but the
underlying structure remains the same.) I think this is a bit of an
odd design but it works well for my purposes since the container
programs already have existing CLIs that reprotest can use.
Like each month, here comes a report about the work of paid contributors to Debian LTS.
Individual reports
In May, 166 work hours have been dispatched among 9 paid contributors. Their reports are available:
Evolution of the situation
The number of sponsored hours stayed the same over May but will likely increase a little bit the next month as we have two new Bronze sponsors being processed.
The security tracker currently lists 36 packages with a known CVE and the dla-needed.txt file lists 36 packages awaiting an update.
Despite the higher than usual number of work hours dispatched in May, we still have more open CVE than we used to have at the end of the squeeze LTS period. So more support is always needed
Thanks to our sponsors
New sponsors are in bold.
Elsa Bike Trophy 2016 my first bike race!
So today, after two months of intermittent training using Zwift and
some actual outside rides, I did my first bike race. Not of 2016,
not of 2000+, but like ever.
Which is strange, as I learned biking very young, and I did like to
bike. But as it turned out, even though I didn't like running as a
child, I did participate in a number of running events over the years,
but no biking ones.
The event
Elsa Bike Trophy is a
mountain bike event cross-country, not downhill or anything crazy; it
takes part in Estavayer-le-Lac, and has two courses - one 60Km with
1'791m altitude gain, and a smaller one of 30Km with 845m altitude
gain. I went, of course, for the latter. 845m is more than I ever did
in a single ride, so it was good enough for a first try. The web page
says that this smaller course est nerveux, technique et ne laisse
que peu de r pit . I choose to think that's a bit of an exaggeration,
and that it will be relatively easy (as I'm not too skilled
technically).
The atmosphere there was like for the running races, with the
exception of bike stuff being sold, and people on very noisy
rollers. I'm glad for my trainer which sounds many decibels quieter
The long race started at 12:00, and the shorter one at 12:20. While
waiting for the start I had to concerns in mind: whether I'm able to
do the whole course (endurance), and whether it will be too cold (the
weather kept moving towards rain). I had a small concern about the
state of the course, as it was not very nice weather recently, but a
small one.
And then, after one hour plus of waiting, go!
Racing, with a bit of "swimming"
At first thing went as expected. Starting on paved roads, moving
towards the small town exit, a couple of 14% climbs, then more flat
roads, then a nice and hard 18% short climb (I'll never again complain
about < 10%!), then entering the woods. It became quickly apparent
that the ground in the forest was in much worse state than I
feared. Much worse as in a few orders of magnitude.
In about 5 minutes after entering the tree cover, my reasonably clean,
reasonably light bike became a muddy, heavy monster. And the pace that
until then went quite OK became walking pace, as the first rider that
didn't manage to keep going up because the wheel turned out of the
track blocked the one behind him, which had to stop, and repeat until
we were one line (or two, depending on how wide the trail was) of
riders walking their bikes up. While on dry ground walking your bike
up is no problem, or hiking through mud with good hiking shoes is also
no problem, walking up with biking shoes is a pain. Your foot slides
and you waste half of your energy "swimming" in the mud.
Once the climb is over, you get on the bike, and of course the pedals
and cleats are full of heavy mud, so it takes a while until you can
actually clip in. Here the trail version of SPD was really useful, as
I could pedal reasonably well without being clipped-in, just had to be
careful and push too hard.
Then maybe you exit the trail and get on paved road, but the wheels
are so full of mud that you still are very slow (and accelerate very
slowly), until the shed enough of the mud to become somewhat more
"normal".
After a bit of this "up through mud, flat and shedding mud", I came
upon the first real downhill section. I would have been somewhat
confident in dry ground, but I got scared and got off my bike. Better
safe than sorry was the thing for now.
And after this is was a repetition of the above: climb, sometimes
(rarely) on the bike, most times pushing the bike, fast flat sections
through muddy terrain where any mistake of controlling the bike can
send the front wheel flying due to the mud being highly viscous, slow
flat sections through very liquid mud where it definitely felt like
swimming, or any dry sections.
My biggest fear, uphill/endurance, was unfounded. The most gains I
made were on the dry uphills, where I had enough stamina to
overtake. On flat ground I mostly kept order (i.e. neither being
overtaken nor overtaking), but on downhill sections, I lost lots of
time, and was overtaken a lot. Still, it was a good run.
And then, after about 20 kilometres out of the 30, I got tired enough
of getting off the bike, on the bike, and also tired mentally and not
being careful enough, that I stopped getting off the bike on
downhills. And the feeling was awesome! It was actually much much
easier to flow through the mud and rocks and roots on downhill, even
when it was difficult (for me) like 40cm drops (estimated), than doing
it on foot, where you slide without control and the bike can come
crashing down on you. It was a liberating feel, like finally having
overcome the mud. I was soo glad to have done a one-day training
course with
Swiss Alpine Adventure,
as it really helped. Thanks Dave!
Of course, people were still overtaking me, but I also overtook some
people (who were on foot; he he, I wasn't the only one it seems). And
being easier, I had some more energy so I was able to push a bit
harder on the flats and dry uphill sections.
And then the remaining distance started shrinking, and the last
downhill was over, I entered through familiar roads the small town, a
passer-by cries "one kilometre left", I push hard (I mean, hard as I
could after all the effort), and I reach the finish.
Oh, and my other concern, the rain? Yes it did rain somewhat, and I
was glad for it (I keep overheating); there was a single moment I felt
cold, when exiting a nice cosy forest into a field where the wind was
very strong headwind, of course.
Lessons learned
I did learn a lot in this first event.
indoor training sessions only help with endurance (but they do good
on this); they don't help with technique, and most importantly, they
don't teach how to handle the bike in inclement weather; biking to
work on paved road also doesn't help.
nevertheless, indoor training does help with endurance
mud guards ; before the race, I thought they'll help; during the
race, I cursed at the extra weight and their seemingly uselessness;
after the race, after I saw how other people looked, I realised that
indeed they helped a lot I was only dirty on my legs, mostly below
the knee, but not on my upper body. Unsure whether I will use the
again.
a drop seat is not needed if your seat is set in-between, but sure
damn would have been more easy with one
installing your GPS on your handle-bar with elastic bands in a
section of non-constant diameter is a very bad idea, as it lives in
an unstable equilibrium: any move towards the thinner section makes
the mount very loose, and you have to lose time fixing it.
Results
So, how did I do after all? As soon as I reached the finish and
recovered my items, among which the phone, I checked the datasport
page: I was rank 59/68 in my category. Damn, I hoped (and thought) I
would do better. Similar % in the overall ranking for this distance.
That aside, it was mighty fun. So much fun I'd do it again tomorrow! I
forgot the awesome atmosphere of such events, even in the back of the
rankings.
And then, after I reach drive home and open on my workstation the
datasport page, I get very confused: the overall number of
participants was different. And the I realised: not everybody finished
the race when I first checked (d'oh)! Final ranking: 59 out of 84 in
my category,
and 247/364 in the
overall 30km rankings. That
makes it 70% and 67% respectively, which matches somewhat with my
usual running results a few years back (but a bit worse). It is in any
case better than what I thought originally, yay!
Also, Strava activity for some more statistics (note that my Garmin
says it was not 800+ meters of altitude ):
I'd embed a Veloviewer nice 3D-map but I can't seem to get the embed
option, hmm
TODO: train more endurance, train more technique, train in more
various conditions!
TL;DR: I put a $5 Raspberry Pi Zero, a Bluetooth USB dongle, and the
required adapter cable into my new Handy Tech Active Star 40 braille
display. An internal USB port provides the power. This has transformed
my braille display into an ARM-based, monitorless, Linux laptop that has
a keyboard and a braille display. It can be charged/powered via USB so it can
also be run from a power bank or a solar charger, thus potentially being able
to run for days, rather than just hours, without needing a standard wall-jack.
Some Background on Braille Display Form Factors
Braille displays come in various sizes. There are
models tailored for desktop use (with 60 cells or more), models tailored
for portable use with a laptop (usually with 40 cells), and, nowadays,
there are even models tailored for on-the-go use with a smartphone or similar
(with something like 14 or 18 cells).
Back in the old days, braille displays were rather massive.
A 40-cell braille display was typically about the size of a 13" laptop.
In modern times, manufacturers have managed to reduce the size of the internals
such that a 40-cell display can be placed in front of a laptop or keyboard
instead of placing the laptop on top of the braille display.
While this is a nice achievement, I personally haven't found it to be
very convenient because you now have to place two physically separate
devices on your lap. It's OK if you have a real desk,
but, at least in my opinion, if you try to use your laptop as its name suggests,
it's actually inconvenient to use a small form factor, 40-cell display.
For this reason, I've been waiting for a long-promised new model
in the Handy Tech Star series. In 2002, they released
the Handy Tech Braille Star 40, which is a 40-cell braille
display with enough space to put a laptop directly on top
of it. To accommodate larger laptop models, they even built in a little
platform at the back that can be pulled out to effectively enlarge the
top surface.
Handy Tech has now released a new model, the Active Star 40,
that has essentially the same layout but modernized internals.
You can still pull out the little platform to increase the space
that can be used to put something on top.
But, most conveniently,
they've designed in an empty compartment, roughly the size of a modern
smartphone, beneath the platform. The original idea was to actually
put a smartphone inside, but this has turned out (at least to me)
to not be very feasible. Fortunately, they thought about the
need for electricity and added a Micro USB cable terminating within the
newly created, empty compartment.
My first idea was to put a conventional Raspberry Pi inside.
When I received the braille display, however, we immediately
noticed that a standard-sized rpi is roughly 3mm too high
to fit into the empty compartment.
Fortunately, though, a co-worker noticed that the Raspberry Pi Zero
was available for order. The Raspberry Pi Zero is a lot thinner,
and fits perfectly inside (actually, I think there's enough space
for two, or even three, of them). So we ordered one, along with some
accessories like a 64GB SDHC card, a Bluetooth dongle, and
a Micro USB adapter cable. The hardware arrived a few days later, and was
immediately bootstrapped with the assistance of very helpful friends.
It works like a charm!
Technical Details
The backside of the Handy Tech Active Star 40 features two USB host ports
that can be used to connect devices such as a keyboard. A small form-factor,
USB keyboard with a magnetic clip-on is included. When a USB keyboard
is connected, and when the display is used via Bluetooth, the braille display
firmware additionally offers the Bluetooth HID profile, and key press/release
events received via the USB port are passed through to it.
I use the Bluetooth dongle for all my communication needs.
Most importantly, BRLTTY is used as a console screen reader.
It talks to the braille display via Bluetooth (more precisely, via an RFCOMM channel).
The keyboard connects through to Linux via the Bluetooth HID profile.
Now, all that is left is network connectivity. To keep the energy
consumption as low as possible, I decided to go for Bluetooth PAN.
It appears that the tethering mode of my mobile phone works (albeit with a quirk),
so I can actually access the internet as long as I have cell phone reception.
Additionally, I configured a Bluetooth PAN access point on my desktop
machines at home and at work, so I can easily (and somewhat more reliably)
get IP connectivity for the rpi when I'm near one of these machines.
I plan to configure a classic Raspberry Pi as a mobile Bluetooth access point.
It would essentially function as a Bluetooth to ethernet adapter, and should
allow me to have network connectivity in places where I don't want to use my phone.
BlueZ 5 and PAN
It was a bit challenging to figure out how to actually configure
Bluetooth PAN with BlueZ 5. I found the bt-pan python script
(see below) to be the only way so far to configure PAN without a GUI.
It handles both ends of a PAN network, configuring a server and a client.
Once instructed to do so (via D-Bus) in client mode, BlueZ will
create a new network device - bnep0 - once a connection to a server has been
established. Typically, DHCP is used to assign IP addresses
for these interfaces. In server mode, BlueZ needs to know the
name of a bridge device to which it can add a slave device for
each incoming client connection. Configuring an address for
the bridge device, as well as running a DHCP server + IP Masquerading
on the bridge, is usually all you need to do.
Now, BlueZ needs to be told to configure a NAP profile.
To my surprise, there seems to be no way to do this with stock BlueZ 5.36
utilities. Please correct me if I'm wrong.
Luckily, I found a very nice blog post, as well as an accommodating
Python script that performs the required D-Bus calls.
For convenience, I use a Systemd service to invoke the script
and to ensure that its dependencies are met.
/etc/systemd/system/pan.service:
[Unit]
Description=Bluetooth Personal Area Network
After=bluetooth.service systemd-networkd.service
Requires=systemd-networkd.service
PartOf=bluetooth.service
[Service]
Type=notify
ExecStart=/usr/local/sbin/pan
[Install]
WantedBy=bluetooth.target
/usr/local/sbin/pan:
#!/bin/sh# Ugly hack to work around #787480
iptables -F
iptables -t nat -F
iptables -t mangle -F
iptables -t nat -A POSTROUTING -o eth0 -j MASQUERADE
exec /usr/local/sbin/bt-pan --systemd --debug server pan
This last file wouldn't be necessary if IPMasquerade= were
supported in Debian right now (see #787480).
After the obligatory systemctl daemon-reload and systemctl restart systemd-networkd,
you can start your Bluetooth Personal Area Network with systemctl start pan.
Bluetooth PAN Client with Systemd
Configuring the client is also quite easy to do with Systemd.
/etc/systemd/network/pan-client.network:
[Match]
Name=bnep*
[Network]
DHCP=yes
/etc/systemd/system/pan@.service:
[Unit]
Description=Bluetooth Personal Area Network client
[Service]
Type=notify
ExecStart=/usr/local/sbin/bt-pan --debug --systemd client %I --wait
Now, after the usual configuration reloading, you should be able to connect
to a specific Bluetooth access point with:
systemctl start pan@00:11:22:33:44:55
Pairing via the Command Line
Of course, the server and client-side service configuration require
a pre-existing pairing between the server and each of its clients.
On the server, start bluetoothctl and issue the following commands:
power on
agent on
default-agent
scan on
scan off
pair XX:XX:XX:XX:XX:XX
trust XX:XX:XX:XX:XX:XX
Once you've set scan mode to on, wait a few seconds until
you see the device you're looking for scroll by. Note its
device address, and use it for the pair and (optional) trust commands.
On the client, the sequence is essentially the same except that
you don't need to issue the trust command. The server needs
to trust a client in order to accept NAP profile connections from it
without waiting for manual confirmation by the user.
I'm actually not sure if this is the optimal sequence of commands.
It might be enough to just pair the client with the server
and issue the trust command on the server,
but I haven't tried this yet.
Enabling Use of the Bluetooth HID Profile
Essentially the same as above also needs to be done
in order to use the Bluetooth HID profile of the Active Star 40 on Linux.
However, instead of agent on, you need to issue the command agent KeyboardOnly.
This explicitly tells bluetoothctl that you're specifically looking for a HID profile.
Configuring Bluetooth via the Command Line Feels Vague
While I'm very happy that I actually managed to set all of this up,
I must admit that the command-line interface to BlueZ feels
a bit incomplete and confusing. I initially thought that agents
were only for PIN code entry. Now that I've discovered that "agent KeyboardOnly"
is used to enable the HID profile, I'm not sure anymore.
I'm surprised that I needed to grab a script from a random git repository
in order to be able to set up PAN. I remember, with earlier version of BlueZ,
that there was a tool called pand that you could use to do all of this
from the command-line. I don't seem to see anything like that
for BlueZ 5 anymore. Maybe I'm missing something obvious?
Performance
The data rate is roughly 120kB/s, which I consider acceptable for such a low
power solution.
The 1GHz ARM CPU actually feels sufficiently fast for a console/text-mode
person like me.
I'll rarely be using much more than ssh and emacs on it anyway.
Console fonts and screen dimensions
The default dimensions of the framebuffer on the Raspberry Pi Zero are a bit
unexpectedly strange. fbset reports that the screen dimension
is 656x416 pixels (of course, no monitor connected). With a typical console
font of 8x16, I got 82 columns and 26 lines.
With a 40 cell braille display, the 82 columns are very inconvenient.
Additionally, as a braille user, I would like to be able to view Unicode
braille characters in addition to the normal charset on the console.
Fortunately, Linux supports 512 glyphs, while most console fonts
do only provide 256. console-setup can load and combine two
256-glyph fonts at once. So I added the following to /etc/default/console-setup
to make the text console a lot more friendly to braille users:
You need console-braille installed for brl-16x8.psf to be available.
Further Projects
There's a 3.5mm audio jack inside the braille display as well.
Unfortunately, there are no converters from Mini-HDMI to 3.5mm audio
that I know of. It would be very nice to be able to use the
sound card that is already built into the Raspberry Pi Zero,
but, unfortunately, this doesn't seem possible at the moment.
Alternatively, I'm looking at using a Micro USB OTG hub and an
additional USB audio adapter to get sound from the Raspberry Pi Zero
to the braille display's speakers. Unfortunately, the two USB audio
adapters I've tried so far have run hot for some unknown reason.
So I have to find some other chipset to see if the problem goes away.
A little nuisance, currently, is that you need to manually power off
the Raspberry, wait a few seconds, and then power down the braille display.
Turning the braille display off cuts power delivery via the internal USB port.
If this is accidentally done too soon then the Raspberry Pi Zero
is shut down ungracefully (which is probably not the best way to do it).
We're looking into connecting a small, buffering battery to the GPIO pins
of the rpi, and into notifying the rpi when external power has dropped.
A graceful, software-initiated shutdown can then be performed.
You can think of it as being like a mini UPS for Micro USB.
The image
If you are a happy owner of a Handy Tech Active Star 40 and would like
to do something similar, I am happy to share my current
(Raspbian Stretch based) image. In fact, if there is enough interest by
other blind users, we might even consider putting a kit together that makes it
as easy as possible for you to get started. Let me know if this could be
of interest to you.
Thanks
Thanks to Dave Mielke for reviewing the text of this posting.
Thanks to Simon Kainz for making the photos for this article.
And I owe a big thank you to my co-workers at Graz University
of Technology who have helped me a lot to bootstrap really quickly into the
rpi world.
P.S.
My first tweet about this topic is just
five days ago, and apart from the soundcard not working yet, I feel
like the project is already almost complete! By the way, I am editing
the final version of this blog posting from my newly created monitorless
ARM-based Linux laptop via an ssh connection to my home machine.
A longish blog post, please bear, a second part of the blog post would be published in few days from now. My fixed visa finally arrived, yeah But this story doesn t start here, it starts about a year back. While I have been contributing to Debian in my free time over the years, and sometimes paid time as well, I had never thought of going overseas as the experiences I knew from friends and relatives, it isn t easy to get all the permissions and paperwork done to say the least (bureaucracy @ work). But last year, when Debconf 15 was being launched, there are/were 2-3 friends of mine who are studying, doing their Ph.D. in some computer/web stuff, living in Germany currently that they goaded me to apply. The first few times I gave some standard excuses, but when they kept on for a while, just to shut them up I applied to the debconf team applying for food, accommodation and travel sponsorship.
I didn t have high hopes as there obviously are many more talented peers around me who understand FOSS and Debian at a much more fundamental, philosophical as well as technical level than me. Much to my surprise though, about a month (and around two or three weeks just before the event was about to take place) I got the bursary/sponsorships for food, accommodation as well as travel. I was unsure that the remaining time was enough to get a visa hence declined that time around.
That whole episode gave me the confidence that perhaps my application would be accepted if I applied again. Using my previous years understanding, decided to give it a shot again as this would also enable me to get a feel of visa bureaucracy as well as gain a bit of novice understanding about what factors go in choosing a flight and believe me the latter part proved to be pretty confusing. While the visa business seems easy, the form at least is easy and what they ask, it can be troublesome as far as visa-processing process is concerned. It took a better part of the month to get the visa which I needed. The in-between time is and can be a bit stressful as you have committed funds for travel i.e. the airline tickets and are in a limbo as you didn t know that if the visa is cancelled for some reason, your tickets would be refunded or not. A little history is needed and hopefully is helpful for anybody who s applying for a short-stay Visa in South Africa.
Exactly, A month and day back I had applied for visa. The visa I had applied for is 17 days as the flights within my budget was for those days only. The visa I got was for 10 days only which was ending in the middle of the conference. I tried many avenues to get information and was told that I needed to write a correction letter telling/sharing the information about the correct time period and dates in BOLD with a heavier weight/point which is what I did and gave to VFS office without any further payment on my part. It took a bit more time than the first time around but the consulate co-operated. While I can understand the oversight as they probably get more visas requests along with special and urgent requests so such occurrences can happen. I am and was happy that there was a recourse rather than starting from scratch which probably would have made me more anxious due to the first experience .
Apparently I was lucky that I had done with Qatar Airways as later came to know that there are other airways which don t refund money even after visa rejection . This information I got to know pretty late in the game otherwise I wouldn t have been much stressed. As had committed knew had to go the whole hog and whatever barriers are there, have overcome at least as far as the visa part/process is concerned.
Now after few days, will probably start to worry about the actual travel, part nervousness, part excitement, nervousness as it will be an alien land, am obese so traveling economy on 787-8 and 777-300 ER will be tricky. The 787-8 will probably be a rough ride as it s a 9 hr. journey and the seat are a mere 18 , the cattle class as shared by one of our esteemed politicians. This blame has to do with Boeing 787 rather than anybody else. Hopefully, if there is a next time, would make better choices.
Anyways,have selected an aisle seat so that will be able to walk every hr. or so to get the circulation in legs going as leg room in economy is not much from my domestic air travel experiences. If I do survive the travel, then will see South Africa and try to get some free time and explore South Africa and try to figure out how are they able to get one and half time tourists while we get around half figure for a whole year even though we are bigger (area-wise) to South Africa. I did find something positive for us as well, it s not all doldrums all around.
Now, I had been thinking about if I know any South African music and movies. I had explored djembe while growing up in teens but other than that, not much. The only music I have heard is Harry Belafonte . So I hope to bring some Indian movies and music with me so that people if they have not explored Bollywood as well as Indian classical music could explore some of it, of course it will be pale imitation of what Sawai Gandharva Music Festival for instance gives. I also hope to hear and get some music and movies to learn more about South Africa. Filed under: Miscellenous Tagged: #bollywood, #Debconf Germany 2015, #Debconf South Africa 2016, #Debconf15, #Debconf16, #djembe, #South-African consulate, music, tourism, visa
After introducing ourselves to the community, we start contributing to the open and free source software. Since this is the first week, I have went through theories which would help me in coding. Before coding it is always safer to refer to theories so that we don t need to spare time in debugging.
The following were my week 1-4 plans:
Getting familiar with Python and coding for connecting to an email account (using IMAP) and examines every message in every folder.
Writing a basic Python script to look at the To , From and CC headers of every email message in the folder. Identifying all the names and email addresses and writing them in a CSV file.
Scanning the body of each message looking for phone numbers.(for messages in plain text format)
Cleaning up the phone numbers and write them in international format and putting those in the CSV file too.(Telify recognizes phone numbers on web pages or in email messages and converts them into clickable links. This works with many CTI applications, SIP clients, Skype, Netmeeting, snom phones, the AGFEO TK-Suite client, SerVonic IXI-PCS and others. In general, all telephony software, devices or interfaces which can be controlled by using a URL, will most likely enable you to call a phone number directly from your browser or email client.
These two weeks I have completed my first two tasks in the list.I have committed and pushed my works in GitHub.https://github.com/Jaminy/GSoC
Successfully logged into the email account using IMAP and examined each folders.Examined inbox to extract To , From and CC of the last message received.Trying to extract all message details to put in CSV file.
GSoC students have officially been coding since 23 May (about 2.5 weeks) and are almost half-way to the mid-summer evaluation (20 - 27 June). Students who haven't completed some meaningful work before that deadline don't receive payment and in such a large program, there is no possibility to give students extensions or let them try and catch up later.
Every project and every student are different, some are still getting to know their environment while others have already done enough to pass the mid-summer evaluation.
I'd like to share a few tips to help students ensure they don't inadvertently fail the mid-summer evaluation
Kill electronic distractions
As a developer of real-time communications projects, many people will find it ironic or hypocritical that this is at the top of my list.
Switch off the mobile phone or put it in silent mode so it doesn't even vibrate. Research has suggested that physically turning it off and putting it out of sight has significant benefits. Disabling the voicemail service can be an effective way of making sure no time is lost listening to a bunch of messages later. Some people may grumble at first but if they respect you, they'll get into the habit of emailing you and waiting for you to respond when you are not working.
Get out a piece of paper and make a list of all the desktop notifications on your computer, whether they are from incoming emails, social media, automatic updates, security alerts or whatever else. Then figure out how to disable them all one-by-one.
Use email to schedule fixed times for meetings with mentors. Some teams/projects also have fixed daily or weekly times for IRC chat. For a development project like GSoC, it is not necessary or productive to be constantly on call for 3 straight months.
Commit every day
Habits are a powerful thing. Successful students have a habit of making at least one commit every day. The "C" in GSoC is for Code and commits are a good way to prove that coding is taking place.
GSoC is not a job, it is like a freelance project. There is no safety-net for students who get sick or have an accident and mentors are not bosses, each student is expected to be their own boss. Although Google has started recommending students work full time, 40 hours per week, it is unlikely any mentors have any way to validate these hours. Mentors can look for a commit log, however, and simply won't be able to pass a student if there isn't code.
There may be one day per week where a student writes a blog or investigates a particularly difficult bug and puts a detailed report in the bug tracker but by the time we reach the second or third week of GSoC, most students are making at least one commit in 3 days out of every 5.
Consider working away from home/family/friends
Can you work without anybody interrupting you for at least five or six hours every day?
Do you feel pressure to help with housework, cooking, siblings or other relatives? Even if there is no pressure to do these things, do you find yourself wandering away from the computer to deal with them anyway?
Do family, friends or housemates engage in social activities, games or other things in close proximity to where you work?
All these things can make a difference between passing and failing.
Maybe these things were tolerable during high school or university. GSoC, however, is a stepping stone into professional life and that means making a conscious decision to shut those things out and focus. Some students have the ability to manage these distractions well, but it is not for everybody. Think about how leading sports stars or musicians find a time and space to be "in the zone" when training or rehearsing, this is where great developers need to be too.
Some students find the right space in a public library or campus computer lab. Some students have been working in hacker spaces or at empty desks in local IT companies. These environments can also provide great networking opportunities.
Managing another summer job concurrently with GSoC
It is no secret that some GSoC students have another job as well. Sometimes the mentor is aware of it, sometimes it has not been disclosed.
The fact is, some students have passed GSoC while doing a summer job or internship concurrently but some have also failed badly in both GSoC and their summer job. Choosing one or the other is the best way to succeed, get the best results and maximize the quality of learning and community interaction. For students in this situation, now it is not too late to make the decision to withdraw from GSoC or the other job.
If doing a summer job concurrently with GSoC is unavoidable, the chance of success can be greatly increased by doing the GSoC work in the mornings, before starting the other job. Some students have found that they actually finish more quickly and produce better work when GSoC is constrained to a period of 4 or 5 hours each morning and their other job is only in the afternoon. On the other hand, if a student doesn't have the motivation or energy to get up and work on GSoC before the other job then this is a strong sign that it is better to withdraw from GSoC now.
I'll tune in to the post-based conversation being held on Planet Debian: Russell Coker wonders about what's needed to get university graduates with enough skills for a sysadmin job, to which Lucas Nussbaum responds with his viewpoints. They present a very contrasting view of what's needed for students And for a good reason, I'd say: Lucas is an academician; I don't know for sure about Russell, but he seems to be a down-to-the-earth, dirty-handed, proficient sysadmin working on the field. They both contact newcomers to their fields, and will notice different shortcomings.
I tend to side with Lucas' view. That does not come as a surprise, as I've been working for over 15 years in an university, and in the last few years I started walking from a mostly-operative sysadmin in an academic setting towards becoming an academician that spends most of his time sysadmining. Subtle but important distinction.
I teach at the BSc level at UNAM, and am a Masters student at IPN (respectively, Mexico's largest and second-largest universities). And yes, the lack of sysadmin abilities in both is surprising. But so is a good understanding of programming. And I'm sure that, were I to dig into several different fields, I'd feel the same: Student formation is very basic at each of those fields.
But I see that as natural. Of course, if I were to judge people as geneticists as they graduate from Biology, or were I to judge them as topologists as they graduate from Mathematics, or any other discipline in which I'm not an expert, I'd surely not know where to start Given I have about 20 years of professional life on my shoulders, I'm quite skewed as to what is basic for a computing professional. And of course, there are severe holes in my formation, in areas I never used. I know next to nothing of electronics, my mathematical basis is quite flaky, and I'm a poor excuse when talking about artificial intelligence.
Where am I going with this? An university degree (BSc in English, would amount to "licenciatura" in Spanish) is not for specialization. It is to have a sufficiently broad panorama of the field, and all of the needed tools to start digging deeper and specializing either by yourself, working on a given field and learning its details as you go, or going through a postgraduate program (Specialization, Masters, Doctorate).
Even most of my colleagues at the Masters in Engineering in Security and Information Technology lack of a good formation in fields I consider essential. However, what does information security mean? Many among them are working on legal implications of several laws that touch our field. Many other are working on authenticity issues in images, audios and other such media. Many other are trying to come up with mathematical ways to cheapen the enormous burden of crypto operations (say, "shaving" CPU cycles off a very large exponentiation). Others are designing autonomous learning mechanisms to characterize malware. Were I as a computing professional to start talking about their research, I'd surely reveal I know nothing about it and get laughed at. That's because I haven't specialized in those fields.
University education should give a broad universal basis to enter a professional field. It should not focus on teaching tools or specific procedures (although some should surely be presented as examples or case studies). Although I'd surely be happy if my university's graduates were to know everything about administering a Debian system, that would be wrong for a university to aim at; I'd criticize it the same way I currently criticize programs that mix together university formation and industry certification as if they were related.
What happened in the Reproducible
Builds effort between May 29th and June 4th 2016:
Media coverage
Ed Maste will present Reproducible Builds in FreeBSD at BDSCan 2016 in Ottawa, Canada on June 11th.
GSoC and Outreachy updates
Paul Gevers uploaded fpc/3.0.0+dfsg-5 with a new helper script fp-fix-timestamps, which helps with reproducibility issues of PPU files in freepascal packages.
Sascha Steinbiss uploaded a patched version of epydoc to our experimental repository to test a patch for the use_epydoc issue.
Improved rescheduling of packages in "depwait" state (h01ger)
Use eatmydata on i386+armhf (h01ger) (doesn't work yet; needs unreleased pbuilder features)
Misc.
Last week we also learned about progress of reproducible builds in FreeBSD. Ed Maste announced a change to record the build timestamp during ports building, which is required for later reproduction.
This week's edition was written by Reiner Herrman, Holger Levsen and Chris Lamb and reviewed by a bunch of Reproducible builds folks on IRC.
Russell Coker wrote about Sysadmin Skills and University Degrees. I couldn t agree more that a major deficiency in Computer Science degrees is the lack of sysadmin training. It seems like most sysadmins learned most of what they know from experience. It s very hard to recruit young engineers (freshly out of university) for sysadmin jobs, and the job interviews are often a bit depressing. Sysadmins jobs are also not very popular with this public, probably because university curriculums fail to emphasize what s exciting about those jobs.
However, I think I disagree rather deeply with Russell s detailed analysis.
First, Version Control. Well, I think that it s pretty well covered in university curriculums nowadays. From my point of view, teaching CS in Universit de Lorraine (France), mostly in Licence Professionnelle Administration de Syst mes, R seaux et Applications base de Logiciels Libres (warning: french), a BSc degree focusing on Linux systems administration, it s not usual to see student projects with a mandatory use of Git. And it doesn t seem to be a major problem for students (which always surprises me). However, I wouldn t rate Version Control as the most important thing that is required for a sysadmin. Similarly Dependencies and Backups are things that should be covered, but probably not as first class citizens.
I think that there are several pillars in the typical sysadmin knowledge.
First and foremost, sysadmins need a good understanding of the inner workings of an operating system. I sometimes feel that many Operating Systems Design courses are a bit too much focused on the Design side of things. Yes, it s useful to understand the low-level mechanisms, and be able to (mentally) recreate an OS from scratch. But it s also interesting to know how real systems are actually built, and what are the trade-off involved. I very much enjoyed reading Branden Gregg s Systems Performance: Enterprise and the Cloud because each chapter starts with a great overview of how things are in the real world, with a very good level of detail. Also, addressing OS design from the point of view of performance could be a way to turn those courses into something more attractive for students: many people like to measure, benchmark, optimize things, and it s quite easy to demonstrate how different designs, or different configurations, make a big difference in terms of performance in the context of OS design. It s possible to be a sysadmin and ignore, say, the existence of the VFS, but there s a large class of problems that you will never be able to solve. It can be a good trade-off for a curriculum (e.g. at the BSc level) to decide to ignore most of the low-level stuff, but it s important to be aware of it.
Students also need to learn how to design a proper infrastructure (that meets requirements in terms of scalability, availability, security, and maybe elasticity). Yes, backups are important. But monitoring is, too. As well as high availability. In order to scale, it s important to be able to automatize stuff. Russell writes that Sysadmins need some programming skills, but that s mostly scripting and basic debugging. Well, when you design an infrastructure, or when you use configuration management tools such as Puppet, in some sense, you are programming, and in terms of needs to abstract things, it s actually similar to doing object-oriented programming, with similar choices (should I use that off-the-shelf puppet module, or re-develop my own? How should everything fit together?). Also, when debugging, it s often useful to be able to dig into code, understand what the developer was trying to do, and if the expected behavior actually matches what you are seeing. It often results in spending a lot of time to create a one-line fix, and it requires very advanced programming skills. Again, it s possible to be a sysadmin with only limited software development knowledge, but there s a large class of things that you are unlikely to address properly.
I think that what makes sysadmins jobs both very interesting and very challenging is that they require a very wide range of knowledge. There s often the ability to learn about new stuff (much more than in software development jobs). Of course, the difficult question is where to draw the line. What is the sysadmin knowledge that every CS graduate should have, even in curriculums not targeting sysadmin jobs? What is the sysadmin knowledge for a sysadmin BSc degree? for a sysadmin MSc degree?
I think that a major deficiency in Computer Science degrees is the lack of sysadmin training.
Version Control
The first thing that needs to be added is the basics of version control. CVS (which is now regarded as obsolete) was initially released when I was in the first year of university. But SCCS and RCS had been in use for some time. I think that the people who designed my course were remiss in not adding any mention of version control (not even strategies for saving old versions of your work), one could say that they taught us about version control by letting us accidentally delete our assignments. :-#
If a course is aimed at just teaching programmers (as most CS degrees are) then version control for group assignments should be a standard part of the course. Having some marks allocated for the quality of comments in the commit log would also be good.
A modern CS degree should cover distributed version control, that means covering Git as it s the most popular distributed version control system nowadays.
For people who want to work as sysadmins (as opposed to developers who run their own PCs) a course should have an optional subject for version control of an entire system. That includes tools like etckeeper for version control of system configuration and tools like Puppet for automated configuration and system maintenance.
Dependencies
It s quite reasonable for a CS degree to provide simplified problems for the students to solve so they can concentrate on one task. But in the real world the problems are more complex. One of the more difficult parts of managing real systems is dependencies. You have issues of header files etc at compile time and library versions at deployment. Often you need a program to run on systems with different versions of the OS which means making it compile for both and deal with differences in behaviour.
There are lots of hacky things that people do to deal with dependencies in systems. People link compiled programs statically, install custom versions of interpreters in user home directories or /usr/local for daemons, and do many other things. These things can have bad consequences including data loss, system downtime, and security problems. It s not always wrong to do such things, but it s something that should only be done with knowledge of the potential consequences and a plan for mitigating them. A CS degree should teach the potential advantages and disadvantages of these options to allow graduates to make informed decisions.
Backups
I ve met many people who call themselves computer professionals and think that backups aren t needed. I ve seen production systems that were designed in a way that backups were impossible. The lack of backups is a serious problem for the entire industry.
Some lectures about backups could be part of a version control subject in a general CS degree. For a degree that majors in Sysadmin at least one subject about backups is appropriate.
For any backup (even backing up your home PC) you should have offsite backups to deal with fire damage, multiple backups of different ages (especially important now that encryption malware is a serious threat), and a plan for how fast you can restore things.
The most common use of backups is to deal with the case of deleting the wrong file. Unfortunately this case seems to be the most rarely mentioned.
Another common situation that should be covered is a configuration error that results in a system that won t boot correctly. It s a very common problem and one that can be solved quickly if you are prepared but which can take a long time if you aren t.
For a Sysadmin course it is important to cover backups of systems in remote datacenters.
Hardware
A good CS degree should cover the process of selecting suitable hardware. Programmers often get to advise on the hardware used to run their code, especially at smaller companies. Reliability features such as RAID, ECC RAM, and clustering should be covered.
Planning for upgrades is a very important part of this which is usually not taught. Not only do you need to plan for an upgrade without much downtime or cost but you also need to plan for what upgrades are possible. Next year will your system require hardware that is more powerful than you can buy next year? If so you need to plan for a cluster now.
For a Sysadmin course some training about selecting cloud providers and remote datacenter hosting should be provided. There are many complex issues that determine whether it s most appropriate to use a cloud service, hosted virtual machines, hosted physical servers managed by the ISP, hosted physical servers purchased by the client, or on-site servers. Often a large system will involve 2 or more of those options, even some small companies use 3 or more of those options to try and provide the performance and reliability they need at a price they can afford.
We Need Sysadmin Degrees
Covering the basic coding skills takes a lot of time. I don t think we can reasonably expect a CS degree to cover all that and also give good coverage to sysadmin work. While some basic sysadmin skills are needed by every programmer I think we need to have separate majors for people who want a career in system administration.
Sysadmins need some programming skills, but that s mostly scripting and basic debugging. Someone who s main job is as a sysadmin can probably expect to never make any significant change to a program that s more than 10,000 lines long. A large amount of the programming in a CS degree can be replaced by file a bug report for a sysadmin degree.
This doesn t mean that sysadmins shouldn t be doing software development or that they aren t good at it. One noteworthy fact is that it appears that the most common job among developers of the Debian distribution of Linux is System Administration. Developing an OS involves some of the most intensive and demanding programming. But I think that more than a few people who do such work would have skipped a couple of programming subjects in favour of sysadmin subjects if they were given a choice.
Suggestions
Did I miss anything? What other sysadmin skills should be taught in a CS degree?
Do any universities teach these things now? If so please name them in the comments, it is good to help people find universities that teach them what they want to learn and help them in their career.
In order to monitor some of the machines I
maintain, I rely
on a simple email setup using
logcheck. Unfortunately that
system completely breaks down if mail delivery stops.
This is the simple setup I've come up with to ensure that mail doesn't
pile up on the remote machine.
Server setup
The first thing I did on the server-side is to follow Sean Whitton's
advice and configure
postfix so that it keeps undelivered emails for 10 days (instead of 5 days,
the default):
postconf -e maximal_queue_lifetime=10d
Then I created a new user:
adduser mailq-check
with a password straight out of pwgen -s 32.
I gave ssh
permission to
that user:
adduser mailq-check sshuser
and then authorized my new ssh key (see next section):
and that's it. I get a (locally delivered) email whenever the mail queue on
the server is non-empty.
There is a race condition built into this setup since it's possible that the
server will want to send an email at 2am. However, all that does is send a
spurious warning email in that case and so it's a pretty small price to pay
for a dirt simple setup that's unlikely to break.

 I'm back from the GTK hackfest in Toronto, Canada and mostly recovered from
jetlag, so it's time to write up my notes on what we discussed there.
Despite the hackfest's title, I was mainly there to talk about non-GUI
parts of the stack, and technologies that fit more closely in what could
be seen as the freedesktop.org platform than they do in GNOME. In particular,
I'm interested in Flatpak as a way to deploy self-contained "apps" in a
freedesktop-based, sandboxed runtime environment layered over

 We are using
 Up next:
Finish converting package set script, create more mustache templates, more site improvements! Then fly to South Africa.
 As some of the world knows full well by now, I've been noodling with Go
for a few years, working through its pros, its cons, and thinking a lot
about how humans use code to express thoughts and ideas. Go's got a lot of
neat use cases, suited to particular problems, and used in the right place,
you can see some clear massive wins.
I've started writing Debian tooling in Go, because it's a pretty natural fit.
Go's fairly tight, and overhead shouldn't be taken up by your operating system.
After a while, I wound up hitting the usual blockers, and started to build up
abstractions. They became pretty darn useful, so, this blog post is announcing
(a still incomplete, year old and perhaps API changing) Debian package for Go.
The Go importable name is
 In 2016-06-18:
 Numbers
The
 I should probably document the

 Like
 TL;DR: I put a $5
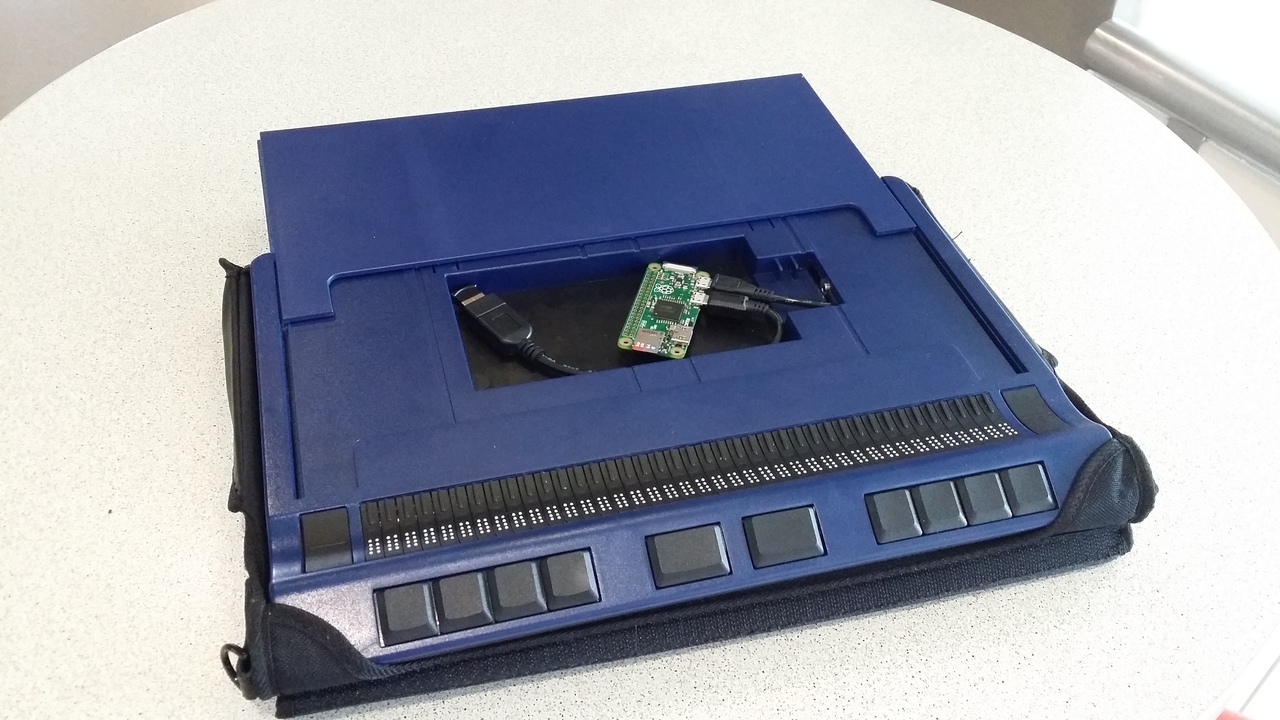
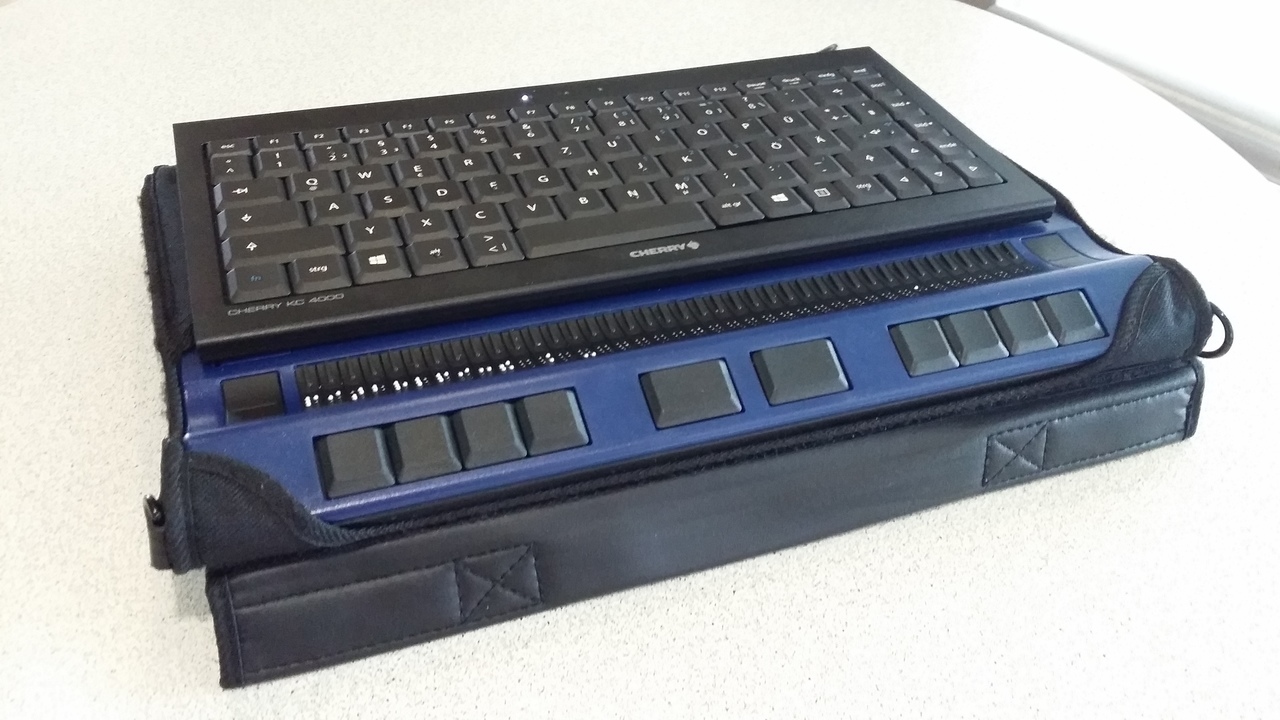
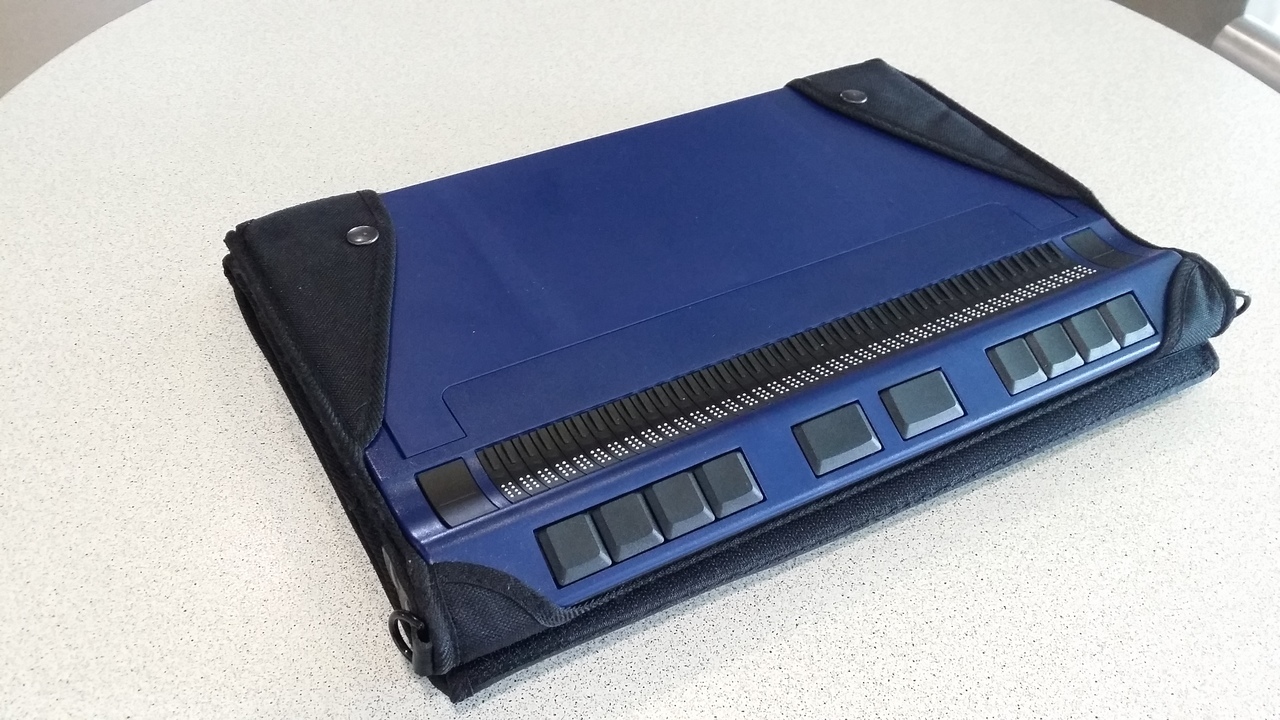 You can still pull out the little platform to increase the space
that can be used to put something on top.
 But, most conveniently,
they've designed in an empty compartment, roughly the size of a modern
smartphone, beneath the platform. The original idea was to actually
put a smartphone inside, but this has turned out (at least to me)
to not be very feasible. Fortunately, they thought about the
need for electricity and added a Micro USB cable terminating within the
newly created, empty compartment.
My first idea was to put a conventional Raspberry Pi inside.
When I received the braille display, however, we immediately
noticed that a standard-sized rpi is roughly 3mm too high
to fit into the empty compartment.
Fortunately, though, a co-worker noticed that the
 A longish blog post, please bear, a second part of the blog post would be published in few days from now. My fixed visa finally arrived, yeah
 But this story doesn t start here, it starts about a year back. While I have been contributing to Debian in my free time over the years, and sometimes paid time as well, I had never thought of going overseas as the experiences I knew from friends and relatives, it isn t easy to get all the permissions and paperwork done to say the least (bureaucracy @ work). But last year, when Debconf 15 was being launched, there are/were 2-3 friends of mine who are studying, doing their Ph.D. in some computer/web stuff, living in Germany currently that they goaded me to apply. The first few times I gave some standard excuses, but when they kept on for a while, just to shut them up I applied to the debconf team applying for food, accommodation and travel sponsorship.
I didn t have high hopes as there obviously are many more talented peers around me who understand FOSS and Debian at a much more fundamental, philosophical as well as technical level than me. Much to my surprise though, about a month (and around two or three weeks just before the event was about to take place) I got the bursary/sponsorships for food, accommodation as well as travel. I was unsure that the remaining time was enough to get a visa hence declined that time around.
That whole episode gave me the confidence that perhaps my application would be accepted if I applied again. Using my previous years understanding, decided to give it a shot again as this would also enable me to get a feel of visa bureaucracy as well as gain a bit of novice understanding about what factors go in choosing a flight and believe me the latter part proved to be pretty confusing. While the visa business seems easy, the form at least is easy and what they ask, it can be troublesome as far as visa-processing process is concerned. It took a better part of the month to get the visa which I needed. The in-between time is and can be a bit stressful as you have committed funds for travel i.e. the airline tickets and are in a limbo as you didn t know that if the visa is cancelled for some reason, your tickets would be refunded or not. A little history is needed and hopefully is helpful for anybody who s applying for a short-stay Visa in South Africa.
Exactly, A month and day back I had applied for visa. The visa I had applied for is 17 days as the flights within my budget was for those days only. The visa I got was for 10 days only which was ending in the middle of the conference. I tried many avenues to get information and was told that I needed to write a correction letter telling/sharing the information about the correct time period and dates in BOLD with a heavier weight/point which is what I did and gave to VFS office without any further payment on my part. It took a bit more time than the first time around but the consulate co-operated. While I can understand the oversight as they probably get more visas requests along with special and urgent requests so such occurrences can happen. I am and was happy that there was a recourse rather than starting from scratch which probably would have made me more anxious due to the first experience .
Apparently I was lucky that I had done with Qatar Airways as later came to know that there are other airways which don t refund money even after visa rejection . This information I got to know pretty late in the game otherwise I wouldn t have been much stressed. As had committed knew had to go the whole hog and whatever barriers are there, have overcome at least as far as the visa part/process is concerned.
Now after few days, will probably start to worry about the actual travel, part nervousness, part excitement, nervousness as it will be an alien land, am obese so traveling economy on 787-8 and 777-300 ER will be tricky. The 787-8 will probably be a rough ride as it s a 9 hr. journey and the seat are a mere 18 , the cattle class as shared by


 I'll tune in to the post-based conversation being held on Planet Debian:
 Russell Coker wrote about
 In order to monitor some of the