Search Results: "pm"

20 January 2014

Michal Čihař: Going to FOSDEM

Same as in past year, I'm attending FOSDEM 2014. This is the best opportunity to meet with free software world in Europe and get in touch with people you know only from mailing lists. If you want to meet me in person and discuss anything, just get in touch with me and we'll arrange it.

Filed under: English phpMyAdmin SUSE Weblate 0 comments Flattr this!

19 January 2014

Daniel Pocock: Debian solving Drupal's third-party library challenge

The tremendously successful Drupal community observes stringent requirements about many things, in particular, licensing and the prohibition of bundling third-party JavaScript. While these policies may seem onerous at first glance, it turns out there is another project with a written guarantee to provide third-party code in a form that meets the expectations of Drupal and does so in a way that completely automates all that tedious effort into one-click oblivion. I'm talking about the Debian GNU/Linux operating system. Drupal's libraries module The libraries module for Drupal appeared as an initial attempt to help track third-party JavaScript. The module has been available in Debian for almost a year and has recently been provided in the wheezy-backports distribution for people running the stable version of Debian. The library provides a standard way for other modules to reference third-party JavaScript but it still leaves the web master with some manual work to go out and download all the necessary JavaScript and copy it into the right place. This is where Debian comes to the rescue. Using the module in practice I've recently uploaded JSCommunicator to Debian and wanted to provide a convenient way for people to get it in Drupal. Therefore, in addition to providing the JSCommunicator packages, I created an extra package, drupal7-mod-jscommunicator. JSCommunicator itself depends on other JavaScript, specifically, the JsSIP library. I repeated the same process for JsSIP. This gives us the following collection of four related packages:
Third-party library Library itself Drupal module, packaged
JSCommunicator libjs-jscommunicator drupal7-mod-jscommunicator
JsSIP libjs-jssip drupal7-mod-jssip
If you explore the package details in Debian's package catalog you will notice that each package depends on the other packages it requires. Debian's package management utility, apt-get, can transitively resolve all the relationships between this set of packages. In fact, on a newly built server, you can simply run the command:
apt-get install drupal7-mod-jscommunicator
and the apt-get utility will install Apache, MySQL, Drupal itself, the libraries module, all the related JavaScript libraries and the final Drupal module of JSCommunicator itself. It really is that easy. Here is an example of the output displayed by the command on a freshly built server:
# apt-get -d install drupal7-mod-jscommunicator
Reading package lists... Done
Building dependency tree       
Reading state information... Done
The following extra packages will be installed:
  apache2 apache2-bin apache2-data curl dbconfig-common drupal7
  drupal7-mod-jssip drupal7-mod-libraries fontconfig-config fonts-dejavu-core
  javascript-common libaio1 libapache2-mod-php5 libapr1 libaprutil1
  libaprutil1-dbd-sqlite3 libaprutil1-ldap libarchive-extract-perl libc6
  libcurl3 libdbd-mysql-perl libdbi-perl libedit2 libfontconfig1 libgcrypt11
  libgd3 libhtml-template-perl libjbig0 libjpeg8 libjs-jssip libjson-c2
  liblocale-gettext-perl liblog-message-simple-perl liblua5.1-0
  libmodule-pluggable-perl libmysqlclient18 libonig2 libperl4-corelibs-perl
  libpng12-0 libpod-latex-perl libqdbm14 librtmp0 libssh2-1 libterm-ui-perl
  libtext-charwidth-perl libtext-iconv-perl libtext-soundex-perl libtiff5
  libuuid-perl libvpx1 libxml2 libxpm4 locales mysql-client mysql-client-5.5
  mysql-common mysql-server mysql-server-5.5 mysql-server-core-5.5 perl
  perl-base perl-modules php5 php5-cli php5-common php5-gd php5-json
  php5-mysql php5-readline ssl-cert wwwconfig-common
Suggested packages:
  apache2-doc apache2-suexec-pristine apache2-suexec-custom apache2-utils
  php-pear glibc-doc libclone-perl libmldbm-perl libnet-daemon-perl
  libplrpc-perl libsql-statement-perl rng-tools libgd-tools
  libipc-sharedcache-perl libterm-readkey-perl tinyca perl-doc
  libterm-readline-gnu-perl libterm-readline-perl-perl make libb-lint-perl
  libcpanplus-dist-build-perl libcpanplus-perl libfile-checktree-perl
  liblog-message-perl libobject-accessor-perl php5-user-cache
  openssl-blacklist postgresql-client
The following NEW packages will be installed:
  apache2 apache2-bin apache2-data curl dbconfig-common drupal7
  drupal7-mod-jscommunicator drupal7-mod-jssip drupal7-mod-libraries
  fontconfig-config fonts-dejavu-core javascript-common libaio1
  libapache2-mod-php5 libapr1 libaprutil1 libaprutil1-dbd-sqlite3
  libaprutil1-ldap libarchive-extract-perl libcurl3 libdbd-mysql-perl
  libdbi-perl libfontconfig1 libgd3 libhtml-template-perl libjbig0 libjpeg8
  libjs-jssip libjson-c2 liblog-message-simple-perl liblua5.1-0
  libmodule-pluggable-perl libmysqlclient18 libonig2 libperl4-corelibs-perl
  libpng12-0 libpod-latex-perl libqdbm14 librtmp0 libssh2-1 libterm-ui-perl
  libtext-soundex-perl libtiff5 libvpx1 libxpm4 mysql-client mysql-client-5.5
  mysql-common mysql-server mysql-server-5.5 mysql-server-core-5.5 php5
  php5-cli php5-common php5-gd php5-json php5-mysql php5-readline ssl-cert
  wwwconfig-common
The following packages will be upgraded:
  libc6 libedit2 libgcrypt11 liblocale-gettext-perl libtext-charwidth-perl
  libtext-iconv-perl libuuid-perl libxml2 locales perl perl-base perl-modules
12 upgraded, 60 newly installed, 0 to remove and 222 not upgraded.
Need to get 37.2 MB of archives.
After this operation, 152 MB of additional disk space will be used.
Do you want to continue [Y/n]? 
Libraries API in Drupal 8 Contrary to an earlier version of this blog, the libraries module is not joining the core in Drupal 8 however its use has been strongly encouraged for any new modules submitted through the Drupal community approval process. This means there will be further opportunity for Drupal users to consolidate on their use of Debian to completely automate the management of all third-party libraries and modules throughout their Drupal system(s).

18 January 2014

James Bromberger: Linux.conf.au 2014: LCA TV

The radio silence here on my blog has been not from lack of activity, but the inverse. Linux.conf.au chewed up the few remaining spare cycles I have had recently (after family and work), but not from organising the conference (been there, got the T-Shirt and the bag). So, let s do a run through of what has happened LCA2014 Perth has come and gone in pretty smooth fashion. A remarkable effort from the likes of the Perth crew of Luke, Paul, Euan, Leon, Jason, Michael, and a slew of volunteers who stepped up not to mention our interstate firends of Steve and Erin, Matthew, James I, Tim the Streaming guy and others, and our pro organisers at Manhattan Events. It was a reasonably smooth ride: the UWA campus was beautiful, the leacture theatres were workable, and the Octogon Theatre was at its best when filled with just shy of 500 like minded people and an accomplished person gracing the stage. What was impressive (to me, at least) was the effort of the AV team (which I was on the extreme edges of); videos of keynotes hit the Linux Australia mirror within hours of the event. Recording and live streaming of all keynotes and sessions happend almost flawlessly. Leon had built a reasonably robust video capture management system (eventstreamer on github) to ensure that people fresh to DVswitch had nothing break so bad it didn t automatically fix itself and all of this was monitored from the Operations Room (called the TAVNOC, which would have been the AV NOC, but somehow a loose reference to the UWA Tavern the Tav crept in there). Some 167 videos were made and uploaded most of this was also mirrored on campus before th end of the conference so attendees could load up their laptops with plenty of content for the return trip home. Euan s quick Blender work meant there was a nice intro and outro graphic, and Leon s scripting ensured that Zookeepr, the LCA conference manegment software, was the source of truth in getting all videos processed and tagged correctly. I was scheduled (and did give) a presentation at LCA 2014 about Debian on Amazon Web Services (on Thursday), and attended as many of the sessions as possible, but my good friend Michael Davies (LCA 2004 chair, and chair of the LCA Papers Committee for a good many years) had another role for this year. We wanted to capture some of the hallway track of Linux.conf.au that is missed in all the videos of presentations. And thus was born LCA TV. LCA TV consisted of the video equipment for an additional stream mixer host, cameras, cables and switches, hooking into the same streaming framework as the rest of the sessions. We took over a corner of the registration room (UWA Undercroft), brought in a few stage lights, a couch, coffee table, seat, some extra mics, and aimed to fill the session gaps with informal chats with some of the people at Linux.conf.au speakers, attendees, volunteers alike. And come they did. One or two interviews didn t succeed (this was an experiment), but in the end, we ve got over 20 interviews with some interesting people. These streamed out live to the people watching LCA from afar; those unable to make it to Perth in early January; but they were recorded too and we can start to watch them (see below) I was also lucky enough to mix the video for the three keynotes as well as the opening and closing, with very capable crew around the Octogon Theatre. As the curtain came down, and the 2014 crew took to the stage to be congratulated by the attendees, I couldn t help but feel a little bit proud and a touch nostalgic memories from 11 years earlier when LCA 2003 came to a close in the very same venue. So, before we head into the viewing season for LCA TV, let me thank all the volunteers who organised, the AV volunteers, the Registration volunteers, the UWA team who helped with Octogon, Networking, awesome CB Radios hooked up to the UWA repeated that worked all the way to the airport. Thanks to the Speakers who submitted proposals. The Speakers who were accepted, made the journey and took to the stage. The people who attended. The sponsors who help make this happen. All of the above helps share the knowledge, and ultimately, move the community forward. But my thanks to Luke and Paul for agreeing to stand there in the middle of all this madness and hive of semi structured activity that just worked. Please remember this was experimental; the noise was the buzz of the conference going on around us. There was pretty much only one person on the AV kit my thanks to Andrew Cooks who I ll dub as our sound editor, vision director, floor manager, and anything else. So who did we interview? One or two talks did not work, so appologies to those that are missing. Here s the playlist to start you off! Enjoy.

Colin Watson: Testing wanted: GRUB 2.02~beta2 Debian/Ubuntu packages

This is mostly a repost of my ubuntu-devel mail for a wider audience, but see below for some additions. I'd like to upgrade to GRUB 2.02 for Ubuntu 14.04; it's currently in beta. This represents a year and a half of upstream development, and contains many new features, which you can see in the NEWS file. Obviously I want to be very careful with substantial upgrades to the default boot loader. So, I've put this in trusty-proposed, and filed a blocking bug to ensure that it doesn't reach trusty proper until it's had a reasonable amount of manual testing. If you are already using trusty and have some time to try this out, it would be very helpful to me. I suggest that you only attempt this if you're comfortable driving apt-get directly and recovering from errors at that level, and if you're willing to spend time working with me on narrowing down any problems that arise. Please ensure that you have rescue media to hand before starting testing. The simplest way to upgrade is to enable trusty-proposed, upgrade ONLY packages whose names start with "grub" (e.g. use apt-get dist-upgrade to show the full list, say no to the upgrade, and then pass all the relevant package names to apt-get install), and then (very important!) disable trusty-proposed again. Provided that there were no errors in this process, you should be safe to reboot. If there were errors, you should be able to downgrade back to 2.00-22 (or 1.27+2.00-22 in the case of grub-efi-amd64-signed). Please report your experiences (positive and negative) with this upgrade in the tracking bug. I'm particularly interested in systems that are complex in any way: UEFI Secure Boot, non-trivial disk setups, manual configuration, that kind of thing. If any of the problems you see are also ones you saw with earlier versions of GRUB, please identify those clearly, as I want to prioritise handling regressions over anything else. I've assigned myself to that bug to ensure that messages to it are filtered directly into my inbox. I'll add a couple of things that weren't in my ubuntu-devel mail. Firstly, this is all in Debian experimental as well (I do all the work in Debian and sync it across, so the grub2 source package in Ubuntu is a verbatim copy of the one in Debian these days). There are some configuration differences applied at build time, but a large fraction of test cases will apply equally well to both. I don't have a definite schedule for pushing this into jessie yet - I only just finished getting 2.00 in place there, and the release schedule gives me a bit more time - but I certainly want to ship jessie with 2.02 or newer, and any test feedback would be welcome. It's probably best to just e-mail feedback to me directly for now, or to the pkg-grub-devel list. Secondly, a couple of news sites have picked this up and run it as "Canonical intends to ship Ubuntu 14.04 LTS with a beta version of GRUB". This isn't in fact my intent at all. I'm doing this now because I think GRUB 2.02 will be ready in non-beta form in time for Ubuntu 14.04, and indeed that putting it in our development release will help to stabilise it; I'm an upstream GRUB developer too and I find the exposure of widely-used packages very helpful in that context. It will certainly be much easier to upgrade to a beta now and a final release later than it would be to try to jump from 2.00 to 2.02 in a month or two's time. Even if there's some unforeseen delay and 2.02 isn't released in time, though, I think nearly three months of stabilisation is still plenty to yield a boot loader that I'm comfortable with shipping in an LTS. I've been backporting a lot of changes to 2.00 and even 1.99, and, as ever for an actively-developed codebase, it gets harder and harder over time (in particular, I've spent longer than I'd like hunting down and backporting fixes for non-512-byte sector disks). While I can still manage it, I don't want to be supporting 2.00 for five more years after upstream has moved on; I don't think that would be in anyone's best interests. And I definitely want some of the new features which aren't sensibly backportable, such as several of the new platforms (ARM, ARM64, Xen) and various networking improvements; I can imagine a number of our users being interested in things like optional signature verification of files GRUB reads from disk, improved Mac support, and the TrueCrypt ISO loader, just to name a few. This should be a much stronger base for five-year support.

17 January 2014

Rog rio Brito: Developing for Android with Debian

I have just enrolled in a MOOC to learn about programming with Android. There are many tutorials and reports of people using Linux for the development of the apps out there, but, unfortunately, many of them are outdated or contain misleading information. You will find bazillion instructions out there telling you to install JDK6. (Even the instructions in the MOOCs say so, and Google says that it is the only supported version of Java). Even more than that, some of them will tell you that you should not use OpenJDK, but use Oracle's JDK instead. So, if you have a pure amd64 system and you try to install the x86-64 version of Google's Android Developer Tools (ADT), you are going to have a surprise: you will have all sorts of programs telling you that you have file not found, even though the required binaries are there. (This is, of course, besides install openjdk-7-jdk, if you wish to use the integrated Eclipse environment). Turns out that the so-called 64-bit ADT/SDK actually has many 32-bit executables(!) and they aren't statically linked. Inspecting them, I needed the following packages:
    gcc-4.8-base:i386
    libc6-i686:i386
    libc6:i386
    libgcc1:i386
    libstdc++6:i386
    zlib1g:i386
It is worth observing that: Given the above, and given that the version of the GCC libraries can vary a lot, it is perhaps better to simply do something like:
apt-get install libstdc++6:i386 zlib1g:i386
Although not necessary, since you are using an amd64 machine, your computer already supports many more recent instructions that will be used if you install the package libc6-i686:i386. To avoid the emulator from spitting out error messages related to libGL.so, install libgl1-mesa-dev (note: not i386 here). This way, you will be able to run the embedded QEMU with full KVM acceleration if you pass the options -qemu -m 1024 -enable-kvm on Eclipse's "Run > Run Configurations... > Target > Additional Emulator Command Line Options". After that, you are probably good to go.

16 January 2014

Andrew Pollock: [life] And now for something completely different...

After 8 years, February 6 will be my last day with Google. The hardest pill to swallow with the end of my marriage was the reduction in my time with Zoe. It was one thing to lose my wife, but to lose 50% of my daughter as well has been, and will continue to be, a struggle for me. 2014 is the last year before Zoe starts in Prep (Queensland's school grade before "one"). This is my last opportunity to be able to have a big chunk of time with her before she gets swallowed up by the school system. It's ridiculous to be sticking her in full-time long day care if I have an alternative. And I do have an alternative. I'm in the fortunate financial position of not having a mortgage, or any debt to speak of, and a modest amount of savings. I shall be Daddy Day Care. It had always been my career goal in life to be a stay at home Dad. I'd wanted to have another child and be the one to stay at home and look after the kids, and allow Sarah to resume her career. Obviously none of that worked out, but there's no reason why I can't be a stay at home Dad for at least this year. Zoe's at a wonderful age now. We can have a lot of fun together this year. She's going to be in a 5 day a fortnight Kindergarten program (Monday, Tuesday and every other Wednesday) between 8:20am to 2:30pm, so I'm planning on using one of those days for Debian contributions, one of those days for exploring some of the crazy startup ideas I have rattling around in my head, and every second Wednesday to keep the home tidy. It's going to be a fun, different year for Zoe and I, and I'm so looking forward to it. I'm planning on doing lots of activities from Play at Home Mom, doing lots of baking and we'll be doing Science Friday's. If anyone knows where I can get a toddler-sized lab coat, drop me a line. I'm hoping I can make time to write up our activities for posterity as well.

15 January 2014

Jon Dowland: Whitley Bay Ice Rink

Recently, North Tyneside Council circulated the beginnings of a regional development plan. This consisted of a detailed map of the borough, complete with various areas marked out as sites for potential housing development. Included amongst the sites for potential development was Whitley Bay Ice Rink and the surrounding leisure facilities: a football pitch, a cricket pitch, and more. Whitley Bay Ice Rink has been a fixture in the cultural history of the region and it would be a terrible shame if it were to close. Many people seemed to agree: a petition calling for the site to be excluded from the plan received over 7,000 signatures. Residents were also able to write comments on the plan itself. The specific paragraph for the Ice Rink had attracted over 100 comments when I looked at it on the last day that comments were open. I hurredly put together one of my own:
Whitley Bay Ice Rink is about to celebrate it s 60th birthday as both a key part of the history and culture of the borough and a unique leisure facility in the wider area. Sadly the Rink has seemed, historically, to be somewhat neglected, rather like the other large cultural landmark in the region - Whitley Bay s Spanish City and Dome. I argue you should no sooner consider closing or redeveloping the Rink site than the Dome itself. Rather, both should be cherished and invested in, particularly if (as rumoured) the current owners are keen to retire or pass it on. In recognising the need to increase the amount of housing in the area, one should consider what facilities will be available to the new residents within the region. Removing facilities to provide housing is slaying the golden goose. Whitley Bay Ice Rink is one of the few rinks left in the country and the nearest permanent ice rink within 30 miles. Ice skating has become a fond and lasting memory for many of the adults who have grown up in the region, many of whom enjoy or look forward to their own children experiencing it. I look forward to taking my niece and nephew there, when they are old enough, as well as my own future children. It is a traditional spot for School trips; the sports teams operating from the rink have a proud history and fearsome reputation. It s an attraction for the large numbers of University students that travel to the two nearest Universities. The borough is blighted with rotting seaside hotels which (following the recent development of the Idols site) should be converted into attractive flat or maisonette housing as a priority.

Sylvestre Ledru: Some thoughts concerning LLVM & Clang and their evolutions: Release of LLVM & Clang 3.4

We just released LLVM & Clang 3.4 (already available in Debian Jessie and Ubuntu Trusty). The clang new release introduces some more warning and error detections. The point of the blog post is not to detail the changes (LLVM / Clang) but more to take a step back on the LLVM and Clang toolchains, usages and dissemination. For the last couple years, I have been presenting our work on the Debian side to make Clang part of the Debian infrastructure. I add the chance to speak at many events (Debconf 12 & 13, FOSDEM 2013, Linux Plumbers 2013, Distro recipes, etc). I even had Linus Torvalds attending to one of these talks (and proposing new approach). I had many feedback from the Debian/Ubuntu communities but also from other communities.
More and more projects are using Clang as part of their workflows, in term of development, production and QA. For example, some of them are running continuous integration using clang instead of gcc, others are running scan-build (Wireshark or LLVM itself) or Address Sanitizer (asan) (Firefox for example), etc.
More and more actors are moving from gcc to clang for their developments (Sony with their PS4, Chrome under Mac OS X, Apple, the Linux Kernel with the LLVMLinux project, FreeBSD, etc).
I stopped counting the number of times when people answered me "Yeh, I am now using Clang" when I said I am involved upstream. In parallel, more and more projects are using LLVM as a backend or computing engine and, in the meantime, getting more and more attraction (not because they are based on LLVM but just because they are great projects). For example, Mesa (llvmpipe), Julia, Rust, Emscripten or Native Client (NaCL) are excellent examples of this. The two last are excellent proofs that LLVM based technologies have an impact which goes further than geek-tools and will be used on a daily basis by millions of users. I also saw an interesting and growing number of new projects using libclang and libTooling. My feeling is that the lack of plugin capabilities in gcc for a long time and, now, its current complexity limited the innovation in term of compilation capabilities, analysis and fun tools. The features and the quality of this library are enabling new developments and I am sure we will see more and more excellent tools based on this library during 2014.
For example, the LLVM toolchain ships Clang modernize and clang format and some cool projects like include-what-you-use, DXR, OCLint or creduce are emerging. Thanks to this great competition, gcc is also improving (ASAN, JIT, better warnings, etc), remaining still relevant as before. No doubt that 2014 will be a great year for compilers.

Jan Wagner: Bye bye Nagios-Plugins

Last night it seems the so called 'Nagios Plugins' project was cut off. The story started a decade ago when development of the plugins compatible with Nagios was taken over by an independend group of developers. Some time later, the domain of the 'Nagios Plugins' project was handed over to 'Nagios Enterprises, LLC.' due trademark reasons. To get an idea about that, I suggest to read on the 'Nagios Trademark Truth' and 'Nagios Trademark Triumph Provides Promise To Open Source Developers, Shows Power of Community'. In the latter Mr. Galstad is cited with "This violation took more than four years and thousands in legal fees before it was finally resolved. My hope is that this can serve as an example to Open Source developers worldwide that they can overcome infringements and protect their brands if they are persistent and engage their respective communities.". Yesterday in the evening the project members recognised that the DNS of nagios-plugins.org was moved to a different location. Now there seems to be a hosted (some may call that 'hijacked' or 'pirated') 'mirror' of the old site. Anyhow ... the content is already different from the original one or maybe changed even more in the future. From my point of view this can serve as an example to Open Source developers worldwide that they can be obstructed by (trademark holding) companies even if those companies profit from the work of them. So please don't use downloads from there, even the release tarballs maybe modified. The news all about that: 'Nagios Plugins are dead, we now have Monitoring Plugins in place!" Be sure you download your tarballs from https://www.monitoring-plugins.org/download.html and verify your checksums! You can follow the Monitoring Plugins Development Team also via Twitter.

14 January 2014

Carl Chenet: My Debian contributions in January 2014

Follow me on Identi.ca or Twitter One of my resolutions for 2014 is to keep trying harder to talk about my Debian contributions. So here it is, on a monthly basis this time I hope, quite short this month because I m leaving for holidays at the end of the week and I think I won t have time to contribute more this month. Debian packages Below are some packages I updated recently: 1. Brebis, the fully automated backup checker I successively packaged Brebis, the fully automated backup checker, versions 0.6 to 0.9 (the latter is today in Debian Sid and Jessie) since my last Debian activities blog posts (in french).
brebis-brown-big-logo

Anisette, the mascot of the Brebis Project

2. Pycallgraph, a Python library that creates call graphs for Python programs Pycallgraph is one of the first Debian packages I have been maintaining. So when I noticed it was upgraded after so much time I was really eager to package the new version 1.0.1. Now available in Debian Sid! Just belown an example of the generated graph for the application Belier, a sysadmin tool. pycallgraph 3. Belier, the SSH connection generation tool Nothing really new for Belier, the SSH connection generation tool but I updated the package in order to update the configuration of the Debian package and get rid of some warning messages. Kind of maintenance job I kept avoiding and avoiding, until now. Bug report I d like to take a few seconds to talk about an interesting bug report about the need for a nagios3-dev package I created asking for a new nagios3-dev or nagios3-headers package to offer a simple access to the headers of Nagios for the developers of Nagios external modules. In Nagios, some headers are generated after the ./configure, meaning it may be platform dependent. I (and not only me, the same request was active already by someone other Nagios module developers) thought it was simple to ask the Nagios3 Debian package maintainer to offer these files in a dedicated package. It seems until now people just add the missing files in tarball of their app or in their Debian packages, even if these Nagios headers are not really part of this application. In my opinion, that s why Build-Depends packages are for, don t you think? nagios It seems it is not so simple. I could not understand why it was more important to prevent Debian users who need these files to access these files in a convenient way than letting them to put theses files in there own source tarball/repository. The maintainer told me it could break things. Sure. But we all know an external module of any app often relies on a really specific version of this app. That s nothing new, thats how external modules work. That s not every apps in the world which could provide a stable API to ease the development of external modules. But at least they give access to their dev files or headers when they are FOSS. But feel free to explain to me. After all, the bug reports are still not tagged as "won t fix" ;) Your turn now :) I d be delighted to have your opinions in the comments of this blog post.

Daniel Leidert: Debian Sid and GNOME 3 - Restoring automount function of USB devices

I recently found, that the automount feature of my recent Debian Sid / GNOME 3 system didn't work anymore. For example: I plugged in an USB stick. Nothing happened, although dmesg clearly showed, that the system recognized it. After manually mounting and unmounting the device, nautilus automatically offered to automount it. But I always had to manually mount and unmount it first. Seems the culprit was a pmount installation. JFTR: In some cases also usbmount might cause trouble.

Petter Reinholdtsen: New chrpath release 0.16

Coverity is a nice tool to find problems in C, C++ and Java code using static source code analysis. It can detect a lot of different problems, and is very useful to find memory and locking bugs in the error handling part of the source. The company behind it provide check of free software projects as a community service, and many hundred free software projects are already checked. A few days ago I decided to have a closer look at the Coverity system, and discovered that the gnash and ipmitool projects I am involved with was already registered. But these are fairly big, and I would also like to have a small and easy project to check, and decided to request checking of the chrpath project. It was added to the checker and discovered seven potential defects. Six of these were real, mostly resource "leak" when the program detected an error. Nothing serious, as the resources would be released a fraction of a second later when the program exited because of the error, but it is nice to do it right in case the source of the program some time in the future end up in a library. Having fixed all defects and added a mailing list for the chrpath developers, I decided it was time to publish a new release. These are the release notes: New in 0.16 released 2014-01-14: You can download the new version 0.16 from alioth. Please let us know via the Alioth project if something is wrong with the new release. The test suite did not discover any old errors, so if you find a new one, please also include a test suite check.

13 January 2014

Daniel Pocock: PostFinance, where is my money?

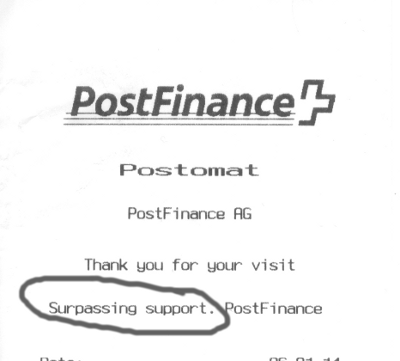
Update: my money has been returned by PostFinance very soon after this blog appeared There's no better way to get the year off to a good start than finding money has gone missing from your bank account. Where I live in Switzerland, it is mandatory for everybody to make a monthly payment for health insurance (as it is mandatory, it is basically a tax, like the monthly council tax in England). Just like British council tax, the premiums go up each year and every person in the country has to log into their bank's web site and change their standing order. A few days after doing just that, I went back in to the web site to make another payment and noticed that the first health insurance payment for 2014 had been duplicated on two consecutive days, the 30th and 31st of December: I immediately sent them an email to alert them to the fault and ask for the duplicate transaction to be corrected. Normally, when a company makes a mistake, it would be fixed within a couple of days and certainly never reach my blog. Instead of getting a helpful reply, I was astonished to receive this:
There has been a misunderstanding when you have set up your standing order.
You selected "First execution" December 30, 2013 and then "monthly execution" 31. The system has followed your instruction and it results a double execution December 30 and 31.
Unfortunately, we are not able to return you the amount.
Great, apparently it is all my own fault. I thought "monthly" would mean one payment in each one month but apparently not everybody uses the same definition of monthly. (Actually, banks do have systems such as the 360 day calendar but that is another story). So let's look at these faulty instructions I supposedly gave. I immediately went back to the standing order page to take a screenshot. I even compared the page in English (my default language, which they are kind enough to let me use) and French (one of the four official languages of the Swiss Confederation) and I found they say much the same thing: Note: exact amounts and account numbers concealed The form is relatively clear: I authorised a monthly payment (Periodicite: mensuel) with the first (Premiere) payment on 30.12.2013 and then, or so I believed (and still do) a following payment (ensuite) on the 31st of each month, with the last payment at the end of November, for 12 payments in total. Simple, right? Where it says ensuite le 31, I sincerely believe that means the second payment is on 31 January, but Postfinance seem to be arguing that I meant the 31 December: just one day, rather than one month, after the first payment. Delaying tactics I replied to their email, telling them explicitly that I had authorized a monthly payment only and demanding the immediate return of the duplicate payment. When I got their next reply, I didn't know what to think:
We are pleased to do the necessary to revoke the transfer to SWICA. This will take at least two weeks.
On the one hand, it appears they are now starting to accept they may have made a blunder. But two more weeks? This was already 10 days after the money went missing. Do they even know what is wrong with their system? It doesn't give me confidence. I wrote back again and insisted that this is their error and that an immediate correction is required. Pass the buck, take three Today, another reply came back. After almost 14 days, I've now got three fob-off excuse mails and none of my money returned:
We did the request at SWICA to send back the money on your account on the 8th January 2014. The decision will be taken by them if they agree to send back this amount.
Unfortunately, we cannot do more except waiting their answer. You can call them and explain them the situation. With your call, maybe the reimbursement could be faster.
Why is it in the hands of the health insurance company? It is not their fault that Postfinance has a problem processing standing orders. Why do I have to waste my time chasing people, will I get compensation for that? Am I the only victim? With many people configuring their new health insurance payments at this time of the year, I can imagine that there may be other victims of this fault too. Are they all being fobbed off with these excuses? Some may not even realize if they don't check their account closely. What next? Sure, maybe I can just cancel the next health insurance payment: but why should I have that inconvenience? What exactly was I supposed to put on that form to not make this mistake they suggest I made? If I cancel the next payment like they suggest and then set up the payment again from March, how can I be sure the same duplication won't happen again? Using customers as unpaid QA testers Many leading financial organisations have experienced teams of developers, QA testers, and comprehensive regime of simulation/testing with paid participants to ensure their systems are reliable and as friendly and accurate as possible. Here, it feels like PostFinance has skipped all that, deploying a form that is ambiguous at best and they are using real customers like me to test the system and report the bugs. Normally organisations pay me for doing that very same task as part of my job as a software engineer. Not only have Postfinance taken almost 200 CHF of my money, but they have wasted my time with their strategy of fobbing me off and at the same time they are probably sending my feedback to their developers instead of paying a QA tester to check their systems. You be the judge What is your opinion?
  • Daniel can't use a web form, it is definitely Daniel's mistake, nobody else would make a mistake like that
  • The Postfinance form is ambiguous and so it is probably their fault and they should give back the money, it is likely these are cut and paste emails they send to all the customers who are duped by the form
  • Postfinance is completely wrong. Monthly means one payment each month.

8 January 2014

Gunnar Wolf: [review] Packt's Instant Haml

Packt Publishing sent me Krzysztof Niki ski's Instant Haml to do a short blog review... Thing is, and those who read me know, I cannot write short reviews ;-) So lets see how this goes. Packt's Instant series First, as for the format this book follows and the series it fits in: They are very short books. I was the tech reviewer for their Instant Debian Build a Web Server , and when I opened it for the first time, I thought I had received only the first chapter. This series' motto is Short Fast Focused so, yes, the books are ~50 pages long, with ample margins and many big screenshots. I told the editors I was quite unsure about the value this kind of publications add, as they are very similar to online tutorials, but given they have so many books in this series (printed and electronic), there must be a market for them. They surely know their business better than me! There is one other detail regarding the publisher I'll stick in this section, although it is not specific to their Instant series: I do most of my reading in my Kindle. Packt seems to have chosen to specify a very small font for their texts. Besides the two books mentioned, I also have their Object Oriented JavaScript book. For all of the other books I read, I use the smallest font setting. Packt books in mobi format (what they present as Amazon format in their web site) are basically illegible without bumping up the font size through the roof. As I understand it, publishers should use industry-wide default sizes, and let the reader adjust their reading experience. Yes, books of technical nature (such as Packt's) often benefit from having more displayed information than what an ebook reader normally shows... But that's for me to decide! And no, this is not a Kindle-specific glitch: I also get a similar experience when opening it from Calibre. And as for the book... I am a long-time Haml convert/fan; I packaged its Ruby implementation for Debian (and should update it soon :-/ as new versions have appeared), the corresponding Emacs Lisp mode, and I use it for basically all of my static HTML sites and Ruby-based Web systems. Haml is a great templating language, meant to make dynamic HTML generation leaner and easier. It is a clean and elegant technology, and can clearly sell itself. And the project webpage has very good documentation, ranging from a short tutorial and a full API documentation for people to contribute to the project. The first part of this book, of course, covers the "why is Haml so great?" part, presenting the basic equivalences with HTML. In my opinion, the book could be structured a bit differently and would generate a stronger following. Why? Because, even given that Haml is greatly benefited from its Ruby integration and has many hooks to be tightly integrated in a Rails workflow, it can also be used by people who don't want to do Ruby. I have some static websites that are just a bunch of Haml files, compiled by a very simple Makefile and calling the haml command from the shell. I think there would be some value in presenting this invocation before learning how to call it from the Gems environment (i.e. bundle install). Using Haml as a standalone tool is only presented almost as an appendix ("Using HAML outside of Rails" section). Even more so if the author presents four different static-site solutions (probably more non-programmer-friendly than my trusty Makefile). Oh, and this little section uses the (old? obsolete?) uppercase HAML notation for the project's name instead of the now-standard Haml. Dirty screenshots About the screenshots presented in this first section (and I refer mainly to the scaffolding examples), they are meant to show how easy things are, but have an important stylistic mistake: Terminals with transparency might look cool (I hate using them, but then again I'm a very boring person when it comes to my computer habits ;-) ), but transparencies have no place in a book (be it printed or e-book), as the images appear very uncrisp. In the Kindle, they just seemed dirty Now that I'm browsing the PDF from my desktop, I see that the screenshot in "Step 1" has a photo of Earth from space behind the terminal, and even worse, in "Step 2" it is shown over a Web page detailing the installation! These elements are just distracting, and the text would be much cleaerer if it were presented typeset just as a regular code fragment. Opening many of those screenshots in the Kindle was plain useless. Editor integration It is perfectly clear from this text that the author strongly prefers Sublime Text, sometimes uses TextMate, and has just heard reports that Haml has some support in Vim, Rubymine, Emacs and Coda. Of course, devoting a full page (as it is for the first case) for each editor would be out of proportion for this size of book... I just felt the imbalance too big, specially given that most editors will sport approximately the same feature set. Text redundancy If the Instant series is about making short books, I would expect them to be loaded with easy to follow content (as they are), but free of repetition. I felt, however, a large chunk of step 1 of the "Quick start" chapter to be repeated with the the first section of the "Top 6 features" chapter. Yes, the second one adds some depth, but very little. Still, in the later parts of this "Top 6 features" chapter, a more thorough explanation could be used for the Filters, Multiline attributes/code/strings and helpers and extensions sections. It seems the author was on a hurry trying to get it finished, as it is barely explained Explaining a bit more deeply would surely benefit readers. Wrapping up Reading my review, I'm mostly talking about negative issues. IMO, the book is not excellent, but it is clearly not bad. Specially given it fits very well the format for which it was designed. There are many items that could be fixed, and I hope some of them can be fixed (i.e. the screenshots) before the book goes to print If I understand Packt's page correctly, it is currently only available as ebook, contrary to most of the Instant series' titles.

Pau Garcia i Quiles: FOSDEM Desktops DevRoom 2014: looking for volunteers for video recordings

Qt and KDE will be present at FOSDEM, the largest open-source event in Europe. One more year, we will be sharing the Desktops DevRoom with Gnome, Unity, Enlightenment, LXQt and Hawaii (a Qt Quick desktop environment). We recently published the schedule for the devroom, which will be also available in the printed booklet available at the front desk. fosdem-logo For the 2014 edition, the FOSDEM organization wants to achieve 100% recording of presentations. That means every presentation, in every room (devroom, lightning talk, main conference, etc) must be recorded. That s hundreds of talks. While the FOSDEM and devrooms organization teams comprise a lot of people, we are far too busy already with the organizative stuff and cannot spend time doing the actual recordings. Good thing is, you can help! Do you want to join the FOSDEM Video Team and receive the t-shirt? We are now looking for volunteer cameramen (and camerawomen, of course :-) ). FOSDEM will provide you with equipment and training, you only need to start recording, focus, make sure nobody gets between the camera and the speaker/stage, etc. You do NOT need to record the whole track, even one talk recording would help. More details on what will be required from you are available in this e-mail from Wouter. Please contact me (pgquiles at elpauer dot org) if you are interested in recording one or more presentations from the Desktops DevRoom.
5 January 2014

Jon Dowland: 2013 In Fiction

I read a lot this year - I'll write more about that and reflections on goodreads in another post - but most of the things I read weren't published in 2013. (I should also write a bit about my thoughts on e-readers). However, it seems I have enough to write about 2013's novels to make a round-up post worthwhile, so here we go.
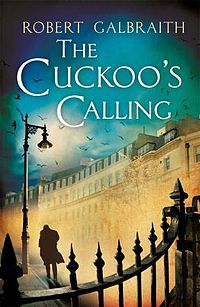
The Cuckoos Calling UK cover
This year, crime author Robert Galbraith published his first novel The Cuckoo's Calling. I'd never have heard of it if Galbraith was not outed as an alias for Joanne "JK" Rowling. Clues that Rowling was working on a detective story exist as early as a Guardian preview article in 2012 for her last novel, The Casual Vacancy. Further hints, for me, that this was no first-time author were the taglines from Ian Rankin and Val McDermid on the cover, writers of a calibre I'd be surprised a new author could attract. However I don't know whether they were on the pre-unveiling cover or not. Rowling was upset be outed, having enjoyed the freedom to write without the baggage of expectation that she is subject to. I hope she's pleased: prior to her unmasking the novel was warmly received by the (admittedly relatively small) number of people who read it. And a very good novel it is too. It starts with a genre clich of a grizzled, meloncholy detective, Mr. Cormoran Strike, in an upstairs office with a neon light flickering through the window, but fleshes the story out both forwards - a client, a mysterious death - and backwards - how did Mr. Strike end up in that upstairs office - living out of it, no less? As is traditional for the genre there's a very clever twist. What I really enjoyed about Cormoran Strike was Galbraith/Rowling moving quickly from Chandler-esque everyman to a well fleshed-out, complex protagonist, intertwining the development of the character with the unfolding of the wider plot. I'm looking forward to the sequel, expected in 2014.
The Shining Girls UK cover
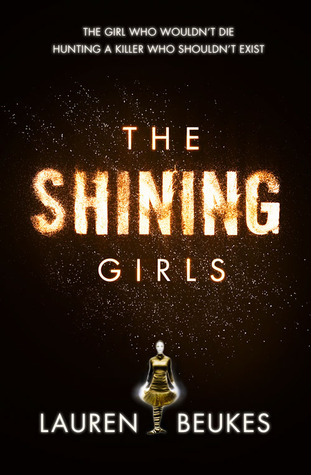
A second surprise favourite this year was Lauren Beukes' time-tripping crime story The Shining Girls. A monsterous murder of women somehow finds a room in Chicago that lets him travel through time (or perhaps the room finds him). He uses this facility to stalk and murder a set of Shining Girls: women who, for one reason or another, literally 'shine' in his perception of them. One such woman survives his first attack and decides to try and find out who attacked her, and why. The crimes are described in a brutal fashion which - from a distance - resemble the sometimes glorified violence for which crime fiction is sometimes criticised, but the focus of the story is very much on the victims: they are fully fleshed out characters and each death is felt by the reader as a genuine tragedy. I discovered Beukes when her earlier novel Zoo City was included in a Humble eBook bundle. On reading The Shining Girls I felt that the novel deserved to be more widely known than I would expect it to be trapped in the ghetto of genre fiction, so I was pleased to discover that the very mainstream Richard and Judy Book Club discovered it. In established author news, Terry Pratchett, having adopted speech recognition for writing (to combat his debilitating Alzheimer's) has seemingly managed to accelerate his rate of production and squeezed out at least two this year: The Long War with Stephen Baxter is the sequel to 2012's The Long Earth which I very much enjoyed, but it really felt like "difficult second novel" to me. Hopefully there'll be a third. Raising Steam, the 40th Discworld novel, was an enjoyable romp around the concept of steam trains, featuring the relatively new Moist von Lipwig who has managed to become one of my favourite Discworld characters. I can't think of much more to say about the novel, really. It's a Discworld novel, probably not the best introduction to the series for a new reader, but will give a reader familiar with the franchise everything they expect, and possibly no more. Iain Banks sadly died this year, shortly after the publication of his last novel, The Quarry. It's sat on my hardback shelf for the time being. I couldn't bring myself to read it in 2013. I did read his last SF offering from the year prior, The Hydrogen Sonata. Sadly, yet coincidentally, both of these books examine the nature of living and dying, The Quarry in particular from the point of view of a terminal cancer sufferer. I have a small backlog of unread Banks fiction which I want to take my time over with. Finally, whilst not really a book, I thoroughly enjoyed the BBC's 2013 adaptation of Neil Gaiman's Neverwhere. Natalie Dormer wrote a piece on the making of the drama which should serve as a good introduction. At the time of writing, most of the programmes have disappeared from iPlayer, but I would be surprised if this wasn't released commercially at some point.

Lisandro Damián Nicanor Pérez Meyer: Qt 5.2.0 in Debian experimental, now available for more archs

Qt 5.2.0 is already available in experimental until we get a transition slot, but don't be afraid to test it. With this release we had major improvements. With 5.1.1 currently in sid we have the following buildd chart:

Qt 5.1.1 in Debian Sid
Now with 5.2.0 in Debian experimental we have:

Qt 5.2.0 in Debian experimental

As you can see Qt has compiled in more archs, thanks to the effort of the Debian's porters and from the Qt/KDE team.

Note that Qt JS Backend has dissapeared: it's functionality (the javascript engine) is now in Qt Declarative itself. It has been ported away from Google's v8 to a Qt-based engine, allowing it to build in more archs among other features.

You can also note that we still have quite some FTBFS, mostly coming from Qt Webkit. Feel free to send patches ;-)

Russ Allbery: More on displaying files with head

That was fun! Since my previous entry on using head to display the contents of several files in a form that's easy to cut and paste, multiple people have sent elaborations or related tricks. It seemed like it would be a good idea to post a roundup, since I learned a bunch. Multiple people (I think Josh Triplett was the first) pointed out that one can avoid having to pick a sufficiently large value of -n by instead using:
    head -n -0 *.install
With GNU head at least, a negative number says to print out all lines of the file except that many at the end, so -0 displays the whole file, regardless of size. Unfortunately, while this works anywhere that I am likely to run it, it's not specified by POSIX, while the original is. Another variation, pointed out by Buck Huppmann, is:
    tail -n +0 *.install
The +0 syntax is required by POSIX, unlike the -0 syntax for head... but unfortunately POSIX doesn't require that tail supports multiple files and the headers, although it does for head. Buck also pointed out that including the -v flag will always force the header even if there's only one file, which is useful. (Although be warned that -v isn't a POSIX-recognized flag.) Markus Raab also pointed out the xsel utility, which I'd heard of but hadn't ever used. If the goal is to cut and paste the output, using:
    head -v -n -0 *.install   xsel -i
avoids the cut part by dumping the result directly into the X selection. Buck pointed out xclip, which does the same thing. Both can be used with the -o flag inside an editor to paste as well if you don't want to reach for a mouse. In vi :r !xclip -o, and in Emacs, C-u M-! xclip -o. Finally, Guillem Jover metioned that:
    grep . *.install
does sort of the same thing with a different output format that may be more useful depending on what you're doing. (I find it less human-readable but more machine-parsable.)

4 January 2014

Andrew Pollock: [life] My daughter, the future Olympic swimmer

I'm not a strong swimmer, and never have been. I was never confident in the water as a child. In my teenage years, I had some skin issues that I was very self-conscious about. Going to a boy's school where I was already bullied, I didn't want to add material, so I avoided swimming. To this day, I can barely swim 50 metres freestyle. To think I once had aspirations of getting into the police, which required a bronze medallion. As as result of my atrocious swimming abilities, it's been very important to me that Zoe be able to swim well. Purely for her own personal safety if nothing more. She's been doing "swim classes" of various sorts since she's been 6 months old. In the US, they were group parent/child water familiarisation classes. When we moved back to Australia and turned three, she was eligible to start doing small-group instructor-led classes with Hampton Swim School. It felt like such an milestone just to no longer have to be in the pool with Zoe. I was initially quite skeptical of Hampton's methods, compared with what I'd observed at the Betty Wright Swim School (which subsequently had to close due to aging facilities). Having seen how well Zoe's swimming has progressed in 3 quarters of classes is just amazing. The last few times I've taken Zoe to a public pool for some non-class swim time, her confidence in the water has been fantastic. I've bought some "sinkies", toys that sink to the bottom, and she'll happily dive down to the bottom to retrieve them (with assistance from me getting down there). Today, to escape the 40 plus degree heat, I took her to the Sleeman Sports Centre, because they have a really cool slide, and the whole thing's indoors. Zoe was confidently swimming between me and the side of the pool in water that was over her head, repeatedly. So to have her go from being fine in the water as long as she was being held, to actively asking me to go further back from the wall, in under a year has been really excellent progress. She's also "diving" in off the side (it's more like a bad belly flop, but she has brilliant form at the start, with her hands over her head). We got to the pool today around 10:30am, and it turned out the slide didn't open until 1pm, so we decided to stick around for lunch and wait until the slide opened. To kill time after lunch, we went to the 50 metre pool, where some other kids were taking turns to jump in off the starting blocks. Fearless Zoe wanted to have a go too. This was seriously deep water. It was really inspiring watching this tiny little girl climb up onto the starting blocks of the 1982 Commonwealth Games 50 metre pool and "dive" into the water, flounder over to me, who was furiously treading water in the middle of the lane, and then flounder over to the side, climb out unassisted and do it all over again. It was a seriously "proud father" moment, while I was trying not to drown myself in the middle of the lane. I wish I'd had someone there with a camera to capture the moment. I have great hopes for the future of her swimming, and I think she's ready to go up a level in her swim class.

1 January 2014

Vincent Bernat: Testing infrastructure with serverspec

Checking if your servers are configured correctly can be done with IT automation tools like Puppet, Chef, Ansible or Salt. They allow an administrator to specify a target configuration and ensure it is applied. They can also run in a dry-run mode and report servers not matching the expected configuration. On the other hand, serverspec is a tool to bring the well known RSpec, a testing tool for the Ruby programming language frequently used for test-driven development, to the infrastructure world. It can be used to remotely test server state through an SSH connection. Why one would use such an additional tool? Many things are easier to express with a test than with a configuration change, like for example checking that a service is correctly installed by checking it is listening to some port.

Getting started Good knowledge of Ruby may help but is not a prerequisite to the use of serverspec. Writing tests feels like writing what we expect in plain English. If you think you need to know more about Ruby, here are two short resources to get started: serverspec s homepage contains a short and concise tutorial on how to get started. Please, read it. As a first illustration, here is a test checking a service is correctly listening on port 80:
describe port(80) do
  it   should be_listening  
end
The following test will spot servers still running with Debian Squeeze instead of Debian Wheezy:
describe command("lsb_release -d") do
  it   should return_stdout /wheezy/  
end
Conditional tests are also possible. For example, we want to check the miimon parameter of bond0, but only when the interface is present:
has_bond0 = file('/sys/class/net/bond0').directory?
# miimon should be set to something other than 0, otherwise, no checks
# are performed.
describe file("/sys/class/net/bond0/bonding/miimon"), :if => has_bond0 do
  it   should be_file  
  its(:content)   should_not eq "0\n"  
end
serverspec comes with a complete documentation of available resource types (like port and command) that can be used after the keyword describe. When a test is too complex to be expressed with simple expectations, it can be specified with arbitrary commands. In the below example, we check if memcached is configured to use almost all the available system memory:
# We want memcached to use almost all memory. With a 2GB margin.
describe "memcached" do
  it "should use almost all memory" do
    total = command("vmstat -s   head -1").stdout #  
    total = /\d+/.match(total)[0].to_i
    total /= 1024
    args = process("memcached").args #  
    memcached = /-m (\d+)/.match(args)[1].to_i
    (total - memcached).should be > 0
    (total - memcached).should be < 2000
  end
end
A bit more arcane, but still understandable: we combine arbitrary shell commands (in ) and use of other serverspec resource types (in ).

Advanced use Out of the box, serverspec provides a strong fundation to build a compliance tool to be run on all systems. It comes with some useful advanced tips, like sharing tests among similar hosts or executing several tests in parallel. I have setup a GitHub repository to be used as a template to get the following features:
  • assign roles to servers and tests to roles;
  • parallel execution;
  • report generation & viewer.

Host classification By default, serverspec-init generates a template where each host has its own directory with its unique set of tests. serverspec only handles test execution on remote hosts: the test execution flow (which tests are executed on which servers) is delegated to some Rakefile1. Instead of extracting the list of hosts to test from a directory hiearchy, we can extract it from a file (or from an LDAP server or from any source) and attach a set of roles to each of them:
hosts = File.foreach("hosts")
  .map    line  line.strip  
  .map do  host 
   
    :name => host.strip,
    :roles => roles(host.strip),
   
end
The roles() function should return a list of roles for a given hostname. It could be something as simple as this:
def roles(host)
  roles = [ "all" ]
  case host
  when /^web-/
    roles << "web"
  when /^memc-/
    roles << "memcache"
  when /^lb-/
    roles << "lb"
  when /^proxy-/
    roles << "proxy"
  end
  roles
end
In the snippet below, we create a task for each server as well as a server:all task that will execute the tests for all hosts (in ). Pay attention, in , at how we attach the roles to each server.
namespace :server do
  desc "Run serverspec to all hosts"
  task :all => hosts.map    h  h[:name]   #  
  hosts.each do  host 
    desc "Run serverspec to host # host[:name] "
    ServerspecTask.new(host[:name].to_sym) do  t 
      t.target = host[:name]
      #  : Build the list of tests to execute from server roles
      t.pattern = './spec/ ' + host[:roles].join(",") + ' /*_spec.rb'
    end
  end
end
You can check the list of tasks created:
$ rake -T
rake check:server:all      # Run serverspec to all hosts
rake check:server:web-10   # Run serverspec to host web-10
rake check:server:web-11   # Run serverspec to host web-11
rake check:server:web-12   # Run serverspec to host web-12
Then, you need to modify spec/spec_helper.rb to tell serverspec to fetch the host to test from the environment variable TARGET_HOST instead of extracting it from the spec file name.

Parallel execution By default, each task is executed when the previous one has finished. With many hosts, this can take some time. rake provides the -j flag to specify the number of tasks to be executed in parallel and the -m flag to apply parallelism to all tasks:
$ rake -j 10 -m check:server:all

Reports rspec is invoked for each host. Therefore, the output is something like this:
$ rake spec
env TARGET_HOST=web-10 /usr/bin/ruby -S rspec spec/web/apache2_spec.rb spec/all/debian_spec.rb
......
Finished in 0.99715 seconds
6 examples, 0 failures
env TARGET_HOST=web-11 /usr/bin/ruby -S rspec spec/web/apache2_spec.rb spec/all/debian_spec.rb
......
Finished in 1.45411 seconds
6 examples, 0 failures
This does not scale well if you have dozens or hundreds of hosts to test. Moreover, the output is mangled with parallel execution. Fortunately, rspec comes with the ability to save results in JSON format. Those per-host results can then be consolidated into a single JSON file. All this can be done in the Rakefile:
  1. For each task, set rspec_opts to --format json --out ./reports/current/# target .json. This is done automatically by the subclass ServerspecTask which also handles passing the hostname in an environment variable and a more concise and colored output.
  2. Add a task to collect the generated JSON files into a single report. The test source code is also embedded in the report to make it self-sufficient. Moreover, this task is executed automatically by adding it as a dependency of the last serverspec-related task.
Have a look at the complete Rakefile for more details on how this is done. A very simple web-based viewer can handle those reports2. It shows the test results as a matrix with failed tests in red: Report viewer example Clicking on any test will display the necessary information to troubleshoot errors, including the test short description, the complete test code, the expectation message and the backtrace: Report viewer showing detailed error I hope this additional layer will help making serverspec another feather in the IT cap, between an automation tool and a supervision tool.

  1. A Rakefile is a Makefile where tasks and their dependencies are described in plain Ruby. rake will execute them in the appropriate order.
  2. The viewer is available in the GitHub repository in the viewer/ directory.

Next.

Previous.