Search Results: "spa"

27 June 2017

Colin Watson: New address book

I ve had a kludgy mess of electronic address books for most of two decades, and have got rather fed up with it. My stack consisted of: The biggest practical problem with this was that I had the address book that was most convenient for me to add things to (Google Contacts) and the one I used when sending email, and no sensible way to merge them or move things between them. I also wasn t especially comfortable with having all my contact information in a proprietary web service. My goals for a replacement address book system were: I think I have all this now! New stack The obvious basic technology to use is CardDAV: it s fairly complex, admittedly, but lots of software supports it and one of my goals was not having to write my own thing. This meant I needed a CardDAV server, some way to sync the database to and from both Android and the system where I run mutt, and whatever query glue was necessary to get mutt to understand vCards. There are lots of different alternatives here, and if anything the problem was an embarrassment of choice. In the end I just decided to go for things that looked roughly the right shape for me and tried not to spend too much time in analysis paralysis. CardDAV server I went with Xandikos for the server, largely because I know Jelmer and have generally had pretty good experiences with their software, but also because using Git for history of the backend storage seems like something my future self will thank me for. It isn t packaged in stretch, but it s in Debian unstable, so I installed it from there. Rather than the standalone mode suggested on the web page, I decided to set it up in what felt like a more robust way using WSGI. I installed uwsgi, uwsgi-plugin-python3, and libapache2-mod-proxy-uwsgi, and created the following file in /etc/uwsgi/apps-available/xandikos.ini which I then symlinked into /etc/uwsgi/apps-enabled/xandikos.ini:
[uwsgi]
socket = 127.0.0.1:8801
uid = xandikos
gid = xandikos
umask = 022
master = true
cheaper = 2
processes = 4
plugin = python3
module = xandikos.wsgi:app
env = XANDIKOSPATH=/srv/xandikos/collections
The port number was arbitrary, as was the path. You need to create the xandikos user and group first (adduser --system --group --no-create-home --disabled-login xandikos). I created /srv/xandikos owned by xandikos:xandikos and mode 0700, and I recommend setting a umask as shown above since uwsgi s default umask is 000 (!). You should also run sudo -u xandikos xandikos -d /srv/xandikos/collections --autocreate and then Ctrl-c it after a short time (I think it would be nicer if there were a way to ask the WSGI wrapper to do this). For Apache setup, I kept it reasonably simple: I ran a2enmod proxy_uwsgi, used htpasswd to create /etc/apache2/xandikos.passwd with a username and password for myself, added a virtual host in /etc/apache2/sites-available/xandikos.conf, and enabled it with a2ensite xandikos:
<VirtualHost *:443>
        ServerName xandikos.example.org
        ServerAdmin me@example.org
        ErrorLog /var/log/apache2/xandikos-error.log
        TransferLog /var/log/apache2/xandikos-access.log
        <Location />
                ProxyPass "uwsgi://127.0.0.1:8801/"
                AuthType Basic
                AuthName "Xandikos"
                AuthBasicProvider file
                AuthUserFile "/etc/apache2/xandikos.passwd"
                Require valid-user
        </Location>
</VirtualHost>
Then service apache2 reload, set the new virtual host up with Let s Encrypt, reloaded again, and off we go. Android integration I installed DAVdroid from the Play Store: it cost a few pounds, but I was OK with that since it s GPLv3 and I m happy to help fund free software. I created two accounts, one for my existing Google Contacts database (and in fact calendaring as well, although I don t intend to switch over to self-hosting that just yet), and one for the new Xandikos instance. The Google setup was a bit fiddly because I have two-step verification turned on so I had to create an app-specific password. The Xandikos setup was straightforward: base URL, username, password, and done. Since I didn t completely trust the new setup yet, I followed what seemed like the most robust option from the DAVdroid contacts syncing documentation, and used the stock contacts app to export my Google Contacts account to a .vcf file and then import that into the appropriate DAVdroid account (which showed up automatically). This seemed straightforward and everything got pushed to Xandikos. There are some weird delays in syncing contacts that I don t entirely understand, but it all seems to get there in the end. mutt integration First off I needed to sync the contacts. (In fact I happen to run mutt on the same system where I run Xandikos at the moment, but I don t want to rely on that, and going through the CardDAV server means that I don t have to poke holes for myself using filesystem permissions.) I used vdirsyncer for this. In ~/.vdirsyncer/config:
[general]
status_path = "~/.vdirsyncer/status/"
[pair contacts]
a = "contacts_local"
b = "contacts_remote"
collections = ["from a", "from b"]
[storage contacts_local]
type = "filesystem"
path = "~/.contacts/"
fileext = ".vcf"
[storage contacts_remote]
type = "carddav"
url = "<Xandikos base URL>"
username = "<my username>"
password = "<my password>"
Running vdirsyncer discover and vdirsyncer sync then synced everything into ~/.contacts/. I added an hourly crontab entry to run vdirsyncer -v WARNING sync. Next, I needed a command-line address book tool based on this. khard looked about right and is in stretch, so I installed that. In ~/.config/khard/khard.conf (this is mostly just the example configuration, but I preferred to sort by first name since not all my contacts have neat first/last names):
[addressbooks]
[[contacts]]
path = ~/.contacts/<UUID of my contacts collection>/
[general]
debug = no
default_action = list
editor = vim
merge_editor = vimdiff
[contact table]
# display names by first or last name: first_name / last_name
display = first_name
# group by address book: yes / no
group_by_addressbook = no
# reverse table ordering: yes / no
reverse = no
# append nicknames to name column: yes / no
show_nicknames = no
# show uid table column: yes / no
show_uids = yes
# sort by first or last name: first_name / last_name
sort = first_name
[vcard]
# extend contacts with your own private objects
# these objects are stored with a leading "X-" before the object name in the vcard files
# every object label may only contain letters, digits and the - character
# example:
#   private_objects = Jabber, Skype, Twitter
private_objects = Jabber, Skype, Twitter
# preferred vcard version: 3.0 / 4.0
preferred_version = 3.0
# Look into source vcf files to speed up search queries: yes / no
search_in_source_files = no
# skip unparsable vcard files: yes / no
skip_unparsable = no
Now khard list shows all my contacts. So far so good. Apparently there are some awkward vCard compatibility issues with creating or modifying contacts from the khard end. I ve tried adding one address from ~/.mutt/aliases using khard and it seems to at least minimally work for me, but I haven t explored this very much yet. I had to install python3-vobject 0.9.4.1-1 from experimental to fix eventable/vobject#39 saving certain vCard files. Finally, mutt integration. I already had set query_command="lbdbq '%s'" in ~/.muttrc, and I wanted to keep that in place since I still wanted to use LDAP querying as well. I had to write a very small amount of code for this (perhaps I should contribute this to lbdb upstream?), in ~/.lbdb/modules/m_khard:
#! /bin/sh
m_khard_query ()  
    khard email --parsable --remove-first-line --search-in-source-files "$1"
 
My full ~/.lbdb/rc now reads as follows (you probably won t want the LDAP stuff, but I ve included it here for completeness):
MODULES_PATH="$MODULES_PATH $HOME/.lbdb/modules"
METHODS='m_muttalias m_khard m_ldap'
LDAP_NICKS='debian canonical'
Next steps I ve deleted one account from Google Contacts just to make sure that everything still works (e.g. I can still search for it when composing a new message), but I haven t yet deleted everything. I won t be adding anything new there though. I need to push everything from ~/.mutt/aliases into the new system. This is only about 30 contacts so shouldn t take too long. Overall this feels like a big improvement! It wasn t a trivial amount of setup for just me, but it means I have both better usability for myself and more independence from proprietary services, and I think I can add extra users with much less effort if I need to. Postscript A day later and I ve consolidated all my accounts from Google Contacts and ~/.mutt/aliases into the new system, with the exception of one group that I had defined as a mutt alias and need to work out what to do with. This all went smoothly. I ve filed the new lbdb module as #866178, and the python3-vobject bug as #866181.

26 June 2017

Jonathan Dowland: Coming in from the cold

I've been using a Mac day-to-day since around 2014, initially as a refreshing break from the disappointment I felt with GNOME3, but since then a few coincidences have kept me on the platform. Something happened earlier in the year that made me start to think about a move back to Linux on the desktop. My next work hardware refresh is due in March next year, which gives me about nine months to "un-plumb" myself from the Mac ecosystem. From the top of my head, here's the things I'm going to have to address: I think that's probably it: not a big list! Notably, I'm not locked into iTunes, which I avoid where possible; Apple's Photo app (formerly iPhoto) which is a bit of a disaster; nor Time Machine, which is excellent, but I have a backup system for other things in place that I can use.

25 June 2017

Andreas Bombe: PDP-8/e Replicated Introduction

I am creating a replica of the DEC PDP-8/e architecture in an FPGA from schematics of the original hardware. So how did I end up with a project like this? The story begins with me wanting to have a computer with one of those front panels that have many, many lights where you can really see, in real time, what the computer is doing while it is executing code. Not because I am nostalgic for a prior experience with any of those I was born a bit too late for that and my first computer as a kid was a Commodore 64. Now, the front panel era ended around 40 years ago with the advent of microprocessors and computers of that age and older that are complete and working are hard to find and not cheap. And even if you do, there s the issue of weight, size (complete systems with peripherals fill at least a rack) and power consumption. So what to do build myself a small one with modern technology of course. While there s many computer architectures of that era to choose from, the various PDP machines by DEC are significant and well known (and documented) due to their large numbers. The most important are probably the 12 bit PDP-8, the 16 bit PDP-11 and the 36 bit PDP-10. While the PDP-11 is enticing because of the possibility to run UNIX I wanted to start with something simpler, so I chose the PDP-8.
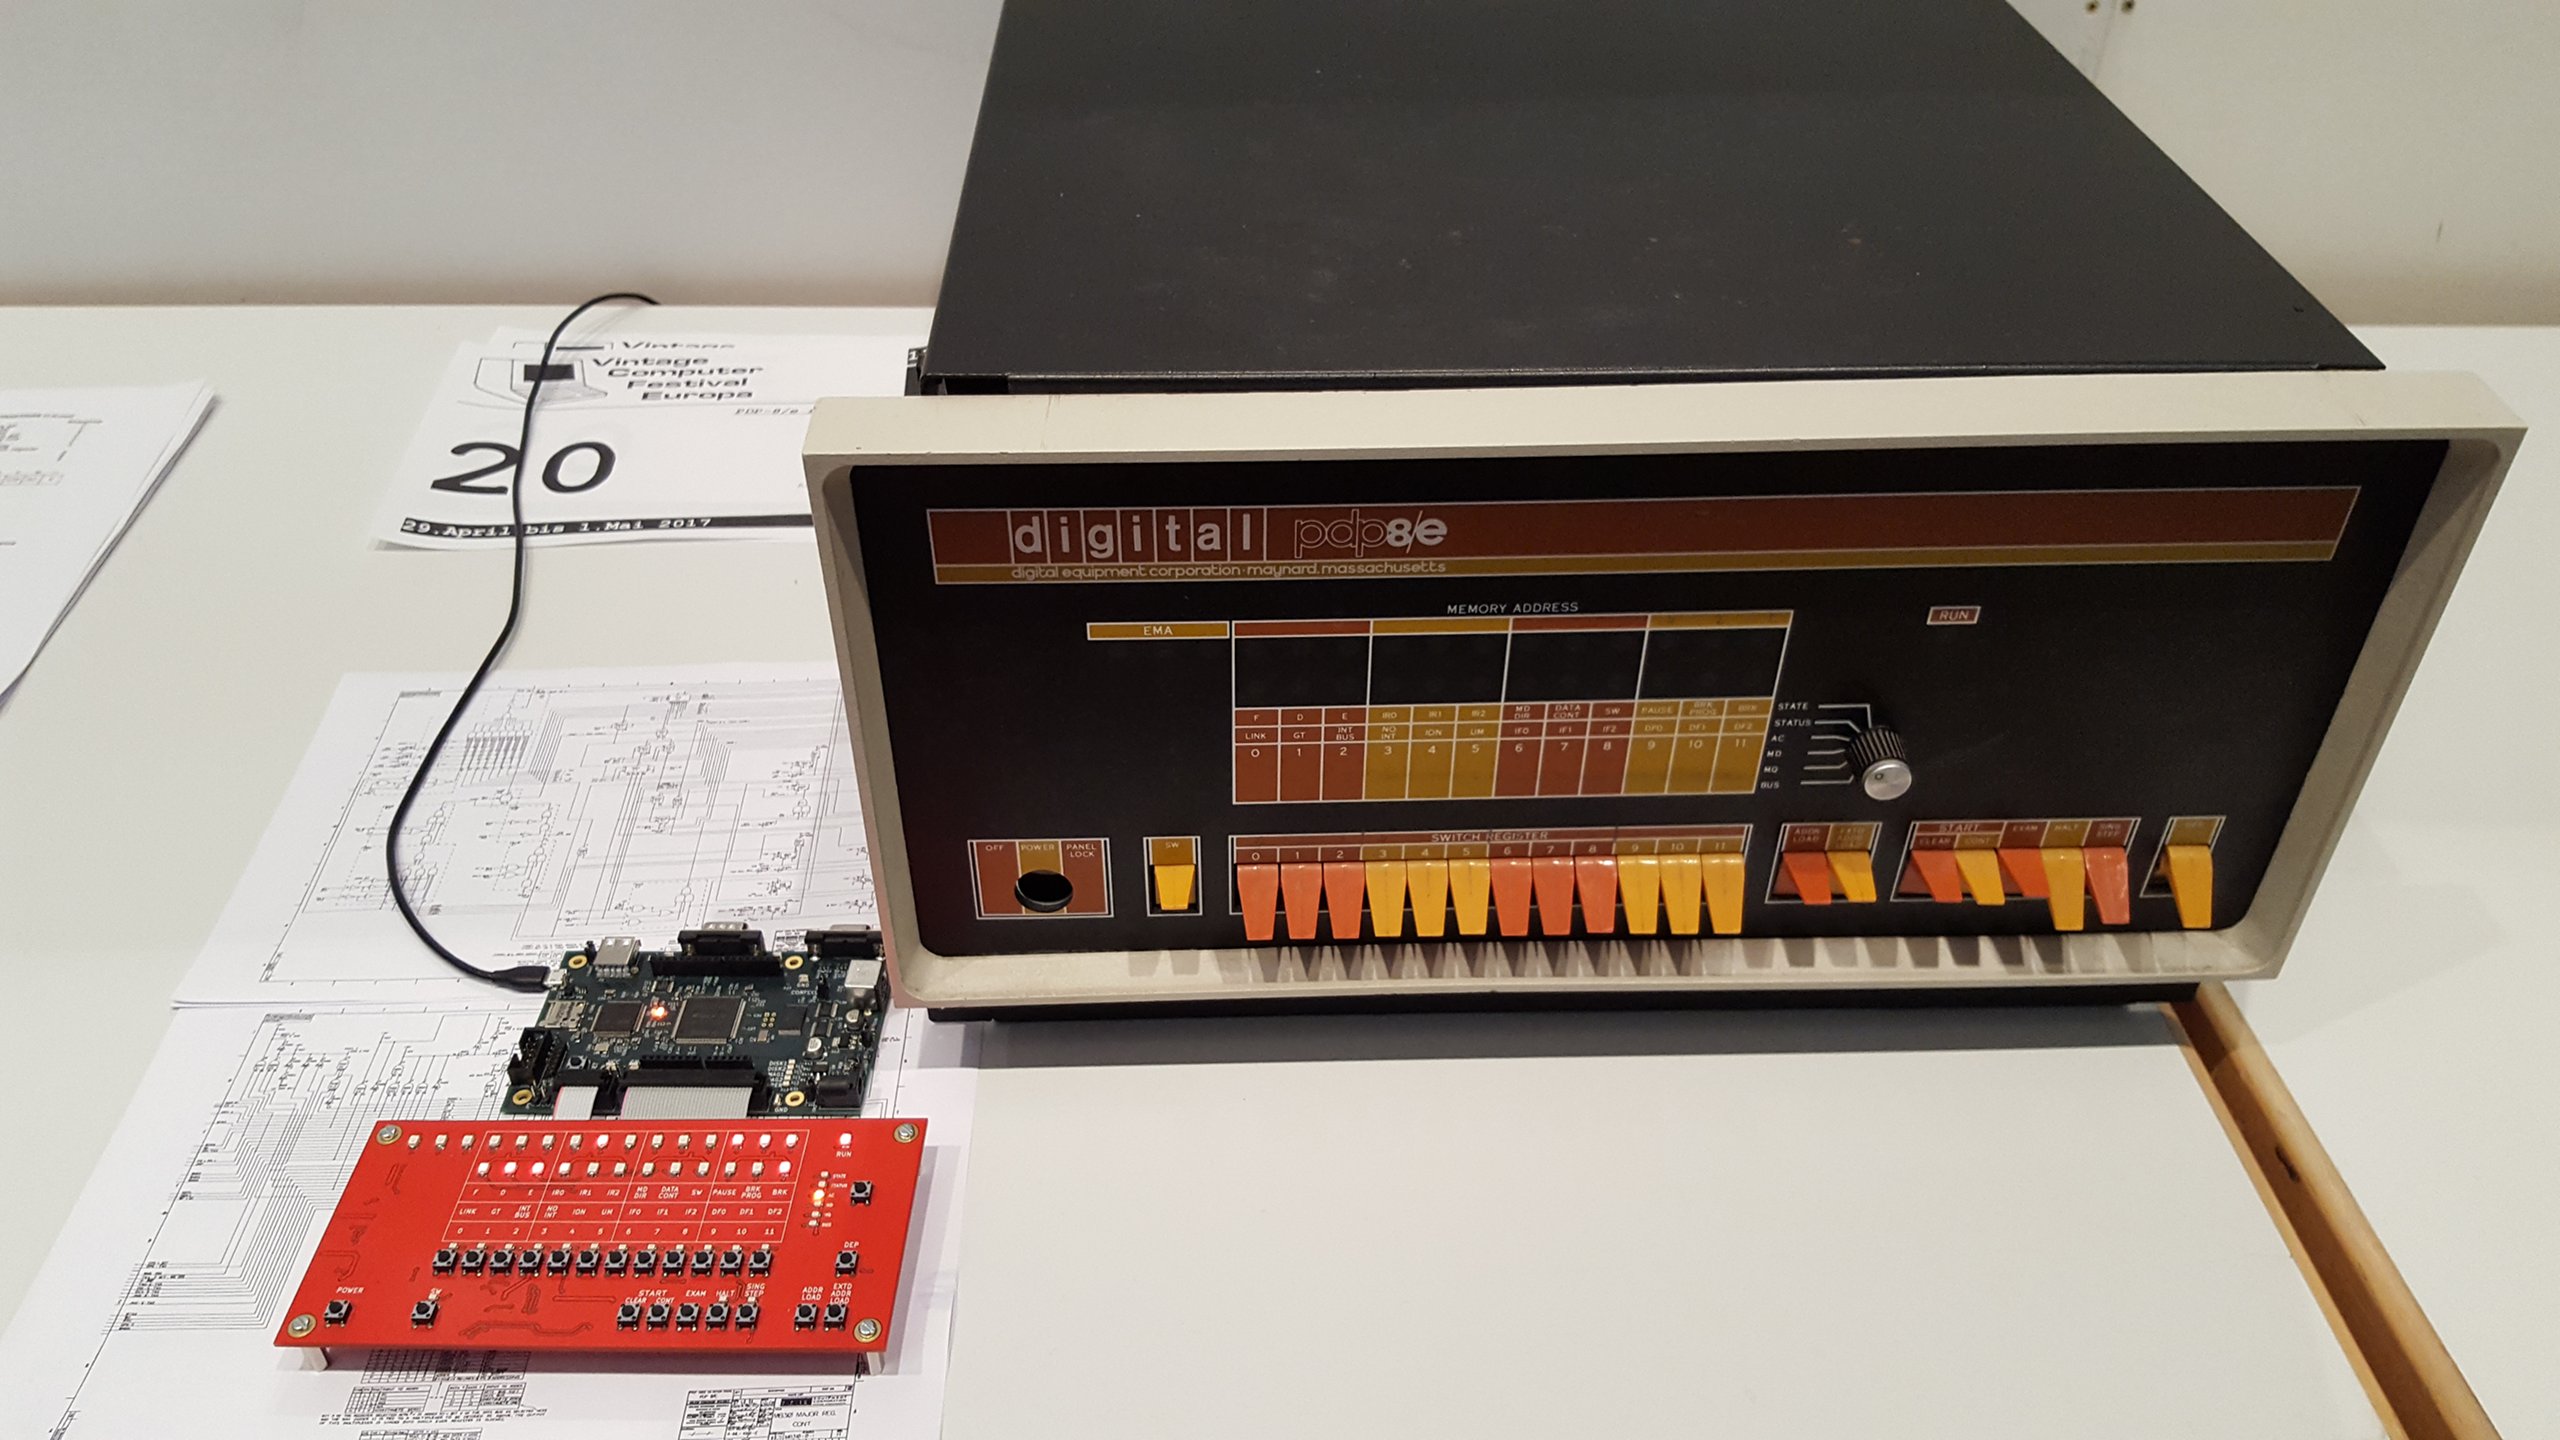
My implementation on display next to a real PDP-8/e at VCFe 18.0

The Original DEC started the PDP-8 line of computers programmed data processors designed as low cost machines in 1965. It is a quite minimalist 12 bit architecture based on the earlier PDP-5, and by minimalist I mean seriously minimal. If you are familiar with early 8 bit microprocessors like the 6502 or 8080 you will find them luxuriously equipped in comparison. The PDP-8 base architecture has a program counter (PC) and an accumulator (AC)1. That s it. There are no pointer or index registers2. There is no stack. It has addition and AND instructions but subtractions and OR operations have to be manually coded. The optional Extended Arithmetic Element adds the MQ register but that s really it for visible registers. The Wikipedia page on the PDP-8 has a good detailed description. Regarding technology, the PDP-8 series has been in production long enough to get the whole range of implementations from discrete transistor logic to microprocessors. The 8/e which I target was right in the middle, implemented in TTL logic where each IC contains multiple logic elements. This allowed the CPU itself (including timing generator) to fit on three large circuit boards plugged into a backplane. Complete systems would have at least another board for the front panel and multiple boards for the core memory, then additional boards for whatever options and peripherals were desired.

Design Choices and Comparisons I m not the only one who had the idea to build something like that, of course. Among the other modern PDP-8 implementations with a front panel, probably the most prominent project is the Spare Time Gizmos SBC6120 which is a PDP-8 single board computer built around the Harris/Intersil HD-6120 microprocessor, which implementes the PDP-8 architecture, combined with a nice front panel. Another is the PiDP-8/I, which is another nice front panel (modeled after the 8/i which has even more lights) driven by the simh simulator running under Linux on a Raspberry Pi. My goal is to get front panel lights that appear exactly like the real ones in operation. This necessitates driving the lights at full speed as they change with every instruction or even within instructions for some display selections. For example, if you run a tight loop that does nothing but increment AC while displaying that register, it would appear that all lights are lit at equal but less than full brightness. The reason is that the loop runs at such a high speed that even the most significant bit, which is blinking the slowest, is too fast to see flicker. Hence they are all effectively 50% on, just at different frequencies, and appear to be constantly light at the same brightness. This is where the other projects lack what I am looking for. The PiDP-8/I is a multiplexed display which updates at something like 30 Hz or 60 Hz, taking whatever value is current in the simulation software at the time. All the states the lights took inbetween are lost and consequently there is flickering where there shouldn t be. On the SBC6120 at least the address lines appear to update at full speed as these are the actual RAM address lines. However the used 6120 microprocessor does not have required data for the indicator display externally available. Instead, the SBC6120 runs an interrupt at 30 Hz to trap into its firmware/monitor program which then reads the current state and writes it to the front panel display, which is essentially just another peripheral. A different considerable problem with the SBC6120 is its use of the 6100 microprocessor family ICs, which are themselves long out of production and not trivial (or cheaply) to come by. Given that the way to go is to drive all lights in step with every cycle3, this can be done by a software running on a dedicated microcontroller which is how I started or by implementing a real CPU with all the needed outputs in an FPGA which is the project I am writing about. In the next post I give an overview of the hardware I built so far and some of the features that are yet to be implemented.

  1. With an associated link bit which is a little different from a carry bit in that it is treated as a thirteenth bit, i.e. it will be flipped rather than set when a carry occurs. [return]
  2. Although there are 8 specially treated memory addresses that will pre-increment when used in indirect addressing. [return]
  3. Basic cycles on the PDP-8/e are 1.4 s for memory modifying cycles and fast cycles of 1.2 s for everything else. Instructions can be one to three cycles long. [return]

24 June 2017

Steve Kemp: Linux security modules, round two.

So recently I wrote a Linux Security Module (LSM) which would deny execution of commands, unless an extended attribute existed upon the filesystem belonging to the executables. The whitelist-LSM worked well, but it soon became apparent that it was a little pointless. Most security changes are pointless unless you define what you're defending against - your "threat model". In my case it was written largely as a learning experience, but also because I figured it seemed like it could be useful. However it wasn't actually as useful because you soon realize that you have to whitelist too much: In short there comes a point where user alice must run executable blah. If alice can run it, then so can mallory. At which point you realize the exercise is not so useful. Taking a step back I realized that what I wanted to to prevent was the execution of unknown/unexpected, and malicious binaries How do you identify known-good binaries? Well hashes & checksums are good. So for my second attempt I figured I'd not look for a mere "flag" on a binary, instead look for a valid hash. Now my second LSM is invoked for every binary that is executed by a user: In practice this is the same behaviour as the previous LSM - a binary is either executable, because there is a good hash, or it is not, because it is missing or bogus. If somebody deploys a binary rootkit this will definitely stop it from executing, but of course there is a huge hole - scripting-languages: Despite that the project was worthwhile, I can clearly describe what it is designed to achieve ("Deny the execution of unknown binaries", and "Deny binaries that have been modified"), and I learned how to hash a file from kernel-space - which was surprisingly simple.
(Yes I know about IMA and EVM - this was a simple project for learning purposes. Public-key signatures will be something I'll look at next/soon/later. :)
Perhaps the only other thing to explore is the complexity in allowing/denying actions based on the user - in a human-readable fashion, not via UIDs. So www-data can execute some programs, alice can run a different set of binaries, and git can only run /usr/bin/git. Of course down that path lies apparmour, selinux, and madness..

Ingo Juergensmann: Upgrade to Debian Stretch - GlusterFS fails to mount

Before I upgrade from Jessie to Stretch everything worked as a charme with glusterfs in Debian. But after I upgraded the first VM to Debian Stretch I discovered that glusterfs-client was unable to mount the storage on Jessie servers. I got this in glusterfs log:
[2017-06-24 12:51:53.240389] I [MSGID: 100030] [glusterfsd.c:2454:main] 0-/usr/sbin/glusterfs: Started running /usr/sbin/glusterfs version 3.8.8 (args: /usr/sbin/glusterfs --read-only --fuse-mountopts=nodev,noexec --volfile-server=192.168.254.254 --volfile-id=/le --fuse-mountopts=nodev,noexec /etc/letsencrypt.sh/certs)
[2017-06-24 12:51:54.534826] E [mount.c:318:fuse_mount_sys] 0-glusterfs-fuse: ret = -1

[2017-06-24 12:51:54.534896] I [mount.c:365:gf_fuse_mount] 0-glusterfs-fuse: direct mount failed (Invalid argument) errno 22, retry to mount via fusermount
[2017-06-24 12:51:56.668254] I [MSGID: 101190] [event-epoll.c:628:event_dispatch_epoll_worker] 0-epoll: Started thread with index 1
[2017-06-24 12:51:56.671649] E [glusterfsd-mgmt.c:1590:mgmt_getspec_cbk] 0-glusterfs: failed to get the 'volume file' from server
[2017-06-24 12:51:56.671669] E [glusterfsd-mgmt.c:1690:mgmt_getspec_cbk] 0-mgmt: failed to fetch volume file (key:/le)
[2017-06-24 12:51:57.014502] W [glusterfsd.c:1327:cleanup_and_exit] (-->/usr/lib/x86_64-linux-gnu/libgfrpc.so.0(rpc_clnt_handle_reply+0x90) [0x7fbea36c4a20] -->/usr/sbin/glusterfs(mgmt_getspec_cbk+0x494) [0x55fbbaed06f4] -->/usr/sbin/glusterfs(cleanup_and_exit+0x54) [0x55fbbaeca444] ) 0-: received signum (0), shutting down
[2017-06-24 12:51:57.014564] I [fuse-bridge.c:5794:fini] 0-fuse: Unmounting '/etc/letsencrypt.sh/certs'.
[2017-06-24 16:44:45.501056] I [MSGID: 100030] [glusterfsd.c:2454:main] 0-/usr/sbin/glusterfs: Started running /usr/sbin/glusterfs version 3.8.8 (args: /usr/sbin/glusterfs --read-only --fuse-mountopts=nodev,noexec --volfile-server=192.168.254.254 --volfile-id=/le --fuse-mountopts=nodev,noexec /etc/letsencrypt.sh/certs)
[2017-06-24 16:44:45.504038] E [mount.c:318:fuse_mount_sys] 0-glusterfs-fuse: ret = -1

[2017-06-24 16:44:45.504084] I [mount.c:365:gf_fuse_mount] 0-glusterfs-fuse: direct mount failed (Invalid argument) errno 22, retry to mount via fusermount
After some searches on the Internet I found Debian #858495, but no solution for my problem. Some search results recommended to set "option rpc-auth-allow-insecure on", but this didn't help. In the end I joined #gluster on Freenode and got some hints there:
JoeJulian ij__: debian breaks apart ipv4 and ipv6. You'll need to remove the ipv6 ::1 address from localhost in /etc/hosts or recombine your ip stack (it's a sysctl thing)
JoeJulian It has to do with the decisions made by the debian distro designers. All debian versions should have that problem. (yes, server side).
Removing ::1 from /etc/hosts and from lo interface did the trick and I could mount glusterfs storage from Jessie servers in my Stretch VMs again. However, when I upgraded the glusterfs storages to Stretch as well, this "workaround" didn't work anymore. Some more searching on the Internet made me found this posting on glusterfs mailing list:
We had seen a similar issue and Rajesh has provided a detailed explanation on why at [1]. I'd suggest you to not to change glusterd.vol but execute "gluster volume set <volname> transport.address-family inet" to allow Gluster to listen on IPv4 by default.
Setting this option instantly fixed my issues with mounting glusterfs storages. So, whatever is wrong with glusterfs in Debian, it seems to have something to do with IPv4 and IPv6. When disabling IPv6 in glusterfs, it works. I added information to #858495.
Kategorie:

Riku Voipio: Cross-compiling with debian stretch

Debian stretch comes with cross-compiler packages for selected architectures:
 $ apt-cache search cross-build-essential
crossbuild-essential-arm64 - Informational list of cross-build-essential packages for
crossbuild-essential-armel - ...
crossbuild-essential-armhf - ...
crossbuild-essential-mipsel - ...
crossbuild-essential-powerpc - ...
crossbuild-essential-ppc64el - ...

Lets have a quick exact steps guide. But first - while you can use do all this in your desktop PC rootfs, it is more wise to contain yourself. Fortunately, Debian comes with a container tool out of box:

sudo debootstrap stretch /var/lib/container/stretch http://deb.debian.org/debian
echo "strech_cross" sudo tee /var/lib/container/stretch/etc/debian_chroot
sudo systemd-nspawn -D /var/lib/container/stretch
Then we set up cross-building enviroment for arm64 inside the container:

# Tell dpkg we can install arm64
dpkg --add-architecture arm64
# Add src line to make "apt-get source" work
echo "deb-src http://deb.debian.org/debian stretch main" >> /etc/apt/sources.list
apt-get update
# Install cross-compiler and other essential build tools
apt install --no-install-recommends build-essential crossbuild-essential-arm64
Now we have a nice build enviroment, lets choose something more complicated than the usual kernel/BusyBox to cross-build, qemu:

# Get qemu sources from debian
apt-get source qemu
cd qemu-*
# New in stretch: build-dep works in unpacked source tree
apt-get build-dep -a arm64 .
# Cross-build Qemu for arm64
dpkg-buildpackage -aarm64 -j6 -b
Now that works perfectly for Qemu. For other packages, challenges may appear. For example you may have to se "nocheck" flag to skip build-time unit tests. Or some of the build-dependencies may not be multiarch-enabled. So work continues :)

23 June 2017

Elena 'valhalla' Grandi: On brokeness, the live installer and being nice to people

On brokeness, the live installer and being nice to people

This morning I've read this blog.einval.com/2017/06/22#tro.

I understand that somebody on the internet will always be trolling, but I just wanted to point out:

* that the installer in the old live images has been broken (for international users) for years
* that nobody cared enough to fix it, not even the people affected by it (the issue was reported as known in various forums, but for a long time nobody even opened an issue to let the *developers* know).

Compare this with the current situation, with people doing multiple tests as the (quite big number of) images were being built, and a fix released soon after for the issues found.

I'd say that this situation is great, and that instead of trolling around we should thank the people involved in this release for their great job.

Arturo Borrero Gonz lez: Backup router/switch configuration to a git repository

git Most routers/switches out there store their configuration in plain text, which is nice for backups. I m talking about Cisco, Juniper, HPE, etc. The configuration of our routers are being changed several times a day by the operators, and in this case we lacked some proper way of tracking these changes. Some of these routers come with their own mechanisms for doing backups, and depending on the model and version perhaps they include changes-tracking mechanisms as well. However, they mostly don t integrate well into our preferred version control system, which is git. After some internet searching, I found rancid, which is a suite for doing tasks like this. But it seemed rather complex and feature-full for what we required: simply fetch the plain text config and put it into a git repo. Worth noting that the most important drawback of not triggering the change-tracking from the router/switch is that we have to follow a polling approach: loggin into each device, get the plain text and the commit it to the repo (if changes detected). This can be hooked in cron, but as I said, we lost the sync behaviour and won t see any changes until the next cron is run. In most cases, we lost authorship information as well. But it was not important for us right now. In the future this is something that we will have to solve. Also, some routers/switches lack some basic SSH security improvements, like public-key authentication, so we end having to hard-code user/pass in our worker script. Since we have several devices of the same type, we just iterate over their names. For example, this is what we use for hp comware devices:
#!/bin/bash
# run this script by cron
USER="git"
PASSWORD="readonlyuser"
DEVICES="device1 device2 device3 device4"
FILE="flash:/startup.cfg"
GIT_DIR="myrepo"
GIT="/srv/git/$ GIT_DIR .git"
TMP_DIR="$(mktemp -d)"
if [ -z "$TMP_DIR" ] ; then
	echo "E: no temp dir created" >&2
	exit 1
fi
GIT_BIN="$(which git)"
if [ ! -x "$GIT_BIN" ] ; then
	echo "E: no git binary" >&2
	exit 1
fi
SCP_BIN="$(which scp)"
if [ ! -x "$SCP_BIN" ] ; then
	echo "E: no scp binary" >&2
	exit 1
fi
SSHPASS_BIN="$(which sshpass)"
if [ ! -x "$SSHPASS_BIN" ] ; then
	echo "E: no sshpass binary" >&2
	exit 1
fi
# clone git repo
cd $TMP_DIR
$GIT_BIN clone $GIT
cd $GIT_DIR
for device in $DEVICES; do
	mkdir -p $device
	cd $device
	# fetch cfg
	CONN="$ USER @$ device "
	$SSHPASS_BIN -p "$PASSWORD" $SCP_BIN $ CONN :$ FILE  .
	# commit
	$GIT_BIN add -A .
	$GIT_BIN commit -m "$ device : configuration change" \
		-m "A configuration change was detected" \
		--author="cron <cron@example.com>"
	$GIT_BIN push -f
	cd ..
done
# cleanup
rm -rf $TMP_DIR
You should create a read-only user git in the devices. And beware that each device model has the config file stored in a different place. For reference, in HP comware, the file to scp is flash:/startup.cfg. And you might try creating the user like this:
local-user git class manage
 password hash xxxxx
 service-type ssh
 authorization-attribute user-role security-audit
#
In Junos/Juniper, the file you should scp is /config/juniper.conf.gz and the script should gunzip the data before committing. For the read-only user, try is something like this:
system  
	[...]
	login  
		[...]
		class git  
			permissions maintenance;
			allow-commands scp.*;
		 
		user git  
			uid xxx;
			class git;
			authentication  
				encrypted-password "xxx";


The file to scp in HP procurve is /cfg/startup-config. And for the read-only user, try something like this:
aaa authorization group "git user" 1 match-command "scp.*" permit
aaa authentication local-user "git" group "git user" password sha1 "xxxxx"
What would be the ideal situation? Get the device controlled directly by git (i.e. commit > git hook > device update) or at least have the device to commit the changes by itself to git. I m open to suggestions :-)

22 June 2017

Norbert Preining: Signal handling in R

Recently I have been programming quite a lot in R, and today stumbled over the problem to implement a kind of monitoring loop in R. Typically that would be a infinite loop with sleep calls, but I wanted to allow for waking up from the sleep via sending UNIX style signals, in particular SIGINT. After some searching I found Beyond Exception Handling: Conditions and Restarts from the Advanced R book. But it didn t really help me a lot to program an interrupt handler.
My requirements were: Unfortunately it seems not to be possible to ignore interrupts at all from with the R code. The best one can do is install interrupt handlers and try to repeat the code which was executed while the interrupt happened. This is what I tried to implement with the following code below. I still have to digest the documentation about conditions and restarts, and play around a lot, but at least this is an initial working version.
workfun <- function()  
  i <- 1
  do_repeat <- FALSE
  while (TRUE)  
    message("begin of the loop")
    withRestarts(
       
        # do all the work here
        cat("Entering work part i =", i, "\n");
        Sys.sleep(10)
        i <- i + 1
        cat("finished work part\n")
       , 
      gotSIG = function()   
        message("interrupted while working, restarting work part")
        do_repeat <<- TRUE
        NULL
       
    )
    if (do_repeat)  
      cat("restarting work loop\n")
      do_repeat <- FALSE
      next
      else  
      cat("between work and sleep part\n")
     
    withRestarts(
       
        # do the sleep part here
        cat("Entering sleep part i =", i, "\n")
        Sys.sleep(10)
        i <- i + 1
        cat("finished sleep part\n")
       , 
      gotSIG = function()  
        message("got work to do, waking up!")
        NULL
       
    )
    message("end of the loop")
   
 
cat("Current process:", Sys.getpid(), "\n");
withCallingHandlers( 
    workfun()
   ,
  interrupt = function(e)  
    invokeRestart("gotSIG")
   )
While not perfect, I guess I have to live with this method for now.

21 June 2017

Joey Hess: DIY professional grade solar panel installation

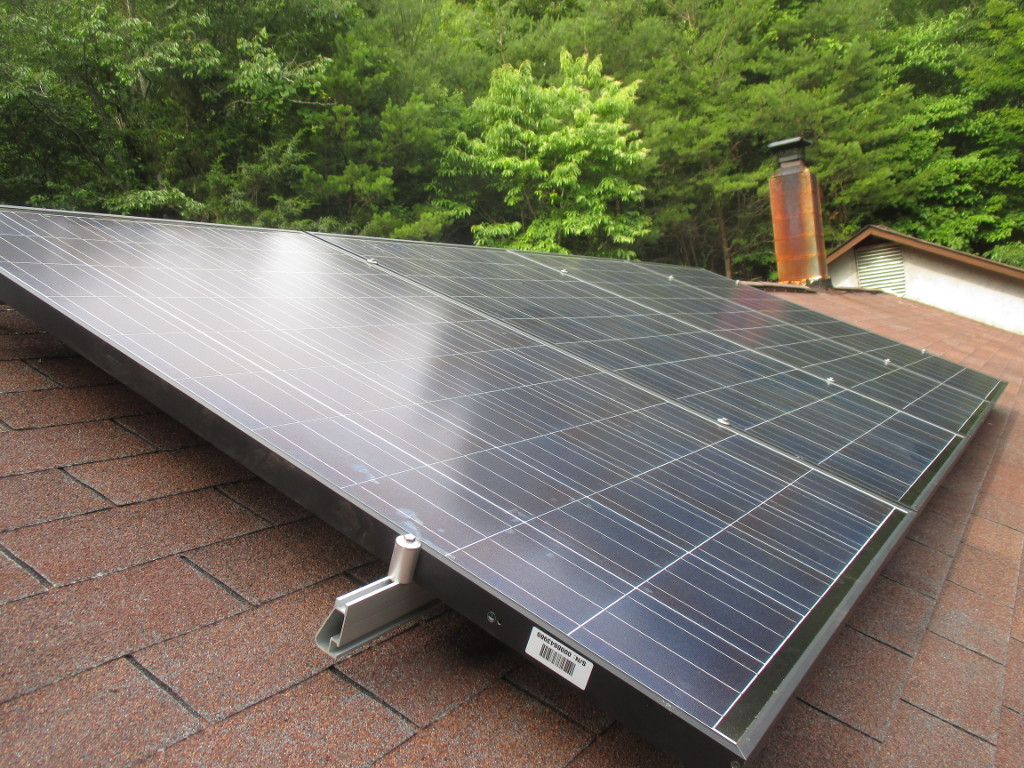
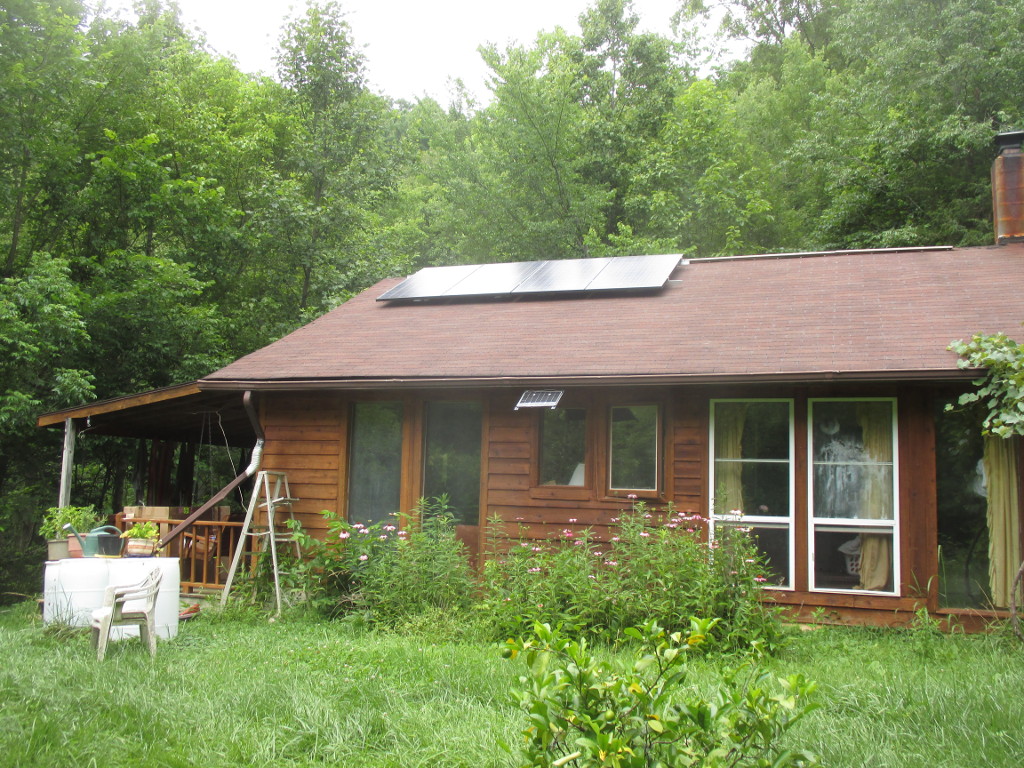
I've installed 1 kilowatt of solar panels on my roof, using professional grade eqipment. The four panels are Astronergy 260 watt panels, and they're mounted on IronRidge XR100 rails. Did it all myself, without help. house with 4 solar panels on roof I had three goals for this install:
  1. Cheap but sturdy. Total cost will be under $2500. It would probably cost at least twice as much to get a professional install, and the pros might not even want to do such a small install.
  2. Learn the roof mount system. I want to be able to add more panels, remove panels when working on the roof, and understand everything.
  3. Make every day a sunny day. With my current solar panels, I get around 10x as much power on a sunny day as a cloudy day, and I have plenty of power on sunny days. So 10x the PV capacity should be a good amount of power all the time.
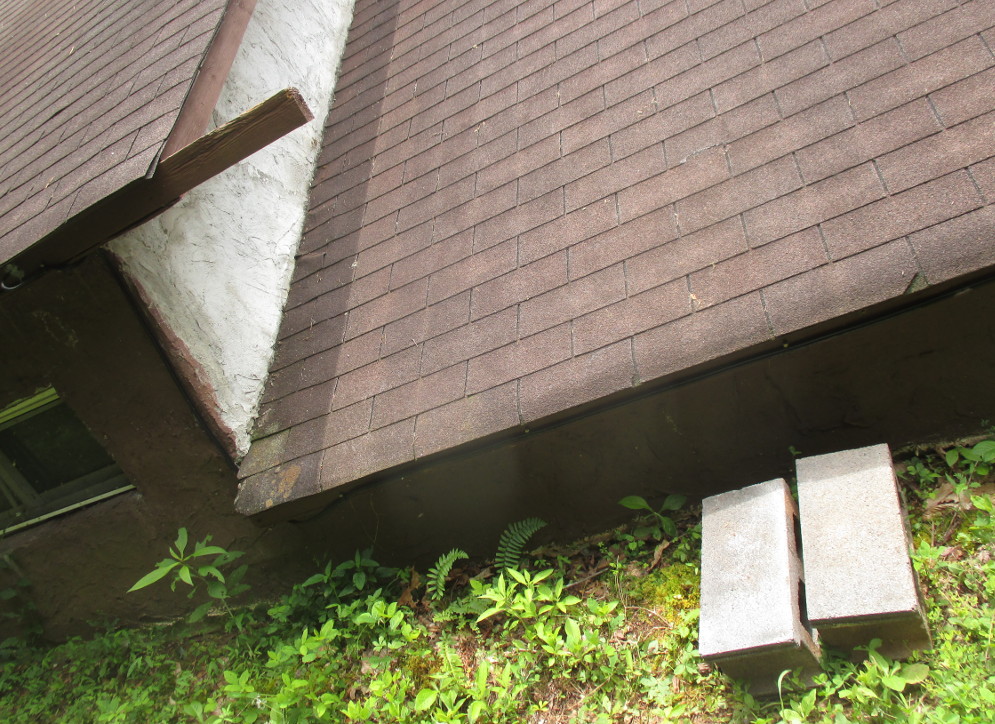
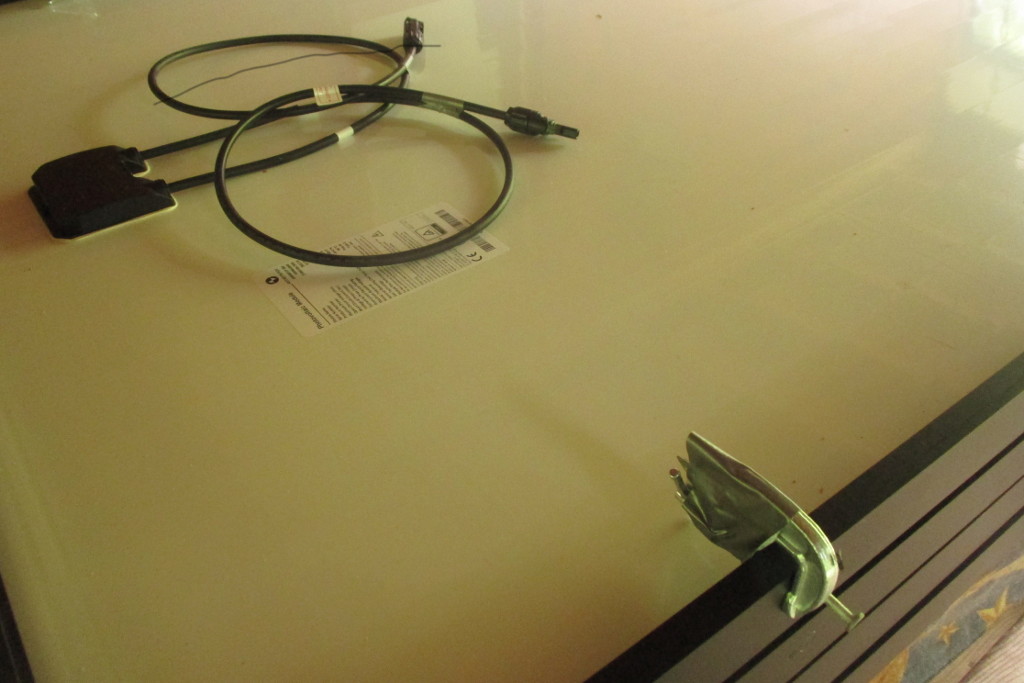
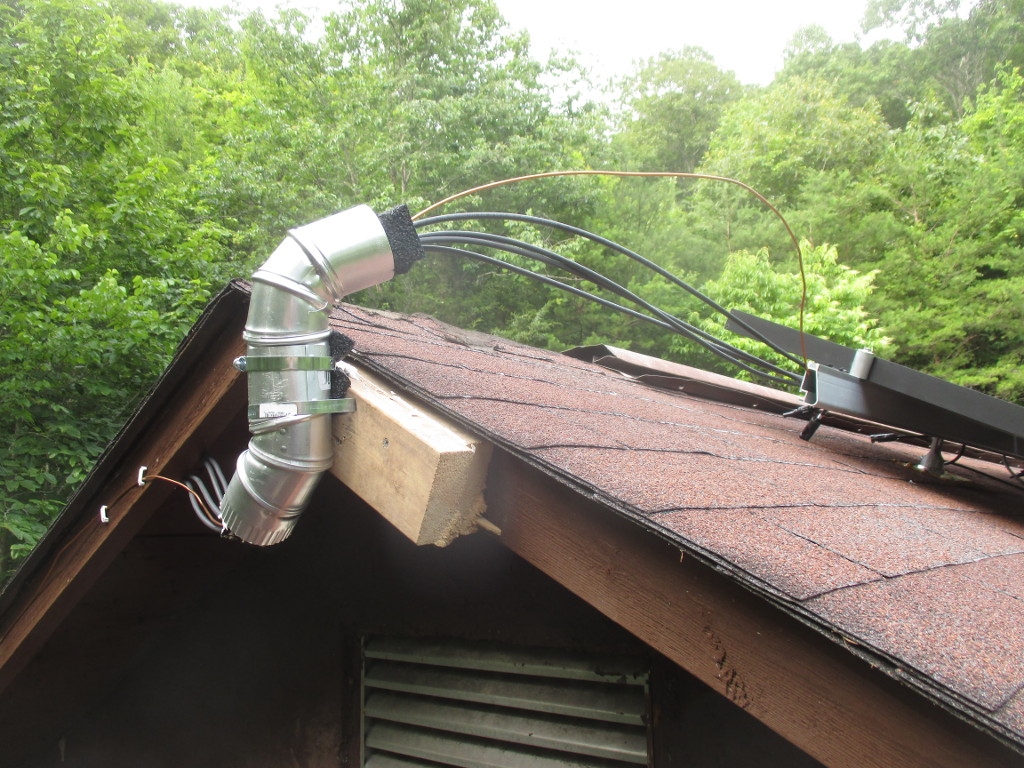
My main concerns were, would I be able to find the rafters when installing the rails, and would the 5x3 foot panels be too unweildly to get up on the roof by myself. I was able to find the rafters, without needing a stud finder, after I removed the roof's vent caps, which exposed the rafters. The shingles were on straight enough that I could follow the lines down and drilled into the rafter on the first try every time. And I got the rails on spaced well and straight, although I could have spaced the FlashFeet out better (oops). My drill ran out of juice half-way, and I had to hack it to recharge on solar power, but that's another story. Between the learning curve, a lot of careful measurement, not the greatest shoes for roofing, and waiting for recharging, it took two days to get the 8 FlashFeet installed and the rails mounted. Taking a break from that and swimming in the river, I realized I should have been wearing my water shoes on the roof all along. Super soft and nubbly, they make me feel like a gecko up there! After recovering from an (unrelated) achilles tendon strain, I got the panels installed today. Turns out they're not hard to handle on the roof by myself. Getting them up a ladder to the roof by yourself would normally be another story, but my house has a 2 foot step up from the back retaining wall to the roof, and even has a handy grip beam as you step up. roof next to the ground with a couple of cinderblock steps The last gotcha, which I luckily anticipated, is that panels will slide down off the rails before you can get them bolted down. This is where a second pair of hands would have been most useful. But, I macguyvered a solution, attaching temporary clamps before bringing a panel up, that stopped it sliding down while I was attaching it. clamp temporarily attached to side of panel I also finished the outside wiring today. Including the one hack of this install so far. Since the local hardware store didn't have a suitable conduit to bring the cables off the roof, I cobbled one together from pipe, with foam inserts to prevent chafing. some pipe with 5 wires running through it, attached to the side of the roof While I have 1 kilowatt of power on my roof now, I won't be able to use it until next week. After ordering the upgrade, I realized that my old PWM charge controller would be able to handle less than half the power, and to get even that I would have needed to mount the fuse box near the top of the roof and run down a large and expensive low-voltage high-amperage cable, around OO AWG size. Instead, I'll be upgrading to a MPPT controller, and running a single 150 volt cable to it. Then, since the MPPT controller can only handle 1 kilowatt when it's converting to 24 volts, not 12 volts, I'm gonna have to convert the entire house over from 12V DC to 24V DC, including changing all the light fixtures and rewiring the battery bank...

Vincent Bernat: IPv4 route lookup on Linux

TL;DR: With its implementation of IPv4 routing tables using LPC-tries, Linux offers good lookup performance (50 ns for a full view) and low memory usage (64 MiB for a full view).
During the lifetime of an IPv4 datagram inside the Linux kernel, one important step is the route lookup for the destination address through the fib_lookup() function. From essential information about the datagram (source and destination IP addresses, interfaces, firewall mark, ), this function should quickly provide a decision. Some possible options are: Since 2.6.39, Linux stores routes into a compressed prefix tree (commit 3630b7c050d9). In the past, a route cache was maintained but it has been removed1 in Linux 3.6.

Route lookup in a trie Looking up a route in a routing table is to find the most specific prefix matching the requested destination. Let s assume the following routing table:
$ ip route show scope global table 100
default via 203.0.113.5 dev out2
192.0.2.0/25
        nexthop via 203.0.113.7  dev out3 weight 1
        nexthop via 203.0.113.9  dev out4 weight 1
192.0.2.47 via 203.0.113.3 dev out1
192.0.2.48 via 203.0.113.3 dev out1
192.0.2.49 via 203.0.113.3 dev out1
192.0.2.50 via 203.0.113.3 dev out1
Here are some examples of lookups and the associated results:
Destination IP Next hop
192.0.2.49 203.0.113.3 via out1
192.0.2.50 203.0.113.3 via out1
192.0.2.51 203.0.113.7 via out3 or 203.0.113.9 via out4 (ECMP)
192.0.2.200 203.0.113.5 via out2
A common structure for route lookup is the trie, a tree structure where each node has its parent as prefix.

Lookup with a simple trie The following trie encodes the previous routing table: Simple routing trie For each node, the prefix is known by its path from the root node and the prefix length is the current depth. A lookup in such a trie is quite simple: at each step, fetch the nth bit of the IP address, where n is the current depth. If it is 0, continue with the first child. Otherwise, continue with the second. If a child is missing, backtrack until a routing entry is found. For example, when looking for 192.0.2.50, we will find the result in the corresponding leaf (at depth 32). However for 192.0.2.51, we will reach 192.0.2.50/31 but there is no second child. Therefore, we backtrack until the 192.0.2.0/25 routing entry. Adding and removing routes is quite easy. From a performance point of view, the lookup is done in constant time relative to the number of routes (due to maximum depth being capped to 32). Quagga is an example of routing software still using this simple approach.

Lookup with a path-compressed trie In the previous example, most nodes only have one child. This leads to a lot of unneeded bitwise comparisons and memory is also wasted on many nodes. To overcome this problem, we can use path compression: each node with only one child is removed (except if it also contains a routing entry). Each remaining node gets a new property telling how many input bits should be skipped. Such a trie is also known as a Patricia trie or a radix tree. Here is the path-compressed version of the previous trie: Patricia trie Since some bits have been ignored, on a match, a final check is executed to ensure all bits from the found entry are matching the input IP address. If not, we must act as if the entry wasn t found (and backtrack to find a matching prefix). The following figure shows two IP addresses matching the same leaf: Lookup in a Patricia trie The reduction on the average depth of the tree compensates the necessity to handle those false positives. The insertion and deletion of a routing entry is still easy enough. Many routing systems are using Patricia trees:

Lookup with a level-compressed trie In addition to path compression, level compression2 detects parts of the trie that are densily populated and replace them with a single node and an associated vector of 2k children. This node will handle k input bits instead of just one. For example, here is a level-compressed version our previous trie: Level-compressed trie Such a trie is called LC-trie or LPC-trie and offers higher lookup performances compared to a radix tree. An heuristic is used to decide how many bits a node should handle. On Linux, if the ratio of non-empty children to all children would be above 50% when the node handles an additional bit, the node gets this additional bit. On the other hand, if the current ratio is below 25%, the node loses the responsibility of one bit. Those values are not tunable. Insertion and deletion becomes more complex but lookup times are also improved.

Implementation in Linux The implementation for IPv4 in Linux exists since 2.6.13 (commit 19baf839ff4a) and is enabled by default since 2.6.39 (commit 3630b7c050d9). Here is the representation of our example routing table in memory3: Memory representation of a trie There are several structures involved: The trie can be retrieved through /proc/net/fib_trie:
$ cat /proc/net/fib_trie
Id 100:
  +-- 0.0.0.0/0 2 0 2
      -- 0.0.0.0
        /0 universe UNICAST
     +-- 192.0.2.0/26 2 0 1
         -- 192.0.2.0
           /25 universe UNICAST
         -- 192.0.2.47
           /32 universe UNICAST
        +-- 192.0.2.48/30 2 0 1
            -- 192.0.2.48
              /32 universe UNICAST
            -- 192.0.2.49
              /32 universe UNICAST
            -- 192.0.2.50
              /32 universe UNICAST
[...]
For internal nodes, the numbers after the prefix are:
  1. the number of bits handled by the node,
  2. the number of full children (they only handle one bit),
  3. the number of empty children.
Moreover, if the kernel was compiled with CONFIG_IP_FIB_TRIE_STATS, some interesting statistics are available in /proc/net/fib_triestat4:
$ cat /proc/net/fib_triestat
Basic info: size of leaf: 48 bytes, size of tnode: 40 bytes.
Id 100:
        Aver depth:     2.33
        Max depth:      3
        Leaves:         6
        Prefixes:       6
        Internal nodes: 3
          2: 3
        Pointers: 12
Null ptrs: 4
Total size: 1  kB
[...]
When a routing table is very dense, a node can handle many bits. For example, a densily populated routing table with 1 million entries packed in a /12 can have one internal node handling 20 bits. In this case, route lookup is essentially reduced to a lookup in a vector. The following graph shows the number of internal nodes used relative to the number of routes for different scenarios (routes extracted from an Internet full view, /32 routes spreaded over 4 different subnets with various densities). When routes are densily packed, the number of internal nodes are quite limited. Internal nodes and null pointers

Performance So how performant is a route lookup? The maximum depth stays low (about 6 for a full view), so a lookup should be quite fast. With the help of a small kernel module, we can accurately benchmark5 the fib_lookup() function: Maximum depth and lookup time The lookup time is loosely tied to the maximum depth. When the routing table is densily populated, the maximum depth is low and the lookup times are fast. When forwarding at 10 Gbps, the time budget for a packet would be about 50 ns. Since this is also the time needed for the route lookup alone in some cases, we wouldn t be able to forward at line rate with only one core. Nonetheless, the results are pretty good and they are expected to scale linearly with the number of cores. The measurements are done with a Linux kernel 4.11 from Debian unstable. I have gathered performance metrics accross kernel versions in Performance progression of IPv4 route lookup on Linux . Another interesting figure is the time it takes to insert all those routes into the kernel. Linux is also quite efficient in this area since you can insert 2 million routes in less than 10 seconds: Insertion time

Memory usage The memory usage is available directly in /proc/net/fib_triestat. The statistic provided doesn t account for the fib_info structures, but you should only have a handful of them (one for each possible next-hop). As you can see on the graph below, the memory use is linear with the number of routes inserted, whatever the shape of the routes is. Memory usage The results are quite good. With only 256 MiB, about 2 million routes can be stored!

Routing rules Unless configured without CONFIG_IP_MULTIPLE_TABLES, Linux supports several routing tables and has a system of configurable rules to select the table to use. These rules can be configured with ip rule. By default, there are three of them:
$ ip rule show
0:      from all lookup local
32766:  from all lookup main
32767:  from all lookup default
Linux will first lookup for a match in the local table. If it doesn t find one, it will lookup in the main table and at last resort, the default table.

Builtin tables The local table contains routes for local delivery:
$ ip route show table local
broadcast 127.0.0.0 dev lo proto kernel scope link src 127.0.0.1
local 127.0.0.0/8 dev lo proto kernel scope host src 127.0.0.1
local 127.0.0.1 dev lo proto kernel scope host src 127.0.0.1
broadcast 127.255.255.255 dev lo proto kernel scope link src 127.0.0.1
broadcast 192.168.117.0 dev eno1 proto kernel scope link src 192.168.117.55
local 192.168.117.55 dev eno1 proto kernel scope host src 192.168.117.55
broadcast 192.168.117.63 dev eno1 proto kernel scope link src 192.168.117.55
This table is populated automatically by the kernel when addresses are configured. Let s look at the three last lines. When the IP address 192.168.117.55 was configured on the eno1 interface, the kernel automatically added the appropriate routes:
  • a route for 192.168.117.55 for local unicast delivery to the IP address,
  • a route for 192.168.117.255 for broadcast delivery to the broadcast address,
  • a route for 192.168.117.0 for broadcast delivery to the network address.
When 127.0.0.1 was configured on the loopback interface, the same kind of routes were added to the local table. However, a loopback address receives a special treatment and the kernel also adds the whole subnet to the local table. As a result, you can ping any IP in 127.0.0.0/8:
$ ping -c1 127.42.42.42
PING 127.42.42.42 (127.42.42.42) 56(84) bytes of data.
64 bytes from 127.42.42.42: icmp_seq=1 ttl=64 time=0.039 ms
--- 127.42.42.42 ping statistics ---
1 packets transmitted, 1 received, 0% packet loss, time 0ms
rtt min/avg/max/mdev = 0.039/0.039/0.039/0.000 ms
The main table usually contains all the other routes:
$ ip route show table main
default via 192.168.117.1 dev eno1 proto static metric 100
192.168.117.0/26 dev eno1 proto kernel scope link src 192.168.117.55 metric 100
The default route has been configured by some DHCP daemon. The connected route (scope link) has been automatically added by the kernel (proto kernel) when configuring an IP address on the eno1 interface. The default table is empty and has little use. It has been kept when the current incarnation of advanced routing has been introduced in Linux 2.1.68 after a first tentative using classes in Linux 2.1.156.

Performance Since Linux 4.1 (commit 0ddcf43d5d4a), when the set of rules is left unmodified, the main and local tables are merged and the lookup is done with this single table (and the default table if not empty). Moreover, since Linux 3.0 (commit f4530fa574df), without specific rules, there is no performance hit when enabling the support for multiple routing tables. However, as soon as you add new rules, some CPU cycles will be spent for each datagram to evaluate them. Here is a couple of graphs demonstrating the impact of routing rules on lookup times: Routing rules impact on performance For some reason, the relation is linear when the number of rules is between 1 and 100 but the slope increases noticeably past this threshold. The second graph highlights the negative impact of the first rule (about 30 ns). A common use of rules is to create virtual routers: interfaces are segregated into domains and when a datagram enters through an interface from domain A, it should use routing table A:
# ip rule add iif vlan457 table 10
# ip rule add iif vlan457 blackhole
# ip rule add iif vlan458 table 20
# ip rule add iif vlan458 blackhole
The blackhole rules may be removed if you are sure there is a default route in each routing table. For example, we add a blackhole default with a high metric to not override a regular default route:
# ip route add blackhole default metric 9999 table 10
# ip route add blackhole default metric 9999 table 20
# ip rule add iif vlan457 table 10
# ip rule add iif vlan458 table 20
To reduce the impact on performance when many interface-specific rules are used, interfaces can be attached to VRF instances and a single rule can be used to select the appropriate table:
# ip link add vrf-A type vrf table 10
# ip link set dev vrf-A up
# ip link add vrf-B type vrf table 20
# ip link set dev vrf-B up
# ip link set dev vlan457 master vrf-A
# ip link set dev vlan458 master vrf-B
# ip rule show
0:      from all lookup local
1000:   from all lookup [l3mdev-table]
32766:  from all lookup main
32767:  from all lookup default
The special l3mdev-table rule was automatically added when configuring the first VRF interface. This rule will select the routing table associated to the VRF owning the input (or output) interface. VRF was introduced in Linux 4.3 (commit 193125dbd8eb), the performance was greatly enhanced in Linux 4.8 (commit 7889681f4a6c) and the special routing rule was also introduced in Linux 4.8 (commit 96c63fa7393d, commit 1aa6c4f6b8cd). You can find more details about it in the kernel documentation.

Conclusion The takeaways from this article are:
  • route lookup times hardly increase with the number of routes,
  • densily packed /32 routes lead to amazingly fast route lookups,
  • memory use is low (128 MiB par million routes),
  • no optimization is done on routing rules.

  1. The routing cache was subject to reasonably easy to launch denial of service attacks. It was also believed to not be efficient for high volume sites like Google but I have first-hand experience it was not the case for moderately high volume sites.
  2. IP-address lookup using LC-tries , IEEE Journal on Selected Areas in Communications, 17(6):1083-1092, June 1999.
  3. For internal nodes, the key_vector structure is embedded into a tnode structure. This structure contains information rarely used during lookup, notably the reference to the parent that is usually not needed for backtracking as Linux keeps the nearest candidate in a variable.
  4. One leaf can contain several routes (struct fib_alias is a list). The number of prefixes can therefore be greater than the number of leaves. The system also keeps statistics about the distribution of the internal nodes relative to the number of bits they handle. In our example, all the three internal nodes are handling 2 bits.
  5. The measurements are done in a virtual machine with one vCPU. The host is an Intel Core i5-4670K running at 3.7 GHz during the experiment (CPU governor was set to performance). The benchmark is single-threaded. It runs a warm-up phase, then executes about 100,000 timed iterations and keeps the median. Timings of individual runs are computed from the TSC.
  6. Fun fact: the documentation of this first tentative of more flexible routing is still available in today s kernel tree and explains the usage of the default class .

20 June 2017

Norbert Preining: TeX Live 2017 hits Debian/unstable

Yesterday I uploaded the first packages of TeX Live 2017 to Debian/unstable, meaning that the new release cycle has started. Debian/stretch was released over the weekend, and this opened up unstable for new developments. The upload comprised the following packages: asymptote, cm-super, context, context-modules, texlive-base, texlive-bin, texlive-extra, texlive-extra, texlive-lang, texworks, xindy.
I mentioned already in a previous post the following changes: The last two changes are described together with other news (easy TEXMF tree management) in the TeX Live release post. These changes more or less sum up the new infra structure developments in TeX Live 2017. Since the last release to unstable (which happened in 2017-01-23) about half a year of package updates have accumulated, below is an approximate list of updates (not split into new/updated, though). Enjoy the brave new world of TeX Live 2017, and please report bugs to the BTS! Updated/new packages:
academicons, achemso, acmart, acro, actuarialangle, actuarialsymbol, adobemapping, alkalami, amiri, animate, aomart, apa6, apxproof, arabluatex, archaeologie, arsclassica, autoaligne, autobreak, autosp, axodraw2, babel, babel-azerbaijani, babel-english, babel-french, babel-indonesian, babel-japanese, babel-malay, babel-ukrainian, bangorexam, baskervaldx, baskervillef, bchart, beamer, beamerswitch, bgteubner, biblatex-abnt, biblatex-anonymous, biblatex-archaeology, biblatex-arthistory-bonn, biblatex-bookinother, biblatex-caspervector, biblatex-cheatsheet, biblatex-chem, biblatex-chicago, biblatex-claves, biblatex-enc, biblatex-fiwi, biblatex-gb7714-2015, biblatex-gost, biblatex-ieee, biblatex-iso690, biblatex-manuscripts-philology, biblatex-morenames, biblatex-nature, biblatex-opcit-booktitle, biblatex-oxref, biblatex-philosophy, biblatex-publist, biblatex-shortfields, biblatex-subseries, bibtexperllibs, bidi, biochemistry-colors, bookcover, boondox, bredzenie, breqn, bxbase, bxcalc, bxdvidriver, bxjalipsum, bxjaprnind, bxjscls, bxnewfont, bxorigcapt, bxpapersize, bxpdfver, cabin, callouts, chemfig, chemformula, chemmacros, chemschemex, childdoc, circuitikz, cje, cjhebrew, cjk-gs-integrate, cmpj, cochineal, combofont, context, conv-xkv, correctmathalign, covington, cquthesis, crimson, crossrefware, csbulletin, csplain, csquotes, css-colors, cstldoc, ctex, currency, cweb, datetime2-french, datetime2-german, datetime2-romanian, datetime2-ukrainian, dehyph-exptl, disser, docsurvey, dox, draftfigure, drawmatrix, dtk, dviinfox, easyformat, ebproof, elements, endheads, enotez, eqnalign, erewhon, eulerpx, expex, exsheets, factura, facture, fancyhdr, fbb, fei, fetamont, fibeamer, fithesis, fixme, fmtcount, fnspe, fontmfizz, fontools, fonts-churchslavonic, fontspec, footnotehyper, forest, gandhi, genealogytree, glossaries, glossaries-extra, gofonts, gotoh, graphics, graphics-def, graphics-pln, grayhints, gregoriotex, gtrlib-largetrees, gzt, halloweenmath, handout, hang, heuristica, hlist, hobby, hvfloat, hyperref, hyperxmp, ifptex, ijsra, japanese-otf-uptex, jlreq, jmlr, jsclasses, jslectureplanner, karnaugh-map, keyfloat, knowledge, komacv, koma-script, kotex-oblivoir, l3, l3build, ladder, langsci, latex, latex2e, latex2man, latex3, latexbug, latexindent, latexmk, latex-mr, leaflet, leipzig, libertine, libertinegc, libertinus, libertinust1math, lion-msc, lni, longdivision, lshort-chinese, ltb2bib, lualatex-math, lualibs, luamesh, luamplib, luaotfload, luapackageloader, luatexja, luatexko, lwarp, make4ht, marginnote, markdown, mathalfa, mathpunctspace, mathtools, mcexam, mcf2graph, media9, minidocument, modular, montserrat, morewrites, mpostinl, mptrees, mucproc, musixtex, mwcls, mweights, nameauth, newpx, newtx, newtxtt, nfssext-cfr, nlctdoc, novel, numspell, nwejm, oberdiek, ocgx2, oplotsymbl, optidef, oscola, overlays, pagecolor, pdflatexpicscale, pdfpages, pdfx, perfectcut, pgfplots, phonenumbers, phonrule, pkuthss, platex, platex-tools, polski, preview, program, proofread, prooftrees, pst-3dplot, pst-barcode, pst-eucl, pst-func, pst-ode, pst-pdf, pst-plot, pstricks, pstricks-add, pst-solides3d, pst-spinner, pst-tools, pst-tree, pst-vehicle, ptex2pdf, ptex-base, ptex-fontmaps, pxbase, pxchfon, pxrubrica, pythonhighlight, quran, ran_toks, reledmac, repere, resphilosophica, revquantum, rputover, rubik, rutitlepage, sansmathfonts, scratch, seealso, sesstime, siunitx, skdoc, songs, spectralsequences, stackengine, stage, sttools, studenthandouts, svg, tcolorbox, tex4ebook, tex4ht, texosquery, texproposal, thaienum, thalie, thesis-ekf, thuthesis, tikz-kalender, tikzmark, tikz-optics, tikz-palattice, tikzpeople, tikzsymbols, titlepic, tl17, tqft, tracklang, tudscr, tugboat-plain, turabian-formatting, txuprcal, typoaid, udesoftec, uhhassignment, ukrainian, ulthese, unamthesis, unfonts-core, unfonts-extra, unicode-math, uplatex, upmethodology, uptex-base, urcls, variablelm, varsfromjobname, visualtikz, xassoccnt, xcharter, xcntperchap, xecjk, xepersian, xetexko, xevlna, xgreek, xsavebox, xsim, ycbook.

19 June 2017

Jeremy Bicha: GNOME Tweak Tool 3.25.3

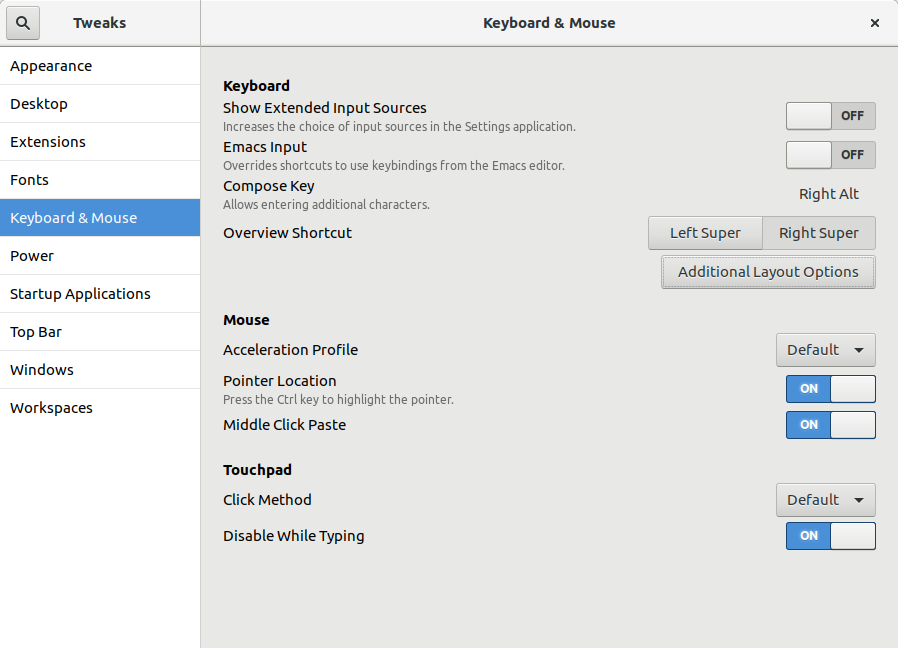
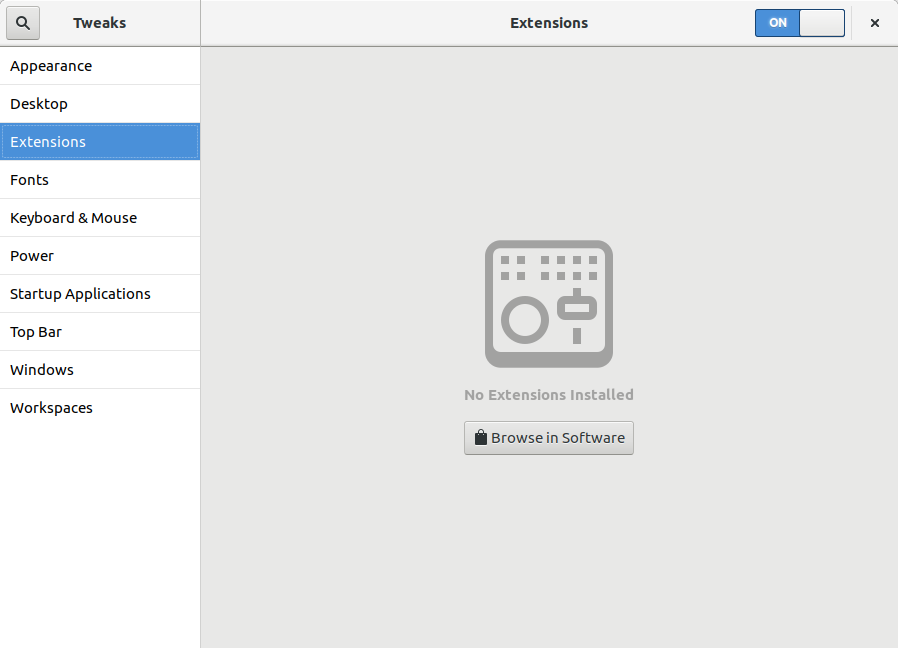
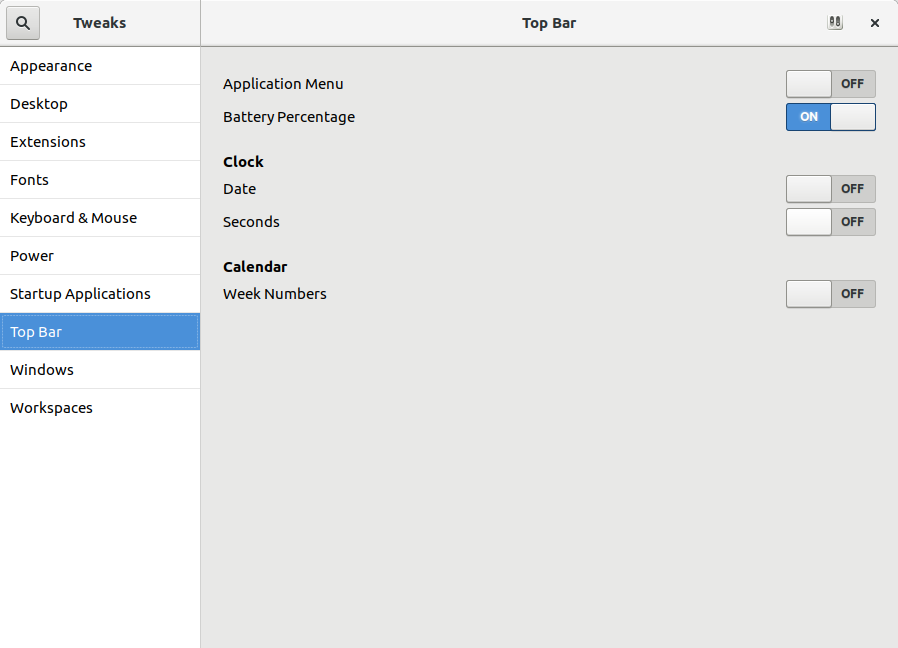
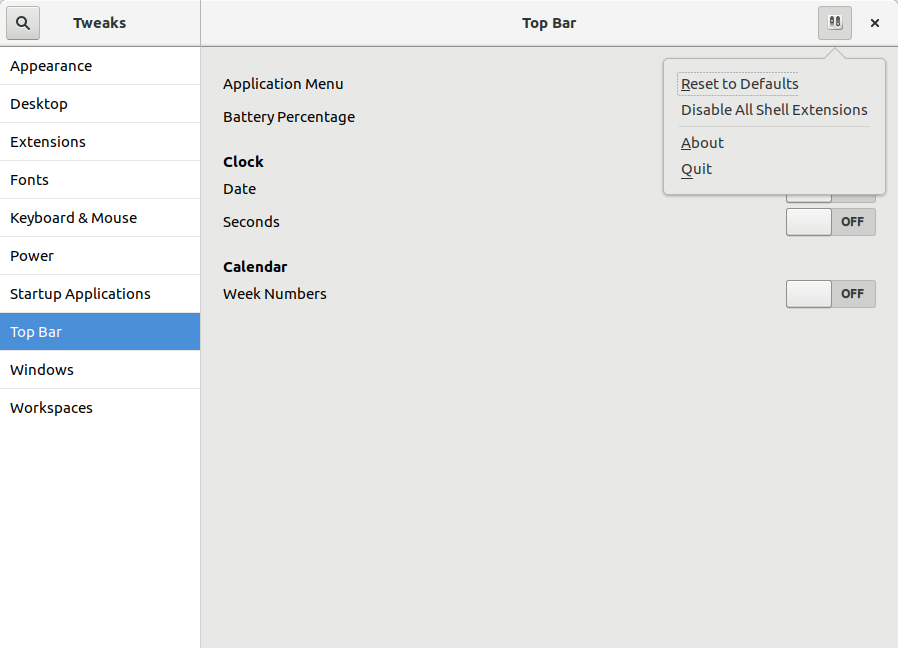
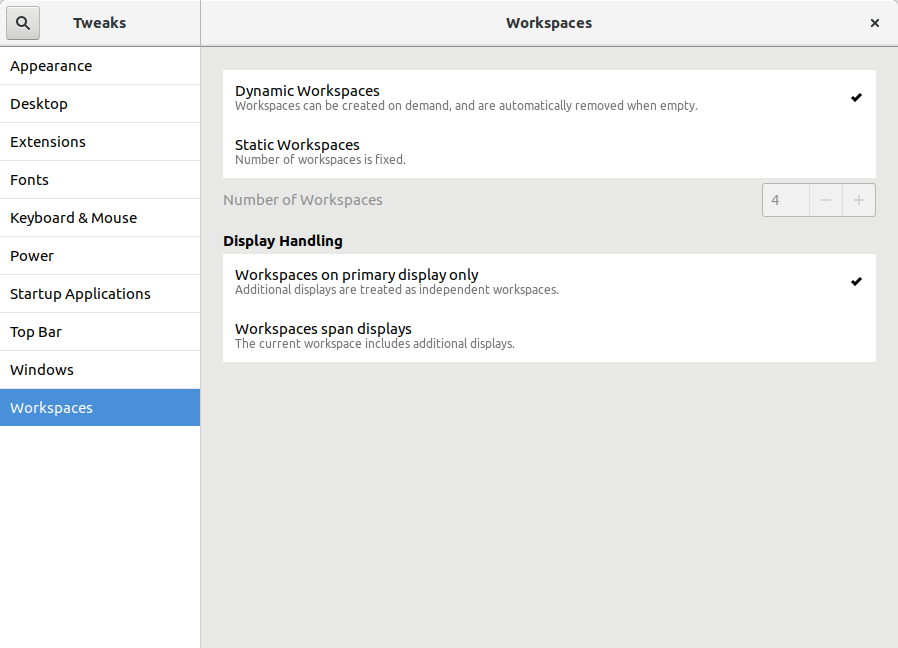
Today I released the second development snapshot (3.25.3) of what will be GNOME Tweak Tool 3.26. I consider the initial User Interface (UI) rework proposed by the GNOME Design Team to be complete now. Every page in Tweak Tool has been updated, either in this snapshot or the previous development snapshot. The hard part still remains: making the UI look as good as the mockups. Tweak Tool s backend makes this a bit more complicated than usual for an app like this. Here are a few visual highlights of this release. The Typing page has been moved into an Additional Layout Options dialog in the Keyboard & Mouse page. Also, the Compose Key option has been given its own dialog box. Florian M llner added content to the Extensions page that is shown if you don t have any GNOME Shell extensions installed yet. A hidden feature that GNOME has had for a long time is the ability to move the Application Menu from the GNOME top bar to a button in the app s title bar. This is easy to enable in Tweak Tool by turning off the Application Menu switch in the Top Bar page. This release improves how well that works, especially for Ubuntu users where the required hidden appmenu window button was probably not pre-configured. Some of the ComboBoxes have been replaced by ListBoxes. One example is on the Workspaces page where the new design allows for more information about the different options. The ListBoxes are also a lot easier to select than the smaller ComboBoxes were. For details of these and other changes, see the commit log or the NEWS file. GNOME Tweak Tool 3.26 will be released alongside GNOME 3.26 in mid-September.

Shirish Agarwal: Seizures, Vigo and bi-pedal motion

Dear all, an update is in order. While talking to physiotherapist couple of days before, came to know the correct term to what was I experiencing. I had experienced convulsive seizure , spasms being a part of it. Reading the wikipedia entry and the associated links/entries it seems I am and was very very lucky. The hospital or any hospital is a very bad bad place. I have seen all horror movies which people say are disturbing but have never been disturbed as much as I was in hospital. I couldn t help but hear people s screams and saw so many cases which turned critical. At times it was not easy to remain positive but dunno from where there was a will to live which pushed me and is still pushing me. One of the things that was painful for a long time were the almost constant stream of injections that were injected in me. It was almost an afterthought that the nurse put a Vigo in me. Similar to the Vigo injected in me. While the above medical device is similar, mine had a cross, the needle was much shorter and is injected into the vein. After that all injections are injected into that including common liquid which is salt,water and something commonly given to patients to stabilize first. I am not remembering the name atm. I also had a urine bag which was attached to my penis in a non-invasive manner. Both my grandfather and grandma used to cry when things went wrong while I didn t feel any pain but when the urine bag was disattached and attached again, so seems things have improved there. I was also very conscious of getting bed sores as both my grandpa and grandma had them when in hospital. As I had no strength I had to beg. plead do everything to make sure that every few hours I was turned from one side to other. I also had an air bag which is supposed to alleviate or relief this condition. Constant physiotherapy every day for a while slowly increased my strength and slowly both the vigo and feeding tube put inside my throat was removed. I have no remembrance as to when they had put the feeding tube as it was all rubber and felt bad when it came out. Further physiotherapy helped me crawl till the top of the bed, the bed was around 6 feet in length and and more than enough so I could turn both sides without falling over. Few days later I found I could also sit up using my legs as a lever and that gave confidence to the doctors to remove the air bed so I could crawl more easily. Couple of more days later I stood on my feet for the first time and it was like I had lead legs. Each step was painful but the sense and feeling of independence won over whatever pain was there. I had to endure wet wipes from nurses and ward boys in place of a shower everyday and while they were respectful always it felt humiliating. The first time I had a bath after 2 weeks or something, every part of my body cried and I felt like a weakling. I had thought I wouldn t be able to do justice to the physiotherapy session which was soon after but after the session was back to feeling normal. For a while I was doing the penguin waddle which while painful was also had humor in it. I did think of shooting the penguin waddle but decided against it as I was half-naked most of the time ( the hospital clothes never fit me properly) Cut to today and I was able to climb up and down the stairs on my own and circled my own block, slowly but was able to do it on my own by myself. While I always had a sense of wonderment for bi-pedal motion as well as all other means of transport, found much more respect of walking. I live near a fast food eating joint so I see lot of youngsters posing in different ways with their legs to show interest to their mates. And this I know happens both on the conscious and sub-conscious levels. To be able to see and discern that also put a sense of wonder in nature s creations. All in all, I m probabl6y around 40% independent and still 60% interdependent. I know I have to be patient with myself and those around me and explain to others what I m going through. For e.g. I still tend to spill things and still can t touch-type much. So, the road is long, I can only pray and hope best wishes for anybody who is my condition and do pray that nobody goes through what I went through, especiallly not children. I am also hoping that things like DxtER and range of non-invasive treatments make their way into India and the developing world at large. Anybody who is overweight and is either disgusted or doesn t like the gym route, would recommend doing sessions with a physiotherapist that you can trust. You have to trust that her judgement will push you a bit more and not more that the gains you make are toppled over. I still get dizziness spells while doing therapy but will to break it as I know dizziness doesn t help me. I hope my writings give strength and understanding to either somebody who is going through it, or relatives or/and caregivers so they know the mental status of the person who s going through it. Till later and sorry it became so long. Update I forgot to share this inspirational story from my city which I shared with a friend days ago. Add to that, she is from my city. What it doesn t share is that Triund is a magical place. I had visited once with a friend who had elf ears (he had put on elf ears) and it is kind of place which alchemist talks about, a place where imagination does turn wild and there is magic in the air.
Filed under: Miscellenous Tagged: #air bag, #bed sores, #convulsive epileptic seizure, #crawling, #horror, #humiliation, #nakedness, #penguin waddle, #physiotherapy, #planet-debian, #spilling things, #urine bag, #Vigo medical device

Vasudev Kamath: Update: - Shell pipelines with subprocess crate and use of Exec::shell function

In my previous post I used Exec::shell function from subprocess crate and passed it string generated by interpolating --author argument. This string was then run by the shell via Exec::shell. After publishing post I got ping on IRC by Jonas Smedegaard and Paul Wise that I should replace Exec::shell, as it might be prone to errors or vulnerabilities of shell injection attack. Indeed they were right, in hurry I did not completely read the function documentation which clearly mentions this fact.
When invoking this function, be careful not to interpolate arguments into the string run by the shell, such as Exec::shell(format!("sort ", filename)). Such code is prone to errors and, if filename comes from an untrusted source, to shell injection attacks. Instead, use Exec::cmd("sort").arg(filename).
Though I'm not directly taking input from untrusted source, its still possible that the string I got back from git log command might contain some oddly formatted string with characters of different encoding which could possibly break the Exec::shell , as I'm not sanitizing the shell command. When we use Exec::cmd and pass argument using .args chaining, the library takes care of creating safe command line. So I went in and modified the function to use Exec::cmd instead of Exec::shell. Below is updated function.
fn copyright_fromgit(repo: &str) -> Result<Vec<String>>  
    let tempdir = TempDir::new_in(".", "debcargo")?;
    Exec::cmd("git")
     .args(&["clone", "--bare", repo, tempdir.path().to_str().unwrap()])
     .stdout(subprocess::NullFile)
     .stderr(subprocess::NullFile)
     .popen()?;
    let author_process =  
        Exec::shell(OsStr::new("git log --format=\"%an <%ae>\"")).cwd(tempdir.path())  
        Exec::shell(OsStr::new("sort -u"))
     .capture()?;
    let authors = author_process.stdout_str().trim().to_string();
    let authors: Vec<&str> = authors.split('\n').collect();
    let mut notices: Vec<String> = Vec::new();
    for author in &authors  
        let author_string = format!("--author= ", author);
        let first =  
            Exec::cmd("/usr/bin/git")
             .args(&["log", "--format=%ad",
                    "--date=format:%Y",
                    "--reverse",
                    &author_string])
             .cwd(tempdir.path())   Exec::shell(OsStr::new("head -n1"))
         .capture()?;
        let latest =  
            Exec::cmd("/usr/bin/git")
             .args(&["log", "--format=%ad", "--date=format:%Y", &author_string])
             .cwd(tempdir.path())   Exec::shell("head -n1")
         .capture()?;
        let start = i32::from_str(first.stdout_str().trim())?;
        let end = i32::from_str(latest.stdout_str().trim())?;
        let cnotice = match start.cmp(&end)  
            Ordering::Equal => format!(" ,  ", start, author),
            _ => format!(" - ,  ", start, end, author),
         ;
        notices.push(cnotice);
     
    Ok(notices)
 
I still use Exec::shell for generating author list, this is not problematic as I'm not interpolating arguments to create command string.

18 June 2017

Vasudev Kamath: Rust - Shell like Process pipelines using subprocess crate

I had to extract copyright information from the git repository of the crate upstream. The need aroused as part of updating debcargo, tool to create Debian package source from the Rust crate. General idea behind taking copyright information from git is to extract starting and latest contribution year for every author/committer. This can be easily achieved using following shell snippet
for author in $(git log --format="%an"   sort -u); do
   author_email=$(git log --format="%an <%ae>" --author="$author"   head -n1)
   first=$(git \
   log --author="$author" --date=format:%Y --format="%ad" --reverse \
               head -n1)
   latest=$(git log --author="$author" --date=format:%Y --format="%ad" \
               head -n1)
   if [ $first -eq $latest ]; then
       echo "$first, $author_email"
   else
       echo "$first-$latest, $author_email"
   fi
done
Now challenge was to execute these command in Rust and get the required answer. So first step was I looked at std::process, default standard library support for executing shell commands. My idea was to execute first command to extract authors into a Rust vectors or array and then have 2 remaining command to extract years in a loop. (Yes I do not need additional author_email command in Rust as I can easily get both in the first command which is used in for loop of shell snippet and use it inside another loop). So I setup to 3 commands outside the loop with input and output redirected, following is snippet should give you some idea of what I tried to do.
let authors_command = Command::new("/usr/bin/git")
             .arg("log")
             .arg("--format=\"%an <%ae>\"")
             .spawn()?;
let output = authors_command.wait()?;
let authors: Vec<String> = String::from_utf8(output.stdout).split('\n').collect();
let head_n1 = Command::new("/usr/bin/head")
             .arg("-n1")
             .stdin(Stdio::piped())
             .stdout(Stdio::piped())
             .spwn()?;
for author in &authors  
             ...
 
And inside the loop I would create additional 2 git commands read their output via pipe and feed it to head command. This is where I learned that it is not straight forward as it looks :-). std::process::Command type does not implement Copy nor Clone traits which means one use of it I will give up the ownership!. And here I started fighting with borrow checker. I need to duplicate declarations to make sure I've required commands available all the time. Additionally I needed to handle error output at every point which created too many nested statements there by complicating the program and reducing its readability When all started getting out of control I gave a second thought and wondered if it would be good to write down this in shell script ship it along with debcargo and use the script Rust program. This would satisfy my need but I would need to ship additional script along with debcargo which I was not really happy with. Then a search on crates.io revealed subprocess, a crate designed to be similar with subprocess module from Python!. Though crate is not highly downloaded it still looked promising, especially the trait implements a trait called BitOr which allows use of operator to chain the commands. Additionally it allows executing full shell commands without need of additional chaining of argument which was done above snippet. End result a much simplified easy to read and correct function which does what was needed. Below is the function I wrote to extract copyright information from git repo.
fn copyright_fromgit(repo: &str) -> Result<Vec<String>>  
    let tempdir = TempDir::new_in(".", "debcargo")?;
    Exec::shell(OsStr::new(format!("git clone --bare    ",
                                repo,
                                tempdir.path().to_str().unwrap())
                              .as_str())).stdout(subprocess::NullFile)
                              .stderr(subprocess::NullFile)
                              .popen()?;
    let author_process =  
         Exec::shell(OsStr::new("git log --format=\"%an <%ae>\"")).cwd(tempdir.path())  
         Exec::shell(OsStr::new("sort -u"))
      .capture()?;
    let authors = author_process.stdout_str().trim().to_string();
    let authors: Vec<&str> = authors.split('\n').collect();
    let mut notices: Vec<String> = Vec::new();
    for author in &authors  
        let reverse_command = format!("git log --author=\" \" --format=%ad --date=format:%Y \
                                    --reverse",
                                   author);
        let command = format!("git log --author=\" \" --format=%ad --date=format:%Y",
                           author);
        let first =  
             Exec::shell(OsStr::new(&reverse_command)).cwd(tempdir.path())  
             Exec::shell(OsStr::new("head -n1"))
          .capture()?;
         let latest =  
             Exec::shell(OsStr::new(&command)).cwd(tempdir.path())   Exec::shell("head -n1")
          .capture()?;
        let start = i32::from_str(first.stdout_str().trim())?;
        let end = i32::from_str(latest.stdout_str().trim())?;
        let cnotice = match start.cmp(&end)  
            Ordering::Equal => format!(" ,  ", start, author),
            _ => format!(" - ,  ", start, end, author),
         ;
        notices.push(cnotice);
     
    Ok(notices)
 
Of course it is not as short as the shell or probably Python code, but that is fine as Rust is system level programming language (which is intended to replace C/C++) and doing complex Shell code (complex due to need of shell pipelines) in approximately 50 lines of code in safe and secure way is very much acceptable. Besides code is as much readable as a plain shell snippet thanks to the operator implemented by subprocess crate.

16 June 2017

Elena 'valhalla' Grandi: Travel piecepack v0.1

Travel piecepack v0.1

Immagine/fotosocial.gl-como.it/photos/valha

A www.piecepack.org/ set of generic board game pieces is nice to have around in case of a sudden spontaneous need of gaming, but carrying my full set www.trueelena.org/fantastic/fe takes some room, and is not going to fit in my daily bag.

I've been thinking for a while that an half-size set could be useful, and between yesterday and today I've actually managed to do the first version.

It's (2d) printed on both sides of a single sheet of heavy paper, laminated and then cut, comes with both the basic suites and the playing card expansion and fits in a mint tin divided by origami boxes.

It's just version 0.1 because there are a few issues: first of all I'm not happy with the manual way I used to draw the page: ideally it would have been programmatically generated from the same svg files as the 3d piecepack (with the ability to generate other expansions), but apparently reading paths from an svg and writing it in another svg is not supported in an easy way by the libraries I could find, and looking for it was starting to take much more time than just doing it by hand.

I also still have to assemble the dice; in the picture above I'm just using the ones from the 3d-printed set, but they are a bit too big and only four of them fit in the mint tin. I already have the faces printed, so this is going to be fixed in the next few days.

Source files are available in the same git repository as the 3d-printable piecepack git.trueelena.org/cgit.cgi/3d/, with the big limitation mentioned above; updates will also be pushed there, just don't hold your breath for it :)

14 June 2017

Nicolas Dandrimont: DebConf 17 bursaries: update your status now!

TL;DR: if you applied for a DebConf 17 travel bursary, and you haven t accepted it yet, login to the DebConf website and update your status before June 20th or your bursary grant will be gone. *blows dust off the blog* As you might be aware, DebConf 17 is coming soon and it s gonna be the biggest DebConf in Montr al ever. Of course, what makes DebConf great is the people who come together to work on Debian, share their achievements, and help draft our cunning plans to take over the world. Also cheese. Lots and lots of cheese. To that end, the DebConf team had initially budgeted US$40,000 for travel grants ($30,000 for contributors, $10,000 for diversity and inclusion grants), allowing the bursaries team to bring people from all around the world who couldn t have made it to the conference. Our team of volunteers rated the 188 applications, we ve made a ranking (technically, two rankings : one on contribution grounds and one on D&I grounds), and we finally sent out a first round of grants last week. After the first round, the team made a new budget assessment, and thanks to the support of our outstanding sponsors, an extra $15,000 has been allocated for travel stipends during this week s team meeting, with the blessing of the DPL. We ve therefore been able to send a second round of grants today. Now, if you got a grant, you have two things to do : you need to accept your grant, and you need to update your requested amount. Both of those steps allow us to use our budget more wisely: having grants expire frees money up to get more people to the conference earlier. Having updated amounts gives us a better view of our overall budget. (You can only lower your requested amount, as we can t inflate our budget) Our system has sent mails to everyone, but it s easy enough to let that email slip (or to not receive it for some reason). It takes 30 seconds to look at the status of your request on the DebConf 17 website, and even less to do the few clicks needed for you to accept the grant. Please do so now! OK, it might take a few minutes if your SSO certificate has expired and you have to look up the docs to renew it. The deadline for the first round of travel grants (which went out last week) is June 20th. The deadline for the second round (which went out today) is June 24th. If somehow you can t login to the website before the deadline, the bursaries team has an email address you can use. We want to send out a third round of grants on June 25th, using the money people freed up: our current acceptance ratio is around 40%, and a lot of very strong applications have been deferred. We don t want them to wait up until July to get a definitive answer, so thanks for helping us! bient t Montr al !

Dirk Eddelbuettel: #7: C++14, R and Travis -- A useful hack

Welcome to the seventh post in the rarely relevant R ramblings series, or R4 for short. We took a short break as several conferences and other events interfered during the month of May, keeping us busy and away from this series. But we are back now with a short and useful hack I came up with this weekend. The topic is C++14, i.e. the newest formally approved language standard for C++, and its support in R and on Travis CI. With release R 3.4.0 of a few weeks ago, R now formally supports C++14. Which is great. But there be devils. A little known fact is that R hangs on to its configuration settings from its own compile time. That matters in cases such as the one we are looking at here: Travis CI. Travis is a tremendously useful and widely-deployed service, most commonly connected to GitHub driving "continuous integration" (the 'CI') testing after each commit. But Travis CI, for as useful as it is, is also maddingly conservative still forcing everybody to live and die by [Ubuntu 14.04]http://releases.ubuntu.com/14.04/). So while we all benefit from the fine work by Michael who faithfully provides Ubuntu binaries for distribution via CRAN (based on the Debian builds provided by yours truly), we are stuck with Ubuntu 14.04. Which means that while Michael can provide us with current R 3.4.0 it will be built on ancient Ubuntu 14.04. Why does this matter, you ask? Well, if you just try to turn the very C++14 support added to R 3.4.0 on in the binary running on Travis, you get this error:
** libs
Error in .shlib_internal(args) : 
  C++14 standard requested but CXX14 is not defined
And you get it whether or not you define CXX14 in the session. So R (in version 3.4.0) may want to use C++14 (because a package we submitted requests it), but having been built on the dreaded Ubuntu 14.04, it just can't oblige. Even when we supply a newer compiler. Because R hangs on to its compile-time settings rather than current environment variables. And that means no C++14 as its compile-time compiler was too ancient. Trust me, I tried: adding not only g++-6 (from a suitable repo) but also adding C++14 as the value for CXX_STD. Alas, no mas. The trick to overcome this is twofold, and fairly straightforward. First off, we just rely on the fact that g++ version 6 defaults to C++14. So by supplying g++-6, we are in the green. We have C++14 by default without requiring extra options. Sweet. The remainder is to tell R to not try to enable C++14 even though we are using it. How? By removing CXX_STD=C++14 on the fly and just for Travis. And this can be done easily with a small script configure which conditions on being on Travis by checking two environment variables:
#!/bin/bash
## Travis can let us run R 3.4.0 (from CRAN and the PPAs) but this R version
## does not know about C++14.  Even though we can select CXX_STD = C++14, R
## will fail as the version we use there was built in too old an environment,
## namely Ubuntu "trusty" 14.04.
##
## So we install g++-6 from another repo and rely on the fact that is
## defaults to C++14.  Sadly, we need R to not fail and hence, just on
## Travis, remove the C++14 instruction
if [[ "$ CI " == "true" ]]; then
    if [[ "$ TRAVIS " == "true" ]]; then 
        echo "** Overriding src/Makevars and removing C++14 on Travis only"
        sed -i 's CXX_STD = CXX14 ' src/Makevars
    fi
fi
I have deployed this now for two sets of builds in two distinct repositories for two "under-development" packages not yet on CRAN, and it just works. In case you turn on C++14 via SystemRequirements: in the file DESCRIPTION, you need to modify it here. So to sum up, there it is: C++14 with R 3.4.0 on Travis. Only takes a quick Travis-only modification.

13 June 2017

Reproducible builds folks: Reproducible Builds: week 111 in Stretch cycle

Here's what happened in the Reproducible Builds effort between Sunday June 4 and Saturday June 10 2017: Past and upcoming events On June 10th, Chris Lamb presented at the Hong Kong Open Source Conference 2017 on reproducible builds. Patches and bugs filed Reviews of unreproducible packages 7 package reviews have been added, 10 have been updated and 14 have been removed in this week, adding to our knowledge about identified issues. Weekly QA work During our reproducibility testing, FTBFS bugs have been detected and reported by: Two FTBFS issues of LEDE (exposed in our setup) were found and were fixed: diffoscope development tests.reproducible-builds.org: Alexander 'lynxis' Couzens made some changes for testing LEDE and OpenWrt: Hans-Christoph Steiner, for testing F-Droid: Daniel Shahaf, for testing Debian: Holger 'h01ger' Levsen, for testing Debian: Misc. This week's edition was written by Ximin Luo, Chris Lamb and Holger Levsen & reviewed by a bunch of Reproducible Builds folks on IRC & the mailing lists.

Next.

Previous.