Search Results: "reg"

18 January 2017

Dirk Eddelbuettel: RProtoBuf 0.4.8: Windows support for proto3

Issue ticket #20 demonstrated that we had not yet set up Windows for version 3 of Google Protocol Buffers ("Protobuf") -- while the other platforms support it. So I made the change, and there is release 0.4.8. RProtoBuf provides R bindings for the Google Protocol Buffers ("Protobuf") data encoding and serialization library used and released by Google, and deployed as a language and operating-system agnostic protocol by numerous projects. The NEWS file summarises the release as follows:

Changes in RProtoBuf version 0.4.8 (2017-01-17)
  • Windows builds now use the proto3 library as well (PR #21 fixing #20)

CRANberries also provides a diff to the previous release. The RProtoBuf page has an older package vignette, a 'quick' overview vignette, a unit test summary vignette, and the pre-print for the JSS paper. Questions, comments etc should go to the GitHub issue tracker off the GitHub repo.

This post by Dirk Eddelbuettel originated on his Thinking inside the box blog. Please report excessive re-aggregation in third-party for-profit settings.

17 January 2017

Arturo Borrero Gonz lez: Debian is a puzzle: difficult

Debian is a puzzle Debian is very difficult, a puzzle. This surprising statement was what I got last week when talking with a group of new IT students (and their teachers). I would like to write down here what I was able to obtain from that conversation. From time to time, as part of my job at CICA, we open the doors of our datacenter to IT students from all around Andalusia (our region) who want to learn what we do here and how we do it. All our infraestructure and servers are primarily built using FLOSS software (we have some exceptions, like backbone routers and switches), and the most important servers run Debian. As part of the talk, when I am in such a meeting with a visiting group, I usually ask about which technologies they use and learn in their studies. The other day, they told me they use mostly Ubuntu and a bit of Fedora. When I asked why not Debian, the answer was that it was very difficult to install and manage. I tried to obtain some facts about this but I failed in what seems to be a case of bad fame, a reputation problem which was extended among the teachers and therefore among the students. I didn t detect any branding biasing or the like. I just seems lack of knowledge, and bad Debian reputation. Using my DD powers and responsabilities, I kindly asked for feedback to improve our installer or whatever they may find difficult, but a week later I have received no email so far. Then, what I obtain is nothing new: I myself recently had to use the Ubuntu installer in a laptop, and it didn t seem that different to the Debian one: same steps and choices, like in every other OS installation. Please, spread the word: Debian is not difficult. Certainly not perfect, but I don t think that installing and using Debian is such a puzzle.

15 January 2017

Dirk Eddelbuettel: Rcpp 0.12.9: Next round

Yesterday afternoon, the nineth update in the 0.12.* series of Rcpp made it to the CRAN network for GNU R. Windows binaries have by now been generated; and the package was updated in Debian too. This 0.12.9 release follows the 0.12.0 release from late July, the 0.12.1 release in September, the 0.12.2 release in November, the 0.12.3 release in January, the 0.12.4 release in March, the 0.12.5 release in May, the 0.12.6 release in July, the 0.12.7 release in September, and the 0.12.8 release in November --- making it the thirteenth release at the steady bi-montly release frequency. Rcpp has become the most popular way of enhancing GNU R with C or C++ code. As of today, 906 packages on CRAN depend on Rcpp for making analytical code go faster and further. That is up by sixthythree packages over the two months since the last release -- or about a package a day! Some of the changes in this release are smaller and detail-oriented. We did squash one annoying bug (stemming from the improved exception handling) in Rcpp::stop() that hit a few people. Nathan Russell added a sample() function (similar to the optional one in RcppArmadillo; this required a minor cleanup by for small number of other packages which used both namespaces 'opened'. Date and Datetime objects now have format() methods and << output support. We now have coverage reports via covr as well. Last but not least James "coatless" Balamuta was once more tireless on documentation and API consistency --- see below for more details.

Changes in Rcpp version 0.12.9 (2017-01-14)
  • Changes in Rcpp API:
    • The exception stack message is now correctly demangled on all compiler versions (Jim Hester in #598)
    • Date and Datetime object and vector now have format methods and operator<< support (#599).
    • The size operator in Matrix is explicitly referenced avoiding a g++-6 issues (#607 fixing #605).
    • The underlying date calculation code was updated (#621, #623).
    • Addressed improper diagonal fill for non-symmetric matrices (James Balamuta in #622 addressing #619)
  • Changes in Rcpp Sugar:
    • Added new Sugar function sample() (Nathan Russell in #610 and #616).
    • Added new Sugar function Arg() (James Balamuta in #626 addressing #625).
  • Changes in Rcpp unit tests
    • Added Environment::find unit tests and an Environment::get(Symbol) test (James Balamuta in #595 addressing issue #594).
    • Added diagonal matrix fill tests (James Balamuta in #622 addressing #619)
  • Changes in Rcpp Documentation:
    • Exposed pointers macros were included in the Rcpp Extending vignette (MathurinD; James Balamuta in #592 addressing #418).
    • The file Rcpp.bib move to directory bib which is guaranteed to be present (#631).
  • Changes in Rcpp build system
    • Travis CI now also calls covr for coverage analysis (Jim Hester in PR #591)

Thanks to CRANberries, you can also look at a diff to the previous release. As always, even fuller details are on the Rcpp Changelog page and the Rcpp page which also leads to the downloads page, the browseable doxygen docs and zip files of doxygen output for the standard formats. A local directory has source and documentation too. Questions, comments etc should go to the rcpp-devel mailing list off the R-Forge page.

This post by Dirk Eddelbuettel originated on his Thinking inside the box blog. Please report excessive re-aggregation in third-party for-profit settings.

14 January 2017

Mike Gabriel: UIF bug: Caused by flawed IPv6 DNS resolving in Perl's NetAddr::IP

TL;DR; If you use NetAddr::IP->new6() for resolving DNS names to IPv6 addresses, the addresses returned by NetAddr::IP are not what you might expect. See below for details. Issue #2 in UIF Over the last couple of days, I tried to figure out the cause of a weird issue observed in UIF (Universal Internet Firewall [1], a nice Perl tool for setting up ip(6)tables based Firewalls). Already a long time ago, I stumbled over a weird DNS resolving issue of DNS names to IPv6 addresses in UIF that I reported as issue #2 [2] against upstream UIF back then. I happen to be co-author of UIF. So, I felt very ashamed all the time for not fixing the issue any sooner. As many of us DDs try to get our packages into shape before the next Debian release these days, I find myself doing the same. I started investigating the underlying cause of issue #2 in UIF a couple of days ago. Issue #119858 on CPAN Today, I figured out that the Perl code in UIF is not causing the observed phenomenon. The same behaviour is reproducible with a minimal and pure NetAddr::IP based Perl script (reported as Debian bug #851388 [2]. Thanks to Gregor Herrmann for forwarding Debian bug upstream (#119858 [3]). Here is the example script that shows the flawed behaviour:
#!/usr/bin/perl
use NetAddr::IP;
my $hostname = "google-public-dns-a.google.com";
my $ip6 = NetAddr::IP->new6($hostname);
my $ip4 = NetAddr::IP->new($hostname);
print "$ip6 <- WTF???\n";
print "$ip4\n";
exit(0);
... gives...
[mike@minobo ~]$ ./netaddr-ip_resolv-ipv6.pl
0:0:0:0:0:0:808:808/128 <- WTF???
8.8.8.8/32
In words... So what happens in NetAddr::IP is that with the new6() "constructor" you initialize a new IPv6 address. If the address is a DNS name, NetAddr::IP internally resolves it into an IPv4 address and converts this IPv4 address into some IPv6'ish format. This bogus IPv6 address is not the one matching the given DNS name. Impacted Software in Debian Various Debian packages use NetAddr::IP and may be affected by this flaw, here is an incomplete list (use apt-rdepends -r libnetaddr-ip-perl for the complete list): Any of the above packages could be affected if NetAddr::IP->new6(<dnsname>) is being used. I haven't checked any of the code bases, but possibly the corresponding maintainers may want to do that. References light+love
Mike

Russ Allbery: Review: Enchanters' End Game

Review: Enchanters' End Game, by David Eddings
Series: The Belgariad #5
Publisher: Del Rey
Copyright: December 1984
Printing: February 1990
ISBN: 0-345-33871-5
Format: Mass market
Pages: 372
And, finally, the conclusion towards which everything has been heading, and the events for which Castle of Wizardry was the preparation. (This is therefore obviously not the place to start with this series.) Does it live up to all the foreshadowing and provide a satisfactory conclusion? I'd say mostly. The theology is a bit thin, but Eddings does a solid job of bringing all the plot threads together and giving each of the large cast a moment to shine. Enchanters' End Game (I have always been weirdly annoyed by that clunky apostrophe) starts with more of Garion and Belgarath, and, similar to the end of Castle of Wizardry, this feels like them rolling on the random encounter table. There is a fairly important bit with Nadraks at the start, but the remaining detour to the north is a mostly unrelated bit of world-building. Before this re-read, I didn't remember how extensive the Nadrak parts of this story were; in retrospect, I realize a lot of what I was remembering is in the Mallorean instead. I'll therefore save my commentary on Nadrak gender roles for an eventual Mallorean re-read, since there's quite a lot to dig through and much of it is based on information not available here. After this section, though, the story leaves Garion, Belgarath, and Silk for nearly the entire book, returning to them only for the climax. Most of this book is about Ce'Nedra, the queens and kings of the west, and what they're doing while Garion and his small party are carrying the Ring into Mordor er, you know what I mean. And this long section is surprisingly good. We first get to see the various queens of the west doing extremely well managing the kingdoms while the kings are away (see my previous note about how Eddings does examine his stereotypes), albeit partly by mercilessly exploiting the sexism of their societies. The story then picks up with Ce'Nedra and company, including all of the rest of Garion's band, being their snarky and varied selves. There are some fairly satisfying set pieces, some battle tactics, some magical tactics, and a good bit of snarking and interplay between characters who feel like old friends by this point (mostly because of Eddings's simple, broad-strokes characterization). And Ce'Nedra is surprisingly good here. I would say that she's grown up after the events of the last book, but sadly she reverts to being awful in the aftermath. But for the main section of the book, partly because she's busy with other things, she's a reasonable character who experiences some actual consequences and some real remorse from one bad decision she makes. She's even admirable in how she handles events leading up to the climax of the book. Eddings does a good job showing every character in their best light, putting quite a lot of suspense (and some dramatic rescues) into this final volume, and providing a final battle that's moderately interesting. I'm not sure I entirely bought the theological ramifications of the conclusion (the bits with Polgara do not support thinking about too deeply), but the voice in Garion's head continues to be one of the better characters of the series. And Errand is a delight. After the climax, the aftermath sadly returns to Eddings's weird war between the sexes presentation of all gender relationships in this series, and it left me with a bit of a bad taste in my mouth. (There is absolutely no way that some of these relationships would survive in reality.) Eddings portrays nearly every woman as a manipulative schemer, sometimes for good and sometimes for evil, and there is just so much gender stereotyping throughout this book for both women and men. You can tell he's trying with the queens, but women are still only allowed to be successful at politics and war within a very specific frame. Even Polgara gets a bit of the gender stereotyping, although she remains mostly an exception (and one aspect of the ending is much better than it could have been). Ah well. One does not (or at least probably should not) read this series without being aware that it has some flaws. But it has a strange charm as well, mostly from its irreverence. The dry wise-cracking of these characters rings more true to me than the epic seriousness of a lot of fantasy. This is how people behave under stress, and this is how quirky people who know each other extremely well interact. It also keeps one turning the pages quite effectively. I stayed up for several late nights finishing it, and was never tempted to put it down and stop reading. This is not great literature, but it's still fun. It wouldn't sustain regular re-reading for me, but a re-read after twenty years or so was pretty much exactly the experience I was hoping for: an unchallenging, optimistic story with amusing characters and a guaranteed happy ending. There's a place for that. Followed, in a series sense, by the Mallorean, the first book of which is The Guardians of the West. But this is a strictly optional continuation; the Belgariad comes to a definite end here. Rating: 7 out of 10

Sven Hoexter: moto g falcon reactivation and exodus mod

I started to reactivate my old moto g falcon during the last days of CyanogenMod in December of 2016. First step was a recovery update to TWRP 3.0.2-2 so I was able to flash CM13/14 builds. While CM14 nightly builds did not boot at all the CM13 builds did, but up to the last build wifi connections to the internet did not work. I could actually register with my wifi (Archer C7 running OpenWRT) but all apps claim the internet connection check failed and I'm offline. So bummer, without wifi a smartphone is not much fun. I was pretty sure that wifi worked when I last used that phone about 1.5 years ago with CM11/12, so I started to dive into the forums of xda-developers to look for alternatives. Here I found out about Exodus. I've a bit of trouble trusting stuff from xda-developer forums but what the hell, the phone is empty anyway so nothing to loose and I flashed the latest falcon build. To flash it I had to clean the whole phone, format all partitions via TWRP and then sideloaded the zip image file via adb (adb from the Debian/stretch adb package works like a charm, thank you guys!). Booted and b m wifi works again! Now Exodus is a really striped down mod, to do anything useful with it I had to activate the developer options and allow USB debugging. Afterwards I could install the f-droid and Opera apk via "adb install foo.apk". Lineage OS As I could derive from another thread on xda-developers Lineage OS has the falcon still on the shortlist for 14.x nightly builds. Maybe that will be an alternative again in the future. For now Exodus is a bit behind the curve (based on Android 6.0.1 from September 2016) but at least it's functional.

Jamie McClelland: What's Up with WhatsApp?

Despite my jaded feelings about corporate Internet services in general, I was suprised to learn that WhatsApp's end-to-end encryption was a lie. In short, it is possible to send an encrypted message to a user that is intercepted and effectively de-crypted without the sender's knowledge. However, I was even more surprised to read Open Whisper Systems critique of the original story, claiming that it is not a backdoor because the WhatsApp sender's client is always notified when a message is de-crypted. The Open Whisper Systems post acknowledges that the WhatsApp sender can choose to disable these notifications, but claims that is not such a big deal because the WhatsApp server has no way to know which clients have this feature enabled and which do not, so intercepting a message is risky because it could result in the sender realizing it. However, there is a fairly important piece of information missing, namely: as far as I can tell, the setting to notify users about key changes is disabled by default. So, using the default installation, your end-to-end encrypted message could be intercepted and decrypted without you or the party you are communicating with knowing it. How is this not a back door? And yes, if the interceptor can't tell whether or not the sender has these notifications turned on, the interceptor runs the risk of someone knowing they have intercepted the message. Great. That's better than nothing. Except that there is strong evidence that many powerful governments on this planet routinely risk exposure in their pursuit of compromising our ability to communicate securely. And... not to mention non-governmental (or governmental) adversaries for whom exposure is not a big deal. Furthermore a critical reason for end-to-end encrption is so that your provider does not have the technical capacity to intercept your communications. That's simply not true of WhatsApp. It is true of Signal and OMEMO, which requires the active participation of the sender to compromise the communication. Why in the world would you distribute a client that not only has the ability to surpress such warnings, but has it enabled by default? Some may argue that users regularly dismiss notifications like "fingerprint has changed" and that this problem is the achilles heal of secure communications. I agree. But... there is still a monumental difference between a user absent-mindedly dismissing an important security warning and never seeing the warning in the first place. This flaw in WhatsApp is a critical reminder that secure communications doesn't just depend on a good protocol or technology, but on trust in the people who design and maintain our systems.

13 January 2017

Elena 'valhalla' Grandi: Modern XMPP Server

Modern XMPP Server

I've published a new HOWTO on my website 'http://www.trueelena.org/computers/howto/modern_xmpp_server.html':

http://www.enricozini.org/blog/2017/debian/modern-and-secure-instant-messaging/ already wrote about the Why (and the What, Who and When), so I'll just quote his conclusion and move on to the How.

I now have an XMPP setup which has all the features of the recent fancy chat systems, and on top of that it runs, client and server, on Free Software, which can be audited, it is federated and I can self-host my own server in my own VPS if I want to, with packages supported in Debian.


How

I've decided to install https://prosody.im/, mostly because it was recommended by the RTC QuickStart Guide http://rtcquickstart.org/; I've heard that similar results can be reached with https://www.ejabberd.im/ and other servers.

I'm also targeting https://www.debian.org/ stable (+ backports); as I write this is jessie; if there are significant differences I will update this article when I will upgrade my server to stretch. Right now, this means that I'm using prosody 0.9 (and that's probably also the version that will be available in stretch).

Installation and prerequisites

You will need to enable the https://backports.debian.org/ repository and then install the packages prosody and prosody-modules.

You also need to setup some TLS certificates (I used Let's Encrypt https://letsencrypt.org/); and make them readable by the prosody user; you can see Chapter 12 of the RTC QuickStart Guide http://rtcquickstart.org/guide/multi/xmpp-server-prosody.html for more details.

On your firewall, you'll need to open the following TCP ports:


The latter two are needed to enable some services provided via http(s), including rich media transfers.

With just a handful of users, I didn't bother to configure LDAP or anything else, but just created users manually via:

prosodyctl adduser alice@example.org

In-band registration is disabled by default (and I've left it that way, to prevent my server from being used to send spim https://en.wikipedia.org/wiki/Messaging_spam).

prosody configuration

You can then start configuring prosody by editing /etc/prosody/prosody.cfg.lua and changing a few values from the distribution defaults.

First of all, enforce the use of encryption and certificate checking both for client2server and server2server communications with:


c2s_require_encryption = true
s2s_secure_auth = true


and then, sadly, add to the whitelist any server that you want to talk to and doesn't support the above:


s2s_insecure_domains = "gmail.com"


virtualhosts

For each virtualhost you want to configure, create a file /etc/prosody/conf.avail/chat.example.org.cfg.lua with contents like the following:


VirtualHost "chat.example.org"
enabled = true
ssl =
key = "/etc/ssl/private/example.org-key.pem";
certificate = "/etc/ssl/public/example.org.pem";


For the domains where you also want to enable MUCs, add the follwing lines:


Component "conference.chat.example.org" "muc"
restrict_room_creation = "local"


the "local" configures prosody so that only local users are allowed to create new rooms (but then everybody can join them, if the room administrator allows it): this may help reduce unwanted usages of your server by random people.

You can also add the following line to enable rich media transfers via http uploads (XEP-0363):


Component "upload.chat.trueelena.org" "http_upload"

The defaults are pretty sane, but see https://modules.prosody.im/mod_http_upload.html for details on what knobs you can configure for this module

Don't forget to enable the virtualhost by linking the file inside /etc/prosody/conf.d/.

additional modules

Most of the other interesting XEPs are enabled by loading additional modules inside /etc/prosody/prosody.cfg.lua (under modules_enabled); to enable mod_something just add a line like:


"something";

Most of these come from the prosody-modules package (and thus from https://modules.prosody.im/ ) and some may require changing when prosody 0.10 will be available; when this is the case it is mentioned below.


@Gruppo Linux Como @LIFO

11 January 2017

Steinar H. Gunderson: 3G-SDI signal support

I had to figure out what kinds of signal you can run over 3G-SDI today, and it's pretty confusing, so I thought I'd share it. For the reference, 3G-SDI is the same as 3G HD-SDI, an extension of HD-SDI, which is an extension of the venerable SDI standard (well, duh). They're all used for running uncompressed audio/video data of regular BNC coaxial cable, possibly hundreds of meters, and are in wide use in professional and semiprofessional setups. So here's the rundown on 3G-SDI capabilities: And then there's dual-link 3G-SDI, which uses two cables instead of one and there's also Blackmagic's proprietary 6G-SDI , which supports basically everything dual-link 3G-SDI does. But in 2015, seemingly there was also a real 6G-SDI and 12G-SDI, and it's unclear to me whether it's in any way compatible with Blackmagic's offering. It's all confusing. But at least, these are the differences from single-link to dual-link 3G-SDI: 4K? I don't know. 120fps? I believe that's also a proprietary extension of some sort. And of course, having a device support 3G-SDI doesn't mean at all it's required to support all of this; in particular, I believe Blackmagic's systems don't support alpha at all except on their single 12G-SDI card, and I'd also not be surprised if RGB support is rather limited in practice.

Reproducible builds folks: Reproducible Builds: week 89 in Stretch cycle

What happened in the Reproducible Builds effort between Sunday January 1 and Saturday January 7 2017: GSoC and Outreachy updates Toolchain development Packages reviewed and fixed, and bugs filed Chris Lamb: Dhole: Reviews of unreproducible packages 13 package reviews have been added, 4 have been updated and 6 have been removed in this week, adding to our knowledge about identified issues. 2 issue types have been added/updated: Upstreaming of reproducibility fixes Merged: Opened: Weekly QA work During our reproducibility testing, the following FTBFS bugs have been detected and reported by: diffoscope development diffoscope 67 was uploaded to unstable by Chris Lamb. It included contributions from :
[ Chris Lamb ]
* Optimisations:
  - Avoid multiple iterations over archive by unpacking once for an ~8X
    runtime optimisation.
  - Avoid unnecessary splitting and interpolating for a ~20X optimisation
    when writing --text output.
  - Avoid expensive diff regex parsing until we need it, speeding up diff
    parsing by 2X.
  - Alias expensive Config() in diff parsing lookup for a 10% optimisation.
* Progress bar:
  - Show filenames, ELF sections, etc. in progress bar.
  - Emit JSON on the the status file descriptor output instead of a custom
    format.
* Logging:
  - Use more-Pythonic logging functions and output based on __name__, etc.
  - Use Debian-style "I:", "D:" log level format modifier.
  - Only print milliseconds in output, not microseconds.
  - Print version in debug output so that saved debug outputs can standalone
    as bug reports.
* Profiling:
  - Also report the total number of method calls, not just the total time.
  - Report on the total wall clock taken to execute diffoscope, including
    cleanup.
* Tidying:
  - Rename "NonExisting" -> "Missing".
  - Entirely rework diffoscope.comparators module, splitting as many separate
    concerns into a different utility package, tidying imports, etc.
  - Split diffoscope.difference into diffoscope.diff, etc.
  - Update file references in debian/copyright post module reorganisation.
  - Many other cleanups, etc.
* Misc:
  - Clarify comment regarding why we call python3(1) directly. Thanks to J r my
    Bobbio <lunar@debian.org>.
  - Raise a clearer error if trying to use --html-dir on a file.
  - Fix --output-empty when files are identical and no outputs specified.
[ Reiner Herrmann ]
* Extend .apk recognition regex to also match zip archives (Closes: #849638)
[ Mattia Rizzolo ]
* Follow the rename of the Debian package "python-jsbeautifier" to
  "jsbeautifier".
[ siamezzze ]
* Fixed no newline being classified as order-like difference.
reprotest development reprotest 0.5 was uploaded to unstable by Chris Lamb. It included contributions from:
[ Ximin Luo ]
* Stop advertising variations that we're not actually varying.
  That is: domain_host, shell, user_group.
* Fix auto-presets in the case of a file in the current directory.
* Allow disabling build-path variations. (Closes: #833284)
* Add a faketime variation, with NO_FAKE_STAT=1 to avoid messing with
  various buildsystems. This is on by default; if it causes your builds
  to mess up please do file a bug report.
* Add a --store-dir option to save artifacts.
Other contributions (not yet uploaded): reproducible-builds.org website development tests.reproducible-builds.org Misc. This week's edition was written by Chris Lamb, Holger Levsen and Vagrant Cascadian, reviewed by a bunch of Reproducible Builds folks on IRC & the mailing lists.

Dirk Eddelbuettel: R / Finance 2017 Call for Papers

Last week, Josh sent the call for papers to the R-SIG-Finance list making everyone aware that we will have our nineth annual R/Finance conference in Chicago in May. Please see the call for paper (at the link, below, or at the website) and consider submitting a paper. We are once again very excited about our conference, thrilled about upcoming keynotes and hope that many R / Finance users will not only join us in Chicago in May 2017 -- but also submit an exciting proposal. We also overhauled the website, so please see R/Finance. It should render well and fast on devices of all sizes: phones, tablets, desktops with browsers in different resolutions. The program and registration details still correspond to last year's conference and will be updated in due course. So read on below, and see you in Chicago in May!

Call for Papers R/Finance 2017: Applied Finance with R
May 19 and 20, 2017
University of Illinois at Chicago, IL, USA The ninth annual R/Finance conference for applied finance using R will be held on May 19 and 20, 2017 in Chicago, IL, USA at the University of Illinois at Chicago. The conference will cover topics including portfolio management, time series analysis, advanced risk tools, high-performance computing, market microstructure, and econometrics. All will be discussed within the context of using R as a primary tool for financial risk management, portfolio construction, and trading. Over the past eight years, R/Finance has included attendees from around the world. It has featured presentations from prominent academics and practitioners, and we anticipate another exciting line-up for 2017. We invite you to submit complete papers in pdf format for consideration. We will also consider one-page abstracts (in txt or pdf format) although more complete papers are preferred. We welcome submissions for both full talks and abbreviated "lightning talks." Both academic and practitioner proposals related to R are encouraged. All slides will be made publicly available at conference time. Presenters are strongly encouraged to provide working R code to accompany the slides. Data sets should also be made public for the purposes of reproducibility (though we realize this may be limited due to contracts with data vendors). Preference may be given to presenters who have released R packages. Financial assistance for travel and accommodation may be available to presenters, however requests must be made at the time of submission. Assistance will be granted at the discretion of the conference committee. Please submit proposals online at http://go.uic.edu/rfinsubmit. Submissions will be reviewed and accepted on a rolling basis with a final deadline of February 28, 2017. Submitters will be notified via email by March 31, 2017 of acceptance, presentation length, and financial assistance (if requested). Additional details will be announced via the conference website as they become available. Information on previous years' presenters and their presentations are also at the conference website. We will make a separate announcement when registration opens. For the program committee:
Gib Bassett, Peter Carl, Dirk Eddelbuettel, Brian Peterson,
Dale Rosenthal, Jeffrey Ryan, Joshua Ulrich

Dirk Eddelbuettel: nanotime 0.1.0: Now on Windows

Last month, we released nanotime, a package to work with nanosecond timestamps. See the initial release announcement for some background material and a few first examples. nanotime relies on the RcppCCTZ package for high(er) resolution time parsing and formatting: R itself stops a little short of a microsecond. And it uses the bit64 package for the actual arithmetic: time at this granularity is commonly represented at (integer) increments (at nanosecond resolution) relative to an offset, for which the standard epoch of Januar 1, 1970 is used. int64 types are a perfect match here, and bit64 gives us an integer64. Naysayers will point out some technical limitations with R's S3 classes, but it works pretty much as needed here. The one thing we did not have was Windows support. RcppCCTZ and the CCTZ library it uses need real C++11 support, and the g++-4.9 compiler used on Windows falls a little short lacking inter alia a suitable std::get_time() implementation. Enter Dan Dillon who ported this from LLVM's libc++ which lead to Sunday's RcppCCTZ 0.2.0 release. And now we have all our ducks in a row: everything works on Windows too. The next paragraph summarizes the changes for both this release as well as the initial one last month:

Changes in version 0.1.0 (2017-01-10)
  • Added Windows support thanks to expanded RcppCCTZ (closes #6)
  • Added "mocked up" demo with nanosecond delay networking analysis
  • Added 'fmt' and 'tz' options to output functions, expanded format.nanotime (closing #2 and #3)
  • Added data.frame support
  • Expanded tests

Changes in version 0.0.1 (2016-12-15)
  • Initial CRAN upload.
  • Package is functional and provides examples.

We also have a diff to the previous version thanks to CRANberries. More details and examples are at the nanotime page; code, issue tickets etc at the GitHub repository.

This post by Dirk Eddelbuettel originated on his Thinking inside the box blog. Please report excessive re-aggregation in third-party for-profit settings.

9 January 2017

Shirish Agarwal: The Great Indian Digital Tamasha

Indian Railways This is an extension to last month s article/sharing where I had shared the changes that had transpired in the last 2-3 months. Now am in a position to share the kind of issues a user can go through in case he is looking for support from IRCTC to help him/her go cashless. If you a new user to use IRCTC services you wouldn t go through this trouble. For those who might have TL;DR issues it s about how hard it can become to get digital credentials fixed in IRCTC (Indian Railway Catering and Tourism Corporation) a. 2 months back Indian Prime Minister gave a call incentivizing people to use digital means to do any commercial activities. One of the big organizations which took/takes part is IRCTC which handles the responsibility for e-ticketing millions of Rail tickets for common people. In India, a massive percentage moves by train as it s cheaper than going by Air. A typical fare from say Pune Delhi (capital of India) by second class sleeper would be INR 645/- for a distance of roughly 1600 odd kms and these are monopoly rates, there are no private trains and I m not suggesting anything of that sort, just making sure that people know. An economy class ticket by Air for the same distance would be anywhere between INR 2500-3500/- for a 2 hour flight between different airlines. Last I checked there are around 8 mainstream airlines including flag-carrier Air India. About 30% of the population live on less than a dollar and a half a day which would come around INR 100/-. There was a comment some six months back on getting more people out of the poverty line. But as there are lots of manipulations in numbers for who and what denotes above poor and below poor in India and lot of it has to do with politics it s not something which would be easily fixable. There are lots to be said in that arena but this article is not an appropriate blog-post for that. All in all, it s only 3-5% of the population at the most who can travel via Air if situation demands and around 1-2% who might be frequent, business or leisure travellers. Now while I can thankfully afford an Air Ticket if the situation so demands, my mother gets motion sickness so while together we can only travel by train. b. With the above background, I had registered with IRCTC few years ago with another number (dual-SIM) I had purchased and was thinking that I would be using this long-term (seems to my first big mistake, hindsight 50:50) . This was somewhere in 2006/2007. c. Few months later I found that the other service provider wasn t giving good service or was not upto mark. I was using IDEA (the main mobile operator) throughout those times. d. As I didn t need the service that much, didn t think to inform them that I want to change to another service provider at that point in time (possibly the biggest mistake, hindsight 50:50) e. In July 2016 itself IRCTC cut service fees, f. This was shared as a NEW news item/policy decision at November-end 2016 . g. While I have done all that has been asked by irctc-care haven t still got the issues resolved  IRCTC s e-mail id care@irctc.co.in Now in detail This is my first e-mail sent to IRCTC in June 2016
Dear Customer care, I had applied and got username and password sometime back . The
number I had used to register with IRCTC was xxxxxxxxxx (BSNL mobile number not used anymore) . My mobile was lost and along with that the number was also lost. I had filed a complaint with the police and stopped that number as well. Now I have an another mobile number but have forgotten both the password and the security answer that I had given when I had registered . I do have all the conversations I had both with the ticketadmn@irctc.co.in as well as care@irctc.co.in if needed to prove my identity. The new number I want to tie it with is xxxxxxxxxx (IDEA number in-use for last 10 years) I see two options :- a. Tie the other number with my e-mail address b. Take out the e-mail address from the database so that I can fill in
as a new applicant. Looking forward to hear from you.
There was lot of back and forth with various individuals on IRCTC and after a lot of back and forth, this is the final e-mail I got from them somewhere in August 2016, he writes
Dear Customer, We request you to send mobile bill of your mobile number if it is post paid or if it is prepaid then contact to your service provider and they will give you valid proof of your mobile number or they will give you in written on company head letter so that we may update your mobile number to update so that you may reset your password through mobile OTP.
and Kindly inform you that you can update your profile by yourself also. 1.login on IRCTC website
2.after login successfully move courser on my profile tab.
3.then click on update profile
4.re-enter your password then you can update your profile
5.click on user-profile then email id.
6. click on update. Still you face any problem related to update profile please revert to us with the screen shots of error message which you will get at the time of update profile . Thanks & Regards Parivesh Patel
Executive, Customer Care
care@irctc.co.in
http://www.irctc.co.in
[#3730034]
IRCTC s response seemed responsible, valid and thought it would be a cake-walk as private providers are supposed to be much more efficient than public ones. The experience proved how wrong was I trust them with doing the right thing 1. First I tried the twitter handle to see how IDEA uses their twitter handle. 2. The idea customer care twitter handle was mild in its response. 3. After sometime I realized that the only way out of this quagmire would perhaps be to go to a brick-mortar shop and get it resolved face-to-face. I went twice or thrice but each time something or the other would happen. On the fourth and final time, I was able to get to the big Official shop only to be told they can t do anything about this and I would have to the appellate body to get the reply. The e-mail address which they shared (and I found it later) was wrong. I sent a somewhat longish e-mail sharing all the details and got bounce-backs. The correct e-mail address for the IDEA Maharashtra appellate body is appellette.mh@idea.aditybirla.com I searched online and after a bit of hit and miss finally got the relevant address. Then finally on 30th December, 2016 wrote a short email to the service provider as follows
Dear Sir,
I have been using prepaid mobile connection number xxxxxxx taken from IDEA for last 10 odd years. I want to register myself with IRCTC for online railway booking using
my IDEA mobile number. Earlier, I was having a BSNL connection which I discontinued 4 years back, For re-registering myself with IRCTC, I have to fulfill their latest
requirements as shown in the email below . It is requested that I please be issued a letter confirming my
credentials with your esteemed firm. I contacted your local office at corner of Law College Road and
Bhandarkar Road, Pune (reference number Q1 84786060793) who
refused to provide me any letter and have advised me to contact on the
above e-mail address, hence this request is being forwarded to you. Please do the needful at your earliest.
Few days later I got this short e-mail from them
Dear Customer, Greetings for the day! This is with reference to your email regarding services. Please accept our apologies for the inconvenience caused to you and delay in response. We regret to inform you that we are unable to provide demographic details from our end as provision for same is not available with us. Should you need any further assistance, please call our Customer Service help line number 9822012345 or email us at customercare@idea.adityabirla.com by mentioning ten digit Idea mobile number in subject line. Thanks & Regards, Javed Khan Customer Service Team IDEA Cellular Limited- Maharashtra & Goa Circle.
Now I was at almost my wit s end. Few days before, I had re-affirmed my e-mail address to IDEA . I went to the IDEA care site, registered with my credentials. While the https connection to the page is weak, but let s not dwell on that atm. I logged into the site, I went through all the drop-down menus and came across My Account > Raise a request link which I clicked on . This came to a page where I could raise requests for various things. One of the options given there was Bill Delivery. As I wasn t a postpaid user but a prepaid user didn t know if that would work or not I still clicked on it. It said it would take 4 days for that to happen. I absently filed it away as I was somewhat sure that nothing would happen from my previous experience with IDEA. But this time the IDEA support staff came through and shared a toll-free SMS number and message format that I could use to generate call details from the last 6 months. The toll-free number from IDEA is 12345 and the message format is EBILL MON (short-form for month so if it s January would be jan, so on and so forth). After gathering all the required credentials, sent my last mail to IRCTC about a week, 10 days back
Dear Mr. Parivesh Patel, I was out-of-town and couldn t do the needful so sorry for the delay.
Now that I m back in town, I have been able to put together my prepaid
bills of last 6 months which should make it easy to establish my
identity. As had shared before, I don t remember my old password and the old
mobile number (BSNL number) is no longer accessible so can t go
through that route. Please let me know the next steps in correcting the existing IRCTC
account (which I haven t operated ever) so I can start using it to
book my tickets. Look forward to hearing from you.
Haven t heard anything them from them, apart from a generated token number, each time you send a reply happens. This time it was #4763548 The whole sequence of events throws a lot of troubling questions a. Could IRCTC done a better job of articulating their need to me instead of the run-around I was given ? b. Shouldn t there be a time limit to accounts from which no transactions have been done ? I hadn t done a single transaction since registering. When cell service providers including BSNL takes number out after a year of not using a number, why is that account active for so long ? c. As that account didn t have OTP at registration, dunno if it s being used for illegal activities or something. Update This doesn t seem to be a unique thing at all. Just sampling some of the tweets by people at @IRCTC_LTD https://twitter.com/praveen4al/status/775614978258718721 https://twitter.com/vis_nov25/status/786062572390932480 https://twitter.com/ShubhamDevadiya/status/794241443950948352 https://twitter.com/rajeshhindustan/status/798028633759584256 https://twitter.com/ameetsangita/status/810081624343908352 https://twitter.com/grkisback/status/813733835213078528 https://twitter.com/gbalaji_/status/804230235625394177 https://twitter.com/chandhu_nr/status/800675627384721409 , all of this just goes to show how un-unique the situation really is.
Filed under: Miscellenous Tagged: #customer-service, #demonetization, #IDEA-aditya birla, #IRCTC, #web-services, rant

Dirk Eddelbuettel: RcppCCTZ 0.2.0

A new version, now at 0.2.0, of RcppCCTZ is now on CRAN. And it brings a significant change: windows builds! Thanks to Dan Dillon who dug deep enough into the libc++ sources from LLVM to port the std::get_time() function that is missing from the 4.* series of g++. And with Rtools being fixed at g++-4.9.3 this was missing for us here. Now we can parse dates for use by RcppCCTZ on Windows as well. That is important not only for RcppCCTZ but also particularly for the one package (so far) depending on it: nanotime. CCTZ is a C++ library for translating between absolute and civil times using the rules of a time zone. In fact, it is two libraries. One for dealing with civil time: human-readable dates and times, and one for converting between between absolute and civil times via time zones. It requires only a proper C++11 compiler and the standard IANA time zone data base which standard Unix, Linux, OS X, ... computers tend to have in /usr/share/zoneinfo -- and for which R on Windows ships its own copy we can use. RcppCCTZ connects this library to R by relying on Rcpp. The RcppCCTZ page has a few usage examples, as does the post announcing the previous release. The changes in this version are summarized here:

Changes in version 0.2.0 (2017-01-08)
  • Windows compilation was enabled by defining OFFSET() and ABBR() for MinGW (#10 partially addressing #9)
  • Windows use completed with backport of std::get_time from LLVM's libc++ to enable strptime semantics (Dan Dillon in #11 completing #9)
  • Timezone information on Windows is supplied via R's own copy of zoneinfo with TZDIR set (also #10)
  • The interface to formatDouble was cleaned up

We also have a diff to the previous version thanks to CRANberries. More details are at the RcppCCTZ page; code, issue tickets etc at the GitHub repository.

This post by Dirk Eddelbuettel originated on his Thinking inside the box blog. Please report excessive re-aggregation in third-party for-profit settings.

8 January 2017

Jonas Meurer: debian lts report 2016.12

Debian LTS report for December 2016 December 2016 was my fourth month as a Debian LTS team member. I was allocated 12 hours. Unfortunately I turned out to have way less time for Debian and LTS work than expected, so I only spent 5,25 hours of them for the following tasks:

Jonas Meurer: debian lts report 2016 12

Debian LTS report for December 2016 December 2016 was my fourth month as a Debian LTS team member. I was allocated 12 hours. Unfortunately I turned out to have way less time for Debian and LTS work than expected, so I only spent 5,25 hours of them for the following tasks:

Dirk Eddelbuettel: Rcpp now used by 900 CRAN packages

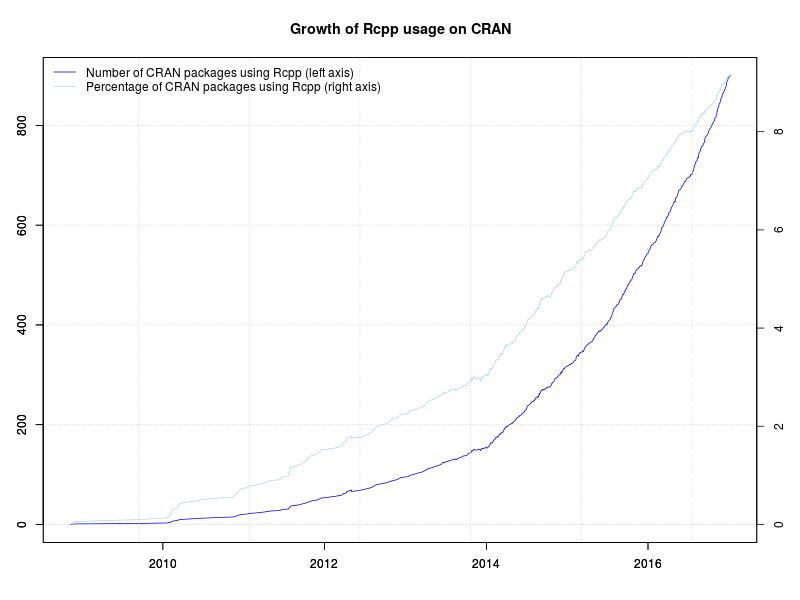
800 Rcpp packages Today, Rcpp passed another milestone as 900 packages on CRAN now depend on it (as measured by Depends, Imports and LinkingTo declarations). The graph is on the left depicts the growth of Rcpp usage over time. The easiest way to compute this is to use the reverse_dependencies_with_maintainers() function from a helper scripts file on CRAN. This still gets one or two false positives of packages declaring a dependency but not actually containing C++ code and the like. There is also a helper function revdep() in the devtools package but it includes Suggests: which does not firmly imply usage, and hence inflates the count. I have always opted for a tighter count with corrections. Rcpp cleared 300 packages in November 2014. It passed 400 packages in June 2015 (when I only tweeted about it), 500 packages in late October 2015, 600 packages last March, 700 packages last July and 800 packages last October. The chart extends to the very beginning via manually compiled data from CRANberries and checked with crandb. The next part uses manually saved entries. The core (and by far largest) part of the data set was generated semi-automatically via a short script appending updates to a small file-based backend. A list of packages using Rcpp is kept on this page. Also displayed in the graph is the relative proportion of CRAN packages using Rcpp. The four per-cent hurdle was cleared just before useR! 2014 where I showed a similar graph (as two distinct graphs) in my invited talk. We passed five percent in December of 2014, six percent July of last year, seven percent just before Christmas eight percent this summer, and nine percent mid-December. 900 user packages is a really large number. This puts more than some responsibility on us in the Rcpp team as we continue to keep Rcpp as performant and reliable as it has been. At the rate things are going, the big 1000 may be hit some time in April. And with that a very big Thank You! to all users and contributors of Rcpp for help, suggestions, bug reports, documentation or, of course, code.

This post by Dirk Eddelbuettel originated on his Thinking inside the box blog. Please report excessive re-aggregation in third-party for-profit settings.

7 January 2017

Enrico Zini: Teamwork

When I saw this video or this video I thought of this article. When I feel part of a tightly coordinated and synchronized team I feel proud for the achievements of the team as a whole, which I see as bigger than what I could have achieved alone. I also don't feel at risk of taking bad decisions. I feel less responsible. If I do what I'm told, I can't be blamed for doing the wrong things. I find it relaxing, every once in a while, to not have to be in charge. I guess this could be part of the allure of a totalitarian regime: being freed from the burden of growing up Thinking about this, reading those articles about romantic relationships, I see quite a bit of parallels also with organising cooperation and teamwork. It looks like I ended up making parallels between Polyamory, Anarchism, and Free Software again. If you think there should traditionally be also a mention of BDSM, go back to "I find it relaxing, every once in a while, to not have to be in charge".

6 January 2017

Elena 'valhalla' Grandi: Candy from Strangers

Candy from Strangers

A few days ago I gave a talk at ESC https://www.endsummercamp.org/ about some reasons why I think that using software and especially libraries from the packages of a community managed distribution is important and much better than alternatives such as pypi, nmp etc. This article is a translation of what I planned to say before forgetting bits of it and luckily adding it back as an answer to a question :)

When I was young, my parents taught me not to accept candy from strangers, unless they were present and approved of it, because there was a small risk of very bad things happening. It was of course a simplistic rule, but it had to be easy enough to follow for somebody who wasn't proficient (yet) in the subtleties of social interactions.

One of the reasons why it worked well was that following it wasn't a big burden: at home candy was plenty and actual offers were rare: I only remember missing one piece of candy because of it, and while it may have been a great one, the ones I could have at home were also good.

Contrary to candy, offers of gratis software from random strangers are quite common: from suspicious looking websites to legit and professional looking ones, to platforms that are explicitly designed to allow developers to publish their own software with little or no checks.

Just like candy, there is also a source of trusted software in the Linux distributions, especially those lead by a community: I mention mostly Debian because it's the one I know best, but the same principles apply to Fedora and, to some measure, to most of the other distributions. Like good parents, distributions can be wrong, and they do leave room for older children (and proficient users) to make their own choices, but still provide a safe default.

Among the unsafe sources there are many different cases and while they do share some of the risks, they have different targets with different issues; for brevity the scope of this article is limited to the ones that mostly concern software developers: language specific package managers and software distribution platforms like PyPi, npm and rubygems etc.

These platforms are extremely convenient both for the writers of libraries, who are enabled to publish their work with minor hassles, and for the people who use such libraries, because they provide an easy way to install and use an huge amount of code. They are of course also an excellent place for distributions to find new libraries to package and distribute, and this I agree is a good thing.

What I however believe is that getting code from such sources and using it without carefully checking it is even more risky than accepting candy from a random stranger on the street in an unfamiliar neighbourhood.

The risk aren't trivial: while you probably won't be taken as an hostage for ransom, your data could be, or your devices and the ones who run your programs could be used in some criminal act causing at least some monetary damage both to yourself and to society at large.

If you're writing code that should be maintained in time there are also other risks even when no malice is involved, because each package on these platform has a different policy with regards to updates, their backwards compatibility and what can be expected in case an old version is found to have security issues.

The very fact that everybody can publish anything on such platforms is both their biggest strength and their main source of vulnerability: while most of the people who publish their libraries do so with good intentions, attacks have been described and publicly tested, such as the fun typo-squatting http://incolumitas.com/2016/06/08/typosquatting-package-managers/ one (archived on http://web.archive.org/web/20160801161807/http://incolumitas.com/2016/06/08/typosquatting-package-managers) that published harmless malicious code under common typos for famous libraries.

Contrast this with Debian, where everybody can contribute, but before they are allowed full unsupervised access to the archive they have to establish a relationship with the rest of the community, which includes meeting other developers in real life, at the very least to get their gpg keys signed.

This doesn't prevent malicious people from introducing software, but raises significantly the effort required to do so, and once caught people can usually be much more effectively prevented from repeating it than a simple ban on an online-only account can do.

It is true that not every Debian maintainer actually does a full code review of everything that they allow in the archive, and in some cases it would be unreasonable to expect it, but in most cases they are at least reasonably familiar with the code to do at least bug triage, and most importantly they are in an excellent position to establish a relationship of mutual trust with the upstream authors.

Additionally, package maintainers don't work in isolation: a growing number of packages are being maintained by a team of people, and most importantly there are aspects that involve potentially the whole community, from the fact that new packages that enter the distribution are publicity announced on a mailing list to the various distribution-wide QA efforts.

Going back to the language specific distribution platforms, sometimes even the people who manage the platform themselves can't be fully trusted to do the right thing: I believe everybody in the field remembers the npm fiasco https://lwn.net/Articles/681410/ where a lawyer letter requesting the removal of a package started a series of events that resulted in potentially breaking a huge amount of automated build systems.

Here some of the problems were caused by some technical policies that caused the whole ecosystem to be especially vulnerable, but one big issue was the fact that the managers of the npm platform are a private entity with no oversight from the user community.

Here not all distributions are equal, but contrast this with Debian, where the distribution is managed by a community that is based on a social contract https://www.debian.org/social_contract and is governed via democratic procedures established in its https://www.debian.org/devel/constitution.

Additionally, the long history of the distribution model means that many issues have already been met, the errors have already been done, and there are established technical procedures to deal with them in a better way.

So, shouldn't we use language specific distribution platforms at all? No! As developers we aren't children, we are adults who have the skills to distinguish between safe and unsafe libraries just as well as the average distribution maintainer can do. What I believe we should do is stop treating them as a safe source that can be used blindly and reserve that status to actual trustful sources like Debian, falling back to the language specific platforms only when strictly needed, and in that case:

actually check carefully what we are using, both by reading the code and by analysing the development and community practices of the authors;
if possible, share that work by becoming ourselves maintainers of that library in our favourite distribution, to prevent duplication of effort and to give back to the community whose work we get advantage from.

Edit: fixed broken typosquatting url

Dirk Eddelbuettel: RcppTOML 0.1.0

Big news: RcppTOML now works on Windows too! This package had an uneventful 2016 without a single update. Release 0.0.5 had come out in late 2015 and we had no bugs or issues to fix. We use the package daily in production: a key part of our parameterisation is in TOML files In the summer, I took one brief stab at building on Windows now that R sports itself a proper C++11 compiler on Windows too. I got stuck over the not-uncommon problem of incomplete POSIX and/or C++11 support with MinGW and g++-4.9. And sadly ... I appears I wasn't quite awake enough to realize that the missing functionality was right there exposed by Rcpp! Having updated that date / datetime functionality very recently, I was in a better position to realize this when Devin Pastoor asked two days ago. I was able to make a quick suggestion which he tested, which I then refined ... here we are: RcppTOML on Windows too! (For the impatient: CRAN has reported that it has built the Windows binaries, they should hit mirrors such as this CRAN package for RcppTOML shortly.) So what is this TOML thing, you ask? A file format, very suitable for configurations, meant to be edited by humans but read by computers. It emphasizes strong readability for humans while at the same time supporting strong typing as well as immediate and clear error reports. On small typos you get parse errors, rather than silently corrupted garbage. Much preferable to any and all of XML, JSON or YAML -- though sadly these may be too ubiquitous now. But TOML is making good inroads with newer and more flexible projects. The Hugo static blog compiler is one example; the Cargo system of Crates (aka "packages") for the Rust language is another example. The new release updates the included cpptoml template header by Chase Geigle, brings the aforementioned Windows support and updates the Travis configuration. We also added a NEWS file for the first time so here are all changes so far:

Changes in version 0.1.0 (2017-01-05)
  • Added Windows support by relying on Rcpp::mktime00() (#6 and #8 closing #5 and #3)
  • Synchronized with cpptoml upstream (#9)
  • Updated Travis CI support via newer run.sh

Changes in version 0.0.5 (2015-12-19)
  • Synchronized with cpptoml upstream (#4)
  • Improved and extended examples

Changes in version 0.0.4 (2015-07-16)
  • Minor update of upstream cpptoml.h
  • More explicit call of utils::str()
  • Properly cope with empty lists (#2)

Changes in version 0.0.3 (2015-04-27)
  • First CRAN release after four weeks of initial development

Courtesy of CRANberries, there is a diffstat report for this release. More information and examples are on the RcppTOML page. Issues and bugreports should go to the GitHub issue tracker.

This post by Dirk Eddelbuettel originated on his Thinking inside the box blog. Please report excessive re-aggregation in third-party for-profit settings.

Next.

Previous.