Search Results: "spa"

15 July 2017

Joey Hess: Functional Reactive Propellor

I wrote this code, and it made me super happy!
data Variety = Installer   Target
    deriving (Eq)
seed :: UserInput -> Versioned Variety Host
seed userinput ver = host "foo"
    & ver (   (== Installer) --> hostname "installer"
          < > (== Target)    --> hostname (inputHostname userinput)
          )
    & osDebian Unstable X86_64
    & Apt.stdSourcesList
    & Apt.installed ["linux-image-amd64"]
    & Grub.installed PC
    & XFCE.installed
    & ver (   (== Installer) --> desktopUser defaultUser
          < > (== Target)    --> desktopUser (inputUsername userinput)
          )
    & ver (   (== Installer) --> autostartInstaller )
This is doing so much in so little space and with so little fuss! It's completely defining two different versions of a Host. One version is the Installer, which in turn installs the Target. The code above provides all the information that propellor needs to convert a copy of the Installer into the Target, which it can do very efficiently. For example, it knows that the default user account should be deleted, and a new user account created based on the user's input of their name. The germ of this idea comes from a short presentation I made about propellor in Portland several years ago. I was describing RevertableProperty, and Joachim Breitner pointed out that to use it, the user essentially has to keep track of the evolution of their Host in their head. It would be better for propellor to know what past versions looked like, so it can know when a RevertableProperty needs to be reverted. I didn't see a way to address the objection for years. I was hung up on the problem that propellor's properties can't be compared for equality, because functions can't be compared for equality (generally). And on the problem that it would be hard for propellor to pull old versions of a Host out of git. But then I ran into the situation where I needed these two closely related hosts to be defined in a single file, and it all fell into place. The basic idea is that propellor first reverts all the revertible properties for other versions. Then it ensures the property for the current version. Another use for it would be if you wanted to be able to roll back changes to a Host. For example:
foos :: Versioned Int Host
foos ver = host "foo"
    & hostname "foo.example.com"
    & ver (   (== 1) --> Apache.modEnabled "mpm_worker"
          < > (>= 2) --> Apache.modEnabled "mpm_event"
          )
    & ver ( (>= 3)   --> Apt.unattendedUpgrades )
foo :: Host
foo = foos  version  (4 :: Int)
Versioned properties can also be defined:
foobar :: Versioned Int -> RevertableProperty DebianLike DebianLike
foobar ver =
    ver (   (== 1) --> (Apt.installed "foo" <!> Apt.removed "foo")
        < > (== 2) --> (Apt.installed "bar" <!> Apt.removed "bar")
        )
Notice that I've embedded a small DSL for versioning into the propellor config file syntax. While implementing versioning took all day, that part was super easy; Haskell config files win again! API documentation for this feature PS: Not really FRP, probably. But time-varying in a FRP-like way.
Development of this was sponsored by Jake Vosloo on Patreon.

Dirk Eddelbuettel: Rcpp 0.12.12: Rounding some corners

The twelveth update in the 0.12.* series of Rcpp landed on CRAN this morning, following two days of testing at CRAN preceded by five full reverse-depends checks we did (and which are always logged in this GitHub repo). The Debian package has been built and uploaded; Windows and macOS binaries should follow at CRAN as usual. This 0.12.12 release follows the 0.12.0 release from late July, the 0.12.1 release in September, the 0.12.2 release in November, the 0.12.3 release in January, the 0.12.4 release in March, the 0.12.5 release in May, the 0.12.6 release in July, the 0.12.7 release in September, the 0.12.8 release in November, the 0.12.9 release in January, the 0.12.10.release in March, and the 0.12.11.release in May making it the sixteenth release at the steady and predictable bi-montly release frequency. Rcpp has become the most popular way of enhancing GNU R with C or C++ code. As of today, 1097 packages (and hence 71 more since the last release in May) on CRAN depend on Rcpp for making analytical code go faster and further, along with another 91 in BioConductor. This releases contain a fairly large number of fairly small and focused pull requests most of which either correct some corner cases or improve other aspects. JJ tirelessly improved the package registration added in the previous release and following R 3.4.0. Kirill tidied up a number of small issues allowing us to run compilation in even more verbose modes---usually a good thing. Jeroen, Elias Pipping and Yo Gong all contributed as well, and we thank everybody for their contributions. All changes are listed below in some detail.

Changes in Rcpp version 0.12.12 (2017-07-13)
  • Changes in Rcpp API:
    • The tinyformat.h header now ends in a newline (#701).
    • Fixed rare protection error that occurred when fetching stack traces during the construction of an Rcpp exception (Kirill M ller in #706).
    • Compilation is now also possibly on Haiku-OS (Yo Gong in #708 addressing #707).
    • Dimension attributes are explicitly cast to int (Kirill M ller in #715).
    • Unused arguments are no longer declared (Kirill M ller in #716).
    • Visibility of exported functions is now supported via the R macro atttribute_visible (Jeroen Ooms in #720).
    • The no_init() constructor accepts R_xlen_t (Kirill M ller in #730).
    • Loop unrolling used R_xlen_t (Kirill M ller in #731).
    • Two unused-variables warnings are now avoided (Jeff Pollock in #732).
  • Changes in Rcpp Attributes:
    • Execute tools::package_native_routine_registration_skeleton within package rather than current working directory (JJ in #697).
    • The R portion no longer uses dir.exists to no require R 3.2.0 or newer (Elias Pipping in #698).
    • Fix native registration for exports with name attribute (JJ in #703 addressing #702).
    • Automatically register init functions for Rcpp Modules (JJ in #705 addressing #704).
    • Add Shield around parameters in Rcpp::interfaces (JJ in #713 addressing #712).
    • Replace dot (".") with underscore ("_") in package names when generating native routine registrations (JJ in #722 addressing #721).
    • Generate C++ native routines with underscore ("_") prefix to avoid exporting when standard exportPattern is used in NAMESPACE (JJ in #725 addressing #723).

Thanks to CRANberries, you can also look at a diff to the previous release. As always, even fuller details are on the Rcpp Changelog page and the Rcpp page which also leads to the downloads page, the browseable doxygen docs and zip files of doxygen output for the standard formats. A local directory has source and documentation too. Questions, comments etc should go to the rcpp-devel mailing list off the R-Forge page.

This post by Dirk Eddelbuettel originated on his Thinking inside the box blog. Please report excessive re-aggregation in third-party for-profit settings.

Vasudev Kamath: debcargo: Replacing subprocess crate with git2 crate

In my previous post I talked about using subprocess crate to extract beginning and ending year from git repository for generating debian/copyright file. In this post I'm going to talk on how I replaced subprocess with native git2 crate and achieved the same result in much cleaner and safer way. git2 is a native Rust crate which provides access to Git repository internals. git2 does not involve any unsafe invocation as it is built against libgit2-sys which is actually using Rust FFI to directly bind to underlying libgit library. Below is the new copyright_fromgit function with git2 crate.
fn copyright_fromgit(repo_url: &str) -> Result<String>  
   let tempdir = TempDir::new_in(".", "debcargo")?;
   let repo = Repository::clone(repo_url, tempdir.path())?;
   let mut revwalker = repo.revwalk()?;
   revwalker.push_head()?;
   // Get the latest and first commit id. This is bit ugly
   let latest_id = revwalker.next().unwrap()?;
   let first_id = revwalker.last().unwrap()?; // revwalker ends here is consumed by last
   let first_commit = repo.find_commit(first_id)?;
   let latest_commit = repo.find_commit(latest_id)?;
   let first_year =
       DateTime::<Utc>::from_utc(
               NaiveDateTime::from_timestamp(first_commit.time().seconds(), 0),
               Utc).year();
   let latest_year =
       DateTime::<Utc>::from_utc(
             NaiveDateTime::from_timestamp(latest_commit.time().seconds(), 0),
             Utc).year();
   let notice = match first_year.cmp(&latest_year)  
       Ordering::Equal => format!(" ", first_year),
       _ => format!(" - ,", first_year, latest_year),
    ;
   Ok(notice)
 
So here is what I'm doing
  1. Use git2::Repository::clone to clone the given URL. We are thus avoiding exec of git clone command.
  2. Get a revision walker object. git2::RevWalk implements Iterator trait and allows walking through the git history. This is what we are using to avoid exec of git log command.
  3. revwalker.push_head() is important because we want to tell revwalker from where we want to walk the history. In this case we are asking it to walk history from repository HEAD. Without this line next line will not work. (Learned it in hard way :-) ).
  4. Then we extract git2::Oid which is we can say similar to commit hash and can be used to lookup a particular commit. We take latest commit hash using RevWalk::next call and the first commit using Revwalk::last, note the order this is because Revwalk::last consumes the revwalker so doing it in reverse order will make borrow checker unhappy :-). This replaces exec of head -n1 command.
  5. Look up the git2::Commit objects using git2::Repository::find_commit
  6. Then convert the git2::Time to chrono::DateTime and take out the years.
After this change I found an obvious error which went unnoticed in previous version, that is if there was no repository key in Cargo.toml. When there was no repo URL git clone exec did not error out and our shell commands happily extracted year from the debcargo repository!. Well since I was testing code from debcargo repository It never failed, but when I executed from non-git repository folder git threw an error but that was git log and not git clone. This error was spotted right away because git2 threw me an error that I gave it empty URL. When it comes to performance I see that debcargo is faster compared to previous version. This makes sense because previously it was doing 5 fork and exec system calls and now that is avoided.

14 July 2017

Chris Lamb: Installation birthday

Fancy receiving congratulations on the anniversary of when you installed your system? Installing the installation-birthday package on your Debian machines will celebrate each birthday of your system by automatically sending a message to the local system administrator. The installation date is based on the system installation time, not the package itself. installation-birthday is available in Debian 9 ("stretch") via the stretch-backports repository, as well as in the testing and unstable distributions:
$ apt install installation-birthday
Enjoy, and patches welcome. :)

Norbert Preining: TeX Live contrib repository (re)new(ed)

It is my pleasure to announce the renewal/rework/restart of the TeX Live contrib repository service. The repository is collecting packages that cannot enter TeX Live directly (mostly due to license reasons), but are free to distribute. The basic idea is to provide a repository mimicking Debian s nonfree branch. The packages on this site are not distributed inside TeX Live proper for one or another of the following reasons: In short, anything related to TeX that can not be on TeX Live but can still legally be distributed over the Internet can hav e a placeon TLContrib. Currently there are 52 packages in the repository, falling roughly into the following categories: The full list of packages can be seen here. The ultimate goal is to provide a companion to the core TeX Live (tlnet) distribution in much the same way as Debian s non-free tree is a companion to the normal distribution. The goal is not to replace TeX Live: packages that could go into TeX Live itself should stay (or be added) there. TLContrib is simply trying to fill in a gap in the current distribution system. Quick Start If you are running the current version of TeX Live, which is 2017 at the moment, the following code will suffice:
  tlmgr repository add http://contrib.texlive.info/current tlcontrib
  tlmgr pinning add tlcontrib '*'
In future there might be releases for certain years. Verification The packages are signed with my GnuPG RSA key: 0x6CACA448860CDC13. tlmgr will automatically verify authenticity if you add my key:
  curl -fsSL https://www.preining.info/rsa.asc   tlmgr key add -
After that tlmgr will tell you about failed authentication of this repository. History Taco Hoekwater started in 2010, but it hasn t seen much activity in recent years. Taco agreed to hand it over to myself, who is currently maintaining the repository. Big thanks to Taco for his long support and cooperation. In contrast to the original tlcontrib page, we don t offer an automatic upload of packages or user registration. If you want to add packages here, see below. Adding packages If you want to see a package included here that cannot enter TeX Live proper, the following ways are possible (from most appreciated to least appreciated): Git repository The packages are kept in a git repository and the tlmgr repo is built from after changes. The location is https://git.texlive.info/tlcontrib. Enjoy.

13 July 2017

Lucy Wayland: Basic Chilli Template

Amounts are to taste:
[Stage one]
Chopped red onion
Chopped garlic
Chopped fresh ginger
Chopped big red chillies (mild)
Chopped birds eye chillies (red or green, quite hot)
Chopped scotch bonnets (hot)
[Fry onion in some olive oil. When getting translucent, and rest of ingredients. May need to add some more oil. When the garlic is browning. On to stage two.]
[Stage two]
Some tins of chopped tomato
Some tomato puree
Some basil
Some thyme
Bay leaf optional
Some sliced mushroom
Some chopped capsicum pepper
Some kidney beans
Other beans optional (butter beans are nice)
Lentils optional (Pro tip: if adding lentils to adding lentils, especially red lentils, I recommend adding some garam masala as well. Lifts the flavour.)
Veggie mince optional
Pearled barley very optional
Stock (some reclaimed from swilling water around tom tims)
Water to keep topping up with if it get too sticky or dry
Dash of red wine optional
Worcester sauce optional
Any other flavouring you feel like optional (I quite often add random herbs or spices
[[Secret ingredient: a spoonful of Marmite]]
[Cook everything up together, but wait until there is enough fluid before you add the dry/sticky ingredients in.]
[Serve with carb of choice. I currently fond of using Ryvita as dipper instead of tortilla chips.]
[Also serve with a a cooler such as natural yogurt, soured cream or something else. You want more than one type of chilli in there to broaden the flavour. I use all three, plus occasionally others as well. If you are feeling masochistic you can go hotter than scotch bonnets, but I although you may get something of the same heat, I think you lose something in the flavour. BTW if you get the chance, of all the tortilla chips, I think blue corn ones are the best. Only seem to find them in health food shops. There you go. It s a Zen recipe, which is why I couldn t give you a link. You just do it until it looks right, feels right, tastes right. And with practice you get it better and better.

12 July 2017

Yakking: Time - What are clocks?

System calls You can't talk about time without clocks. A standard definition of clocks is "An instrument to measure time". Strictly speaking the analogy isn't perfect, since these clocks aren't just different ways of measuring time, they measure some different notions of time, but this is a somewhat philosophical point. The interface for this in Linux are system calls with a clkid_t parameter, though not all system calls are valid for every clock. This is not an exhaustive list of system calls, since there are also older system calls for compatibility with POSIX or other UNIX standards, that offer a subset of the functionality of the above ones. System calls beginning clock_ are about getting the time or waiting, beginning timer_ are for setting periodic or one-shot timers, timerfd_ are for timers that can be put in event loops. For the sake of not introducing too many concepts at once, we're going to start with the simplest clock and work our way up. CLOCK_MONOTONIC_RAW The first clock we care about is CLOCK_MONOTONIC_RAW. This is the simplest clock. It it initialised to an arbitrary value on boot and counts up at a rate of one second per second to the best of its ability. This clock is of limited use on its own since the only clock-related system calls that work with it are clock_gettime(2) and clock_getres(2). It can be used to determine the order of events, if the time of the event was recorded and the relative time difference between when they happened, since we know that the clock increments one second per second. Example In this program below, we time how long it takes to read 4096 bytes from /dev/zero, and print the result.
#include <stdio.h> /* fopen, fread, printf */
#include <time.h> /* clock_gettime, CLOCK_MONOTONIC_RAW, struct timespec */
int main(void)  
    FILE *devzero;
    int ret;
    struct timespec start, end;
    char buf[4096];
    devzero = fopen("/dev/zero", "r");
    if (!devzero)  
        return 1;
     
    /* get start time */
    ret = clock_gettime(CLOCK_MONOTONIC_RAW, &start);
    if (ret < 0)  
        return 2;
     
    if (fread(buf, sizeof *buf, sizeof buf, devzero) != sizeof buf)  
        return 3;
     
    /* get end time */
    ret = clock_gettime(CLOCK_MONOTONIC_RAW, &end);
    if (ret < 0)  
        return 4;
     
    end.tv_nsec -= start.tv_nsec;
    if (end.tv_nsec < 0)  
        end.tv_sec--;
        end.tv_nsec += 1000000000l;
     
    end.tv_sec -= start.tv_sec;
    printf("Reading %zu bytes took %.0f.%09ld seconds\n",
           sizeof buf, (double)end.tv_sec, (long)end.tv_nsec);
    return 0;
 

You're possibly curious about the naming of the clock called MONOTONIC_RAW. In the next article we will talk about CLOCK_MONOTONIC, which may help you understand why it's named the way it is. I suggested the uses of this clock are for the sequencing of events and for calculating the relative period between them. If you can think of another use please send us a comment. If you like to get hands-on, you may want to try reimplementing the above program in your preferred programming language, or extending it to time arbitrary events.

11 July 2017

Rapha&#235;l Hertzog: Freexian s report about Debian Long Term Support, June 2017

A Debian LTS logoLike each month, here comes a report about the work of paid contributors to Debian LTS. Individual reports In May, about 161 work hours have been dispatched among 11 paid contributors. Their reports are available: Evolution of the situation The number of sponsored hours increased slightly with one new bronze sponsor and another silver sponsor is in the process of joining. The security tracker currently lists 49 packages with a known CVE and the dla-needed.txt file 54. The number of open issues is close to last month. Thanks to our sponsors New sponsors are in bold.

One comment Liked this article? Click here. My blog is Flattr-enabled.

10 July 2017

Kees Cook: security things in Linux v4.12

Previously: v4.11. Here s a quick summary of some of the interesting security things in last week s v4.12 release of the Linux kernel: x86 read-only and fixed-location GDT
With kernel memory base randomization, it was stil possible to figure out the per-cpu base address via the sgdt instruction, since it would reveal the per-cpu GDT location. To solve this, Thomas Garnier moved the GDT to a fixed location. And to solve the risk of an attacker targeting the GDT directly with a kernel bug, he also made it read-only. usercopy consolidation
After hardened usercopy landed, Al Viro decided to take a closer look at all the usercopy routines and then consolidated the per-architecture uaccess code into a single implementation. The per-architecture code was functionally very similar to each other, so it made sense to remove the redundancy. In the process, he uncovered a number of unhandled corner cases in various architectures (that got fixed by the consolidation), and made hardened usercopy available on all remaining architectures. ASLR entropy sysctl on PowerPC
Continuing to expand architecture support for the ASLR entropy sysctl, Michael Ellerman implemented the calculations needed for PowerPC. This lets userspace choose to crank up the entropy used for memory layouts. LSM structures read-only
James Morris used __ro_after_init to make the LSM structures read-only after boot. This removes them as a desirable target for attackers. Since the hooks are called from all kinds of places in the kernel this was a favorite method for attackers to use to hijack execution of the kernel. (A similar target used to be the system call table, but that has long since been made read-only.) KASLR enabled by default on x86
With many distros already enabling KASLR on x86 with CONFIG_RANDOMIZE_BASE and CONFIG_RANDOMIZE_MEMORY, Ingo Molnar felt the feature was mature enough to be enabled by default. Expand stack canary to 64 bits on 64-bit systems
The stack canary values used by CONFIG_CC_STACKPROTECTOR is most powerful on x86 since it is different per task. (Other architectures run with a single canary for all tasks.) While the first canary chosen on x86 (and other architectures) was a full unsigned long, the subsequent canaries chosen per-task for x86 were being truncated to 32-bits. Daniel Micay fixed this so now x86 (and future architectures that gain per-task canary support) have significantly increased entropy for stack-protector. Expanded stack/heap gap
Hugh Dickens, with input from many other folks, improved the kernel s mitigation against having the stack and heap crash into each other. This is a stop-gap measure to help defend against the Stack Clash attacks. Additional hardening needs to come from the compiler to produce stack probes when doing large stack expansions. Any Variable Length Arrays on the stack or alloca() usage needs to have machine code generated to touch each page of memory within those areas to let the kernel know that the stack is expanding, but with single-page granularity. That s it for now; please let me know if I missed anything. The v4.13 merge window is open!

2017, Kees Cook. This work is licensed under a Creative Commons Attribution-ShareAlike 3.0 License.
Creative Commons License

6 July 2017

Thadeu Lima de Souza Cascardo: News on Debian on apexqtmo

I had been using my Samsung Galaxy S Relay 4G for almost three years when I decided to get a new phone. I would use this new phone for daily tasks and take the chance to get a new model for hacking in the future. My apexqtmo would still be my companion and would now be more available for real hacking. And so it also happened that its power button got stuck. It was not the first time, but now it would happen every so often, and would require me to disassemble it. So I managed to remove the plastic button and leave it with a hole so I could press the button with a screwdriver or a paperclip. That was the excuse I needed to get it to running Debian only. Though it's now always plugged on my laptop, I got the chance to hack on it on my scarce free time. As I managed to get a kernel I built myself running on it, I started fixing things like enabling devtmpfs. I didn't insist much on running systemd, though, and kept with System V. The Xorg issues were either on the server or the client, depending on which client I ran. I decided to give a chance to running the Android userspace on a chroot, but gave up after some work to get some firmware loaded. I managed to get the ALSA controls right after saving them inside a chroot on my CyanogenMod system. Then, restoring them on Debian allowed to play songs. Unfortunately, it seems I broke the audio jack when disassembling it. Otherwise, it would have been a great portable audio player. I even wrote a small program that would allow me to control mpd by swiping on the touchscreen. Then, as Debian release approached, I decided to investigate the framebuffer issue closely. I ended finding out that it was really a bug in the driver, and after fixing it, the X server and client crashes were gone. It was beautiful to get some desktop environment running with the right colors, get a calculator started and really using the phone as a mobile device. There are two lessons or findings here for me. The first one is that the current environments are really lacking. Even something like GPE can't work. The buttons are tiny, scrollbars are still the only way for scrolling, some of the time. No automatic virtual keyboards. So, there needs to be some investing in the existing environments, and maybe even the development of new environments for these kinds of devices. This was something I expected somehow, but it's still disappointing to know that we had so much of those developed in the past and now gone. I really miss Maemo. Running something like Qtopia would mean grabing a very old unmaintained software not available in Debian. There is still matchbox, but it's as subpar as the others I tested. The second lesson is that building a userspace to run on old kernels will still hit the problem of broken drivers. In my particular case, unless I wrote code for using Ion instead of the framebuffer, I would have had that problem. Or it would require me to add code to xorg-xserver that is not appropriate. Or fix the kernel drivers of available kernel sourcecodes. But this does not scale much more than doing the right thing and adding upstream support for these devices. So, I decided it was time I started working on upstream support for my device. I have it in progress and may send some upstream patches soon. I have USB and MMC/SDcard working fine. DRM is still a challenge, but thanks to Rob Clark, it's something I expect to get working soon, and after that, I would certainly celebrate. Maybe even consider starting the work on other devices a little sooner. Trying to review my post on GNU on smartphones, here is where I would put some of the status of my device and some extra notes. On Halium I am really glad people started this project. This was one of the things I criticized: that though Ubuntu Phone and FirefoxOS built on Android userspace, they were not easily portable to many devices out there. But as I am looking for a more pure GNU experience, let's call it that, Halium does not help much in that direction. But I'd like to see it flourish and allow people to use more OSes on more devices. Unfortunately, it suffers from similar problems as the strategy I was trying to go with. If you have a device with a very old kernel, you won't be able to run some of the latest userspace, even with Android userspace help. So, lots of devices would be left unsupported, unless we start working on some upstream support. On RYF Hardware My device is one of the worst out there. It's a modem that has a peripherical CPU. Much has already been said about Qualcomm chips being some of the least freedom-friendly. Ironically, it's some with the best upstream support, as far as I found out while doing this upstreaming work. Guess we'll have to wait for opencores, openrisc and risc-v to catch up here. Diversity Though I have been experimenting with Debian, the upstream work would sure benefit lots of other OSes out there, mainly GNU+Linux based ones, but also other non-GNU Linux based ones. Not so much for other kernels. On other options After the demise of Ubuntu Phone, I am glad to see UBports catching up. I hope the project is sustainable and produce more releases for more devices. Rooting This needs documentation. Most of the procedures rely on booting a recovery system, which means we are already past the root requirement. We simply boot our own system, then. However, for some debugging strategies, getting root on the OEM system is useful. So, try to get root on your system, but beware of malware out there. Booting Most of these devices will have their bootloaders in there. They may be unlocked, allowing unsigned kernels to be booted. Replacing these bootloaders is still going to be a challenge for another future phase. Though adding a second bootloader there, one that is freedom respecting, and that allows more control on that booting step to the user is something possible once you have some good upstream support. One could either use kexec for that, or try to use the same device tree for U-Boot, and use the knowledge of the device drivers for Linux on writing drivers for U-Boot, GRUB or Libreboot. Installation If you have root on your OEM system, this is something that could be worked on. Otherwise, there is magic-device-tool, whose approach is one that could be used. Kernels While I am working on adding Linux upstream support for my device, it would be wonderful to see more kernels supporting those gadgets. Hopefully, some of the device driver writing and reverse engineering could help with that, though I am not too much optimistic. But there is hope. Basic kernel drivers Adding the basic support, like USB and MMC, after clocks, gpios, regulators and what not, is the first step to a long road. But it would allow using the device as a board computer, under better control of the user. Hopefully, lots of eletronic garbage out there would have some use as control gadgets. Instead of buying a new board, just grab your old phone and put it to some nice use. Sensors, input devices, LEDs There are usually easy too. Some sensors may depend on your modem or some userspace code that is not that easily reverse engineered. But others would just require some device tree work, or some small input driver. Graphics Here, things may get complicated. Even basic video output is something I have some trouble with. Thanks to some other people's work, I have hope at least for my device. And using the vendor's linux source code, some framebuffer should be possible, even some DRM driver. But OpenGL or other 3D acceleration support requires much more work than that, and, at this moment, it's not something I am counting on. I am thankful for the work lots of people have been doing on this area, nonetheless. Wireless Be it Wifi or Bluetooth, things get ugly here. The vendor driver might be available. Rewriting it would take a long time. Even then, it would most likely require some non-free firmware loading. Using USB OTG here might be an option. Modem/GSM The work of the Replicant folks on that is what gives me some hope that it might be possible to get this working. Something I would leave to after I have a good interface experience in my hands. GPS Problem is similar to the Modem/GSM one, as some code lives in userspace, sometimes talking to the modem is a requirement to get GPS access, etc. Shells This is where I would like to see new projects, even if they work on current software to get them more friendly to these form factors. I consider doing some work there, though that's not really my area of expertise. Next steps For me, my next steps are getting what I have working upstream, keep working on DRM support, packaging GPE, then experimenting with some compositor code. In the middle of that, trying to get some other devices started. But documenting some of my work is something I realized I need to do more often, and this post is some try on that.

5 July 2017

Shirish Agarwal: Debian 9 release party at Co-hive

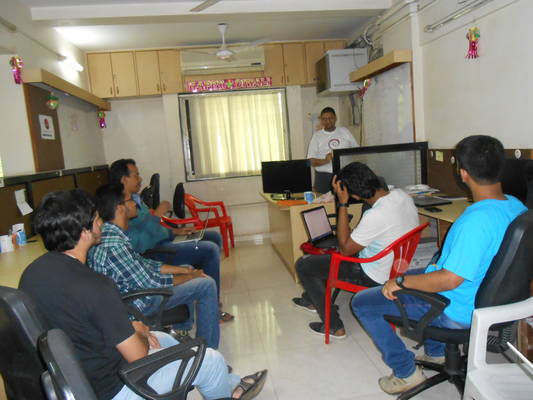
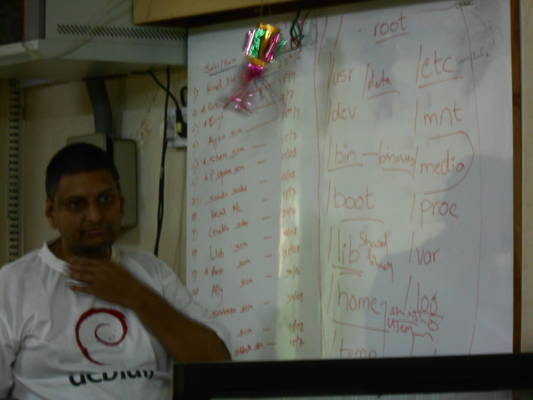
Dear all, This would be a biggish one so please have a chai/coffee or something stronger as it would take a while. I would start with attempt at some alcohol humor. While some people know that I have had a series of convulsive epileptic seizure I had shared bits about it in another post as well. Recovery is going through allopathic medicines as well as physiotherapy which I go to every alternate day. One of the exercises that I do in physiotherapy sessions is walk cross-legged on a line. While doing it today, it occurred to me that this is the same test that a Police inspector would do if they caught you drinking or are suspected of drunk driving. While some in the police force have now also have breath analyzer machines to determine alcohol content in the breath and body (and ways to deceive it are also there) the above exercise is still an integral part of examination. Now few of my friends who do drink have and had made expertise of walking on a line, while I due to this neurological disorder still have issues of walking on a line. So while I don t think of a drinking party in the near future (6 months at least), if I ever do get caught with a friend who is drunk (by association I would also be a suspect) by a policeman who doesn t have a breath analyzer machine, I could be in a lot of trouble. In addition if I tell him I have a neurological disorder I am bound to land up in a cell as he will think I m trying to make a fool of him. If you are able to picturize the situation, I m sure you will get a couple of laughs. Now coming to the release party, I was a bit apprehensive. It s been quite a while I had faced an audience and just coming out of illness didn t know how well or ill-prepared I would be for the session. I had forsaken/given up exercising two days earlier before the event as I wanted to have loose body, loose limbs all over. I also took a mild sedative (1mg) the day before just so I will have a fit night sleep and be able to focus all my energies on the big day. (I don t recommend sedatives unless the doctor prescribes) and I did have a doctor prescription so was able to have a nice sleep. I didn t do any Debian study as I hoped my somewhat long experience with both Ubuntu and Debian should help me. On the d-day, I had asked dhanesh (the organizer of the event) to accompany me from home to venue and back as I was unsure of the journey as it was around 9-10 kms. from my place and while I had been to the venue about couple of years back, I had just a mild remembrance of the place. Anyways, Dhanesh compiled with my request and together we reached the venue before the appointed 1500 hrs. As it was a Sunday I was unsure as how many people would turn up as people usually like to cozy up on a Sunday. Around 1530 hrs everybody showed up The whole group It included couple of co-organizers with most people being newbies so while I had thought of showing how to contribute via reporting bugs or putting up patches, had to set that aside and explain how things work in free software and open-source world. We didn t get into the debate of free vs open-source or free/open-source/open-core as that would have been counter-productive and probably confusing for newbies. We did however share the debian tree structure debian-tree-structure-discussion I was stumped by /var and /proc . I hadn t taken my lappy as it is expensive (a lenovo thinkpad I love very dearly) and I was unsure if I would be able to take care of it (weight wise). Dhanesh had told me that he had Debian on his lappy + zsh both of which are my favourites. While back at home I realized /var has been relegated to having apache/server logs and stuff like that, I do recall (vaguely) a thread on debian-devel about removing /var although that discussion went nowhere. One of the bugs that we hit early on is that nobody had enough space on their hdd to have Debian comfortably. It took a while to get an external hdd and push some of the content from somebody s lappy to the external drive to have space for the installation. I did share the /. /home, optional swap while Dhanesh helped by sharing about having a separate /boot partition as well which I had forgotten. I can t even begin to remember the number of times having a separate /boot partition has helped me in all of my systems. That done, we did try to install/show Debian 9 without network but were hit with #866629 so wasn t able to complete the installation. We had got the latest 9.0.1 as I had seen Steve s message about issues with the live images but even then we were hit with the above bug. As shared in the bug history, it might be a good idea to have the last couple of RC s (Release Candidate releases) as pre-release parties so people have a chance to report bugs and get them fixed. It was also nice to see Praveen raising the seriousness of the bug shared above. The next day I also filed #866971 as I had mistaken the release to be a regular release and not the live instance. I have pushed my rationale and hope the right thing happens. As installation takes a bit of time, we used the time to share about Google s Summer of Code and absence of Debian from GSoC this year. I should have directed them to an itfoss article I wrote sometime ago and also shared that Debian is also looking to having a similar apprenticeship within Debian itself. There were questions about why Debian would like to take the administrative overhead, my response was that it probably had to do with Debian wanting more control over the process. While Debian has had some great luck getting all number of seats that it asks for in GSoC, the ball is always in Google s court. Having that uncertainty off would be beneficial to Debian both in short-term as well as long-term. One interesting stat that was shared with me was that something akin to 89 students from India had been selected this year to GSoC even with the lower stipend and that is a far cry from the 10-15 students who are able to complete GSoC every year. Let s see what happens this year. One of the interesting fact/gossip I shared with them is that Google uses a modified/forked Debian internally which it probably would never release ever. There were quite a few queries about GSoC which resulted into how contributions are made and how git had become the master of all VCS (Version Control Systems). While I do have pet bugs about git (the biggest one being for places/countries having not big bandwidth git fails many a times while cloning). I *think* the bug has been reported enough times but haven t seen any improvements yet. There is a need of a solution like wget and wget -c so git just works even under the most trying circumstances (bandwidth wise) We also shared what a repo is and Dhanesh helpfully did a git shortlog to show people how commits are commented. It was from his official work so he couldn t show anything apart from the shortlog. I also shared how non-technical people can help with regard to documentation, artwork but didn t get into any concrete examples although wiki.debian.org would have been a good start. I also don t know if it s a fact or not but it seems/seemed that moinmoin (the current wiki solution used by debian) seems to have got sectional edit feature which I used sometime back. If moinmoin has got this feature then it is on par with mediawiki, although do know that mediawiki has lot more features going for it. Dhanesh did manage to install a Debian 8.0.7 (while 8.8.0 was the last release) which might have been better. The debian-installer (d-i) looks the same even though I know there are improvements with respect to UEFI and many updated components. There are and were many bugs which I wanted to share but didn t know if it was the right forum or not, for e.g. #597176 which probably needs improvements in other libraries along with the JPEG 2000 support #604859 all of which I m subscribed to. We also had a talk about code documentation and code readability, python (as almost everything in Debian is based on python) I had actually wanted to show metrics.debian.net but had seen it was down the day before and again checked to see it is down now as well, hence reported it, will hopefully come on Debian BTS some time soonish. The idea was to share that Debian does have/uses other programming languages as well and is only limited by people interested in a specific language and be willing to package and maintain packages in that specific programming language. As Dhanesh was part of Firefox OS and a Campus Ambassador we did discuss what went wrong in Firefox OS deployment and Firefox as a whole, specifically between the community and Mozilla the Corporation. In this there were lots that was lot that I wasn t able to share as had become tired otherwise would have shared that ncurses debian-installer interface although bit ugly to look at is still good as it has speech for visually differently abled people as well as people with poor sight. There is and was lots to share about Debian but was conscious that I might over-burden the audience and my stamina was also stretched. We also shared about automated builds bud didn t show either travis.debian.net or jeankins.debian.net We also had a small discussion about Artificial Intelligence, Robotics and how the outlook for people coming in Computer Science looks today. One thing I forgot to share we did do the cake-cutting together Dhanesh-Shirish cutting cake together Dhanesh is on the left while I m on the right. We did have a cute 3-4 year old boy as our guest as well bud didn t get good pictures of him. Lastly, the Debian cake itself Debian 9 cake We also talked about the kernel and subsystem maintainers and how Linus is the overlord. Look forward to comments. I am hoping Dhanesh might recollect some points that I might have missed/forgotten. Update 07/07/17 All programming languages stats. can be seen here
Filed under: Miscellenous Tagged: #alcohol humor, #co-hive, #crystal-gazing, #Debian bugs, #Debian cake, #Debian-release-party-9-pune, #live-installer, #moinmoin, #planet-debian, debian-installer, Pune

Yakking: Open your minds, and your data (formats)

Whether I am writing my own program, or chosing between existing solutions, one aspect of the decision making process which always weighs heavily on my mind is that of the input and output data formats. I have been spending a lot of my work days recently working on converting data from a proprietary tool's export format into another tool's input format. This has involved a lot of XML diving, a lot more swearing, and a non-trivial amount of pain. This drove home to me once more that the format of input and output of data is such a critical part of software tooling that it must weigh as heavily as, or perhaps even more heavily than, the software's functionality. As Tannenbaum tells us, the great thing about standards is that there's so many of them to choose from. XKCD tells us, how that comes about. Data formats are many and varied, and suffer from specifications as vague as "plain text" to things as complex as the structure of data stored in custom database formats. If you find yourself writing software which requires a brand new data format then, while I might caution you to examine carefully if it really does need a new format, you should ensure that you document the format carefully and precisely. Ideally give your format specification to a third party and get them to implement a reader and writer for your format, so that they can check that you've not missed anything. Tests and normative implementations can help prop up such an endeavour admirably. Be sceptical of data formats which have "implementation specific" areas, or "vendor specific extension" space because this is where everyone will put the most important and useful data. Do not put such beasts into your format design. If you worry that you've made your design too limiting, deal with that after you have implemented your use-cases for the data format. Don't be afraid to version the format and extend later; but always ensure that a given version of the data format is well understood; and document what it means to be presented with data in a format version you do not normally process. Phew.
Given all that, I exhort you to consider carefully how your projects manage their input and output data, and for these things to be uppermost when you are choosing between different solutions to a problem at hand. Your homework is, as you may have grown to anticipate at this time, to look at your existing projects and check that their input and output data formats are well documented if appropriate.

3 July 2017

Antoine Beaupr : My free software activities, June 2017

Debian Long Term Support (LTS) This is my monthly Debian LTS report. This time I worked on Mercurial, sudo and Puppet.

Mercurial remote code execution I issued DLA-1005-1 to resolve problems with the hg server --stdio command that could be abused by "remote authenticated users to launch the Python debugger, and consequently execute arbitrary code, by using --debugger as a repository name" (CVE-2017-9462). Backporting the patch was already a little tricky because, as is often the case in our line of work, the code had changed significantly in newer version. In particular, the commandline dispatcher had been refactored which made the patch non-trivial to port. On the other hand, mercurial has an extensive test suite which allowed me to make those patches in all confidence. I also backported a part of the test suite to detect certain failures better and to fix the output so that it matches the backported code. The test suite is slow, however, which meant slow progress when working on this package. I also noticed a strange issue with the test suite: all hardlink operations would fail. Somehow it seems that my new sbuild setup doesn't support doing hardlinks. I ended up building a tarball schroot to build those types of packages, as it seems the issue is related to the use of overlayfs in sbuild. The odd part is my tests of overlayfs, following those instructions, show that it does support hardlinks, so there maybe something fishy here that I misunderstand. This, however, allowed me to get a little more familiar with sbuild and the schroots. I also took this opportunity to optimize the builds by installing an apt-cacher-ng proxy to speed up builds, which will also be useful for regular system updates.

Puppet remote code execution I have issued DLA-1012-1 to resolve a remote code execution attack against puppetmaster servers, from authenticated clients. To quote the advisory: "Versions of Puppet prior to 4.10.1 will deserialize data off the wire (from the agent to the server, in this case) with a attacker-specified format. This could be used to force YAML deserialization in an unsafe manner, which would lead to remote code execution." The fix was non-trivial. Normally, this would have involved fixing the YAML parsing, but this was considered problematic because the ruby libraries themselves were vulnerable and it wasn't clear we could fix the problem completely by fixing YAML parsing. The update I proposed took the bold step of switching all clients to PSON and simply deny YAML parsing from the server. This means all clients need to be updated before the server can be updated, but thankfully, updated clients will run against an older server as well. Thanks to LeLutin at Koumbit for helping in testing patches to solve this issue.

Sudo privilege escalation I have issued DLA-1011-1 to resolve an incomplete fix for a privilege escalation issue (CVE-2017-1000368 from CVE-2017-1000367). The backport was not quite trivial as the code had changed quite a lot since wheezy as well. Whereas mercurial's code was more complex, it's nice to see that sudo's code was actually simpler and more straightforward in newer versions, which is reassuring. I uploaded the packages for testing and uploaded them a year later. I also took extra time to share the patch in the Debian bugtracker, so that people working on the issue in stable may benefit from the backported patch, if needed. One issue that came up during that work is that sudo doesn't have a test suite at all, so it is quite difficult to test changes and make sure they do not break anything.

Should we upload on fridays? I brought up a discussion on the mailing list regarding uploads on fridays. With the sudo and puppet uploads pending, it felt really ... daring to upload both packages, on a friday. Years of sysadmin work hardwired me to be careful on fridays; as the saying goes: "don't deploy on a friday if you don't want to work on the weekend!" Feedback was great, but I was surprised to find that most people are not worried worried about those issues. I have tried to counter some of the arguments that were brought up: I wonder if there could be a disconnection here between the package maintainer / programmer work and the sysadmin work that is at the receiving end of that work. Having myself to deal with broken updates in the past, I'm surprised this has never come up in the discussions yet, or that the response is so underwhelming. So far, I'll try to balance the need for prompt security updates and the need for stable infrastructure. One does not, after all, go without the other...

Triage I also did small fry triage: Hopefully some of those will come to fruitition shortly.

Other work My other work this month was a little all over the place.

Stressant Uploaded a new release (0.4.1) of stressant to split up the documentation from the main package, as the main package was taking up too much space according to grml developers. The release also introduces limited anonymity option, by blocking serial numbers display in the smartctl output.

Debiman Also did some small followup on the debiman project to fix the FAQ links.

Local server maintenance I upgraded my main server to Debian stretch. This generally went well, althought the upgrade itself took way more time than I would have liked (4 hours!). This is partly because I have a lot of cruft installed on the server, but also because of what I consider to be issues in the automation of major Debian upgrades. For example, I was prompted for changes in configuration files at seemingly random moments during the upgrade, and got different debconf prompts to answer. This should really be batched together, and unfortunately I had forgotten to use the home-made script I established when i was working at Koumbit which shortens the upgrade a bit. I wish we would improve on our major upgrade mechanism. I documented possible solutions for this in the AutomatedUpgrade wiki page, but I'm not sure I see exactly where to go from here. I had a few regressions after the upgrade:
  • the infrared remote control stopped working: still need to investigate
  • my home-grown full-disk encryption remote unlocking script broke, but upstream has a nice workaround, see Debian bug #866786
  • gdm3 breaks bluetooth support (Debian bug #805414 - to be fair, this is not a regression in stretch, it's just that I switched my workstation from lightdm to gdm3 after learning that the latter can do rootless X11!)

Docker and Subsonic I did my first (and late?) foray into Docker and containers. My rationale was that I wanted to try out Subsonic, an impressive audio server which some friends have shown me. Since Subsonic is proprietary, I didn't want it to contaminate the rest of my server and it seemed like a great occasion to try out containers to keep things tidy. Containers may also allow me to transparently switch to the FLOSS fork LibreSonic once the trial period is over. I have learned a lot and may write more about the details of that experience soon, for now you can look at the contributions I made to the unofficial Subsonic docker image, but also the LibreSonic one. Since Subsonic also promotes album covers as first-class citizens, I used beets to download a lot of album covers, which was really nice. I look forward to using beets more, but first I'll need to implement two plugins.

Wallabako I did a small release of wallabako to fix the build with the latest changes in the underlying wallabago library, which led me to ask upstream to make versionned releases. I also looked into creating a separate documentation site but it looks like mkdocs doesn't like me very much: the table of contents is really ugly...

Small fry That's about it! And that was supposed to be a slow month...

Vincent Bernat: Performance progression of IPv4 route lookup on Linux

TL;DR: Each of Linux 2.6.39, 3.6 and 4.0 brings notable performance improvements for the IPv4 route lookup process.
In a previous article, I explained how Linux implements an IPv4 routing table with compressed tries to offer excellent lookup times. The following graph shows the performance progression of Linux through history: IPv4 route lookup performance Two scenarios are tested: All kernels are compiled with GCC 4.9 (from Debian Jessie). This version is able to compile older kernels1 as well as current ones. The kernel configuration used is the default one with CONFIG_SMP and CONFIG_IP_MULTIPLE_TABLES options enabled (however, no IP rules are used). Some other unrelated options are enabled to be able to boot them in a virtual machine and run the benchmark. The measurements are done in a virtual machine with one vCPU2. The host is an Intel Core i5-4670K and the CPU governor was set to performance . The benchmark is single-threaded. Implemented as a kernel module, it calls fib_lookup() with various destinations in 100,000 timed iterations and keeps the median. Timings of individual runs are computed from the TSC (and converted to nanoseconds by assuming a constant clock). The following kernel versions bring a notable performance improvement:

  1. Compiling old kernels with an updated userland may still require some small patches.
  2. The kernels are compiled with the CONFIG_SMP option to use the hierarchical RCU and activate more of the same code paths as actual routers. However, progress on parallelism are left unnoticed.

2 July 2017

Ritesh Raj Sarraf: apt-offline 1.8.1 released

apt-offline 1.8.1 released. This is a bug fix release fixing some python3 glitches related to module imports. Recommended for all users. apt-offline (1.8.1) unstable; urgency=medium * Switch setuptools to invoke py3
* No more argparse needed on py3
* Fix genui.sh based on comments from pyqt mailing list
* Bump version number to 1.8.1 -- Ritesh Raj Sarraf <rrs@debian.org> Sat, 01 Jul 2017 21:39:24 +0545
What is apt-offline
Description: offline APT package manager
 apt-offline is an Offline APT Package Manager.
 .
 apt-offline can fully update and upgrade an APT based distribution without
 connecting to the network, all of it transparent to APT.
 .
 apt-offline can be used to generate a signature on a machine (with no network).
 This signature contains all download information required for the APT database
 system. This signature file can be used on another machine connected to the
 internet (which need not be a Debian box and can even be running windows) to
 download the updates.
 The downloaded data will contain all updates in a format understood by APT and
 this data can be used by apt-offline to update the non-networked machine.
 .
 apt-offline can also fetch bug reports and make them available offline.

Categories:

Keywords:

Like:

1 July 2017

Russ Allbery: Review: Make It Stick

Review: Make It Stick, by Peter C. Brown, et al.
Author: Peter C. Brown
Author: Henry L. Roediger III
Author: Mark A. McDaniel
Publisher: Belknap Press
Copyright: 2014
ISBN: 0-674-72901-3
Format: Kindle
Pages: 255
Another read for the work book club. "People generally are going about learning in the wrong ways." This is the first sentence of the preface of this book by two scientists (Roediger and McDaniel are both psychology researchers specializing in memory) and a novelist and former management consultant (Brown). The goal of Make It Stick is to apply empirical scientific research to the problem of learning, specifically retention of information for long-term use. The authors aim to convince the reader that subjective impressions of the effectiveness of study habits are highly deceptive, and that scientific evidence points strongly towards mildly counter-intuitive learning methods that don't feel like they're producing as good of results. I have such profound mixed feelings about this book. Let's start with the good. Make It Stick is a book containing actual science. The authors quote the studies, results, and scientific argument at length. There are copious footnotes and an index, as well as recommended reading. And the science is concrete and believable, as is the overlaid interpretation based on cognitive and memory research. The book's primary argument is that short-term and long-term memory are very different things, that what we're trying to achieve when we say "learning" is based heavily on long-term memory and recall of facts for an extended time after study, and that building this type of recall requires not letting our short-term memory do all the work. We tend towards study patterns that show obvious short-term improvement and that produce an increased feeling of effortless recall of the material, but those study patterns are training short-term memory and mean the knowledge slips away quickly. Choosing learning methods that instead make us struggle a little with what we're learning are significantly better. It's that struggle that leads to committing the material to long-term memory and building good recall pathways for it. On top of this convincingly-presented foundation, the authors walk through learning methods that feel worse in the moment but have better long-term effects: mixing practice of different related things (different types of solids when doing geometry problems, different pitches in batting practice) and switching types before you've mastered the one you're working on, forcing yourself to interpret and analyze material (such as writing a few paragraphs of summary in your own words) instead of re-reading it, and practicing material at spaced intervals far enough apart that you've forgotten some of the material and have to struggle to recall it. Possibly the most useful insight here (at least for me) was the role of testing in learning, not as just a way of measuring progress, but as a learning tool. Frequent, spaced, cumulative testing forces exactly the type of recall that builds long-term memory. The tests themselves help improve our retention of what we're learning. It's bad news for people like me who were delighted to leave school and not have to take a test again, but viewing tests as a more effective learning tool than re-reading and review (which they are) does cast them in a far more positive light. This is all solid stuff, and I'm very glad the research underlying this book exists and that I now know about it. But there are some significant problems with its presentation. The first is that there just isn't much here. The two long paragraphs above summarize nearly all of the useful content of this book. The authors certainly provide more elaboration, and I haven't talked about all of the study methods they mention or some of the useful examples of their application. But 80% of it is there, and the book is intentionally repetitive (because it tries to follow the authors' advice on learning theory). Make It Stick therefore becomes tedious and boring, particularly in the first four chapters. I was saying a lot of "yes, yes, you said that already" and falling asleep while trying to read it. The summaries at the end of the book are a bit better, but you will probably not need most of this book to get the core ideas. And then there's chapter five, which ends in a train wreck. Chapter five is on cognitive biases, and I see why the authors wanted to include it. The Dunning-Kruger effect is directly relevant to their topic. It undermines our ability to learn, and is yet another thing that testing helps avoid. Their discussion of Daniel Kahneman's two system theory (your fast, automatic, subconscious reactions and your slow, thoughtful, conscious processing) is somewhat less directly relevant, but it's interesting stuff, and it's at least somewhat related to the short-term and long-term memory dichotomy. But some of the stories they choose to use to illustrate this are... deeply unfortunate. Specifically, the authors decided to use US police work in multiple places as their example of choice for two-system thinking, and treat it completely uncritically. Some of you are probably already wincing because you can see where this is going. They interview a cop who, during scenario training for traffic stops, was surprised by the car trunk popping open and a man armed with a shotgun popping out of it. To this day, he still presses down on the trunk of the car as he walks up; it's become part of his checklist for every traffic stop. This would be a good example if the authors realized how badly his training has failed and deconstructed it, but they're apparently oblivious. I wanted to reach into the book and shake them. People have a limited number of things they can track and follow as part of a procedure, and some bad trainer has completely wasted part of this cop's attention in every traffic stop and thereby made him less safe! Just calculate the chances that someone would be curled up in an unlocked trunk with a shotgun and a cop would just happen to stop that car for some random reason, compared to any other threat the cop could use that same attention to watch for. This is exactly the type of scenario that's highly memorable but extremely improbable and therefore badly breaks human risk analysis. It's what Bruce Schneier calls a movie plot threat. The correct reaction to movie plot threats is to ignore them; wasting effort on mitigating them means not having that effort to spend on mitigating some other less memorable but more likely threat. This isn't the worst, though. The worst is the very next paragraph, also from police training, of showing up at a domestic call, seeing an armed person on the porch who stands up and walks away when ordered to drop their weapon, and not being sure how to react, resulting in that person (in the simulated exercise) killing the cop before they did anything. The authors actually use this as an example of how the cop was using system two and needed to train to use system one in that situation to react faster, and that this is part of the point of the training. Those of us who have been paying attention to the real world know what using system one here means: the person on the porch gets shot if they're black and doesn't get shot if they're white. The authors studiously refuse to even hint at this problem. I would have been perfectly happy if this book avoided the unconscious bias aspect of system one thinking. It's a bit far afield of the point of the book, and the authors are doubtless trying to stay apolitical. But that's why you pick some other example. You cannot just drop this kind of thing on the page and then refuse to even comment on it! It's like writing a chapter about the effect of mass transit on economic development, choosing Atlanta as one of your case studies, and then never mentioning race. Also, some editor seriously should have taken an ax to the sentence where the authors (for no justified reason) elaborate a story to describe a cop maiming a person, solely to make a cliched joke about how masculinity is defined by testicles and how people who lose body parts are less human. Thanks, book. This was bad enough that it dominated my memory of this chapter, but, reviewing the book for this review, I see it was just a few badly chosen examples at the end of the chapter and one pointless story at the start. The rest of the chapter is okay, although it largely summarizes things covered better in other books. The most useful part that's relevant to the topic of the book is probably the discussion of peer instruction. Just skip over all the police bits; you won't be missing anything. Thankfully, the rest of the book mostly avoids failing quite this hard. Chapter six does open with the authors obliviously falling for a string of textbook examples of survivorship bias (immediately after the chapter on cognitive biases!), but they shortly thereafter settle down to the accurate and satisfying work of critiquing theories of learning methods and types of intelligence. And by critiquing, I mean pointing out that they're mostly unscientific bullshit, which is fighting the good fight as far as I'm concerned. So, mixed feelings. The science seems solid, and is practical and directly applicable to my life. Make It Stick does an okay job at presenting it, but gets tedious and boring in places, particularly near the beginning. And there are a few train-wreck examples that had me yelling at the book and scribbling notes, which wasn't really the cure for boredom I was looking for. I recommend being aware of this research, and I'm glad the authors wrote this book, but I can't really recommend the book itself as a reading experience. Rating: 6 out of 10

Paul Wise: FLOSS Activities June 2017

Changes

Issues

Review

Administration
  • Debian: redirect 2 users to support channels, redirect 1 person to the mirrors team, investigate SMTP TLS question, fix ACL issue, restart dead exim4 service
  • Debian mentors: service restarts, security updates & reboot
  • Debian QA: deploy my changes
  • Debian website: release related rebuilds, rebuild installation-guide
  • Debian wiki: whitelist several email addresses, whitelist 1 domain
  • Debian package tracker: deploy my changes
  • Debian derivatives census: deploy my changes
  • Openmoko: security updates & reboots.

Communication

Sponsors All work was done on a volunteer basis.

30 June 2017

Chris Lamb: Free software activities in June 2017

Here is my monthly update covering what I have been doing in the free software world (previous month):
Reproducible builds

Whilst anyone can inspect the source code of free software for malicious flaws, most software is distributed pre-compiled to end users. The motivation behind the Reproducible Builds effort is to allow verification that no flaws have been introduced either maliciously or accidentally during this compilation process by promising identical results are always generated from a given source. Multiple third-parties then can come to a consensus on whether a build was compromised or not. I have generously been awarded a grant from the Core Infrastructure Initiative to fund my work in this area. This month I:
  • Chaired our monthly IRC meeting. (Summary, logs, etc.)
  • Presented at Hong Kong Open Source Conference 2017.
  • Presented at LinuxCon China.
  • Submitted the following patches to fix reproducibility-related toolchain issues within Debian:
    • cracklib2: Ensuring /var/cache/cracklib/src-dicts are reproducible. (#865623)
    • fontconfig: Ensuring the cache files are reproducible. (#864082)
    • nfstrace: Make the PDF footers reproducible. (#865751)
  • Submitted 6 patches to fix specific reproducibility issues in cd-hit, janus, qmidinet, singularity-container, tigervnc & xabacus.
  • Submitted a wishlist request to the TeX mailing list to ensure that PDF files are reproducible even if generated from a difficult path after identifying underlying cause. (Thread)
  • Categorised a large number of packages and issues in the Reproducible Builds notes.git repository.
  • Worked on publishing our weekly reports. (#110, #111, #112 & #113)
  • Updated our website with 13 missing talks (e291180), updated the metadata for some existing talks (650a201) and added OpenEmbedded to the projects page (12dfcf0).

I also made the following changes to our tooling:
diffoscope

diffoscope is our in-depth and content-aware diff utility that can locate and diagnose reproducibility issues.


strip-nondeterminism

strip-nondeterminism is our tool to remove specific non-deterministic results from a completed build.

  • Add libarchive-cpio-perl with the !nocheck build profile. (01e408e)
  • Add dpkg-dev dependency build profile. (f998bbe)


Debian My activities as the current Debian Project Leader are covered in my "Bits from the DPL" email to the debian-devel-announce mailing list. However, I:
Debian LTS

This month I have been paid to work 16 hours hours on Debian Long Term Support (LTS). In that time I did the following:
  • "Frontdesk" duties, triaging CVEs, etc.
  • Issued DLA 974-1 fixing a command injection vulnerability in picocom, a dumb-terminal emulation program.
  • Issued DLA 972-1 which patches a double-free vulnerability in the openldap LDAP server.
  • Issued DLA 976-1 which corrects a buffer over-read vulnerability in the yodl ("Your Own Document Language") document processor.
  • Issued DLA 985-1 to address a vulnerability in libsndfile (a library for reading/writing audio files) where a specially-crafted AIFF file could result in an out-of-bounds memory read.
  • Issued DLA 990-1 to fix an infinite loop vulnerability in the expat, an XML parsing library.
  • Issued DLA 999-1 for the openvpn VPN server if clients used a HTTP proxy with NTLM authentication, a man-in-the-middle attacker could cause the client to crash or disclose stack memory that was likely to contain the proxy password.

Uploads
  • bfs (1.0.2-1) New upstream release, add basic/smoke autopkgtests.
  • installation-birthday (5) Add some basic autopkgtest smoke tests and correct the Vcs- Git,Browser headers.
  • python-django:
    • 1:1.11.2-1 New upstream minor release & backport an upstream patch to prevent a test failure if the source is not writable. (#816435)
    • 1:1.11.2-2 Upload to unstable, use !nocheck profile for build dependencies that are only required for tests and various packaging updates.

I also made the following non-maintainer uploads (NMUs):
  • kluppe (0.6.20-1.1) Fix segmentation fault caused by passing a truncated pointer instead of a GtkType. (#863421)
  • porg (2:0.10-1.1) Fix broken LD_PRELOAD path for libporg-log.so. (#863495)
  • ganeti-instance-debootstrap (0.16-2.1) Fix "illegal option for fgrep" error by using "--" to escape the search needle. (#864025)
  • pavuk (0.9.35-6.1) Fix segmentation fault when opening the "Limitations" window due to pointer truncation in src/gtkmulticol.[ch]. (#863492)
  • timemachine (0.3.3-2.1) Fix two segmentation faults in src/gtkmeter.c and gtkmeterscale.c caused by passing a truncated pointers using guint instead of a GtkType. (#863420)
  • jackeq (0.5.9-2.1) Fix another segmentation fault caused by passing a truncated pointer instead of a GtkType. (#863416)

Debian bugs filed
  • debhelper: Don't run dh_installdocs if nodoc is specified in DEB_BUILD_PROFILES? (#865869)
  • python-blessed: Non-determistically FTBFS due to unreliable timing in tests. (#864337)
  • apt: Please print a better error message if zero certificates are loaded from the system CA store. (#866377)

28 June 2017

Steve Kemp: Yet more linux security module craziness ..

I've recently been looking at linux security modules. My first two experiments helped me learn:
My First module - whitelist_lsm.c
This looked for the presence of an xattr, and if present allowed execution of binaries. I learned about the Kernel build-system, and how to write a simple LSM.
My second module - hashcheck_lsm.c
This looked for the presence of a "known-good" SHA1 hash xattr, and if it matched the actual hash of the file on-disk allowed execution. I learned how to hash the contents of a file, from kernel-space.
Both allowed me to learn things, but both were a little pointless. They were not fine-grained enough to allow different things to be done by different users. (i.e. If you allowed "alice" to run "wget" you'd also allow www-data to do the same.) So, assuming you wanted to do your security job more neatly what would you want? You'd want to allow/deny execution of commands based upon: So your local users could run "bad" commands, but "www-data" (post-compromise) couldn't. Obviously you don't want to have to recompile your kernel to change the rules of who can execute what. So you think to yourself "I'll write those rules down in a file". But of course reading a file from kernel-space is tricky. And parsing any list of rules, in a file, from kernel-space would prone to buffer-related problems. So I had a crazy idea: Calling userspace? Every time a command is to be executed? Crazy. But it just might work. One problem I had with this approach is that userspace might not even be available, when you're booting. So I setup a flag to enable this stuff:
# echo 1 >/proc/sys/kernel/can-exec/enabled
Now the kernel will invoke the following on every command:
/sbin/can-exec $UID $PATH
Because the kernel waits for this command to complete - as it reads the exit-code - you cannot execute any child-processes from it as you'd end up in recursive hell, but you can certainly read files, write to syslog, etc. My initial implementionation was as basic as this:
int main( int argc, char *argv[] )
 
...
  // Get the UID + Program
  int uid = atoi( argv[1] );
  char *prg = argv[2];
  // syslog
  openlog ("can-exec", LOG_CONS   LOG_PID   LOG_NDELAY, LOG_LOCAL1);
  syslog (LOG_NOTICE, "UID:%d CMD:%s", uid, prg );
  // root can do all.
  if ( uid == 0 )
    return 0;
  // nobody
  if ( uid == 65534 )  
    if ( ( strcmp( prg , "/bin/sh" ) == 0 )  
         ( strcmp( prg , "/usr/bin/id" ) == 0 ) )  
      fprintf(stderr, "Allowing 'nobody' access to shell/id\n" );
      return 0;
     
   
  fprintf(stderr, "Denied\n" );
  return -1;
 
Although the UIDs are hard-code it actually worked! Yay! I updated the code to convert the UID to a username, then check executables via the file /etc/can-exec/$USERNAME.conf, and this also worked. I don't expect anybody to actually use this code, but I do think I've reached a point where I can pretend I've written a useful (or non-pointless) LSM at last. That means I can stop.

Next.

Previous.




