Search Results: "reg"

16 March 2017

Joey Hess: end of an era

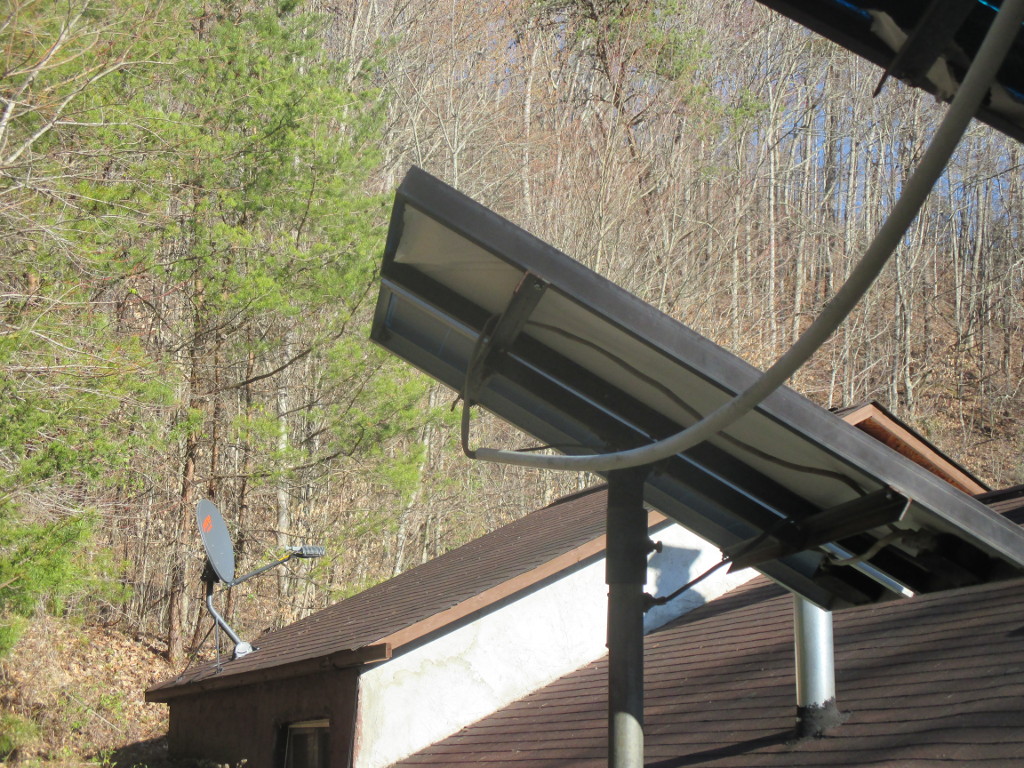
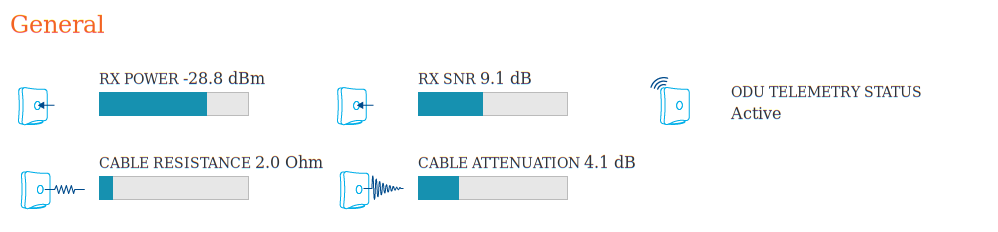
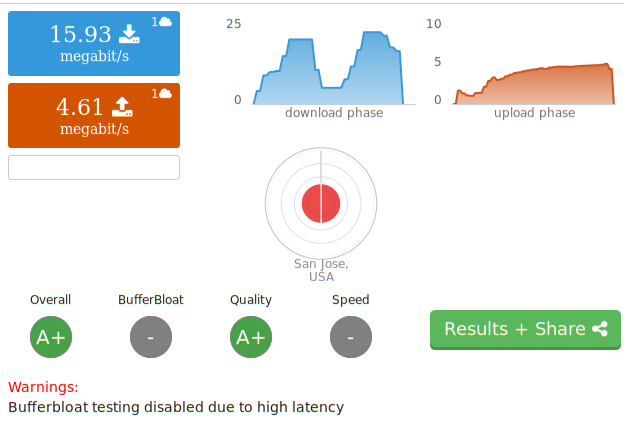
I'm at home downloading hundreds of megabytes of stuff. This is the first time I've been in position of "at home" + "reasonably fast internet" since I moved here in 2012. It's weird! Satellite internet dish with solar panels in foreground While I was renting here, I didn't mind dialup much. In a way it helps to focus the mind and build interesting stuff. But since I bought the house, the prospect of only dialup at home ongoing became more painful. While I hope to get on the fiber line that's only a few miles away eventually, I have not convinced that ISP to build out to me yet. Not enough neighbors. So, satellite internet for now. 9.1 dB SNR speedtest results: 15 megabit down / 4.5 up with significant variation Dish seems well aligned, speed varies a lot, but is easily hundreds of times faster than dialup. Latency is 2x dialup. The equipment uses more power than my laptop, so with the current solar panels, I anticipate using it only 6-9 months of the year. So I may be back to dialup most days come winter, until I get around to adding more PV capacity. It seems very cool that my house can capture sunlight and use it to beam signals 20 thousand miles into space. Who knows, perhaps there will even be running water one day. Satellite dish

15 March 2017

Dirk Eddelbuettel: RcppEigen 0.3.2.9.1

A new maintenance release 0.3.2.9.1 of RcppEigen, still based on Eigen 3.2.9 is now on CRAN and is now going into Debian soon. This update ensures that RcppEigen and the Matrix package agree on their #define statements for the CholMod / SuiteSparse library. Thanks to Martin Maechler for the pull request. I also added a file src/init.c as now suggested (soon: requested) by the R CMD check package validation. The complete NEWS file entry follows.

Changes in RcppEigen version 0.3.2.9.1 (2017-03-14)
  • Synchronize CholMod header file with Matrix package to ensure binary compatibility on all platforms (Martin Maechler in #42)
  • Added file init.c with calls to R_registerRoutines() and R_useDynamicSymbols(); also use .registration=TRUE in useDynLib in NAMESPACE

Courtesy of CRANberries, there is also a diffstat report for the most recent release.

This post by Dirk Eddelbuettel originated on his Thinking inside the box blog. Please report excessive re-aggregation in third-party for-profit settings.

Michal Čihař: Life of free software project

During last week I've noticed several interesting posts about challenges being free software maintainer. After being active in open source for 16 years I can share much of the feelings I've read and I can also share my dealings with the things. First of all let me link some of the other posts on the topic: I guess everybody involved in in some popular free software project knows it - there is much more work to be done than people behind the project can handle. It really doesn't matter it those are bug reports, support requests, new features or technical debt, it's simply too much of that. If you are the only one behind the project it can feel even more pressing. There can be several approaches how to deal with that, but you have to choose what you prefer and what is going to work for you and your project. I've used all of the below mentioned approaches on some of the projects, but I don't think there is a silver bullet. Finding more people Obviously if you can not cope with the work, let's find more people to do the work. Unfortunately it's not that easy. Sometimes people come by, contribute few patches, but it's not that easy to turn them into regular contributor. You should encourage them to stay and to care about the part of the project they have touched. You can try to attract completely new contributors through programs as Google Summer of Code (GSoC) or Outreachy, but that has it's own challenges as well. With phpMyAdmin we're participating regularly in GSoC (we've only missed last year as we were not chosen by Google that year) and it indeed helps to bring new people on the board. Many of them even stay around your project (currently 3 of 5 phpMyAdmin team members are former GSoC students). But I think this approach really works only for bigger organizations. You can also motivate people by money. It's way which is not really much used on free software projects, partly because lack of funding (I'll get to that later) and partly because it doesn't necessarily bring long time contributors, just cash hunters. I've been using Bountysource for some of my projects (Weblate and Gammu) and so far it mostly works other way around - if somebody posts bounty on the issue, it means it's quite important for him to get that fixed, so I use that as indication for myself. On attracting new developers it never really worked well, even when I've tried to post bounties to some easy to fix issues, where newbies could learn our code base and get paid for that. These issues stayed opened for months and in the end I've fixed them myself because they annoyed me. Don't care too much I think this is most important aspect - you simply can never fix all the problems. Let's face it and work according to that. There can be various levels of don't caring. I find it always better to try to encourage people to fix their problem, but you can't expect big success rate in that, so you might find it not worth of the time. What I currently do: If you still can't handle that, you should consider abandoning the project as well. Does it bring something to you other than frustration of not completed work? I know it can be hard decision, in the end it is your child, but sometimes it's the best think you can do. Get paid to do the work Are you doing your fulltime job and then work on free software on nights or weekends? It can probably work for some time, but unless you find some way to make these two match, you will lack free time to relax and spend with friends or family. There are several options to make these work together. You can find job where doing free software will be natural part of it. This worked for me pretty well at SUSE, but I'm sure there are more companies where it will work. It can happen that the job will not cover all your free software activities, but this still helps. You can also make your project to become your employer. This can be sometimes challenging to make volunteers and paid contractors to work on one project, but I think this can be handled. Such setup currently works currently quite well for phpMyAdmin (we will announce second contractor soon) and works quite well for me with Weblate as well. Funding free software projects Once your project is well funded, you can fix many problems by money. You can pay yourself to do the work, hire additional developers, get better infrastructure or travel to conferences to spread word about it. But the question is how to get to the point of being well funded. There are several crowdfunding platforms which can help you with that (Liberapay, Bountysource salt, Gratipay or Snowdrift to mention some). You can also administer the funding yourself or using some legal entity such as Software Freedom Conservancy which handles this for phpMyAdmin. But the most important thing is to persuade people and companies to give back. You know there are lot of companies relying on your project, but how to make them fund the project? I really don't know, I still struggle with this as I don't want to be too pushy in asking for money, but I'd really like to see them to give back. What kind of works is giving your sponsors logo / link placement on your website. If your website is well ranked, you can expect to get quite a lot of SEO sponsors and the question is where to draw a line what you still find acceptable. Obviously the most willing to pay companies will have nothing to do with what you do and they just want to get the link. The industry you can expect is porn, gambling, binary options and various MFA sites. You will get some legitimate sponsors related to your project as well. We felt we've gone too far with phpMyAdmin last year and we've stricten the rules recently, but the outcome is still not visible on our website (as we've just limited new sponsors, but existing contracts will be honored). Another option is to monetize your project more directly. You can offer consulting services or provide it as a service (this is what I currently do with Weblate). It really depends on the product if you can build customer base on that or not, but certainly this is not something what would work well for all projects. Thanks for reading this and I hope it's not too chaotic, as I've moved parts there and back while writing and I'm afraid it got too long in the end.

Filed under: Debian English Gammu phpMyAdmin SUSE Weblate 0 comments

13 March 2017

Sean Whitton: Initial views of 5th edition DnD

I ve been playing in a 5e campaign for around two months now. In the past ten days or so I ve been reading various source books and Internet threads regarding the design of 5th edition. I d like to draw some comparisons and contrasts between 5th edition, and the 3rd edition family of games (DnD 3.5e and Paizo s Pathfinder, which may be thought of as 3.75e). The first thing I d like to discuss is that wizards and clerics are no longer Vancian spellcasters. In rules terms, this is the idea that individual spells are pieces of ammunition. Spellcasters have a list of individual spells stored in their heads, and as they cast spells from that list, they cross off each item. Barring special rules about spontaneously converting prepared spells to healing spells, for clerics, the only way to add items back to the list is to take a night s rest. Contrast this with spending points from a pool of energy in order to use an ability to cast a fireball. Then the limiting factor on using spells is having enough points in your mana pool, not having further castings of the spell waiting in memory. One of the design goals of 5th edition was to reduce the dominance of spellcasters at higher levels of play. The article to which I linked in the previous paragraph argues that this rebalancing requires the removal of Vancian magic. The idea, to the extent that I ve understood it, is that Vancian magic is not an effective restriction on spellcaster power levels, so it is to be replaced with other restrictions adding new restrictions while retaining the restrictions inherent in Vancian magic would leave spellcasters crippled. A further reason for removing Vancian magic was to defeat the so-called five minute adventuring day . The compat ability of a party that contains higher level Vancian spellcasters drops significantly once they ve fired off their most powerful combat spells. So adventuring groups would find themselves getting into a fight, and then immediately retreating to fully rest up in order to get their spells back. This removes interesting strategic and roleplaying possibilities involving the careful allocation of resources, and continuing to fight as hit points run low. There are some other related changes. Spell components are no longer used up when casting a spell. So you can use one piece of bat guano for every fireball your character ever casts, instead of each casting requiring a new piece. Correspondingly, you can use a spell focus, such as a cool wand, instead of a pouch full of material components since the pouch never runs out, there s no mechanical change if a wizard uses an arcane focus instead. 0th level spells may now be cast at will (although Pathfinder had this too). And there are decent 0th level attack spells, so a spellcaster need not carry a crossbow or shortbow in order to have something to do on rounds when it would not be optimal to fire off one of their precious spells. I am very much in favour of these design goals. The five minute adventuring day gets old fast, and I want it to be possible for the party to rely on the cool abilities of non-spellcasters to deal with the challenges they face. However, I am concerned about the flavour changes that result from the removal of Vancian magic. These affect wizards and clerics differently, so I ll take each case in turn. Firstly, consider wizards. In third edition, a wizard had to prepare and cast Read Magic (the only spell they could prepare without a spellbook), and then set about working through their spellbook. This involved casting the spells they wanted to prepare, up until the last few triggering words or gestures that would cause the effect of the spell to manifest. They would commit these final parts of the spell to memory. When it came to casting the spell, the wizard would say the final few words and make the required gestures, and bring out relevant material components from their component pouch. The completed spell would be ripped out of their mind, to manifest its effect in the world. We see that the casting of a spell is a highly mentally-draining activity it rips the spell out of the caster s memory! not to be undertaken lightly. Thus it is natural that a wizard would learn to use a crossbow for basic damage-dealing. Magic is not something that comes very naturally to the wizard, to be deployed in combat as readily as the fighter swings their sword. They are not a superhero or video game character, pew pew ing their way to victory. This is a very cool starting point upon which to roleplay an academic spellcaster, not really available outside of tabletop games. I see it as a distinction between magical abilities and real magic. Secondly, consider clerics. Most of the remarks in the previous paragraph apply, suitably reworked to be in terms of requesting certain abilities from the deity to whom the cleric is devoted. Additionally, there is the downgrading of the importance of the cleric s healing magic in 5th edition. Characters can heal themselves by taking short and long rests. Previously, natural healing was very slow, so a cleric would need to convert all their remaining magic to healing spells at the end of the day, and hope that it was enough to bring the party up to fighting shape. Again, this made the party of adventurers seem less like superheroes or video game characters. Magic had a special, important and unique role, that couldn t be replaced by the abilities of other classes.
There are some rules in the back of the DMG Slow Natural Healing , Healing Kit Dependency , Lingering Wounds which can be used to make healing magic more important. I m not sure how well they would work without changes to the cleric class.
I would like to find ways to restore the feel and flavour of Vancian clerics and wizards to 5th edition, without sacrificing the improvements that have been made that let other party members do cool stuff too. I hope it is possible to keep magic cool and unique without making it dominate the game. It would be easy to forbid the use of arcane foci, and say that material component pouches run out if the party do not visit a suitable marketplace often enough. This would not have a significant mechanical effect, and could enhance roleplaying possibilities. I am not sure how I could deal with the other issues I ve discussed without breaking the game. The second thing I would like to discuss is bounded accuracy. Under this design principle, the modifiers to dice rolls grow much more slowly. The gain of hit points remains unbounded. Under third edition, it was mechanically impossible for a low-level monster to land a hit on a higher-level adventurer, rendering them totally useless even in overwhelming numbers. With bounded accuracy, it s always possible for a low-level monster to hit a PC, even if they do insigificant damage. That means that multiple low-level monsters pose a threat. This change opens up many roleplaying opportunities by keeping low-level character abilities relevant, as well as monster types that can remain involves in stories without giving them implausible new abilities so they don t fall far behind the PCs. However, I m a little worried that it might make high level player characters feel a lot less powerful to play. I want to cease a be a fragile adventurer and become a world-changing hero at later levels, rather than forever remain vulnerable to the things that I was vulnerable to at the start of the game. This desire might just be the result of the video games which I played growing up. In the JRPGs I played and in Diablo II, enemies in earlier areas of the map were no threat at all once you d levelled up by conquering higher-level areas. My concerns about bounded accuracy might just be that it clashes with my own expectations of how fantasy heroes work. A good DM might be able to avoid these worries entirely. The final thing I d like to discuss is the various simplifications to the rules of 5th edition, when it is compared with 3rd edition and Pathfinder. Attacks of opportunity are only provoked when leaving a threatened square; you can go ahead and cast a spell when in melee with someone. There is a very short list of skills, and party members are much closer to each other in skills, now that you can t pump more and more ranks into one or two abilities. Feats as a whole are an optional rule. At first I was worried about these simplifications. I thought that they might make character building and tactics in combat a lot less fun. However, I am now broadly in favour of all of these changes, for two reasons. Firstly, they make the game so much more accessible, and make it far more viable to play without relying on a computer program to fill in the boxes on your character sheet. In my 5th edition group, two of us have played 3rd edition games, and the other four have never played any tabletop games before. But nobody has any problems figuring out their modifiers because it is always simply your ability bonus or penalty, plus your proficiency bonus if relevant. And advantage and disadvantage is so much more fun than getting an additional plus or minus two. Secondly, these simplifications downplay the importance of the maths, which means it is far less likely to be broken. It is easier to ensure that a smaller core of rules is balanced than it is to keep in check a larger mass of rules, constantly being supplemented by more and more addon books containing more and more feats and prestige classes. That means that players make their characters cool by roleplaying them in interesting ways, not making them cool by coming up with ability combos and synergies in advance of actually sitting down to play. Similarly, DMs can focus on flavouring monsters, rather than writing up longer stat blocks. I think that this last point reflects what I find most worthwhile about tabletop RPGs. I like characters to encounter cool NPCs and cool situations, and then react in cool ways. I don t care that much about character creation. (I used to care more about this, but I think it was mainly because of interesting options for magic items, which hasn t gone away.) The most important thing is exercising group creativity while actually playing the game, rather than players and DMs having to spend a lot of time preparing the maths in advance of playing. Fifth edition enables this by preventing the rules from getting in the way, because they re broken or overly complex. I think this is why I love Exalted: stunting is vital, and there is social combat. I hope to be able to work out a way to restore Vancian magic, but even without that, on balance, fifth edition seems like a better way to do group storytelling about fantasy heroes. Hopefully I will have an opportunity to DM a 5th edition campaign. I am considering disallowing all homebrew and classes and races from supplemental books. Stick to the well-balanced core rules, and do everything else by means of roleplaying and flavour. This is far less gimmicky, if more work for unimaginative players (such as myself!). Some further interesting reading:

12 March 2017

Mike Hommey: When the memory allocator works against you

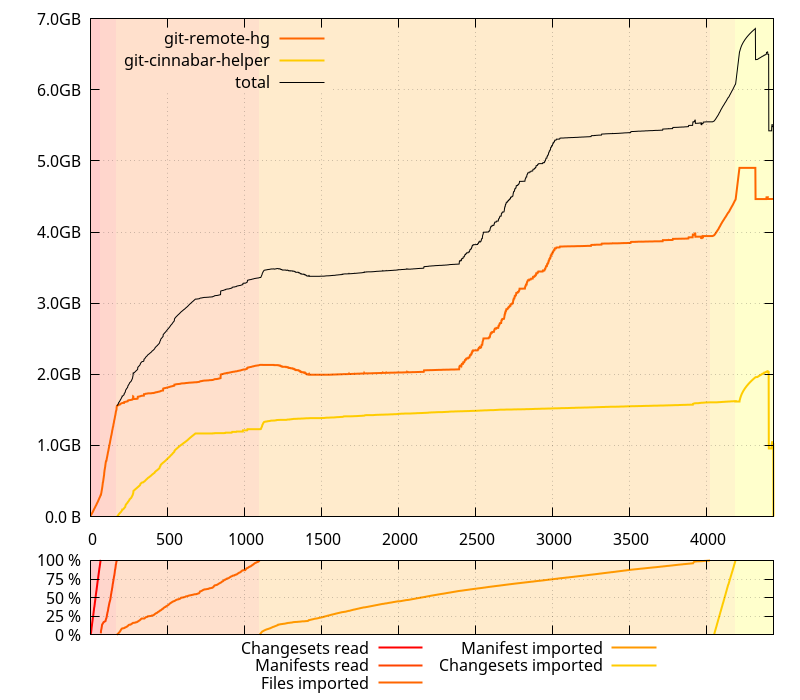
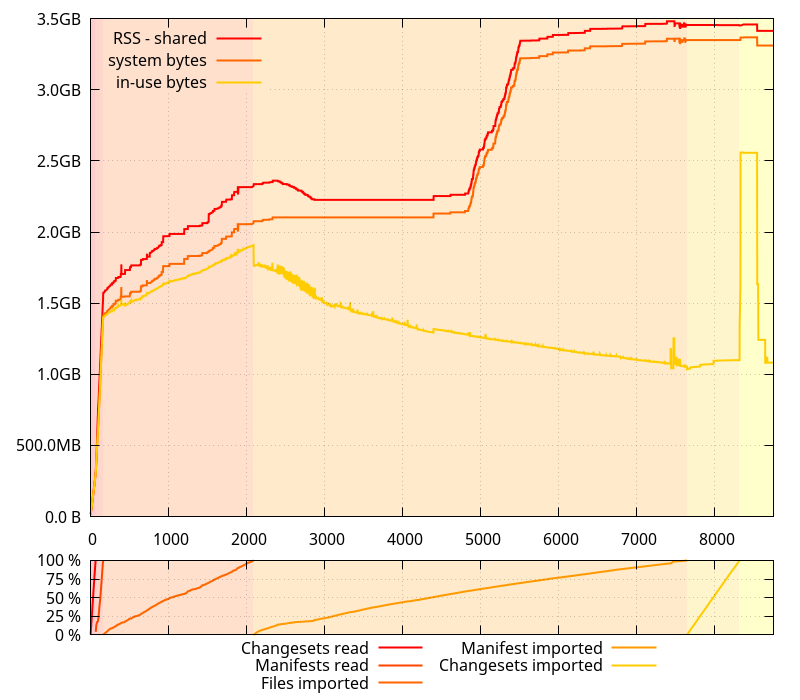
Cloning mozilla-central with git-cinnabar requires a lot of memory. Actually too much memory to fit in a 32-bits address space. I hadn t optimized for memory use in the first place. For instance, git-cinnabar keeps sha-1s in memory as hex values (40 bytes) rather than raw values (20 bytes). When I wrote the initial prototype, it didn t matter that much, and while close(ish) to the tipping point, it didn t require more than 2GB of memory at the time. Time passed, and mozilla-central grew. I suspect the recent addition of several thousands of commits and files has made things worse. In order to come up with a plan to make things better (short or longer term), I needed data. So I added some basic memory resource tracking, and collected data while cloning mozilla-central. I must admit, I was not ready for what I witnessed. Follow me for a tale of frustrations (plural). I was expecting things to have gotten worse on the master branch (which I used for the data collection) because I am in the middle of some refactoring and did many changes that I was suspecting might have affected memory usage. I wasn t, however, expecting to see the clone command using 10GB(!) memory at peak usage across all processes. (Note, those memory sizes are RSS, minus shared ) It also was taking an unexpected long time, but then, I hadn t cloned a large repository like mozilla-central from scratch in a while, so I wasn t sure if it was just related to its recent growth in size or otherwise. So I collected data on 0.4.0 as well. Less time spent, less memory usage ok. There s definitely something wrong on master. But wait a minute, that slope from ~2GB to ~4GB on the git-remote-hg process doesn t actually make any kind of sense. I mean, I d understand it if it were starting and finishing with the Import manifest phase, but it starts in the middle of it, and ends long before it finishes. WTH? First things first, since RSS can be a variety of things, I checked /proc/$pid/smaps and confirmed that most of it was, indeed, the heap. That s the point where you reach for Google, type something like python memory profile and find various tools. One from the results that I remembered having used in the past is guppy s heapy. Armed with pdb, I broke execution in the middle of the slope, and tried to get memory stats with heapy. SIGSEGV. Ouch. Let s try something else. I reached out to objgraph and pympler. SIGSEGV. Ouch again. Tried working around the crashes for a while (too long while, retrospectively, hindsight is 20/20), and was somehow successful at avoiding them by peaking at a smaller set of objects. But whatever I did, despite being attached to a process that had 2.6GB RSS, I wasn t able to find more than 1.3GB of data. This wasn t adding up. It surely didn t help that getting to that point took close to an hour each time. Retrospectively, I wish I had investigated using something like Checkpoint/Restore in Userspace. Anyways, after a while, I decided that I really wanted to try to see the whole picture, not smaller peaks here and there that might be missing something. So I resolved myself to look at the SIGSEGV I was getting when using pympler, collecting a core dump when it happened. Guess what? The Debian python-dbg package does not contain the debug symbols for the python package. The core dump was useless. Since I was expecting I d have to fix something in python, I just downloaded its source and built it. Ran the command again, waited, and finally got a backtrace. First Google hit for the crashing function? The exact (unfixed) crash reported on the python bug tracker. No patch. Crashing code is doing:
((f)->f_builtins != (f)->f_tstate->interp->builtins)
And (f)->f_tstate is NULL. Classic NULL deref. Added a guard (assessing it wouldn t break anything). Ran the command again. Waited. Again. SIGSEGV. Facedesk. Another crash on the same line. Did I really use the patched python? Yes. But this time (f)->f_tstate->interp is NULL. Sigh. Same player, shoot again. Finally, no crash but still stuck on only 1.3GB accounted for. Ok, I know not all python memory profiling tools are entirely reliable, let s try heapy again. SIGSEGV. Sigh. No debug info on the heapy module, where the crash happens. Sigh. Rebuild the module with debug info, try again. The backtrace looks like heapy is recursing a lot. Look at %rsp, compare with the address space from /proc/$pid/maps. Confirmed. A stack overflow. Let s do ugly things and increase the stack size in brutal ways. Woohoo! Now heapy tells me there s even less memory used than the 1.3GB I found so far. Like, half less. Yeah, right. I m not clear on how I got there, but that s when I found gdb-heap, a tool from Red Hat s David Malcolm, and the associated talk Dude, where s my RAM? A deep dive into how Python uses memory (slides). With a gdb attached, I would finally be able to rip python s guts out and find where all the memory went. Or so I thought. The gdb-heap tool only found about 600MB. About as much as heapy did, for that matter, but it could be coincidental. Oh. Kay. I don t remember exactly what went through my mind then, but, since I was attached to a running process with gdb, I typed the following on the gdb prompt:
gdb> call malloc_stats()
And that s when the truth was finally unvealed: the memory allocator was just acting up the whole time. The ouput was something like:
Arena 0:
system bytes    =  some number above (but close to) 2GB
in use bytes    =  some number above (but close to) 600MB
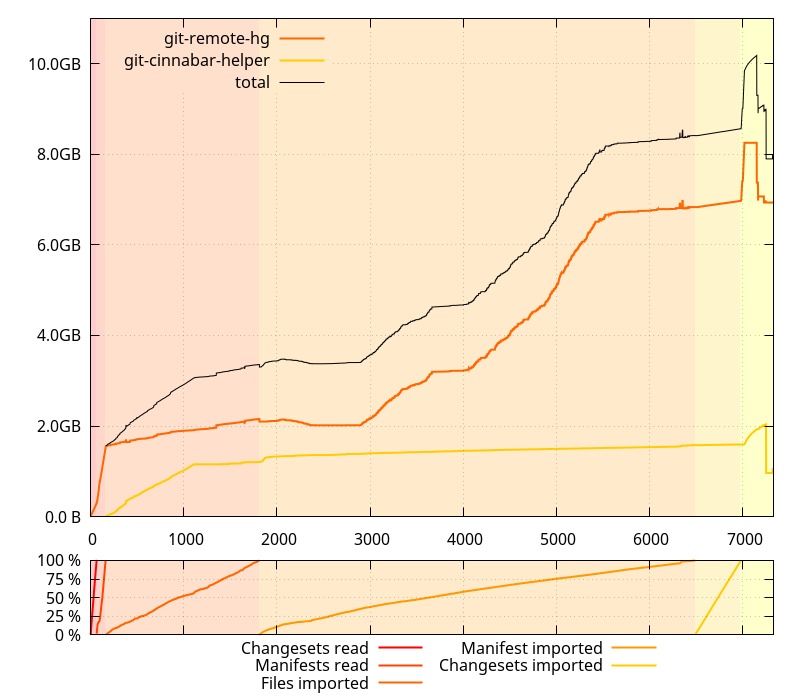
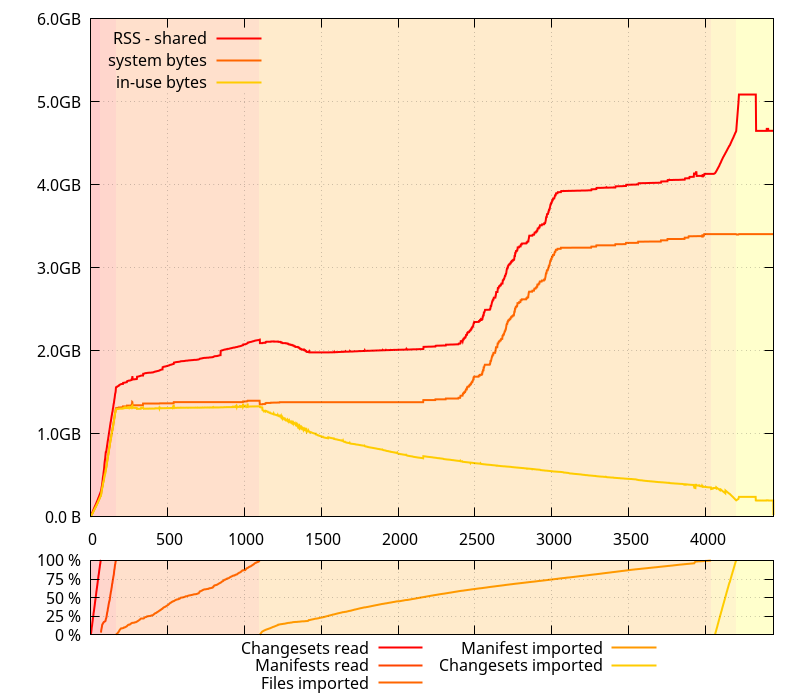
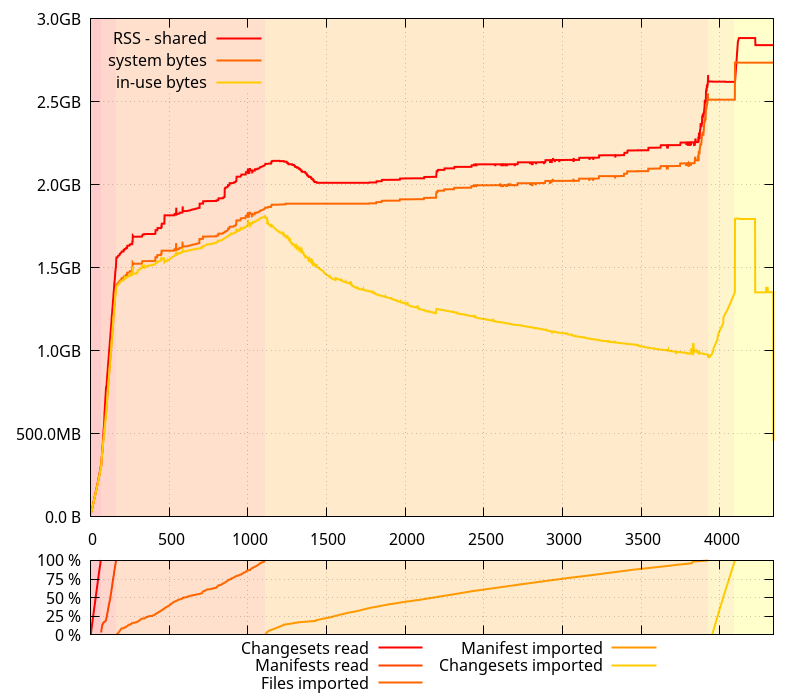
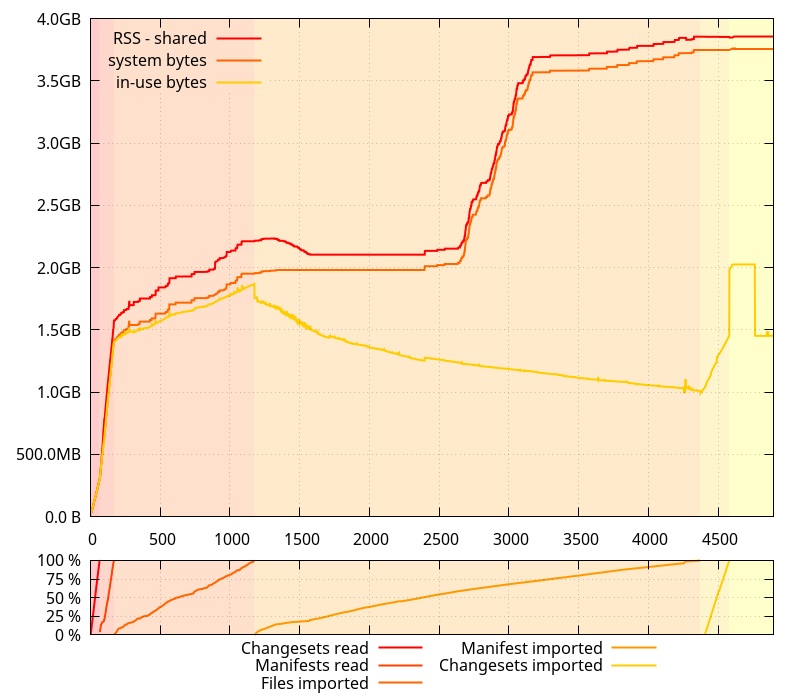
Yes, the glibc allocator was just telling it had allocated 600MB of memory, but was holding onto 2GB. I must have found a really bad allocation pattern that causes massive fragmentation. One thing that David Malcolm s talk taught me, though, is that python uses its own allocator for small sizes, so the glibc allocator doesn t know about them. And, roughly, adding the difference between RSS and what glibc said it was holding to to the use bytes it reported somehow matches the 1.3GB I had found so far. So it was time to see how those things evolved in time, during the entire clone process. I grabbed some new data, tracking the evolution of system bytes and in use bytes . There are two things of note on this data: In fact, the latter is exactly how git-cinnabar is supposed to work: It reads changesets and manifests chunks, and holds onto them while importing files. Then it throws away those manifests and changesets chunks one by one while it imports them. There is, however, some extra bookkeeping that requires some additional memory, but it s expected to be less memory consuming than keeping all the changesets and manifests chunks in memory. At this point, I thought a possible explanation is that since both python and glibc are mmap()ing their own arenas, they might be intertwined in a way that makes things not go well with the allocation pattern happening during the Import manifest phase (which, in fact, allocates and frees increasingly large buffers for each manifest, as manifests grow in size in the mozilla-central history). To put the theory at work, I patched the python interpreter again, making it use malloc() instead of mmap() for its arenas. Aha! I thought. That definitely looks much better. Less gap between what glibc says it requested from the system and the RSS size. And, more importantly, no runaway increase of memory usage in the middle of nowhere. I was preparing myself to write a post about how mixing allocators could have unintended consequences. As a comparison point, I went ahead and ran another test, with the python allocator entirely disabled, this time. Heh. It turns out glibc was acting up all alone. So much for my (plausible) theory. (I still think mixing allocators can have unintended consequences.) (Note, however, that the reason why the python allocator exists is valid: without it, the overall clone took almost 10 more minutes) And since I had been getting all this data with 0.4.0, I gathered new data without the python allocator with the master branch. This paints a rather different picture than the original data on that branch, with much less memory use regression than one would think. In fact, there isn t much difference, except for the spike at the end, which got worse, and some of the noise during the Import manifests phase that got bigger, implying larger amounts of temporary memory used. The latter may contribute to the allocation patterns that throw glibc s memory allocator off. It turns out tracking memory usage in python 2.7 is rather painful, and not all the tools paint a complete picture of it. I hear python 3.x is somewhat better in that regard, and I hope it s true, but at the moment, I m stuck with 2.7. The most reliable tool I ve used here, it turns out, is pympler. Or rebuilding the python interpreter without its allocator, and asking the system allocator what is allocated. With all this data, I now have some defined problems to tackle, some easy (the spike at the end of the clone), and some less easy (working around glibc allocator s behavior). I have a few hunches as to what kind of allocations are causing the runaway increase of RSS. Coincidentally, I m half-way through a refactor of the code dealing with manifests, and it should help dealing with the issue. But that will be the subject of a subsequent post.

10 March 2017

Mart n Ferrari: SunCamp happening again this May!

As I announced in mailing lists a few days ago, the Debian SunCamp (DSC2017) is happening again this May. SunCamp different to most other Debian events. Instead of a busy schedule of talks, SunCamp focuses on the hacking and socialising aspect, without making it just a Debian party/vacation.
DSC2016 - Hacking and discussing
The idea is to have 4 very productive days, staying in a relaxing and comfy environment, working on your own projects, meeting with your team, or presenting to fellow Debianites your most recent pet project.
DSC2016 - Tincho talking about Prometheus
We have tried to make this event the simplest event possible, both for organisers and attendees. There will be no schedule, except for the meal times at the hotel. But these can be ignored too, there is a lovely bar that serves snacks all day long, and plenty of restaurants and caf s around the village. DSC2016 - Hacking and discussing The SunCamp is an event to get work done, but there will be time for relaxing and socialising too.
DSC2016 - Well deserved siesta
DSC2016 - Playing P tanque
Do you fancy a hack-camp in a place like this? Swimming pool Caf Caf  terrace One of the things that makes the event simple, is that we have negotiated a flat price for accommodation that includes usage of all the facilities in the hotel, and optionally food. We will give you a booking code, and then you arrange your accommodation as you please, you can even stay longer if you feel like it! The rooms are simple but pretty, and everything has been renovated very recently. Room Room view We are not preparing a talks programme, but we will provide the space and resources for talks if you feel inclined to prepare one. You will have a huge meeting room, divided in 4 areas to reduce noise, where you can hack, have team discussions, or present talks. Hacklab Hacklab Do you want to see more pictures? Check the full gallery
Debian SunCamp 2017 Hotel Anabel, LLoret de Mar, Province of Girona, Catalonia, Spain May 18-21, 2017

Tempted already? Head to the wikipage and register now, it is only 2 months away! Please try to reserve your room before the end of March. The hotel has reserved a number of rooms for us until that time. You can reserve a room after March, but we can't guarantee the hotel will still have free rooms. Comment

9 March 2017

Petter Reinholdtsen: Detecting NFS hangs on Linux without hanging yourself...

Over the years, administrating thousand of NFS mounting linux computers at the time, I often needed a way to detect if the machine was experiencing NFS hang. If you try to use df or look at a file or directory affected by the hang, the process (and possibly the shell) will hang too. So you want to be able to detect this without risking the detection process getting stuck too. It has not been obvious how to do this. When the hang has lasted a while, it is possible to find messages like these in dmesg:
nfs: server nfsserver not responding, still trying
nfs: server nfsserver OK
It is hard to know if the hang is still going on, and it is hard to be sure looking in dmesg is going to work. If there are lots of other messages in dmesg the lines might have rotated out of site before they are noticed. While reading through the nfs client implementation in linux kernel code, I came across some statistics that seem to give a way to detect it. The om_timeouts sunrpc value in the kernel will increase every time the above log entry is inserted into dmesg. And after digging a bit further, I discovered that this value show up in /proc/self/mountstats on Linux. The mountstats content seem to be shared between files using the same file system context, so it is enough to check one of the mountstats files to get the state of the mount point for the machine. I assume this will not show lazy umounted NFS points, nor NFS mount points in a different process context (ie with a different filesystem view), but that does not worry me. The content for a NFS mount point look similar to this:
[...]
device /dev/mapper/Debian-var mounted on /var with fstype ext3
device nfsserver:/mnt/nfsserver/home0 mounted on /mnt/nfsserver/home0 with fstype nfs statvers=1.1
        opts:   rw,vers=3,rsize=65536,wsize=65536,namlen=255,acregmin=3,acregmax=60,acdirmin=30,acdirmax=60,soft,nolock,proto=tcp,timeo=600,retrans=2,sec=sys,mountaddr=129.240.3.145,mountvers=3,mountport=4048,mountproto=udp,local_lock=all
        age:    7863311
        caps:   caps=0x3fe7,wtmult=4096,dtsize=8192,bsize=0,namlen=255
        sec:    flavor=1,pseudoflavor=1
        events: 61063112 732346265 1028140 35486205 16220064 8162542 761447191 71714012 37189 3891185 45561809 110486139 4850138 420353 15449177 296502 52736725 13523379 0 52182 9016896 1231 0 0 0 0 0 
        bytes:  166253035039 219519120027 0 0 40783504807 185466229638 11677877 45561809 
        RPC iostats version: 1.0  p/v: 100003/3 (nfs)
        xprt:   tcp 925 1 6810 0 0 111505412 111480497 109 2672418560317 0 248 53869103 22481820
        per-op statistics
                NULL: 0 0 0 0 0 0 0 0
             GETATTR: 61063106 61063108 0 9621383060 6839064400 453650 77291321 78926132
             SETATTR: 463469 463470 0 92005440 66739536 63787 603235 687943
              LOOKUP: 17021657 17021657 0 3354097764 4013442928 57216 35125459 35566511
              ACCESS: 14281703 14290009 5 2318400592 1713803640 1709282 4865144 7130140
            READLINK: 125 125 0 20472 18620 0 1112 1118
                READ: 4214236 4214237 0 715608524 41328653212 89884 22622768 22806693
               WRITE: 8479010 8494376 22 187695798568 1356087148 178264904 51506907 231671771
              CREATE: 171708 171708 0 38084748 46702272 873 1041833 1050398
               MKDIR: 3680 3680 0 773980 993920 26 23990 24245
             SYMLINK: 903 903 0 233428 245488 6 5865 5917
               MKNOD: 80 80 0 20148 21760 0 299 304
              REMOVE: 429921 429921 0 79796004 61908192 3313 2710416 2741636
               RMDIR: 3367 3367 0 645112 484848 22 5782 6002
              RENAME: 466201 466201 0 130026184 121212260 7075 5935207 5961288
                LINK: 289155 289155 0 72775556 67083960 2199 2565060 2585579
             READDIR: 2933237 2933237 0 516506204 13973833412 10385 3190199 3297917
         READDIRPLUS: 1652839 1652839 0 298640972 6895997744 84735 14307895 14448937
              FSSTAT: 6144 6144 0 1010516 1032192 51 9654 10022
              FSINFO: 2 2 0 232 328 0 1 1
            PATHCONF: 1 1 0 116 140 0 0 0
              COMMIT: 0 0 0 0 0 0 0 0
device binfmt_misc mounted on /proc/sys/fs/binfmt_misc with fstype binfmt_misc
[...]
The key number to look at is the third number in the per-op list. It is the number of NFS timeouts experiences per file system operation. Here 22 write timeouts and 5 access timeouts. If these numbers are increasing, I believe the machine is experiencing NFS hang. Unfortunately the timeout value do not start to increase right away. The NFS operations need to time out first, and this can take a while. The exact timeout value depend on the setup. For example the defaults for TCP and UDP mount points are quite different, and the timeout value is affected by the soft, hard, timeo and retrans NFS mount options. The only way I have been able to get working on Debian and RedHat Enterprise Linux for getting the timeout count is to peek in /proc/. But according to Solaris 10 System Administration Guide: Network Services, the 'nfsstat -c' command can be used to get these timeout values. But this do not work on Linux, as far as I can tell. I asked Debian about this, but have not seen any replies yet. Is there a better way to figure out if a Linux NFS client is experiencing NFS hangs? Is there a way to detect which processes are affected? Is there a way to get the NFS mount going quickly once the network problem causing the NFS hang has been cleared? I would very much welcome some clues, as we regularly run into NFS hangs.

Arturo Borrero Gonz lez: Netfilter in GSoC 2017

logo Great news! The Netfilter project has been elected by Google to be a mentoring organization in this year Google Summer of Code program. Following the pattern of the last years, Google seems to realise and support the importance of this software project in the Linux ecosystem. I will be proudly mentoring some student this 2017 year, along with Eric Leblond and of course Pablo Neira. The focus of the Netfilter project has been in nftables for the last years, and the students joining our community will likely work on the new framework. For prospective students: there is an ideas document which you must read. The policy in the Netfilter project is to encourage students to send patches before they are elected to join us. Therefore, a good starting point is to subscribe to the mailing lists, download the git code repositories, build by hand the projects (compilation) and look at the bugzilla (registration required). Due to this type of internships and programs, I believe is interesting to note the ascending involvement of women in the last years. I can remember right now: Ana Rey (@AnaRB), Shivani Bhardwaj (@tuxish), Laura Garc a and Elise Lennion (blog). On a side note, Debian is not participating in GSoC this year :-(

8 March 2017

Antoine Beaupr : An update to GitHub's terms of service

On February 28th, GitHub published a brand new version of its Terms of Service (ToS). While the first draft announced earlier in February didn't generate much reaction, the new ToS raised concerns that they may break at least the spirit, if not the letter, of certain free-software licenses. Digging in further reveals that the situation is probably not as dire as some had feared. The first person to raise the alarm was probably Thorsten Glaser, a Debian developer, who stated that the "new GitHub Terms of Service require removing many Open Source works from it". His concerns are mainly about section D of the document, in particular section D.4 which states:
You grant us and our legal successors the right to store and display your Content and make incidental copies as necessary to render the Website and provide the Service.
Section D.5 then goes on to say:
[...] You grant each User of GitHub a nonexclusive, worldwide license to access your Content through the GitHub Service, and to use, display and perform your Content, and to reproduce your Content solely on GitHub as permitted through GitHub's functionality

ToS versus GPL The concern here is that the ToS bypass the normal provisions of licenses like the GPL. Indeed, copyleft licenses are based on copyright law which forbid users from doing anything with the content unless they comply with the license, which forces, among other things, "share alike" properties. By granting GitHub and its users rights to reproduce content without explicitly respecting the original license, the ToS may allow users to bypass the copyleft nature of the license. Indeed, as Joey Hess, author of git-annex, explained :
The new TOS is potentially very bad for copylefted Free Software. It potentially neuters it entirely, so GPL licensed software hosted on Github has an implicit BSD-like license
Hess has since removed all his content (mostly mirrors) from GitHub. Others disagree. In a well-reasoned blog post, Debian developer Jonathan McDowell explained the rationale behind the changes:
My reading of the GitHub changes is that they are driven by a desire to ensure that GitHub are legally covered for the things they need to do with your code in order to run their service.
This seems like a fair point to make: GitHub needs to protect its own rights to operate the service. McDowell then goes on to do a detailed rebuttal of the arguments made by Glaser, arguing specifically that section D.5 "does not grant [...] additional rights to reproduce outside of GitHub". However, specific problems arise when we consider that GitHub is a private corporation that users have no control over. The "Services" defined in the ToS explicitly "refers to the applications, software, products, and services provided by GitHub". The term "Services" is therefore not limited to the current set of services. This loophole may actually give GitHub the right to bypass certain provisions of licenses used on GitHub. As Hess detailed in a later blog post:
If Github tomorrow starts providing say, an App Store service, that necessarily involves distribution of software to others, and they put my software in it, would that be allowed by this or not? If that hypothetical Github App Store doesn't sell apps, but licenses access to them for money, would that be allowed under this license that they want to my software?
However, when asked on IRC, Bradley M. Kuhn of the Software Freedom Conservancy explained that "ultimately, failure to comply with a copyleft license is a copyright infringement" and that the ToS do outline a process to deal with such infringement. Some lawyers have also publicly expressed their disagreement with Glaser's assessment, with Richard Fontana from Red Hat saying that the analysis is "basically wrong". It all comes down to the intent of the ToS, as Kuhn (who is not a lawyer) explained:
any license can be abused or misused for an intent other than its original intent. It's why it matters to get every little detail right, and I hope Github will do that.
He went even further and said that "we should assume the ambiguity in their ToS as it stands is favorable to Free Software". The ToS are in effect since February 28th; users "can accept them by clicking the broadcast announcement on your dashboard or by continuing to use GitHub". The immediacy of the change is one of the reasons why certain people are rushing to remove content from GitHub: there are concerns that continuing to use the service may be interpreted as consent to bypass those licenses. Hess even hosted a separate copy of the ToS [PDF] for people to be able to read the document without implicitly consenting. It is, however, unclear how a user should remove their content from the GitHub servers without actually agreeing to the new ToS.

CLAs When I read the first draft, I initially thought there would be concerns about the mandatory Contributor License Agreement (CLA) in section D.5 of the draft:
[...] unless there is a Contributor License Agreement to the contrary, whenever you make a contribution to a repository containing notice of a license, you license your contribution under the same terms, and agree that you have the right to license your contribution under those terms.
I was concerned this would establish the controversial practice of forcing CLAs on every GitHub user. I managed to find a post from a lawyer, Kyle E. Mitchell, who commented on the draft and, specifically, on the CLA. He outlined issues with wording and definition problems in that section of the draft. In particular, he noted that "contributor license agreement is not a legal term of art, but an industry term" and "is a bit fuzzy". This was clarified in the final draft, in section D.6, by removing the use of the CLA term and by explicitly mentioning the widely accepted norm for licenses: "inbound=outbound". So it seems that section D.6 is not really a problem: contributors do not need to necessarily delegate copyright ownership (as some CLAs require) when they make a contribution, unless otherwise noted by a repository-specific CLA. An interesting concern he raised, however, was with how GitHub conducted the drafting process. A blog post announced the change on February 7th with a link to a form to provide feedback until the 21st, with a publishing deadline of February 28th. This gave little time for lawyers and developers to review the document and comment on it. Users then had to basically accept whatever came out of the process as-is. Unlike every software project hosted on GitHub, the ToS document is not part of a Git repository people can propose changes to or even collaboratively discuss. While Mitchell acknowledges that "GitHub are within their rights to update their terms, within very broad limits, more or less however they like, whenever they like", he sets higher standards for GitHub than for other corporations, considering the community it serves and the spirit it represents. He described the process as:
[...] consistent with the value of CYA, which is real, but not with the output-improving virtues of open process, which is also real, and a great deal more pleasant.
Mitchell also explained that, because of its position, GitHub can have a major impact on the free-software world.
And as the current forum of preference for a great many developers, the knock-on effects of their decisions throw big weight. While GitHub have the wheel and they ve certainly earned it for now they can do real damage.
In particular, there have been some concerns that the ToS change may be an attempt to further the already diminishing adoption of the GPL for free-software projects; on GitHub, the GPL has been surpassed by the MIT license. But Kuhn believes that attitudes at GitHub have begun changing:
GitHub historically had an anti-copyleft culture, which was created in large part by their former and now ousted CEO, Preston-Warner. However, recently, I've seen people at GitHub truly reach out to me and others in the copyleft community to learn more and open their minds. I thus have a hard time believing that there was some anti-copyleft conspiracy in this ToS change.

GitHub response However, it seems that GitHub has actually been proactive in reaching out to the free software community. Kuhn noted that GitHub contacted the Conservancy to get its advice on the ToS changes. While he still thinks GitHub should fix the ambiguities quickly, he also noted that those issues "impact pretty much any non-trivial Open Source and Free Software license", not just copylefted material. When reached for comments, a GitHub spokesperson said:
While we are confident that these Terms serve the best needs of the community, we take our users' feedback very seriously and we are looking closely at ways to address their concerns.
Regardless, free-software enthusiasts have other concerns than the new ToS if they wish to use GitHub. First and foremost, most of the software running GitHub is proprietary, including the JavaScript served to your web browser. GitHub also created a centralized service out of a decentralized tool (Git). It has become the largest code hosting service in the world after only a few years and may well have become a single point of failure for free software collaboration in a way we have never seen before. Outages and policy changes at GitHub can have a major impact on not only the free-software world, but also the larger computing world that relies on its services for daily operation. There are now free-software alternatives to GitHub. GitLab.com, for example, does not seem to have similar licensing issues in its ToS and GitLab itself is free software, although based on the controversial open core business model. The GitLab hosting service still needs to get better than its grade of "C" in the GNU Ethical Repository Criteria Evaluations (and it is being worked on); other services like GitHub and SourceForge score an "F". In the end, all this controversy might have been avoided if GitHub was generally more open about the ToS development process and gave more time for feedback and reviews by the community. Terms of service are notorious for being confusing and something of a legal gray area, especially for end users who generally click through without reading them. We should probably applaud the efforts made by GitHub to make its own ToS document more readable and hope that, with time, it will address the community's concerns.
Note: this article first appeared in the Linux Weekly News.

Clint Adams: Oh, little boy, pick up the pieces

Chris sat in the window seat in the row behind his parents. Actually he also sat in half of his neighbor s seat. His neighbor was uncomfortable but said nothing and did not attempt to lower the armrest to try to contain his girth. His parents were awful human beings: selfish, self-absorbed and controlling. Chris, his dad would say, look out the window! His dad was the type of officious busybody who would snitch on you at work for not snitching on someone else. What? Chris would reply, after putting down The Handmaid s Tale and removing one of his earbuds. Then his dad would insist that it was very important that he look out the window to see a very important cloud or glacial landform. Chris would comply and then return to his book and music. Chris, his mom would say, you need to review our travel itinerary. His mom cried herself to sleep when she heard that Nigel Stock died, gave up on ever finding True Love, and resolved to achieve a husband and child instead. What? Chris would reply, after putting down The Handmaid s Tale and removing one of his earbuds. Then his mom would insist that it was very important that review photos and prose regarding their managed tour package in Costa Rica, because he wouldn t want to show up there unprepared. Chris would passive-aggressively stare at each page of the packet, then hand it back to his mother. It was already somewhat clear that due to delays in taking off they would be missing their connecting flight to Costa Rica. About of the passengers on the aeroplane were also going to Costa Rica, and were discussing the probable missed connection amongst themselves and with the flight staff. Chris s parents were oblivious to all of this, despite being native speakers of English. Additionally, just as they were unaware of what other people were discussing, they imagined that no one else could hear their private family discussions. Everyone on the plane missed their connecting flights. Chris s parents continued to be terrible human beings.
Posted on 2017-03-08
Tags: etiamdisco

7 March 2017

Daniel Stender: Remotely deploy a WSGI application (as a Debian package) with Ansible

This is a mini workshop as an introduction into using Ansible for the administration of Debian systems. As an example it s shown how this configuration management tool can be used to remotely set up a simple WSGI application running on an Apache web server on a Debian installation to make it available on the net. The application which is used as an example is httpbin by Runscope. This is an useful HTTP request service for the development of web software or any other purposes which features a number of specific endpoints that can be used for different testing matters. For example, the address http://<address>/user-agent of httpbin returns the user agent identification of the client program which has been used to query it (that s taken from the header of the request). There are official instances of this request server running on the net, like the one at http://httpbin.org/. WSGI is a widespread standard for programming web application in Python, and httpbin is implemented in Python using the Flask web framework. The basis of the workshop is a simple base installation of an up-to-date Debian 8 Jessie on a demonstration host, and the latest official release of that is 8.7. As a first step, the installation has to be switched over to the testing branch of Debian, because the Debian packages of httpbin are comparatively new and are going to be introduced into the stable branch of the archive the first time with the upcoming major release number 9 Stretch . After that, the Apache packages which are needed to make it available (apache2 and libapache2-mod-wsgi other web servers of course could be used instead), and which are not part of a base installation, are installed from the archive. The web server then gets launched remotely, and the httpbin package will be also pulled and the service is going to be integrated into Apache to run on that. To achieve that, two configuration files must be deployed on the target system, and a few additional operations are needed to get everything working together. Every step is preconfigured within Ansible so that the whole process could be launched by a single command on the control node, and could be run on a single or a number of comparable target machines automatically and reproducibly. If a server is needed for trying this workshop out, straightforward cloud server instances are available on the net for example at DigitalOcean, but let me underline this there are other cloud providers which offer the same things, too! If it s needed for experiments or other purposes only for a limited time, low priced droplets are available here which are billed by the hour. After being registered, the machine(s) which is/are wanted could be set up easily over the web interface (choose Debian 8.7 as OS), but there are also command line clients available like doctl (which is not yet available as a Debian package). For the convenient use of a droplet the user should generate a SSH key pair on the local machine, first:
$ ssh-keygen -t rsa -b 4096 -C "john@doe.com" -f ~/.ssh/mykey
The public part of the key ~/.ssh/mykey.pub then can be uploaded into the user account before the droplet is going to be created, it then could be integrated automatically. There is a good introduction on the whole process available in the excellent tutorial series serversforhackers.com, here. Ansible then can use the SSH keypair to login into a droplet without the need to type in the password every time. On a cloud server like this carrying a Debian base system, the examples in this workshop can be tried well. Ansible works client-less and doesn t need to be installed on the remote system but only on the control node, however a Python 2.7 interpreter is needed there (the base system of DigitalOcean includes that). For that Ansible can do anything on them, remote servers which are going to be controlled must be added to /etc/ansible/hosts. This is a configuration file in the INI format for DNS names and IP addresses. For a flexible organisation of the server inventory it s possible to group hosts here, IP ranges could be given, and optional variables can be used among other useful things (the default file contains a couple of examples). One or a couple of servers (in Ansible they are called hosts ) on which something particular is going to be happening (like httpbin is going to be installed) could be added like this (the group name is arbitrary):
[httpbin]
192.0.2.0
Whether Ansible could communicate with the hosts in the group and actually can operate on them can be verified by just pinging them like this:
$ ansible httpbin -m ping -u root --private-key=~/.ssh/mykey
192.0.2.0   SUCCESS =>  
    "changed": false, 
    "ping": "pong"
 
The command succeeded well, so it appears there isn t no significant problem regarding this machine. The return value changed:false indicates that there haven t been any changes on that host as a result of the execution of this command. Next to ping there are several other modules which could be used with the command line tool ansible the same way, and these modules are actually something like the core components of Ansible. The module shell for example can be used to execute shell commands on the remote machine like uname to get some system information returned from the server:
$ ansible httpbin -m shell -a "uname -a" -u root --private-key=~/.ssh/mykey
192.0.2.0   SUCCESS   rc=0 >>
Linux debian-512mb-fra1-01 3.16.0-4-amd64 #1 SMP Debian 3.16.36-1+deb8u2 (2016-10-19) x86_64 GNU/Linux
In the same way, the module apt could be used to remotely install packages. But with that there s no major advantage over other software products that offer a similar functionality, and using those modules on the command line is just the basics of Ansible usage. Playbooks in Ansible are YAML scripts for the manipulation of the registered hosts in /etc/ansible/hosts. Different tasks can be defined here for successive processing, like a simple playbook for changing the package source from stable to testing for example goes like this:
---
 - hosts: httpbin
   tasks:
   - name: remove "jessie" package source
     apt_repository: repo='deb http://mirrors.digitalocean.com/debian jessie main' state=absent
   - name: add "testing" package source
     apt_repository: repo='deb http://httpredir.debian.org/debian testing main contrib non-free' state=present
   - name: upgrade packages
     apt: update_cache=yes upgrade=dist
First, like used with the CLI tool ansible above, the targeted host group httpbin is chosen. The default user root and the SSH key could be fixed here, too, to spare the need to give them on the command line. Then there are three tasks defined to get worked down consecutively: With the module apt_repository the preset package source jessie is removed from /etc/apt/sources.list. Then, a new package source for the testing archive gets added to /etc/apt/sources.list.d/ by using the same module (by the way, mirrors.digitalocean.org also provides testing, though, and that might be faster). After that, the apt module is used to upgrade the package inventory (it performs apt-get dist-upgrade), after an update of the package cache has taken place (by running apt-get update) A playbook like this (the filename is arbitrary, but commonly carries the suffix .yml) can be run by the CLI tool ansible-playbook, like this:
$ ansible-playbook httpbin.yml -u root --private-key=~/.ssh/mykey
Ansible then works down the individual plays of the tasks on the remote server(s) top-down, and due to a high speed net connection and SSD block device hardware the change of the system to being a Debian Testing base installation only takes around a minute to complete in the cloud. While working, Ansible puts out status reports for the individual operations. If certain changes on the base system have been taken place already like when a playbook is run through one more time, the modules of course sense that and return just the information that the system haven t been changed because it s already there what have been wanted to change to. Beyond the basic playbook which is shown here there are more advanced features like register and when available to bind the execution of a play to the error-free result of a previous one. The apt module then can be used in the playbook to install the three needed binary packages one after another:
   - name: install apache2
     apt: pkg=apache2 state=present
   - name: install mod_wsgi
     apt: pkg=libapache2-mod-wsgi state=present
   - name: install httpbin
     apt: pkg=python-httpbin state=present
The Debian packages are configured in a way that the Apache web server is running immediately after installation, and the Apache module mod_wsgi is automatically integrated. If that would be otherwise desired, there are Ansible modules available for operating on Apache which can reverse this if that is wanted. By the way, after the package have been installed the httpbin server can be launched with python -m httpbin.core, but this runs only a mini web server which is not suitable for productive use. To get httpbin running on the Apache web server two configuration files are needed. They could be set up in the project directory on the control node and then uploaded onto the remote machine with another Ansible module. The file httpbin.wsgi (the name is again arbitrary) contains only a single line which is the starter for the WSGI application to run:
from httpbin import app as application
The module copy can be used to deploy that script on the host, while the target folder /var/www/httpbin must be set up before that by the module file. In addition to that, a separate user account like httpbin (the name is also arbitrary but picked up in the other config file) is needed to run it, and the module user can set this up. The demonstrational playbook continues, and the plays which are performing these three operations are going like this:
   - name: mkdir /var/www/httpbin
     file: path=/var/www/httpbin state=directory
   - name: set up user "httpbin"
     user: name=httpbin
   - name: copy WSGI starter
     copy: src=httpbin.wsgi dest=/var/www/httpbin/httpbin.wsgi owner=httpbin group=httpbin mode=0644 
Another configuration script httpbin.conf is needed for Apache on the remote server to include the WSGI application httpbin running as a virtual host. It goes like this:
<VirtualHost *>
 WSGIDaemonProcess httpbin user=httpbin group=httpbin threads=5
 WSGIScriptAlias / /var/www/httpbin/httpbin.wsgi
 <Directory /var/www/httpbin>
  WSGIProcessGroup httpbin
  WSGIApplicationGroup % GLOBAL 
  Order allow,deny
  Allow from all
 </Directory>
</VirtualHost>
This file needs to be copied into the folder /etc/apache2/sites-available on the host, which already exists when the apache2 package is installed. The remaining operations which are missing to get anything running together are: The default welcome screen of Apache blocks anything else and should be disabled by Apache s CLI tool a2dissite. And after that, the new virtual host needs to be activated with the complementary tool a2ensite both could be run remotely by the module command. Then the Apache server on the remote machine must be restarted to read in the new configuration. You ve guessed it already, that s all easy to perform with Ansible:
   - name: deploy configuration script
     copy: src=httpbin.conf dest=/etc/apache2/sites-available owner=root group=root mode=0644
   - name: deactivate default welcome screen
     command: a2dissite 000-default.conf
     
   - name: activate httpbin virtual host
     command: a2ensite httpbin.conf
   - name: restart Apache
     service: name=apache2 state=restarted 
That s it. After this playbook has been performed by Ansible on a (or several) freshly set up remote Debian base installation completely, then the httpbin request server is available running on the Apache web server and could be queried from anywhere by a web browser, or for example by curl:
$ curl http://192.0.2.0/user-agent
 
  "user-agent": "curl/7.50.1"
 
With the broad set of Ansible modules and the playbooks a lot of tasks can be accomplished like the example problem which has been explained here. But the range of functions of Ansible however is still even more comprehensive, but to discuss that would have blown the frame of this blog post. For example the playbooks offer more advanced features like event handler which can be used for recurring operations like the restart of Apache in more extensive projects. And beyond playbooks, templates could be set up in the roles which can behave differently on selected machine groups Ansible uses Jinja2 as template engine for that. And the scope of functions of the basic modules could be expanded by employing external tools. To drop a word on why it could be useful in certain situations to run own instances of the httpbin request server instead of using the official ones which are provided on the net by Runscope: Like some people would prefer to run a private instance for example in the local network instead of querying the one on the internet. Or for some development reasons a couple or even a large number of identical instances might be needed Ansible is ideal for setting them up automatically. Anyway, the Javascript bindings to the tracking services like Google Analytics in httpbin/templates/trackingscripts.html are patched out in the Debian package. That could be another reason to prefer to set up an own instance on a Debian server.

Dirk Eddelbuettel: RProtoBuf 0.4.9

RProtoBuf provides R bindings for the Google Protocol Buffers ("Protobuf") data encoding and serialization library used and released by Google, and deployed as a language and operating-system agnostic protocol by numerous projects. The RProtoBuf 0.4.9 release is the fourth and final update this weekend following the request by CRAN to not use package= in .Call() when PACKAGE= is really called for. Some of the code in RProtoBuf 0.4.9 had this bug; some other entry points had neither (!!). With the ongoing drive to establish proper registration of entry points, a few more issues were coming up, all of which are now addressed. And we had some other unreleased minor cleanup, so this made for a somewhat longer (compared to the other updates this weekend) NEWS list:

Changes in RProtoBuf version 0.4.9 (2017-03-06)
  • A new file init.c was added with calls to R_registerRoutines() and R_useDynamicSymbols()
  • Symbol registration is enabled in useDynLib
  • Several missing PACKAGE= arguments were added to the corresponding .Call invocations
  • Two (internal) C++ functions were renamed with suffix _cpp to disambiguate them from R functions with the same name
  • All of above were part of #26
  • Some editing corrections were made to the introductory vignette (David Kretch in #25)
  • The 'configure.ac' file was updated, and renamed from the older converntion 'configure.in', along with 'src/Makevars'. (PR #24 fixing #23)

CRANberries also provides a diff to the previous release. The RProtoBuf page has an older package vignette, a 'quick' overview vignette, a unit test summary vignette, and the pre-print for the JSS paper. Questions, comments etc should go to the GitHub issue tracker off the GitHub repo.

This post by Dirk Eddelbuettel originated on his Thinking inside the box blog. Please report excessive re-aggregation in third-party for-profit settings.

Dirk Eddelbuettel: RVowpalWabbit 0.0.9

The RVowpalWabbit package update is the third of four upgrades requested by CRAN, following RcppSMC 0.1.5 and RcppGSL 0.3.2. This package being somewhat raw, the change was simple and just meant converting the single entry point to using Rcpp Attributes -- which addressed the original issue in passing. No new code or features were added. We should mention that is parallel work ongoing in a higher-level package interfacing the vw binary -- rvw -- as well as plan to redo this package via the external libraries. In that sounds interesting to you, please get in touch. More information is on the RVowpalWabbit page. Issues and bugreports should go to the GitHub issue tracker.

This post by Dirk Eddelbuettel originated on his Thinking inside the box blog. Please report excessive re-aggregation in third-party for-profit settings.

5 March 2017

Dirk Eddelbuettel: RcppGSL 0.3.2

The RcppGSL package provides an interface from R to the GNU GSL using the Rcpp package. RcppGSL release 0.3.2 is one of several maintenance releases this weekend to fix an issue flagged by CRAN: calls to .Call() sometimes used package= where PACKAGE= was meant. This came up now while the registration mechanism is being reworked. So RcppGSL was updated too, and we took the opportunity to bring several packaging aspects up to the newest standards, including support for the soon-to-be required registration of routines. No new code or features were added. The NEWS file entries follow below:

Changes in version 0.3.2 (2017-03-04)
  • In the fastLm function, .Call now uses the correct PACKAGE= argument
  • Added file init.c with calls to R_registerRoutines() and R_useDynamicSymbols(); also use .registration=TRUE in useDynLib in NAMESPACE
  • The skeleton configuration for created packages was updated.

Courtesy of CRANberries, a summary of changes to the most recent release is available. More information is on the RcppGSL page. Questions, comments etc should go to the issue tickets at the GitHub repo.

This post by Dirk Eddelbuettel originated on his Thinking inside the box blog. Please report excessive re-aggregation in third-party for-profit settings.

Dirk Eddelbuettel: RcppSMC 0.1.5

RcppSMC provides Rcpp-based bindings to R for them Sequential Monte Carlo Template Classes (SMCTC) by Adam Johansen described in his JSS article. RcppSMC release 0.1.5 is one of several maintenance releases this weekend to fix an issue flagged by CRAN: calls to .Call() sometimes used package= where PACKAGE= was meant. This came up now while the registration mechanism is being reworked. Hence RcppSMC was updated, and we took the opportunity to bring several packaging aspects up to the newest standards, including support for the soon-to-be required registration of routines. No new code or features were added. The NEWS file entries follow below:

Changes in RcppSMC version 0.1.5 (2017-03-03)
  • Correct .Call to use PACKAGE= argument
  • DESCRIPTION, NAMESPACE, README.md changes to comply with current R CMD check levels
  • Added file init.c with calls to R_registerRoutines() and R_useDynamicSymbols()
  • Updated .travis.yml file for continuous integration

Courtesy of CRANberries, there is a diffstat report for this release. More information is on the RcppSMC page. Issues and bugreports should go to the GitHub issue tracker.

This post by Dirk Eddelbuettel originated on his Thinking inside the box blog. Please report excessive re-aggregation in third-party for-profit settings.

Julien Viard de Galbert: Raspberry Pi 3 as desktop computer

For about six months I ve been using a Raspberry Pi 3 as my desktop computer at home. The overall experience is fine, but I had to do a few adjustments.
First was to use KeePass, the second to compile gcc for cross-compilation (ie use buildroot).
KeePass I m using KeePass + KeeFox to maintain my passwords on the various websites (and avoid reusing the same everywhere).
For this to work on the Raspberry Pi, one need to use mono from Xamarin:
sudo apt-key adv --keyserver hkp://keyserver.ubuntu.com:80 --recv-keys 3FA7E0328081BFF6A14DA29AA6A19B38D3D831EF
echo "deb http://download.mono-project.com/repo/debian wheezy main"   sudo tee /etc/apt/sources.list.d/mono-xamarin.list
sudo apt-get update
sudo apt-get upgrade
sudo apt-get install mono-runtime
The install instruction comes from mono-project and the initial pointer was found on raspberrypi forums, stackoverflow and Benny Michielsen s blog.
And for some plugin to work I think I had to apt-get install mono-complete. Compiling gcc Using the Raspberry Pi 3, I recovered an old project based on buildroot for the raspberry pi 2. And just for building the tool-chain I had a few issues. First the compilation would stop during mnp compilation:
 /usr/bin/gcc -std=gnu99 -c -DHAVE_CONFIG_H -I. -I.. -D__GMP_WITHIN_GMP -I.. -DOPERATION_divrem_1 -O2 -Wa,--noexecstack tmp-divrem_1.s -fPIC -DPIC -o .libs/divrem_1.o
tmp-divrem_1.s: Assembler messages:
tmp-divrem_1.s:129: Error: selected processor does not support ARM mode  mls r1,r4,r8,r11'
tmp-divrem_1.s:145: Error: selected processor does not support ARM mode  mls r1,r4,r8,r11'
tmp-divrem_1.s:158: Error: selected processor does not support ARM mode  mls r1,r4,r8,r11'
tmp-divrem_1.s:175: Error: selected processor does not support ARM mode  mls r1,r4,r3,r8'
tmp-divrem_1.s:209: Error: selected processor does not support ARM mode  mls r11,r4,r12,r3'
Makefile:768: recipe for target 'divrem_1.lo' failed
make[]: *** [divrem_1.lo] Error 1
I Googled the error and found this post on the Raspberry Pi forum not really helpful
But I finally found an explanation on Jan Hrach s page on the subject.
The raspbian distribution is still optimized for the first Raspberry Pi so basically the compiler is limited to the old raspberypi instructions. While I was compiling gcc for a Raspberry Pi 2 so needed the extra ones. The proposed solution is to basically update raspbian to debian proper. While this is a neat idea, I still wanted to get some raspbian specific packages (like the kernel) but wanted to be sure that everything else comes from debian. So I did some apt pinning. First I experienced that pinning is not sufficient so when updating source.list with plain debian Jessie, make sure to add theses lines before the raspbian lines:
# add official debian jessie (real armhf gcc)
deb http://ftp.fr.debian.org/debian/ jessie main contrib non-free
deb-src http://ftp.fr.debian.org/debian/ jessie main
deb http://security.debian.org/ jessie/updates main
deb-src http://security.debian.org/ jessie/updates main
deb http://ftp.fr.debian.org/debian/ jessie-updates main
deb-src http://ftp.fr.debian.org/debian/ jessie-updates main
Then run the following to get the debian gpg keys, but don t yet upgrade your system:
apt update
apt install debian-archive-keyring
Now, let s add the pinning.
First if you were using APT::Default-Release "stable"; in your apt.conf (as I did) remove it. It does not mix well with fine grained pinning we will then implement. Then, fill your /etc/apt/preferences file with the following:
# Debian
Package: *
Pin: release o=Debian,a=stable,n=jessie
Pin-Priority: 700
# Raspbian
Package: *
Pin: release o=Raspbian,a=stable,n=jessie
Pin-Priority: 600
Package: *
Pin: release o=Raspberry Pi Foundation,a=stable,n=jessie
Pin-Priority: 600
# Mono
Package: *
Pin: release v=7.0,o=Xamarin,a=stable,n=wheezy,l=Xamarin-Stable,c=main
Pin-Priority: 800
Note: You can use apt-cache policy (no parameter) to debug pinning.
The pinning above is mainly based on the origin field of the repositories (o=)
Finally you can upgrade your system:
apt update 
apt-cache policy gcc 
rm /var/cache/apt/archives/* 
apt upgrade 
apt-cache policy gcc
Note: Removing the cache ensure we download the packages from debian as raspbian is using the exact same naming but we now they are not compiled with a real armhf tool-chain. Second issue with gcc The build stopped on recipe for target 's-attrtab' failed. There are many references on the web, that one was easy, it just need more memory, so I added some swap on the external SSD I was already using to work on buildroot. Conclusion That s it for today, not bad considering my last post was more that 3 years ago

4 March 2017

intrigeri: Contribute your skills to Debian in Paris, May 13-14 2017

(There is a French translation of this announcement.) Join us in Paris, on May 13-14 2017, and we will find a way in which you can help Debian with your current set of skills! You might even learn one or two things in passing (but you don't have to). Debian is a free operating system for your computer. An operating system is the set of basic programs and utilities that make your computer run. Debian comes with dozens of thousands of packages, precompiled software bundled up for easy installation on your machine. A number of other operating systems, such as Ubuntu and Tails, are based on Debian. The upcoming version of Debian, called Stretch, will be released later this year. We need you to help us make it awesome :) Whether you're a computer user, a graphics designer, or a bug triager, there are many ways you can contribute to this effort. We also welcome experience in consensus decision-making, anti-harassment teams, and package maintenance. No effort is too small and whatever you bring to this community will be appreciated. Here's what we will be doing: Goals and principles Before diving into the exact content of this event, a few words from the organization team. This is a work in progress, and a statement of intent. Not everything is organized and confirmed yet. We want to bring together a heterogeneous group of people. This goal will guide our handling of sponsorship requests, and will help us make decisions if more people want to attend than we can welcome properly. In other words: if you're part of a group that is currently under-represented in computer communities, we would like you to be able to attend. We are committed to providing a friendly, safe and welcoming environment for all, regardless of level of experience, gender, gender identity and expression, sexual orientation, disability, personal appearance, body size, race, ethnicity, age, religion, nationality, or other similar personal characteristic. Attending this event requires reading and respecting our Code of Conduct, that sets the standards in terms of behaviour for the whole event, including communication (public and private) before, while and after. There will be a team ready to act if you feel you have been or are being harassed or made uncomfortable by an attendee. We believe that money should not be a blocker for contributing to Debian. We will sponsor travel and find a place to sleep for as many enthusiastic attendees as possible. The space where this event will take place is accessible to wheelchairs. We are trying to organize a translation into (probably French) sign language. Vegan food should be provided for lunch. If you have any specific needs regarding food, please let us know when registering, and we will do our best. What we will be doing There will be a number of stations, i.e. physical space dedicated to people with a given set of skills, hosted by someone who is ready to make this space welcoming and productive. A few stations are already organized, and are described below. If you want to host a station yourself, or would like us to organize another one, please let us know. For example, you may want to assess the state of Debian Stretch for a specific field of interest, be it audio editing, office work, network auditing or whatever you are doing with Debian :) Test the upcoming version of Debian We will test Debian Stretch and gather feedback. We are particularly interested in: Experienced Debian contributors will be ready to relay this feedback to the relevant teams so it is put to good use. Hypra collaborators will be there to bring a focus on universal access technologies. Design and graphics Truth be told, Debian lacks people who are good at design and graphics. There are definitely a good number of low-hanging fruits that can be tackled in a week-end, either in Debian per-se, or in upstream) projects, or in Debian derivatives. This station will be hosted by Juliette Belin. She designed the themes for the last two versions of Debian. Triage Release Critical bugs Bugs flagged as Release Critical are blocking the release of the upcoming version of Debian. To fix them, it helps to make sure the bug report documents the up-to-date status of the bug, and of its resolution. One does not need to be a programmer to do this work! For example, you can try and reproduce bugs in software you use... or in software you will discover. This helps package maintainers better focus their work. This station will be hosted by Solveig. She has experience in bug triaging, in Debian and elsewhere. Cyril Brulebois, a long-time Debian developer, will provide support and advice upon request. Fix Release Critical bugs There will be a Bug Squashing Party. Where? When? How to register? See https://wiki.debian.org/BSP/2017/05/fr/Paris for the exact address and time. Please register by the end of March if you want to attend this event! If you have any questions, please get in touch with us.

3 March 2017

Markus Koschany: My Free Software Activities in February 2017

Welcome to gambaru.de. Here is my monthly report that covers what I have been doing for Debian. If you re interested in Java, Games and LTS topics, this might be interesting for you. We have reached the end of Stretch s development cycle, a phase called full freeze. That means packages may only migrate to Testing aka Stretch after approval by the release team. Changes must be minimal and only address important or release critical bugs. This is usually the time when I stop uploading new upstream releases to unstable to avoid any disruptions. Of course there are exceptions but if you are unsure best practice is to use experimental instead. A lot of RC bugs are still open and affect the next release. In February I could close five one and triage two more. Debian Games Debian Java Debian LTS This was my twelfth month as a paid contributor and I have been paid to work 13 hours on Debian LTS, a project started by Rapha l Hertzog. In that time I did the following: Non-maintainer uploads Thanks for reading and see you next time.

Michal &#268;iha&#345;: Weblate 2.12

Weblate 2.12 has been released today, few days behind schedule. It brings improved screenshots management, better search and replace features or improved import. Many of the new features were already announced in previous post, where you can find more details about them. Full list of changes: If you are upgrading from older version, please follow our upgrading instructions. You can find more information about Weblate on https://weblate.org, the code is hosted on Github. If you are curious how it looks, you can try it out on demo server. You can login there with demo account using demo password or register your own user. Weblate is also being used on https://hosted.weblate.org/ as official translating service for phpMyAdmin, OsmAnd, Aptoide, FreedomBox, Weblate itself and many other projects. Should you be looking for hosting of translations for your project, I'm happy to host them for you or help with setting it up on your infrastructure. Further development of Weblate would not be possible without people providing donations, thanks to everybody who have helped so far! The roadmap for next release is just being prepared, you can influence this by expressing support for individual issues either by comments or by providing bounty for them.

Filed under: Debian English phpMyAdmin SUSE Weblate 0 comments

2 March 2017

Joey Hess: what I would ask my lawyers about the new Github TOS

The Internet saw Github's new TOS yesterday and collectively shrugged. That's weird.. I don't have any lawyers, but the way Github's new TOS is written, I feel I'd need to consult with lawyers to understand how it might affect the license of my software if I hosted it on Github. And the license of my software is important to me, because it is the legal framework within which my software lives or dies. If I didn't care about my software, I'd be able to shrug this off, but since I do it seems very important indeed, and not worth taking risks with. If I were looking over the TOS with my lawyers, I'd ask these questions...
4 License Grant to Us
This seems to be saying that I'm granting an additional license to my software to Github. Is that right or does "license grant" have some other legal meaning? If the Free Software license I've already licensed my software under allows for everything in this "License Grant to Us", would that be sufficient, or would my software still be licenced under two different licences? There are violations of the GPL that can revoke someone's access to software under that license. Suppose that Github took such an action with my software, and their GPL license was revoked. Would they still have a license to my software under this "License Grant to Us" or not? "Us" is actually defined earlier as "GitHub, Inc., as well as our affiliates, directors, subsidiaries, contractors, licensors, officers, agents, and employees". Does this mean that if someone say, does some brief contracting with Github, that they get my software under this license? Would they still have access to it under that license when the contract work was over? What does "affiliates" mean? Might it include other companies? Is it even legal for a TOS to require a license grant? Don't license grants normally involve an intentional action on the licensor's part, like signing a contract or writing a license down? All I did was loaded a webpage in a browser and saw on the page that by loading it, they say I've accepted the TOS. (I then set about removing everything from Github.) Github's old TOS was not structured as a license grant. What reasons might they have for structuring this TOS in such a way? Am I asking too many questions only 4 words into this thing? Or not enough?
Your Content belongs to you, and you are responsible for Content you post even if it does not belong to you. However, we need the legal right to do things like host it, publish it, and share it. You grant us and our legal successors the right to store and display your Content and make incidental copies as necessary to render the Website and provide the Service.
If this is a software license, the wording seems rather vague compared with other software licenses I've read. How much wiggle room is built into that wording? What are the chances that, if we had a dispute and this came before a judge, that Github's laywers would be able to find a creative reading of this that makes "do things like" include whatever they want? Suppose that my software is javascript code or gets compiled to javascript code. Would this let Github serve up the javascript code for their users to run as part of the process of rendering their website?
That means you're giving us the right to do things like reproduce your content (so we can do things like copy it to our database and make backups); display it (so we can do things like show it to you and other users); modify it (so our server can do things like parse it into a search index); distribute it (so we can do things like share it with other users); and perform it (in case your content is something like music or video).
Suppose that Github modified my software, does not distribute the modified version, but converts it to javascipt code and distributes that to their users to run as part of the process of rendering their website. If my software is AGPL licensed, they would be in violation of that license, but doesn't this additional license allow them to modify and distribute my software in such a way?
This license does not grant GitHub the right to sell your Content or otherwise distribute it outside of our Service.
I see that "Service" is defined as "the applications, software, products, and services provided by GitHub". Does that mean at the time I accept the TOS, or at any point in the future? If Github tomorrow starts providing say, an App Store service, that necessarily involves distribution of software to others, and they put my software in it, would that be allowed by this or not? If that hypothetical Github App Store doesn't sell apps, but licenses access to them for money, would that be allowed under this license that they want to my software?
5 License Grant to Other Users Any Content you post publicly, including issues, comments, and contributions to other Users' repositories, may be viewed by others. By setting your repositories to be viewed publicly, you agree to allow others to view and "fork" your repositories (this means that others may make their own copies of your Content in repositories they control).
Let's say that company Foo does something with my software that violates its GPL license and the license is revoked. So they no longer are allowed to copy my software under the GPL, but it's there on Github. Does this "License Grant to Other Users" give them a different license under which they can still copy my software? The word "fork" has a particular meaning on Github, which often includes modification of the software in a repository. Does this mean that other users could modify my software, even if its regular license didn't allow them to modify it or had been revoked? How would this use of a platform-specific term "fork" be interpreted in this license if it was being analized in a courtroom?
If you set your pages and repositories to be viewed publicly, you grant each User of GitHub a nonexclusive, worldwide license to access your Content through the GitHub Service, and to use, display and perform your Content, and to reproduce your Content solely on GitHub as permitted through GitHub's functionality. You may grant further rights if you adopt a license.
This paragraph seems entirely innocious. So, what does your keen lawyer mind see in it that I don't? How sure are you about your answers to all this? We're fairly sure we know how well the GPL holds up in court; how well would your interpretation of all this hold up? What questions have I forgotten to ask?
And finally, the last question I'd be asking my lawyers: What's your bill come to? That much? Is using Github worth that much to me?

Next.

Previous.