Search Results: "reg"

6 December 2025

Simon Josefsson: Reproducible Guix Container Images

Around a year ago I wrote about Guix Container Images for GitLab CI/CD and these images have served the community well. Besides continous use in CI/CD, these Guix container images are used to confirm reproducibility of the source tarball artifacts in the releases of Libtasn1 v4.20, InetUtils v2.6, Libidn2 v2.3.8, Libidn v1.43, SASL v2.2.2, Guile-GnuTLS v5.0.1, and OATH Toolkit v2.6.13. See how all those release announcements mention a Guix commit? That s the essential supply-chain information about the Guix build environment that allows the artifacts to be re-created. To make sure this is repeatable, the release tarball artifacts are re-created from source code every week in the verify-reproducible-artifacts project, that I wrote about earlier. Guix s time travelling feature make this sustainable to maintain, and hopefully will continue to be able to reproduce the exact same tarball artifacts for years to come. During the last year, unfortunately Guix was removed from Debian stable. My Guix container images were created from Debian with that Guix package. My setup continued to work since the old stage0 Debian+Guix containers were still available. Such a setup is not sustainable, as there will be bit-rot and we don t want to rely on old containers forever, which (after the removal of Guix in Debian) could not be re-produced any more. Let this be a reminder how user-empowering features such as Guix time-travelling is! I have reworked my Guix container image setup, and this post is an update on the current status of this effort. The first step was to re-engineer Debian container images with Guix, and I realized these were useful on their own, and warrant a separate project. A more narrowly scoped project makes will hopefully make it easier to keep them working. Now instead of apt-get install guix they use the official Guix guix-install.sh approach. Read more about that effort in the announcement of Debian with Guix. The second step was to reconsider my approach to generate the Guix images. The earlier design had several stages. First, Debian+Guix containers were created. Then from those containers, a pure Guix container was created. Finally, using the pure Guix container another pure Guix container was created. The idea behind that GCC-like approach was to get to reproducible images that were created from an image that had no Debian left on it. However, I never managed to finish this. Partially because I hadn t realized that every time you build a Guix container image from Guix, you effectively go back in time. When using Guix version X to build a container with Guix on it, it will not put Guix version X into the container but will put whatever version of Guix is available in its package archive, which will be an earlier version, such as version X-N. I had hope to overcome this somehow (running a guix pull in newly generated images may work), but never finished this before Guix was removed from Debian. So what could a better design look like? For efficiency, I had already started experimenting with generating the final images directly from the Debian+Guix images, and after reproducibility bugs were fixed I was able to get to reproducible images. However, I was still concerned that the Debian container could taint the process somehow, and was also concerned about the implied dependency on non-free software in Debian. I ve been using comparative rebuilds using similar distributions to confirm artifact reproducibility for my software projects, comparing builds on Trisquel 11 with Ubuntu 22.04, and AlmaLinux 9 with RockyLinux 9 for example. This works surprisingly well. Including one freedom-respecting distribution like Trisquel will detect if any non-free software has bearing on artifacts. Using different architectures, such as amd64 vs arm64 also help with deeper supply-chain concerns. My conclusion was that I wanted containers with the same Guix commit for both Trisquel and Ubuntu. Given the similarity with Debian, adapting and launching the Guix on Trisquel/Debian project was straight forward. So we now have Trisquel 11/12 and Ubuntu 22.04/24.04 images with the same Guix on them. Do you see where the debian-with-guix and guix-on-dpkg projects are leading to? We are now ready to look at the modernized Guix Container Images project. The tags are the same as before:
registry.gitlab.com/debdistutils/guix/container:latest
registry.gitlab.com/debdistutils/guix/container:slim
registry.gitlab.com/debdistutils/guix/container:extra
registry.gitlab.com/debdistutils/guix/container:gash
The method to create them is different. Now there is a build job that uses the earlier Guix+Trisquel container (for amd64) or Guix+Debian (for arm64, pending Trisquel arm64 containers). The build job create the final containers directly. Next a Ubuntu reproduce job is launched that runs the same commands, failing if it cannot generate the bit-by-bit identical container. Then single-arch images are tested (installing/building GNU hello and building libksba), and then pushed to the GitLab registry, adding multi-arch images in the process. Then the final multi-arch containers are tested by building Guile-GnuTLS and, on success, uploaded to the Docker Hub. How would you use them? A small way to start the container is like this:
jas@kaka:~$ podman run -it --privileged --entrypoint=/bin/sh registry.gitlab.com/debdistutils/guix/container:latest
sh-5.2# env HOME=/ guix describe # https://issues.guix.gnu.org/74949
  guix 21ce6b3
    repository URL: https://git.guix.gnu.org/guix.git
    branch: master
    commit: 21ce6b392ace4c4d22543abc41bd7c22596cd6d2
sh-5.2# 
The need for --entrypoint=/bin/sh is because Guix s pack command sets up the entry point differently than most other containers. This could probably be fixed if people want that, and there may be open bug reports about this. The need for --privileged is more problematic, but is discussed upstream. The above example works fine without it, but running anything more elaborate with guix-daemon installing packages will trigger a fatal error. Speaking of that, here is a snippet of commands that allow you to install Guix packages in the container.
cp -rL /gnu/store/*profile/etc/* /etc/
echo 'root:x:0:0:root:/:/bin/sh' > /etc/passwd
echo 'root:x:0:' > /etc/group
groupadd --system guixbuild
for i in $(seq -w 1 10); do useradd -g guixbuild -G guixbuild -d /var/empty -s $(command -v nologin) -c "Guix build user $i" --system guixbuilder$i; done
env LANG=C.UTF-8 guix-daemon --build-users-group=guixbuild &
guix archive --authorize < /share/guix/ci.guix.gnu.org.pub
guix archive --authorize < /share/guix/bordeaux.guix.gnu.org.pub
guix install hello
GUIX_PROFILE="/var/guix/profiles/per-user/root/guix-profile"
. "$GUIX_PROFILE/etc/profile"
hello
This could be simplified, but we chose to not hard-code in our containers because some of these are things that probably shouldn t be papered over but fixed properly somehow. In some execution environments, you may need to pass --disable-chroot to guix-daemon. To use the containers to build something in a GitLab pipeline, here is an example snippet:
test-amd64-latest-wget-configure-make-libksba:
  image: registry.gitlab.com/debdistutils/guix/container:latest
  before_script:
  - cp -rL /gnu/store/*profile/etc/* /etc/
  - echo 'root:x:0:0:root:/:/bin/sh' > /etc/passwd
  - echo 'root:x:0:' > /etc/group
  - groupadd --system guixbuild
  - for i in $(seq -w 1 10); do useradd -g guixbuild -G guixbuild -d /var/empty -s $(command -v nologin) -c "Guix build user $i" --system guixbuilder$i; done
  - export HOME=/
  - env LANG=C.UTF-8 guix-daemon --build-users-group=guixbuild &
  - guix archive --authorize < /share/guix/ci.guix.gnu.org.pub
  - guix archive --authorize < /share/guix/bordeaux.guix.gnu.org.pub
  - guix describe
  - guix install libgpg-error
  - GUIX_PROFILE="//.guix-profile"
  - . "$GUIX_PROFILE/etc/profile"
  script:
  - wget https://www.gnupg.org/ftp/gcrypt/libksba/libksba-1.6.7.tar.bz2
  - tar xfa libksba-1.6.7.tar.bz2
  - cd libksba-1.6.7
  - ./configure
  - make V=1
  - make check VERBOSE=t V=1

More help on the project page for the Guix Container Images. That s it for tonight folks, and remember, Happy Hacking!

Taavi V n nen: How to import a new Wikipedia language edition (in hard mode)

I created the latest Wikipedia language edition, the Toki Pona Wikipedia, last month. Unlike most other wikis which start their lives in the Wikimedia Incubator before the full wiki is created, in this case the community had been using a completely external MediaWiki site to build the wiki before it was approved as a "proper" Wikipedia wiki,1 and now that external wiki needed to be imported to the newly created Wikimedia-hosted wiki. (As far as I'm aware, the last and previously only time an external wiki has been imported to a Wikimedia project was in 2013 when Wikitravel was forked as Wikivoyage.) Creating a Wikimedia wiki these days is actually pretty straightforward, at least when compared to what it used to be like a couple of years ago. Today the process mostly involves using a script to generate two configuration changes, one to add the basic configuration for a wiki to operate and an another to add the wiki to the list of all wikis that exist, and then running a script to create the wiki database in between of deploying those two configuration changes. And then you wait half an hour while the script to tell all Wikidata client wikis about the new wiki runs on one wiki at a time. The primary technical challenge in importing a third-party wiki is that there's no SUL making sure that a single username maps to the same account on both wikis. This means that the usual strategy of using the functionality I wrote in CentralAuth to manually create local accounts can't be used as is, and so we needed to come up with a new way of matching everyone's contributions to their existing Wikimedia accounts. (Side note: While the user-facing interface tries to present a single "global" user account that can be used on all public Wikimedia wikis, in reality the account management layer in CentralAuth is mostly just a glue layer to link together individual "local" accounts on each wiki that the user has ever visited. These local accounts have independent user ID numbers for example I am user #35938993 on the English Wikipedia but #4 on the new Toki Pona Wikipedia and are what most of MediaWiki code interacts with except for a few features specifically designed with cross-wiki usage in mind. This distinction is also still very much present and visible in the various administrative and anti-abuse workflows.) The approach we ended up choosing was to re-write the dump file before importing, so that a hypothetical account called $Name would be turned $Name~wikipesija.org after the import.2 We also created empty user accounts that would take ownership of the edits to be imported so that we could use the standard account management tools on them later on. MediaWiki supports importing contributions without a local account to attribute them to, but it doesn't seem to be possible to convert an imported actor3 to a regular user later on which we wanted to keep as a possibility, even with the minor downside of creating a few hundred users that'll likely never get touched again later. We also made specific decisions to add the username suffix to everyone, not to just those names that'd conflicted with existing SUL accounts, and to deal with renaming users that wanted their contributions linked to an existing SUL account only after the import. This both reduced complexity and thus risk from the import phase, which already had much more unknowns compared to the rest of the process, but also were much better options ethically as well: suffixing all names meant we would not imply that those people chose to be Wikimedians with those specific usernames (when in reality it was us choosing to import those edits to the Wikimedia universe), and doing renames using the standard MediaWiki account management tooling meant that it produced the normal public log entries that all other MediaWiki administrative actions create. With all of the edits imported, the only major thing remaining was doing those merges I mentioned earlier to attribute imported edits to people's existing SUL accounts. Thankfully, the local account -based system makes it actually pretty simple. Usually CentralAuth prevents renaming individual local accounts that are attached to a global account, but that check can be bypassed with a maintenance script or a privileged enough account. Renaming the user automatically detached it from the previous global account, after which an another maintenance script could be used to attach the user to the correct global account.

  1. That external site was a fork of a fork of the original Toki Pona Wikipedia that was closed in 2005. And because cool URIs don't change, we made the the URLs that the old Wikipedia was using work again. Try it: https://art-tokipona.wikipedia.org.
  2. wikipesija.org was the domain where the old third-party wiki was hosted on, and ~ was used as a separator character in usernames during the SUL finalization in the early 2010s so using it here felt appropriate as well.
  3. An actor is a MediaWiki term and a database table referring to anything that can do edits or logged actions. Usually an actor is a user account or an IP address, but an imported user name in a specific format can also be represented as an actor.

2 December 2025

Simon Josefsson: Guix on Trisquel & Ubuntu for Reproducible CI/CD Artifacts

Last week I published Guix on Debian container images that prepared for today s announcement of Guix on Trisquel/Ubuntu container images. I have published images with reasonably modern Guix for Trisquel 11 aramo, Trisquel 12 ecne, Ubuntu 22.04 and Ubuntu 24.04. The Ubuntu images are available for both amd64 and arm64, but unfortunately Trisquel arm64 containers aren t available yet so they are only for amd64. Images for ppc64el and riscv64 are work in progress. The currently supported container names:
registry.gitlab.com/debdistutils/guix/guix-on-dpkg:trisquel11-guix
registry.gitlab.com/debdistutils/guix/guix-on-dpkg:trisquel12-guix
registry.gitlab.com/debdistutils/guix/guix-on-dpkg:ubuntu22.04-guix
registry.gitlab.com/debdistutils/guix/guix-on-dpkg:ubuntu24.04-guix
Or you prefer guix-on-dpkg on Docker Hub:
docker.io/jas4711/guix-on-dpkg:trisquel11-guix
docker.io/jas4711/guix-on-dpkg:trisquel12-guix
docker.io/jas4711/guix-on-dpkg:ubuntu22.04-guix
docker.io/jas4711/guix-on-dpkg:ubuntu24.04-guix
You may use them as follows. See the guix-on-dpkg README for how to start guix-daemon and installing packages.
jas@kaka:~$ podman run -it --hostname guix --rm registry.gitlab.com/debdistutils/guix/guix-on-dpkg:trisquel11-guix
root@guix:/# head -1 /etc/os-release 
NAME="Trisquel GNU/Linux"
root@guix:/# guix describe
  guix 136fc8b
    repository URL: https://gitlab.com/debdistutils/guix/mirror.git
    branch: master
    commit: 136fc8bfe91a64d28b6c54cf8f5930ffe787c16e
root@guix:/# 
You may now be asking yourself: why? Fear not, gentle reader, because having two container images of roughly similar software is a great tool for attempting to build software artifacts reproducible, and comparing the result to spot differences. Obviously. I have been using this pattern to get reproducible tarball artifacts of several software releases for around a year and half, since libntlm 1.8. Let s walk through how to setup a CI/CD pipeline that will build a piece of software, in four different jobs for Trisquel 11/12 and Ubuntu 22.04/24.04. I am in the process of learning Codeberg/Forgejo CI/CD, so I am still using GitLab CI/CD here, but the concepts should be the same regardless of platform. Let s start by defining a job skeleton:
.guile-gnutls: &guile-gnutls
  before_script:
  - /root/.config/guix/current/bin/guix-daemon --version
  - env LC_ALL=C.UTF-8 /root/.config/guix/current/bin/guix-daemon --build-users-group=guixbuild $GUIX_DAEMON_ARGS &
  - GUIX_PROFILE=/root/.config/guix/current; . "$GUIX_PROFILE/etc/profile"
  - type guix
  - guix --version
  - guix describe
  - time guix install --verbosity=0 wget gcc-toolchain autoconf automake libtool gnutls guile pkg-config
  - time apt-get update
  - time apt-get install -y make git texinfo
  - GUIX_PROFILE="/root/.guix-profile"; . "$GUIX_PROFILE/etc/profile"
  script:
  - git clone https://codeberg.org/guile-gnutls/guile-gnutls.git
  - cd guile-gnutls
  - git checkout v5.0.1
  - ./bootstrap
  - ./configure
  - make V=1
  - make V=1 check VERBOSE=t
  - make V=1 dist
  after_script:
  - mkdir -pv out/$CI_JOB_NAME_SLUG/src
  - mv -v guile-gnutls/*-src.tar.* out/$CI_JOB_NAME_SLUG/src/
  - mv -v guile-gnutls/*.tar.* out/$CI_JOB_NAME_SLUG/
  artifacts:
    paths:
    - out/**
This installs some packages, clones guile-gnutls (it could be any project, that s just an example), build it and return tarball artifacts. The artifacts are the git-archive and make dist tarballs. Let s instantiate the skeleton into four jobs, running the Trisquel 11/12 jobs on amd64 and the Ubuntu 22.04/24.04 jobs on arm64 for fun.
guile-gnutls-trisquel11-amd64:
  tags: [ saas-linux-medium-amd64 ]
  image: registry.gitlab.com/debdistutils/guix/guix-on-dpkg:trisquel11-guix
  extends: .guile-gnutls
guile-gnutls-ubuntu22.04-arm64:
  tags: [ saas-linux-medium-arm64 ]
  image: registry.gitlab.com/debdistutils/guix/guix-on-dpkg:ubuntu22.04-guix
  extends: .guile-gnutls
guile-gnutls-trisquel12-amd64:
  tags: [ saas-linux-medium-amd64 ]
  image: registry.gitlab.com/debdistutils/guix/guix-on-dpkg:trisquel12-guix
  extends: .guile-gnutls
guile-gnutls-ubuntu24.04-arm64:
  tags: [ saas-linux-medium-arm64 ]
  image: registry.gitlab.com/debdistutils/guix/guix-on-dpkg:ubuntu24.04-guix
  extends: .guile-gnutls
Running this pipeline will result in artifacts that you want to confirm for reproducibility. Let s add a pipeline job to do the comparison:
guile-gnutls-compare:
  image: alpine:latest
  needs: [ guile-gnutls-trisquel11-amd64,
           guile-gnutls-trisquel12-amd64,
           guile-gnutls-ubuntu22.04-arm64,
           guile-gnutls-ubuntu24.04-arm64 ]
  script:
  - cd out
  - sha256sum */*.tar.* */*/*.tar.*   sort   grep    -- -src.tar.
  - sha256sum */*.tar.* */*/*.tar.*   sort   grep -v -- -src.tar.
  - sha256sum */*.tar.* */*/*.tar.*   sort   uniq -c -w64   sort -rn
  - sha256sum */*.tar.* */*/*.tar.*   grep    -- -src.tar.   sort   uniq -c -w64   grep -v '^      1 '
  - sha256sum */*.tar.* */*/*.tar.*   grep -v -- -src.tar.   sort   uniq -c -w64   grep -v '^      1 '
# Confirm modern git-archive tarball reproducibility
  - cmp guile-gnutls-trisquel12-amd64/src/*.tar.gz guile-gnutls-ubuntu24-04-arm64/src/*.tar.gz
# Confirm old git-archive (export-subst but long git describe) tarball reproducibility
  - cmp guile-gnutls-trisquel11-amd64/src/*.tar.gz guile-gnutls-ubuntu22-04-arm64/src/*.tar.gz
# Confirm 'make dist' generated tarball reproducibility
  - cmp guile-gnutls-trisquel11-amd64/*.tar.gz guile-gnutls-ubuntu22-04-arm64/*.tar.gz
  - cmp guile-gnutls-trisquel12-amd64/*.tar.gz guile-gnutls-ubuntu24-04-arm64/*.tar.gz
  artifacts:
    when: always
    paths:
    - ./out/**
Look how beautiful, almost like ASCII art! The commands print SHA256 checksums of the artifacts, sorted in a couple of ways, and then proceeds to compare relevant artifacts. What would the output of such a run be, you may wonder? You can look for yourself in the guix-on-dpkg pipeline but here is the gist of it:
$ cd out
$ sha256sum */*.tar.* */*/*.tar.*   sort   grep    -- -src.tar.
79bc24143ba083819b36822eacb8f9e15a15a543e1257c53d30204e9ffec7aca  guile-gnutls-trisquel11-amd64/src/guile-gnutls-v5.0.1-src.tar.gz
79bc24143ba083819b36822eacb8f9e15a15a543e1257c53d30204e9ffec7aca  guile-gnutls-ubuntu22-04-arm64/src/guile-gnutls-v5.0.1-src.tar.gz
b190047cee068f6b22a5e8d49ca49a2425ad4593901b9ac8940f8842ba7f164f  guile-gnutls-trisquel12-amd64/src/guile-gnutls-v5.0.1-src.tar.gz
b190047cee068f6b22a5e8d49ca49a2425ad4593901b9ac8940f8842ba7f164f  guile-gnutls-ubuntu24-04-arm64/src/guile-gnutls-v5.0.1-src.tar.gz
$ sha256sum */*.tar.* */*/*.tar.*   sort   grep -v -- -src.tar.
1e8d107ad534b85f30e432d5c98bf599aab5d8db5f996c2530aabe91f203018a  guile-gnutls-trisquel11-amd64/guile-gnutls-5.0.1.tar.gz
1e8d107ad534b85f30e432d5c98bf599aab5d8db5f996c2530aabe91f203018a  guile-gnutls-ubuntu22-04-arm64/guile-gnutls-5.0.1.tar.gz
bc2df2d868f141bca5f3625aa146aa0f24871f6dcf0b48ff497eba3bb5219b84  guile-gnutls-trisquel12-amd64/guile-gnutls-5.0.1.tar.gz
bc2df2d868f141bca5f3625aa146aa0f24871f6dcf0b48ff497eba3bb5219b84  guile-gnutls-ubuntu24-04-arm64/guile-gnutls-5.0.1.tar.gz
$ sha256sum */*.tar.* */*/*.tar.*   sort   uniq -c -w64   sort -rn
      2 bc2df2d868f141bca5f3625aa146aa0f24871f6dcf0b48ff497eba3bb5219b84  guile-gnutls-trisquel12-amd64/guile-gnutls-5.0.1.tar.gz
      2 b190047cee068f6b22a5e8d49ca49a2425ad4593901b9ac8940f8842ba7f164f  guile-gnutls-trisquel12-amd64/src/guile-gnutls-v5.0.1-src.tar.gz
      2 79bc24143ba083819b36822eacb8f9e15a15a543e1257c53d30204e9ffec7aca  guile-gnutls-trisquel11-amd64/src/guile-gnutls-v5.0.1-src.tar.gz
      2 1e8d107ad534b85f30e432d5c98bf599aab5d8db5f996c2530aabe91f203018a  guile-gnutls-trisquel11-amd64/guile-gnutls-5.0.1.tar.gz
$ sha256sum */*.tar.* */*/*.tar.*   grep    -- -src.tar.   sort   uniq -c -w64   grep -v '^      1 '
      2 79bc24143ba083819b36822eacb8f9e15a15a543e1257c53d30204e9ffec7aca  guile-gnutls-trisquel11-amd64/src/guile-gnutls-v5.0.1-src.tar.gz
      2 b190047cee068f6b22a5e8d49ca49a2425ad4593901b9ac8940f8842ba7f164f  guile-gnutls-trisquel12-amd64/src/guile-gnutls-v5.0.1-src.tar.gz
$ sha256sum */*.tar.* */*/*.tar.*   grep -v -- -src.tar.   sort   uniq -c -w64   grep -v '^      1 '
      2 1e8d107ad534b85f30e432d5c98bf599aab5d8db5f996c2530aabe91f203018a  guile-gnutls-trisquel11-amd64/guile-gnutls-5.0.1.tar.gz
      2 bc2df2d868f141bca5f3625aa146aa0f24871f6dcf0b48ff497eba3bb5219b84  guile-gnutls-trisquel12-amd64/guile-gnutls-5.0.1.tar.gz
$ cmp guile-gnutls-trisquel12-amd64/src/*.tar.gz guile-gnutls-ubuntu24-04-arm64/src/*.tar.gz
$ cmp guile-gnutls-trisquel11-amd64/src/*.tar.gz guile-gnutls-ubuntu22-04-arm64/src/*.tar.gz
$ cmp guile-gnutls-trisquel11-amd64/*.tar.gz guile-gnutls-ubuntu22-04-arm64/*.tar.gz
$ cmp guile-gnutls-trisquel12-amd64/*.tar.gz guile-gnutls-ubuntu24-04-arm64/*.tar.gz
That s it for today, but stay tuned for more updates on using Guix in containers, and remember; Happy Hacking!

30 November 2025

Utkarsh Gupta: FOSS Activites in November 2025

Here s my monthly but brief update about the activities I ve done in the FOSS world.

Debian
Whilst I didn t get a chance to do much, here are still a few things that I worked on:
  • Did a few sessions with the new DFSG team to help kickstart things, et al.
  • Assited a few folks in getting their patches submitted via Salsa.
  • Mentoring for newcomers.
  • Moderation of -project mailing list.

Ubuntu
I joined Canonical to work on Ubuntu full-time back in February 2021. Whilst I can t give a full, detailed list of things I did, here s a quick TL;DR of what I did:
  • Successfully released Resolute Snapshot 1!
    • This one was particularly interesting as it was done without the ISO tracker and cdimage access.
    • There are some wrinkles that need ironing out for the next snapshot.
  • Resolute Raccoon is now fully and formally open.
  • Assisted a bunch of folks with my Archive Admin and Release team hats to:
    • review NEW packages for Ubuntu Studio.
    • remove old binaries that are stalling transition and/or migration.
    • LTS requalification of Ubuntu flavours.
    • bootstrapping dotnet-10 packages.
    • removal of openjdk-19 from Jammy, which sparked some interesting discussions.

Debian (E)LTS
This month I have worked 22 hours on Debian Long Term Support (LTS) and on its sister Extended LTS project and did the following things:
  • wordpress: There were multiple vulnerabilities reported in Wordpress, leading to Sent Data & Cross-site Scripting.
    • [bookworm]: Roberto rightly pointed out that the upload to bookworm hadn t gone through last month, so I re-uploaded wordpress/6.1.9+dfsg1-0+deb12u1 to bookworm-security.
    • This is now released as DSA 6075-1.
  • ruby-rack: There were multiple vulnerabilities reported in Rack, leading to DoS (memory exhaustion) and proxy bypass.
    • [ELTS]: Last month I had backported fixes for CVE-2025-46727 & CVE-2025-32441 to buster and stretch but the other backports were being a bit tricky due to really old versions.
    • I spent a bit more time but there s a lot to demystify. Gonna take a bit of break from this one and come back to this after doing other updates. Might even consider sending a RFH to the list.
  • libwebsockets: Multiple issues were reported in LWS causing denial of service and stack-based buffer overflow.
  • mako: It was found that Mako, a Python template library, was vulnerable to a denial of service attack via crafted regular expressions.
    • [LTS]: For bullseye, these were fixed via 1.1.3+ds1-2+deb11u1. And released as DLA 4393-1.
    • Backporting tests was an interesting exercise as I had to make them compatible with the bullseye version. :)
  • ceph: Affected by CVE-2024-47866, using the argument x-amz-copy-source to put an object and specifying an empty string as its content leads to the RGW daemon crashing, resulting in a DoS attack.
    • [LTS]: Whilst the patch is straightforward, backports are a bit tricky. I ve prepared the update but would like to reach out to zigo, the maintainer, to make sure nothing regresses.
    • [ELTS]: Same as LTS, I d like to get a quick review and upload to LTS first before I start staging uploads for ELTS.
  • [LTS] Attended the monthly LTS meeting on IRC. Summary here.
    • It was also followed by a 50-minute post-meeting technical discussion/question session.
  • [E/LTS] Monitored discussions on mailing lists, IRC, and all the documentation updates. Thanks, Sylvain, for a great documentation summary.

Until next time.
:wq for today.

Otto Kek l inen: DEP-18: A proposal for Git-based collaboration in Debian

Featured image of post DEP-18: A proposal for Git-based collaboration in DebianI am a huge fan of Git, as I have witnessed how it has made software development so much more productive compared to the pre-2010s era. I wish all Debian source code were in Git to reap the full benefits. Git is not perfect, as it requires significant effort to learn properly, and the ecosystem is complex with even more things to learn ranging from cryptographic signatures and commit hooks to Git-assisted code review best practices, forge websites, and CI systems. Sure, there is still room to optimize its use, but Git certainly has proven itself and is now the industry standard. Thus, some readers might be surprised to learn that Debian development in 2025 is not actually based on Git. In Debian, the version control is done by the Debian archive itself. Each commit is a new upload to the archive, and the commit message is the debian/changelog entry. The commit log is available at snapshots.debian.org. In practice, most Debian Developers (people who have the credentials to upload to the Debian archive) do use Git and host their packaging source code on salsa.debian.org the GitLab instance of Debian. This is, however, based on each DD s personal preferences. The Debian project does not have any policy requiring that packages be hosted on salsa.debian.org or be in version control at all.

Is collaborative software development possible without git and version control software? Debian, however, has some peculiarities that may be surprising to people who have grown accustomed to GitHub, GitLab or various company-internal code review systems. In Debian:
  • The source code of the next upload is not public but resides only on the developer s laptop.
  • Code contributions are plain patch files, based on the latest revision released in the Debian archive (where the unstable area is equivalent to the main development branch).
  • These patches are submitted by email to a bug tracker that does no validation or testing whatsoever.
  • Developers applying these patches typically have elaborate Mutt or Emacs setups to facilitate fetching patches from email.
  • There is no public staging area, no concept of rebasing patches or withdrawing a patch and replacing it with a better version.
  • The submitter won t see any progress information until a notification email arrives after a new version has been uploaded to the Debian archive.
This system has served Debian for three decades. It is not broken, but using the package archive just feels well, archaic. There is a more efficient way, and indeed the majority of Debian packages have a metadata field Vcs-Git that advertises which version control repository the maintainer uses. However, newcomers to Debian are surprised to notice that not all packages are hosted on salsa.debian.org but at various random places with their own account and code submission systems, and there is nothing enforcing or even warning if the code there is out of sync with what was uploaded to Debian. Any Debian Developer can at any time upload a new package with whatever changes, bypassing the Git repository, even when the package advertised a Git repository. All PGP signed commits, Git tags and other information in the Git repository are just extras currently, as the Debian archive does not enforce or validate anything about them. This also makes contributing to multiple packages in parallel hard. One can t just go on salsa.debian.org and fork a bunch of repositories and submit Merge Requests. Currently, the only reliable way is to download source packages from Debian unstable, develop patches on top of them, and send the final version as a plain patch file by email to the Debian bug tracker. To my knowledge, no system exists to facilitate working with the patches in the bug tracker, such as rebasing patches 6 months later to detect if they or equivalent changes were applied or if sending refreshed versions is needed. To newcomers in Debian, it is even more surprising that there are packages that are on salsa.debian.org but have the Merge Requests feature disabled. This is often because the maintainer does not want to receive notification emails about new Merge Requests, but rather just emails from bugs.debian.org. This may sound arrogant, but keep in mind that these developers put in the effort to set up their Mutt/Emacs workflow for the existing Debian process, and extending it to work with GitLab notifications is not trivial. There are also purists who want to do everything via the command-line (without having to open a browser, run JavaScript and maintain a live Internet connection), and tools like glab are not convenient enough for the full workflow.

Inefficient ways of working prevent Debian from flourishing I would claim, based on my personal experiences from the past 10+ years as a Debian Developer, that the lack of high-quality and productive tooling is seriously harming Debian. The current methods of collaboration are cumbersome for aspiring contributors to learn and suboptimal to use for both new and seasoned contributors. There are no exit interviews for contributors who left Debian, no comprehensive data on reasons to contribute or stop contributing, nor are there any metrics tracking how many people tried but failed to contribute to Debian. Some data points to support my concerns do exist:
  • The contributor database shows that the number of contributors is growing slower than Debian s popularity.
  • Most packages are maintained by one person working alone (just pick any package at random and look at the upload history).

Debian should embrace git, but decision-making is slow Debian is all about community and collaboration. One would assume that Debian prioritized above all making collaboration tools and processes simpler, faster and less error-prone, as it would help both current and future package maintainers. Yet, it isn t so, due to some reasons unique to Debian. There is no single company or entity running Debian, and it has managed to operate as a pure meritocracy and do-cracy for over 30 years. This is impressive and admirable. Unfortunately, some of the infrastructure and technical processes are also nearly 30 years old and very difficult to change for the same reason: the nature of Debian s distributed decision-making process. As a software developer and manager with 25+ years of experience, I strongly feel that developing software collaboratively using Git is a major step forward that Debian needs to take, in one form or another, and I hope to see other DDs voice their support if they agree.

Debian Enhancement Proposal 18 Following how consensus is achieved in Debian, I started drafting DEP-18 in 2024, and it is currently awaiting enough thumbs up at https://salsa.debian.org/dep-team/deps/-/merge_requests/21 to get into CANDIDATE status next. In summary, the DEP-18 proposes that everyone keen on collaborating should:
  1. Maintain Debian packaging sources in Git on Salsa.
  2. Use Merge Requests to show your work and to get reviews.
  3. Run Salsa CI before upload.
The principles above are not novel. According to stats at e.g. trends.debian.net, and UDD, ~93% of all Debian source packages are already hosted on salsa.debian.org. As of June 1st, 2025, only 1640 source packages remain that are not hosted on Salsa. The purpose of DEP-18 is to state in writing what Debian is currently doing for most packages, and thus express what among others new contributors should be learning and doing, so basic collaboration is smooth and free from structural obstacles. Most packages are also already allowing Merge Requests and using Salsa CI, but there hasn t been any written recommendation anywhere in Debian to do so. The Debian Policy (v.4.7.2) does not even mention the word Salsa a single time. The current process documentation on how to do non-maintainer uploads or salvaging packages are all based on uploading packages to the archive, without any consideration of using git-based collaboration such as posting a Merge Request first. Personally I feel posting a Merge Request would be a better approach, as it would invite collaborators to discuss and provide code reviews. If there are no responses, the submitter can proceed to merge, but compared to direct uploads to the Debian archive, the Merge Request practice at least tries to offer a time and place for discussions and reviews to happen. It could very well be that in the future somebody comes up with a new packaging format that makes upstream source package management easier, or a monorepo with all packages, or some other future structures or processes. Having a DEP to state how to do things now does not prevent people from experimenting and innovating if they intentionally want to do that. The DEP is merely an expression of the minimal common denominators in the packaging workflow that maintainers and contributors should follow, unless they know better.

Transparency and collaboration Among the DEP-18 recommendations is:
The recommended first step in contributing to a package is to use the built-in Fork feature on Salsa. This serves two purposes. Primarily, it allows any contributor to publish their Git branches and submit them as Merge Requests. Additionally, the mere existence of a list of Forks enables contributors to discover each other, and in rare cases when the original package is not accepting improvements, collaboration could arise among the contributors and potentially lead to permanent forks in the general meaning. Forking is a fundamental part of the dynamics in open source that helps drive quality and agreement. The ability to fork ultimately serves as the last line of defense of users rights. Git supports this by making both temporary and permanent forks easy to create and maintain.
Further, it states:
Debian packaging work should be reasonably transparent and public to allow contributors to participate. A maintainer should push their pending changes to Salsa at regular intervals, so that a potential contributor can discover if a particular change has already been made or a bug has been fixed in version control, and thus avoid duplicate work. Debian maintainers should make reasonable efforts to publish planned changes as Merge Requests on Salsa and solicit feedback and reviews. While pushing changes directly on the main Git branch is the fastest workflow, second only to uploading all changes directly to Debian repositories, it is not an inclusive way to develop software. Even packages that are maintained by a single maintainer should at least occasionally publish Merge Requests to allow new contributors to step up and participate.
I think these are key aspects leading to transparency and true open source collaboration. Even though this talks about Salsa which is based on GitLab the concepts are universal and will work also on other forges, like Forgejo or GitHub. The point is that sharing work-in-progress on a real-time platform, with CI and other supporting features, empowers and motivates people to iterate on code collaboratively. As an example of an anti-pattern, Oracle MySQL publishes the source code for all their releases and is license-compliant, but as they don t publish their Git commits in real-time, it does not feel like a real open source project. Non-Oracle employees are not motivated to participate as second-class developers who are kept in the dark. Debian should embrace git and sharing work in real-time, embodying a true open source spirit.

Recommend, not force Note that the Debian Enhancement Proposals are not binding. Only the Debian Policy and Technical Committee decisions carry that weight. The nature of collaboration is voluntary anyway, so the DEP does not need to force anything on people who don t want to use salsa.debian.org. The DEP-18 is also not a guide for package maintainers. I have my own views and have written detailed guides in blog articles if you want to read more on, for example, how to do code reviews efficiently. Within DEP-18, there is plenty of room to work in many different ways, and it does not try to force one single workflow. The goal here is to simply have agreed-upon minimal common denominators among those who are keen to collaborate using salsa.debian.org, not to dictate a complete code submission workflow. Once we reach this, there will hopefully be less friction in the most basic and recurring collaboration tasks, giving DDs more energy to improve other processes or just invest in having more and newer packages for Debian users to enjoy.

Next steps In addition to lengthy online discussions on mailing lists and DEP reviews, I also presented on this topic at DebConf 2025 in Brest, France. Unfortunately the recording is not yet up on Peertube. The feedback has been overwhelmingly positive. However, there are a few loud and very negative voices that cannot be ignored. Maintaining a Linux distribution at the scale and complexity of Debian requires extraordinary talent and dedication, and people doing this kind of work often have strong views, most of the time for good reasons. We do not want to alienate existing key contributors with new processes, so maximum consensus is desirable. We also need more data on what the 1000+ current Debian Developers view as a good process to avoid being skewed by a loud minority. If you are a current or aspiring Debian Developer, please add a thumbs up if you think I should continue with this effort (or a thumbs down if not) on the Merge Request that would make DEP-18 have candidate status. There is also technical work to do. Increased Git use will obviously lead to growing adoption of the new tag2upload feature, which will need to get full git-buildpackage support so it can integrate into salsa.debian.org without turning off Debian packaging security features. The git-buildpackage tool itself also needs various improvements, such as making contributing to multiple different packages with various levels of diligence in debian/gbp.conf maintenance less error-prone. Eventually, if it starts looking like all Debian packages might get hosted on salsa.debian.org, I would also start building a review.debian.org website to facilitate code review aspects that are unique to Debian, such as tracking Merge Requests across GitLab projects in ways GitLab can t do, highlighting which submissions need review most urgently, feeding code reviews and approvals into the contributors.debian.org database for better attribution, and so forth. Details on this vision will be in a later blog post, so subscribe to updates!

28 November 2025

Simon Josefsson: Container Images for Debian with Guix

The debian-with-guix-container project build and publish container images of Debian GNU/Linux stable with GNU Guix installed. The images are like normal Debian stable containers but have the guix tool and a reasonable fresh guix pull. Supported architectures include amd64 and arm64. The multi-arch container is called: registry.gitlab.com/debdistutils/guix/debian-with-guix-container:stable It may also be accessed via debian-with-guix at Docker Hub as: docker.io/jas4711/debian-with-guix:stable The container images may be used like this:
$ podman run --privileged -it --hostname guix --rm registry.gitlab.com/debdistutils/guix/debian-with-guix-container:stable
root@guix:/# hello
bash: hello: command not found
root@guix:/# guix describe
  guix c9eb69d
    repository URL: https://gitlab.com/debdistutils/guix/mirror.git
    branch: master
    commit: c9eb69ddbf05e77300b59f49f4bb5aa50cae0892
root@guix:/# LC_ALL=C.UTF-8 /root/.config/guix/current/bin/guix-daemon --build-users-group=guixbuild &
[1] 21
root@guix:/# GUIX_PROFILE=/root/.config/guix/current; . "$GUIX_PROFILE/etc/profile"
root@guix:/# guix describe
Generation 2    Nov 28 2025 10:14:11    (current)
  guix c9eb69d
    repository URL: https://gitlab.com/debdistutils/guix/mirror.git
    branch: master
    commit: c9eb69ddbf05e77300b59f49f4bb5aa50cae0892
root@guix:/# guix install --verbosity=0 hello
accepted connection from pid 55, user root
The following package will be installed:
   hello 2.12.2
hint: Consider setting the necessary environment variables by running:
     GUIX_PROFILE="/root/.guix-profile"
     . "$GUIX_PROFILE/etc/profile"
Alternately, see  guix package --search-paths -p "/root/.guix-profile"'.
root@guix:/# GUIX_PROFILE="/root/.guix-profile"
root@guix:/# . "$GUIX_PROFILE/etc/profile"
root@guix:/# hello
Hello, world!
root@guix:/# 
Below is an example GitLab pipeline job that demonstrate how to run guix install to install additional dependencies, and then download and build a package that pick up the installed package from the system.
test-wget-configure-make-libksba-amd64:
  image: registry.gitlab.com/debdistutils/guix/debian-with-guix-container:stable
  before_script:
  - env LC_ALL=C.UTF-8 /root/.config/guix/current/bin/guix-daemon --build-users-group=guixbuild $GUIX_DAEMON_ARG &
  - GUIX_PROFILE=/root/.config/guix/current; . "$GUIX_PROFILE/etc/profile"
  - guix describe
  - guix install libgpg-error
  - GUIX_PROFILE="/root/.guix-profile"; . "$GUIX_PROFILE/etc/profile"
  - apt-get install --update -y --no-install-recommends build-essential wget ca-certificates bzip2
  script:
  - wget https://www.gnupg.org/ftp/gcrypt/libksba/libksba-1.6.7.tar.bz2
  - tar xfa libksba-1.6.7.tar.bz2
  - cd libksba-1.6.7
  - ./configure
  - make V=1
  - make check VERBOSE=t V=1

The images were initially created for use in GitLab CI/CD Pipelines but should work for any use. The images are built in a GitLab CI/CD pipeline, see .gitlab-ci.yml. The containers are derived from official Debian stable images with Guix installed and a successful run of guix pull, built using buildah invoked from build.sh using image/Containerfile that runs image/setup.sh. The pipeline also push images to the GitLab container registry, and then also to Docker Hub. Guix binaries are downloaded from the Guix binary tarballs project because of upstream download site availability and bandwidth concerns. Enjoy these images! Hopefully they can help you overcome the loss of Guix in Debian which made it a mere apt-get install guix away before. There are several things that may be improved further. An alternative to using podman --privileged is to use --security-opt seccomp=unconfined --cap-add=CAP_SYS_ADMIN,CAP_NET_ADMIN which may be slightly more fine-grained. For ppc64el support I ran into an error message that I wasn t able to resolve:
guix pull: error: while setting up the build environment: cannot set host name: Operation not permitted
For riscv64, I can t even find a Guix riscv64 binary tarball for download, is there one anywhere? For arm64 containers, it seems that you need to start guix-daemon with --disable-chroot to get something to work, at least on GitLab.com s shared runners, otherwise you will get this error message:
guix install: error: clone: Invalid argument
Building the images themselves also require disabling some security functionality, and I was not able to build images with buildah without providing --cap-add=CAP_SYS_ADMIN,CAP_NET_ADMIN otherwise there were errors like this:
guix pull: error: cloning builder process: Operation not permitted
guix pull: error: clone: Operation not permitted
guix pull: error: while setting up the build environment: cannot set loopback interface flags: Operation not permitted
Finally on amd64 it seems --security-opt seccomp=unconfined is necessary, otherwise there is an error message like this, even if you use --disable-chroot:
guix pull: error: while setting up the child process: in phase setPersonality: cannot set personality: Function not implemented
This particular error is discussed upstream, but I think generally that these error suggest that guix-daemon could use more optional use of features: if some particular feature is not available, gracefully fall back to another mode of operation, instead of exiting with an error. Of course, it should never fall back to an insecure mode of operation, unless the user requests that. Happy Hacking!

26 November 2025

Dirk Eddelbuettel: tidyCpp 0.0.8 on CRAN: Maintenance

Another maintenance release of the tidyCpp package arrived on CRAN this morning, the first in about two years. The packages offers a clean C++ layer (as well as one small C++ helper class) on top of the C API for R which aims to make use of this robust (if awkward) C API a little easier and more consistent. See the (now updated, see below) vignette for motivating examples. This release contains mostly internal upkeep of the usual type: refreshing continuous integration, updating links, switching to Authors@R. But as we wrap the C API of R here too, changes made in R-devel this week affected the two reverse-dependencies (i.e. downstream ) packages (of mine) using this. So we commented-out the definitions for the five now-hidden accessors so that these downstream packages can build again under R-devel. The NEWS entry follows.

Changes in tidyCpp version 0.0.8 (2025-11-25)
  • Updated continuous integration setup several times
  • Updated README.md documentation with link to R API site
  • Updated example snippets to use of Protect
  • Updated documentation in defines.h header
  • Updated internals.h header reflecting in R API changes

As it happens, hours after the release at CRAN a helpful issue ticket was opened detailing more than a handful of typos in the vignette. This has been corrected, and I am not exporting the vignette via GitHub Pages so the motivating examples vignette contains the corrections. Thanks to my CRANberries, there is also a diffstat report for this release. For questions, suggestions, or issues please use the issue tracker at the GitHub repo. If you like this or other open-source work I do, you can now sponsor me at GitHub.

This post by Dirk Eddelbuettel originated on his Thinking inside the box blog. Please report excessive re-aggregation in third-party for-profit settings.

25 November 2025

Russell Coker: EDID and my 8K TV

I previously blogged about buying a refurbished Hisense 65u80g 8K TV with the aim of making it a large monitor [1] and about searching for a suitable video card for 8k [2]. After writing the second post I bought an Intel Arc B580 which also did a maximum of 4096*2160 resolution. This post covers many attempts to try and get the TV to work correctly and it doesn t have good answers. The best answer might be to not buy Hisense devices but I still lack data. Attempts to Force 8K I posted on Lemmy again about this [3] and got a single response, which is OK as it was a good response. They didn t give me the answer on a silver platter but pointed me in the right direction of EDID [4]. I installed the Debian packages read-edid, wxedid, and edid-decode. The command get-edid > out.edid saves the binary form of the edid to a file. The command wxedid out.edid allows graphical analysis of the EDID data. The command edid-decode out.edid dumps a plain text representation of the output, the command edid-decode out.edid grep VIC cut -d: -f2 sort -n shows an ordered list of video modes, in my case the highest resolution is 4096 2160 which is the highest that Linux had allowed me to set with two different video cards and a selection of different cables (both HDMI and DisplayPort).
xrandr --newmode 7680x4320 1042.63  7680 7984 7760 7824  4320 4353 4323 4328
xrandr --addmode HDMI-3 7680x4320
xrandr --output HDMI-3 --mode 7680x4320
I ran the above commands and got the below error:
xrandr: Configure crtc 0 failed
At this time I don t know how much of this is due to the video card and how much is due to the TV. The parameters for xrandr came from a LLM because I couldn t find any Google results on what 8K parameters to use. As an aside if you have a working 8K TV or monitor connected to a computer please publish the EDID data, xrandr, and everything else you can think of. I found a Github repository for EDID data [5] but that didn t have an entry for my TV and didn t appear to have any other entry for an 8K device I could use. Resolution for Web Browsing I installed a browser on the TV, Chrome and Firefox aren t available for a TV and the Play Store program tells you that (but without providing a reason) when you search for them. I tried the site CodeShack What is my Screen Resolution [6] which said that my laptop is 2460*1353 while the laptop display is actually 2560*1440. So apparently I have 100 pixels used for the KDE panel at the left of the screen and 87 pixels used by the Chrome tabs and URL bar which seems about right. My Note 9 phone reports 384*661 out of it s 2960*1440 display so it seems that Chrome on my phone is running web sites at 4/15 of the native resolution and about 16% of the height of the screen is used by the system notification bar, the back/home/tasklist buttons (I choose buttons instead of swipe for navigation in system settings), and the URL bar when I have Screen zoom in system settings at 1/4. When I changed Screen zoom to 0/4 the claimed resolution changed to 411*717 (2/7 of the native resolution). Font size changes didn t change the claimed resolution. The claimed Browser Viewport Size by CodeShack is 1280*720 which is 1/6 of the real horizontal resolution and slightly more than 1/6 of the vertical resolution, it claims that the Pixel Density is 2* and a screen resolution of 970*540 which means to imply that the browser is only working at 1920*1080 resolution! Netflix When I view Netflix shows using the Netflix app running on the TV is reports 4K which doesn t happen on Linux PCs (as they restrict 4K content to platforms with DRM) and in the Device setting it reports Device Model as Hisense_SmartTV 8K FFM so the Netflix app knows all about 4K content and knows the text string 8K . YouTube When I view a YouTube video that s described as being 8K I don t get a request for paying for YouTube Premium which is apparently what happens nowadays when you try to play actual 8K video. I turn on State for Nerds and one line has Viewport / Frames 1920 1080*2.00 and another has Current / Optimal Res 3840 2160@60 / 3840 2160@60 so it seems that the YouTube app is seeing the screen as 4K but choosing to only display FullHD even when I have Quality set to 2160p60 HDR . It declares the network speed to be over 100mbit most of the time and the lowest it gets is 60mbit while 50mbit is allegedly what s required for 8K. I installed a few Android apps to report hardware capabilities and they reported the screen resolution to be 1920*1080. Have I Been Ripped Off? It looks like I might have been ripped off by this. I can t get any app other than Netflix to display 4K content. My PC will only connect to it at 4K. Android apps (including YouTube) regard it as 1920*1080. The AI Upscaling isn t really that great and in most ways it seems at best equivalent to a 4K TV and less than a 4K TV that runs Android apps with an actual 4K display buffer. Next Steps The next things I plan to do are to continue attempts to get the TV to do what it s claimed to be capable of, either an Android app that can display 8K content or a HDMI input of 8K content will do. Running a VNC client on the TV would be an acceptable way of getting an 8K display from a Linux PC. I need to get a somewhat portable device that can give 8K signal output. Maybe a mini PC with a powerful GPU or maybe one of those ARM boards that s designed to drive an 8K sign. Then I can hunt for stores that have 8K TVs on display. It would be nice if someone made a USB device that does 8K video output NOT a USB-C DisplayPort alternative mode that uses the video hardware on the laptop. Then I could take a laptop to any place that has an 8K display to show and connect my laptop to it. The one thing I haven t done yet is testing 8K MP4 files on a USB stick. That s mainly due to a lack of content and the fact that none of the phone cameras I have access to can do 8K video. I will try displaying 8K PNG and JPEG files from a USB stick. Most people would give up about now. But I am determined to solve this and buying another large TV isn t out of the question.

24 November 2025

Dirk Eddelbuettel: RcppQuantuccia 0.1.3 on CRAN: Micro Maintenance

A minor release of RcppQuantuccia arrived on CRAN moments ago. RcppQuantuccia started from the Quantuccia header-only subset / variant of QuantLib which it brings it to R. This project validated the idea of making the calendaring functionality of QuantLib available in a more compact and standalone project which we now do with qlcal which can be seen as a successor package to this earlier package. qlcal tracks QuantLib (releases) closely and provides approximately quarterly updates. Switching to using qlcal is generally recommended. This release, the first in almost exactly two years, only updates internals (as detailed below). Notably it switches to Authors@R to avoid a nag from CRAN on two platforms. The complete list changes for this release follows.

Changes in version 0.1.3 (2025-11-24)
  • A badge URL and link have been updated in README.md
  • The continuous integration sript switched first to r-ci-setup and then to the r-ci action with embedded setup
  • The DESCRIPTION file now uses Authors@R

Courtesy of CRANberries, there is also a diffstat report relative to the previous release. More information is on the RcppQuantuccia page. Issues and bugreports should go to the GitHub issue tracker. If you like this or other open-source work I do, you can now sponsor me at GitHub.

This post by Dirk Eddelbuettel originated on his Thinking inside the box blog. Please report excessive re-aggregation in third-party for-profit settings.

22 November 2025

Dirk Eddelbuettel: RcppArmadillo 15.2.2-1 on CRAN: Upstream Update, OpenMP Updates

armadillo image Armadillo is a powerful and expressive C++ template library for linear algebra and scientific computing. It aims towards a good balance between speed and ease of use, has a syntax deliberately close to Matlab, and is useful for algorithm development directly in C++, or quick conversion of research code into production environments. RcppArmadillo integrates this library with the R environment and language and is widely used by (currently) 1286 other packages on CRAN, downloaded 42.6 million times (per the partial logs from the cloud mirrors of CRAN), and the CSDA paper (preprint / vignette) by Conrad and myself has been cited 659 times according to Google Scholar. This versions updates to the 15.2.2 upstream Armadillo release made two days ago. It brings a few changes over the RcppArmadillo 15.2.0 release made only to GitHub (and described in this post), and of course even more changes relative to the last CRAN release described in this earlier post. As described previously, and due to both the upstream transition to C++14 coupled with the CRAN move away from C++11, the package offers a transition by allowing packages to remain with the older, pre-15.0.0 legacy Armadillo yet offering the current version as the default. During the transition we did not make any releases to CRAN allowing both the upload cadence to settle back to the desired about six in six months that the CRAN Policy asks for, and for packages to adjust to any potential changes. Most affected packages have done so (as can be seen in the GitHub issues #489 and #491) which is good to see. We appreciate all the work done by the respective package maintainers. A number of packages are still under a (now formally expired) deadline at CRAN and may get removed. Our offer to help where we can still stands, so please get in touch if we can be of assistance. As a reminder, the meta-issue #475 regroups all the resources for the transition. With respect to changes in the package, we once more overhauled the OpenMP detection and setup, following the approach take by package data.table but sticking with an autoconf-based configure. The detailed changes since the last CRAN release follow.

Changes in RcppArmadillo version 15.2.2-1 (2025-11-21)
  • Upgraded to Armadillo release 15.2.2 (Medium Roast Deluxe)
    • Improved reproducibility of random number generation when using OpenMP
  • Skip a unit test file under macOS as complex algebra seems to fail under newer macOS LAPACK setting
  • Further OpenMP detection rework for macOS (Dirk in #497, #499)
  • Define ARMA_CRIPPLED_LAPACK on Windows only if 'LEGACY' Armadillo selected

Changes in RcppArmadillo version 15.2.1-0 (2025-10-28) (GitHub Only)
  • Upgraded to Armadillo release 15.2.1 (Medium Roast Deluxe)
    • Faster handling of submatrices with one row
  • Improve OpenMP detection (Dirk in #495 fixing #493)

Changes in RcppArmadillo version 15.2.0-0 (2025-10-20) (GitHub Only)
  • Upgraded to Armadillo release 15.2.0 (Medium Roast Deluxe)
    • Added rande() for generating matrices with elements from exponential distributions
    • shift() has been deprecated in favour of circshift(), for consistency with Matlab/Octave
    • Reworked detection of aliasing, leading to more efficient compiled code
  • OpenMP detection in configure has been simplified

Courtesy of my CRANberries, there is a diffstat report relative to previous release. More detailed information is on the RcppArmadillo page. Questions, comments etc should go to the rcpp-devel mailing list off the Rcpp R-Forge page.

This post by Dirk Eddelbuettel originated on his Thinking inside the box blog. If you like this or other open-source work I do, you can sponsor me at GitHub.

21 November 2025

Daniel Kahn Gillmor: Transferring Signal on Android

Transferring a Signal account between two Android devices I spent far too much time recently trying to get a Signal Private Messenger account to transfer from one device to another. What I eventually found worked was a very finicky path to enable functioning "Wi-Fi Direct", which I go into below. I also offer some troubleshooting and recovery-from-failure guidance. All of this blogpost uses "original device" to refer to the Android pocket supercomputer that already has Signal installed and set up, and "new device" to mean the Android device that doesn't yet have Signal on it.

Why Transfer? Signal Private Messenger is designed with the expectation that the user has a "primary device", which is either an iPhone or an Android pocket supercomputer. If you have an existing Signal account, and try to change your primary device by backing up and restoring from backup, it looks to me like Signal will cause your long-term identity keys to be changed. This in turn causes your peers to see a message like "Your safety number with Alice has changed." These warning messages are the same messages that they would get if an adversary were to take over your account. So it's a good idea to minimize them when there isn't an account takeover false alarms train people to ignore real alarms. You can avoid "safety number changed" warnings by using signal's "account transfer" process during setup, at least if you're transferring between two Android devices. However, my experience was that the transfer between two Android devices was very difficult to get to happen at all. I ran into many errors trying to do this, until I finally found a path that worked.

Dealing with Failure After each failed attempt at a transfer, my original device's Signal installation would need to be re-registered. Having set a PIN meant that i could re-register the device without needing to receive a text message or phone call. Set a PIN before you transfer! Also, after a failure, you need to re-link any "linked device" (i.e. any Signal Desktop or iPad installation). If any message came in during the aborted transfer, the linked device won't get a copy of that message. Finally, after a failed transfer, i recommend completely uninstalling Signal from the new device, and starting over with a fresh install on the new device.

Permissions My understanding is that Signal on Android uses Wi-Fi Direct to accomplish the transfer. But to use Wi-Fi Direct, Signal needs to have the right permissions. On each device:
  • Entirely stop the Signal app
  • Go to Settings Apps Signal Permissions
  • Ensure that the following permissions are all enabled whenever the app is running:
  • Location
  • Nearby Devices
  • Network

Preparing for Wi-Fi Direct The transfer process depends on "Wi-Fi Direct", which is a bit of a disaster on its own. I found that if i couldn't get Wi-Fi Direct to work between the two devices, then the Signal transfer was guaranteed to fail. So, for clearer debugging, i first tried to establish a Wi-Fi Direct link on Android, without Signal being involved at all. Setting up a Wi-Fi Direct connection directly failed, multiple times, until i found the following combination of steps, to be done on each device:
  • Turn off Bluetooth
  • Ensure Wi-Fi is enabled
  • Disconnect from any Wi-Fi network you are connected to (go to the "Internet" or "Wi-Fi" settings page, long-press on the currently connected network, and choose "Disconnect"). If your device knows how to connect to multiple local Wi-Fi networks, disconnct from each of them in turn until you are in a stable state where Wi-Fi is enabled, but no network is connected.
  • Close to the bottom of the "Inteernet" or "Wi-Fi" settings page, choose "Network Preferences" and then "Wi-Fi Direct"
  • if there are any entries listed under "Remembered groups", tap them and choose to "Forget this group"
  • If there are Peer devices that say "Invited", tap them and choose to "Cancel invitation"
I found that this configuration is the most likely to enable a successful Wi-Fi Direct connection, where clicking "invite" on one device would pop up an alert on the other asking to accept the connection, and result in a "Connected" state between the two devices.

Actually Transferring Start with both devices fully powered up and physically close to one another (on the same desk should be fine). On the new device:
  • Reboot the device, and log into the profile you want to use
  • Enable Internet access via Wi-Fi.
  • Remove any old version of Signal.
  • Install Signal, but DO NOT OPEN IT!
  • Set up the permissions for the Signal app as described above
  • Open Signal, and choose "restore or transfer" -- you still need to be connected to the network at this point.
  • The new device should display a QR code.
On the original device:
  • Reboot the device, and log into the profile that has the Signal account you're looking to transfer
  • Enable Internet access via Wi-Fi, using the same network that the old device is using.
  • Make sure the permissions for Signal are set up as described above
  • Open Signal, and tap the camera button
  • Point the camera at the new device's QR code
Now tap the "continue" choices on both devices until they both display a message that they are searching for each other. You might see the location indicator (a green dot) turn on during this process. If you see an immediate warning of failure on either device, you probably don't have the permissions set up right. You might see an alert (a "toast") on one of the devices that the other one is trying to connect. You should click OK on that alert. In my experience, both devices are likely to get stuck "searching" for each other. Wait for both devices to show Signal's warning that the search has timed out. At this point, leave Signal open on both devices, and go through all the steps described above to prepare for Wi-Fi Direct. Your Internet access will be disabled. Now, tap "Try again" in Signal on both devices, pressing the buttons within a few seconds of each other. You should see another alert that one device is trying to connect to the other. Press OK there. At this point, the transfer should start happening! The old device will indicate what percentag has been transferred, and the new device will indicate how many messages hav been transferred. When this is all done, re-connect to Wi-Fi on the new device.

Temporal gap for Linked Devices Note that during this process, if new messages are arriving, they will be queuing up for you. When you reconnect to wi-fi, the queued messages will flow to your new device. But the process of transferring automatically unlinks any linked devices. So if you want to keep your instance of Signal Desktop with as short a gap as possible, you should re-link that installation promptly after the transfer completes.

Clean-up After all this is done successfully, you probably want to go into the Permissions settings and turn off the Location and Nearby Devices permissions for Signal on both devices. I recommend also going into Wi-Fi Direct and removing any connected devices and forgetting any existing connections.

Conclusion This is an abysmally clunky user experience, and I'm glad I don't have to do it often. It would have been much simpler to make a backup and restore from it, but I didn't want to freak out my contacts with a safety number change. By contrast, when i wanted extend a DeltaChat account across two devices, the transfer was prompt and entirely painless -- i just had to make sure the devices were on the same network, and then scanned a QR code from one to the other. And there was no temporal gap for any other deviees. And i could use Delta on both devices simultaneously until i was convinced that it would work on the new device -- Delta doesn't have the concept of a primary account. I wish Signal made it that easy! Until it's that easy, i hope the processes described here are useful to someone.

19 November 2025

Dirk Eddelbuettel: digest 0.6.39 on CRAN: Micro Update

Release 0.6.39 of the digest package arrived at CRAN today and has also been uploaded to Debian. digest creates hash digests of arbitrary R objects. It can use a number different hashing algorithms (md5, sha-1, sha-256, sha-512, crc32, xxhash32, xxhash64, murmur32, spookyhash, blake3,crc32c, xxh3_64 and xxh3_128), and enables easy comparison of (potentially large and nested) R language objects as it relies on the native serialization in R. It is a mature and widely-used package (with 86.8 million downloads just on the partial cloud mirrors of CRAN which keep logs) as many tasks may involve caching of objects for which it provides convenient general-purpose hash key generation to quickly identify the various objects. As noted last week in the 0.6.38 release note, hours after it was admitted to CRAN, I heard from the ever-so-tireless Brian Ripley about an SAN issue on arm64 only (and apparently non-reproducible elsewhere). He kindly provided a fix; it needed a cast. Checking this on amd64 against our Rocker-based ASAN and UBSAN containers (where is remains impossible to replicate, this issue is apparently known for some arm64 issues) another micro-issue (of a missing final argument NULL missing in one .Call()) was detected. Both issues were fixed the same day, and constitute the only change here. I merely waited a week to avoid a mechanical nag triggered when release happen within a week. My CRANberries provides a summary of changes to the previous version. For questions or comments use the issue tracker off the GitHub repo. For documentation (including the changelog) see the documentation site. If you like this or other open-source work I do, you can now sponsor me at GitHub.

This post by Dirk Eddelbuettel originated on his Thinking inside the box blog. Please report excessive re-aggregation in third-party for-profit settings.

Dirk Eddelbuettel: #055: More Frequent r2u Updates

Welcome to post 55 in the R4 series. r2u brings CRAN packages for R to Ubuntu. We mentioned it in the R4 series within the last year in posts #54 about faster CI, #48 about the r2u keynote at U Mons, #47 reviewing r2u it at its third birthday, #46 about adding arm64 support, and #44 about the r2u for mlops talk. Today brings news of an important (internal) update. Following both the arm64 builds as well as the last bi-annual BioConductor package update (and the extension of BioConductor coverage to arm64), more and more of our build setup became automated at GitHub. This has now been unified. We dispatch builds for amd64 packages for jammy (22.04) and noble (24.04) (as well as for the arm64 binaries for noble ) from the central build repository and enjoy the highly parallel build of the up to fourty available GitHub Runners. In the process we also switched fully to source builds. In the past, we had relied on p3m.dev (formerly known as ppm and rspm) using its binaries. These so-called naked binaries are what R produces when called as R CMD INSTALL --build. They are portable with the same build architecture and release, but do not carry packaging information. Now, when a Debian or Ubuntu .deb binary is built, the same step of R CMD INSTALL --build happens. So our earlier insight was to skip the compilation step, use the p3m binary, and then wrap the remainder of a complete package around it. Which includes the all-important dependency information for both the R package relations (from hard Depends / Imports / LinkingTo or soft Suggests declarations) as well as the shared library dependency resolution we can do when building for a Linux distribution. That served us well, and we remain really grateful for the p3m.dev build service. But it also meant were dependending on the clock and cadence of p3m.dev. Which was not really a problem when it ran reliably daily, and early too, included weekends, and showed a timestamp of last updates. By now it is a bit more erratic, frequently late, skips weekends more regularly and long stopped showing when it was last updated. Late afternoon releases reflecting the CRAN updates ending one and half-days earlier is still good, it s just not all that current. Plus there was always the very opaque occurrencem where maybe one in 50 packages or so would not even be provided as a binary so we had to build it anyway the fallback always existing, and was used for both BioConductor (no binaries) and arm64 (no binaries at first, this now changed). So now we just build packages the standard way, albeit as GitHub Actions. In doing so we can ignore p3m.dev, and rather follow the CRAN clock and cadence (as for example CRANberries does), and can update several times a day. For example early this morning (Central time) we ran update for the then-new 28 source packages resulting in 28 jammy and 36 noble binary packages; right now in mid-afternoon we are running another build for 37 source packages resuling in 37 jammy and 47 noble packages. (Packages without a src/ directory and hence no compilation can be used across amd64 and arm64; those that do have src/ are rebuilt for arm64 hence the different sets of jammy and noble packages as only the latter has arm64 now.) This gets us packages from this morning into r2u which p3m.dev should have by tomorrow afternoon or so. And with that r2u remains Fast. Easy. Reliable. Pick all three! and also a little more predictable and current in its delivery. What s not to like?

This post by Dirk Eddelbuettel originated on his Thinking inside the box blog. If you like this or other open-source work I do, you can now sponsor me at GitHub.

Gunnar Wolf: While it is cold-ish season in the North hemisphere...

Last week, our university held a Mega Vaccination Center . Things cannot be small or regular with my university, ever! According to the official information, during last week 31,000 people were given a total of 74,000 vaccine dosis against influenza, COVID-19, pneumococcal disease and measles (specific vaccines for each person selected according to an age profile). I was a tiny blip in said numbers. One person, three shots. Took me three hours, but am quite happy to have been among the huge crowd. Long, long line ( photo credit: La Jornada, 2025.11.14) Really vaccinated! And why am I bringing this up? Because I have long been involved in organizing DebConf, the best conference ever, naturally devoted to improving Debian GNU/Linux. And last year, our COVID reaction procedures ended up hurting people we care about. We, as organizers, are taking it seriously to shape a humane COVID handling policy that is, at the same time, responsible and respectful for people who are (reasonably!) afraid to catch the infection. No, COVID did not disappear in 2022, and its effects are not something we can turn a blind eye to. Next year, DebConf will take place in Santa Fe, Argentina, in July. This means, it will be a Winter DebConf. And while you can catch COVID (or influenza, or just a bad cold) at any time of year, odds are a bit higher. I know not every country still administers free COVID or influenza vaccines to anybody who requests them. And I know that any protection I might have got now will be quite weaker by July. But I feel it necessary to ask of everyone who can get it to get a shot. Most Northern Hemisphere countries will have a vaccination campaign (or at least, higher vaccine availability) before Winter. If you plan to attend DebConf (hell If you plan to attend any massive gathering of people travelling from all over the world to sit at a crowded auditorium) during the next year, please Act responsibly. For yourself and for those surrounding you. Get vaccinated. It won t absolutely save you from catching it, but it will reduce the probability. And if you do catch it, you will probably have a much milder version. And thus, you will spread it less during the first days until (and if!) you start developing symptoms.

17 November 2025

Valhalla's Things: Historically Inaccurate Hemd

Posted on November 17, 2025
Tags: madeof:atoms, craft:sewing
A woman wearing a white shirt with a tall, thick collar with lines of blue embroidery, closed in the front with small buttons; the sleeves are wide and billowing, gathered at the cuffs with more blue embroidery. She's keeping her hands at the waist so that the shirt, which reaches to mid thigh, doesn't look like a shapeless tent from the neck down. After cartridge pleating and honeycombing, I was still somewhat in the mood for that kind of fabric manipulation, and directing my internet searches in that vague direction, and I stumbled on this: https://katafalk.wordpress.com/2012/06/26/patternmaking-for-the-kampfrau-hemd-chemise/ Now, do I want to ever make myself a 16th century German costume, especially a kampfrau one? No! I m from lake Como! Those are the enemies who come down the Alps pillaging and bringing the Black Death with them! Although I have to admit that at times during my day job I have found the idea of leaving everything to go march with the J germonsters attractive. You know, the exciting prospective of long days of march spent knitting sturdy socks, punctuated by the excitement of settling down in camp and having a chance of doing lots of laundry. Or something. Sometimes being a programmer will make you think odd things. Anyway, going back to the topic, no, I didn t need an historically accurate hemd. But I did need a couple more shirts for daily wear, I did want to try my hand at smocking, and this looked nice, and I was intrigued by the way the shaping of the neck and shoulder worked, and wondered how comfortable it would be. And so, it had to be done. I didn t have any suitable linen, but I did have quite a bit of cotton voile, and since I wasn t aiming at historical accuracy it looked like a good option for something where a lot of fabric had to go in a small space. At first I considered making it with a bit less fabric than the one in the blog, but then the voile was quite thin, so I kept the original measurement as is, only adapting the sleeve / sides seams to my size. The same woman, from the back. This time the arms are out, so that the big sleeves show better, but the body does look like a tent. With the pieces being rectangles the width of the fabric, I was able to have at least one side of selvedge on all seams, and took advantage of it by finishing the seams by simply folding the allowances to one sides so that the selvedge was on top, and hemstitching them down as I would have done with a folded edge when felling. Also, at first I wanted to make the smocking in white on white, but then I thought about a few hanks of electric blue floss I had in my stash, and decided to just go with it. The initial seams were quickly made, then I started the smocking at the neck, and at that time the project went on hold while I got ready to go to DebConf. Then I came back and took some time to get back into a sewing mood, but finally the smocking on the next was finished, and I could go on with the main sewing, which, as I expected, went decently fast for a handsewing project. detail of the smocking in progress on the collar, showing the lines of basting thread I used as a reference, and the two in progress zig-zag lines being worked from each side. While doing the diagonal smocking on the collar I counted the stitches to make each side the same length, which didn t completely work because the gathers weren t that regular to start with, and started each line from the two front opening going towards the center back, leaving a triangle with a different size right in the middle. I think overall it worked well enough. Then there were a few more interruptions, but at last it was ready! just as the weather turned cold-ish and puffy shirts were no longer in season, but it will be there for me next spring. I did manage to wear it a few times and I have to say that the neck shaping is quite comfortable indeed: it doesn t pull in odd ways like the classical historically accurate pirate shirt sometimes does, and the heavy gathering at the neck makes it feel padded and soft. The same shirt belted (which looks nicer); one hand is held out to show that the cuff is a bit too wide and falls down over the hand. I m not as happy with the cuffs: the way I did them with just honeycombing means that they don t need a closure, and after washing and a bit of steaming they lie nicely, but then they tend to relax in a wider shape. The next time I think I ll leave a slit in the sleeves, possibly make a different type of smocking (depending on whether I have enough fabric) and then line them like the neck so that they are stable. Because, yes, I think that there will be another time: I have a few more project before that, and I want to spend maybe another year working from my stash, but then I think I ll buy some soft linen and make at least another one, maybe with white-on-white smocking so that it will be easier to match with different garments.
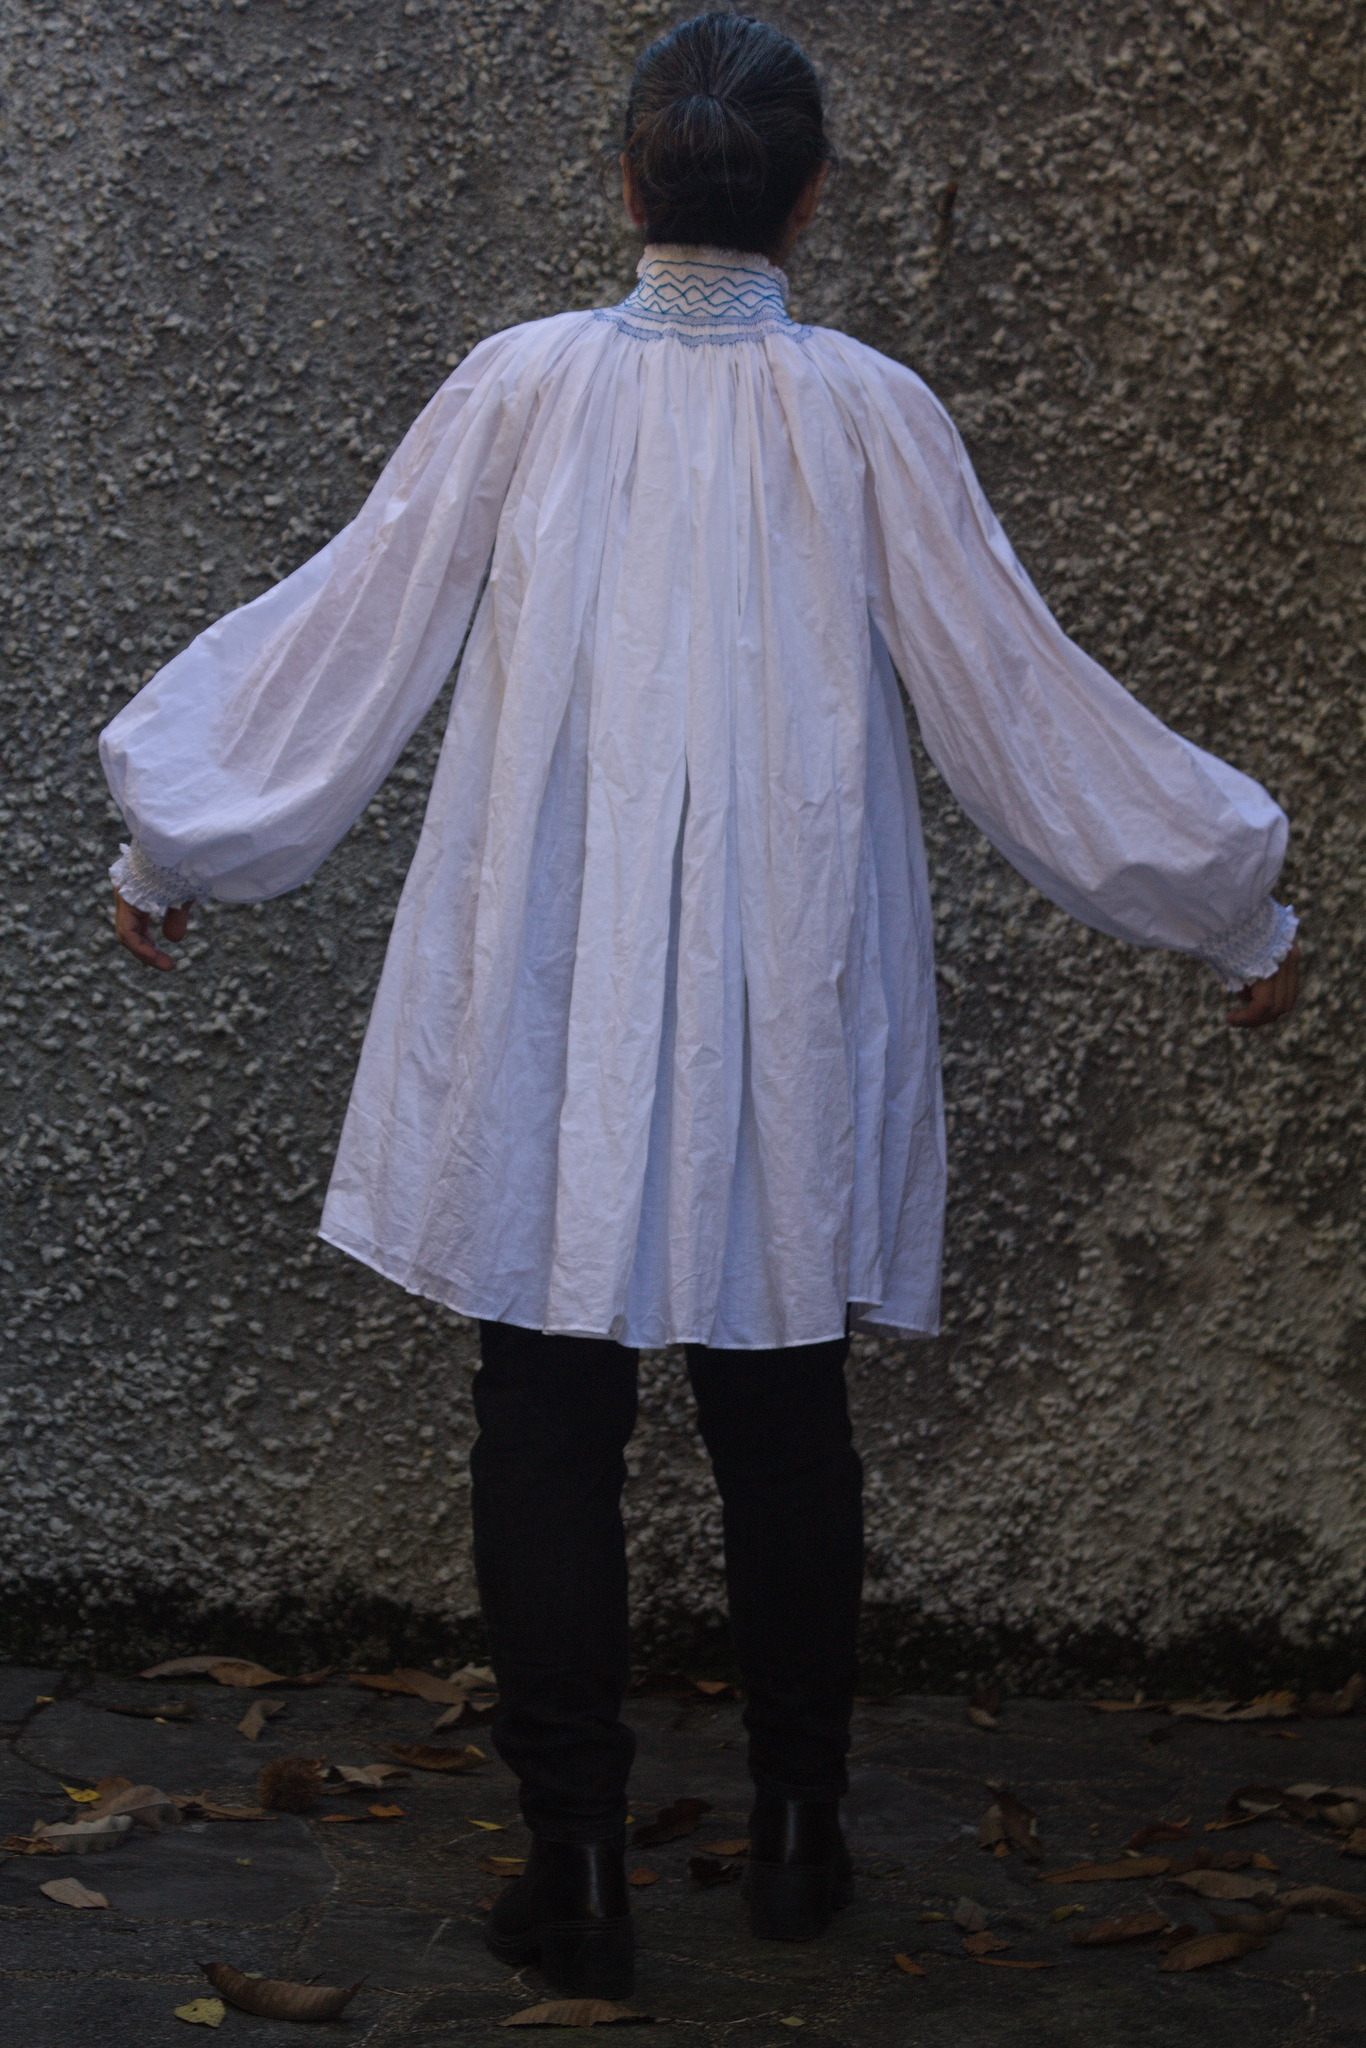
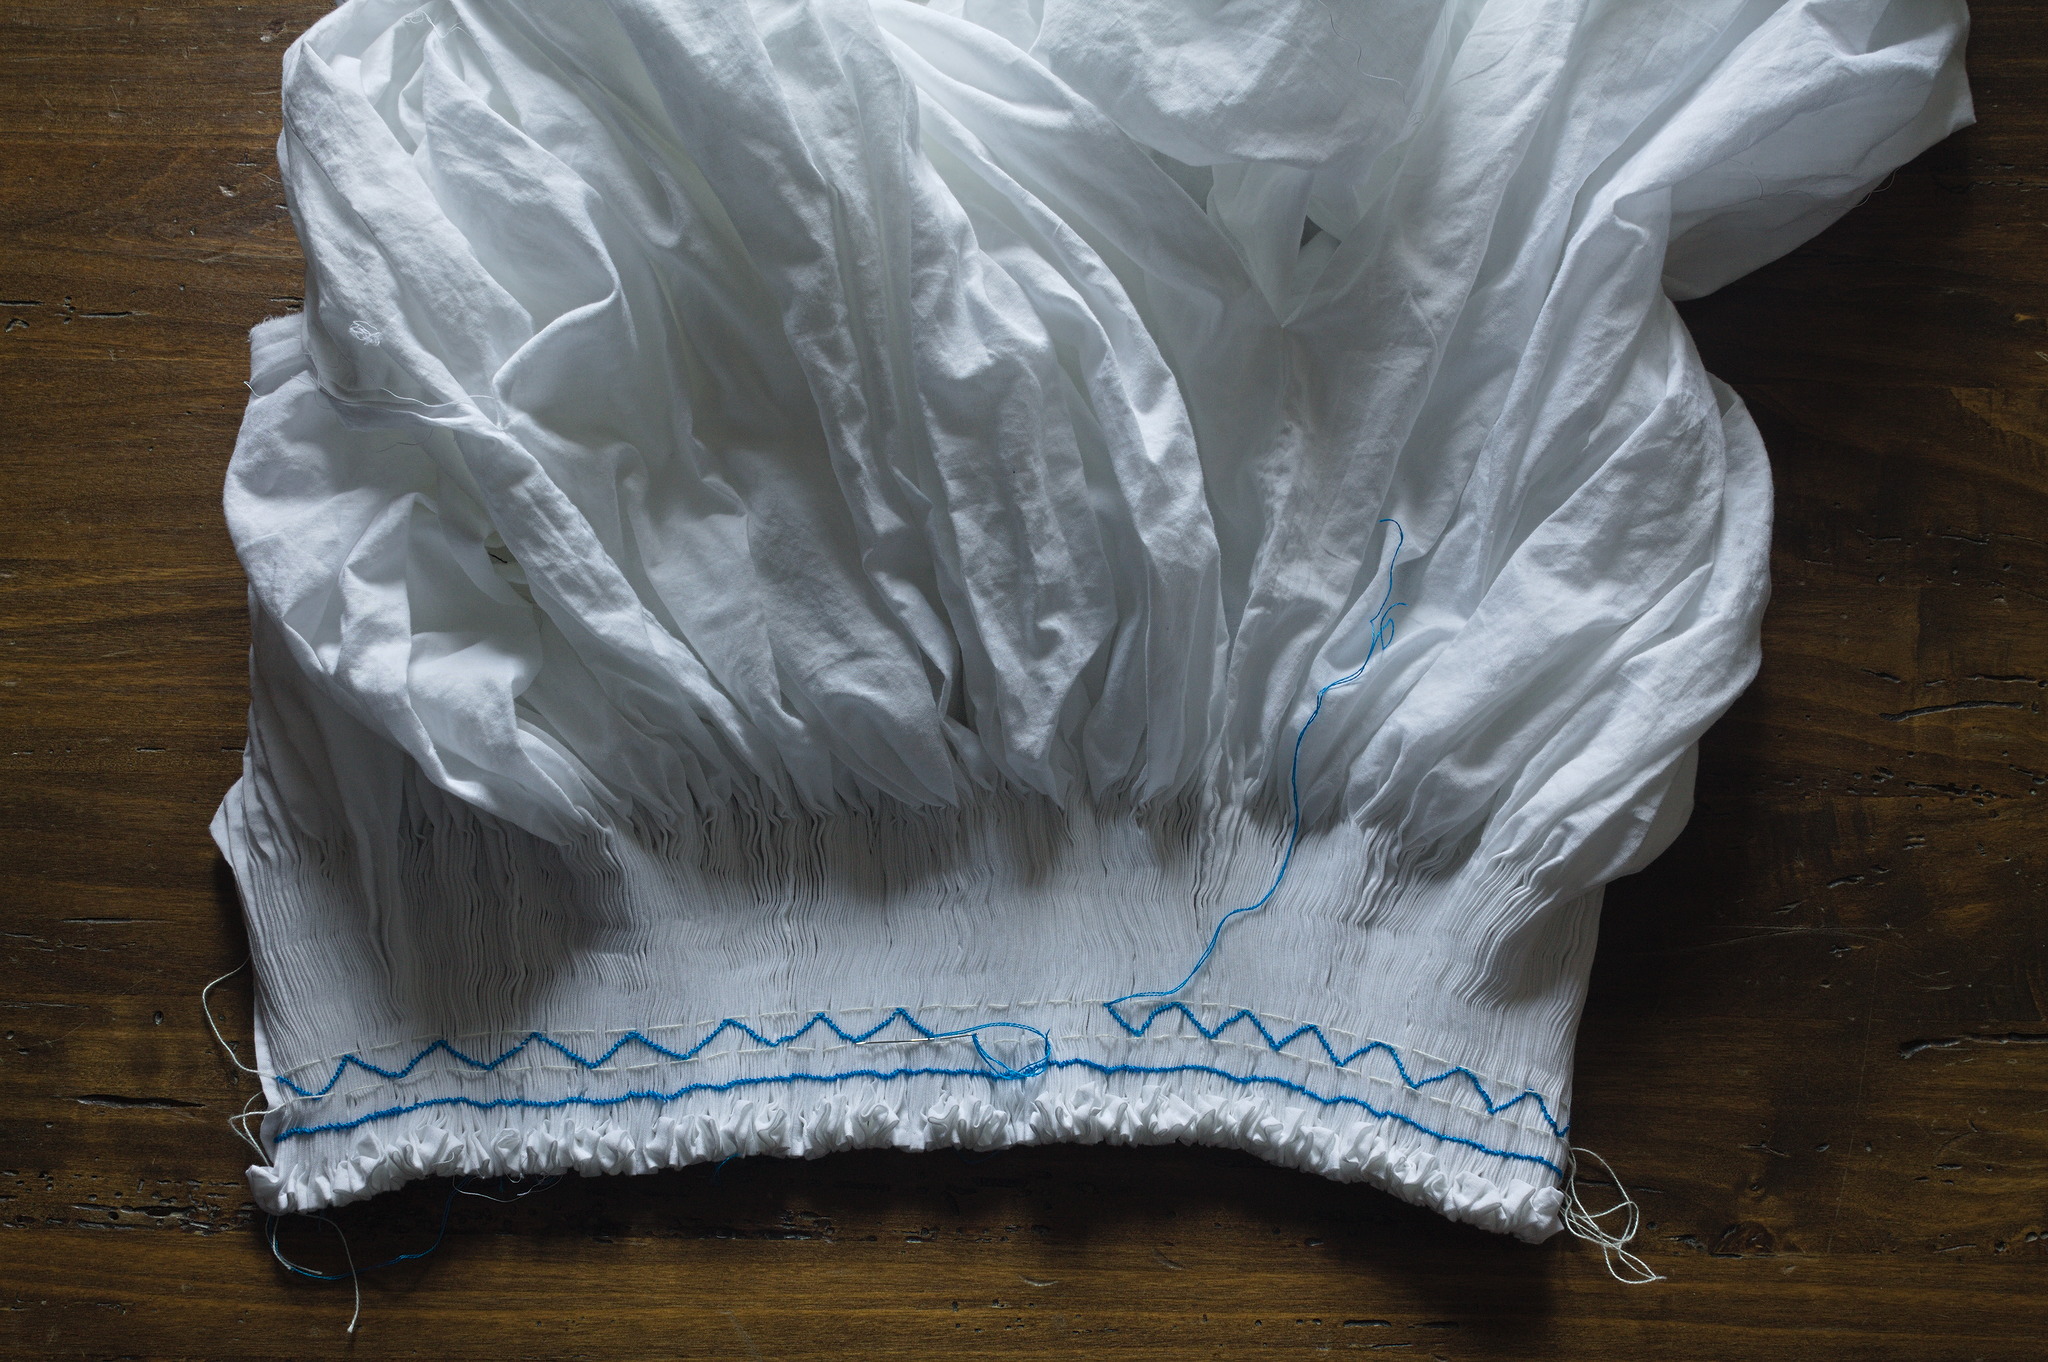
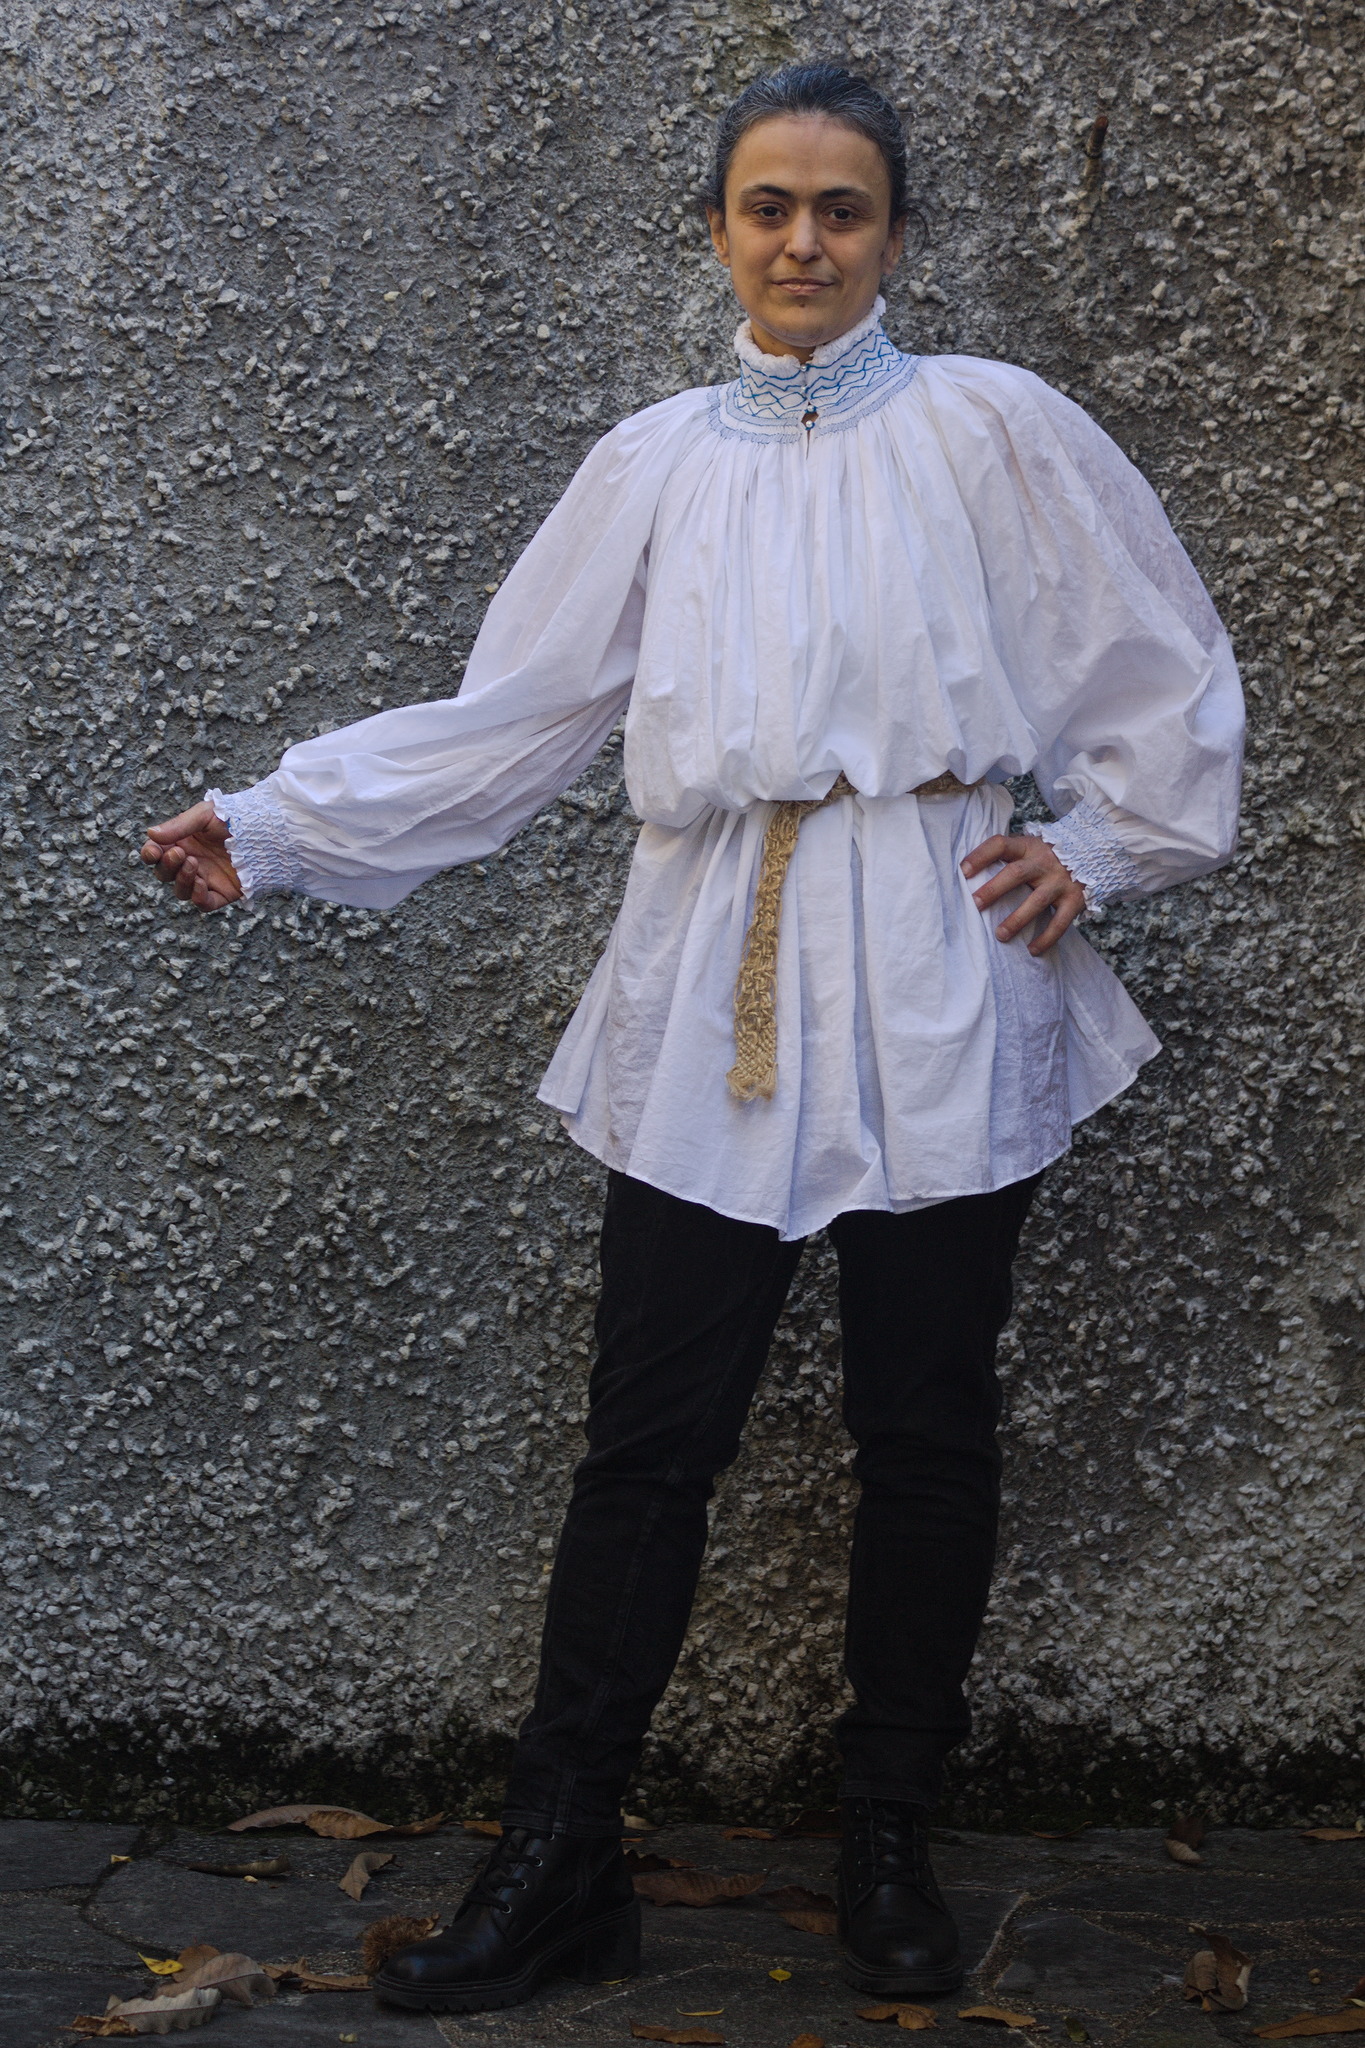

Rodrigo Siqueira: XDC 2025

It has been a long time since I published any update in this space. Since this was a year of colossal changes for me, maybe it is also time for me to make something different with this blog and publish something just for a change why not start talking about XDC 2025? This year, I attended XDC 2025 in Vienna as an Igalia developer. I was thrilled to see some faces from people I worked with in the past and people I m working with now. I had a chance to hang out with some folks I worked with at AMD (Harry, Alex, Leo, Christian, Shashank, and Pierre), many Igalians ( an, Job, Ricardo, Paulo, Tvrtko, and many others), and finally some developers from Valve. In particular, I met T mur in person for the first time, even though we have been talking for months about GPU recovery. Speaking of GPU recovery, we held a workshop on this topic together. The workshop was packed with developers from different companies, which was nice because it added different angles on this topic. We began our discussion by focusing on the topic of job resubmission. Christian began sharing a brief history of how the AMDGPU driver started handling resubmission and the associated issues. After learning from erstwhile experience, amdgpu ended up adopting the following approach:
  1. When a job cause a hang, call driver specific handler.
  2. Stop the scheduler.
  3. Copy all jobs from the ring buffer, minus the job that caused the issue, to a temporary ring.
  4. Reset the ring buffer.
  5. Copy back the other jobs to the ring buffer.
  6. Resume the scheduler.
Below, you can see one crucial series associated with amdgpu recovery implementation: The next topic was a discussion around the replacement of drm_sched_resubmit_jobs() since this function became deprecated. Just a few drivers still use this function, and they need a replacement for that. Some ideas were floating around to extract part of the specific implementation from some drivers into a generic function. The next day, Philipp Stanner continued to discuss this topic in his workshop, DRM GPU Scheduler. Another crucial topic discussed was improving GPU reset debuggability to narrow down which operations cause the hang (keep in mind that GPU recovery is a medicine, not the cure to the problem). Intel developers shared their strategy for dealing with this by obtaining hints from userspace, which helped them provide a better set of information to append to the devcoredump. AMD could adopt this alongside dumping the IB data into the devcoredump (I am already investigating this). Finally, we discussed strategies to avoid hang issues regressions. In summary, we have two lines of defense: Lighting talk This year, as always, XDC was super cool, packed with many engaging presentations which I highly recommend everyone check out. If you are interested, check the schedule and the presentation recordings available on the X.Org Foundation Youtube page. Anyway, I hope this blog post marks the inauguration of a new era for this site, where I will start posting more content ranging from updates to tutorials. See you soon.

13 November 2025

Freexian Collaborators: Debian Contributions: Upstreaming cPython patches, ansible-core autopkgtest robustness and more! (by Anupa Ann Joseph)

Debian Contributions: 2025-10 Contributing to Debian is part of Freexian s mission. This article covers the latest achievements of Freexian and their collaborators. All of this is made possible by organizations subscribing to our Long Term Support contracts and consulting services.

Upstreaming cPython patches, by Stefano Rivera Python 3.14.0 (final) released in early October, and Stefano uploaded it to Debian unstable. The transition to support 3.14 has begun in Ubuntu, but hasn t started in Debian, yet. While build failures in Debian s non-release ports are typically not a concern for package maintainers, Python is fairly low in the stack. If a new minor version has never successfully been built for a Debian port by the time we start supporting it, it will quickly become a problem for the port. Python 3.14 had been failing to build on two Debian ports architectures (hppa and m68k), but thankfully their porters provided patches. These were applied and uploaded, and Stefano forwarded the hppa one upstream. Getting it into shape for upstream approval took some work, and shook out several other regressions for the Python hppa port. Debugging these on slow hardware takes a while. These two ports aren t successfully autobuilding 3.14 yet (they re both timing out in tests), but they re at least manually buildable, which unblocks the ports. Docutils 0.22 also landed in Debian around this time, and Python needed some work to build its docs with it. The upstream isn t quite comfortable with distros using newer docutils, so there isn t a clear path forward for these patches, yet. The start of the Python 3.15 cycle was also a good time to renew submission attempts on our other outstanding python patches, most importantly multiarch tuples for stable ABI extension filenames.

ansible-core autopkgtest robustness, by Colin Watson The ansible-core package runs its integration tests via autopkgtest. For some time, we ve seen occasional failures in the expect, pip, and template_jinja2_non_native tests that usually go away before anyone has a chance to look into them properly. Colin found that these were blocking an openssh upgrade and so decided to track them down. It turns out that these failures happened exactly when the libpython3.13-stdlib package had different versions in testing and unstable. A setup script removed /usr/lib/python3*/EXTERNALLY-MANAGED in order that pip can install system packages for some of the tests, but if a package shipping that file were ever upgraded then that customization would be undone, and the same setup script removed apt pins in a way that caused problems when autopkgtest was invoked in certain ways. In combination with this, one of the integration tests attempted to disable system apt sources while testing the behaviour of the ansible.builtin.apt module, but it failed to do so comprehensively enough and so that integration test accidentally upgraded the testbed from testing to unstable in the middle of the test. Chaos ensued. Colin fixed this in Debian and contributed the relevant part upstream.

Miscellaneous contributions
  • Carles kept working on the missing-relations (packages which Recommends or Suggests packages that are not available in Debian). He improved the tooling to detect Suggested packages that are not available in Debian because they were removed (or changed names).
  • Carles improved po-debconf-manager to send translations for packages that are not in Salsa. He also improved the UI of the tool (using rich for some of the output).
  • Carles, using po-debconf-manager, reviewed and submitted 38 debconf template translations.
  • Carles created a merge request for distro-tracker to align text and input-field (postponed until distro-tracker uses Bootstrap 5).
  • Rapha l updated gnome-shell-extension-hamster for GNOME 49. It is a GNOME Shell integration for the Hamster time tracker.
  • Rapha l merged a couple of trivial merge requests, but he did not yet find the time to properly review and test the bootstrap 5 related merge requests that are still waiting on salsa.
  • Helmut sent patches for 20 cross build failures.
  • Helmut refactored debvm dropping support for running on bookworm . There are two trixie features improving the operation. mkfs.ext4 can now consume a tar archive to populate the filesystem via libarchive and dash now supports set -o pipefail. Beyond this change in operation, a number of robustness and quality issues have been resolved.
  • Thorsten fixed some bugs in the printing software and uploaded improved versions of brlaser and ifhp. Moreover he uploaded a new upstream version of cups.
  • Emilio updated xorg-server to the latest security release and helped with various transitions.
  • Santiago worked on and reviewed different Salsa CI MR to address some regressions introduced by the move to sbuild+unshare. Those MR included stop adding the salsa-ci user in the build image to the sbuild group, fix the suffix path used by mmdebstrap to create the chroot and update the documentation about how to use aptly repos in another project.
  • Santiago supported the work on the DebConf 26 organisation, particularly helping with an implemented method to count the votes to choose the conference logo.
  • Stefano reviewed Python PEP-725 and PEP-804, which hope to provide a mechanism to declare external (e.g. APT) dependencies in Python packages. Stefano engaged in discussion and provided feedback to the authors.
  • Stefano prepared for Berkeley DB removal in Python.
  • Stefano ported the backend to reverse-depends to Python 3 (yes, it had been running on 2.7) and migrated it to git from bzr.
  • Stefano updated miscellaneous packages, including beautifulsoup4, mkdocs-macros-plugin, python-pipx.
  • Stefano applied an upstream patch to pypy3, fixing an AST Compiler Assertion error.
  • Stefano uploaded an update to distro-info-data, including data for two additional Debian derivatives: eLxr and Devuan.
  • Stefano prepared an update to dh-python, the python packaging tool, merging several contributed patches and resolving some bugs.
  • Colin upgraded OpenSSH to 10.1p1, helped upstream to chase down some regressions, and further upgraded to 10.2p1. This is also now in trixie-backports.
  • Colin fixed several build regressions with Python 3.14, scikit-learn 1.7, and other transitions.
  • Colin investigated a malware report against tini, making use of reproducible builds to help demonstrate that this is highly likely to be a false positive.
  • Anupa prepared questions and collected interview responses from women contributors in Debian to publish the post as part of Ada Lovelace day 2025.

12 November 2025

Simon Josefsson: Introducing the Debian Libre Live Images

The Debian Libre Live Images allows you to run and install Debian GNU/Linux without non-free software. The general goal is to provide a way to use Debian without reliance on non-free software, to the extent possible within the Debian project. One challenge are the official Debian live and installer images. Since the 2022 decision on non-free firmware, the official images for bookworm and trixie contains non-free software. The Debian Libre Live Images project provides Live ISO images for Intel/AMD-compatible 64-bit x86 CPUs (amd64) built without any non-free software, suitable for running and installing Debian. The images are similar to the Debian Live Images distributed as Debian live images. One advantage of Debian Libre Live Images is that you do not need to agree to the distribution terms and usage license agreements of the non-free blobs included in the official Debian images. The rights to your own hardware won t be crippled by the legal restrictions that follows from relying on those non-free blobs. The usage of your own machine is no longer limited to what the non-free firmware license agreements allows you to do. This improve your software supply-chain situation, since you no longer need to consider their implication on your computing environment for your liberty, privacy or security. Inclusion of non-free firmware is a vehicle for xz-style attacks. For more information about the advantages of free software, see the FSF s page on What is Free Software?. Enough talking, show me the code! Err, binaries! Download images:
wget https://gitlab.com/api/v4/projects/74667529/packages/generic/debian-libre-live/main/live-image-amd64.hybrid.iso
wget https://gitlab.com/api/v4/projects/74667529/packages/generic/debian-libre-live/main/live-image-amd64.hybrid.iso.SHA256SUMS
sha256sum -c live-image-amd64.hybrid.iso.SHA256SUMS
Run in a virtual machine:
kvm -cdrom live-image-amd64.hybrid.iso -m 8G
Burn to an USB drive for installation on real hardware:
sudo dd if=live-images-amd64.hybrid.iso of=/dev/sdX # use sdX for USB drive
Images are built using live-build from the Debian Live Team. Inspiration has been taken from Reproducible Live Images and Kali Live. The images are built by GitLab CI/CD shared runners. The pipeline .gitlab-ci.yml container job creates a container with live-build installed, defined in container/Containerfile. The build job then invokes run.sh that includes a run to lb build, and then upload the image to the package registry. This is a first initial public release, calibrate your expectations! The primary audience are people already familiar with Debian. There are known issues. I have performed successful installations on a couple of different machines including laptops like Lenovo X201, Framework AMD Laptop 13 etc. Are you able to install Debian without any non-free software on some hardware using these images? Happy Hacking!

Dirk Eddelbuettel: digest 0.6.38 on CRAN: Several Updates

Release 0.6.38 of the digest package arrived at CRAN today and has also been uploaded to Debian. digest creates hash digests of arbitrary R objects. It can use a number different hashing algorithms (md5, sha-1, sha-256, sha-512, crc32, xxhash32, xxhash64, murmur32, spookyhash, blake3,crc32c, xxh3_64 and xxh3_128), and enables easy comparison of (potentially large and nested) R language objects as it relies on the native serialization in R. It is a mature and widely-used package (with 86.8 million downloads just on the partial cloud mirrors of CRAN which keep logs) as many tasks may involve caching of objects for which it provides convenient general-purpose hash key generation to quickly identify the various objects. This release, the first in about fifteen months, updates a number of items. Carl Pearson suggested, and lead, a cleanup of the C API in order to make more of the functionality accessibly at the source level of other packages. This is ongoing / not yet complete but lead to several nice internal cleanups, mostly done by Carl. Several typos were corrected, mostly in Rd files, by Bill Denney, who also improved the test coverage statistics. Thierry Onkelinx and I improved the sha1 functionality. Sergey Fedorov improved an endianness check that matter for his work on PowerPC. I updated the blake3 hasher, expanded the set of ORCID IDs for listed contributors, updated the continuous integration setup, reinstated code coverage reports, refreshed / converted the documentation site setup, and made general updates and edits to the documentation. The release was prepared a week ago, and held up a few days until an affected package was updated: it requested raw returns where none were previously delivered (for xxhash64) but now are so it needed to not reqest them. It was then seen that another package made some assumptions about our DESCRIPTION file; this has been addressed at its end via a pull request we submitted (that remains unmerged). This delayed processing at CRAN for a few days and as it happens, hours after the packages was updated at CRAN today I heard from the ever-so-tireless Brian Ripley about an SAN issue on arm64 only. He kindly provided a fix; it needed a cast. Checking this on amd64 against our Rocker-based ASAN and UBSAN containers (where is remains impossible to replicate, this issue is apparently known for some arm64 issues) another micro-issue (of a missing final argument NULL missing in one .Call()) was detected. I plan to fix both of these in a follow-up release next week. My CRANberries provides a summary of changes to the previous version. For questions or comments use the issue tracker off the GitHub repo. For documentation (including the changelog) see the documentation site. If you like this or other open-source work I do, you can now sponsor me at GitHub.

This post by Dirk Eddelbuettel originated on his Thinking inside the box blog. Please report excessive re-aggregation in third-party for-profit settings.

11 November 2025

Dirk Eddelbuettel: duckdb-mlpack 0.0.4: Added random forest and logistic regression

A new release of the budding duckdb extension for mlpack, the C++ header-only library for machine learning, was merged into the duckdb community extensions repo today, and has been updated at its duckdb mlpack extension page. This release 0.0.4 adds two new methods (random forests, and regularized logistic regression), reworked the interface a little to now consistently provide fit (or train) and predict methods, adds a new internal state variable mlpack_verbose which can trigger (or suppress) verbose mode directly from SQL, expanded the documentation and added more unit tests. For more details, see the repo for code, issues and more, and the extension page for more about this duckdb community extension.

This post by Dirk Eddelbuettel originated on his Thinking inside the box blog. If you like this or other open-source work I do, you can sponsor me at GitHub.

Next.

Previous.