Search Results: "ag"

25 August 2008

Jeff Licquia: Standards and Conversations, Part 2

Picking up where we left off last time…
The LSB spec invents things without consulting distros. Like the whole init scripts thing. But that s not as bad as depending on RPM or requiring a specific layout.
What can be very frustrating is that we do reach out to all the major distros, and a number of the less major ones. But we don’t talk to every single person on every single distro; we can’t. We also try to follow best practices for an open project: open version control, open IRC, open mailing lists. Part of the problem may be that we also talk to independent software developers, and sometimes, distro people aren’t prepared to hear what developers are saying. So, it looks like we’re pushing things on them, like predictable directory layouts, hooks for working with the user environment, different options for software installation, and the like. We used to just listen to distros and do what they wanted. Part of the reason there’s still a lingering perception that “the LSB failed” is that software developers saw us as irrelevant. And they were right: we were irrelevant, because we only listened to the distros. So now we listen to both sides, and try to get them to talk to each other, and act as a go-between when they don’t seem able to. I had an eye-opening experience in Berlin in 2006. We talked to packaging people, and talked about the need for cooperation between package managers and third-party installer tools. A lot of people thought that was a bad idea. So we got them together with some major ISVs in Berlin, and told them to figure it out. And they did figure something out, and surprise! Communication between package managers and third-party installers became a good thing, at least if done right. And we don’t have a problem with the “done right” part, either. We made a few attempts at proposals for the communication system above, and someone has created an independent implementation. Some of those proposals came under sharp criticism. And we’re cool with that; happy, in fact, that it got attention. So if you want to find out what’s going on with us, and what terrible things we’re going to make you do in the future, check out our project plan, sign up for our mailing list, or just come by our IRC channel (irc.linuxfoundation.org, #lsb) and ask some questions. We try to be friendly and helpful.

Wouter Verhelst: Why apt sucks

From a buildd log:
The following packages have unmet dependencies:
  apache2-threaded-dev: Depends: apache2.2-common (= 2.2.9-7) but it is not going to be installed
                        Depends: libaprutil1-dev but it is not going to be installed
E: Broken packages
Investigating with my set of perl scripts yields:
wouter@country:~/code/perl$ ./check-dep-waits
apache2-threaded-dev
dep-wait libmysqlclient15off (>> 5.0.51a)
Note the complete lack of any reference to mysql in the apt output. Also, in case you thought any of the above is bogus: apache2-threaded-dev depends on apache2.2-common which depends on libaprutil1 which depends on libmysqlclient15off. So there. I've long been hoping for someone to finally fix #325786, but that never happened. Now that I wrote that perl script that I linked to above, I don't think I still need it -- particularly because my script works on my laptop, too, rather than only on m68k machines. Which is good.

Holger Levsen: One RC bug per week

Probably still affected by jetlag, I've decided at the end of last week while going through my Debian mailinglists backlog, to (try to) fix one RC bug per week from now on until Lenny is released. I guess I was also influenced by Neils talk about Lenny at DebConf8 :-) At that time, which it is merely nine days ago, there were 378 RC bugs open in Lenny. Today we have 428 :-(

Also I decided I will blog about this regulary, in the hope that others pick up similar procedures for them, so that we can release Lenny sometime soon. We, as a project, need to gain speed in fixing these issues, this will only happen if more people start fixing these bugs. After that, we can happily go back to adding more features! ;-)

So for now I closed (or contributed to closing) three bugs: #492299: downgraded & closed, generic bug report, users didnt provide moreinfo, #495587 (bug in atd, caused by a bug in lsb-base, suggested to forcemerge), #438885 (downgraded, as all blocking bugs for this one have been fixed).

For 475036 (removal of kernel-package requested by maintainer) I updated status in the bugreport and notified the kernel-team, that they are one of the two last users of this package in Debian. Not sure which change is more appropriate now: fix kernel-package, so that it can stay in Lenny, or change the linux-2.6 build-system.

The other package which uses kernel-package is cdfs-src, but I'm not sure we should with that package anyway, see 482075.

That's it for this week. Oh, I forgot to mention why I choose one RC bug per week: it's a goal I can fullfill. If I'd choose more, I might not manage to keep up with my plan and stop it altogether. So I choose something which I hopefully can manage over a some period of time ;-) I'm aware this is not very much, but at least something.

What's your plan to help releasing Lenny on time?

Russell Coker: Is SE Linux Unixish?

In a comment on my AppArmor is dead post [1] someone complained that SE Linux is not “Unixish“. The security model in Unix is almost exclusively Discretionary Access Control (DAC) [2]. This means that any process that owns a resource can grant access to the resource to other processes without restriction. For example a user can run “chmod 777 ~” and grant every other user on the system the ability to access their files (and take over their account by modifying ~/.login and similar files). I say that it’s almost exclusively DAC because there are some things that a user can not give away, for example they can not permit a program running under a different non-root UID to ptrace their processes. But for file and directory access it’s entirely discretionary. SE Linux is based around the concept of Mandatory Access Control (MAC) [3]. This means that the system security policy (as defined by the people who developed the distribution and the local sysadmin) can not be overridden by the user. When a daemon is prevented from accessing files in a user’s home directory by the SE Linux policy and the user is not running in the unconfined_t domain there is no possibility of them granting access. SE Linux has separate measures for protecting integrity and confidentiality. An option is to use MultiLevel Security (MLS) [4], but a more user-friendly option is MCS (Multi-Category Security). The design of SE Linux is based on the concept of having as much of the security policy as possible being loaded at boot time. The design of the Unix permissions model was based on the concept of using the minimal amount of memory at a time when 1M of RAM was a big machine. An access control policy is comprised of two parts, file labels (which is UID, GID, permissions, and maybe ACLs for Unix access controls and a “security context” for SE Linux) and a policy which determines how those file labels are used. The policy in the Unix system is compiled into the kernel and is essentially impossible to change. The SE Linux policy is loaded at boot time, and the most extreme changes to the policy will at most require a reboot. The policy language used for SE Linux is based on the concept of deny by default (everything that is not specifically permitted is denied) and access controls apply to all operations. The Unix access control is mostly permissive and many operations (such as seeing more privileged processes in the output of “ps”) can not be denied on a standard Unix system. So it seems that in many ways SE Linux is not “Unixish”, and it seems to me that any system which makes a Unix system reasonably secure could also be considered to be “not Unixish”. Unix just wasn’t designed for security, not that it is bad by the standards of modern server and desktop OSs. Of course many of the compromises in the design of Unix (such as having all login sessions recorded in a single /var/run/utmp file and having all user accounts stored in a single /etc/passwd file) impact SE Linux systems. But some of them can be worked around, and others will be fixed eventually.

24 August 2008

Michael Schutte: At least I didn t write spoon()

Do not at the same time, half an hour past midnight.
pid = os.fork()
pin, pout = os.pipe()
It just took me five minutes to figure out why these processes don t talk to each other. I m going to bed now.

Russell Coker: Xen and Linux Memory Assignment Bugs

The Linux kernel has a number of code sections which look at the apparent size of the machine and determine what would be the best size for buffers. For physical hardware this makes sense as the hardware doesn’t change at runtime. There are many situations where performance can be improved by using more memory for buffers, enabling large buffers for those situations when the machine has a lot of memory makes it convenient for the sysadmin. Virtual machines change things as the memory available to the kernel may change at run-time. For Xen the most common case is the Dom0 automatically shrinking when memory is taken by a DomU - but it also supports removing memory from a DomU via the xm mem-set command (the use of xm mem-set seems very rare). Now a server that is purchased for the purpose of running Xen will have a moderate amount of RAM. In recent times the smallest machine I’ve seen purchased for running Xen had 4G of RAM - and it has spare DIMM slots for another 4G if necessary. While a non-virtual server with 8G of RAM would be an unusually powerful machine dedicated for some demanding application, a Xen server with 8G or 16G of RAM is not excessively big, it’s merely got space for more DomU’s. For example one of my Xen servers has 8 CPU cores, 8G of RAM, and 14 DomUs. Each DomU has on average just over half a gig of RAM and half of a CPU core - not particularly big. In a default configuration the Dom0 will start by using all the RAM in the machine, which in this case meant that the buffer sizes were appropriate for a machine with 8G of RAM. Then as DomUs are started memory is removed from the Dom0 and these buffers become a problem. This ended up forcing a reboot of the machine by preventing Xen virtual network access to most of the DomUs. I was seeing many messages in the Dom0 kernel message log such as “xen_net: Memory squeeze in netback driver” and most DomUs were inaccessible from the Internet (I didn’t verify that all DomUs were partially or fully unavailable or test the back-end network as I was in a hurry to shut it down and reboot before too many customers complained). The solution to this is to have the Dom0 start by using a small amount of RAM. To do this I edited the GRUB configuration file and put “dom0_mem=256000” at the end of the Xen kernel line (that is the line starting with “kernel /xen.gz“). This gives the Dom0 kernel just under 256M of RAM from when it is first loaded and prevents allocation of bad buffer sizes, it’s the only solution to this network problem that a quick Google search (the kind you do when trying to fix a serious outage before your client notices (*)) could find. One thing to note is that my belief that it’s kernel buffer sizes that are at the root cause of this problem is based on my knowledge of how some of the buffers are allocated plus an observation of the symptoms. I don’t have a test machine with anything near 8G of RAM so I really can’t do anything more to track this down. There is another benefit to limiting the Dom0 memory, I have found that on smaller machines it’s impossible to reduce the Dom0 memory below a certain limit at run-time. In the past I’ve had problems in reducing the memory of a Dom0 below about 250M, while such a reduction is hardly desirable on a machine with 8G of RAM, when running an old P3 machine with 512M of RAM there are serious benefits to making Dom0 smaller than that. As a general rule I recommend having a limit on the memory of the Dom0 on all Xen servers. If you use the model of having no services running on the Dom0 there is no benefit in having much ram assigned to it. (*) Hiding problems from a client is a bad idea and is not something I recommend. But being able to fix a problem and then tell the client that it’s already fixed is much better than having them call you when you don’t know how long the fix will take.

Enrico Zini: Polysms

Polysms Here is my first software designed for the FreeRunner: polysms. It's a commandline tool: you pass it a polygen grammar name and a phone number, and it will send a SMS to that phone number using the polygen output for that grammar as the SMS text:
# polyrun manager 0012345678

And here is the code, that works on the http://www.freesmartphone.org dbus framework:
#!/usr/bin/python
# (C) 2008 Enrico Zini
# Most bits of this are stripped from zhone, which is:
# (C) 2007 Johannes 'Josch' Schauer
# (C) 2008 Michael 'Mickey' Lauer <mlauer@vanille-media.de>
# (C) 2008 Jan 'Shoragan' Luebbe
# (C) 2008 Daniel 'Alphaone' Willmann
# (C) 2008 Openmoko, Inc.
# GPLv2 or later
from dbus import SystemBus, Interface
from dbus.exceptions import DBusException
import logging
logger = logging.getLogger( __name__ )
from dbus.mainloop.glib import DBusGMainLoop
DBusGMainLoop(set_as_default=True)
import gobject
import sys
from subprocess import Popen, PIPE
class Phone:
    def tryGetProxy( self, busname, objname ):
        try:
            return self.bus.get_object( busname, objname )
        except DBusException, e:
            logger.warning( "could not create proxy for %s:%s" % ( busname, objname ) )
    def __init__(self):
        try:
            self.bus = SystemBus()
        except DBusException, e:
            logger.error( "could not connect to dbus_object system bus: %s" % e )
            return False
        # Phone
        self.gsm_device_obj = self.tryGetProxy( 'org.freesmartphone.ogsmd', '/org/freesmartphone/GSM/Device' )
        if ( self.gsm_device_obj is not None ):
            self.gsm_device_iface = Interface(self.gsm_device_obj, 'org.freesmartphone.GSM.Device')
            self.gsm_sim_iface = Interface(self.gsm_device_obj, 'org.freesmartphone.GSM.SIM')
            self.gsm_network_iface = Interface(self.gsm_device_obj, 'org.freesmartphone.GSM.Network')
            self.gsm_call_iface = Interface(self.gsm_device_obj, 'org.freesmartphone.GSM.Call')
            self.gsm_test_iface = Interface(self.gsm_device_obj, 'org.freesmartphone.GSM.Test')
        # Main loop
        self.loop = gobject.MainLoop()
    def send(self, number, message):
        def onSent():
            print "SENT"
            self.loop.quit()
        def onStore(index):
            print "STORED AS", index
            self.gsm_sim_iface.SendStoredMessage(
                index,
                reply_handler=onSent,
                error_handler=self.onError
            )
        self.gsm_sim_iface.StoreMessage(
            number, message,
            reply_handler=onStore,
            error_handler=self.onError
        )
    def onError(self, result):
        print "ERROR", result
    def mainloop(self):
        self.loop.run()
if len(sys.argv) != 3:
    print >>sys.stderr, "Usage: %s grammarname phonenumber"
    sys.exit(1)
message = Popen(["/usr/bin/polyrun", sys.argv[1]], stdout=PIPE).communicate()[0]
number = sys.argv[2]
print "Sending to %s:" % number
print message
phone = Phone()
phone.send(number, message)
phone.mainloop()

Jonathan McDowell: DebConf8 writeup

I took a note of the various talks I attended at DebConf, with the aim of writing a few notes about each so that I could try to explain to my work mates exactly what I get out of going. However I think a lot of the benefit is about general face to face contact with fellow DDs and random conversations that happen. Having worked from home for over 3 years I'm finding it quite nice to be back in an office with people working on the same things as me; there are conversations that you will have over a quick cup of coffee or in the corridor that you wouldn't bother typing on IRC or email or picking up the phone for. Debian is a lot like a large organisation full of telecommuters and DebConf provides a vital opportunity for us to have those "minor" conversations that prove quite useful and to remind each other what we're actually like in person. I didn't end up writing a lot of notes during the talks so these are just snippets after the fact. If I'd been more organised I'd have done a write up on a daily basis rather than leaving it all until the week after. A lot of the below is fragmented thoughts, but the longer I leave it the less relevant it gets and the more chance I forget something. It'd have been up faster if I hadn't been fighting Movable Type to try and get some sort of headings. Sunday
Introduction, Marga The "Welcome to DebConf" bit. Marga got up and talked about how at DebConf4 (Brazil) she hadn't been a DD and now she was and how it had been a life changing event. She'd thought she was to blame for DebConf8 in Argentina, but trawling mail archives had shown it was originally Mart n's idea. She hadn't realised at the start quite how much work it would be. Steve's DPL talk, Steve McIntyre The DPL welcomes us to DebConf and talks about Debian's achievements, some of the results of his team survey (the teams largely say they need more manpower. Not really a huge surprise.). NM/User Survey BOF, Paul Wise Paul emailed debian-user, debian-newmaint and various other places (I think) asking about people's experiences as a Debian user or applicant to New Maint. His final results aren't yet published and I got the impression a disappointing number of our users had replied. The NM problems these days seem to be largely down to a lack of AMs, at least according to the stats on nm.debian.org. Meet SPI board - bdale, maulkin, jimmy, michael, others A chance to meet those of the SPI board who were present. The usual "If you're involved with Debian you should seriously consider joining SPI". Some discussion about the fact that although SPI was originally mostly Debian these days other projects are making more and more use of it - OFTC, PostgreSQL and Madwifi for example. Not a huge amount of new information for me. I've been an SPI member for some time and I think they perform a vital role for Debian. They've had issues in the past but it's really good to see them overcome and more projects on board. Monday
http://hp.com/go/debian, bdale Bdale talks about the history of Debian and HP. And makes the point that HP aren't doing any of this to be "nice"; their primary responsibility is to their shareholders. Not surprising, but it's good that even with that criteria at the fore front Debian ends up a good idea for a large multinational. Managing 666 packages, Mart n Ferrari Mostly centered around the pkg-perl experience and the tools/workflow they have to help manage things. Impressive web tool (DEHS) to help track packages with new upstreams, issues or pending uploads. Quality Assurance in Lenny + 1 I can't remember a lot of this, which is a bit bad. I remember a discussion about whether we should release with orphaned packages, or if they should be removed. The argument for not removing them seemed to revolve around a theory that if they weren't buggy then what was the harm, the argument for was that if they were unmaintained and not really used than how did we actually know they weren't buggy, and was it reasonable that they potentially held up library transitions etc? Bugs in large packages Don Armstrong and ways in which the BTS can help people with lots of bugs. This (thankfully) doesn't affect me, but it was interesting to hear Don talk about his work on the BTS and his various ideas. I was sorry I'd missed his talk on SOAP access to it; I shall have to find time to watch the video. Tuesday
Debian and Ubuntu, Mark Shuttleworth The usual interaction with Debian stuff, including how we interact with our upstreams. If a bug is raised with an Ubuntu package then it might well be appropriate to raise it with Debian and upstream as well, but each set of people should be able to use their own bug reporting systems rather than having to go to a foreign system. I don't think it was actually said, but I guess the idea is that launchpad is the thing that will do this gluing together. He also talked about Ubuntu as an "experiment" rather than a fork of Debian; something that has potentially different ideas about how to do things but that these ideas may lead to things that should be fed back into Debian. The point was made that even if you consider Ubuntu a fork they've forked 9 times now; it hasn't been a case of forking once and diverging wildly since thast point. I have a few thoughts on all the whole Debian/Ubuntu stuff which I should really try to form into something coherant and post. I think it's important to take Mark's talk in the context of bdale's "Shareholders come first" point. Derivatives round table Didn't stay for most of this. Ubuntu, Debian-EDU (which I hadn't realised was a derivative rather than a team within Debian, but apparently there are various things it was much easier for them just to patch now and try to work towards a generic solution later), someone from Extramadura and someone from the Munich government Linux stuff. I'm sure I've missed someone off. tdebs/i18n This was a useful BOF. It helped that we said no to the usual video team requirement that if you want to speak you had to wait for the microphone. This works fine for a normal talk, but really impedes the flow of conversation in something like a BOF. tdebs are something that have partly come from a need of Emdebian to reduce installed package size and partly from the desire of the i18n team to be able to update package translations without having to do a full binary NMU of a package. We had some of the FTP team, the release team, the i18n team and Emdebian there and I think some progress has been made. There'd been various conversations had before this meeting which I think helped people think about the issues and objections so that we had answers by the time we all sat down together - an excellent example of the use of DebConf. DebConf9 C ceres Various bits of discussion about next year's DebConf in Extramadura. Temperature is likely to be an issue for me as they reckon it could easily get up to 40C! I'll melt! Venue sounds good; some queries regarding late night hacklabs and net connections to same, but I'm sure the networking team will sort it all out as usual. ;) DebConf10 bids Venezela and New York were both pitching. Lots of people don't want to travel to the US or think they'll have problems doing so (I hadn't realised there was such an issue for people from South America). I suspect various people will have issues with Venezela as well; I heard expressions of doubt over their political stability expressed. However I'd be happy to go to either (and preferably both! DebConf10 + 12 perhaps?) Speaking of which, what ever happened to the Sarajevo bid? If they're reading, have you considered DebConf11? Wednesday
A day trip to an Argentinian ranch and lunch was an asido. Fantastic food and a pleasant afternoon spent sitting in the sun chatting to people. That evening was the formal, but thanks to having stayed up until after 4 on Tuesday I had to wimp out and go to bed fairly early. Not until I'd seen the DPL dance though. :) Thursday
Internationalization in Debian I forget most of this other than pretty graphs from Christian regarding what's translated and what other languages we might have; e.g. you can consider South America to be covered largely by Spanish and Portuguese, or you can consider it to not be covered very much at all by the local indigenous languages. dh-make-webapp: yeah right! Mainly what I took away from this was "It'll never happen thanks to the fact that every web app author uses a different system" and that more work needs to be done on the web apps best practices document. I don't really do web apps, but having them easily installable on my systems is a good thing so I hope some standardisation within Debian comes from this. Best practises in team-maintaining packages Various team members got up to talk about work flow in their teams. Not unsurprisingly different things seem to work for different people. Predictable PRNG in the Vulnerable Debian OpenSSL Package Lucian giving his Black Hat talk about the OpenSSL issues we faced earlier this year. Some queries about automated testing and that it should have found this, which originally I agreed with until I thought about it - you'd have to have run > 65536 tests and compared all the data to find this; something like the FIPS tests against a single run wouldn't have shown any issues. Lucian wanted feedback on ensuring he was presenting the Debian side of things acceptably as well. Keysigning Run by Don Armstrong. Nothing to really remark except I think key signing attendance is dropping off after things like the Helsinki experience. Also I've now managed to get my new RSA key signed by keys other than my own (and I'll try to get sorted out to sign keys myself soon). Friday
LessWatts Intel's drive towards reducing power usage. Odd to hear such things from someone who wasn't Matthew Garrett and I think I'd heard most of it before. Debian technical policy update Sorry Manoj, I should have been paying more attention. Debian Policy is something I think is important, but I'm not enough of a nitpicker to really feel I can contribute a whole lot. Virtualisation in Debian - Present and future This was depressing. What I took away was "We had 2 forms of virtualisation in etch (Xen + vserver) and we're supporting neither for Lenny". As someone running a Xen machine this is problematic. The host does have the hardware support that would allow kvm, but I'm worried about smooth migration (it's a colo box). There was some mention of Xenner, which isn't packaged for Debian. I took a look at doing so but there are some worrying items in the TODO list (like, oh, locking to enable reliable SMP) and I've spectacularly failed to get it compiling so far. I should have another go. Emdebian update Neil Williams about where Emdebian is and waved his Balloon3 about. Some interest from the Openmoko guys and discussion about why it might be better than OpenEmbedded. And equally what it couldn't do that OpenEmbedded can manage (mainly very small installs; a minimal Emdebian install is 24MB+ and with X that goes up to 75MB+ I believe). netconf I'd never actually seen Martin talk about netconf before. Am impressive flow of control diagram. It all sounds quite complex for little benefit at present, but if he pulls it off then I can see it being a much more flexible replacement for the likes of Network Manager. Saturday
Lenny - The Road To Release Neil played with putting the heads of the release team on random images. And tried to tell us all how to behave during the release process in terms of what should and shouldn't be uploaded etc. Most of it is just common sense, but apparently everything he talked about he'd experienced. Also pointed out we were supposed to release in 3 weeks and didn't even have the appropriate kernel in testing yet so it's probably not going to happen. Colour me surprised. Sustainable Computing Low power consumption/affordable computing. Interesting points about the OLPC being used in the middle of nowhere with no chance of an Internet connection being close by compared to neighbours in large cities where people can't necessarily afford top of the line computers or individual connections - in this sort of scenario mesh networking is really viable in terms of getting people connected up. Multi winner voting Manoj needs pretty diagrams, probably drawn by Martin Krafft. ;) Semi-interesting discussion about multi-winner voting (e.g. SPI board elections) and how the current Debian voting system is completely tied to Debian's infrastructure eg the LDAP setup. Manoj would like to make it more generic so it could be used by other groups as well as for different sorts of votes in Debian.

23 August 2008

Adam Rosi-Kessel: Missing the Show

Seeing John Hodgman in Flight of the Conchords reminded me of this. Does anyone else miss the show? It’s hard to believe it finished less than a year-and-a-half ago. Seems like ancient new-media history now. A favorite episode from long before the Scrabulous kerfuffle: Scrabble. Technorati Tags: , ,

James Morrison: How not to find a friends blog

A while ago I started using Google Reader. Reader has a nice social feature where you can share articles with your friends. This is nicer than posted items in an activity stream since you don't have to click on anything, the article is right there. Anyway, I got a shared item in my stream of articles today with the second sentence as "She somehow got her own claw stuck into her paw.". Then it struck me, I've heard this story before. My dinner guests last week told this same story. So it seems I've found Michelle's blog. Thanks Tony.

John Goerzen: Dot-Matrix Teletype Simulator Update and Request for Teletype Info

I recently wrote about wanting to have a teletype. Well, I have since realized that teletypes weigh hundreds of pounds, draw hundreds of watts, and aren't available on eBay for a reasonable price. Well I knew the hundreds of pounds bit, but still. I pretty well have had to give up on a real teletype.

So, now on to the next best thing: a teletype simulator. Enter the two free dot-matrix printers that found their way to my office earlier this week. One of them even works. I bicycled to the awesome local office supplies store (about 11 miles away) to buy a ribbon for it. This is the place that's been there since the 1890s. They still stock dot matrix ribbons, typewriter ribbons, and even fanfold paper.

On the project. Linux has its heritage in Unix, which was used with these devices. It can be made to work with them even now. But there's a trick: teletypes used a bidirectional serial link. Dot matrix printers have no keyboard. So we have to take input from a different device than we send output to.

A simple trick will do for that:

TERM=escpterm telnet localhost > /dev/lp0

Now, here's the next problem. Dot-matrix printers have a line buffer. They don't start printing the line at all until they see CR or LF. Makes it annoying for interactive use. So I wrote a quick tool to insert into that pipeline. After a certain timeout after the input stops, it will force the printer to flush its buffer. Took a little while to figure out how to do that, too; turns out there's a command ESC J that takes an increment for vertical spacing in 1/216 inch, and accepts 0. So I can send \x1BJ\x00 to flush the buffer. I can run it like this:

TERM=escpterm telnet localhost escpbuf > /dev/lp0

That leaves another problem, though: the printhead is right over the text. (Even though it moves to the right of the printing position, and then moves back left for the next character to print.) I modified the program to roll the paper out a bit, and then reverse feed it to continue printing the line. But that is slow and, I suspect, tough on the stepper motor.

Also, I have crafted a terminfo file for the Epson-compatible dot-matrix printers (which are almost all of them), which can also be found at the above link.

So here's the question, for anyone that has used a real teletype:

Did the printhead obscure the text there too, or could you see the entire current line at all times?

Russell Coker: Play Machine Downtime

From the 13th to the 14th of August my Play Machine [1] was offline. There was a power failure for a few seconds and the machine didn’t boot correctly. As I had a lot of work to do I left it offline for a day before fixing it. The reason it didn’t boot was that due to an issue with the GRUB package it was trying to boot a non-Xen kernel with Xen, this would cause the Xen Dom0 load to abort and it would then reboot after 5 seconds - and automatically repeat the process. The problem is that update-grub in Lenny will generate boot entries for Xen kernels to boot without Xen and for non-Xen kernels to boot with Xen. Two days ago someone launched a DOS attack on my Play Machine and I’ve only just put it back online. I’ve changed the ulimit settings a bit, that won’t make DOS attacks impossible, just force the attacker to use a little bit more effort.

Steve Langasek: A Portland, la ciudad de Mejores Aires

I'm back (for several days now) from Argentina and DebConf 8 to Portland. Too long a journey and too short a trip, as always. It was great to see everybody again as well as to meet a number of new folks from the local community. Here's hoping that DebConf 8 inspires more involvement in Debian from Argentina! It was my first time to this wonderful South American country, which made it even more melancholy to have to leave after such a short time and to be making this trip without Patty. Random observations about Argentina, for posterity: As always it was a pleasure to take part in another annual DebConf, an event which is such a positive force for rejuvenating the Debian community. And BTW, Biella, NYC is not the only US city entertaining a bid for DebConf 10.

Daniel Burrows: Package Management Sudoku 2

I got several emails in reply to my previous post on representing Sudoku problems as package dependencies. Several people asked about the algorithm that aptitude uses to solve these problems. A slightly out-of-date discussion package management and the aptitude algorithm can be found at http://people.debian.org/~dburrows/model.pdf. One question was interesting enough to deserve a follow-up blog post: Wolf T. referred to the page http://norvig.com/sudoku.html and asked how long it would take aptitude aptitude to solve the hard Sudoku problems on that page. He suspected that aptitude would do basic constraint propagation and then be forced to exhaustively search all the possible solutions to the problem. In brief: the answer is that it doesn't work by default, but not for the reason he suggested, and you can make it work with a few command-line arguments. In order to try this out you'll need a new version of the Sudoku reducer that can parse the problems on that Web page: debsudoku2.py. If I do a straight conversion of one of those problems and then run it through aptitude, it goes spinning off and never comes back. But aptitude is coded to avoid exhaustive searches; otherwise it couldn't solve dependency problems in reasonable amounts of time. In this particular situation, though, aptitude is clearly performing an exhaustive search; here's one series of status outputs:
open: 5124; closed: 4993; defer: 0; conflict: 374
Resolving dependencies...
open: 10090; closed: 9942; defer: 0; conflict: 398
Resolving dependencies...
open: 14726; closed: 14888; defer: 0; conflict: 440
Resolving dependencies...
Here open is the number of partial solutions that aptitude wants to examine, and closed is the number that it's already examined. aptitude isn't making progress here and it isn't finding solutions; in fact, it's creating, on average, about two new partial solutions for every one it examines. Why is aptitude doing this? Its resolver isn't a brute-force algorithm; in fact, it looks remarkably like the Sudoku solver discussed at http://norvig.com/sudoku.html. On each step, aptitude takes a partial solution, picks one dependency, and resolves it by installing or removing a package. This is pretty much equivalent to filling in one not-filled-in cell; in fact, in the conflicts Sudoku reduction, it's exactly equivalent. There is one difference, though, and it stems from a difference in the problem domains of Sudoku and package management:
Not all dependency resolutions are created equal.
In Sudoku, any solution to the puzzle will do. Not so in package management; solving a dependency problem by removing every package on the system will produce a formally correct answer and a very unhappy user. Even results that are not utterly disastrous could be annoying to the user, so the resolver needs to somehow aim for good answers. The page on Sudoku solvers suggests sticking to whatever value you placed in a cell, unless that doesn't lead to any solutions at all. This is technically known as a depth-first search. The problem with taking this approach when resolving package dependencies is that an apparently safe choice can end up requiring undesirable actions later on (like removing large swathes of the system). For this reason, aptitude tries to strike a balance between sticking to its current line of reasoning, and abandoning it when it seems to be turning out badly (this makes it a form of best-first search). On typical Debian archives, the package relationships are simple enough that it's OK if aptitude does this from time to time; it makes the search a little more thorough (thus costly), but the ability to back out of questionable branches is very valuable. But it looks like when aptitude is applied to Sudoku puzzles, it has trouble settling on a single series of choices. It keeps thinking that the solutions are getting worse, so it backs up and tries another branch, but they don't look any better over there, so it backs up and tries another branch, and so on. The option Aptitude::ProblemResolver::StepScore sets how hard aptitude will try to stick to the same line of reasoning. Its default value is 70, which is reasonable for package archives, but turning it up to a large value such as 10000 will cause aptitude to use a straight depth-first search, just like the Sudoku page recommends:
$ aptitude -s -o 'aptitude::problemresolver::stepscore=10000' -o 'aptitude::auto-install=false' install puzzle
Setting auto-install to false is a workaround for another odd corner case/bug that happens to bite this Sudoku problem: for technical reasons, doing this lets aptitude know that it should avoid solutions that cancel the installation of puzzle. Otherwise you have to sit there telling it no for a bunch of solutions you aren't interested in. Future versions of aptitude will probably provide a way to explicitly give hints to the resolver. With these options, aptitude was able to solve the hard Sudoku puzzles that I gave it in anywhere from fifteen seconds to a minute and 47 seconds. In contrast, the straight Sudoku solver does 30 problems in a second. Why is aptitude so slow? Based on skimming debug traces and looking at the run-time behavior, I conjecture that there are several reasons:
  1. The aptitude search algorithm is very heavyweight. In the case where it takes over a minute, it only actually examines about 5,000 possible solutions. I don't know exactly where all this time is going, but I do know that the resolver does a lot of work on each step, for instance to try and detect dead ends that it hasn't reached yet. This is the conflicts counter that appears while the resolver is running. This pays off tremendously in terms of allowing aptitude to skip huge amounts of work (it may be why aptitude can solve Sudoku puzzles at all!), but it means that the resolver takes a long time for each potential solution it looks at.
  2. The Sudoku page suggests taking the cell with the fewest number of possible entries as the choice. I distinctly remember writing code to do this in aptitude, but it looks like I threw it out at some point or never committed it. I don't see why it should be any worse than the current approach, though (which is to pick an arbitrary dependency); maybe it just got misplaced at some point. Implementing this behavior decreased the time required to solve one puzzle from a minute and 45 seconds to just under a minute; I've committed this change to the post-lenny branch.
  3. The Sudoku resolver has the advantage of being able to very quickly identify illegal moves. aptitude's resolver can learn this information, but it takes time and it can't apply Sudoku-specific optimizations. For instance, the Sudoku solver knows exactly which values can be placed in a given cell at any time. aptitude has to actually consider each of the cells that's available as a possibility and prove to itself that, e.g., 4 and 6 can't be written in the same cell at the same time. And although it can learn this information, it takes time to do so and it takes time to see whether any of the past conflicts that it remembers are present in a given solution.
As I noted above, I've already checked in one change to the resolver's behavior. It might also be worth seeing what happens with a massive increase in StepScore, so I've pegged it at 10000 on my computer to see whether the results I get are noticeably worse. The third item above -- the fact that aptitude needs to do more work to understand which packages can't be installed -- is interesting. The Sudoku solver is very proactive about this: it keeps track at all times of which cell values are legal, and updates these sets every time it transitions. In contrast, aptitude constantly re-checks all the possible moves it could make to see which ones are currently legal. I think that the resolver's speed could be boosted a little by doing the following:
  1. Cache the currently legal solutions of each dependency at the time it's inserted into the queue.
  2. When a new search node is generated by resolving a dependency, drop the formerly legal moves that are knocked out (for instance, by installing a different version of the same package).
  3. Come up with a quick way of re-testing new conflicts (the global list of dead-ends) so that search nodes that are already in the queue can be checked against the conflicts that were added since they were queued.
These changes won't make aptitude able to solve problems that it couldn't solve before, or at least not very many of them, but they should make the resolver faster on every problem it encounters. However, I don't think I want to actually implement them. It would be tricky to confirm that the resolver got faster on real dependency problems (since it's normally almost instantaneous), the changes would make the resolver code more complex and fragile (less readable, less maintainable), and there's a real chance of breaking something. Unless there are cases where the resolver is currently too slow on real package archives that don't involve an exponential blowup, I'm going to shelve the idea for now.

Christoph Haas: Bad idea of the day: upgrading to Lenny with aptitude

I like aptitude. Okay, I just understand 10% of its features and I can’t live without apt-get (e.g. apt-get source) or apt-cache (e.g. apt-cache search) but for resolving broken dependencies it’s heaven-sent. It just seems like upgrading to Lenny using aptitude (I just learned about “U” to toggle an update - I’ve always used apt-get for that purpose) is a bad idea at this moment. Thanks to Daniel et al for this great piece of software anyway. Just if you upgrade to Lenny I’d recommend apt-get for the moment. It’s now four hours later and I managed to forcefully install slapd’s dependencies, recover the Samba LDAP schemas and get over all kinds of weird error messages. Bacula failed to upgrade the database (I swear it had worked before with dbconfig-common) so all I had was my emergency afbackup. Not to mention that I had to work on the server console because due to lack of LDAP I couldn’t fix that from my laptop. Do I need to mention that my TFT monitor at my server just died today? Don’t think so.

Ian Wienand: Spice hacking

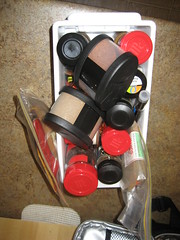
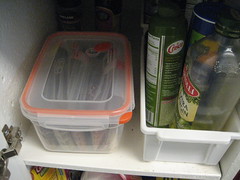
Sick of a ridiculous pile of tiny bottles falling everywhere in your cupboard? Spice Hacking Many people will sell you many expensive solutions. However, I think we've hit on something cheap, effective and practical; zip-lock bags in a deep tub, labelled with sticky tags. Spice Hacking Spice Hacking

22 August 2008

Joey Hess: vacation

This "beach trip" was unusual, as its ocracode shows: OBX1.1 P5/6/4 L6 S12+b----c---- U10(mountains,freshwater,etc) T0 f0 b0 Rd Bb----m----n---- F+ SC----s--g0 H----f0i0.5 V+++s--m0 E-r-- Here are 4 generations of Hess's on a visit to the Bluff Mountain Preserve, which is not normally open to the public and has what is supposed to be the only fen in the southern Appalachians. photo photo Also, I no longer have a car after that trip. I am, however, looking at various electric bicycles. As someone who hates being posessed by posessions, I'm happy that losing my car doesn't really bother me. Oh, and Leo has kitty-laryngitis.

Adeodato Sim : Board games

Here in Dublin I’ve been more “formally” introduced to the world of board games. Back at home, a friend had a copy of Settlers of Catan, and we used to play every now and then, but that was it. Since I arrived I’ve been attending to weekly “board game nights”, and I’ve had the opportunity to play several more, most of which I liked a lot. I’ve played Agricola, Caylus, and Power Grid, all very nice. I’ve also played Race for the Galaxy, which I didn’t like much at first, but which I’ve come to enjoy a bit more as of lately. (All four are in the top-10 of Board Game Geek.) I’m going to miss this when I get back, particularly since my friends will most certainly not be up to weekly games. I should investigate to see if some kind of board games club exists in Alicante. If you know of one, or are reading this and would be interested in organizing something, please let me know.

Benjamin Mako Hill: Free Software Project Management HOWTO

I took a little time today to make a new release of the Free Software Project Management HOWTO. Nearly eight years after I wrote it, much of the document is out of date or has been replaced with better, more comprehensive write-ups. In particular, I think Karl Fogel's book, Producing Open Source Software says everything insightful I say in the HOWTO, a whole lot clearly -- plus adds a lot I missed. That said, my HOWTO is short and is apparently still useful to folks. I updated it to include links to a new German translation courtesy to Robert F. Schmitt, to fix a bunch of links that time broke, and to address a few obvious mistakes that readers have pointed out. Thinking about the documents' future, I'm happy to release it under Creative Commons BY-SA in addition to GFDL and would love to help out on a wiki book project to merge a few of related efforts into a comprehensive wiki reference work.

Enrico Zini: Docking the FreeRunner into the laptop

Docking the FreeRunner into the laptop Earlier in the day, I wrote:
So yes, my laptop can now be turned into a phone charger with networking, DNS and apt cache services. I shall look into hooking that script into dbus to have it run automatically when the phone is plugged and unplugged.
It's not dbus, it's udev, and I've managed to do it. It's an udev rule:
# cat /etc/udev/rules.d/z60_openmoko_net.rules
ACTION=="add", SUBSYSTEM=="net", ATTRS idVendor =="1457", ATTRS idProduct =="5122", RUN+="/root/bin/share-openmoko"
ACTION=="remove", SUBSYSTEM=="net", INTERFACE="usb0", RUN+="/root/bin/share-openmoko"

And a script:
# cat bin/share-openmoko 
#!/bin/sh
if [ "$ACTION" == "add" ]
then
    ACTION=start
fi
if [ "$ACTION" == "remove" ]
then
    ACTION=stop
fi
INTERFACE=$ INTERFACE:-"usb0" 
ACTION=$ ACTION:-"$1" 
case "$ACTION" in
    start)
        logger -t openmoko "Connected, setting up network"
        iptables -t nat -A POSTROUTING -o eth0 -j MASQUERADE -s 192.168.0.200/29
        ifconfig usb0 192.168.0.200 netmask 255.255.255.248
        /etc/init.d/dnsmasq start
        echo 1 > /proc/sys/net/ipv4/ip_forward
        ;;
    stop)
        logger -t openmoko "Disconnected, bringing down network"
        echo 0 > /proc/sys/net/ipv4/ip_forward
        /etc/init.d/dnsmasq stop
        iptables -t nat -F POSTROUTING
        ifconfig usb0 down
        ;;
esac

The script has extra cruft that makes it double as a udev script and as a init.d style script, just because I didn't feel like abandoning the init.d style interface. However, udev handles it perfectly, so there's probably no use at all for the start/stop part. This means that the interface and all supporting services will be brought up and down when the phone is connected/disconnected, and also when the phone is suspended/resumed. Of course, more fancy things can be plugged into the script, like syncing PIM info, file systems, turning on applets in panels, mounting phone file systems and whatnot.

Next.

Previous.