Search Results: "cas"

13 April 2017

Antoine Beaupr : New approaches to network fast paths

With the speed of network hardware now reaching 100 Gbps and distributed denial-of-service (DDoS) attacks going in the Tbps range, Linux kernel developers are scrambling to optimize key network paths in the kernel to keep up. Many efforts are actually geared toward getting traffic out of the costly Linux TCP stack. We have already covered the XDP (eXpress Data Path) patch set, but two new ideas surfaced during the Netconf and Netdev conferences held in Toronto and Montreal in early April 2017. One is a patch set called af_packet, which aims at extracting raw packets from the kernel as fast as possible; the other is the idea of implementing in-kernel layer-7 proxying. There are also user-space network stacks like Netmap, DPDK, or Snabb (which we previously covered). This article aims at clarifying what all those components do and to provide a short status update for the tools we have already covered. We will focus on in-kernel solutions for now. Indeed, user-space tools have a fundamental limitation: if they need to re-inject packets onto the network, they must again pay the expensive cost of crossing the kernel barrier. User-space performance is effectively bounded by that fundamental design. So we'll focus on kernel solutions here. We will start from the lowest part of the stack, the af_packet patch set, and work our way up the stack all the way up to layer-7 and in-kernel proxying.

af_packet v4 John Fastabend presented a new version of a patch set that was first published in January regarding the af_packet protocol family, which is currently used by tcpdump to extract packets from network interfaces. The goal of this change is to allow zero-copy transfers between user-space applications and the NIC (network interface card) transmit and receive ring buffers. Such optimizations are useful for telecommunications companies, which may use it for deep packet inspection or running exotic protocols in user space. Another use case is running a high-performance intrusion detection system that needs to watch large traffic streams in realtime to catch certain types of attacks. Fastabend presented his work during the Netdev network-performance workshop, but also brought the patch set up for discussion during Netconf. There, he said he could achieve line-rate extraction (and injection) of packets, with packet rates as high as 30Mpps. This performance gain is possible because user-space pages are directly DMA-mapped to the NIC, which is also a security concern. The other downside of this approach is that a complete pair of ring buffers needs to be dedicated for this purpose; whereas before packets were copied to user space, now they are memory-mapped, so the user-space side needs to process those packets quickly otherwise they are simply dropped. Furthermore, it's an "all or nothing" approach; while NIC-level classifiers could be used to steer part of the traffic to a specific queue, once traffic hits that queue, it is only accessible through the af_packet interface and not the rest of the regular stack. If done correctly, however, this could actually improve the way user-space stacks access those packets, providing projects like DPDK a safer way to share pages with the NIC, because it is well defined and kernel-controlled. According to Jesper Dangaard Brouer (during review of this article):
This proposal will be a safer way to share raw packet data between user space and kernel space than what DPDK is doing, [by providing] a cleaner separation as we keep driver code in the kernel where it belongs.
During the Netdev network-performance workshop, Fastabend asked if there was a better data structure to use for such a purpose. The goal here is to provide a consistent interface to user space regardless of the driver or hardware used to extract packets from the wire. af_packet currently defines its own packet format that abstracts away the NIC-specific details, but there are other possible formats. For example, someone in the audience proposed the virtio packet format. Alexei Starovoitov rejected this idea because af_packet is a kernel-specific facility while virtio has its own separate specification with its own requirements. The next step for af_packet is the posting of the new "v4" patch set, although Miller warned that this wouldn't get merged until proper XDP support lands in the Intel drivers. The concern, of course, is that the kernel would have multiple incomplete bypass solutions available at once. Hopefully, Fastabend will present the (by then) merged patch set at the next Netdev conference in November.

XDP updates Higher up in the networking stack sits XDP. The af_packet feature differs from XDP in that it does not perform any sort of analysis or mangling of packets; its objective is purely to get the data into and out of the kernel as fast as possible, completely bypassing the regular kernel networking stack. XDP also sits before the networking stack except that, according to Brouer, it is "focused on cooperating with the existing network stack infrastructure, and on use-cases where the packet doesn't necessarily need to leave kernel space (like routing and bridging, or skipping complex code-paths)." XDP has evolved quite a bit since we last covered it in LWN. It seems that most of the controversy surrounding the introduction of XDP in the Linux kernel has died down in public discussions, under the leadership of David Miller, who heralded XDP as the right solution for a long-term architecture in the kernel. He presented XDP as a fast, flexible, and safe solution. Indeed, one of the controversies surrounding XDP was the question of the inherent security challenges with introducing user-provided programs directly into the Linux kernel to mangle packets at such a low level. Miller argued that whatever protections are expected for user-space programs also apply to XDP programs, comparing the virtual memory protections to the eBPF (extended BPF) verifier applied to XDP programs. Those programs are actually eBPF that have an interesting set of restrictions:
  • they have a limited size
  • they cannot jump backward (and thus cannot loop), so they execute in predictable time
  • they do only static allocation, so they are also limited in memory
XDP is not a one-size-fits-all solution: netfilter, the TC traffic shaper, and other normal Linux utilities still have their place. There is, however, a clear use case for a solution like XDP in the kernel. For example, Facebook and Cloudflare have both started testing XDP and, in Facebook's case, deploying XDP in production. Martin Kafai Lau, from Facebook, presented the tool set the company is using to construct a DDoS-resilience solution and a level-4 load balancer (L4LB), which got a ten-times performance improvement over the previous IPVS-based solution. Facebook rolled out its own user-space solution called "Droplet" to detect hostile traffic and deploy blocking rules in the form of eBPF programs loaded in XDP. Lau demonstrated the way Facebook deploys a three-part chained eBPF program: the first part allows debugging and dumping of packets, the second is Droplet itself, which drops undesirable traffic, and the last segment is the load balancer, which mangles the packets to tweak their destination according to internal rules. Droplet can drop DDoS attacks at line rate while keeping the architecture flexible, which were two key design requirements. Gilberto Bertin, from Cloudflare, presented a similar approach: Cloudflare has a tool that processes sFlow data generated from iptables in order to generate cBPF (classic BPF) mitigation rules that are then deployed on edge routers. Those rules are created with a tool called bpfgen, part of Cloudflare's BSD-licensed bpftools suite. For example, it could create a cBPF bytecode blob that would match DNS queries to any example.com domain with something like:
    bpfgen dns *.example.com
Originally, Cloudflare would deploy those rules to plain iptables firewalls with the xt_bpf module, but this led to performance issues. It then deployed a proprietary user-space solution based on Solarflare hardware, but this has the performance limitations of user-space applications getting packets back onto the wire involves the cost of re-injecting packets back into the kernel. This is why Cloudflare is experimenting with XDP, which was partly developed in response to the company's problems, to deploy those BPF programs. A concern that Bertin identified was the lack of visibility into dropped packets. Cloudflare currently samples some of the dropped traffic to analyze attacks; this is not currently possible with XDP unless you pass the packets down the stack, which is expensive. Miller agreed that the lack of monitoring for XDP programs is a large issue that needs to be resolved, and suggested creating a way to mark packets for extraction to allow analysis. Cloudflare is currently in a testing phase with XDP and it is unclear if its whole XDP tool chain will be publicly available. While those two companies are starting to use XDP as-is, there is more work needed to complete the XDP project. As mentioned above and in our previous coverage, massive statistics extraction is still limited in the Linux kernel and introspection is difficult. Furthermore, while the existing actions (XDP_DROP and XDP_TX, see the documentation for more information) are well implemented and used, another action may be introduced, called XDP_REDIRECT, which would allow redirecting packets to different network interfaces. Such an action could also be used to accelerate bridges as packets could be "switched" based on the MAC address table. XDP also requires network driver support, which is currently limited. For example, the Intel drivers still do not support XDP, although that should come pretty soon. Miller, in his Netdev keynote, focused on XDP and presented it as the standard solution that is safe, fast, and usable. He identified the next steps of XDP development to be the addition of debugging mechanisms, better sampling tools for statistics and analysis, and user-space consistency. Miller foresees a future for XDP similar to the popularization of the Arduino chips: a simple set of tools that anyone, not just developers, can use. He gave the example of an Arduino tutorial that he followed where he could just look up a part number and get easy-to-use instructions on how to program it. Similar components should be available for XDP. For this purpose, the conference saw the creation of a new mailing list called xdp-newbies where people can learn how to create XDP build environments and how to write XDP programs.

In-kernel layer-7 proxying The third approach that struck me as innovative is the idea of doing layer-7 (application) proxying directly in the kernel. This comes from the idea that, traditionally, we build firewalls to segregate traffic and apply controls, but as most services move to HTTP, those policies become ineffective. Thomas Graf, presented this idea during Netconf using a Star Wars allegory: what if the Death Star were a server with an API? You would have endpoints like /dock or /comms that would allow you to dock a ship or communicate with the Death Star. Those API endpoints should obviously be public, but then there is this /exhaust-port endpoint that should never be publicly available. In order for a firewall to protect such a system, it must be able to inspect traffic at a higher level than the traditional address-port pairs. Graf presented a design where the kernel would create an in-kernel socket that would negotiate TCP connections on behalf of user space and then be able to apply arbitrary eBPF rules in the kernel. Graf's design of in-kernel proxying In this scenario, instead of doing the traditional transfer from Netfilter's TPROXY to user space, the kernel directly decapsulates the HTTP traffic and passes it to BPF rules that can make decisions without doing expensive context switches or memory copies in the case of simply wanting to refuse traffic (e.g. issue an HTTP 403 error). This, of course, requires the inclusion of kTLS to process HTTPS connections. HTTP2 support may also prove problematic, as it multiplexes connections and is harder to decapsulate. This design was described as a "pure pre-accept() hook". Starovoitov also compared the design to the kernel connection multiplexer (KCM). Tom Herbert, KCM's author, agreed that it could be extended to support this, but would require some extensions in user space to provide an interface between regular socket-based applications and the KCM layer. In any case, if the application does TLS (and lots of them do), kTLS gets tricky because it breaks the end-to-end nature of TLS, in effect becoming a man in the middle between the client and the application. Eric Dumazet argued that HA-Proxy already does things like this: it uses splice() to avoid copying too much data around, but it still does a context switch to hand over processing to user space, something that could be fixed in the general case. Another similar project that was presented at Netdev is the Tempesta firewall and reverse-proxy. The speaker, Alex Krizhanovsky, explained the Tempesta developers have taken one person month to port the mbed TLS stack to the Linux kernel to allow an in-kernel TLS handshake. Tempesta also implements rate limiting, cookies, and JavaScript challenges to mitigate DDoS attacks. The argument behind the project is that "it's easier to move TLS to the kernel than it is to move the TCP/IP stack to user space". Graf explained that he is familiar with Krizhanovsky's work and he is hoping to collaborate. In effect, the design Graf is working on would serve as a foundation for Krizhanovsky's in-kernel HTTP server (kHTTP). In a private email, Graf explained that:
The main differences in the implementation are currently that we foresee to use BPF for protocol parsing to avoid having to implement every single application protocol natively in the kernel. Tempesta likely sees this less of an issue as they are probably only targeting HTTP/1.1 and HTTP/2 and to some [extent] JavaScript.
Neither project is really ready for production yet. There didn't seem to be any significant pushback from key network developers against the idea, which surprised some people, so it is likely we will see more and more layer-7 intelligence move into the kernel sooner rather than later.

Conclusion All of this work aims at replacing a rag-tag bunch of proprietary solutions that recently came up to bypass the Linux kernel TCP/IP stack and improve performance for firewalls, proxies, and other key edge network elements. The idea is that, unless the kernel improves its performance, or at least provides a way to bypass its more complex code paths, people will work around it. With this set of solutions in place, engineers will now be able to use standard APIs to hook high-performance systems into the Linux kernel.
The author would like to thank the Netdev and Netconf organizers for travel assistance, Thomas Graf for a review of the in-kernel proxying section of this article, and Jesper Dangaard Brouer for review of the af_packet and XDP sections. Note: this article first appeared in the Linux Weekly News.

12 April 2017

Vincent Bernat: Proper isolation of a Linux bridge

TL;DR: when configuring a Linux bridge, use the following commands to enforce isolation:
# bridge vlan del dev br0 vid 1 self
# echo 1 > /sys/class/net/br0/bridge/vlan_filtering

A network bridge (also commonly called a switch ) brings several Ethernet segments together. It is a common element in most infrastructures. Linux provides its own implementation. A typical use of a Linux bridge is shown below. The hypervisor is running three virtual hosts. Each virtual host is attached to the br0 bridge (represented by the horizontal segment). The hypervisor has two physical network interfaces: Typical use of Linux bridging with virtual machines The main expectation of such a setup is that while the virtual hosts should be able to use resources from the public network, they should not be able to access resources from the infrastructure network (including resources hosted on the hypervisor itself, like a SSH server). In other words, we expect a total isolation between the green domain and the purple one. That s not the case. From any virtual host:
# ip route add 192.168.14.3/32 dev eth0
# ping -c 3 192.168.14.3
PING 192.168.14.3 (192.168.14.3) 56(84) bytes of data.
64 bytes from 192.168.14.3: icmp_seq=1 ttl=59 time=0.644 ms
64 bytes from 192.168.14.3: icmp_seq=2 ttl=59 time=0.829 ms
64 bytes from 192.168.14.3: icmp_seq=3 ttl=59 time=0.894 ms
--- 192.168.14.3 ping statistics ---
3 packets transmitted, 3 received, 0% packet loss, time 2033ms
rtt min/avg/max/mdev = 0.644/0.789/0.894/0.105 ms

Why? There are two main factors of this behavior:
  1. A bridge can accept IP traffic. This is a useful feature if you want Linux to act as a bridge and provide some IP services to bridge users (a DHCP relay or a default gateway). This is usually done by configuring the IP address on the bridge device: ip addr add 192.0.2.2/25 dev br0.
  2. An interface doesn t need an IP address to process incoming IP traffic. Additionally, by default, Linux accepts to answer ARP requests independently from the incoming interface.

Bridge processing After turning an incoming Ethernet frame into a socket buffer, the network driver transfers the buffer to the netif_receive_skb() function. The following actions are executed:
  1. copy the frame to any registered global or per-device taps (e.g. tcpdump),
  2. evaluate the ingress policy (configured with tc),
  3. hand over the frame to the device-specific receive handler, if any,
  4. hand over the frame to a global or device-specific protocol handler (e.g. IPv4, ARP, IPv6).
For a bridged interface, the kernel has configured a device-specific receive handler, br_handle_frame(). This function won t allow any additional processing in the context of the incoming interface, except for STP and LLDP frames or if brouting is enabled1. Therefore, the protocol handlers are never executed in this case. After a few additional checks, Linux will decide if the frame has to be locally delivered:
  • the entry for the target MAC in the FDB is marked for local delivery, or
  • the target MAC is a broadcast or a multicast address.
In this case, the frame is passed to the br_pass_frame_up() function. A VLAN-related check is optionally performed. The socket buffer is attached to the bridge interface (br0) instead of the physical interface (eth0), is evaluated by Netfilter and sent back to netif_receive_skb(). It will go through the four steps a second time.

IPv4 processing When a device doesn t have a protocol-independent receive handler, a protocol-specific handler will be used:
# cat /proc/net/ptype
Type Device      Function
0800          ip_rcv
0011          llc_rcv [llc]
0004          llc_rcv [llc]
0806          arp_rcv
86dd          ipv6_rcv
Therefore, if the Ethernet type of the incoming frame is 0x800, the socket buffer is handled by ip_rcv(). Among other things, the three following steps will happen:
  • If the frame destination address is not the MAC address of the incoming interface, not a multicast one and not a broadcast one, the frame is dropped ( not for us ).
  • Netfilter gets a chance to evaluate the packet (in a PREROUTING chain).
  • The routing subsystem will decide the destination of the packet in ip_route_input_slow(): is it a local packet, should it be forwarded, should it be dropped, should it be encapsulated? Notably, the reverse-path filtering is done during this evaluation in fib_validate_source().
Reverse-path filtering (also known as uRPF, or unicast reverse-path forwarding, RFC 3704) enables Linux to reject traffic on interfaces which it should never have originated: the source address is looked up in the routing tables and if the outgoing interface is different from the current incoming one, the packet is rejected.

ARP processing When the Ethernet type of the incoming frame is 0x806, the socket buffer is handled by arp_rcv().
  • Like for IPv4, if the frame is not for us, it is dropped.
  • If the incoming device has the NOARP flag, the frame is dropped.
  • Netfilter gets a chance to evaluate the packet (configuration is done with arptables).
  • For an ARP request, the values of arp_ignore and arp_filter may trigger a drop of the packet.

IPv6 processing When the Ethernet type of the incoming frame is 0x86dd, the socket buffer is handled by ipv6_rcv().
  • Like for IPv4, if the frame is not for us, it is dropped.
  • If IPv6 is disabled on the interface, the packet is dropped.
  • Netfilter gets a chance to evaluate the packet (in a PREROUTING chain).
  • The routing subsystem will decide the destination of the packet. However, unlike IPv4, there is no reverse-path filtering2.

Workarounds There are various methods to fix the situation. We can completely ignore the bridged interfaces: as long as they are attached to the bridge, they cannot process any upper layer protocol (IPv4, IPv6, ARP). Therefore, we can focus on filtering incoming traffic from br0. It should be noted that for IPv4, IPv6 and ARP protocols, the MAC address check can be circumvented by using the broadcast MAC address.

Protocol-independent workarounds The four following fixes will indistinctly drop IPv4, ARP and IPv6 packets.

Using VLAN-aware bridge Linux 3.9 introduced the ability to use VLAN filtering on bridge ports. This can be used to prevent any local traffic:
# echo 1 > /sys/class/net/br0/bridge/vlan_filtering
# bridge vlan del dev br0 vid 1 self
# bridge vlan show
port    vlan ids
eth0     1 PVID Egress Untagged
eth2     1 PVID Egress Untagged
eth3     1 PVID Egress Untagged
eth4     1 PVID Egress Untagged
br0     None
This is the most efficient method since the frame is dropped directly in br_pass_frame_up().

Using ingress policy It s also possible to drop the bridged frame early after it has been re-delivered to netif_receive_skb() by br_pass_frame_up(). The ingress policy of an interface is evaluated before any handler. Therefore, the following commands will ensure no local delivery (the source interface of the packet is the bridge interface) happens:
# tc qdisc add dev br0 handle ffff: ingress
# tc filter add dev br0 parent ffff: u32 match u8 0 0 action drop
In my opinion, this is the second most efficient method.

Using ebtables Just before re-delivering the frame to netif_receive_skb(), Netfilter gets a chance to issue a decision. It s easy to configure it to drop the frame:
# ebtables -A INPUT --logical-in br0 -j DROP
However, to the best of my knowledge, this part of Netfilter is known to be inefficient.

Using namespaces Isolation can also be obtained by moving all the bridged interfaces into a dedicated network namespace and configure the bridge inside this namespace:
# ip netns add bridge0
# ip link set netns bridge0 eth0
# ip link set netns bridge0 eth2
# ip link set netns bridge0 eth3
# ip link set netns bridge0 eth4
# ip link del dev br0
# ip netns exec bridge0 brctl addbr br0
# for i in 0 2 3 4; do
>    ip netns exec bridge0 brctl addif br0 eth$i
>    ip netns exec bridge0 ip link set up dev eth$i
> done
# ip netns exec bridge0 ip link set up dev br0
The frame will still wander a bit inside the IP stack, wasting some CPU cycles and increasing the possible attack surface. But ultimately, it will be dropped.

Protocol-dependent workarounds Unless you require multiple layers of security, if one of the previous workarounds is already applied, there is no need to apply one of the protocol-dependent fix below. It s still interesting to know them because it is not uncommon to already have them in place.

ARP The easiest way to disable ARP processing on a bridge is to set the NOARP flag on the device. The ARP packet will be dropped as the very first step of the ARP handler.
# ip link set arp off dev br0
# ip l l dev br0
8: br0: <BROADCAST,MULTICAST,NOARP,UP,LOWER_UP> mtu 1500 qdisc noqueue state UP mode DEFAULT group default qlen 1000
    link/ether 50:54:33:00:00:04 brd ff:ff:ff:ff:ff:ff
arptables can also drop the packet quite early:
# arptables -A INPUT -i br0 -j DROP
Another way is to set arp_ignore to 2 for the given interface. The kernel will only answer to ARP requests whose target IP address is configured on the incoming interface. Since the bridge interface doesn t have any IP address, no ARP requests will be answered.
# sysctl -qw net.ipv4.conf.br0.arp_ignore=2
Disabling ARP processing is not a sufficient workaround for IPv4. A user can still insert the appropriate entry in its neighbor cache:
# ip neigh replace 192.168.14.3 lladdr 50:54:33:00:00:04 dev eth0
# ping -c 1 192.168.14.3
PING 192.168.14.3 (192.168.14.3) 56(84) bytes of data.
64 bytes from 192.168.14.3: icmp_seq=1 ttl=49 time=1.30 ms
--- 192.168.14.3 ping statistics ---
1 packets transmitted, 1 received, 0% packet loss, time 0ms
rtt min/avg/max/mdev = 1.309/1.309/1.309/0.000 ms
As the check on the target MAC address is quite loose, they don t even need to guess the MAC address:
# ip neigh replace 192.168.14.3 lladdr ff:ff:ff:ff:ff:ff dev eth0
# ping -c 1 192.168.14.3
PING 192.168.14.3 (192.168.14.3) 56(84) bytes of data.
64 bytes from 192.168.14.3: icmp_seq=1 ttl=49 time=1.12 ms
--- 192.168.14.3 ping statistics ---
1 packets transmitted, 1 received, 0% packet loss, time 0ms
rtt min/avg/max/mdev = 1.129/1.129/1.129/0.000 ms

IPv4 The earliest place to drop an IPv4 packet is with Netfilter3:
# iptables -t raw -I PREROUTING -i br0 -j DROP
If Netfilter is disabled, another possibility is to enable strict reverse-path filtering for the interface. In this case, since there is no IP address configured on the interface, the packet will be dropped during the route lookup:
# sysctl -qw net.ipv4.conf.br0.rp_filter=1
Another option is the use of a dedicated routing rule. Compared to the reverse-path filtering option, the packet will be dropped a bit earlier, still during the route lookup.
# ip rule add iif br0 blackhole

IPv6 Linux provides a way to completely disable IPv6 on a given interface. The packet will be dropped as the very first step of the IPv6 handler:
# sysctl -qw net.ipv6.conf.br0.disable_ipv6=1
Like for IPv4, it s possible to use Netfilter or a dedicated routing rule.

About the example In the above example, the virtual host get ICMP replies because they are routed through the infrastructure network to Internet (e.g. the hypervisor has a default gateway which also acts as a NAT router to Internet). This may not be the case. If you want to check if you are vulnerable despite not getting an ICMP reply, look at the guest neighbor table to check if you got an ARP reply from the host:
# ip route add 192.168.14.3/32 dev eth0
# ip neigh show dev eth0
192.168.14.3 lladdr 50:54:33:00:00:04 REACHABLE
If you didn t get a reply, you could still have issues with IP processing. Add a static neighbor entry before checking the next step:
# ip neigh replace 192.168.14.3 lladdr ff:ff:ff:ff:ff:ff dev eth0
To check if IP processing is enabled, check the bridge host s network statistics:
# netstat -s   grep "ICMP messages"
    15 ICMP messages received
    15 ICMP messages sent
    0 ICMP messages failed
If the counters are increasing, it is processing incoming IP packets. One-way communication still allows a lot of bad things, like DoS attacks. Additionally, if the hypervisor happens to also act as a router, the reach is extended to the whole infrastructure network, potentially exposing weak devices (e.g. PDU) exposing an SNMP agent. If one-way communication is all that s needed, the attacker can also spoof its source IP address, bypassing IP-based authentication.

  1. A frame can be forcibly routed (L3) instead of bridged (L2) by brouting the packet. This action can be triggered using ebtables.
  2. For IPv6, reverse-path filtering needs to be implemented with Netfilter, using the rpfilter match.
  3. If the br_netfilter module is loaded, net.bridge.bridge-nf-call-ipatbles sysctl has to be set to 0. Otherwise, you also need to use the physdev match to not drop IPv4 packets going through the bridge.

Daniel Pocock: What is the risk of using proprietary software for people who prefer not to?

Jonas berg has recently blogged about Using Proprietary Software for Freedom. He argues that it can be acceptable to use proprietary software to further free and open source software ambitions if that is indeed the purpose. Jonas' blog suggests that each time proprietary software is used, the relative risk and reward should be considered and there may be situations where the reward is big enough and the risk low enough that proprietary software can be used. A question of leadership Many of the free software users and developers I've spoken to express frustration about how difficult it is to communicate to their family and friends about the risks of proprietary software. A typical example is explaining to family members why you would never install Skype. Imagine a doctor who gives a talk to school children about the dangers of smoking and is then spotted having a fag at the bus stop. After a month, if you ask the children what they remember about that doctor, is it more likely to be what he said or what he did? When contemplating Jonas' words, it is important to consider this leadership factor as a significant risk every time proprietary software or services are used. Getting busted with just one piece of proprietary software undermines your own credibility and posture now and well into the future. Research has shown that when communicating with people, what they see and how you communicate is ninety three percent of the impression you make. What you actually say to them is only seven percent. When giving a talk at a conference or a demo to a client, or communicating with family members in our everyday lives, using a proprietary application or a product or service that is obviously proprietary like an iPhone or Facebook will have far more impact than the words you say. It is not only a question of what you are seen doing in public: somebody who lives happily and comfortably without using proprietary software sounds a lot more credible than somebody who tries to explain freedom without living it. The many faces of proprietary software One of the first things to consider is that even for those developers who have a completely free operating system, there may well be some proprietary code lurking in their BIOS or other parts of their hardware. Their mobile phone, their car, their oven and even their alarm clock are all likely to contain some proprietary code too. The risks associated with these technologies may well be quite minimal, at least until that alarm clock becomes part of the Internet of Things and can be hacked by the bored teenager next door. Accessing most web sites these days inevitably involves some interaction with proprietary software, even if it is not running on your own computer. There is no need to give up Some people may consider this state of affairs and simply give up, using whatever appears to be the easiest solution for each problem at hand without thinking too much about whether it is proprietary or not. I don't think Jonas' blog intended to sanction this level of complacency. Every time you come across a piece of software, it is worth considering whether a free alternative exists and whether the software is really needed at all. An orderly migration to free software In our professional context, most software developers come across proprietary software every day in the networks operated by our employers and their clients. Sometimes we have the opportunity to influence the future of these systems. There are many cases where telling the client to go cold-turkey on their proprietary software would simply lead to the client choosing to get advice from somebody else. The free software engineer who looks at the situation strategically may find that it is possible to continue using the proprietary software as part of a staged migration, gradually helping the user to reduce their exposure over a period of months or even a few years. This may be one of the scenarios where Jonas is sanctioning the use of proprietary software. On a technical level, it may be possible to show the client that we are concerned about the dangers but that we also want to ensure the continuity of their business. We may propose a solution that involves sandboxing the proprietary software in a virtual machine or a DMZ to prevent it from compromising other systems or "calling home" to the vendor. As well as technical concerns about a sudden migration, promoters of free software frequently encounter political issues as well. For example, the IT manager in a company may be five years from retirement and is not concerned about his employer's long term ability to extricate itself from a web of Microsoft licenses after he or she has the freedom to go fishing every day. The free software professional may need to invest significant time winning the trust of senior management before he is able to work around a belligerant IT manager like this. No deal is better than a bad deal People in the UK have probably encountered the expression "No deal is better than a bad deal" many times already in the last few weeks. Please excuse me for borrowing it. If there is no free software alternative to a particular piece of proprietary software, maybe it is better to simply do without it. Facebook is a great example of this principle: life without social media is great and rather than trying to find or create a free alternative, why not just do something in the real world, like riding motorcycles, reading books or getting a cat or dog? Burning bridges behind you For those who are keen to be the visionaries and leaders in a world where free software is the dominant paradigm, would you really feel satisfied if you got there on the back of proprietary solutions? Or are you concerned that taking such shortcuts is only going to put that vision further out of reach? Each time you solve a problem with free software, whether it is small or large, in your personal life or in your business, the process you went through strengthens you to solve bigger problems the same way. Each time you solve a problem using a proprietary solution, not only do you miss out on that process of discovery but you also risk conditioning yourself to be dependent in future. For those who hope to build a successful startup company or be part of one, how would you feel if you reach your goal and then the rug is pulled out underneath you when a proprietary software vendor or cloud service you depend on changes the rules? Personally, in my own life, I prefer to avoid and weed out proprietary solutions wherever I can and force myself to either make free solutions work or do without them. Using proprietary software and services is living your life like a rat in a maze, where the oligarchs in Silicon Valley can move the walls around as they see fit.

11 April 2017

Matthew Garrett: Disabling SSL validation in binary apps

Reverse engineering protocols is a great deal easier when they're not encrypted. Thankfully most apps I've dealt with have been doing something convenient like using AES with a key embedded in the app, but others use remote protocols over HTTPS and that makes things much less straightforward. MITMProxy will solve this, as long as you're able to get the app to trust its certificate, but if there's a built-in pinned certificate that's going to be a pain. So, given an app written in C running on an embedded device, and without an easy way to inject new certificates into that device, what do you do?

First: The app is probably using libcurl, because it's free, works and is under a license that allows you to link it into proprietary apps. This is also bad news, because libcurl defaults to having sensible security settings. In the worst case we've got a statically linked binary with all the symbols stripped out, so we're left with the problem of (a) finding the relevant code and (b) replacing it with modified code. Fortuntely, this is much less difficult than you might imagine.

First, let's find where curl sets up its defaults. Curl_init_userdefined() in curl/lib/url.c has the following code:
set->ssl.primary.verifypeer = TRUE;
set->ssl.primary.verifyhost = TRUE;
#ifdef USE_TLS_SRP
set->ssl.authtype = CURL_TLSAUTH_NONE;
#endif
set->ssh_auth_types = CURLSSH_AUTH_DEFAULT; /* defaults to any auth
type */
set->general_ssl.sessionid = TRUE; /* session ID caching enabled by
default */
set->proxy_ssl = set->ssl;

set->new_file_perms = 0644; /* Default permissions */
set->new_directory_perms = 0755; /* Default permissions */

TRUE is defined as 1, so we want to change the code that currently sets verifypeer and verifyhost to 1 to instead set them to 0. How to find it? Look further down - new_file_perms is set to 0644 and new_directory_perms is set to 0755. The leading 0 indicates octal, so these correspond to decimal 420 and 493. Passing the file to objdump -d (assuming a build of objdump that supports this architecture) will give us a disassembled version of the code, so time to fix our problems with grep:
objdump -d target grep --after=20 ,420 grep ,493

This gives us the disassembly of target, searches for any occurrence of ",420" (indicating that 420 is being used as an argument in an instruction), prints the following 20 lines and then searches for a reference to 493. It spits out a single hit:
43e864: 240301ed li v1,493
Which is promising. Looking at the surrounding code gives:
43e820: 24030001 li v1,1
43e824: a0430138 sb v1,312(v0)
43e828: 8fc20018 lw v0,24(s8)
43e82c: 24030001 li v1,1
43e830: a0430139 sb v1,313(v0)
43e834: 8fc20018 lw v0,24(s8)
43e838: ac400170 sw zero,368(v0)
43e83c: 8fc20018 lw v0,24(s8)
43e840: 2403ffff li v1,-1
43e844: ac4301dc sw v1,476(v0)
43e848: 8fc20018 lw v0,24(s8)
43e84c: 24030001 li v1,1
43e850: a0430164 sb v1,356(v0)
43e854: 8fc20018 lw v0,24(s8)
43e858: 240301a4 li v1,420
43e85c: ac4301e4 sw v1,484(v0)
43e860: 8fc20018 lw v0,24(s8)
43e864: 240301ed li v1,493
43e868: ac4301e8 sw v1,488(v0)

Towards the end we can see 493 being loaded into v1, and v1 then being copied into an offset from v0. This looks like a structure member being set to 493, which is what we expected. Above that we see the same thing being done to 420. Further up we have some more stuff being set, including a -1 - that corresponds to CURLSSH_AUTH_DEFAULT, so we seem to be in the right place. There's a zero above that, which corresponds to CURL_TLSAUTH_NONE. That means that the two 1 operations above the -1 are the code we want, and simply changing 43e820 and 43e82c to 24030000 instead of 24030001 means that our targets will be set to 0 (ie, FALSE) rather than 1 (ie, TRUE). Copy the modified binary back to the device, run it and now it happily talks to MITMProxy. Huge success.

(If the app calls Curl_setopt() to reconfigure the state of these values, you'll need to stub those out as well - thankfully, recent versions of curl include a convenient string "CURLOPT_SSL_VERIFYHOST no longer supports 1 as value!" in this function, so if the code in question is using semi-recent curl it's easy to find. Then it's just a matter of looking for the constants that CURLOPT_SSL_VERIFYHOST and CURLOPT_SSL_VERIFYPEER are set to, following the jumps and hacking the code to always set them to 0 regardless of the argument)

comment count unavailable comments

Riku Voipio: Deploying OBS

Open Build Service from SuSE is web service building deb/rpm packages. It has recently been added to Debian, so finally there is relatively easy way to set up PPA style repositories in Debian. Relative as in "there is a learning curve, but nowhere near the complexity of replicating Debian's internal infrastructure". OBS will give you both repositories and build infrastructure with a clickety web UI and command line client (osc) to manage. See Hectors blog for quickstart instructions. Things to learned while setting up OBSMe coming from Debian background, and OBS coming from SuSE/RPM world, there are some quirks that can take by surprise. Well done packagingUsually web services are a tough fit for Distros. The cascade of weird dependencies and build systems where the only practical way to build an "open source" web service is by replicating the upstream CI scripts. Not in case of OBS. Being done by distro people shows. OBS does automatic rebuilds of reverse dependenciesAka automatic binNMUs when you update a library. This however means you need lots of build power around. OBS has it's own dependency resolver on the server that recalculate what packages need rebuilding when - workers just get a list of packages to install for build-depends. This a major divergence from Debian, where sbuild handles dependencies client side. The OBS dependency handler doesn't handle virtual packages* / alternative build-deps like Debian - you may have to add a specific "Prefer: foo-dev" into the OBS project config to solve alternative choices. OBS server and worker do http requests in both directionsOn startup workers connect to OBS server, open a TCP port and wait requests coming OBS. Having connections both directions is a bit of hassle firewall-wise. On the bright side, no need to setup uploads via FTP here.. Signing repositories is complicatedWith Debian 9.0 making signed repositories pretty much mandatory, OBS makes signing rather complicated. obs-signd isn't included in Debian, since it depends on gnupg patch that hasn't been upstreamed. Fortunately I found a workaround. OBS signs release files with /usr/bin/sign -d /path/to/release. Where replacing the obs-signd provided sign command your own script is easy ;) Git integration is rather bolted-on than integratedOBS provides a method to integrate with git using services. - There is no clickety UI to link to git repo, instead you make an xml file called _service with osc. There is no way to have debian/ tree in git. The upstream community is friendlyIncluding the happiest thanks from an upstream I've seen recently. SummaryAll in all rather satisfied with OBS. If you have a home-grown jenkins etc based solution for building DEB/RPM packages, you should definitely consider OBS. For simpler uses, no need to install OBS yourself, openSUSE public OBS will happily build Debian packages for you. *How useful are virtual packages anymore? "foo-defaults" packages seem to be the go-to solution for most real usecases anyways.

Antoine Beaupr : A report from Netconf: Day 1

As is becoming traditional, two times a year the kernel networking community meets in a two-stage conference: an invite-only, informal, two-day plenary session called Netconf, held in Toronto this year, and a more conventional one-track conference open to the public called Netdev. I was invited to cover both conferences this year, given that Netdev was in Montreal (my hometown), and was happy to meet the crew of developers that maintain the network stack of the Linux kernel. This article covers the first day of the conference which consisted of around 25 Linux developers meeting under the direction of David Miller, the kernel's networking subsystem maintainer. Netconf has no formal sessions; although some people presented slides, interruptions are frequent (indeed, encouraged) and the focus is on hashing out issues that are blocked on the mailing list and getting suggestions, ideas, solutions, and feedback from their peers.

Removing ndo_select_queue() One of the first discussions that elicited a significant debate was the ndo_select_queue() function, a key component of the Linux polling system that determines when and how to send packets on a network interface (see netdev_pick_tx and friends). The general question was whether the use of ndo_select_queue() in drivers is a good idea. Alexander Duyck explained that Intel people were considering using ndo_select_queue() for receive/transmit queue matching. Intel drivers do not currently use the hook provided by the Linux kernel and it turns out no one is happy with ndo_select_queue(): the heuristics it uses don't really please anyone. The consensus (including from Duyck himself) seemed to be that it should just not be used anymore, or at least not used for that specific purpose. The discussion turned toward the wireless network stack, which uses it extensively, but for other purposes. Johannes Berg explained that the wireless stack uses ndo_select_queue() for traffic classification, for example to get voice traffic through even if the best-effort queue is backed up. The wireless stack could stop using it by doing flow control completely inside the wireless stack, which already uses the fq_codel flow-control mechanism for other purposes, so porting away from ndo_select_queue() seems possible there. The problem then becomes how to update all the drivers to change that behavior, which would be a lot of work. Still, it seems people are moving away from a generic ndo_select_queue() interface to stack-specific or even driver-specific (in the case of Intel) queue management interfaces.

refcount_t followup There was a followup discussion on the integration of the refcount_t type into the network stack, which we covered recently. This type is meant to be an in-kernel defense against exploits based on overflowing or underflowing an object's reference count. The consensus seems to be that having refcount_t used for debugging is acceptable, but it cannot be enabled by default. An issue that was identified is that the networking developers are fairly sure that introducing refcount_t would have a severe impact on performance, but they do not have benchmarks to prove it, something Miller identified as a problem that needs to be worked on. Miller then expressed some openness to the idea of having it as a kernel configuration option. A similar discussion happened, on the second day, regarding the KASan memory error detector which was covered when it was introduced in 2014. Eric Dumazet warned that there could be a lot of issues that cannot be detected by KASan because of the way the network stack often bypasses regular memory-allocation routines for performance reasons. He also noted that this can sometimes mean the stack may go over the regular 10% memory limit (the tcp_mem parameter, described in the tcp(7) man page) for certain operations, especially when rebuilding out of order packets with lots of parallel TCP connections. Therefore it was proposed that these special memory recycling tricks could be optionally disabled, at run or compile-time, to instrument proper memory tracking. Dumazet argued this was a situation similar to refcount_t in that we need a way to disable high performance to make the network stack easier to debug with KAsan. The problem with optional parameters is that they are often disabled in production or even by default, which, in turn, means that critical bugs cannot actually be found because the code paths are not tested. When I asked Dumazet about this, he explained that Google performs integration testing of new kernels before putting them in production, and those toggles could be enabled there to find and fix those bugs. But he agreed that certain code paths are then not tested until the code gets deployed in production. So it seems the status quo remains: security folks wants to improve the reliability of the kernel, but the network folks can't afford the performance cost. Yet it was clear in the discussions that the team cares about security issues and wants those issues to be fixed; the impact of some of the solutions is just too big.

Lightweight wireless management packet access Berg explained that some users need to have high-performance access to certain management frames in the wireless stack and wondered how to best expose those to user space. The wireless stack already allows users to clone a network interface in "monitor" mode, but this has a big performance cost, as the radiotap header needs to be constructed from scratch and the packet header needs to be copied. As wireless improves and the bandwidth rises to gigabit levels, this can become significant bottleneck for packet sniffers or reporting software that need to know precisely what's going on over the air outside of the regular access point client operation. It seems the proper way to do this is with an eBPF program. As Miller summarized, just add another API call that allows loading a BPF program into the kernel and then those users can use a BPF filtering point to get the statistics they need. This will require an extra hook in the wireless stack, but it seems like this is the way that will be taken to implement this feature.

VLAN 0 inconsistencies Hannes Frederic Sowa brought up the seemingly innocuous question of "how do we handle VLAN 0?" In theory, VLAN 0 means "no VLAN". But the Linux kernel currently handles this differently depending on whether the VLAN module is loaded and whether a VLAN 0 interface was created. Sometimes the VLAN tag is stripped, sometimes not. It turns out the semantics of this were accidentally changed last time there was a change here and this was originally working but is now broken. Sowa therefore got the go-ahead to fix this to make the behavior consistent again.

Loopy fun Then it came the turn of Jamal Hadi Salim, the maintainer of the kernel's traffic-control (tc) subsystem. The first issue he brought up is a problem in the tc REDIRECT action that can create infinite loops within the kernel. The problem can be easily alleviated when loops are created on the same interface: checks can be added that just drop packets coming from the same device and rate-limit logging to avoid a denial-of-service (DoS) condition. The more serious problem occurs when a packet is forwarded from (say) interface eth0 to eth1 which then promptly redirects it from eth1 back to eth0. Obviously, this kind of problem can only be created by a user with root access so, at first glance, those issues don't seem that serious: admins can shoot themselves in the foot, so what? But things become a little more serious when you consider the container case, where an untrusted user has root access inside a container and should have constrained resource limitations. Such a loop could allow this user to deploy an effective DoS attack against a whole group of containers running on the same machine. Even worse, this endless loop could possibly turn into a deadlock in certain scenarios, as the kernel could try to transmit the packet on the same device it originated from and block, progressively filling the queues and eventually completely breaking network access. Florian Westphal argued that a container can already create DoS conditions, for example by doing a ping flood. According to Salim, this whole problem was created when two bits used for tracking such packets were reclaimed from the skb structure used to represent packets in the kernel. Those bits were a simple TTL (time to live) field that was incremented on each loop and dropped after a pre-determined limit was reached, breaking infinite loops. Salim asked everyone if this should be fixed or if we should just forget about this issue and move on. Miller proposed to keep a one-behind state for the packet, fixing the simplest case (two interfaces). The general case, however, would requite a bitmap of all the interfaces to be scanned, which would impose a large overhead. Miller said an attempt to fix this should somehow be made. The root of the problem is that the network maintainers are trying to reduce the size of the skb structure, because it's used in many critical paths of the network stack. Salim's position is that, without the TTL fields, there is no way to fix the general case here, and this constitutes a security issue. So either the bits need to be brought back, or we need to live with the inherent DoS threat.

Dumping large statistics sets Another issue Salim brought up was the question of how to export large statistics sets from the kernel. It turns out that some use cases may end up dumping a lot of data. Salim mentioned a real-world tc use case that calls for reading six-million entries. The current netlink-based API provides a way to get only 20 entries at a time, which means it takes forever to dump the state of all those policy actions. Salim has a patch that changes the dump size be eight times the NLMSG_GOOD_SIZE, which improves performance by an order of magnitude already, although there are issues with checking the user-space buffer size there. But a more complete solution is needed. What Salim proposed was a way to ask only for the states that changed since the last dump was requested. He has a patch to add a last_access field to the netlink_callback structure used by netlink_dump() to output data; that raised the question of how to actually use that field. Since Salim fetches that data every five seconds, he figured he could just tell the kernel to return all the nodes that changed in that period. But then if the dump takes more than five seconds to complete, the next dump may be missing states that changed during the extra delay. An alternative mechanism would be for the user-space utility to keep the time stamp it requested and use that as a delta for the next dump. It turns out this is a larger problem than just tc. Dumazet mentioned this was an issue with fq_codel classes: he would even like to be able to dump those statistics faster than every five seconds. Roopa Prabhu mentioned that Cumulus also has similar problems dumping stats from bridges, so clearly a more generic solution is needed here. There is, however, a fundamental problem with dumping large statistics sets from the kernel: those statistics are constantly changing while the dump is created and unless versioning or locking mechanisms are used which would slow things down the data returned is bound to be only an approximation of reality. Salim promised to send a set of RFC patches to further discussions regarding this issue, but during the following Netdev conference, Berg published a patch to fix this ten-year-old issue, which brought cheers from the audience.
The author would like to thank the Netconf and Netdev organizers for travel to, and hosting assistance in, Toronto. Many thanks to Berg, Dumazet, Salim, and Sowa for their time taken for a technical review of this article. Note: this article first appeared in the Linux Weekly News.

Antoine Beaupr : A report from Netconf: Day 2

This article covers the second day of the informal Netconf discussions, held on on April 4, 2017. Topics discussed this day included the binding of sockets in VRF, identification of eBPF programs, inconsistencies between IPv4 and IPv6, changes to data-center hardware, and more. (See this article for coverage from the first day of discussions).

How to bind to specific sockets in VRF One of the first presentations was from David Ahern of Cumulus, who presented a few interesting questions for the audience. His first was the problem of binding sockets to a given interface. Right now, there are four different ways this can be done:
  • the old SO_BINDTODEVICE generic socket option (see socket(7))
  • the IP_PKTINFO, IP-specific socket option (see ip(7)), introduced in Linux 2.2
  • the IP_UNICAST_IF flag, introduced in Linux 3.3 for WINE
  • the IPv6 scope ID suffix, part of the IPv6 addressing standard
So there's a problem of having too many ways of doing the same thing, something that cannot really be fixed without breaking ABI compatibility. But even worse, conflicts between those options are not reported by the kernel so it's possible for a user to set up socket flags in a way that certain flags override others and there are no checks made or errors reported. It was agreed that the user should get some notification of conflicting changes here, at least. Furthermore, binding sockets to a specific VRF (Virtual Routing and Forwarding) device is not currently possible, so Ahern asked what the best way to do this would be, considering the many options available. A use case example is a UDP multicast socket that could be bound to a specific interface within a VRF. This is an old problem: Tom Herbert explained that there were previous discussions about making the bind() system call more programmable so that, for example, you could bind() a UDP socket to a discrete list of IP addresses or a subnet. So he identified this issue as a broader problem that should be addressed by making the interfaces more generic. Ahern explained that it is currently possible to bind sockets to the slave device of a VRF even though that should not be allowed. He also raised the question of how the kernel should tell which socket should be selected for incoming packets. Right now, there is a scoring mechanism for UDP sockets, but that cannot be used directly in this more general case. David Miller said that there are already different ways of specifying scope: there is the VRF layer and the namespace ("netns") layer. A long time ago, Miller reluctantly accepted the addition of netns keys everywhere, swallowing the performance cost to gain flexibility. He argued that a new key should not be added and instead existing infrastructure should be reused. Herbert argued this was exactly the reason why this should be simplified: "if we don't answer the question, people will keep on trying this". For example, one can use a VRF to limit listening addresses, but it gets complicated if we need a device for every address. It seems the consensus evolved towards using, IP_UNICAST_IF, added back in 2012, which is accessible for non-root users. It is currently limited to UDP and RAW sockets, but it could be extended for TCP.

XDP and eBPF program identification Ahern then turned to the problem of extracting BPF programs from the kernel. He gave the example of a simple cBPF (classic BPF) filter that checks for ARP packets. If the filter is read back from the kernel, the user gets a blob of binary data, which is hard to interpret. There is an kernel verifier that can show C-like output, but that is also difficult to interpret. Ahern then added annotations to his slide that showed what the original program actually does, which was a good demonstration of why such a feature is needed. Ahern explained that, at least for cBPF, it should be possible to recover the original plaintext, or at least something close to the original program. A first step would be to replace known constants (like 0x806 for ARP). Even with eBPF, it should be possible to improve the output. Alexei Starovoitov, the BPF maintainer, explained that it might make sense to start by returning information about the maps used by an eBPF program. Then more complex data structures could be inspected once we know their type. The first priority is to get simple debugging tools working but, in the long term, the goal is a full decompiler that can reconstruct instructions into a human-readable program. The question that remains is how to return this data. Ahern explained that right now the bpf() system call copies the data to a different file descriptor, but it could just fill in a buffer. Starovoitov argued for a file descriptor; that would allow the kernel to stream everything through the same descriptor instead of having many attach points. Netlink cannot be used for this because of its asynchronous nature. A similar issue regarding the way we identify express data path (XDP) programs (which are also written in BPF) was raised by Daniel Borkmann from Covalent. Miller explained that users will want ways to figure out which XDP program was installed, so XDP needs an introspection mechanism. We currently have SHA-1 identifiers that can be internally used to tell which binary is currently loaded but those are not exposed to user space. Starovoitov mentioned it is now just a boolean that shows if a program is loaded or not. A use case for this, on top of just trying to figure out which BPF program is loaded, is to actually fetch the source code of a BPF program that was deployed in the field for which the source was lost. It is still uncertain that it will be possible to extract an exact copy that could then be recompiled into the same program. Starovoitov added that he needed this in production to do proper reporting.

IPv4/IPv6 equivalency The last issue or set of issues that Ahern brought up was the question of inconsistencies between IPv4 and IPv6. It turns out that, because both protocols were (naturally) implemented separately, there are inconsistencies in how they are handled in the Linux kernel, which affect, among other things, the VRF framework. The first example he gave was the fact that IPv6 addresses added on the loopback interface generate unreachable routes in the main routing table, yet this doesn't happen with IPv4 addresses. Hannes Frederic Sowa explained this was part of the IPv6 specification: there are stronger restrictions on loopback interfaces in IPv6 than IPv4. Ahern explained that VRF loopback interfaces do not implement these restrictions and wanted to know if this was a problem. Another issue is that anycast routes are added to the wrong interface. This is apparently not specific to VRF: this was done "just because Java", and has been there from day one. It seems that the Java Virtual Machine builds its own routing table and assumes this behavior, so changing this would break every JVM out there, which is obviously not acceptable. Finally, Martin Kafai Lau asked if work should be done to merge the IPv4 and IPv6 FIB (forwarding information base) trees. The FIB tree is the data structure that represents routing tables in the Linux kernel. Miller explained that the two trees are not semantically equivalent: while IPv6 does source-address lookup and routing, IPv4 does not. We can't remove the source lookups from IPv6, because "people probably use that". According to Alexander Duyck, adding source tables to IPv4 would degrade performance to the level of IPv6 performance, which was jokingly referred to as an incentive to switch to IPv6. More seriously, Sowa argued that using the same compressed tree IPv4 uses in IPv6 could make sense. People may want to have source routing in IPv4 as well. Miller argued that the kernel is optimized for 32-bit addresses in IPv4, and conceded that it could be scaled to 64-bit subnets, but 128-bit addresses would be much harder. Sowa suggested that they could be limited to 64 bits, as global routes that are announced over BGP usually have such a limit, and more specific routes are usually at discrete prefixes like /65, /127 (for interconnect links) or /128 for (for point-to-point links). He expressed concerns over the reliability of such an implementation so, at this point, it is unlikely that the data structures could be merged. What is more likely is that the code path could be merged and simplified, while keeping the data structures separate.

Modules options substitutions The next issue that was raised was from Ji P rko, who asked how to pass configuration options to a driver before the driver is initialized. Some chips require that some settings be sent before the firmware is loaded, which leads to a weird situation where there is a need to address a device before it's actually recognized by the kernel. The question then can be summarized as to how to pass information to a device that doesn't exist yet. The answer seems to be that devlink could do this, as it has access to the full device tree and, therefore, to devices that can be addressed by (say) PCI identifiers. Then a possible devlink command could look something like:
    devlink dev pci/0000:03:00.0 option set foo bar
This idea raised a bunch of extra questions: some devices don't have a one-to-one mapping with the PCI bridge identifiers, for example, meaning that those identifiers cannot be used to access such devices. Another issue is that you may want to send multiple settings in a single transaction, which doesn't fit well in the devlink model. Miller then proposed to let the driver initialize itself to some state and wait for configuration to be sent when necessary. Another way would be to unregister the driver and re-register with the given configuration. Shrijeet Mukherjee explained that right now, Cumulus is doing this using horrible startup script magic by retrying and re-registering, but it would be nice to have a more standard way to do this.

Control over UAPI patches Another issue that came up was the problem of changes in the user-space API (UAPI) which break backward compatibility. P rko said that "we have to be more careful about those changes". The problem is that reviewers are not always available to make detailed reviews of such changes and may not notice API-breaking changes. P rko proposed creating a bot to check if a given patch introduces UAPI changes, changes in structs, or in netlink enums. Miller said he could block merges until discussions happen and that patchwork, which Miller uses to process patches from the mailing list, does some of this. He also pointed out there aren't enough test cases in the first place. Starovoitov argued UAPI isn't special, there are other ways of breaking backward compatibility. He expressed concerns that such a bot could create a false sense that everything is fine while a patch could break compatibility and not be detected. Miller countered that UAPI is special in that "we're stuck with it forever". He then went on to propose that, since there's a maintainer (or more) for each module, he can make sure that each maintainer explicitly approves changes to those modules.

Data-center hardware changes Starovoitov brought up the issue of a new type of hardware that is currently being deployed in data centers called a "multi-host NIC" (network interface card). It's a single NIC that is connected to multiple servers. Facebook, for example, uses this in its Yosemite platform that shoves twelve servers into a 2U rack mount, in three modules. Each module is made of four servers connected to the traditional switch fabric with a single NIC through PCI-Express. Mellanox and and Broadcom also have similar devices. One question is how to manage those devices. Since they are connected through a PCI-Express bus, Linux will see them as a NIC, yet they are also a little like switches, in that they interconnect multiple servers. Furthermore, the kernel security model assumes that a NIC is trusted, and gladly opens its own memory to NICs through DMA; this can become a huge security issue when the NIC is under the control of another server. This can especially become problematic if we consider that there could be TLS hardware offloading in the future with the introduction of in-kernel TLS stacks. The other problem is the question of reliability: since those devices are currently "dumb", they need to be managed just like a regular NIC. If the host managing the card crashes, it could disable a whole set of servers that rely on the same NIC. There could be an election process among the servers, but that complicates significantly what used to be a simple PCI connection. Mukherjee pointed out that the model Cisco uses for this is that the "smart NIC" is a "slave" of the main switch fabric. It's a daughter card, which makes it easier to manage from a network perspective. It is clear that Linux will need a way to represent those devices, probably through the newly introduced switchdev or DSA (distributed switch architecture), but it will be something to keep an eye on as density increases in the data center. There were many more discussions during Netconf, too many to cover here, but in the end, Miller thanked everyone for all the interesting topics as the participants dispersed for a day off to travel to Montreal to attend the following Netdev conference.
The author would like to thank the Netconf and Netdev organizers for travel to, and hosting assistance in, Toronto. Many thanks to Alexei Starovoitov for his time taken for a technical review of this article. Note: this article first appeared in the Linux Weekly News.

Reproducible builds folks: Reproducible Builds: week 102 in Stretch cycle

Here's what happened in the Reproducible Builds effort between Sunday April 2 and Saturday April 8 2017: Media coverage Toolchain development and fixes Reviews of unreproducible packages 27 package reviews have been added, 14 have been updated and 17 have been removed in this week, adding to our knowledge about identified issues. Weekly QA work During our reproducibility testing, FTBFS bugs have been detected and reported by: tests.reproducible-builds.org Misc. This week's edition was written by Chris Lamb, Vagrant Cascadian & reviewed by a bunch of Reproducible Builds folks on IRC & the mailing lists.

10 April 2017

Daniel Pocock: If Alan Turing was born today, would he be a Muslim?

Alan Turing's name and his work are well known to anybody with a theoretical grounding in computer science. Turing developed his theories well before anybody invented file sharing, overclocking or mass surveillance. In fact, Turing was largely working in the absence of any computers at all: the transistor was only invented in 1947 and the microchip, the critical innovation that has made computing both affordable and portable, only came in 1960, four years after Turing's death. To this day, the Turing Test remains a well known challenge in the field of Artificial Intelligence. The most prestigious prize in computing, the A.M. Turing Award from the ACM, equivalent to the Nobel Prize in other fields of endeavour, is named in Turing's honour. (This year's award is another British scientist, Sir Tim Berners-Lee, inventor of the World Wide Web).
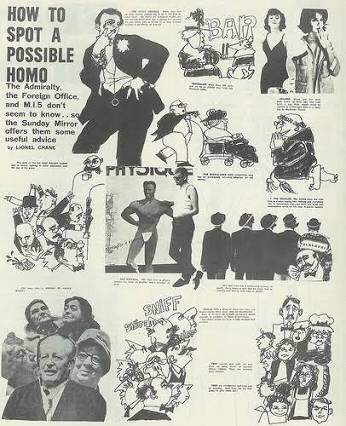
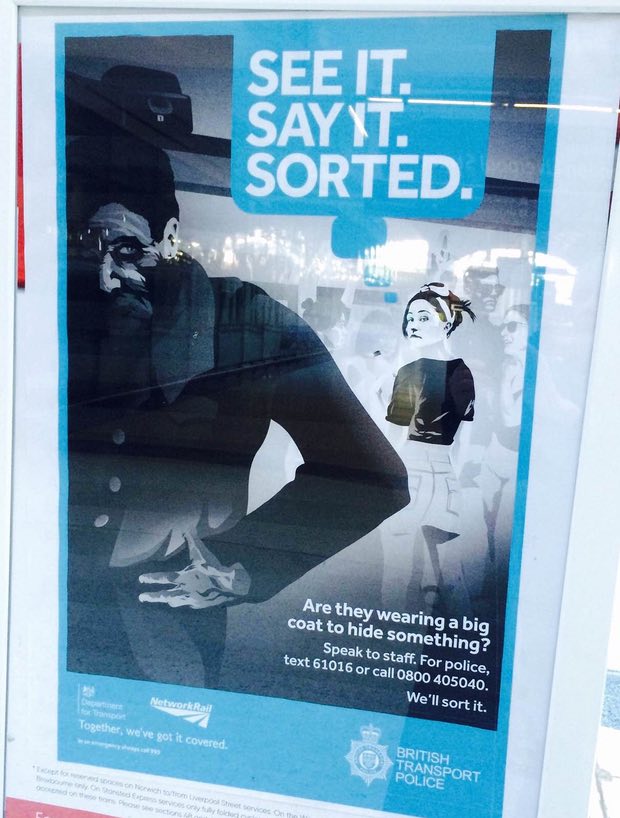
Potentially far more people know of Alan Turing for his groundbreaking work at Bletchley Park and the impact it had on cracking the Nazi's Enigma machines during World War 2, giving the allies an advantage against Hitler. While in his lifetime, Turing exposed the secret communications of the Nazis, in his death, he exposed something manifestly repugnant about his own society. Turing's challenges with his sexuality (or Britain's challenge with it) are just as well documented as his greatest scientific achievements. The 2014 movie The Imitation Game tells Turing's story, bringing together the themes from his professional and personal life. Had Turing chosen to flee British persecution by going abroad, he would be a refugee in the same sense as any person who crossed the seas to reach Europe today to avoid persecution elsewhere. Please prove me wrong In March, I blogged about the problem of racism that plagues Britain today. While some may have felt the tone of the blog was quite strong, I was in no way pleased to find my position affirmed by the events that occurred in the two days after the blog appeared. Two days and two more human beings (both immigrants and both refugees) subjected to abhorrent and unnecessary acts of abuse in Great Britain. Both cases appear to be fuelled directly by the evil that has been oozing out of number 10 Downing Street since they decided to have a referendum on "Brexit". What stands out about these latest crimes is not that they occurred (this type of thing has been going on for months now) but certain contrasts between their circumstances and to a lesser extent, the fact they occurred immediately after Theresa May formalized Britain's departure from the EU. One of the victims was almost beaten to death by a street gang, while the other was abused by men wearing uniforms. One was only a child, while the other is a mature adult who has been in the UK almost three decades, completely assimilated into British life, working and paying taxes. Both were doing nothing out of the ordinary at the time the abuse occurred: one had engaged in a conversation at a bus stop, the other was on a routine visit to a Government office. There is no evidence that either of them had done anything to provoke or invite the abhorrent treatment meted out to them by the followers of Theresa May and Nigel Farage. The first victim, on 30 March, was Stojan Jankovic, a refugee from Yugoslavia who has been in the UK for 26 years. He had a routine meeting at an immigration department office where he was ambushed, thrown in the back of a van and sent to rot in a prison cell by Theresa May's gestapo. On Friday, 31 March, it was Reker Ahmed, a 17 year old Kurdish-Iranian beaten to the brink of death by a crowd in south London. One of the more remarkable facts to emerge about these two cases is that while Stojan Jankovic was basically locked up for no reason at all, the street thugs who the police apprehended for the assault on Ahmed were kept in a cell for less than 48 hours and released again on bail. While the harmless and innocent Jankovic was eventually released after a massive public outcry, he spent more time locked up than that gang of violent criminals who beat Reker Ahmed. In other words, Theresa May and Nigel Farage's Britain has more concern for the liberty of violent criminals than somebody like Jankovic who has been working and paying taxes in the UK since before any of those street thugs were born. A deeper insight into Turing's fate With gay marriage having been legal in the UK for a number of years now, the rainbow flag flying at the Tate and Sir Elton John achieving a knighthood, it becomes difficult for people to relate to the world in which Turing and many other victims were collectively classified by their sexuality, systematically persecuted by the state and ultimately died far sooner than they should have. (Turing was only 41 when he died). In fact, the cruel and brutal forces that ripped Turing apart (and countless other victims too) haven't dissipated at all, they have simply shifted their target. The slanderous comments insinuating that immigrants "steal" jobs or that Islam is about terrorism are eerily reminiscent of suggestions that gay men abduct young boys or work as Soviet spies. None of these lies has any basis in fact, but repeat them often enough in certain types of newspaper and these ideas spread like weeds. In an ironic twist, Turing's groundbreaking work at Bletchley Park was founded on the contributions of Polish mathematicians, their own country having been the first casualty to Hitler, they were also both immigrants and refugees in Britain. Today, under the Theresa May/Nigel Farage leadership, Polish citizens have been subjected to regular vilification by the media and some have even been killed in the street. It is said that a picture is worth a thousand words. When you compare these two pieces of propaganda: a 1963 article in the Sunday Mirror advising people "How to spot a possible homo" and a UK Government billboard encouraging people to be on the lookout for people who look different, could you imagine the same type of small-minded and power-hungry tyrants crafting them, singling out a minority so as to keep the public's attention in the wrong place?
Many people have noticed that these latest UK Government posters portray foreigners, Muslims and basically anybody who is not white using a range of characteristics found in anti-semetic propaganda from the Third Reich: Do the people who create such propaganda appear to have any concern whatsoever for the people they hurt? How would Alan Turing have felt when he encountered propaganda like that from the Sunday Mirror? Do posters like these encourage us to judge people by their gifts in science, the arts or sporting prowess or do they encourage us to lump them all together based on their physical appearance? It is a basic expectation of scientific methodology that when you repeat the same experiment, you should get the same result. What type of experiment are Theresa May and Nigel Farage conducting and what type of result would you expect? Playing ping-pong with children If anybody has any doubt that this evil comes from the top, take a moment to contemplate the 3,000 children who were baited with the promise of resettlement from the Calais "jungle" camp into the UK under the Dubs amendment. When French authorities closed the "jungle" in 2016, the children were lured out of the camp and left with nowhere to go as Theresa May and French authorities played ping-pong with them. Given that the UK parliament had already agreed they should be accepted, was there any reason for Theresa May to dig her heels in and make these children suffer? Or was she just trying to prove her credentials as somebody who can bastardize migrants just the way Nigel Farage would do it? How do British politicians really view migrants? Parliamentarian Keith Vaz, former chair of the Home Affairs Select Committee (responsible for security, crime, prostitution and similar things) was exposed with young men from eastern Europe, encouraging them to take drugs before he ordered them "Take your shirt off. I'm going to attack you.". How many British MP's see foreigners this way? Next time you are groped at an airport security checkpoint, remember it was people like Keith Vaz and his committee who oversee those abuses, writing among other things that "The wider introduction of full-body scanners is a welcome development". No need to "take your shirt off" when these machines can look through it as easily as they can look through your children's underwear. According to the World Health Organization, HIV/AIDS kills as many people as the September 11 attacks every single day. Keith Vaz apparently had no concern for the possibility he might spread this disease any further: the media reported he doesn't use any protection in his extra-marital relationships. While Britain's new management continue to round up foreigners like Stojan Jankovic who have done nothing wrong, they chose not to prosecute Keith Vaz for his antics with drugs and prostitution. Who is Britain's next Alan Turing? Britain's next Alan Turing may not be a homosexual. He or she may have been a child turned away by Theresa May's spat with the French at Calais, a migrant bundled into a deportation van by the gestapo (who are just following orders) or perhaps somebody of Muslim appearance who is set upon by thugs in the street who have been energized by Nigel Farage. If you still have any uncertainty about what Brexit really means, this is it. A country that denies itself the opportunity to be great by subjecting itself to be ruled under the "divide and conquer" mantra of the colonial era. Throughout the centuries, Britain has produced some of the most brilliant scientists of their time. Newton, Darwin and Hawking are just some of those who are even more prominent than Turing, household names around the world. One can only wonder what the history books will have to say about Theresa May and Nigel Farage however. Next time you see a British policeman accosting a Muslim, whether it is at an airport, in a shopping centre, keeping Manchester United souvenirs or simply taking a photograph, spare a thought for Alan Turing and the era when homosexuals were their target of choice.
9 April 2017

Enrico Zini: Ansible config for my stereo

I bought a Raspberry Pi 2 and its case. I could not reuse the existing SD card because it wants a MicroSD. A wise person once told me:
First you do it, then you document it, then you automate it.
I had done the first two, and now I've redone the whole setup with ansible, here: stereo.tar.xz. Hifi with a Raspberry Pi 2 and its case

Sam Hartman: When "when" is too hard a question: SQLAlchemy, Python datetime, and ISO8601

A new programmer asked on a work chat room how timezones are handled in databases. He asked if it was a good idea to store things in UTC. The senior programmers all laughed as we told some of our horror stories with timezones. Yes, UTC is great; if only it were that simple.
About a week later I was designing the schema for a blue sky project I'm implementing. I had to confront time in all its Pythonic horror.
Let's start with the datetime.datetime class. Datetime objects optionally include a timezone. If no timezone is present, several methods such as timestamp treat the object as a local time in the system's timezone. The timezone method returns a POSIX timestamp, which is always expressed in UTC, so knowing the input timezone is important. The now method constructs such an object from the current time.
However other methods act differently. The utcnow method constructs a datetime object that has the UTC time, but is not marked with a timezone. So, for example datetime.fromtimestamp(datetime.utcnow().timestamp()) produces the wrong result unless your system timezone happens to have the same offset as UTC.
It's also possible to construct a datetime object that includes a UTC time and is marked as having a UTC time. The utcnow method never does this, but you can pass the UTC timezone into the now method and get that effect. As you'd expect, the timestamp method returns the correct result on such a datetime.
Now enter SQLAlchemy, one of the more popular Python ORMs. Its DATETIME type has an argument that tries to request a column capable of storing a a timezone from the underlying database. You aren't guaranteed to get this though; some databases don't provide that functionality. With PostgreSQL, I do get such a column, although something in SQLAlchemy is not preserving the timezones (although it is correctly adjusting the time). That is, I'll store a UTC time in an object, flush it to my session, and then read back the same time represented in my local timezone (marked as my local timezone). You'd think this would be safe.
Enter SQLite. SQLite makes life hard for people wanting to store time; it seems to want to store things as strings. That's fairly incompatible with storing a timezone and doing any sort of comparisons on dates. SQLAlchemy does not try to store a timezone in SQLite. It just trims any timezone information from the datetime. So, if I do something like
d = datetime.now(timezone.utc)
obj.date_col = d
session.add(obj)
session.flush()
assert obj.date_col == d # fails
assert obj.date_col.timestamp() == d.timestamp() # fails
assert d == obj.date_col.replace(tzinfo = timezone.utc) # finally succeeds

There are some unfortunate consequences of this. If you mark your datetimes with timezone information (even if it is always the same timezone), whether two datetimes representing the same datetime compare equal depends on whether objects have been flushed to the session yet. If you don't mark your objects with timezones, then you may not store timezone information on other databases.
At least if you use only the methods we've discussed so far, you're reasonably safe if you use local time everywhere in your application and don't mark your datetimes with timezones. That's undesirable because as our new programmer correctly surmised, you really should be using UTC. This is particularly true if users of your database might span multiple timezones.
You can use UTC time and not mark your objects as UTC. This will give the wrong data with a database that actually does support timezones, but will sort of work with SQLite. You need to be careful never to convert your datetime objects into POSIX time as you'll get the wrong result.
It turns out that my life was even more complicated because parts of my project serialize data into JSON. For that serialization, I've chosen ISO 8601. You've probably seen that format: '2017-04-09T18:17:27.340410+00:00. Datetime provides the convenient isoformat method to print timestamps in the ISO 8601 format. If the datetime has a timezone indication, it is included in the ISO formatted string. If not, then no timezone indication is included. You know how I mentioned that datetime takes a string without a timezone marker as local time? Yeah, well, that's not what 8601 does: UTC all the way, baby! And at least the parser in the iso8601 module will always include timezone markers. So, if you use datetime to print a timestamp without a timezone marker and then read that back in to construct a new datetime on the deserialization side, then you'll get the wrong time. OK, so mark things with timezones then. Well, if you use local time, then the time you get depends on whether you print the ISO string before or after session flush (before or after SQLAlchemy trims the timezone information as it goes to SQLite).
It turns out that I had the additional complication of one side of my application using SQLite and one side using PostgreSQL. Remember how I mentioned that something between SQLAlchemy and PostgreSQL was recasting my times in local timezone (although keeping the time the same)? Well, consider how that's going to work. I serialize with the timezone marker on the PostgreSQL side. I get a ISO8601 localtime marked with the correct timezone marker. I deserialize on the SQLite side. Before session flush, I get a local time marked as localtime. After session flush, I get a local time with no marking. That's bad. If I further serialize on the SQLite side, I'll get that local time incorrectly marked as UTC. Moreover, all the times being locally generated on the SQLite side are UTC, and as we explored, SQLite really only wants one timezone in play.
I eventually came up with the following approach:

  1. If I find myself manipulating a time without a timezone marking, assert that its timezone is UTC not localtime.

  2. Always use UTC for times coming into the system.

  3. If I'm generating an ISO 8601 time from a datetime that has a timezone marker in a timezone other than UTC, represent that time as a UTC-marked datetime adjusting the time for the change in timezone.


This is way too complicated. I think that both datetime and SQLAlchemy's SQLite time handling have a lot to answer for. I think SQLAlchemy's core time handling may also have some to answer for, but I'm less sure of that.

5 April 2017

Steinar H. Gunderson: Nageru 1.5.0 released

I just released version 1.5.0 of Nageru, my live video mixer. The biggest feature is obviously the HDMI/SDI live output, but there are lots of small nuggets everywhere; it's been four months in the making. I'll simply paste the NEWS entry here:
Nageru 1.5.0, April 5th, 2017
  - Support for low-latency HDMI/SDI output in addition to (or instead of) the
    stream. This currently only works with DeckLink cards, not bmusb. See the
    manual for more information.
  - Support changing the resolution from the command line, instead of locking
    everything to 1280x720.
  - The A/V sync code has been rewritten to be more in line with Fons
    Adriaensen's original paper. It handles several cases much better,
    in particular when trying to match 59.94 and 60 Hz sources to each other.
    However, it might occasionally need a few extra seconds on startup to
    lock properly if startup is slow.
  - Add support for using x264 for the disk recording. This makes it possible,
    among other things, to run Nageru on a machine entirely without VA-API
    support.
  - Support for 10-bit Y'CbCr, both on input and output. (Output requires
    x264 disk recording, as Quick Sync Video does not support 10-bit H.264.)
    This requires compute shader support, and is in general a little bit
    slower on input and output, due to the extra amount of data being shuffled
    around. Intermediate precision is 16-bit floating-point or better,
    as before.
  - Enable input mode autodetection for DeckLink cards that support it.
    (bmusb mode has always been autodetected.)
  - Add functionality to add a time code to the stream; useful for debugging
    latency.
  - The live display is now both more performant and of higher image quality.
  - Fix a long-standing issue where the preview displays would be too bright
    when using an NVIDIA GPU. (This did not affect the finished stream.)
  - Many other bugfixes and small improvements.
1.5.0 is on its way into Debian experimental (it's too late for the stretch release, especially as it also depends on Movit and bmusb from experimental), or you can get it from the home page as always.

4 April 2017

Ritesh Raj Sarraf: Fixing Hardware Bugs

Bugs can be annoying. Especially the ones that crash or hang and do not have a root cause. A good example of such annoyance can be kernel bugs, where a faulty hardware/device driver hinders the kernel's suspend/resume process. Because, as a user, while in the middle of your work, you suspend your machine hoping to resume your work, back when at your destination. But, during suspend, or during resume, randomly the bug triggers leaving you with no choice but a hardware reset. Ultimately, resulting in you losing the entire work state you were in. Such is a situation I encountered with my 2 year old, Lenovo Yoga 2 13. For 2 years, I had been living with this bug with all the side-effects mentioned.
Mar 01 18:43:28 learner kernel: usb 2-4: new high-speed USB device number 38 using xhci_hcd
Mar 01 18:43:54 learner kernel: usb 2-4: new high-speed USB device number 123 using xhci_hcd
Mar 01 18:44:00 learner kernel: usb 2-4: new high-speed USB device number 125 using xhci_hcd
Mar 01 18:44:11 learner kernel: usb 2-4: new high-speed USB device number 25 using xhci_hcd
Mar 01 18:44:16 learner kernel: usb 2-4: new high-speed USB device number 26 using xhci_hcd
Mar 01 18:44:22 learner kernel: usb 2-4: new high-speed USB device number 27 using xhci_hcd
Mar 01 18:44:22 learner kernel: usb 2-4: device descriptor read/64, error -71
Mar 01 18:44:22 learner kernel: usb 2-4: new high-speed USB device number 28 using xhci_hcd
Mar 01 18:44:23 learner kernel: usb 2-4: device descriptor read/64, error -71
Mar 01 18:44:23 learner kernel: usb 2-4: new high-speed USB device number 29 using xhci_hcd
Mar 01 18:44:23 learner kernel: usb 2-4: Device not responding to setup address.
Mar 01 18:44:23 learner kernel: usb 2-4: device not accepting address 29, error -71
Mar 01 18:44:24 learner kernel: usb 2-4: new high-speed USB device number 30 using xhci_hcd
Mar 01 18:44:24 learner kernel: usb 2-4: Device not responding to setup address.
Mar 01 18:44:24 learner kernel: usb 2-4: device not accepting address 30, error -71
Mar 01 18:44:24 learner kernel: usb usb2-port4: unable to enumerate USB device
Mar 01 18:44:24 learner kernel: usb 2-4: new high-speed USB device number 31 using xhci_hcd
Mar 01 18:44:24 learner kernel: usb 2-4: device descriptor read/64, error -71
Mar 01 18:44:25 learner kernel: usb 2-4: new high-speed USB device number 32 using xhci_hcd
Mar 01 18:44:30 learner kernel: usb 2-4: new high-speed USB device number 33 using xhci_hcd
Mar 01 18:44:30 learner kernel: usb 2-4: device descriptor read/64, error -71
Mar 01 18:44:31 learner kernel: usb 2-4: device descriptor read/64, error -71
Mar 01 18:44:31 learner kernel: usb 2-4: new high-speed USB device number 34 using xhci_hcd
Mar 01 18:44:36 learner kernel: usb 2-4: new high-speed USB device number 35 using xhci_hcd
Mar 01 18:44:36 learner kernel: usb 2-4: device descriptor read/64, error -71
Mar 01 18:44:37 learner kernel: usb 2-4: new high-speed USB device number 36 using xhci_hcd
Mar 01 18:44:37 learner kernel: usb 2-4: device descriptor read/64, error -71
Mar 01 18:44:37 learner kernel: usb 2-4: new high-speed USB device number 37 using xhci_hcd
Mar 01 18:44:37 learner kernel: usb 2-4: Device not responding to setup address.
Mar 01 18:44:38 learner kernel: usb 2-4: device not accepting address 37, error -71
Mar 01 18:44:38 learner kernel: usb 2-4: new high-speed USB device number 38 using xhci_hcd
Mar 01 18:44:38 learner kernel: usb 2-4: Device not responding to setup address.
Mar 02 13:34:05 learner kernel: usb 2-4: new high-speed USB device number 45 using xhci_hcd
Mar 02 13:34:05 learner kernel: usb 2-4: new high-speed USB device number 46 using xhci_hcd
Mar 02 13:34:05 learner kernel: usb 2-4: New USB device found, idVendor=0bda, idProduct=0129
Mar 02 13:34:05 learner kernel: usb 2-4: New USB device strings: Mfr=1, Product=2, SerialNumber=3
Mar 02 13:34:05 learner kernel: usb 2-4: Product: USB2.0-CRW
Mar 02 13:34:05 learner kernel: usb 2-4: Manufacturer: Generic
Mar 02 13:34:05 learner kernel: usb 2-4: SerialNumber: 20100201396000000
Mar 02 13:34:06 learner kernel: usb 2-4: USB disconnect, device number 46
Mar 02 13:34:16 learner kernel: usb 2-4: new high-speed USB device number 47 using xhci_hcd
Mar 02 13:34:21 learner kernel: usb 2-4: new high-speed USB device number 48 using xhci_hcd
Mar 02 13:34:26 learner kernel: usb 2-4: new high-speed USB device number 49 using xhci_hcd
Mar 02 13:34:32 learner kernel: usb 2-4: new high-speed USB device number 51 using xhci_hcd
Mar 02 13:34:37 learner kernel: usb 2-4: new high-speed USB device number 52 using xhci_hcd
Mar 02 13:34:43 learner kernel: usb 2-4: new high-speed USB device number 54 using xhci_hcd
Mar 02 13:34:43 learner kernel: usb 2-4: new high-speed USB device number 55 using xhci_hcd
Mar 02 13:34:49 learner kernel: usb 2-4: new high-speed USB device number 57 using xhci_hcd
Mar 02 13:34:55 learner kernel: usb 2-4: new high-speed USB device number 58 using xhci_hcd
Mar 02 13:35:00 learner kernel: usb 2-4: new high-speed USB device number 60 using xhci_hcd
Mar 02 13:35:06 learner kernel: usb 2-4: new high-speed USB device number 61 using xhci_hcd
Mar 02 13:35:11 learner kernel: usb 2-4: new high-speed USB device number 63 using xhci_hcd
Mar 02 13:35:17 learner kernel: usb 2-4: new high-speed USB device number 64 using xhci_hcd
Mar 02 13:35:22 learner kernel: usb 2-4: new high-speed USB device number 65 using xhci_hcd
Mar 02 13:35:28 learner kernel: usb 2-4: new high-speed USB device number 66 using xhci_hcd
Mar 02 13:35:33 learner kernel: usb 2-4: new high-speed USB device number 68 using xhci_hcd
Mar 02 13:35:39 learner kernel: usb 2-4: new high-speed USB device number 69 using xhci_hcd
Mar 02 13:35:44 learner kernel: usb 2-4: new high-speed USB device number 70 using xhci_hcd
Mar 02 13:35:50 learner kernel: usb 2-4: new high-speed USB device number 71 using xhci_hcd
Mar 02 13:35:50 learner kernel: usb 2-4: Device not responding to setup address.
Mar 02 13:35:50 learner kernel: usb 2-4: device not accepting address 71, error -71
Mar 02 13:35:50 learner kernel: usb 2-4: new high-speed USB device number 73 using xhci_hcd
Mar 02 13:35:51 learner kernel: usb 2-4: new high-speed USB device number 74 using xhci_hcd
Mar 02 13:35:56 learner kernel: usb 2-4: new high-speed USB device number 75 using xhci_hcd
Mar 02 13:35:57 learner kernel: usb 2-4: new high-speed USB device number 77 using xhci_hcd
Mar 02 13:36:03 learner kernel: usb 2-4: new high-speed USB device number 78 using xhci_hcd
Mar 02 13:36:08 learner kernel: usb 2-4: new high-speed USB device number 79 using xhci_hcd
Mar 02 13:36:14 learner kernel: usb 2-4: new high-speed USB device number 80 using xhci_hcd
Mar 02 13:36:20 learner kernel: usb 2-4: new high-speed USB device number 83 using xhci_hcd
Mar 02 13:36:26 learner kernel: usb 2-4: new high-speed USB device number 86 using xhci_hcd
Thanks to the Linux USB maintainers, we tried investigating the issue, which resulted in uncovering other bugs. Unfortunately, this bug was concluded as a possible hardware bug. The only odd bit is that this machine has a Windows 8.1 copy still lying on the spare partition, where the issue was not seen at all. It could very well be that it was not a hardware bug at all, or a hardware bug which had a workaround in the Windows driver. But, the results of the exercise weren't much useful to me because I use the machine under the Linux kernel most of the time. So, this March 2017, with 2 years completion on me purchasing the device, I was annoyed enough by the bugs. That led me trying out finding other ways to taming this issue. Lenovo has some variations of this device. I know that it comes with multiple options for the storgae and the wifi component. I'm not sure if there are more differences. The majority of the devices are connected over the xHCI bus on this machine. If a single device is faulty, or has faulty hardware; it could screw up the entire user experience for that machine. Such is my case. Hardware manufacturers could do a better job if they could provide a means to disable hardware, for example in the BIOS. HP shipped machines have such an option in the BIOS where you can disable devices that do not have an important use case for the user. Good example of such devices are Fingerprint Readers, SD Card Readers, LOMs and mabye Bluetooth too. At least the latter should apply for Linux users, as majority of us have an unpleasant time getting Bluetooth to work out of the box. But on my Lenovo Yoga, it came with a ridiculous BIOS/UEFI, with very very limited options for change. Thankfully, they did have an option to set the booting mode for the device, giving the choices of Legacy Boot and UEFI. Back to the topic, with 2 years of living with the bug, and no clarity on if and whether it was a hardware bug or a driver bug, it left me with no choice but to open up the machine. Next to the mSATA HDD sits the additional board, which houses the Power, USB, Audio In, and the SD Card reader. Opening that up, I got the small board. I barely use the SD Card reader, and given the annoyances I had to suffer because of it, there was no more mercy in killing that device. So, next was to unsolder the SD Card reader completely. Once done, and fitted back into the machine, everything has been working awesomely great in the last 2 weeks. This entire fix costed me 0. So sometimes, fixing a bug is all that matters. In the Hindi language, a nice phrase for such a scenario remnids me of the great Chanakya, " , , ".
Categories:

Keywords:

Like:

Matthias Klumpp: On Tanglu

It s time for a long-overdue blogpost about the status of Tanglu. Tanglu is a Debian derivative, started in early 2013 when the systemd debate at Debian was still hot. It was formed by a few people wanting to create a Debian derivative for workstations with a time-based release schedule using and showcasing new technologies (which include systemd, but also bundling systems and other things) and built in the open with a community using the similar infrastructure to Debian. Tanglu is designed explicitly to complement Debian and not to compete with it on all devices. Tanglu has achieved a lot of great things. We were the first Debian derivative to adopt systemd and with the help of our contributors we could kill a few nasty issues affecting it and Debian before it ended up becoming default in Debian Jessie. We also started to use the Calamares installer relatively early, bringing a modern installation experience additionally to the traditional debian-installer. We performed the usrmerge early, uncovering a few more issues which were fed back into Debian to be resolved (while workarounds were added to Tanglu). We also briefly explored switching from initramfs-tools to Dracut, but this release goal was dropped due to issues (but might be revived later). A lot of other less-impactful changes happened as well, borrowing a lot of useful ideas and code from Ubuntu (kudos to them!). On the infrastructure side, we set up the Debian Archive Kit (dak), managing to find a couple of issues (mostly hardcoded assumptions about Debian) and reporting them back to make using dak for distributions which aren t Debian easier. We explored using fedmsg for our infrastructure, went through a long and painful iteration of build systems (buildbot -> Jenkins -> Debile) before finally ending up with Debile, and added a set of own custom tools to collect archive QA information and present it to our developers in an easy to digest way. Except for wanna-build, Tanglu is hosting an almost-complete clone of basic Debian archive management tools. During the past year however, the project s progress slowed down significantly. For this, mostly I am to blame. One of the biggest challenges for a young project is to attract new developers and members and keep them engaged. A lot of the people coming to Tanglu and being interested in contributing were unfortunately no packagers and sometimes no developers, and we didn t have the manpower to individually mentor these people and teach them the necessary skills. People asking for tasks were usually asked where their interests were and what they would like to do to give them a useful task. This sounds great in principle, but in practice it is actually not very helpful. A curated list of junior jobs is a much better starting point. We also invested almost zero time in making our project known and create the necessary buzz and excitement that s actually needed to sustain a project like this. Doing more in the advertisement domain and help newcomers area is a high priority issue in the Tanglu bugtracker, which to the day is still open. Doing good alone isn t enough, talking about it is of crucial importance and that is something I knew about, but didn t realize the impact of for quite a while. As strange as it sounds, investing in the tech only isn t enough, community building is of equal importance. Regardless of that, Tanglu has members working on the project, but way too few to manage a project of this magnitude (getting package transitions migrated alone is a large task requiring quite some time while at the same time being incredibly boring :P). A lot of our current developers can only invest small amounts of time into the project because they have a lot of other projects as well. The other issue why Tanglu has problems is too much stuff being centralized on myself. That is a problem I wanted to rectify for a long time, but as soon as a task wasn t done in Tanglu because no people were available to do it, I completed it. This essentially increased the project s dependency on me as single person, giving it a really low bus factor. It not only centralizes power in one person (which actually isn t a problem as long as that person is available enough to perform tasks if asked for), it also centralizes knowledge on how to run services and how to do things. And if you want to give up power, people will need the knowledge on how to perform the specific task first (which they will never gain if there s always that one guy doing it). I still haven t found a great way to solve this it s a problem that essentially kills itself as soon as the project is big enough, but until then the only way to counter it slightly is to write lots of documentation. Last year I had way less time to work on Tanglu than the project deserves. I also started to work for Purism on their PureOS Debian derivative (which is heavily influenced by some of the choices we made for Tanglu, but with different focus that s probably something for another blogpost). A lot of the stuff I do for Purism duplicates the work I do on Tanglu, and also takes away time I have for the project. Additionally I need to invest a lot more time into other projects such as AppStream and a lot of random other stuff that just needs continuous maintenance and discussion (especially AppStream eats up a lot of time since it became really popular in a lot of places). There is also my MSc thesis in neuroscience that requires attention (and is actually in focus most of the time). All in all, I can t split myself and KDE s cloning machine remains broken, so I can t even use that ;-). In terms of projects there is also a personal hard limit of how much stuff I can handle, and exceeding it long-term is not very healthy, as in these cases I try to satisfy all projects and in the end do not focus enough on any of them, which makes me end up with a lot of half-baked stuff (which helps nobody, and most importantly makes me loose the fun, energy and interest to work on it). Good news everyone! (sort of) So, this sounded overly negative, so where does this leave Tanglu? Fact is, I can not commit the crazy amounts of time for it as I did in 2013. But, I love the project and I actually do have some time I can put into it. My work on Purism has an overlap with Tanglu, so Tanglu can actually benefit from the software I develop for them, maybe creating a synergy effect between PureOS and Tanglu. Tanglu is also important to me as a testing environment for future ideas (be it in infrastructure or in the make bundling nice! department). So, what actually is the way forward? First, maybe I have the chance to find a few people willing to work on tasks in Tanglu. It s a fun project, and I learned a lot while working on it. Tanglu also possesses some unique properties few other Debian derivatives have, like being built from source completely (allowing us things like swapping core components or compiling with more hardening flags, switching to newer KDE Plasma and GNOME faster, etc.). Second, if we do not have enough manpower, I think converting Tanglu into a rolling-release distribution might be the only viable way to keep the project running. A rolling release scheme creates much less effort for us than making releases (especially time-based ones!). That way, users will have a constantly updated and secure Tanglu system with machines doing most of the background work. If it turns out that absolutely nothing works and we can t attract new people to help with Tanglu, it would mean that there generally isn t much interest from the developer or user side in a project like this, so shutting it down or scaling it down dramatically would be the only option. But I do not think that this is the case, and I believe that having Tanglu around is important. I also have some interesting plans for it which will be fun to implement for testing  The only thing that had to stop is leaving our users in the dark on what is happening. Sorry for the long post, but there are some subjects which are worth writing more than 140 characters about  If you are interested in contributing to Tanglu, get in touch with us! We have an IRC channel #tanglu-devel on Freenode (go there for quicker responses!), forums and mailinglists, It looks like I will be at Debconf this year as well, so you can also catch me there! I might even talk about PureOS/Tanglu infrastructure at the conference.

3 April 2017

Vincent Fourmond: Variations around ls -lrt

I have been using almost compulsively ls -lrt for a long time now. As per the ls man page, this command lists the files of the current directory, with the latest files at the end, so that they are the ones that show up just above your next command-line. This is very convenient to work with, hmmm, not-so-well-organized directories, because it just shows what you're working on, and you can safely ignore the rest. Typical example is a big Downloads directory, for instance, but I use it everywhere. I quickly used alias lrt="ls -lrt" to make it easier, but... I though I might have as well a reliable way to directly use what I saw. So I came up with the following shell function (zsh, but probably works with most Bourne-like shells):
lrt()  
    ls -lrt "$@"
    lrt="$(ls -rt "$@"   tail -n1)"
 
This small function runs ls -lrt as usual, but also sets the $lrt shell variable to the latest file, so you can use it in your next commands ! Especially useful for complex file names. Demonstration:
22:05 vincent@ashitaka ~/Downloads lrt
[...]
-rw-r--r-- 1 vincent vincent   1490027 Apr  2 15:44 k.zip
-rw-r--r-- 1 vincent vincent    668566 Apr  3 22:05 1-s2.0-S0013468617305947-main.pdf
22:06 vincent@ashitaka ~/Downloads cp -v $lrt ~/nice-paper.pdf
'1-s2.0-S0013468617305947-main.pdf' -> '/home/vincent/nice-paper.pdf'
This saves typing the name of the 1-s2.0-S0013468617305947-main.pdf: in this case, automatic completion doesn't help much, since many files in my Downloads directory start with the same orefix... I hope this helps !

Markus Koschany: My Free Software Activities in March 2017

Welcome to gambaru.de. Here is my monthly report that covers what I have been doing for Debian. If you re interested in Android, Java, Games and LTS topics, this might be interesting for you. Debian Android Debian Games Debian Java Debian LTS This was my thirteenth month as a paid contributor and I have been paid to work 14,75 hours on Debian LTS, a project started by Rapha l Hertzog. In that time I did the following: Misc Thanks for reading and see you next time.

2 April 2017

Eugene V. Lyubimkin: experiment: optionalising shared libraries without dl_open via generating stub libraries

Reading the discussion on debian-devel about shared library dependencies in C/C++, I wondered if it's possible to link with a shared library without having an absolute dependency on it.

The issue comes often when one has a piece of software which could use extra functionality the shared library (let's call it biglib) provides, but the developer/maintainer doesn't want to force all users to install it. The common solution seems to be either:

- defining a plugin interface and a bridge library (better detailed at here);

- dlopen/dlsym to load each library symbol by hand (good luck doing that for high-level C++ libraries).


Both solutions involve dlopen at one stage or another to avoid linking with a biglib, since if you do that, the application loader will refuse to load the application unless biglib and all of its dependencies are present. But what if application is prepared to fallback at run time, and just needs a way to be able to start without biglib?

I went ahead to check what if there was a stub library to provide all symbols which the application uses (directly or indirectly) out of biglib. Turns out that yes, at least for simple cases it seems to work. I've published my experimental stub generator at https://github.com/jackyf/so-stub .

For practical use, we'd also need a way to tell the loader that a stub library has to be loaded if the real library is not found. While there is many ways to instruct the loader to load something instead of system libraries (LD_PRELOAD, LD_LIBRARY_PATH, runpath, rpath), I found no way to load something if a system library was not found. In other words, I'd like to say "dear linker/loader, when you're loading myapp: if you didn't find libfoo1.so.4 in any of system directories configured, try also at /usr/lib/myapp/stubs/ (which'd contain stubbed libfoo1.so.4)". Apparently, nothing like "rpath-fallback" exists right now. I'm considering creating a feature request for such a "rpath-fallback" if the "optional libraries via stubs" idea gets wider support.

1 April 2017

Mike Hommey: git-cinnabar experimental features

Since version 0.4.0, git-cinnabar has a few hidden experimental features. Two of them are available in 0.4.0, and a third was recently added on the master branch. The basic mechanism to enable experimental features is to set a preference in the git configuration with a comma-separated list of features to enable, or all, for all of them. That preference is cinnabar.experiments. Any means to set a git configuration can be used. You can: But what features are there? wire In order to talk to Mercurial repositories, git-cinnabar normally uses mercurial python modules. This experimental feature allows to access Mercurial repositories without using the mercurial python modules. It then relies on git-cinnabar-helper to connect to the repository through the mercurial wire protocol. As of version 0.4.0, the feature is automatically enabled when Mercurial is not installed. merge Git-cinnabar currently doesn t allow to push merge commits. The main reason for this is that generating the correct mercurial data for those merges is tricky, and needs to be gotten right. In version 0.4.0, enabling this feature allows to push merge commits as long as the parent commits are available on the mercurial repository. If they aren t, you need to first push them independently, and then push the merge. On current master, that limitation doesn t exist anymore ; you can just push everything in one go. The main caveat with this experimental support for pushing merges is that it currently doesn t handle the case where a file was moved on one of the branches the same way mercurial would (i.e. the information would be lost to mercurial users). clonebundles As of mercurial 3.6, Mercurial servers can opt-in to providing pre-generated bundles, which, when clients support it, takes CPU load off the server when a clone is performed. Good for servers, and usually good for clients too when they have a fast network connection, because downloading a pre-generated bundle is usually faster than waiting for the server to generate one. As of a few days ago, the master branch of git-cinnabar supports cloning using those pre-generated bundles, provided the server advertizes them (mozilla-central does).

Antoine Beaupr : My free software activities, February and March 2017

Looking into self-financing Before I begin, I should mention that I started tracking my time working on free software more systematically. I spend a lot of time on the computer, as regular readers of this blog might remember so I wanted to know exactly how much time was paid vs free work. I was already using org-mode's time clock system to keep track of my work hours, so I just extended this to my regular free software contributions, which also helps in writing those reports. It turns out that over 60% of my computer time is spent working on free software. That's huge! I was expecting something more along the range of 20 to 40% of my time. So I started thinking about ways of financing this work. I created a Patreon page but I'm hesitant into launching such a campaign: the only thing worse than "no patreon page" is "a patreon page with failed goals and no one financing it". So before starting such an effort, I'd like to get a feeling of what other people's experience with it are. I know that joeyh is close to achieving his goals, but I can't compare with the guy that invented git-annex or debhelper, so I'm concerned I wouldn't be able to raise the same level of funding. So any advice you have, feel free to contact me in private or in the comments. If you would be ready to fund my work, I'd love to know about it, obviously, but I guess I wouldn't get real numbers until I actually open up such a page... Now, onto the regular report.

Wallabako I spent a good chunk of time completing most of the things I had in mind for Wallabako, which I mentioned quickly in the previous report. Wallabako is now much easier to installed, with clearer instructions, an easier to use configuration file, more reliable synchronization and read status propagation. As usual the Wallabako README file has all the details. I've also looked at better integration with Koreader, the free software e-reader that forms the basis of the okreader free software distribution which has been able to port Debian to the Kobo e-readers, a project I am really excited about. This project has the potential of supporting Kobo readers beyond the lifetime that upstream grants it and removes a lot of proprietary software and spyware that ships with the Kobo readers. So I have made a few contributions to okreader and also on koreader, the ebook reader okreader is based on.

Stressant I rewrote stressant, my simple burn-in and stress-testing tool. After struggling in turn with Debirf, live-build, vmdebootstrap and even FAI, I just figured maybe it wasn't the best idea to try and reinvent that particular wheel: instead of reinventing how to build yet another Debian system build tool, maybe I should just reuse what's already there. It turns out there's a well known, succesful and fairly complete recovery system called Grml. It is a Debian Derivative, so all I needed to do was to stop procrastinating and actually write the actual stressant tool instead of just creating a distribution with a bunch of random tools shipped in. This allowed me to focus on which tools were the best to stress test different components. This selection ended up being: fio can also be used to overwrite disk drives with the proper options (--overwrite and --size=100%), although grml also ships with nwipe for wiping old spinning disks and hdparm to do a secure erase of SSD disks (whatever that's worth). Stressant still needs to be shipped with grml for this transition to be complete. In the meantime, I was able to configure the excellent public Gitlab CI service to provide ISO images with Stressant built-in as a stopgap measure. I also need to figure out a way to automate starting stressant from a boot menu to automate deployments on a larger scale, although because I have little need for the feature at this moment in time, this will likely wait for a sponsor to show up for this to be implemented. Still, stressant has useful features like the capability of sending logs by email using a fresh new implementation of the Python SMTPHandler (BufferedSMTPHandler) which waits for logging to complete before sending a single email. Another interesting piece of code in there is the NegateAction argparse handler that enables the use of "toggle flags" (e.g. --flag / --no-flag). I'm so happy with the code that I figure I could just share it here directly:
class NegateAction(argparse.Action):
    '''add a toggle flag to argparse

    this is similar to 'store_true' or 'store_false', but allows
    arguments prefixed with --no to disable the default. the default
    is set depending on the first argument - if it starts with the
    negative form (define by default as '--no'), the default is False,
    otherwise True.
    '''
    negative = '--no'
    def __init__(self, option_strings, *args, **kwargs):
        '''set default depending on the first argument'''
        default = not option_strings[0].startswith(self.negative)
        super(NegateAction, self).__init__(option_strings, *args,
                                           default=default, nargs=0, **kwargs)
    def __call__(self, parser, ns, values, option):
        '''set the truth value depending on whether
        it starts with the negative form'''
        setattr(ns, self.dest, not option.startswith(self.negative))
Short and sweet. I wonder why stuff like this is not in the standard library yet - maybe just because no one bothered yet? It'd be great to get feedback of more experienced Pythonistas on this one. I hope that my work on Stressant is complete. I get zero funding for this work, and have little use for it myself: I manage only a few machines and such a tool really shines when you regularly put new hardware online, which is (fortunately?) not my case anymore. I'd be happy, of course, to accompany organisations and people that wish to further develop and use such a tool. A short demo of stressant as well as detailed description of how it works is of course available in its README file.

Standard third party repositories After looking at improvements for the grml repository instructions, I realized there was no real "best practices" document on how to configure an Apt repository. Sure, there are tools like reprepro and others, but those hardly qualify as policy: they are very flexible and there are lots of ways to create insecure repositories or curl sh style instructions, which we of course generally want to avoid. While the larger problem of Unstrusted Debian packages remain generally unsolved (e.g. when you install any .deb file, it can get root on your system), it seemed to me one critical part of this problem was how to add a random third-party repository to your machine while limiting, as much as possible, what possible attackers could do with such a repository. In other words, to solve the more general problem of insecure .deb files, we also need to solve the distribution problem, otherwise fixing the .deb files themselves will be useless. This lead to the creation of standardized repository instructions that define:
  1. how to distribute the repository's public signing key (ie. over HTTPS)
  2. how to name suites and components (e.g. use stable and main unless you have a good reason, and explain yourself)
  3. recommend a healthy does of apt preferences pinning
  4. how to distribute keys (e.g. with a derive-archive-keyring package)
I've seen so many third party repositories get this wrong. For example, a lot of repositories recommend this type of command to intialize the OpenPGP trust path:
curl http://example.com/key.asc   apt-key add -
This has the following problems:
  • the key is transfered in plaintext and can easily be manipulated by an active attacker (e.g. a router on your path to the server or a neighbor in a Wifi cafe)
  • the key is added to the main trust root, which allows the key to authentify as the real Debian archive, therefore giving it all rights over all packages
  • since it's part of the global archive, it's difficult for a package to remove/add the key when a key rollover is necessary (and repositories generally don't provide a deriv-archive-keyring to do that process anyways)
An example of this are the Docker install instructions that, at least, manage to do this over HTTPS. Some other repositories don't even bother teaching people about the proper way of adding those keys. We settled for:
wget -O /usr/share/keyrings/deriv-archive-keyring.gpg https://deriv.example.net/debian/deriv-archive-keyring.gpg
That location was explicitly chosen to be out of the main trust directory, so that it needs to be explicitly added to the sources.list as well:
deb [signed-by=/usr/share/keyrings/deriv-archive-keyring.gpg] https://deriv.example.net/debian/ stable main
Similarly, we highly recommend users setup "apt pinning" to restrict what a given repository can do. Since pinning is so confusing, most people don't actually bother even configuring it and I have yet to see a single repo advise its users to configure those preferences, which are essential to limit what a repository can do. To keep configuration simple, we recommend this:
Package: *
Pin: origin deriv.example.net
Pin-Priority: 100
Obviously, for a single-package repository, the actual package name should be listed, e.g.:
Package: foo
Pin: origin deriv.example.net
Pin-Priority: 100
And the priority should probably be set to 1 unless you want to allow automatic upgrades. It is my hope that this design will get more traction in the years to come and become a de-facto standard that will be a key part in safely adding third party repositories. There is obviously much more work to be done to improve security when installing untrusted .deb files, and I encourage Debian developers to consider contributing to the UntrustedDebs discussions and particularly to the Teams/Dpkg/Spec/DeclarativePackaging work.

Signal R&D I spent a significant amount of time this month struggling with the Signal project on my phone. I'm still ambivalent on Signal: it's a centralized designed, too dependent on phone numbers, but I must admit they get a lot of things right and it's the only free-software platform that allows for easy-to-use, multi-platform videoconferencing that my family can use. I've been following Signal for a while: up until now, I had been using the LibreSignal rebuild of the official client, as it is distributed on a F-Droid repository. Because I try to avoid Google (proprietary) software on my phone, it's basically the only way I could even install Signal. Unfortunately, the repository is out of date and introduces another point of trust in the distribution model: now you not only need to trust the Signal authors to do the right thing, you also need to trust that F-Droid repo not to inject nasty code on your phone. I've therefore started a discussion about how Signal could be distributed outside of the Google Play Store. I'd like to think it's one of the things that led the Signal people to distribute an official copy of Signal outside of the playstore. After much struggling, I was able to upgrade to this official client and will be able to upgrade easily by just downloading the APK. (Do note that I ended up reinstalling and re-registering Signal, which unfortunately changed my secret keys.) I do hope Signal enters F-Droid one day, but it could take a while because it still doesn't work without Google services and barely works with MicroG, the free software alternative to the Google services clients. Moxie also set a list of requirements like crash reporting and statistics that need to be implemented on F-Droid's side before he agrees to the deployment, so this could take a while. I've also participated in the, ahem, discussion on the JWZ blog regarding a supposed vulnerability in Signal where it would leak previously unknown phone numbers to third parties. I reviewed the way the phone number is uploaded and, while it's possible to create a rainbow table of phone numbers (which are hashed with a truncated SHA-1 checksum), I couldn't verify the claims of other participants in the thread. For me, Signal still does the right thing with contacts, although I do question the way "read status" notifications get transmitted, but that belong in another bug report / blog post.

Debian Long Term Support (LTS) It's been more than a year working on Debian LTS, started by Raphael Hertzog at Freexian. I didn't work much in February so I had a lot of hours to catchup with, and was unfortunately unable to do so, partly because I was busy with other projects, and partly because my colleagues are doing a great job at resolving the most important issues. So one my concerns this month was finding work. It seemed that all the hard packages were either taken (e.g. my usual favorites, tiff and imagemagick, we done by others) or just too challenging (e.g. I don't feel quite comfortable tackling the LTS branch of the Linux kernel yet). I spent quite a bit of time trying to figure out what was wrong with pcre3, only to realise the "32" in the report was not about the architecture, but about the character width. Because of thise, I marked 4 CVEs (CVE-2017-7186, CVE-2017-7244, CVE-2017-7245, CVE-2017-7246) as "not-affected", since the 32-bith character support wasn't enabled in wheezy (or jessie, for that matter). I still spent some time trying to reproduce the issues, which require a compiler with an AddressSanitizer, something that was introduced in both Clang and GCC after Wheezy was released, which makes reproducing this fairly complicated... This allowed me to experiment more with Vagrant, however, and I have provided the Debian cloud team with a 32-bit Vagrant box that was merged in shortly after, although it doesn't show up yet in the official list of Debian images. Then I looked at the apparmor situation (CVE-2017-6507), Debian bug #858768). That was one tricky bug as well, since it's not a security issue in apparmor per se, but more an issue with things that assume a certain behavior from apparmor. I have concluded that Wheezy was not affected because there are no assumptions of proper isolation there - which are provided only starting from LXC 1.0 - and Docker is not in Wheezy. I also couldn't reproduce the issue on Jessie, but, as it turns out, the issue was sysvinit-specific, which is why I couldn't reproduce it under the default systemd configuration shipped with Jessie. I also looked at the various binutils security issues: as I reported on the mailing list, I didn't see anything serious enough in there to warrant a a security release and followed the lead of both the stable and Red Hat security teams by marking this "no-dsa". I similiarly reviewed the mp3splt security issues (specifically CVE-2017-5666) and was fairly puzzled by that issue, which seems to be triggered only the same address sanitization extensions than PCRE, although there was some pretty wild interplay with debugging flags in there. All in all, it seems we can't reproduce that issue in wheezy, but I do not feel confident enough in the results to push that issue aside for now. I finally uploaded the pending graphicsmagick issue (DLA-547-2), a regression update to fix a crash that was introduced in the previous release (DLA-547-1, mistakenly named DLA-574-1). Hopefully that release should clear up some of the confusion and fix the regression. I also released DLA-879-1 for the CVE-2017-6369 in firebird2.5 which was an interesting experiment: I couldn't reproduce the issue in a local VM. After following the Ubuntu setup tutorial, as I wasn't too familiar with the Firebird database until now (hint: the default username and password is sysdba/masterkey), I ended up assuming we were vulnerable and just backporting the patch after seeing the jessie folks push out a release just in case. I also looked at updating the ca-certificates package to deal with the pending WoSign/Startcom removal: I made an explicit list of the CAs that need to be removed after reviewing the Mozilla list. I also sent a patch for an unrelated issue where ca-certificates is writing to /usr/local (!!) in Debian bug #843722. I have also done some "meta" work in starting a discussion about fixing the missing DLA links in the tracker, as you will notice all of the above links lead to nowhere. Thanks to pabs, there are now some links but unfortunately there are about 500 DLAs missing from the website. We also discussed ways to Debian bug #859123, something which is currently a manual process. This is now in the hands of the excellent webmaster team. I have also filed a few missing security bugs (Debian bug #859135, Debian bug #859136), partly because I wanted to help the security team. But it turned out that I felt the script needed some improvements, so I submitted a patch to improve the script so it is easier to run.

Other projects As usual, there's the usual mixed bags of chaos: More stuff on Github...

David Kalnischkies: Winning the Google Open Source Lottery

I don't know about you, but I frequently get mails announcing that I was picked as the lucky winner of a lottery, compensation program or simply as "business associate". Obvious Spam of course, that never happens in reality. Just like my personal "favorite" at the moment: Mails notifying me of inheritance from a previously (more or less) unknown relative. Its just that this is what has happend basically a few weeks ago in reality to me (over the phone through) and I am still dealing with the bureaucracy required of teaching the legal system that I have absolutely no intention of becoming the legal successor of someone I haven't seen in 20 years, regardless of how close the family relation is on paper but that might be the topic of another day. On the 1st March a mail titled "Google Open Source Peer Bonus Program" looked at first as if it would fall into this lottery spam class. It didn't exactly help that the mail was multipart HTML and text, but the text really only the text, not mentioning the embedded links used in the HTML part. It even included a prominent and obvious red flag: "Please fill out the form". 20% Bayes score didn't come from nothing. Still, for better or worse the words "Open Source" made it unlikely to be spam similar to how the word PGP indicates authenticity. So it happened, another spam message became true for me. I wonder which one will be next You have probably figured out by now that I didn't know that program before. Kinda embarrassing for a previous Google Summer of Code student (GSoC is run by the same office), but the idea behind it is simple: Google employees can nominate contributors to open source stuff for a small monetary "thank you!" gift card. Earlier this week winners for this round were announced 52 contributors including yours truly. You might be surprised, but the rational given behind my name is APT (I got a private mail with the full rational from my "patron", just in case you wonder if at least I would know more). It is funny how a guy who was taken aback by the prospect of needing a package manager like YaST to use Linux contributed just months later the first patch to apt and has roughly 8 years later amassed more than 2400 commits. It's birthday season in my family with e.g. mine just a few days ago, so its seems natural that apt has its own birthday today just as if it would be part of my family: 19th years this little bundle of bugs joy is now! In more sober moments I wonder sometimes how apt and I would have turned out if we hadn't meet. Would apt have met someone else? Would I? Given that I am still the newest team member and only recently joined Debian as DD at all APT has some strange ways of showing that it loves you: It e.g. helps users compose mails which end in a dilemma to give a recent example. Perhaps you need to be a special kind of crazy1 to consider this good, but as I see it apt has a big enough userbase that regardless of what your patch is doing, someone will like it. That drastically increases the chances that someone will also like it enough to say so in public offsetting complains from all those who don't like the (effects of the) patch which are omnipresent. And twice in a blue moon some of those will even step forward and thank you explicitly. Not that it would be necessary, but it is nice anyhow. So, thanks for the love supercow, Google & apt users! Or in other words: APT might very well be one of the most friendly (package manager related) project to contribute to as the language-specific managers have smaller userbases and hence a smaller chance of having someone liking your work (in public) so contribute a patch or two and be loved, too! Disclaimer: I get no bonus for posting this nor are any other strings attached. Birthdays are just a good time to reflect. In terms of what I do with my new found riches (in case I really receive them I haven't yet so that could still be an elaborate scam ): APT is a very humble program, but even it is thinking about moving away from a dev-box with less than 4 GB of RAM and no SSD, so it is happily accepting the gift and expects me to upgrade sooner now. What kind of precedence this sets for the two decades milestone next year? If APT isn't obsolete by then We will see.

  1. which even ended up topping Hacker News around New Year's Eve who would have thought that apt and reproducibility bugs are top news ;)

Next.

Previous.