Search Results: "beh"

13 January 2011

Dominique Dumont: Debian copyright DEP5 parser/editor/validator/migrator is released

Hello The new version of libconfig-model-perl 1.229 is now available in Debian/Sid. This new version provides a model of Debian s DEP-5 copyright file specification updated according to the CANDIDATE version. (Among other features, like editor/validator for debian/control). The DEP-5 editor must be run in the source package directory (I ll provide an example below) with the following command:
config-edit -application dpkg-copyright
Features: Known issues: Example: The copyright file of libconfig-model-backend-augeas-perl needs to be updated: Here s the original copyright file (slightly edited to protect my mail box and save electrons) :
$ cat debian/copyright
Format-Specification: http://wiki.debian.org/Proposals/CopyrightFormat?action=recall&rev=196 Upstream-Maintainer: Dominique Dumont (ddumont at cpan.org)
Upstream-Source: http://search.cpan.org/dist/Config-Model-Backend-Augeas/
Upstream-Name: Config-Model-Backend-Augeas Copyright: 2008-2009, Dominique Dumont (ddumont at cpan.org)
License: LGPL-2+ Files: debian/*
Copyright: 2009, Dominique Dumont
License: LGPL-2+ License: LGPL-2+
This program is free software; you can redistribute it and/or
[snip]
First, let s just check issues:
$ config-edit -application dpkg-copyright -ui none
Element Upstream-Maintainer of node Debian::Dpkg::Copyright is deprecated
Element Upstream-Source of node Debian::Dpkg::Copyright is deprecated
Element Upstream-Name of node Debian::Dpkg::Copyright is deprecated
Missing Files: specification at top of section number 2. Adding Files: * spec
Then, let s see what s config-edit can fix all by itself:
$ config-edit -application dpkg-copyright -ui none -save
[ same warnings displayed ]
Let s check the result of the migration:
$ config-edit -application dpkg-copyright -ui none
[ good: no more warnings ]
And here s the content of the upgraded file (drum rolls, please):
$ cat debian/copyright
Format: http://dep.debian.net/deps/dep5/
Upstream-Name: Config-Model-Backend-Augeas
Upstream-Contact: Dominique Dumont (ddumont at cpan.org)
Source: http://search.cpan.org/dist/Config-Model-Backend-Augeas/ Files: *
Copyright: 2008-2009, Dominique Dumont (ddumont at cpan.org)
License: LGPL-2+ Files: debian/*
Copyright: 2009, Dominique Dumont
License: LGPL-2+ License: LGPL-2+
This program is free software; you can redistribute it and/or
[snip]
You can see that: Please provide feedback! If you have problem migrating DEP5 files, yell, and we ll fix them. If this migration works fine, don t be shy, please say so. Under the hood:

Most of the migration work is specified in DEP-5 model [2]. Using config-model s GUI [3] to update DEP-5 model, about one hour was spent to: This shows one important feature of Config::Model: maintenance and evolution of a model is not a huge task. Even though copyright files are not configuration files, the same approach can be used to specify model and migration of other configuration files. Now comes the question of the migration as seen by the user. Well, it s your turn now. Try it and tell us how it works! Hopefully, encouraged by your feedback, other people will apply config-model to other specifications or other configuration. All the best (*) E.g, in the text format produced by the model editor GUI: 'Upstream-Contact',

'value_type' => 'string',
'migrate_from' =>
'formula' => '$old_maintainer',
'variables' =>
'old_maintainer' => '- Maintainer'

,
'type' => 'leaf',
'description' => '* Syntax: line based list [snip]'
,

11 January 2011

Nikita Youshchenko: Different page headers on different pages in OpenOffice.org document

To get different page headers on different parts of document, one needs to set different page styles. To set page style for a page, one needs to double-click on new style name in page style list window, while cursor is inside the page. And surprise that changes style of all pages, not single page! So what about different page headers?.. Solution here. In fact this behaviour is somewhat logical. Unless there are explicit page breaks, the split of document into pages is not stable it changes while document is being edited. So applying a custom style to what currently is a page is actually an invalid operation. It is valid only for the first page after a break. Style for next page is defined in appropriate field of the style for previous page.

8 January 2011

Nikita Youshchenko: Psi / Psi+: want to avoid auto-online after auto-offline

Older versions of Psi jabber client required manual changing status to online to leave auto-offline state. It was very handy for me: I connect to my jabber account from two locations (from home and from office), so after I left one of these locations, auto-offline soon happened, and Psi at that location did not return online until I returned and manually instructed it to re-login. Unfortunately newer versions of Psi (I guess, starting from commit 4a54500c on git://git.psi-im.org/psi.git, which was between 0.11 and 0.12 releases), and also Psi+, behave differently: if user activity is detected on the desktop, auto-offline state is left, and status becomes online again similar to leaving auto-away and auto-xa states. This change is not good for me, at least in two situations: In both these situations, Psi client not at my current location becomes online, which can cause routing incoming messages to wrong location. I don t state that new behaviour is somehow worse than old behaviour. But for my use cases, I want to get old behaviour back. I ve done some code reading. I think that point to fix is near the bottom of PsiAccount::secondsIdle() method, where any auto status is disabled if no timeout condition currently exists. This should be changed so that auto-offline state won t be left if some config key is set. I will try to implement this change soon (or at least I hope I will try ) P.S.
To make things even better, a check of some external condition could be performed to decide if client should return online from auto-offline or not. Then fancy things could be set up, e.g. return to online at office only if my mobile phone is currently registered in the office wifi network not really required but cool.

7 January 2011

Evgeni Golov: Is Delicious loosing their data?

I use Delicious from time to time to save bookmarks and search for stuff I can t remember where I found it. It was sad to read rumors that Yahoo! will shut it down, but that s not the point here now.In the last months I noticed some strange behavior with their site: when surfing a page of a bookmark, you see the total number of people who have bookmarked that particular link and that number started to jump from view to view. First loaded you see a total of 183 bookmarks, 10 minutes later it s 265 bookmarks, and then 183 again. What s going on there? I guess that is some inconsistency between their datacentres or something, but I m not sure (and I am sure that this should not happen!).Today I noticed another funny thing: bookmarks without an owner:

Again, not sure what is happening here. Did the user delete his account? Delicious says all bookmarks will be gone when deleting, so this should be something different, but again, I have no clue.I fear I will have to search a new home for my bookmarks. Any (open-source) social bookmarking service out there worth a try?

Simon Josefsson: On Password Hashing and RFC 6070

The RFC Editor has announced a new document, RFC 6070, with test vectors for PKCS5 PBKDF2. The document grow out of my implementation of SCRAM for GNU SASL. During interop testing, more than one other implementation turned out to have mistakes in the PBKDF2 implementation. It didn t help that there weren t any stable test vectors for PBKDF2, so that we could do black-box testing of our PBKDF2 implementations against well-known and stable test vectors. Debugging this was time consuming. The document addresses this problem. So what is PBKDF2?

Briefly, the PBKDF2 is the state of the art way to convert a password string into a cryptographic binary key. There are many ways to design such an algorithm. To understand why PBKDF2 is designed the way it is we need some basic understanding. The typical attack you would be concerned with is if someone compromises your authentication servers and steals the credential database. This is what happened with the recent Gawker attack, where passwords were apparently stored in clear text. The first security improvement compared to storing passwords in clear text is to only store a hashed or encrypted form of the password. Hashing is preferable over encryption in this context, because with encryption it is possible to go back to the unencrypted form (if you know the key) whereas with a hash it is computationally infeasible to do so. The downside of hashing is that it is impossible to be compatible with all kind of authentication systems: the hash of the password in the database needs to be computed using the same algorithm as the system will be using. Unfortunately there are many different schemes out there to do password hashing, including the old Unix crypt(3) algorithm and the Windows LM-hash. You normally never know in advance what kind of systems your hashed credential database needs to work for, so you have to pick some set of algorithms and hope for the best. The next security improvements are iterations and salting. Iterations means to run the hash function not once, but hundreds or even thousands of times, on the input data (e.g., password). The extra time is hardly noticeable for the user, but for an attacker who is testing an entire dictionary of common passwords against your hash, making the work cost thousand times higher quickly makes the attack vector computationally infeasible. Salting means to include something other than the password in the input to the hash function, typically a random string. Without salting, a pre-computed rainbow table would provide a dictionary attack against all hashed password databases (one rainbow table per hashing algorithm). By using a sufficiently long and random salt, a rainbow table for one system is not applicable to another system. Since generating a rainbow table is time consuming, this adds another barrier to the attacker. PBKDF2 combines these three concepts hashing, iteration and salting into one construct, and it is designed flexible enough so that it can work on any pseudo-random function. In practice, I ve only ever seen HMAC-SHA1 be used. Some final words on the publication behind RFC 6070: Out of my earlier publications, this was the document that (by a large margin) spent the least time in the IETF process. You see various milestones of the document in the RFC 6070 datatracker history page. The time in the publication process was from 2010-08-09 to 2011-01-06. One month was in the AUTH48 state, of which the initial 20 days were waiting for me to respond. Thank you to my sponsoring AD, Sean Turner, for making this possible!

2 January 2011

Lucas Nussbaum: Giving up on Ruby packaging

I have finally reached a decision regarding my involvement in the Debian Ruby packaging efforts. I have decided to stop. This has been a very hard decision to make. I have invested huge amounts of time in that work over the years. I still love the language, and will continue to use it on a daily basis for my own developments. I still hope that it will succeed. I know that some people will be disappointed by that decision (and that others will think your work was useless anyway, people should use RVM and rubygems ). But I also know that I won t be able to push for all the required changes alone. I just don t have the time, nor the motivation. For the record, here are the changes I would have liked to see in the Ruby community. The core Ruby development community should mature.
The core Ruby development community is still dominated by Japanese developers. While not a bad thing in itself, it is easily explained by the fact that the main development mailing list, where most of the important decisions are taken, is in japanese. ruby-dev@ should be closed, and all the technical discussions should happen on the english-speaking ruby-core@ list instead. The release management process should also improve. Currently, it looks like a total mess. The following Ruby development branches are actively maintained:
ruby_1_8 (106 commits over the last six months)
ruby_1_8_6 (4 commits over the last six months)
ruby_1_8_7 (35 commits over the last six months)
ruby_1_9_1 (4 commits over the last six months)
ruby_1_9_2 (227 commits over the last six months)
trunk (1543 commits over the last six months) While the state of the ruby_1_8_6 and ruby_1_9_1 branches is clear (very important bugfixes only), the state of all of the other branches is rather unclear.
What s the stable Ruby branch? 1.8 or 1.9? If it s 1.9, why are people still actively developing in the ruby_1_8 branch? How long will they continue to be maintained in parallel, dividing the manpower? Is a Ruby 1.8.8 release to be expected? Will it be ABI/API compatible with 1.8.7? Is the ruby_1_8_7 branch really bugfixes-only? How much testing of it has been done? If it s bugfixes-only and regression-free, I should push it to Debian squeeze, due to be released in a few weeks. But would you recommend that? Due to past breakages in the ruby_1_8_7 branch, it s unlikely that we will do it.
Is the ruby_1_9_2 a regression-free, bugfix-only branch? If yes, isn t 227 commits over 6 months a lot? What will be the version of the next release of trunk ? When is it expected? Will it be ABI-compatible with the current ruby_1_9_2 branch? API-compatible?
New releases in the 1.8.7 and 1.9.2 branches were done on december 25th. Why were they no betas or RCs allowing wider testing? How much testing has been done behind the scenes? Most of those questions have no clear answer. The Ruby development community should build a common understanding of the status of the various branches, and of their release expectations. Releasing on december 25th of each year sounds fun, but is releasing when everybody is on vacation really a good idea? It would be fantastic to have something similar to Python Enhancement Proposals in the Ruby community. But having open discussions in english about the major issues would already be great. Ruby is not just the interpreter.
The Ruby development community should clearly define what the Ruby platform is. There are some big players, like Rails, and newer interpreter releases should not be done before ensuring that those big players still work. Also, since we have alternative Ruby interpreters, like JRuby, Rubinius and MacRuby, we need a clear process on how they integrate with the rest of the ecosystem. For example, having each of them rely on their own outdated fork of the whole stdlib is ridiculous, since it s not where they compete. The Ruby community should acknowledge that RVM and Rubygems are not for everybody. People who say so should be laughed at. Of course, RVM and Rubygems are nice tools for some people. But it is completely wrong to believe that compiling from source using RVM should be the standard way of installing Ruby, or that all people interested in installing Redmine should know that Ruby has its own specific packaging system. The Ruby community should work with their target platforms to improve how Ruby is distributed instead of reinventing the wheel. That includes Debian, but also RedHat-based distros, for example. It is likely that it won t be possible to reach a one-size-fits-all situation. But that s real life. Some people in the Ruby community should stop behaving like assholes. As one of the Debian Ruby maintainers, I have been routinely accused of creating crippled packages on purpose (FTR, I don t think that the Debian packages are crippled, despite what the rumors says). Debian is not the only target of that. Just yesterday, someone called for abandonning YARV (the new Ruby VM in Ruby 1.9), calling it Yet Another Random Vailure. This kind of comments is really hurting the people who are investing their free time in Ruby, and is turning away people who consider getting involved. In Debian, we have had a lot of problems getting people to help with Ruby maintenance since they are getting shit from the community all the time. So, what s the future for Ruby in Debian? Update: there s also a number of interesting comments about this post on this site.
Update 2: First, thanks a lot for all the interesting comments. I will make some follow-up posts trying to summarize what was said. It seems that this post also triggered some reactions on ruby-core@, with Charles Olivier explaining the JRuby stdlib fork, and Yui Naruse clarifying that all questions are welcomed on ruby-core@. This is great, really.

1 January 2011

Stephan Peijnik: ISC dhcpd and IP assignments from a pool to specific hosts only

Assigning an IP address statically to a host with a given MAC address using ISC dhcpd is quite trivial, one host entry, a hardware ethernet entry and a fixed-address entry and you are up and running.
But what if you want to assign IP addresses from a pool to only a few hosts with specific MAC addresses?

Before you ask yourself why someone might want to do that, have a look at my (very real) use-case.
I am currently working on setting up an installation server for my employer, ANEXIA Internetdienstleistungs GmbH. The server itself uses PXE, TFTP and FAI for installing systems. To be able to do PXE booting one has to set up an DHCP server to provide configuration details, like the TFTP Server Address and the boot filename.

Now what one should consider is that this system is designed to provide automatic installations for internet-facing hosts, namely ones in public IP networks. Running a DHCP server in such a network is not a good idea. We neither want to dish out configurations to each and every hosts that asks for them, neither do not want to do a PXE boot each and every time one of our systems is restarted. Now the combination of FAI and pxelinux allows for default configurations which force local booting, but this still causes the (re-)boot time for those systems to increase and potentially also increases the load on the TFTP server. Also, let's not even consider thinking about whether this setup is "clean" or not. I personally believe that dishing out IP addresses in a public IP network is a bad thing(tm) and I guess a lot of people will be nodding when reading these lines.

What I was asking myself is how to get something like that set up in a cleaner way, and guess what, I found a solution.
The basic idea behind this is only providing IP configuration via DHCP to a specific set of hosts (with a specific set of MAC addresses) and not providing any information to all other hosts. The specific set of hosts are those that we want to do an install run on. This is a no-brainer and I guess the right way to do that, but implementing this approach is not as straight-forward as I initially thought.

Actually the implementation of that idea caused me a bit of a headache and cost me a few work-hours to get right, that's why I'd like to share the configuration details with you.


Let's have a look at how to get such a setup using ISC dhcpd. We are using the fact that ISC dhcpd allows you to not only configure a subnet, but rather also pools inside subnets, which can have allow and deny rules. Such rules can be in the form of "allow/deny member of <class>", where classes (and subclasses, keep on reading for details) can be defined inside the configuration file as well.</class>

What we first did was creating a subnet with a pool declaration, as follows:
subnet 10.0.0.0 netmask 255.255.255.0
option routers 10.0.0.254;
option broadcast-address 10.0.0.255;
filename "fai/pxelinux.0";
next-server 10.0.0.254;
server-name "10.0.0.254";
pool
allow members of "install";
range 10.0.0.10 10.0.0.230;
This one configures the subnet 10.0.0.0/24, with 10.0.0.254 being the network gateway, 10.0.0.254 being the TFTP server and "fai/pxelinux.0" being the TFTP filename. Additionally pool allows us to define a range of IP addresses we want to use, along with a line stating that only members of the "install" class should get a network configuration. If you do not have any other subnet defined in your config and a client that is not in this "install" class asks for an IP address you will see something like this in your syslog: "dhcpd: DHCPDISCOVER from 11:22:33:44:55:66 via eth1: network 10.0.0/24: no free leases". dhcpd will not even answer these requests and thus the client will not even know that there is a DHCP server running here. Exactly what we wanted.

I wrote about this giving me a headache, but so far things have been pretty straight-forward. Getting this far did not take very long, believe me.

Next thing we did was defining that "install" class as follows:

class "install" match hardware;
Again, not very hard to do. This tells dhcpd to look for subclasses of "install" with a matching hardware-address. So let's have a look at the subclass for, let's say the host with MAC address "11:22:33:44:55:66":

subclass "install" 1:11:22:33:44:55:66;
I intentionally highlighted the leading "1:" there. This means nothing more or less than "ethernet". Without that leading "1:" you won't get anywhere. Matching will fail, simple as that. It took me a while to find information about this in "man 5 dhcp-eval". Quoting parts of the interesting section:

The hardware operator returns a data string whose first element is
the type of network interface indicated in packet being considered,
and whose subsequent elements are client s link-layer address. [...] Hardware types include ethernet (1), token-ring (6), and fddi (8).
Now, with the combination of the subnet, pool, class and subclass directives we could get the setup we wanted: a DHCP server only providing IP configuration to a specific set of hosts and ignoring all other DHCP requests.

If you have any comments about this setup or ideas on how to get something similar set-up using another approach feel free to leave a comment.

Personal final note: accidentally typing 80 instead of 08 in a MAC address will cost you an additional two hours and will even have you re-compile ISC dhcpd with eval debugging turned on, believe me. :-)

31 December 2010

Dirk Eddelbuettel: R / Finance 2011 Call for Papers: Updated and expanded

One week ago, I sent the updated announcement below to the r-sig-finance list; this was kindly blogged about by fellow committee member Josh and by our pal Dave @ REvo. By now. I also updated the R / Finance conference website. So to round things off, a quick post here is in order as well. It may even get a few of the esteemed reader to make a New Year's resolution about submitting a paper :) Dear R / Finance community, The preparations for R/Finance 2011 are progressing, and due to favourable responses from the different sponsors we contacted, we are now able to offer

  1. a competition for best paper, which given the focus of the conference will award for both an 'academic' paper and an 'industry' paper
  2. availability of travel grants for up to two graduate students provided suitable papers were accepted for presentations
More details are below in the updated Call for Papers. Please feel free to re-circulate this Call for Papers with collegues, students and other associations. Cheers, and Season's Greeting, Dirk (on behalf of the organizing / program committee) Call for Papers: R/Finance 2011: Applied Finance with R April 29 and 30, 2011 Chicago, IL, USA The third annual R/Finance conference for applied finance using R will be held this spring in Chicago, IL, USA on April 29 and 30, 2011. The two-day conference will cover topics including portfolio management, time series analysis, advanced risk tools, high-performance computing, market microstructure and econometrics. All will be discussed within the context of using R as a primary tool for financial risk management, portfolio construction, and trading. Complete papers or one-page abstracts (in txt or pdf format) are invited to be submitted for consideration. Academic and practitioner proposals related to R are encouraged. We welcome submissions for full talks, abbreviated lightning talks, and for a limited number of pre-conference (longer) seminar sessions. Presenters are strongly encouraged to provide working R code to accompany the presentation/paper. Data sets should also be made public for the purposes of reproducibility (though we realize this may be limited due to contracts with data vendors). Preference may be given to presenters who have released R packages. The conference will award two $1000 prizes for best paper: one for best practitioner-oriented paper and one for best academic-oriented paper. Further, to defray costs for graduate students, two travel and expense grants of up to $500 each will be awarded to graduate students whose papers are accepted. To be eligible, a submission must be a full paper; extended abstracts are not eligible. Please send submissions to: committee at RinFinance.com The submission deadline is February 15th, 2011. Early submissions may receive early acceptance and scheduling. The graduate student grant winners will be notified by February 23rd, 2011. Submissions will be evaluated and submitters notified via email on a rolling basis. Determination of whether a presentation will be a long presentation or a lightning talk will be made once the full list of presenters is known. R/Finance 2009 and 2010 included attendees from around the world and featured keynote presentations from prominent academics and practitioners. 2009-2010 presenters names and presentations are online at the conference website. We anticipate another exciting line-up for 2011---including keynote presentations from John Bollinger, Mebane Faber, Stefano Iacus, and Louis Kates. Additional details will be announced via the conference website as they become available. For the program committee:
Gib Bassett, Peter Carl, Dirk Eddelbuettel, Brian Peterson,
Dale Rosenthal, Jeffrey Ryan, Joshua Ulrich

25 December 2010

Petter Reinholdtsen: The reply from Edgar Villanueva to Microsoft in Peru

A few days ago an article in the Norwegian Computerworld magazine about how version 2.0 of European Interoperability Framework has been successfully lobbied by the proprietary software industry to remove the focus on free software. Nothing very surprising there, given earlier reports on how Microsoft and others have stacked the committees in this work. But I find this very sad. The definition of an open standard from version 1 was very good, and something I believe should be used also in the future, alongside the definition from Digistan. Version 2 have removed the open standard definition from its content. Anyway, the news reminded me of the great reply sent by Dr. Edgar Villanueva, congressman in Peru at the time, to Microsoft as a reply to Microsofts attack on his proposal regarding the use of free software in the public sector in Peru. As the text was not available from a few of the URLs where it used to be available, I copy it here from my source to ensure it is available also in the future. Some background information about that story is available in an article from Linux Journal in 2002.
Lima, 8th of April, 2002
To: Se or JUAN ALBERTO GONZ LEZ
General Manager of Microsoft Per Dear Sir: First of all, I thank you for your letter of March 25, 2002 in which you state the official position of Microsoft relative to Bill Number 1609, Free Software in Public Administration, which is indubitably inspired by the desire for Peru to find a suitable place in the global technological context. In the same spirit, and convinced that we will find the best solutions through an exchange of clear and open ideas, I will take this opportunity to reply to the commentaries included in your letter. While acknowledging that opinions such as yours constitute a significant contribution, it would have been even more worthwhile for me if, rather than formulating objections of a general nature (which we will analyze in detail later) you had gathered solid arguments for the advantages that proprietary software could bring to the Peruvian State, and to its citizens in general, since this would have allowed a more enlightening exchange in respect of each of our positions. With the aim of creating an orderly debate, we will assume that what you call "open source software" is what the Bill defines as "free software", since there exists software for which the source code is distributed together with the program, but which does not fall within the definition established by the Bill; and that what you call "commercial software" is what the Bill defines as "proprietary" or "unfree", given that there exists free software which is sold in the market for a price like any other good or service. It is also necessary to make it clear that the aim of the Bill we are discussing is not directly related to the amount of direct savings that can by made by using free software in state institutions. That is in any case a marginal aggregate value, but in no way is it the chief focus of the Bill. The basic principles which inspire the Bill are linked to the basic guarantees of a state of law, such as:
  • Free access to public information by the citizen.
  • Permanence of public data.
  • Security of the State and citizens.
To guarantee the free access of citizens to public information, it is indispensable that the encoding of data is not tied to a single provider. The use of standard and open formats gives a guarantee of this free access, if necessary through the creation of compatible free software. To guarantee the permanence of public data, it is necessary that the usability and maintenance of the software does not depend on the goodwill of the suppliers, or on the monopoly conditions imposed by them. For this reason the State needs systems the development of which can be guaranteed due to the availability of the source code. To guarantee national security or the security of the State, it is indispensable to be able to rely on systems without elements which allow control from a distance or the undesired transmission of information to third parties. Systems with source code freely accessible to the public are required to allow their inspection by the State itself, by the citizens, and by a large number of independent experts throughout the world. Our proposal brings further security, since the knowledge of the source code will eliminate the growing number of programs with *spy code*. In the same way, our proposal strengthens the security of the citizens, both in their role as legitimate owners of information managed by the state, and in their role as consumers. In this second case, by allowing the growth of a widespread availability of free software not containing *spy code* able to put at risk privacy and individual freedoms. In this sense, the Bill is limited to establishing the conditions under which the state bodies will obtain software in the future, that is, in a way compatible with these basic principles. From reading the Bill it will be clear that once passed:
  • the law does not forbid the production of proprietary software
  • the law does not forbid the sale of proprietary software
  • the law does not specify which concrete software to use
  • the law does not dictate the supplier from whom software will be bought
  • the law does not limit the terms under which a software product can be licensed.
  • What the Bill does express clearly, is that, for software to be acceptable for the state it is not enough that it is technically capable of fulfilling a task, but that further the contractual conditions must satisfy a series of requirements regarding the license, without which the State cannot guarantee the citizen adequate processing of his data, watching over its integrity, confidentiality, and accessibility throughout time, as these are very critical aspects for its normal functioning. We agree, Mr. Gonzalez, that information and communication technology have a significant impact on the quality of life of the citizens (whether it be positive or negative). We surely also agree that the basic values I have pointed out above are fundamental in a democratic state like Peru. So we are very interested to know of any other way of guaranteeing these principles, other than through the use of free software in the terms defined by the Bill. As for the observations you have made, we will now go on to analyze them in detail: Firstly, you point out that: "1. The bill makes it compulsory for all public bodies to use only free software, that is to say open source software, which breaches the principles of equality before the law, that of non-discrimination and the right of free private enterprise, freedom of industry and of contract, protected by the constitution." This understanding is in error. The Bill in no way affects the rights you list; it limits itself entirely to establishing conditions for the use of software on the part of state institutions, without in any way meddling in private sector transactions. It is a well established principle that the State does not enjoy the wide spectrum of contractual freedom of the private sector, as it is limited in its actions precisely by the requirement for transparency of public acts; and in this sense, the preservation of the greater common interest must prevail when legislating on the matter. The Bill protects equality under the law, since no natural or legal person is excluded from the right of offering these goods to the State under the conditions defined in the Bill and without more limitations than those established by the Law of State Contracts and Purchasing (T.U.O. by Supreme Decree No. 012-2001-PCM). The Bill does not introduce any discrimination whatever, since it only establishes *how* the goods have to be provided (which is a state power) and not *who* has to provide them (which would effectively be discriminatory, if restrictions based on national origin, race religion, ideology, sexual preference etc. were imposed). On the contrary, the Bill is decidedly antidiscriminatory. This is so because by defining with no room for doubt the conditions for the provision of software, it prevents state bodies from using software which has a license including discriminatory conditions. It should be obvious from the preceding two paragraphs that the Bill does not harm free private enterprise, since the latter can always choose under what conditions it will produce software; some of these will be acceptable to the State, and others will not be since they contradict the guarantee of the basic principles listed above. This free initiative is of course compatible with the freedom of industry and freedom of contract (in the limited form in which the State can exercise the latter). Any private subject can produce software under the conditions which the State requires, or can refrain from doing so. Nobody is forced to adopt a model of production, but if they wish to provide software to the State, they must provide the mechanisms which guarantee the basic principles, and which are those described in the Bill. By way of an example: nothing in the text of the Bill would prevent your company offering the State bodies an office "suite", under the conditions defined in the Bill and setting the price that you consider satisfactory. If you did not, it would not be due to restrictions imposed by the law, but to business decisions relative to the method of commercializing your products, decisions with which the State is not involved. To continue; you note that:" 2. The bill, by making the use of open source software compulsory, would establish discriminatory and non competitive practices in the contracting and purchasing by public bodies..." This statement is just a reiteration of the previous one, and so the response can be found above. However, let us concern ourselves for a moment with your comment regarding "non-competitive ... practices." Of course, in defining any kind of purchase, the buyer sets conditions which relate to the proposed use of the good or service. From the start, this excludes certain manufacturers from the possibility of competing, but does not exclude them "a priori", but rather based on a series of principles determined by the autonomous will of the purchaser, and so the process takes place in conformance with the law. And in the Bill it is established that *no one* is excluded from competing as far as he guarantees the fulfillment of the basic principles. Furthermore, the Bill *stimulates* competition, since it tends to generate a supply of software with better conditions of usability, and to better existing work, in a model of continuous improvement. On the other hand, the central aspect of competivity is the chance to provide better choices to the consumer. Now, it is impossible to ignore the fact that marketing does not play a neutral role when the product is offered on the market (since accepting the opposite would lead one to suppose that firms' expenses in marketing lack any sense), and that therefore a significant expense under this heading can influence the decisions of the purchaser. This influence of marketing is in large measure reduced by the bill that we are backing, since the choice within the framework proposed is based on the *technical merits* of the product and not on the effort put into commercialization by the producer; in this sense, competitiveness is increased, since the smallest software producer can compete on equal terms with the most powerful corporations. It is necessary to stress that there is no position more anti-competitive than that of the big software producers, which frequently abuse their dominant position, since in innumerable cases they propose as a solution to problems raised by users: "update your software to the new version" (at the user's expense, naturally); furthermore, it is common to find arbitrary cessation of technical help for products, which, in the provider's judgment alone, are "old"; and so, to receive any kind of technical assistance, the user finds himself forced to migrate to new versions (with non-trivial costs, especially as changes in hardware platform are often involved). And as the whole infrastructure is based on proprietary data formats, the user stays "trapped" in the need to continue using products from the same supplier, or to make the huge effort to change to another environment (probably also proprietary). You add: "3. So, by compelling the State to favor a business model based entirely on open source, the bill would only discourage the local and international manufacturing companies, which are the ones which really undertake important expenditures, create a significant number of direct and indirect jobs, as well as contributing to the GNP, as opposed to a model of open source software which tends to have an ever weaker economic impact, since it mainly creates jobs in the service sector." I do not agree with your statement. Partly because of what you yourself point out in paragraph 6 of your letter, regarding the relative weight of services in the context of software use. This contradiction alone would invalidate your position. The service model, adopted by a large number of companies in the software industry, is much larger in economic terms, and with a tendency to increase, than the licensing of programs. On the other hand, the private sector of the economy has the widest possible freedom to choose the economic model which best suits its interests, even if this freedom of choice is often obscured subliminally by the disproportionate expenditure on marketing by the producers of proprietary software. In addition, a reading of your opinion would lead to the conclusion that the State market is crucial and essential for the proprietary software industry, to such a point that the choice made by the State in this bill would completely eliminate the market for these firms. If that is true, we can deduce that the State must be subsidizing the proprietary software industry. In the unlikely event that this were true, the State would have the right to apply the subsidies in the area it considered of greatest social value; it is undeniable, in this improbable hypothesis, that if the State decided to subsidize software, it would have to do so choosing the free over the proprietary, considering its social effect and the rational use of taxpayers money. In respect of the jobs generated by proprietary software in countries like ours, these mainly concern technical tasks of little aggregate value; at the local level, the technicians who provide support for proprietary software produced by transnational companies do not have the possibility of fixing bugs, not necessarily for lack of technical capability or of talent, but because they do not have access to the source code to fix it. With free software one creates more technically qualified employment and a framework of free competence where success is only tied to the ability to offer good technical support and quality of service, one stimulates the market, and one increases the shared fund of knowledge, opening up alternatives to generate services of greater total value and a higher quality level, to the benefit of all involved: producers, service organizations, and consumers. It is a common phenomenon in developing countries that local software industries obtain the majority of their takings in the service sector, or in the creation of "ad hoc" software. Therefore, any negative impact that the application of the Bill might have in this sector will be more than compensated by a growth in demand for services (as long as these are carried out to high quality standards). If the transnational software companies decide not to compete under these new rules of the game, it is likely that they will undergo some decrease in takings in terms of payment for licenses; however, considering that these firms continue to allege that much of the software used by the State has been illegally copied, one can see that the impact will not be very serious. Certainly, in any case their fortune will be determined by market laws, changes in which cannot be avoided; many firms traditionally associated with proprietary software have already set out on the road (supported by copious expense) of providing services associated with free software, which shows that the models are not mutually exclusive. With this bill the State is deciding that it needs to preserve certain fundamental values. And it is deciding this based on its sovereign power, without affecting any of the constitutional guarantees. If these values could be guaranteed without having to choose a particular economic model, the effects of the law would be even more beneficial. In any case, it should be clear that the State does not choose an economic model; if it happens that there only exists one economic model capable of providing software which provides the basic guarantee of these principles, this is because of historical circumstances, not because of an arbitrary choice of a given model. Your letter continues: "4. The bill imposes the use of open source software without considering the dangers that this can bring from the point of view of security, guarantee, and possible violation of the intellectual property rights of third parties." Alluding in an abstract way to "the dangers this can bring", without specifically mentioning a single one of these supposed dangers, shows at the least some lack of knowledge of the topic. So, allow me to enlighten you on these points. On security: National security has already been mentioned in general terms in the initial discussion of the basic principles of the bill. In more specific terms, relative to the security of the software itself, it is well known that all software (whether proprietary or free) contains errors or "bugs" (in programmers' slang). But it is also well known that the bugs in free software are fewer, and are fixed much more quickly, than in proprietary software. It is not in vain that numerous public bodies responsible for the IT security of state systems in developed countries require the use of free software for the same conditions of security and efficiency. What is impossible to prove is that proprietary software is more secure than free, without the public and open inspection of the scientific community and users in general. This demonstration is impossible because the model of proprietary software itself prevents this analysis, so that any guarantee of security is based only on promises of good intentions (biased, by any reckoning) made by the producer itself, or its contractors. It should be remembered that in many cases, the licensing conditions include Non-Disclosure clauses which prevent the user from publicly revealing security flaws found in the licensed proprietary product. In respect of the guarantee: As you know perfectly well, or could find out by reading the "End User License Agreement" of the products you license, in the great majority of cases the guarantees are limited to replacement of the storage medium in case of defects, but in no case is compensation given for direct or indirect damages, loss of profits, etc... If as a result of a security bug in one of your products, not fixed in time by yourselves, an attacker managed to compromise crucial State systems, what guarantees, reparations and compensation would your company make in accordance with your licensing conditions? The guarantees of proprietary software, inasmuch as programs are delivered AS IS'', that is, in the state in which they are, with no additional responsibility of the provider in respect of function, in no way differ from those normal with free software. On Intellectual Property: Questions of intellectual property fall outside the scope of this bill, since they are covered by specific other laws. The model of free software in no way implies ignorance of these laws, and in fact the great majority of free software is covered by copyright. In reality, the inclusion of this question in your observations shows your confusion in respect of the legal framework in which free software is developed. The inclusion of the intellectual property of others in works claimed as one's own is not a practice that has been noted in the free software community; whereas, unfortunately, it has been in the area of proprietary software. As an example, the condemnation by the Commercial Court of Nanterre, France, on 27th September 2001 of Microsoft Corp. to a penalty of 3 million francs in damages and interest, for violation of intellectual property (piracy, to use the unfortunate term that your firm commonly uses in its publicity). You go on to say that: "The bill uses the concept of open source software incorrectly, since it does not necessarily imply that the software is free or of zero cost, and so arrives at mistaken conclusions regarding State savings, with no cost-benefit analysis to validate its position." This observation is wrong; in principle, freedom and lack of cost are orthogonal concepts: there is software which is proprietary and charged for (for example, MS Office), software which is proprietary and free of charge (MS Internet Explorer), software which is free and charged for (Red Hat, SuSE etc GNU/Linux distributions), software which is free and not charged for (Apache, Open Office, Mozilla), and even software which can be licensed in a range of combinations (MySQL). Certainly free software is not necessarily free of charge. And the text of the bill does not state that it has to be so, as you will have noted after reading it. The definitions included in the Bill state clearly *what* should be considered free software, at no point referring to freedom from charges. Although the possibility of savings in payments for proprietary software licenses are mentioned, the foundations of the bill clearly refer to the fundamental guarantees to be preserved and to the stimulus to local technological development. Given that a democratic State must support these principles, it has no other choice than to use software with publicly available source code, and to exchange information only in standard formats. If the State does not use software with these characteristics, it will be weakening basic republican principles. Luckily, free software also implies lower total costs; however, even given the hypothesis (easily disproved) that it was more expensive than proprietary software, the simple existence of an effective free software tool for a particular IT function would oblige the State to use it; not by command of this Bill, but because of the basic principles we enumerated at the start, and which arise from the very essence of the lawful democratic State. You continue: "6. It is wrong to think that Open Source Software is free of charge. Research by the Gartner Group (an important investigator of the technological market recognized at world level) has shown that the cost of purchase of software (operating system and applications) is only 8% of the total cost which firms and institutions take on for a rational and truly beneficial use of the technology. The other 92% consists of: installation costs, enabling, support, maintenance, administration, and down-time." This argument repeats that already given in paragraph 5 and partly contradicts paragraph 3. For the sake of brevity we refer to the comments on those paragraphs. However, allow me to point out that your conclusion is logically false: even if according to Gartner Group the cost of software is on average only 8% of the total cost of use, this does not in any way deny the existence of software which is free of charge, that is, with a licensing cost of zero. In addition, in this paragraph you correctly point out that the service components and losses due to down-time make up the largest part of the total cost of software use, which, as you will note, contradicts your statement regarding the small value of services suggested in paragraph 3. Now the use of free software contributes significantly to reduce the remaining life-cycle costs. This reduction in the costs of installation, support etc. can be noted in several areas: in the first place, the competitive service model of free software, support and maintenance for which can be freely contracted out to a range of suppliers competing on the grounds of quality and low cost. This is true for installation, enabling, and support, and in large part for maintenance. In the second place, due to the reproductive characteristics of the model, maintenance carried out for an application is easily replicable, without incurring large costs (that is, without paying more than once for the same thing) since modifications, if one wishes, can be incorporated in the common fund of knowledge. Thirdly, the huge costs caused by non-functioning software ("blue screens of death", malicious code such as virus, worms, and trojans, exceptions, general protection faults and other well-known problems) are reduced considerably by using more stable software; and it is well known that one of the most notable virtues of free software is its stability. You further state that: "7. One of the arguments behind the bill is the supposed freedom from costs of open-source software, compared with the costs of commercial software, without taking into account the fact that there exist types of volume licensing which can be highly advantageous for the State, as has happened in other countries." I have already pointed out that what is in question is not the cost of the software but the principles of freedom of information, accessibility, and security. These arguments have been covered extensively in the preceding paragraphs to which I would refer you. On the other hand, there certainly exist types of volume licensing (although unfortunately proprietary software does not satisfy the basic principles). But as you correctly pointed out in the immediately preceding paragraph of your letter, they only manage to reduce the impact of a component which makes up no more than 8% of the total. You continue: "8. In addition, the alternative adopted by the bill (I) is clearly more expensive, due to the high costs of software migration, and (II) puts at risk compatibility and interoperability of the IT platforms within the State, and between the State and the private sector, given the hundreds of versions of open source software on the market." Let us analyze your statement in two parts. Your first argument, that migration implies high costs, is in reality an argument in favor of the Bill. Because the more time goes by, the more difficult migration to another technology will become; and at the same time, the security risks associated with proprietary software will continue to increase. In this way, the use of proprietary systems and formats will make the State ever more dependent on specific suppliers. Once a policy of using free software has been established (which certainly, does imply some cost) then on the contrary migration from one system to another becomes very simple, since all data is stored in open formats. On the other hand, migration to an open software context implies no more costs than migration between two different proprietary software contexts, which invalidates your argument completely. The second argument refers to "problems in interoperability of the IT platforms within the State, and between the State and the private sector" This statement implies a certain lack of knowledge of the way in which free software is built, which does not maximize the dependence of the user on a particular platform, as normally happens in the realm of proprietary software. Even when there are multiple free software distributions, and numerous programs which can be used for the same function, interoperability is guaranteed as much by the use of standard formats, as required by the bill, as by the possibility of creating interoperable software given the availability of the source code. You then say that: "9. The majority of open source code does not offer adequate levels of service nor the guarantee from recognized manufacturers of high productivity on the part of the users, which has led various public organizations to retract their decision to go with an open source software solution and to use commercial software in its place." This observation is without foundation. In respect of the guarantee, your argument was rebutted in the response to paragraph 4. In respect of support services, it is possible to use free software without them (just as also happens with proprietary software), but anyone who does need them can obtain support separately, whether from local firms or from international corporations, again just as in the case of proprietary software. On the other hand, it would contribute greatly to our analysis if you could inform us about free software projects *established* in public bodies which have already been abandoned in favor of proprietary software. We know of a good number of cases where the opposite has taken place, but not know of any where what you describe has taken place. You continue by observing that: "10. The bill discourages the creativity of the Peruvian software industry, which invoices 40 million US$/year, exports 4 million US$ (10th in ranking among non-traditional exports, more than handicrafts) and is a source of highly qualified employment. With a law that encourages the use of open source, software programmers lose their intellectual property rights and their main source of payment." It is clear enough that nobody is forced to commercialize their code as free software. The only thing to take into account is that if it is not free software, it cannot be sold to the public sector. This is not in any case the main market for the national software industry. We covered some questions referring to the influence of the Bill on the generation of employment which would be both highly technically qualified and in better conditions for competition above, so it seems unnecessary to insist on this point. What follows in your statement is incorrect. On the one hand, no author of free software loses his intellectual property rights, unless he expressly wishes to place his work in the public domain. The free software movement has always been very respectful of intellectual property, and has generated widespread public recognition of its authors. Names like those of Richard Stallman, Linus Torvalds, Guido van Rossum, Larry Wall, Miguel de Icaza, Andrew Tridgell, Theo de Raadt, Andrea Arcangeli, Bruce Perens, Darren Reed, Alan Cox, Eric Raymond, and many others, are recognized world-wide for their contributions to the development of software that is used today by millions of people throughout the world. On the other hand, to say that the rewards for authors rights make up the main source of payment of Peruvian programmers is in any case a guess, in particular since there is no proof to this effect, nor a demonstration of how the use of free software by the State would influence these payments. You go on to say that: "11. Open source software, since it can be distributed without charge, does not allow the generation of income for its developers through exports. In this way, the multiplier effect of the sale of software to other countries is weakened, and so in turn is the growth of the industry, while Government rules ought on the contrary to stimulate local industry." This statement shows once again complete ignorance of the mechanisms of and market for free software. It tries to claim that the market of sale of non- exclusive rights for use (sale of licenses) is the only possible one for the software industry, when you yourself pointed out several paragraphs above that it is not even the most important one. The incentives that the bill offers for the growth of a supply of better qualified professionals, together with the increase in experience that working on a large scale with free software within the State will bring for Peruvian technicians, will place them in a highly competitive position to offer their services abroad. You then state that: "12. In the Forum, the use of open source software in education was discussed, without mentioning the complete collapse of this initiative in a country like Mexico, where precisely the State employees who founded the project now state that open source software did not make it possible to offer a learning experience to pupils in the schools, did not take into account the capability at a national level to give adequate support to the platform, and that the software did not and does not allow for the levels of platform integration that now exist in schools." In fact Mexico has gone into reverse with the Red Escolar (Schools Network) project. This is due precisely to the fact that the driving forces behind the Mexican project used license costs as their main argument, instead of the other reasons specified in our project, which are far more essential. Because of this conceptual mistake, and as a result of the lack of effective support from the SEP (Secretary of State for Public Education), the assumption was made that to implant free software in schools it would be enough to drop their software budget and send them a CD ROM with Gnu/Linux instead. Of course this failed, and it couldn't have been otherwise, just as school laboratories fail when they use proprietary software and have no budget for implementation and maintenance. That's exactly why our bill is not limited to making the use of free software mandatory, but recognizes the need to create a viable migration plan, in which the State undertakes the technical transition in an orderly way in order to then enjoy the advantages of free software. You end with a rhetorical question: "13. If open source software satisfies all the requirements of State bodies, why do you need a law to adopt it? Shouldn't it be the market which decides freely which products give most benefits or value?" We agree that in the private sector of the economy, it must be the market that decides which products to use, and no state interference is permissible there. However, in the case of the public sector, the reasoning is not the same: as we have already established, the state archives, handles, and transmits information which does not belong to it, but which is entrusted to it by citizens, who have no alternative under the rule of law. As a counterpart to this legal requirement, the State must take extreme measures to safeguard the integrity, confidentiality, and accessibility of this information. The use of proprietary software raises serious doubts as to whether these requirements can be fulfilled, lacks conclusive evidence in this respect, and so is not suitable for use in the public sector. The need for a law is based, firstly, on the realization of the fundamental principles listed above in the specific area of software; secondly, on the fact that the State is not an ideal homogeneous entity, but made up of multiple bodies with varying degrees of autonomy in decision making. Given that it is inappropriate to use proprietary software, the fact of establishing these rules in law will prevent the personal discretion of any state employee from putting at risk the information which belongs to citizens. And above all, because it constitutes an up-to-date reaffirmation in relation to the means of management and communication of information used today, it is based on the republican principle of openness to the public. In conformance with this universally accepted principle, the citizen has the right to know all information held by the State and not covered by well- founded declarations of secrecy based on law. Now, software deals with information and is itself information. Information in a special form, capable of being interpreted by a machine in order to execute actions, but crucial information all the same because the citizen has a legitimate right to know, for example, how his vote is computed or his taxes calculated. And for that he must have free access to the source code and be able to prove to his satisfaction the programs used for electoral computations or calculation of his taxes. I wish you the greatest respect, and would like to repeat that my office will always be open for you to expound your point of view to whatever level of detail you consider suitable. Cordially,
    DR. EDGAR DAVID VILLANUEVA NU EZ
    Congressman of the Republic of Per .

    23 December 2010

    Rapha&#235;l Hertzog: People behind Debian: Mehdi Dogguy, release assistant

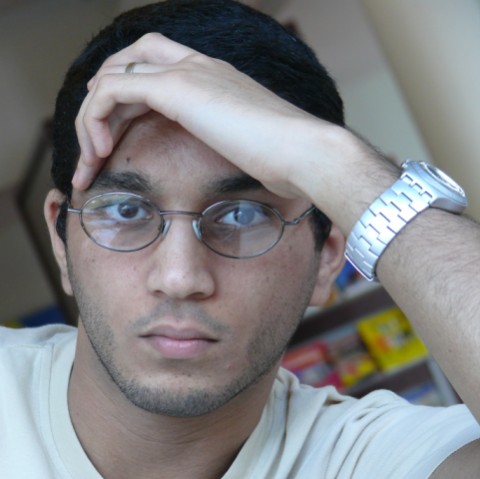
    Mehdi Dogguy

    Picture of Mehdi taken by Antoine Madet

    Mehdi is a Debian developer for a bit more than a year, and he s already part of the Debian Release Team. His story is quite typical in that he started there by trying to help while observing the team do its work. That s a recurrent pattern for people who get co-opted in free software teams. Read on for more info about the release team, and Mehdi s opinion on many topics. My questions are in bold, the rest is by Mehdi (except for the additional information that I inserted in italics). Who are you? I m 27 years old. I grew up in Ariana in northern Tunisia, but have been living in Paris, France, since 2002. I m a PhD Student at the PPS laboratory where I study synchronous concurrent process calculi. I became interested in Debian when I saw one of my colleagues, Samuel Mimram (first sponsor and advocate) trying to resolve #440469, which is a bug reported against a program I wrote. We have never been able to resolve it but my intent to contribute was born there. Since then, I started to maintain some packages and help where I can. What s your biggest achievement within Debian? I don t think I had time to accomplish a lot yet :) I ve been mostly active in the OCaml team where we designed a tool to compute automatically the dependencies between OCaml packages, called dh-ocaml. This was a joint work with St phane Glondu, Sylvain Le Gall and Stefano Zacchiroli. I really appreciated the time spent with them while developing dh-ocaml. Some of the bits included in dh-ocaml have been included upstream in their latest release. I ve also tried to give a second life to the Buildd Status Pages because they were (kind of) abandoned. I intend to keep them alive and add new features to them. If you had a wand and could change one thing in Debian, what would that be? Make OCaml part of a default Debian installation :D But, since I m not a magician yet, I d stick to more realistic plans:
    1. A lot of desktop users fear Debian. I think that the Desktop installation offered by Debian today is very user-friendly and we should be able to attract more and more desktop users. Still, there is some work to be done in various places to make it even more attractive. The idea is trying to enhance the usability and integration of various tools together. Each fix could be easy or trivial but the final result would be an improved Desktop experience for our users. Our packaged software run well. So, each person can participate since the most difficult part is to find the broken scenarios. Fixes could be found together with maintainers, upstream or other interested people.

      I ll try to come up with a plan, a list of things that need polishing or fixes and gather a group of people to work on it. I d definitely be interested in participating in such a project and I hope that I ll find other people to help. If the plan is clear enough and has well described objectives and criteria, it could be proposed to the Release Team to consider it as a Release Goal for Wheezy.

    2. NMUs are a great way to make things move forward. But, sometimes, an NMU could break things or have some undesirable effects. For now, NMUers have to manually track the package s status for some time to be sure that everything is alright. It could be a good idea to be auto-subscribed to the bugs notifications of NMUed packages for some period of time (let s say for a month) to be aware of any new issues and try to fix them. NMUing a package is not just applying a patch and hitting enter after dput. It s also about making sure that the changes are correct and that no regressions have been introduced, etc

    3. Orphaned packages: It could be considered as too strict and not desired, but what about not keeping orphaned and buggy packages in Testing? What about removing them from the archive if they are buggy and still unmaintained for some period? Our ftp archive is growing. It could make sense to do some (more strict) housekeeping. I believe that this question can be raised during the next QA meeting. We should think about what we want to do with those packages before they rot in the archive.
    [Raphael Hertzog: I would like to point out that pts-subscribe provided by devscripts makes it easy to temporarily subscribe to bug notifications after an Non-Maintainer Upload (NMU).] You re a Debian developer since August 2009 and you re already an assistant within the Release Management team. How did that happen and what is this about? In the OCaml team, we have to start a transition each time we upload a new version of the OCaml compiler (actually, for each package). So, some coordination with the Release Team is needed to make the transition happen. When we are ready to upload a new version of the compiler, we ask the Release Team for permission and wait for their ack. Sometimes, their reply is fast (e.g. if their is no conflicting transition running), but it s not always the case. While waiting for an ack, I used to check what was happening on debian-release@l.d.o. It made me more and more interested in the activities of the Release Team. Then (before getting my Debian account), I had the chance to participate in DebConf9 where I met Luk and Phil. It was a good occasion to see more about the tools used by the Release Team. During April 2010, I had some spare time and was able to implement a little tool called Jamie to inspect the relations between transitions. It helps us to quickly see which transitions can run in parallel, or what should wait. And one day (in May 2010, IIRC), I got offered by Adam to join the team. As members of the Release Team, we have multiple areas to work on:
    1. Taking care of transitions during the development cycle, which means making sure that some set of packages are correctly (re-)built or fixed against a specific (to each transition) set of packages, and finding a way to tell Britney that those packages can migrate and it would be great if she also shared the same opinion. [Raphael Hertzog: britney is the name of the software that controls the content of the Testing distribution.]
    2. Paying attention to what is happening in the archive (uploads, reported RC bugs, etc ). The idea is to try to detect unexpected transitions, blocked packages, make sure that RC bug fixes reach Testing in a reasonable period of time, etc
    3. During a freeze, making sure that unblock requests and freeze exceptions are not forgotten and try to make the RC bug count decrease.
    There are other tasks that I ll let you discover by joining the game. Deciding what goes (or not) in the next stable release is a big responsibility and can be incredibly difficult at times. You have to make judgement calls all the time. What are your own criteria? That s a very hard to answer question (at least, for me). It really depends on the case . I try to follow the criteria that we publish in each release update. Sometimes, an unblock request doesn t match those criteria and we have to decide what to accept from the set of proposed changes. Generally, new features and non-fixes (read new upstream versions) changes are not the kind of changes that we would accept during the freeze. Some of them could be accepted if they are not intrusive, easy and well defended. When, I m not sure I try to ask other members of the Release Team to see if they share my opinion or if I missed something important during the review. The key point is to have a clear idea on what s the benefit of the proposed update, and compare it to the current situation. For example, accepting a new upstream release (even if it fixes some critical bugs) is taking a risk to break other features and that s why we (usually) ask for a backported fix. It s also worth noticing that (most of the time) we don t decide what goes in, but (more specifically) what version of a given package goes in and try to give to the contributors an idea on what kind of changes are acceptable during the freeze. There are some exceptions though. Most of them are to fix a critical package or feature. Do you have plans to improve the release process for Debian Wheezy? We do have plans to improve every bit in Debian. Wheezy will be the best release ever. We just don t know the details yet :) During our last meeting in Paris last October, the Release Team agreed to organize a meeting after Squeeze s release to discuss (among other questions) Wheezy s cycle. But the details of the meeting are not fixed yet (we still have plenty of time to organize it and other more important tasks to care about). We would like to be able to announce a clear roadmap for Wheezy and enhance our communication with the rest of the project. We certainly want to avoid what happened for Squeeze. Making things a bit more predictable for developers is one of our goals. Do you think the Constantly Usable Testing project will help? The original idea by Joey Hess is great because it allows d-i developers to work with a stable version of the archive. It allows them to focus on the new features they want to implement or the parts they want to fix (AIUI). It also allows to have constantly available and working installation images. Then, there is the idea of having a constantly usable Testing for users. The idea seems nice. People tend to like the idea behind CUT because they miss some software disappearing from Testing and because of the long delays for security fixes to reach Testing. If the Release Team has decided to remove a package from Testing, I think that there must be a reason for that. It either means that the software is broken, has unfixed security holes or was asked for the removal by its maintainer. I think that we should better try to spend some time to fix those packages, instead of throwing a broken version in a new suite. It could be argued that one could add experimental s version in CUT (or sid s) but every user is free to cherry-pick packages from the relevant suite when needed while still following Testing as a default branch. Besides, it s quite easy to see what was removed recently by checking the archive of debian-testing-changes or by querying UDD. IMO, It would be more useful to provide a better interface of that archive for our users. We could even imagine a program that alerts the user about installed software that got recently removed from Testing, to keep the user constantly aware any issue that could affect his machine. About the security or important updates, one has to recall the existence of Testing-security and testing-proposed-updates that are used specifically to let fixes reach Testing as soon as possible when it s not possible to go through Unstable. I m sure that the security team would appreciate some help to deal with security updates for Testing. We also have ways to speed migrate packages from Unstable to Testing. I have to admit that I m not convinced yet by the benefits brought by CUT for our users.
    Thank you to Mehdi for the time spent answering my questions. I hope you enjoyed reading his answers as I did. Subscribe to my newsletter to get my monthly summary of the Debian/Ubuntu news and to not miss further interviews. You can also follow along on Identi.ca, Twitter and Facebook.

    2 comments Liked this article? Click here. My blog is Flattr-enabled.

    19 December 2010

    Gintautas Miliauskas: Mobile App Camp

    On the last weekend my team and I participated in the Mobile App Camp (link in Lithuanian) organized by Omnitel, which is one of the dominant mobile operators in Lithuania. The event seems to be part of Omnitel's push for increasing the share of smartphones in the Lithuanian market, which has been lagging behind the European trends.

    Our team consisted of Povilas Kytra, who is behind the TV.LT project, Mantas Kanaporis from A-Gain and me. In the weekend we built an app that shows the TV programme for the coming day for all the Lithuanian TV channels. (The app is not yet available on the Android Market, but we are working on it.)

    Here's a screenshot of the main screen of the application:


    The app was built using the standard Android Development Toolkit on Eclipse. The app gets the content from a Rails-based server containing a simple database and couple JSON views.

    I had some experience of developing for Android before, but it was mostly about working with graphics on canvas, while in this app we used some standard GUI controls (with some nifty styling).

    For the source control, we used a private repository on bitbucket.org. That one was a huge letdown: a 'hg push' or 'hg pull' would take ages (or at least that's how it seemed to me in comparison to GitHub), and we had no end of trouble with merging, partly due to the number of commands needed to get the repositories in sync (hg pull; hg update; hg merge; hg commit; hg push). Even Subversion would probably have worked better.

    The event itself was great fun. It had been a while since I had last coded intensively for the entire weekend. There were quite a few decent ideas presented by the participants, and some of them were successfully implemented.

    The rating system was somewhat disappointing though. The event was supposed to be a contest, with four predefined criteria for winning apps (still available on the website): uniqueness in the Lithuanian market, magnitude of the target group, value provided to the user and creativity. In the end, however, the jury nominated apps for three different awards (best app built on an existing database, best app built anew, and the "hope" nomination) with one app awarded from each category. Our app scored second in the first nomination, so we did not get an award, even though we would probably have been in the global top three, were the original criteria upheld.

    To be fair, we did not stand much chance against the winner in our category, an app based on vaistai.lt, which sported a database of pharmaceuticals with detailed usage instructions, information about drug stores in Lithuania with maps and inventory status, and even a barcode scanner. Hats off to them. Another winner was "Alaus radaras" ("Beer radar") with locations of local beer bars and inventory info. The third one was "3 milijonai teis j " (Three million judges"), which, as far as I understood, was a conception for a basketball-throwing game (basketball is very big in Lithuania, it is a second national religion).

    To conclude, it was a fun event and I wish we will be having more of those in Vilnius, even though the Monday after the long weekend was very unproductive.

    18 December 2010

    Russell Coker: Locked Down Phones and Horrible Telcos

    Choosing a PhoneI was considering renewing my Three contract and getting a HTC Desire HD [1]. What I need is a phone that is good for being a ssh client on 3G networks, has a good camera, and has all the fancy Google Apps.In the comments Lon recommended a Norwegian review of phone cameras which gave the Sony Ericsson Xperia X10 a much better review than the HTC Desire HD [2] the Xperia was the highest rating Android camera phone while the Nokia N8 was the best overall.Also the Xperia is a lot cheaper, I can get it on a $29 monthly cap from Virgin as opposed to $44 per month from Three. So just on hardware and price the Xperia beats the Desire HD.One of the advantages of the Xperia from Virgin being cheap is that my wife and I can use the same model of phone. This avoids having to solve two sets of phone related problems and also allows us to do things like swap batteries between the phones based on who can most conveniently charge their phone.The Need for RootBut one problem with e Xperia is that the CyanogenMod images for rooted Android phones can t be installed on an Xperia because the boot loader hasn t yet been cracked [3]. I would like to run CyanogenMod so I can get wireless proxy support, and support for tunneling IP over DNS, ICMP, and OpenVPN.The Three web site claims that they have 3G phone and net access in Bendigo, but on a recent holiday my phone said that it was roaming all the time and I couldn t get net access. I ended up having to use McDonalds Wifi net access which had ports such as 22 blocked and thus forced me to use Iodine IP over DNS to get proper net access. To avoid having to talk my mother through rebooting servers in future I need to have a mobile ssh client that can use all possible protocols. I could carry my EeePC with me all the time, but sometimes it s good to travel light.OTOH, as I feel compelled to fiddle with all my computers it would probably give me a more reliable mobile experience if I was unable to mess with my phone.Why Buying a Phone Outright Isn t ViableA $29 monthly plan is probably the cheapest plan that will do for anyone who uses a phone regularly, I have had a Three $29 plan for the last four years which allows up to $150 of calls to be made in a month and typically use about $60. So any plan which doesn t have such a cap will have to be no more than half the price of Three on a per-minute basis to compete. If I m going to pay $29 per month ($696 over a 24 month contract) then I can use a free phone. If I was to buy a phone then it would cost at least $500 for anything that I like and maybe a lot more.Buying a phone independently of a contract would about double the cost of owning a phone. It s really not a viable option.Therefore I am compelled to buy a phone that is on offer from a Telco. Things like the Nokia N900 are nice devices but as the Telcos don t offer them I can t consider them.No Discount if you Don t get a PhoneThe annoying thing is that the Telcos don t offer a discount if you choose not to get a phone. Obviously buying the hardware costs them some money, so a $29 cap with a phone included should have a matching offer of something less than $29 if you choose not to get the phone from them. I currently have a $29 per month contract with Three, I can renew that for another two years at the same rate and get a half-decent phone for free or I can renew for two years on a $19 per month contract and get a low-end phone for free but I can t get a price that is lower than $19 per month if I decide to keep my current phone.If Three was to offer such a discount then I would consider buying a phone outright over the net and staying with them. But as it is they don t provide good deals for buying a phone and give me an economic incentive to go to another provider. So I will probably use Virgin when my contract runs out in January.Locked PhonesMany Telcos still sell locked phones on a contract. When that happens it s really difficult to get a phone unlocked as the Telco employees usually aren t very helpful. There are a variety of web sites claiming to generate unlock codes for phones, most seem to charge $10 or more for this service and the free ones have a very small range of phones, so getting the unlock code from the Telco seems to be the only option for a phone at the end of it s contract period as it s not worth enough to justify the $10 expense.While some Telcos sell unlocked phones on plans the ones that lock their phones have a chilling effect on the industry. Most people don t test whether their old phone can be used with a different provider they just throw it out the phone stores conveniently provide bins for old phones that are apparently recycled for some good cause.ConclusionIf you make serious use of mobile phones (EG being ready to fix errors reported by Nagios 24*7) then choosing a new phone and plan is one of the most difficult things there is to do. All the plans are quite complicated and every Telco offers a different set of phones. The Telco web sites are usually poorly done, most of them don t have an option to search for Android phones or for phones with a certain minimum resolution they usually don t even state the resolution and use terms such as WQVGA which don t even have a fixed meaning in pixels. When it comes to choosing a plan most Telcos don t have a clear comparison of the different plans, writing your own spreadsheet comparing plan costs is a good idea.The fact that Telcos such as Virgin and Three/Vodaphone allow free calls to other people using the same company makes it even more tricky. I have to discuss my phone plans with several relatives as there is a good incentive for everyone to use the same provider.I think that we need government regulation on the way that phones are bundled. The market for phones that aren t associated with Telco contracts has been destroyed by the anti-competitive behavior of the Telcos.

    Joey Hess: dadagoogoo

    The Google books ngram datasets are a nice resource for playing with text generation. I've created a program that will, given a starting phrase, blather on by connecting phrases from the datasets. The results are much more varied, and seem to more often make sense than most Markov text generators I've seen before, such as dadadodo. It had better be -- it's working with data derived from 4% of all books ever written! Some examples. Do they tell a story? (The starting phrase I entered is in italics.) I have cheated slightly by picking where to stop quoting the blather each time. It tends to go on for quite a while otherwise. Although it often does manage some kind of sense at length too:
    This was accomplished using only 99 lines of code. I imported the datasets into Xapian databases using this program. And this program is the text generator. I threw out the metadata, to keep the Xapian databases of reasonable size. By which I mean, only a dozen gigabytes. It might be interesting to include the publication year data in Xapian, so that it could prefer ngrams that were published around the same time as the input text. I'm still importing data. I may put up a web interface later if there's interest. PS: PPS:

    Felipe Sateler: CDBS -- An introduction

    It seems the current trend is to use short-form dh. Some people have even thought that dh has superseded CDBS. Since I prefer CDBS for my own packaging, I will say that no, CDBS is not being deprecated and in fact has been active. Packaging with CDBS is very simple. I'll try to explain how it works, and how to package with it. This may turn into a blog post series, but I won't promise anything.

    CDBS is a set of makefiles that do several tasks that are common while packaging software, so that you don't have to repeat them over and over on each package. The makefiles are classified into 2 groups: classes and rules. Classes implement the rules required for building and installing software. These are classes because they can and do inherit from others. For example, there is the makefile class, and the autotools, qmake and cmake classes inherit from it, and the gnome and kde (which is for kde 3) classes inherits from the autotools class. Rules implement several other general purpose rules that don't depend on the toolchain used to build the package. For example, there is the debhelper rules file, which takes care of creating the debian package using the usual dh_* commands. There are several rules files which do all sorts of useful stuff, from running license checks to downloading new upstream releases. If this post transforms into a series, we may look into some of them. For now, I'll demonstrate how to use CDBS to package some simple software (only the debian/rules file, of course).

    The first task while running creating debian/rules is determining which build system the software uses. I will use qutecsound package as a guide. So, first things first, we start using CDBS!
    #!/usr/bin/make -f

    # Uncomment this to turn on verbose mode.
    #export DH_VERBOSE=1

    include /usr/share/cdbs/1/rules/debhelper.mk
    include /usr/share/cdbs/1/class/qmake.mk


    Now this would be all that is required if qutecsound where a standard qmake package where nothing needs to be customized. Alas, this is not the case. First, there are some variables that need to be passed to qmake to appropriately configure the build. Also, the projects .pro file is not standard-named. How do we fix this? The CDBS way of overriding this kind of behavior is through the use of variables. Since we are using the qmake class, we will be overriding variables named DEB_QMAKE_*:
    DEB_QMAKE_CONFIG_VAL += build64
    DEB_QMAKE_ARGS = qcs.pro


    We add a configuration value (because CDBS is setting other config values), and we set the extra arguments to qmake.

    Now, there is a problem: the resulting binary is not created with the name we want. How do we change that? We could patch the source to avoid that, but it is far easier to add a rule to the makefile to do that. We will modify the build to rename the file at the end (and then clean it up on clean because the upstream makefile will not spot it):
    build/qutecsound::
    [ -f bin/qutecsound ] mv bin/qutecsound-d bin/qutecsound

    clean::
    rm -f bin/qutecsound


    So what did we just do? We extended the build and clean rules with extra stuff to do. In CDBS each package listed in debian/control gets a build/package rule (and several others at different stages of the build) so that one can add stuff specific to each package (this will be much more useful when dpkg finally learns about build-arch and build-indep).

    For the final touch, we want to do a few more things. First, we want to ensure that we are using QT4's qmake, because the build will fail if QT3's is used. Second, since I created a manpage for the command, I want to install it. Finally, we want to use parallel building when the user has specified it, to build the project faster. How to do that? Again, via variables:
    QMAKE = qmake-qt4
    DEB_BUILD_PARALLEL = 1
    DEB_INSTALL_MANPAGES_qutecsound = debian/qutecsound.1


    CDBS creates several variables for each of the packages listed in debian/control, so we can customize each package build. In our case, this variable is passed to dh_installman from the debhelper rules file (CDBS will invoke the debhelper tools once for each binary package).

    After all this we now have the complete debian/rules of a relatively simple package. How does it look like? Like this:
    #!/usr/bin/make -f

    # Uncomment this to turn on verbose mode.
    #export DH_VERBOSE=1

    include /usr/share/cdbs/1/rules/debhelper.mk
    include /usr/share/cdbs/1/class/qmake.mk

    QMAKE = qmake-qt4
    DEB_QMAKE_CONFIG_VAL += build64
    DEB_QMAKE_ARGS = qcs.pro
    DEB_BUILD_PARALLEL = 1

    DEB_INSTALL_MANPAGES_qutecsound = debian/qutecsound.1

    build/qutecsound::
    [ -f bin/qutecsound ] mv bin/qutecsound-d bin/qutecsound

    clean::
    rm -f bin/qutecsound

    Tags: cdbs, packaging

    David Welton: Do More Faster: TechStars Lessons to Accelerate Your Startup

    <iframe frameborder="0" marginheight="0" marginwidth="0" scrolling="no" src="http://rcm.amazon.com/e/cm?lt1=_blank&amp;bc1=000000&amp;IS2=1&amp;bg1=FFFFFF&amp;fc1=000000&amp;lc1=0000FF&amp;t=dedasys-20&amp;o=1&amp;p=8&amp;l=as1&amp;m=amazon&amp;f=ifr&amp;md=10FE9736YVPPT7A0FBG2&amp;asins=0470929839" style="width: 120px; height: 240px;"></iframe> I got this to read on my trip to Oregon. Initially I was a bit dubious, after reading the chapter headings on Amazon. Indeed, if you read a lot of articles about tech startups, a lot of the material is not particularly novel, and are things that you've already read elsewhere. If, on the other hand, you're looking for a quick introduction to some of the common ideas behind web/tech startups, it's a pretty good list, written by a variety of people, with a lot of practical advice. The list of concepts includes "execution, not ideas", "fail fast", get feedback early", "get a co-founder", and a lot of similar advice that permeates discussions of early stage internet companies. Other people have different tastes, but for me, this passage was a strikingly effective advertisement for living in Boulder, Colorado:

    With this as the backdrop, it was natural to make cycling a central part of my work with Everlater's founders, Nate Abbott and Natty Zola. Nate, Natty, and I scheduled regular weekly rides (sometimes several times a week) and while we didn't keep a formal agenda, each ride had a number of topics planned out for us to cover. In this way, we worked through many of the early challenges the business faced as it moved from idea to reality in the course of the summer of 2009. Our typical rides lasted from 60 to 90 minutes during which time we were able to focus on the business without interruption. And while getting some fresh air helps bring perspective, it's hard to avoid thinking about problems in a new way when you're out of the office, surrounded by the beauty of the Boulder foothills while your mind is completely clear. Startups, cycling, mountains... sign me up! Another tidbit I found interesting:

    We often talk about the Number One startup killer at TechStars making a product for which there is no interesting market. TechStars accepts just 10 of more than 600 startups that apply and presumably they are among the best. But still, we find that at least one-third of those startups are attempting to build a product that they want, or that no one wants, instead of what the market wants But wait, I thought "execution is everything", and "ideas are worthless". It seems like avoiding bad ideas is potentially worth a whole lot of money in wasted time and energy though, no? The bit about ideas being worthless is a load of crap. The reason there is no market for ideas is that they are not "excludable". There was never a market for lighthouses either, the classic example in economics of a public good. So the government built them, and they were valuable to people operating ships. Ideas for startups may not have a lot of value compared to people executing them well, but to say they are worthless is hyperbole. In any case, though, if you're interested in startups, or especially if you happen to be interested in the TechStars program, it's book full of good advice, even if none of it will come as a revalation to anyone who follows that sort of thing regularly.

    17 December 2010

    Daniel Stone: new x.org multitouch patchset posted

    So, I've been working on multitouch on and off the past few months (which have included a solid ten weeks of holiday), but have finally posted the third patch series, which I think should be pretty close to final, to the list today.

    Touch events look kind of similar to standard Xi 2.1 events (DeviceMotionNotify and friends), but the implementation of grabbing and event delivery is quite different from the traditional X model that we all know and love.

    Firstly, touch grabs are not strictly grabs as with other input events. When a synchronous pointer or keyboard grab activates, it 'freezes' the device, stopping delivery of all further events until the grabbing client has decided what to do. The client can either pass on the event to the next client (replay), opt to continue receiving all events with the device freezing again after each event (synchronous mode), or continue receiving all events with the device unfrozen (asynchronous). While this is happening, the grabbing client is the only one receiving events, hence the name.

    Touch grabs break both of these assumptions. Firstly, the device never freezes: delivery of all events (pointer, keyboard, touch, whatever) continues at full tilt, and a touch grab never affects pointer or keyboard events, with the possible future exception of pointer events that are emulated from touch events. Secondly, all clients with grabs, as well as the client with the first selection we find<super>0</super>, receive the events. An 'owner' flag is set (or unset) to indicate to the client that it does, or does not, own the touch stream in question.

    The owner principle is important: the theory is that all touch streams must be considered as a whole (i.e. from init, through all the motion events, to the touch stream ending), and cannot be separated into component parts. So a client which does not own a touch stream can do gesture recognition or whathaveyou in the background, but must not act upon it until it becomes the owner. We added an extra request, XIAllowTouchEvents, to control ownership: clients can either reject ownership, passing it on to the next in line, or assert their ownership and permanently remove all other clients from the delivery list.

    So it's somewhat different, but (hopefully) not without reason. The motivation behind this was to keep latency as low as humanly possible, since people seem to demand lower latencies from direct touch-based devices. Sticking to the traditional grab model would have meant a flurry of round trips between all the clients in the stack and the server, as well as maintaining huge buffers in the server for every touch event, which each client would have to transfer in turn.

    This model is a compromise between my original design and Ubuntu's suggested design; both of us had far more simple designs, but oriented towards different usecases. The original Ubuntu usecase was for a global gesture recognition system, which apps would only opt out of in rare cases. My primary usecase was exactly the reverse: apps doing their own gesture recognition, with a very small, if any, global system. Hopefully it's actually the best of both worlds, rather than the worst possible intersection: I guess we'll find out. :)

    At the moment, it's all largely theoretical, but some of the Nokia Qt guys are working on a port and have provided really helpful feedback, and hopefully the GTK+ multitouch branch, which was written against a much earlier and, er, speculative, version of the spec, gets updated too.

    Finally, some thanks: to both Nokia and my excellent employer Collabora for sponsoring my part of this work; to Chase Douglas from Canonical for his contributions and for not just giving us the finger and vanishing when we rejected the X Gesture Extension, but hanging around and working through it; and to Peter Hutterer, for spec work and review. There were also numerous others involved earlier (including, but not limited to, Henrik Rydberg working on mtdev and others) who deserve credit, so sorry if I forgot anyone.

    If you want to get it and play around with it, the patches/repositories are all laid out in my initial mail linked to earlier, as well as the follow-up mail noting the evdev repository location. The spec has more details, and will hopefully be cleaned up to be a lot less clunkily-written.

    [0]: The delivery order is unchanged. For grabs, we start at the root window and proceed down the window stack to the innermost child window, activating grabs in that order. For events selected for with XISelectEvents, we start at the innermost child window, work our way up towards the root window, and stop as soon as we find one.

    Bernhard R. Link: C Code to avoid

    One of the bad aspects of the the C Programing language is that it silently allows many bad C programs. Together with the widespread use of an architecture that is very bad at catching errors (i386), this sometimes leads to common ideoms that are only working accidentially. This is bad as they often break on other architectures and can break with every new optimisations or new feature the compiler adds. Take for example a look at the code there (I tried to leave a comment there but did not succeed): If you see something like this:
         char buffer[1000];
         struct thingy *header;
         header = (struct thingy *)buffer;
    
    then it is time to run. I hope you do not depend on this software, because it is a pure accident if this is doing anything at all. While you can cast a char * to a struct, that is only allowed if that memory actually was this struct (or one compatible, like a struct with the same initial part and you are only accessing that part). In this case it is obviously not (it's just an array of char), so you might see bus errors or random values if the compiler does no optimisations and you are on a architecture where alignment matters. Or the compiler might optimize it to whatever it wants to, because the C compiler is allowed to do everything with code like that. The next problem is the one that post was about: You are not allowed to access an array after its end. Something like
     struct thingy  
         int magic;
         char data[4];
      
    
    means you may only access the first 4 bytes of data. If you access more than that it may work now on your machine, but it can stop tomorrow with the next revision of the compiler or on another machine. If you have a struct with a variable length data block, then you can use the new C99 feature of char data[] or the old gcc extension of char data[0]. Or you can use unions. (Or in some case use the behaviour of structs with the same initial parts). If you use C code with undefined semantics then every new compiler might break it with some optimisation. There is often the tempting option of just using a slightly different code that currently works. But in the not too distant future the compiler (or even some processor) might again get some new optimisations and the code will break again. Fixing it properly might be harder but it's less likely it will fail to compile again and it also reduces the chances that it will not fail to compile but simply do something you did not expect.

    14 December 2010

    Dirk Eddelbuettel: RcppDE 0.1.0

    A new package RcppDE has been uploaded in a first version 0.1.0 to CRAN. It provides differential evolution optimisation---a variant of stochastic optimisation that is similar to genetic algorithms but particularly suitable for the floating-point representations common in numerical optimisation. It builds of on the nice DEoptim package by Ardia et al, but reimplements the algorithm in C++ (rather than C) using a large serving of Rcpp and RcppArmadillo. I worked on this on for a few evenings and weekends in October and November and then spent a few more evenings writing a paper / vignette (which is finished as a very first draft now) about it. This was an interesting and captivating problem as I had worked on genetic algorithms going back quite some time to the beginning and then again the end of graduate school (and traces of that early work are near the bottom of my presentations page). So what got me started? DEoptim is a really nice package, but it is implemented in old-school C. There is nothing wrong with that per se, but at the same time that I was wrestling with GAs, I also taught myself C++ which, to put it simply, offers a few more choices to the programmer. I like having those choices. And with all the work that Romain and I have put into Rcpp, I was curious how far I could push this cart if I were to move it along. I made a bet with myself starting from the old saw shorter, easier, faster: pick any two. Would it be possible to achieve all three of these goals? DEoptim, and I take version 2.0-7 as my reference point here, is pretty efficiently yet verbosely coded. Copying a vector takes a loop with an assignment for each element, copying a matrix does the same using two loops. Replacing that with a single statement in C++ is pretty easy. We also have a few little optimisations behind the scenes here and there in Rcpp: would all that be enough to move the needle in terms of performance? And the same time, DEoptim is also full of the uses of the old R API which we often point to in the Rcpp documentation so fixing readibility should be a relatively low-hanging fruit. To cut a long story short, I was able to reduce code size quite easily by using a combination of C++ and Rcpp idioms. I was also able to get to faster: the paper / vignette demostrates consistent speed improvements on all setups that I tested (three standard functions on three small and three larger parameter vectors). More important speed gains were achieved by allowing use of objective functions that are written in C++ which again is both possible and easy thanks to Rcpp. That leaves easier to prove: adding compiled objective functions is one indication; further proof could be provided by, say, moving the inner loop to parallel execution thanks to Open MP which I may attempt over the next few months. So far I'd like to give myself about half a point here. So not quite yet shorter, easier, faster: pick any three, but working on it. Over the next few days I may try to follow up with a blog post or two contrasting some code examples and maybe showing a chart from the vignette.

    13 December 2010

    Joey Hess: recent sightings

    Anna visited the Hollow a month ago and blogged a "tour of an underground solar house". She was quietly taking pictures the whole time, and I'm atonished how well they capture the place. I was honored to be the first in Rapha l Hertzog's series of Debian developer interviews. My interview -- the others he's done since seemed better to me. I was pleasantly surprised to open Linux Weekly News this week and see an in-depth article about git-annex. LWN's well-researched content continually impresses. Finally, I was indirectly mentioned in November's Science magazine. I'll leave you to guess which of the articles is the one I influenced.

    12 December 2010

    Neil Williams: Free software under the bus

    Sometimes, free software isn't better than proprietary, it's true - and one of the principal reasons is that the majority of free software does not use the full power of the freedom of the software. Far too many free software projects are single-developer projects. Many single-developer projects at SourceForge or Savannah and elsewhere have a single maintainer for the distribution providing the packages too and some (including nearly all of my own) have one person doing both jobs. In other words, there is no collaboration upstream or in packaging, so there is little or no benefit to the code of being free software...

    It begs the question of what happens when the omnipresent developer-under-a-bus risk actually bites.

    When comparing free software and proprietary, considering end-of-life effects can be very illuminating, especially when considering the interests of third-parties who come to rely upon the output of the project. When a proprietary software producer declares a software product to be end-of-life (whether due to collapse/purchase of the company or some other restructuring) third parties are left high and dry. In effect, all proprietary software is directly equivalent to a single developer writing free software. The more important the software, the worse this gets because at least if the single free software developer does disappear, the third party can try and pick up the pieces.

    The bigger problem for free software is the common failure to actually collaborate. This has been my main upstream bug bear for a long time now. The model must change. New contributors must be dissuaded from writing new code just because they prefer one language over another. Distributions need to change their guidelines for new developers to actively discourage new packagers from starting with new upstream code. We are in danger of undermining the main appeal of free software by not stamping harder on the NotInventedHere (NIH) syndrome. NIH is pernicious, NIH is dangerous and there is even an argument for considering NIH as an anti-feature.
    New is considered harmful
    New is not necessarily a good idea, new can be positively harmful to the interests of the wider software community. New promotes reinventing the wheel. It's another incidence of "Just because we can, does not mean we should."

    If free software advocates neglect to counteract the poison of NIH, then free software will lose the argument by losing the fundamental merit of free software. A freedom which is not utilised is akin to not having that freedom at all. Yes, someone can pick up a free software project after the single developer abandons it but, in practise, what actually happens is that someone else comes along whilst the single developer is struggling along alone and decides to fall prey to NIH simply because the original is written in C and their preferred language is Python or Ruby or Haskell or whatever.

    The "choice" argument is simply invalid - providing another implementation of program foo in a different language is just a way of reinventing the bugs already fixed in foo in new ways in a new language - and then adding some more which are unique to that language. Yes, the new developer might argue that the new code is more active but for how long? Long enough to become just as stable as the abandoned code? What benefit is that? In a few years time we will have two abandoned codebases in two different languages written by two different developers who never collaborated on the actual problem both of them were trying to solve independently. Lunacy.

    The dilemma for distributions like Debian is that the list of Debian Packages that Need Lovin' is a burden to Debian during a release freeze yet provides an ideal launchpad for new developers to refresh stale code. I've long thought that Debian needs to be more strict on removing such packages, yet at the same time I cannot help but feel that this tends to encourage more NIH behaviour.

    It's a common mantra amongst free software developers that many eyes make all bugs shallow. The problem for free software is that outside certain key teams, there are simply too few eyes and the community is not doing enough to shine a light on existing code before dancing to the sound of the NIH drum.

    Far too much free software is at risk from that omnipresent bus called "RealLife" and this makes far too much free software little better than proprietary software. Pandering to the fashions of NIH only makes things worse.

    This isn't a technical problem that can be solved with a new cool tool (which itself is subject to the NIH poison), it is a social problem and, sadly, the free software community has a history of failing to tackle purely social problems successfully.

    There is a small role for existing technical solutions to make it easier to spot NIH tendencies, including sites like SourceForge and Savannah having greater scrutiny about new projects and distributors like Debian being more averse to adding yet more ITP bugs (or closing them automatically unless something happens within a month). Fundamentally, it comes down to how new and existing members of the free software community decide to handle their own projects and bugs. The model of "do it this way because that's more fun" has got us so far, the challenge is to remove NIH tendencies without removing that fun.

    Next.

    Previous.