Search Results: "rul"

28 October 2008

Ondřej Čertík: Google Mentor Summit III

On Sunday I checked out from the hotel and enjoyed the breakfast, basically the same as the first picture here. Which is cool, the best way to start a day is with a good breakfast in the morning.


At Google I finally met with Bart Massey, who works at the Portland State University where I was an intern (in 2005) and also he was sponsoring one SymPy GSoC student in 2007.


Then we started to port SymPy to Jython with Philip Jenvey. I first installed openjdk-6, which is in Debian main, then checked out Jython svn, typed "ant" and it just worked. This is so awesome, that we finally have a truly opensource and fully working java implementation in Debian. Philip fixed some bugs already, so SymPy imports just fine. Most of the tests run, but also quite a lot still fail.

We managed to isolate two bugs: issue 1158 and 1159. Then there was an annoying recursion bug, that took us several hours to dig into and I then had to leave at 6pm without a clue. But Philip kept saying, I just need to look more at the java stacktraces that Jython was generating and I'll figure it out. And he did! The next morning he filed an issue 412 in the PyPy tracker, because they seem to have the same problem. There are subtle differences in how to handle __mul__ and __rmul__ methods that are not well documented, so it works in CPython but fails in Jython/PyPy. I think we can fix that in SymPy too in the meantime, so I am very excited, because it seems SymPy will work on top of Jython soon.

There was also a git vs hg session with both hg and git developers. Since I recently switched from hg to git for all stuff where I can choose the vcs, it was very interesting for me. And I must say I am glad I switched. Mercurial works fine enough and with the recent rebase feature I think it is usable, but git just has a bigger momentum at the moment and it just doesn't get in my way.

During the day Steve sent an email to the GSoC list that Dirk forgot his jacket in the hotel room, so I said to myself, haha, that's a pity. And then I realized, oh shit, I left my jacket there as well. They didn't have it in the evening when I stopped there, but fortunately they sent me an email yesterday that they found it, so I'll stop there on my way back.

We also took couple of group pictures, here is just my lame attempt (I am sure people will soon post better ones):


On Monday morning I met with Fernando Perez, the author of ipython, he know works with Jarrod. Then I rented a car and came to visit Brian Granger and his family in San Luis Obispo.

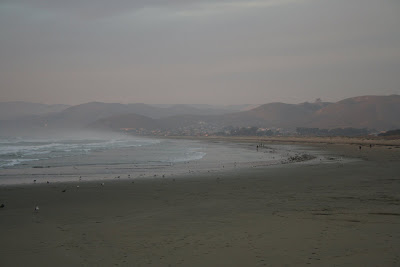
We went to the beach in the evening:


And had a dinner together. Brian showed me his options pricing example he did with SymPy, so I made him create an issue 1175 with the code.
Then we played with the parallel stuff that Brian contributed to ipython and we tried sympy with it and to our disappointment, we found pickling bugs in sympy, it works with protocol 0, but not protocol 2, see the issue 1176 and 1177. This almost smells like a bug in Python itself, but I need to investigate that later more deeply.

Today is Tuesday and we'll work on doing atomic physics calculations with sympy. See also Brian's email to the sympy list about it.

27 October 2008

Decklin Foster: We could customer care less

(And now, a cathartic "I hate this company and I am never patronizing them again, please don't either" post. I should have done ones for at least Speakeasy/Covad and IBM's server division last year. Ah well.) I went to go register a new domain yesterday (announcement soon! Probably this weekend). I've been using Joker for a while, IIRC on the principle that the cooks were using it so it must be decent enough. While registering, I had a bunch of problems with the horrid, useless "Verified by Visa" popup [1] that you see everywhere these days, and eventually this must have looked like suspicious activity to the bank so my card was declined. I only actually found this out when I got mail saying my order was canceled. Okay, sure. I wrote back and explained what I thought was going on and that I'd like to resolve it. Another half hour later, I got this response:
Hello,
please use
   https://joker.com/goto/support/
for all support inquiries.
Regards, your Joker.com team
This is complete and utter bullshit [2]. If a company is going to mail me, I expect to be able to mail them. I have a mail client; it manages communication the way I want it to, and runs my preferred editor to compose messages (which is, in fact, how I am writing this very blog post). I am sick of dicking around on JavaScript-requiring web forms that all work differently and typing in postage-stamp-sized little textareas. Anything I do type in them is lost, because unlike my email client, web forms don't save sent messages unless the authors feel like letting you have a Cc:. When a company forces me to do this, I take it as a sign of disrespect. I tolerate a web browser [3] for reading pages; "applications" are universally painful [4]. One of the things I used to like about Joker was the PGP mail interface. AFAIK, they have not killed it (I didn't bother to check), but with automatic "we don't want to listen to you unless you inconvenience yourself" bounces like this, what's the point? I surmise that there is, or was, some smart person there who understood how (and more to the point, why) to hook a pseudo-mailbox up to a software system, and that they have been overridden by someone in management who realized it's much easier to have dime-a-dozen webmonkeys hook a form up to the same system since 90% of users just don't care (and even people who do notice and dislike this, but are not as inflamed as I, have come to expect it because everyone else refuses mail, so, y'know, pick yr battles son, etc.). Not the sort of culture I put faith my in. The irony of it all was that I was registering this domain to run a service I had decided to create specifically because of another site refusing mail and directing me to an even lamer web form. That would take incoming mail and, you know... process it with software. Suffice it to say, I am no longer going to be their customer. In deciding who to use instead, I figured I'd do a survey of where the domains in that "Subscription" column [5] on Planet Debian were registered, but... WHOIS is basically useless. Every server just returns free text, formatted differently by (apparently) every implementation under the sun. Cheaply parsing something out from .com/.org/.net is possible, but InterNIC kindly blacklists your IP after making more than a few requests in a few minutes. I guess I'm just gonna go with Gandi (but other suggestions would be welcome). In somewhat unrelated developments, I went to nic.at to update my nameservers for Where the Bus At? last week. There was no authentication or anything on the request form, so I just filled it in and sent it off. I got some automatic mail saying I need to print out a PDF, sign it, and fax it internationally. Annoying, and hardly as secure as mailing them with PGP, but whatever. But then, also yesterday, I got another mail saying the update was complete (lo and behold, it was). I am now somewhat concerned about the security of my domain: it seems like anyone can come by and put something in the form and if I'm not around to notice the courtesy mail and ask that they stop the request, it'll eventually go through, no questions asked. I have not yet written them to figure out what the deal is, though. Kinda burned out. I guess I didn't really have high hopes for dealing directly with a ccTLD registrar (this was the first time I've done it... I can't believe I blew 60 on a cutesy domain name) rather than a reseller who competes in a market, but then, I go and google "domain registrar" and look at all the AdWords dollars spent trying to compete with GoDaddy [6] and just kind of want to put my head in my hands. On DJB's DNS pages there's this bit about setting up a domain. It doesn't say "How to (buy register whatever) a domain name". It says, "How to receive a delegation from .com". Which is of course, how it works. And what I want to buy. I don't want "parking" or even gratis nameservers. Just a delegation from .com. Please. No AdWords came up when I googled for that phrase to copy the link. Sometimes I guess markets just sink to the bottom. Anyway. I feel like there's a free-software angle here. My continuing irrational hatred of using other people's forms, web-based mailing-list substitutes, nameservers, etc. stems not so much from their suckage but from the fact that there is no longer any software there, in front of me, for the four freedoms to possibly apply to. Being able to run your mail reader for any purpose doesn't win you much if no one uses mail. I don't really know what to do about this.
[1]It was only twelve dollars! If I go to hipster market or some other place with brand-new POS systems they don't even make me sign a paper slip for less than $20 or so. But this is the sort of thing dreamed up by people who think good security is setting a cookie to denote that I've answered "what was your first dog's name" or whatever. IF YOU WANT TO BREAK INTO MY BANK ACCOUNTS: I've set the answer to every single one of these questions to "security theater". Easy to remember.
[2]Not to mention a glaringly RESTless URI.
[3]Also, as a rule I normally try not to have anything up on my desktop that I can't close and re-open at any time, thanks to screen, MPD, emacsclient, actually using my browser's bookmark function and resisting the lure of tab-bar.js, etc. Web browsers are supposed to suck at preserving state; HTTP is stateless. See also here (and for further reading on that in the Haskell world, check out Yi. I'm hoping to switch to it someday).
[4]Debbugs, for example, may not have the slickest interface, but if I want to do flags, labels, archiving, threading, or whatever, I can; I'm not at the mercy of some front-end web developer. But we've all heard this litany before.
[5]Thanks, Hpricot!
[6]Even if GoDaddy's customer service were completely hacker-friendly, I would not use them, because their president Hates America.

Romain Beauxis: About democracy (revisited)

After my last post about the ongoing debate on the new process to accept and handle debian project members, Rapha l Hertzog proposed an alternative organisation which could be a solution, but misses the most important fact: how the people in charge of the process would be chosed and dismissed. Rapha l Hertzog wants that we consider a group of skilled and trustfull people in charge of giving and revoking powers to lower class of developers, on a per-event basis. Their procedure would be an internal vote amongst this group, and they would be called the "Debian Community Managers". Although it could be a good idea, it really misses the MOST IMPORTANT FACT: how they are chosed and to whom are they responsible. As a reply to my comment, Rapha l propose that they would be elected at first, and then nominated/revoked on the basis of the decision procedure mentioned above. Not only is it exactly what have been in place for the last years in the various core teams, but also it is a dangerous naive vision of how powers and regulations must happen. Before the Debian project started to consider these issues, the various ideas to build a system where the majority is ruled by a minority and the means to prevent the most important issues has already been studied, in the field of Law and how to write a Constitution for a democratic system. The goal of a democratic system is to put some higher power in the hand of several, but prevent as much as possible any issue. And preventing means act before shit happens, not after. Furthermore, power has to be divided into several domains, where the people in charge of these domains are strongly seperated and share as less common interest as possible. Hence, the goal of a constitution is to weaken power and put barreers, even if this leads to slow and frustrating reform processes. In the same idea, elections, which redraw the positions, are planed on a regular basis, and if the previously elected people were good, they are relected, not the opposite, in which if they aren't good they are dismissed. Again, we prevent issues, so the requirement to be responsible for what you did is implicit. And, last, it is well known that the less direct a decision process is, the less democratic it is. Hence, one should always prefer direct elections to indirect nominations. Now, coming back to Debian, we can have a very similar distinction in the various powers available: Now, the propositions, and all the various discussions are motivated by either the fact that there are issues with some developper's behaviour, which falls into the justice side and for which we already have a wide history of long debates before we act whatever the act is, or the executive power to give rights and introduce a new member in the project. Yes, we clearly miss a role in the project for applying rules and sanctions and deciding about these issues. However, we really ought to fix it the right way. In particular, never should we, in any way, give any justice power to someone in charge of any of the other power, in particular core teams. And the same for the right to appoint new members. For instance, to name an issue, the Frans vs. Sven issue would have been really different if there wasn't any kind of personal interest and power in the people in charge of the decisions. In real social systems, the right to apply a sanction or give new rights is a very dangerous power. It suppose a high level of separation between your personal interest, and the decision you have to make, as well as a high level of responsability against the people who trust you. We used to claim that Debian was not a democracy, but a meritocracy where technical skills are the ultimate ranking for deciding who's good or bad when giving reponsabilities. I have never been convinced by this approach, which I consider, just as anarchy, as valid for a small group of developers, but completely naive for a big group. Now, it is clear that the issues that we are dealing with in this situation have nothing to do with technical skills. In particular, the original proposition creates a class of non technical contributors, documentation writers, or translators etc... Furthermore, if you look back in the past, there have been a lot of situation where the issue, and its solution had nothing to do at all with technical issues, like issue mentioned above, or the Duck Tank or whatever it was called. We really should drop this naive idea that technicals skills are the only way to put on decision on the project. That is no longer how it works, nor a solution to the human issues that we face now.

26 October 2008

Sean Finney: ps3-kboot for debian

now that ps3-utils is packaged, and it seems spufs didn't take much to get to work, i'd like to turn back to the installation procedure, which was admittedly manual and not exactly as "seamless" as i think it could be. the first step as i see it is to get the bootloader working both generally and also specifically for the installer. by "working", i mean the following: the third of these being the most complicated, as will be detailed below. how a linux (kboot) "otheros" bootloader works on the ps3 okay, so i'm not intimately familiar with the powerpc architecture, nor with all the details of cross-compilation, but this is as much as i can tell. how kboot can be used on the installer including support for this "otheros.bld" bootloader on the installer is fairly easy from a technical point of view, whether it's a usb disk or netinst cdrom image. basically, in either case the media should have a directory called "ps3/otheros", in which the file is placed and named "otheros.bld". when running the PS3 in game-os mode, this is where it looks when you tell it to "scan for otheros". how kboot can be used/maintained, generally speaking beyond a kboot.conf file, nothing really needs to be done on the host os to use kboot. of course, it would be nice to be able to issue updates for an image, which should be possible with a package that makes use of ps3-flash-util from the ps3-utils package. nothing too difficult/complicated there. how kboot can be used/built within debian this is the tricky part. in additional to the standard Free Software guidelines which debian is so (in)famous for following, we also have some basic QA rules that are needed from a distribution release management / security perspective. one of these rules is that generally speaking it is considered taboo to include embedded copies of other software within a package, if that software is already available in debian. for example, i don't think it's very likely that the ftp-masters will look very kindly on some new software package that includes a copy of the entire kernel source tree, the gcc compiler, (uc)libc, busybox, coreutils, udev, etc. it may be that a certain subset will require special patches, in which case some convincing/justification will be in order, but for the big ones (i.e. the kernel) there will almost certainly need to be modifications made. ps3-kboot in ubuntu there are already source packages available for ps3-kboot in ubuntu. apart from the fact that i can't stand working with packages that use cdbs, this package can't be used because the package maintainers' solution to the previously mentioned problem is basically to ignore that it exists. it also seems that there's quite a bit of customization in this source package with respect to the initrd generation, which is probably worth some review... so i will likely still use this package as a base point of reference.

24 October 2008

Biella Coleman: Hacker practice: Moral genres and the cultural articulation of liberalism

So I usually don’t announce my publications on my blog and for various reasons. The main one is that I am more than a little embarrassed that some of them are behind walled gardens (but being I am a junior prof, I am not in a position to negotiate otherwise). Otherwise, some of my pieces are semi-jargony (in the academic sense) and may not be of interest to readers who I think are more geek than academic. Finally, the process of publishing is so slow, so long, and so painful, I try not to think about it, much less write about it, if I can help it. But I decided to announce this
piece , which is on hackers (surprise surprise) as it might be of interest to some readers and because people can download it for free here for the rest of the month (but registration is required ) Co-written with Alex Rex Golub, I am pretty happy to see in print although it is far more academic in its tone, argument, and language than most of everything else I have written. This is in part because the article is more theoretical than ethnographic (hence the journal, Anthropological Theory) and tackles the question of liberalism alongside hacking. It seeks to demonstrate that these can be talked about 1) together and in cultural terms 2) that we we can identify some cohesive elements to hacking and liberalism, in part by placing them in conversation with each other 3) and yet we can also locate plurality and diversity within liberalism and hacking as well. This is a lot to tackle and cover in one piece under 35 pages and I am sure it could have been pulled off better but I think it is is a decent start to thinking about these questions. If you are interested but are allergic to academicalese, sticking to the Introduction, the Hacker Ethical Practice: Three Examples section, and Conclusion, will give you a taste of the arguments while avoiding most of the jargon. The irony of this article is that even if it hits at some pretty theoretical issues, it was provoked by a mundane conversation and disagreement I had with one hacker, Karl Fogel, over another hacker, Kevin Mitnick. After returning from the hacker conference, HOPE, I had dinner with Karl and told him about Kevin Mitnick’s keynote speech, which I found particularity enjoyable and entertaining. After calling Mitnick a hacker, Karl responded with the following: Kevin is not hacker. He is a cracker. Though I think I convinced him that cracker may not be the best word for him (and he convinced me there are differences between hacking, noting perceptively that his primary motivation seemed to be getting access to something he wasn’t allowed to have access to that is, it was more about breaking the rules and the thrill of crossing a social line, than about learning a technical system. ), I decided that I wanted to write a piece that squarely addressed tensions and differences among hackers instead of whitewashing them away as most authors, journalist, and even some hackers do.
Although most of the time, it seems like it is the Karl-type hackers who accuse the Mitnick-type hackers of not being true and authentic, recently I have been in a few situations where the tables were turned. For example, last year I was having coffee with a 2600-type who insisted that hacking on Linux was not hacking at all (not innovative enough, according to his world view). Another example I came across was in a recent Phrack issue where the prophiled hacker, the Unix Terrorist, takes a swipe at (well honestly at everyone and everythin) but when he is talking trash about who is and who is not a hacker, he singles out F/OSS developers:
Linus Torvalds isn’t a hacker! Richard Stallman isn’t a hacker! Niels Provos
isn’t a hacker! Fat/ugly, maybe! Hackers, no! And what is up with
the use of the term “cracker”? As far as I’m concerned, that term
applies to people that bypass copyright protection mechanisms.
Vladimir Levin? HACKER. phiber optik? HACKER. Kevin Mitnick? OK,
maybe a gay/bad one, but still WAS a “hacker.” Hope that’s clear.
Of course, one can play the game of defining the authentic hacking (and it makes sense for many to do this!) but my interest as an anthropologist has never been to draw a bright and clear boundary between good hackers and bad hackers. or “real and fake hackers,” but instead to describe and grapple with the tension points and internal ambiguities among hackers (my whole course is designed around this theme, in fact). This is not to say that anything goes in the world of hacking (that is, I don’t consider any computer break in a hack; I often just call it a crime) but if there is a group of people calling themselves hackers and thinking to some degree of the ethical implications of their actions, as an anthropologist, this is enough “social evidence” to start asking some questions about the political and cultural significance of their actions.

23 October 2008

Romain Beauxis: About democracy..

Following the recent announce about an intent to extend debian membership to various levels of contribution, I would like to add my two cents.. Some bloggers mentioned how they disagree on the notion of various level of rights, claiming that it was yet another class inequality. Some other bloggers mentioned their support to the proposal, and other felt that the announcement was badly done. I, for myself, don't have an objection to the idea that they should be various level of rights. I do like the notion of anarchism, but I have some doubts it can extend to a wide group of persons. Besides, I personally don't want to have rights on everything, since I don't want to be responsible for them. As for real life, I believe the less broken system to rule a big group of people is democracy. And, as such, I don't have objection to a system establishing different levels of rights, provided it is transparent and responsible to the majority of members. In particular, voting right and vote outcomes should rule everything. According to the debian constitution, it is already the rule that most major decisions in the project can only be taken by votes. That's a good thing for actions and resolutions concerning the project. Now, concerning members, the proposition would establish new rule to accept and give rights to new coming users. Fine. But, I wouldn't think it is fair until the same process apply also to core teams, and until the basis of the project are the voters, which would choose or dismiss members of those teams. Inequality class, just like democracy, can be seen as a necessary evil. But inequality is balanced, to me, when there is a democratic process of electing and dismissing people. Then, we can hope that there won't be any sort of aristocracy.

Matthew Palmer: Porting debian-installer to the DNS-323

I've just started a new job, so I decided to take a few days holiday in between and work on something that's been on my todo list for way too long now -- making the debian-installer work on the D-Link DNS-323. After a couple of days of work, I've just finished off the install of Debian on my DNS-323, which I initiated by loading a firmware image into the web interface of the stock firmware, and then SSHing into the machine at the appropriate moment. What this means is that anyone with a DNS-323 can install Debian on it. I think that's worthy of a small, quiet "woo hoo!"... Looking back now, it seems to have been a fairly simple and straightforward operation, but I can remember that it didn't look so simple when I started a week ago. So, in the interests of perhaps short-cutting someone else's adventure into the world of d-i hacking, I'm writing everything up while it's fresh in my mind (the benefits of being on holidays -- plenty of time to write long blog posts). Alternately, if anyone has a random device they'd like to see d-i on but doesn't have the inclination to do it themselves, feel free to send me one and I'll do it for you. Before I begin, I've got a few "shout outs" (I think that's what the cool kids are calling it these days) to people who've helped me along the way. First off, Martin Michlmayr has answered innumerable dumb questions from me, and I think wrote most of the parts of d-i that I've extended -- it's fair to say that I'd have had no hope of doing this without him. Thanks also to the people in #debian-boot and #debian-arm for answering questions and putting up with my frequent bouts of self-congratulation whenever I passed the most miniscule milestone. Finally, everyone who has put work into d-i has my thanks, too -- it's not perfect, but it's a damn sight better (both to use and also to hack on) than any other installer I've ever met. So, without further ado, off we go... Work out how to get a console Unless you are a guru of unbelievable skill, you will undoubtedly not do everything quite perfectly the first time, and you'll want to see the kernel/init boot messages, and maybe in some cases try some investigation and diagnostic work. For that, you're going to have to have some sort of console access. If the device doesn't have a full screen/keyboard thing going on, the chances are you'll almost certainly end up with a serial console. A few devices have a network management thingo that will give you a console, usually over VNC or some sort of horrid Java applet, but I've only ever encountered that in rackmount servers, which have a keyboard/video interface anyway... In theory, I suppose, the kernel could provide a network console, but I've never heard of such a thing being attempted, and Google is not helping me out. I might add that to the todo list as a future hacking project... On the DNS-323, it was a serial console that was needed. Like a lot of the embedded devices I've seen, it didn't quite talk RS-232, so I needed an adapter (I got a TTL-232R-3V3 USB-to-3.3v-serial adapter from a local electronics supply place, which worked perfectly with Linux as soon as I plugged it in). I needed to solder a few wires to a connecter inside, and connect that up to the USB doohickey, but it all came good in the end. The chances are someone's done a similar job for your device of choice, so a search for things like "devicename serial console" will almost certainly pay off. Work out how to load and boot a kernel/initrd Your development work will involve booting weird kernels and initial ramdisks to make everything work; you need some way of stuffing those into the device and booting from them. Everything has a boot loader of one sort or another; working out what you've got and how to make it sing and dance is the ultimate quest here. How this is done will vary greatly from device to device; the WRT-54GL, for example, waits for a tftp connection for a couple of seconds on startup, which you can use to send a new firmware; many other devices have a boot loader that you have to explicitly control (via the console), but it will make a tftp connection out to another machine if you ask it to. Some devices you just need to load the data in via serial cable (at 115200bps it's bearable; at the 9600bps I've heard some devices work at, it would be tres painful). The DNS-323 runs uBoot as the boot loader, which will do a tftp request by default. However, D-link, or Marvell, or someone in the decision-making chain for this thing decided to knobble it and removed most of the useful commands, so sending the thing via serial port is the only option. Since writing to flash takes a pile of extra time, I found (eventually) that you can just load the data into RAM somewhere and boot from there, without needing to write it to flash (also handy to avoid wasting precious write cycles), since you can tell uBoot to boot a kernel located anywhere in the address space. Obviously you need to reload the kernel/initrd on every boot if you don't write it to flash, so if you've got a "stable" kernel or initrd that you think you'll be using for a while (when you're testing the other item) you should flash it then. One note on uBoot, that took me far too long to work out -- you can't just stuff a kernel fresh off the Makefile in and assume it'll work -- uBoot needs a special header prepended that tells it all about what you're loading (architecture, file type, compression method, etc). You "wrap" a file in this uBoot header with the "mkimage" command (in the uboot-mkimage package in Debian). Incidentally, if you need to remove the uBoot bits from a file, just strip the first 64 bytes off -- that's all the uBoot header is, so something like this will do nicely:
 dd if=file.uboot of=file bs=64 skip=1
A final uBoot warning: it's fairly important to specify a "load address" for the files; if you get them wrong, your kernel and initrd may or may not boot (I never quite got the hang of why some wrong values worked and some didn't). If your device uses uBoot, and you have the ability to extract the uBoot-enabled kernel and initrd from a vendor-provided firmware image, you can use mkimage -l to inspect what all the values need to be for your own kernels and initrds. Just stick with them. Does Debian support your hardware? Obviously, if you want to run Debian on something, Debian has to support that hardware. The easiest way to test this out is to try an install. For this, you'll need to retrieve an appropriate kernel and initrd pair for the installer. Some arches, like i386 and amd64, only have one kernel and initrd for the installer, so you just have to choose if you're going to netboot, or do a full CD install, or whatever. Other arches, though, like arm, have subtly different images for different machines. There are two reasons they vary: firstly, they often need to split into subarches, where they all share a general CPU architecture but there are enough differences in the hardware that they're not all supportable by the same kernel. At a more fine-grained level some different machines of the same sub-architecture need differently formatted firmware images to boot. On ARM, in particular, it's pretty common to need to prepend a "device ID" to the kernel image so that the kernel knows what sort of machine it's booting on, which means that every machine typically needs it's own kernel image, regardless of any other issues with firmware formats. Choosing the sub-architecture should be relatively straightforward, if you know much about the machine you're targetting. Picking a machine type can be a bit harder, but again, if you know what your boot loader needs, it shouldn't be too hard to find a kernel/initrd from the existing machines in your subarch that you can mangle to fit. Load up your kernel/initrd into the device, boot it, and see how far it gets. You might get lucky, and the kernel inits, your hard drives are detected, your NIC is initialised, and you're off and running without further ado. Or you might not be so lucky. The worst case is that the kernel doesn't even get as far as loading the initrd -- it might not print anything at all, or the kernel might hang part way through the boot. This is likely to require a fair amount of debugging fun, as initial boot failures get a bit tricky. A better situation is where the kernel boots OK, and d-i starts, but something in the install process falls over. This can either be a kernel/driver problem, or a d-i problem. Either way, since d-i has started, you're likely to be able to get a shell and do some debugging. In order to make d-i work, you need to have somewhere to install to (disks, usually) and a source of packages to install from (CD/DVD if you're on a suitably large device, or the network otherwise). These are the two key ingredients you need; most everything else is stuff that ranges between "nice to have" and "critical" for operational purposes, but which has absolutely zero impact on your ability to do the install, so we'll ignore it for now. For the DNS-323, I had a few kernel problems (which I'd been warned about by Martin before I started) -- the NIC wasn't initialised with it's MAC address, which meant it was running around my Ethernet screaming "I am 00:00:00:00:00:00! Ph33r m3!", and the SATA controller just didn't seem to exist at all. These were kinda critical to doing an install, so it was time to get hacking to make those work. There were also a couple of parts of d-i that needed tweaking -- the preseeding code didn't support the device, and I needed to package a tool to build a "complete" uploadable firmware image and teach d-i how to use it. Apart from that, though, things were looking pretty good. Make the Debian kernel support your hardware Once you've worked out what hardware you need to make work, you need to dig into the kernel and fix it. Sometimes, if you're really lucky, a kernel version newer than the one currently in Debian has better support for something, and you can backport the fix / feature improvement. Other times, there's something similar already in the kernel for a different device and you can crib off that (I did this extensively for my little fixes). Then there's the "ask an expert" school, where you find someone who knows what they're on about and pick their brain (I did a bit of that, too). Finally, there's plain old "research and development", for which there are piles of documentation already out there. My changes for the DNS-323 came to 121 added lines and 16 deleted lines, most of which was cribbed-and-tweaked from other parts of the kernel. I might have written 10-20 lines of code "from scratch". It's not always scary-hard. Cross-compiling your own kernel One thing that I think needs mentioning in the kernel hacking department is cross-compiling a modified kernel for testing purposes. Chances are your main workstation has a lot more grunt (and build tools) than whatever you're trying to get Debian onto, so cross-compilation is the way to go. You need to first grab a copy of the source you want to build (from apt-get source linux-image-blahdiblah, or a release tarball, or Linus' git repo, it doesn't really matter) and a cross-compilation toolchain. For my cross-compilation toolchain, I just added this to my sources.list:
 deb http://www.emdebian.org/debian/ unstable main
then I ran apt-get update, and installed these packages:
	binutils-arm-linux-gnueabi gcc-4.1-arm-linux-gnueabi
	gcc-4.3-arm-linux-gnueabi-base libc6-dev-armel-cross
Kudos to the emdebian team for making that such an utterly painless exercise, by the way -- the days of needing to faff round with gcc sources to get a cross-compilation toolchain are apparently over. Once you've got a source tree and a cross-compiler available, you can run any of the usual kernel make commands (like make zImage or make oldconfig), as long as you've got a couple of make variables defined. In my case, I used:
 ARCH=arm CROSS_COMPILE=arm-linux-gnueabi-
ARCH tells the kernel what architecture to build for (useful in all make commands because not all arches have the same config options in make menuconfig, for example) and CROSS_COMPILE tells the build system what to prefix the calls to gcc, ld and such with (if you installed the same cross-compiler packages as I did, you'll find it installs files like /usr/bin/arm-linux-gnueabi-gcc, so you can ls /usr/bin/*gcc to find out what you'll need for the CROSS_COMPILE setting). Hack d-i to make things work In addition to tweaking the kernel, it's quite possible that the internals of d-i might need some tuning. It's possible that d-i might need to be "taught" to recognise the hardware in your device, or you'll need to extend some aspect of the installation process to complete the installation. In order to hack d-i, you need to know a bit about how it works and how it is structured, so let's run through that first. The entireity of d-i is based around udebs, which are packages of the same format as "real" debs, but which have been built differently (against a small libc, for instance) and have had everything that isn't absolutely necessary (docs, non-essential scripts, extra functionality, etc) stripped out of them to create the smallest possible packages. There are a variety of different udebs -- most are derived from otherwise normal, law-abiding citizens of the archive, like busybox (basic unix utilities like cp and ls), the shell that's used in the installer, parted, various libraries, and so on. Others are "special", and have no big brother in the archive. These are mostly "task" udebs, that define what actually happens in the installer. When they're "installed", they have special fields in the package metadata that define where in the install sequence they go, and they end up on the menu you see if your installation goes a bit pear-shaped. The tricky thing about udebs is that, as small as they are, there's too many of them to be able to have them all available when the system first boots, so even the "setup" of the installation gets done in several stages. First, the kernel and initrd boot. The initrd contains just enough stuff to get access to the rest of the udebs, and nothing else. Even this early stage is built from udebs -- there's lists of what goes into the initrd for various architectures and flavours of installer under installer/build/pkg-list in the d-i SVN. If you need an extra udeb in your initrd, that's the place to specify it. Once the initrd has gotten access to a source of packages (off a CD, over the network, telepathy, whatever) it can drag the rest of the packages it needs from there. Space is still an issue at this point, though -- there's no diskspace yet to put anything onto, so everything needs to fit into a ramdisk. Don't go loading anything you don't need. The packages loaded at this stage are what defines most of the steps that will be done for the rest of the install, so once all those extra udebs are loaded, the remainder of the install kicks off and does it's thing. Different architectures and install methods have different requirements, too, which complicates matters. For example, when you're installing on a regular PC with screen/keyboard, you can guide the install using that. However, if you've got no screen, how can you control the install? There's serial consoles, but requiring everyone to void the warranty (more) on their little embedded doodad by installing a serial console cable to install Debian isn't so hot. So, lacking a terminal, how do you control the install? Well, on install flavours for devices that might be in this situation, you can SSH into the installer and complete it that way. That feature is, like everything else, provided in a udeb -- called network-console, as it happens. But what IP address do you connect to, and what network settings does the device use? Again, without a console you can't configure your network, and not everyone has a DHCP server (and even fewer people have a DHCP server that will hand out an address that they'll know in advance, or be able to find out). So, there's a udeb (called oldsys-preseed) that does it's best to configure your network based on the settings already in the nvram for your device. In short, there's a lot of tricky, well-thought-out shit going on inside d-i, and you might have to deal with a little bit of it. The nice thing is that by now I expect most of the really hard problems have been solved, so with a bit of luck you'll only ever have to do minor tweaking. In general, all of the packages that are "d-i specific" live in packages in the d-i SVN. If you need to modify a udeb, you need to rebuild it and put it in installer/build/localudebs/ (creating it first if need be) and every time you change it, you need to delete installer/build/apt.udeb/cache/. To give a concrete example (from the ever-present DNS-323), I had to modify oldsys-preseed so that it would get the details from the nvram that the stock firmware uses to configure itself. This, in turn, required that the minix-modules udeb be included in the initrd, because the DNS-323's nvram is actually a small minix partition stored in flash. Painfully, this required some more hacking, because the armel d-i kernel wasn't configured to generate minix-modules. That might need some explanation... Since building the kernel is a fairly massive undertaking, CPU-wise, instead of building all the udebs from scratch there's a package called kernel-wedge to split a real linux-image package into lots of little udebs. There's a separate source package for each architecture, linux-kernel-di-$ARCH-2.6, that contains the configuration data for kernel-wedge to specify what udebs need to be built, and what goes into each of them. A small tweak to the armel package and voila! I had a minix-modules udeb to include in the initrd. With the config stuff I'd done in the d-i build itself and my changes to oldsys-preseed, we were done with d-i. Tell d-i how to build your bootable artifacts If your device needs a "different" install image from other similar devices, you need to write some makefile rules to build those files. Look under the installer/build/config/$ARCH/ directory to see the various rules files available. I had to package a new tool to create uploadable firmware images for the DNS-323, along with adding a rule to use that tool to build images. None of it was particularly difficult. Polish the diamond Getting d-i working is only part of the battle; it's quite likely that there will be other hardware in the machine that needs to be supported. This could involve kernel-level stuff to interface to the hardware, or userland tools to manage the hardware. There's several bits in the DNS-323 that still need work; I can't control the LEDs on the front panel, nor the fan, and I can't use the on-board temperature sensors yet. But, I do have Debian running on the thing, which is what I was shooting for. Examples If you're interested in exactly what I did, there are a number of bugs in the BTS that contain the patches I made:

17 October 2008

Ian Murdock: It s the end of the world as we know it (and I feel fine)

Warren Buffett: “A simple rule dictates my buying: Be fearful when others are greedy, and be greedy when others are fearful.”

16 October 2008

Cyril Brulebois: Programming 3D apps 101

Learnt today: Don t use printf() debugging within 3D applications. At least, not with \n. Some figures follow. First case
while (!viewer.done ())
 
  viewer.frame ();
  printf(".");
  /*   */
 
Gives roughly 75 FPS. Second case
while (!viewer.done ())
 
  viewer.frame ();
  printf(".\n");
  /*   */
 
Now gives roughly 35 FPS. What Yes, >50% performance hit due to newlines. By the way, the OpenSceneGraph 3D framework is very pleasant to work with, and pretty well documented. Could almost make coding in C++ enjoyable. Almost.

15 October 2008

Martin F. Krafft: Fixing the credit crunch problems the wrong way

We re all aware of the financial crisis due to credit default swaps shaking up the markets, media, politics, and what not. Some of us are feeling the pain, most of us aren t yet. A few days ago, politicians of the big, capitalist nations convened to agree on a way forward to stablise the financial market and set an end to the crisis. They are planning on doing this by throwing hundreds of billions at the market, buying all the subprime loan packages with the intention to create a new market for them, thus taking the weight off the shoulders of the countless barely-surviving banks and investors, who have written off billions in losses without an end in sight. Where does this money come from? Taxes and newly printed money. You may not yet feel the effects of this, but you will: taxes will rise, and inflation soar to even higher levels. Today is Blog Action Day with poverty as the focus, and it s a good occasion for me to state what s long been on my mind. The strategy by our political leaders to combat the credit crunch is short-sighted, and it fights symptoms, not causes. In fact, it s Robin Hood played in reverse: tax increases and inflation will hurt those most who cannot do anything against it: the poor. On the other side of things, those active in the financial markets will have their damages limited, and new CDS markets might even create more opportunities for those who can. I strongly oppose the way our politicians are handling the issue, even though I do have small amounts of funds invested in financial products myself, and have already seen the positive effects of their actions. Rather than throwing money at the markets, we really ought to put those away who have caused all this, those ruthless, greedy ones who have speculated way over their heads, underestimated the risks, and caused this crisis that killed many businesses, threatens to endanger entire countries, and hurts individuals who hardly ever had a choice. Think of it as a driver s licence, and that should be revoked for those who screwed up so royally bad and got us into this situation in the first place. Don t let them speculate again! Update: Andreas Metzeler notes that he is (rightfully) missing a what is to be done instead section in my blog post. I don t have anything to offer on that front, sadly. I also realise I should have phrased my opposition differently. Reading this interesting interview with Deutsche Bank ex-CEO Hilmar Kopper (German only) (thanks, Andreas!) helped me understand more that the politicians aren t saving banks, they are saving the system, and that they have little other choice. Another aspect I haven t previously seen as clearly as now is that the governments are purchasing (and willing to carry) risk for others, to relieve the markets. Risk by itself doesn t cost anything, so it might turn out that the billions they made available won t actually be spent though I always new that the governments might well come out of this with a profit even. The whole affair still stinks, and what I truly miss are the actions to prevent those responsible for getting us into this mess in the first place from doing so again. NP: This Will Destroy You: Young Mountain

14 October 2008

Patrick Schoenfeld: Extending Debian with customizable packages

In my previous post I drafted a rough idea how to add a feature to Debian that would bridge the gap between Debian as a Binary Distribution and any Source Distribution. The feature in question is giving users the chance to build customized Debian packages for specific feature sets. The possible use cases are simple:

Lets say Anthony User needs super-duper-tool with postgresql support. However this is a not so common use case and so the archive only has postgresql support. If he now wants to build a custom package, the process is "as simple" as:

apt-get source super-duper-tool
cd super-duper-tool-*
apt-get build-dep super-duper-tool OR sudo mk-build-deps -r -i
(possibly try out which ./configure options are supported by super-duper-tool)
vi debian/rules
edit debian/rules
dpkg-buildpackage -us -uc
sudo debi

That is, to be honest lot of work. And the biggest problem about it is that you need to know all this, which is not really user knowledge.

The basic idea is that Anthony can do something like
export DEB_BUILD_OPTIONS=nomysql,postgresql
deb-build-tool build super-duper-tool

and is done.
So the question is how could this be achieved?

  1. Define a set of common options (options should be consistent through all source packages, otherwise it makes not that much sense) that every package should support, if it is a supported feature by the package in question. This includes flags like mysql, postgresql, ldap and its no-equivalents (nomysql, nopostgresql) to negate it.
  2. Enable use of this common options in the package build process and that is really the hardest part. Defining a lot of ifneq..findstring constructs for 2-10 options per source package in any available source package is.... not.... a good approach. Luckily a lot of packages uses autoconf where enabling and disabling features is as easy as adding a --with-foo or --enable-foo option to the ./configure parameters. So we could write a wrapper that would handle these options. The debhelper scripts already have dh_auto_configure: Maybe this could get enhanced.
  3. If it does not exist: Write a tool to auto-build packages with DEB_BUILD_OPTIONS set by the user. Should automatically get the source, (optional: setup/update a pbuilder environment) and build it and optional install/upload it (to a user repository for example) .
Still, the idea is only a rough draft. There are still a lot of open questions/issues, for example:
Is anybody interested in pushing this idea forward? I'm happily interested in it and I know people who like the idea, too. But I can't push this forward on my own all alone. Certainly the work won't affect Lenny anymore, but considerable the time frame that is planned for Lenny+1 by the release team, this could be a feature for Lenny+1.

13 October 2008

Francois Marier: mutt's OpenPGP support and FireGPG

mutt has excellent OpenPGP and GPG support. However different clients send GnuPG encrypted/signed data in different ways. Lots of people seem to be using FireGPG these days so that they can use GnuPG within the GMail/Hotmail/Yahoo! web clients.

Here's the procmail rule I used to convert almost all incoming emails to the OpenPGP/MIME format:
:0
* !^Content-Type: multipart/
* !^Content-Type: application/pgp

:0 fBw
* ^-----BEGIN PGP MESSAGE-----
* ^-----END PGP MESSAGE-----
formail \
-i "Content-Type: application/pgp; format=text; x-action=encrypt"

:0 fBw
* ^-----BEGIN PGP SIGNED MESSAGE-----
* ^-----BEGIN PGP SIGNATURE-----
* ^-----END PGP SIGNATURE-----
formail \
-i "Content-Type: application/pgp; format=text; x-action=sign"
However, this didn't actually work with FireGPG and the way that it puts encrypted messages inline. I eventually found out that putting this in my ~/.muttrc would fix it:
set pgp_auto_decode=yes

MJ Ray: Report on Listening to the Social Entrepreneur

Last Thursday, I was at a conference called Listening to the Social Entrepreneur. Here are some short notes about the plenary session, which were written at the time, along with thoughts on the workshops that I’ve just written up. HCT Group - credit crunch opportunity - business with ethics - transport - dislike 3rd sector term - difference between social enterprise and charity - optimism. Haley House - ex-soup kitchen staffed by ex-homeless, bakery, bank donated equipment, financial picture - catering grew 36% cafe grew 21% september, cooking classes; recipe for success: collaborate with experienced partner, secure enough capital or equivalent, align venture with mission; plan for sustainability; future… Roskilde university - relevance of academic research - why references for things I know - hard to have your feelings discussed. (meeting last Monday?) - don’t care what it’s called - too much jargon - several ways of learning, conceptual doesn’t seem useful but will later. CICs. Four flags of SEs - eship, er, e, econ. Bikeworks - practitioner and academic. Formation, setup, establishment, sustain. SE changes; viewpoint: academic, researchers, help us. Useless website. Then came three workshops of varying usefulness: Procurement Versus Marketplace was an interesting idea and reminded me why I avoided public-sector projects for years: I’m better at negotiated than at rules-based selling. I also was told (with a straight face) by a development trust worker that cooperatives are simply profit-sharing schemes, which was very disappointing. Social verses Business Goals seemed pretty ill-conceived. The reason why many people work in social enterprises is because we don’t believe we should choose between them. It’s an integrated, multi-faceted approach. Born or Made? was an interesting examination of the people powering social enterprises. Food for thought, but I’m not sure it really produced much. But I’m not that sure whether any of the workshops had much of a productive purpose. The final plenary session was confusing. I was sat further back, the sound system was intermittent and echoy and the talks seemed truncated and still, but maybe I was just tired. A lot of people had left by this point. I stayed on for the networking reception and met a few interesting people, but left earlyish to meet another TTLLP member on the light railway. The venue was OK (I think the main hall problems were more sound system and operation than the hall itself) and coffee, lunch and reception were well-catered. In conclusion, it was an interesting conference, but I don’t feel that we got much out of it, apart from some thoughts from a workshop session. I suspect it was more useful for the researchers than for the entrepreneurs. There weren’t many opportunities for professional development or sales or even putting things into consultations or . I’m not sure I’d spend best part of two days work (attending plus travel plus costs) on another similar event.

Patrick Schoenfeld: Re: Gentoo destroying earth?

I fully agree that working with Gentoo is no fun at all, as Julian points out in his post
My impression, when I tried Gentoo for the first (and last) time is the same. Thats not because it is made bad. In fact things in Gentoo aren't made that bad. There is good documentation, portage is quiet nice (with its USE flags and alike), but in the end I'm not really satisfied.
After all Gentoo uses a copied concept, which itself is good. The concept is derived from the BSD-world and is just the concept of source-based systems. This concept has its advantages over binary distributions, because it allows a flexibility that is not really possible with a binary distribution. That really is the only appreciable advantage of these systems. Users of these systems (including FreeBSD and alike) tend to give other arguments as well: Newest Software, Highest Performance and even Security is a point they give.

Usually the "newest software" argument is brought up with a rant against Debian. I keep hearing statements like "Debian Etch is totally outdated and Testing is broken". That statement in itself is just wrong, but the important thing is: What do you need such new software for? On a server its preferrable not to upgrade to each and every major release, for certain reasons. Its also a bad thing to build on production systems, so you need to take further measures to administer systems like that. On a desktop I can understand the logic, but then again: No. Why would I want a system I have to compile from scratch and on each upgrade (wasting a lot of time, power etc.) which changes often?

The performance argument is the dumbest of all. Binary distributions usually build binaries for various platforms. And while they can't be optimized for a very specific processor or a very specific feature set (=reduces binary size) they usually perform well enough that a difference between the self-compiled Gentoo system and a foreign-compiled Debian is not noticed by the user and sometimes not even measurable. So the time you save during the lifetime of your builds (which is not very long on a Desktop, is it?) because of the enhanced performance is used up a hundred times, by the time you waste for compiling the whole software only for yourself. Even if some of the software performs noticable better (e.g. video processing is said to benefit a lot from an optimized platform).

What about the security argument? It has been said, that you get your updates earlier then users of binary distributions. That is partly true, because in a binary distribution the update needs to be built first, before it gets to the end user (however, everything before is the same for a binary or a source distribution). But do you really follow security issues that close, that you benefit a lot from this? If you do, indeed, you save some hours. If (and only if) both distributions have a solution for a security issue at the same time.

Anyway. The flexibility argument can't get discussed away. Its the argument that makes Ports in BSD-systems attractive. You can have exactly the features you want, with the build-time options you want. In a comfortable manner. That is in contrast to binary distributions where we package developers need to guess which features might be needed (/wanted) by the users with mixed results. Good if they can decide for themselves. Still, I don't see the reason for compiling the whole system, if I need one or two customized components. So I go with Debian and customize packages if I really need/want to. The only difference is that it takes a lot of more effort.

I would love to see something done in Debian to reach a compromise. Making rebuilding of packages with different options very comfortable. We have DEB_BUILD_OPTIONS, maybe we should enhance it to support a lot more options then noopt,nostrip or nodoc. Possibly it would be a good thing to standardize on some use flags (e.g. [no]ssl, [no]ldap, etc.) and support them in the debian/rules file. This way building customized packages would be as easy as setting sensible DEB_BUILD_OPTIONS and run dpkg-buildpackage on the source. This could be eased further by providing a tool to download the source and build a given package (IIRC such a tool already exists). How does that sound?

9 October 2008

Adeodato Sim : The game of unblocking

Rules: (ObQuote: “In every job that must be done, there is an element of fun. You find the fun and... snap, the job’s a game!”)

5 October 2008

Matthew Palmer: The Healing Power of Hate

They say that there's very little difference between love and hate. A good example of this is the Linux Hater's Blog. It's written by someone who obviously has a lot of experience with Linux and Open Source, and I get the feeling that the hate comes of frustration and pain. Certainly, I've seen plenty of similarly themed articles coming out of Planet Debian at one time or another. One of the best articles I've found yet is One bug report to rule them all, a humourous but altogether painfully accurate rendition of far too many bug reports I've seen and dealt with of the years.

2 October 2008

Russell Coker: How Many Singularities?

There is a lot of discussion and speculation about The Singularity. The term seems to be defined by Ray Kurzweil’s book “The Singularity Is Near” [1] which focuses on a near-future technological singularity defined by significant increases in medical science (life extension and methods to increase mental capacity) and an accelerating rate of scientific advance. In popular culture the idea that there will only be one singularity seems to be well accepted, so the discussion is based on when it will happen. One of the definitions for a singularity is that it is a set of events that change society in significant ways such that predictions are impossible - based on the concept of the Gravitational Singularity (black hole) [2]. Science fiction abounds with stories about what happens after someone enters a black hole, so the concept of a singularity not being a single event (sic) is not unknown, but it seems to me that based on our knowledge of science no-one considers there to be a black hole with multiple singularities - not even when confusing the event horizon with the singularity. If we consider a singularity to merely consist of a significant technological change (or set of changes) that change society in ways that could not have been predicted (not merely changes that were not predicted) then it seems that there have been several already, here are the ones that seem to be likely candidates: 0) The development of speech was a significant change for our species (and a significant change OF our species). Maybe we should consider that to be singularity 0 as hominids that can’t speak probably can’t be considered human. 1) The adoption of significant tool use and training children in making and using tools (as opposed to just letting them learn by observation) made a significant change to human society. I don’t think that with the knowledge available to bands of humans without tools it would have been possible to imagine that making stone axes and spears would enable them to dominate the environment and immediately become the top of the food chain. In fact as pre-tool hominids were generally not near the top of the food chain they probably would have had difficulty imagining being rulers of the world. I’m sure that it led to an immediate arms race too. 2) The development of agriculture was a significant change to society that seems to have greatly exceeded the expectations that anyone could have had at the time. I’m sure that people started farming as merely a way of ensuring that the next time they migrated to an area there was food available (just sowing seeds along traditional migration routes for a hunter-gatherer existence). They could not have expected that the result would be a significant increase in the ability to support children and a significant increase in the number of people who could be sustained by a given land area, massive population growth, new political structures to deal with greater population density, and then wiping out hunter-gatherer societies in surrounding regions. It seems likely to me that the mental processes needed to predict the actions of a domestic animal (in terms of making it a friend, worker, or docile source of food) differ from those needed to predict the actions of other humans (who’s mental processes are similar) and from those needed to predict the actions of prey that is being hunted (you only need to understand enough to kill it). 3) The invention of writing allowed the creation of larger empires through better administration. All manner of scientific and political development was permitted by writing. 4) The work of Louis Pasteur sparked a significant development in biology which led to much greater medical technology [3]. This permitted much greater population densities (both in cities and in armies) without the the limitation of significant disease problems. It seems that among other things the world-wars depended on developments in preventing disease which were linked to Louis’ work. Large populations densely congregated in urban areas permit larger universities and a better exchange of knowledge which permitted further significant developments in technology. It seems unlikely that a population suffering the health problems that were common in 1850 could have simultaneously supported large-scale industrial warfare and major research projects such as the Manhattan Project. 5) The latest significant change in society has been the development of the Internet and mobile phones. Mobile phones were fairly obvious in concept, but have made structural changes to society. For example I doubt that hand-writing is going to be needed to any great extent in the future [4], the traditional letter has disappeared, and “Dates” are now based on “I’ll call your mobile when I’m in the area” instead of meeting at a precise time - but this is the trivial stuff. Scientific development and education have dramatically increased due to using the Internet and business now moves a lot faster due to mobile phones. It seems that nowadays any young person who doesn’t want to be single and unemployed needs to have either a mobile phone or Internet access - and preferably both. When mobile phones were first released I never expected that almost everyone would feel compelled to have one, and when I first started using the Internet in 1992 I never expected it to have the rich collaborative environment of Wikipedia, blogging, social networking, etc (I didn’t imagine anything much more advanced than file exchange and email). Of these changes the latest (Internet and mobile phones) seems at first glance to be the least significant - but let’s not forget that it’s still an ongoing process. The other changes became standard parts of society long ago. So it seems that we could count as many as six singularities, but it seems that even the most conservative count would have three singularities (tool use, agriculture, and writing). It seems to me that the major factors for a singularity are an increased population density (through couples being able to support more children, through medical technology extending the life expectancy, through greater food supplies permitting more people to live in an area, or through social structures which manage the disputes that arise when there is a great population density) and increased mental abilities (which includes better education and communication). Research into education methods is continuing, so even without genetically modified humans, surgically connecting computers to human brains, or AI we can expect intelligent beings with a significant incremental advance over current humans in the near future. Communications technology is continually being improved, with some significant advances in the user-interfaces. Even if we don’t get surgically attached communications devices giving something similar to “telepathy” (which is not far from current technology), there are possibilities for significant increments in communication ability through 3D video-conferencing, better time management of communication (inappropriate instant communication destroys productivity), and increased communication skills (they really should replace some of the time-filler subjects at high-school with something useful like how to write effective diagrams). It seems to me that going from the current situation of something significantly less than one billion people with current (poor) education and limited communications access (which most people don’t know how to use properly) to six billion people with devices that are more user-friendly and powerful than today’s computers and mobile phones combined with better education as to how to use them has the potential to increase the overall rate of scientific development by more than an order of magnitude. This in itself might comprise a singularity depending on the criteria you use to assess it. Of course that would take at least a generation to implement, a significant advance in medical technology or AI could bring about a singularity much sooner. But I feel safe in predicting that people who expect the world to remain as it is forever will be proven wrong yet again, and I also feel safe in predicting that most of them will still be alive to see it. I believe that we will have a technological singularity (which will be nothing like the “rapture” which was invented by some of the most imaginative interpretations of the bible). I don’t believe that it will be the final singularity unless we happen to make our species extinct (in which case there will most likely be another species to take over the Earth and have it’s own singularities).

1 October 2008

Dirk Eddelbuettel: Berlin Marathon 2008

Last Sunday was the 35th Berlin Marathon. I had flown over to Berlin on Thursday after work, and had Friday and Saturday to 'chill'. The weather was already pretty nice before the race, and truly gorgeous on Sunday: sunny yet not too warm, blue skies, no wind. As has been widely reported, Haile Gebrselassie set a new world record breaking his own mark set the year before and becoming the first man to finish under two hours and four minutes. Truly impressive. My race was pretty good too. I shaved over four and a half minutes off my own personal record (which was set in early 2006 at Sunburst) and finished in 3:13:09. That's a pace of 7:22 min/mile (or 4:35 min/km) which I am rather happy with. I held a fairly steady pace of under 7:30 almost all the way but but had to fight off the onset of cramps with some short walks about less than two miles to go. Coming back in Berlin after all those years is always a charm. The city has obviously changed a lot in some very visible areas. Yet it still recalls the Berlin of those years. The course was really nice, covering numerous neighbourhoods and starting and ending in Tiergarten. Lastly, it was also good to see old friends who have now been there since the mid- to late 1980s. And I managed to pack a quick visit to my parents in as they are just a good 80 minute ICE train ride away. All in all a very nice trip even though the travel from Chicago (without a direct flight!) is a bit of a hike.

Ross Burton: Translation Nightmare

I just got a new bug titled Very weird translation template, need comments in .pot file to clarify, and giggled to myself. I was wondering how long it would be for this bug to be filed. The problem is that whilst most of the translatable strings in Tasks are pretty boring: "Tasks", "today", "Priority" and so on, all of a sudden the template goes a bit mental:
"^(?<task>.+) (?:by due on)? (?<month>\\w+) (?<day>\\d 1,2 )(?:st nd rd th)?$"
Apparently the average translator doesn't think that learning PCRE-style regular expressions, and reading the source that uses this string to understand how it is to be used, is appropriate. [note: this is sarcasm] Maybe I should have added some translator comments to clarify exactly what I meant by this. These monster strings (all in koto-date-parser.c) are GRegex regular expressions which are used to parse the user's input to try and extract meaningful date information. To translate these strings you'll need to have a basic understanding of regular expressions: if you don't then skip them and hopefully someone who does will finish the translation. If you know regular expressions then translating these strings is easy, honest. The golden rule is to never translate the words which look like this: (?<foo>. These are markers which identify portions of the input (such as task or month) and need to remain in English, although they can be moved around if required. The rest of the strings are translatable. I'll give an example using the French translation by Stéphane Raimbault. First, the string in English and a worked example:
"^(?<task>.+) (?:by due on)? (?<day>\\d 1,2 )(?:st nd rd th)? (?<month>\\w+)$"
First, we have a sequence of any characters identified as task, which magically expands to be as many as possible. This is optionally followed by one of the words "by", "due" or "on". This is followed by one or two digits identified as day followed by "st", "nd", "rd" or "th". Finally a sequence of characters which is identified as month. If the user had entered "pay bills on 2nd june" then task would be "pay bills", day would be "2", and month would be "june". Tasks can then turn "june" into a month number through other translations, and it now knows what date the user entered. In French, this translates as follows:
"^(?<task>.+) (?:pour pr vu pour le)? (?<day>\\d 1,2 )(?:er e)? (?<month>\\w+)$"
See, I said it was easy! All I need now is a legion of translators who understand regular expressions enough to correctly translate the new Tasks... [this, again, is sarcasm] Luckily, plans are afoot to move the Tasks source to the GNOME Subversion server, so the full fury of the GNOME translation team can attack this. NP: Trailer Park, Beth Orton

30 September 2008

Russell Coker: Links September 2008

RAM is the new Disk [1] - interesting post about using a distributed network of servers with RAM for main storage. The concept is that RAM on another machine can be accessed faster than local disk and that disk performance for contiguous IO has been increasing steadily at a greater rate than random seek performance. So disks can be used in a similar manner to tape drives (backing up data) and RAM can be used as main storage (2RU machines with 1TB of RAM are predicted soon). It is interesting to contrast this with the Rubik’s Cube solver which uses disk as RAM [2]. Interesting Sun Blog post about how ZFS uses flash based SSD (Solid State Disk) for read caching [3]. Yahoo has released a Firefox plugin named Yslow to tell you why your web site is slow [4]. This complements the Yahoo Best Practices for Speeding Up Your Web Site document [5]. Amsterdam now has cargo trams [6]. This reduces pollution and traffic congestion while allowing efficient transport of cargo. The cargo trams tend to follow passenger trams so they don’t provide any additional obstacle to traffic. Interesting article by Cory Doctorow about how the standard formats limit creative content [7]. He makes the unfortunate mistake of claiming that “no one tries to make sitcoms about stories that take five minutes to tell” and “no one tries to make feature films about subjects that take 30 seconds to elucidate” - I think that the majority of sitcom episodes can be described in considerably less than 5 minutes and a significant number of movies (EG every one that stars Jean-Claude Van Damme [8]) can have their plot described in less than 30 seconds.

Next.

Previous.