Search Results: "will"

18 June 2021

Enrico Zini: Playbooks, host vars, group vars

This is part of a series of posts on ideas for an ansible-like provisioning system, implemented in Transilience. Host variables Ansible allows to specify per-host variables, and I like that. Let's try to model a host as a dataclass:
@dataclass
class Host:
    """
    A host to be provisioned.
    """
    name: str
    type: str = "Mitogen"
    args: Dict[str, Any] = field(default_factory=dict)
    def _make_system(self) -> System:
        cls = getattr(transilience.system, self.type)
        return cls(self.name, **self.args)
This should have enough information to create a connection to the host, and can be subclassed to add host-specific dataclass fields. Host variables can then be provided as default constructor arguments when instantiating Roles:
    # Add host/group variables to role constructor args
    host_fields =  f.name: f for f in fields(host) 
    for field in fields(role_cls):
        if field.name in host_fields:
            role_kwargs.setdefault(field.name, getattr(host, field.name))
    role = role_cls(**role_kwargs)
Group variables It looks like I can model groups and group variables by using dataclasses as mixins:
@dataclass
class Webserver:
    server_name: str = "www.example.org"
@dataclass
class Srv1(Webserver):
    ...
Doing things like filtering all hosts that are members of a given group can be done with a simple isinstance or issubclass test. Playbooks So far Transilience is executing on one host at a time, and Ansible can execute on a whole host inventory. Since the most part of running a playbook is I/O bound, we can parallelize hosts using threads, without worrying too much about the performance impact of GIL. Let's introduce a Playbook class as the main entry point for a playbook:
class Playbook:
    def setup_logging(self):
        ...
    def make_argparser(self):
        description = inspect.getdoc(self)
        if not description:
            description = "Provision systems"
        parser = argparse.ArgumentParser(description=description)
        parser.add_argument("-v", "--verbose", action="store_true",
                            help="verbose output")
        parser.add_argument("--debug", action="store_true",
                            help="verbose output")
        return parser
    def hosts(self) -> Sequence[Host]:
        """
        Generate a sequence with all the systems on which the playbook needs to run
        """
        return ()
    def start(self, runner: Runner):
        """
        Start the playbook on the given runner.
        This method is called once for each system returned by systems()
        """
        raise NotImplementedError(f" self.__class__.__name__ .start is not implemented")
    def main(self):
        parser = self.make_argparser()
        self.args = parser.parse_args()
        self.setup_logging()
        # Start all the runners in separate threads
        threads = []
        for host in self.hosts():
            runner = Runner(host)
            self.start(runner)
            t = threading.Thread(target=runner.main)
            threads.append(t)
            t.start()
        # Wait for all threads to complete
        for t in threads:
            t.join()
And an actual playbook will now look like something like this:
from dataclasses import dataclass
import sys
from transilience import Playbook, Host
@dataclass
class MyServer(Host):
    srv_root: str = "/srv"
    site_admin: str = "enrico@enricozini.org"
class VPS(Playbook):
    """
    Provision my VPS
    """
    def hosts(self):
        yield MyServer(name="server", args= 
            "method": "ssh",
            "hostname": "host.example.org",
            "username": "root",
         )
    def start(self, runner):
        runner.add_role("fail2ban")
        runner.add_role("prosody")
        runner.add_role(
                "mailserver",
                postmaster="enrico",
                myhostname="mail.example.org",
                aliases= ... )
if __name__ == "__main__":
    sys.exit(VPS().main())
It looks quite straightforward to me, works on any number of hosts, and has a proper command line interface:
./provision  --help
usage: provision [-h] [-v] [--debug]
Provision my VPS
optional arguments:
  -h, --help     show this help message and exit
  -v, --verbose  verbose output
  --debug        verbose output
Next step: check mode!

17 June 2021

Elana Hashman: I'm hosting a Bug Scrub for Kubernetes SIG Node

It's been a long while since I last hosted a BSP, but 'tis the season. Kubernetes SIG Node will be holding a bug scrub on June 24-25, and this is a great opportunity for you to get involved if you're interested in contributing to Kubernetes or SIG Node! We will be hosting a global event with region captains for all timezones. I am one of the NASA captains (~17:00-01:00 UTC) and I'll be leading the kickoff. We will be working on Slack and Zoom. I hope you'll be able to drop in! Details I'm an existing contributor, what should I work on? Work on triaging and closing SIG Node bugs. We have a lot of bugs!! The goal of our event is to categorize, clean up, and resolve some of the 450+ issues in k/k for SIG Node. Check out the event docs for more instructions. I'm a new contributor and want to join but I have no idea what I'm doing! At some point, that was all of us! This is a great opportunity to get involved if you've never contributed to Kubernetes. We'll have dedicated mentors available to coordinate and help out new contributors. If you've never contributed to Kubernetes before, I recommend you check out the Getting Started and Contributor Guide resources in advance of the event. You will want to ensure you've signed the contributor license agreement (CLA). Remember, you don't have to code to make valuable contributions! Triaging the bug tracker is a great example of this. See you there! Happy hacking.

Enrico Zini: Reimagining Ansible variables

This is part of a series of posts on ideas for an ansible-like provisioning system, implemented in Transilience. While experimenting with Transilience, I've been giving some thought about Ansible variables. My gripes I like the possibility to define host and group variables, and I like to have a set of variables that are autodiscovered on the target systems. I do not like to have everything all blended in a big bucket of global variables. Let's try some more prototyping. My fiddlings First, Role classes could become dataclasses, too, and declare the variables and facts that they intend to use (typed, even!):
class Role(role.Role):
    """
    Postfix mail server configuration
    """
    # Postmaster username
    postmaster: str = None
    # Public name of the mail server
    myhostname: str = None
    # Email aliases defined on this mail server
    aliases: Dict[str, str] = field(default_factory=dict)
Using dataclasses.asdict() I immediately gain context variables for rendering Jinja2 templates:
class Role:
    # [...]
    def render_file(self, path: str, **kwargs):
        """
        Render a Jinja2 template from a file, using as context all Role fields,
        plus the given kwargs.
        """
        ctx = asdict(self)
        ctx.update(kwargs)
        return self.template_engine.render_file(path, ctx)
    def render_string(self, template: str, **kwargs):
        """
        Render a Jinja2 template from a string, using as context all Role fields,
        plus the given kwargs.
        """
        ctx = asdict(self)
        ctx.update(kwargs)
        return self.template_engine.render_string(template, ctx)
I can also model results from fact gathering into dataclass members:
# From ansible/module_utils/facts/system/platform.py
@dataclass
class Platform(Facts):
    """
    Facts from the platform module
    """
    ansible_system: Optional[str] = None
    ansible_kernel: Optional[str] = None
    ansible_kernel: Optional[str] = None
    ansible_kernel_version: Optional[str] = None
    ansible_machine: Optional[str] = None
    # [...]
    ansible_userspace_architecture: Optional[str] = None
    ansible_machine_id: Optional[str] = None
    def summary(self):
        return "gather platform facts"
    def run(self, system: transilience.system.System):
        super().run(system)
        # ... collect facts
I like that this way, one can explicitly declare what variables a Facts action will collect, and what variables a Role needs. At this point, I can add machinery to allow a Role to declare what Facts it needs, and automatically have the fields from the Facts class added to the Role class. Then, when facts are gathered, I can make sure that their fields get copied over to the Role classes that use them. In a way, variables become role-scoped, and Facts subclasses can be used like some kind of Role mixin, that contributes only field members:
# Postfix mail server configuration
@role.with_facts([actions.facts.Platform])
class Role(role.Role):
    # Postmaster username
    postmaster: str = None
    # Public name of the mail server
    myhostname: str = None
    # Email aliases defined on this mail server
    aliases: Dict[str, str] = field(default_factory=dict)
    # All fields from actions.facts.Platform are inherited here!
    def have_facts(self, facts):
        # self.ansible_domain comes from actions.facts.Platform
        self.add(builtin.command(
            argv=["certbot", "certonly", "-d", f"mail. self.ansible_domain ", "-n", "--apache"],
            creates=f"/etc/letsencrypt/live/mail. self.ansible_domain /fullchain.pem"
        ), name="obtain mail.* certificate")
        # the template context will have the Role variables, plus the variables
        # of all the Facts the Role uses
        with self.notify(ReloadPostfix):
            self.add(builtin.copy(
                dest="/etc/postfix/main.cf",
                content=self.render_file("roles/mailserver/templates/main.cf"),
            ), name="configure /etc/postfix/main.cf")
One can also fill in variables when instantiating Roles, making parameterized generic Roles possible and easy:
    runner.add_role(
            "mailserver",
            postmaster="enrico",
            myhostname="mail.enricozini.org",
            aliases= 
                "me": "enrico",
             ,
    )
Outcomes I like where this is going: having well defined variables for facts and roles, means that the variables that get into play can be explicitly defined, well known, and documented. I think this design lends itself quite well to role reuse: I have a feeling that, this way, it may be much easier to create generic libraries of Roles that one can reuse to compose complex playbooks. Since roles are just Python modules, we even already know how to package and distribute them! Next step: Playbooks, host vars, group vars.

Raphaël Hertzog: Submit your ideas for Debian and +1 those that you find important

A while ago, I got a request from Kentaro Hayashi on the project I use to manage funding requests addressed to Freexian. He was keen to see some improvements on the way reimbursement requests are handled in Debian. In my opinion, the idea is certainly good but he s not part of the treasurer team and was not willing to implement the project either, so it was not really ready to be submitted to us. To be able to fund a useful project, we need either someone that is willing to do the work and try to push it further in Debian, or we need a Debian team interested in the result of the project (and in that case, we can try to find someone willing to implement the project). In this case, it s a bit sad that the treasurer team didn t comment at all but in general, what should we do with those suggestions ? It would still be interesting to have a list of such suggestions and have Debian developers be able to advocate (+1) those suggestions. It s in this spirit that Kentaro created the Grow your ideas project on salsa.debian.org. Browse the list of issues, submit your own and click on  (+1) to bump the suggestions that you find interesting. And click on the Watch button on the homepage to receive notifications when others submit suggestions so that you can evaluate those suggestions and possibly improve them through your comments. In the end, this can only help those that are looking for ways to contribute to Debian: maybe some of them will formalize a concrete action plan and request funding for it! We have a pile of money sitting unused that s clearly targeted to pay contributors to improve our infrastructure. And we have endless lists of (wishlist) bugs on all our infrastructure projects (dak, distro-tracker, ). What are you waiting ?

Joey Hess: typed pipes in every shell

Powershell and nushell take unix piping beyond raw streams of text to structured or typed data. Is it possible to keep a traditional shell like bash and still get typed pipes? I think it is possible, and I'm now surprised noone seems to have done it yet. This is a fairly detailed design for how to do it. I've not implemented it yet. RFC. Let's start with a command called typed. You can use it in a pipeline like this:
typed foo   typed bar   typed baz
What typed does is discover the types of the commands to its left and its right, while communicating the type of the command it runs back to them. Then it checks if the types match, and runs the command, communicating the type information to it. Pipes are unidirectional, so it may seem hard to discover the type to the right, but I'll explain how it can be done in a minute. Now suppose that foo generates json, and bar filters structured data of a variety of types, and baz consumes csv and pretty-prints a table. Then bar will be informed that its input is supposed to be json, and that its output should be csv. If bar didn't support json, typed foo and typed bar would both fail with a type error. Writing "typed" in front of everything is annoying. But it can be made a shell alias like "t". It also possible to wrap programs using typed:
cat >~/bin/foo <<EOF
#/usr/bin/typed /usr/bin/foo
EOF
Or program could import a library that uses typed, so it natively supports being used in typed pipelines. I'll explain one way to make such a library later on, once some more details are clear. Which gets us back to a nice simple pipeline, now automatically typed.
foo   bar   baz
If one of the commands is not actually typed, the other ones in the pipe will treat it as having a raw stream of text as input or output. Which will sometimes result in a type error (yay, I love type errors!), but in other cases can do something useful.
find   bar   baz
# type error, bar expected json or csv
foo   bar   less
# less displays csv 
So how does typed discover the types of the commands to the left and right? That's the hard part. It has to start by finding the pids to its left and right. There is no really good way to do that, but on Linux, it can be done: Look at what /proc/self/fd/0 and /proc/self/fd/1 link to, which contains the unique identifiers of the pipes. Then look at other processes' fd/0 and fd/1 to find matching pipe identifiers. (It's also possible to do this on OSX, I believe. I don't know about BSDs.) Searching through all processes would be a bit expensive (around 15 ms with an average number of processes), but there's a nice optimisation: The shell will have started the processes close together in time, so the pids are probably nearby. So look at the previous pid, and the next pid, and fan outward. Also, check isatty to detect the beginning and end of the pipeline and avoid scanning all the processes in those cases. To indicate the type of the command it will run, typed simply opens a file with an extension of ".typed". The file can be located anywhere, and can be an already existing file, or can be created as needed (eg in /run). Once it discovers the pid at the other end of a pipe, typed first looks at /proc/$pid/cmdline to see if it's also running typed. If it is, it looks at its open file handles to find the first ".typed" file. It may need to wait for the file handle to get opened, which is why it needs to verify the pid is running typed. There also needs to be a way for typed to learn the type of the command it will run. Reading /usr/share/typed/$command.typed is one way. Or it can be specified at the command line, which is useful for wrapper scripts:
cat >~/bin/bar <<EOF
#/usr/bin/typed --type="JSON   CSV" --output-type="JSON   CSV" /usr/bin/bar
EOF
And typed communicates the type information to the command that it runs. This way a command like bar can know what format its input should be in, and what format to use as output. This might be done with environment variables, eg INPUT_TYPE=JSON and OUTPUT_TYPE=CSV I think that's everything typed needs, except for the syntax of types and how the type checking works. Which I should probably not try to think up off the cuff. I used Haskell ADT syntax in the example above, but don't think that's necessarily the right choice. Finally, here's how to make a library that lets a program natively support being used in a typed pipeline. It's a bit tricky, because it has to run typed, because typed checks /proc/$pid/cmdline as detailed above. So, check an environment variable. When not set yet, set it, and exec typed, passing it the path to the program, which it will re-exec. This should be done before program does anything else.
This work was sponsored by Mark Reidenbach on Patreon.

16 June 2021

Julien Danjou: Python Tools to Try in 2021

Python Tools to Try in 2021The Python programming language is one of the most popular and in huge demand. It is free, has a large community, is intended for the development of projects of varying complexity, is easy to learn, and opens up great opportunities for programmers. To work comfortably with it, you need special Python tools, which are able to simplify your work. We have selected the best Python tools that will be relevant in 2021.

MailtrapAs you may probably know, in order to send an email, you need SMTP (Simple Mail Transfer Protocol). This is because you can't just send a letter to the recipient. It needs to be sent to the server from which the recipient will download this letter using IMAP and POP3.Mailtrap provides an opportunity to send emails in python. Moreover, Mailtrap provides #rest #api to access current emails. It can be used to automate email testing, which will improve your email marketing campaigns. For example, you can check the password recovery form in the Selenium Test and immediately see if an email was sent to the correct address. Then take a new password from the email and try to enter the site with it. Cool, isn't it?

Pros
  • All emails are in one place.
  • Mailtrap provides multiple inboxes.
  • Shared access is present.
  • It is easy to set up.
  • RESTful API

ConsNo visible disadvantages were found.

Django
Python Tools to Try in 2021
Django is a free and open-source full-stack framework. It is one of the most important and popular among Python developers. It helps you move from a prototype to a ready-made working solution in a short time since its main task is to automate processes and speed up work through associations and libraries. It s a great choice for a product launch.You can use Django if at least a few of the following points interest you:
  • There is a need to develop the server-side of the API.
  • You need to develop a web application.
  • In the course of work, many changes are made, you have to constantly deploy the application and make edits.
  • There are many complex tasks that are difficult to solve on your own, and you will need the help of the community.
  • ORM support is needed to avoid accessing the database directly.
  • There is a need to integrate new technologies such as machine learning.
Django is a great Python Web Framework that does its job. It is not for nothing that it is one of the most popular, and is actively used by millions of developers.

ProsDjango has quite a few advantages. It contains a large number of ready-made solutions, which greatly simplifies development. Admin panel, database migration, various forms, user authentication tools are extremely helpful. The structure is very clear and simple.A large community helps to solve almost any problem. Thanks to ORM, there is a high level of security and it is comfortable to work with databases.

ConsDespite its powerful capabilities, Django's Python Web Framework has drawbacks. It is very massive, monolithic, therefore it develops slowly. Despite the many generic modules, the development speed of Django itself is reduced.

CherryPy
Python Tools to Try in 2021
CherryPy is a micro-framework. It is designed to solve specific problems, capable of running the program on any operating system. CherryPy is used in the following cases:
  • To create an application with small code size.
  • There is a need to manage several servers at the same time.
  • You need to monitor the performance of applications.
CherryPy refers to Python Frameworks, which are designed for specific tasks. It's clear, user-friendly, and ideal for Android development.

ProsCherryPy Python tool has a friendly and understandable development environment. This is a functional and complete framework, which can be used to build good applications. The source code is open, so the platform is completely free for developers, and the community, although not too large, is very responsive, and always helps to solve problems.

ConsThere are not so many cons to this Python tool. It is not capable of performing complex tasks and functions, it is intended more for specific solutions, for example, for the development of certain plugins or modules.

Pyramid
Python Tools to Try in 2021
Python Pyramid tool is designed for programming complex objects and solving multifunctional problems. It is used by professional programmers and is traditionally used for identification and routing. It is aimed at a wide audience and is capable of developing API prototypes.It is used in the following cases:
  • You need problem indicator tools to make timely adjustments and edits.
  • You use several programming languages at once;
  • You work with reporting and financial calculations, forecasting;
  • You need to quickly create a simple application.
At the same time, the Python Web Framework Pyramid allows you to create complex applications with great functionality like a translation software.

ProsPyramid does an excellent job of developing basic applications quickly. It is quite flexible and easy to learn. In fact, the key to the success of this framework is that it is completely based on fundamental principles, using simple and basic programming techniques. It is minimalistic, but at the same time offers users a lot of freedom of action. It is able to work with both small applications and powerful multifunctional programs.

ConsIt is difficult to deviate from the basic principles. This Python tool makes the decision for you. Simple programs are very easy to implement. But to do something complex and large-scale, you have to completely immerse yourself in the study of the environment and obey it.

Grok
Python Tools to Try in 2021
Grok is a Python tool that works with templates. Its main task is to eliminate repetitions in the code. If the element is repeated, then the template that was already created earlier is simply applied. This greatly simplifies and speeds up the work.Grok suits developers in the following cases:
  • If a programmer has little experience and is not yet ready to develop his modules.
  • There is a need to quickly develop a simple application.
  • The functionality of the application is simple, straightforward, and the interface does not play a key role.

ProsThe Grok framework is a child of Zope3, which was released earlier. It has a simplified structure of work, easy installation of modules, more capabilities, and better flexibility. It is designed to develop small applications. Yes, it is not intended for complex work, but due to its functionality, it allows you to quickly implement a project.

ConsThe Grok community is not very large, as this Python tool has not gained widespread popularity. Nevertheless, it is used by Python adepts for comfortable development. It is impossible to implement complex tasks on it since the possibilities are quite limited.Grok is one of the best Python Web Frameworks. It is understandable and has enough features for comfortable development.

Web2Py
Python Tools to Try in 2021
Web2Py is a Python tool that has its own IDEwhich, which includes a code editor, debugger, and deployment. It works great without the need for configuration or installation, provides a high level of data security, and is suitable for work on various platforms.Web2Py is great in the following cases:
  • When there is a need to develop something on different operating systems.
  • If there is no way to install and configure the framework.
  • When a high level of data security is required, for example, when developing financial applications or sales performance management tools.
  • If you need to carefully track bugs right during development, and not during the testing phase.

ProsWeb2Py is capable of working with different protocols, has a built-in error tracker, and has a backward compatibility feature that helps to work on the basis of previous versions of the framework. This means that code maintenance becomes much easier and cheaper. It's free, open-source, and very flexible.

ConsAmong the many Python tools, there are not many that require the latest version of the language. Web2Py is one of those and won't work on Python 3 and below. Therefore, you need to constantly monitor the updates.Web2Py does an excellent job of its tasks. It is quite simple and accessible to everyone.

BlueBream
Python Tools to Try in 2021
BlueBream used to be called Zope3 before. It copes well with tasks of the medium and high level of complexity and is suitable for working on serious projects.

ProsThe BlueBream build system is quite powerful and suitable for complex tasks. You can create functional applications on it, and the principle of reuse of components makes the code easier. At the same time, the speed of development increases. The software can be scaled, and a transactional object database provides an easy path to store it. This means that queries are processed quickly and database management is simple.

ConsThis is not a very flexible framework, it is better to know clearly in advance what is required of it. In addition, it cannot withstand heavy loads. When working with 1000 users at the same time, it can crash and give errors. Therefore, it should be used to solve narrow problems.Python frameworks are often designed for specific tasks. BlueBream is one of these and is suitable for applications where database management plays a key role.

ConclusionPython tools come in different forms and have vastly different capabilities. There are quite a few of them, but in 2021 these will be the most popular and in demand. Experienced programmers always choose several development tools for their comfortable work.

Abhijith PA: Changing LCD screen of car infotainment system

I have a 2013 model used car that I bought two years ago. It came with a 7 inch touch screen infotainment system on its dash board with features like navigation, Bluetooth phone connectivity and a good FM AM radio. Except the radio I rarely use navigation or Bluetooth phone sync. After couple of months the touch started to become non-responsive. Since all important things such as call termination, mute and volume control have physical switches, I was happy with it. During a periodic car check up on a local workshop, mechanic pulled battery terminals making the infotainment system locked. Now it ask for 4 digit pass code. Its one of their ant-theft mechanism and in order to enter those digits you need a touch responsive screen. So now I am completed locked out. I visited service center of this car to get it changed, turns out they don t repair it and only change by the unit. And will cost me Rs 50,000. Considering my usage is restricted to radio. That price is way too much. So my next options were,
  1. Use a normal cheap car radio player. I dropped this plan, since stereo players comes in very small size and I might need plastic placeholders to close rest of the area from the 7 inch screen. This can mess aesthetics of dash board. And it also affect value of the car if I will sell in future.
  2. Use a 7 inch third party infotainment system available in the market. I did enquired with local car accessories shop and I dropped this plan as well because most of them are android and comes with enormous number of pre installed apps which I never gonna use it anyway. And I don t need one more device that need to be connected to the Internet. Also the wiring at the back of these devices are different than what I have already so it need rewiring.
  3. Last option was to change the infotainment system parts my own. I was under the impression that these units are in-house made, tightly assembled and sealed with screws that you never see in your life and you will never able to be open it up, let alone fix parts.
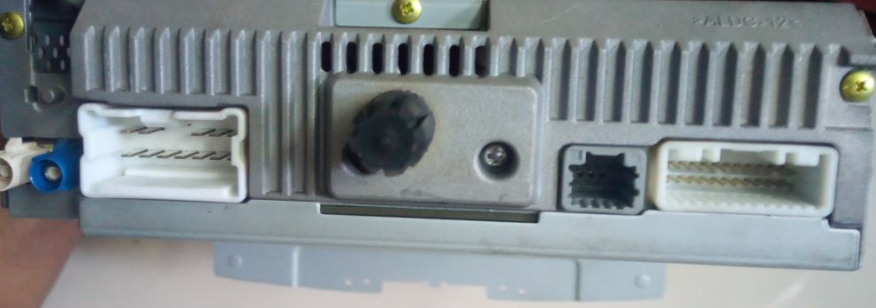
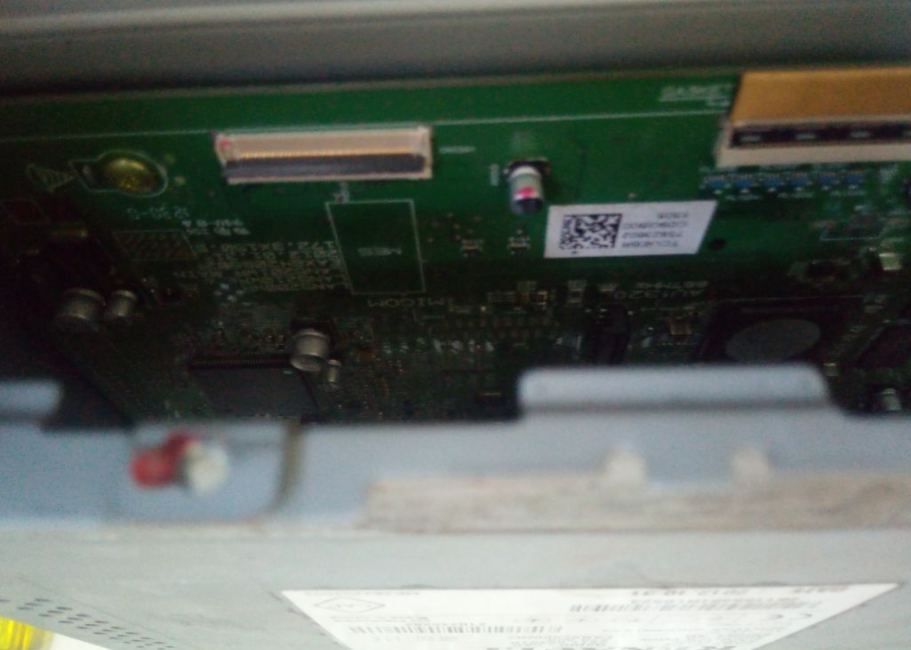
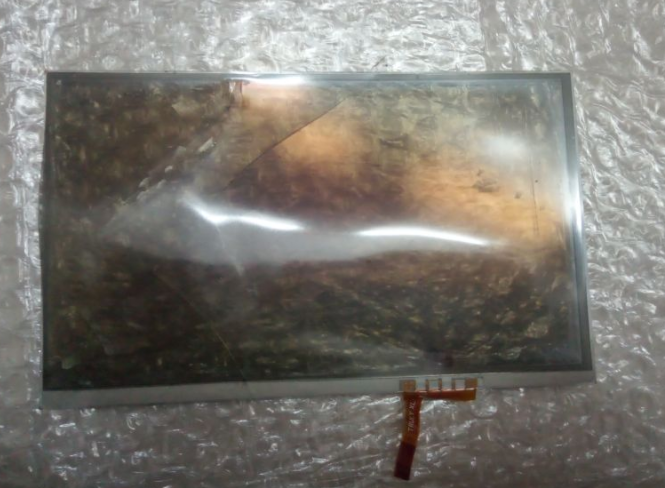
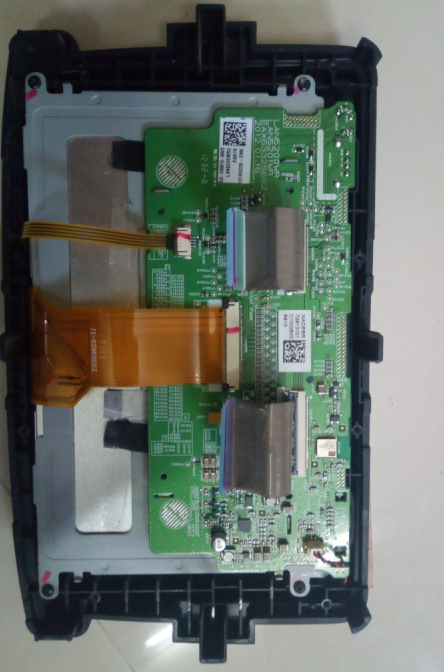
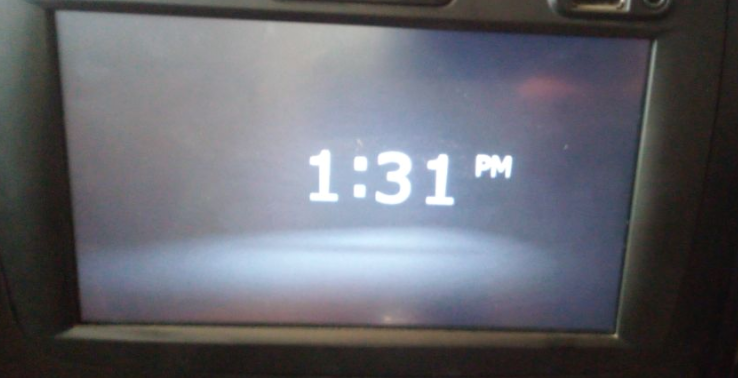
Couple of articles showed me that car infotainment system sizes and wiring at the back are actually standardized. This particular system s OEM is LG After gaining confidence from several youtube videos and articles, I chose the 3rd option and started to disassemble head unit. Luckily all those screw driver heads were with me. After taking everything apart I could see back of touch screen glass bulged and pushing against the display. The back of the display had a label with its manufacturers name Innolux display and its model number AT070TN94. You might know this company from all those raspberry pi displays in the market. Also Tesla car makers use Innolux display in their infotainment unit. I was able to spot an online reseller in Hong Kong. I only need a touch screen display but to be on the safe side I also placed order for display as well(Price difference were negligible) Took 1 month to reach at my hand due to COVID restrictions. I assembled everything together and collected radio pass code the very same day I received the item. Everything is working now. yay! The touch screen + display cost me Rs 6000/-. I can easily get an average android infotainment around this price. But it was the price I paid for avoiding e-waste. So if you have a broken head unit in your pre 2015 era car. Try to change the parts yourself. Its not complicated like our mobile phones. Back of the infotainment system inside infotainment damaged screen After reassembling with new screen Finally

14 June 2021

Ben Hutchings: Debian LTS work, May 2021

In May I was assigned 13.5 hours of work by Freexian's Debian LTS initiative and carried over 4.5 hours from earlier months. I worked 16 hours and will carry over the remainder. I finished reviewing the futex code in the PREEMPT_RT patchset for Linux 4.9, and identified several places where it had been mis-merged with the recent futex security fixes. I sent a patch for these upstream, which was accepted and applied in v4.9.268-rt180. I have continued updating the Linux 4.9 package to later upstream stable versions, and backported some missing security fixes. I have still not made a new upload, but intend to do so this week.

Enrico Zini: Pipelining

This is part of a series of posts on ideas for an ansible-like provisioning system, implemented in Transilience. Running actions on a server is nice, but a network round trip for each action is not very efficient. If I need to run a linear sequence of actions, I can stream them all to the server, and then read replies streamed from the server as they get executed. This technique is called pipelining and one can see it used, for example, in Redis, or Mitogen. Roles Ansible has the concept of "Roles" as a series of related tasks: I'll play with that. Here's an example role to install and setup fail2ban:
class Role(role.Role):
    def main(self):
        self.add(builtin.apt(
            name=["fail2ban"],
            state="present",
        ))
        self.add(builtin.copy(
            content=inline("""
                [postfix]
                enabled = true
                [dovecot]
                enabled = true
            """),
            dest="/etc/fail2ban/jail.local",
            owner="root",
            group="root",
            mode=0o644,
        ), name="configure fail2ban")
I prototyped roles as classes, with methods that push actions down the pipeline. If an action fails, all further actions for the same role won't executed, and will be marked as skipped. Since skipping is applied per-role, it means that I can blissfully stream actions for multiple roles to the server down the same pipe, and errors in one role will stop executing that role and not others. Potentially I can get multiple roles going with a single network round-trip:
#!/usr/bin/python3
import sys
from transilience.system import Mitogen
from transilience.runner import Runner
@Runner.cli
def main():
    system = Mitogen("my server", "ssh", hostname="server.example.org", username="root")
    runner = Runner(system)
    # Send roles to the server
    runner.add_role("general")
    runner.add_role("fail2ban")
    runner.add_role("prosody")
    # Run until all roles are done
    runner.main()
if __name__ == "__main__":
    sys.exit(main())
That looks like a playbook, using Python as glue rather than YAML. Decision making in roles Besides filing a series of actions, a role may need to take decisions based on the results of previous actions, or on facts discovered from the server. In that case, we need to wait until the results we need come back from the server, and then decide if we're done or if we want to send more actions down the pipe. Here's an example role that installs and configures Prosody:
from transilience import actions, role
from transilience.actions import builtin
from .handlers import RestartProsody
class Role(role.Role):
    """
    Set up prosody XMPP server
    """
    def main(self):
        self.add(actions.facts.Platform(), then=self.have_facts)
        self.add(builtin.apt(
            name=["certbot", "python-certbot-apache"],
            state="present",
        ), name="install support packages")
        self.add(builtin.apt(
            name=["prosody", "prosody-modules", "lua-sec", "lua-event", "lua-dbi-sqlite3"],
            state="present",
        ), name="install prosody packages")
    def have_facts(self, facts):
        facts = facts.facts  # Malkovich Malkovich Malkovich!
        domain = facts["domain"]
        ctx =  
            "ansible_domain": domain
         
        self.add(builtin.command(
            argv=["certbot", "certonly", "-d", f"chat. domain ", "-n", "--apache"],
            creates=f"/etc/letsencrypt/live/chat. domain /fullchain.pem"
        ), name="obtain chat certificate")
        with self.notify(RestartProsody):
            self.add(builtin.copy(
                content=self.template_engine.render_file("roles/prosody/templates/prosody.cfg.lua", ctx),
                dest="/etc/prosody/prosody.cfg.lua",
            ), name="write prosody configuration")
            self.add(builtin.copy(
                src="roles/prosody/templates/firewall-ruleset.pfw",
                dest="/etc/prosody/firewall-ruleset.pfw",
            ), name="write prosody firewall")
    # ...
This files some general actions down the pipe, with a hook that says: when the results of this action come back, run self.have_facts(). At that point, the role can use the results to build certbot command lines, render prosody's configuration from Jinja2 templates, and use the results to file further action down the pipe. Note that this way, while the server is potentially still busy installing prosody, we're already streaming prosody's configuration to it. If anything goes wrong with the installation of prosody's package, the role will be marked as failed and all further actions of the same role, even those filed by have_facts() will be skipped. Notify and handlers In the previous example self.notify() also appears: that's my attempt to model the equivalent of Ansible's handlers. If any of the actions inside the with produce changes, then the RestartProsody role will be executed, potentially filing more actions ad the end of the playbook. The runner will take care of collecting all the triggered role classes in a set, which discards duplicates, and then running the main() method of all resulting roles, which will cause more actions to be filed down the pipe. Action conditions Sometimes some actions are only meaningful as consequences of other actions. Let's take, for example, enabling buster-backports as an extra apt source:
        a = self.add(builtin.copy(
            owner="root",
            group="root",
            mode=0o644,
            dest="/etc/apt/sources.list.d/debian-buster-backports.list",
            content="deb [arch=amd64] https://mirrors.gandi.net/debian/ buster-backports main contrib",
        ), name="enable backports")
        self.add(builtin.apt(
            update_cache=True
        ), name="update after enabling backports",
           # Run only if the previous copy changed anything
           when= a: ResultState.CHANGED ,
        )
Here we want to update Apt's cache, which is a slow operation, only after we actually write /etc/apt/sources.list.d/debian-buster-backports.list. If the file was already there from a previous run, we can skip downloading the new package lists. The when= attributes adds an annotation to the action that is sent town the pipeline, that says that it should only be run if the state of a previous action matches the given one. In this case, when on the remote it's the turn of "update after enabling backports", it gets skipped unless the state of the previous "enable backports" action is CHANGED. Effects of pipelining I ported enough of Ansible's modules to be able to run the provisioning scripts of my VPS entirely via ansible. This is the playbook run as plain Ansible:
$ time ansible-playbook vps.yaml
[...]
servername       : ok=55   changed=1    unreachable=0    failed=0    skipped=0    rescued=0    ignored=0
real    2m10.072s
user    0m33.149s
sys 0m10.379s
This is the same playbook run with Ansible speeded up via the Mitogen backend, which makes Ansible more bearable:
$ export ANSIBLE_STRATEGY=mitogen_linear
$ time ansible-playbook vps.yaml
[...]
servername       : ok=55   changed=1    unreachable=0    failed=0    skipped=0    rescued=0    ignored=0
real    0m24.428s
user    0m8.479s
sys 0m1.894s
This is the same playbook ported to Transilience:
$ time ./provision
[...]
real    0m2.585s
user    0m0.659s
sys 0m0.034s
Doing nothing went from 2 minutes down to 3 seconds! That's the kind of running time that finally makes me comfortable with maintaining my VPS by editing the playbook only, and never logging in to mess with the system configuration by hand! Next steps I'm quite happy with what I have: I can now maintain my VPS with a simple script with quick iterative cycles. I might use it to develop new playbooks, and port them to ansible only when they're tested and need to be shared with infrastructure that needs to rely on something more solid and battle tested than a prototype provisioning system. I might also keep working on it as I have more interesting ideas that I'd like to try. I feel like Ansible reached some architectural limits that are hard to overcome without a major redesign, and are in many way hardcoded in its playbook configuration. It's nice to be able to try out new designs without that baggage. I'd love it if even just the library of Transilience actions could grow, and gain widespread use. Ansible modules standardized a set of management operations, that I think became the way people think about system management, and should really be broadly available outside of Ansible. If you are interesting in playing with Transilience, such as: do get in touch or send a pull request! :) Next step: Reimagining Ansible variables.

Enrico Zini: My gripes with Ansible

This is part of a series of posts on ideas for an ansible-like provisioning system, implemented in Transilience. Musing about Ansible I like infrastructure as code. I like to be able to represent an entire system as text files in a git repositories, and to be able to use that to recreate the system, from my Virtual Private Server, to my print server and my stereo, to build machines, to other kind of systems I might end up setting up. I like that the provisioning work I do on a machine can be self-documenting and replicable at will. The good For that I quite like Ansible, in principle: simple (in theory) YAML files describe a system in (reasonably) high-level steps, and it can be run on (almost) any machine that happens to have a simple Python interpreter installed. I also like many of the modules provided with Ansible: they are convenient, platform-independent implementations of common provisioning steps. They'd be fantastic to have in a library that I could use in normal programs. The bad Unfortunately, Ansible is slow. Running the playbook on my VPS takes about 3 whole minutes even if I'm just changing a line in a configuration file. This means that most of the time, instead of changing that line in the playbook and running it, to then figure out after 3 minutes that it was the wrong line, or I made a spelling mistake in the playbook, I end up logging into the server and editing in place. That defeats the whole purpose, but that level of latency between iterations is just unacceptable to me. The ugly I also think that Ansible has outgrown its original design, and the supposedly declarative, idempotent YAML has become a full declarative scripting language in disguise, whose syntax is extremely awkward and verbose. If I'm writing declarative descriptions, YAML is great. If I'm writing loops and conditionals, I want to write code, not templated YAML. I also keep struggling trying to use Ansible to provision chroots and nspawn containers. A personal experiment: Transilience There's another thing I like in Ansible: it's written in Python, which is a language I'm comfortable with. Compared to other platforms, it's one that I'm more likely to be able to control beyond being a simple user. What if I can port Ansible modules into a library of high-level provisioning functions, that I can just run via normal Python scripts? What if I can find a way to execute those scripts remotely and not just locally? I've started writing some prototype code, and the biggest problem is, of course, finding a name. Ansible comes from Ursula K. Le Guin's Hainish Cycle novels, where it is a device that allows its users to communicate near-instantaneously over interstellar distances. Traveling, however, is still constrained by the speed of light. Later in the same universe, the novels A Fisherman of the Inland Sea and The Shobies' Story, talk about experiments with instantaneous interstellar travel, as a science Ursula Le Guin called transilience:
Transilience: n. A leap across or from one thing to another [1913 Webster]
Transilience. I like everything about this name. Now that the hardest problem is solved, the rest is just a simple matter of implementation details.

Fran ois Marier: Self-hosting an Ikiwiki blog

8.5 years ago, I moved my blog to Ikiwiki and Branchable. It's now time for me to take the next step and host my blog on my own server. This is how I migrated from Branchable to my own Apache server.

Installing Ikiwiki dependencies Here are all of the extra Debian packages I had to install on my server:
apt install ikiwiki ikiwiki-hosting-common gcc libauthen-passphrase-perl libcgi-formbuilder-perl libcrypt-sslauthen-passphrase-perl libcgi-formbuilder-perl libcrypt-ssleay-perl libjson-xs-perl librpc-xml-perl python-docutils libxml-feed-perl libsearch-xapian-perl libmailtools-perl highlight-common libsearch-xapian-perl xapian-omega
apt install --no-install-recommends ikiwiki-hosting-web libgravatar-url-perl libmail-sendmail-perl libcgi-session-perl
apt purge libnet-openid-consumer-perl
Then I enabled the CGI module in Apache:
a2enmod cgi
and un-commented the following in /etc/apache2/mods-available/mime.conf:
AddHandler cgi-script .cgi

Creating a separate user account Since Ikiwiki needs to regenerate my blog whenever a new article is pushed to the git repo or a comment is accepted, I created a restricted user account for it:
adduser blog
adduser blog sshuser
chsh -s /usr/bin/git-shell blog

git setup Thanks to Branchable storing blogs in git repositories, I was able to import my blog using a simple git clone in /home/blog (the srcdir):
git clone --bare git://feedingthecloud.branchable.com/ source.git
Note that the name of the directory (source.git) is important for the ikiwikihosting plugin to work. Then I pulled the .setup file out of the setup branch in that repo and put it in /home/blog/.ikiwiki/FeedingTheCloud.setup. After that, I deleted the setup branch and the origin remote from that clone:
git branch -d setup
git remote rm origin
Following the recommended git configuration, I created a working directory (the repository) for the blog user to modify the blog as needed:
cd /home/blog/
git clone /home/blog/source.git FeedingTheCloud
I added my own ssh public key to /home/blog/.ssh/authorized_keys so that I could push to the srcdir from my laptop. Finaly, I generated a new ssh key without a passphrase:
ssh-keygen -t ed25519
and added it as deploy key to the GitHub repo which acts as a read-only mirror of my blog.

Ikiwiki config While I started with the Branchable setup file, I changed the following things in it:
adminemail: webmaster@fmarier.org
srcdir: /home/blog/FeedingTheCloud
destdir: /var/www/blog
url: https://feeding.cloud.geek.nz
cgiurl: https://feeding.cloud.geek.nz/blog.cgi
cgi_wrapper: /var/www/blog/blog.cgi
cgi_wrappermode: 675
add_plugins:
- goodstuff
- lockedit
- comments
- blogspam
- sidebar
- attachment
- favicon
- format
- highlight
- search
- theme
- moderatedcomments
- flattr
- calendar
- headinganchors
- notifyemail
- anonok
- autoindex
- date
- relativedate
- htmlbalance
- pagestats
- sortnaturally
- ikiwikihosting
- gitpush
- emailauth
disable_plugins:
- brokenlinks
- fortune
- more
- openid
- orphans
- passwordauth
- progress
- recentchanges
- repolist
- toggle
- txt
sslcookie: 1
cookiejar:
  file: /home/blog/.ikiwiki/cookies
useragent: ikiwiki
git_wrapper: /home/blog/source.git/hooks/post-update
urlalias:
- http://feeds.cloud.geek.nz/
- http://www.feeding.cloud.geek.nz/
owner: francois@fmarier.org
hostname: feeding.cloud.geek.nz
emailauth_sender: login@fmarier.org
allowed_attachments: admin()
Then I created the destdir:
mkdir /var/www/blog
chown blog:blog /var/www/blog
and generated the initial copy of the blog as the blog user:
ikiwiki --setup .ikiwiki/FeedingTheCloud.setup --wrappers --rebuild
One thing that failed to generate properly was the tag cloug (from the pagestats plugin). I have not been able to figure out why it fails to generate any output when run this way, but if I push to the repo and let the git hook handle the rebuilding of the wiki, the tag cloud is generated correctly. Consequently, fixing this is not high on my list of priorities, but if you happen to know what the problem is, please reach out.

Apache config Here's the Apache config I put in /etc/apache2/sites-available/blog.conf:
<VirtualHost *:443>
    ServerName feeding.cloud.geek.nz
    SSLEngine On
    SSLCertificateFile /etc/letsencrypt/live/feeding.cloud.geek.nz/fullchain.pem
    SSLCertificateKeyFile /etc/letsencrypt/live/feeding.cloud.geek.nz/privkey.pem
    Header set Strict-Transport-Security: "max-age=63072000; includeSubDomains; preload"
    Include /etc/fmarier-org/blog-common
</VirtualHost>
<VirtualHost *:443>
    ServerName www.feeding.cloud.geek.nz
    ServerAlias feeds.cloud.geek.nz
    SSLEngine On
    SSLCertificateFile /etc/letsencrypt/live/feeding.cloud.geek.nz/fullchain.pem
    SSLCertificateKeyFile /etc/letsencrypt/live/feeding.cloud.geek.nz/privkey.pem
    Redirect permanent / https://feeding.cloud.geek.nz/
</VirtualHost>
<VirtualHost *:80>
    ServerName feeding.cloud.geek.nz
    ServerAlias www.feeding.cloud.geek.nz
    ServerAlias feeds.cloud.geek.nz
    Redirect permanent / https://feeding.cloud.geek.nz/
</VirtualHost>
and the common config I put in /etc/fmarier-org/blog-common:
ServerAdmin webmaster@fmarier.org
DocumentRoot /var/www/blog
LogLevel core:info
CustomLog $ APACHE_LOG_DIR /blog-access.log combined
ErrorLog $ APACHE_LOG_DIR /blog-error.log
AddType application/rss+xml .rss
<Location /blog.cgi>
        Options +ExecCGI
</Location>
before enabling all of this using:
a2ensite blog
apache2ctl configtest
systemctl restart apache2.service
The feeds.cloud.geek.nz domain used to be pointing to Feedburner and so I need to maintain it in order to avoid breaking RSS feeds from folks who added my blog to their reader a long time ago.

Server-side improvements Since I'm now in control of the server configuration, I was able to make several improvements to how my blog is served. First of all, I enabled the HTTP/2 and Brotli modules:
a2enmod http2
a2enmod brotli
and enabled Brotli compression by putting the following in /etc/apache2/conf-available/compression.conf:
<IfModule mod_brotli.c>
  <IfDefine !TRANSFER_COMPRESSION>
    Define TRANSFER_COMPRESSION BROTLI_COMPRESS
  </IfDefine>
</IfModule>
<IfModule mod_deflate.c>
  <IfDefine !TRANSFER_COMPRESSION>
    Define TRANSFER_COMPRESSION DEFLATE
  </IfDefine>
</IfModule>
<IfDefine TRANSFER_COMPRESSION>
  <IfModule mod_filter.c>
    AddOutputFilterByType $ TRANSFER_COMPRESSION  text/html text/plain text/xml text/css text/javascript
    AddOutputFilterByType $ TRANSFER_COMPRESSION  application/x-javascript application/javascript application/ecmascript
    AddOutputFilterByType $ TRANSFER_COMPRESSION  application/rss+xml
    AddOutputFilterByType $ TRANSFER_COMPRESSION  application/xml
  </IfModule>
</IfDefine>
and replacing /etc/apache2/mods-available/deflate.conf with the following:
# Moved to /etc/apache2/conf-available/compression.conf as per https://bugs.debian.org/972632
before enabling this new config:
a2enconf compression
Next, I made my blog available as a Tor onion service by putting the following in /etc/apache2/sites-available/blog.conf:
<VirtualHost *:443>
    ServerName feeding.cloud.geek.nz
    ServerAlias xfdug5vmfi6oh42fp6ahhrqdjcf7ysqat6fkp5dhvde4d7vlkqixrsad.onion
    Header set Onion-Location "http://xfdug5vmfi6oh42fp6ahhrqdjcf7ysqat6fkp5dhvde4d7vlkqixrsad.onion% REQUEST_URI s"
    Header set alt-svc 'h2="xfdug5vmfi6oh42fp6ahhrqdjcf7ysqat6fkp5dhvde4d7vlkqixrsad.onion:443"; ma=315360000; persist=1'
    ... 
<VirtualHost *:80>
    ServerName xfdug5vmfi6oh42fp6ahhrqdjcf7ysqat6fkp5dhvde4d7vlkqixrsad.onion
    Include /etc/fmarier-org/blog-common
</VirtualHost>
Then I followed the Mozilla Observatory recommendations and enabled the following security headers:
Header set Content-Security-Policy: "default-src 'none'; report-uri https://fmarier.report-uri.com/r/d/csp/enforce ; style-src 'self' 'unsafe-inline' ; img-src 'self' https://seccdn.libravatar.org/ ; script-src https://feeding.cloud.geek.nz/ikiwiki/ https://xfdug5vmfi6oh42fp6ahhrqdjcf7ysqat6fkp5dhvde4d7vlkqixrsad.onion/ikiwiki/ http://xfdug5vmfi6oh42fp6ahhrqdjcf7ysqat6fkp5dhvde4d7vlkqixrsad.onion/ikiwiki/ 'unsafe-inline' 'sha256-pA8FbKo4pYLWPDH2YMPqcPMBzbjH/RYj0HlNAHYoYT0=' 'sha256-Kn5E/7OLXYSq+EKMhEBGJMyU6bREA9E8Av9FjqbpGKk=' 'sha256-/BTNlczeBxXOoPvhwvE1ftmxwg9z+WIBJtpk3qe7Pqo=' ; base-uri 'self'; form-action 'self' ; frame-ancestors 'self'"
Header set X-Frame-Options: "SAMEORIGIN"
Header set Referrer-Policy: "same-origin"
Header set X-Content-Type-Options: "nosniff"
Note that the Mozilla Observatory is mistakenly identifying HTTP onion services as insecure, so you can ignore that failure. I also used the Mozilla TLS config generator to improve the TLS config for my server. Then I added security.txt and gpc.json to the root of my git repo and then added the following aliases to put these files in the right place:
Alias /.well-known/gpc.json /var/www/blog/gpc.json
Alias /.well-known/security.txt /var/www/blog/security.txt
I also followed these instructions to create a sitemap for my blog with the following alias:
Alias /sitemap.xml /var/www/blog/sitemap/index.rss
Finally, I simplified a few error pages to save bandwidth:
ErrorDocument 301 " "
ErrorDocument 302 " "
ErrorDocument 404 "Not Found"

Monitoring 404s Another advantage of running my own web server is that I can monitor the 404s easily using logcheck by putting the following in /etc/logcheck/logcheck.logfiles:
/var/log/apache2/blog-error.log 
Based on that, I added a few redirects to point bots and users to the location of my RSS feed:
Redirect permanent /atom /index.atom
Redirect permanent /comments.rss /comments/index.rss
Redirect permanent /comments.atom /comments/index.atom
Redirect permanent /FeedingTheCloud /index.rss
Redirect permanent /feed /index.rss
Redirect permanent /feed/ /index.rss
Redirect permanent /feeds/posts/default /index.rss
Redirect permanent /rss /index.rss
Redirect permanent /rss/ /index.rss
and to tell them to stop trying to fetch obsolete resources:
Redirect gone /~ff/FeedingTheCloud
Redirect gone /gittip_button.png
Redirect gone /ikiwiki.cgi
I also used these 404s to discover a few old Feedburner URLs that I could redirect to the right place using archive.org:
Redirect permanent /feeds/1572545745827565861/comments/default /posts/watch-all-of-your-logs-using-monkeytail/comments.atom
Redirect permanent /feeds/1582328597404141220/comments/default /posts/news-feeds-rssatom-for-mythtvorg-and/comments.atom
...
Redirect permanent /feeds/8490436852808833136/comments/default /posts/recovering-lost-git-commits/comments.atom
Redirect permanent /feeds/963415010433858516/comments/default /posts/debugging-openwrt-routers-by-shipping/comments.atom
I also put the following robots.txt in the git repo in order to stop a bunch of authentication errors coming from crawlers:
User-agent: *
Disallow: /blog.cgi
Disallow: /ikiwiki.cgi

Future improvements There are a few things I'd like to improve on my current setup. The first one is to remove the iwikihosting and gitpush plugins and replace them with a small script which would simply git push to the read-only GitHub mirror. Then I could uninstall the ikiwiki-hosting-common and ikiwiki-hosting-web since that's all I use them for. Next, I would like to have proper support for signed git pushes. At the moment, I have the following in /home/blog/source.git/config:
[receive]
    advertisePushOptions = true
    certNonceSeed = "(random string)"
but I'd like to also reject unsigned pushes. While my blog now has a CSP policy which doesn't rely on unsafe-inline for scripts, it does rely on unsafe-inline for stylesheets. I tried to remove this but the actual calls to allow seemed to be located deep within jQuery and so I gave up. Update: now fixed. Finally, I'd like to figure out a good way to deal with articles which don't currently have comments. At the moment, if you try to subscribe to their comment feed, it returns a 404. For example:
[Sun Jun 06 17:43:12.336350 2021] [core:info] [pid 30591:tid 140253834704640] [client 66.249.66.70:57381] AH00128: File does not exist: /var/www/blog/posts/using-iptables-with-network-manager/comments.atom
This is obviously not ideal since many feed readers will refuse to add a feed which is currently not found even though it could become real in the future. If you know of a way to fix this, please let me know.

12 June 2021

Norbert Preining: Future of Cinnamon in Debian

OK, this is not an easy post. I have been maintaining Cinnamon in Debian for quite some time, since around the times version 4 came out. The soon (hahaha) to be released Bullseye will carry the last release of the 4-track, but version 5 is already waiting, After Bullseye, the future of Cinnamon in Debian currently looks bleak. Since my switch to KDE/Plasma, I haven t used Cinnamon in months. Only occasionally I tested new releases, but never gave them a real-world test. Having left Gnome3 for it s complete lack of usability for pro-users, I escaped to Cinnamon and found a good home there for quite some time using modern technology but keeping user interface changes conservative. For long time I haven t even contemplated using KDE, having been burned during the bad days of KDE3/4 when bloat-as-bloat-can-be was the best description. What revelation it was that KDE/Plasma was more lightweight, faster, responsive, integrated, customizable, all in all simple great. Since my switch to KDE/Plasma I think not for a second I have missed anything from the Gnome3 or Cinnamon world. And that means, I will most probably NOT packaging Cinnamon 5, nor do any real packaging work of Cinnamon for Debian in the future. Of course, I will try to keep maintenance of the current set of packages for Bullseye, but for the next release, I think it is time that someone new steps in. Cinnamon packaging taught me a lot on how to deal with multiple related packages, which is of great use in the KDE packaging world. If someone steps forward, I will surely be around for support and help, but as long as nobody takes the banner, it will mean the end of Cinnamon in Debian. Please contact me if you are interested!
11 June 2021

Mike Gabriel: New: The Debian BBB Packaging Team (and: Kurento Media Server goes Debian)

Today, Fre(i)e Software GmbH has been contracted for packaging Kurento Media Server for Debian. This packaging project will be funded by GUUG e.V. (the German Unix User Group e.V.). A big thanks to the people from GUUG e.V. for making this packaging project possible. About Kurento Media Server Kurento is an open source software project providing a platform suitable for creating modular applications with advanced real-time communication capabilities. For knowing more about Kurento, please visit the Kurento project website: https://www.kurento.org. Kurento is part of FIWARE. For further information on the relationship of FIWARE and Kurento check the Kurento FIWARE Catalog Entry. Kurento is also part of the NUBOMEDIA research initiative. Kurento Media Server is a WebRTC-compatible server that processes audio and video streams, doing composable pipeline-based processing of media. About BigBlueButton As some of you may know, Kurento Media Server is one of the core components of the BigBlueButton software, an ,,Open Source Virtual Classroom Software''. The context of the KMS funding is - after several other steps - getting the complete software component stack of BigBlueButton (aka BBB) into Debian some day, so that we can provide BBB as native Debian packages. On Debian. (Currently, one needs to use an always already a bit outdated version of Ubuntu). Due to this greater context, I just created the Debian BBB Packaging Team on salsa.debian.org. Outlook and Appreciation The current project (uploading Kurento Media Server to Debian) will very likely be extended to one year of package maintenance for all Kurento Media Server components in Debian. Extending this maintenance funding to a second year, has also been discussed, and seems a possible option. Probably most Debian Developer colleagues will agree with me when I say that Debian packaging is not a one-time shot until the first uploads of software packages have landed and settled. Debian package maintenance is a long term responsibility and requires long term commitment. I am very glad, that the people at GUUG e.V are on the same page with me (with us) regarding this. This is much and dearly appreciated. Thank you!!! What else? Well, we have also talked about another BigBlueButton component that is not yet in Debian: FreeSwitch. But more of that, when time has come. How to Join the Debian BBB Packaging Team? Please ping me via IRC (sunweaver on OFTC IRC) or [matrix] (@sunweaver:matrix.org). How to Support the Debian BBB Packaging Team? If you, your organization, your company, your municipality, your university, etc. feels like supporting the effort of packaging BigBlueButton for Debian, please get in touch with: mike.gabriel@freiesoftware.gmbh And yes, the company homepage is not online, yet, but it is in the makings... light+love
Mike (aka sunweaver)

Colin Watson: SSH quoting

A while back there was a thread on one of our company mailing lists about SSH quoting, and I posted a long answer to it. Since then a few people have asked me questions that caused me to reach for it, so I thought it might be helpful if I were to anonymize the original question and post my answer here. The question was why a sequence of commands involving ssh and fiddly quoting produced the output they did. The first example was this:
$ ssh user@machine.local bash -lc "cd /tmp;pwd"
/home/user
Oh hi, my dubious life choices have been such that this is my specialist subject! This is because SSH command-line parsing is not quite what you expect. First, recall that your local shell will apply its usual parsing, and the actual OS-level execution of ssh will be like this:
[0]: ssh
[1]: user@machine.local
[2]: bash
[3]: -lc
[4]: cd /tmp;pwd
Now, the SSH wire protocol only takes a single string as the command, with the expectation that it should be passed to a shell by the remote end. The OpenSSH client deals with this by taking all its arguments after things like options and the target, which in this case are:
[0]: bash
[1]: -lc
[2]: cd /tmp;pwd
It then joins them with a single space:
bash -lc cd /tmp;pwd
This is passed as a string to the server, which then passes that entire string to a shell for evaluation, so as if you d typed this directly on the server:
sh -c 'bash -lc cd /tmp;pwd'
The shell then parses this as two commands:
bash -lc cd /tmp
pwd
The directory change thus happens in a subshell (actually it doesn t quite even do that, because bash -lc cd /tmp in fact ends up just calling cd because of the way bash -c parses multiple arguments), and then that subshell exits, then pwd is called in the outer shell which still has the original working directory. The second example was this:
$ ssh user@machine.local bash -lc "pwd;cd /tmp;pwd"
/home/user
/tmp
Following the logic above, this ends up as if you d run this on the server:
sh -c 'bash -lc pwd; cd /tmp; pwd'
The third example was this:
$ ssh user@machine.local bash -lc "cd /tmp;cd /tmp;pwd"
/tmp
And this is as if you d run:
sh -c 'bash -lc cd /tmp; cd /tmp; pwd'
Now, I wouldn t have implemented the SSH client this way, because I agree that it s confusing. But /usr/bin/ssh is used as a transport for other things so much that changing its behaviour now would be enormously disruptive, so it s probably impossible to fix. (I have occasionally agitated on openssh-unix-dev@ for at least documenting this better, but haven t made much headway yet; I need to get round to preparing a documentation patch.) Once you know about it you can use the proper quoting, though. In this case that would simply be:
ssh user@machine.local 'cd /tmp;pwd'
Or if you do need to specifically invoke bash -l there for some reason (I m assuming that the original example was reduced from something more complicated), then you can minimise your confusion by passing the whole thing as a single string in the form you want the remote sh -c to see, in a way that ensures that the quotes are preserved and sent to the server rather than being removed by your local shell:
ssh user@machine.local 'bash -lc "cd /tmp;pwd"'
Shell parsing is hard.

10 June 2021

Petter Reinholdtsen: Nikita version 0.6 released - free software archive API server

I am very pleased to be able to share with you the announcement of a new version of the archiving system Nikita published by its lead developer Thomas S dring:
It is with great pleasure that we can announce a new release of nikita. Version 0.6 (https://gitlab.com/OsloMet-ABI/nikita-noark5-core). This release makes new record keeping functionality available. This really is a maturity release. Both in terms of functionality but also code. Considerable effort has gone into refactoring the codebase and simplifying the code. Notable changes for this release include:
  • Significantly improved OData parsing
  • Support for business specific metadata and national identifiers
  • Continued implementation of domain model and endpoints
  • Improved testing
  • Ability to export and import from arkivstruktur.xml
We are currently in the process of reaching an agreement with an archive institution to publish their picture archive using nikita with business specific metadata and we hope that we can share this with you soon. This is an interesting project as it allows the organisation to bring an older picture archive back to life while using the original metadata values stored as business specific metadata. Combined with OData means the scope and use of the archive is significantly increased and will showcase both the flexibility and power of Noark. I really think we are approaching a version 1.0 of nikita, even though there is still a lot of work to be done. The notable work at the moment is to implement access-control and full text indexing of documents. My sincere thanks to everyone who has contributed to this release! - Thomas Release 0.6 2021-06-10 (d1ba5fc7e8bad0cfdce45ac20354b19d10ebbc7b)
  • Refactor metadata entity search
  • Remove redundant security configuration
  • Make OpenAPI documentation work
  • Change database structure / inheritance model to a more sensible approach
  • Make it possible to move entities around the fonds structure
  • Implemented a number of missing endpoints
  • Make sure yml files are in sync
  • Implemented/finalised storing and use of
    • Business Specific Metadata
    • Norwegian National Identifiers
    • Cross Reference
    • Keyword
    • StorageLocation
    • Author
    • Screening for relevant objects
    • ChangeLog
    • EventLog
  • Make generation of updated docker image part of successful CI pipeline
  • Implement pagination for all list requests
    • Refactor code to support lists
    • Refactor code for readability
    • Standardise the controller/service code
  • Finalise File->CaseFile expansion and Record->registryEntry/recordNote expansion
  • Improved Continuous Integration (CI) approach via gitlab
  • Changed conversion approach to generate tagged PDF documents
  • Updated dependencies
    • For security reasons
    • Brought codebase to spring-boot version 2.5.0
    • Remove import of necessary dependencies
    • Remove non-used metrics classes
  • Added new analysis to CI including
  • Implemented storing of Keyword
  • Implemented storing of Screening and ScreeningMetadata
  • Improved OData support
    • Better support for inheritance in queries where applicable
    • Brought in more OData tests
    • Improved OData/hibernate understanding of queries
    • Implement $count, $orderby
    • Finalise $top and $skip
    • Make sure & is used between query parameters
  • Improved Testing in codebase
    • A new approach for integration tests to make test more readable
    • Introduce tests in parallel with code development for TDD approach
    • Remove test that required particular access to storage
  • Implement case-handling process from received email to case-handler
    • Develop required GUI elements (digital postroom from email)
    • Introduced leader, quality control and postroom roles
  • Make PUT requests return 200 OK not 201 CREATED
  • Make DELETE requests return 204 NO CONTENT not 200 OK
  • Replaced 'oppdatert*' with 'endret*' everywhere to match latest spec
  • Upgrade Gitlab CI to use python > 3 for CI scripts
  • Bug fixes
    • Fix missing ALLOW
    • Fix reading of objects from jar file during start-up
    • Reduce the number of warnings in the codebase
    • Fix delete problems
    • Make better use of cascade for "leaf" objects
    • Add missing annotations where relevant
    • Remove the use of ETAG for delete
    • Fix missing/wrong/broken rels discovered by runtest
    • Drop unofficial convertFil (konverterFil) end point
    • Fix regex problem for dateTime
    • Fix multiple static analysis issues discovered by coverity
    • Fix proxy problem when looking for object class names
    • Add many missing translated Norwegian to English (internal) attribute/entity names
    • Change UUID generation approach to allow code also set a value
    • Fix problem with Part/PartParson
    • Fix problem with empty OData search results
    • Fix metadata entity domain problem
  • General Improvements
    • Makes future refactoring easier as coupling is reduced
    • Allow some constant variables to be set from property file
    • Refactor code to make reflection work better across codebase
    • Reduce the number of @Service layer classes used in @Controller classes
    • Be more consistent on naming of similar variable types
    • Start printing rels/href if they are applicable
    • Cleaner / standardised approach to deleting objects
    • Avoid concatenation when using StringBuilder
    • Consolidate code to avoid duplication
    • Tidy formatting for a more consistent reading style across similar class files
    • Make throw a log.error message not an log.info message
    • Make throw print the log value rather than printing in multiple places
    • Add some missing pronom codes
    • Fix time formatting issue in Gitlab CI
    • Remove stale / unused code
    • Use only UUID datatype rather than combination String/UUID for systemID
    • Mark variables final and @NotNull where relevant to indicate intention
  • Change Date values to DateTime to maintain compliance with Noark 5 standard
  • Domain model improvements using Hypersistence Optimizer
    • Move @Transactional from class to methods to avoid borrowing the JDBC Connection unnecessarily
    • Fix OneToOne performance issues
    • Fix ManyToMany performance issues
    • Add missing bidirectional synchronization support
    • Fix ManyToMany performance issue
  • Make List
  • and Set
  • use final-keyword to avoid potential problems during update operations
  • Changed internal URLs, replaced "hateoas-api" with "api".
  • Implemented storing of Precedence.
  • Corrected handling of screening.
  • Corrected _links collection returned for list of mixed entity types to match the specific entity.
  • Improved several internal structures.
If free and open standardized archiving API sound interesting to you, please contact us on IRC (#nikita on irc.oftc.net) or email (nikita-noark mailing list). As usual, if you use Bitcoin and want to show your support of my activities, please send Bitcoin donations to my address 15oWEoG9dUPovwmUL9KWAnYRtNJEkP1u1b.

9 June 2021

Michael Prokop: efivars is gone with Debian/bullseye #newinbullseye

Continuing with #newinbullseye, it s worth being aware of, that efivars is gone with the kernel version shipped as of Debian/bullseye. Quoting from wiki.debian.org/UEFI:
The Linux kernel gives access to the UEFI configuration variables via a set of files under /sys, using two different interfaces. The older interface was showing files under /sys/firmware/efi/vars, and this is what was used by default in both Wheezy and Jessie. The new interface is efivarfs, which will expose things in a slightly different format under /sys/firmware/efi/efivars.
This is the new preferred way of using UEFI configuration variables, and Debian switched to it by default from Stretch onwards.
Now, CONFIG_EFI_VARS is no longer enabled in Debian due to commit 20146398c4 (shipped as such with Debian kernel package versions >=5.10.1-1~exp1). As a result, the kernel module efivars is no longer available on systems running Debian kernels >=5.10 (which includes Debian/bullseye). Now, when running such a system in EFI mode, chroot-ing into a system and executing e.g. efibootmgr, it might fail with:
# efibootmgr
EFI variables are not supported on this system.
This is caused by /sys/firmware/efi/vars no longer being available, because of the disabled CONFIG_EFI_VARS. To get this working again, you need to make efivarfs available via:
# mount -t efivarfs efivarfs /sys/firmware/efi/efivars
Then efibootmgr and further tools relying on efivars should work again. FYI: if you re a user of Grml s grml-chroot tool, this is going to be handled out of the box for you.

Thorsten Alteholz: My Debian Activities in May 2021

FTP master This month I accepted 85 and rejected 6 packages. The overall number of packages that got accepted was only 88. Yeah, Debian is frozen but hopefully will unfreeze soon. Debian LTS This was my eighty-third month that I did some work for the Debian LTS initiative, started by Raphael Hertzog at Freexian. This month my all in all workload has been 29.75h. During that time I did LTS and normal security uploads of: I also made some progress with gpac and struggle with dozens of issues here. Last but not least I did some days of frontdesk duties, which for whatever reason was rather time-consuming this month. Debian ELTS This month was the thirty-fifth ELTS month. During my allocated time I uploaded: I also made some progress with python3.4 Last but not least I did some days of frontdesk duties. Other stuff On my neverending golang challenge I again uploaded some packages either for NEW or as source upload. Last but not least I adopted gnucobol.

Enrico Zini: Ansible recurse and follow quirks

I'm reading Ansible's builtin.file sources for, uhm, reasons, and the use of follow stood out to my eyes. Reading on, not only that. I feel like the ansible codebase needs a serious review, at least in essential core modules like this one. In the file module documentation it says:
This flag indicates that filesystem links, if they exist, should be followed.
In the recursive_set_attributes implementation instead, follow means "follow symlinks to directories", but if a symlink to a file is found, it does not get followed, kind of. What happens is that ansible will try to change the mode of the symlink, which makes sense on some operating systems. And it does try to use lchmod if present. Buf if not, this happens:
# Attempt to set the perms of the symlink but be
# careful not to change the perms of the underlying
# file while trying
underlying_stat = os.stat(b_path)
os.chmod(b_path, mode)
new_underlying_stat = os.stat(b_path)
if underlying_stat.st_mode != new_underlying_stat.st_mode:
    os.chmod(b_path, stat.S_IMODE(underlying_stat.st_mode))
So it tries doing chmod on the symlink, and if that changed the mode of the actual file, switch it back. I would have appreciated a comment documenting on which systems a hack like this makes sense. As it is, it opens a very short time window in which a symlink attack can make a system file vulerable, and an exception thrown by the second stat will make it vulnerable permanently. What about follow following links during recursion: how does it avoid loops? I don't see a cache of (device, inode) pairs visited. Let's try:
fatal: [localhost]: FAILED! =>  "changed": false, "details": "maximum recursion depth exceeded", "gid": 1000, "group": "enrico", "mode": "0755", "msg": "mode must be in octal or symbolic form", "owner": "enrico", "path": "/tmp/test/test1", "size": 0, "state": "directory", "uid": 1000 
Ok, it, uhm, delegates handling that to the Python stack size. I guess it means that a ln -s .. foo in a directory that gets recursed will always fail the task. Fun! More quirks Turning a symlink into a hardlink is considered a noop if the symlink points to the same file:
---
- hosts: localhost
  tasks:
   - name: create test file
     file:
        path: /tmp/testfile
        state: touch
   - name: create test link
     file:
        path: /tmp/testlink
        state: link
        src: /tmp/testfile
   - name: turn it into a hard link
     file:
        path: /tmp/testlink
        state: hard
        src: /tmp/testfile
gives:
$ ansible-playbook test3.yaml
[WARNING]: provided hosts list is empty, only localhost is available. Note that the implicit localhost does not match 'all'
PLAY [localhost] ************************************************************************************************************************************************************************************************************
TASK [Gathering Facts] ******************************************************************************************************************************************************************************************************
ok: [localhost]
TASK [create test file] *****************************************************************************************************************************************************************************************************
changed: [localhost]
TASK [create test link] *****************************************************************************************************************************************************************************************************
changed: [localhost]
TASK [turn it into a hard link] *********************************************************************************************************************************************************************************************
ok: [localhost]
PLAY RECAP ******************************************************************************************************************************************************************************************************************
localhost                  : ok=4    changed=2    unreachable=0    failed=0    skipped=0    rescued=0    ignored=0
More quirks Converting a directory into a hardlink should work, but it doesn't because unlink is used instead of rmdir:
---
- hosts: localhost
  tasks:
   - name: create test dir
     file:
        path: /tmp/testdir
        state: directory
   - name: turn it into a symlink
     file:
        path: /tmp/testdir
        state: hard
        src: /tmp/
        force: yes
gives:
$ ansible-playbook test4.yaml
[WARNING]: provided hosts list is empty, only localhost is available. Note that the implicit localhost does not match 'all'
PLAY [localhost] ************************************************************************************************************************************************************************************************************
TASK [Gathering Facts] ******************************************************************************************************************************************************************************************************
ok: [localhost]
TASK [create test dir] ******************************************************************************************************************************************************************************************************
changed: [localhost]
TASK [turn it into a symlink] ***********************************************************************************************************************************************************************************************
fatal: [localhost]: FAILED! =>  "changed": false, "gid": 1000, "group": "enrico", "mode": "0755", "msg": "Error while replacing: [Errno 21] Is a directory: b'/tmp/testdir'", "owner": "enrico", "path": "/tmp/testdir", "size": 0, "state": "directory", "uid": 1000 
PLAY RECAP ******************************************************************************************************************************************************************************************************************
localhost                  : ok=2    changed=1    unreachable=0    failed=1    skipped=0    rescued=0    ignored=0
More quirks This is hard to test, but it looks like if source and destination are hardlinks to the same inode numbers, but on different filesystems, the operation is considered a successful noop: https://github.com/ansible/ansible/blob/devel/lib/ansible/modules/file.py#L821 It should probably be something like:
if (st1.st_dev, st1.st_ino) == (st2.st_dev, st2.st_ino):

8 June 2021

Enrico Zini: Mock syscalls with C++

I wrote and maintain some C++ code to stream high quantities of data as fast as possible, and I try to use splice and sendfile when available. The availability of those system calls varies at runtime according to a number of factors, and the code needs to be written to fall back to read/write loops depending on what the splice and sendfile syscalls say. The tricky issue is unit testing: since the code path chosen depends on the kernel, the test suite will test one path or the other depending on the machine and filesystems where the tests are run. It would be nice to be able to mock the syscalls, and replace them during tests, and it looks like I managed. First I made catalogues of the mockable syscalls I want to be able to mock. One with function pointers, for performance, and one with std::function, for flexibility:
/**
 * Linux versions of syscalls to use for concrete implementations.
 */
struct ConcreteLinuxBackend
 
    static ssize_t (*read)(int fd, void *buf, size_t count);
    static ssize_t (*write)(int fd, const void *buf, size_t count);
    static ssize_t (*writev)(int fd, const struct iovec *iov, int iovcnt);
    static ssize_t (*sendfile)(int out_fd, int in_fd, off_t *offset, size_t count);
    static ssize_t (*splice)(int fd_in, loff_t *off_in, int fd_out,
                             loff_t *off_out, size_t len, unsigned int flags);
    static int (*poll)(struct pollfd *fds, nfds_t nfds, int timeout);
    static ssize_t (*pread)(int fd, void *buf, size_t count, off_t offset);
 ;
/**
 * Mockable versions of syscalls to use for testing concrete implementations.
 */
struct ConcreteTestingBackend
 
    static std::function<ssize_t(int fd, void *buf, size_t count)> read;
    static std::function<ssize_t(int fd, const void *buf, size_t count)> write;
    static std::function<ssize_t(int fd, const struct iovec *iov, int iovcnt)> writev;
    static std::function<ssize_t(int out_fd, int in_fd, off_t *offset, size_t count)> sendfile;
    static std::function<ssize_t(int fd_in, loff_t *off_in, int fd_out,
                                 loff_t *off_out, size_t len, unsigned int flags)> splice;
    static std::function<int(struct pollfd *fds, nfds_t nfds, int timeout)> poll;
    static std::function<ssize_t(int fd, void *buf, size_t count, off_t offset)> pread;
    static void reset();
 ;
Then I converted the code to templates, parameterized on the catalogue class. Explicit template instantiation helps in making sure that one doesn't need to include template code in all sorts of places. Finally, I can have a RAII class for mocking:
/**
 * RAII mocking of syscalls for concrete stream implementations
 */
struct MockConcreteSyscalls
 
    std::function<ssize_t(int fd, void *buf, size_t count)> orig_read;
    std::function<ssize_t(int fd, const void *buf, size_t count)> orig_write;
    std::function<ssize_t(int fd, const struct iovec *iov, int iovcnt)> orig_writev;
    std::function<ssize_t(int out_fd, int in_fd, off_t *offset, size_t count)> orig_sendfile;
    std::function<ssize_t(int fd_in, loff_t *off_in, int fd_out,
                                 loff_t *off_out, size_t len, unsigned int flags)> orig_splice;
    std::function<int(struct pollfd *fds, nfds_t nfds, int timeout)> orig_poll;
    std::function<ssize_t(int fd, void *buf, size_t count, off_t offset)> orig_pread;
    MockConcreteSyscalls();
    ~MockConcreteSyscalls();
 ;
MockConcreteSyscalls::MockConcreteSyscalls()
    : orig_read(ConcreteTestingBackend::read),
      orig_write(ConcreteTestingBackend::write),
      orig_writev(ConcreteTestingBackend::writev),
      orig_sendfile(ConcreteTestingBackend::sendfile),
      orig_splice(ConcreteTestingBackend::splice),
      orig_poll(ConcreteTestingBackend::poll),
      orig_pread(ConcreteTestingBackend::pread)
 
 
MockConcreteSyscalls::~MockConcreteSyscalls()
 
    ConcreteTestingBackend::read = orig_read;
    ConcreteTestingBackend::write = orig_write;
    ConcreteTestingBackend::writev = orig_writev;
    ConcreteTestingBackend::sendfile = orig_sendfile;
    ConcreteTestingBackend::splice = orig_splice;
    ConcreteTestingBackend::poll = orig_poll;
    ConcreteTestingBackend::pread = orig_pread;
 
And here's the specialization to pretend sendfile and splice aren't available:
/**
 * Mock sendfile and splice as if they weren't available on this system
 */
struct DisableSendfileSplice : public MockConcreteSyscalls
 
    DisableSendfileSplice();
 ;
DisableSendfileSplice::DisableSendfileSplice()
 
    ConcreteTestingBackend::sendfile = [](int out_fd, int in_fd, off_t *offset, size_t count) -> ssize_t  
        errno = EINVAL;
        return -1;
     ;
    ConcreteTestingBackend::splice = [](int fd_in, loff_t *off_in, int fd_out,
                                        loff_t *off_out, size_t len, unsigned int flags) -> ssize_t  
        errno = EINVAL;
        return -1;
     ;
 
It's now also possible to reproduce in the test suite all sorts of system-related issues we might observe in production over time.

Jonathan Dowland: LaTeX draft documents

I'm writing up a PhD deliverable (which will show up here eventually) using LaTeX, which is my preferred tool for such things, since I also use it for papers, and will eventually be using it for my thesis itself. For this last document, I experimented with a few packages and techniques for organising the document which I found useful, so I thought I'd share them. What version is this anyway? I habitually store and develop my documents in git repositories. From time to time I generate a PDF and copy it off elsewhere to review (e.g., an iPad). Later on it can be useful to be able to figure out exactly what source built the PDF. I achieve this using
\newcommand \version \input "git describe --always --dirty" 
And \version\ somewhere in the header of the document. Draft mode The common document classes all accept a draft argument, to enable Draft Mode.
\documentclass[12pt,draft] article 
Various other packages behave differently if Draft Mode is enabled. The graphicx package, for example, doesn't actually draw pictures in draft mode, which I don't find useful. So for that package, I force it to behave as if we were in "Final Mode" at all times:
\usepackage[final] graphicx 
I want to also include some different bits and pieces in Draft Mode. Although the final version won't need it, I find having a Table of Contents very helpful during the writing process. The ifdraft package adds a convenience macro to query whether we are in draft or not. I use it like so:
\ifdraft 
This page will be cut from the final report.
\tableofcontents
\newpage
 
For this document, I have been given the section headings I must use and the number of pages each section must run to. When drafting, I want to include the page budget in the section names (e.g. Background (2 pages)). I also force new pages at the beginning of each Section, to make it easier to see how close I am to each section's page budget.
\ifdraft \newpage 
\section Work completed\ifdraft  (1 page)  % 1 Page
todonotes
Two TODO items in the margin Two TODO items in the margin
Collated TODOs in a list Collated TODOs in a list
The todonotes package package is one of many that offers macros to make managing in-line TODO notes easier. Within the source of my document, I can add a TODO right next to the relevant text with \todo something to do . In the document, by default, this is rendered in the right-hand margin. With the right argument, the package will only render the notes in draft mode.
\usepackage[textsize=small,obeyDraft] todonotes 
todonotes can also collate all the TODOs together into a single list. The list items are hyperlinked back to the page where the relevant item appears.
\ifdraft 
\newpage
\section TODO 
  This page will be cut from the final report.
  \listoftodos
 

Next.

Previous.