Search Results: "ag"

6 January 2009

Gunnar Wolf: Historias de la Historia del c mputo en m xico


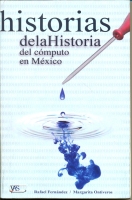
Some months ago, I got a phone call from Rafael Fern ndez Flores. He wanted to interview me for a book he was working on regarding the history of computers in Mexico. The first computer in Latin America was installed in 1958 at my University (UNAM), and last year there were several activities conmemorating it. One of said activities is the publication of the book Historias de la Historia del c mputo en m xico, by Rafael Fern ndez and Margarita Ontiveros.
The book was printed in November, and Rafael gave me my copy in early December. It is quite an entertaining read - I mostly enjoyed the archaeological parts of it, referring to the 1950s and 1960s, and with many people that I know first hand (as my father is one of the founding researchers of the Centro de Investigaci n en Matem ticas Aplicadas, Sistemas y Servicios, CIMASS, now IIMAS).
I do believe, anyway, the book is focused too heavily on what happened in the large-scale computer world during a fundamental point in time for me (late 1970s, early 1980s) - It shows that the authors were very involved in the important projects the University set foot on, but they overlook fundamental pieces of the history. Very important developments were made in smaller venues (it was shocking for me to find only one mention, and just as a reference, to Fundaci n Arturo Rosenblueth and its great Centros Galileo, where many hundreds of kids (me included) learned to love computers, to program, and had a thriving socialization place. I also missed mentions of the BBS scene in Mexico, for which there are various exponents. And, just to single out one person, I found it absurd to have me interviewed and not to include La Mancha de la Calabaza que Ladra.
One of the last chapters -there are over 40 chapters, stemming from over 30 individual interviews- publishes the talk I had with Rafael. I must say there are small errata in its transcription (the first example that comes to my mind: I told him that one of the fruits of the OLPC project was the appearance of the now-popular netbooks, partly due to the appearance of lower cost parts, but I must reiterate I didn't say the Asus EEE is a part of said project). You can I am attaching my interview (as scanned, low-res images) to this post, in case you are interested.
Anyway - If the topic interests you, you will find many interesting passages, many passages you will surely laugh with and probably remember. The book is very well laid out. And it is a great joy to be part of it!

Vincent Fourmond: Switching to mpd

I was until recently using xmms2 as a music daemon. I was finding it neat, providing a good command-line (thus scriptable) control over how the music was playing, and I was using xmms2 info to automatically write signature files for my mails. However, I got annoyed by one quite painful thing: on my computer, it can take up to 40% of the processor to play a MP3 file (AMD64 x2 4200+ @2.2GHz)! That is mad. One of the consequences was that the music was jaggy whenever aptitude was upgrading packages... Annoying. So, I've switched to mpd. It provides a decent command-line client, with possibly a bit less features than xmms2, but it takes only a few percent of the processor's usage... Thanks !

Julien Valroff: DSPAM-Community - first RC: call for testing

I was happy to receive Dov Zamir s email announcing the creation of a fork of the DSPAM anti-spam filter, called dspam-community. I have been using DSPAM for a while now, and am very happy with it, but was quite anxious that the project is left out by Sensory Networks (the company took over DSPAM in May 2007). I give all my confidence in the fork as the original author, Jonathan Zdziarski, is part of the new development team! I have prepared EXPERIMENTAL packages of the first RC of DSPAM-Community.

These are only meant for testing and should not be used in a production environment! I haven t tested these packages in depth (only tested installation or upgrade from previous official/unofficial packages).
There might still be problems due to the new names. I have built packages for i386 and amd64 architectures. They are built against current unstable distribution. They might be used on Ubuntu, but I haven t tested this yet. I have setup a quick page for these packages. All the applied patches are available for review and possible merge into git: http://packages.kirya.net/dspam-community/debian-patches/ To use these packages, add these lines to your /etc/apt/sources.list:
deb http://packages.kirya.net/dspam-community/ experimental main
deb-src http://packages.kirya.net/dspam-community/ experimental main
The repository uses secure-apt, you can hence check packages integrity thanks to my dedicated GPG key:
gpg --keyserver wwwkeys.eu.pgp.net --recv-keys FBABB737
gpg --export -a FBABB737   apt-key add -
or
wget -O - http://packages.kirya.net/Kirya.netDebianpackagesVerificationKey.asc   apt-key add -
Fingerprint: 97A0 69D9 A150 687E 599F F168 EEFB 43B2 FBAB B737 Feel free to test the packages and the first DSPAM-Community RC.
Any comment is welcome! To the official DSPAM packaging team: feel free to take these packages as a basis for your work in case you are interested in packaging DSPAM-Community!

David Welton: Git is a Pain in the Ass

Everyone's been talking about how great and wonderful git is, and I've tried using it for a few projects of my own, on a local basis, sort of like an advanced form of 'rcs'. So I thought I'd try it out in a little bit more complicated setup, for a site I host on my web server. I want to have a main repository, that I "check out" (or 'clone', in git terms) on my laptop. My laptop can't be the main repository, because I also want to be able to commit from the web server (once in a while a quick live update is called for), so I need a stable address. Ok, I'll put it in my home directory on the web server, just to see how things work.
mkdir foobar
cd foobar
git init
Ok, so far so good. Now I try and clone it on my laptop, where I will then add files, commit, then push them. Oops, that doesn't work. You can't clone an empty repository. Ok, I add something on the server where I init'ed it, an empty file, just to give it some content. Now cloning it works on the laptop. Great, we're in business! I add a bunch of files from the project to the laptop repository, commit, then push them. Seems to be ok so far... I do a checkout on the remote/server machine, and I see my files. Good. Ok, let's try making a change on the laptop. I remove a file, commit it, push it (which is already an extra step compared to subversion... hrmph). I do a checkout on the server, but it won't erase the file I removed on the laptop. Weird. I google around a bit, and find that this is supposed to be for my own good, so I won't wreck things on the server. I need to do git reset --hard (which isn't a very reassuringly named command) there, and then a checkout, and now things work. That, however, is a lot of work just to commit and update stuff! I ask for some help on #git, where they mention the --bare option to init. Since I'm just messing around, I go back and redo the init step, wiping the old repository. Now I try and clone that to start over again. Oops, I forgot, I can't clone it because it's empty. Grrrrrr.... this is getting annoying. So, the kind folks on #git tell me I should push to the new server repository from one that's already populated. Ok, let's try setting up the laptop:
git init
... add/commit some files ...
git remote add origin ...myurl...
Now let's try pushing. Nope, still doesn't do it, I'm missing something. Frustrating. A bit more fiddling and googling, and i find:
get push origin master
Aha! It worked! Weird. And now a simple git push works too. The whole thing seems kind of shaky in the sense that it's not very confidence inspiring: I feel like it wouldn't take much to make a wrong turn and find all my files gone forever. I can see some of the advantages, and will likely stick with it - git is quite convenient for local files that I might not have bothered putting under version control in the past, but it's also a bit more "bureaucratic" in that you have more steps to do, and you have to fill in the forms just so... or else!

David Welton: Git is a Pain in the Ass

Everyone's been talking about how great and wonderful git is, and I've tried using it for a few projects of my own, on a local basis, sort of like an advanced form of 'rcs'. So I thought I'd try it out in a little bit more complicated setup, for a site I host on my web server. I want to have a main repository, that I "check out" (or 'clone', in git terms) on my laptop. My laptop can't be the main repository, because I also want to be able to commit from the web server (once in a while a quick live update is called for), so I need a stable address. Ok, I'll put it in my home directory on the web server, just to see how things work.
mkdir foobar
cd foobar
git init
Ok, so far so good. Now I try and clone it on my laptop, where I will then add files, commit, then push them. Oops, that doesn't work. You can't clone an empty repository. Ok, I add something on the server where I init'ed it, an empty file, just to give it some content. Now cloning it works on the laptop. Great, we're in business! I add a bunch of files from the project to the laptop repository, commit, then push them. Seems to be ok so far... I do a checkout on the remote/server machine, and I see my files. Good. Ok, let's try making a change on the laptop. I remove a file, commit it, push it (which is already an extra step compared to subversion... hrmph). I do a checkout on the server, but it won't erase the file I removed on the laptop. Weird. I google around a bit, and find that this is supposed to be for my own good, so I won't wreck things on the server. I need to do git reset --hard (which isn't a very reassuringly named command) there, and then a checkout, and now things work. That, however, is a lot of work just to commit and update stuff! I ask for some help on #git, where they mention the --bare option to init. Since I'm just messing around, I go back and redo the init step, wiping the old repository. Now I try and clone that to start over again. Oops, I forgot, I can't clone it because it's empty. Grrrrrr.... this is getting annoying. So, the kind folks on #git tell me I should push to the new server repository from one that's already populated. Ok, let's try setting up the laptop:
git init
... add/commit some files ...
git remote add origin ...myurl...
Now let's try pushing. Nope, still doesn't do it, I'm missing something. Frustrating. A bit more fiddling and googling, and i find:
get push origin master
Aha! It worked! Weird. And now a simple git push works too. The whole thing seems kind of shaky in the sense that it's not very confidence inspiring: I feel like it wouldn't take much to make a wrong turn and find all my files gone forever. I can see some of the advantages, and will likely stick with it - git is quite convenient for local files that I might not have bothered putting under version control in the past, but it's also a bit more "bureaucratic" in that you have more steps to do, and you have to fill in the forms just so... or else!

Uwe Hermann: Running homebrew and open-source software on your Wii, using the Twilight Hack and the Homebrew Channel

Wii I've been owning a Nintendo Wii for quite a while now, but so far only played an occasional game of tennis or the like. Over the holidays I got The Legend of Zelda: Twilight Princess, which is a really nice game in itself. What is even more interesting though, is that this game allows you to run homebrew software on your Wii. What you usually want to do, is to use the so-called Twilight Hack to install the Homebrew Channel on your Wii (you'll need an SD card and the Twilight Princess game for this). Once the process has finished you won't need the game anymore though. So, here's a quick tutorial on how to install the Homebrew Channel. I basically followed the Setting up your Wii for Homebrew HOWTO from wiibrew.org. Requirements An SD card max. 2GB in size (not an SDHC card!), an SD card reader in your PC or laptop, and the Twilight Princess game (which you must play at least once). Backup First, you'll want to backup your Twilight Princess save games (if any). For that, we format the SD card (it needs a FAT16/FAT32) filesystem.
 $ mkfs.vfat /dev/mmcblk0p1 (you may need to change "mmcblk0p1" to whatever fits your setup)
Now insert the SD card into the Wii, start the Wii, go to Wii Options --> Data Management --> Save Data --> Wii and copy your Twilight Princess save games onto the SD card. Then, poweroff, remove the SD card, insert it into your laptop/PC and copy the save games to a safe place.
 $ mount -t vfat /dev/mmcblk0p1 /mnt
 $ mv /mnt/private ~/zelda_savegames
Twilight Hack and Homebrew Channel The Legend of Zelda: Twilight Princess Next up: download the Twilight Hack and Homebrew Channel, and put the files on the SD card:
 $ wget http://hbc.hackmii.com/dist/twilight-hack-v0.1-beta1.zip
 $ unzip twilight-hack-v0.1-beta1.zip
 $ cp -r private /mnt
 $ wget http://hbc.hackmii.com/dist/the_homebrew_channel-1.0.1.tar.gz
 $ tar xfvz the_homebrew_channel-1.0.1.tar.gz
 $ cp the_homebrew_channel-1.0.1/boot.dol /mnt
 $ umount /mnt
Now remove the SD card, insert it into the Wii and power-up the Wii. Go to Wii Options --> Data Management --> Save Data --> Wii, delete the Wii Twilight Princess save games, then copy the "Twilight Hack" save game from the SD card onto the Wii (you need to select the correct one for your region). Quit the menu, start Twilight Princess, load the "Twilight Hack" savegame and finally talk to the person in front of you (do not perform any other actions, or the Wii may crash!). Follow the remaining instructions on the screen and you're done. You now have an additional channel named Homebrew Channel where all your homebrew programs/games (and your own Free Software programs you may write/port) will appear. Installing homebrew software So far, there are no real applications in the Homebrew Channel, you need to put all the homebrew software you want on the SD card. There's a huuuge list of applications and games to choose from, many of them Free Software with source code, some however are binary-only. Basically, you put each application in a sub-directory of apps/ on the SD card, the most important file in every sub-directory is always boot.dol. If you have a boot.elf file instead, you'll probably need to convert it using the ELF to DOL converter. Restoring Twilight Princess save games You may now want to restore your Twilight Princess save games onto the Wii, you no longer need the "Twilight Hack" save game. Put your ~/zelda_savegames directory on the SD card and name it private/ again. Insert the SD card into the Wii and copy the save games on the Wii (similar procedure as above). Have fun with homebrew software on your Wii, or even better write your own software or port existing Linux applications/games!

David Moreno: Returning an specific HTTP status/return code and content with mod_perl 2

Making a simple PerlResponseHandler that does something like this:
sub handler  
    my($r) = shift;
    $r->content_type("text/plain");
    $r->print("You suck.\n");
    return Apache2::Const::HTTP_BAD_REQUEST;
 
doesn t make what you d be expecting. This is because mod_perl assumes, since you are specifying content type and something to print, that this is a legit and valid (200-ish) request. This is what you get:

POST http://myserver/resource --> 200 OK
Connection: close
Date: Mon, 05 Jan 2009 23:02:57 GMT
Content-Type: text/plain; charset=UTF-8
Client-Date: Mon, 05 Jan 2009 23:03:00 GMT
Client-Response-Num: 1
Client-Transfer-Encoding: chunked
[ some headers snipped ]
You suck.
<!DOCTYPE HTML PUBLIC "-//IETF//DTD HTML 2.0//EN">
<html><head>
<title>200 OK<</title>
</head><body>
<h1>OK</h1>
<p>Your browser sent a request that this server could not understand.<br />
</p>
</body></html>
So, yes, I was expecting to return a 400 Bad Request return with just You suck on the response body. mod_perl disagrees, which, kind of sucks if you are trying to make a RESTful service with mod_perl HTTP handlers and filters. To avoid this behaviour, this is one way to go:
sub handler  
    my($r) = shift;
    $r->status(400); # or the one you are interested in
    $r->content_type("text/plain");
    $r->print("You suck.");
    return Apache2::Const::OK;
 
You can also take a look at status_line that overrides status. You can also avoid the content_type method call if you are sloth enough. Now, this is what you get:

GET https://myserver/resource --> 400 Bad Request
Connection: close
Date: Mon, 05 Jan 2009 23:27:08 GMT
Content-Type: text/plain; charset=UTF-8
Client-Date: Mon, 05 Jan 2009 23:27:10 GMT
Client-Peer: 209.234.249.38:443
Client-Response-Num: 1
[ some headers snipped :) ]
You suck.
And so, beer awaits.

Benjamin Mako Hill: Change of Plans

One change and one addition to my current European tour. First, it looks like we'll be skipping Amsterdam this time and heading straight to London from Zagreb on the evening of January 10th. We'll still plan to arrive in Cambridge before the 13th. Second, I'll be giving a redux of my Revealing Errors talk at Mama in Zagreb on January 10th at 14:00 as part of the normal skill sharing meeting. It's the longer version of my OSCON keynote with many more examples. Folks who have seen earlier versions of the talk seem to think it's a lot of fun. If you are in or near Zagreb, you should come!

Benjamin Mako Hill: Debian Bug Squashing at MIT

I was thrilled to be part of a successful Debian bug squashing party organized by MIT's Student Information Processing Board on December 13th. Greg Price, who helped organize the event, did a wonderful write up which he sent to the debian-devel email list. I though it was worth mentioning the BSP now because I think it's a wonderful model that I'd love to see replicated in Debian and beyond. The event was initiated, organized, run, and executed by people with little or no direct experience with the project. While the organizers went out of their way to recruit several Debian developers and other experts to the party, these experts' role was more in answering questions and helping others. The the majority of the participants -- around 30 of them in total -- had no previous experience doing Debian development. While the 11 bugs closed or dealt with are the most visible outcome, I'm not sure that it is the most important. The event acted as an important learning experience for everyone involved and, perhaps most centrally, an important first step for most participants from using free software to giving back and participating in the community. You don't need experience, connections, or a @project.org email address to organize a party like this for Debian or your own free software project. All you really need is a few people, some technical knowledge, an Internet connection, and the desire to make it happen. Other things can help, of course. In particular, the SIPB folks have packaged up some scripts they used to select bugs to work on and put them online.

MJ Ray: Copyrighting the Future consultation ends this month

The Copyrighting the Future: Keeping ahead of the game consultation finishes in a month s time (6 February). They actually called it that - copyrighting the future - can you believe it? In case you haven t seen it yet, this is the consultation that ignores the Gowers review findings and tries to start it all over again. Please respond and try to avoid term extension, DRM/TPM and other similar landmines. Any comments you can leave me to help us all would be very much appreciated!

5 January 2009

Ben Hutchings: Searching for invalid object code

J r my Bobbio suggested that I should explain how I looked for packages affected by a compiler bug (Debian bug 506713; gcc bug 38287). I don't claim that this is a particularly good way to do it, but here it is: First, I identified a pattern to search for. Unfortunately I don't really understand the cause or fix for the bug, but I did have the example which led to this bug report: Debian bug 490999. The bad code was a stack-pointer-relative load immediately after a stack allocation (SPARC save instruction) where the offset was not adjusted for the stack allocation:
save  %sp, -112, %sp
ld  [ %sp + 0x40 ], %i5
I generalised this to:
save  %sp, offset1, sp
...
ld  [ %sp + offset2 ], register
where offset1 + offset2 < 0. Of course, this may be valid if the intervening instructions include a restore, branch or store to the effective stack location that the last instruction loads from. I ended up allowing up to 10 intervening instructions and examining a disassembly to work out which cases were valid. I looked up the instruction encoding for these two instructions. Thankfully SPARC is RISC so they are simple and regular: I took the dumb but effective approach of scanning entire files for this pattern rather than only scanning their code sections. This seemed to work - I got no false hits for non-code - but might not work for other patterns that could match ASCII text. I wrote the scanning program in Python, which is my default choice of language unless I know it's going to be too slow. I was hoping to be able to read the code files into arrays, but unfortunately the Python array type only supports the native byte-order (SPARC is big-endian and I was intending to use an x86 which is little-endian). I tried reading into a tuple using struct.unpack, which does support explicit byte-ordering, but this used so much memory for larger files that the program swapped to a crawl. So finally I resorted to reading the file into a string, doing a string search for '\x9d\xe3', rejecting matches that weren't appropriately aligned, then unpacking and comparing the code words from the point of the string match. (In Python 3.0 I would have to use the bytes type for this, as str is a Unicode string type.) So that's how I scanned single files. The next step was to find, unpack and scan all the SPARC shared libraries in the archive. (This particular code generation bug is understood to affect only PIC code, and that is normally only used in shared libraries.) I wrote functions to search Contents-sparc for shared library files - assumed to match the pattern ([^\s]*/lib[^/\s]+\.so(?:\.[^/\s]*)?) - and to parse Packages to find the filenames for the packages containing those files. The latter uses the debian_bundle.deb822 module from python-debian. The last key function downloads and unpacks a package using wget and dpkg-deb. I could have used the httplib module for downloading but I correctly anticipated that I'd need to restart the script several times so I wanted to cache the packages which was easier to do using wget. So, that's the explanation. If you really want to see it, here's the code.

Gunnar Wolf: DebGem is on its way

This morning, I got a mail that made me very happy. I followed it up a bit, and some hours later, echoed it over the pkg-ruby-extras list. And, yes, a blog posting won't hurt :)
I have done some rantings on why it is so painful to integrate cultures such as Debian and Rails. Those rants were part of quite a large rant-net and attracted a fair share of traffic/comments over here. Flamefesting over your blog is fun! :-) but anyway, I am delighted to say that at least some people worth their weight in code were watching, interested.
The mail I got this morning (yes, follow the links above!) was from Hongli Lai, one of the very nice people at Phusion - The people behind Phusion Passenger (a.k.a. mod_rails) and Ruby Enterprise Edition. Yes, people with a very different mindset to mine (specially when it comes to being a 100% Free Software person).
Hongli invited me to try their new DebGem service (still in Beta, although quite usable as it is). They are offering an auto-built full repository of Rubyforge, translated to Debian packages. They are currently supporting Debian 4.0 (Etch) and Ubuntu 8.04 and 8.10 (Intrepid and Hardy). And, yes, installing any arbitrary Ruby module is now just as easy as aptitude install libsomething-ruby. For over 20,000 Gems.
There is a catch, yes. The service is currently free, while they finish the public beta period. Their pricing is available.
Best luck to you guys. And... Shall you enjoy fierce competition from Debian proper! ;-)
[Update]: They just posted the official Beta announcement for DebGem

Benjamin Mako Hill: Lookalike

Is Richard Stallman leading a secret life as Serbian Nationalist "Chetnik" Zoran Radovanovic? /copyrighteous/images/lookalike_rms_zoran.png

Vincent Fourmond: Process substitution is cool !

I've finally found some time to work on ctioga again ! My main problem there is that I keep adding new features without ever bothering to document them... One of my main concerns is therefore to find out about the list of command-line switches that are not documented in the manual page. I've just written a neat shell one-liner that precisely does that:
diff <(man -a -l $HOME/SciYAG/ctioga/doc/ctioga.1   \
  egrep -o -- '--[a-z0-9-]+'   sort   uniq) \
  <(ctioga --help   egrep -o -- '--[][a-z0-9-]+'   \
  sort   uniq)   colordiff   less -R
(of course, I broke it into lines for clarity). It is based on process substitution, a shell trick that lets you use the output/input of a shell command exactly as a file on command line. Neat ! The trouble is, replacing the colordiff... part by egrep '^>' wc tells me there are 65 undocumented features... Lots of work in perspective, and I'm not sure I'll do it all before the 1.9 release...

MJ Ray: journals.aol.com closure botched

America OnLine (AOL) killed their blogging service - actually, all their Hometown sites - last September and I only just noticed. AOL didn t kill it cleanly. They could have offered 301 Moved Permanently redirects to users new hosting (good - maybe no interruption to users), returning a 404 Not Found with an explanation (OK - software like RSS readers would detect the serious problem) or even simply taking the hostname offline (bad, but better than what they did). Instead, AOL 301-redirected everyone to a page on their own journal (which hasn t closed down) to sincerely apologize for any inconvenience . It wouldn t have been so much inconvenience if it had been closed down cleanly. I was only reading one journal there (Pripensulo) which I can t find anywhere else, but I m surprised by the incompetent webmastering. AOL s webmasters run managing massive (if bland) websites, after all, and if they re smart enough to do a 301 redirect to their apology, then they re smart enough to do a useful redirect or a 404 Not Found. Why didn t they? Don t they care about their users? Are they trying to take SEO points from all their users and give them to People Connection?

4 January 2009

Andrew Pollock: [tech] Feed breakage, Blosxom's shiteful RSS 0.91 implementation

(or echo "blosxom hold" sudo dpkg --set-selections) A few people had pointed out to me that my blog was appearing weirdly in Google Reader. I myself read my blog via Planet Debian and Planet Linux Australia, where it appears fine, so I hadn't noticed the problem first hand. I did some digging tonight with the Feed Validator, and I think I've figured it out. Funnily enough, it all started with a previous session with the Feed Validator... I wanted my blog to be UTF-8, with it being the new hotness and all. Blosxom was spitting it out as ISO-8859-1. I've just learned from this evening's debugging, that this is the behaviour of CGI.pm's header() function if not provided with the -charset parameter. I'd previously worked around this by defining my own content_type for the RSS and HTML flavours. In this file, I just put text/xml; charset=utf-8and text/html; charset=utf-8, respectively. Unfortunately, this then breaks Blosxom's internal HTML-escaping-for-RSS-feed code, which is conditional on the content type being XML:
if ($content_type =~ m \Wxml$ )  
        # Escape <, >, and &amp;, and to produce valid RSS
        my %escape = ('<'=>'&lt;', '>'=>'&gt;', '&'=&gt;'&', '"'=>'&quot;');  
        my $escape_re  = join ' ' => keys %escape;
        $title =~ s/($escape_re)/$escape $1 /g;
        $body =~ s/($escape_re)/$escape $1 /g;
       
This block of code was being ignored because the regex was anchored. "text/xml; charset=utf-8" didn't match "\Wxml$". Whenever I last had an attempt to make my blog's feed pass the Feed Validator, I must have edited the Blosxom source code to make this regex not be anchored. Then on November 11, 2008, I updated my Blosxom package to 2.0-14+etch1, to address CVE-2008-2236 (incidentally, there doesn't appear to be a Debian Security Advisory for this?), and my local modification got clobbered. That'll teach me to make local modifications and not put the package on hold. Blah. It seems I'm screwed, there's no way to have a well-formed UTF-8 RSS feed without requiring a source-code modification to Blosxom. I've either got to change the way the header() function is being called, or I've got to change the regex to allow me to specify a charset in the flavour file, and not disable HTML escaping. Speaking of screwed, Blosxom seems incapable of making a well-formed RSS 0.91 feed anyway. It wants to put the <pubDate> tag inside an <item>, which is a violation of the DTD. There's supposed to be one for the whole <channel>, not one per item (or "story" in Blosxom-flavour-speak). You can't just move that from the story flavour file to the head flavour file, because a pile of variables that you'd otherwise use seem to only get set on a per-story basis. Double blah. I'm starting to feel like Blosxom is outliving its usefulness, but I really do not feel like embarking on a wholesale move to a new blogging platform, I'm fairly entrenched.

Jeff Bailey: ... 2008

I try to practice Inbox Zero, and this past year has been brutal far staying on top of my Inbox. When I started pruning the home email a week or so ago (having just gotten my work email box down to zero). It's giving me a pretty good review of 2008. And, umm.. wow:

Spinal tumor, surgery, hating Mountain View (the place, not the job there. My coworkers are pretty uniformly awesome), having a toddler, not being able to lift my toddler, crazy mood altering drugs, visa renewal, a funeral, unexpected pregnancy, weddings, buying a house, mid-term miscarriage, Angie's hospitalisation from that, pneumonia, a move home, having to withdraw from my Master's courses 3 times over the course of the year for medical reasons - eventually causing me to withdraw from the program. Extend it by another 3 months into 2007 (because while I'd love to believe that stress reset at the start of a calendar year...), and we have another wedding, a move to the US and a new job.

I've just gotten to an email where I took notes on what the risks were for the angiogram before I'd told many friends. There's a small pile of emails and such from people wishing me well that I never managed to reply to. I also find myself thinking back to the people I didn't hear from, and the reevaluation of my communities and friendships that came along with that.

The lyrics from Counting Crows come to mind: "It's been a long December and there's reason to believe that maybe this year will be better than the last."

Here's to 2009. =)

Andrew Pollock: [tech] Mixing electricity and water: monitoring the cat water bowl with Nagios

(this is something I've had "in production" for many months now, I just haven't had the time or energy to do a proper write up about what I did) We have a cat water bowl, it looks like this: The cat water bowl Under "normal" circumstances, it usually lasts about seven days. So when our weekly routine is happening, we'll refill it on a Saturday whilst doing house chores, and it'll last until the following Saturday when it gets refilled. Unfortunately, sometimes our routine gets disrupted, and we forget. Sometimes, we travel and have a house-sitter, who may not pay as close attention to such things as ourselves. Once, one of our cats was licking the condensation off a chilled bottle of soft drink that was on the kitchen counter one evening, before we realised the water bowl needed refilling. Naturally, we felt like terrible pet owners. So I think it was some time around the 2008 Maker Faire, that I hatched the idea of having some sort of water sensor on the cat bowl, which would communicate to one of the various computers in house. At the Maker Faire, I bought a copy of Making things talk, and an Arduino starter kit, which consisted of a Diecimila board and a make-it-yourself proto shield. I also bought a little electronics starter kit, which consisted of a breadboard and various components, and a USB-TTL cable. I decided to use Bluetooth to communicate with the board, as I already had my MythTV setup using a Bluetooth keyboard and mouse, and it was within range of the water bowl. I decided against using Zigbee, because I didn't know anything about it, and I didn't want to add (or learn about) yet another wireless infrastructure just for this project. I should point out that I know very little about electronics. I'd never owned (or really used) a soldering iron until I embarked on this project. I took a basic soldering class at the Tech Shop, but I'd already assembled the proto shield by the time I took the class, so I'd pretty much figured it out. I had a very naive vision that I could just basically shove two wires in some water and it'd close a circuit and that would be my water sensor. Of course this didn't work, so I started hunting around on the Internet for a circuit that would do this. I happened upon a circuit (I don't seem to have retained the URL, so I can't link to it), which just consisted of a couple of transistors and some resistors. So I headed off to Fry's to try and buy the transistors I needed. I quickly discovered that I didn't have sufficient information to identify the transistors that I wanted, but I did happen to stumble upon a cheap assemble-it-yourself water alarm. It consisted of a PCB, and a transistor and some resistors and a buzzer. I bought a couple of these instead. Between studying the PCB and the circuit diagram that came with the alarm, I was able to reproduce it on my breadboard instead of on the PCB. Sure enough, placing the two probes in water closed the circuit. I replaced the buzzer with an LED so I could see what was going on. I attached the circuit to the Arduino proto shield, and had it feed into one of the digital I/O ports. I wrote some quick and dirty Wiring code so that when water not present (i.e. the circuit was open and no current was detected on that I/O port) the LED was switched on. Really at this point, I didn't need a microcontroller, I could have presumably achieved the same thing with a NOT gate. At this point, I wanted to make the sensor remotely queryable. I bought a BlueSMiRF Silver Bluetooth modem, which I attached to the TX and RX lines of the board (I first configured it by attaching the USB-TTL cable to it and using Minicom on my laptop). I extended the Wiring code to provide a rudimentary prompt, and accept a command to check if water was present. I think around this time it also dawned on me that I could use the digital I/O pins as a switch. When they're "high" they provide power. So rather than constantly running a current through the water, I only needed to briefly power up the water detection circuit, see if the circuit closed or not, and then report if water was present if it did. I much preferred this, as at the time, I was endeavouring to power the whole sensor off a 9 volt battery. I figured I'd get much better battery life if I wasn't running a current through the water the entire time. I should point out that I did some "tongue tests" in a glass of water while the circuit was powered up, and couldn't detect a difference between when the circuit was on or off. The last thing I wanted to be doing was zapping the cats! At this point, the Wiring and Arduino work was pretty much complete. I setup ser2net on the MythTV server, so that I could just connect to port 4000, and be connected to the water sensor.
apollock@icarus:~$ telnet teevee 4000
Trying 172.16.0.9...
Connected to teevee.andrew.net.au.
Escape character is '^]'.
ser2net port 4000 device /dev/rfcomm0 [9600 N81] (Debian GNU/Linux)
waterbowl> s
Water is present
waterbowl>
telnet> q
Connection closed.
apollock@icarus:~$
The Wiring code running on the Arduino board is checked in here. Next, I wanted to monitor this with Nagios. One thing I found with the Bluetooth connection was that it wasn't all that reliable. Not every connection to port 4000 resulted in a connection with the water sensor. I elected to write some standalone code that submitted results to Nagios by way of a passive check, rather than having Nagios try to actively monitor it. Again, trying to conserve energy, I decided to only check the sensor once every 8 hours. So I wrote a Python daemon, which tried to be as robust as possible. If at first it doesn't make a connection on its 8 hourly schedule, it keeps trying until it does. Nagios itself has some freshness detection for this monitor, so if no passive result is submitted within 8 hours and one minute, Nagios alerts that something is possibly wrong with the sensor itself. (The original intent was to deal with the situation where the battery went flat) This is the Nagios service definition I've got. Some of it may be unnecessary or redundant:
define service  
        host_name                       teevee
        service_description             Cat water bowl
        check_command                   check_stale!2!"Check water bowl monitor is on and reachable"
        normal_check_interval           480
        notification_interval           240
        active_checks_enabled           0
        check_freshness                 1
        freshness_threshold             28860
        max_check_attempts              1
        check_period                    24x7
        use                             generic-service
        stalking_options                o,w,c
        contact_groups                  everyone
 
The code for the Python daemon is checked in here. So everything was going swimmingly, apart from I couldn't get even 24 hours of monitoring on my conservative 3 times a day schedule, and the Bluetooth modem configured for all of its power saving options, and the water sensor itself only being powered on when it was performing a check. There wasn't much more I could do to try and reduce power consumption, at least with my limited electronics knowledge. Perhaps using Zigbee instead of Bluetooth would have helped, but I still think I'd have been going through 9 volt batteries more quickly than I'd have liked. I also had a brief foray into solar powering the board. I thought maybe the lighting in the house would be sufficient to power the board. Of course this didn't work out. I'd also have needed to make the code running on the board more self-sufficient, and have it just provide a water status indication whenever it had enough power to do so, instead of being a fairly dumb device like it currently is. This all felt a whole level more complicated, and out of my league, and I wasn't interested in attempting this sort of remote-sensing exercise at this time. The Arduino board can also be powered by USB, so as I already had some long USB type A to type B cables (that had funky lights in them to boot), I decided to just get a wall wart that had a USB type A receptacle, and powered the Arduino board that way. So much for being completely "wireless". (I could have also gotten a general purpose DC power supply that was capable of spitting out 9 volts, but I doubted I'd get one with a sufficiently long cable, which is why I went for the USB-powered option, as I already had a cable long enough) Speaking of wires, the most challenging part was the probes for the water sensor. As they were going to be permanently in the cats' drinking water, I didn't want to contaminate the water with them. I figured plain untinned copper wire would be okay, since water pipes are copper. Finding untinned, unstranded copper wire was a real challenge. I started out using some FM antenna cable, but that was stranded, and the shielding was a nightmare to strip. It was also reasonably difficult to make go where I wanted it. What I really wanted was something more solid, that would flex and stay where I put it. I cannibalised a spare IEC power cable, but it was also stranded copper wire. I finally managed to obtain some solid-core CAT-5 cable from a hardware store, and this has worked exactly as I wanted. I haven't done any further work on the setup since getting the CAT-5 cable for the probe. Further improvements that I'd like to do at some point: The finished product I had a lot of fun with this project. I had a real sense of achievement, being able to go from concept to completion, and learn a few things about electronics along the way. I'm normally not a fan of messing around with hardware. Some photos of the project are here.

Wouter Verhelst: Quake I

Years ago I think some two years after it was released I bought me a copy of Quake. I found the original box in a shop that had just one left, and was selling it at a serious discount; I still have the box, with the original artwork. I didn't have Internet at the time, though, so I never played it online. I did finish the game at one point, though I don't remember whether it was with or without cheatcodes. I'm certain I got very far, though I had a tendency to start using cheatcodes when the monsters I had to pass got too hard for me to actually be able to pass them. When I did get an Internet connection, Quake III Arena had just been released, so not many people still played Quake I. However, my very own ISP then did have a QuakeWorld server still running, and I fondly remember playing a lot on that server. Since I hadn't heard of +mlook, which enables modern-style mouse-based movement in quake, I was still playing with doom-style controls, that is, keyboard only. At first I got fragged all the time, but it didn't take me long to master this method. I got so good at it that I've won some deathmatch games, with keyboard only. Seriously. Eventually, however, I migrated to a state where I did not have any Microsoft operating systems installed on my system anymore; and while Debian had a 'quakeforge' package in potato, it was rather buggy; I remember it would reproducibly crash when you would load a particular level from the third episode. I did think about fixing the code, but then I didn't really have the time or expertise to do so, so that never got anywhere. Eventually, it was pulled from the archives; and after a while around the time when my ISP shut down their quakeworld server I stopped playing Quake; and though I was sad about it not being installed anymore, I just forgot about it. Recently, however, I somehow stumbled upon this 'Linux Quake HOWTO' over at tldp, and noticed that apart from Quakeforge, there really are other engines, and there really still is a Quake I community around. With quakeworld servers and everything. Oh boy. So I installed this 'tyrquake' a few days ago, and I've now already reached episode 3. Some things are coming back, but others aren't really... Of course, when I connect to one of those quakeworld servers, I get fragged all over. I'm lucky when I end up with a positive frag count. For reference: in Quake I, you only lose frag points when you kill yourself... Hah. To be continued, I guess...

Neil Williams: Installing Emdebian Grip with D-I

A few experiments have led to a partial route to pre-seeding Emdebian Grip from a standard Debian Lenny ISO. A few issues arise:


Overall, it is possible to install Emdebian Grip - with a little help - using Debian Installer. A few more changes should make it possible to select a standard Emdebian Grip installation without X and an Emdebian Grip XFCE desktop.

Remaining issues include:


A bespoke config package can be arranged for this purpose - it won't be compliant with Debian Policy, at least as far as the status of Policy for Lenny.

Lots more to do but Lenny is still in-progress so there's time to get a usable installation before FOSDEM.

Next.

Previous.