Search Results: "cts"

26 March 2017

Dirk Eddelbuettel: RcppTOML 0.1.2

A new release of RcppTOML is now on CRAN. This release fixes a few parsing issues for less frequently-used inputs: vectors of boolean or date(time) types, as well as table array input. RcppTOML brings TOML to R. TOML is a file format that is most suitable for configurations, as it is meant to be edited by humans but read by computers. It emphasizes strong readability for humans while at the same time supporting strong typing as well as immediate and clear error reports. On small typos you get parse errors, rather than silently corrupted garbage. Much preferable to any and all of XML, JSON or YAML -- though sadly these may be too ubiquitous now. TOML is making good inroads with newer and more flexible projects such as the Hugo static blog compiler, or the Cargo system of Crates (aka "packages") for the Rust language.

Changes in version 0.1.2 (2017-03-26)
  • Dates and Datetimes in arrays in the input now preserve their types instead of converting to numeric vectors (#13)
  • Boolean vectors are also correctly handled (#14)
  • TableArray types are now stored as lists in a single named list (#15)
  • The README.md file was expanded with an example and screenshot.
  • Added file init.c with calls to R_registerRoutines() and R_useDynamicSymbols(); also use .registration=TRUE in useDynLib in NAMESPACE
  • Two example files were updated.

Courtesy of CRANberries, there is a diffstat report for this release. More information is on the RcppTOML page page. Issues and bugreports should go to the GitHub issue tracker.

This post by Dirk Eddelbuettel originated on his Thinking inside the box blog. Please report excessive re-aggregation in third-party for-profit settings.

24 March 2017

Gunnar Wolf: Dear lazyweb: How would you visualize..?

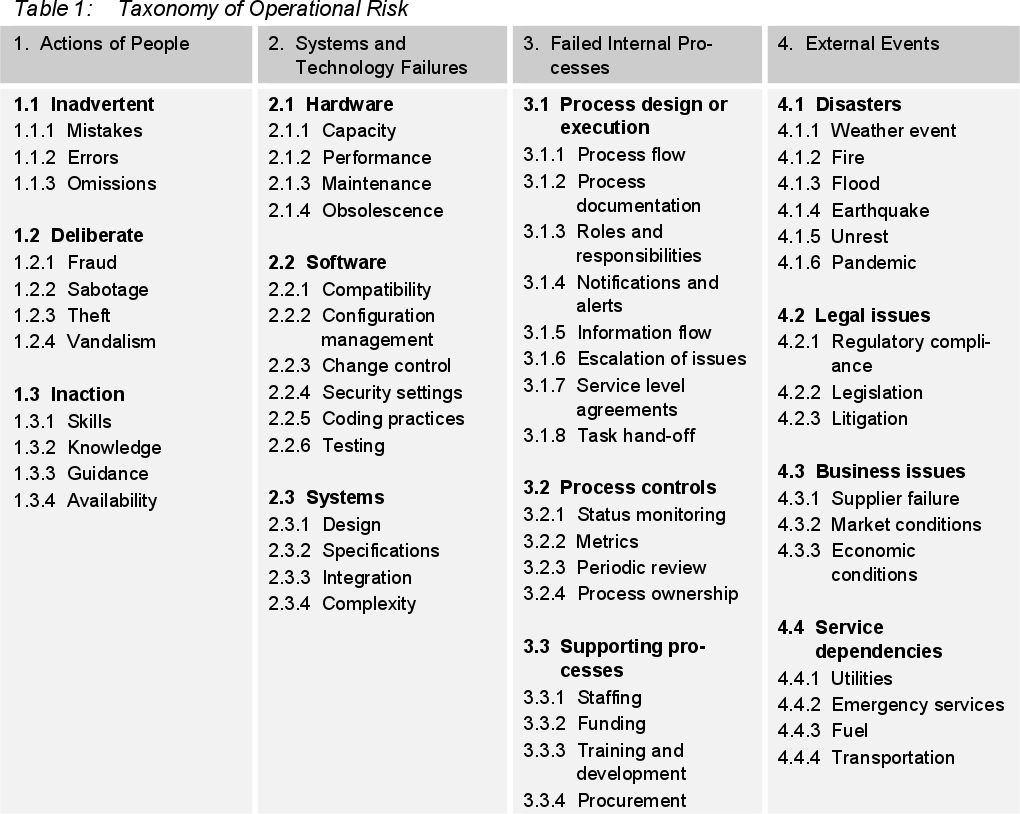
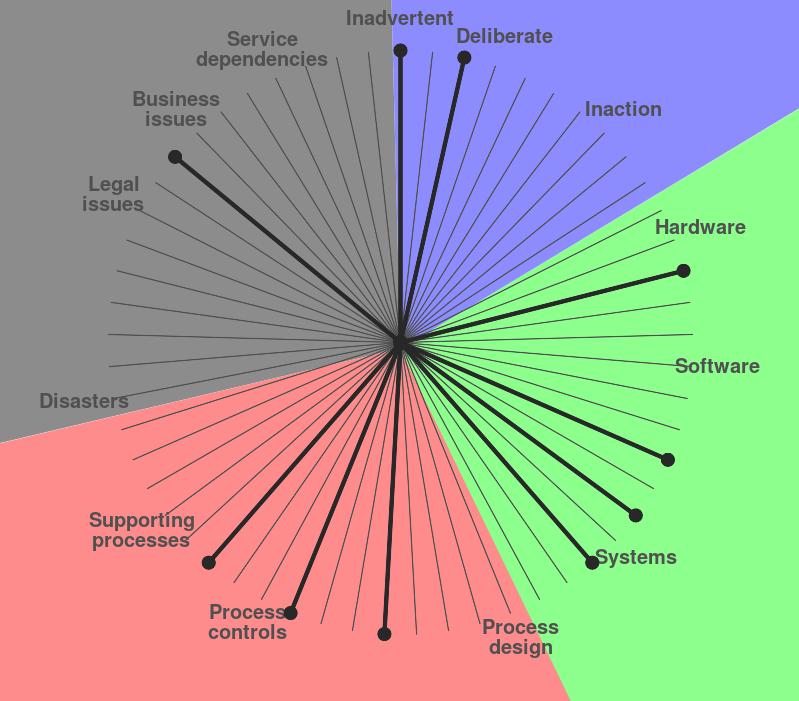
Dear lazyweb, I am trying to get a good way to present the categorization of several cases studied with a fitting graph. I am rating several vulnerabilities / failures according to James Cebula et. al.'s paper, A taxonomy of Operational Cyber Security Risks; this is a somewhat deep taxonomy, with 57 end items, but organized in a three levels deep hierarchy. Copying a table from the cited paper (click to display it full-sized): My categorization is binary: I care only whether it falls within a given category or not. My first stab at this was to represent each case using a star or radar graph. As an example: As you can see, to a "bare" star graph, I added a background color for each top-level category (blue for actions of people, green for systems and technology failures), red for failed internal processes and gray for external events), and printed out only the labels for the second level categories; for an accurate reading of the graphs, you have to refer to the table and count bars. And, yes, according to the Engineering Statistics Handbook:
Star plots are helpful for small-to-moderate-sized multivariate data sets. Their primary weakness is that their effectiveness is limited to data sets with less than a few hundred points. After that, they tend to be overwhelming.
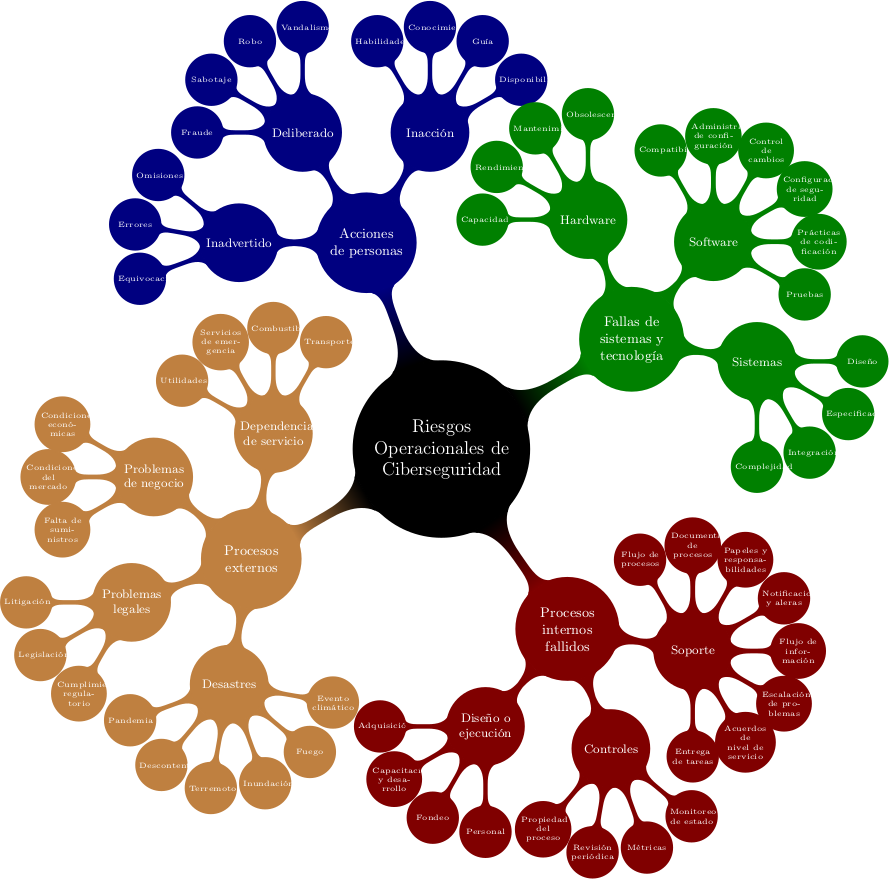
I strongly agree with the above statement And stating that "a few hundred points" can be understood is even an overstatement. 50 points are just too much. Now, trying to increase usability for this graph, I came across the Sunburst diagram. One of the proponents for this diagram, John Stasko, has written quite a bit about it. Now... How to create my beautiful Sunburst diagram? That's a tougher one. Even though the page I linked to in the (great!) Data visualization catalogue presents even some free-as-in-software tools to do this... They are Javascript projects that will render their beautiful plots (even including an animation)... To the browser. I need them for a static (i.e. to be printed) document. Yes, I can screenshot and all, but I want them to be automatically generated, so I can review and regenerate them all automatically. Oh, I could just write JSON and use SaaS sites such as Aculocity to do the heavy-lifting, but if you know me, you will understand why I don't want to. So... I set out to find a Gunnar-approved way to display the information I need. Now, as the Protovis documentation says, an icicle is simply a sunburst transformed from polar to cartesian coordinates... But I came to a similar conclusion: The tools I found are not what I need. OK, but an icicle graph seems much simpler to produce I fired up my Emacs, and started writing using Ruby, RMagick and RVG... I decided to try a different way. This is my result so far: So... What do you think? Does this look right to you? Clearer than the previous one? Worst? Do you have any idea on how I could make this better? Oh... You want to tell me there is something odd about it? Well, yes, of course! I still need to tweak it quite a bit. Would you believe me if I told you this is not really a left-to-right icicle graph, but rather a strangely formatted Graphviz non-directed graph using the dot formatter? I can assure you you don't want to look at my Graphviz sources... But in case you insist... Take them and laugh. Or cry. Of course, this file comes from a hand-crafted template, but has some autogenerated bits to it. I have still to tweak it quite a bit to correct several of its usability shortcomings, but at least it looks somewhat like what I want to achieve. Anyway, I started out by making a "dear lazyweb" question. So, here it goes: Do you think I'm using the right visualization for my data? Do you have any better suggestions, either of a graph or of a graph-generating tool? Thanks! [update] Thanks for the first pointer, Lazyweb! I found a beautiful solution; we will see if it is what I need or not (it is too space-greedy to be readable... But I will check it out more thoroughly). It lays out much better than anything I can spew out by myself Writing it as a mindmap using TikZ directly from within LaTeX, I get the following result:

23 March 2017

Simon McVittie: GTK hackfest 2017: D-Bus communication with containers

At the GTK hackfest in London (which accidentally became mostly a Flatpak hackfest) I've mainly been looking into how to make D-Bus work better for app container technologies like Flatpak and Snap. The initial motivating use cases are: At the moment, Flatpak runs a D-Bus proxy for each app instance that has access to D-Bus, connects to the appropriate bus on the app's behalf, and passes messages through. That proxy is in a container similar to the actual app instance, but not actually the same container; it is trusted to not pass messages through that it shouldn't pass through. The app-identification mechanism works in practice, but is Flatpak-specific, and has a known race condition due to process ID reuse and limitations in the metadata that the Linux kernel maintains for AF_UNIX sockets. In practice the use of X11 rather than Wayland in current systems is a much larger loophole in the container than this race condition, but we want to do better in future. Meanwhile, Snap does its sandboxing with AppArmor, on kernels where it is enabled both at compile-time (Ubuntu, openSUSE, Debian, Debian derivatives like Tails) and at runtime (Ubuntu, openSUSE and Tails, but not Debian by default). Ubuntu's kernel has extra AppArmor features that haven't yet gone upstream, some of which provide reliable app identification via LSM labels, which dbus-daemon can learn by querying its AF_UNIX socket. However, other kernels like the ones in openSUSE and Debian don't have those. The access-control (AppArmor mediation) is implemented in upstream dbus-daemon, but again doesn't work portably, and is not sufficiently fine-grained or flexible to do some of the things we'll likely want to do, particularly in dconf. After a lot of discussion with dconf maintainer Allison Lortie and Flatpak maintainer Alexander Larsson, I think I have a plan for fixing this. This is all subject to change: see fd.o #100344 for the latest ideas. Identity model Each user (uid) has some uncontained processes, plus 0 or more containers. The uncontained processes include dbus-daemon itself, desktop environment components such as gnome-session and gnome-shell, the container managers like Flatpak and Snap, and so on. They have the user's full privileges, and in particular they are allowed to do privileged things on the user's session bus (like running dbus-monitor), and act with the user's full privileges on the system bus. In generic information security jargon, they are the trusted computing base; in AppArmor jargon, they are unconfined. The containers are Flatpak apps, or Snap apps, or other app-container technologies like Firejail and AppImage (if they adopt this mechanism, which I hope they will), or even a mixture (different app-container technologies can coexist on a single system). They are containers (or container instances) and not "apps", because in principle, you could install com.example.MyApp 1.0, run it, and while it's still running, upgrade to com.example.MyApp 2.0 and run that; you'd have two containers for the same app, perhaps with different permissions. Each container has an container type, which is a reversed DNS name like org.flatpak or io.snapcraft representing the container technology, and an app identifier, an arbitrary non-empty string whose meaning is defined by the container technology. For Flatpak, that string would be another reversed DNS name like com.example.MyGreatApp; for Snap, as far as I can tell it would look like example-my-great-app. The container technology can also put arbitrary metadata on the D-Bus representation of a container, again defined and namespaced by the container technology. For instance, Flatpak would use some serialization of the same fields that go in the Flatpak metadata file at the moment. Finally, the container has an opaque container identifier identifying a particular container instance. For example, launching com.example.MyApp twice (maybe different versions or with different command-line options to flatpak run) might result in two containers with different privileges, so they need to have different container identifiers. Contained server sockets App-container managers like Flatpak and Snap would create an AF_UNIX socket inside the container, bind() it to an address that will be made available to the contained processes, and listen(), but not accept() any new connections. Instead, they would fd-pass the new socket to the dbus-daemon by calling a new method, and the dbus-daemon would proceed to accept() connections after the app-container manager has signalled that it has called both bind() and listen(). (See fd.o #100344 for full details.) Processes inside the container must not be allowed to contact the AF_UNIX socket used by the wider, uncontained system - if they could, the dbus-daemon wouldn't be able to distinguish between them and uncontained processes and we'd be back where we started. Instead, they should have the new socket bind-mounted into their container's XDG_RUNTIME_DIR and connect to that, or have the new socket set as their DBUS_SESSION_BUS_ADDRESS and be prevented from connecting to the uncontained socket in some other way. Those familiar with the kdbus proposals a while ago might recognise this as being quite similar to kdbus' concept of endpoints, and I'm considering reusing that name. Along with the socket, the container manager would pass in the container's identity and metadata, and the method would return a unique, opaque identifier for this particular container instance. The basic fields (container technology, technology-specific app ID, container ID) should probably be added to the result of GetConnectionCredentials(), and there should be a new API call to get all of those plus the arbitrary technology-specific metadata. When a process from a container connects to the contained server socket, every message that it sends should also have the container instance ID in a new header field. This is OK even though dbus-daemon does not (in general) forbid sender-specified future header fields, because any dbus-daemon that supported this new feature would guarantee to set that header field correctly, the existing Flatpak D-Bus proxy already filters out unknown header fields, and adding this header field is only ever a reduction in privilege. The reasoning for using the sender's container instance ID (as opposed to the sender's unique name) is for services like dconf to be able to treat multiple unique bus names as belonging to the same equivalence class of contained processes: instead of having to look up the container metadata once per unique name, dconf can look it up once per container instance the first time it sees a new identifier in a header field. For the second and subsequent unique names in the container, dconf can know that the container metadata and permissions are identical to the one it already saw. Access control In principle, we could have the new identification feature without adding any new access control, by keeping Flatpak's proxies. However, in the short term that would mean we'd be adding new API to set up a socket for a container without any access control, and having to keep the proxies anyway, which doesn't seem great; in the longer term, I think we'd find ourselves adding a second new API to set up a socket for a container with new access control. So we might as well bite the bullet and go for the version with access control immediately. In principle, we could also avoid the need for new access control by ensuring that each service that will serve contained clients does its own. However, that makes it really hard to send broadcasts and not have them unintentionally leak information to contained clients - we would need to do something more like kdbus' approach to multicast, where services know who has subscribed to their multicast signals, and that is just not how dbus-daemon works at the moment. If we're going to have access control for broadcasts, it might as well also cover unicast. The plan is that messages from containers to the outside world will be mediated by a new access control mechanism, in parallel with dbus-daemon's current support for firewall-style rules in the XML bus configuration, AppArmor mediation, and SELinux mediation. A message would only be allowed through if the XML configuration, the new container access control mechanism, and the LSM (if any) all agree it should be allowed. By default, processes in a container can send broadcast signals, and send method calls and unicast signals to other processes in the same container. They can also receive method calls from outside the container (so that interfaces like org.freedesktop.Application can work), and send exactly one reply to each of those method calls. They cannot own bus names, communicate with other containers, or send file descriptors (which reduces the scope for denial of service). Obviously, that's not going to be enough for a lot of contained apps, so we need a way to add more access. I'm intending this to be purely additive (start by denying everything except what is always allowed, then add new rules), not a mixture of adding and removing access like the current XML policy language. There are two ways we've identified for rules to be added: Initially, many contained apps would work in the first way (and in particular sockets=session-bus would add a rule that allows almost everything), while over time we'll probably want to head towards recommending more use of the second. Related topics Access control on the system bus We talked about the possibility of using a very similar ruleset to control access to the system bus, as an alternative to the XML rules found in /etc/dbus-1/system.d and /usr/share/dbus-1/system.d. We didn't really come to a conclusion here. Allison had the useful insight that the XML rules are acting like a firewall: they're something that is placed in front of potentially-broken services, and not part of the services themselves (which, as with firewalls like ufw, makes it seem rather odd when the services themselves install rules). D-Bus system services already have total control over what requests they will accept from D-Bus peers, and if they rely on the XML rules to mediate that access, they're essentially rejecting that responsibility and hoping the dbus-daemon will protect them. The D-Bus maintainers would much prefer it if system services took responsibility for their own access control (with or without using polkit), because fundamentally the system service is always going to understand its domain and its intended security model better than the dbus-daemon can. Analogously, when a network service listens on all addresses and accepts requests from elsewhere on the LAN, we sometimes work around that by protecting it with a firewall, but the optimal resolution is to get that network service fixed to do proper authentication and access control instead. For system services, we continue to recommend essentially this "firewall" configuration, filling in the $ variables as appropriate:
<busconfig>
    <policy user="$ the daemon uid under which the service runs ">
        <allow own="$ the service's bus name "/>
    </policy>
    <policy context="default">
        <allow send_destination="$ the service's bus name "/>
    </policy>
</busconfig>
We discussed the possibility of moving towards a model where the daemon uid to be allowed is written in the .service file, together with an opt-in to "modern D-Bus access control" that makes the "firewall" unnecessary; after some flag day when all significant system services follow that pattern, dbus-daemon would even have the option of no longer applying the "firewall" (moving to an allow-by-default model) and just refusing to activate system services that have not opted in to being safe to use without it. However, the "firewall" also protects system bus clients, and services like Avahi that are not bus-activatable, against unintended access, which is harder to solve via that approach; so this is going to take more thought. For system services' clients that follow the "agent" pattern (BlueZ, polkit, NetworkManager, Geoclue), the correct "firewall" configuration is more complicated. At some point I'll try to write up a best-practice for these. New header fields for the system bus At the moment, it's harder than it needs to be to provide non-trivial access control on the system bus, because on receiving a method call, a service has to remember what was in the method call, then call GetConnectionCredentials() to find out who sent it, then only process the actual request when it has the information necessary to do access control. Allison and I had hoped to resolve this by adding new D-Bus message header fields with the user ID, the LSM label, and other interesting facts for access control. These could be "opt-in" to avoid increasing message sizes for no reason: in particular, it is not typically useful for session services to receive the user ID, because only one user ID is allowed to connect to the session bus anyway. Unfortunately, the dbus-daemon currently lets unknown fields through without modification. With hindsight this seems an unwise design choice, because header fields are a finite resource (there are 255 possible header fields) and are defined by the D-Bus Specification. The only field that can currently be trusted is the sender's unique name, because the dbus-daemon sets that field, overwriting the value in the original message (if any). To make it safe to rely on the new fields, we would have to make the dbus-daemon filter out all unknown header fields, and introduce a mechanism for the service to check (during connection to the bus) whether the dbus-daemon is sufficiently new that it does so. If connected to an older dbus-daemon, the service would not be able to rely on the new fields being true, so it would have to ignore the new fields and treat them as unset. The specification is sufficiently vague that making new dbus-daemons filter out unknown header fields is a valid change (it just says that "Header fields with an unknown or unexpected field code must be ignored", without specifying who must ignore them, so having the dbus-daemon delete those fields seems spec-compliant). This all seemed fine when we discussed it in person; but GDBus already has accessors for arbitrary header fields by numeric ID, and I'm concerned that this might mean it's too easy for a system service to be accidentally insecure: It would be natural (but wrong!) for an implementor to assume that if g_message_get_header (message, G_DBUS_MESSAGE_HEADER_FIELD_SENDER_UID) returned non-NULL, then that was guaranteed to be the correct, valid sender uid. As a result, fd.o #100317 might have to be abandoned. I think more thought is needed on that one. Unrelated topics As happens at any good meeting, we took the opportunity of high-bandwidth discussion to cover many useful things and several useless ones. Other discussions that I got into during the hackfest included, in no particular order: More notes are available from the GNOME wiki. Acknowledgements The GTK hackfest was organised by GNOME and hosted by Red Hat and Endless. My attendance was sponsored by Collabora. Thanks to all the sponsors and organisers, and the developers and organisations who attended.

Mike Hommey: Why is the git-cinnabar master branch slower to clone?

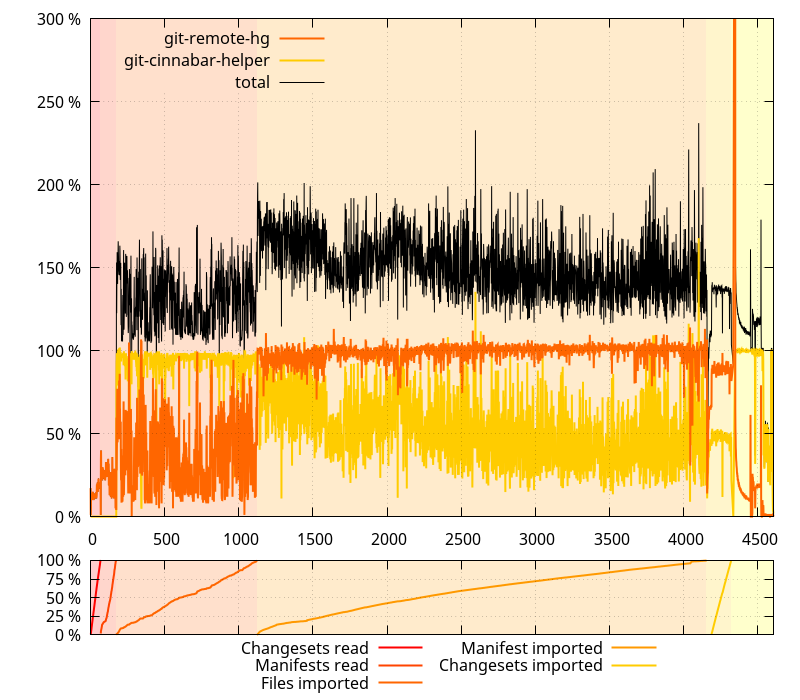
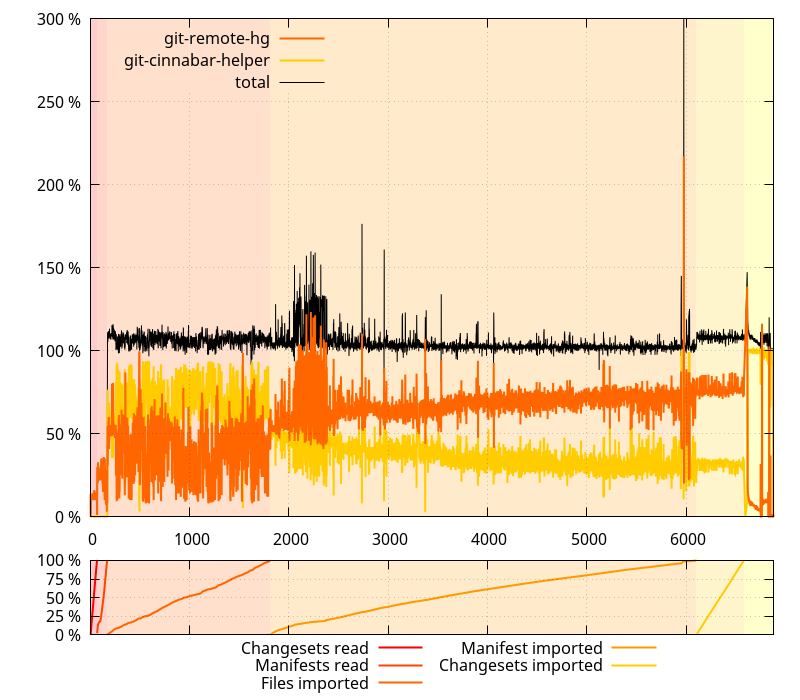
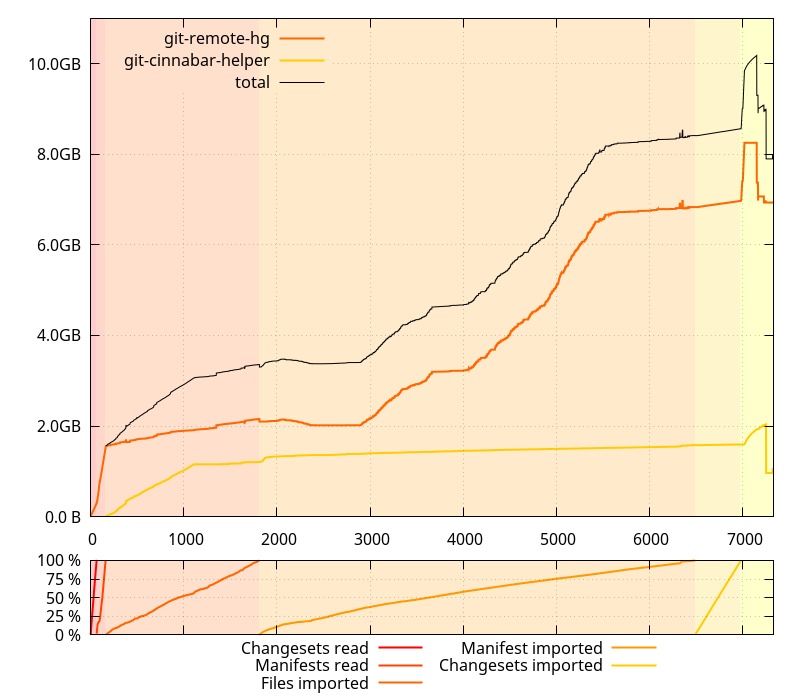
Apart from the memory considerations, one thing that the data presented in the When the memory allocator works against you post that I haven t touched in the followup posts is that there is a large difference in the time it takes to clone mozilla-central with git-cinnabar 0.4.0 vs. the master branch. One thing that was mentioned in the first followup is that reducing the amount of realloc and substring copies made the cloning more than 15 minutes faster on master. But the same code exists in 0.4.0, so this isn t part of the difference. So what s going on? Looking at the CPU usage during the clone is enlightening. On 0.4.0: On master: (Note: the data gathering is flawed in some ways, which explains why the git-remote-hg process goes above 100%, which is not possible for this python process. The data is however good enough for the high level analysis that follows, so I didn t bother to get something more acurate) On 0.4.0, the git-cinnabar-helper process was saturating one CPU core during the File import phase, and the git-remote-hg process was saturating one CPU core during the Manifest import phase. Overall, the sum of both processes usually used more than one and a half core. On master, however, the total of both processes barely uses more than one CPU core. What happened? This and that happened. Essentially, before those changes, git-remote-hg would send instructions to git-fast-import (technically, git-cinnabar-helper, but in this case it s only used as a wrapper for git-fast-import), and use marks to track the git objects that git-fast-import created. After those changes, git-remote-hg asks git-fast-import the git object SHA1 of objects it just asked to be created. In other words, those changes replaced something asynchronous with something synchronous: while it used to be possible for git-remote-hg to work on the next file/manifest/changeset while git-fast-import was working on the previous one, it now waits. The changes helped simplify the python code, but made the overall clone process much slower. If I m not mistaken, the only real use for that information is for the mapping of mercurial to git SHA1s, which is actually rarely used during the clone, except at the end, when storing it. So what I m planning to do is to move that mapping to the git-cinnabar-helper process, which, incidentally, will kill not 2, but 3 birds with 1 stone: So expect git-cinnabar 0.5 to get moar faster, and to use moar less memory.
Mike Hommey: Analyzing git-cinnabar memory use

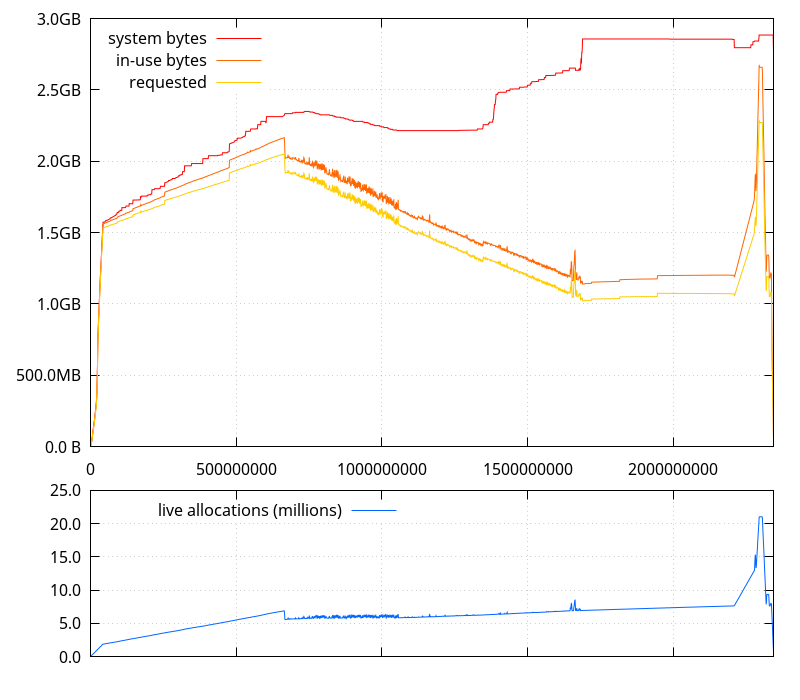
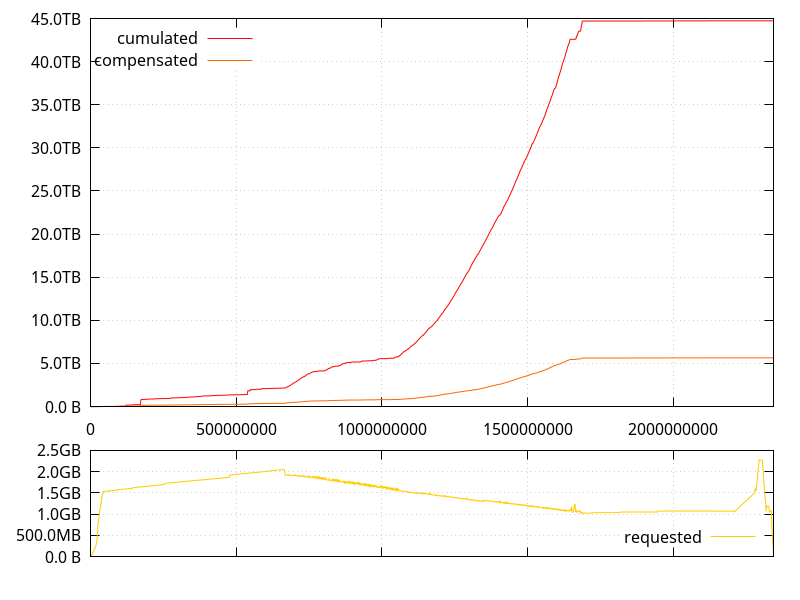
In previous post, I was looking at the allocations git-cinnabar makes. While I had the data, I figured I d also look how the memory use correlates with expectations based on repository data, to put things in perspective. As a reminder, this is what the allocations look like (horizontal axis being the number of allocator function calls): There are 7 different phases happening during a git clone using git-cinnabar, most of which can easily be identified on the graph above: Overall, except for the stupid spike during the final phase, the manifest DAG and the glibc allocator runaway memory use described in previous posts, there is nothing terribly bad with the git-cinnabar memory usage, all things considered. Mozilla-central is just big. The spike is already half addressed, and work is under way for the glibc allocator runaway memory use. The manifest DAG, interestingly, is actually mostly useless. It s only used to track the heads of the DAG, and it s very much possible to track heads of a DAG without actually storing the entire DAG. In fact, that s what git-cinnabar already does for changeset heads so we would only need to do the same for manifest heads. One could argue that the 1.4GB of raw RevChunk data we re keeping in memory for later user could be kept on disk instead. I haven t done this so far because I didn t want to have to handle temporary files (and answer questions like where to put them? , what if there isn t enough disk space there? , what if disk access is slow? , etc.). But the majority of this data is from manifests. I m already planning changes in how git-cinnabar stores manifests data that will actually allow to import them directly, instead of keeping them in memory until files are imported. This would instantly remove 1.18GB of memory usage. The downside, however, is that this would be more CPU intensive: Importing changesets will require creating the corresponding git trees, and getting the stored manifest data. I think it s worth, though. Finally, one thing that isn t obvious here, but that was found while analyzing why RSS would be going up despite memory usage going down, is that git-cinnabar is doing way too many reallocations and substring allocations. So let s look at two metrics that hopefully will highlight the problem: Assuming all the requested memory is filled at some point, the former gives us an upper bound to the amount of memory that is ever filled or copied (the amount that would be filled if no realloc was ever in-place), while the the latter gives us a lower bound (the amount that would be filled or copied if all reallocs were in-place). Ideally, we d want the upper and lower bounds to be close to each other (indicating few realloc calls), and the total amount at the end of the process to be as close as possible to the amount of data we re handling (which we ve seen is around 3TB). and this is clearly bad. Like, really bad. But we already knew that from the previous post, although it s nice to put numbers on it. The lower bound is about twice the amount of data we re handling, and the upper bound is more than 10 times that amount. Clearly, we can do better. We ll see how things evolve after the necessary code changes happen. Stay tuned.

22 March 2017

Dirk Eddelbuettel: anytime 0.2.2

A bugfix release of the anytime package arrived at CRAN earlier today. This is tenth release since the inaugural version late last summer, and the second (bugfix / feature) release this year. anytime is a very focused package aiming to do just one thing really well: to convert anything in integer, numeric, character, factor, ordered, ... format to either POSIXct or Date objects -- and to do so without requiring a format string. See the anytime page, or the GitHub README.md for a few examples. This releases addresses an annoying bug related to British TZ settings and the particular impact of a change in 1971, and generalizes input formats to accept integer or numeric format in two specific ranges. Details follow below:

Changes in anytime version 0.2.2 (2017-03-21)
  • Address corner case of integer-typed (large) values corresponding to POSIXct time (PR #57 closing ##56)
  • Add special case for Europe/London and 31 Oct 1971 BST change to avoid a one-hour offset error (#58 fixing #36 and #51)
  • Address another corner case of numeric values corresponding to Date types which are now returned as Date
  • Added file init.c with calls to R_registerRoutines() and R_useDynamicSymbols(); already used .registration=TRUE in useDynLib in NAMESPACE

Courtesy of CRANberries, there is a comparison to the previous release. More information is on the anytime page. For questions or comments use the issue tracker off the GitHub repo.

This post by Dirk Eddelbuettel originated on his Thinking inside the box blog. Please report excessive re-aggregation in third-party for-profit settings.

21 March 2017

Matthew Garrett: Announcing the Shim review process

Shim has been hugely successful, to the point of being used by the majority of significant Linux distributions and many other third party products (even, apparently, Solaris). The aim was to ensure that it would remain possible to install free operating systems on UEFI Secure Boot platforms while still allowing machine owners to replace their bootloaders and kernels, and it's achieved this goal.

However, a legitimate criticism has been that there's very little transparency in Microsoft's signing process. Some people have waited for significant periods of time before being receiving a response. A large part of this is simply that demand has been greater than expected, and Microsoft aren't in the best position to review code that they didn't write in the first place.

To that end, we're adopting a new model. A mailing list has been created at shim-review@lists.freedesktop.org, and members of this list will review submissions and provide a recommendation to Microsoft on whether these should be signed or not. The current set of expectations around binaries to be signed documented here and the current process here - it is expected that this will evolve slightly as we get used to the process, and we'll provide a more formal set of documentation once things have settled down.

This is a new initiative and one that will probably take a little while to get working smoothly, but we hope it'll make it much easier to get signed releases of Shim out without compromising security in the process.

comment count unavailable comments

Reproducible builds folks: Reproducible Builds: week 99 in Stretch cycle

Here's what happened in the Reproducible Builds effort between Sunday March 12 and Saturday March 18 2017: Upcoming events Reproducible Builds Hackathon Hamburg 2017 The Reproducible Builds Hamburg Hackathon 2017, or RB-HH-2017 for short is a 3 day hacking event taking place May 5th-7th in the CCC Hamburg Hackerspace located inside Frappant, as collective art space located in a historical monument in Hamburg, Germany. The aim of the hackathon is to spent some days working on Reproducible Builds in every distribution and project. The event is open to anybody interested on working on Reproducible Builds issues, with or without prior experience! Accomodation is available and travel sponsorship may be available by agreement. Please register your interest as soon as possible. Reproducible Builds Summit Berlin 2016 This is just a quick note, that all the pads we've written during the Berlin summit in December 2016 are now online (thanks to Holger), nicely complementing the report by Aspiration Tech. Request For Comments for new specification: BUILD_PATH_PREFIX_MAP Ximin Luo posted a draft version of our BUILD_PATH_PREFIX_MAP specification for passing build-time paths between high-level and low-level build tools. This is meant to help eliminate irreproducibility caused by different paths being used at build time. At the time of writing, this affects an estimated 15-20% of 25000 Debian packages. This is a continuation of an older proposal SOURCE_PREFIX_MAP, which has been updated based on feedback on our patches from GCC upstream, attendees of our Berlin 2016 summit, and participants on our mailing list. Thanks to everyone that contributed! The specification also contains runnable source code examples and test cases; see our git repo. Please comment on this draft ASAP - we plan to release version 1.0 of this in a few weeks. Toolchain changes Packages reviewed and fixed, and bugs filed Chris Lamb: Reviews of unreproducible packages 5 package reviews have been added, 274 have been updated and 800 have been removed in this week, adding to our knowledge about identified issues. 1 issue type has been added: Weekly QA work During our reproducibility testing, FTBFS bugs have been detected and reported by: diffoscope development diffoscope 79 and 80 were uploaded to experimental by Chris Lamb. It included contributions from: Chris Lamb: Maria Glukhova: strip-nondeterminism development strip-nondeterminism 0.032-1 was uploaded to unstable by Chris Lamb. It included contributions from: Chris Lamb: tests.reproducible-builds.org Misc. This week's edition was written by Ximin Luo, Holger Levsen and Chris Lamb & reviewed by a bunch of Reproducible Builds folks on IRC & the mailing lists.

20 March 2017

Matthew Garrett: Buying a Utah teapot

The Utah teapot was one of the early 3D reference objects. It's canonically a Melitta but hasn't been part of their range in a long time, so I'd been watching Ebay in the hope of one turning up. Until last week, when I discovered that a company called Friesland had apparently bought a chunk of Melitta's range some years ago and sell the original teapot[1]. I've just ordered one, and am utterly unreasonably excited about this.

Update: Friesland have apparently always produced the Utah teapot, but were part of the Melitta group for some time - they didn't buy the range from Melitta.

[1] They have them in 0.35, 0.85 and 1.4 litre sizes. I believe (based on the measurements here) that the 1.4 litre one matches the Utah teapot.

comment count unavailable comments

Bits from Debian: DebConf17 welcomes its first eighteen sponsors!

DebConf17 logo DebConf17 will take place in Montreal, Canada in August 2017. We are working hard to provide fuel for hearts and minds, to make this conference once again a fertile soil for the Debian Project flourishing. Please join us and support this landmark in the Free Software calendar. Eighteen companies have already committed to sponsor DebConf17! With a warm welcome, we'd like to introduce them to you. Our first Platinum sponsor is Savoir-faire Linux, a Montreal-based Free/Open-Source Software company which offers Linux and Free Software integration solutions and actively contributes to many free software projects. "We believe that it's an essential piece [Debian], in a social and political way, to the freedom of users using modern technological systems", said Cyrille B raud, president of Savoir-faire Linux. Our first Gold sponsor is Valve, a company developing games, social entertainment platform, and game engine technologies. And our second Gold sponsor is Collabora, which offers a comprehensive range of services to help its clients to navigate the ever-evolving world of Open Source. As Silver sponsors we have credativ (a service-oriented company focusing on open-source software and also a Debian development partner), Mojatatu Networks (a Canadian company developing Software Defined Networking (SDN) solutions), the Bern University of Applied Sciences (with over 6,600 students enrolled, located in the Swiss capital), Microsoft (an American multinational technology company), Evolix (an IT managed services and support company located in Montreal), Ubuntu (the OS supported by Canonical) and Roche (a major international pharmaceutical provider and research company dedicated to personalized healthcare). ISG.EE, IBM, Bluemosh, Univention and Skroutz are our Bronze sponsors so far. And finally, The Linux foundation, R seau Koumbit and adte.ca are our supporter sponsors. Become a sponsor too! Would you like to become a sponsor? Do you know of or work in a company or organization that may consider sponsorship? Please have a look at our sponsorship brochure (or a summarized flyer), in which we outline all the details and describe the sponsor benefits. For further details, feel free to contact us through sponsors@debconf.org, and visit the DebConf17 website at https://debconf17.debconf.org.

19 March 2017

Dirk Eddelbuettel: Rcpp 0.12.10: Some small fixes

The tenth update in the 0.12.* series of Rcpp just made it to the main CRAN repository providing GNU R with by now over 10,000 packages. Windows binaries for Rcpp, as well as updated Debian packages will follow in due course. This 0.12.10 release follows the 0.12.0 release from late July, the 0.12.1 release in September, the 0.12.2 release in November, the 0.12.3 release in January, the 0.12.4 release in March, the 0.12.5 release in May, the 0.12.6 release in July, the 0.12.7 release in September, the 0.12.8 release in November, and the 0.12.9 release in January --- making it the fourteenth release at the steady and predictable bi-montly release frequency. Rcpp has become the most popular way of enhancing GNU R with C or C++ code. As of today, 975 packages on CRAN depend on Rcpp for making analytical code go faster and further. That is up by sixtynine packages over the two months since the last release -- or just over a package a day! The changes in this release are almost exclusively minor bugfixes and enhancements to documentation and features: James "coatless" Balamuta rounded out the API, I aki Ucar fixed a bug concerning one-character output, Jeroen Ooms allowed for finalizers on XPtr objects, Nathan Russell corrected handling of lower (upper) triangular matrices, Dan Dillon and I dealt with Intel compiler quirks for his algorithm.h header, and I added a C++17 plugin along with some (overdue!) documentation regarding the various C++ standards that are supported by Rcpp (which is in essence whatever your compiler supports, i.e., C++98, C++11, C++14 all the way to C++17 but always keep in mind what CRAN and different users may deploy).

Changes in Rcpp version 0.12.10 (2017-03-17)
  • Changes in Rcpp API:
    • Added new size attribute aliases for number of rows and columns in DataFrame (James Balamuta in #638 addressing #630).
    • Fixed single-character handling in Rstreambuf (I aki Ucar in #649 addressing #647).
    • XPtr gains a parameter finalizeOnExit to enable running the finalizer when R quits (Jeroen Ooms in #656 addressing #655).
  • Changes in Rcpp Sugar:
    • Fixed sugar functions upper_tri() and lower_tri() (Nathan Russell in #642 addressing #641).
    • The algorithm.h file now accomodates the Intel compiler (Dirk in #643 and Dan in #645 addressing issue #640).
  • Changes in Rcpp Attributes
    • The C++17 standard is supported with a new plugin (used eg for g++-6.2).
  • Changes in Rcpp Documentation:
    • An overdue explanation of how C++11, C++14, and C++17 can be used was added to the Rcpp FAQ.

Thanks to CRANberries, you can also look at a diff to the previous release. As always, even fuller details are on the Rcpp Changelog page and the Rcpp page which also leads to the downloads page, the browseable doxygen docs and zip files of doxygen output for the standard formats. A local directory has source and documentation too. Questions, comments etc should go to the rcpp-devel mailing list off the R-Forge page.

This post by Dirk Eddelbuettel originated on his Thinking inside the box blog. Please report excessive re-aggregation in third-party for-profit settings.

Petter Reinholdtsen: Free software archive system Nikita now able to store documents

The Nikita Noark 5 core project is implementing the Norwegian standard for keeping an electronic archive of government documents. The Noark 5 standard document the requirement for data systems used by the archives in the Norwegian government, and the Noark 5 web interface specification document a REST web service for storing, searching and retrieving documents and metadata in such archive. I've been involved in the project since a few weeks before Christmas, when the Norwegian Unix User Group announced it supported the project. I believe this is an important project, and hope it can make it possible for the government archives in the future to use free software to keep the archives we citizens depend on. But as I do not hold such archive myself, personally my first use case is to store and analyse public mail journal metadata published from the government. I find it useful to have a clear use case in mind when developing, to make sure the system scratches one of my itches. If you would like to help make sure there is a free software alternatives for the archives, please join our IRC channel (#nikita on irc.freenode.net) and the project mailing list. When I got involved, the web service could store metadata about documents. But a few weeks ago, a new milestone was reached when it became possible to store full text documents too. Yesterday, I completed an implementation of a command line tool archive-pdf to upload a PDF file to the archive using this API. The tool is very simple at the moment, and find existing fonds, series and files while asking the user to select which one to use if more than one exist. Once a file is identified, the PDF is associated with the file and uploaded, using the title extracted from the PDF itself. The process is fairly similar to visiting the archive, opening a cabinet, locating a file and storing a piece of paper in the archive. Here is a test run directly after populating the database with test data using our API tester:
~/src//noark5-tester$ ./archive-pdf mangelmelding/mangler.pdf
using arkiv: Title of the test fonds created 2017-03-18T23:49:32.103446
using arkivdel: Title of the test series created 2017-03-18T23:49:32.103446
 0 - Title of the test case file created 2017-03-18T23:49:32.103446
 1 - Title of the test file created 2017-03-18T23:49:32.103446
Select which mappe you want (or search term): 0
Uploading mangelmelding/mangler.pdf
  PDF title: Mangler i spesifikasjonsdokumentet for NOARK 5 Tjenestegrensesnitt
  File 2017/1: Title of the test case file created 2017-03-18T23:49:32.103446
~/src//noark5-tester$
You can see here how the fonds (arkiv) and serie (arkivdel) only had one option, while the user need to choose which file (mappe) to use among the two created by the API tester. The archive-pdf tool can be found in the git repository for the API tester. In the project, I have been mostly working on the API tester so far, while getting to know the code base. The API tester currently use the HATEOAS links to traverse the entire exposed service API and verify that the exposed operations and objects match the specification, as well as trying to create objects holding metadata and uploading a simple XML file to store. The tester has proved very useful for finding flaws in our implementation, as well as flaws in the reference site and the specification. The test document I uploaded is a summary of all the specification defects we have collected so far while implementing the web service. There are several unclear and conflicting parts of the specification, and we have started writing down the questions we get from implementing it. We use a format inspired by how The Austin Group collect defect reports for the POSIX standard with their instructions for the MANTIS defect tracker system, in lack of an official way to structure defect reports for Noark 5 (our first submitted defect report was a request for a procedure for submitting defect reports :). The Nikita project is implemented using Java and Spring, and is fairly easy to get up and running using Docker containers for those that want to test the current code base. The API tester is implemented in Python.

Clint Adams: Measure once, devein twice

Ophira lived in a wee house in University Square, Tampa. It had one floor, three bedrooms, two baths, a handful of family members, a couple pets, some plants, and an occasional staring contest. Mauricio lived in Lowry Park North, but Ophira wasn t allowed to go there because Mauricio was afraid that someone would tell his girlfriend. Ophira didn t like Mauricio s girlfriend and Mauricio s girlfriend did not like Ophira. Mauricio did not bring his girlfriend along when he and Ophira went to St. Pete Beach. They frolicked in the ocean water, and attempted to have sex. Mauricio and Ophira were big fans of science, so Somewhat quickly they concluded that it is impossible to have sex underwater, and absconded to Ophira s car to have sex therein. I hate Mauricio s girlfriend, Ophira told Amit on the telephone. She s not even pretty. Hey, listen, said Amit. I m going to a wedding on Captiva. Oh, my family used to go to Captiva every year. There s bioluminescent algae and little crabs and stuff. Yeah? Do you want to come along? You could pick me up at the airport. Why would I want to go to a wedding? Well, it s on the beach and they re going to have a bouncy castle. A bouncy castle Are you serious? Yes. Well, okay. Amit prepared to go to the wedding and Ophira became terse then unresponsive. After he landed at RSW, he called Ophira, but instead of answering the phone she startled and fell out of her chair. Amit arranged for other transportation toward the Sanibel Causeway. Ophira bit her nails for a few hours, then went to her car and drove to Cape Coral. Ophira cruised around Cape Coral for a while, until she spotted a teenager cleaning a minivan. She parked her car and approached him. Whatcha doing? asked Ophira, pretending to chew on imaginary gum. The youth slid the minivan door open. I m cleaning, he said hesitantly. Didn t your parents teach you not to talk to strangers? I could do all kinds of horrible things to you. They conversed for a bit. She recounted a story of her personal hero, a twelve-year-old girl who seduced and manipulated older men into ruin. She rehashed the mysteries of Mauricio s girlfriend. She waxed poetic on her love of bouncy castles. The youth listened, hypnotized. What s your name, kid? Ophira yawned. Arjun, he replied. How old are you? Arjun thought about it. 15, he said. Hmm, Ophira stroked her chin. Can you sneak me into your room so that your parents never find out about it? Arjun s eyes went wide. MEANWHILE, on Captiva Island, Amit had learned that even though the Tenderly had multiple indoor jacuzzis, General Fitzpatrick and Mrs. Fitzpatrick had decided it prudent to have sex in the hot tub on the deck; that the execution of this plan had somehow necessitated a lengthy cleaning process before the hot tub could be used again; that that s why workmen were cleaning the hot tub; and that the Fitzpatrick children had gotten General Fitzpatrick and Mrs. Fitzpatrick to agree to not do that again, with an added suggestion that they not be seen doing anything else naked in public. A girl walked up to Amit. Hey, I heard you lost your plus-one. Are you here alone? What a loser! she giggled nervously, then stared. Leave me alone, Darlene, sighed Amit. Darlene s face reddened as she spun on her heels and stormed over to Lisette. Oh my god, did you see that? I practically threw myself at him and he was abusive toward me. He probably has all the classic signs of being an abuser. Did you hear about that girl he dated in Ohio? I bet I know why that ended. Oh really? said Lisette distractedly, looking Amit up and down. So he s single now? Darlene glared at Lisette as Amit wandered back outside to stare at the hot tub. Hey kid, said Ophira, bring me some snacks. I don t bring food into my room, said Arjun. It attracts pests. Is that what your parents told you? scoffed Ophira. Don t be such a wuss. Three minutes later, Ophira was finishing a bag of paprika puffs. These are great, Arjun! Where do you get these? My cousin sends them from Europe, he explained. Now get me a diet soda. Amit strolled along the beach, then yelped. What s biting my legs? he cried out. Those are sand fleas, said Nessarose. What are sand fleas? asked Amit incredulously. Nessarose rolled her eyes. Stop being a baby and have a drink. After the sun went down, Amit began to notice the crabs, and this made him drink more. When everyone was soused, General Fitzpatrick announced that they were going for a swim in the Gulf, in direct contravention of safety guidelines. Most of the guests were wise enough to refuse, but an eightsome swam out, occasionally stopping to slap the algae, but continuing until they reached the sandbar that General Fitzpatrick correctly claimed was there. Then screams echoed through the night as all the jellyfish attacked everyone invading their sandbar. The crestfallen swimming party eventually made it back to shore. Pee on the jellyfish sting, commanded Nessarose. It s the best cure. No! shouted General Fitzpatrick s daughter. Urine makes it worse. Things quickly escalated from Nessarose and General Fitzpatrick s daughter screaming at each other to the beach dividing into three factions: those siding with Nessarose, those siding with General Fitzpatrick s daughter, and those who had no idea what was going on. General Fitzpatrick had no interest in any of this, and went straight to bed. It s getting late, kid, said Ophira. I m taking your bed. What? squeaked Arjun. Look, said Ophira, your bed is small and there isn t room for both of us. You may sleep on the floor if you re quiet and don t bother me. What? squeaked Arjun. Are you deaf, kid? Ophira grunted and then went to bed. Arjun blinked in confusion, then tried to fall asleep on the floor, without much success. Ophira got up in the morning and said, Before I go, I want to teach you a valuable lesson. What? groaned Arjun, getting to his feet. You should be careful talking to strangers. Now, I told you that I could do horrible things to you, so this is not my fault; it s yours, she announced, then sucker-punched him in the gut. Ophira climbed out the window as Arjun doubled over. As the ceremony began, only a small minority of the wedding party was visibly suffering from jellyfish stings, which may or may not have helped with ignoring the sand fleas. The ceremony ended shortly thereafter, and now that marriage had been accomplished, everyone turned their attention to food and drink and swimming less irresponsibly than the night before. Guests that needed to return home sooner departed in waves and Amit started to appreciate the more peaceful environment. He heard the deck door slide open behind him and turned his attention away from the hot tub. Hey, mofo, Ophira shouted as strode stylishly out onto the deck. Where s this bouncy castle? Amit blinked in surprise. That was yesterday. You missed it. Oh, she frowned. So I met this South Slav guy with a really sexy forehead, and I need some advice. I don t know if I should call him or wait. Amit pointed to the hot tub and told her the story of General Fitzpatrick and Mrs. Fitzpatrick and the hot tub. What? said Ophira. How could they have sex underwater? What do you mean? asked Amit. Well, it s impossible, she replied.
Posted on 2017-03-19
Tags: mintings

18 March 2017

Vincent Sanders: A rose by any other name would smell as sweet

Often I end up dealing with code that works but might not be of the highest quality. While quality is subjective I like to use the idea of "code smell" to convey what I mean, these are a list of indicators that, in total, help to identify code that might benefit from some improvement.

Such smells may include:
I am most certainly not alone in using this approach and Fowler et al have covered this subject in the literature much better than I can here. One point I will raise though is some programmers dismiss code that exhibits these traits as "legacy" and immediately suggest a fresh implementation. There are varying opinions on when a rewrite is the appropriate solution from never to always but in my experience making the old working code smell nice is almost always less effort and risk than a re-write.
TestsWhen I come across smelly code, and I decide it is worthwhile improving it, I often discover the biggest smell is lack of test coverage. Now do remember this is just one code smell and on its own might not be indicative, my experience is smelly code seldom has effective test coverage while fresh code often does.

Test coverage is generally understood to be the percentage of source code lines and decision paths used when instrumented code is exercised by a set of tests. Like many metrics developer tools produce, "coverage percentage" is often misused by managers as a proxy for code quality. Both Fowler and Marick have written about this but sufficient to say that for a developer test coverage is a useful tool but should not be misapplied.

Although refactoring without tests is possible the chances for unintended consequences are proportionally higher. I often approach such a refactor by enumerating all the callers and constructing a description of the used interface beforehand and check that that interface is not broken by the refactor. At which point is is probably worth writing a unit test to automate the checks.

Because of this I have changed my approach to such refactoring to start by ensuring there is at least basic API code coverage. This may not yield the fashionable 85% coverage target but is useful and may be extended later if desired.

It is widely known and equally widely ignored that for maximum effectiveness unit tests must be run frequently and developers take action to rectify failures promptly. A test that is not being run or acted upon is a waste of resources both to implement and maintain which might be better spent elsewhere.

For projects I contribute to frequently I try to ensure that the CI system is running the coverage target, and hence the unit tests, which automatically ensures any test breaking changes will be highlighted promptly. I believe the slight extra overhead of executing the instrumented tests is repaid by having the coverage metrics available to the developers to aid in spotting areas with inadequate tests.
ExampleA short example will help illustrate my point. When a web browser receives an object over HTTP the server can supply a MIME type in a content-type header that helps the browser interpret the resource. However this meta-data is often problematic (sorry that should read "a misleading lie") so the actual content must be examined to get a better answer for the user. This is known as mime sniffing and of course there is a living specification.

The source code that provides this API (Linked to it rather than included for brevity) has a few smells:
While some of these are obvious the non-use of the global string table and the API complexity needed detailed knowledge of the codebase, just to highlight how subjective the sniff test can be. There is also one huge air freshener in all of this which definitely comes from experience and that is the modules author. Their name at the top of this would ordinarily be cause for me to move on, but I needed an example!

First thing to check is the API use

$ git grep -i -e mimesniff_compute_effective_type --or -e mimesniff_init --or -e mimesniff_fini
content/hlcache.c: error = mimesniff_compute_effective_type(handle, NULL, 0,
content/hlcache.c: error = mimesniff_compute_effective_type(handle,
content/mimesniff.c:nserror mimesniff_init(void)
content/mimesniff.c:void mimesniff_fini(void)
content/mimesniff.c:nserror mimesniff_compute_effective_type(llcache_handle *handle,
content/mimesniff.h:nserror mimesniff_compute_effective_type(struct llcache_handle *handle,
content/mimesniff.h:nserror mimesniff_init(void);
content/mimesniff.h:void mimesniff_fini(void);
desktop/netsurf.c: ret = mimesniff_init();
desktop/netsurf.c: mimesniff_fini();

This immediately shows me that this API is used in only a very small area, this is often not the case but the general approach still applies.

After a little investigation the usage is effectively that the mimesniff_init API must be called before the mimesniff_compute_effective_type API and the mimesniff_fini releases the initialised resources.

A simple test case was added to cover the API, this exercised the behaviour both when the init was called before the computation and not. Also some simple tests for a limited number of well behaved inputs.

By changing to using the global string table the initialisation and finalisation API can be removed altogether along with a large amount of global context and pre-processor macros. This single change removes a lot of smell from the module and raises test coverage both because the global string table already has good coverage and because there are now many fewer lines and conditionals to check in the mimesniff module.

I stopped the refactor at this point but were this more than an example I probably would have:
ConclusionThe approach examined here reduce the smell of code in an incremental, testable way to improve the codebase going forward. This is mainly necessary on larger complex codebases where technical debt and bit-rot are real issues that can quickly overwhelm a codebase if not kept in check.

This technique is subjective but helps a programmer to quantify and examine a piece of code in a structured fashion. However it is only a tool and should not be over applied nor used as a metric to proxy for code quality.

17 March 2017

Antonio Terceiro: Patterns for Testing Debian Packages

At the and of 2016 I had the pleasure to attend the 11th Latin American Conference on Pattern Languages of Programs, a.k.a SugarLoaf PLoP. PLoP is a series of conferences on Patterns (as in Design Patterns ), a subject that I appreciate a lot. Each of the PLoP conferences but the original main big conference has a funny name. SugarLoaf PLoP is called that way because its very first edition was held in Rio de Janeiro, so the organizers named it after a very famous mountain in Rio. The name stuck even though a long time has passed since it was held in Rio for the last time. 2016 was actually the first time SugarLoaf PLoP was held outside of Brazil, finally justifying the Latin American part of its name. I was presenting a paper I wrote on patterns for testing Debian packages. The Debian project funded my travel expenses through the generous donations of its supporters. PLoP s are very fun conferences with a relaxed atmosphere, and is amazing how many smart (and interesting!) people gather together for them. My paper is titled Patterns for Writing As-Installed Tests for Debian Packages , and has the following abstract:
Large software ecosystems, such as GNU/Linux distributions, demand a large amount of effort to make sure all of its components work correctly invidually, and also integrate correctly with each other to form a coherent system. Automated Quality Assurance techniques can prevent issues from reaching end users. This paper presents a pattern language originated in the Debian project for automated software testing in production-like environments. Such environments are closer in similarity to the environment where software will be actually deployed and used, as opposed to the development environment under which developers and regular Continuous Integration mechanisms usually test software products. The pattern language covers the handling of issues arising from the difference between development and production-like environments, as well as solutions for writing new, exclusive tests for as-installed functional tests. Even though the patterns are documented here in the context of the Debian project, they can also be generalized to other contexts.
In practical terms, the paper documents a set of patterns I have noticed in the last few years, when I have been pushing the Debian Continous Integration project. It should be an interesting read for people interested in the testing of Debian packages in their installed form, as done with autopkgtest. It should also be useful for people from other distributions interested in the subject, as the issues are not really Debian-specific. I have recently finished the final version of the paper, which should be published in the ACM Digital Library at any point now. You can download a copy of the paper in PDF. Source is also available, if you are into markdown, LaTeX, makefiles and this sort of thing. If everything goes according to plan, I should be presenting a talk on this at the next Debconf in Montreal.

15 March 2017

Michal &#268;iha&#345;: Life of free software project

During last week I've noticed several interesting posts about challenges being free software maintainer. After being active in open source for 16 years I can share much of the feelings I've read and I can also share my dealings with the things. First of all let me link some of the other posts on the topic: I guess everybody involved in in some popular free software project knows it - there is much more work to be done than people behind the project can handle. It really doesn't matter it those are bug reports, support requests, new features or technical debt, it's simply too much of that. If you are the only one behind the project it can feel even more pressing. There can be several approaches how to deal with that, but you have to choose what you prefer and what is going to work for you and your project. I've used all of the below mentioned approaches on some of the projects, but I don't think there is a silver bullet. Finding more people Obviously if you can not cope with the work, let's find more people to do the work. Unfortunately it's not that easy. Sometimes people come by, contribute few patches, but it's not that easy to turn them into regular contributor. You should encourage them to stay and to care about the part of the project they have touched. You can try to attract completely new contributors through programs as Google Summer of Code (GSoC) or Outreachy, but that has it's own challenges as well. With phpMyAdmin we're participating regularly in GSoC (we've only missed last year as we were not chosen by Google that year) and it indeed helps to bring new people on the board. Many of them even stay around your project (currently 3 of 5 phpMyAdmin team members are former GSoC students). But I think this approach really works only for bigger organizations. You can also motivate people by money. It's way which is not really much used on free software projects, partly because lack of funding (I'll get to that later) and partly because it doesn't necessarily bring long time contributors, just cash hunters. I've been using Bountysource for some of my projects (Weblate and Gammu) and so far it mostly works other way around - if somebody posts bounty on the issue, it means it's quite important for him to get that fixed, so I use that as indication for myself. On attracting new developers it never really worked well, even when I've tried to post bounties to some easy to fix issues, where newbies could learn our code base and get paid for that. These issues stayed opened for months and in the end I've fixed them myself because they annoyed me. Don't care too much I think this is most important aspect - you simply can never fix all the problems. Let's face it and work according to that. There can be various levels of don't caring. I find it always better to try to encourage people to fix their problem, but you can't expect big success rate in that, so you might find it not worth of the time. What I currently do: If you still can't handle that, you should consider abandoning the project as well. Does it bring something to you other than frustration of not completed work? I know it can be hard decision, in the end it is your child, but sometimes it's the best think you can do. Get paid to do the work Are you doing your fulltime job and then work on free software on nights or weekends? It can probably work for some time, but unless you find some way to make these two match, you will lack free time to relax and spend with friends or family. There are several options to make these work together. You can find job where doing free software will be natural part of it. This worked for me pretty well at SUSE, but I'm sure there are more companies where it will work. It can happen that the job will not cover all your free software activities, but this still helps. You can also make your project to become your employer. This can be sometimes challenging to make volunteers and paid contractors to work on one project, but I think this can be handled. Such setup currently works currently quite well for phpMyAdmin (we will announce second contractor soon) and works quite well for me with Weblate as well. Funding free software projects Once your project is well funded, you can fix many problems by money. You can pay yourself to do the work, hire additional developers, get better infrastructure or travel to conferences to spread word about it. But the question is how to get to the point of being well funded. There are several crowdfunding platforms which can help you with that (Liberapay, Bountysource salt, Gratipay or Snowdrift to mention some). You can also administer the funding yourself or using some legal entity such as Software Freedom Conservancy which handles this for phpMyAdmin. But the most important thing is to persuade people and companies to give back. You know there are lot of companies relying on your project, but how to make them fund the project? I really don't know, I still struggle with this as I don't want to be too pushy in asking for money, but I'd really like to see them to give back. What kind of works is giving your sponsors logo / link placement on your website. If your website is well ranked, you can expect to get quite a lot of SEO sponsors and the question is where to draw a line what you still find acceptable. Obviously the most willing to pay companies will have nothing to do with what you do and they just want to get the link. The industry you can expect is porn, gambling, binary options and various MFA sites. You will get some legitimate sponsors related to your project as well. We felt we've gone too far with phpMyAdmin last year and we've stricten the rules recently, but the outcome is still not visible on our website (as we've just limited new sponsors, but existing contracts will be honored). Another option is to monetize your project more directly. You can offer consulting services or provide it as a service (this is what I currently do with Weblate). It really depends on the product if you can build customer base on that or not, but certainly this is not something what would work well for all projects. Thanks for reading this and I hope it's not too chaotic, as I've moved parts there and back while writing and I'm afraid it got too long in the end.

Filed under: Debian English Gammu phpMyAdmin SUSE Weblate 0 comments

14 March 2017

Reproducible builds folks: Reproducible Builds: week 98 in Stretch cycle

Here's what happened in the Reproducible Builds effort between Sunday March 5 and Saturday March 11 2017: Upcoming events Reproducible Builds Hackathon Hamburg The Reproducible Builds Hamburg Hackathon 2017, or RB-HH-2017 for short, is a 3 day hacking event taking place in the CCC Hamburg Hackerspace located inside the Frappant, which is collective art space located in a historical monument in Hamburg, Germany. The aim of the hackathon is to spent some days working on Reproducible Builds in every distribution and project. The event is open to anybody interested on working on Reproducible Builds issues in any distro or project, with or without prio experience! Packages filed Chris Lamb: Toolchain development Reviews of unreproducible packages 39 package reviews have been added, 7 have been updated and 9 have been removed in this week, adding to our knowledge about identified issues. 2 issue types have been added: Weekly QA work During our reproducibility testing, FTBFS bugs have been detected and reported by: buildinfo.debian.net development reproducible-website development tests.reproducible-builds.org Misc. This week's edition was written by Chris Lamb, Holger Levsen, Vagrant Cascadian & reviewed by a bunch of Reproducible Builds folks on IRC & the mailing lists.

13 March 2017

Sean Whitton: Initial views of 5th edition DnD

I ve been playing in a 5e campaign for around two months now. In the past ten days or so I ve been reading various source books and Internet threads regarding the design of 5th edition. I d like to draw some comparisons and contrasts between 5th edition, and the 3rd edition family of games (DnD 3.5e and Paizo s Pathfinder, which may be thought of as 3.75e). The first thing I d like to discuss is that wizards and clerics are no longer Vancian spellcasters. In rules terms, this is the idea that individual spells are pieces of ammunition. Spellcasters have a list of individual spells stored in their heads, and as they cast spells from that list, they cross off each item. Barring special rules about spontaneously converting prepared spells to healing spells, for clerics, the only way to add items back to the list is to take a night s rest. Contrast this with spending points from a pool of energy in order to use an ability to cast a fireball. Then the limiting factor on using spells is having enough points in your mana pool, not having further castings of the spell waiting in memory. One of the design goals of 5th edition was to reduce the dominance of spellcasters at higher levels of play. The article to which I linked in the previous paragraph argues that this rebalancing requires the removal of Vancian magic. The idea, to the extent that I ve understood it, is that Vancian magic is not an effective restriction on spellcaster power levels, so it is to be replaced with other restrictions adding new restrictions while retaining the restrictions inherent in Vancian magic would leave spellcasters crippled. A further reason for removing Vancian magic was to defeat the so-called five minute adventuring day . The compat ability of a party that contains higher level Vancian spellcasters drops significantly once they ve fired off their most powerful combat spells. So adventuring groups would find themselves getting into a fight, and then immediately retreating to fully rest up in order to get their spells back. This removes interesting strategic and roleplaying possibilities involving the careful allocation of resources, and continuing to fight as hit points run low. There are some other related changes. Spell components are no longer used up when casting a spell. So you can use one piece of bat guano for every fireball your character ever casts, instead of each casting requiring a new piece. Correspondingly, you can use a spell focus, such as a cool wand, instead of a pouch full of material components since the pouch never runs out, there s no mechanical change if a wizard uses an arcane focus instead. 0th level spells may now be cast at will (although Pathfinder had this too). And there are decent 0th level attack spells, so a spellcaster need not carry a crossbow or shortbow in order to have something to do on rounds when it would not be optimal to fire off one of their precious spells. I am very much in favour of these design goals. The five minute adventuring day gets old fast, and I want it to be possible for the party to rely on the cool abilities of non-spellcasters to deal with the challenges they face. However, I am concerned about the flavour changes that result from the removal of Vancian magic. These affect wizards and clerics differently, so I ll take each case in turn. Firstly, consider wizards. In third edition, a wizard had to prepare and cast Read Magic (the only spell they could prepare without a spellbook), and then set about working through their spellbook. This involved casting the spells they wanted to prepare, up until the last few triggering words or gestures that would cause the effect of the spell to manifest. They would commit these final parts of the spell to memory. When it came to casting the spell, the wizard would say the final few words and make the required gestures, and bring out relevant material components from their component pouch. The completed spell would be ripped out of their mind, to manifest its effect in the world. We see that the casting of a spell is a highly mentally-draining activity it rips the spell out of the caster s memory! not to be undertaken lightly. Thus it is natural that a wizard would learn to use a crossbow for basic damage-dealing. Magic is not something that comes very naturally to the wizard, to be deployed in combat as readily as the fighter swings their sword. They are not a superhero or video game character, pew pew ing their way to victory. This is a very cool starting point upon which to roleplay an academic spellcaster, not really available outside of tabletop games. I see it as a distinction between magical abilities and real magic. Secondly, consider clerics. Most of the remarks in the previous paragraph apply, suitably reworked to be in terms of requesting certain abilities from the deity to whom the cleric is devoted. Additionally, there is the downgrading of the importance of the cleric s healing magic in 5th edition. Characters can heal themselves by taking short and long rests. Previously, natural healing was very slow, so a cleric would need to convert all their remaining magic to healing spells at the end of the day, and hope that it was enough to bring the party up to fighting shape. Again, this made the party of adventurers seem less like superheroes or video game characters. Magic had a special, important and unique role, that couldn t be replaced by the abilities of other classes.
There are some rules in the back of the DMG Slow Natural Healing , Healing Kit Dependency , Lingering Wounds which can be used to make healing magic more important. I m not sure how well they would work without changes to the cleric class.
I would like to find ways to restore the feel and flavour of Vancian clerics and wizards to 5th edition, without sacrificing the improvements that have been made that let other party members do cool stuff too. I hope it is possible to keep magic cool and unique without making it dominate the game. It would be easy to forbid the use of arcane foci, and say that material component pouches run out if the party do not visit a suitable marketplace often enough. This would not have a significant mechanical effect, and could enhance roleplaying possibilities. I am not sure how I could deal with the other issues I ve discussed without breaking the game. The second thing I would like to discuss is bounded accuracy. Under this design principle, the modifiers to dice rolls grow much more slowly. The gain of hit points remains unbounded. Under third edition, it was mechanically impossible for a low-level monster to land a hit on a higher-level adventurer, rendering them totally useless even in overwhelming numbers. With bounded accuracy, it s always possible for a low-level monster to hit a PC, even if they do insigificant damage. That means that multiple low-level monsters pose a threat. This change opens up many roleplaying opportunities by keeping low-level character abilities relevant, as well as monster types that can remain involves in stories without giving them implausible new abilities so they don t fall far behind the PCs. However, I m a little worried that it might make high level player characters feel a lot less powerful to play. I want to cease a be a fragile adventurer and become a world-changing hero at later levels, rather than forever remain vulnerable to the things that I was vulnerable to at the start of the game. This desire might just be the result of the video games which I played growing up. In the JRPGs I played and in Diablo II, enemies in earlier areas of the map were no threat at all once you d levelled up by conquering higher-level areas. My concerns about bounded accuracy might just be that it clashes with my own expectations of how fantasy heroes work. A good DM might be able to avoid these worries entirely. The final thing I d like to discuss is the various simplifications to the rules of 5th edition, when it is compared with 3rd edition and Pathfinder. Attacks of opportunity are only provoked when leaving a threatened square; you can go ahead and cast a spell when in melee with someone. There is a very short list of skills, and party members are much closer to each other in skills, now that you can t pump more and more ranks into one or two abilities. Feats as a whole are an optional rule. At first I was worried about these simplifications. I thought that they might make character building and tactics in combat a lot less fun. However, I am now broadly in favour of all of these changes, for two reasons. Firstly, they make the game so much more accessible, and make it far more viable to play without relying on a computer program to fill in the boxes on your character sheet. In my 5th edition group, two of us have played 3rd edition games, and the other four have never played any tabletop games before. But nobody has any problems figuring out their modifiers because it is always simply your ability bonus or penalty, plus your proficiency bonus if relevant. And advantage and disadvantage is so much more fun than getting an additional plus or minus two. Secondly, these simplifications downplay the importance of the maths, which means it is far less likely to be broken. It is easier to ensure that a smaller core of rules is balanced than it is to keep in check a larger mass of rules, constantly being supplemented by more and more addon books containing more and more feats and prestige classes. That means that players make their characters cool by roleplaying them in interesting ways, not making them cool by coming up with ability combos and synergies in advance of actually sitting down to play. Similarly, DMs can focus on flavouring monsters, rather than writing up longer stat blocks. I think that this last point reflects what I find most worthwhile about tabletop RPGs. I like characters to encounter cool NPCs and cool situations, and then react in cool ways. I don t care that much about character creation. (I used to care more about this, but I think it was mainly because of interesting options for magic items, which hasn t gone away.) The most important thing is exercising group creativity while actually playing the game, rather than players and DMs having to spend a lot of time preparing the maths in advance of playing. Fifth edition enables this by preventing the rules from getting in the way, because they re broken or overly complex. I think this is why I love Exalted: stunting is vital, and there is social combat. I hope to be able to work out a way to restore Vancian magic, but even without that, on balance, fifth edition seems like a better way to do group storytelling about fantasy heroes. Hopefully I will have an opportunity to DM a 5th edition campaign. I am considering disallowing all homebrew and classes and races from supplemental books. Stick to the well-balanced core rules, and do everything else by means of roleplaying and flavour. This is far less gimmicky, if more work for unimaginative players (such as myself!). Some further interesting reading:

12 March 2017

Mike Hommey: When the memory allocator works against you

Cloning mozilla-central with git-cinnabar requires a lot of memory. Actually too much memory to fit in a 32-bits address space. I hadn t optimized for memory use in the first place. For instance, git-cinnabar keeps sha-1s in memory as hex values (40 bytes) rather than raw values (20 bytes). When I wrote the initial prototype, it didn t matter that much, and while close(ish) to the tipping point, it didn t require more than 2GB of memory at the time. Time passed, and mozilla-central grew. I suspect the recent addition of several thousands of commits and files has made things worse. In order to come up with a plan to make things better (short or longer term), I needed data. So I added some basic memory resource tracking, and collected data while cloning mozilla-central. I must admit, I was not ready for what I witnessed. Follow me for a tale of frustrations (plural). I was expecting things to have gotten worse on the master branch (which I used for the data collection) because I am in the middle of some refactoring and did many changes that I was suspecting might have affected memory usage. I wasn t, however, expecting to see the clone command using 10GB(!) memory at peak usage across all processes. (Note, those memory sizes are RSS, minus shared ) It also was taking an unexpected long time, but then, I hadn t cloned a large repository like mozilla-central from scratch in a while, so I wasn t sure if it was just related to its recent growth in size or otherwise. So I collected data on 0.4.0 as well. Less time spent, less memory usage ok. There s definitely something wrong on master. But wait a minute, that slope from ~2GB to ~4GB on the git-remote-hg process doesn t actually make any kind of sense. I mean, I d understand it if it were starting and finishing with the Import manifest phase, but it starts in the middle of it, and ends long before it finishes. WTH? First things first, since RSS can be a variety of things, I checked /proc/$pid/smaps and confirmed that most of it was, indeed, the heap. That s the point where you reach for Google, type something like python memory profile and find various tools. One from the results that I remembered having used in the past is guppy s heapy. Armed with pdb, I broke execution in the middle of the slope, and tried to get memory stats with heapy. SIGSEGV. Ouch. Let s try something else. I reached out to objgraph and pympler. SIGSEGV. Ouch again. Tried working around the crashes for a while (too long while, retrospectively, hindsight is 20/20), and was somehow successful at avoiding them by peaking at a smaller set of objects. But whatever I did, despite being attached to a process that had 2.6GB RSS, I wasn t able to find more than 1.3GB of data. This wasn t adding up. It surely didn t help that getting to that point took close to an hour each time. Retrospectively, I wish I had investigated using something like Checkpoint/Restore in Userspace. Anyways, after a while, I decided that I really wanted to try to see the whole picture, not smaller peaks here and there that might be missing something. So I resolved myself to look at the SIGSEGV I was getting when using pympler, collecting a core dump when it happened. Guess what? The Debian python-dbg package does not contain the debug symbols for the python package. The core dump was useless. Since I was expecting I d have to fix something in python, I just downloaded its source and built it. Ran the command again, waited, and finally got a backtrace. First Google hit for the crashing function? The exact (unfixed) crash reported on the python bug tracker. No patch. Crashing code is doing:
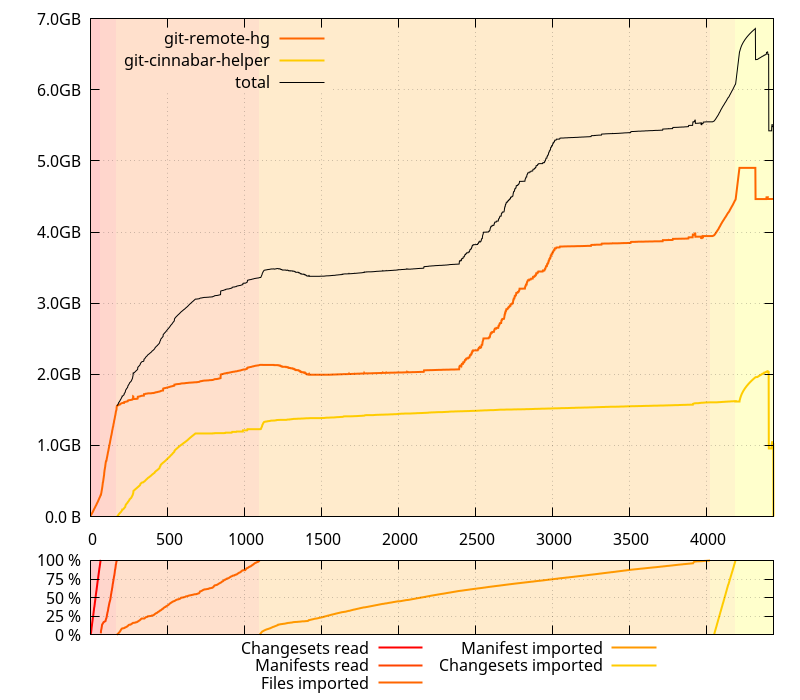
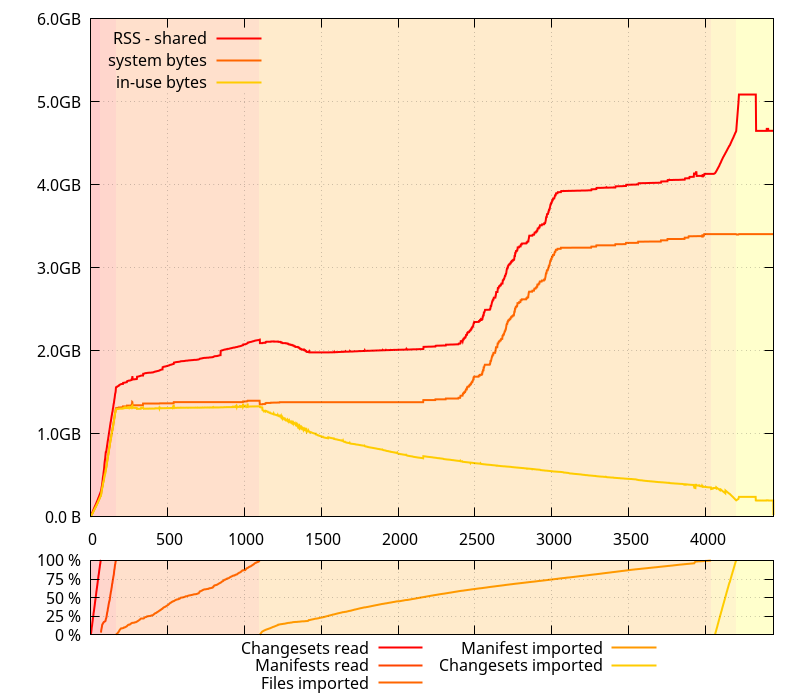
((f)->f_builtins != (f)->f_tstate->interp->builtins)
And (f)->f_tstate is NULL. Classic NULL deref. Added a guard (assessing it wouldn t break anything). Ran the command again. Waited. Again. SIGSEGV. Facedesk. Another crash on the same line. Did I really use the patched python? Yes. But this time (f)->f_tstate->interp is NULL. Sigh. Same player, shoot again. Finally, no crash but still stuck on only 1.3GB accounted for. Ok, I know not all python memory profiling tools are entirely reliable, let s try heapy again. SIGSEGV. Sigh. No debug info on the heapy module, where the crash happens. Sigh. Rebuild the module with debug info, try again. The backtrace looks like heapy is recursing a lot. Look at %rsp, compare with the address space from /proc/$pid/maps. Confirmed. A stack overflow. Let s do ugly things and increase the stack size in brutal ways. Woohoo! Now heapy tells me there s even less memory used than the 1.3GB I found so far. Like, half less. Yeah, right. I m not clear on how I got there, but that s when I found gdb-heap, a tool from Red Hat s David Malcolm, and the associated talk Dude, where s my RAM? A deep dive into how Python uses memory (slides). With a gdb attached, I would finally be able to rip python s guts out and find where all the memory went. Or so I thought. The gdb-heap tool only found about 600MB. About as much as heapy did, for that matter, but it could be coincidental. Oh. Kay. I don t remember exactly what went through my mind then, but, since I was attached to a running process with gdb, I typed the following on the gdb prompt:
gdb> call malloc_stats()
And that s when the truth was finally unvealed: the memory allocator was just acting up the whole time. The ouput was something like:
Arena 0:
system bytes    =  some number above (but close to) 2GB
in use bytes    =  some number above (but close to) 600MB
Yes, the glibc allocator was just telling it had allocated 600MB of memory, but was holding onto 2GB. I must have found a really bad allocation pattern that causes massive fragmentation. One thing that David Malcolm s talk taught me, though, is that python uses its own allocator for small sizes, so the glibc allocator doesn t know about them. And, roughly, adding the difference between RSS and what glibc said it was holding to to the use bytes it reported somehow matches the 1.3GB I had found so far. So it was time to see how those things evolved in time, during the entire clone process. I grabbed some new data, tracking the evolution of system bytes and in use bytes . There are two things of note on this data: In fact, the latter is exactly how git-cinnabar is supposed to work: It reads changesets and manifests chunks, and holds onto them while importing files. Then it throws away those manifests and changesets chunks one by one while it imports them. There is, however, some extra bookkeeping that requires some additional memory, but it s expected to be less memory consuming than keeping all the changesets and manifests chunks in memory. At this point, I thought a possible explanation is that since both python and glibc are mmap()ing their own arenas, they might be intertwined in a way that makes things not go well with the allocation pattern happening during the Import manifest phase (which, in fact, allocates and frees increasingly large buffers for each manifest, as manifests grow in size in the mozilla-central history). To put the theory at work, I patched the python interpreter again, making it use malloc() instead of mmap() for its arenas. Aha! I thought. That definitely looks much better. Less gap between what glibc says it requested from the system and the RSS size. And, more importantly, no runaway increase of memory usage in the middle of nowhere. I was preparing myself to write a post about how mixing allocators could have unintended consequences. As a comparison point, I went ahead and ran another test, with the python allocator entirely disabled, this time. Heh. It turns out glibc was acting up all alone. So much for my (plausible) theory. (I still think mixing allocators can have unintended consequences.) (Note, however, that the reason why the python allocator exists is valid: without it, the overall clone took almost 10 more minutes) And since I had been getting all this data with 0.4.0, I gathered new data without the python allocator with the master branch. This paints a rather different picture than the original data on that branch, with much less memory use regression than one would think. In fact, there isn t much difference, except for the spike at the end, which got worse, and some of the noise during the Import manifests phase that got bigger, implying larger amounts of temporary memory used. The latter may contribute to the allocation patterns that throw glibc s memory allocator off. It turns out tracking memory usage in python 2.7 is rather painful, and not all the tools paint a complete picture of it. I hear python 3.x is somewhat better in that regard, and I hope it s true, but at the moment, I m stuck with 2.7. The most reliable tool I ve used here, it turns out, is pympler. Or rebuilding the python interpreter without its allocator, and asking the system allocator what is allocated. With all this data, I now have some defined problems to tackle, some easy (the spike at the end of the clone), and some less easy (working around glibc allocator s behavior). I have a few hunches as to what kind of allocations are causing the runaway increase of RSS. Coincidentally, I m half-way through a refactor of the code dealing with manifests, and it should help dealing with the issue. But that will be the subject of a subsequent post.
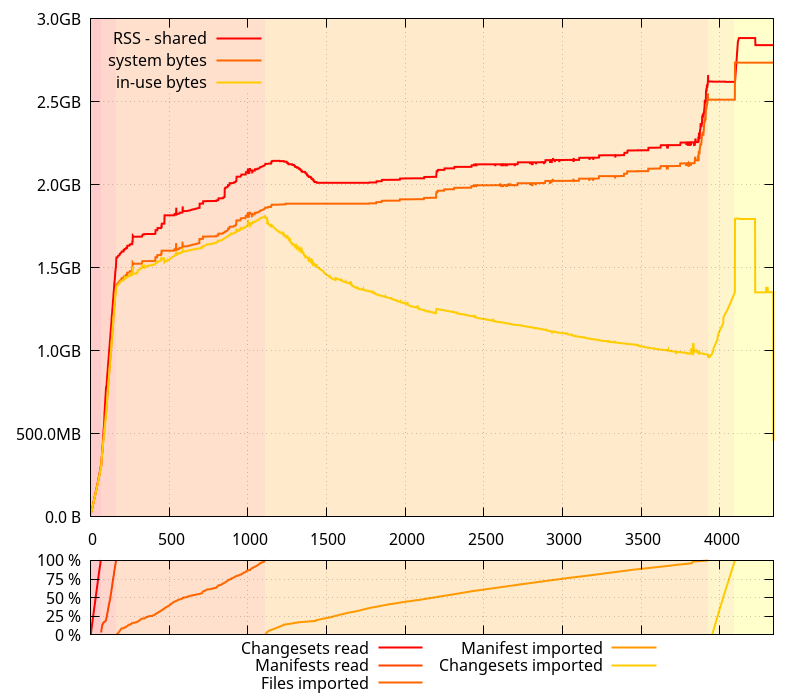
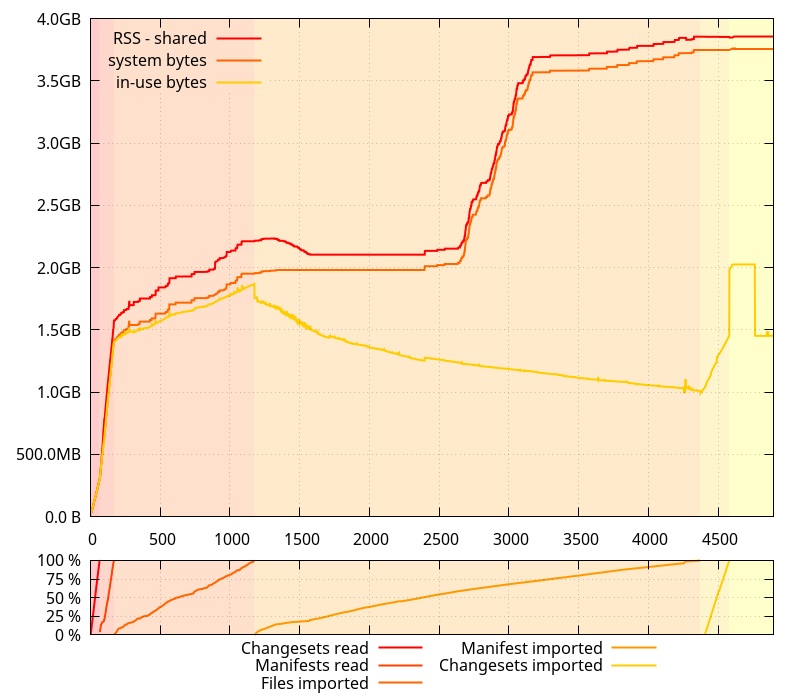
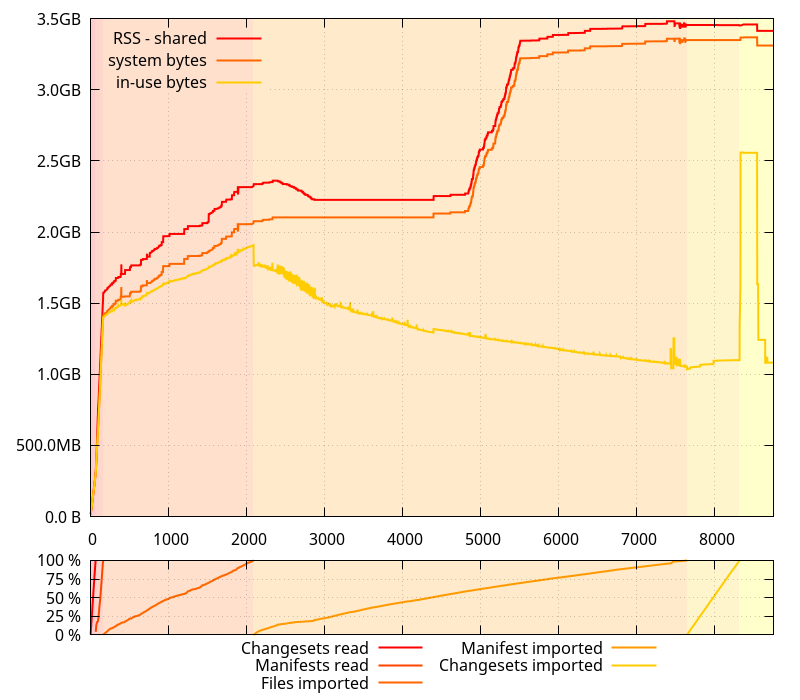
10 March 2017

Reproducible builds folks: Reproducible Builds: week 97 in Stretch cycle

Here's what happened in the Reproducible Builds effort between Sunday February 26 and Saturday March 4 2017: Upcoming Events Ed Maste will present Reproducible Builds in FreeBSD at AsiaBSDCon 2017. Ximin Luo will present Reproducible builds, its uses and the future at Open Source Days in Copenhagen on March 18. Holger Levsen will give a talk at the German Unix User Group's "Fr hjahrsfachgespr ch" in Darmstadt, Germany, about Reproducible Builds everywhere on March 23. Verifying Software Freedom with Reproducible Builds will be presented by Vagrant Cascadian at Libreplanet2017 in Boston, March 25th-26th. Media coverage Aspiration Tech published a very detailed report on our Reproducible Builds World Summit 2016 in Berlin. Reproducible work in other projects Duncan published a very thorough post on the Rust Programming Language Forum about reproducible builds in the Rust compiler and toolchain. In particular, he produced a table recording the reproducibility of different build products under different individual variations, totalling 187 build+variation combinations. Packages reviewed and fixed, and bugs filed Chris Lamb: Dhole: Reviews of unreproducible packages 60 package reviews have been added, 8 have been updated and 13 have been removed in this week, adding to our knowledge about identified issues. 1 issue type has been added: Weekly QA work During our reproducibility testing, FTBFS bugs have been detected and reported by: diffoscope development diffoscope 78 was uploaded to unstable and jessie-backports by Mattia Rizzolo. It included contributions from: In addition, the following changes were made on the experimental branch: reproducible-website development tests.reproducible-builds.org Misc. This week's edition was written by Ximin Luo, Chris Lamb, Holger Levsen & reviewed by a bunch of Reproducible Builds folks on IRC & the mailing lists.

Next.

Previous.