Search Results: "cas"

30 July 2017

Niels Thykier: Introducing the debhelper buildlabel prototype for multi-building packages

For most packages, the dh short-hand rules (possibly with a few overrides) work great. It can often auto-detect the buildsystem and handle all the trivial parts. With one notably exception: What if you need to compile the upstream code twice (or more) with different flags? This is the case for all source packages building both regular debs and udebs. In that case, you would previously need to override about 5-6 helpers for this to work at all. The five dh_auto_* helpers and usually also dh_install (to call it with different sourcedir for different packages). This gets even more complex if you want to support Build-Profiles such as noudeb and nodoc . The best way to support nodoc in debhelper is to move documentation out of dh_install s config files and use dh_installman, dh_installdocs, and dh_installexamples instead (NB: wait for compat 11 before doing this). This in turn will mean more overrides with sourcedir and -p/-N. And then there is noudeb , which currently requires manual handling in debian/rules. Basically, you need to use make or shell if-statements to conditionally skip the udeb part of the builds. All of this is needlessly complex. Improving the situation In an attempt to make things better, I have made a new prototype feature in debhelper called buildlabels in experimental. The current prototype is designed to deal with part (but not all) of the above problems: However, it currently not solve the need for overriding the dh_auto_* tools and I am not sure when/if it will. The feature relies on being able to relate packages to a given series of calls to dh_auto_*. In the following example, I will use udebs for the secondary build. However, this feature is not tied to udebs in any way and can be used any source package that needs to do two or more upstream builds for different packages. Assume our example source builds the following binary packages: And in the rules file, we would have something like:
[...]
override_dh_auto_configure:
    dh_auto_configure -B build-deb -- --with-feature1 --with-feature2
    dh_auto_configure -B build-udeb -- --without-feature1 --without-feature2
[...]
What is somewhat obvious to a human is that the first configure line is related to the regular debs and the second configure line is for the udebs. However, debhelper does not know how to infer this and this is where buildlabels come in. With buildlabels, you can let debhelper know which packages and builds that belong together. How to use buildlabels To use buildlabels, you have to do three things:
  1. Pick a reasonable label name for the secondary build. In the example, I will use udeb .
  2. Add buildlabel=$LABEL to all dh_auto_* calls related to your secondary build.
  3. Tag all packages related to my-label with X-DH-Buildlabel: $LABEL in debian/control. (For udeb packages, you may want to add Build-Profiles: <!noudeb> while you are at it).
For the example package, we would change the debian/rules snippet to:
[...]
override_dh_auto_configure:
    dh_auto_configure -B build-deb -- --with-feature1 --with-feature2
    dh_auto_configure --buildlabel=udeb -B build-udeb -- --without-feature1 --without-feature2
[...]
(Remember to update *all* calls to dh_auto_* helpers; the above only lists dh_auto_configure to keep the example short.) And then add X-DH-Buildlabel: udeb in the stanzas for foo-udeb + libfoo1-udeb. With those two minor changes: Real example Thanks to Michael Biebl, I was able to make an branch in the systemd git repository to play with this feature. Therefore I have an real example to use as a show case. The gist of it is in the following three commits: Full branch can be seen at: https://anonscm.debian.org/git/pkg-systemd/systemd.git/log/?h=wip-dh-prototype-smarter-multi-builds Request for comments / call for testing This prototype is now in experimental (debhelper/10.7+exp.buildlabels) and you are very welcome to take it for a spin. Please let me know if you find the idea useful and feel free to file bugs or feature requests. If deemed useful, I will merge into master and include in a future release. If you have any questions or comments about the feature or need help with trying it out, you are also very welcome to mail the debhelper-devel mailing list. Known issues / the fine print:
Filed under: Debhelper, Debian

29 July 2017

Antoine Beaupr : My free software activities, July 2017

Debian Long Term Support (LTS) This is my monthly working on Debian LTS. This time I worked on various hairy issues surrounding ca-certificates, unattended-upgrades, apache2 regressions, libmtp, tcpdump and ipsec-tools.

ca-certificates updates I've been working on the removal of the Wosign and StartCom certificates (Debian bug #858539) and, in general, the synchronisation of ca-certificates across suites (Debian bug #867461) since at least last march. I have made an attempt at summarizing the issue which led to a productive discussion and it seems that, in the end, the maintainer will take care of synchronizing information across suites. Guido was right in again raising the question of synchronizing NSS across all suites (Debian bug #824872) which itself raised the other question of how to test reverse dependencies. This brings me back to Debian bug #817286 which, basically proposed the idea of having "proposed updates" for security issues. The problem is while we can upload test packages to stable proposed-updates, we can't do the same in LTS because the suite is closed and we operate only on security packages. This issue came up before in other security upload and we need to think better about how to solve this.

unattended-upgrades Speaking of security upgrades brings me to the question of a bug (Debian bug #867169) that was filed against the wheezy version of unattended-upgrades, which showed that the package simply stopped working since the latest stable release, because wheezy became "oldoldstable". I first suggested using the "codename" but that appears to have been introduced only after wheezy. In the end, I proposed a simple update that would fix the configuration files and uploaded this as DLA-1032-1. This is thankfully fixed in later releases and will not require such hackery when jessie becomes LTS as well.

libmtp Next up is the work on the libmtp vulnerabilities (CVE-2017-9831 and CVE-2017-9832). As I described in my announcement, the work to backport the patch was huge, as upstream basically backported a whole library from the gphoto2 package to fix those issues (and probably many more). The lack of a test suite made it difficult to trust my own work, but given that I had no (negative) feedback, I figured it was okay to simply upload the result and that became DLA-1029-1.

tcpdump I then looked at reproducing CVE-2017-11108, a heap overflow triggered tcpdump would parse specifically STP packets. In Debian bug #867718, I described how to reproduce the issue across all suites and opened an issue upstream, given that the upstream maintainers hadn't responded responded in weeks according to notes in the RedHat Bugzilla issue. I eventually worked on a patch which I shared upstream, but that was rejected as they were already working on it in their embargoed repository. I can explain this confusion and duplication of work with:
  1. the original submitter didn't really contact security@tcpdump.org
  2. he did and they didn't reply, being just too busy
  3. they replied and he didn't relay that information back
I think #2 is most likely: the tcpdump.org folks are probably very busy with tons of reports like this. Still, I should probably have contacted security@tcpdump.org directly before starting my work, even though no harm was done because I didn't divulge issues that were already public. Since then, tcpdump has released 4.9.1 which fixes the issue, but then new CVEs came out that will require more work and probably another release. People looking into this issue must be certain to coordinate with the tcpdump security team before fixing the actual issues.

ipsec-tools Another package that didn't quite have a working solution is the ipsec-tools suite, in which the racoon daemon was vulnerable to a remotely-triggered DOS attack (CVE-2016-10396). I reviewed and fixed the upstream patch which introduced a regression. Unfortunately, there is no test suite or proof of concept to control the results. The reality is that ipsec-tools is really old, and should maybe simply be removed from Debian, in favor of strongswan. Upstream hasn't done a release in years and various distributions have patched up forks of those to keep it alive... I was happy, however, to know that a maintainer will take care of updating the various suites, including LTS, with my improved patch. So this fixes the issue for now, but I would strongly encourage users to switch away from ipsec-tools in the future.

apache2 Finally, I was bitten by the old DLA-841-1 upload I did all the way back in February, as it introduced a regression (Debian bug #858373). It turns out it was possible to segfault Apache workers with a trivial HTTP request, in certain (rather exotic, I might add) configurations (ErrorDocument 400 directive pointing to a cgid script in worker mode). Still, it was a serious regression and I found a part of the nasty long patch we worked on back then that was faulty, and introduced a small fix to correct that. The proposed package unfortunately didn't yield any feedback, and I can only assume it will work okay for people. The result is the DLA-841-2 upload which fixes the regression. I unfortunately didn't have time to work on the remaining CVEs affecting apache2 in LTS at the time of writing.

Triage I also did some miscellaneous triage by filing Debian bug #867477 for poppler in an effort to document better the pending issue. Next up was some minor work on eglibc issues. CVE-2017-8804 has a patch, but it's been disputed. since the main victim of this and the core of the vulnerability (rpcbind) has already been fixed, I am not sure this vulnerability is still a thing in LTS at all. I also looked at CVE-2014-9984, but the code is so different in wheezy that I wonder if LTS is affected at all. Unfortunately, the eglibc gymnastics are a little beyond me and I do not feel confident enough to just push those issues aside for now and let them open for others to look at.

Other free software work And of course, there's my usual monthly volunteer work. My ratio is a little better this time, having reached an about even ratio between paid and volunteer work, whereas this was 60% volunteer work in march.

Announcing ecdysis I recently published ecdysis, a set of template and code samples that I frequently reuse across project. This is probably the least pronounceable project name I have ever chosen, but this is somewhat on purpose. The goal of this project is not collaboration or to become a library: it's just a personal project which I share with the world as a curiosity. To quote the README file:
The name comes from what snakes and other animals do to "create a new snake": they shed their skin. This is not so appropriate for snakes, as it's just a way to rejuvenate their skin, but is especially relevant for anthropods since then "ecdysis" may be associated with a metamorphosis:
Ecdysis is the moulting of the cuticle in many invertebrates of the clade Ecdysozoa. Since the cuticle of these animals typically forms a largely inelastic exoskeleton, it is shed during growth and a new, larger covering is formed. The remnants of the old, empty exoskeleton are called exuviae. Wikipedia
So this project is metamorphosed into others when the documentation templates, code examples and so on are reused elsewhere. For that reason, the license is an unusally liberal (for me) MIT/Expat license. The name also has the nice property of being absolutely unpronounceable, which makes it unlikely to be copied but easy to search online.
It was an interesting exercise to go back into older projects and factor out interesting code. The process is not complete yet, as there are older projects I'm still curious in reviewing. A bunch of that code could also be factored into upstream project and maybe even the Python standard library. In short, this is stuff I keep on forgetting how to do: a proper setup.py config, some fancy argparse extensions and so on. Instead of having to remember where I had written that clever piece of code, I now shove it in the crazy chaotic project where I can find it again in the future.

Beets experiments Since I started using Subsonic (or Libresonic) to manage the music on my phone, album covers are suddenly way more interesting. But my collection so far has had limited album covers: my other media player (gmpc) would download those on the fly on its own and store them in its own database - not on the filesystem. I guess this could be considered to be a limitation of Subsonic, but I actually appreciate the separation of duty here. Garbage in, garbage out: the quality of Subsonic's rendering depends largely on how well setup your library and tags are. It turns out there is an amazing tool called beets to do exactly that kind of stuff. I originally discarded that "media library management system for obsessive-compulsive [OC] music geeks", trying to convince myself i was not an "OC music geek". Turns out I am. Oh well. Thanks to beets, I was able to download album covers for a lot of the albums in my collection. The only covers that are missing now are albums that are not correctly tagged and that beets couldn't automatically fix up. I still need to go through those and fix all those tags, but the first run did an impressive job at getting album covers. Then I got the next crazy idea: after a camping trip where we forgot (again) the lyrics to Georges Brassens, I figured I could start putting some lyrics on my ebook reader. "How hard can that be?" of course, being the start of another crazy project. A pull request and 3 days later, I had something that could turn a beets lyrics database into a Sphinx document which, in turn, can be turned into an ePUB. In the process, I probably got blocked from MusixMatch a hundred times, but it's done. Phew! The resulting e-book is about 8000 pages long, but is still surprisingly responsive. In the process, I also happened to do a partial benchmark of Python's bloom filter libraries. The biggest surprise there was the performance of the set builtin: for small items, it is basically as fast as a bloom filter. Of course, when the item size grows larger, its memory usage explodes, but in this case it turned out to be sufficient and bloom filter completely overkill and confusing. Oh, and thanks to those efforts, I got admitted in the beetbox organization on GitHub! I am not sure what I will do with that newfound power: I was just scratching an itch, really. But hopefully I'll be able to help here and there in the future as well.

Debian package maintenance I did some normal upkeep on a bunch of my packages this month, that were long overdue:
  • uploaded slop 6.3.47-1: major new upstream release
  • uploaded an NMU for maim 5.4.64-1.1: maim was broken by the slop release
  • uploaded pv 1.6.6-1: new upstream release
  • uploaded kedpm 1.0+deb8u1 to jessie (oldstable): one last security fix (Debian bug #860817, CVE-2017-8296) for that derelict password manager
  • uploaded charybdis 3.5.5-1: new minor upstream release, with optional support for mbedtls
  • filed Debian bug #866786 against cryptsetup to make the remote initramfs SSH-based unlocking support multiple devices: thanks to the maintainer, this now works flawlessly in buster and may be backported to stretch
  • expanded on Debian bug #805414 against gdm3 and Debian bug #845938 against pulseaudio, because I had trouble connecting my computer to this new Bluetooth speaker. turns out this is a known issue in Pulseaudio: whereas it releases ALSA devices, it doesn't release Bluetooth devices properly. Documented this more clearly in the wiki page
  • filed Debian bug #866790 regarding old stray Apparmor profiles that were lying around my system after an upgrade, which got me interested in Debian bug #830502 in turn
  • filed Debian bug #868728 against cups regarding a weird behavior I had interacting with a network printer. turns out the other workstation was misconfigured... why are printers still so hard?
  • filed Debian bug #870102 to automate sbuild schroots upgrades
  • after playing around with rash tried to complete the packaging (Debian bug #754972) of percol with this pull request upstream. this ended up to be way too much overhead and I reverted to my old normal history habits.

Dirk Eddelbuettel: Updated overbought/oversold plot function

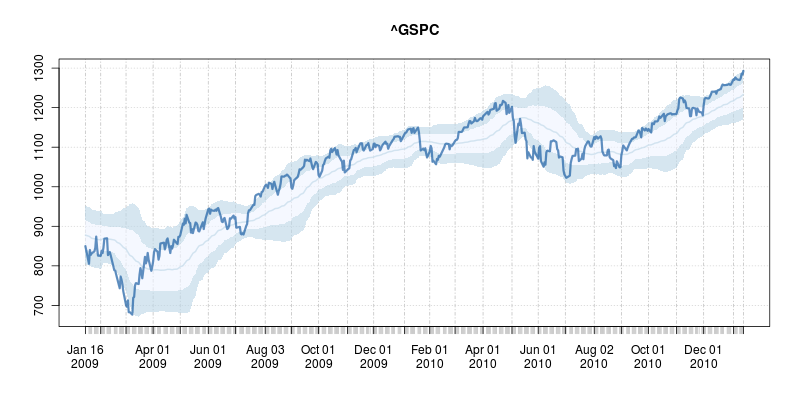
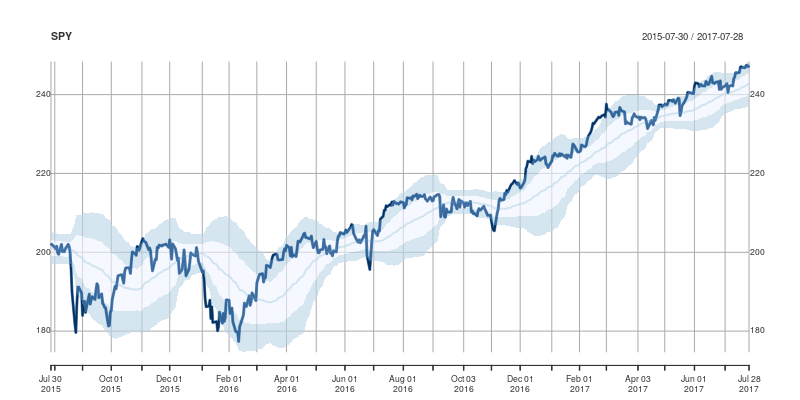
A good six years ago I blogged about plotOBOS() which charts a moving average (from one of several available variants) along with shaded standard deviation bands. That post has a bit more background on the why/how and motivation, but as a teaser here is the resulting chart of the SP500 index (with ticker ^GSCP): Example chart of overbought/oversold levels from plotOBOS() function The code uses a few standard finance packages for R (with most of them maintained by Joshua Ulrich given that Jeff Ryan, who co-wrote chunks of these, is effectively retired from public life). Among these, xts had a recent release reflecting changes which occurred during the four (!!) years since the previous release, and covering at least two GSoC projects. With that came subtle API changes: something we all generally try to avoid but which is at times the only way forward. In this case, the shading code I used (via polygon() from base R) no longer cooperated with the beefed-up functionality of plot.xts(). Luckily, Ross Bennett incorporated that same functionality into a new function addPolygon --- which even credits this same post of mine. With that, the updated code becomes
## plotOBOS -- displaying overbough/oversold as eg in Bespoke's plots
##
## Copyright (C) 2010 - 2017  Dirk Eddelbuettel
##
## This is free software: you can redistribute it and/or modify it
## under the terms of the GNU General Public License as published by
## the Free Software Foundation, either version 2 of the License, or
## (at your option) any later version.
suppressMessages(library(quantmod))     # for getSymbols(), brings in xts too
suppressMessages(library(TTR))          # for various moving averages
plotOBOS <- function(symbol, n=50, type=c("sma", "ema", "zlema"),
                     years=1, blue=TRUE, current=TRUE, title=symbol,
                     ticks=TRUE, axes=TRUE)  
    today <- Sys.Date()
    if (class(symbol) == "character")  
        X <- getSymbols(symbol, from=format(today-365*years-2*n), auto.assign=FALSE)
        x <- X[,6]                          # use Adjusted
      else if (inherits(symbol, "zoo"))  
        x <- X <- as.xts(symbol)
        current <- FALSE                # don't expand the supplied data
     
    n <- min(nrow(x)/3, 50)             # as we may not have 50 days
    sub <- ""
    if (current)  
        xx <- getQuote(symbol)
        xt <- xts(xx$Last, order.by=as.Date(xx$ Trade Time ))
        colnames(xt) <- paste(symbol, "Adjusted", sep=".")
        x <- rbind(x, xt)
        sub <- paste("Last price: ", xx$Last, " at ",
                     format(as.POSIXct(xx$ Trade Time ), "%H:%M"), sep="")
     
    type <- match.arg(type)
    xd <- switch(type,                  # compute xd as the central location via selected MA smoother
                 sma = SMA(x,n),
                 ema = EMA(x,n),
                 zlema = ZLEMA(x,n))
    xv <- runSD(x, n)                   # compute xv as the rolling volatility
    strt <- paste(format(today-365*years), "::", sep="")
    x  <- x[strt]                       # subset plotting range using xts' nice functionality
    xd <- xd[strt]
    xv <- xv[strt]
    xyd <- xy.coords(.index(xd),xd[,1]) # xy coordinates for direct plot commands
    xyv <- xy.coords(.index(xv),xv[,1])
    n <- length(xyd$x)
    xx <- xyd$x[c(1,1:n,n:1)]           # for polygon(): from first point to last and back
    if (blue)  
        blues5 <- c("#EFF3FF", "#BDD7E7", "#6BAED6", "#3182BD", "#08519C") # cf brewer.pal(5, "Blues")
        fairlylight <<- rgb(189/255, 215/255, 231/255, alpha=0.625) # aka blues5[2]
        verylight <<- rgb(239/255, 243/255, 255/255, alpha=0.625) # aka blues5[1]
        dark <<- rgb(8/255, 81/255, 156/255, alpha=0.625) # aka blues5[5]
        ## buglet in xts 0.10-0 requires the <<- here
      else  
        fairlylight <<- rgb(204/255, 204/255, 204/255, alpha=0.5)  # two suitable grays, alpha-blending at 50%
        verylight <<- rgb(242/255, 242/255, 242/255, alpha=0.5)
        dark <<- 'black'
     
    plot(x, ylim=range(range(x, xd+2*xv, xd-2*xv, na.rm=TRUE)), main=title, sub=sub, 
         major.ticks=ticks, minor.ticks=ticks, axes=axes) # basic xts plot setup
    addPolygon(xts(cbind(xyd$y+xyv$y, xyd$y+2*xyv$y), order.by=index(x)), on=1, col=fairlylight)  # upper
    addPolygon(xts(cbind(xyd$y-xyv$y, xyd$y+1*xyv$y), order.by=index(x)), on=1, col=verylight)    # center
    addPolygon(xts(cbind(xyd$y-xyv$y, xyd$y-2*xyv$y), order.by=index(x)), on=1, col=fairlylight)  # lower
    lines(xd, lwd=2, col=fairlylight)   # central smooted location
    lines(x, lwd=3, col=dark)           # actual price, thicker
 
and the main change are the three calls to addPolygon. To illustrate, we call plotOBOS("SPY", years=2) with an updated plot of the ETF representing the SP500 over the last two years: Updated example chart of overbought/oversold levels from plotOBOS() function Comments and further enhancements welcome!

This post by Dirk Eddelbuettel originated on his Thinking inside the box blog. Please report excessive re-aggregation in third-party for-profit settings.

Robert McQueen: Hello again!

Like all good blog posts, this one starts with an apology about not blogging for ages in my case it looks like it s been about 7 years which is definitely a new personal best (perhaps the equally or more remarkable thing is that I have diligently kept WordPress running in the meantime). In that time, as you might expect, a few things have happened, like I met a wonderful woman and fell in love and we have two wonderful children. I also decided to part ways with my first baby and leave my role as CTO & co-founder of Collabora. This was obviously a very tough decision it s a fantastic team where I met and made many life-long friends, and they are still going strong and doing awesome things with Open Source. However, shortly after that, in February last year, I was lucky enough to land what is basically a dream job working at Endless Computers as the VP of Deployment. As I m sure most readers know, Endless is building an OS to bring personal computing to millions of new users across the world. It s based on Free Software like GNOME, Debian, ostree and Flatpak, and the more successful Endless is, the more people who get access to education, technology and opportunity and the more FOSS users and developers there will be in the world. But in my role, I get to help define the product, understand our users and how technology might help them, take Open Source out to new people, solve commercial problems to get Endless OS out into the world, manage a fantastic team and work with bright people, learn from great managers and mentors, and still find time to squash bugs, review and write more code than I used to. Like any startup, we have a lot to do and not enough time to do it, so although there aren t quite enough days in the week, I m really happy! In any case, the main point of this blog post is that I m at GUADEC in Manchester right now, and I d like to blog about Flathub, but I thought it would be weird to just show up and say that after 7 years of silence without saying hello again.

Russell Coker: Apache Mesos on Debian

I decided to try packaging Mesos for Debian/Stretch. I had a spare system with a i7-930 CPU, 48G of RAM, and SSDs to use for building. The i7-930 isn t really fast by today s standards, but 48G of RAM and SSD storage mean that overall it s a decent build system faster than most systems I run (for myself and for clients) and probably faster than most systems used by Debian Developers for build purposes. There s a github issue about the lack of an upstream package for Debian/Stretch [1]. That upstream issue could probably be worked around by adding Jessie sources to the APT sources.list file, but a package for Stretch is what is needed anyway. Here is the documentation on building for Debian [2]. The list of packages it gives as build dependencies is incomplete, it also needs zlib1g-dev libapr1-dev libcurl4-nss-dev openjdk-8-jdk maven libsasl2-dev libsvn-dev. So BUILDING this software requires Java + Maven, Ruby, and Python along with autoconf, libtool, and all the usual Unix build tools. It also requires the FPM (Fucking Package Management) tool, I take the choice of name as an indication of the professionalism of the author. Building the software on my i7 system took 79 minutes which includes 76 minutes of CPU time (I didn t use the -j option to make). At the end of the build it turned out that I had mistakenly failed to install the Fucking Package Management gem and it aborted. At this stage I gave up on Mesos, the pain involved exceeds my interest in trying it out. How to do it Better One of the aims of Free Software is that bugs are more likely to get solved if many people look at them. There aren t many people who will devote 76 minutes of CPU time on a moderately fast system to investigate a single bug. To deal with this software should be prepared as components. An example of this is the SE Linux project which has 13 source modules in the latest release [3]. Of those 13 only 5 are really required. So anyone who wants to start on SE Linux from source (without considering a distribution like Debian or Fedora that has it packaged) can build the 5 most important ones. Also anyone who has an issue with SE Linux on their system can find the one source package that is relevant and study it with a short compile time. As an aside I ve been working on SE Linux since long before it was split into so many separate source packages and know the code well, but I still find the separation convenient I rarely need to work on more than a small subset of the code at one time. The requirement of Java, Ruby, and Python to build Mesos could be partly due to language interfaces to call Mesos interfaces from Ruby and Python. Ohe solution to that is to have the C libraries and header files to call Mesos and have separate packages that depend on those libraries and headers to provide the bindings for other languages. Another solution is to have autoconf detect that some languages aren t installed and just not try to compile bindings for them (this is one of the purposes of autoconf). The use of a tool like Fucking Package Management means that you don t get help from experts in the various distributions in making better packages. When there is a FOSS project with a debian subdirectory that makes barely functional packages then you will be likely to have an experienced Debian Developer offer a patch to improve it (I ve offered patches for such things on many occasions). When there is a FOSS project that uses a tool that is never used by Debian developers (or developers of Fedora and other distributions) then the only patches you will get will be from inexperienced people. A software build process should not download anything from the Internet. The source archive should contain everything that is needed and there should be dependencies for external software. Any downloads from the Internet need to be protected from MITM attacks which means that a responsible software developer has to read through the build system and make sure that appropriate PGP signature checks etc are performed. It could be that the files that the Mesos build downloaded from the Apache site had appropriate PGP checks performed but it would take me extra time and effort to verify this and I can t distribute software without being sure of this. Also reproducible builds are one of the latest things we aim for in the Debian project, this means we can t just download files from web sites because the next build might get a different version. Finally the fpm (Fucking Package Management) tool is a Ruby Gem that has to be installed with the gem install command. Any time you specify a gem install command you should include the -v option to ensure that everyone is using the same version of that gem, otherwise there is no guarantee that people who follow your documentation will get the same results. Also a quick Google search didn t indicate whether gem install checks PGP keys or verifies data integrity in other ways. If I m going to compile software for other people to use I m concerned about getting unexpected results with such things. A Google search indicates that Ruby people were worried about such things in 2013 but doesn t indicate whether they solved the problem properly.

Norbert Preining: Gaming: The Long Dark

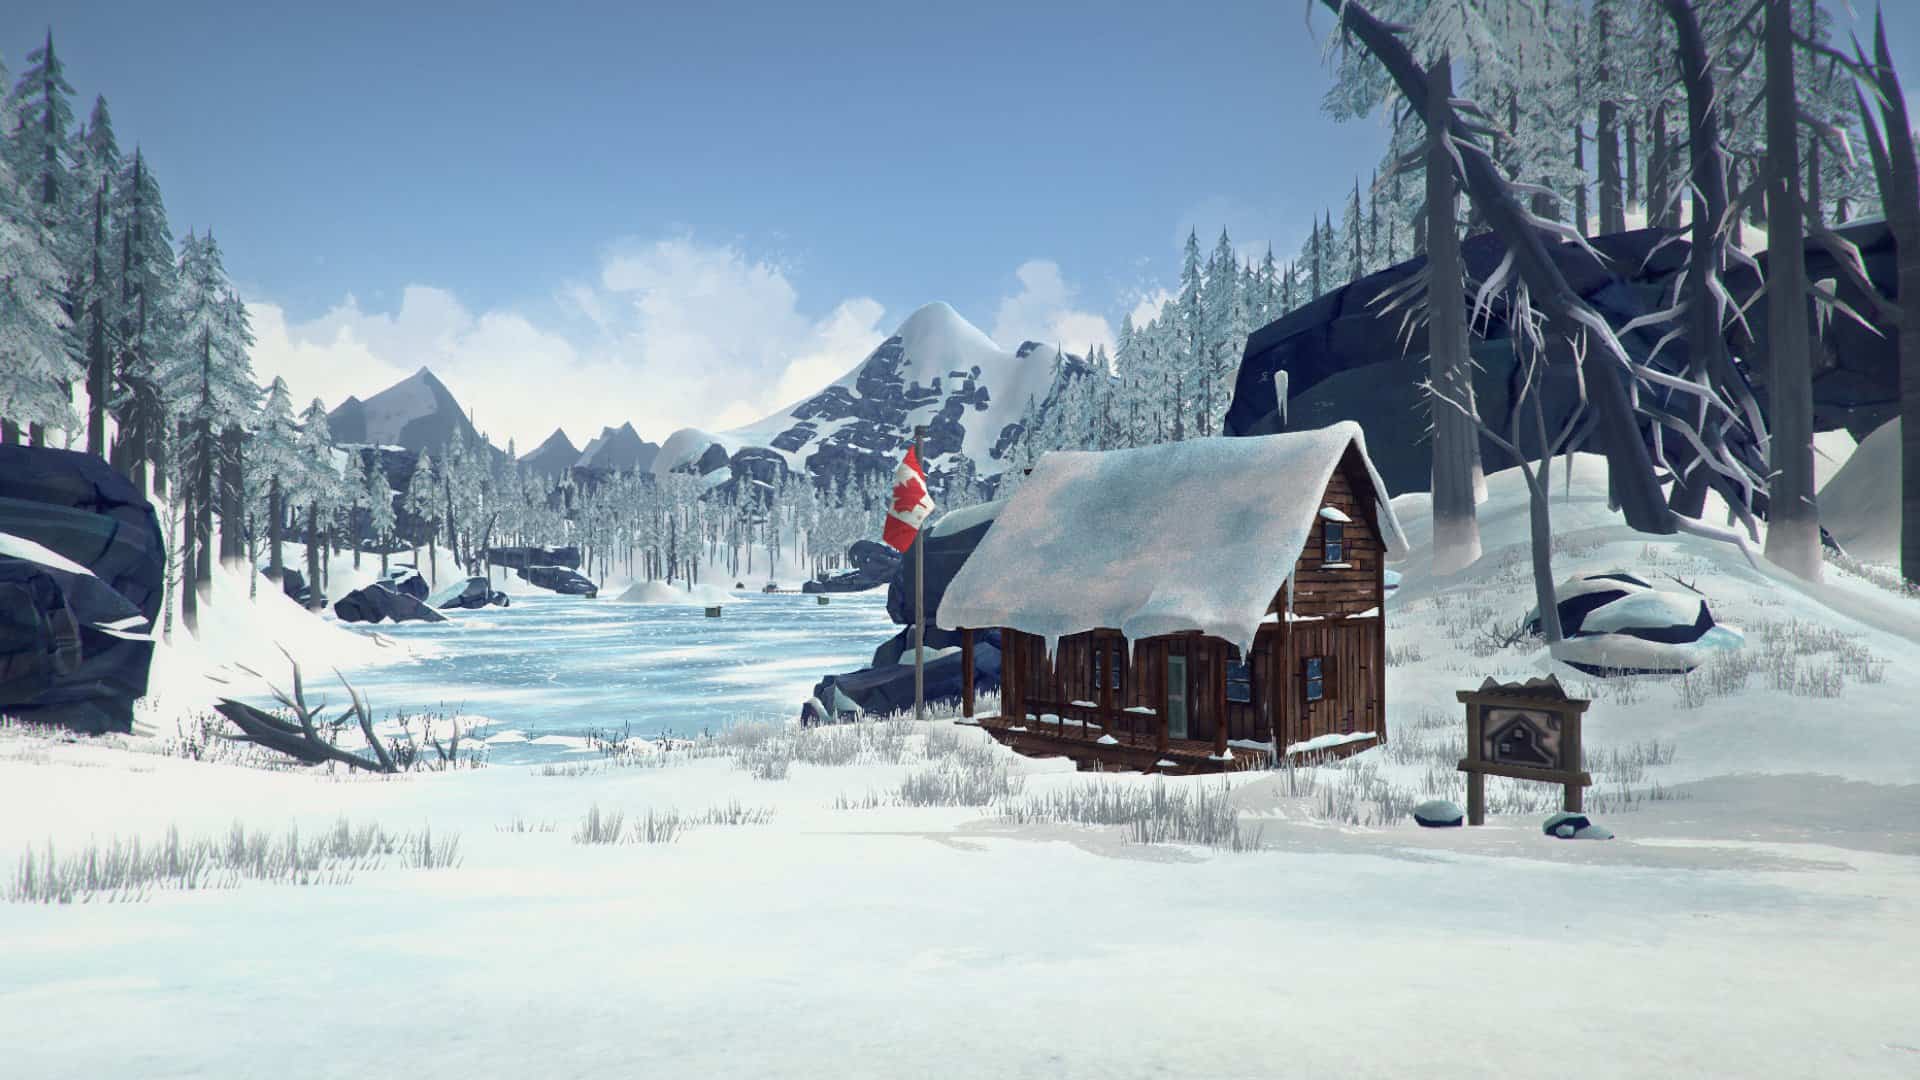
I normally don t play survival games or walking simulators, but The Long Dark by Hinterland Games, which I purchased back then when it was still in early access on Steam, took me into new realms. You are tossed out into the Canadian wilderness with hardly anything, and your only aim is to survive, find shelter, food, craft tools, hunt for food, explore. And while everything by now is Sandbox mode, on August 1st the first episode of Story mode is released. Best time to get the game! You will be greeted with some icy nights, but also with great vistas, relaxed evenings at a fire place, you will try to survive on moldy food and rotten energy bars, but also feast on the fireside while reading a good book. A real treat this game! Sandbox mode features five different areas to explore. Each one is large enough to spend weeks (in game time) wandering around. The easiest area to start with is Mystery Lake, with plenty of shelter (several huts) and abundance of resources. And just in case you are getting bored, all the areas are connected via tunnels or caves and one can wander of into the neighboring places. My home in Mystery Lake was always the Camp Office, the usual suspect. Nice views, fishing huts nearby to get fresh fish, lots of space. After managing to get from your starting place (which is arbitrary as far as I see) to one of the shelters, one starts collecting food, wood, savaging every accessible place for tools, weapons, burning material. And soon the backpack becomes to heavy, and one needs to store stuff and decide what to take. This is a very well done part of the game. The backpack is not limited by number of items, but you are limited in weight you can carry. That includes clothes (which can get quite heavy) and all the items in your backpack. In addition, the longer the day and the more tired you become, the less weight you can carry. And if the backpack starts getting too heavy you crawl to a very slow movement. There are many influences of the outside world on the player s condition: temperature, the wetness of your clothes, hunger, thirst, exhaustion, but also infections and bruises, all need to be taken care of, otherwise the end is coming faster than one wishes for. I have only two things to complain: First, if one walks outside, or runs outside, the own body temperature does not rise. This is unrealistically and should have been taken into account. The other thing is the difficulty: I have played weeks in game time in the easiest level, without any problem. But the moment I switched to the second level of difficulty (of 5!), I not even manage it for 2(!) days. Wolves, starvation, thirst, any of those kills me within an instant. I don t want to know how the hardest level feels, but it has a certain steep step here. The game takes a very realistic view onto the weather: Every day is different, sunny, foggy, blizzard, windy, often changing very quickly. It is wise to plan one s activities according to the weather, as it is very unforgiving. With beautifully crafted landscapes, loads of areas to explore, your own pride to survive for at least a few weeks, and lots of tools to find and craft and try out, this games, even while it is still in Sandbox mode, is a real feat. My absolute favorite since I have finished the Talos Principle and Portal series, absolutely recommendable!
28 July 2017

Joachim Breitner: How is coinduction the dual of induction?

Earlier today, I demonstrated how to work with coinduction in the theorem provers Isabelle, Coq and Agda, with a very simple example. This reminded me of a discussion I had in Karlsruhe with my then colleague Denis Lohner: If coinduction is the dual of induction, why do the induction principles look so different? I like what we observed there, so I d like to share this. The following is mostly based on my naive understanding of coinduction based on what I observe in the implementation in Isabelle. I am sure that a different, more categorial presentation of datatypes (as initial resp. terminal objects in some category of algebras) makes the duality more obvious, but that does not necessarily help the working Isabelle user who wants to make sense of coninduction.

Inductive lists I will use the usual polymorphic list data type as an example. So on the one hand, we have normal, finite inductive lists:
datatype 'a list = nil   cons (hd : 'a) (tl : "'a list")
with the well-known induction principle that many of my readers know by heart (syntax slightly un-isabellized):
P nil   ( x xs. P xs   P (cons x xs))     xs. P xs

Coinductive lists In contrast, if we define our lists coinductively to get possibly infinite, Haskell-style lists, by writing
codatatype 'a llist = lnil   lcons (hd : 'a)  (tl : "'a llist")
we get the following coinduction principle:
(  xs ys.
    R xs ys'   (xs = lnil) = (ys = lnil)  
               (xs   lnil   ys'   lnil  
	         hd xs = hd ys   R (tl xs) (tl ys)))  
  (  xs ys. R xs ys   xs = ys)
This is less scary that it looks at first. It tell you if you give me a relation R between lists which implies that either both lists are empty or both lists are nonempty, and furthermore if both are non-empty, that they have the same head and tails related by R, then any two lists related by R are actually equal. If you think of the infinte list as a series of states of a computer program, then this is nothing else than a bisimulation. So we have two proof principles, both of which make intuitive sense. But how are they related? They look very different! In one, we have a predicate P, in the other a relation R, to point out just one difference.

Relation induction To see how they are dual to each other, we have to recognize that both these theorems are actually specializations of a more general (co)induction principle. The datatype declaration automatically creates a relator:
rel_list :: ('a   'b   bool)   'a list   'b list   bool
The definition of rel_list R xs ys is that xs and ys have the same shape (i.e. length), and that the corresponding elements are pairwise related by R. You might have defined this relation yourself at some time, and if so, you probably introduced it as an inductive predicate. So it is not surprising that the following induction principle characterizes this relation:
Q nil nil  
( x xs y ys. R x y   Q xs ys   Q (cons x xs) (cons y ys))  
( xs ys   rel_list R xs ys   Q xs ys)
Note how how similar this lemma is in shape to the normal induction for lists above! And indeed, if we choose Q xs ys (P xs xs = ys) and R x y (x = y), then we obtain exactly that. In that sense, the relation induction is a generalization of the normal induction.

Relation coinduction The same observation can be made in the coinductive world. Here, as well, the codatatype declaration introduces a function
rel_llist :: ('a   'b   bool)   'a llist   'b llist   bool
which relates lists of the same shape with related elements only that this one also relates infinite lists, and therefore is a coinductive relation. The corresponding rule for proof by coinduction is not surprising and should remind you of bisimulation, too:
( xs ys.
    R xs ys   (xs = lnil) = (ys = lnil)  
              (xs   lnil   ys   lnil  
	        Q (hd xs) (hd ys)   R (tl xs) (tl ys)))  
(  xs ys   R xs ys   rel_llist Q xs ys)
It is even more obvious that this is a generalization of the standard coinduction principle shown above: Just instantiate Q with equality, which turns rel_llist Q into equality on the lists, and you have the theorem above.

The duality With our induction and coinduction principle generalized to relations, suddenly a duality emerges: If you turn around the implication in the conclusion of one you get the conclusion of the other one. This is an example of cosomething is something with arrows reversed . But what about the premise(s) of the rules? What happens if we turn around the arrow here? Although slighty less immediate, it turns out that they are the same as well. To see that, we start with the premise of the coinduction rule, reverse the implication and then show that to be equivalent to the two premises of the induction rule:
( xs ys.
    R xs ys   (xs = lnil) = (ys = lnil)  
              (xs   lnil   ys   lnil  
	        Q (hd xs) (hd ys)   R (tl xs) (tl ys)))
=   case analysis (the other two cases are vacuously true)  
  ( xs ys.
    xs = lnil   ys = lnil  
    R xs ys   (xs = lnil) = (ys = lnil)  
              (xs   lnil   ys   lnil  
	        Q (hd xs) (hd ys)   R (tl xs) (tl ys)))
  ( xs ys.
    xs   lnil   ys   lnil
    R xs ys   (xs = lnil) = (ys = lnil)  
              (xs   lnil   ys   lnil  
	        Q (hd xs) (hd ys)   R (tl xs) (tl ys)))
=   simplification  
  ( xs ys.  xs = lnil   ys = lnil   R xs ys
  ( x xs y ys.  R (cons x xs) (cons y ys)   (Q x y   R xs ys))
=   more rewriting  
  R nil nil
  ( x xs y ys. Q x y   R xs ys   R (cons x xs) (cons y ys))

Conclusion The coinduction rule is not the direct dual of the induction rule, but both are specializations of more general, relational proof methods, where the duality is clearly present. More generally, this little excursion shows that it is often beneficial to think of types less as sets, and more as relations this way of thinking is surprisingly fruitful, and led to proofs of parametricity and free theorems and other nice things.

27 July 2017

Joachim Breitner: Coinduction in Coq and Isabelle

The DeepSpec Summer School is almost over, and I have had a few good discussions. One revolved around coinduction: What is it, how does it differ from induction, and how do you actually prove something. In the course of the discussion, I came up with a very simple coinductive exercise, and solved it both in Coq and Isabelle

The task Define the extended natural numbers coinductively. Define the min function and the relation. Show that min(n, m) n holds.

Coq The definitions are straight forward. Note that in Coq, we use the same command to define a coinductive data type and a coinductively defined relation:
CoInductive ENat :=
    N : ENat
    S : ENat -> ENat.
CoFixpoint min (n : ENat) (m : ENat)
  :=match n, m with   S n', S m' => S (min n' m')
                      _, _       => N end.
CoInductive le : ENat -> ENat -> Prop :=
    leN : forall m, le N m
    leS : forall n m, le n m -> le (S n) (S m).
The lemma is specified as
Lemma min_le: forall n m, le (min n m) n.
and the proof method of choice to show that some coinductive relation holds, is cofix. One would wish that the following proof would work:
Lemma min_le: forall n m, le (min n m) n.
Proof.
  cofix.
  destruct n, m.
  * apply leN.
  * apply leN.
  * apply leN.
  * apply leS.
    apply min_le.
Qed.
but we get the error message
Error:
In environment
min_le : forall n m : ENat, le (min n m) n
Unable to unify "le N ?M170" with "le (min N N) N
Effectively, as Coq is trying to figure out whether our proof is correct, i.e. type-checks, it stumbled on the equation min N N = N, and like a kid scared of coinduction, it did not dare to run the min function. The reason it does not just run a CoFixpoint is that doing so too daringly might simply not terminate. So, as Adam explains in a chapter of his book, Coq reduces a cofixpoint only when it is the scrutinee of a match statement. So we need to get a match statement in place. We can do so with a helper function:
Definition evalN (n : ENat) :=
  match n with   N => N
                 S n => S n end.
Lemma evalN_eq : forall n, evalN n = n.
Proof. intros. destruct n; reflexivity. Qed.
This function does not really do anything besides nudging Coq to actually evaluate its argument to a constructor (N or S _). We can use it in the proof to guide Coq, and the following goes through:
Lemma min_le: forall n m, le (min n m) n.
Proof.
  cofix.
  destruct n, m; rewrite <- evalN_eq with (n := min _ _).
  * apply leN.
  * apply leN.
  * apply leN.
  * apply leS.
    apply min_le.
Qed.

Isabelle In Isabelle, definitions and types are very different things, so we use different commands to define ENat and le:
theory ENat imports  Main begin
codatatype ENat =  N   S  ENat
primcorec min where
   "min n m = (case n of
       N   N
       S n'   (case m of
        N   N
        S m'   S (min n' m')))"
coinductive le where
  leN: "le N m"
  leS: "le n m   le (S n) (S m)"
There are actually many ways of defining min; I chose the one most similar to the one above. For more details, see the corec tutorial. Now to the proof:
lemma min_le: "le (min n m) n"
proof (coinduction arbitrary: n m)
  case le
  show ?case
  proof(cases n)
    case N then show ?thesis by simp
  next
    case (S n') then show ?thesis
    proof(cases m)
      case N then show ?thesis by simp
    next
      case (S m')  with  n = _  show ?thesis
        unfolding min.code[where n = n and m = m]
        by auto
    qed
  qed
qed
The coinduction proof methods produces this goal:
proof (state)
goal (1 subgoal):
 1.  n m. ( m'. min n m = N   n = m')  
          ( n' m'.
               min n m = S n'  
               n = S m'  
	       (( n m. n' = min n m   m' = n)   le n' m'))
I chose to spell the proof out in the Isar proof language, where the outermost proof structure is done relatively explicity, and I proceed by case analysis mimiking the min function definition. In the cases where one argument of min is N, Isabelle s simplifier (a term rewriting tactic, so to say), can solve the goal automatically. This is because the primcorec command produces a bunch of lemmas, one of which states n = N m = N min n m = N. In the other case, we need to help Isabelle a bit to reduce the call to min (S n) (S m) using the unfolding methods, where min.code contains exactly the equation that we used to specify min. Using just unfolding min.code would send this method into a loop, so we restrict it to the concrete arguments n and m. Then auto can solve the remaining goal (despite all the existential quantifiers).

Summary Both theorem provers are able to prove the desired result. To me it seems that it is slightly more convenient in Isabelle because a lot of Coq infrastructure relies on the type checker being able to effectively evaluate expressions, which is tricky with cofixpoints, wheras evaluation plays a much less central role in Isabelle, where rewriting is the crucial technique, and while one still cannot simply throw min.code into the simpset, so working with objects that do not evaluate easily or completely is less strange.

Agda I was challenged to do it in Agda. Here it is:
module ENat where
open import Coinduction
data ENat : Set where
  N : ENat
  S :   ENat   ENat
min : ENat   ENat   ENat
min (S n') (S m') = S (  (min (  n') (  m')))
min _ _ = N
data le : ENat   ENat   Set where
  leN :    m    le N m
  leS :    n m      (le (  n) (  m))   le (S n) (S m)
min_le :    n m    le (min n m) n
min_le  S n'   S m'  = leS (  min_le)
min_le  N      S m'  = leN
min_le  S n'   N  = leN
min_le  N      N  = leN
I will refrain from commenting it, because I do not really know what I have been doing here, but it typechecks, and refer you to the official documentation on coinduction in Agda. But let me note that I wrote this using plain inductive types and recursion, and added , and until it worked.

Michal &#268;iha&#345;: Weblate 2.16: Call for translations

Weblate 2.16 is almost ready (I expect no further code changes), so it's really great time to contribute to it's translations! Weblate 2.16 will be probably released during my presence at DebConf 17. As you might expect, Weblate is translated using Weblate, so the contributions should be really easy. In case there is something unclear, you can look into Weblate documentation. I'd especially like to see improvements in the Italian translation which was one of the first in Weblate beginnings, but hasn't received much love in past years.

Filed under: Debian English SUSE Weblate

25 July 2017

Reproducible builds folks: Reproducible Builds: week 117 in Buster cycle

Here's what happened in the Reproducible Builds effort between Sunday July 16 and Saturday July 22 2017: Toolchain development Bernhard M. Wiedemann wrote a tool to automatically run through different sources of non-determinism, and report which of these caused irreproducibility. Dan Kegel's patches to fpm were merged. Bugs filed Patches submitted upstream: Patches filed in Debian: Reviews of unreproducible packages 73 package reviews have been added, 44 have been updated and 50 have been removed in this week, adding to our knowledge about identified issues. No issue types were updated. Weekly QA work During our reproducibility testing, FTBFS bugs have been detected and reported by: diffoscope development reprotest development Ximin also restarted the discussion with autopkgtest-devel about code reuse for reprotest. Santiago Torres began a series of patches to make reprotest more distro-agnostic, with the aim of making it usable on Arch Linux. Ximin reviewed these patches. Misc. This week's edition was written by Ximin Luo, Bernhard M. Wiedemann and Chris Lamb & reviewed by a bunch of Reproducible Builds folks on IRC & the mailing lists.

24 July 2017

Jonathan Carter: Plans for DebCamp17

In a few days, I ll be attending DebCamp17 in Montr al, Canada. Here are a few things I plan to pay attention to:

Joerg Jaspert: Automated wifi login, update

With recent changes the automated login script for WifiOnICE stopped working. Fortunately a fix is easy, it is enough to add a referrer header to the call and have de/ added to the url. Updated script:
#!/bin/bash
# (Some) docs at
# https://wiki.ubuntuusers.de/NetworkManager/Dispatcher/
IFACE=$ 1:-"none" 
ACTION=$ 2:-"up" 
case $ ACTION  in
    up)
        CONID=$ CONNECTION_ID:-$(iwgetid "$ IFACE " -r) 
        if [[ $ CONID  == WIFIonICE ]]; then
            /usr/bin/timeout -k 20 15 /usr/bin/wget -q -O - --referer http://www.wifionice.de/de/ http://www.wifionice.de/de/?login > /dev/null
        fi
        ;;
    *)
        # We are not interested in this
        :
        ;;
esac

23 July 2017

Vincent Fourmond: Screen that hurts my eyes, take 2

Six month ago, I wrote a lengthy post about my new computer hurting my eyes. I haven't made any progress with that, but I've accidentally upgraded my work computer from Kernel 4.4 to 4.8 and the nvidia drivers from 340.96-4 to 375.66-2. Well, my work computer now hurts, I've switched back to the previous kernel and drivers, I hope it'll be back to normal.Any ideas of something specific that changed, either between 4.4 and 4.8 (kernel startup code, default framebuffer modes, etc ?), or between the 340.96 and the 375.66 drivers ? In any case, I'll try that specific combination of kernels/drivers home to see if I can get it to a useable state.Update, July 23rdI reverted to the earlier drivers/kernel, to no avail. But it seems in fact the problem with my work computer is linked to an allergy of some kind, since antihistamine drugs have an effect (there are construction works in my lab, perhaps they are the cause ?). No idea still for my home computer, for which the problem is definitely not solved.

22 July 2017

Niels Thykier: Improving bulk performance in debhelper

Since debhelper/10.3, there has been a number of performance related changes. The vast majority primarily improves bulk performance or only have visible effects at larger input sizes. Most visible cases are: For debhelper, this mostly involved: How to take advantage of these improvements in tools that use Dh_Lib: Credits: I would like to thank the following for reporting performance issues, regressions or/and providing patches. The list is in no particular order: Should I have missed your contribution, please do not hesitate to let me know.
Filed under: Debhelper, Debian

18 July 2017

Reproducible builds folks: Reproducible Builds: week 116 in Stretch cycle

Here's what happened in the Reproducible Builds effort between Sunday July 9 and Saturday July 15 2017: Packages reviewed and fixed, and bugs filed Reviews of unreproducible packages 13 package reviews have been added, 12 have been updated and 19 have been removed in this week, adding to our knowledge about identified issues. 2 issue types have been added: 3 issue types have been updated: Weekly QA work During our reproducibility testing, FTBFS bugs have been detected and reported by: diffoscope development Version 84 was uploaded to unstable by Mattia Rizzolo. It included contributions already reported from the previous weeks, as well as new ones: After the release, development continued in git with contributions from: strip-nondeterminism development Versions 0.036-1, 0.037-1 and 0.038-1 were uploaded to unstable by Chris Lamb. They included contributions from: reprotest development Development continued in git with contributions from: buildinfo.debian.net development tests.reproducible-builds.org Misc. This week's edition was written by Bernhard M. Wiedemann, Chris Lamb, Mattia Rizzolo, Vagrant Cascadian & reviewed by a bunch of Reproducible Builds folks on IRC & the mailing lists.

Norbert Preining: Calibre and rar support

Thanks to the cooperation with upstream authors and the maintainer Martin Pitt, the Calibre package in Debian is now up-to-date at version 3.4.0, and has adopted a more standard packaging following upstream. In particular, all the desktop files and man pages have been replaced by what is shipped by Calibre. What remains to be done is work on RAR support.
Rar support is necessary in the case that the eBook uses rar as compression, which happens quite often in comic books (cbr extension). Calibre 3 has split out rar support into a dynamically loaded module, so what needs to be done is packaging it. I have prepared a package for the Python library unrardll which allows Calibre to read rar-compressed ebooks, but it depends on the unrar shared library, which unfortunately is not built in Debian. I have sent a patch to fix this to the maintainer, see bug 720051, but without reaction from the maintainer. Thus, I am publishing updated packages for unrar shipping also libunrar5, and unrardll Python package in my calibre repository. After installing python-unrardll Calibre will happily import meta-data from rar-compressed eBooks, as well as display them.
deb http://www.preining.info/debian/ calibre main
deb-src http://www.preining.info/debian/ calibre main
The releases are signed with my Debian key 0x6CACA448860CDC13 Enjoy

17 July 2017

Steinar H. Gunderson: Solskogen 2017: Nageru all the things

Solskogen 2017 is over! What a blast that was; I especially enjoyed that so many old-timers came back to visit, it really made the party for me. This was the first year we were using Nageru for not only the stream but also for the bigscreen mix, and I was very relieved to see the lack of problems; I've had nightmares about crashes with 150+ people watching (plus 200-ish more on stream), but there were no crashes and hardly a dropped frame. The transition to a real mixing solution as well as from HDMI to SDI everywhere gave us a lot of new opportunities, which allowed a number of creative setups, some of them cobbled together on-the-spot: It's been a lot of fun, but also a lot of work. And work will continue for an even better show next year after some sleep. :-)

15 July 2017

Dirk Eddelbuettel: Rcpp 0.12.12: Rounding some corners

The twelveth update in the 0.12.* series of Rcpp landed on CRAN this morning, following two days of testing at CRAN preceded by five full reverse-depends checks we did (and which are always logged in this GitHub repo). The Debian package has been built and uploaded; Windows and macOS binaries should follow at CRAN as usual. This 0.12.12 release follows the 0.12.0 release from late July, the 0.12.1 release in September, the 0.12.2 release in November, the 0.12.3 release in January, the 0.12.4 release in March, the 0.12.5 release in May, the 0.12.6 release in July, the 0.12.7 release in September, the 0.12.8 release in November, the 0.12.9 release in January, the 0.12.10.release in March, and the 0.12.11.release in May making it the sixteenth release at the steady and predictable bi-montly release frequency. Rcpp has become the most popular way of enhancing GNU R with C or C++ code. As of today, 1097 packages (and hence 71 more since the last release in May) on CRAN depend on Rcpp for making analytical code go faster and further, along with another 91 in BioConductor. This releases contain a fairly large number of fairly small and focused pull requests most of which either correct some corner cases or improve other aspects. JJ tirelessly improved the package registration added in the previous release and following R 3.4.0. Kirill tidied up a number of small issues allowing us to run compilation in even more verbose modes---usually a good thing. Jeroen, Elias Pipping and Yo Gong all contributed as well, and we thank everybody for their contributions. All changes are listed below in some detail.

Changes in Rcpp version 0.12.12 (2017-07-13)
  • Changes in Rcpp API:
    • The tinyformat.h header now ends in a newline (#701).
    • Fixed rare protection error that occurred when fetching stack traces during the construction of an Rcpp exception (Kirill M ller in #706).
    • Compilation is now also possibly on Haiku-OS (Yo Gong in #708 addressing #707).
    • Dimension attributes are explicitly cast to int (Kirill M ller in #715).
    • Unused arguments are no longer declared (Kirill M ller in #716).
    • Visibility of exported functions is now supported via the R macro atttribute_visible (Jeroen Ooms in #720).
    • The no_init() constructor accepts R_xlen_t (Kirill M ller in #730).
    • Loop unrolling used R_xlen_t (Kirill M ller in #731).
    • Two unused-variables warnings are now avoided (Jeff Pollock in #732).
  • Changes in Rcpp Attributes:
    • Execute tools::package_native_routine_registration_skeleton within package rather than current working directory (JJ in #697).
    • The R portion no longer uses dir.exists to no require R 3.2.0 or newer (Elias Pipping in #698).
    • Fix native registration for exports with name attribute (JJ in #703 addressing #702).
    • Automatically register init functions for Rcpp Modules (JJ in #705 addressing #704).
    • Add Shield around parameters in Rcpp::interfaces (JJ in #713 addressing #712).
    • Replace dot (".") with underscore ("_") in package names when generating native routine registrations (JJ in #722 addressing #721).
    • Generate C++ native routines with underscore ("_") prefix to avoid exporting when standard exportPattern is used in NAMESPACE (JJ in #725 addressing #723).

Thanks to CRANberries, you can also look at a diff to the previous release. As always, even fuller details are on the Rcpp Changelog page and the Rcpp page which also leads to the downloads page, the browseable doxygen docs and zip files of doxygen output for the standard formats. A local directory has source and documentation too. Questions, comments etc should go to the rcpp-devel mailing list off the R-Forge page.

This post by Dirk Eddelbuettel originated on his Thinking inside the box blog. Please report excessive re-aggregation in third-party for-profit settings.

Vasudev Kamath: debcargo: Replacing subprocess crate with git2 crate

In my previous post I talked about using subprocess crate to extract beginning and ending year from git repository for generating debian/copyright file. In this post I'm going to talk on how I replaced subprocess with native git2 crate and achieved the same result in much cleaner and safer way. git2 is a native Rust crate which provides access to Git repository internals. git2 does not involve any unsafe invocation as it is built against libgit2-sys which is actually using Rust FFI to directly bind to underlying libgit library. Below is the new copyright_fromgit function with git2 crate.
fn copyright_fromgit(repo_url: &str) -> Result<String>  
   let tempdir = TempDir::new_in(".", "debcargo")?;
   let repo = Repository::clone(repo_url, tempdir.path())?;
   let mut revwalker = repo.revwalk()?;
   revwalker.push_head()?;
   // Get the latest and first commit id. This is bit ugly
   let latest_id = revwalker.next().unwrap()?;
   let first_id = revwalker.last().unwrap()?; // revwalker ends here is consumed by last
   let first_commit = repo.find_commit(first_id)?;
   let latest_commit = repo.find_commit(latest_id)?;
   let first_year =
       DateTime::<Utc>::from_utc(
               NaiveDateTime::from_timestamp(first_commit.time().seconds(), 0),
               Utc).year();
   let latest_year =
       DateTime::<Utc>::from_utc(
             NaiveDateTime::from_timestamp(latest_commit.time().seconds(), 0),
             Utc).year();
   let notice = match first_year.cmp(&latest_year)  
       Ordering::Equal => format!(" ", first_year),
       _ => format!(" - ,", first_year, latest_year),
    ;
   Ok(notice)
 
So here is what I'm doing
  1. Use git2::Repository::clone to clone the given URL. We are thus avoiding exec of git clone command.
  2. Get a revision walker object. git2::RevWalk implements Iterator trait and allows walking through the git history. This is what we are using to avoid exec of git log command.
  3. revwalker.push_head() is important because we want to tell revwalker from where we want to walk the history. In this case we are asking it to walk history from repository HEAD. Without this line next line will not work. (Learned it in hard way :-) ).
  4. Then we extract git2::Oid which is we can say similar to commit hash and can be used to lookup a particular commit. We take latest commit hash using RevWalk::next call and the first commit using Revwalk::last, note the order this is because Revwalk::last consumes the revwalker so doing it in reverse order will make borrow checker unhappy :-). This replaces exec of head -n1 command.
  5. Look up the git2::Commit objects using git2::Repository::find_commit
  6. Then convert the git2::Time to chrono::DateTime and take out the years.
After this change I found an obvious error which went unnoticed in previous version, that is if there was no repository key in Cargo.toml. When there was no repo URL git clone exec did not error out and our shell commands happily extracted year from the debcargo repository!. Well since I was testing code from debcargo repository It never failed, but when I executed from non-git repository folder git threw an error but that was git log and not git clone. This error was spotted right away because git2 threw me an error that I gave it empty URL. When it comes to performance I see that debcargo is faster compared to previous version. This makes sense because previously it was doing 5 fork and exec system calls and now that is avoided.

Next.

Previous.