Search Results: "cas"

16 August 2017

Ross Gammon: My Debian & Ubuntu work from April to mid-August 2017
Okay, so I have been slack with my blogging again. I have been travelling around Europe with work quite a bit, had a short holiday over Easter in Denmark, and also had 3 weeks of Summer Holiday in Germany. Debian
  • Tidied up the packaging and tried building the latest version of libdrumstick, but tests had been added to the package by upstream which were failing. I still need to get back and investigate that.
  • Updated node-seq (targeted at experimental due to the Debian Stretch release freeze) and asked for sponsorship (as I did not have DM rights for it yet).
  • Uploaded the latest version of abcmidi (also to experimental), and again.
  • Updated node-tmp to the latest version and uploaded to experimental.
  • Worked some more on bluebird RFP, but getting errors when running tests. I still haven t gone back to investigate that.
  • Updated node-coffeeify to the latest version and uploaded to experimental.
  • Uploaded the latest version of node-os-tmpdir (also to experimental).
  • Uploaded the latest version of node-concat-stream (also to experimental).
  • After encouragement from several Debian Developers, I applied to become a full Debian Developer. Over the summer months I worked with Santiago as my Application Manager and answered questions about working in the Debian Project.
  • A web vulnerability was identified in node-concat-stream, so I prepared a fix to the version in unstable, uploaded it to unstable, and submitted a unblock request bug so that it would be fixed in the coming Debian Stretch release.
  • Debian 10 (Stretch) was released! Yay!
  • Moved abcmidi from experimental to unstable, adding an autopkgtest at the same time.
  • Moved node-concat-stream from experimental to unstable. During the process I had to take care of the intermediate upload to stretch (on a separate branch) because of the freeze.
  • Moved node-tmp to unstable from experimental.
  • Moved node-os-tmpdir from experimental to unstable.
  • Filed a removal bug for creepy, which seems to be unmaintained upstream these days. Sent my unfinished Qt4 to Qt5 porting patches upstream just in case!
  • Uploaded node-object-inspect to experimental to check the reverse dependencies, then moved it to unstable. Then a new upstream version came out which is now in experimental waiting for a retest of reverse dependencies.
  • Uploaded the latest version of gramps (4.2.6).
  • Uploaded a new version of node-cross-spawn to experimental.
  • Discovered that I had successfully completed the DD application process and I was now a Debian Developer. I celebrated by uploading the Debian Multimedia Blends package to the NEW queue, which I was not able to do before!
  • Tweaked and uploaded the node-seq package (with an RC fix) which had been sitting there because I did not have DM rights to the package. It is not an important package anyhow, as it is just one of the many dependencies that need to be packaged for Browserify.
  • Packaged and uploaded the latest node-isarray directly to unstable, as the changes seemed harmless.
  • Prepared and uploaded the latest node-js-yaml to experimental.
  • Did an update to the Node packaging Manual now that we are allowed to use node as the executable in Debian instead of nodejs which caused us to do a lot of patching in the past to get node packages working in Debian.
Ubuntu
  • Did a freeze exception bug for ubuntustudio-controls, but we did not manage to get it sponsored before the Ubuntu Studio Zesty 17.04 release.
  • Investigated why Ardour was not migrating from zesty-proposed, but I couldn t be sure of what was holding it up. After getting some help from the Developer s mailing list, I prepared no change rebuild of pd-aubio which was sponsored by Steve Langasek after a little tweak. This did the trick.
  • Wrote to the Ubuntu Studio list asking for support for testing the Ubuntu Studio Zesty release, as I would be on holiday in the lead up to the release. When I got back, I found the release had gone smoothly. Thanks team!
  • Worked on some blueprints for the next Ubuntu Studio Artful release.
  • As Set no longer has enough spare time to work on Ubuntu Studio, we had a meeting on IRC to decide what to do. We decided that we should set up a Council like Xubuntu have. I drafted an announcement, but we still have not gone live with it yet. Maybe someone will have read this far and give us a push (or help).
  • Did a quick test of Len s ubuntustudio-controls re-write (at least the GUI bits). We better get a move on if we want this to be part of Artful!
  • Tested ISO for Ubuntu Studio Xenial 16.04.3 point release, and updated the release notes.
  • Started working on a merge of Qjackctl using git-ubuntu for the first time. Had some issues getting going, so I asked the authors for some advice.


15 August 2017

Lisandro Dami n Nicanor P rez Meyer: Qt 4 removal in Debian testing (Buster)/unstable

We have been announcing it: we are going to remove Qt 4 during the Buster cycle.

Or at least that's the best outcome we can expect. Removing a very highly used library is hard, as Qt4's Webkit has proved. Qt 4 is long dead upstream and we have already started to need to patch it with untested patches as in the OpenSSL 1.1 case (will be in experimental in a few hours after this post).

We will try to put as less effort as possible in keeping it alive meaning that from now on if we need to patch it to make it support a newer lib or alike we will simply remove its support if possible. Using the OpenSSL case as an example, if we need to support any version > 1.1 we will simply remove the SSL support. That means things will break.

So, if you depend on FLOSS which is still based on Qt 4 be sure to try to port it. If you depend on a proprietary vendor software which uses Qt 4 then you better start telling them it's really time to update it. Really.

We will soon start filing bugs against packages using Qt 4. I'll update this blog post later to add that info.

For the Qt/KDE team, Lisandro.

14 August 2017

Reproducible builds folks: Reproducible Builds: Weekly report #119

Here's what happened in the Reproducible Builds effort between Sunday July 30 and Saturday August 5 2017: Media coverage We were mentioned on Late Night Linux Episode 17, around 29:30. Packages reviewed and fixed, and bugs filed Upstream packages: Debian packages: Reviews of unreproducible packages 29 package reviews have been added, 72 have been updated and 151 have been removed in this week, adding to our knowledge about identified issues. 4 issue types have been updated: Weekly QA work During our reproducibility testing, FTBFS bugs have been detected and reported by: diffoscope development Version 85 was uploaded to unstable by Mattia Rizzolo. It included contributions from: as well as previous weeks' contributions, summarised in the changelog. There were also further commits in git, which will be released in a later version: Misc. This week's edition was written by Ximin Luo, Bernhard M. Wiedemann and Chris Lamb & reviewed by a bunch of Reproducible Builds folks on IRC & the mailing lists.

13 August 2017

Enrico Zini: Consensually doing things together?

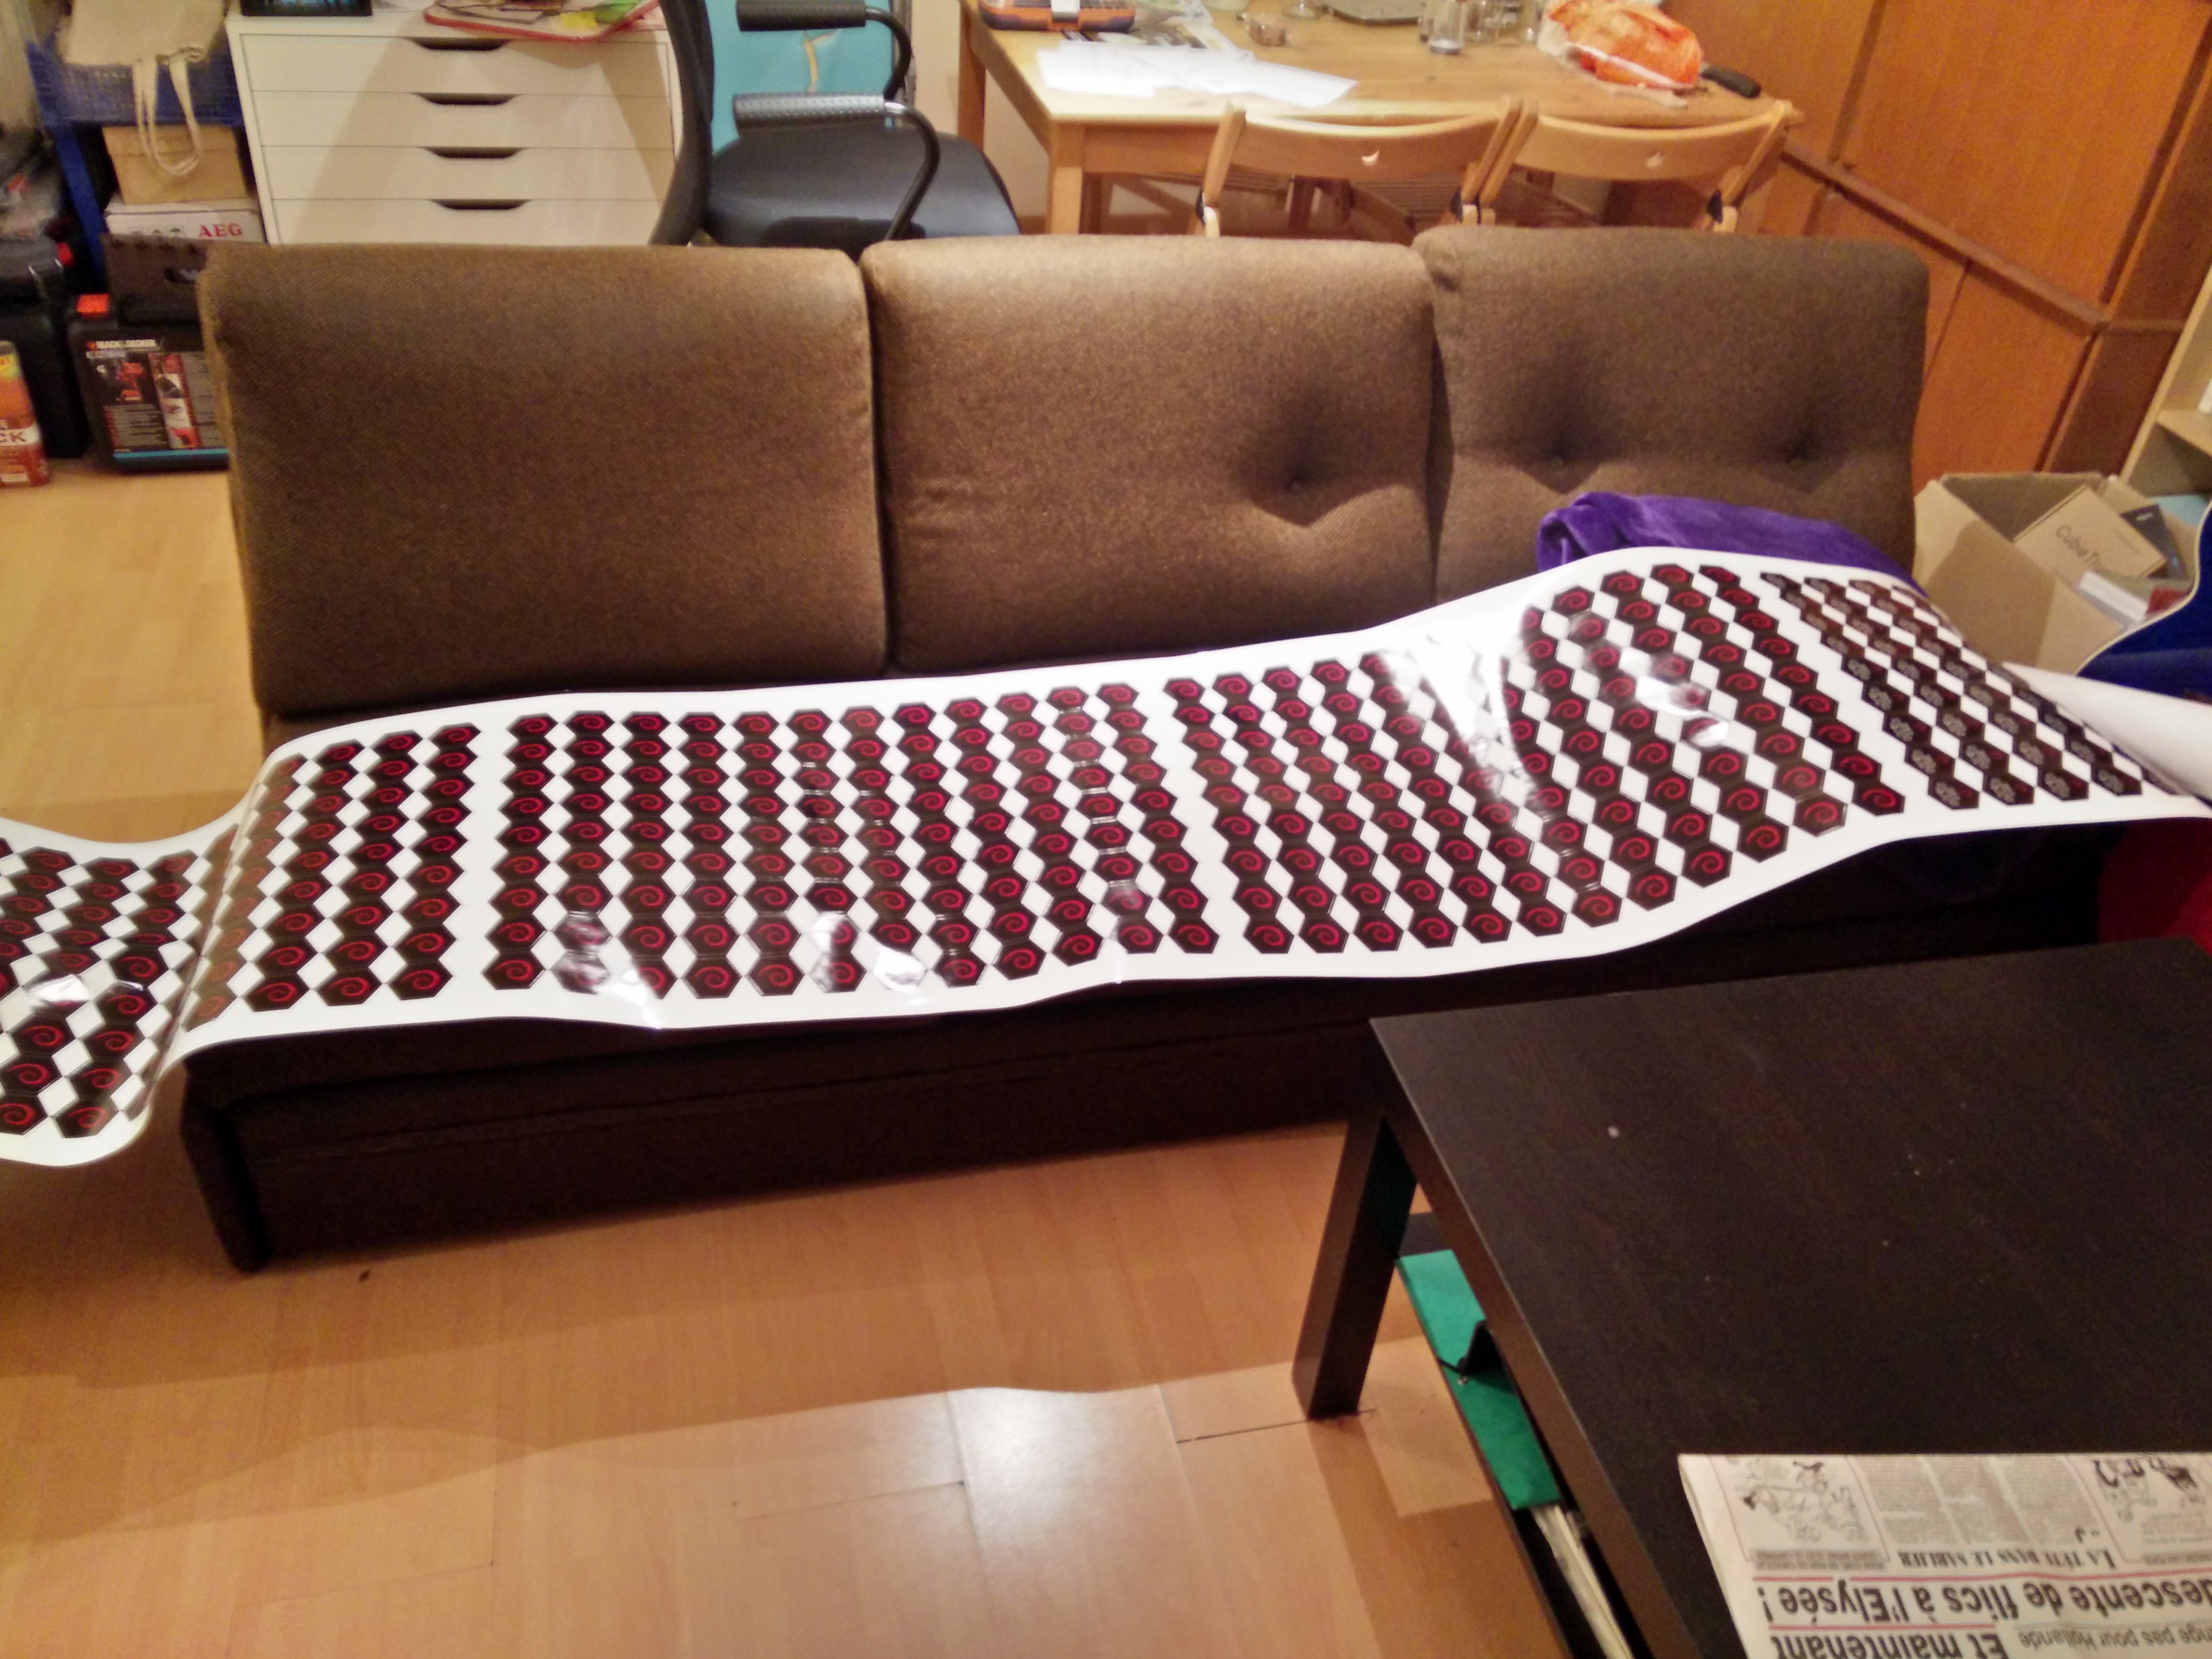
On 2017-08-06 I have a talk at DebConf17 in Montreal titled "Consensually doing things together?" (video). Here are the talk notes. Abstract At DebConf Heidelberg I talked about how Free Software has a lot to do about consensually doing things together. Is that always true, at least in Debian? I d like to explore what motivates one to start a project and what motivates one to keep maintaining it. What are the energy levels required to manage bits of Debian as the project keeps growing. How easy it is to say no. Whether we have roles in Debian that require irreplaceable heroes to keep them going. What could be done to make life easier for heroes, easy enough that mere mortals can help, or take their place. Unhappy is the community that needs heroes, and unhappy is the community that needs martyrs. I d like to try and make sure that now, or in the very near future, Debian is not such an unhappy community. Consensually doing things together I gave a talk in Heidelberg. Valhalla made stickers Debian France distributed many of them. There's one on my laptop. Which reminds me of what we ought to be doing. Of what we have a chance to do, if we play our cards right. I'm going to talk about relationships. Consensual relationships. Relationships in short. Nonconsensual relationships are usually called abuse. I like to see Debian as a relationship between multiple people. And I'd like it to be a consensual one. I'd like it not to be abuse. Consent From wikpedia:
In Canada "consent means the voluntary agreement of the complainant to engage in sexual activity" without abuse or exploitation of "trust, power or authority", coercion or threats.[7] Consent can also be revoked at any moment.[8] There are 3 pillars often included in the description of sexual consent, or "the way we let others know what we're up for, be it a good-night kiss or the moments leading up to sex." They are:
  • Knowing exactly what and how much I'm agreeing to
  • Expressing my intent to participate
  • Deciding freely and voluntarily to participate[20]
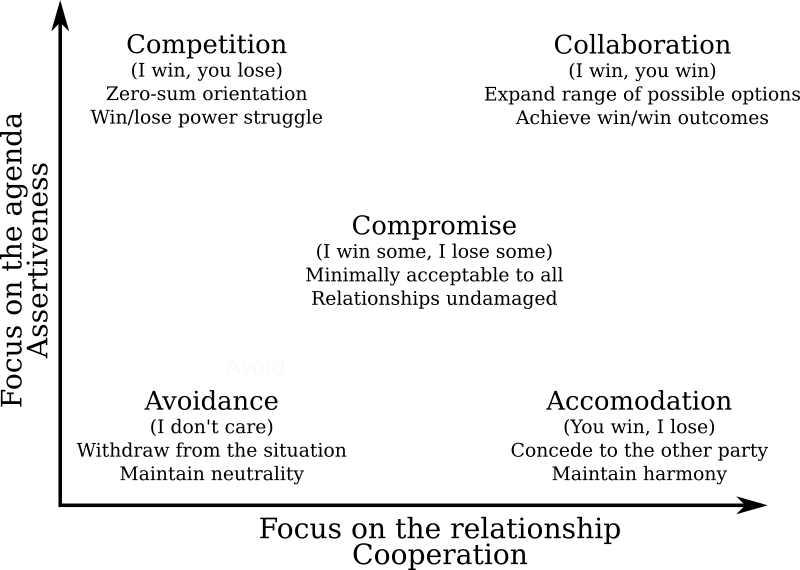
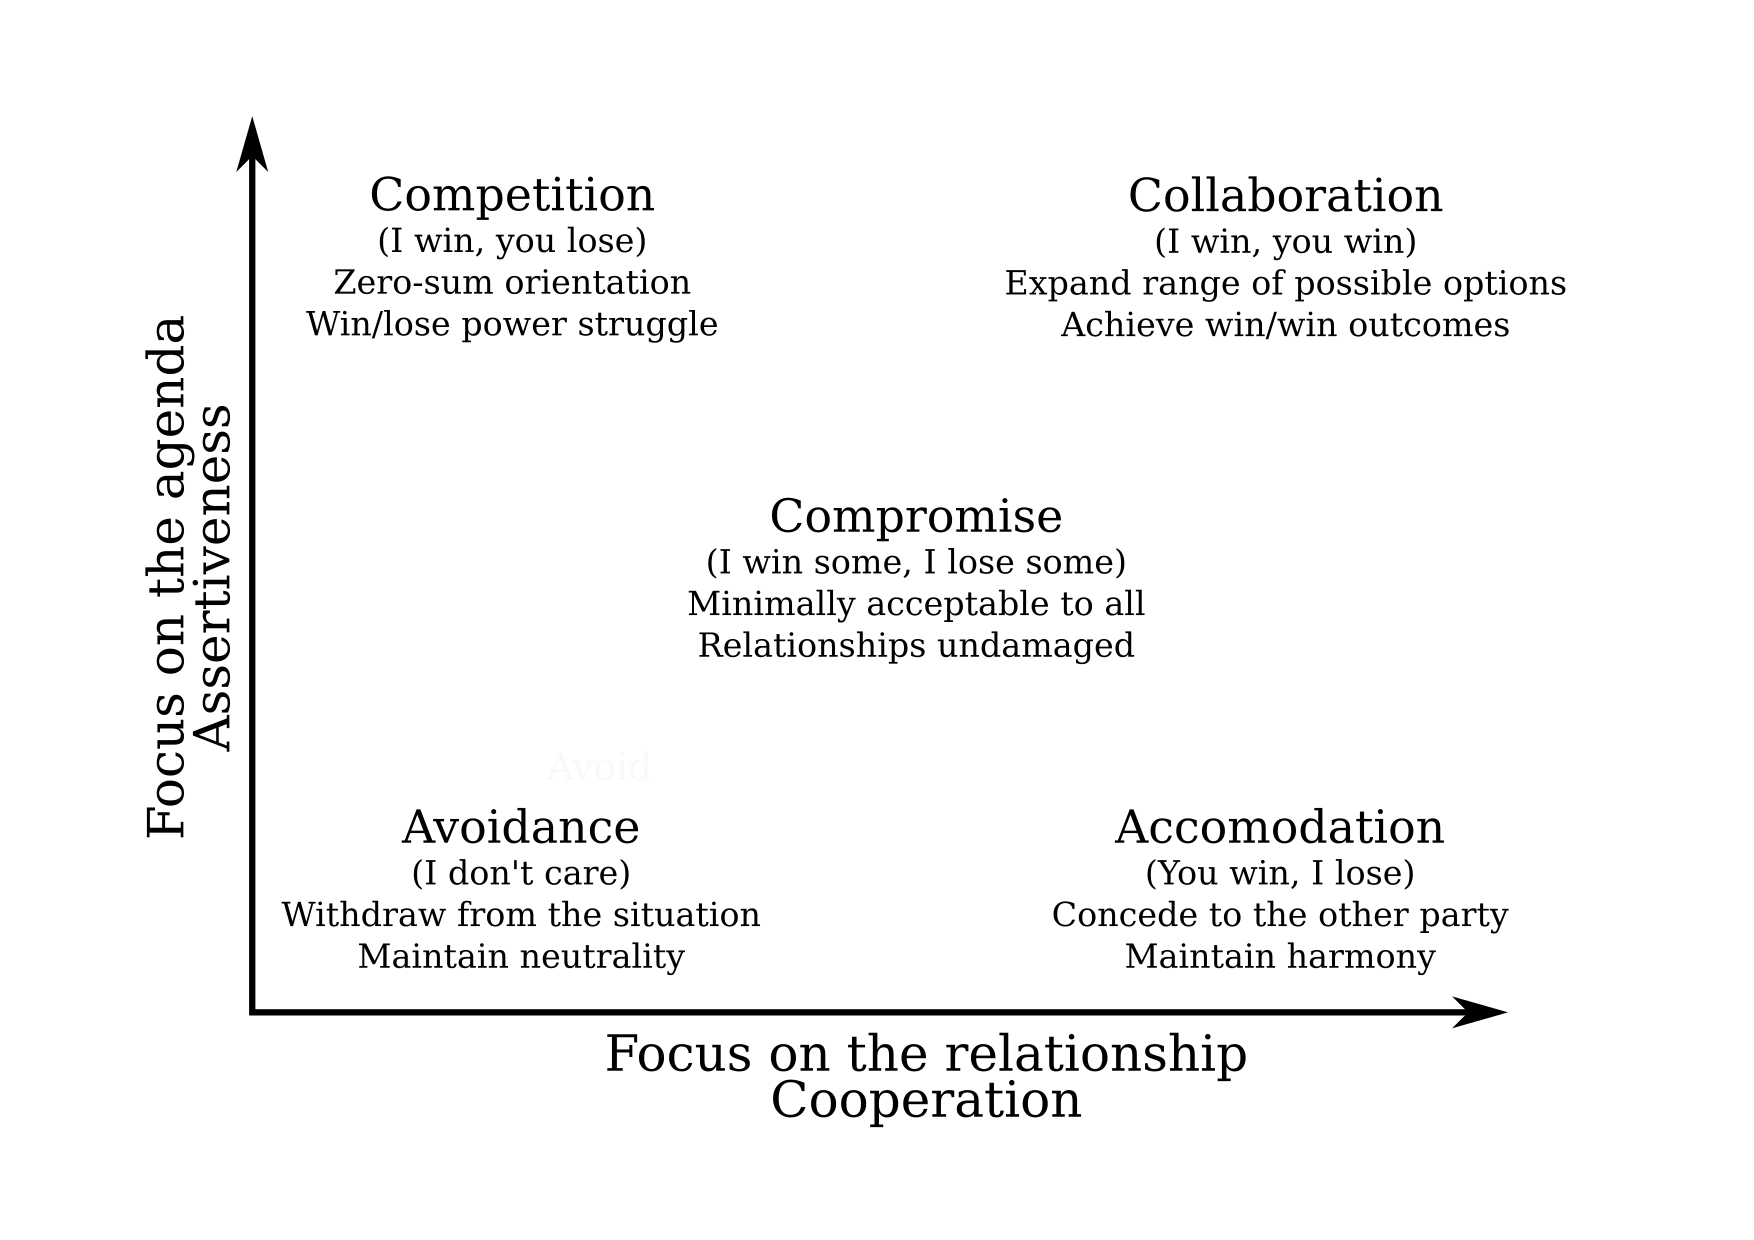
Saying "I've decided I won't do laundry anymore" when the other partner is tired, or busy doing things. Is different than saying "I've decided I won't do laundry anymore" when the other partner has a chance to say "why? tell me more" and take part in negotiation. Resources: Relationships Debian is the Universal Operating System. Debian is made and maintained by people. The long term health of debian is a consequence of the long term health of the relationship between Debian contributors. Debian doesn't need to be technically perfect, it needs to be socially healthy. Technical problems can be fixed by a healty community. graph showing relationship between avoidance, accomodation, compromise, competition, collaboration The Thomas-Kilmann Conflict Mode Instrument: source png. Motivations Quick poll: What are your motivations to be in a relationship? Which of those motivations are healthy/unhealthy? "Galadriel" (noun, by Francesca Ciceri): a task you have to do otherwise Sauron takes over Middle Earth See: http://blog.zouish.org/nonupdd/#/22/1 What motivates me to start a project or pick one up? What motivates me to keep maintaning a project? What motivates you? What's an example of a sustainable motivation? Is it really all consensual in Debian? Energy Energy that thing which is measured in spoons. The metaphore comes from people suffering with chronic health issues:
"Spoons" are a visual representation used as a unit of measure used to quantify how much energy a person has throughout a given day. Each activity requires a given number of spoons, which will only be replaced as the person "recharges" through rest. A person who runs out of spoons has no choice but to rest until their spoons are replenished.
For example, in Debian, I could spend: What is one person capable of doing? Have reasonable expectations, on others: Have reasonable expectations, on yourself: Debian is a shared responsibility When spoons are limited, what takes more energy tends not to get done As the project grows, project-wide tasks become harder Are they still humanly achievable? I don't want Debian to have positions that require hero-types to fill them Dictatorship of who has more spoons: Perfectionism You are in a relationship that is just perfect. All your friends look up to you. You give people relationship advice. You are safe in knowing that You Are Doing It Right. Then one day you have an argument in public. You don't just have to deal with the argument, but also with your reputation and self-perception shattering. One things I hate about Debian: consistent technical excellence. I don't want to be required to always be right. One of my favourite moments in the history of Debian is the openssl bug Debian doesn't need to be technically perfect, it needs to be socially healthy, technical problems can be fixed. I want to remove perfectionism from Debian: if we discover we've been wrong all the time in something important, it's not the end of Debian, it's the beginning of an improved Debian. Too good to be true There comes a point in most people's dating experience where one learns that when some things feel too good to be true, they might indeed be. There are people who cannot say no: There are people who cannot take a no: Note the diversity statement: it's not a problem to have one of those (and many other) tendencies, as long as one manages to keep interacting constructively with the rest of the community Also, it is important to be aware of these patterns, to be able to compensate for one's own tendencies. What happens when an avoidant person meets a narcissistic person, and they are both unaware of the risks? Resources: Note: there are problems with the way these resources are framed: Red flag / green flag http://pervocracy.blogspot.ca/2012/07/green-flags.html Ask for examples of red/green flags in Debian. Green flags: Red flags: Apologies / Dealing with issues I don't see the usefulness of apologies that are about accepting blame, or making a person stop complaining. I see apologies as opportunities to understand the problem I caused, help fix it, and possibly find ways of avoiding causing that problem again in the future. A Better Way to Say Sorry lists a 4 step process, which is basically what we do when in bug reports already: 1, Try to understand and reproduce the exact problem the person had. 2. Try to find the cause of the issue. 3. Try to find a solution for the issue. 4. Verify with the reporter that the solution does indeed fix the issue. This is just to say
My software ate
the files
that where in
your home directory and which
you were probably
needing
for work Forgive me
it was so quick to write
without tests
and it worked so well for me
(inspired by a 1934 poem by William Carlos Williams) Don't be afraid to fail Don't be afraid to fail or drop the ball. I think that anything that has a label attached of "if you don't do it, nobody will", shouldn't fall on anybody's shoulders and should be shared no matter what. Shared or dropped. Share the responsibility for a healthy relationship Don't expect that the more experienced mates will take care of everything. In a project with active people counted by the thousand, it's unlikely that harassment isn't happening. Is anyone writing anti-harassment? Do we have stats? Is having an email address and a CoC giving us a false sense of security?
When you get involved in a new community, such as Debian, find out early where, if that happens, you can find support, understanding, and help to make it stop. If you cannot find any, or if the only thing you can find is people who say "it never happens here", consider whether you really want to be in that community.
(from http://www.enricozini.org/blog/2016/debian/you-ll-thank-me-later/)
There are some nice people in the world. I mean nice people, the sort I couldn t describe myself as. People who are friends with everyone, who are somehow never involved in any argument, who seem content to spend their time drawing pictures of bumblebees on flowers that make everyone happy. Those people are great to have around. You want to hold onto them as much as you can. But people only have so much tolerance for jerkiness, and really nice people often have less tolerance than the rest of us. The trouble with not ejecting a jerk whether their shenanigans are deliberate or incidental is that you allow the average jerkiness of the community to rise slightly. The higher it goes, the more likely it is that those really nice people will come around less often, or stop coming around at all. That, in turn, makes the average jerkiness rise even more, which teaches the original jerk that their behavior is acceptable and makes your community more appealing to other jerks. Meanwhile, more people at the nice end of the scale are drifting away.
(from https://eev.ee/blog/2016/07/22/on-a-technicality/) Give people freedom If someone tries something in Debian, try to acknowledge and accept their work. You can give feedback on what they are doing, and try not to stand in their way, unless what they are doing is actually hurting you. In that case, try to collaborate, so that you all can get what you need. It's ok if you don't like everything that they are doing. I personally don't care if people tell me I'm good when I do something, I perceive it a bit like "good boy" or "good dog". I rather prefer if people show an interest, say "that looks useful" or "how does it work?" or "what do you need to deploy this?" Acknowledge that I've done something. I don't care if it's especially liked, give me the freedom to keep doing it. Don't give me rewards, give me space and dignity. Rather than feeding my ego, feed by freedom, and feed my possibility to create.

11 August 2017

Mike Gabriel: @DebConf17: Story Telling about Debian Edu in Northern Germany

Last Monday, I gave a 20min talk about our little FLOSS school project "IT-Zukunft Schule" at the Debian Conference 17 in Montreal. The talk had video coverage, so may want to peek in, if you couldn't manage to watch the life stream: http://meetings-archive.debian.net/pub/debian-meetings/2017/debconf17/su... I'd like to share some major outcomes (so far) of this talk.
  1. I realized how attached I am to "IT-Zukunft Schule" and how much it means to me that our kids grow up in a world of freedom and choice. Also and esp. when it comes to choosing your daily communication tools and computer working environment
  2. I met Foteini Tsiami and Alkis Georgopoulos from Greece. They work on LTSP and have deployed 1000+ schools in Greece with LTSP + Debian GNU/Linux + MATE Desktop Environment
  3. I met Vagrant Cascadian who is the maintainer of LTSP in Debian and also a major LTSP upstream contributor
  4. I received a lot of fine feedback that was very encouraging to go on with our local work in Schleswig-Holstein
If you have some more time for watching DebConf talks on video, I dearly recommend the talk given by Alkis and Foteini on their Greek FLOSS success story. If you don't have that much time, please skip through the video until you are at 26:15 and enjoy the map that shows how much Debian + LTSP has spread over all of Greece. http://meetings-archive.debian.net/pub/debian-meetings/2017/debconf17/lt... Unfortunately, the schools in Greece are so much smaller than schools in Germany. Most schools there have between 50 and 300 students. So at the Greek schools, it is possible to have a teacher machine being the server for one computer lab. This teacher / server machine provides the infrastructure for a room full of LTSP fat clients (no hard drive inside) and that's it. For German schools, unfortunately, we need a larger scale setup. German schools often have 800+ students and network services need to be spread over more than one server machine. So, the current approach with one server running LDAP, Kerberos etc. is quite appropriate, but also extendible, possibly on municipality level or on county level. We (from IT-Zukunft Schule) are quite positive that there will be opportunities for introducing FLOSS approaches more on the county level in Schleswig-Holstein in the near future. So stay tuned...

Lucas Nussbaum: systemd services, and queue management?

I ve been increasingly using systemd timers as a replacement for cron jobs. The fact that you get free logging is great, and also the fact that you don t have to care about multiple instances running simultaneously. However, sometimes I would be interested in more complex scenarios, such as: Is this doable with systemd? If not, how do people do that outside of systemd?

9 August 2017

Petter Reinholdtsen: Simpler recipe on how to make a simple $7 IMSI Catcher using Debian

On friday, I came across an interesting article in the Norwegian web based ICT news magazine digi.no on how to collect the IMSI numbers of nearby cell phones using the cheap DVB-T software defined radios. The article refered to instructions and a recipe by Keld Norman on Youtube on how to make a simple $7 IMSI Catcher, and I decided to test them out. The instructions said to use Ubuntu, install pip using apt (to bypass apt), use pip to install pybombs (to bypass both apt and pip), and the ask pybombs to fetch and build everything you need from scratch. I wanted to see if I could do the same on the most recent Debian packages, but this did not work because pybombs tried to build stuff that no longer build with the most recent openssl library or some other version skew problem. While trying to get this recipe working, I learned that the apt->pip->pybombs route was a long detour, and the only piece of software dependency missing in Debian was the gr-gsm package. I also found out that the lead upstream developer of gr-gsm (the name stand for GNU Radio GSM) project already had a set of Debian packages provided in an Ubuntu PPA repository. All I needed to do was to dget the Debian source package and built it. The IMSI collector is a python script listening for packages on the loopback network device and printing to the terminal some specific GSM packages with IMSI numbers in them. The code is fairly short and easy to understand. The reason this work is because gr-gsm include a tool to read GSM data from a software defined radio like a DVB-T USB stick and other software defined radios, decode them and inject them into a network device on your Linux machine (using the loopback device by default). This proved to work just fine, and I've been testing the collector for a few days now. The updated and simpler recipe is thus to
  1. start with a Debian machine running Stretch or newer,
  2. build and install the gr-gsm package available from http://ppa.launchpad.net/ptrkrysik/gr-gsm/ubuntu/pool/main/g/gr-gsm/,
  3. clone the git repostory from https://github.com/Oros42/IMSI-catcher,
  4. run grgsm_livemon and adjust the frequency until the terminal where it was started is filled with a stream of text (meaning you found a GSM station).
  5. go into the IMSI-catcher directory and run 'sudo python simple_IMSI-catcher.py' to extract the IMSI numbers.
To make it even easier in the future to get this sniffer up and running, I decided to package the gr-gsm project for Debian (WNPP #871055), and the package was uploaded into the NEW queue today. Luckily the gnuradio maintainer has promised to help me, as I do not know much about gnuradio stuff yet. I doubt this "IMSI cacher" is anywhere near as powerfull as commercial tools like The Spy Phone Portable IMSI / IMEI Catcher or the Harris Stingray, but I hope the existance of cheap alternatives can make more people realise how their whereabouts when carrying a cell phone is easily tracked. Seeing the data flow on the screen, realizing that I live close to a police station and knowing that the police is also wearing cell phones, I wonder how hard it would be for criminals to track the position of the police officers to discover when there are police near by, or for foreign military forces to track the location of the Norwegian military forces, or for anyone to track the location of government officials... It is worth noting that the data reported by the IMSI-catcher script mentioned above is only a fraction of the data broadcasted on the GSM network. It will only collect one frequency at the time, while a typical phone will be using several frequencies, and not all phones will be using the frequencies tracked by the grgsm_livemod program. Also, there is a lot of radio chatter being ignored by the simple_IMSI-catcher script, which would be collected by extending the parser code. I wonder if gr-gsm can be set up to listen to more than one frequency?

Joey Hess: unifying OS installation and configuration management

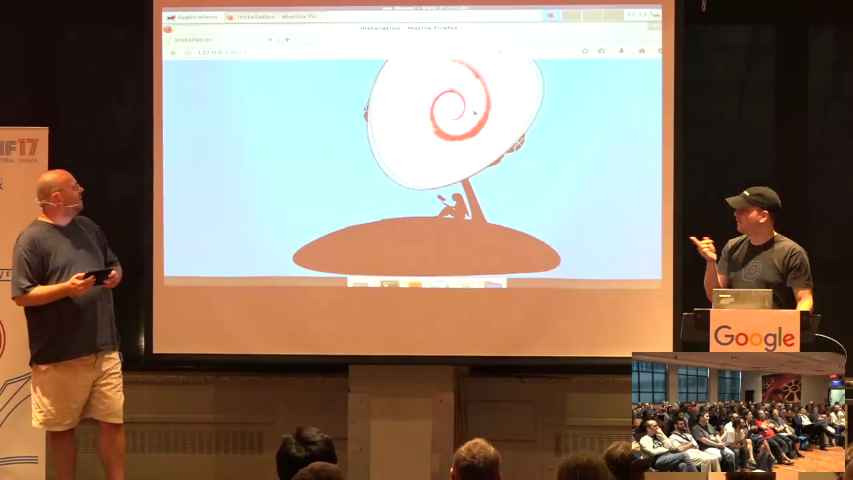
Three years ago, I realized that propellor (my configuration management system that is configured using haskell) could be used as an installer for Debian (or other versions of Linux). In propellor is d-i 2.0, I guessed it would take "a month and adding a few thousand lines of code". I've now taken that month, and written that code, and I presented the result at DebConf yesterday. I demoed propellor building a live Debian installation image, and then handed it off to a volenteer from the audience to play with its visual user interface and perform the installation. The whole demo took around 20 minutes, and ended with a standard Debian desktop installation. (Video) The core idea is to reuse the same configuration management system for several different purposes.
  1. Building a bootable disk image that can be used as both a live system and as an OS installer.
  2. Running on that live system, to install the target system. Which can just involve copying the live system to the target disk and then letting the configuration management system make the necessary changes to get from the live system configuration to the target system configuration.
  3. To support such things as headless arm boards, building customized images tuned for the target board and use case, that can then simply be copied to the board to install.
  4. Optionally, running on the installed system later, to futher customize it. Starting from the same configuration that produced the installed system in the first place.
There can be enourmous code reuse here, and improvements made for one of those will often benefit all the rest as well. Once everything is handled by configuration management, all user interface requirements become just a matter of editing the configuration. Including: That's the gist of it. Configuration management reused for installation and image building, and multiple editor interfaces to make it widely usable. I was glad, sitting in to a BoF session before my talk, that several people in Debian are already thinking along similar lines. And if Debian wanted to take this work and run with it, I'd be glad to assist as propellor's maintainer. But the idea is more important than the code and I hope my elaboration of it helps point a way if not the way. While what I've built installs Debian, little of it is Debian-specific. It would probably be easy to port it to Arch Linux, which propellor already supports. There are Linux-specific parts, so porting to FreeBSD would be harder, but propellor knows, at the type level which OSs properties support, which will ease porting. GuixSD and NixOS already use configuration management for installation, and were part of my inspiration. I've extended what they do in some ways (in other ways they remain far ahead).
The code is here. And here are some links to more details about what I built, and ideas encountered along the way:

8 August 2017

Jonathan Dowland: libraries

Cover for The Rise Of The Meritocracy Cover for The Rise Of The Meritocracy
At some point during my Undergraduate years I lost the habit of using Libraries. On reflection this is probably Amazon's fault. In recent years I've tried to get back into the habit of using them. Using libraries is a great idea if you are trying to lead a more minimalist life. I am registered to use Libraries in two counties: North Tyneside, where I live, and Newcastle, where I work. The union of the two counties' catalogues is pretty extensive. Perhaps surprisingly I have found North Tyneside to offer both better customer service and a more interesting selection of books. Sometimes there are still things that are hard to get ahold of. After listening to BBC Radio 4's documentary The Rise and Fall of Meritocracy, presented by Toby Young, I became interested in reading The Rise of the Meritocracy: an alarmist, speculative essay that coined the term meritocracy, written by Toby's father, Michael Young. The book was not on either catalogue. It is out of print, with the price of second hand copies fluctuating but generally higher than I am prepared to pay. I finally managed to find a copy in Newcastle University's Library. As an associate of the School of Computing I have access to the Library services. It's an interesting read, and I think if it were framed more as a novel than as an essay it might be remembered in the same bracket as Brave New World or 1984.

6 August 2017

Joachim Breitner: Communication Failure

I am still far from being a professor, but I recently got a glimps of what awaits you in that role
From: Sebastian R. < @gmail.com>
To: joachim@cis.upenn.edu
Subject: re: Errors I've spotted a basic error in your course on Haskell (https://www.seas.upenn.edu/~cis194/fall16/). Before I proceed, it's cool if you're not receptive to errors being indicated; I've come across a number of professors who would rather take offense than admit we're all human and thus capable of making mistakes... My goal is to find a resource that might be useful well into the future, and a good indicator of that is how responsive the author is to change. In your introduction note you have written:
n contrast to a classical intro into Haskell, we do not start with numbers, booleans, tuples, lists and strings, but we start with pictures. These are of course library-defined (hence the input CodeWorld) and not part of the language . But that does not make them less interesting, and in fact, even the basic boolean type is library defined it just happens to be the standard library.
Howeverm there is no input CodeWorld in the code above. Have you been made aware of this error earlier? Regards, ...
Nice. I like when people learn from my lectures. The introduction is a bit werid, but ok, maybe this guy had some bad experiences. Strangley, I don t see a mistake in the material, so I respond:
From: Joachim Breitner <noscript>joachim at cis dot upenn dot edu</noscript>
To: Sebastian R. < @gmail.com>
Subject: Re: Errors Dear Sebastian, thanks for pointing out errors. But the first piece of code under Basic Haskell starts with
 -# LANGUAGE OverloadedStrings #- 
import CodeWorld
so I am not sure what you are referring to. Note that these are lecture notes, so you have to imagine a lecturer editing code live on stage along with it. If you only have the notes, you might have to infer a few things. Regards, Joachim
A while later, I receive this response:
From: Sebastian R. < @gmail.com>
To: Joachim Breitner <noscript>joachim at cis dot upenn dot edu</noscript>
Subject: Re: Errors Greetings, Joachim. Kindly open the lecture slides and search for "input CodeWorld" to find the error; it is not in the code, but in the paragraph that implicitly refers back to the code. You might note that I quoted this precisely from the lectures... and so I repeat myself... this came from your lectures; they're not my words!
In contrast to a classical intro into Haskell, we do not start with numbers, booleans, tuples, lists and strings, but we start with pictures. These are of course library-defined (hence the input CodeWorld) and not part of the language . But that does not make them less interesting, and in fact, even the basic boolean type is library defined it just happens to be the standard library.
This time around, I've highlighted the issue. I hope that made it easier for you to spot... Nonetheless, I got my answer. Don't reply if you're going to fight tooth and nail about such a basic fix; it's simply a waste of both of our time. I'd rather learn from somewhere else... On Tue, Aug 1, 2017 at 11:19 PM, Joachim Breitner <noscript>joachim at cis dot upenn dot edu</noscript> wrote:
I am a bit reminded of Sean Spicer they re not my words! but clearly I am missing something. And indeed I am: In the code snippet, I wrote correctly import CodeWorld, but in the text I had input CodeWorld. I probably did write LaTeX before writing the lecture notes. Well, glad to have that sorted out. I fixed the mistake and wrote back:
From: Joachim Breitner <noscript>joachim at cis dot upenn dot edu</noscript>
To: Sebastian R. < @gmail.com>
Betreff: Re: Errors Dear Sebastian, nobody is fighting, and I see the mistake now: The problem is not that the line is not in the code, the problem is that there is a typo in the line and I wrote input instead of import . Thanks for the report, although you did turn it into quite a riddle a simple you wrote import when it should have been import would have been a better user of both our time. Regards, Joachim Am Donnerstag, den 03.08.2017, 13:32 +1000 schrieb Sebastian R.:
(And it seems I now made the inverse typo, writing import instead of input . Anyways, I did not think of this any more until a few days later, when I found this nice message in my mailbox:
From: Sebastian R. < @gmail.com>
To: Joachim Breitner <noscript>joachim at cis dot upenn dot edu</noscript>
Subject: Re: Errors
a simple you wrote import when it should have been import would have been a better user of both our time.
We're both programmers. How about I cut ALL of the unnecessary garbage and just tell you to s/import/input/ on that last quotation (the thing immediately before this paragraph, in case you didn't know). I blatantly quoted the error, like this:
In your introduction note you have written:
n contrast to a classical intro into Haskell, we do not start with numbers, booleans, tuples, lists and strings, but we start with pictures. These are of course library-defined (hence the input CodeWorld) and not part of the language . But that does not make them less interesting, and in fact, even the basic boolean type is library defined it just happens to be the standard library.
Howeverm there is no input CodeWorld in the code above.
Since that apparently wasn't clear enough, in my second email to you I had to highlight it like so:
You might note that I quoted this precisely from the lectures... and so I repeat myself... this came from your lectures; they're not my words!
In contrast to a classical intro into Haskell, we do not start with numbers, booleans, tuples, lists and strings, but we start with pictures. These are of course library-defined (hence the input CodeWorld) and not part of the language . But that does not make them less interesting, and in fact, even the basic boolean type is library defined it just happens to be the standard library.
This time around, I've highlighted the issue. I hope that made it easier for you to spot...
I'm not sure if you're memeing at me or not now, but it seems either your reading comprehension, or your logical deduction skills might be substandard. Unfortunately, there isn't much either of us can do about that, so I'm happy to accept that some people will be so stupid; after all, it's to be expected and if we don't accept that which is to be expected then we live our lives in denial. Happy to wrap up this discusson here, Seb... On Fri, Aug 4, 2017 at 12:22 AM, Joachim Breitner <noscript>joachim at cis dot upenn dot edu</noscript> wrote:
Well, I chose to be amused by this, and I am sharing my amusement with you.

5 August 2017

Daniel Silverstone: USB Device Stacks, on RTFM, part 2

Previously we talked about all the different kinds of descriptors which USB devices use to communicate their capability. This is important stuff because to write any useful USB device firmware we need to be able to determine how to populate our descriptors. However, having that data on the device is entirely worthless without an understanding of how it gets from the device to the host so that it can be acted upon. To understand that, let's look at the USB wire protocol.
Note, I'll again be talking mostly about USB2.0 low- and full-speed. I believe that high speed is approximately the same but with faster wires, except not quite that simple.

Down to the wire I don't intend to talk about the actual electrical signalling, though it's not un-reasonable for you to know that USB is a pair of wires forming a differentially signalled bidirectional serial communications link. The host is responsible for managing all the framing and timing on the link, and for formatting the communications into packets. There are a number of packet types which can appear on the USB link:
Packet type Purpose
Token Packet When the host wishes to send a message to the Control endpoint to configure the device, read data IN, or write data OUT, it uses this to start the transaction.
Data(0/1) Packet Following a Setup, In, or Out token, a Data packet is a transfer of data (in either direction). The 0 and 1 alternate to provide a measure of confidence against lost packets.
Handshake Packet Following a data packet of some kind, the other end may ACK the packet (all was well), NAK the packet (report that the device cannot, temporarily, send/receive data, or that an interrupt endpoint isn't triggered), or STALL the bus in which case the host needs to intervene.
Start of Frame Every 1ms (full-speed) the host will send a SOF packet which carries a frame number. This can be used to help keep time on very simple devices. It also divides the bus into frames within which bandwidth is allocated.
As an example, when the host wishes to perform a control transfer, the following packets are transacted in turn:
  1. Setup Token - The host addresses the device and endpoint (OUT0)
  2. Data0 Packet - The host transmits a GET_DESCRIPTOR for the device descriptor
  3. Ack Packet - The device acknowledges receipt of the request
This marks the end of the first transaction. The device decodes the GET_DESCRIPTOR request and prepares the device descriptor for transmission. The transmission occurs as the next transaction on the bus. In this example, we're assuming 8 byte maximum transmission sizes, for illustrative purposes.
  1. In Token - The host addresses the device and endpoint (IN0)
  2. Data1 Packet - The device transmits the first 8 bytes of the descriptor
  3. Ack Packet - The host acknowledges the data packet
  4. In Token - The host addresses the device and endpoint (IN0)
  5. Data0 Packet - The device transmits the remaining 4 bytes of the descriptor (padded)
  6. Ack Packet - The host acknowledges the data packet
The second transaction is now complete, and the host has all the data it needs to proceed. Finally a status transaction occurs in which:
  1. Out Token - The host addresses the device and endpoint (OUT0)
  2. Data1 Packet - The host transmits a 0 byte data packet to indicate successful completion
  3. Ack Packet - The device acknowledges the completion, indicating its own satisfaction
And thus ends the full control transaction in which the host retrieves the device descriptor. From a high level, we need only consider the activity which occurs at the point of the acknowledgement packets. In the above example:
  1. On the first ACK the device prepares IN0 to transmit the descriptor, readying whatever low level device stack there is with a pointer to the descriptor and its length in bytes.
  2. On the second ACK the low levels are still thinking.
  3. On the third ACK the transmission from IN0 is complete and the endpoint no longer expects to transfer data.
  4. On the fourth ACK the control transaction is entirely complete.

Thinking at the low levels of the control interface Before we can build a high level USB stack, we need to consider the activity which might occur at the lower levels. At the low levels, particularly of the device control interface, work has to be done at each and every packet. The hardware likely deals with the token packet for us, leaving the data packets for us to process, and the resultant handshake packets will be likely handled by the hardware in response to our processing the data packets. Since every control transaction is initiated by a setup token, let's look at the setup requests which can come our way...
Setup Packet (Data) Format
Field Name Byte start Byte length Encoding Meaning
bmRequestType 0 1 Bitmap Describes the kind of request, and the target of it. See below.
bRequest 1 1 Code The request code itself, meanings of the rest of the fields vary by bRequest
wValue 2 2 Number A 16 bit value whose meaning varies by request type
wIndex 4 2 Number A 16 bit value whose meaning varies by request type but typically encodes an interface number or endpoint.
wLength 6 2 Number A 16 bit value indicating the length of the transfer to come.
Since bRequest is essentially a switch against which multiple kinds of setup packet are selected between, here's the meanings of a few...
GET_DESCRIPTOR (Device) setup packet
Field Name Value Meaning
bmRequestType 0x08 Data direction is IN (from device to host), recipient is the device
bRequest 0x06 GET_DESCRIPTOR (in this instance, the device descriptor is requested)
wValue 0x0001 This means the device descriptor
wIndex 0x0000 Irrelevant, there's only 1 device descriptor anyway
wLength 12 This is the length of a device descriptor (12 bytes)
SET_ADDRESS to set a device's USB address
Field Name Value Meaning
bmRequestType 0x00 Data direction is OUT (from host to device), recipient is the device
bRequest 0x05 SET_ADDRESS (Set the device's USB address)
wValue 0x00nn The address for the device to adopt (max 127)
wIndex 0x0000 Irrelevant for address setting
wLength 0 There's no data transfer expected for this setup operation
Most hardware blocks will implement an interrupt at the point that the Data packet following the Setup packet has been receive. This is typically called receiving a 'Setup' packet and then it's up to the device stack low levels to determine what to do and dispatch a handler. Otherwise an interrupt will fire for the IN or OUT tokens and if the endpoint is zero, the low level stack will handle it once more. One final thing worth noting about SET_ADDRESS is that it doesn't take effect until the completion of the zero-length "status" transaction following the setup transaction. As such, the status request from the host will still be sent to address zero (the default for new devices).

A very basic early "packet trace" This is an example, and is not guaranteed to be the packet sequence in all cases. It's a good indication of the relative complexity involved in getting a fresh USB device onto the bus though... When a device first attaches to the bus, the bus is in RESET state and so the first event a device sees is a RESET which causes it to set its address to zero, clear any endpoints, clear the configuration, and become ready for control transfers. Shortly after this, the device will become suspended. Next, the host kicks in and sends a port reset of around 30ms. After this, the host is ready to interrogate the device. The host sends a GET_DESCRIPTOR to the device, whose address at this point is zero. Using the information it receives from this, it can set up the host-side memory buffers since the device descriptor contains the maximum transfer size which the device supports. The host is now ready to actually 'address' the device, and so it sends another reset to the device, again around 30ms in length. The host sends a SET_ADDRESS control request to the device, telling it that its new address is nn. Once the acknowledgement has been sent from the host for the zero-data status update from the device, the device sets its internal address to the value supplied in the request. From now on, the device shall respond only to requests to nn rather than to zero. At this point, the host will begin interrogating further descriptors, looking at the configuration descriptors and the strings, to build its host-side representation of the device. These will be GET_DESCRIPTOR and GET_STRING_DESCRIPTOR requests and may continue for some time. Once the host has satisfied itself that it knows everything it needs to about the device, it will issue a SET_CONFIGURATION request which basically starts everything up in the device. Once the configuration is set, interrupt endpoints will be polled, bulk traffic will be transferred, Isochronous streams begin to run, etc.

Okay, but how do we make this concrete? So far, everything we've spoken about has been fairly abstract, or at least "soft". But to transfer data over USB does require some hardware. (Okay, okay, we could do it all virtualised, but there's no fun in that). The hardware I'm going to be using for the duration of this series is the STM32 on the blue-pill development board. This is a very simple development board which does (in theory at least) support USB device mode. If we view the schematic for the blue-pill, we can see a very "lightweight" USB interface which has a pullup resistor for D+. This is the way that a device signals to the host that it is present, and that it wants to speak at full-speed. If the pullup were on D- then it would be a low-speed device. High speed devices need a little more complexity which I'm not going to go into for today. The USB lines connect to pins PA11 and PA12 which are the USB pins on the STM32 on the board. Since USB is quite finicky, the STM32 doesn't let you remap that function elsewhere, so this is all looking quite good for us so far. The specific STM32 on the blue-pill is the STM32F103C8T6. By viewing its product page on ST's website we can find the reference manual for the part. Jumping to section 23 we learn that this STM32 supports full-speed USB2.0 which is convenient given the past article and a half. We also learn it supports up to eight endpoints active at any one time, and offers double-buffering for our bulk and isochronous transfers. It has some internal memory for packet buffering, so it won't use our RAM bandwidth while performing transfers, which is lovely. I'm not going to distill the rest of that section here, because there's a large amount of data which explains how the USB macrocell operates. However useful things to note are:
  • How IN OUT and SETUP transfers work.
  • How the endpoint buffer memory is configured.
  • That all bus-powered devices MUST respond to suspend/resume properly
  • That the hardware will prioritise endpoint interrupts for us so that we only need deal with the most pressing item at any given time.
  • There is an 'Enable Function' bit in the address register which must be set or we won't see any transactions at all.
  • How the endpoint registers signal events to the device firmware.
Next time, we're going to begin the process of writing a very hacky setup routine to try and initialise the USB device macrocell so that we can see incoming transactions through the ITM. It should be quite exciting, but given how complex this will be for me to learn, it might be a little while before it comes through.

4 August 2017

Daniel Silverstone: USB Device Stacks, on RTFM

I have been spending time with Jorge Aparicio's RTFM for Cortex M3 framework for writing Rust to target Cortex-M3 devices from Arm (and particularly the STM32F103 from ST Microelectronics). Jorge's work in this area has been of interest to me ever since I discovered him working on this stuff a while ago. I am very tempted by the idea of being able to implement code for the STM32 with the guarantees of Rust and the language features which I have come to love such as the trait system. I have been thinking to myself that, while I admire and appreciate the work done on the GNUK, I would like to, personally, have a go at implementing some kind of security token on an STM32 as a USB device. And with the advent of the RTFM for M3 work, and Jorge's magical tooling to make it easier to access and control the registers on an M3 microcontroller, I figured it'd be super-nice to do this in Rust, with all the advantages that entails in terms of isolating unsafe behaviour and generally having the potential to be more easily verified as not misbehaving. To do this though, means that I need a USB device stack which will work in the RTFM framework. Sadly it seems that, thus-far, only Jorge has been working on drivers for any of the M3 devices his framework supports. And one person can only do so much. So, in my infinite madness, I decided I should investigate the complexity of writing a USB device stack in Rust for the RTFM/M3 framework. (Why I thought this was a good idea is lost to the mists of late night Googling, but hey, it might make a good talk at the next conference I go to). As such, this blog post, and further ones along these lines, will serve as a partial tour of what I'm up to, and a partial aide-memoir for me about learning USB. If I get something horribly wrong, please DO contact me to correct me, otherwise I'll just continue to be wrong. If I've simplified something but it's still strictly correct, just let me know if it's an oversimplification since in a lot of cases there's no point in me putting the full details into a blog posting. I will mostly be considering USB2.0 protocol details but only really for low and full speed devices. (The hardware I'm targetting does low-speed and full-speed, but not high-speed. Though some similar HW does high-speed too, I don't have any to hand right now)

A brief introduction to USB In order to go much further, I needed a grounding in USB. It's a multi-layer protocol as you might expect, though we can probably ignore the actual electrical layer since any device we might hope to support will have to have a hardware block to deal with that. We will however need to consider the packet layer (since that will inform how the hardware block is implemented and thus its interface) and then the higher level protocols on top. USB is a deliberately asymmetric protocol. Devices are meant to be significantly easier to implement, both in terms of hardware and software, as compared with hosts. As such, despite some STM32s having OTG ports, I have no intention of supporting host mode at this time. USB is arranged into a set of busses which are, at least in the USB1.1 case, broadcast domains. As such, each device has an address assigned to it by the host during an early phase called 'configuration'. Once the address is assigned, the device is expected to only ever respond to messages addressed to it. Note that since everything is asymmetric in USB, the device can't send messages on its own, but has to be asked for them by the host, and as such the addressing is always from host toward device. USB devices then expose a number of endpoints through which communication can flow IN to the host or OUT to the device. Endpoints are not bidirectional, but the in and out endpoints do overlap in numbering. There is a special pair of endpoints, IN0 and OUT0 which, between them, form what I will call the device control endpoints. The device control endpoints are important since every USB device MUST implement them, and there are a number of well defined messages which pass over them to control the USB device. In theory a bare minimum USB device would implement only the device control endpoints.

Configurations, and Classes, and Interfaces, Oh My! In order for the host to understand what the USB device is, and what it is capable of, part of the device control endpoints' responsibility is to provide a set of descriptors which describe the device. These descriptors form a heirarchy and are then glommed together into a big lump of data which the host can download from the device in order to decide what it is and how to use it. Because of various historical reasons, where a multi-byte value is used, they are defined to be little-endian, though there are some BCD fields. Descriptors always start with a length byte and a type byte because that way the host can parse/skip as necessary, with ease. The first descriptor is the device descriptor, is a big one, and looks like this:
Device Descriptor
Field Name Byte start Byte length Encoding Meaning
bLength 0 1 Number Size of the descriptor in bytes (18)
bDescriptorType 1 1 Constant Device Descriptor (0x01)
bcdUSB 2 2 BCD USB spec version compiled with
bDeviceClass 4 1 Class Code, assigned by USB org (0 means "Look at interface descriptors", common value is 2 for CDC)
bDeviceSubClass 5 1 SubClass Code, assigned by USB org (usually 0)
bDeviceProtocol 6 1 Protocol Code, assigned by USB org (usually 0)
bMaxPacketSize 7 1 Number Max packet size for IN0/OUT0 (Valid are 8, 16, 32, 64)
idVendor 8 2 ID 16bit Vendor ID (Assigned by USB org)
idProduct 10 2 ID 16bit Product ID (Assigned by manufacturer)
bcdDevice 12 2 BCD Device version number (same encoding as bcdUSB)
iManufacturer 14 1 Index String index of manufacturer name (0 if unavailable)
iProduct 15 1 Index String index of product name (0 if unavailable)
iSerialNumber 16 1 Index String index of device serial number (0 if unavailable)
bNumConfigurations 17 1 Number Count of configurations the device has.
This looks quite complex, but breaks down into a relatively simple two halves. The first eight bytes carries everything necessary for the host to be able to configure itself and the device control endpoints properly in order to communicate effectively. Since eight bytes is the bare minimum a device must be able to transmit in one go, the host can guarantee to get those, and they tell it what kind of device it is, what USB protocol it supports, and what the maximum transfer size is for its device control endpoints. The encoding of the bcdUSB and bcdDevice fields is interesting too. It is of the form 0xMMmm where MM is the major number, mm the minor. So USB2.0 is encoded as 0x0200, USB1.1 as 0x0110 etc. If the device version is 17.36 then that'd be 0x1736. Other fields of note are bDeviceClass which can be 0 meaning that interfaces will specify their classes, and idVendor/idProduct which between them form the primary way for the specific USB device to be identified. The Index fields are indices into a string table which we'll look at later. For now it's enough to know that wherever a string index is needed, 0 can be provided to mean "no string here". The last field is bNumConfigurations and this indicates the number of ways in which this device might function. A USB device can provide any number of these configurations, though typically only one is provided. If the host wishes to switch between configurations then it will have to effectively entirely quiesce and reset the device. The next kind of descriptor is the configuration descriptor. This one is much shorter, but starts with the same two fields:
Configuration Descriptor
Field Name Byte start Byte length Encoding Meaning
bLength 0 1 Number Size of the descriptor in bytes (9)
bDescriptorType 1 1 Constant Configuration Descriptor (0x02)
wTotalLength 2 2 Number Size of the configuration in bytes, in total
bNumInterfaces 4 1 Number The number of interfaces in this configuration
bConfigurationValue 5 1 Number The value to use to select this configuration
iConfiguration 6 1 Index The name of this configuration (0 for unavailable)
bmAttributes 7 1 Bitmap Attributes field (see below)
bMaxPower 8 1 Number Maximum bus power this configuration will draw (in 2mA increments)
An important field to consider here is the bmAttributes field which tells the host some useful information. Bit 7 must be set, bit 6 is set if the device would be self-powered in this configuration, bit 5 indicates that the device would like to be able to wake the host from sleep mode, and bits 4 to 0 must be unset. The bMaxPower field is interesting because it encodes the power draw of the device (when set to this configuration). USB allows for up to 100mA of draw per device when it isn't yet configured, and up to 500mA when configured. The value may be used to decide if it's sensible to configure a device if the host is in a low power situation. Typically this field will be set to 50 to indicate the nominal 100mA is fine, or 250 to request the full 500mA. Finally, the wTotalLength field is interesting because it tells the host the total length of this configuration, including all the interface and endpoint descriptors which make it up. With this field, the host can allocate enough RAM to fetch the entire configuration descriptor block at once, simplifying matters dramatically for it. Each configuration has one or more interfaces. The interfaces group some endpoints together into a logical function. For example a configuration for a multifunction scanner/fax/printer might have an interface for the scanner function, one for the fax, and one for the printer. Endpoints are not shared among interfaces, so when building this table, be careful. Next, logically, come the interface descriptors:
Interface Descriptor
Field Name Byte start Byte length Encoding Meaning
bLength 0 1 Number Size of the descriptor in bytes (9)
bDescriptorType 1 1 Constant Interface Descriptor (0x04)
bInterfaceNumber 2 1 Number The number of the interface
bAlternateSetting 3 1 Number The interface alternate index
bNumEndpoints 4 1 Number The number of endpoints in this interface
bInterfaceClass 5 1 Class The interface class (USB Org defined)
bInterfaceSubClass 6 1 SubClass The interface subclass (USB Org defined)
bInterfaceProtocol 7 1 Protocol The interface protocol (USB Org defined)
iInterface 8 1 Index The name of the interface (or 0 if not provided)
The important values here are the class/subclass/protocol fields which provide a lot of information to the host about what the interface is. If the class is a USB Org defined one (e.g. 0x02 for Communications Device Class) then the host may already have drivers designed to work with the interface meaning that the device manufacturer doesn't have to provide host drivers. The bInterfaceNumber is used by the host to indicate this interface when sending messages, and the bAlternateSetting is a way to vary interfaces. Two interfaces with the came bInterfaceNumber but different bAlternateSettings can be switched between (like configurations, but) without resetting the device. Hopefully the rest of this descriptor is self-evident by now. The next descriptor kind is endpoint descriptors:
Endpoint Descriptor
Field Name Byte start Byte length Encoding Meaning
bLength 0 1 Number Size of the descriptor in bytes (7)
bDescriptorType 1 1 Constant Endpoint Descriptor (0x05)
bEndpointAddress 2 1 Endpoint Endpoint address (see below)
bmAttributes 3 1 Bitmap Endpoint attributes (see below)
wMaxPacketSize 4 2 Number Maximum packet size this endpoint can send/receive
bInterval 6 1 Number Interval for polling endpoint (in frames)
The bEndpointAddress is a 4 bit endpoint number (so there're 16 endpoint indices) and a bit to indicate IN vs. OUT. Bit 7 is the direction marker and bits 3 to 0 are the endpoint number. This means there are 32 endpoints in total, 16 in each direction, 2 of which are reserved (IN0 and OUT0) giving 30 endpoints available for interfaces to use in any given configuration. The bmAttributes bitmap covers the transfer type of the endpoint (more below), and the bInterval is an interval measured in frames (1ms for low or full speed, 125 s in high speed). bInterval is only valid for some endpoint types. The final descriptor kind is for the strings which we've seen indices for throughout the above. String descriptors have two forms:
String Descriptor (index zero)
Field Name Byte start Byte length Encoding Meaning
bLength 0 1 Number Size of the descriptor in bytes (variable)
bDescriptorType 1 1 Constant String Descriptor (0x03)
wLangID[0] 2 2 Number Language code zero (e.g. 0x0409 for en_US)
wLangID[n] 4.. 2 Number Language code n ...
This form (for descriptor 0) is that of a series of language IDs supported by the device. The device may support any number of languages. When the host requests a string descriptor, it will supply both the index of the string and also the language id it desires (from the list available in string descriptor zero). The host can tell how many language IDs are available simply by dividing bLength by 2 and subtracting 1 for the two header bytes. And for string descriptors of an index greater than zero:
String Descriptor (index greater than zero)
Field Name Byte start Byte length Encoding Meaning
bLength 0 1 Number Size of the descriptor in bytes (variable)
bDescriptorType 1 1 Constant String Descriptor (0x03)
bString 2.. .. Unicode The string, in "unicode" format
This second form of the string descriptor is simply the the string is in what the USB spec calls 'Unicode' format which is, as of 2005, defined to be UTF16-LE without a BOM or terminator. Since string descriptors are of a variable length, the host must request strings in two transactions. First a request for 2 bytes is sent, retrieving the bLength and bDescriptorType fields which can be checked and memory allocated. Then a request for bLength bytes can be sent to retrieve the entire string descriptor.

Putting that all together Phew, this is getting to be quite a long posting, so I'm going to leave this here and in my next post I'll talk about how the host and device pass packets to get all that information to the host, and how it gets used.

2 August 2017

Markus Koschany: My Free Software Activities in July 2017

Welcome to gambaru.de. Here is my monthly report that covers what I have been doing for Debian. If you re interested in Java, Games and LTS topics, this might be interesting for you. Debian Games Debian Java Debian LTS This was my seventeenth month as a paid contributor and I have been paid to work 23,5 hours on Debian LTS, a project started by Rapha l Hertzog. In that time I did the following: Non-maintainer upload Thanks for reading and see you next time.

Steve Kemp: So I did a thing, then another thing.

So I did start a project, to write a puppet-dashboard, it is functionally complete, but the next step is to allow me to raise alerts based on failing runs of puppet - in real-time. (i.e. Now that I have a dashboard I wish to not use it. I want to be alerted to failures, without having to remember to go look for them. Something puppet-dashboard can't do ..) In other news a while back I slipped in a casual note about having a brain scan done, here in sunny Helsinki. One of the cool things about that experience, in addition to being told I wasn't going to drop dead that particular day, was that the radiologist told me that I could pay 25 to get a copy of my brain data in DICOM format. I've not yet played with this very much, but I couldn't resist a brief animation:
Markus Koschany: PDFsam: How to upgrade a Maven application for Debian

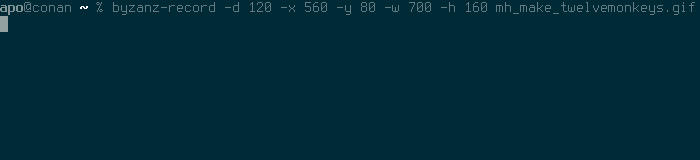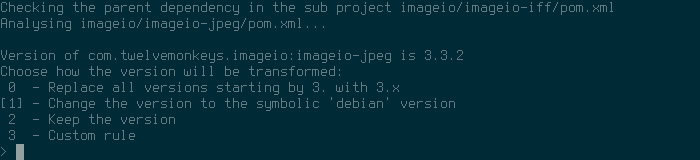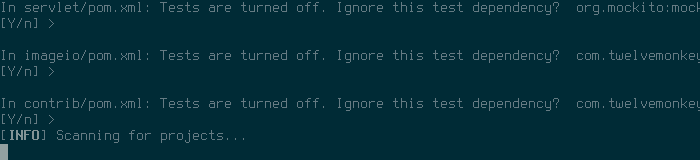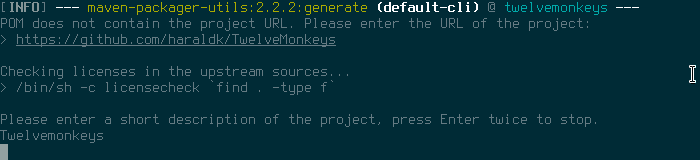
In the coming weeks and months I intend to write a mini series about packaging Java software for Debian. The following article basically starts in the middle of this journey because the PDFsam upgrade is still fresh in my mind. It requires some preexisting knowledge about build tools like Maven and some Java terminology. But do not fear. Hopefully it will make sense in the end when all pieces fall into place. A month ago I decided to upgrade PDFsam, a Java application to split, merge, extract, mix and rotate PDF documents. The current version 1.1.4 is already seven years old and uses Ant as its build system. Unfortunately up to now nobody was interested enough to invest the time to upgrade it to the latest version. A quick internet search unveils that the current sources can be found on github.com. Another brief look reveals we are dealing with a Maven project here because we can find a pom.xml file in the root directory and there is no sign of Ant s typical build.xml file anymore. Here are some general tips how to proceed from this point by using the PDFsam upgrade as an example. Find out how many new dependencies you really need The pom.xml file declares its dependencies in the <dependencies> section. It is good practice to inspect the pom.xml file and determine how much work will be required to upgrade the package. A seasoned Java packager will quickly find common dependencies like Hibernate or the Apache Commons libraries. Fortunately for you they are already packaged in Debian because a lot of projects depend on them. If you are unsure what is and what is not packaged for Debian, tracker.debian.org and codesearch.debian.net are useful tools to search for those packages. If in doubt just ask on debian-java@lists.debian.org. There is no automagical tool (yet) to find out what dependencies are really new (we talk about mh_make soon) but if you use the aforementioned tools and websites you will notice that in June 2017 one could not find the following artifacts: fontawesomefx, eventstudio, sejda-* and jackson-jr-objects. There are also jdepend and testFx but notice they are marked as <scope>test</scope> meaning they are only required if you would like to run upstream s test suite as well. For the sake of simplicity, it is best to ignore them for now and to focus on packaging only dependencies which are really needed to compile the application. Test dependencies can always be added later. This pom.xml investigation leads us to the following conclusion: PDFsam depends on Sejda, a PDF library. Basically Sejda is the product of a major refactoring that happened years ago and allows upstream to develop PDFsam faster and in multiple directions. For Debian packagers it is quite clear now that the upgrade of PDFsam is in reality more like packaging a completely new application. The inspection of Sejda s pom.xml file (another Maven project) reveals we also have to package imgscalr, Twelvemonkeys and SAMBox. We continue with these pom.xml analyses and end up with these new source packages: jackson-jr, libimgscalr-java, libsambox-java, libsejda-java, libsejda-injector-java, libsejda-io-java, libsejda-eventstudio-java, libtwelvemonkeys-java, fontawesomefx and libpdfbox2-java. Later I discovered that gettext-maven-plugin was also required. This was not obvious at first glance if you only check the pom.xml in the root directory but PDFsam and Sejda are multi-module projects! In this case every subdirectory (module) contains another pom.xml with additional information, so ideally you should check those too before you decide to start with your packaging. But don t worry it is often possible to ignore modules with a simple ignore rule inside your debian/*.poms file. The package will have less functionality but it can be still useful if you only need a subset of the modules. Of course in this case ignoring the gettext-maven-plugin artifact would result in a runtime error. C est la vie. A brief remark about Java package names: Java library packages must be named like libXXX-java. This is important for binary packages to avoid naming collisions. We are more tolerant when it comes to source package names but in general we recommend to use the exact same name as for the binary package. There are exceptions like prefixing source packages with their well known project name like jackson-XXX or jboss-XXX but this should only be used when there are already existing packages that use such a naming scheme. If in doubt, talk to us. mh_make or how to quickly generate an initial debian directory Packaging a Maven library is usually not very difficult even if it consists of multiple modules. The tricky part is to get the maven.rules, maven.IgnoreRules and your *.poms file right but debian/rules often only consists of a single dh line and the rest is finding the build-dependencies and adding them to debian/control. A small tool called mh_make, which is included in maven-debian-helper, can lend you a helping hand. The tool is not perfect yet. It requires that most build-dependencies are already installed on your local system, otherwise it won t create the initial debian directory and will only produce some unfinished (but in some cases still useful) files. A rule of thumb is to start with a package that does not depend on any other new dependency and requires the fewest build-dependencies. I have chosen libtwelvemonkeys-java because it was the simplest package and met the aforementioned criteria. Here is how mh_make looks like in action. (The animated GIF was created with Byzanz) First of all download the release tarball, unpack it and run mh_make inside the root directory. Ok, what is happening here? First you can choose a source and binary package name. Then disable the tests and don t run javadoc to create the documentation. This will simplify things a little. Tests and javadoc settings can be added later. Choose the version you want to package and then you can basically follow the default recommendations and confirm them by hitting the Enter key. Throughout the project we choose to transform the upstream version with the symbolic debian version. Remember that Java/Maven is version-centric. This will ensure that our Maven dependencies are always satisfied later and we can simply upgrade our Maven libraries and don t have to change the versions by hand in various pom.xml files; maven-debian-helper will automatically transform them for us to debian . Enable all modules. If you choose not to, you can select each module individually. Note that later on some of the required build-dependencies cannot be found because they are either not installed (libjmagick6-java) or they cannot be found in Debian s Maven repository under /usr/share/maven-repo. You can fix this by entering a substitution rule or, as I did in this case, you can just ignore these artifacts for now. They will be added to maven.IgnoreRules. In order to successfully compile your program you have to remove them from this file later again, create the correct substitution rule in maven.rules and add the missing build-dependencies to debian/control. For now we just want to quickly create our initial debian directory. If everything went as planned a complete debian directory should be visible in your root directory. The only thing left is to fix the substitution rule for the Servlet API 3.1. Add libservlet3.1-java to Build-Depends and the following rule to maven.rules: javax.servlet s/servlet-api/javax.servlet-api/ * s/.*/3.1/ * *
s/javax.servlet/javax.servlet.jsp/ s/jsp-api/javax.servlet.jsp-api/ * s/.*/2.3/ * * The maven.rules file consists of multiple rows separated by six columns. The values represent groupId, artifactId, type, version number and two fields which I never use.  You can just use an asterisk to match any value. Every value can be substituted. This is necessary when the value of upstream s pom.xml file differs from Debian s system packages. This happens frequently for API packages which are uploaded to Maven Central multiple times under a different groupId/artifactId but provide the same features. In this case the Twelvemonkeys pom requires an older API version but Debian is already at version 3.1. Note that we require a strict version number in this case because libservlet3.1-java does not use a symbolic debian version since we provide more than one Servlet API in the archive and this measure prevents conflicts. Thanks for reading this far. More articles about Java packaging will follow in the near future and hopefully they will clarify some terms and topics which could only be briefly mentioned in this post.
before

and after

1 August 2017

Paul Wise: FLOSS Activities July 2017

Changes

Issues

Review

Administration
  • Debian: fsck/reboot a buildd, reboot a segfaulting buildd, report/fix broken hoster contact, ping hoster about down machines, forcibly reset backup machine, merged cache patch for network-test.d.o, do some samhain dances, fix two stunnel services, update an IP address in LDAP, fix /etc/aliases on one host, reboot 1 non-responsive VM
  • Debian mentors: security updates, reboot
  • Debian wiki: whitelist several email addresses
  • Debian build log scanner: deploy my changes
  • Debian PTS: deploy my changes
  • Openmoko: security updates & reboots

Communication
  • Ping Advogato users on Planet Debian about updating/removing their feeds since it shut down
  • Invite deepin to the Debian derivatives census
  • Welcome Deepin to the Debian derivatives census
  • Inquire about the status of GreenboneOS, HandyLinux

Sponsors All work was done on a volunteer basis.

Russell Coker: QEMU for ARM Processes

I m currently doing some embedded work on ARM systems. Having a virtual ARM environment is of course helpful. For the i586 class embedded systems that I run it s very easy to setup a virtual environment, I just have a chroot run from systemd-nspawn with the --personality=x86 option. I run it on my laptop for my own development and on a server my client owns so that they can deal with the hit by a bus scenario. I also occasionally run KVM virtual machines to test the boot image of i586 embedded systems (they use GRUB etc and are just like any other 32bit Intel system). ARM systems have a different boot setup, there is a uBoot loader that is fairly tightly coupled with the kernel. ARM systems also tend to have more unusual hardware choices. While the i586 embedded systems I support turned out to work well with standard Debian kernels (even though the reference OS for the hardware has a custom kernel) the ARM systems need a special kernel. I spent a reasonable amount of time playing with QEMU and was unable to make it boot from a uBoot ARM image. The Google searches I performed didn t turn up anything that helped me. If anyone has good references for getting QEMU to work for an ARM system image on an AMD64 platform then please let me know in the comments. While I am currently surviving without that facility it would be a handy thing to have if it was relatively easy to do (my client isn t going to pay me to spend a week working on this and I m not inclined to devote that much of my hobby time to it). QEMU for Process Emulation I ve given up on emulating an entire system and now I m using a chroot environment with systemd-nspawn. The package qemu-user-static has staticly linked programs for emulating various CPUs on a per-process basis. You can run this as /usr/bin/qemu-arm-static ./staticly-linked-arm-program . The Debian package qemu-user-static uses the binfmt_misc support in the kernel to automatically run /usr/bin/qemu-arm-static when an ARM binary is executed. So if you have copied the image of an ARM system to /chroot/arm you can run the following commands like the following to enter the chroot: cp /usr/bin/qemu-arm-static /chroot/arm/usr/bin/qemu-arm-static
chroot /chroot/arm bin/bash Then you can create a full virtual environment with /usr/bin/systemd-nspawn -D /chroot/arm if you have systemd-container installed. Selecting the CPU Type There is a huge range of ARM CPUs with different capabilities. How this compares to the range of x86 and AMD64 CPUs depends on how you are counting (the i5 system I m using now has 76 CPU capability flags). The default CPU type for qemu-arm-static is armv7l and I need to emulate a system with a armv5tejl. Setting the environment variable QEMU_CPU=pxa250 gives me armv5tel emulation. The ARM Architecture Wikipedia page [2] says that in armv5tejl the T stands for Thumb instructions (which I don t think Debian uses), the E stands for DSP enhancements (which probably isn t relevant for me as I m only doing integer maths), the J stands for supporting special Java instructions (which I definitely don t need) and I m still trying to work out what L means (comments appreciated). So it seems clear that the armv5tel emulation provided by QEMU_CPU=pxa250 will do everything I need for building and testing ARM embedded software. The issue is how to enable it. For a user shell I can just put export QEMU_CPU=pxa250 in .login or something, but I want to emulate an entire system (cron jobs, ssh logins, etc). I ve filed Debian bug #870329 requesting a configuration file for this [1]. If I put such a configuration file in the chroot everything would work as desired. To get things working in the meantime I wrote the below wrapper for /usr/bin/qemu-arm-static that calls /usr/bin/qemu-arm-static.orig (the renamed version of the original program). It s ugly (I would use a config file if I needed to support more than one type of CPU) but it works. #include <stdio.h>
#include <unistd.h>
#include <stdlib.h> int main(int argc, char **argv)

if(setenv("QEMU_CPU", "pxa250", 1))

printf("Can't set $QEMU_CPU\n");
return 1;

execv("/usr/bin/qemu-arm-static.orig", argv);
printf("Can't execute \"%s\" because of qemu failure\n", argv[0]);
return 1;

Russ Allbery: Review: The Fifth Season

Review: The Fifth Season, by N.K. Jemisin
Series: The Broken Earth #1
Publisher: Orbit
Copyright: 2015
ISBN: 0-316-22930-X
Format: Kindle
Pages: 497
The world of The Fifth Season is one of near-constant seismic activity. Volcanoes, massive earthquakes, and all the catastrophes that follow them are a constant threat. Civilization barely survives the turmoil, and only because of two things: strict cultural rules about how to handle a "fifth season" of heavy seismic activity and its aftermath (called stonelore), and the orogenes. Orogenes are humans (well, there is some debate about that) who have an organ that others don't, a biological ability to manipulate the seismic activity and the earth itself. They can protect others by damping down activity, smoothing faults, and redirecting seismic shock waves, but they can also destroy: pull earth out of shape, set off quakes, and create paths for magma to surface. And, to gather the power to manipulate the earth, they draw energy from everything around them, including from other people, often fatally. Orogenes are feared and hated by the typical person. The Stillness, the ironically-named continent on which this book is set, is very old and has had numerous civilizations destroyed by some seismic catastrophe. The landscape is scattered with useless or dangerous remnants of previous forgotten civilizations; the history, likewise, with only the stonelore and some muddled mythology available to most people. The current rulers have kept their empire for a surprising length of time, however, due mostly to the stable ground beneath their centrally-located capital. That stability comes from Fulcrum-trained orogenes, who are taken from their family as children and trained harshly to serve their society by suppressing or fixing dangerous seismic events. Fulcrum orogenes don't have an awful life (well, most of them; for some, it is pure torture), but they're effectively slaves, kept under the watchful eye of Guardians who have mysterious powers of their own. Against this background, The Fifth Season tells three interwoven stories. Essun lives in a small village (comm) at the start of the book, leading a quiet life, until one of her children is beaten to death by her husband following a seismic event that he thinks the child stopped. He's taken their other child and left. Essun, severely traumatized, heads after him to attempt a rescue, or at least revenge. Damaya is a child from another comm who is sold to the Guardians by her parents when she demonstrates orogenic ability, and who goes through Fulcrum training. And Syenite is a Fulcrum orogene, assigned to a field mission with a difficult but very senior orogene named Alabaster. All of these stories eventually interweave, and eventually reveal where they fit in the somewhat unobvious chronology of the story, but it takes some time to get there. It also takes some time for the primary characters to have much in the way of agency. Essun starts with the most, once she recovers her senses enough to start her hunt for revenge. Syenite is ambitious but junior, and Damaya is a child, trying to navigate an unknown world of student politics and strict rules. And all three of the main characters are orogenes, rogga when one is being insulting, and this world does not like orogenes. At all. The Fifth Season starts with an unusual narrative style: a conversational narrator who begins with some of the world background and some mysterious scenes that didn't make sense until much later in the book (late enough that I didn't remember them or make sense of them until I re-read them for this review). The book then focuses on Essun, whose scenes are written in second person present. Normally I think second person feels weirdly intrusive and off-putting, but once I got used to it here, I think it works as well as I've seen it work anywhere. I also see why Jemisin did it: Essun starts the story so traumatized that she's partly disassociating. First person wouldn't have worked, and the second-person voice gives that trauma some immediacy and emotional heft that would have been hard to achieve in third person. The story starts slowly, and builds slowly, as the world is introduced and Jemisin lays down the texture and history of the world. The world-building is ambitious in tracing down the ramifications of the seismic chaos and the implications of orogene ability (although it's best to think of it as pure magic, despite the minor science fiction trappings). But through that world-building, what this story is building is a deep, powerful, frustrated rage. The Fifth Season is an angry book. It's a book about outcasts, about slaves. About people who, even if they're succeeding within the parameters they're given, are channeled and stymied and controlled. It's a story about smiling, kind paternalism hiding lies, control, and abuse, about how hard it is to find enough space from the smothering destructiveness of a totalitarian culture to let yourself relax. It's a story about the horrible things people are willing to do to those they don't consider fully human, and all the ways in which safety, expediency, tradition, culture, and established social roles conspire to keep people within the box where they belong. And it's a story about how being constantly on edge, constantly dreading the next abuse, breaking under it, and being left wanting to burn the whole world to the ground. I struggled at the start of this book, but it grew on me, and by about halfway through it had me hooked completely. At first, Syenite's part of the story (the most traditionally told) was my favorite, but the coming-of-age stories of her and Damaya were overtaken by Essun's far more complex, cautious, and battle-weary tale. And I loved Jemisin's world-building. There's a lot of depth here, a lot of things going on that are unexplained but clearly important, and a restraint and maturity in how the world is revealed that makes it feel older and more layered than Jemisin's The Hundred Thousand Kingdoms. The major drawback of this book is that it is very much the first book of a series, and it doesn't so much have an ending as a hard stop. It's not quite a cliff-hanger, but it's nearly as unsatisfying as one. Most of the major questions of the book who the stone eaters are and what they want, and the fate of Essun's husband and child, just to name two are still unresolved at the end of the story. There is a bit of emotional closure, but not a true moment of catharsis for all of the rage. Hopefully that will be coming in a future book. This is a very unusual story, mixing fantasy and a sort of magic (orogeny) with some science fiction elements and a deep history. It's gritty, textured, emotional, and furious, and very much worth reading. I'm looking forward to the next book in the series. Followed by The Obelisk Gate. Rating: 8 out of 10

31 July 2017

Jonathan McDowell: How to make a keyring

Every month or two keyring-maint gets a comment about how a key update we say we ve performed hasn t actually made it to the active keyring, or a query about why the keyring is so out of date, or told that although a key has been sent to the HKP interface and that is showing the update as received it isn t working when trying to upload to the Debian archive. It s frustrating to have to deal with these queries, but the confusion is understandable. There are multiple public interfaces to the Debian keyrings and they re not all equal. This post attempts to explain the interactions between them, and how I go about working with them as part of the keyring-maint team. First, a diagram to show the different interfaces to the keyring and how they connect to each other: keyring-maint workflow
Public interfaces

rsync: keyring.debian.org::keyrings This is the most important public interface; it s the one that the Debian infrastructure uses. It s the canonical location of the active set of Debian keyrings and is what you should be using if you want the most up to date copy. The validity of the keyrings can be checked using the included sha512sums.txt file, which will be signed by whoever in keyring-maint did the last keyring update.

HKP interface: hkp://keyring.debian.org/ What you talk to with gpg --keyserver keyring.debian.org. Serves out the current keyrings, and accepts updates to any key it already knows about (allowing, for example, expiry updates, new subkeys + uids or new signatures without the need to file a ticket in RT or otherwise explicitly request it). Updates sent to this interface will be available via it within a few hours, but must be manually folded into the active keyring. This in general happens about once a month when preparing for a general update of the keyring; for example b490c1d5f075951e80b22641b2a133c725adaab8. Why not do this automatically? Even though the site uses GnuPG to verify incoming updates there are still occasions we ve seen bugs (such as #787046, where GnuPG would always import subkeys it didn t understand, even when that subkey was already present). Also we don t want to allow just any UID to be part of the keyring. It is thus useful to retain a final set of human based sanity checking for any update before it becomes part of the keyring proper.

Alioth/anonscm: https://anonscm.debian.org/git/keyring/keyring/ A public mirror of the git repository the keyring-maint team use to maintain the keyring. Every action is recorded here, and in general each commit should be a single action (such as adding a new key, doing a key replacement or moving a key between keyrings). Note that pulling in the updates sent via HKP count as a single action, rather than having a commit per key updated. This mirror is updated whenever a new keyring is made active (i.e. made available via the rsync interface). Until that point pending changes are kept private; we sometimes deal with information such as the fact someone has potentially had a key compromised that we don t want to be public until we ve actually disabled it. Every keyring push (as we refer to the process of making a new keyring active) is tagged with the date it was performed. Releases are also tagged with their codenames, to make it easy to do comparisons over time.

Debian archive This is actually the least important public interface to the keyring, at least from the perspective of the keyring-maint team. No infrastructure makes use of it and while it s mostly updated when a new keyring is made active we only make a concerted effort to do so when it is coming up to release. It s provided as a convenience package rather than something which should be utilised for active verification of which keys are and aren t currently part of the keyring.

Team interface

Master repository: kaufmann.debian.org:/srv/keyring.debian.org/master-keyring.git The master git repository for keyring maintenance is stored on kaufmann.debian.org AKA keyring.debian.org. This system is centrally managed by DSA, with only DSA and keyring-maint having login rights to it. None of the actual maintenance work takes place here; it is a bare repo providing a central point for the members of keyring-maint to collaborate around.

Private interface

Private working clone This is where all of the actual keyring work happens. I have a local clone of the repository from kaufmann on a personal machine. The key additions / changes I perform all happen here, and are then pushed to the master repository so that they re visible to the rest of the team. When preparing to make a new keyring active the changes that have been sent to the HKP interface are copied from kaufmann via scp and folded in using the pull-updates script. The tree is assembled into keyrings with a simple make and some sanity tests performed using make test. If these are successful the sha512sums.txt file is signed using gpg --clearsign and the output copied over to kaufmann. update-keyrings is then called to update the active keyrings (both rsync + HKP). A git push public pushes the changes to the public repository on anonscm. Finally gbp buildpackage --git-builder='sbuild -d sid' tells git-buildpackage to use sbuild to build a package ready to be uploaded to the archive. Hopefully that helps explain the different stages and outputs of keyring maintenance; I m aware that it would be a good idea for this to exist somewhere on keyring.debian.org as well and will look at doing so.

Chris Lamb: Free software activities in July 2017

Here is my monthly update covering what I have been doing in the free software world during July 2017 (previous month): I also blogged about my recent lintian hacking and installation-birthday package.
Reproducible builds

Whilst anyone can inspect the source code of free software for malicious flaws, most software is distributed pre-compiled to end users. The motivation behind the Reproducible Builds effort is to permit verification that no flaws have been introduced either maliciously or accidentally during this compilation process by promising identical results are always generated from a given source, thus allowing multiple third-parties to come to a consensus on whether a build was compromised. (I have generously been awarded a grant from the Core Infrastructure Initiative to fund my work in this area.) This month I:
  • Assisted Mattia with a draft of an extensive status update to the debian-devel-announce mailing list. There were interesting follow-up discussions on Hacker News and Reddit.
  • Submitted the following patches to fix reproducibility-related toolchain issues within Debian:
  • I also submitted 5 patches to fix specific reproducibility issues in autopep8, castle-game-engine, grep, libcdio & tinymux.
  • Categorised a large number of packages and issues in the Reproducible Builds "notes" repository.
  • Worked on publishing our weekly reports. (#114 #115, #116 & #117)

I also made the following changes to our tooling:
diffoscope

diffoscope is our in-depth and content-aware diff utility that can locate and diagnose reproducibility issues.

  • comparators.xml:
    • Fix EPUB "missing file" tests; they ship a META-INF/container.xml file. [ ]
    • Misc style fixups. [ ]
  • APK files can also be identified as "DOS/MBR boot sector". (#868486)
  • comparators.sqlite: Simplify file detection by rewriting manual recognizes call with a Sqlite3Database.RE_FILE_TYPE definition. [ ]
  • comparators.directory:
    • Revert the removal of a try-except. (#868534)
    • Tidy module. [ ]

strip-nondeterminism

strip-nondeterminism is our tool to remove specific non-deterministic results from a completed build.

  • Add missing File::Temp imports in the JAR and PNG handlers. This appears to have been exposed by lazily-loading handlers in #867982. (#868077)

buildinfo.debian.net

buildinfo.debian.net is my experiment into how to process, store and distribute .buildinfo files after the Debian archive software has processed them.

  • Avoid a race condition between check-and-creation of Buildinfo instances. [ ]


Debian My activities as the current Debian Project Leader are covered in my "Bits from the DPL emails to the debian-devel-announce mailing list.
Patches contributed
  • obs-studio: Remove annoying "click wrapper" on first startup. (#867756)
  • vim: Syntax highlighting for debian/copyright files. (#869965)
  • moin: Incorrect timezone offset applied due to "84600" typo. (#868463)
  • ssss: Add a simple autopkgtest. (#869645)
  • dch: Please bump $latest_bpo_dist to current stable release. (#867662)
  • python-kaitaistruct: Remove Markdown and homepage references from package long descriptions. (#869265)
  • album-data: Correct invalid Vcs-Git URI. (#869822)
  • pytest-sourceorder: Update Homepage field. (#869125)
I also made a very large number of contributions to the Lintian static analysis tool. To avoid duplication here, I have outlined them in a separate post.

Debian LTS

This month I have been paid to work 18 hours on Debian Long Term Support (LTS). In that time I did the following:
  • "Frontdesk" duties, triaging CVEs, etc.
  • Issued DLA 1014-1 for libclamunrar, a library to add unrar support to the Clam anti-virus software to fix an arbitrary code execution vulnerability.
  • Issued DLA 1015-1 for the libgcrypt11 crypto library to fix a "sliding windows" information leak.
  • Issued DLA 1016-1 for radare2 (a reverse-engineering framework) to prevent a remote denial-of-service attack.
  • Issued DLA 1017-1 to fix a heap-based buffer over-read in the mpg123 audio library.
  • Issued DLA 1018-1 for the sqlite3 database engine to prevent a vulnerability that could be exploited via a specially-crafted database file.
  • Issued DLA 1019-1 to patch a cross-site scripting (XSS) exploit in phpldapadmin, a web-based interface for administering LDAP servers.
  • Issued DLA 1024-1 to prevent an information leak in nginx via a specially-crafted HTTP range.
  • Issued DLA 1028-1 for apache2 to prevent the leakage of potentially confidential information via providing Authorization Digest headers.
  • Issued DLA 1033-1 for the memcached in-memory object caching server to prevent a remote denial-of-service attack.

Uploads
  • redis:
    • 4:4.0.0-1 Upload new major upstream release to unstable.
    • 4:4.0.0-2 Make /usr/bin/redis-server in the primary package a symlink to /usr/bin/redis-check-rdb in the redis-tools package to prevent duplicate debug symbols that result in a package file collision. (#868551)
    • 4:4.0.0-3 Add -latomic to LDFLAGS to avoid a FTBFS on the mips & mipsel architectures.
    • 4:4.0.1-1 New upstream version. Install 00-RELEASENOTES as the upstream changelog.
    • 4:4.0.1-2 Skip non-deterministic tests that rely on timing. (#857855)
  • python-django:
    • 1:1.11.3-1 New upstream bugfix release. Check DEB_BUILD_PROFILES consistently, not DEB_BUILD_OPTIONS.
  • bfs:
    • 1.0.2-2 & 1.0.2-3 Use help2man to generate a manpage.
    • 1.0.2-4 Set hardening=+all for bindnow, etc.
    • 1.0.2-5 & 1.0.2-6 Don't use upstream's release target as it overrides our CFLAGS & install RELEASES.md as the upstream changelog.
    • 1.1-1 New upstream release.
  • libfiu:
    • 0.95-4 Apply patch from Steve Langasek to fix autopkgtests. (#869709)
  • python-daiquiri:
    • 1.0.1-1 Initial upload. (ITP)
    • 1.1.0-1 New upstream release.
    • 1.1.0-2 Tidy package long description.
    • 1.2.1-1 New upstream release.

I also reviewed and sponsored the uploads of gtts-token 1.1.1-1 and nlopt 2.4.2+dfsg-3.

Debian bugs filed
  • ITP: python-daiquiri Python library to easily setup basic logging functionality. (#867322)
  • twittering-mode: Correct incorrect time formatting due to "84600" typo. (#868479)

Next.

Previous.