I have a Kindle. I ve spent a lot of time saying this sheepishly it s Amazon, it s proprietary, DRM is bad, etc, etc. It was a very thoughtful gift from my parents, taking into account things like my travel schedule, preference for traveling lighter, love of reading, and small apartment.
I wanted to share some observations from my experience owning a Kindle.
I don t like to read for school on it. I really markup the papers I read for school, underlining things, notes in the margins, flipping back and forth between pages, cross-referencing things. (Note: My greatest grad school investment has probably been getting a solid printer.) The Kindle doesn t work well for this.
I don t like buying ebooks. I don t inherently mind buying ebooks in general. I own some. I don t want to pay $15 for a DRMed ebook though. It feels too much like renting a book. I find organizing ebooks tedious, while organizing my physical books joyful. I ve bought ebooks from non-Amazon sites, taken advantage of Tor.com s Book of the Month Club, and some other things.
I love borrowing ebooks. Borrowing ebooks from the library is the absolute best. I love it. It s convenient, I have a huge range of books I can read, and between my phone and the Kindle, I can get one or add it to a To Read queue the moment I think about it, rather than forgetting on-and-off for months.
It connects me to my parents. Because the Kindle is connected to my parents Amazon account, I get to see what they read. It s like a little social network with just my family. We have similar tastes in books (for some part anyway), and it s cool to also get some recommendations when I m in a rush or on the train and don t have time to actually ask for them.
In a lot of ways my Kindle is an extension of the public library system. It allows me to connect with it (and the books I want to read). It feels very scifi to me having a personal device that connects to this seemingly endless public store of cool stuff.
I've been using Vim as my main text editor for 18 years, but for most of that
time I've been using something very close to the default configuration: my
vimrc contained not much more than preferences for indentation and how to
visually indicate white space characters like tabs.
Last but not least, I've used a single colour scheme for most of that time:
Zenburn.
In 20151 I started exploring a few Vim plugins2. To manage
them, I started by choosing a plugin manager,
Pathogen3. Recently I
noticed that the plugin's author, Tim Pope, now recommends new users just use
Vim's built in package management instead. I got curious about Tim Pope's
other plugins: He has written a great deal of them.
Given I've spent most of two decades with a barely-configured Vim, you can
imagine that I don't want to radically alter the way it works, and so I did
not expect to want to use a lot of plugins. The utility of a plugin would have
to outweight the disadvantages of coming to rely on one. But when browsing
Tim's plugins, time and time again, I found myself reacting to description
with How did I manage without this?. And so, I've ended up installing all
of the following, all by Tim Pope:
vim-rsi - readline key mappings in a few sensible places
vim-sleuth Figure out whitespace preferences (tabs, indentation level) from the current buffer
vim-speeddating handle dates (YYYY-MM-DD) properly with the increment/decrement functions (<C-A>, <C-X>)
vim-surround mappings to manage "pairs" of characters nicely (e.g. brackets, quotes)
vim-unimpaired pairs of complementary mappings, e.g. short mappings for :cnext and :cprevious
vim-vinegar quality-of-live improvements to netrw, Vim's built-in file browser
I had to look this up, probably because I started at redhat
I have opinions about Plugins, what supporting them means
architecturally for your application, the interaction with Open
Source, and stuff like that, perhaps for another post.
To try out Vim plugins the first thing you need to figure out is how to manage
them (install, activate, configure). Vim grew a Plugin manager in version 8
(2016). Prior to that, people wrote third-party ones. For this reason there is
a frankly absurd number of Plugin managers, including: Vim's own; Vim Plug;
Vundle; Dein; Volt and Pathogen.
Many developers manage their user-specific application configuration also
known as dotfiles in a version control system such as git. This allows
for keeping track of changes and synchronizing the dotfiles across different
machines. Searching on github, you ll find thousands of dotfile
repositories.
As your dotfiles are sprinkled all over your home directory, managing them in
a single repository is not trivial, i.e. how do you make sure that your
.bashrc, .tmux.conf, etc. that life in your dotfile repository appear in
the proper places in your home directory? The most common solution is to use
symlinks so that the .tmux.conf in your home directory is just a symlink
pointing to the appropriate file in your dotfile repository:
This leads immediately to another problem: how do you manage the symlinks? For
the longest time I just manually maintained the symlinks on the various
machines, but this approach does not scale well with the number of dotfiles
and machines you re using this repository on. Often, people write their own
shell scripts that help them with the maintenance of the symlinks, but at
least the solutions I ve seen so far did not convince me.
Last year I stumbled upon GNU Stow, an unpretentious little tool that
does not reveal at first sight how useful it would be for the job. The
description on the website says:
GNU Stow is a symlink farm manager which takes distinct packages of software
and/or data located in separate directories on the filesystem, and makes
them appear to be installed in the same place.
Right.
How does it work?
In stow s terminology, a package is a set of files and directories that
need to be installed in a particular directory structure. The target
directory is the root of the tree in which the package appear to be
installed.
When you stow a package, stow creates symlinks in the target directory
that point into the package.
Let s say I have my dotfiles repository in ~/git/dotfiles/. Within this
repository, I have a tmux package, containing the .tmux.conf dotfile:
$ pwd
/home/venthur/git/dotfiles
$ find tmux
tmux                # the package
tmux/.tmux.conf     # the dotfile
The target directory is my home directory, as this is where the symlinks
need to be created. I can now stow the tmux package into the target
directory like so:
$ stow --target=/home/venthur tmux
and stow will create the appropriate symlinks to the contents of the package
into the target directory:
$ ls -l ~/.tmux.conf
lrwxrwxrwx 1 venthur venthur 342. Jun 2021 /home/venthur/.tmux.conf -> git/dotfiles/tmux/.tmux.conf
Note that the name of the package (i.e. the name of the directory) does not
matter as stow points the symlinks into the package, so you can choose
it freely. I usually use the name of the program that the configuration
belongs to as the package name.
Your package can also contain several files or even a complex directory
structure. Let s look at the configuration for neovim, which lives below
~/.config/nvim/:
At this point we should mention that the target directory for my dotfiles will
always be my home directory, so the contents of the packages are either the
configuration files or the directory structure as they live in my home
directory.
Deleting a package from the parent directory
You can also remove (unstow) a package from the target directory again, using
the --delete parameter:
$ ls -l ~/.tmux.conf
lrwxrwxrwx 1 venthur venthur 3418. Dez 22:53 /home/venthur/.tmux.conf -> git/dotfiles/tmux/.tmux.conf
$ stow --target=/home/venthur --delete tmux/
$ ls -l ~/.tmux.conf
ls: cannot access '/home/venthur/.tmux.conf': No such file or directory
Stowing several packages at once
Since your dotfile repository will likely contain more than one package, it
makes sense to combine the individual stow commands into one, so instead of
stowing everything individually,
Note that I use */ instead of * to match all directories (i.e. packages),
since my dotfiles repository also contains a README.md and a makefile.
Putting it all together
My dotfiles repository contains a makefile that allows me to
create/update or delete all symlinks at once:
The --restow parameter tells stow to unstow the packages first before
stowing them again, which is useful for pruning obsolete symlinks from the
target directory.
Et voil ! Whenever I make a change in my dotfiles repository that involves
creating or deleting a dotfile (or a package), I simply call:
$ make
and everything is updated. To delete all dotfile-related symlinks from this
machine, I simply run:
Tarisai was raised alone in Bhekina House by an array of servants and
tutors who were not allowed to touch her. Glimpses of the world were
fleeting and sometimes ended by nailed-shut windows. Her life revolved
around her rarely-seen mother, The Lady, who treats her with deep
affection but rarely offers a word of praise, instead only pushing her to
study harder. The servants whispered behind her back (but still in her
hearing) that she was not human.
At the age of seven, in a child's attempt to locate her absent mother by
sneaking out of the house, she finds her father and is told a piece of the
truth: she is the daughter of the Lady and a captive ehru, a djinn. At
the age of eleven she's sent with two guardians to Oluwan City, the
capital of Aritsar, to enter a competition she knows nothing about, for
reasons no one has ever explained.
Raybearer is a young adult fantasy novel, the first of a duology.
Like a lot of young adult novels, it is a coming of age story that follows
Tarisai from the end of her highly manipulated childhood through her
introduction to a world she was carefully never taught about. Like a lot
of young adult fantasy novels, Tarisai has some unusual abilities. What
those are, and why she has them, is perhaps less obvious than it may
appear at first.
Unlike a lot of young adult fantasy novels, Raybearer is not set in
a facsimile of Western Europe, the structure of gods and religion is not
obviously derived from Christianity or Greek or Norse mythology, and
neither Tarisai nor most of the characters of this story are white. Some
of the characters are; Ifueko draws from a grab bag of cultures that does
include European as well as African, Middle Eastern, and Asian. But the
food, the physical descriptions, the landscape, and the hair and hair
styles feel primarily African not in the sense of specific identifiable
regions, but in the same way that most fantasy feels European even if the
map isn't recognizable.
That gives this story a freshness that I found delightful. The mythology
of this world shares some similarities to standard fantasy tropes,
including a bargain with the underworld that plays a similar role to fae
bargains in some European fantasy, but it also goes in different
directions and finds atypical balances, which gave the story room to catch
me by surprise.
The magical center of this book (and series), which Tarisai is carefully
not told about until the story starts, is a system for anointing and
protecting the emperor: selection of people who swear loyalty to him and
each other and become his innermost circle, and thereby grant him magical
protection. The emperor himself is the Raybearer, possessing an artifact
that makes him invulnerable to one form of death for each member of his
council he anoints. At eleven council members, he becomes invulnerable to
anything but old age, or an attack from one of the council themselves.
As the reader learns early in the book, that last part is important.
Tarisai is an assassin; her mother's goal is for her to be selected as a
member of the council for the prince, who will become the next emperor.
But there is rather more to this system of magic than it may first appear,
in a way that adds good depth to the mythology. And there is quite a bit
more to Tarisai herself than anyone expects.
Tarisai as a protagonist follows a more typical young adult pattern, but
it's a formula that works for me. Her upbringing isolated from any other
children has left her craving connection, but it also made her
self-reliant, stubborn, and good at keeping her own counsel. One of the
things that I loved about this book is that she's not thrown into a nest
of vipers and cynical politics. Some of that is happening in the
background, but the first step of her mother's plan is for her to earn the
trust of the prince in a competition with other potential council members,
all of whom are, well, kids. They fight (some), but they also make
friends, helped along by the goal and requirement that they join a
cooperative council or be sent home. That gives the plot a more
collaborative and social feel than one would otherwise expect from the
setup. Ifueko does a great job juggling a challenging cast size by
focusing on a few kids with whom Tarisai strikes up a friendship but
giving the others distinct-enough personalities that their presence is
still felt in the story.
There are two character dynamics that stand out: Tarisai's relationship
with Prince Ekundayo, and her friendship with Sanjeet. The first carries
much of the weight of the plot, of course; Tarisai is supposed to gain his
trust and then kill him, and the reader will be unsurprised that this
takes twists and turns no one expected. But Ifueko, refreshingly, does
not reach for the stock plot development of a romance to complicate
matters, even though many of the characters expect that. To the contrary,
this is a rare story that at least hints at an acknowledgment that some
people are not interested in romance at all, and there are other forms
that mutual respect can take.
Tarisai's relationship with Sanjeet is a different type of depth: two kids
with very different histories finding a common understanding in the ways
that they were both abused, and create space for each other. It's a great
friendship that includes some deeply touching moments.
It took me a bit to get into this book, but once Tarisai starts finding
her feet and navigating her new relationships, I was engrossed. The story
takes a sharp and nasty turn that was hard to read, but Ifueko chooses to
turn it into a story of resiliency rather than survival, which makes it
much easier to read than it could have been. She also pulls off the kind
of plot that complicates and deepens the motives of the obvious villains
in a way that gives the story much greater heft, but without disregarding
the damage that they have done. I think the plot did fall apart a bit at
the end of the book, with too much quick travel and world-building
revelations at the cost of development of the relationships that were
otherwise at the center of the book, but I'm hoping the sequel will pull
those threads back together.
And it's so refreshing to read a fantasy novel of this type with a
different setting. It's not perfect: Ifueko falls back on
Planet of
the Hats regional characterization in a few places, and Songland is so
obviously Korea that it felt jarring and out of place. Christianity also
snuck its nose into the world-building tent near the end in ways that
bugged me a bit, although it was subtle enough that I think most readers
won't notice. But compared to most fantasy settings, it feels original
and fresh. More of this!
Ifueko starts this book with a wonderfully memorable dedication:
For the kid scanning fairy tales for a hero with a face like theirs.
And for the girls whose stories we compressed into pities and wonders,
triumphs and cautions, without asking, even once, for their names.
I think she was successful on both parts of that promise, and it makes for
some great reading. Recommended.
Followed by Redemptor.
Rating: 8 out of 10
We've more or less finished the release of the Debian CD/DVD/Blu-Ray and other media for Bullseye 11.2 release. This is one of the (roughly) quarterly point releases and roll-up releases.Thanks firstly to the developers, users, helpers, bug filers who help to keep Debian moving and working and to the release team and press team who more or less finish their job before the media team start theirs. Thanks to Sledge and RattusRattus and Isy in Cambridge and to Schweer who single-handedly clears all the Debian-edu testing. This release run seemed to be a bit more slick, a bit faster, a few fewer problems and it's always a joy to work with colleagues who are like family.The last couple of years have been more than a bit difficult: this (should) be more or less the last major action from the release team and others for 2021.I'm going to take the opportunity this gives me to wish all concerned with Debian (and every other Linux) the very best wishes for the year to come. Surely, it can only get better - eventually.
Armadillo is a powerful and expressive C++ template library for linear algebra aiming towards a good balance between speed and ease of use with a syntax deliberately close to a Matlab. RcppArmadillo integrates this library with the R environment and language and is widely used by (currently) 937 other packages on CRAN, and downloaded over 22 million times (per the partial logs from the cloud mirrors of CRAN).
This release brings another bug fix release 10.7.5 by Conrad in the long-term support 10.7.* series we started with 0.10.7.0 on September 30. As the bug fixes can come a little quicker than the desired monthly cadence CRAN aims for, we skipped a few of those release for CRAN only but of course still provide them via the Rcpp drat repo.
The full set of changes (since the last CRAN release 0.10.7.3.0) follows. It includes the nice fixes to the fields type mentioned right after the last release.
Changes in RcppArmadillo version 0.10.7.5.0 (2021-12-16)
Upgraded to Armadillo release 10.7.5
fix aliasing bug in diagmat()
fix detection of 2x2 triangular matrices
Changes in RcppArmadillo version 0.10.7.4.0 (2021-11-23)
Upgraded to Armadillo release 10.7.4
faster handling of diagonal matrices by inv_sympd(), pinv(), rank()
more robust detection of incorrect data format by .load()
Correct dimensions setting in import/export of arma::field types, protected by #define (Jonathan Berrisch in #352 fixing #351)
Add unit tests for fields both with and without new #define (Dirk)
Two weeks ago I decided to make myself a combined birthday and Christmas present and upgrade my coffee gear.
I ve got my first espresso machine back in 2013, it was a cheap Saeco Philips Poemia, which made reasonably
drinkable coffee, but not being able to make good coffee made me increasingly unhappy about it. However,
since it worked, I wasn t motivated enough to change anything until it stopped working. One day the nut holding
the shower screen broke, and I couldn t replace it.
Having no coffee machine is arguably worse than having a mediocre one, so I started looking for a new one in the budget
range. Having spent about two months reading reviews for all sorts of manual espresso machines, I realised the best
thing I can probably do for the money I was willing to spend at the time was to buy a second-hand Gaggia Classic.
Which is what I did: I paid 260 to a person who apparently decided they prefer to press a button to get their espresso
rather than have to prepare it themselves.
My first attempts at making espresso weren t very much successful, as my hand grinder couldn t produce the right grind for
espresso (without using pressurised baskets), so I quickly upgraded it to the 50 De Longhi electric grinder, which was much
better for espresso.
Gaggia Classic 2015 and De Longhi grinder
This setup has worked for me for nearly 4 years, but over the time the Gaggia started malfunctioning.
See, this particular Gaggia Classic is the 2015 model, which resulted in the overhaul of the design after Gaggia was acquired by
Philips. They replaced the boiler, changed the exterior design a bit, and importantly for me replaced the fully metal group
head with the metal and plastic version typically found in cheap espresso machines like my old Poemia.
The Gaggia Classic 2015 group head
The trouble with this one is that the plastic bit (barely seen on the picture, but it s inserted into the notches on the sides
of the group head) is that it gets damaged over the time, especially when the portafilter is inserted very tightly. The more
damaged it gets, the tigher it is necessary to insert the portafilter to avoid leakage, the more damaged it gets and so on.
At one point, the Gaggia was leaking water every time I was making coffee, affecting the quality of the brew and making a mess
in the kitchen. I made a mistake and removed the plastic bit only to realise it cannot be purchased separately and nobody knows
how to put it back once it s been removed; I ended up paying more than a hundred euro to replace the group head as a whole.
Once I ve got the Gaggia back, I became too conscious of the potential damage I can make by overengaging the portafilter, I decided
it s probably the time to get a new coffee machine.
Gaggia Classic 2015 vs 2019
The makers of Gaggia listened to the critics and undid the 2015 changes to the Gaggia Classic design, reverting to the previous one
and fixing it they basically merged the fixes many of the owners of the old Gaggia did themselves. The group head is now without
any plastic, so I don t have to worry that much about damaging it accidentally.
A friend pointed out that my grinder is probably not good enough and recommended a couple of models to me; I checked
Kev s Coffee Blog and found a grinder, Sage Dose Control Pro,
which was available on sale in my local shop for a reasonable price.
I ve also got a portafilter holder to make tamping more comfortable I used to tamp against an edge of the sink:
The final setup:
Gaggia Classic 2019 and Sage BCG600 Dose Control Pro
What I learnt from this is that the grinder does indeed make a huge difference. I am now able to consistently produce brews I would only occasionally
get with the old De Longhi grinder. There is one downside to the new grinder.
Happy with my new purchase, I went to read this review and thought to myself: lucky me, my grinder is absolutely quiet! And then I realised that
the noise in my kitchen is not, in fact, produced by the fridge, but the grinder. Well, a cheap switched plug solved the issue completely (I wish
sockets here each had a switch like they usually to in the UK!)
Debian security is pretty good, but there s always scope for improvement. Here are some ideas that I think could be used to improve things.
A security wizard , basically a set of scripts with support for plugins that will investigate your system and look for things that can be improved. It could give suggestions on LSMs that could be used, sysctl settings, lists of daemons running as root that possibly don t need root privs, etc. Plugins could be for different daemons, so there could be a plugin for Apache that looks for potential issues with Apache configuration. It wouldn t be possible to cover everything, but it would be possible to cover many common cases. It appears that we used to have a harden package to do some of these things which disappeared. It appears that the only remnant of that is the hardening-runtime package.
Kali Linux [1] is a distribution designed for penetration testing, I recently tried out many of it s features and I was very impressed. While I don t think that the aim should be to copy all Kali features into Debian there are probably some that are worthy of inclusion. Most Kali features run well in a VM, but the Wifi penetration testing tools need access to the hardware, so they could be a good candidate for inclusion in Debian (license permitting).
We have a Securing Debian Manual [2] that is really good. It s a little out of date and needs some contributions, it also needs to be better known.
The Security Management page of the Debian wiki [3] has links to a number of pages about improving system security. It needs some updates, it doesn t have a link to a page about SE Linux so there s some work for me to do there.
Can training help people? I would be happy to run some Debian SE Linux training sessions over Matrix or Jitsi. We can probably find people to offer training on other aspects of Linux security that are implemented in Debian if there is an audience. I don t think that I and other DDs (Debian Developers) can train everyone, but we could train people who then go on to run other training sessions and make the session notes etc available under the GPL.
There would also be some benefits to training other DDs as probably no-one has a good overview of all the security features that are supported.
Any other ideas? Feel free to comment here or start a thread on a public mailing list. If you start a mailing list discussion please email me or comment here with the URL if it s a list that I m not on so I can track it via the archives. This post was inspired by a discussion on a private list of a related topic. I think it s better to have a public discussion instead.
The first time I applied for grad school it was a bit of a lark. I was serious about it, I wanted to go, I had goals, and I am happy to be here now. However, it was a little fun. I took a white paper and crisped it up with the help of some friends who read it and provided comments. I wrote a personal statement, got some letters of recommendation, and generally felt pretty good about the process. It wasn t stressful.
The second time I applied to grad school it was a slog. For several weeks I gave up most of my free time to application writing and when I wasn t working on applications I thought about how I ought to be doing something about it. Applications are due while you re coming up on the end of your semester or end of the year push at work or both! There just isn t enough time for everything. I think even applying for grad school qualifies you to attend.
Here are some things I learned in the application process. Note, I haven t gotten in anywhere (yet), so we ll see how it pans out.
You have to do a lot of research.
This changes by field, school, and even individual faculty preference. Some possible mentors / advisors like to talk with prospective students ahead of time. On two of my applications I was explicitly asked who I spoke with in the department. On others I was asked to list faculty (in order of preference even!) that I would be interested in working with. Some schools requested in essays to list faculty. In general, it s considered important to explain why a particular school: what about that school attracts you? What resources do they have that you want to take advantage of? What research that they are doing interests you?
Faculty profiles and department websites are useful for this, but far from complete. A co-worker suggested I contact someone who, based on their profile, I shared no research interests with. However, we talked and it turns out we had things in common! In general, colleagues, peers, other academics, and friends were the best resource I had for investigating schools and potential faculty.
I also went to some Q&A sessions / office hours run by schools / departments / labs. Some really cool people wrote blog posts and / or Tweets soliciting grad students. These are great.
Sometimes the people you want to work with aren t taking grad students.
Most schools I looked at did not maintain lists of who is taking on grad students starting in the fall, but I think two did. Sometimes I contacted people and got back Sorry, not taking on anyone this year. Try $OtherProfessor. This was actually really helpful! But, it s a downer to learn you re not going to get to work with one of your academic heroes because the timing is wrong.
It s expensive and waivers might not help.
Most applications in the US cost about $100 (USD). In some fields it s recommended you apply to 8-10 schools. That s a lot of money. I think everywhere I applied had a waiver you could apply for, but I generally didn t qualify. Some waivers require you to submit days to weeks ahead of the deadline. Others require that you participate in certain professional organizations, student organizations, or live locally to the school. These might be less useful than you were hoping.
Everyone says your writing sample matters, but only five people will read it.
This is what I was told anyway. I was told that my writing sample (which was 20 pages!) will probably only be read by faculty who are thinking of taking me on as an advisee. Someone else might pick it up and read it out of curiosity. I was told stories about how the right writing sample turned eh, maybe candidates into enthusiastic yeses.
Everyone says letters of recommendation matter and it s extremely frustrating.
My recommenders are all amazing people I have so much respect and admiration for it s wild. They re people I want to be like in my academic career. They also all got their letters in the day they were due. I had a moment where I genuinely thought I was just not going to go to grad school because of how close the deadline was.
I ve been told that a great letter matters a lot, but meh letters don t hold you back as much as it sounds like they will. I ve been told that where a recommender is affiliated matters a lot.
My personal statement radically changed based on school / program.
Two of the schools I applied to had very specific requirements for their personal statements. Other schools wanted me to mostly talk about my research interests. One school had a 350 word personal statement, but a 1,000 word research statement. I wrote a research statement and a personal statement and then used them as the basis for what I submitted to different schools. Each application ended up with something pretty different, and not just because I talked about why each program was exciting to me in different ways.
I also applied to different kinds of programs, and presented myself a differently depending on the program s focus and the faculty. For the more social science heavy programs I emphasized the empirical research I did, while for others I leaned more heavily on my philosophical background and theoretical interests.
Oh, also, I was told to not use contractions. Getting rid of them in all my materials was super tedious.
Diversity Statements are becoming more common.
A few of my schools had diversity statements either required or optional. The purpose of these, I was told, is not to play some sort of marginalization Olympics, but to show that you can talk about diversity (and equity and inclusion, etc) without being offensive. It s just as valid to write about your own disability as the disability of a parent (though, ask their permission first).
Triple check what s required.
I made spreadsheets about what each school required. For example, some people wanted official transcripts, some unofficial. Some places required essays rather than generic personal statements, and I needed to build in enough time to manage that.
Ask your friends to help.
I hate asking for help, but applying for grad school made me shameless. I asked anyone I could to read over materials, proofread, or just talk with me about what I was writing. People picked up on things like you used the word technology five times in this one sentence and it looks real weird.
Some schools have projects where current grad students will even look over materials!
Advent of Code 2021Advent of Code, for those not in the know,
is a yearly Advent calendar (since 2015) of coding puzzles many people
participate in for a plenary of reasons ranging from speed coding to code
golf with stops at learning a new language or practicing already known
ones.
I usually write boring C++, but any language and then some can be used.
There are reports of people implementing it in hardware, solving them by
hand on paper or using Microsoft Excel
so, after solving a puzzle the easy way yesterday, this time
I thought: CHALLENGE ACCEPTED! as I somehow remembered an old 2008
article about solving Sudoku with aptitude
(Daniel Burrows via archive.org as the blog is long gone)
and the good same old a package management system that can solve [puzzles] based on package dependency rules is not something that I think would be useful or worth having (Russell Coker).
Day 8 has a rather lengthy
problem description and can reasonably be approached in a bunch of
different way. One unreasonable approach might be to massage the
problem description into Debian packages and let apt help me solve the
problem (specifically Part 2, which you unlock by solving Part 1. You
can do that now, I will wait here.)
Be warned: I am spoiling Part 2 in the following, so solve it yourself
first if you are interested.
I will try to be reasonable consistent in naming things in the following
and so have chosen: The input we get are lines like acedgfb cdfbe gcdfa fbcad dab cefabd cdfgeb eafb cagedb ab cdfeb fcadb cdfeb cdbaf.
The letters are wires mixed up and connected to the segments of the
displays: A group of these letters is hence a digit (the first 10)
which represent one of the digits 0 to 9 and (after the pipe) the four
displays which match (after sorting) one of the digits which means
this display shows this digit. We are interested in which digits are
displayed to solve the puzzle. To help us we also know which segments
form which digit, we just don't know the wiring in the back.
So we should identify which wire maps to which segment!
We are introducing the packages wire-X-connects-to-Y for this which
each provide & conflict1 with the virtual packages segment-Y and
wire-X-connects.
The later ensures that for a given wire we can only pick one segment and
the former ensures that not multiple wires map onto the same segment.
As an example: wire a's possible association with segment b is
described as:
Note that we do not know if this is true! We generate packages for
all possible (and then some) combinations and hope dependency resolution
will solve the problem for us. So don't worry, the hard part will be
done by apt, we just have to provide all (im)possibilities!
What we need now is to translate the 10 digits (and 4 outputs) from
something like acedgfb into digit-0-is-eight and not, say
digit-0-is-one. A clever solution might realize that a one consists
only of two segments so a digit wiring up seven segments can not be
a 1 (and must be 8 instead), but again we aren't here to be clever:
We want apt to figure that out for us! So what we do is simply making
every digit-0-is-N (im)possible choice available as a package and
apply constraints: A given digit-N can only display one number and
each N is unique as digit so for both we deploy Provides
& Conflicts again.
We also need to reason about the segments in the digits: Each of the
digit packages gets Depends on wire-X-connects-to-Y where X is each
possible wire (e.g. acedgfb) and Y each segment forming the digit
(e.g. cf for one). The different choices for X are or'ed together,
so that either of them satisfies the Y.
We know something else too through: The segments which are not used by
the digit can not be wired to any of the Xs. We model this with
Conflicts on wire-X-connects-to-Y.
As an example: If digit-0s acedgfb would be displaying a one
(remember, it can't) the following package would be installable:
Repeat such stanzas for all 10 possible digits for digit-0 and then
repeat this for all the other nine digit-N. We produce pretty much the
same stanzas for display-0(-is-one), just that we omit the second
Provides & Conflicts from above (digit-is-one) as in the display
digits can be repeated. The rest is the same (modulo using display
instead of digit as name of course).
Lastly we create a package dubbed solution which depends on all 10
digit-N and 4 display-N all of them virtual packages apt will have
to choose an installable provider from and we are nearly done!
The resulting Packages file2 we can give to apt while requesting to
install the package solution and it will spit out not only the display
values we are interested in but also which number each digit represents
and which wire is connected to which segment. Nifty!
$ ./skip-aoc 'acedgfb cdfbe gcdfa fbcad dab cefabd cdfgeb eafb cagedb ab   cdfeb fcadb cdfeb cdbaf'
[ ]
The following additional packages will be installed:
  digit-0-is-eight digit-1-is-five digit-2-is-two digit-3-is-three
  digit-4-is-seven digit-5-is-nine digit-6-is-six digit-7-is-four
  digit-8-is-zero digit-9-is-one display-1-is-five display-2-is-three
  display-3-is-five display-4-is-three wire-a-connects-to-c
  wire-b-connects-to-f wire-c-connects-to-g wire-d-connects-to-a
  wire-e-connects-to-b wire-f-connects-to-d wire-g-connects-to-e
[ ]
0 upgraded, 22 newly installed, 0 to remove and 0 not upgraded.
We are only interested in the numbers on the display through, so grepping
the apt output (-V is our friend here) a bit should let us end up with
what we need as calculating3 is (unsurprisingly) not a strong suit of
our package relationship language so we need a few shell commands to
help us with the rest.
$ ./skip-aoc 'acedgfb cdfbe gcdfa fbcad dab cefabd cdfgeb eafb cagedb ab   cdfeb fcadb cdfeb cdbaf' -qq
5353
I have written the skip-aoc script as a testcase for apt,
so to run it you need to place it in
/path/to/source/of/apt/test/integration and built apt first, but that
is only due to my laziness. We could write a standalone script
interfacing with the system installed apt directly and in any apt
version since
~2011.
To hand in the solution for the puzzle we just need to run this on each
line of the input (~200 lines) and add all numbers together. In other
words: Behold this beautiful shell one-liner:
parallel -I ' ' ./skip-aoc ' ' -qq < input.txt paste -s -d'+' - bc
(You may want to run parallel with -P to properly grill your CPU as
that process can take a while otherwise and it still does anyhow as
I haven't optimized it at all the testing framework does a lot of
pointless things wasting time here, but we aren't aiming for the
leaderboard so )
That might or even likely will fail through as I have so far omitted a
not unimportant detail: The default APT resolver is not able to solve
this puzzle with the given problem description we need another solver!
Thankfully that is as easy as installing apt-cudf (and with it aspcud)
which the script is using via --solver aspcud to make apt hand over the
puzzle to a "proper" solver (or better: A solver who is supposed to be
good at "answering set" questions). The buildds are using this for
experimental and/or backports builds and also for installability checks
via dose3 btw, so you might have encountered it before.
Be careful however: Just because aspcud can solve this puzzle doesn't
mean it is a good default resolver for your day to day apt. One of the
reasons the default resolver has such a hard time solving this here is
that or-groups have usually an order in which the first is preferred over
every later option and so fort. This is of no concern here as all these
alternatives will collapse to a single solution anyhow, but if there are
multiple viable solutions (which is often the case) picking the "wrong"
alternative can have bad consequences. A classic example would be
exim4 postfix nullmailer. They are all MTAs
but behave very different. The non-default solvers also tend to lack
certain features like keeping track of auto-installed packages or
installing Recommends/Suggests. That said, Julian is working on
another solver
as I write this which might deal with more of these issues.
And lastly: I am also relatively sure that with a bit of massaging the
default resolver could be made to understand the problem, but I can't
play all day with this maybe some other day.
Disclaimer: Originally posted in the daily megathread
on reddit, the version here is just slightly better understandable as
I have hopefully renamed all the packages to have more conventional
names and tried to explain what I am actually doing.
No cows were harmed in this improved version, either.
If you would upload those packages somewhere, it would be good
style to add Replaces as well, but it is of minor concern for apt
so I am leaving them out here for readability.
We have generated 49 wires, 100 digits, 40 display and 1 solution
package for a grant total of 190 packages. We are also making use of
a few purely virtual ones, but that doesn't add up to many packages
in total. So few packages are practically childs play for apt given it
usually deals with thousand times more. The instability for those
packages tends to be a lot better through as only 22 of 190 packages
we generated can (and will) be installed. Britney will hate you if
your uploads to Debian unstable are even remotely as bad as this.
What we could do is introduce 10.000 packages which denote every
possible display value from 0000 to 9999. We would then need to
duplicate our 10.190 packages for each line (namespace them) and then
add a bit more than a million packages with the correct dependencies
for summing up the individual packages for apt to be able to display
the final result all by itself. That would take a while through as at
that point we are looking at working with ~22 million packages with
a gazillion amount of dependencies probably overworking every solver
we would throw at it a bit of shell glue seems the better option for
now.
This article was written by David Kalnischkies on apt-get a life and republished here by pulling it from a syndication feed. You should check there for updates and more articles about apt and EDSP.
Hello Everyone!
I am Abiola Ajadi from Lagos, Nigeria. I have my B.sc in computer science from the University of Ilorin where I was involved in various community building and also a student leader.
In my free time, I love watching anime, reading comics also surfing the net. I enjoy learning about different cultures and will love to travel the world soon!
Concerning pets, I love dogs(they are so cute!!)
My core values
I will use the 3Cs to describe my core values, which stands for Curiosity, Compassion and Community.
Curiosity: Being curious builds the thirst and interest for knowlegde and how things work. I believe being curious helps us as individuals be vigilant and gain knowledge.
Compassion: This is one of my core values because i love to support people the way i can, especially in technology which is why community will be the third C. the role of community is very important i enjoy being with people who share the same goals and mindset with me.
Why I applied to Outreachy.
I have been curious about open source and how to get started. I wasn t sure of the right way to start so i made some research and spoke to a friend who introduced me to outreachy as a good place to start. I submitted my initial application and made it to the contribution stage. It was exciting to see my first merged contribution to open source. I look forward to an exciting internship with the Debian community and Outreachy!
One might think, this blog is exclusively about weirdlanguage behavior and yelling at computers Well, welcome to another episode of Jackass!
Today's opponent is Ruby, or maybe minitest , or maybe Mocha. I'm not exactly sure, but it was a rather amusing exercise and I like to share my nightmares ;)
It all started with the classical "you're using old and unmaintained software, please switch to something new".
The first attempt was to switch from the ci_reporter_minitest plugin to the minitest-ci plugin. While the change worked great for Foreman itself, it broke the reporting in Katello - the tests would run but no junit.xml was generated and Jenkins rightfully complained that it got no test results.
While investigating what the hell was wrong, we realized that Katello was already using a minitest reporting plugin: minitest-reporters. Loading two different reporting plugins seemed like a good source for problems, so I tried using the same plugin for Foreman too.
Guess what? After a bit of massaging (mostly to disable the second minitest-reporters initialization in Katello) reporting of test results from Katello started to work like a charm. But now the Foreman tests started to fail. Not fail to report, fail to actually run. WTH
The failure was quite interesting too:
test/unit/parameter_filter_test.rb:5:in  block in <class:ParameterFilterTest>':
  Mocha methods cannot be used outside the context of a test (Mocha::NotInitializedError)
Yes, this is a single test file failing, all others were fine.
The failing code doesn't look problematic on first glance:
The failing line (5) is mock('Example').tap and for some reason Mocha thinks it's not initialized here.
This certainly has something to do with how the various reporting plugins inject themselves, but I really didn't want to debug how to run two reporting plugins in parallel (which, as you remember, didn't expose this behavior). So the only real path forward was to debug what's happening here.
Calling the test on its own, with one of the working reporter was the first step:
Wait, what? #<Mocha::Mock: >? Shouldn't this read more like ParameterFilterTest:: as it happens for every single other test in our test suite? It definitely should! That's actually great, as it tells us that there is really something wrong with the test and the change of the reporting plugin just makes it worse.
What comes next is sheer luck. Well, that, and years of experience in yelling at computers.
We use let(:klass) to define an object called klass and this object is a Mocha::Mock that we'll use in our tests later. Now klass is a very common term in Ruby when talking about classes and needing to store them mostly because one can't use class which is a keyword. Is something else in the stack using klass and our let is overriding that, making this whole thing explode?
It was! The moment we replaced klass with klass1 (silly, I know, but there also was a klass2 in that code, so it did fit), things started to work nicely.
I really liked Tomer's comment in the PR: "no idea why, but I am not going to dig into mocha to figure that out."
Turns out, I couldn't let (HAH!) the code rest and really wanted to understand what happened there.
What I didn't want to do is to debug the whole Foreman test stack, because it is massive.
So I started to write a minimal reproducer for the issue.
All starts with a Gemfile, as we need a few dependencies:
And a test! I took the liberty to replace ActiveSupport::TestCase with Minitest::Test, as the test won't be using any Rails features and I wanted to keep my environment minimal.
Wait, I didn't change anything and it's already failing?! Fuck! I mean, cool!
But the test isn't minimal yet. What can we reduce? let is just a fancy, lazy def, right? So instead of let(:klass) we should be able to write def class and achieve a similar outcome and drop that Minitest::Spec.
$ bundle exec rake testTESTOPTS=-v
/home/evgeni/Devel/minitest-wtf/test/parameter_filter_test.rb:5:in klass': Mocha methods cannot be used outside the context of a test (Mocha::NotInitializedError) from /home/evgeni/Devel/minitest-wtf/vendor/bundle/ruby/3.0.0/gems/railties-6.1.4.1/lib/rails/test_unit/reporter.rb:68:in format_line' from /home/evgeni/Devel/minitest-wtf/vendor/bundle/ruby/3.0.0/gems/railties-6.1.4.1/lib/rails/test_unit/reporter.rb:15:in record' from /home/evgeni/Devel/minitest-wtf/vendor/bundle/ruby/3.0.0/gems/minitest-5.10.3/lib/minitest.rb:682:in block in record' from /home/evgeni/Devel/minitest-wtf/vendor/bundle/ruby/3.0.0/gems/minitest-5.10.3/lib/minitest.rb:681:in each' from /home/evgeni/Devel/minitest-wtf/vendor/bundle/ruby/3.0.0/gems/minitest-5.10.3/lib/minitest.rb:681:in record' from /home/evgeni/Devel/minitest-wtf/vendor/bundle/ruby/3.0.0/gems/minitest-5.10.3/lib/minitest.rb:324:in run_one_method' from /home/evgeni/Devel/minitest-wtf/vendor/bundle/ruby/3.0.0/gems/minitest-5.10.3/lib/minitest.rb:311:in block (2 levels) in run' from /home/evgeni/Devel/minitest-wtf/vendor/bundle/ruby/3.0.0/gems/minitest-5.10.3/lib/minitest.rb:310:in each' from /home/evgeni/Devel/minitest-wtf/vendor/bundle/ruby/3.0.0/gems/minitest-5.10.3/lib/minitest.rb:310:in block in run' from /home/evgeni/Devel/minitest-wtf/vendor/bundle/ruby/3.0.0/gems/minitest-5.10.3/lib/minitest.rb:350:in on_signal' from /home/evgeni/Devel/minitest-wtf/vendor/bundle/ruby/3.0.0/gems/minitest-5.10.3/lib/minitest.rb:337:in with_info_handler' from /home/evgeni/Devel/minitest-wtf/vendor/bundle/ruby/3.0.0/gems/minitest-5.10.3/lib/minitest.rb:309:in run' from /home/evgeni/Devel/minitest-wtf/vendor/bundle/ruby/3.0.0/gems/minitest-5.10.3/lib/minitest.rb:159:in block in __run' from /home/evgeni/Devel/minitest-wtf/vendor/bundle/ruby/3.0.0/gems/minitest-5.10.3/lib/minitest.rb:159:in map' from /home/evgeni/Devel/minitest-wtf/vendor/bundle/ruby/3.0.0/gems/minitest-5.10.3/lib/minitest.rb:159:in __run' from /home/evgeni/Devel/minitest-wtf/vendor/bundle/ruby/3.0.0/gems/minitest-5.10.3/lib/minitest.rb:136:in run' from /home/evgeni/Devel/minitest-wtf/vendor/bundle/ruby/3.0.0/gems/minitest-5.10.3/lib/minitest.rb:63:in block in autorun'rake aborted!
Oh nice, this is even better! Instead of the mangled class name, we now get the very same error the Foreman tests aborted with, plus a nice stack trace! But wait, why is it pointing at railties? We're not loading that! Anyways, lets look at railties-6.1.4.1/lib/rails/test_unit/reporter.rb, line 68
defformat_line(result)klass=result.respond_to?(:klass)?result.klass:result.class"%s#%s = %.2f s = %s"%[klass,result.name,result.time,result.result_code]end
Heh, this is touching result.klass, which we just messed up. Nice!
But quickly back to railties What if we only add that to the Gemfile, not full blown Rails?
Yepp, same failure. Also happens with require => false added to the line, so it seems railties somehow injects itself into rake even if nothing is using it?! "Cool"!
By the way, why are we still pinning minitest to < 5.11? Oh right, this was the original reason to look into that whole topic. And, uh, it's pointing at klass there already! 4 years ago!
So lets remove that boundary and funny enough, now tests are passing again, even if we use klass!
Minitest 5.11 changed how Minitest::Test is structured, and seems not to rely on klass at that point anymore. And I guess Rails also changed a bit since the original pin was put in place four years ago.
I didn't want to go another rabbit hole, finding out what changed in Rails, but I did try with 5.0 (well, 5.0.7.2) to be precise, and the output with newer (>= 5.11) Minitest was interesting:
It's leaking Minitest::Result as klass now, instead of Mocha::Mock. So probably something along these lines was broken 4 years ago and triggered this pin.
What do we learn from that?
klass is cursed and shouldn't be used in places where inheritance and tooling might decide to use it for some reason
inheritance is cursed - why the heck are implementation details of Minitest leaking inside my tests?!
tooling is cursed - why is railties injecting stuff when I didn't ask it to?!
dependency pinning is cursed - at least if you pin to avoid an issue and then forget about said issue for four years
After last year's blunder with trying to hide the Adobe toolchain and using hilarious stock photos, the Linux Foundation did much better in their 2021 annual report1 published Dec. 6, 2021.
Still they are using the Adobe toolchain (InDesign, Acrobat PDF) and my fellow DebianKernel2 Developer Geert was quick to point that out as the first comment to the LWN note on the publication:
I think it is important to call the Linux Foundation (LF) out again and again. Adobe is a Silver member of the LF and they can motivate them to publish their applications for Linux. And if that is not an option, there are Free alternatives like Scribus that could well use the exposure and funds of LF to help catch up to the market leading product, Adobe InDesign.
Personally, as a photographer, I am very happy they used stock images from Unsplash to illustrate the 2021 edition over the cringeworthy Shutterstock footage from last year's report.
And they gave proper credit:
Now for next year ... find an editor that knows how to spell photographers, please. And consider Scribus. And make Adobe publish their apps for Linux. Thank you.
Update 07.12.2021 22:00 CET: I had to replace the link to the Linux Foundation 2021 annual report with an archive.org one as they updated the report to fix the typo as per the comment from Melissa Schmidt below. Stable URLs are not a thing, apparently. You can find their new report at https://www.linuxfoundation.org/wp-content/uploads/2021_LF_Annual_Report_120721c.pdf. Unless somebody points out more typos. There is a Last-Modified Header in HTTP 1.1. Wordpress, Varnish and Nginx, serving the LF website, all support that.
08.12.2021: Geert Uytterhoeven wrote in that he is "geert" on LWN, both are very nice Geert's but different Geert's :-)
Last week I attended the UK Systems Research
2021 conference in County Durham, my first
conference in nearly two years (since FOSDEM 2020,
right on the cusp of the Pandemic). The Systems conference community
is very pleasant and welcoming and so when I heard it was going to
take place "physically" again this year I was so keen to attend I
decided to hedge my bets and submit two talk proposals. I wasn't
expecting them both to be accepted
As well as the regular talks (more on those in another post) there is
a tradition for people to give short, impromptu lightning talks after
dinner on the second night. I've given two of these before, and I'd
been considering whether to offer to one this time or not, but with
two talks to deliver (and finish writing) I wasn't sure. Usually
people talk about something interesting that they have been doing
besides their research or day-jobs, but the last two years have been
somewhat difficult and I didn't really think I had a topic to talk
about. Then I wondered if that was a topic in itself
During the first day of the conference (and especially one I'd got
past one of my talks) I started to outline a lightning talk idea and
it seemed to come out well enough that I thought I'd give it a go.
Unusually I therefore had something written down and I was surprised
how well it was received, so I thought I'd share it. Here it is:
I was anticipating the lightning talks and being cajoled into talking
about something. I've done it twice before. So I've been racking my
brains to figure out if I've done anything interesting enough to talk
about.
in 2018 I talked about some hack I'd made to the classic computer game
Doom from 1993. I've done several hacks to Doom that I could probably
talk about except I've become a bit uncomfortable about increasingly
being thought of as "that doom guy". I'd been reflecting on why it was
that I continued to mess about with that game in the first place and I
realised it was a form of expression: I was treating Doom like a canvas.
I've spent most of my career thinking about what I do in the frame of
either science or engineering. I suffer from the creative urge and I've
often expressed (and sated) that through my work. And that's possible
because there's a craft in what we do.
In 2019 I talked about a project I'd embarked on to resurrect my
childhood computer, a Commodore Amiga 500, in order to rescue my
childhood drawings and digital paintings. (There's the artistic thing
again). I'd achieved that and I have ambitions to do some more Amiga
stuff but again that's a work in progress and there's nothing much to
talk about.
In recent years I've been thinking more and more about art and became
interested in the works and writings of people like Grayson Perry,
Laurie Anderson and Brian Eno. I first learned about Eno through his
music but he's also a visual artist. and a music producer. As a producer
in the 70s he co-invented a system to try and break out of writer's
block called "oblique strategies": A deck of cards with oblique
suggestions written on them. When you're stuck, you pull a card and it
might help you to reframe what you are working on and think about it in
a completely different way.
I love this idea and I think we should use more things like that in
software engineering at least.
So back to casting about for something to talk about. What have I been
doing in the last couple of years? Frankly, surviving - I've just about
managed to keep doing my day job, and keep working on the PhD, at home
with two young kids and home schooling and the rest of it. Which is an
achievement but makes for a boring lightning talk. But I'd like to say
that for anyone here who might have been worrying similarly: I think
surviving is more than enough.
I'll close on the subject of thinking like an artist and not an
engineer. I brought some of the Oblique Strategies deck with me and I
thought I'd draw a card to perhaps help you out of a creative dilemma if
you're in one. And I kid you not, the first card I drew was this one:
On the road to AppStream 1.0, a lot of items from the long todo list have been done so far only one major feature is remaining, external release descriptions, which is a tricky one to implement and specify. For AppStream 1.0 it needs to be present or be rejected though, as it would be a major change in how release data is handled in AppStream.
Besides 1.0 preparation work, the recent 0.15 release and the releases before it come with their very own large set of changes, that are worth a look and may be interesting for your application to support. But first, for a change that affects the implementation and not the XML format:
1. Completely rewritten caching code
Keeping all AppStream data in memory is expensive, especially if the data is huge (as on Debian and Ubuntu with their large repositories generated from desktop-entry files as well) and if processes using AppStream are long-running. The latter is more and more the case, not only does GNOME Software run in the background, KDE uses AppStream in KRunner and Phosh will use it too for reading form factor information. Therefore, AppStream via libappstream provides an on-disk cache that is memory-mapped, so data is only consuming RAM if we are actually doing anything with it.
Previously, AppStream used an LMDB-based cache in the background, with indices for fulltext search and other common search operations. This was a very fast solution, but also came with limitations, LMDB s maximum key size of 511 bytes became a problem quite often, adjusting the maximum database size (since it has to be set at opening time) was annoyingly tricky, and building dedicated indices for each search operation was very inflexible. In addition to that, the caching code was changed multiple times in the past to allow system-wide metadata to be cached per-user, as some distributions didn t (want to) build a system-wide cache and therefore ran into performance issues when XML was parsed repeatedly for generation of a temporary cache. In addition to all that, the cache was designed around the concept of one cache for data from all sources , which meant that we had to rebuild it entirely if just a small aspect changed, like a MetaInfo file being added to /usr/share/metainfo, which was very inefficient.
To shorten a long story, the old caching code was rewritten with the new concepts of caches not necessarily being system-wide and caches existing for more fine-grained groups of files in mind. The new caching code uses Richard Hughes excellent libxmlb internally for memory-mapped data storage. Unlike LMDB, libxmlb knows about the XML document model, so queries can be much more powerful and we do not need to build indices manually. The library is also already used by GNOME Software and fwupd for parsing of (refined) AppStream metadata, so it works quite well for that usecase. As a result, search queries via libappstream are now a bit slower (very much depends on the query, roughly 20% on average), but can be mmuch more powerful. The caching code is a lot more robust, which should speed up startup time of applications. And in addition to all of that, the AsPool class has gained a flag to allow it to monitor AppStream source data for changes and refresh the cache fully automatically and transparently in the background.
All software written against the previous version of the libappstream library should continue to work with the new caching code, but to make use of some of the new features, software using it may need adjustments. A lot of methods have been deprecated too now.
2. Experimental compose support
Compiling MetaInfo and other metadata into AppStream collection metadata, extracting icons, language information, refining data and caching media is an involved process. The appstream-generator tool does this very well for data from Linux distribution sources, but the tool is also pretty heavyweight with lots of knobs to adjust, an underlying database and a complex algorithm for icon extraction. Embedding it into other tools via anything else but its command-line API is also not easy (due to D s GC initialization, and because it was never written with that feature in mind). Sometimes a simpler tool is all you need, so the libappstream-compose library as well as appstreamcli compose are being developed at the moment. The library contains building blocks for developing a tool like appstream-generator while the cli tool allows to simply extract metadata from any directory tree, which can be used by e.g. Flatpak. For this to work well, a lot of appstream-generator s D code is translated into plain C, so the implementation stays identical but the language changes.
Ultimately, the generator tool will use libappstream-compose for any general data refinement, and only implement things necessary to extract data from the archive of distributions. New applications (e.g. for new bundling systems and other purposes) can then use the same building blocks to implement new data generators similar to appstream-generator with ease, sharing much of the code that would be identical between implementations anyway.
2. Supporting user input controls
Want to advertise that your application supports touch input? Keyboard input? Has support for graphics tablets? Gamepads? Sure, nothing is easier than that with the new control relation item and supports relation kind (since 0.12.11 / 0.15.0, details):
3. Defining minimum display size requirements
Some applications are unusable below a certain window size, so you do not want to display them in a software center that is running on a device with a small screen, like a phone. In order to encode this information in a flexible way, AppStream now contains a display_length relation item to require or recommend a minimum (or maximum) display size that the described GUI application can work with. For example:
This will make the application require a display length greater or equal to 300 logical pixels. A logical pixel (also device independent pixel) is the amount of pixels that the application can draw in one direction. Since screens, especially phone screens but also screens on a desktop, can be rotated, the display_length value will be checked against the longest edge of a display by default (by explicitly specifying the shorter edge, this can be changed).
This feature is available since 0.13.0, details. See also Tobias Bernard s blog entry on this topic.
4. Tags
This is a feature that was originally requested for the LVFS/fwupd, but one of the great things about AppStream is that we can take very project-specific ideas and generalize them so something comes out of them that is useful for many. The new tags tag allows people to tag components with an arbitrary namespaced string. This can be useful for project-internal organization of applications, as well as to convey certain additional properties to a software center, e.g. an application could mark itself as featured in a specific software center only. Metadata generators may also add their own tags to components to improve organization. AppStream gives no recommendations as to how these tags are to be interpreted except for them being a strictly optional feature. So any meaning is something clients and metadata authors need to negotiate. It therefore is a more specialized usecase of the already existing custom tag, and I expect it to be primarily useful within larger organizations that produce a lot of software components that need sorting. For example:
This feature is available since 0.15.0, details.
5. MetaInfo Creator changes
The MetaInfo Creator (source) tool is a very simple web application that provides you with a form to fill out and will then generate MetaInfo XML to add to your project after you have answered all of its questions. It is an easy way for developers to add the required metadata without having to read the specification or any guides at all.
Recently, I added support for the new control and display_length tags, resolved a few minor issues and also added a button to instantly copy the generated output to clipboard so people can paste it into their project. If you want to create a new MetaInfo file, this tool is the best way to do it!
The creator tool will also not transfer any data out of your webbrowser, it is strictly a client-side application.
And that is about it for the most notable changes in AppStream land! Of course there is a lot more, additional tags for the LVFS and content rating have been added, lots of bugs have been squashed, the documentation has been refined a lot and the library has gained a lot of new API to make building software centers easier. Still, there is a lot to do and quite a few open feature requests too. Onwards to 1.0!
This post is part of a series called "PACKRAT". If this is the first post
you've found, it'd be worth reading the
intro post first and then looking over
all posts in the series.
In the last post, we left off at being able to send and recieve PACKRAT frames
to and from devices. Since we can transport IPv4 packets over the network,
let s go ahead and see if we can read/write
Ethernet frames from a Linux network
interface, and on the backend, read and write PACKRAT frames over the air.
This has the benifit of continuing to allow Linux userspace tools to work (like
cURL, as we ll try!), which means we don t have to do a lot of work to
implement higher level protocols or tactics to get a connection established
over the link.
Given that this post is less RF and more Linuxy, I m going to include more code
snippits than in prior posts, and those snippits are closer to runable Go, but
still not complete examples. There s also a lot of different ways to do this,
I ve just picked the easiest one for me to implement and debug given my
existing tooling for you, you may find another approach easier to implement!
Again, deviation here is very welcome, and since this segment is the least
RF centric post in the series, the pace and tone is going to feel different.
If you feel lost here, that s OK. This isn t the most important part of
the series, and is mostly here to give a concrete ending to the story arc.
Any way you want to finish your own journy is the best way for you to finish
it!
Implement Ethernet conversion code
This assumes an importable package with a Frame struct, which we can use to
convert a Frame to/from Ethernet. Given that the PACKRAT frame has a field that
Ethernet doesn t (namely, Callsign), that will need to be explicitly passed
in when turning an Ethernet frame into a PACKRAT Frame.
...// ToPackrat will create a packrat frame from an Ethernet frame.
funcToPackrat(callsign [8]byte, frame*ethernet.Frame) (*packrat.Frame, error)
varframeTypepackrat.FrameTypeswitchframe.EtherTypecaseethernet.EtherTypeIPv4:
frameType = packrat.FrameTypeIPv4default:
returnnil, fmt.Errorf("ethernet: unsupported ethernet type %x", frame.EtherType)
return&packrat.FrameDestination: frame.Destination,
Source: frame.Source,
Type: frameType,
Callsign: callsign,
Payload: frame.Payload,
, nil// FromPackrat will create an Ethernet frame from a Packrat frame.
funcFromPackrat(frame*packrat.Frame) (*ethernet.Frame, error)
varetherTypeethernet.EtherTypeswitchframe.Typecasepackrat.FrameTypeRaw:
returnnil, fmt.Errorf("ethernet: unsupported packrat type 'raw'")
casepackrat.FrameTypeIPv4:
etherType = ethernet.EtherTypeIPv4default:
returnnil, fmt.Errorf("ethernet: unknown packrat type %x", frame.Type)
// We lose the Callsign here, which is sad.
returnðernet.FrameDestination: frame.Destination,
Source: frame.Source,
EtherType: etherType,
Payload: frame.Payload,
, nil
Our helpers, ToPackrat and FromPackrat can now be used to transmorgify
PACKRAT into Ethernet, or Ethernet into PACKRAT. Let s put them into use!
Implement a TAP interface
On Linux, the networking stack can be exposed to userland using TUN or
TAP interfaces. TUN devices allow a
userspace program to read and write data at the Layer 3 / IP layer. TAP devices
allow a userspace program to read and write data at the Layer 2 Data Link /
Ethernet layer. Writing data at Layer 2 is what we want to do, since we re
looking to transform our Layer 2 into Ethernet s Layer 2 Frames. Our first job
here is to create the actual TAP interface, set the MAC address, and set the IP
range to our pre-coordinated IP range.
...import (
"net""github.com/mdlayher/ethernet""github.com/songgao/water""github.com/vishvananda/netlink"
)
...config:=water.ConfigDeviceType: water.TAPconfig.Name = "rat0"iface, err:=water.New(config)
...netIface, err:=netlink.LinkByName("rat0")
...// Pick a range here that works for you!
//
// For my local network, I'm using some IPs
// that AMPR (ampr.org) was nice enough to
// allocate to me for ham radio use. Thanks,
// AMPR!
//
// Let's just use 10.* here, though.
//
ip, cidr, err:=net.ParseCIDR("10.0.0.1/24")
...cidr.IP = iperr = netlink.AddrAdd(netIface, &netlink.AddrIPNet: cidr,
Peer: cidr,
)
...// Add all our neighbors to the ARP table
for_, neighbor:=rangeneighborsnetlink.NeighAdd(&netlink.NeighLinkIndex: netIface.Attrs().Index,
Type: netlink.FAMILY_V4,
State: netlink.NUD_PERMANENT,
IP: neighbor.IP,
HardwareAddr: neighbor.MAC,
)
// Pick a MAC that is globally unique here, this is
// just used as an example!
addr, err:=net.ParseMAC("FA:DE:DC:AB:LE:01")
...netlink.LinkSetHardwareAddr(netIface, addr)
...err = netlink.LinkSetUp(netIface)
varframe = ðernet.Framevarbuf = make([]byte, 1500)
forn, err:=iface.Read(buf)
...err = frame.UnmarshalBinary(buf[:n])
...// process frame here (to come)
...
Now that our network stack can resolve an IP to a MAC Address (via ip neigh
according to our pre-defined neighbors), and send that IP packet to our daemon,
it s now on us to send IPv4 data over the airwaves. Here, we re going to take
packets coming in from our TAP interface, and marshal the Ethernet frame into a
PACKRAT Frame and transmit it. As with the rest of the RF code, we ll leave
that up to the implementer, of course, using what was built during Part 2:
Transmitting BPSK symbols and Part 4: Framing
data.
...for// continued from above
n, err:=iface.Read(buf)
...err = frame.UnmarshalBinary(buf[:n])
...switchframe.EtherTypecase0x0800:
// ipv4 packet
pack, err:=ToPackrat(
// Add my callsign to all Frames, for now
[8]byte'K', '3', 'X', 'E', 'C' ,
frame,
)
...err = transmitPacket(pack)
......
Now that we have transmitting covered, let s go ahead and handle the recieve
path here. We re going to listen on frequency using the code built in
Part 3: Receiving BPSK symbols and
Part 4: Framing data. The Frames we decode from
the airwaves are expected to come back from the call
packratReader.Next in the code below, and the exact way that works
is up to the implementer.
...for// pull the next packrat frame from
// the symbol stream as we did in the
// last post
packet, err:=packratReader.Next()
...// check for CRC errors and drop invalid
// packets
err = packet.Check()
...ifbytes.Equal(packet.Source, addr)
// if we've heard ourself transmitting
// let's avoid looping back
continue// create an ethernet frame
frame, err:=FromPackrat(packet)
...buf, err:=frame.MarshalBinary()
...// and inject it into the tap
err = iface.Write(buf)
......
Phew. Right. Now we should be able to listen for PACKRAT frames on the
air and inject them into our TAP interface.
Putting it all Together
After all this work weeks of work! we can finally get around to putting
some real packets over the air. For me, this was an incredibly satisfying
milestone, and tied together months of learning!
I was able to start up a UDP server on a remote machine with an RTL-SDR dongle
attached to it, listening on the TAP interface s host IP with my defined MAC
address, and send UDP packets to that server via PACKRAT using my laptop,
/dev/udp and an Ettus B210, sending packets into the TAP interface.
Now that UDP was working, I was able to get TCP to work using two PlutoSDRs,
which allowed me to run the cURL command I pasted in the first post (both
simultaneously listen and transmit on behalf of my TAP interface).
It s my hope that someone out there will be inspired to implement their own
Layer 1 and Layer 2 as a learning exercise, and gets the same sense of
gratification that I did! If you re reading this, and at a point
where you ve been able to send IP traffic over your own Layer 1 / Layer 2,
please get in touch! I d be thrilled to hear all about it. I d love to link
to any posts or examples you publish here!
Welcome to the November 2021 report from the Reproducible Builds project.
As a quick recap, whilst anyone may inspect the source code of free software for malicious flaws, almost all software is distributed to end users as pre-compiled binaries. The motivation behind the reproducible builds effort is therefore to ensure no flaws have been introduced during this compilation process by promising identical results are always generated from a given source, thus allowing multiple third-parties to come to a consensus on whether a build was compromised. If you are interested in contributing to our project, please visit our Contribute page on our website.
On November 6th, Vagrant Cascadian presented at this year s edition of the SeaGL conference, giving a talk titled Debugging Reproducible Builds One Day at a Time:
I ll explore how I go about identifying issues to work on, learn more about the specific issues, recreate the problem locally, isolate the potential causes, dissect the problem into identifiable parts, and adapt the packaging and/or source code to fix the issues.
In the role of a packager, updating packages is a recurring task. For some projects, a packager is involved in upstream maintenance, or well written release notes make it easy to figure out what changed between the releases. This isn t always the case, for instance with some small project maintained by one or two people somewhere on GitHub, and it can be useful to verify what exactly changed. Diffoscope can help determine the changes between package releases. []
diffoscopediffoscope is our in-depth and content-aware diff utility. Not only can it locate and diagnose reproducibility issues, it can provide human-readable diffs from many kinds of binary formats. This month, Chris Lamb made the following changes, including preparing and uploading versions 190, 191, 192, 193 and 194 to Debian:
New features:
Continue loading a .changes file even if the referenced files do not exist, but include a comment in the returned diff. []
Log the reason if we cannot load a Debian .changes file. []
Bug fixes:
Detect XML files as XML files if file(1) claims if they are XML files or if they are named .xml. (#999438)
Don t duplicate file lists at each directory level. (#989192)
Don t raise a traceback when comparing nested directories with non-directories. []
Re-enable test_android_manifest. []
Don t reject Debian .changes files if they contain non-printable characters. []
Codebase improvements:
Avoid aliasing variables if we aren t going to use them. []
Use isinstance over type. []
Drop a number of unused imports. []
Update a bunch of %-style string interpolations into f-strings or str.format. []
When pretty-printing JSON, mark the difference as being reformatted, additionally avoiding including the full path. []
Import itertools top-level module directly. []
Chris Lamb also made an update to the command-line client to trydiffoscope, a web-based version of the diffoscope in-depth and content-aware diff utility, specifically only waiting for 2 minutes for try.diffoscope.org to respond in tests. (#998360)
In addition Brandon Maier corrected an issue where parts of large diffs were missing from the output [], Zbigniew J drzejewski-Szmek fixed some logic in the assert_diff_startswith method [] and Mattia Rizzolo updated the packaging metadata to denote that we support both Python 3.9 and 3.10 [] as well as a number of warning-related changes[][]. Vagrant Cascadian also updated the diffoscope package in GNU Guix [][].
Software development
The Reproducible Builds project detects, dissects and attempts to fix as many currently-unreproducible packages as possible. We endeavour to send all of our patches upstream where appropriate. This month, we wrote a large number of such patches, including:
Elsewhere, in software development, Jonas Witschel updated strip-nondeterminism, our tool to remove specific non-deterministic results from a completed build so that it did not fail on JAR archives containing invalid members with a .jar extension []. This change was later uploaded to Debian by Chris Lamb.
reprotest is the Reproducible Build s project end-user tool to build the same source code twice in widely different environments and checking whether the binaries produced by the builds have any differences. This month, Mattia Rizzolo overhauled the Debian packaging [][][] and fixed a bug surrounding suffixes in the Debian package version [], whilst Stefano Rivera fixed an issue where the package tests were broken after the removal of diffoscope from the package s strict dependencies [].
Testing framework
The Reproducible Builds project runs a testing framework at tests.reproducible-builds.org, to check packages and other artifacts for reproducibility. This month, the following changes were made:
Holger Levsen:
Document the progress in setting up snapshot.reproducible-builds.org. []
Extend testing to include Debian bookworm too.. []
Automatically create the Jenkins view to display jobs related to building the Live images. []
Vagrant Cascadian:
Add a Debian package set group for the packages and tools maintained by the Reproducible Builds maintainers themselves. []
If you are interested in contributing to the Reproducible Builds project, please visit our Contribute page on our website. However, you can get in touch with us via:
This post is part of a series called "PACKRAT". If this is the first post
you've found, it'd be worth reading the
intro post first and then looking over
all posts in the series.
In the last post, we we were able to build a functioning
Layer 1 PHY where we can encode symbols to transmit, and receive symbols on the
other end, we re now at the point where we can encode and decode those symbols
as bits and frame blocks of data, marking them with a Sender and a Destination
for routing to the right host(s). This is a Layer 2 scheme in the OSI model,
which is otherwise known as the Data Link
Layer. You re using one to
view this website right now I m willing to bet your data is going
through an Ethernet layer 2 as well as WiFi or maybe a cellular data
protocol like 5G or LTE.
Given that this entire exercise is hard enough without designing a complex
Layer 2 scheme, I opted for simplicity in the hopes this would free me from the
complexity and research that has gone into this field for the last 50 years. I
settled on stealing a few ideas from Ethernet Frames namely, the use of MAC
addresses to identify parties, and
the EtherType field to indicate the Payload type. I also stole the idea of
using a CRC at the end of the Frame to check for corruption, as well as the
specific CRC method (crc32 using 0xedb88320 as the polynomial).
Lastly, I added a callsign field to make life easier on ham radio frequencies
if I was ever to seriously attempt to use a variant of this protocol over the
air with multiple users. However, given this scheme is not a commonly used
scheme, it s best practice to use a nearby radio to identify your transmissions
on the same frequency while testing or use a Faraday box to test without
transmitting over the airwaves. I added the callsign field in an effort to lean
into the spirit of the Part 97 regulations, even if I relied on a phone
emission to identify the Frames.
As an aside, I asked the ARRL for input here, and their stance to me over email
was I d be OK according to the regs if I were to stick to UHF and put my
callsign into the BPSK stream using a widely understood encoding (even with no
knowledge of PACKRAT, the callsign is ASCII over BPSK and should be easily
demodulatable for followup with me). Even with all this, I opted to use FM
phone to transmit my callsign when I was active on the air (specifically, using
an SDR and a small bash script to automate transmission while I watched for
interference or other band users).
Right, back to the Frame:
sync
dest
source
callsign
type
payload
crc
With all that done, I put that layout into a struct, so that we can marshal
and unmarshal bytes to and from our Frame objects, and work with it
in software.
Time to pick some consts
I picked a unique and distinctive sync sequence, which the sender
will transmit before the Frame, while the receiver listens for that
sequence to know when it s in byte alignment with the symbol stream.
My sync sequence is [3]byte 'U', 'f', '~' which works out to be a
very pleasant bit sequence of 01010101 01100110 01111110. It s important
to have soothing preambles for your Frames. We need all the good energy
we can get at this point.
var (
FrameStart = [3]byte'U', 'f', '~'FrameMaxPayloadSize = 1500
)
Next, I defined some FrameType values for the type field,
which I can use to determine what is done with that data next,
something Ethernet was originally missing, but has since grown
to depend on (who needs Length anyway? Not me. See below!)
FrameType
Description
Bytes
Raw
Bytes in the Payload field are opaque and not to be parsed.
[2]byte 0x00, 0x01
IPv4
Bytes in the Payload field are an IPv4 packet.
[2]byte 0x00, 0x02
And finally, I decided on a maximum length of the Payload, and decided on
limiting it to 1500 bytes to align with the MTU of Ethernet.
var (
FrameTypeRaw = FrameType0, 1FrameTypeIPv4 = FrameType0, 2
)
Given we know how we re going to marshal and unmarshal binary data to and from
Frames, we can now move on to looking through the bit stream for our Frames.
Why is there no Length field?
I was initially a bit surprised that Ethernet Frames didn t have a Length field
in use, but the more I thought about it, the more it seemed like a big ole'
failure mode without a good implementation outcome. Either the Length is right
(resulting in no action and used bits on every packet) or the Length is not the
length of the Payload and the driver needs to determine what to do with the
packet does it try and trim the overlong payload and ignore the rest? What
if both the end of the read bytes and the end of the subset of the packet
denoted by Length have a valid CRC? Which is used? Will everyone agree? What
if Length is longer than the Payload but the CRC is good where we detected a
lost carrer?
I decided on simplicity. The end of a Frame is denoted by the loss of the BPSK
carrier when the signal is no longer being transmitted (or more correctly,
when the signal is no longer received), we know we ve hit the end of a packet.
Missing a single symbol will result in the Frame being finalized. This can
cause some degree of corruption, but it s also a lot easier than doing tricks
like bit stuffing to create an end of symbol stream delimiter.
Finding the Frame start in a Symbol Stream
First thing we need to do is find our sync bit pattern in the symbols we re
receiving from our BPSK demodulator. There s some smart ways to do this, but
given that I m not much of a smart man, I again decided to go for simple
instead. Given our incoming vector of symbols (which are still float values)
prepend one at a time to a vector of floats that is the same length as the
sync phrase, and compare against the sync phrase, to determine if we re in
sync with the byte boundary within the symbol stream.
The only trick here is that because we re using BPSK to modulate and demodulate
the data, post phaselock we can be 180 degrees out of alignment (such that a +1
is demodulated as -1, or vice versa). To deal with that, I check against both
the sync phrase as well as the inverse of the sync phrase (both [1, -1, 1] as well as [-1, 1, -1]) where if the inverse sync is matched, all symbols
to follow will be inverted as well. This effectively turns our symbols back
into bits, even if we re flipped out of phase. Other techniques like
NRZI will represent a 0 or
1 by a change in phase state which is great, but can often cascade into long
runs of bit errors, and is generally more complex to implement. That
representation isn t ambiguous, given you look for a phase change, not the
absolute phase value, which is incredibly compelling.
Here s a notional example of how I ve been thinking about the phrase sliding
window and how I ve been thinking of the checks. Each row is a new symbol
taken from the BPSK receiver, and pushed to the head of the sliding window,
moving all symbols back in the vector by one.
Given the pseudocode above, let s step through what the checks would be doing
at each step:
Buffer
Sync
Inverse Sync
[ ]float 0, ,0
[ ]float -1, ,-1
[ ]float 1, ,1
[ ]float 0, ,1
[ ]float -1, ,-1
[ ]float 1, ,1
[more bits in]
[ ]float -1, ,-1
[ ]float 1, ,1
[ ]float 1, ,1
[ ]float -1, ,-1
[ ]float 1, ,1
After this notional set of comparisons, we know that at the last step, we are
now aligned to the frame and byte boundary the next symbol / bit will be the
MSB of the 0th Frame byte. Additionally, we know we re also 180 degrees out of
phase, so we need to flip the symbol s sign to get the bit. From this point on
we can consume 8 bits at a time, and re-assemble the byte stream. I don t know
what this technique is called or even if this is used in real grown-up
implementations, but it s been working for my toy implementation.
Next Steps
Now that we can read/write Frames to and from PACKRAT, the next steps here are
going to be implementing code to encode and decode Ethernet traffic into
PACKRAT, coming next in Part 5!
This post is part of a series called "PACKRAT". If this is the first post
you've found, it'd be worth reading the
intro post first and then looking over
all posts in the series.
In the last post, we worked through how to generate
a BPSK signal, and hopefully transmit it using one of our SDRs.
Let s take that and move on to Receiving BPSK and turning that back
into symbols!
Demodulating BPSK data is a bit more tricky than transmitting BPSK data, mostly
due to tedious facts of life such as space, time, and hardware built with
compromises because not doing that makes the problem impossible. Unfortunately,
it s now our job to work within our imperfect world to recover perfect data. We
need to handle the addition of noise, differences in frequency, clock
synchronization and interference in order to recover our information. This
makes life a lot harder than when we transmit information, and as a result, a
lot more complex.
Coarse Sync
Our starting point for this section will be working from a capture of a number
of generated PACKRAT packets
as heard by a PlutoSDR at (xz compressed interleaved int16, 2,621,440 samples per second)
Every SDR has its own oscillator, which eventually controls a number of
different components of an SDR, such as the IF (if it s a superheterodyne
architecture) and the sampling rate. Drift in oscillators lead to drifts in
frequency such that what one SDR may think is 100MHz may be 100.01MHz for
another radio. Even if the radios were perfectly in sync, other artifacts such
as doppler time dilation due to motion
can cause the frequency to appear higher or lower in frequency than it was
transmitted.
All this is a long way of saying, we need to determine when we see a strong
signal that s close-ish to our tuned frequency, and take steps to roughly
correct it to our center frequency (in the order of 100s of Hz to kHz) in order
to acquire a phase lock on the signal to attempt to decode information contained
within.
The easiest way of detecting the loudest signal of interest is to use an
FFT. Getting into how
FFTs work is out of scope of this post, so if this is the first time you re
seeing mention of an FFT, it may be a good place to take a quick break to learn
a bit about the time domain (which is what the IQ data we ve been working with
so far is), frequency domain, and how the FFT and iFFT operations can convert
between them.
Lastly, because FFTs average power over the window, swapping phases such that
the transmitted wave has the same number of in-phase and inverted-phase symbols
the power would wind up averaging to zero. This is not helpful, so I took a tip
from Dr. Marc Lichtman s PySDR
project
and used complex squaring to drive
our BPSK signal into a single detectable carrier by squaring the IQ data.
Because points are on the unit circle and at tau/2 (specifically, tau/(2^1)
for BPSK, 2^2 for QPSK) angles, and given that squaring has the effect of
doubling the angle, and angles are all mod tau, this will drive our wave
comprised of two opposite phases back into a continuous wave effectively
removing our BPSK modulation, making it much easier to detect in the
frequency domain. Thanks to Tom Bereknyei
for helping me with that!
...variq []complexvarfreq []complexfori:=rangeiqiq[i] = iq[i] *iq[i]
// perform an fft, computing the frequency
// domain vector in freq given the iq data
// contained in iq .
fft(iq, freq)
// get the array index of the max value in the
// freq array given the magnitude value of the
// complex numbers.
varbinIdx = max(abs(freq))
...
Now, most FFT operations will lay the frequency domain data out a bit
differently than you may expect (as a human), which is that the 0th element of
the FFT is 0Hz, not the most negative number (like in a waterfall). Generally
speaking, zero first is the most common frequency domain layout (and
generally speaking the most safe assumption if there s no other documentation
on fft layout). Negative first is usually used when the FFT is being rendered
for human consumption such as a waterfall plot.
Given that we now know which FFT bin (which is to say, which index into the
FFT array) contains the strongest signal, we ll go ahead and figure out what
frequency that bin relates to.
In the time domain, each complex number is the next time instant. In the
frequency domain, each bin is a discrete frequency or more specifically a
frequency range. The bandwidth of the bin is a function of the sampling rate
and number of time domain samples used to do the FFT operation. As you increase
the amount of time used to preform the FFT, the more precise the FFT
measurement of frequency can be, but it will cover the same bandwidth, as
defined by the sampling rate.
...varsampleRate = 2,621,440// bandwidth is the range of frequencies
// contained inside a single FFT bin,
// measured in Hz.
varbandwidth = sampleRate/len(freq)
...
Now that we know we have a zero-first layout and the bin bandwidth,
we can compute what our frequency offset is in Hz.
...// binIdx is the index into the freq slice
// containing the frequency domain data.
varbinIdx = 0// binFreq is the frequency of the bin
// denoted by binIdx
varbinFreq = 0ifbinIdx > len(freq)/2// This branch covers the case where the bin
// is past the middle point - which is to say,
// if this is a negative frequency.
binFreq = bandwidth* (binIdx- len(freq))
else// This branch covers the case where the bin
// is in the first half of the frequency array,
// which is to say - if this frequency is
// a positive frequency.
binFreq = bandwidth*binIdx...
However, sice we squared the IQ data, we re off in frequency by twice the
actual frequency if we are reading 12kHz, the bin is actually 6kHz. We
need to adjust for that before continuing with processing.
...varbinFreq = 0...// [compute the binFreq as above]
...// Adjust for the squaring of our IQ data
binFreq = binFreq/2...
Finally, we need to shift the frequency by the inverse of the binFreq
by generating a carrier wave at a specific frequency and rotating every
sample by our carrier wave so that a wave at the same frequency will
slow down (or stand still!) as it approaches 0Hz relative to the carrier
wave.
vartau = pi*2// ts tracks where in time we are (basically: phase)
vartsfloat// inc is the amount we step forward in time (seconds)
// each sample.
varincfloat = (1/sampleRate)
// amount to shift frequencies, in Hz,
// in this case, shift +12 kHz to 0Hz
varshift = -12,000fori:=rangeiqts+=incifts > tau// not actually needed, but keeps ts within
// 0 to 2*pi (since it is modulus 2*pi anyway)
ts-=tau// Here, we're going to create a carrier wave
// at the provided frequency (in this case,
// -12kHz)
cwIq = complex(cos(tau*shift*ts), sin(tau*shift*ts))
iq[i] = iq[i] *cwIq
Now we ve got the strong signal we ve observed (which may or may not be
our BPSK modulated signal!) close enough to 0Hz that we ought to be able
to Phase Lock the signal in order to begin demodulating the signal.
Filter
After we re roughly in the neighborhood of a few kHz, we can now take some
steps to cut out any high frequency components (both positive high frequencies
and negative high frequencies). The normal way to do this would be to do an
FFT, apply the filter in the frequency domain, and then do an iFFT to turn it
back into time series data. This will work in loads of cases, but I ve
found it to be incredibly tricky to get right when doing PSK. As such, I ve
opted to do this the old fashioned way in the time domain.
I ve again opted to go simple rather than correct, and haven t used
nearly any of the advanced level trickery I ve come across for fear of using
it wrong. As a result, our process here is going to be generating a
sinc filter by computing a
number of taps, and applying that in the time domain directly on the IQ
stream.
...// Apply sinc taps to an IQ stream
variq []complex// taps as created in dst above
vartaps []floatvardelay = make([]complex, len(taps))
fori:=rangeiq// let's shift the next sample into
// the delay buffer
copy(delay[1:], delay)
delay[0] = iq[i]
varphasorcomplexforj:=rangedelay// for each sample in the buffer, let's
// weight them by the tap values, and
// create a new complex number based on
// filtering the real and imag values.
phasor+= complex(
taps[j] * real(delay[j]),
taps[j] * imag(delay[j]),
)
// now that we've run this sample
// through the filter, we can go ahead
// and scale it back (since we multiply
// above) and drop it back into the iq
// buffer.
iq[i] = complex(
real(phasor) / len(taps),
imag(phasor) / len(taps),
)
...
After running IQ samples through the taps and back out, we ll have a signal
that s been filtered to the shape of our designed Sinc filter which will
cut out captured high frequency components (both positive and negative).
Astute observers will note that we re using the real (float) valued taps
on both the real and imaginary values independently. I m sure there s a way
to apply taps using complex numbers, but it was a bit confusing to work
through without being positive of the outcome. I may revisit this in the
future!
Downsample
Now, post-filter, we ve got a lot of extra RF bandwidth being represented in
our IQ stream at our high sample rate All the high frequency values are now
filtered out, which means we can reduce our sampling rate without losing much
information at all. We can either do nothing about it and process at the fairly
high sample rate we re capturing at, or we can drop the sample rate down and
help reduce the volume of numbers coming our way.
There s two big ways of doing this; either you can take every Nth sample (e.g.,
take every other sample to half the sample rate, or take every 10th to decimate
the sample stream to a 10th of what it originally was) which is the easiest to
implement (and easy on the CPU too), or to average a number of samples to
create a new sample.
A nice bonus to averaging samples is that you can trade-off some CPU time for a
higher effective number of bits
(ENOB) in your IQ
stream, which helps reduce noise, among other things. Some hardware does
exactly this (called Oversampling ), and like many things, it has
some pros and some cons.
I ve opted to treat our IQ stream like an oversampled IQ stream
and average samples to get a marginal bump in ENOB.
Taking a group of 4 samples and averaging them results in a bit of added
precision. That means that a stream of IQ data at 8 ENOB can be bumped to 9
ENOB of precision after the process of oversampling and averaging. That
resulting stream will be at 1/4 of the sample rate, and this process can be
repeated 4 samples can again be taken for a bit of added precision; which is
going to be 1/4 of the sample rate (again), or 1/16 of the original sample
rate. If we again take a group of 4 samples, we ll wind up with another bit and
a sample rate that s 1/64 of the original sample rate.
Phase Lock
Our starting point for this section is the same capture as above, but
post-coarse sync, filtering downsampling (xz compressed interleaved float32, 163,840 samples per second)
The PLL in PACKRAT was one
of the parts I spent the most time stuck on. There s no shortage of discussions
of how hardware PLLs work, or even a few software PLLs, but very little by way
of how to apply them and/or troubleshoot them. After getting frustrated trying
to follow the well worn path, I decided to cut my own way through the bush
using what I had learned about the concept, and hope that it works well enough
to continue on.
PLLs, in concept are fairly simple you generate a carrier wave at a
frequency, compare the real-world SDR IQ sample to where your carrier wave is
in phase, and use the difference between the local wave and the observed wave
to adjust the frequency and phase of your carrier wave. Eventually, if all goes
well, that delta is driven as small as possible, and your carrier wave can be
used as a reference clock to determine if the observed signal changes in
frequency or phase.
In reality, tuning PLLs is a total pain, and basically no one outlines how to
apply them to BPSK signals in a descriptive way. I ve had to steal an approach
I ve seen in hardware to implement my software PLL, with any hope it s close
enough that this isn t a hazard to learners. The concept is to generate the
carrier wave (as above) and store some rolling averages to tune the carrier
wave over time. I use two constants, alpha and beta (which appear to be
traditional PLL variable names for this function) which control how quickly the
frequency and phase is changed according to observed mismatches. Alpha is set
fairly high, which means discrepancies between our carrier and observed data
are quickly applied to the phase, and a lower constant for Beta, which will
take long-term errors and attempt to use that to match frequency.
This is all well and good. Getting to this point isn t all that obscure, but
the trouble comes when processing a BPSK signal. Phase changes kick the PLL
out of alignment and it tends to require some time to get back into phase lock,
when we really shouldn t even be loosing it in the first place. My attempt is
to generate two predicted samples, one for each phase of our BPSK signal. The
delta is compared, and the lower error of the two is used to adjust the PLL,
but the carrier wave itself is used to rotate the sample.
varalpha = 0.1varbeta = (alpha*alpha) /2varphase = 0.0varfrequency = 0.0...fori:=rangeiqpredicted = complex(cos(phase), sin(phase))
sample = iq[i] *conj(predicted)
delta = phase(sample)
predicted2 = complex(cos(phase+pi), sin(phase+pi))
sample2 = iq[i] *conj(predicted2)
delta2 = phase(sample2)
ifabs(delta2) < abs(delta)
// note that we do not update 'sample'.
delta = delta2phase+=alpha*deltafrequency+=beta*delta// adjust the iq sample to the PLL rotated
// sample.
iq[i] = sample...
If all goes well, this loop has the effect of driving a BPSK signal s imaginary
values to 0, and the real value between +1 and -1.
Average Idle / Carrier Detect
Our starting point for this section is the same capture as above, but
post-PLL (xz compressed interleaved float32, 163,840 samples per second)
When we start out, we have IQ samples that have been mostly driven to an
imaginary component of 0 and real value range between +1 and -1 for each symbol
period. Our goal now is to determine if we re receiving a signal, and if so,
determine if it s +1 or -1. This is a deceptively hard problem given it spans a
lot of other similarly entertaining hard problems. I ve opted to not solve the
hard problems involved and hope that in practice my very haphazard
implementation works well enough. This turns out to be both good (not solving a
problem is a great way to not spend time on it) and bad (turns out it does
materially impact performance). This segment is the one I plan on revisiting,
first. Expect more here at some point!
Given that I want to be able to encapsulate three states in the output from
this section (our Symbols are no carrier detected ( 0 ), real value 1 ( 1 ) or
real value -1 ("-1")), which means spending cycles to determine what the
baseline noise is to try and identify when a signal breaks through the noise
becomes incredibly important.
varidleThresholdvarthresholdFactor = 10...// sigThreshold is used to determine if the symbol
// is -1, +1 or 0. It's 1.3 times the idle signal
// threshold.
varsigThreshold = (idleThreshold*0.3) +idleThreshold// iq contains a single symbol's worth of IQ samples.
// clock alignment isn't really considered; so we'll
// get a bad packet if we have a symbol transition
// in the middle of this buffer. No attempt is made
// to correct for this yet.
variq []complex// avg is used to average a chunk of samples in the
// symbol buffer.
varavgfloatvarmid = len(iq) /2// midNum is used to determine how many symbols to
// average at the middle of the symbol.
varmidNum = len(iq) /50forj:=mid; j < mid+midNum; j++avg+= real(iq[j])
avg/=midNumvarsymbolfloatswitchcaseavg > sigThreshold:
symbol = 1caseavg < -sigThreshold:
symbol = -1default:
symbol = 0// update the idleThreshold using the thresholdFactor
// to average the idleThreshold over more samples to
// get a better idea of average noise.
idleThreshold = (
(idleThreshold*(thresholdFactor-1) +symbol) \
/thresholdFactor
)
// write symbol to output somewhere
...
Next Steps
Now that we have a stream of values that are either +1, -1 or 0, we
can frame / unframe the data contained in the stream, and decode Packets
contained inside, coming next in Part 4!
 I've been using Vim as my main text editor for 18 years, but for most of that
time I've been using something very close to the default configuration: my
 Many developers manage their user-specific application configuration also
known as dotfiles in a version control system such as


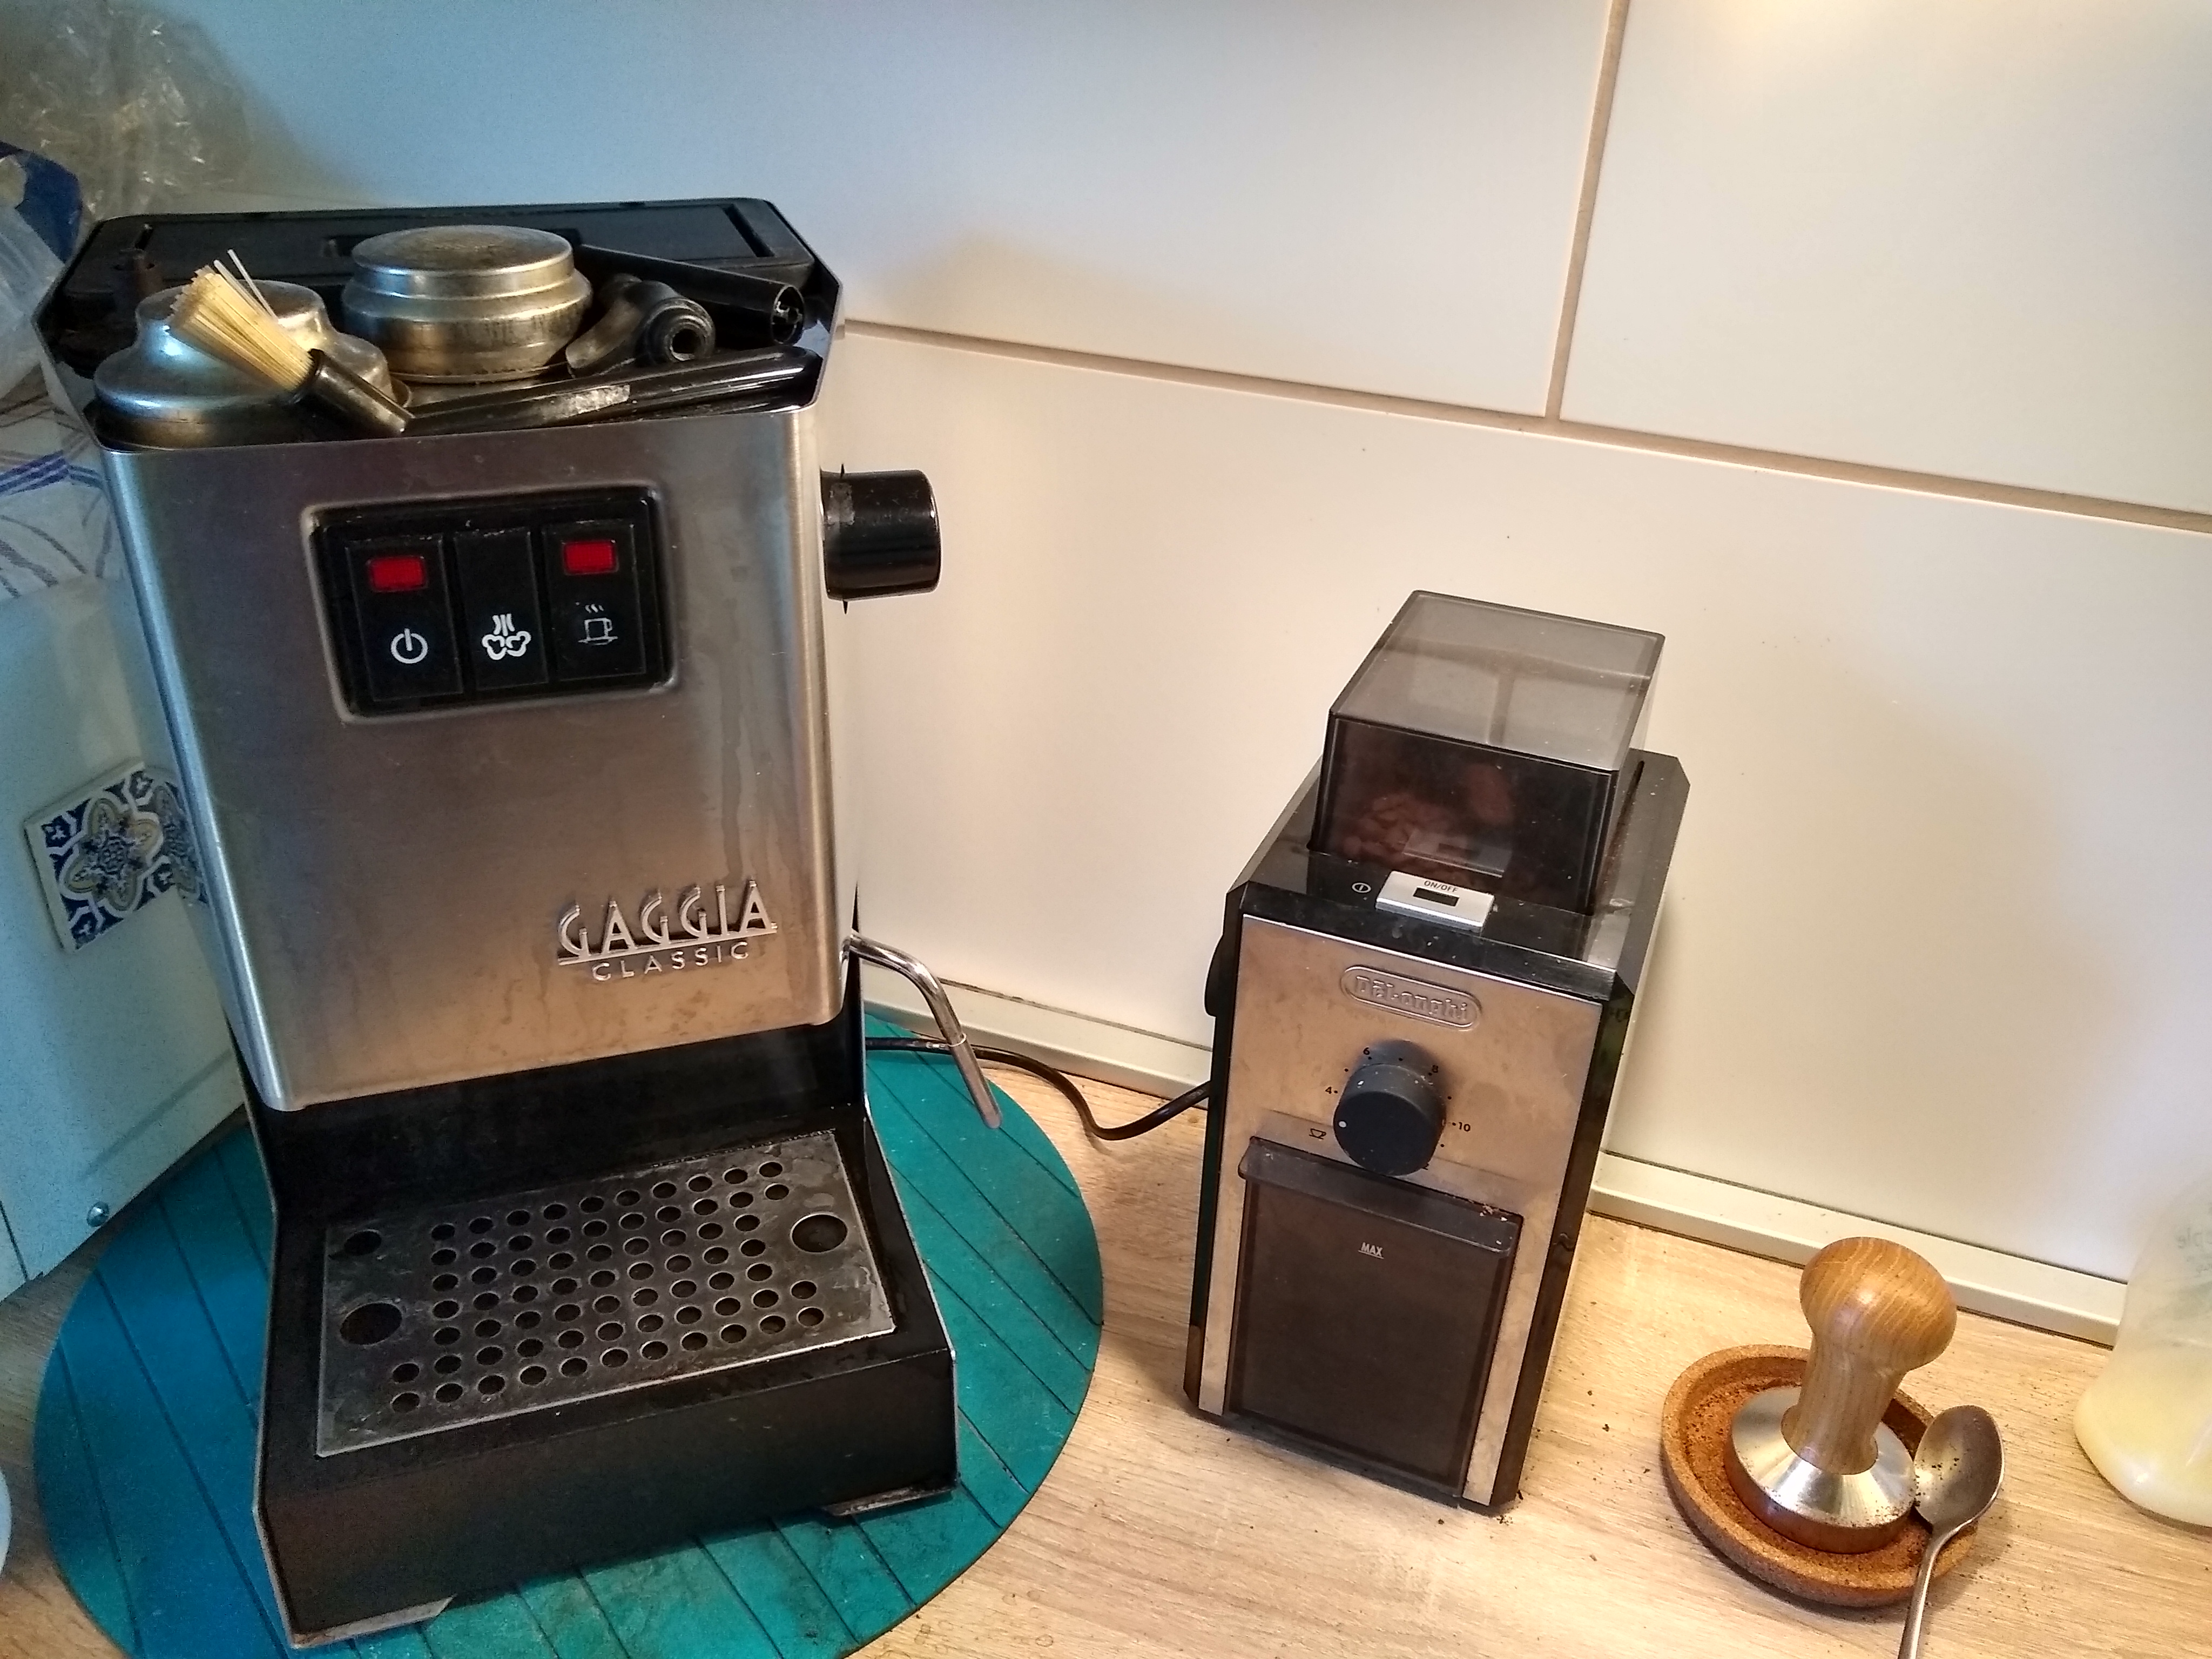 Gaggia Classic 2015 and De Longhi grinder
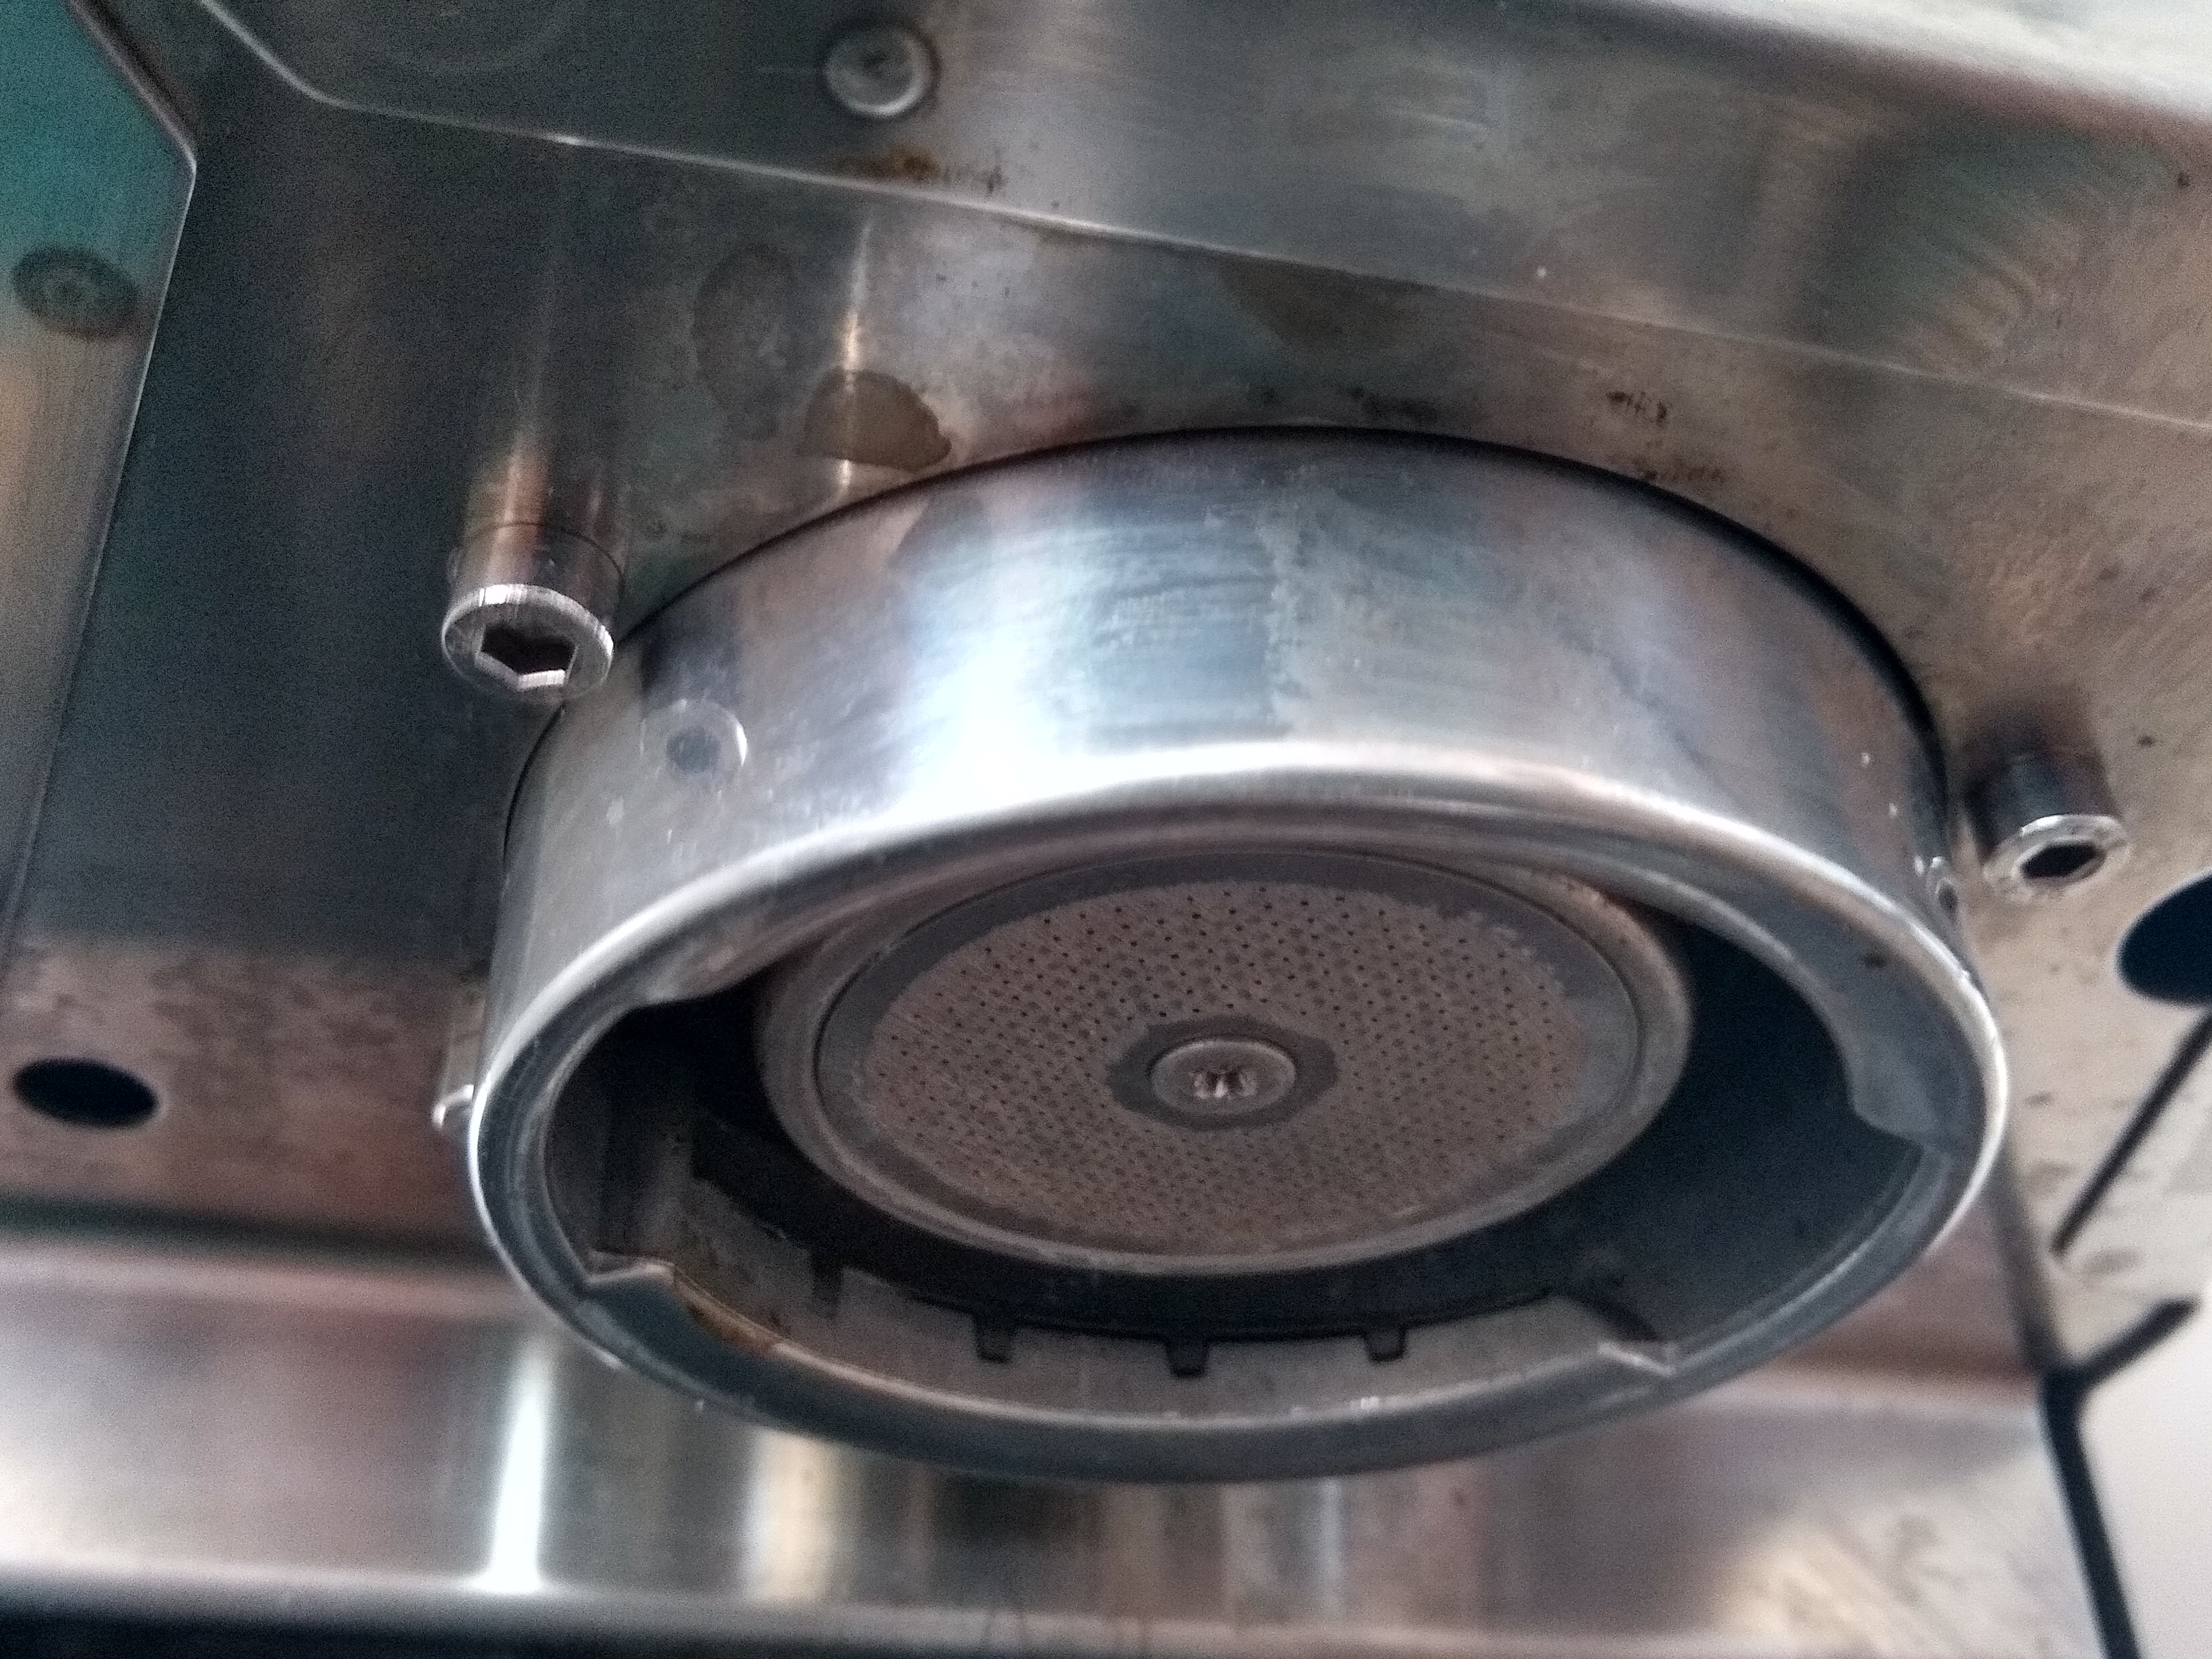 The Gaggia Classic 2015 group head
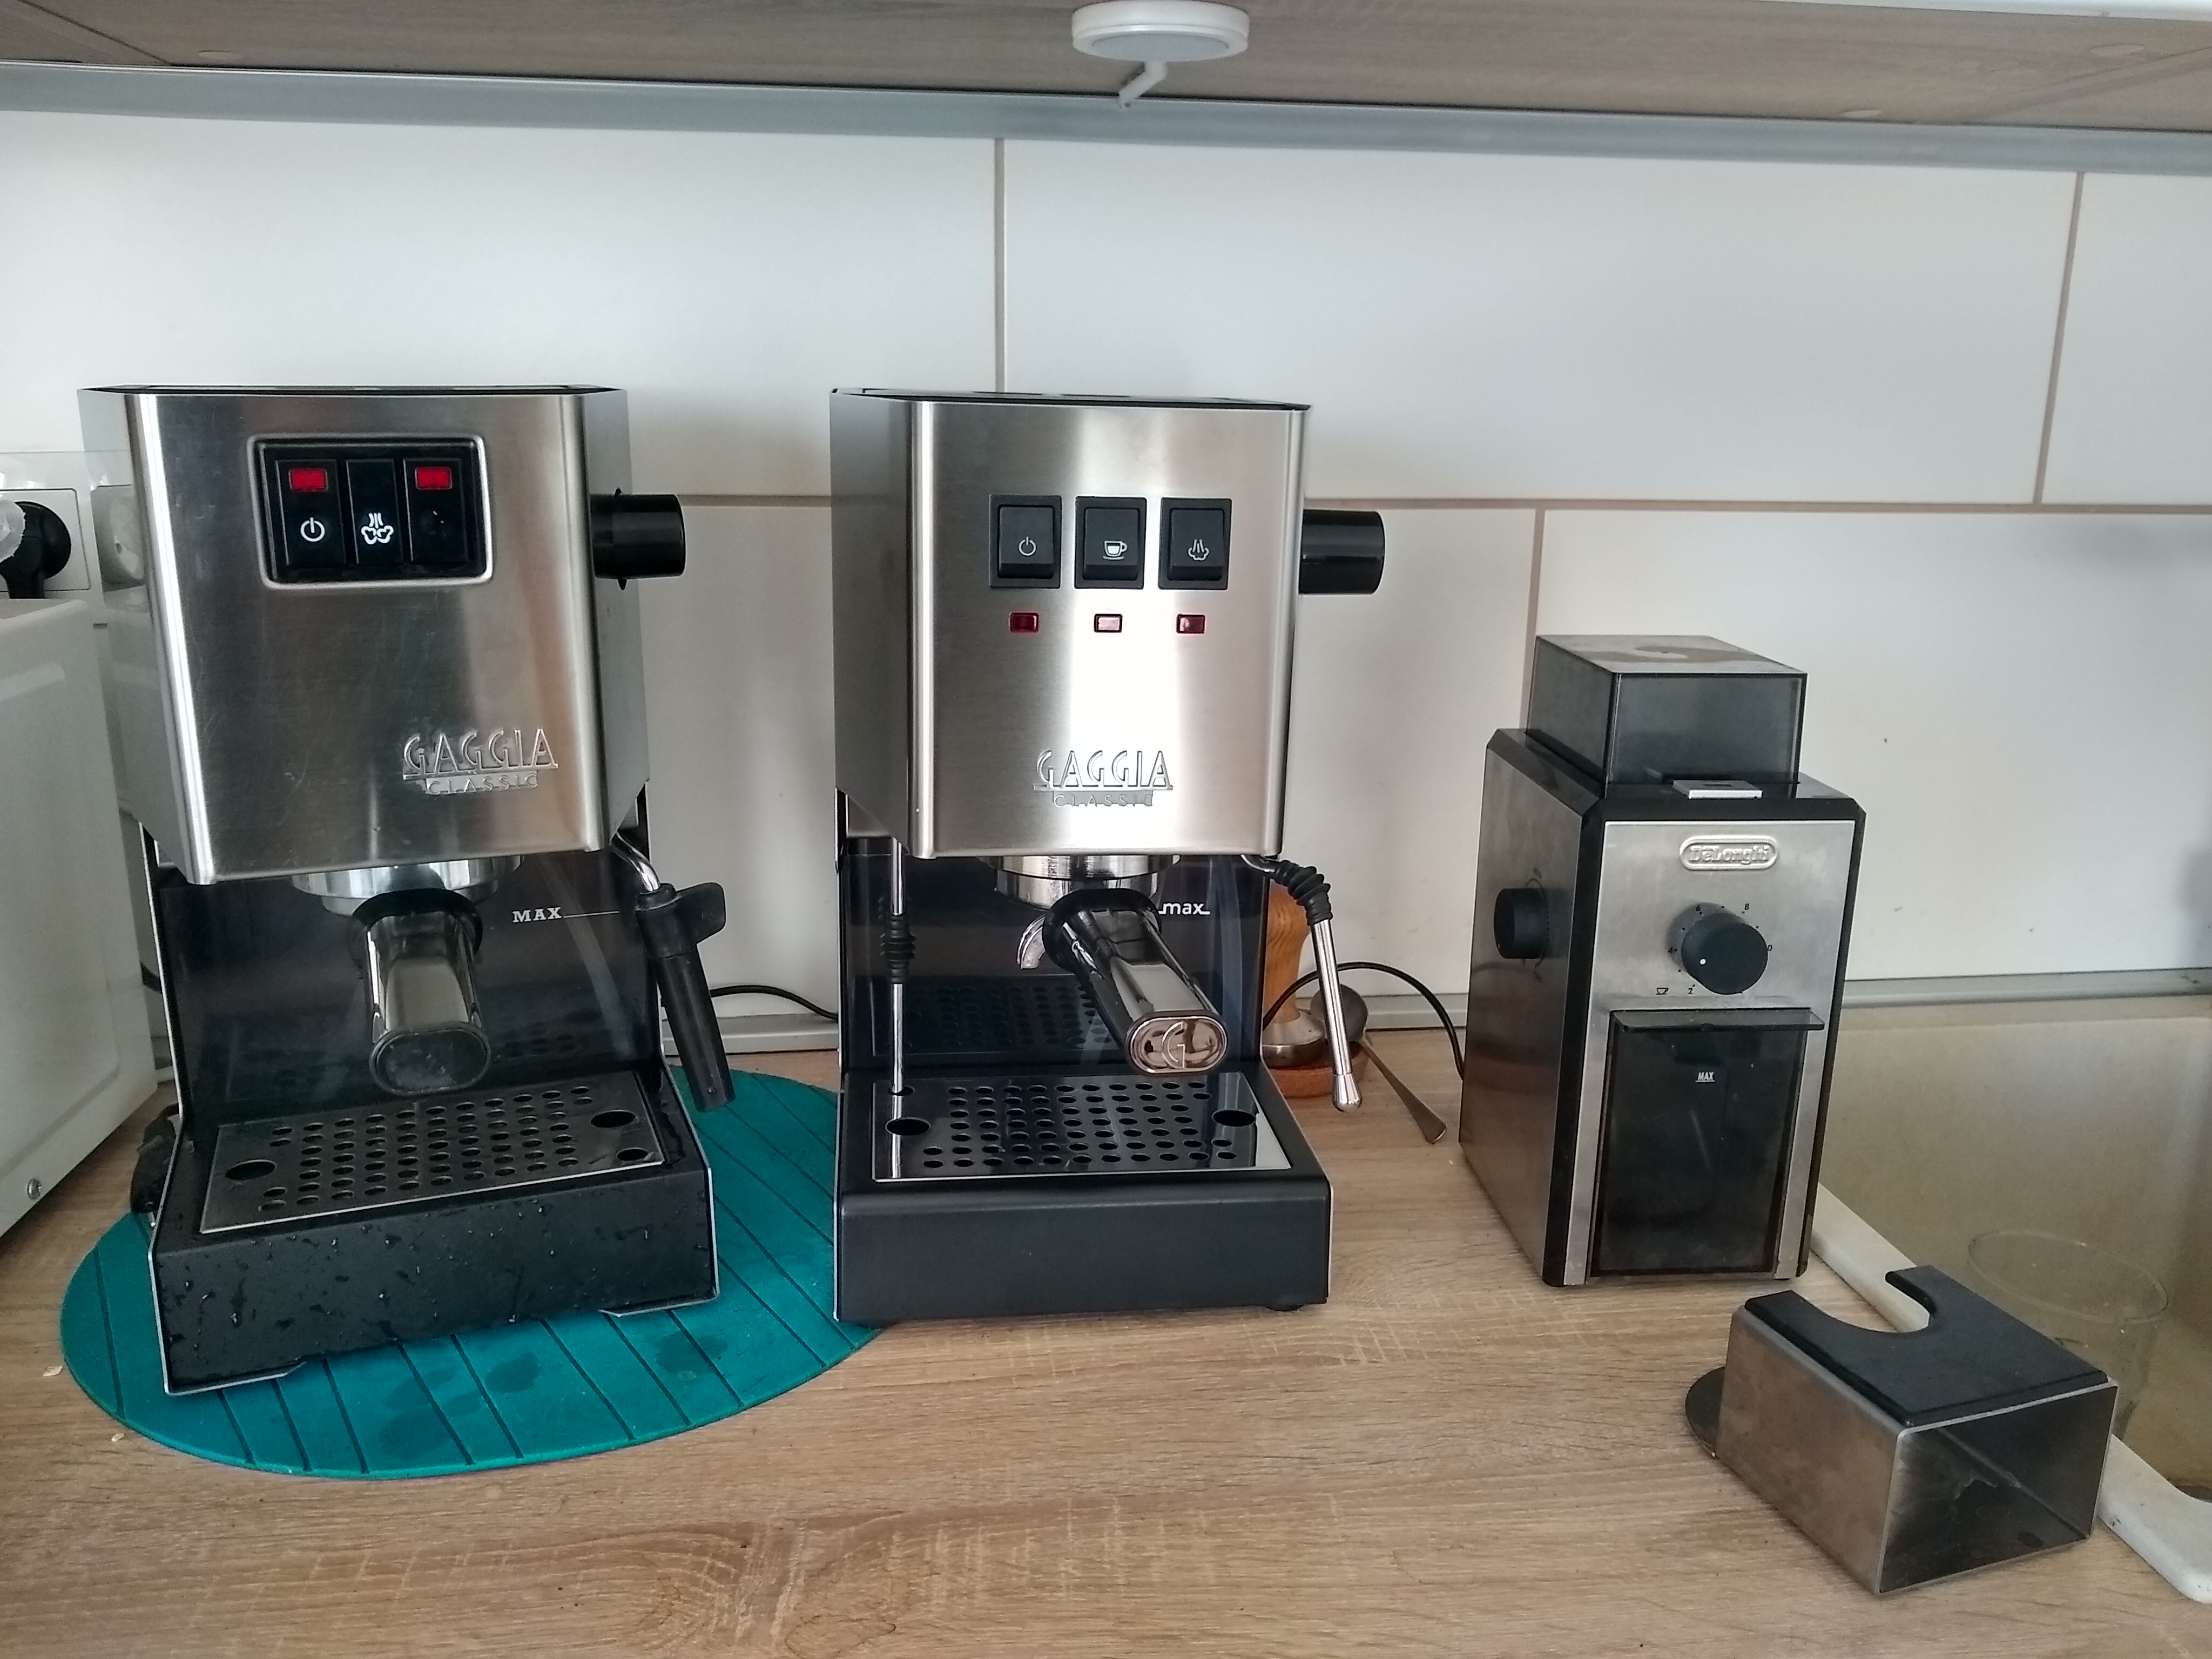 Gaggia Classic 2015 vs 2019
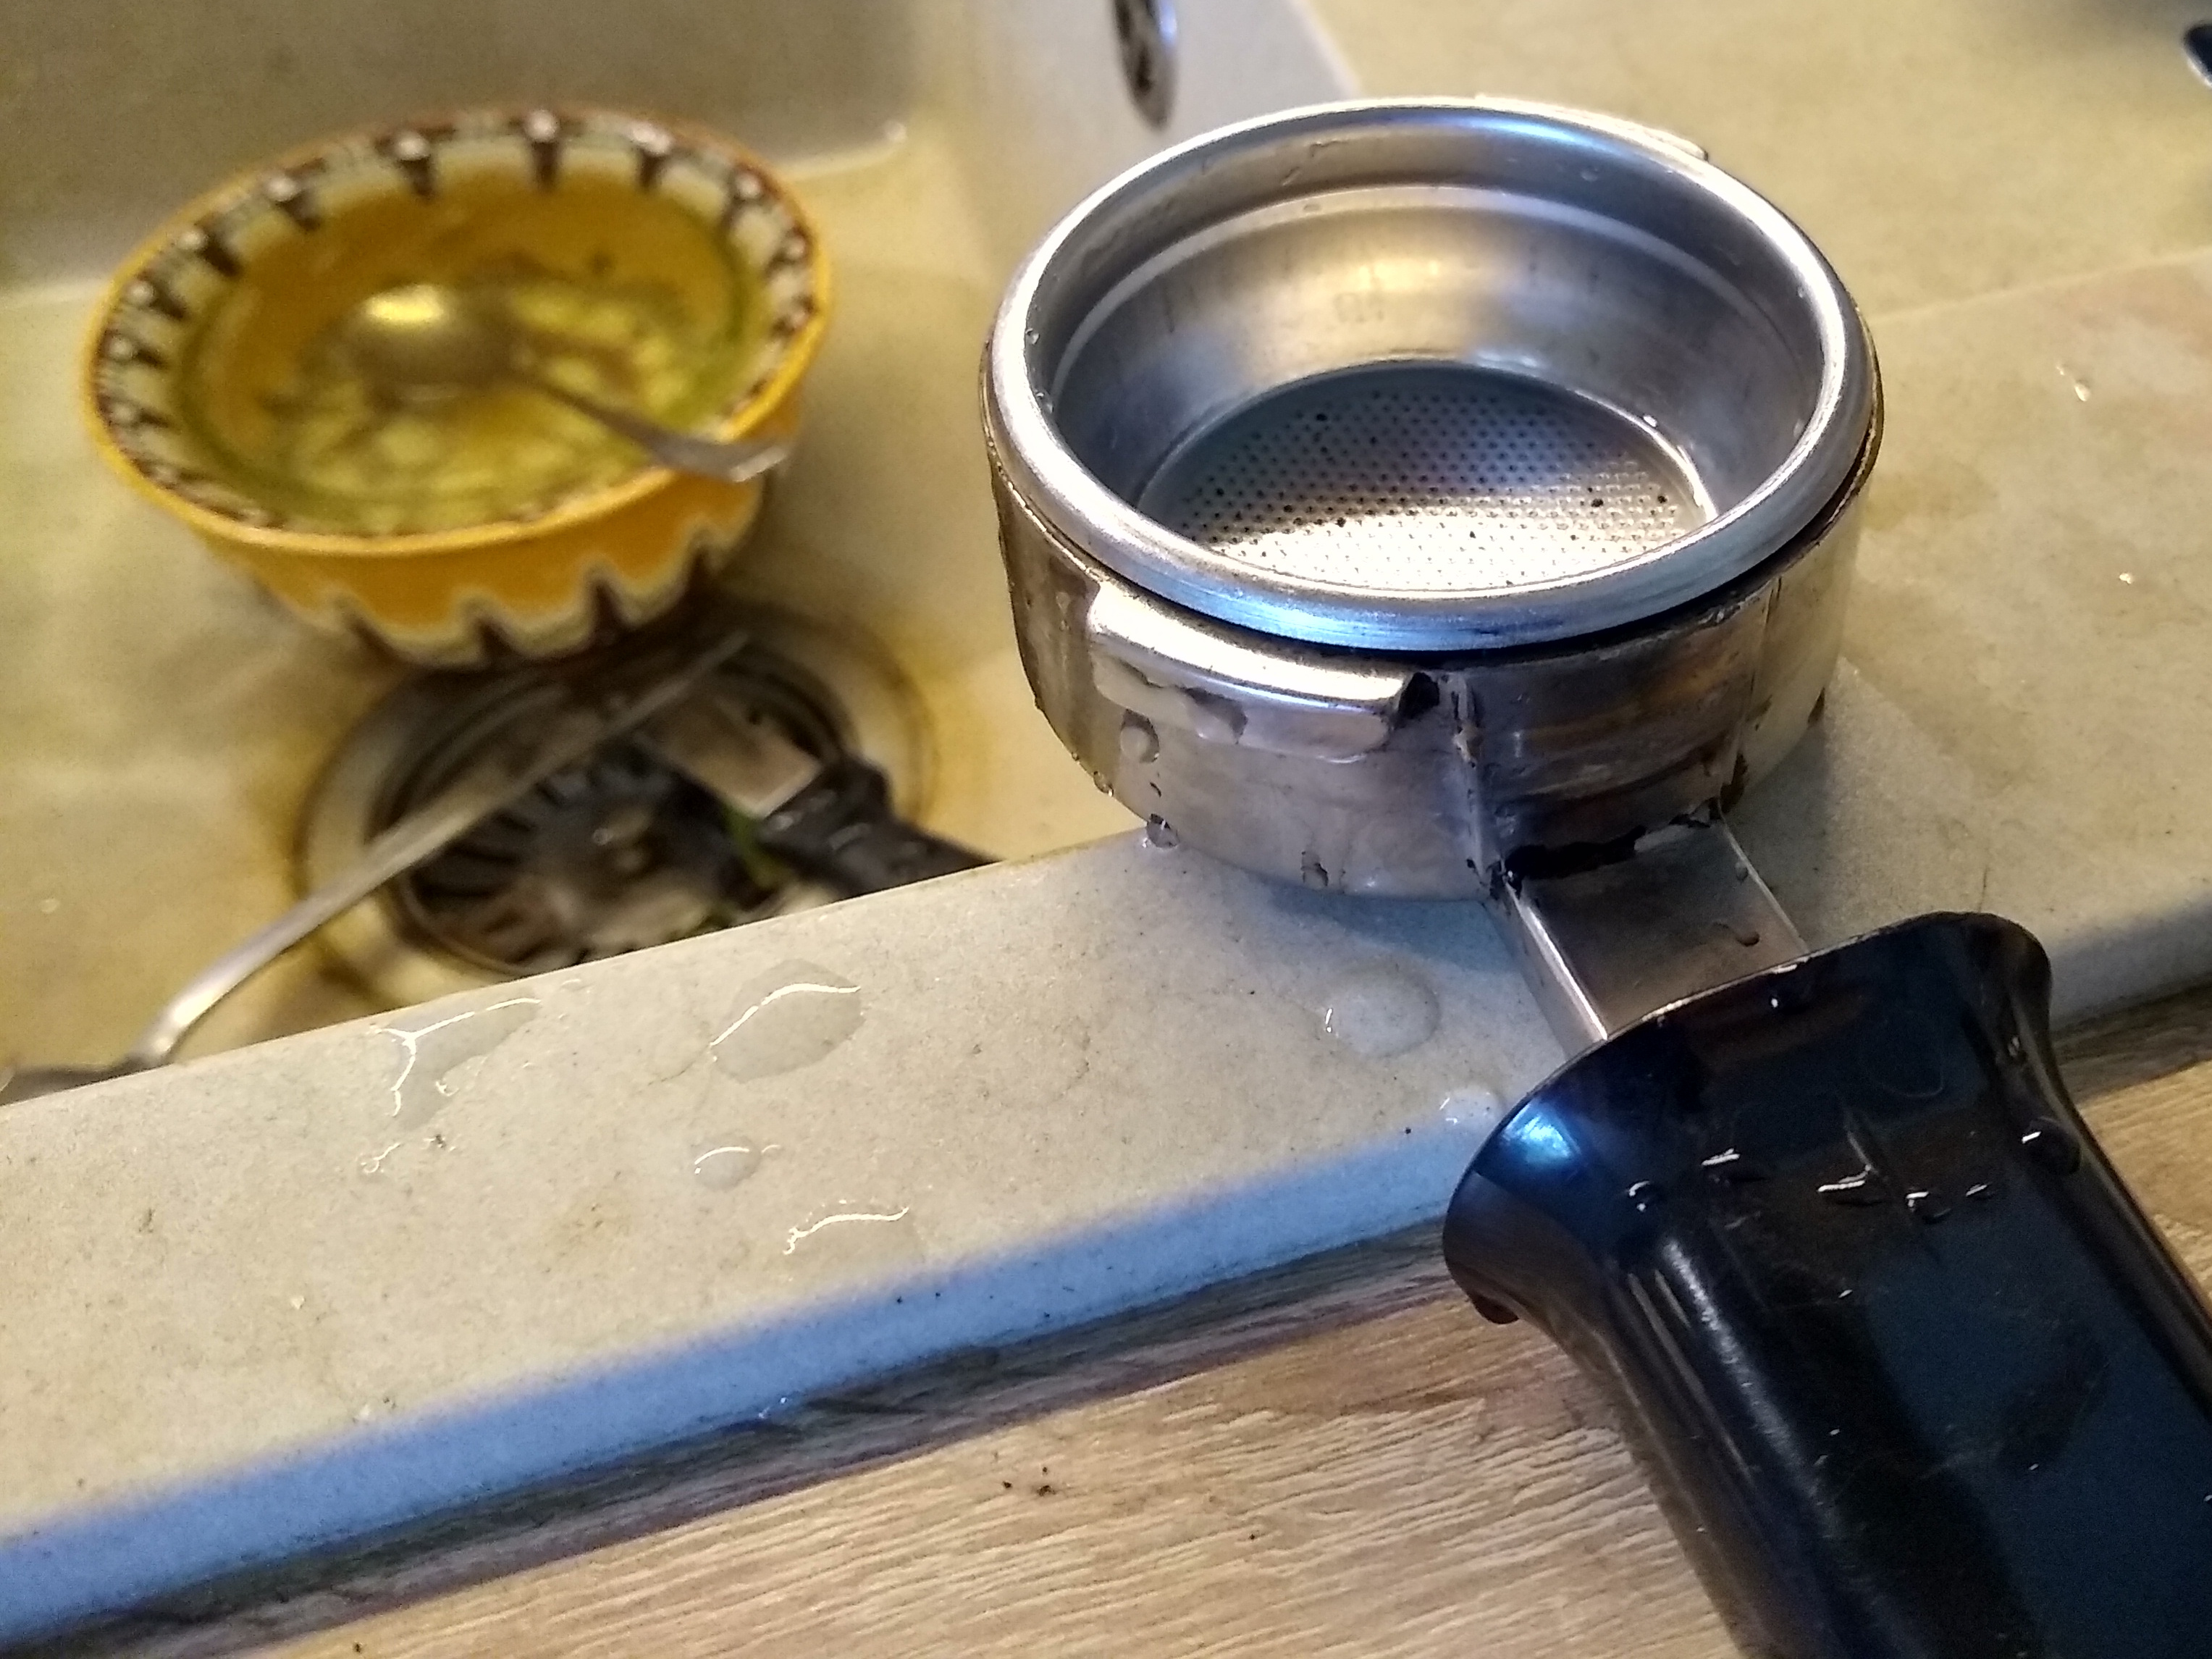
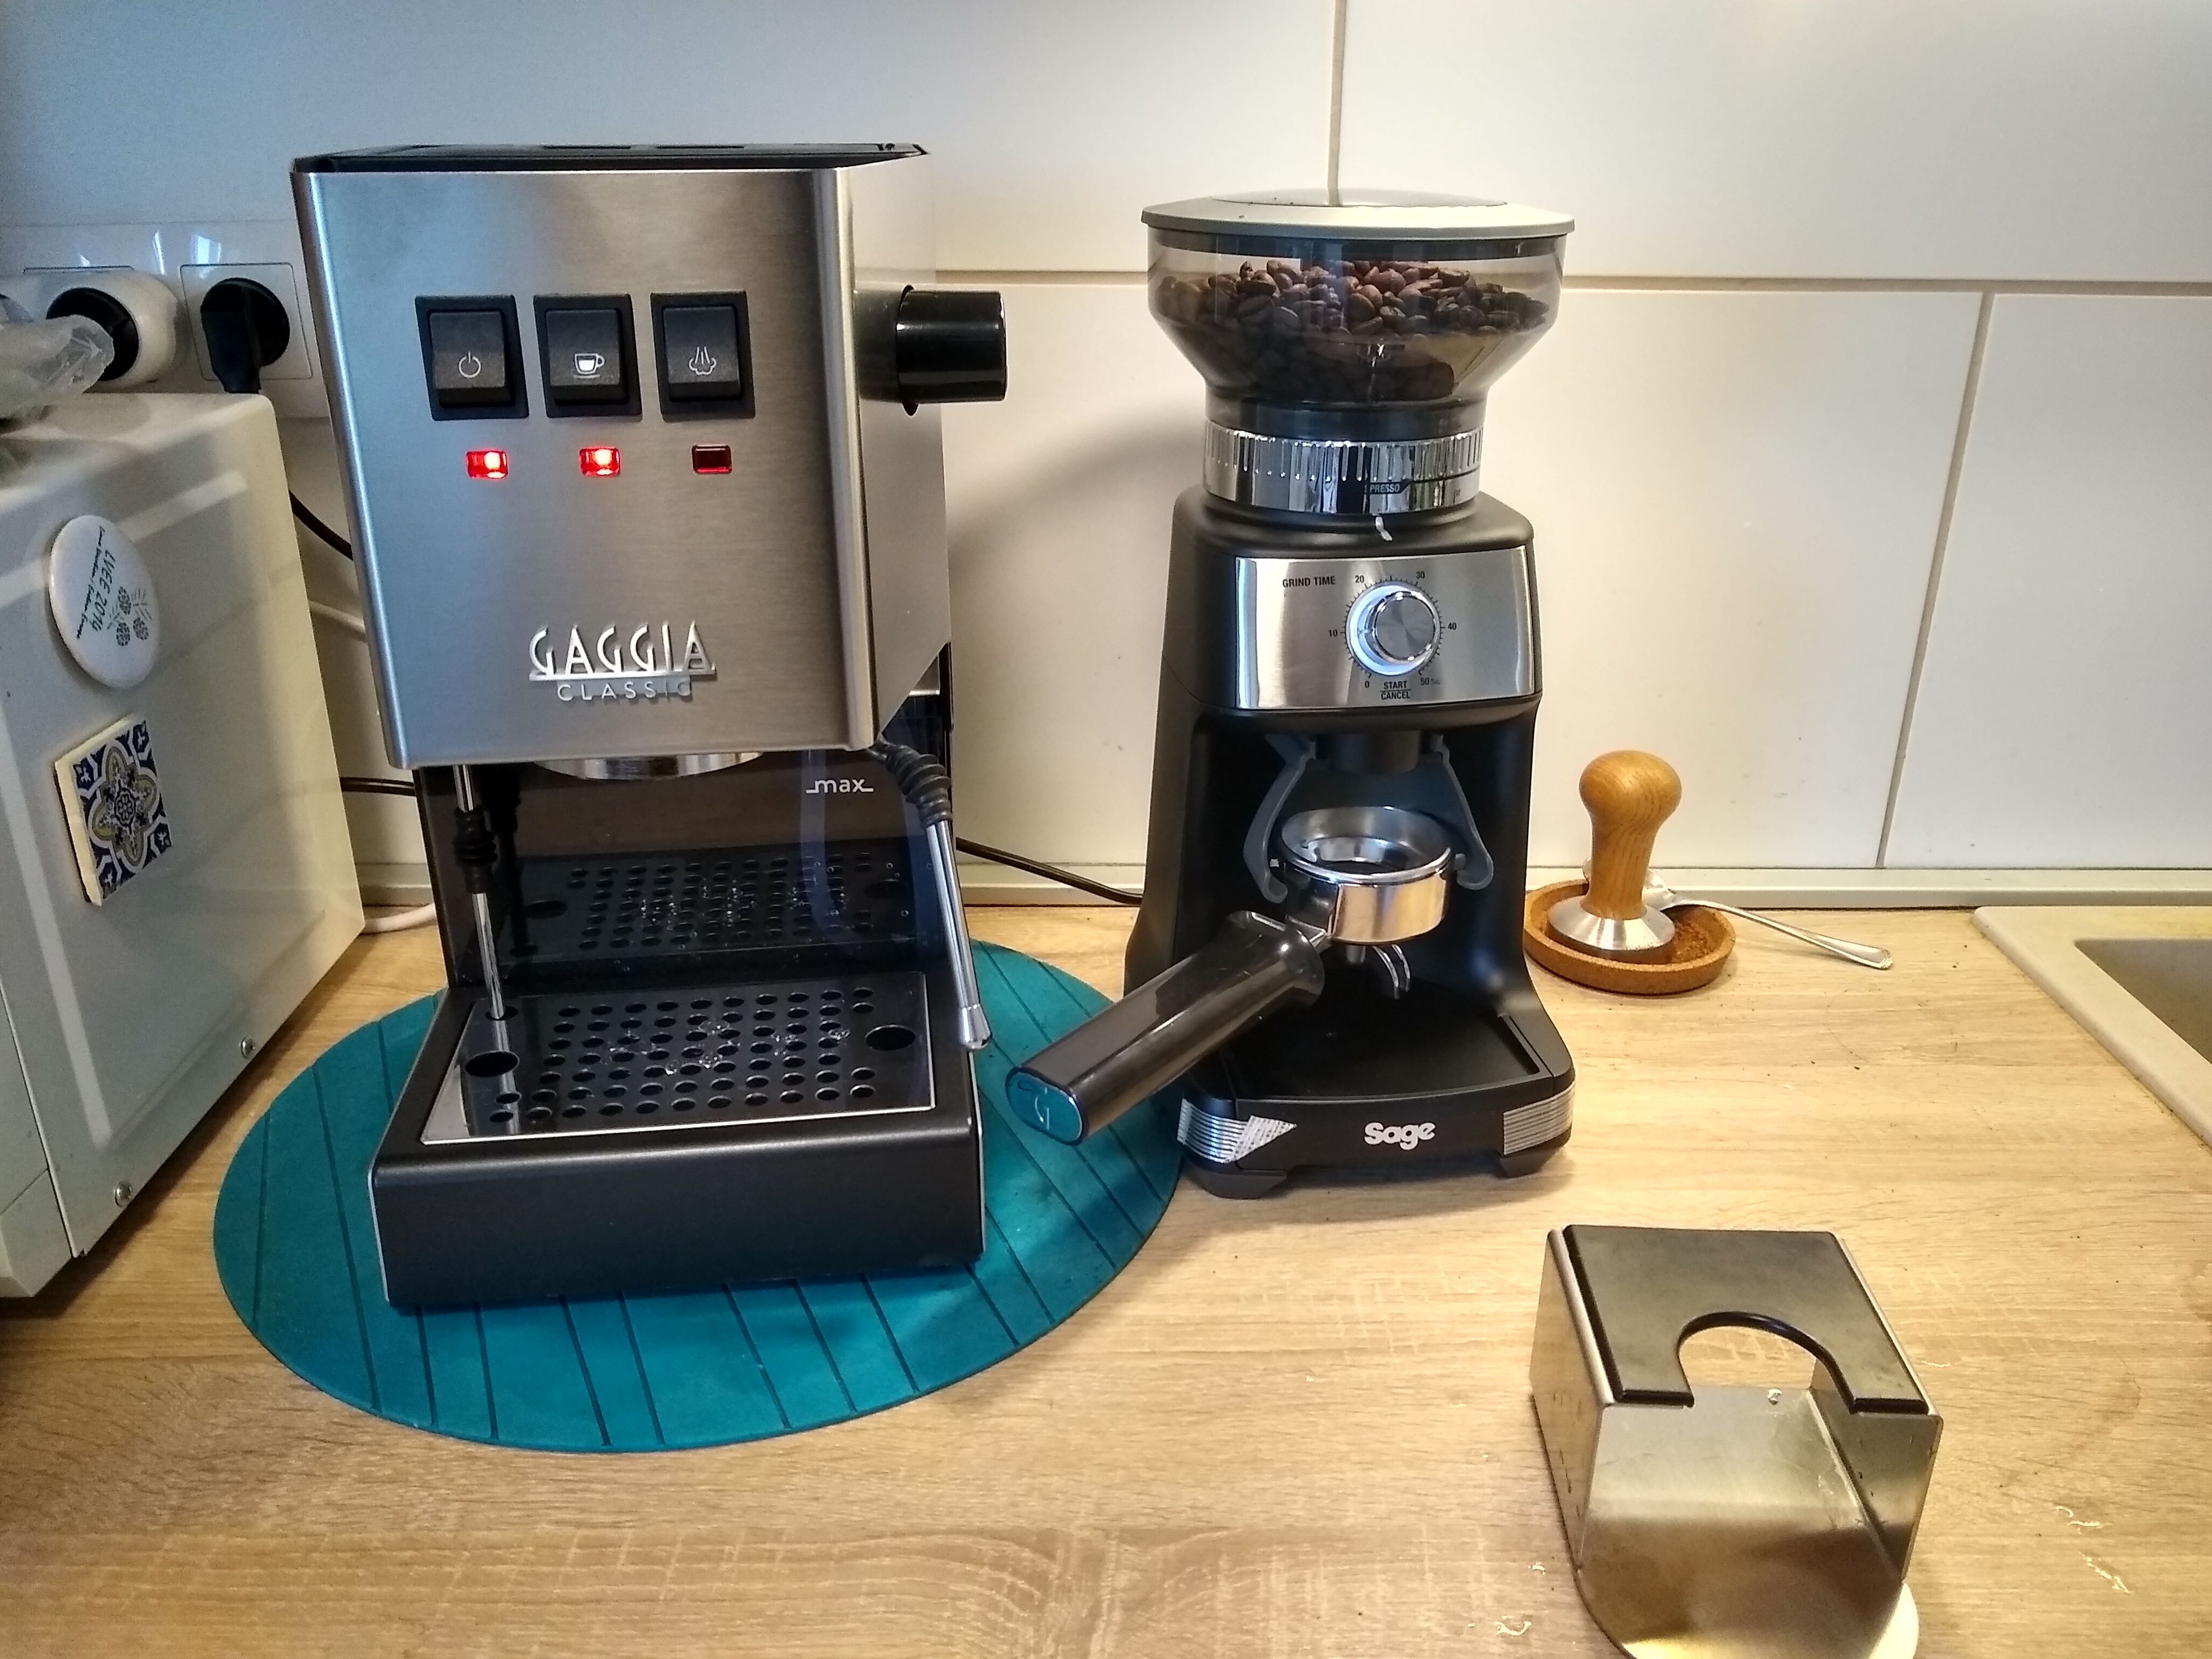 Gaggia Classic 2019 and Sage BCG600 Dose Control Pro
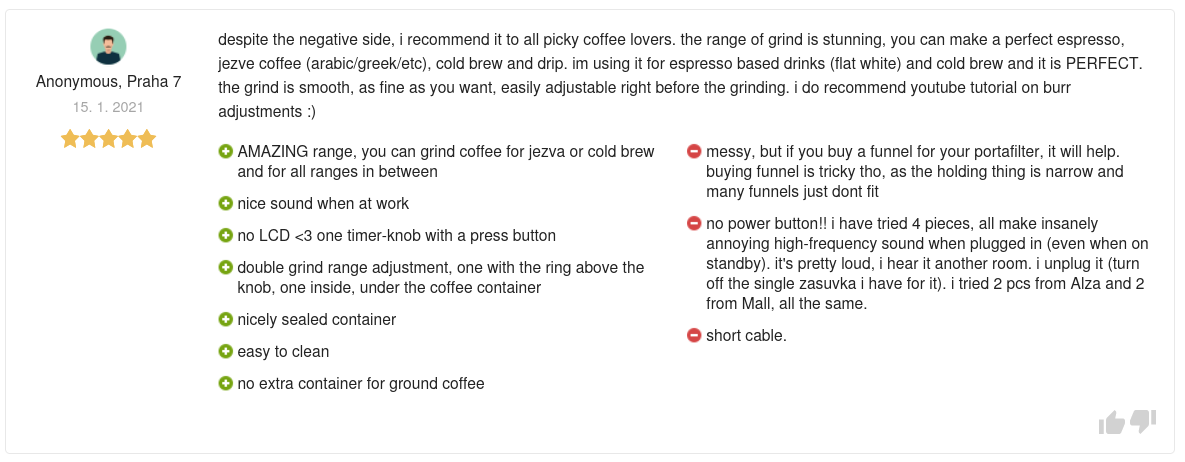 Happy with my new purchase, I went to read this review and thought to myself: lucky me, my grinder is absolutely quiet! And then I realised that
the noise in my kitchen is not, in fact, produced by the fridge, but the grinder. Well, a cheap switched plug solved the issue completely (I wish
sockets here each had a switch like they usually to in the UK!)
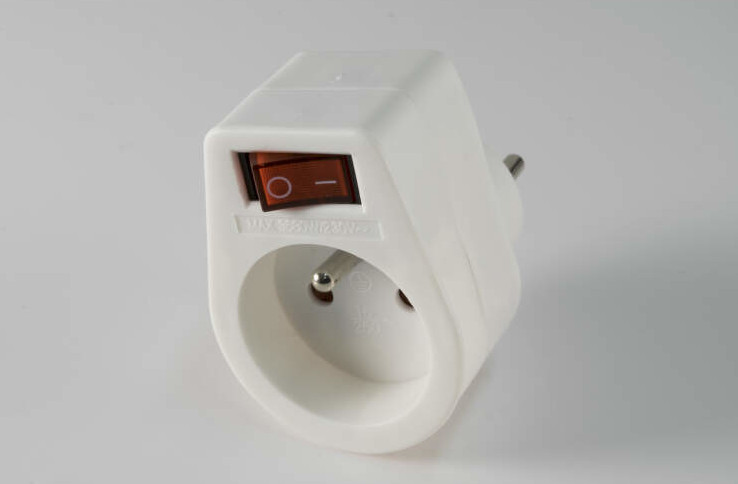

 After
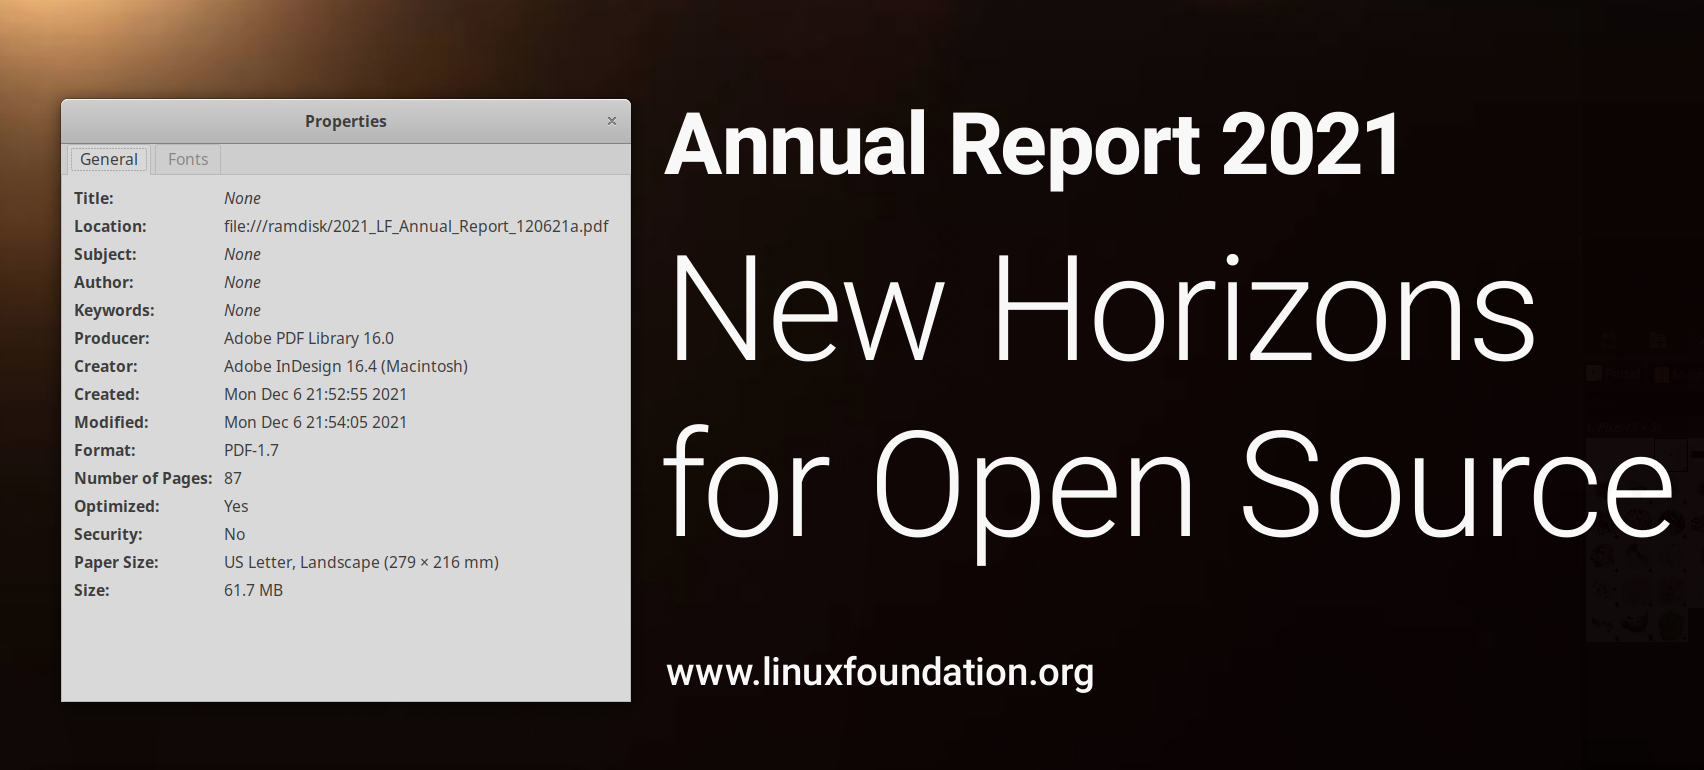 Personally, as a photographer, I am very happy they used stock images from
 Now for next year ... find an editor that knows how to spell photographers, please. And consider Scribus. And make Adobe publish their apps for Linux. Thank you.
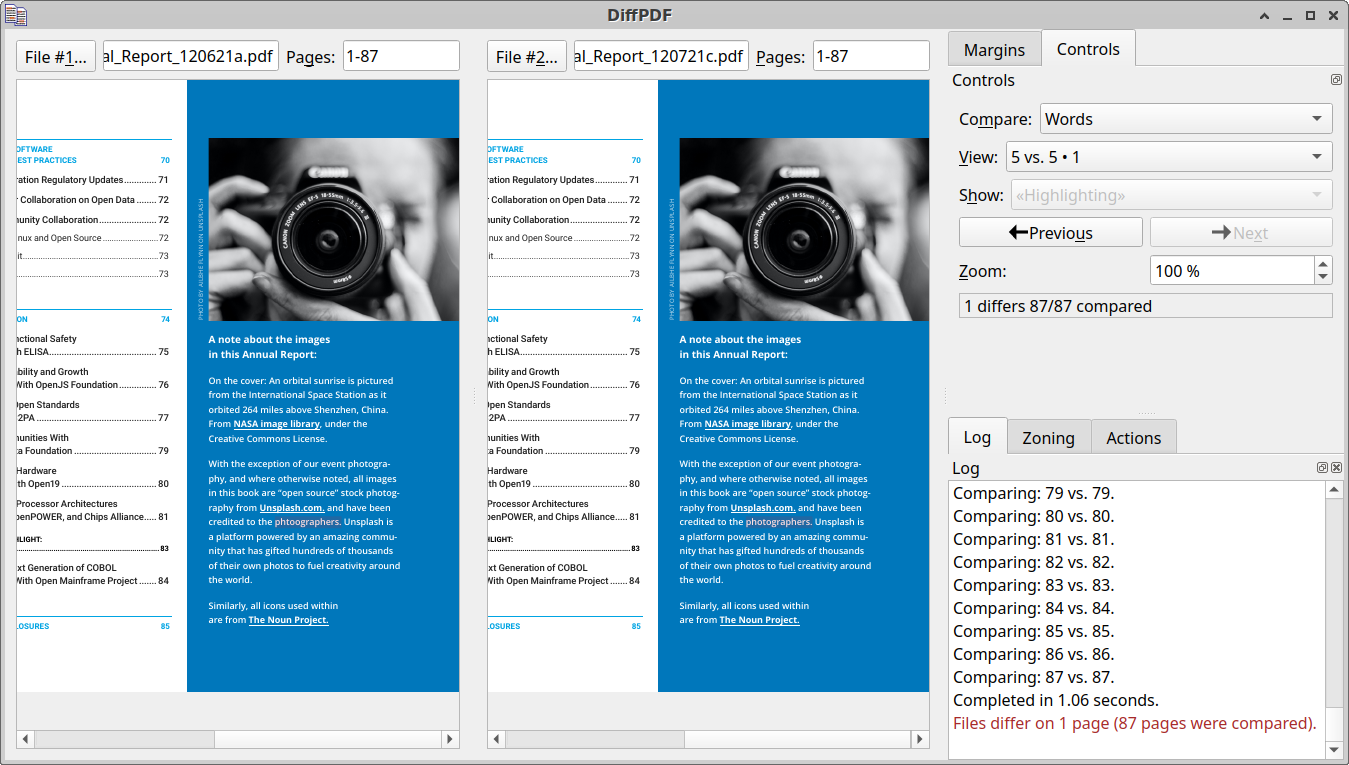
](https://jmtd.net/log/lightning/tweet.jpg)
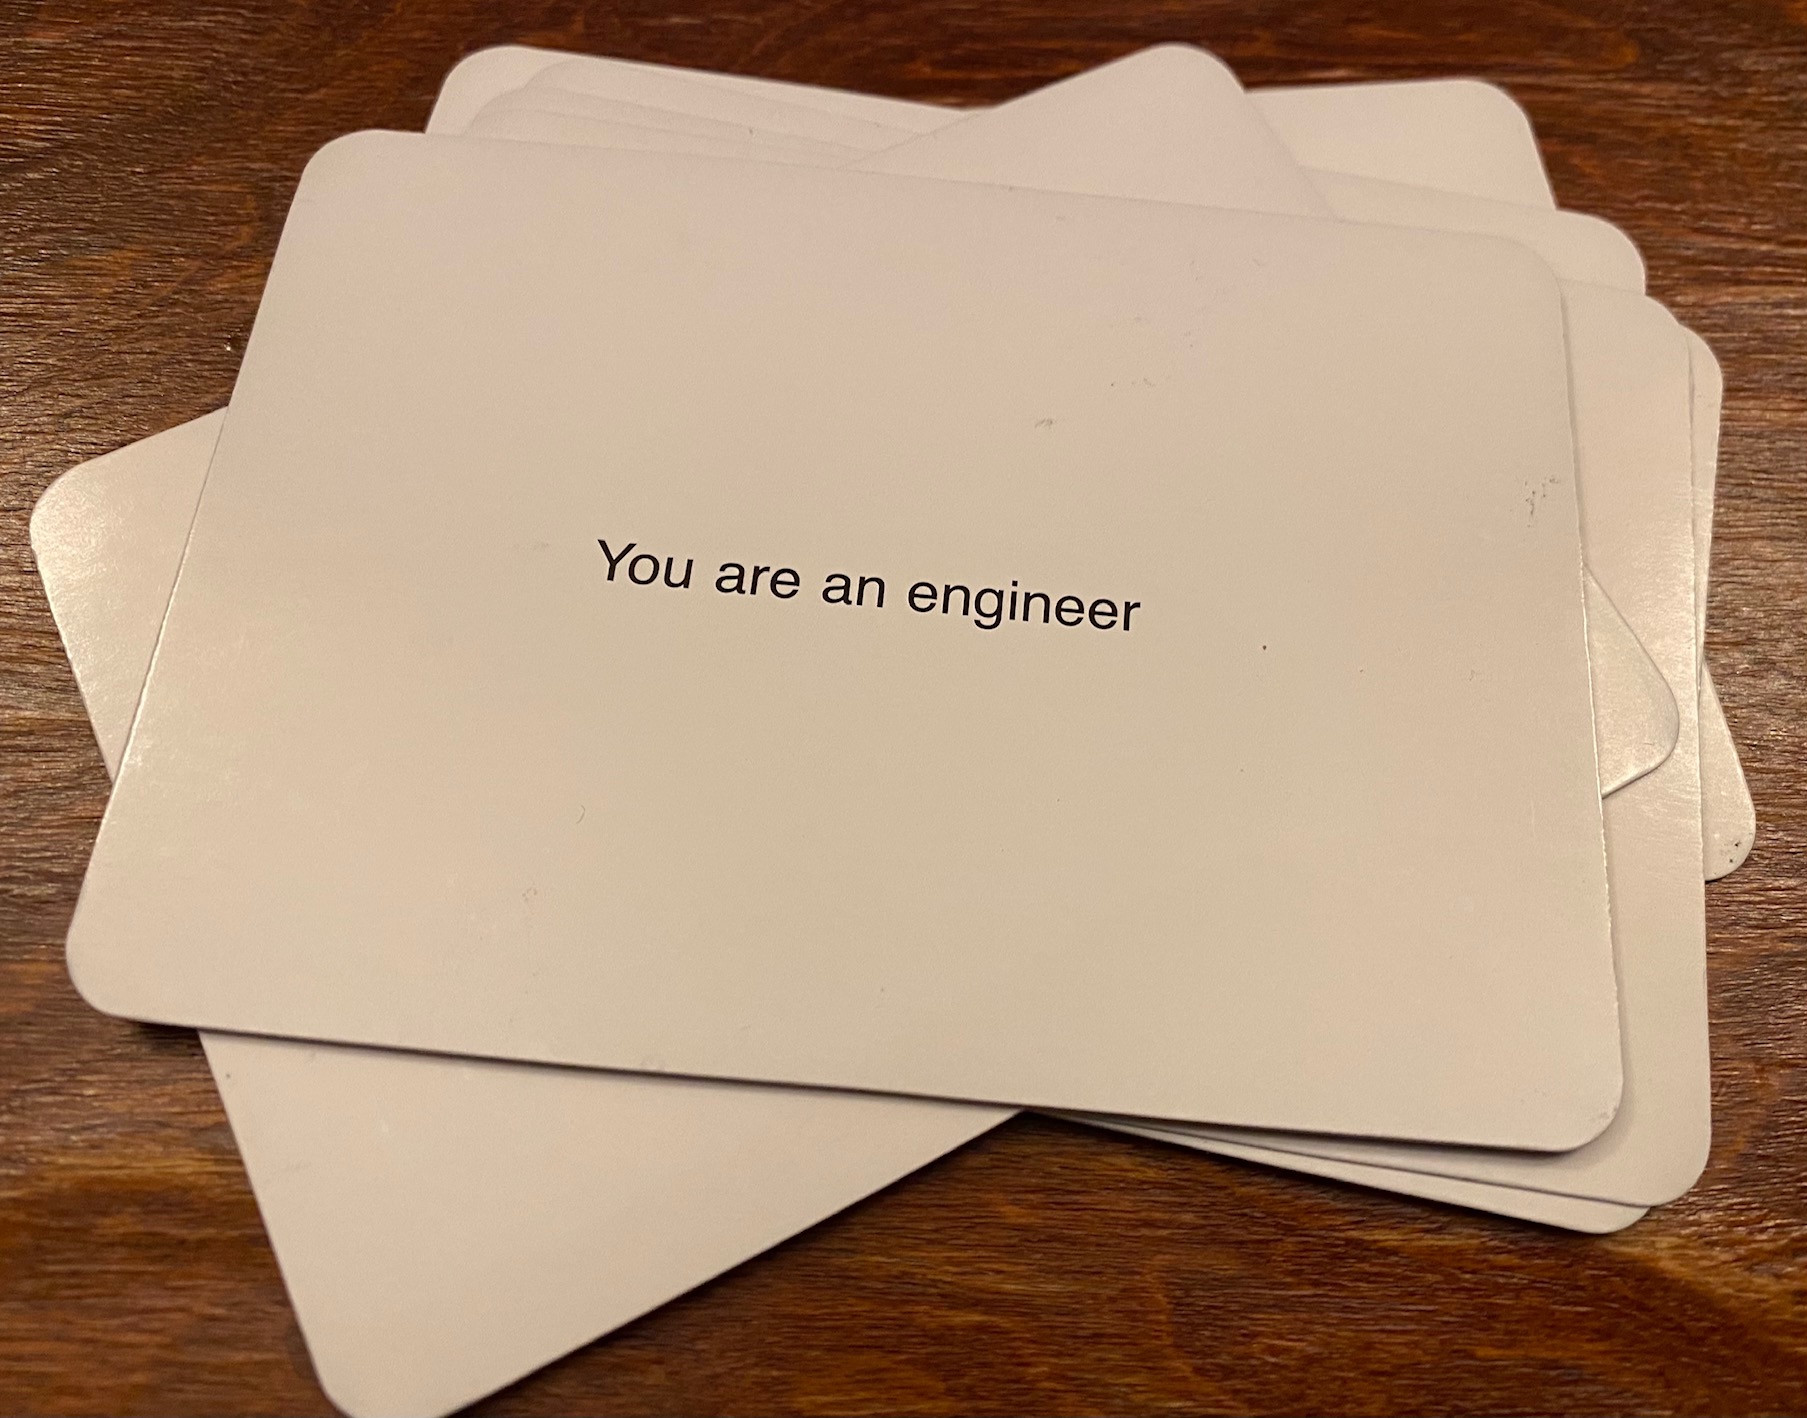

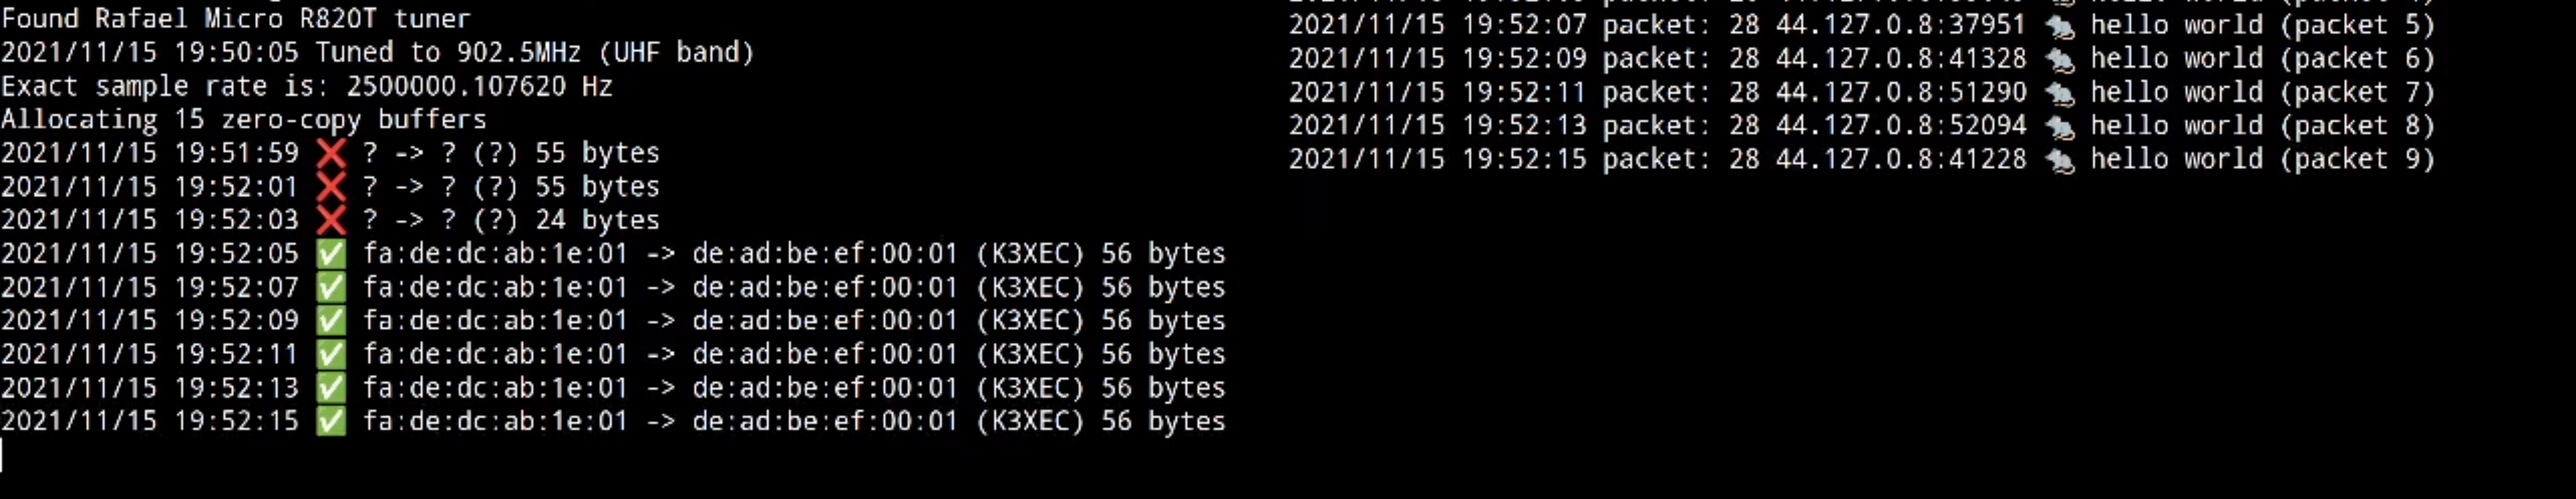 Now that UDP was working, I was able to get TCP to work using two PlutoSDRs,
which allowed me to run the cURL command I pasted in the first post (both
simultaneously listen and transmit on behalf of my TAP interface).
It s my hope that someone out there will be inspired to implement their own
Layer 1 and Layer 2 as a learning exercise, and gets the same sense of
gratification that I did! If you re reading this, and at a point
where you ve been able to send IP traffic over your own Layer 1 / Layer 2,
please get in touch! I d be thrilled to hear all about it. I d love to link
to any posts or examples you publish here!