Search Results: "zed"

1 July 2025

Guido G nther: Free Software Activities June 2025

Another short status update of what happened on my side last month. Phosh 0.48.0 is out with nice improvements, phosh.mobi e.V. is alive, helped a bit to get cellbroadcastd out, osk bugfixes and some more: See below for details on the above and more: phosh phoc phosh-mobile-settings stevia (formerly phosh-osk-stub) phosh-osk-data phosh-vala-plugins pfs xdg-desktop-portal-phosh xdg-desktop-portal phosh-debs meta-phosh feedbackd feedbackd-device-themes gmobile GNOME clocks Debian Mobian ModemManager libmbim libqmi mobile-broadband-provider-info Cellbroadcastd iio-sensor-proxy twenty-twenty-hugo gotosocial Reviews This is not code by me but reviews on other peoples code. The list is (as usual) slightly incomplete. Thanks for the contributions! Help Development If you want to support my work see donations. Comments? Join the Fediverse thread

30 June 2025

Gunnar Wolf: Get your personalized map of DebConf25 in Brest

As I often do, this year I have also prepared a set of personalized maps for your OpenPGP keysigning in DebConf25, in Brest! What is that, dare you ask? Partial view of my OpenPGP map One of the not-to-be-missed traditions of DebConf is a Key-Signing Party (KSP) that spans the whole conference! Travelling from all the corners of the world to a single, large group gathering, we have the ideal opportunity to spread some communicable diseases trust on your peers identities and strengthen Debian s OpenPGP keyring. But whom should you approach for keysigning? Go find yourself in the nice listing I have prepared. By clicking on your long keyid (in my case, the link labeled 0x2404C9546E145360), anybody can download your certificate (public key + signatures). The SVG and PNG links will yield a graphic version of your position within the DC25 keyring, and the TXT link will give you a textual explanation of it. (of course, your links will differ, yada yada ) Please note this is still a preview of our KSP information: You will notice there are outstanding several things for me to fix before marking the file as final. First, some names have encoding issues I will fix. Second, some keys might be missing if you submitted your key as part of the conference registration form but it is not showing, it must be because my scripts didn t find it in any of the queried keyservers. My scripts are querying the following servers:
hkps://keyring.debian.org/
hkps://keys.openpgp.org/
hkps://keyserver.computer42.org/
hkps://keyserver.ubuntu.com/
hkps://pgp.mit.edu/
hkps://pgp.pm/
hkps://pgp.surf.nl/
hkps://pgpkeys.eu/
hkps://the.earth.li/
Make sure your key is available in at least some of them; I will try to do a further run on Friday, before travelling, or shortly after arriving to France. If you didn t submit your key in time, but you will be at DC25, please mail me stating [DC25 KSP] in your mail title, and I will manually add it to the list. On (hopefully!) Friday, I ll post the final, canonical KSP coordination page which you should download and calculate its SHA256-sum. We will have printed out convenience sheets to help you do your keysigning at the front desk.

Otto Kek l inen: Corporate best practices for upstream open source contributions

Featured image of post Corporate best practices for upstream open source contributions
This post is based on presentation given at the Validos annual members meeting on June 25th, 2025.
When I started getting into Linux and open source over 25 years ago, the majority of the software development in this area was done by academics and hobbyists. The number of companies participating in open source has since exploded in parallel with the growth of mobile and cloud software, the majority of which is built on top of open source. For example, Android powers most mobile phones today and is based on Linux. Almost all software used to operate large cloud provider data centers, such as AWS or Google, is either open source or made in-house by the cloud provider. Pretty much all companies, regardless of the industry, have been using open source software at least to some extent for years. However, the degree to which they collaborate with the upstream origins of the software varies. I encourage all companies in a technical industry to start contributing upstream. There are many benefits to having a good relationship with your upstream open source software vendors, both for the short term and especially for the long term. Moreover, with the rollout of CRA in EU in 2025-2027, the law will require software companies to contribute security fixes upstream to the open source projects their products use. To ensure the process is well managed, business-aligned and legally compliant, there are a few do s and don t do s that are important to be aware of.

Maintain your SBOMs For every piece of software, regardless of whether the code was done in-house, from an open source project, or a combination of these, every company needs to produce a Software Bill of Materials (SBOM). The SBOMs provide a standardized and interoperable way to track what software and which versions are used where, what software licenses apply, who holds the copyright of which component, which security fixes have been applied and so forth. A catalog of SBOMs, or equivalent, forms the backbone of software supply-chain management in corporations.

Identify your strategic upstream vendors The SBOMs are likely to reveal that for any piece of non-trivial software, there are hundreds or thousands of upstream open source projects in use. Few organizations have resources to contribute to all of their upstreams. If your organization is just starting to organize upstream contribution activities, identify the key projects that have the largest impact on your business and prioritize forming a relationship with them first. Organizations with a mature contribution process will be collaborating with tens or hundreds of upstreams.

Appoint an internal coordinator and champions Having a written policy on how to contribute upstream will help ensure a consistent process and avoid common pitfalls. However, a written policy alone does not automatically translate into a well-running process. It is highly recommended to appoint at least one internal coordinator who is knowledgeable about how open source communities work, how software licensing and patents work, and is senior enough to have a good sense of what business priorities to optimize for. In small organizations it can be a single person, while larger organizations typically have a full Open Source Programs Office. This coordinator should oversee the contribution process, track all contributions made across the organization, and further optimize the process by working with stakeholders across the business, including legal experts, business owners and CTOs. The marketing and recruiting folks should also be involved, as upstream contributions will have a reputation-building aspect as well, which can be enhanced with systematic tracking and publishing of activities. Additionally, at least in the beginning, the organization should also appoint key staff members as open source champions. Implementing a new process always includes some obstacles and occasional setbacks, which may discourage employees from putting in the extra effort to reap the full long-term benefits for the company. Having named champions will empower them to make the first few contributions themselves, setting a good example and encouraging and mentoring others to contribute upstream as well.

Avoid excessive approvals To maintain a high quality bar, it is always good to have all outgoing submissions reviewed by at least one or two people. Two or three pairs of eyeballs are significantly more likely to catch issues that might slip by someone working alone. The review also slows down the process by a day or two, which gives the author time to sleep on it , which usually helps to ensure the final submission is well-thought-out by the author. Do not require more than one or two reviewers. The marginal utility goes quickly to zero beyond a few reviewers, and at around four or five people the effect becomes negative, as the weight of each approval decreases and the reviewers begin to take less personal responsibility. Having too many people in the loop also makes each feedback round slow and expensive, to the extent that the author will hesitate to make updates and ask for re-reviews due to the costs involved. If the organization experiences setbacks due to mistakes slipping through the review process, do not respond by adding more reviewers, as it will just grind the contribution process to a halt. If there are quality concerns, invest in training for engineers, CI systems and perhaps an internal certification program for those making public upstream code submissions. A typical software engineer is more likely to seriously try to become proficient at their job and put effort into a one-off certification exam and then make multiple high-quality contributions, than it is for a low-skilled engineer to improve and even want to continue doing more upstream contributions if they are burdened by heavy review processes every time they try to submit an upstream contribution.

Don t expect upstream to accept all code contributions Sure, identifying the root cause of and fixing a tricky bug or writing a new feature requires significant effort. While an open source project will certainly appreciate the effort invested, it doesn t mean it will always welcome all contributions with open arms. Occasionally, the project won t agree that the code is correct or the feature is useful, and some contributions are bound to be rejected. You can minimize the chance of experiencing rejections by having a solid internal review process that includes assessing how the upstream community is likely to understand the proposal. Sometimes how things are communicated is more important than how they are coded. Polishing inline comments and git commit messages help ensure high-quality communication, along with a commitment to respond quickly to review feedback and conducting regular follow-ups until a contribution is finalized and accepted.

Start small to grow expertise and reputation In addition to keeping the open source contribution policy lean and nimble, it is also good to start practical contributions with small issues. Don t aim to contribute massive features until you have a track record of being able to make multiple small contributions. Keep in mind that not all open source projects are equal. Each has its own culture, written and unwritten rules, development process, documented requirements (which may be outdated) and more. Starting with a tiny contribution, even just a typo fix, is a good way to validate how code submissions, reviews and approvals work in a particular project. Once you have staff who have successfully landed smaller contributions, you can start planning larger proposals. The exact same proposal might be unsuccessful when proposed by a new person, and successful when proposed by a person who already has a reputation for prior high-quality work.

Embrace all and any publicity you get Some companies have concerns about their employees working in the open. Indeed, every email and code patch an employee submits, and all related discussions become public. This may initially sound scary, but is actually a potential source of good publicity. Employees need to be trained on how to conduct themselves publicly, and the discussions about code should contain only information strictly related to the code, without any references to actual production environments or other sensitive information. In the long run most employees contributing have a positive impact and the company should reap the benefits of positive publicity. If there are quality issues or employee judgment issues, hiding the activity or forcing employees to contribute with pseudonyms is not a proper solution. Instead, the problems should be addressed at the root, and bad behavior addressed rather than tolerated. When people are working publicly, there tends to also be some degree of additional pride involved, which motivates people to try their best. Contributions need to be public for the sponsoring corporation to later be able to claim copyright or licenses. Considering that thousands of companies participate in open source every day, the prevalence of bad publicity is quite low, and the benefits far exceed the risks.

Scratch your own itch When choosing what to contribute, select things that benefit your own company. This is not purely about being selfish - often people working on resolving a problem they suffer from are the same people with the best expertise of what the problem is and what kind of solution is optimal. Also, the issues that are most pressing to your company are more likely to be universally useful to solve than any random bug or feature request in the upstream project s issue tracker.

Remember there are many ways to help upstream While submitting code is often considered the primary way to contribute, please keep in mind there are also other highly impactful ways to contribute. Submitting high-quality bug reports will help developers quickly identify and prioritize issues to fix. Providing good research, benchmarks, statistics or feedback helps guide development and the project make better design decisions. Documentation, translations, organizing events and providing marketing support can help increase adoption and strengthen long-term viability for the project. In some of the largest open source projects there are already far more pending contributions than the core maintainers can process. Therefore, developers who contribute code should also get into the habit of contributing reviews. As Linus law states, given enough eyeballs, all bugs are shallow. Reviewing other contributors submissions will help improve quality, and also alleviate the pressure on core maintainers who are the only ones providing feedback. Reviewing code submitted by others is also a great learning opportunity for the reviewer. The reviewer does not need to be better than the submitter - any feedback is useful; merely posting review feedback is not the same thing as making an approval decision. Many projects are also happy to accept monetary support and sponsorships. Some offer specific perks in return. By human nature, the largest sponsors always get their voice heard in important decisions, as no open source project wants to take actions that scare away major financial contributors.

Starting is the hardest part Long-term success in open source comes from a positive feedback loop of an ever-increasing number of users and collaborators. As seen in the examples of countless corporations contributing open source, the benefits are concrete, and the process usually runs well after the initial ramp-up and organizational learning phase has passed. In open source ecosystems, contributing upstream should be as natural as paying vendors in any business. If you are using open source and not contributing at all, you likely have latent business risks without realizing it. You don t want to wake up one morning to learn that your top talent left because they were forbidden from participating in open source for the company s benefit, or that you were fined due to CRA violations and mismanagement in sharing security fixes with the correct parties. The faster you start with the process, the less likely those risks will materialize.

24 June 2025

Evgeni Golov: Using LXCFS together with Podman

JP was puzzled that using podman run --memory=2G would not result in the 2G limit being visible inside the container. While we were able to identify this as a visualization problem tools like free(1) only look at /proc/meminfo and that is not virtualized inside a container, you'd have to look at /sys/fs/cgroup/memory.max and friends instead I couldn't leave it at that. And then I remembered there is actually something that can provide a virtual (cgroup-aware) /proc for containers: LXCFS! But does it work with Podman?! I always used it with LXC, but there is technically no reason why it wouldn't work with a different container solution cgroups are cgroups after all. As we all know: there is only one way to find out! Take a fresh Debian 12 VM, install podman and verify things behave as expected:
user@debian12:~$ podman run -ti --rm --memory=2G centos:stream9
bash-5.1# grep MemTotal /proc/meminfo
MemTotal:        6067396 kB
bash-5.1# cat /sys/fs/cgroup/memory.max
2147483648
And after installing (and starting) lxcfs, we can use the virtual /proc/meminfo it generates by bind-mounting it into the container (LXC does that part automatically for us):
user@debian12:~$ podman run -ti --rm --memory=2G --mount=type=bind,source=/var/lib/lxcfs/proc/meminfo,destination=/proc/meminfo centos:stream9
bash-5.1# grep MemTotal /proc/meminfo
MemTotal:        2097152 kB
bash-5.1# cat /sys/fs/cgroup/memory.max
2147483648
The same of course works with all the other proc entries lxcfs provides (cpuinfo, diskstats, loadavg, meminfo, slabinfo, stat, swaps, and uptime here), just bind-mount them. And yes, free(1) now works too!
bash-5.1# free -m
               total        used        free      shared  buff/cache   available
Mem:            2048           3        1976           0          67        2044
Swap:              0           0           0
Just don't blindly mount the whole /var/lib/lxcfs/proc over the container's /proc. It did work (as in: "bash and free didn't crash") for me, but with /proc/$PID etc missing, I bet things will go south pretty quickly.

Dirk Eddelbuettel: RcppRedis 0.2.6 on CRAN: Extensions

A new minor release 0.2.6 of our RcppRedis package arrived on CRAN today. RcppRedis is one of several packages connecting R to the fabulous Redis in-memory datastructure store (and much more). It works equally well with the newer fork Valkey. RcppRedis does not pretend to be feature complete, but it may do some things faster than the other interfaces, and also offers an optional coupling with MessagePack binary (de)serialization via RcppMsgPack. The package has been deployed in production as a risk / monitoring tool on a trading floor for several years. It also supports pub/sub dissemination of streaming market data as per this earlier example. This update brings new functions del, lrem, and lmove (for the matching Redis / Valkey commands) which may be helpful in using Redis (or Valkey) as a job queue. We also extended the publish accessor by supporting text (i.e. string) mode along with raw or rds (the prior default which always serialized R objects) just how listen already worked with these three cases. The change makes it possible to publish from R to subscribers not running R as they cannot rely on the R deserealizer. An example is provided by almm, a live market monitor, which we introduced in this blog post. Apart from that the continuous integration script received another mechanical update. The detailed changes list follows.

Changes in version 0.2.6 (2025-06-24)
  • The commands DEL, LREM and LMOVE have been added
  • The continuous integration setup was updated once more
  • The pub/sub publisher now supports a type argument similar to the listener, this allows string message publishing for non-R subscribers

Courtesy of my CRANberries, there is also a diffstat report for this this release. More information is on the RcppRedis page and at the repository and its issue tracker.

This post by Dirk Eddelbuettel originated on his Thinking inside the box blog. If you like this or other open-source work I do, you can sponsor me at GitHub.

21 June 2025

Ravi Dwivedi: Getting Brunei visa

In December 2024, my friend Badri and I were planning a trip to Southeast Asia. At this point, we were planning to visit Singapore, Malaysia and Vietnam. My Singapore visa had already been approved, and Malaysia was visa-free for us. For Vietnam, we had to apply for an e-visa online. We considered adding Brunei to our itinerary. I saw some videos of the Brunei visa process and got the impression that we needed to go to the Brunei embassy in Kuching, Malaysia in person. However, when I happened to search for Brunei on Organic Maps1, I stumbled upon the Brunei Embassy in Delhi. It seemed to be somewhere in Hauz Khas. As I was going to Delhi to collect my Singapore visa the next day, I figured I d also visit the Brunei Embassy to get information about the visa process. The next day I went to the location displayed by Organic Maps. It was next to the embassy of Madagascar, and a sign on the road divider confirmed that I was at the right place. That said, it actually looked like someone s apartment. I entered and asked for directions to the Brunei embassy, but the people inside did not seem to understand my query. After some back and forth, I realized that the embassy wasn t there. I now searched for the Brunei embassy on the Internet, and this time I got an address in Vasant Vihar. It seemed like the embassy had been moved from Hauz Khas to Vasant Vihar. Going by the timings mentioned on the web page, the embassy was closing in an hour. I took a Metro from Hauz Khas to Vasant Vihar. After deboarding at the Vasant Vihar metro station, I took an auto to reach the embassy. The address listed on the webpage got me into the correct block. However, the embassy was still nowhere to be seen. I asked around, but security guards in that area pointed me to the Burundi embassy instead. After some more looking around, I did end up finding the embassy. I spoke to the security guards at the gate and told them that I would like to know the visa process. They dialled a number and asked that person to tell me the visa process. I spoke to a lady on the phone. She listed the documents required for the visa process and mentioned that the timings for visa application were from 9 o clock to 11 o clock in the morning. She also informed me that the visa fees was 1000. I also asked about the process Badri, who lives far away in Tamil Nadu and cannot report at the embassy physically. She told me that I can submit a visa application on his behalf, along with an authorization letter. Having found the embassy in Delhi was a huge relief. The other plan - going to Kuching, Malaysia - was a bit uncertain, and we didn t know how much time it would take. Getting our passport submitted at an embassy in a foreign country was also not ideal. A few days later, Badri sent me all the documents required for his visa. I went to the embassy and submitted both the applications. The lady who collected our visa submissions asked me for our flight reservations from Delhi to Brunei, whereas ours were (keeping with our itinerary) from Kuala Lampur. She said that she might contact me later if it was required. For reference, here is the list of documents we submitted - I then asked about the procedure to collect the passports and visa results. Usually, embassies will tell you that they will contact you when they have decided on your applications. However, here I was informed that if they don t contact me within 5 days, I can come and collect our passports and visa result between 13:30-14:30 hours on the fifth day. That was strange :) I did visit the embassy to collect our visa results on the fifth day. However, the lady scolded me for not bringing the receipt she gave me. I was afraid that I might have to go all the way back home and bring the receipt to get our passports. The travel date was close, and it would take some time for Badri to receive his passport via courier as well. Fortunately, she gave me our passports (with the visa attached) and asked me to share a scanned copy of the receipt via email after I get home. We were elated that our visas were approved. Now we could focus on booking our flights. If you are going to Brunei, remember to fill their arrival card from the website within 48 hours of your arrival! Thanks to Badri and Contrapunctus for reviewing the draft before publishing the article.

  1. Nowadays, I prefer using Comaps instead of Organic Maps and recommend you do the same. Organic Maps had some issues with its governance and the community issues weren t being addressed.

19 June 2025

Jonathan Carter: My first tag2upload upload

Tag2upload? The tag2upload service has finally gone live for Debian Developers in an open beta. If you ve never heard of tag2upload before, here is a great primer presented by Ian Jackson and prepared by Ian Jackson and Sean Whitton. In short, the world has moved on to hosting and working with source code in Git repositories. In Debian, we work with source packages that are used to generated the binary artifacts that users know as .deb files. In Debian, there is so much tooling and culture built around this. For example, our workflow passes what we call the island test you could take every source package in Debian along with you to an island with no Internet, and you ll still be able to rebuild or modify every package. When changing the workflows, you risk losing benefits like this, and over the years there has been a number of different ideas on how to move to a purely or partially git flow for Debian, none that really managed to gain enough momentum or project-wide support. Tag2upload makes a lot of sense. It doesn t take away any of the benefits of the current way of working (whether technical or social), but it does make some aspects of Debian packages significantly simpler and faster. Even so, if you re a Debian Developer and more familiar with how the sausage have made, you ll have noticed that this has been a very long road for the tag2upload maintainers, they ve hit multiple speed bumps since 2019, but with a lot of patience and communication and persistence from all involved (and almost even a GR), it is finally materializing.

Performing my first tag2upload So, first, I needed to choose which package I want to upload. We re currently in hard freeze for the trixie release, so I ll look for something simple that I can upload to experimental.
I chose bundlewrap, it s quote a straightforward python package, and updates are usually just as straightforward, so it s probably a good package to work on without having to deal with extra complexities in learning how to use tag2upload. So, I do the usual uscan and dch -i to update my package
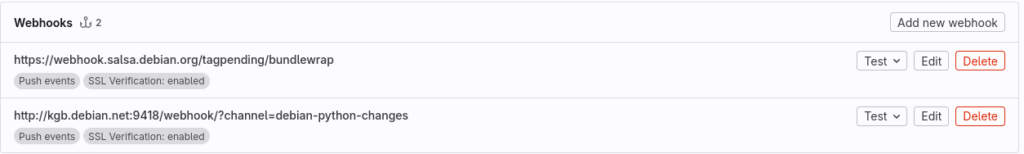
And then I realise that I still want to build a source package to test it in cowbuilder. Hmm, I remember that Helmut showed me that building a source package isn t necessary in sbuild, but I have a habit of breaking my sbuild configs somehow, but I guess I should revisit that. So, I do a dpkg-buildpackage -S -sa and test it out with cowbuilder, because that s just how I roll (at least for now, fixing my local sbuild setup is yak shaving for another day, let s focus!). I end up with a binary that looks good, so I m satisfied that I can upload this package to the Debian archives. So, time to configure tag2upload. The first step is to set up the webhook in Salsa. I was surprised two find two webhooks already configured:
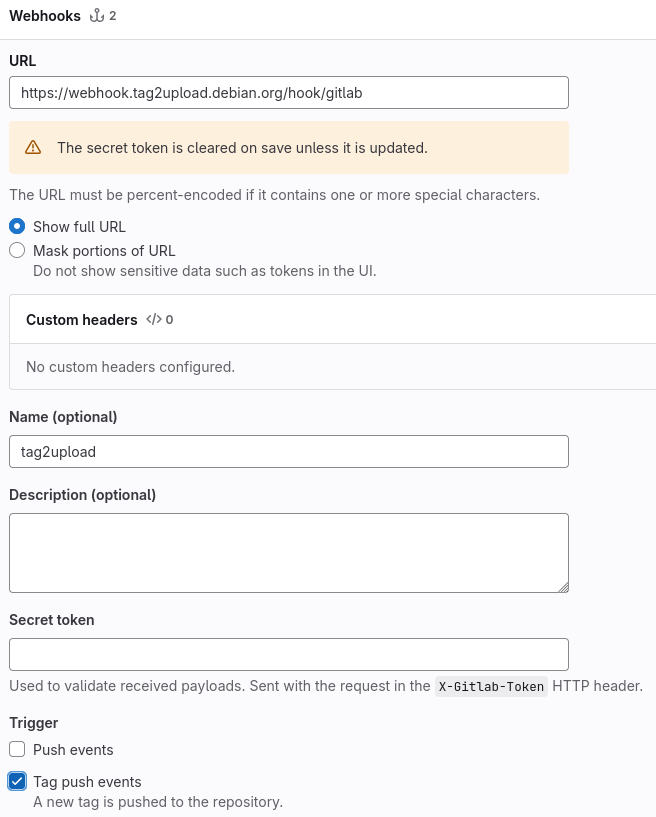
I know of KGB that posts to IRC, didn t know that this was the mechanism it does that by before. Nice! Also don t know what the tagpending one does, I ll go look into that some other time. Configuring a tag2upload webhook is quite simple, add a URL, call the name tag2upload, and select only tag push events:
I run the test webhook, and it returned a code 400 message about a missing message header, which the documentation says is normal. Next, I install git-debpush from experimental. The wiki page simply states that you can use the git-debpush command to upload, but doesn t give any examples on how to use it, and its manpage doesn t either. And when I run just git-debpush I get:
jonathan@lapcloud:~/devel/debian/python-team/bundlewrap/bundlewrap-4.23.1$ git-debpush
git-debpush: check failed: upstream tag upstream/4.22.0 is not an ancestor of refs/heads/debian/master; probably a mistake ('upstream-nonancestor' check)
pristine-tar is /usr/bin/pristine-tar
git-debpush: some check(s) failed; you can pass --force to ignore them
I have no idea what that s supposed to mean. I was also not sure whether I should tag anything to begin with, or if some part of the tag2upload machinery automatically does it. I think I might have tagged debian/4.23-1 before tagging upstream/4.23 and perhaps it didn t like it, I reverted and did it the other way around and got a new error message. Progress!
jonathan@lapcloud:~/devel/debian/python-team/bundlewrap/bundlewrap-4.23.1$ git-debpush
git-debpush: could not determine the git branch layout
git-debpush: please supply a --quilt= argument
Looking at the manpage, it looks like quilt=baredebian matches my package the best, so I try that:
jonathan@lapcloud:~/devel/debian/python-team/bundlewrap/bundlewrap-4.23.1$ git-debpush --quilt=baredebian
Enumerating objects: 70, done.
Counting objects: 100% (70/70), done.
Delta compression using up to 12 threads
Compressing objects: 100% (37/37), done.
Writing objects: 100% (37/37), 8.97 KiB   2.99 MiB/s, done.
Total 37 (delta 30), reused 0 (delta 0), pack-reused 0 (from 0)
To salsa.debian.org:python-team/packages/bundlewrap.git
6f55d99..3d5498f debian/master -> debian/master
 * [new tag] upstream/4.23.1 -> upstream/4.23.1
 * [new tag] debian/4.23.1-1_exp1 -> debian/4.23.1-1_exp1
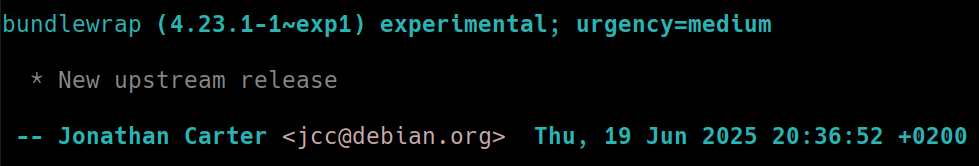
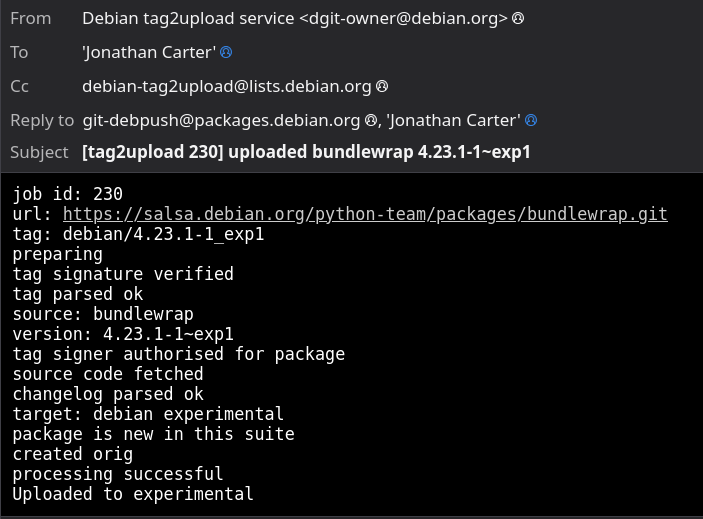
Ooh! That looked like it did something! And a minute later I received the notification of the upload in my inbox:
So, I m not 100% sure that this makes things much easier for me than doing a dput, but, it s not any more difficult or more work either (once you know how it works), so I ll be using git-debpush from now on, and I m sure as I get more used to the git workflow of doing things I ll understand more of the benefits. And at last, my one last use case for using FTP is now properly dead. RIP FTP :)

18 June 2025

Sergio Durigan Junior: GCC, glibc, stack unwinding and relocations A war story

I ve been meaning to write a post about this bug for a while, so here it is (before I forget the details!). First, I d like to thank a few people: I ll probably forget some details because it s been more than a week (and life at $DAYJOB moves fast), but we ll see.

The background story Wolfi OS takes security seriously, and one of the things we have is a package which sets the hardening compiler flags for C/C++ according to the best practices recommended by OpenSSF. At the time of this writing, these flags are (in GCC s spec file parlance):
*self_spec:
+ % !O:% !O1:% !O2:% !O3:% !O0:% !Os:% !0fast:% !0g:% !0z:-O2  -fhardened -Wno-error=hardened -Wno-hardened % !fdelete-null-pointer-checks:-fno-delete-null-pointer-checks  -fno-strict-overflow -fno-strict-aliasing % !fomit-frame-pointer:-fno-omit-frame-pointer  -mno-omit-leaf-frame-pointer
*link:
+ --as-needed -O1 --sort-common -z noexecstack -z relro -z now
The important part for our bug is the usage of -z now and -fno-strict-aliasing. As I was saying, these flags are set for almost every build, but sometimes things don t work as they should and we need to disable them. Unfortunately, one of these problematic cases has been glibc. There was an attempt to enable hardening while building glibc, but that introduced a strange breakage to several of our packages and had to be reverted. Things stayed pretty much the same until a few weeks ago, when I started working on one of my roadmap items: figure out why hardening glibc wasn t working, and get it to work as much as possible.

Reproducing the bug I started off by trying to reproduce the problem. It s important to mention this because I often see young engineers forgetting to check if the problem is even valid anymore. I don t blame them; the anxiety to get the bug fixed can be really blinding. Fortunately, I already had one simple test to trigger the failure. All I had to do was install the py3-matplotlib package and then invoke:
$ python3 -c 'import matplotlib'
This would result in an abortion with a coredump. I followed the steps above, and readily saw the problem manifesting again. OK, first step is done; I wasn t getting out easily from this one.

Initial debug The next step is to actually try to debug the failure. In an ideal world you get lucky and are able to spot what s wrong after just a few minutes. Or even better: you also can devise a patch to fix the bug and contribute it to upstream. I installed GDB, and then ran the py3-matplotlib command inside it. When the abortion happened, I issued a backtrace command inside GDB to see where exactly things had gone wrong. I got a stack trace similar to the following:
#0  0x00007c43afe9972c in __pthread_kill_implementation () from /lib/libc.so.6
#1  0x00007c43afe3d8be in raise () from /lib/libc.so.6
#2  0x00007c43afe2531f in abort () from /lib/libc.so.6
#3  0x00007c43af84f79d in uw_init_context_1[cold] () from /usr/lib/libgcc_s.so.1
#4  0x00007c43af86d4d8 in _Unwind_RaiseException () from /usr/lib/libgcc_s.so.1
#5  0x00007c43acac9014 in __cxxabiv1::__cxa_throw (obj=0x5b7d7f52fab0, tinfo=0x7c429b6fd218 <typeinfo for pybind11::attribute_error>, dest=0x7c429b5f7f70 <pybind11::reference_cast_error::~reference_cast_error() [clone .lto_priv.0]>)
    at ../../../../libstdc++-v3/libsupc++/eh_throw.cc:93
#6  0x00007c429b5ec3a7 in ft2font__getattr__(std::__cxx11::basic_string<char, std::char_traits<char>, std::allocator<char> >) [clone .lto_priv.0] [clone .cold] () from /usr/lib/python3.13/site-packages/matplotlib/ft2font.cpython-313-x86_64-linux-gnu.so
#7  0x00007c429b62f086 in pybind11::cpp_function::initialize<pybind11::object (*&)(std::__cxx11::basic_string<char, std::char_traits<char>, std::allocator<char> >), pybind11::object, std::__cxx11::basic_string<char, std::char_traits<char>, std::allocator<char> >, pybind11::name, pybind11::scope, pybind11::sibling>(pybind11::object (*&)(std::__cxx11::basic_string<char, std::char_traits<char>, std::allocator<char> >), pybind11::object (*)(std::__cxx11::basic_string<char, std::char_traits<char>, std::allocator<char> >), pybind11::name const&, pybind11::scope const&, pybind11::sibling const&):: lambda(pybind11::detail::function_call&)#1 ::_FUN(pybind11::detail::function_call&) [clone .lto_priv.0] ()
   from /usr/lib/python3.13/site-packages/matplotlib/ft2font.cpython-313-x86_64-linux-gnu.so
#8  0x00007c429b603886 in pybind11::cpp_function::dispatcher(_object*, _object*, _object*) () from /usr/lib/python3.13/site-packages/matplotlib/ft2font.cpython-313-x86_64-linux-gnu.so
...
Huh. Initially this didn t provide me with much information. There was something strange seeing the abort function being called right after _Unwind_RaiseException, but at the time I didn t pay much attention to it. OK, time to expand our horizons a little. Remember when I said that several of our packages would crash with a hardened glibc? I decided to look for another problematic package so that I could make it crash and get its stack trace. My thinking here is that maybe if I can compare both traces, something will come up. I happened to find an old discussion where Dann Frazier mentioned that Emacs was also crashing for him. He and I share the Emacs passion, and I totally agreed with him when he said that Emacs crashing is priority -1! (I m paraphrasing). I installed Emacs, ran it, and voil : the crash happened again. OK, that was good. When I ran Emacs inside GDB and asked for a backtrace, here s what I got:
#0  0x00007eede329972c in __pthread_kill_implementation () from /lib/libc.so.6
#1  0x00007eede323d8be in raise () from /lib/libc.so.6
#2  0x00007eede322531f in abort () from /lib/libc.so.6
#3  0x00007eede262879d in uw_init_context_1[cold] () from /usr/lib/libgcc_s.so.1
#4  0x00007eede2646e7c in _Unwind_Backtrace () from /usr/lib/libgcc_s.so.1
#5  0x00007eede3327b11 in backtrace () from /lib/libc.so.6
#6  0x000059535963a8a1 in emacs_backtrace ()
#7  0x000059535956499a in main ()
Ah, this backtrace is much simpler to follow. Nice. Hmmm. Now the crash is happening inside _Unwind_Backtrace. A pattern emerges! This must have something to do with stack unwinding (or so I thought keep reading to discover the whole truth). You see, the backtrace function (yes, it s a function) and C++ s exception handling mechanism use similar techniques to do their jobs, and it pretty much boils down to unwinding frames from the stack. I looked into Emacs source code, specifically the emacs_backtrace function, but could not find anything strange over there. This bug was probably not going to be an easy fix

The quest for a minimal reproducer Being able to easily reproduce the bug is awesome and really helps with debugging, but even better is being able to have a minimal reproducer for the problem. You see, py3-matplotlib is a huge package and pulls in a bunch of extra dependencies, so it s not easy to ask other people to just install this big package plus these other dependencies, and then run this command , especially if we have to file an upstream bug and talk to people who may not even run the distribution we re using. So I set up to try and come up with a smaller recipe to reproduce the issue, ideally something that s not tied to a specific package from the distribution. Having all the information gathered from the initial debug session, especially the Emacs backtrace, I thought that I could write a very simple program that just invoked the backtrace function from glibc in order to trigger the code path that leads to _Unwind_Backtrace. Here s what I wrote:
#include <execinfo.h>

int
main(int argc, char *argv[])
 
  void *a[4096];
  backtrace (a, 100);
  return 0;
 
After compiling it, I determined that yes, the problem did happen with this small program as well. There was only a small nuisance: the manifestation of the bug was not deterministic, so I had to execute the program a few times until it crashed. But that s much better than what I had before, and a small price to pay. Having a minimal reproducer pretty much allows us to switch our focus to what really matters. I wouldn t need to dive into Emacs or Python s source code anymore. At the time, I was sure this was a glibc bug. But then something else happened.

GCC 15 I had to stop my investigation efforts because something more important came up: it was time to upload GCC 15 to Wolfi. I spent a couple of weeks working on this (it involved rebuilding the whole archive, filing hundreds of FTBFS bugs, patching some programs, etc.), and by the end of it the transition went smooth. When the GCC 15 upload was finally done, I switched my focus back to the glibc hardening problem. The first thing I did was to yes, reproduce the bug again. It had been a few weeks since I had touched the package, after all. So I built a hardened glibc with the latest GCC and the bug did not happen anymore! Fortunately, the very first thing I thought was this must be GCC , so I rebuilt the hardened glibc with GCC 14, and the bug was there again. Huh, unexpected but very interesting.

Diving into glibc and libgcc At this point, I was ready to start some serious debugging. And then I got a message on Signal. It was one of those moments where two minds think alike: Gabriel decided to check how I was doing, and I was thinking about him because this involved glibc, and Gabriel contributed to the project for many years. I explained what I was doing, and he promptly offered to help. Yes, there are more people who love low level debugging! We spent several hours going through disassembles of certain functions (because we didn t have any debug information in the beginning), trying to make sense of what we were seeing. There was some heavy GDB involved; unfortunately I completely lost the session s history because it was done inside a container running inside an ephemeral VM. But we learned a lot. For example:
  • It was hard to actually understand the full stack trace leading to uw_init_context_1[cold]. _Unwind_Backtrace obviously didn t call it (it called uw_init_context_1, but what was that [cold] doing?). We had to investigate the disassemble of uw_init_context_1 in order to determined where uw_init_context_1[cold] was being called.
  • The [cold] suffix is a GCC function attribute that can be used to tell the compiler that the function is unlikely to be reached. When I read that, my mind immediately jumped to this must be an assertion , so I went to the source code and found the spot.
  • We were able to determine that the return code of uw_frame_state_for was 5, which means _URC_END_OF_STACK. That s why the assertion was triggering.
After finding these facts without debug information, I decided to bite the bullet and recompiled GCC 14 with -O0 -g3, so that we could debug what uw_frame_state_for was doing. After banging our heads a bit more, we found that fde is NULL at this excerpt:
// ...
  fde = _Unwind_Find_FDE (context->ra + _Unwind_IsSignalFrame (context) - 1,
                          &context->bases);
  if (fde == NULL)
     
#ifdef MD_FALLBACK_FRAME_STATE_FOR
      /* Couldn't find frame unwind info for this function.  Try a
         target-specific fallback mechanism.  This will necessarily
         not provide a personality routine or LSDA.  */
      return MD_FALLBACK_FRAME_STATE_FOR (context, fs);
#else
      return _URC_END_OF_STACK;
#endif
     
// ...
We re debugging on amd64, which means that MD_FALLBACK_FRAME_STATE_FOR is defined and therefore is called. But that s not really important for our case here, because we had established before that _Unwind_Find_FDE would never return NULL when using a non-hardened glibc (or a glibc compiled with GCC 15). So we decided to look into what _Unwind_Find_FDE did. The function is complex because it deals with .eh_frame , but we were able to pinpoint the exact location where find_fde_tail (one of the functions called by _Unwind_Find_FDE) is returning NULL:
if (pc < table[0].initial_loc + data_base)
  return NULL;
We looked at the addresses of pc and table[0].initial_loc + data_base, and found that the former fell within libgcc s text section, which the latter fell within /lib/ld-linux-x86-64.so.2 text. At this point, we were already too tired to continue. I decided to keep looking at the problem later and see if I could get any further.

Bisecting GCC The next day, I woke up determined to find what changed in GCC 15 that caused the bug to disappear. Unless you know GCC s internals like they are your own home (which I definitely don t), the best way to do that is to git bisect the commits between GCC 14 and 15. I spent a few days running the bisect. It took me more time than I d have liked to find the right range of commits to pass git bisect (because of how branches and tags are done in GCC s repository), and I also had to write some helper scripts that:
  • Modified the gcc.yaml package definition to make it build with the commit being bisected.
  • Built glibc using the GCC that was just built.
  • Ran tests inside a docker container (with the recently built glibc installed) to determine whether the bug was present.
At the end, I had a commit to point to:
commit 99b1daae18c095d6c94d32efb77442838e11cbfb
Author: Richard Biener <rguenther@suse.de>
Date:   Fri May 3 14:04:41 2024 +0200
    tree-optimization/114589 - remove profile based sink heuristics
Makes sense, right?! No? Well, it didn t for me either. Even after reading what was changed in the code and the upstream bug fixed by the commit, I was still clueless as to why this change fixed the problem (I say fixed because it may very well be an unintended consequence of the change, and some other problem might have been introduced).

Upstream takes over After obtaining the commit that possibly fixed the bug, while talking to Dann and explaining what I did, he suggested that I should file an upstream bug and check with them. Great idea, of course. I filed the following upstream bug: https://gcc.gnu.org/bugzilla/show_bug.cgi?id=120653 It s a bit long, very dense and complex, but ultimately upstream was able to find the real problem and have a patch accepted in just two days. Nothing like knowing the code base. The initial bug became: https://sourceware.org/bugzilla/show_bug.cgi?id=33088 In the end, the problem was indeed in how the linker defines __ehdr_start, which, according to the code (from elf/dl-support.c):
if (_dl_phdr == NULL)
   
    /* Starting from binutils-2.23, the linker will define the
       magic symbol __ehdr_start to point to our own ELF header
       if it is visible in a segment that also includes the phdrs.
       So we can set up _dl_phdr and _dl_phnum even without any
       information from auxv.  */


    extern const ElfW(Ehdr) __ehdr_start attribute_hidden;
    assert (__ehdr_start.e_phentsize == sizeof *GL(dl_phdr));
    _dl_phdr = (const void *) &__ehdr_start + __ehdr_start.e_phoff;
    _dl_phnum = __ehdr_start.e_phnum;
   
But the following definition is the problematic one (from elf/rtld.c):
extern const ElfW(Ehdr) __ehdr_start attribute_hidden;
This symbol (along with its counterpart, __ehdr_end) was being run-time relocated when it shouldn t be. The fix that was pushed added optimization barriers to prevent the compiler from doing the relocations. I don t claim to fully understand what was done here, and Jakub s analysis is a thing to behold, but in the end I was able to confirm that the patch fixed the bug. And in the end, it was indeed a glibc bug.

Conclusion This was an awesome bug to investigate. It s one of those that deserve a blog post, even though some of the final details of the fix flew over my head. I d like to start blogging more about these sort of bugs, because I ve encountered my fair share of them throughout my career. And it was great being able to do some debugging with another person, exchange ideas, learn things together, and ultimately share that deep satisfaction when we find why a crash is happening. I have at least one more bug in my TODO list to write about (another one with glibc, but this time I was able to get to the end of it and come up with a patch). Stay tunned. P.S.: After having published the post I realized that I forgot to explain why the -z now and -fno-strict-aliasing flags were important. -z now is the flag that I determined to be the root cause of the breakage. If I compiled glibc with every hardening flag except -z now, everything worked. So initially I thought that the problem had to do with how ld.so was resolving symbols at runtime. As it turns out, this ended up being more a symptom than the real cause of the bug. As for -fno-strict-aliasing, a Gentoo developer who commented on the GCC bug above mentioned that this OpenSSF bug had a good point against using this flag for hardening. I still have to do a deep dive on what was discussed in the issue, but this is certainly something to take into consideration. There s this very good write-up about strict aliasing in general if you re interested in understanding it better.

17 June 2025

Evgeni Golov: Arguing with an AI or how Evgeni tried to use CodeRabbit

Everybody is trying out AI assistants these days, so I figured I'd jump on that train and see how fast it derails. I went with CodeRabbit because I've seen it on YouTube ads work, I guess. I am trying to answer the following questions: To reduce the amount of output and not to confuse contributors, CodeRabbit was configured to only do reviews on demand. What follows is a rather unscientific evaluation of CodeRabbit based on PRs in two Foreman-related repositories, looking at the summaries CodeRabbit posted as well as the comments/suggestions it had about the code. Ansible 2.19 support PR: theforeman/foreman-ansible-modules#1848 summary posted The summary CodeRabbit posted is technically correct.
This update introduces several changes across CI configuration, Ansible roles, plugins, and test playbooks. It expands CI test coverage to a new Ansible version, adjusts YAML key types in test variables, refines conditional logic in Ansible tasks, adds new default variables, and improves clarity and consistency in playbook task definitions and debug output.
Yeah, it does all of that, all right. But it kinda misses the point that the addition here is "Ansible 2.19 support", which starts with adding it to the CI matrix and then adjusting the code to actually work with that version. Also, the changes are not for "clarity" or "consistency", they are fixing bugs in the code that the older Ansible versions accepted, but the new one is more strict about. Then it adds a table with the changed files and what changed in there. To me, as the author, it felt redundant, and IMHO doesn't add any clarity to understand the changes. (And yes, same "clarity" vs bugfix mistake here, but that makes sense as it apparently miss-identified the change reason) And then the sequence diagrams They probably help if you have a dedicated change to a library or a library consumer, but for this PR it's just noise, especially as it only covers two of the changes (addition of 2.19 to the test matrix and a change to the inventory plugin), completely ignoring other important parts. Overall verdict: noise, don't need this. comments posted CodeRabbit also posted 4 comments/suggestions to the changes. Guard against undefined result.task IMHO a valid suggestion, even if on the picky side as I am not sure how to make it undefined here. I ended up implementing it, even if with slightly different (and IMHO better readable) syntax. Inconsistent pipeline in when for composite CV versions That one was funny! The original complaint was that the when condition used slightly different data manipulation than the data that was passed when the condition was true. The code was supposed to do "clean up the data, but only if there are any items left after removing the first 5, as we always want to keep 5 items". And I do agree with the analysis that it's badly maintainable code. But the suggested fix was to re-use the data in the variable we later use for performing the cleanup. While this is (to my surprise!) valid Ansible syntax, it didn't make the code much more readable as you need to go and look at the variable definition. The better suggestion then came from Ewoud: to compare the length of the data with the number we want to keep. Humans, so smart! But Ansible is not Ewoud's native turf, so he asked whether there is a more elegant way to count how much data we have than to use list count in Jinja (the data comes from a Python generator, so needs to be converted to a list first). And the AI helpfully suggested to use count instead! However, count is just an alias for length in Jinja, so it behaves identically and needs a list. Luckily the AI quickly apologized for being wrong after being pointed at the Jinja source and didn't try to waste my time any further. Wouldn't I have known about the count alias, we'd have committed that suggestion and let CI fail before reverting again. Apply the same fix for non-composite CV versions The very same complaint was posted a few lines later, as the logic there is very similar just slightly different data to be filtered and cleaned up. Interestingly, here the suggestion also was to use the variable. But there is no variable with the data! The text actually says one need to "define" it, yet the "committable suggestion" doesn't contain that part. Interestingly, when asked where it sees the "inconsistency" in that hunk, it said the inconsistency is with the composite case above. That however is nonsense, as while we want to keep the same number of composite and non-composite CV versions, the data used in the task is different it even gets consumed by a totally different playbook so there can't be any real consistency between the branches. I ended up applying the same logic as suggested by Ewoud above. As that refactoring was possible in a consistent way. Ensure consistent naming for Oracle Linux subscription defaults One of the changes in Ansible 2.19 is that Ansible fails when there are undefined variables, even if they are only undefined for cases where they are unused. CodeRabbit complains that the names of the defaults I added are inconsistent. And that is technically correct. But those names are already used in other places in the code, so I'd have to refactor more to make it work properly. Once being pointed at the fact that the variables already exist, the AI is as usual quick to apologize, yay. add new parameters to the repository module PR: theforeman/foreman-ansible-modules#1860 summary posted Again, the summary is technically correct
The repository module was updated to support additional parameters for repository synchronization and authentication. New options were added for ansible collections, ostree, Python packages, and yum repositories, including authentication tokens, filtering controls, and version retention settings. All changes were limited to module documentation and argument specification.
But it doesn't add anything you'd not get from looking at the diff, especially as it contains a large documentation chunk explaining those parameters. No sequence diagram this time. That's a good thing! Overall verdict: noise (even if the amount is small), don't need this. comments posted CodeRabbit generated two comments for this PR. Interestingly, none of them overlapped with the issues ansible-lint and friends found. get rid of the FIXMEs Yepp, that's fair add validation for the new parameters Yepp, I forgot these (not intentionally!). The diff it suggests is nonsense, as it doesn't take into account the existing Ansible and Yum validations, but it clearly has read them as the style etc of the new ones matches. It also managed to group the parameters correctly by repository type, so it's something.
 if module.foreman_params['content_type'] != 'ansible_collection':
     invalid_list = [key for key in ['ansible_collection_requirements'] if key in module.foreman_params]
     if invalid_list:
         module.fail_json(msg="( 0 ) can only be used with content_type 'ansible_collection'".format(",".join(invalid_list)))
+
+# Validate ansible_collection specific parameters
+if module.foreman_params['content_type'] != 'ansible_collection':
+    invalid_list = [key for key in ['ansible_collection_auth_token', 'ansible_collection_auth_url'] if key in module.foreman_params]
+    if invalid_list:
+        module.fail_json(msg="( 0 ) can only be used with content_type 'ansible_collection'".format(",".join(invalid_list)))
+
+# Validate ostree specific parameters
+if module.foreman_params['content_type'] != 'ostree':
+    invalid_list = [key for key in ['depth', 'exclude_refs', 'include_refs'] if key in module.foreman_params]
+    if invalid_list:
+        module.fail_json(msg="( 0 ) can only be used with content_type 'ostree'".format(",".join(invalid_list)))
+
+# Validate python package specific parameters
+if module.foreman_params['content_type'] != 'python':
+    invalid_list = [key for key in ['excludes', 'includes', 'package_types', 'keep_latest_packages'] if key in module.foreman_params]
+    if invalid_list:
+        module.fail_json(msg="( 0 ) can only be used with content_type 'python'".format(",".join(invalid_list)))
+
+# Validate yum specific parameter
+if module.foreman_params['content_type'] != 'yum' and 'upstream_authentication_token' in module.foreman_params:
+    module.fail_json(msg="upstream_authentication_token can only be used with content_type 'yum'")
Interestingly, it also said "Note: If 'python' is not a valid content_type, please adjust the validation accordingly." which is quite a hint at a bug in itself. The module currently does not even allow to create content_type=python repositories. That should have been more prominent, as it's a BUG! parameter persistence in obsah PR: theforeman/obsah#72 summary posted Mostly correct. It did miss-interpret the change to a test playbook as an actual "behavior" change: "Introduced new playbook variables for database configuration" there is no database configuration in this repository, just the test playbook using the same metadata as a consumer of the library. Later on it does say "Playbook metadata and test fixtures", so unclear whether this is a miss-interpretation or just badly summarized. As long as you also look at the diff, it won't confuse you, but if you're using the summary as the sole source of information (bad!) it would. This time the sequence diagram is actually useful, yay. Again, not 100% accurate: it's missing the fact that saving the parameters is hidden behind an "if enabled" flag something it did represent correctly for loading them. Overall verdict: not really useful, don't need this. comments posted Here I was a bit surprised, especially as the nitpicks were useful! Persist-path should respect per-user state locations (nitpick) My original code used os.environ.get('OBSAH_PERSIST_PATH', '/var/lib/obsah/parameters.yaml') for the location of the persistence file. CodeRabbit correctly pointed out that this won't work for non-root users and one should respect XDG_STATE_HOME. Ewoud did point that out in his own review, so I am not sure whether CodeRabbit came up with this on its own, or also took the human comments into account. The suggested code seems fine too just doesn't use /var/lib/obsah at all anymore. This might be a good idea for the generic library we're working on here, and then be overridden to a static /var/lib path in a consumer (which always runs as root). In the end I did not implement it, but mostly because I was lazy and was sure we'd override it anyway. Positional parameters are silently excluded from persistence (nitpick) The library allows you to generate both positional (foo without --) and non-positional (--foo) parameters, but the code I wrote would only ever persist non-positional parameters. This was intentional, but there is no documentation of the intent in a comment which the rabbit thought would be worth pointing out. It's a fair nitpick and I ended up adding a comment. Enforce FQDN validation for database_host The library has a way to perform type checking on passed parameters, and one of the supported types is "FQDN" so a fully qualified domain name, with dots and stuff. The test playbook I added has a database_host variable, but I didn't bother adding a type to it, as I don't really need any type checking here. While using "FQDN" might be a bit too strict here technically a working database connection can also use a non-qualified name or an IP address, I was positively surprised by this suggestion. It shows that the rest of the repository was taken into context when preparing the suggestion. reset_args() can raise AttributeError when a key is absent This is a correct finding, the code is not written in a way that would survive if it tries to reset things that are not set. However, that's only true for the case where users pass in --reset-<parameter> without ever having set parameter before. The complaint about the part where the parameter is part of the persisted set but not in the parsed args is wrong as parsed args inherit from the persisted set. The suggested code is not well readable, so I ended up fixing it slightly differently. Persisted values bypass argparse type validation When persisting, I just yaml.safe_dump the parsed parameters, which means the YAML will contain native types like integers. The argparse documentation warns that the type checking argparse does only applies to strings and is skipped if you pass anything else (via default values). While correct, it doesn't really hurt here as the persisting only happens after the values were type-checked. So there is not really a reason to type-check them again. Well, unless the type changes, anyway. Not sure what I'll do with this comment. consider using contextlib.suppress This was added when I asked CodeRabbit for a re-review after pushing some changes. Interestingly, the PR already contained try: except: pass code before, and it did not flag that. Also, the code suggestion contained import contextlib in the middle of the code, instead in the head of the file. Who would do that?! But the comment as such was valid, so I fixed it in all places it is applicable, not only the one the rabbit found. workaround to ensure LCE and CV are always sent together PR: theforeman/foreman-ansible-modules#1867 summary posted
A workaround was added to the _update_entity method in the ForemanAnsibleModule class to ensure that when updating a host, both content_view_id and lifecycle_environment_id are always included together in the update payload. This prevents partial updates that could cause inconsistencies.
Partial updates are not a thing. The workaround is purely for the fact that Katello expects both parameters to be sent, even if only one of them needs an actual update. No diagram, good. Overall verdict: misleading summaries are bad! comments posted Given a small patch, there was only one comment. Implementation looks correct, but consider adding error handling for robustness. This reads correct on the first glance. More error handling is always better, right? But if you dig into the argumentation, you see it's wrong. Either: The AI accepted defeat once I asked it to analyze things in more detail, but why did I have to ask in the first place?! Summary Well, idk, really. Did the AI find things that humans did not find (or didn't bother to mention)? Yes. It's debatable whether these were useful (see e.g. the database_host example), but I tend to be in the "better to nitpick/suggest more and dismiss than oversee" team, so IMHO a positive win. Did the AI output help the humans with the review (useful summary etc)? In my opinion it did not. The summaries were either "lots of words, no real value" or plain wrong. The sequence diagrams were not useful either. Luckily all of that can be turned off in the settings, which is what I'd do if I'd continue using it. Did the AI output help the humans with the code (useful suggestions etc)? While the actual patches it posted were "meh" at best, there were useful findings that resulted in improvements to the code. Was the AI output misleading? Absolutely! The whole Jinja discussion would have been easier without the AI "help". Same applies for the "error handling" in the workaround PR. Was the AI output distracting? The output is certainly a lot, so yes I think it can be distracting. As mentioned, I think dropping the summaries can make the experience less distracting. What does all that mean? I will disable the summaries for the repositories, but will leave the @coderabbitai review trigger active if someone wants an AI-assisted review. This won't be something that I'll force on our contributors and maintainers, but they surely can use it if they want. But I don't think I'll be using this myself on a regular basis. Yes, it can be made "usable". But so can be vim ;-) Also, I'd prefer to have a junior human asking all the questions and making bad suggestions, so they can learn from it, and not some planet burning machine.

8 June 2025

Debian Outreach Team: GSoC 2024 Final Report: Project DebMobCom

GSoC 2024: Project DebMobCom

Introduction Hi, my name is Nathan Doris and this is my report on contributing to the Debian Mobile Communication project for GSoC 2024 under the guidance of my mentor, Thorsten Alteholz.

Project MobCom Debian s Mobile Communication team takes care of updating and creating packages for the open-source mobile communication software suite known as Osmocom. The ongoing development of this software stack requires constant updating and creation of packages to support this progress. The goal of GSoC 2024 DebMobCom is to update, recreate and add these Osmocom packages.

My Work Over the few months that I contributed to Debian I successfully updated/recreated more than a dozen packages for DebMobCom. A list of my accomplishments can be found here as well as on the Debian QA page.

What I Learned Before I began this journey I had very little experience with Debian packaging. By the end of GSoC not only had I learned about building packages but I also gained more knowledge regarding Linux, Debian, shell scripting, automake, C, GNU and gitlab/Salsa. As I reflect back on the past few months I am amazed at the amount and depth of information I have learned. Listed below are examples of items that I found especially important.
  • Debian Packaging Workflow
    • Every package to be built relies upon the information inside the /debian folder. This is where I learned the importance of every templated file such as the control, changelog, rules, watch, *.symbols, *.install and many others. As I worked on these files I witnessed the relationship between them and the finished .deb package. From this workflow I can appreciate the amount of imagination and work that was put into this process.
  • Debian Tooling
    • I learned many tools while building packages but sbuild accompanied by lintian is what I spent the most time with. Sbuild is an autobuilder that produces the final .deb packages. It also integrates with another tool, lintian, which checks each package and informs you of any errors such as policy violations, common mistakes and best practices. Thorsten s words, keep lintian happy still resonate with me after each package build.
    • Another tool I frequently require use of is quilt. Quilt is a wonderful tool that manages patches for packages. I became quite well versed in updating patches, removing and also creating my own.
  • Copyright
    • I hadn t realised how important licensing was until I started contributing to Debian. I predominantly used licensecheck to extract copyright information from source code. This was a tedious task but obviously extremely important in keeping Debian packages free.

Challenges What I found particularly challenging (and enjoyable) was the amount of troubleshooting required to complete tasks. Although I spent countless hours reading documentation such as the New Maintainers Guide, Policy Manual, Wiki and manual pages it was still extremely difficult. Complex packages are not quite covered in the docs so out-of-the-box thinking is required.

Conclusion First of all I d like to say a big thank you to my mentor Thorsten. His support was critical for my success. Contributing to Debian and the overall GSoC experience was such a positive event in my life. I enjoyed all aspects of the experience. The skills I have acquired will propel me forward into further open-source activities and communities. As I continue to contribute to this project my goal of becoming a Debian Maintainer is becoming a reality.

4 June 2025

Gunnar Wolf: Humanities and big data in Ibero-America Theory, methodology and practical applications

This post is an unpublished review for Humanities and big data in Ibero-America Theory, methodology and practical applications
Digital humanities is a young though established field. It deals with different expressions in which digital data manipulation techniques can be applied and used to analyze subjects that are identified as belonging to the humanities. Although most often used to analyze different aspects of literature or social network analysis, it can also be applied to other humanistic disciplines or artistic expressions. Digital humanities employs many tools, but those categorized as big data are among the most frequently employed. This book samples different takes on digital humanities, with the particularity that it focuses on Ibero-American uses. It is worth noting that this book is the second in a series of four volumes, published or set to be published between 2022 and 2026. Being the output of a field survey, I perceive this book to be targeted towards fellow Digital Humanists people interested in applying computational methods to further understand and research topics in the humanities. It is not a technical book in the sense Computer Science people would recognize as such, but several of the presented works do benefit from understanding some technical concepts. The 12 articles (plus an introduction) that make up this book are organized in three parts: (1) Theoretical Framework presents the ideas and techniques of data science (that make up the tools for handling big data), and explores how data science can contribute to literary analysis, all while noting that many such techniques are usually frowned upon in Latin America as data science smells neoliberal ; (2) Methodological Issues looks at specific issues through the lens of how they can be applied to big data, with specific attention given to works in Spanish; and (3) Practical Applications analyzes specific Spanish works and communities based on big data techniques. Several chapters treat a recurring theme: the simultaneous resistance and appropriation of big data by humanists. For example, at least three of the chapters describe the tensions between humanism ( aesthesis ) and cold, number-oriented data analysis ( mathesis ). The analyzed works of Parts 2 and 3 are interesting and relatively easy to follow. Some inescapable ideological gleans from several word uses from the book s and series name, which refers to the Spanish-speaking regions as Ibero-America , often seen as Eurocentric, in contrast with the Latin America term much more widely used throughout the region. I will end with some notes about the specific versions of the book I reviewed. I read both an EPUB version and a print copy. The EPUB did not include links for easy navigation to footnotes, that is, the typographical superindexes are not hyperlinked to the location of the notes, so it is very impractical to try to follow them. The print version (unlike the EPUB) did not have an index, that is, the six pages before the introduction are missing from the print copy I received. For a book such as this one, not having an index hampers the ease of reading and referencing.

1 June 2025

Emmanuel Kasper: ARM64 desktop as daily driver

I have bought myself an expensive ARM64 workstation, the System 76 Thelio Astra that I intend to use as my main desktop computer for the next 15 years, running Debian. The box is basically a server motherboard repurposed in a good desktop chassis. In Europe it seems you can order similar ready systems here. The hardware is well supported by Debian 12 and Debian testing.I had some initial issues with graphics, due to the board being designed for a server use, but I am solving these as we go. Annoyances I got so far:
  • When you power on the machine using the power supply switch, you have to wait for the BMC to finished its startup sequence, before the front power button does anything. As starting the BMC can take 90 seconds, I thought initially the machine was dead on arrival.
  • The default graphical output is redirected to the BMC Serial over LAN, which means if you want to install Debian using an attached display you need to force the output on the attached display passing console=tty0 as an installer parameter.
  • Finally the Xorg Nouveau driver does not work with the Nvidia A400 GPU I got with the machine. After passing nodemodeset as a kernel parameter, I can force Xorg to use an unaccelerated framebuffer, which at least displays something. I passed this parameter to the installer, so that I could install in graphical mode. The driver from Nvidia works, but I d like very much to get Nouveau running.
Ugly point
  • A server mother board we said. This mean there is NO suspend to RAM, you have to power off if you don t want to keep the machine on all the time. As the boot sequence is long (server board again) I am pondering setting a startup time in the UEFI firmware to turn the box on at specific usage time.
Good points
  • The firmware of the machine is a standard EFI, which means you can use the debian arm64 installer on an USB stick straight away, without any kind of device tree / bootloader fiddling.
  • The 3 Nics, Wifi, bluetooth were all recognized on first boot.
  • I was afraid the machine would be loud. However it is quiet, you hear the humming of a fan, but it is quieter than most desktops I owned, from the Atari TT to an all in one Lenovo M92z I used for 10 years. I am certainly not a hardware and cooling specialist, but meseems the quietness comes from slow rotating but very large fans.
  • Due the clean design of Linux and Debian, thousands of packages working correctly on ARM64, starting with the Gnome desktop environment and Firefox.
  • The documentation from system76 is fine, their Ubuntu 20.04 setup guide was helpful to understand the needed parameters mentioned above.
Update: The display is working correctly with the nouveau driver after installing the non-free Nvidia firmware. See the Debian wiki.

31 May 2025

Antoine Beaupr : Traffic meter per ASN without logs

Have you ever found yourself in the situation where you had no or anonymized logs and still wanted to figure out where your traffic was coming from? Or you have multiple upstreams and are looking to see if you can save fees by getting into peering agreements with some other party? Or your site is getting heavy load but you can't pinpoint it on a single IP and you suspect some amoral corporation is training their degenerate AI on your content with a bot army? (You might be getting onto something there.) If that rings a bell, read on.

TL;DR: ... or just skip the cruft and install asncounter:
pip install asncounter
Also available in Debian 14 or later, or possibly in Debian 13 backports (soon to be released) if people are interested:
apt install asncounter
Then count whoever is hitting your network with:
awk ' print $2 ' /var/log/apache2/*access*.log   asncounter
or:
tail -F /var/log/apache2/*access*.log   awk ' print $2 '   asncounter
or:
tcpdump -q -n   asncounter --input-format=tcpdump --repl
or:
tcpdump -q -i eth0 -n -Q in "tcp and tcp[tcpflags] & tcp-syn != 0 and (port 80 or port 443)"   asncounter --input-format=tcpdump --repl
Read on for why this matters, and why I wrote yet another weird tool (almost) from scratch.

Background and manual work This is a tool I've been dreaming of for a long, long time. Back in 2006, at Koumbit a colleague had setup TAS ("Traffic Accounting System", " " in Russian, apparently), a collection of Perl script that would do per-IP accounting. It was pretty cool: it would count bytes per IP addresses and, from that, you could do analysis. But the project died, and it was kind of bespoke. Fast forward twenty years, and I find myself fighting off bots at the Tor Project (the irony...), with our GitLab suffering pretty bad slowdowns (see issue tpo/tpa/team#41677 for the latest public issue, the juicier one is confidential, unfortunately). (We did have some issues caused by overloads in CI, as we host, after all, a fork of Firefox, which is a massive repository, but the applications team did sustained, awesome work to fix issues on that side, again and again (see tpo/applications/tor-browser#43121 for the latest, and tpo/applications/tor-browser#43121 for some pretty impressive correlation work, I work with really skilled people). But those issues, I believe were fixed.) So I had the feeling it was our turn to get hammered by the AI bots. But how do we tell? I could tell something was hammering at the costly /commit/ and (especially costly) /blame/ endpoint. So at first, I pulled out the trusted awk, sort uniq -c sort -n tail pipeline I am sure others have worked out before:
awk ' print $1 ' /var/log/nginx/*.log   sort   uniq -c   sort -n   tail -10
For people new to this, that pulls the first field out of web server log files, sort the list, counts the number of unique entries, and sorts that so that the most common entries (or IPs) show up first, then show the top 10. That, other words, answers the question of "which IP address visits this web server the most?" Based on this, I found a couple of IP addresses that looked like Alibaba. I had already addressed an abuse complaint to them (tpo/tpa/team#42152) but never got a response, so I just blocked their entire network blocks, rather violently:
for cidr in 47.240.0.0/14 47.246.0.0/16 47.244.0.0/15 47.235.0.0/16 47.236.0.0/14; do 
  iptables-legacy -I INPUT -s $cidr -j REJECT
done
That made Ali Baba and his forty thieves (specifically their AL-3 network go away, but our load was still high, and I was still seeing various IPs crawling the costly endpoints. And this time, it was hard to tell who they were: you'll notice all the Alibaba IPs are inside the same 47.0.0.0/8 prefix. Although it's not a /8 itself, it's all inside the same prefix, so it's visually easy to pick it apart, especially for a brain like mine who's stared too long at logs flowing by too fast for their own mental health. What I had then was different, and I was tired of doing the stupid thing I had been doing for decades at this point. I had recently stumbled upon pyasn recently (in January, according to my notes) and somehow found it again, and thought "I bet I could write a quick script that loops over IPs and counts IPs per ASN". (Obviously, there are lots of other tools out there for that kind of monitoring. Argos, for example, presumably does this, but it's a kind of a huge stack. You can also get into netflows, but there's serious privacy implications with those. There are also lots of per-IP counters like promacct, but that doesn't scale. Or maybe someone already had solved this problem and I just wasted a week of my life, who knows. Someone will let me know, I hope, either way.)

ASNs and networks A quick aside, for people not familiar with how the internet works. People that know about ASNs, BGP announcements and so on can skip. The internet is the network of networks. It's made of multiple networks that talk to each other. The way this works is there is a Border Gateway Protocol (BGP), a relatively simple TCP-based protocol, that the edge routers of those networks used to announce each other what network they manage. Each of those network is called an Autonomous System (AS) and has an AS number (ASN) to uniquely identify it. Just like IP addresses, ASNs are allocated by IANA and local registries, they're pretty cheap and useful if you like running your own routers, get one. When you have an ASN, you'll use it to, say, announce to your BGP neighbors "I have 198.51.100.0/24" over here and the others might say "okay, and I have 216.90.108.31/19 over here, and I know of this other ASN over there that has 192.0.2.1/24 too! And gradually, those announcements flood the entire network, and you end up with each BGP having a routing table of the global internet, with a map of which network block, or "prefix" is announced by which ASN. It's how the internet works, and it's a useful thing to know, because it's what, ultimately, makes an organisation responsible for an IP address. There are "looking glass" tools like the one provided by routeviews.org which allow you to effectively run "trace routes" (but not the same as traceroute, which actively sends probes from your location), type an IP address in that form to fiddle with it. You will end up with an "AS path", the way to get from the looking glass to the announced network. But I digress, and that's kind of out of scope. Point is, internet is made of networks, networks are autonomous systems (AS) and they have numbers (ASNs), and they announced IP prefixes (or "network blocks") that ultimately tells you who is responsible for traffic on the internet.

Introducing asncounter So my goal was to get from "lots of IP addresses" to "list of ASNs", possibly also the list of prefixes (because why not). Turns out pyasn makes that really easy. I managed to build a prototype in probably less than an hour, just look at the first version, it's 44 lines (sloccount) of Python, and it works, provided you have already downloaded the required datafiles from routeviews.org. (Obviously, the latest version is longer at close to 1000 lines, but it downloads the data files automatically, and has many more features). The way the first prototype (and later versions too, mostly) worked is that you feed it a list of IP addresses on standard input, it looks up the ASN and prefix associated with the IP, and increments a counter for those, then print the result. That showed me something like this:
root@gitlab-02:~/anarcat-scripts# tcpdump -q -i eth0 -n -Q in "(udp or tcp)"   ./asncounter.py --tcpdump                                                                                                                                                                          
tcpdump: verbose output suppressed, use -v[v]... for full protocol decode                                                                
listening on eth0, link-type EN10MB (Ethernet), snapshot length 262144 bytes                                                             
INFO: collecting IPs from stdin, using datfile ipasn_20250523.1600.dat.gz                                                                
INFO: loading datfile /root/.cache/pyasn/ipasn_20250523.1600.dat.gz...                                                                   
INFO: loading /root/.cache/pyasn/asnames.json                       
ASN     count   AS               
136907  7811    HWCLOUDS-AS-AP HUAWEI CLOUDS, HK                                                                                         
[----]  359     [REDACTED]
[----]  313     [REDACTED]
8075    254     MICROSOFT-CORP-MSN-AS-BLOCK, US
[---]   164     [REDACTED]
[----]  136     [REDACTED]
24940   114     HETZNER-AS, DE  
[----]  98      [REDACTED]
14618   82      AMAZON-AES, US                                                                                                           
[----]  79      [REDACTED]
prefix  count                                         
166.108.192.0/20        1294                                                                                                             
188.239.32.0/20 1056                                          
166.108.224.0/20        970                    
111.119.192.0/20        951              
124.243.128.0/18        667                                         
94.74.80.0/20   651                                                 
111.119.224.0/20        622                                         
111.119.240.0/20        566           
111.119.208.0/20        538                                         
[REDACTED]  313           
Even without ratios and a total count (which will come later), it was quite clear that Huawei was doing something big on the server. At that point, it was responsible for a quarter to half of the traffic on our GitLab server or about 5-10 queries per second. But just looking at the logs, or per IP hit counts, it was really hard to tell. That traffic is really well distributed. If you look more closely at the output above, you'll notice I redacted a couple of entries except major providers, for privacy reasons. But you'll also notice almost nothing is redacted in the prefix list, why? Because all of those networks are Huawei! Their announcements are kind of bonkers: they have hundreds of such prefixes. Now, clever people in the know will say "of course they do, it's an hyperscaler; just ASN14618 (AMAZON-AES) there is way more announcements, they have 1416 prefixes!" Yes, of course, but they are not generating half of my traffic (at least, not yet). But even then: this also applies to Amazon! This way of counting traffic is way more useful for large scale operations like this, because you group by organisation instead of by server or individual endpoint. And, ultimately, this is why asncounter matters: it allows you to group your traffic by organisation, the place you can actually negotiate with. Now, of course, that assumes those are entities you can talk with. I have written to both Alibaba and Huawei, and have yet to receive a response. I assume I never will. In their defence, I wrote in English, perhaps I should have made the effort of translating my message in Chinese, but then again English is the Lingua Franca of the Internet, and I doubt that's actually the issue.

The Huawei and Facebook blocks Another aside, because this is my blog and I am not looking for a Pullitzer here. So I blocked Huawei from our GitLab server (and before you tear your shirt open: only our GitLab server, everything else is still accessible to them, including our email server to respond to my complaint). I did so 24h after emailing them, and after examining their user agent (UA) headers. Boy that was fun. In a sample of 268 requests I analyzed, they churned out 246 different UAs. At first glance, they looked legit, like:
Mozilla/5.0 (Macintosh; Intel Mac OS X 10_15_7) AppleWebKit/537.36 (KHTML, like Gecko) Chrome/131.0.0.0 Safari/537.36
Safari on a Mac, so far so good. But when you start digging, you notice some strange things, like here's Safari running on Linux:
Mozilla/5.0 (X11; U; Linux i686; en-US) AppleWebKit/534.3 (KHTML, like Gecko) Chrome/6.0.457.0 Safari/534.3
Was Safari ported to Linux? I guess that's.. possible? But here is Safari running on a 15 year old Ubuntu release (10.10):
Mozilla/5.0 (X11; Linux i686) AppleWebKit/534.24 (KHTML, like Gecko) Ubuntu/10.10 Chromium/12.0.702.0 Chrome/12.0.702.0 Safari/534.24
Speaking of old, here's Safari again, but this time running on Windows NT 5.1, AKA Windows XP, released 2001, EOL since 2019:
Mozilla/5.0 (Windows; U; Windows NT 5.1; en-CA) AppleWebKit/534.13 (KHTML like Gecko) Chrome/9.0.597.98 Safari/534.13
Really? Here's Firefox 3.6, released 14 years ago, there were quite a lot of those:
Mozilla/5.0 (Windows; U; Windows NT 6.1; lt; rv:1.9.2) Gecko/20100115 Firefox/3.6
I remember running those old Firefox releases, those were the days. But to me, those look like entirely fake UAs, deliberately rotated to make it look like legitimate traffic. In comparison, Facebook seemed a bit more legit, in the sense that they don't fake it. most hits are from:
meta-externalagent/1.1 (+https://developers.facebook.com/docs/sharing/webmasters/crawler)
which, according their documentation:
crawls the web for use cases such as training AI models or improving products by indexing content directly
From what I could tell, it was even respecting our rather liberal robots.txt rules, in that it wasn't crawling the sprawling /blame/ or /commit/ endpoints, explicitly forbidden by robots.txt. So I've blocked the Facebook bot in robots.txt and, amazingly, it just went away. Good job Facebook, as much as I think you've given the empire to neo-nazis, cause depression and genocide, you know how to run a crawler, thanks. Huawei was blocked at the web server level, with a friendly 429 status code telling people to contact us (over email) if they need help. And they don't care: they're still hammering the server, from what I can tell, but then again, I didn't block the entire ASN just yet, just the blocks I found crawling the server over a couple hours.

A full asncounter run So what does a day in asncounter look like? Well, you start with a problem, say you're getting too much traffic and want to see where it's from. First you need to sample it. Typically, you'd do that with tcpdump or tailing a log file:
tail -F /var/log/apache2/*access*.log   awk ' print $2 '   asncounter
If you have lots of traffic or care about your users' privacy, you're not going to log IP addresses, so tcpdump is likely a good option instead:
tcpdump -q -n   asncounter --input-format=tcpdump --repl
If you really get a lot of traffic, you might want to get a subset of that to avoid overwhelming asncounter, it's not fast enough to do multiple gigabit/second, I bet, so here's only incoming SYN IPv4 packets:
tcpdump -q -n -Q in "tcp and tcp[tcpflags] & tcp-syn != 0 and (port 80 or port 443)"   asncounter --input-format=tcpdump --repl
In any case, at this point you're staring at a process, just sitting there. If you passed the --repl or --manhole arguments, you're lucky: you have a Python shell inside the program. Otherwise, send SIGHUP to the thing to have it dump the nice tables out:
pkill -HUP asncounter
Here's an example run:
> awk ' print $2 ' /var/log/apache2/*access*.log   asncounter
INFO: using datfile ipasn_20250527.1600.dat.gz
INFO: collecting addresses from <stdin>
INFO: loading datfile /home/anarcat/.cache/pyasn/ipasn_20250527.1600.dat.gz...
INFO: finished reading data
INFO: loading /home/anarcat/.cache/pyasn/asnames.json
count   percent ASN AS
12779   69.33   66496   SAMPLE, CA
3361    18.23   None    None
366 1.99    66497   EXAMPLE, FR
337 1.83    16276   OVH, FR
321 1.74    8075    MICROSOFT-CORP-MSN-AS-BLOCK, US
309 1.68    14061   DIGITALOCEAN-ASN, US
128 0.69    16509   AMAZON-02, US
77  0.42    48090   DMZHOST, GB
56  0.3 136907  HWCLOUDS-AS-AP HUAWEI CLOUDS, HK
53  0.29    17621   CNCGROUP-SH China Unicom Shanghai network, CN
total: 18433
count   percent prefix  ASN AS
12779   69.33   192.0.2.0/24    66496   SAMPLE, CA
3361    18.23   None        
298 1.62    178.128.208.0/20    14061   DIGITALOCEAN-ASN, US
289 1.57    51.222.0.0/16   16276   OVH, FR
272 1.48    2001:DB8::/48   66497   EXAMPLE, FR
235 1.27    172.160.0.0/11  8075    MICROSOFT-CORP-MSN-AS-BLOCK, US
94  0.51    2001:DB8:1::/48 66497   EXAMPLE, FR
72  0.39    47.128.0.0/14   16509   AMAZON-02, US
69  0.37    93.123.109.0/24 48090   DMZHOST, GB
53  0.29    27.115.124.0/24 17621   CNCGROUP-SH China Unicom Shanghai network, CN
Those numbers are actually from my home network, not GitLab. Over there, the battle still rages on, but at least the vampire bots are banging their heads against the solid Nginx wall instead of eating the fragile heart of GitLab. We had a significant improvement in latency thanks to the Facebook and Huawei blocks... Here are the "workhorse request duration stats" for various time ranges, 20h after the block:
range mean max stdev
20h 449ms 958ms 39ms
7d 1.78s 5m 14.9s
30d 2.08s 3.86m 8.86s
6m 901ms 27.3s 2.43s
We went from two seconds mean to 500ms! And look at that standard deviation! 39ms! It was ten seconds before! I doubt we'll keep it that way very long but for now, it feels like I won a battle, and I didn't even have to setup anubis or go-away, although I suspect that will unfortunately come. Note that asncounter also supports exporting Prometheus metrics, but you should be careful with this, as it can lead to cardinal explosion, especially if you track by prefix (which can be disabled with --no-prefixes . Folks interested in more details should read the fine manual for more examples, usage, and discussion. It shows, among other things, how to effectively block lots of networks from Nginx, aggregate multiple prefixes, block entire ASNs, and more! So there you have it: I now have the tool I wish I had 20 years ago. Hopefully it will stay useful for another 20 years, although I'm not sure we'll have still have internet in 20 years. I welcome constructive feedback, "oh no you rewrote X", Grafana dashboards, bug reports, pull requests, and "hell yeah" comments. Hacker News, let it rip, I know you can give me another juicy quote for my blog. This work was done as part of my paid work for the Tor Project, currently in a fundraising drive, give us money if you like what you read.

29 May 2025

Arthur Diniz: Bringing Kubernetes Back to Debian

I ve been part of the Debian Project since 2019, when I attended DebConf held in Curitiba, Brazil. That event sparked my interest in the community, packaging, and how Debian works as a distribution. In the early years of my involvement, I contributed to various teams such as the Python, Golang and Cloud teams, packaging dependencies and maintaining various tools. However, I soon felt the need to focus on packaging software I truly enjoyed, tools I was passionate about using and maintaining. That s when I turned my attention to Kubernetes within Debian.

A Broken Ecosystem The Kubernetes packaging situation in Debian had been problematic for some time. Given its large codebase and complex dependency tree, the initial packaging approach involved vendorizing all dependencies. While this allowed a somewhat functional package to be published, it introduced several long-term issues, especially security concerns. Vendorized packages bundle third-party dependencies directly into the source tarball. When vulnerabilities arise in those dependencies, it becomes difficult for Debian s security team to patch and rebuild affected packages system-wide. This approach broke Debian s best practices, and it eventually led to the abandonment of the Kubernetes source package, which had stalled at version 1.20.5. Due to this abandonment, critical bugs emerged and the package was removed from Debian s testing channel, as we can see in the package tracker.

New Debian Kubernetes Team Around this time, I became a Debian Maintainer (DM), with permissions to upload certain packages. I saw an opportunity to both contribute more deeply to Debian and to fix Kubernetes packaging. In early 2024, just before DebConf Busan in South Korea, I founded the Debian Kubernetes Team. The mission of the team was to repackage Kubernetes in a maintainable, security-conscious, and Debian-compliant way. At DebConf, I shared our progress with the broader community and received great feedback and more visibility, along with people interested in contributing to the team. Our first tasks was to migrate existing Kubernetes-related tools such as kubectx, kubernetes-split-yaml and kubetail into a dedicated namespace on Salsa, Debian s GitLab instance. Many of these tools were stored across different teams (like the Go team), and consolidating them helped us organize development and focus our efforts.

De-vendorizing Kubernetes Our main goal was to un-vendorize Kubernetes and bring it up-to-date with upstream releases. This meant:
  • Removing the vendor directory and all embedded third-party code.
  • Trimming the build scope to focus solely on building kubectl, Kubernetes CLI.
  • Using Files-Excluded in debian/copyright to cleanly drop unneeded files during source imports.
  • Rebuilding the dependency tree, ensuring all Go modules were separately packaged in Debian.
We used uscan, a standard Debian packaging tool that fetches upstream tarballs and prepares them accordingly. The Files-Excluded directive in our debian/copyright file instructed uscan to automatically remove unnecessary files during the repackaging process:
$ uscan
Newest version of kubernetes on remote site is 1.32.3, specified download version is 1.32.3
Successfully repacked ../v1.32.3 as ../kubernetes_1.32.3+ds.orig.tar.gz, deleting 30616 files from it.
The results were dramatic. By comparing the original upstream tarball with our repackaged version, we can see that our approach reduced the tarball size by over 75%:
$ du -h upstream-v1.32.3.tar.gz kubernetes_1.32.3+ds.orig.tar.gz
14M	upstream-v1.32.3.tar.gz
3.2M	kubernetes_1.32.3+ds.orig.tar.gz
This significant reduction wasn t just about saving space. By removing over 30,000 files, we simplified the package, making it more maintainable. Each dependency could now be properly tracked, updated, and patched independently, resolving the security concerns that had plagued the previous packaging approach.

Dependency Graph To give you an idea of the complexity involved in packaging Kubernetes for Debian, the image below is a dependency graph generated with debtree, visualizing all the Go modules and other dependencies required to build the kubectl binary. kubectl-depgraph This web of nodes and edges represents every module and its relationship during the compilation process of kubectl. Each box is a Debian package, and the lines connecting them show how deeply intertwined the ecosystem is. What might look like a mess of blue spaghetti is actually a clear demonstration of the vast and interconnected upstream world that tools like kubectl rely on. But more importantly, this graph is a testament to the effort that went into making kubectl build entirely using Debian-packaged dependencies only, no vendoring, no downloading from the internet, no proprietary blobs.
Upstream Version 1.32.3 and Beyond After nearly two years of work, we successfully uploaded version 1.32.3+ds of kubectl to Debian unstable. kubernetes/-/merge_requests/1 The new package also includes:
  • Zsh, Fish, and Bash completions installed automatically
  • Man pages and metadata for improved discoverability
  • Full integration with kind and docker for testing purposes

Integration Testing with Autopkgtest To ensure the reliability of kubectl in real-world scenarios, we developed a new autopkgtest suite that runs integration tests using real Kubernetes clusters created via Kind. Autopkgtest is a Debian tool used to run automated tests on binary packages. These tests are executed after the package is built but before it s accepted into the Debian archive, helping catch regressions and integration issues early in the packaging pipeline. Our test workflow validates kubectl by performing the following steps:
  • Installing Kind and Docker as test dependencies.
  • Spinning up two local Kubernetes clusters.
  • Switching between cluster contexts to ensure multi-cluster support.
  • Deploying and scaling a sample nginx application using kubectl.
  • Cleaning up the entire test environment to avoid side effects.
  • debian/tests/kubectl.sh

Popcon: Measuring Adoption To measure real-world usage, we rely on data from Debian s popularity contest (popcon), which gives insight into how many users have each binary installed. popcon-graph popcon-table Here s what the data tells us:
  • kubectl (new binary): Already installed on 2,124 systems.
  • golang-k8s-kubectl-dev: This is the Go development package (a library), useful for other packages and developers who want to interact with Kubernetes programmatically.
  • kubernetes-client: The legacy package that kubectl is replacing. We expect this number to decrease in future releases as more systems transition to the new package.
Although the popcon data shows activity for kubectl before the official Debian upload date, it s important to note that those numbers represent users who had it installed from upstream source-lists, not from the Debian repositories. This distinction underscores a demand that existed even before the package was available in Debian proper, and it validates the importance of bringing it into the archive.
Also worth mentioning: this number is not the real total number of installations, since users can choose not to participate in the popularity contest. So the actual adoption is likely higher than what popcon reflects.

Community and Documentation The team also maintains a dedicated wiki page which documents:
  • Maintained tools and packages
  • Contribution guidelines
  • Our roadmap for the upcoming Debian releases
https://debian-kubernetes.org

Looking Ahead to Debian 13 (Trixie) The next stable release of Debian will ship with kubectl version 1.32.3, built from a clean, de-vendorized source. This version includes nearly all the latest upstream features, and will be the first time in years that Debian users can rely on an up-to-date, policy-compliant kubectl directly from the archive. By comparing with upstream, our Debian package even delivers more out of the box, including shell completions, which the upstream still requires users to generate manually. In 2025, the Debian Kubernetes team will continue expanding our packaging efforts for the Kubernetes ecosystem. Our roadmap includes:
  • kubelet: The primary node agent that runs on each node. This will enable Debian users to create fully functional Kubernetes nodes without relying on external packages.
  • kubeadm: A tool for creating Kubernetes clusters. With kubeadm in Debian, users will then be able to bootstrap minimum viable clusters directly from the official repositories.
  • helm: The package manager for Kubernetes that helps manage applications through Kubernetes YAML files defined as charts.
  • kompose: A conversion tool that helps users familiar with docker-compose move to Kubernetes by translating Docker Compose files into Kubernetes resources.

Final Thoughts This journey was only possible thanks to the amazing support of the debian-devel-br community and the collective effort of contributors who stepped up to package missing dependencies, fix bugs, and test new versions. Special thanks to:
  • Carlos Henrique Melara (@charles)
  • Guilherme Puida (@puida)
  • Jo o Pedro Nobrega (@jnpf)
  • Lucas Kanashiro (@kanashiro)
  • Matheus Polkorny (@polkorny)
  • Samuel Henrique (@samueloph)
  • Sergio Cipriano (@cipriano)
  • Sergio Durigan Junior (@sergiodj)
I look forward to continuing this work, bringing more Kubernetes tools into Debian and improving the developer experience for everyone.

Arthur Diniz: Bringing Kubernetes Back to Debian

I ve been part of the Debian Project since 2019, when I attended DebConf held in Curitiba, Brazil. That event sparked my interest in the community, packaging, and how Debian works as a distribution. In the early years of my involvement, I contributed to various teams such as the Python, Golang and Cloud teams, packaging dependencies and maintaining various tools. However, I soon felt the need to focus on packaging software I truly enjoyed, tools I was passionate about using and maintaining. That s when I turned my attention to Kubernetes within Debian.

A Broken Ecosystem The Kubernetes packaging situation in Debian had been problematic for some time. Given its large codebase and complex dependency tree, the initial packaging approach involved vendorizing all dependencies. While this allowed a somewhat functional package to be published, it introduced several long-term issues, especially security concerns. Vendorized packages bundle third-party dependencies directly into the source tarball. When vulnerabilities arise in those dependencies, it becomes difficult for Debian s security team to patch and rebuild affected packages system-wide. This approach broke Debian s best practices, and it eventually led to the abandonment of the Kubernetes source package, which had stalled at version 1.20.5. Due to this abandonment, critical bugs emerged and the package was removed from Debian s testing channel, as we can see in the package tracker.

New Debian Kubernetes Team Around this time, I became a Debian Maintainer (DM), with permissions to upload certain packages. I saw an opportunity to both contribute more deeply to Debian and to fix Kubernetes packaging. In early 2024, just before DebConf Busan in South Korea, I founded the Debian Kubernetes Team. The mission of the team was to repackage Kubernetes in a maintainable, security-conscious, and Debian-compliant way. At DebConf, I shared our progress with the broader community and received great feedback and more visibility, along with people interested in contributing to the team. Our first tasks was to migrate existing Kubernetes-related tools such as kubectx, kubernetes-split-yaml and kubetail into a dedicated namespace on Salsa, Debian s GitLab instance. Many of these tools were stored across different teams (like the Go team), and consolidating them helped us organize development and focus our efforts.

De-vendorizing Kubernetes Our main goal was to un-vendorize Kubernetes and bring it up-to-date with upstream releases. This meant:
  • Removing the vendor directory and all embedded third-party code.
  • Trimming the build scope to focus solely on building kubectl, Kubernetes CLI.
  • Using Files-Excluded in debian/copyright to cleanly drop unneeded files during source imports.
  • Rebuilding the dependency tree, ensuring all Go modules were separately packaged in Debian.
We used uscan, a standard Debian packaging tool that fetches upstream tarballs and prepares them accordingly. The Files-Excluded directive in our debian/copyright file instructed uscan to automatically remove unnecessary files during the repackaging process:
$ uscan
Newest version of kubernetes on remote site is 1.32.3, specified download version is 1.32.3
Successfully repacked ../v1.32.3 as ../kubernetes_1.32.3+ds.orig.tar.gz, deleting 30616 files from it.
The results were dramatic. By comparing the original upstream tarball with our repackaged version, we can see that our approach reduced the tarball size by over 75%:
$ du -h upstream-v1.32.3.tar.gz kubernetes_1.32.3+ds.orig.tar.gz
14M	upstream-v1.32.3.tar.gz
3.2M	kubernetes_1.32.3+ds.orig.tar.gz
This significant reduction wasn t just about saving space. By removing over 30,000 files, we simplified the package, making it more maintainable. Each dependency could now be properly tracked, updated, and patched independently, resolving the security concerns that had plagued the previous packaging approach.

Dependency Graph To give you an idea of the complexity involved in packaging Kubernetes for Debian, the image below is a dependency graph generated with debtree, visualizing all the Go modules and other dependencies required to build the kubectl binary. kubectl-depgraph This web of nodes and edges represents every module and its relationship during the compilation process of kubectl. Each box is a Debian package, and the lines connecting them show how deeply intertwined the ecosystem is. What might look like a mess of blue spaghetti is actually a clear demonstration of the vast and interconnected upstream world that tools like kubectl rely on. But more importantly, this graph is a testament to the effort that went into making kubectl build entirely using Debian-packaged dependencies only, no vendoring, no downloading from the internet, no proprietary blobs.
Upstream Version 1.32.3 and Beyond After nearly two years of work, we successfully uploaded version 1.32.3+ds of kubectl to Debian unstable. kubernetes/-/merge_requests/1 The new package also includes:
  • Zsh, Fish, and Bash completions installed automatically
  • Man pages and metadata for improved discoverability
  • Full integration with kind and docker for testing purposes

Integration Testing with Autopkgtest To ensure the reliability of kubectl in real-world scenarios, we developed a new autopkgtest suite that runs integration tests using real Kubernetes clusters created via Kind. Autopkgtest is a Debian tool used to run automated tests on binary packages. These tests are executed after the package is built but before it s accepted into the Debian archive, helping catch regressions and integration issues early in the packaging pipeline. Our test workflow validates kubectl by performing the following steps:
  • Installing Kind and Docker as test dependencies.
  • Spinning up two local Kubernetes clusters.
  • Switching between cluster contexts to ensure multi-cluster support.
  • Deploying and scaling a sample nginx application using kubectl.
  • Cleaning up the entire test environment to avoid side effects.
  • debian/tests/kubectl.sh

Popcon: Measuring Adoption To measure real-world usage, we rely on data from Debian s popularity contest (popcon), which gives insight into how many users have each binary installed. popcon-graph popcon-table Here s what the data tells us:
  • kubectl (new binary): Already installed on 2,124 systems.
  • golang-k8s-kubectl-dev: This is the Go development package (a library), useful for other packages and developers who want to interact with Kubernetes programmatically.
  • kubernetes-client: The legacy package that kubectl is replacing. We expect this number to decrease in future releases as more systems transition to the new package.
Although the popcon data shows activity for kubectl before the official Debian upload date, it s important to note that those numbers represent users who had it installed from upstream source-lists, not from the Debian repositories. This distinction underscores a demand that existed even before the package was available in Debian proper, and it validates the importance of bringing it into the archive.
Also worth mentioning: this number is not the real total number of installations, since users can choose not to participate in the popularity contest. So the actual adoption is likely higher than what popcon reflects.

Community and Documentation The team also maintains a dedicated wiki page which documents:
  • Maintained tools and packages
  • Contribution guidelines
  • Our roadmap for the upcoming Debian releases
https://debian-kubernetes.org

Looking Ahead to Debian 13 (Trixie) The next stable release of Debian will ship with kubectl version 1.32.3, built from a clean, de-vendorized source. This version includes nearly all the latest upstream features, and will be the first time in years that Debian users can rely on an up-to-date, policy-compliant kubectl directly from the archive. By comparing with upstream, our Debian package even delivers more out of the box, including shell completions, which the upstream still requires users to generate manually. In 2025, the Debian Kubernetes team will continue expanding our packaging efforts for the Kubernetes ecosystem. Our roadmap includes:
  • kubelet: The primary node agent that runs on each node. This will enable Debian users to create fully functional Kubernetes nodes without relying on external packages.
  • kubeadm: A tool for creating Kubernetes clusters. With kubeadm in Debian, users will then be able to bootstrap minimum viable clusters directly from the official repositories.
  • helm: The package manager for Kubernetes that helps manage applications through Kubernetes YAML files defined as charts.
  • kompose: A conversion tool that helps users familiar with docker-compose move to Kubernetes by translating Docker Compose files into Kubernetes resources.

Final Thoughts This journey was only possible thanks to the amazing support of the debian-devel-br community and the collective effort of contributors who stepped up to package missing dependencies, fix bugs, and test new versions. Special thanks to:
  • Carlos Henrique Melara (@charles)
  • Guilherme Puida (@puida)
  • Jo o Pedro Nobrega (@jnpf)
  • Lucas Kanashiro (@kanashiro)
  • Matheus Polkorny (@polkorny)
  • Samuel Henrique (@samueloph)
  • Sergio Cipriano (@cipriano)
  • Sergio Durigan Junior (@sergiodj)
I look forward to continuing this work, bringing more Kubernetes tools into Debian and improving the developer experience for everyone.

28 May 2025

Bits from Debian: Debian welcomes the 2025 GSOC contributors/students

GSoC logo We are very excited to announce that Debian has selected nine contributors to work under mentorship on a variety of projects with us during the Google Summer of Code. Here is a list of the projects and students, along with details of the tasks to be performed.
Project: Quality assurance and continuous integration for biological and medical applications inside Debian Deliverables of the project: Continuous integration tests for Debian Med applications lacking a test, Quality Assurance review and bug fixing if issues might be uncovered.
Project: Device-specific Tweaks Management Deliverables of the project: Analysis and discussion of the current state of device tweaks management in Debian and Mobian. Proposal for a unified, run-time approach. Packaging of this service and tweaks data/configuration for at least one device.
Project: Enhancing Debian packages with ROCm GPU acceleration Deliverables of the project: New Debian packages with GPU support. Enhanced GPU support within existing Debian packages. More autopackagetests running on the Debian ROCm CI.
Project: Make Debian for Raspberry Pi Build Again Deliverables of the project: Refreshing the set of daily-built images. Having the set of daily-built images become automatic again that is, go back to the promise of having it daily-built. Write an Ansible playbook/Chef recipe/Puppet whatsitsname to define a virtual serve and have it build daily. Do the (very basic!) hardware testing on several Raspberry computers. Do note, naturally, this will require having access to the relevant hardware.
Project: Package LLM Inference Libraries Deliverables of the project: Eventually I hope we can make vLLM into Debian archive, based on which we can deliver something for LLM inference out-of-the-box. If the amount of work eventually turns to be beyond my expectation, I'm still happy to see how far we can go towards this goal. If the amount of work required for vLLM is less than I expected, we can also look at something else like SGLang, another open source LLM inference library.
Project: Autopkgtests for the rsync package Deliverables of the project: Autopkgtests for the rsync package.
Project: Enhancing Salsa CI in Debian Deliverables of the project: More features, robustness, speed.
Congratulations and welcome to all the contributors! The Google Summer of Code program is possible in Debian thanks to the efforts of Debian Developers and Debian Contributors that dedicate part of their free time to mentor contributors and outreach tasks. Join us and help extend Debian! You can follow the contributors' weekly reports on the debian-outreach mailing-list, chat with us on our IRC channel or reach out to the individual projects' team mailing lists.

Bits from Debian: Debian Day 2025 - call for celebration

Each year on August the 16th, we celebrate the Debian Project Anniversary. Several communities around the world join us in celebrating "Debian Day" with local events, parties, or gatherings. So, how about celebrating the 32nd anniversary of the Debian Project in 2025 in your city? As the 16th of August falls on a Saturday this year, we believe it is great timing to gather people around your event. We invite you and your local community to organize a Debian Day by hosting an event with talks, workshops, a bug squashing party, or OpenPGP keysigning gathering, etc. You could also hold a meeting with others in the Debian community in a smaller social setting like a bar/pizzeria/cafeteria/restaurant to celebrate. In other words, any type of celebrating is valid! Remember to add your city to the Debian Day wiki page There is a list of Debian Local Groups around the world. If your city is listed, talk to them to organize DebianDay together. To inspire you and your local community, see some photos from 2023 and 2024 Let's use hashtags #DebianDay #DebianDay2025 on social media. debianday-logo

27 May 2025

Ravi Dwivedi: Singapore Visa Process

In November 2024, Badri and I applied for a Singapore visa to visit the country. To apply for a Singapore visa, you need to visit an authorized travel agent listed by the Singapore High Commission on their website. Unlike the Schengen visa (where only VFS can process applications), the Singapore visa has many authorized travel agents to choose from. I remember that the list mentioned as many as 25 authorized agents in Chennai. For my application, I randomly selected Ria International in Karol Bagh, New Delhi from the list. Further, you need to apply not more than a month before your travel dates. As our travel dates were in December, we applied in the month of November. For your reference, I submitted the following documents: I didn t have my photograph in the specified dimensions, so the travel agent took my photo on the spot. The visa application was 2,567. Furthermore, I submitted my application on a Saturday and received a call from the travel agent on Tuesday informing me that they had received my visa from the Singapore High Commission. The next day, I visit the travel agent s office and picked up my passport and a black and white copy of my e-visa. Later, I downloaded a PDF of my visa from the website mentioned on it, and took a colored printout myself. Singapore granted me a multiple-entry visa for 2 months, even though I had applied for a 4-day single-entry visa. We were planning to add more countries to this trip; therefore, a multiple-entry visa would be helpful in case we wanted to use Singapore Airport, as it has good connectivity. However, it turned out that flights from Kuala Lumpur were much cheaper than those from Singapore, so we didn t enter Singapore again after leaving. Badri also did the same process but entirely remotely he posted the documents to the visa agency in Chennai, and got his e-visa in a few days followed by his original passport which was delivered by courier. He got his photo taken in the same dimensions mentioned above, and printed as matte finish as instructed. However, the visa agents asked why his photo was looking so faded. We don t know if they thought the matte finish was faded or what. To rectify this, Badri emailed them a digital copy of the photo to them (both the cropped version and the original) and they handled the reprinting on their end (which he never got to see). Before entering Singapore, we had to fill an arrival card - an online form asking a few details about our trip - within 72 hours of our arrival in Singapore. That s it for now. Meet you in the next post. Thanks to Badri for reviewing the draft.

26 May 2025

Otto Kek l inen: Creating Debian packages from upstream Git

Featured image of post Creating Debian packages from upstream GitIn this post, I demonstrate the optimal workflow for creating new Debian packages in 2025, preserving the upstream git history. The motivation for this is to lower the barrier for sharing improvements to and from upstream, and to improve software provenance and supply-chain security by making it easy to inspect every change at any level using standard git tooling. Key elements of this workflow include: To make the instructions so concrete that anyone can repeat all the steps themselves on a real package, I demonstrate the steps by packaging the command-line tool Entr. It is written in C, has very few dependencies, and its final Debian source package structure is simple, yet exemplifies all the important parts that go into a complete Debian package:
  1. Creating a new packaging repository and publishing it under your personal namespace on salsa.debian.org.
  2. Using dh_make to create the initial Debian packaging.
  3. Posting the first draft of the Debian packaging as a Merge Request (MR) and using Salsa CI to verify Debian packaging quality.
  4. Running local builds efficiently and iterating on the packaging process.

Create new Debian packaging repository from the existing upstream project git repository First, create a new empty directory, then clone the upstream Git repository inside it:
shell
mkdir debian-entr
cd debian-entr
git clone --origin upstreamvcs --branch master \
 --single-branch https://github.com/eradman/entr.git
Using a clean directory makes it easier to inspect the build artifacts of a Debian package, which will be output in the parent directory of the Debian source directory. The extra parameters given to git clone lay the foundation for the Debian packaging git repository structure where the upstream git remote name is upstreamvcs. Only the upstream main branch is tracked to avoid cluttering git history with upstream development branches that are irrelevant for packaging in Debian. Next, enter the git repository directory and list the git tags. Pick the latest upstream release tag as the commit to start the branch upstream/latest. This latest refers to the upstream release, not the upstream development branch. Immediately after, branch off the debian/latest branch, which will have the actual Debian packaging files in the debian/ subdirectory.
shell
cd entr
git tag # shows the latest upstream release tag was '5.6'
git checkout -b upstream/latest 5.6
git checkout -b debian/latest
%% init:   'gitGraph':   'mainBranchName': 'master'      %%
gitGraph:
checkout master
commit id: "Upstream 5.6 release" tag: "5.6"
branch upstream/latest
checkout upstream/latest
commit id: "New upstream version 5.6" tag: "upstream/5.6"
branch debian/latest
checkout debian/latest
commit id: "Initial Debian packaging"
commit id: "Additional change 1"
commit id: "Additional change 2"
commit id: "Additional change 3"
At this point, the repository is structured according to DEP-14 conventions, ensuring a clear separation between upstream and Debian packaging changes, but there are no Debian changes yet. Next, add the Salsa repository as a new remote which called origin, the same as the default remote name in git.
shell
git remote add origin git@salsa.debian.org:otto/entr-demo.git
git push --set-upstream origin debian/latest
This is an important preparation step to later be able to create a Merge Request on Salsa that targets the debian/latest branch, which does not yet have any debian/ directory.

Launch a Debian Sid (unstable) container to run builds in To ensure that all packaging tools are of the latest versions, run everything inside a fresh Sid container. This has two benefits: you are guaranteed to have the most up-to-date toolchain, and your host system stays clean without getting polluted by various extra packages. Additionally, this approach works even if your host system is not Debian/Ubuntu.
shell
cd ..
podman run --interactive --tty --rm --shm-size=1G --cap-add SYS_PTRACE \
 --env='DEB*' --volume=$PWD:/tmp/test --workdir=/tmp/test debian:sid bash
Note that the container should be started from the parent directory of the git repository, not inside it. The --volume parameter will loop-mount the current directory inside the container. Thus all files created and modified are on the host system, and will persist after the container shuts down. Once inside the container, install the basic dependencies:
shell
apt update -q && apt install -q --yes git-buildpackage dpkg-dev dh-make

Automate creating the debian/ files with dh-make To create the files needed for the actual Debian packaging, use dh_make:
shell
# dh_make --packagename entr_5.6 --single --createorig
Maintainer Name : Otto Kek l inen
Email-Address : otto@debian.org
Date : Sat, 15 Feb 2025 01:17:51 +0000
Package Name : entr
Version : 5.6
License : blank
Package Type : single
Are the details correct? [Y/n/q]

Done. Please edit the files in the debian/ subdirectory now.
Due to how dh_make works, the package name and version need to be written as a single underscore separated string. In this case, you should choose --single to specify that the package type is a single binary package. Other options would be --library for library packages (see libgda5 sources as an example) or --indep (see dns-root-data sources as an example). The --createorig will create a mock upstream release tarball (entr_5.6.orig.tar.xz) from the current release directory, which is necessary due to historical reasons and how dh_make worked before git repositories became common and Debian source packages were based off upstream release tarballs (e.g. *.tar.gz). At this stage, a debian/ directory has been created with template files, and you can start modifying the files and iterating towards actual working packaging.
shell
git add debian/
git commit -a -m "Initial Debian packaging"

Review the files The full list of files after the above steps with dh_make would be:
 -- entr
   -- LICENSE
   -- Makefile.bsd
   -- Makefile.linux
   -- Makefile.linux-compat
   -- Makefile.macos
   -- NEWS
   -- README.md
   -- configure
   -- data.h
   -- debian
     -- README.Debian
     -- README.source
     -- changelog
     -- control
     -- copyright
     -- gbp.conf
     -- entr-docs.docs
     -- entr.cron.d.ex
     -- entr.doc-base.ex
     -- manpage.1.ex
     -- manpage.md.ex
     -- manpage.sgml.ex
     -- manpage.xml.ex
     -- postinst.ex
     -- postrm.ex
     -- preinst.ex
     -- prerm.ex
     -- rules
     -- salsa-ci.yml.ex
     -- source
       -- format
     -- upstream
       -- metadata.ex
     -- watch.ex
   -- entr.1
   -- entr.c
   -- missing
     -- compat.h
     -- kqueue_inotify.c
     -- strlcpy.c
     -- sys
     -- event.h
   -- status.c
   -- status.h
   -- system_test.sh
 -- entr_5.6.orig.tar.xz
You can browse these files in the demo repository. The mandatory files in the debian/ directory are:
  • changelog,
  • control,
  • copyright,
  • and rules.
All the other files have been created for convenience so the packager has template files to work from. The files with the suffix .ex are example files that won t have any effect until their content is adjusted and the suffix removed. For detailed explanations of the purpose of each file in the debian/ subdirectory, see the following resources:
  • The Debian Policy Manual: Describes the structure of the operating system, the package archive and requirements for packages to be included in the Debian archive.
  • The Developer s Reference: A collection of best practices and process descriptions Debian packagers are expected to follow while interacting with one another.
  • Debhelper man pages: Detailed information of how the Debian package build system works, and how the contents of the various files in debian/ affect the end result.
As Entr, the package used in this example, is a real package that already exists in the Debian archive, you may want to browse the actual Debian packaging source at https://salsa.debian.org/debian/entr/-/tree/debian/latest/debian for reference. Most of these files have standardized formatting conventions to make collaboration easier. To automatically format the files following the most popular conventions, simply run wrap-and-sort -vast or debputy reformat --style=black.

Identify build dependencies The most common reason for builds to fail is missing dependencies. The easiest way to identify which Debian package ships the required dependency is using apt-file. If, for example, a build fails complaining that pcre2posix.h cannot be found or that libcre2-posix.so is missing, you can use these commands:
shell
$ apt install -q --yes apt-file && apt-file update
$ apt-file search pcre2posix.h
libpcre2-dev: /usr/include/pcre2posix.h
$ apt-file search libpcre2-posix.so
libpcre2-dev: /usr/lib/x86_64-linux-gnu/libpcre2-posix.so
libpcre2-posix3: /usr/lib/x86_64-linux-gnu/libpcre2-posix.so.3
libpcre2-posix3: /usr/lib/x86_64-linux-gnu/libpcre2-posix.so.3.0.6
The output above implies that the debian/control should be extended to define a Build-Depends: libpcre2-dev relationship. There is also dpkg-depcheck that uses strace to trace the files the build process tries to access, and lists what Debian packages those files belong to. Example usage:
shell
dpkg-depcheck -b debian/rules build

Build the Debian sources to generate the .deb package After the first pass of refining the contents of the files in debian/, test the build by running dpkg-buildpackage inside the container:
shell
dpkg-buildpackage -uc -us -b
The options -uc -us will skip signing the resulting Debian source package and other build artifacts. The -b option will skip creating a source package and only build the (binary) *.deb packages. The output is very verbose and gives a large amount of context about what is happening during the build to make debugging build failures easier. In the build log of entr you will see for example the line dh binary --buildsystem=makefile. This and other dh commands can also be run manually if there is a need to quickly repeat only a part of the build while debugging build failures. To see what files were generated or modified by the build simply run git status --ignored:
shell
$ git status --ignored
On branch debian/latest

Untracked files:
 (use "git add <file>..." to include in what will be committed)
 debian/debhelper-build-stamp
 debian/entr.debhelper.log
 debian/entr.substvars
 debian/files

Ignored files:
 (use "git add -f <file>..." to include in what will be committed)
 Makefile
 compat.c
 compat.o
 debian/.debhelper/
 debian/entr/
 entr
 entr.o
 status.o
Re-running dpkg-buildpackage will include running the command dh clean, which assuming it is configured correctly in the debian/rules file will reset the source directory to the original pristine state. The same can of course also be done with regular git commands git reset --hard; git clean -fdx. To avoid accidentally committing unnecessary build artifacts in git, a debian/.gitignore can be useful and it would typically include all four files listed as untracked above. After a successful build you would have the following files:
shell
 -- entr
   -- LICENSE
   -- Makefile -> Makefile.linux
   -- Makefile.bsd
   -- Makefile.linux
   -- Makefile.linux-compat
   -- Makefile.macos
   -- NEWS
   -- README.md
   -- compat.c
   -- compat.o
   -- configure
   -- data.h
   -- debian
     -- README.source.md
     -- changelog
     -- control
     -- copyright
     -- debhelper-build-stamp
     -- docs
     -- entr
       -- DEBIAN
         -- control
         -- md5sums
       -- usr
       -- bin
         -- entr
       -- share
       -- doc
         -- entr
         -- NEWS.gz
         -- README.md
         -- changelog.Debian.gz
         -- copyright
       -- man
       -- man1
       -- entr.1.gz
     -- entr.debhelper.log
     -- entr.substvars
     -- files
     -- gbp.conf
     -- patches
       -- PR149-expand-aliases-in-system-test-script.patch
       -- series
       -- system-test-skip-no-tty.patch
       -- system-test-with-system-binary.patch
     -- rules
     -- salsa-ci.yml
     -- source
       -- format
     -- tests
       -- control
     -- upstream
       -- metadata
       -- signing-key.asc
     -- watch
   -- entr
   -- entr.1
   -- entr.c
   -- entr.o
   -- missing
     -- compat.h
     -- kqueue_inotify.c
     -- strlcpy.c
     -- sys
     -- event.h
   -- status.c
   -- status.h
   -- status.o
   -- system_test.sh
 -- entr-dbgsym_5.6-1_amd64.deb
 -- entr_5.6-1.debian.tar.xz
 -- entr_5.6-1.dsc
 -- entr_5.6-1_amd64.buildinfo
 -- entr_5.6-1_amd64.changes
 -- entr_5.6-1_amd64.deb
 -- entr_5.6.orig.tar.xz
The contents of debian/entr are essentially what goes into the resulting entr_5.6-1_amd64.deb package. Familiarizing yourself with the majority of the files in the original upstream source as well as all the resulting build artifacts is time consuming, but it is a necessary investment to get high-quality Debian packages. There are also tools such as Debcraft that automate generating the build artifacts in separate output directories for each build, thus making it easy to compare the changes to correlate what change in the Debian packaging led to what change in the resulting build artifacts.

Re-run the initial import with git-buildpackage When upstreams publish releases as tarballs, they should also be imported for optimal software supply-chain security, in particular if upstream also publishes cryptographic signatures that can be used to verify the authenticity of the tarballs. To achieve this, the files debian/watch, debian/upstream/signing-key.asc, and debian/gbp.conf need to be present with the correct options. In the gbp.conf file, ensure you have the correct options based on:
  1. Does upstream release tarballs? If so, enforce pristine-tar = True.
  2. Does upstream sign the tarballs? If so, configure explicit signature checking with upstream-signatures = on.
  3. Does upstream have a git repository, and does it have release git tags? If so, configure the release git tag format, e.g. upstream-vcs-tag = %(version%~%.)s.
To validate that the above files are working correctly, run gbp import-orig with the current version explicitly defined:
shell
$ gbp import-orig --uscan --upstream-version 5.6
gbp:info: Launching uscan...
gpgv: Signature made 7. Aug 2024 07.43.27 PDT
gpgv: using RSA key 519151D83E83D40A232B4D615C418B8631BC7C26
gpgv: Good signature from "Eric Radman <ericshane@eradman.com>"
gbp:info: Using uscan downloaded tarball ../entr_5.6.orig.tar.gz
gbp:info: Importing '../entr_5.6.orig.tar.gz' to branch 'upstream/latest'...
gbp:info: Source package is entr
gbp:info: Upstream version is 5.6
gbp:info: Replacing upstream source on 'debian/latest'
gbp:info: Running Postimport hook
gbp:info: Successfully imported version 5.6 of ../entr_5.6.orig.tar.gz
As the original packaging was done based on the upstream release git tag, the above command will fetch the tarball release, create the pristine-tar branch, and store the tarball delta on it. This command will also attempt to create the tag upstream/5.6 on the upstream/latest branch.

Import new upstream versions in the future Forking the upstream git repository, creating the initial packaging, and creating the DEP-14 branch structure are all one-off work needed only when creating the initial packaging. Going forward, to import new upstream releases, one would simply run git fetch upstreamvcs; gbp import-orig --uscan, which fetches the upstream git tags, checks for new upstream tarballs, and automatically downloads, verifies, and imports the new version. See the galera-4-demo example in the Debian source packages in git explained post as a demo you can try running yourself and examine in detail. You can also try running gbp import-orig --uscan without specifying a version. It would fetch it, as it will notice there is now Entr version 5.7 available, and import it.

Build using git-buildpackage From this stage onwards you should build the package using gbp buildpackage, which will do a more comprehensive build.
shell
gbp buildpackage -uc -us
The git-buildpackage build also includes running Lintian to find potential Debian policy violations in the sources or in the resulting .deb binary packages. Many Debian Developers run lintian -EviIL +pedantic after every build to check that there are no new nags, and to validate that changes intended to previous Lintian nags were correct.

Open a Merge Request on Salsa for Debian packaging review Getting everything perfectly right takes a lot of effort, and may require reaching out to an experienced Debian Developers for review and guidance. Thus, you should aim to publish your initial packaging work on Salsa, Debian s GitLab instance, for review and feedback as early as possible. For somebody to be able to easily see what you have done, you should rename your debian/latest branch to another name, for example next/debian/latest, and open a Merge Request that targets the debian/latest branch on your Salsa fork, which still has only the unmodified upstream files. If you have followed the workflow in this post so far, you can simply run:
  1. git checkout -b next/debian/latest
  2. git push --set-upstream origin next/debian/latest
  3. Open in a browser the URL visible in the git remote response
  4. Write the Merge Request description in case the default text from your commit is not enough
  5. Mark the MR as Draft using the checkbox
  6. Publish the MR and request feedback
Once a Merge Request exists, discussion regarding what additional changes are needed can be conducted as MR comments. With an MR, you can easily iterate on the contents of next/debian/latest, rebase, force push, and request re-review as many times as you want. While at it, make sure the Settings > CI/CD page has under CI/CD configuration file the value debian/salsa-ci.yml so that the CI can run and give you immediate automated feedback. For an example of an initial packaging Merge Request, see https://salsa.debian.org/otto/entr-demo/-/merge_requests/1.

Open a Merge Request / Pull Request to fix upstream code Due to the high quality requirements in Debian, it is fairly common that while doing the initial Debian packaging of an open source project, issues are found that stem from the upstream source code. While it is possible to carry extra patches in Debian, it is not good practice to deviate too much from upstream code with custom Debian patches. Instead, the Debian packager should try to get the fixes applied directly upstream. Using git-buildpackage patch queues is the most convenient way to make modifications to the upstream source code so that they automatically convert into Debian patches (stored at debian/patches), and can also easily be submitted upstream as any regular git commit (and rebased and resubmitted many times over). First, decide if you want to work out of the upstream development branch and later cherry-pick to the Debian packaging branch, or work out of the Debian packaging branch and cherry-pick to an upstream branch. The example below starts from the upstream development branch and then cherry-picks the commit into the git-buildpackage patch queue:
shell
git checkout -b bugfix-branch master
nano entr.c
make
./entr # verify change works as expected
git commit -a -m "Commit title" -m "Commit body"
git push # submit upstream
gbp pq import --force --time-machine=10
git cherry-pick <commit id>
git commit --amend # extend commit message with DEP-3 metadata
gbp buildpackage -uc -us -b
./entr # verify change works as expected
gbp pq export --drop --commit
git commit --amend # Write commit message along lines "Add patch to .."
The example below starts by making the fix on a git-buildpackage patch queue branch, and then cherry-picking it onto the upstream development branch:
shell
gbp pq import --force --time-machine=10
nano entr.c
git commit -a -m "Commit title" -m "Commit body"
gbp buildpackage -uc -us -b
./entr # verify change works as expected
gbp pq export --drop --commit
git commit --amend # Write commit message along lines "Add patch to .."
git checkout -b bugfix-branch master
git cherry-pick <commit id>
git commit --amend # prepare commit message for upstream submission
git push # submit upstream
The key git-buildpackage commands to enter and exit the patch-queue mode are:
shell
gbp pq import --force --time-machine=10
gbp pq export --drop --commit
%% init:   'gitGraph':   'mainBranchName': 'debian/latest'      %%
gitGraph
checkout debian/latest
commit id: "Initial packaging"
branch patch-queue/debian/latest
checkout patch-queue/debian/latest
commit id: "Delete debian/patches/..."
commit id: "Patch 1 title"
commit id: "Patch 2 title"
commit id: "Patch 3 title"
These can be run at any time, regardless if any debian/patches existed prior, or if existing patches applied cleanly or not, or if there were old patch queue branches around. Note that the extra -b in gbp buildpackage -uc -us -b instructs to build only binary packages, avoiding any nags from dpkg-source that there are modifications in the upstream sources while building in the patches-applied mode.

Programming-language specific dh-make alternatives As each programming language has its specific way of building the source code, and many other conventions regarding the file layout and more, Debian has multiple custom tools to create new Debian source packages for specific programming languages. Notably, Python does not have its own tool, but there is an dh_make --python option for Python support directly in dh_make itself. The list is not complete and many more tools exist. For some languages, there are even competing options, such as for Go there is in addition to dh-make-golang also Gophian. When learning Debian packaging, there is no need to learn these tools upfront. Being aware that they exist is enough, and one can learn them only if and when one starts to package a project in a new programming language.

The difference between source git repository vs source packages vs binary packages As seen in earlier example, running gbp buildpackage on the Entr packaging repository above will result in several files:
entr_5.6-1_amd64.changes
entr_5.6-1_amd64.deb
entr_5.6-1.debian.tar.xz
entr_5.6-1.dsc
entr_5.6.orig.tar.gz
entr_5.6.orig.tar.gz.asc
The entr_5.6-1_amd64.deb is the binary package, which can be installed on a Debian/Ubuntu system. The rest of the files constitute the source package. To do a source-only build, run gbp buildpackage -S and note the files produced:
entr_5.6-1_source.changes
entr_5.6-1.debian.tar.xz
entr_5.6-1.dsc
entr_5.6.orig.tar.gz
entr_5.6.orig.tar.gz.asc
The source package files can be used to build the binary .deb for amd64, or any architecture that the package supports. It is important to grasp that the Debian source package is the preferred form to be able to build the binary packages on various Debian build systems, and the Debian source package is not the same thing as the Debian packaging git repository contents.
flowchart LR
git[Git repository<br>branch debian/latest] --> gbp buildpackage -S  src[Source Package<br>.dsc + .tar.xz]
src --> dpkg-buildpackage  bin[Binary Packages<br>.deb]
If the package is large and complex, the build could result in multiple binary packages. One set of package definition files in debian/ will however only ever result in a single source package.

Option to repackage source packages with Files-Excluded lists in the debian/copyright file Some upstream projects may include binary files in their release, or other undesirable content that needs to be omitted from the source package in Debian. The easiest way to filter them out is by adding to the debian/copyright file a Files-Excluded field listing the undesired files. The debian/copyright file is read by uscan, which will repackage the upstream sources on-the-fly when importing new upstream releases. For a real-life example, see the debian/copyright files in the Godot package that lists:
debian
Files-Excluded: platform/android/java/gradle/wrapper/gradle-wrapper.jar
The resulting repackaged upstream source tarball, as well as the upstream version component, will have an extra +ds to signify that it is not the true original upstream source but has been modified by Debian:
godot_4.3+ds.orig.tar.xz
godot_4.3+ds-1_amd64.deb

Creating one Debian source package from multiple upstream source packages also possible In some rare cases the upstream project may be split across multiple git repositories or the upstream release may consist of multiple components each in their own separate tarball. Usually these are very large projects that get some benefits from releasing components separately. If in Debian these are deemed to go into a single source package, it is technically possible using the component system in git-buildpackage and uscan. For an example see the gbp.conf and watch files in the node-cacache package. Using this type of structure should be a last resort, as it creates complexity and inter-dependencies that are bound to cause issues later on. It is usually better to work with upstream and champion universal best practices with clear releases and version schemes.

When not to start the Debian packaging repository as a fork of the upstream one Not all upstreams use Git for version control. It is by far the most popular, but there are still some that use e.g. Subversion or Mercurial. Who knows maybe in the future some new version control systems will start to compete with Git. There are also projects that use Git in massive monorepos and with complex submodule setups that invalidate the basic assumptions required to map an upstream Git repository into a Debian packaging repository. In those cases one can t use a debian/latest branch on a clone of the upstream git repository as the starting point for the Debian packaging, but one must revert the traditional way of starting from an upstream release tarball with gbp import-orig package-1.0.tar.gz.

Conclusion Created in August 1993, Debian is one of the oldest Linux distributions. In the 32 years since inception, the .deb packaging format and the tooling to work with it have evolved several generations. In the past 10 years, more and more Debian Developers have converged on certain core practices evidenced by https://trends.debian.net/, but there is still a lot of variance in workflows even for identical tasks. Hopefully, you find this post useful in giving practical guidance on how exactly to do the most common things when packaging software for Debian. Happy packaging!

25 May 2025

Otto Kek l inen: New Debian package creation from upstream git repository

Featured image of post New Debian package creation from upstream git repositoryIn this post, I demonstrate the optimal workflow for creating new Debian packages in 2025, preserving the upstream git history. The motivation for this is to lower the barrier for sharing improvements to and from upstream, and to improve software provenance and supply-chain security by making it easy to inspect every change at any level using standard git tooling. Key elements of this workflow include: To make the instructions so concrete that anyone can repeat all the steps themselves on a real package, I demonstrate the steps by packaging the command-line tool Entr. It is written in C, has very few dependencies, and its final Debian source package structure is simple, yet exemplifies all the important parts that go into a complete Debian package:
  1. Creating a new packaging repository and publishing it under your personal namespace on salsa.debian.org.
  2. Using dh_make to create the initial Debian packaging.
  3. Posting the first draft of the Debian packaging as a Merge Request (MR) and using Salsa CI to verify Debian packaging quality.
  4. Running local builds efficiently and iterating on the packaging process.

Create new Debian packaging repository from the existing upstream project git repository First, create a new empty directory, then clone the upstream Git repository inside it:
shell
mkdir debian-entr
cd debian-entr
git clone --origin upstreamvcs --branch master \
 --single-branch https://github.com/eradman/entr.git
Using a clean directory makes it easier to inspect the build artifacts of a Debian package, which will be output in the parent directory of the Debian source directory. The extra parameters given to git clone lay the foundation for the Debian packaging git repository structure where the upstream git remote name is upstreamvcs. Only the upstream main branch is tracked to avoid cluttering git history with upstream development branches that are irrelevant for packaging in Debian. Next, enter the git repository directory and list the git tags. Pick the latest upstream release tag as the commit to start the branch upstream/latest. This latest refers to the upstream release, not the upstream development branch. Immediately after, branch off the debian/latest branch, which will have the actual Debian packaging files in the debian/ subdirectory.
shell
cd entr
git tag # shows the latest upstream release tag was '5.6'
git checkout -b upstream/latest 5.6
git checkout -b debian/latest
%% init:   'gitGraph':   'mainBranchName': 'master'      %%
gitGraph:
checkout master
commit id: "Upstream 5.6 release" tag: "5.6"
branch upstream/latest
checkout upstream/latest
commit id: "New upstream version 5.6" tag: "upstream/5.6"
branch debian/latest
checkout debian/latest
commit id: "Initial Debian packaging"
commit id: "Additional change 1"
commit id: "Additional change 2"
commit id: "Additional change 3"
At this point, the repository is structured according to DEP-14 conventions, ensuring a clear separation between upstream and Debian packaging changes, but there are no Debian changes yet. Next, add the Salsa repository as a new remote which called origin, the same as the default remote name in git.
shell
git remote add origin git@salsa.debian.org:otto/entr-demo.git
git push --set-upstream origin debian/latest
This is an important preparation step to later be able to create a Merge Request on Salsa that targets the debian/latest branch, which does not yet have any debian/ directory.

Launch a Debian Sid (unstable) container to run builds in To ensure that all packaging tools are of the latest versions, run everything inside a fresh Sid container. This has two benefits: you are guaranteed to have the most up-to-date toolchain, and your host system stays clean without getting polluted by various extra packages. Additionally, this approach works even if your host system is not Debian/Ubuntu.
shell
cd ..
podman run --interactive --tty --rm --shm-size=1G --cap-add SYS_PTRACE \
 --env='DEB*' --volume=$PWD:/tmp/test --workdir=/tmp/test debian:sid bash
Note that the container should be started from the parent directory of the git repository, not inside it. The --volume parameter will loop-mount the current directory inside the container. Thus all files created and modified are on the host system, and will persist after the container shuts down. Once inside the container, install the basic dependencies:
shell
apt update -q && apt install -q --yes git-buildpackage dpkg-dev dh-make

Automate creating the debian/ files with dh-make To create the files needed for the actual Debian packaging, use dh_make:
shell
# dh_make --packagename entr_5.6 --single --createorig
Maintainer Name : Otto Kek l inen
Email-Address : otto@debian.org
Date : Sat, 15 Feb 2025 01:17:51 +0000
Package Name : entr
Version : 5.6
License : blank
Package Type : single
Are the details correct? [Y/n/q]

Done. Please edit the files in the debian/ subdirectory now.
Due to how dh_make works, the package name and version need to be written as a single underscore separated string. In this case, you should choose --single to specify that the package type is a single binary package. Other options would be --library for library packages (see libgda5 sources as an example) or --indep (see dns-root-data sources as an example). The --createorig will create a mock upstream release tarball (entr_5.6.orig.tar.xz) from the current release directory, which is necessary due to historical reasons and how dh_make worked before git repositories became common and Debian source packages were based off upstream release tarballs (e.g. *.tar.gz). At this stage, a debian/ directory has been created with template files, and you can start modifying the files and iterating towards actual working packaging.
shell
git add debian/
git commit -a -m "Initial Debian packaging"

Review the files The full list of files after the above steps with dh_make would be:
 -- entr
   -- LICENSE
   -- Makefile.bsd
   -- Makefile.linux
   -- Makefile.linux-compat
   -- Makefile.macos
   -- NEWS
   -- README.md
   -- configure
   -- data.h
   -- debian
     -- README.Debian
     -- README.source
     -- changelog
     -- control
     -- copyright
     -- gbp.conf
     -- entr-docs.docs
     -- entr.cron.d.ex
     -- entr.doc-base.ex
     -- manpage.1.ex
     -- manpage.md.ex
     -- manpage.sgml.ex
     -- manpage.xml.ex
     -- postinst.ex
     -- postrm.ex
     -- preinst.ex
     -- prerm.ex
     -- rules
     -- salsa-ci.yml.ex
     -- source
       -- format
     -- upstream
       -- metadata.ex
     -- watch.ex
   -- entr.1
   -- entr.c
   -- missing
     -- compat.h
     -- kqueue_inotify.c
     -- strlcpy.c
     -- sys
     -- event.h
   -- status.c
   -- status.h
   -- system_test.sh
 -- entr_5.6.orig.tar.xz
You can browse these files in the demo repository. The mandatory files in the debian/ directory are:
  • changelog,
  • control,
  • copyright,
  • and rules.
All the other files have been created for convenience so the packager has template files to work from. The files with the suffix .ex are example files that won t have any effect until their content is adjusted and the suffix removed. For detailed explanations of the purpose of each file in the debian/ subdirectory, see the following resources:
  • The Debian Policy Manual: Describes the structure of the operating system, the package archive and requirements for packages to be included in the Debian archive.
  • The Developer s Reference: A collection of best practices and process descriptions Debian packagers are expected to follow while interacting with one another.
  • Debhelper man pages: Detailed information of how the Debian package build system works, and how the contents of the various files in debian/ affect the end result.
As Entr, the package used in this example, is a real package that already exists in the Debian archive, you may want to browse the actual Debian packaging source at https://salsa.debian.org/debian/entr/-/tree/debian/latest/debian for reference. Most of these files have standardized formatting conventions to make collaboration easier. To automatically format the files following the most popular conventions, simply run wrap-and-sort -vast or debputy reformat --style=black.

Identify build dependencies The most common reason for builds to fail is missing dependencies. The easiest way to identify which Debian package ships the required dependency is using apt-file. If, for example, a build fails complaining that pcre2posix.h cannot be found or that libcre2-posix.so is missing, you can use these commands:
shell
$ apt install -q --yes apt-file && apt-file update
$ apt-file search pcre2posix.h
libpcre2-dev: /usr/include/pcre2posix.h
$ apt-file search libpcre2-posix.so
libpcre2-dev: /usr/lib/x86_64-linux-gnu/libpcre2-posix.so
libpcre2-posix3: /usr/lib/x86_64-linux-gnu/libpcre2-posix.so.3
libpcre2-posix3: /usr/lib/x86_64-linux-gnu/libpcre2-posix.so.3.0.6
The output above implies that the debian/control should be extended to define a Build-Depends: libpcre2-dev relationship. There is also dpkg-depcheck that uses strace to trace the files the build process tries to access, and lists what Debian packages those files belong to. Example usage:
shell
dpkg-depcheck -b debian/rules build

Build the Debian sources to generate the .deb package After the first pass of refining the contents of the files in debian/, test the build by running dpkg-buildpackage inside the container:
shell
dpkg-buildpackage -uc -us -b
The options -uc -us will skip signing the resulting Debian source package and other build artifacts. The -b option will skip creating a source package and only build the (binary) *.deb packages. The output is very verbose and gives a large amount of context about what is happening during the build to make debugging build failures easier. In the build log of entr you will see for example the line dh binary --buildsystem=makefile. This and other dh commands can also be run manually if there is a need to quickly repeat only a part of the build while debugging build failures. To see what files were generated or modified by the build simply run git status --ignored:
shell
$ git status --ignored
On branch debian/latest

Untracked files:
 (use "git add <file>..." to include in what will be committed)
 debian/debhelper-build-stamp
 debian/entr.debhelper.log
 debian/entr.substvars
 debian/files

Ignored files:
 (use "git add -f <file>..." to include in what will be committed)
 Makefile
 compat.c
 compat.o
 debian/.debhelper/
 debian/entr/
 entr
 entr.o
 status.o
Re-running dpkg-buildpackage will include running the command dh clean, which assuming it is configured correctly in the debian/rules file will reset the source directory to the original pristine state. The same can of course also be done with regular git commands git reset --hard; git clean -fdx. To avoid accidentally committing unnecessary build artifacts in git, a debian/.gitignore can be useful and it would typically include all four files listed as untracked above. After a successful build you would have the following files:
shell
 -- entr
   -- LICENSE
   -- Makefile -> Makefile.linux
   -- Makefile.bsd
   -- Makefile.linux
   -- Makefile.linux-compat
   -- Makefile.macos
   -- NEWS
   -- README.md
   -- compat.c
   -- compat.o
   -- configure
   -- data.h
   -- debian
     -- README.source.md
     -- changelog
     -- control
     -- copyright
     -- debhelper-build-stamp
     -- docs
     -- entr
       -- DEBIAN
         -- control
         -- md5sums
       -- usr
       -- bin
         -- entr
       -- share
       -- doc
         -- entr
         -- NEWS.gz
         -- README.md
         -- changelog.Debian.gz
         -- copyright
       -- man
       -- man1
       -- entr.1.gz
     -- entr.debhelper.log
     -- entr.substvars
     -- files
     -- gbp.conf
     -- patches
       -- PR149-expand-aliases-in-system-test-script.patch
       -- series
       -- system-test-skip-no-tty.patch
       -- system-test-with-system-binary.patch
     -- rules
     -- salsa-ci.yml
     -- source
       -- format
     -- tests
       -- control
     -- upstream
       -- metadata
       -- signing-key.asc
     -- watch
   -- entr
   -- entr.1
   -- entr.c
   -- entr.o
   -- missing
     -- compat.h
     -- kqueue_inotify.c
     -- strlcpy.c
     -- sys
     -- event.h
   -- status.c
   -- status.h
   -- status.o
   -- system_test.sh
 -- entr-dbgsym_5.6-1_amd64.deb
 -- entr_5.6-1.debian.tar.xz
 -- entr_5.6-1.dsc
 -- entr_5.6-1_amd64.buildinfo
 -- entr_5.6-1_amd64.changes
 -- entr_5.6-1_amd64.deb
 -- entr_5.6.orig.tar.xz
The contents of debian/entr are essentially what goes into the resulting entr_5.6-1_amd64.deb package. Familiarizing yourself with the majority of the files in the original upstream source as well as all the resulting build artifacts is time consuming, but it is a necessary investment to get high-quality Debian packages. There are also tools such as Debcraft that automate generating the build artifacts in separate output directories for each build, thus making it easy to compare the changes to correlate what change in the Debian packaging led to what change in the resulting build artifacts.

Re-run the initial import with git-buildpackage When upstreams publish releases as tarballs, they should also be imported for optimal software supply-chain security, in particular if upstream also publishes cryptographic signatures that can be used to verify the authenticity of the tarballs. To achieve this, the files debian/watch, debian/upstream/signing-key.asc, and debian/gbp.conf need to be present with the correct options. In the gbp.conf file, ensure you have the correct options based on:
  1. Does upstream release tarballs? If so, enforce pristine-tar = True.
  2. Does upstream sign the tarballs? If so, configure explicit signature checking with upstream-signatures = on.
  3. Does upstream have a git repository, and does it have release git tags? If so, configure the release git tag format, e.g. upstream-vcs-tag = %(version%~%.)s.
To validate that the above files are working correctly, run gbp import-orig with the current version explicitly defined:
shell
$ gbp import-orig --uscan --upstream-version 5.6
gbp:info: Launching uscan...
gpgv: Signature made 7. Aug 2024 07.43.27 PDT
gpgv: using RSA key 519151D83E83D40A232B4D615C418B8631BC7C26
gpgv: Good signature from "Eric Radman <ericshane@eradman.com>"
gbp:info: Using uscan downloaded tarball ../entr_5.6.orig.tar.gz
gbp:info: Importing '../entr_5.6.orig.tar.gz' to branch 'upstream/latest'...
gbp:info: Source package is entr
gbp:info: Upstream version is 5.6
gbp:info: Replacing upstream source on 'debian/latest'
gbp:info: Running Postimport hook
gbp:info: Successfully imported version 5.6 of ../entr_5.6.orig.tar.gz
As the original packaging was done based on the upstream release git tag, the above command will fetch the tarball release, create the pristine-tar branch, and store the tarball delta on it. This command will also attempt to create the tag upstream/5.6 on the upstream/latest branch.

Import new upstream versions in the future Forking the upstream git repository, creating the initial packaging, and creating the DEP-14 branch structure are all one-off work needed only when creating the initial packaging. Going forward, to import new upstream releases, one would simply run git fetch upstreamvcs; gbp import-orig --uscan, which fetches the upstream git tags, checks for new upstream tarballs, and automatically downloads, verifies, and imports the new version. See the galera-4-demo example in the Debian source packages in git explained post as a demo you can try running yourself and examine in detail. You can also try running gbp import-orig --uscan without specifying a version. It would fetch it, as it will notice there is now Entr version 5.7 available, and import it.

Build using git-buildpackage From this stage onwards you should build the package using gbp buildpackage, which will do a more comprehensive build.
shell
gbp buildpackage -uc -us
The git-buildpackage build also includes running Lintian to find potential Debian policy violations in the sources or in the resulting .deb binary packages. Many Debian Developers run lintian -EviIL +pedantic after every build to check that there are no new nags, and to validate that changes intended to previous Lintian nags were correct.

Open a Merge Request on Salsa for Debian packaging review Getting everything perfectly right takes a lot of effort, and may require reaching out to an experienced Debian Developers for review and guidance. Thus, you should aim to publish your initial packaging work on Salsa, Debian s GitLab instance, for review and feedback as early as possible. For somebody to be able to easily see what you have done, you should rename your debian/latest branch to another name, for example next/debian/latest, and open a Merge Request that targets the debian/latest branch on your Salsa fork, which still has only the unmodified upstream files. If you have followed the workflow in this post so far, you can simply run:
  1. git checkout -b next/debian/latest
  2. git push --set-upstream origin next/debian/latest
  3. Open in a browser the URL visible in the git remote response
  4. Write the Merge Request description in case the default text from your commit is not enough
  5. Mark the MR as Draft using the checkbox
  6. Publish the MR and request feedback
Once a Merge Request exists, discussion regarding what additional changes are needed can be conducted as MR comments. With an MR, you can easily iterate on the contents of next/debian/latest, rebase, force push, and request re-review as many times as you want. While at it, make sure the Settings > CI/CD page has under CI/CD configuration file the value debian/salsa-ci.yml so that the CI can run and give you immediate automated feedback. For an example of an initial packaging Merge Request, see https://salsa.debian.org/otto/entr-demo/-/merge_requests/1.

Open a Merge Request / Pull Request to fix upstream code Due to the high quality requirements in Debian, it is fairly common that while doing the initial Debian packaging of an open source project, issues are found that stem from the upstream source code. While it is possible to carry extra patches in Debian, it is not good practice to deviate too much from upstream code with custom Debian patches. Instead, the Debian packager should try to get the fixes applied directly upstream. Using git-buildpackage patch queues is the most convenient way to make modifications to the upstream source code so that they automatically convert into Debian patches (stored at debian/patches), and can also easily be submitted upstream as any regular git commit (and rebased and resubmitted many times over). First, decide if you want to work out of the upstream development branch and later cherry-pick to the Debian packaging branch, or work out of the Debian packaging branch and cherry-pick to an upstream branch. The example below starts from the upstream development branch and then cherry-picks the commit into the git-buildpackage patch queue:
shell
git checkout -b bugfix-branch master
nano entr.c
make
./entr # verify change works as expected
git commit -a -m "Commit title" -m "Commit body"
git push # submit upstream
gbp pq import --force --time-machine=10
git cherry-pick <commit id>
git commit --amend # extend commit message with DEP-3 metadata
gbp buildpackage -uc -us -b
./entr # verify change works as expected
gbp pq export --drop --commit
git commit --amend # Write commit message along lines "Add patch to .."
The example below starts by making the fix on a git-buildpackage patch queue branch, and then cherry-picking it onto the upstream development branch:
shell
gbp pq import --force --time-machine=10
nano entr.c
git commit -a -m "Commit title" -m "Commit body"
gbp buildpackage -uc -us -b
./entr # verify change works as expected
gbp pq export --drop --commit
git commit --amend # Write commit message along lines "Add patch to .."
git checkout -b bugfix-branch master
git cherry-pick <commit id>
git commit --amend # prepare commit message for upstream submission
git push # submit upstream
The key git-buildpackage commands to enter and exit the patch-queue mode are:
shell
gbp pq import --force --time-machine=10
gbp pq export --drop --commit
%% init:   'gitGraph':   'mainBranchName': 'debian/latest'      %%
gitGraph
checkout debian/latest
commit id: "Initial packaging"
branch patch-queue/debian/latest
checkout patch-queue/debian/latest
commit id: "Delete debian/patches/..."
commit id: "Patch 1 title"
commit id: "Patch 2 title"
commit id: "Patch 3 title"
These can be run at any time, regardless if any debian/patches existed prior, or if existing patches applied cleanly or not, or if there were old patch queue branches around. Note that the extra -b in gbp buildpackage -uc -us -b instructs to build only binary packages, avoiding any nags from dpkg-source that there are modifications in the upstream sources while building in the patches-applied mode.

Programming-language specific dh-make alternatives As each programming language has its specific way of building the source code, and many other conventions regarding the file layout and more, Debian has multiple custom tools to create new Debian source packages for specific programming languages. Notably, Python does not have its own tool, but there is an dh_make --python option for Python support directly in dh_make itself. The list is not complete and many more tools exist. For some languages, there are even competing options, such as for Go there is in addition to dh-make-golang also Gophian. When learning Debian packaging, there is no need to learn these tools upfront. Being aware that they exist is enough, and one can learn them only if and when one starts to package a project in a new programming language.

The difference between source git repository vs source packages vs binary packages As seen in earlier example, running gbp buildpackage on the Entr packaging repository above will result in several files:
entr_5.6-1_amd64.changes
entr_5.6-1_amd64.deb
entr_5.6-1.debian.tar.xz
entr_5.6-1.dsc
entr_5.6.orig.tar.gz
entr_5.6.orig.tar.gz.asc
The entr_5.6-1_amd64.deb is the binary package, which can be installed on a Debian/Ubuntu system. The rest of the files constitute the source package. To do a source-only build, run gbp buildpackage -S and note the files produced:
entr_5.6-1_source.changes
entr_5.6-1.debian.tar.xz
entr_5.6-1.dsc
entr_5.6.orig.tar.gz
entr_5.6.orig.tar.gz.asc
The source package files can be used to build the binary .deb for amd64, or any architecture that the package supports. It is important to grasp that the Debian source package is the preferred form to be able to build the binary packages on various Debian build systems, and the Debian source package is not the same thing as the Debian packaging git repository contents.
flowchart LR
git[Git repository<br>branch debian/latest] --> gbp buildpackage -S  src[Source Package<br>.dsc + .tar.xz]
src --> dpkg-buildpackage  bin[Binary Packages<br>.deb]
If the package is large and complex, the build could result in multiple binary packages. One set of package definition files in debian/ will however only ever result in a single source package.

Option to repackage source packages with Files-Excluded lists in the debian/copyright file Some upstream projects may include binary files in their release, or other undesirable content that needs to be omitted from the source package in Debian. The easiest way to filter them out is by adding to the debian/copyright file a Files-Excluded field listing the undesired files. The debian/copyright file is read by uscan, which will repackage the upstream sources on-the-fly when importing new upstream releases. For a real-life example, see the debian/copyright files in the Godot package that lists:
debian
Files-Excluded: platform/android/java/gradle/wrapper/gradle-wrapper.jar
The resulting repackaged upstream source tarball, as well as the upstream version component, will have an extra +ds to signify that it is not the true original upstream source but has been modified by Debian:
godot_4.3+ds.orig.tar.xz
godot_4.3+ds-1_amd64.deb

Creating one Debian source package from multiple upstream source packages also possible In some rare cases the upstream project may be split across multiple git repositories or the upstream release may consist of multiple components each in their own separate tarball. Usually these are very large projects that get some benefits from releasing components separately. If in Debian these are deemed to go into a single source package, it is technically possible using the component system in git-buildpackage and uscan. For an example see the gbp.conf and watch files in the node-cacache package. Using this type of structure should be a last resort, as it creates complexity and inter-dependencies that are bound to cause issues later on. It is usually better to work with upstream and champion universal best practices with clear releases and version schemes.

When not to start the Debian packaging repository as a fork of the upstream one Not all upstreams use Git for version control. It is by far the most popular, but there are still some that use e.g. Subversion or Mercurial. Who knows maybe in the future some new version control systems will start to compete with Git. There are also projects that use Git in massive monorepos and with complex submodule setups that invalidate the basic assumptions required to map an upstream Git repository into a Debian packaging repository. In those cases one can t use a debian/latest branch on a clone of the upstream git repository as the starting point for the Debian packaging, but one must revert the traditional way of starting from an upstream release tarball with gbp import-orig package-1.0.tar.gz.

Conclusion Created in August 1993, Debian is one of the oldest Linux distributions. In the 32 years since inception, the .deb packaging format and the tooling to work with it have evolved several generations. In the past 10 years, more and more Debian Developers have converged on certain core practices evidenced by https://trends.debian.net/, but there is still a lot of variance in workflows even for identical tasks. Hopefully, you find this post useful in giving practical guidance on how exactly to do the most common things when packaging software for Debian. Happy packaging!

Next.

Previous.