There has been a video blog post recently published with a review of Ubuntu Touch as an option to opt out of the Android world: https://www.youtube.com/watch?v=wTK6TS3pXgc
Thanks to @SwitchandClick for spending time on this and publishing that video. Much appreciated.
Many Issues amended in upcoming 24.04-2.0 Release
When I watched that video referenced above, I continuously thought: ah... this is fixed in the next major release of Ubuntu Touch, or: ah... this is a known issue that we have on the roadmap..., or: ah... this is done in this ways by design (so it's a feature or basic functionality)...
Let me just state, that most of the criticized aspects will be resolved in upcoming Ubuntu Touch release 24.04-2.0 (the tests in that video blog post have been run on Ubuntu Touch 24.04-1.x):
Camera notch and rounding corners get honoured now by the UI
Ubuntu Touch's default webbrowser (Morph Browser) has been bumped from Chromium engine v87 (Qt5 based) to v134 (Qt6 based), installing another browser should not be necessary anymore (note that the privacy level in Morph Browser is pretty high, so using other browsers could mean a loss of privacy).
Bluetooth pairing agent got added to the bluetooth indicator
Ubuntu Touch now supports Snaps on CLI level and in the OpenStore app
Libertine has received fixes, but no substantial improvements. It mainly targets users who want to use their Ubuntu Touch device as desktop daily driver. Libertine-provided desktop apps UI-wise are often not usable on a phone-like device.
The full feature preview of the 24.04-2.0 release can be found here: https://ubports.com/blog/ubports-news-1/ubuntu-touch-24-04-2-0-beta-is-n...
Ubuntu Touch App Ecosystem
The app ecosystem of Ubuntu Touch is quite specific, because many apps in Ubuntu Touch have been explicitly developed for Ubuntu Touch using a widget toolkit called Lomiri.Components. However, in Ubuntu Touch we also encourage developers to provide apps written with other convergent-capable toolkits, such as QQC2-based apps or Kirigami-based apps.
One reason for the very different app ecosystem in Ubuntu Touch is that many service providers don't have Ubuntu Touch on their radar when investing in app development for their services. Some Ubuntu Touch App Developers work around this by either implementing unofficial client apps for web services (e.g. the Flow app for Deezer by Sander Klootwijk), others provide the web service via implementing a web app (will not work when offline, but at least will show up as an app in the launcher).
The overall solution for making Open-Store.io more familiar to users who migrate from Android is that commercial service providers start honouring digital sovereignty and start providing apps for Linux. Not just for the Linux desktop, but also for mobile Linux platforms. This dual use case can easily achieved with an app development that bears convergence in mind.
App Ecosystems are also a Matter of Perspective
And one more minor note: whenever I open an Android appstore or can peak over someone's shoulder using an iOS device: I always wonder: what are all these apps about??? Never heard about them.
So, familiarity really depends on perspective. And perspective depends on what you are used to. Change what you do and your perspective will follow.
Ubuntu Touch's root filesystem (rootfs) is Immutable
Only thing from that video blog post that we haven't fixed and won't do so in the midterm future is apt-get not working on the command line.
The reason for this is: the Ubuntu Touch root file system is an immutable file system and thus shall not be changed via apt-get & friends by ordinary users.
There are various discussions ongoing such as dpkg-divert'ing apt-get to a wrapper shell script that spits out an error message if rootfs is mounted read-only and someone tries to install packages the Debian/Ubuntu way. Other approaches are to mount some RAM disk over the rootfs, so apt-get can be used at runtime but changes to the system get reset at reboot.
However, it is possible to mount the root filesystem read-write and test newer package versions (as UT core developers do regularly, in fact). If you tinker with this, it is recommended to reflash your device (don't wipe user data, when you reflash!) from time to time, because adding packages or package upgrades to your rootfs may over time corrupt the integrity of the rootfs.
One reason for apt-get breaking the rootfs and thus your Ubuntu Touch development device is that the upgrade process of the rootfs image is incremental, so update tarballs sometimes contain only those parts that got changed between this and your previous upgrade (sometimes, upgrades contain a complete rootf image, depending on the interval between upgrades). If files from an incremental update tarball mix into a rootfs that got tinkered with via apt-get, you really end up on your own. Re-flashing will grab the complete rootfs tarball and wipe the whole rootfs and reinstall a fresh version of the newest rootfs image. Developers also do this in regular intervals to ensure their test device is clean again before running more/other tests.
Very happy to share that a new package rspdlite arrived on
CRAN today in its inaugural
version 0.1.0-1. It wraps and provides the (header-only) C++20 library
spdlite which its author
describes (aptly) as tiny, fast, capable. Just like its bigger
sibbling spdlog (which we
wrapped as rcppspdlog), it is
written by Gabi Melman. However,
with a focus on C++20 and compile-time configuration, it is lighter,
nimbler and faster. It is also still a fairly young project so changes
may occur.
I have been working on this for about a month, and it is ready for
use by R and C++. It contains the initial upstream release 0.1.0, and I
plan to follow the upstream versioning making this first release as
0.1.0-1.
The package itself provides the headers for use from other C++
projects (i.e. mostly other packages), as well as a simple R wrapper so
that logging can occur from either C++ or R. It will generally access
the single logger instance in a compilation unit. So for a package built
against these header it would be shared library of that package. At
present we provide the basic logging level setters and getters,
formatting accessors, and two (compile-time) options of a null logger
and a file-based logger. More options are availble from the C++ level,
multiple logging sinks are but one example. Some examples are provided
in the package as an R
example and a C++
example; these are probably best examined from the sources.
The NEWS entry for this release is simply and just announces that we
have a release. More details are in the ChangeLog
and the GitHub
repo.
The next Ubuntu Touch major release is approaching rapidly, yesterday we reached a major step in the preparation of the upcoming Ubuntu Touch 24.04-2.0 release: The branching-off (see below on what that is).
Ubuntu Touch 24.04-2.0 Beta is Now Available
Part of this development release step is the publication of the 24.04-2.0 Beta release images, for more details and information see: https://ubports.com/blog/ubports-news-1/ubuntu-touch-24-04-2-0-beta-is-n...
And additionally, find below some background information on how we maintain various Ubuntu Touch releases in parallel via Git(Lab). In fact, the release model of Ubuntu Touch has partially been adopted from how we in Debian maintains our various Debian versions in parallel, only that in Ubuntu Touch we use Git(Lab) for maintaining the different package versions and not, like in Debian, the APT archive itself.
What does 'Branching-Off' Mean?
Last Saturday, in the UBports Q&A, I explained Ubuntu Touch's "branching-off", an aspect of the Ubuntu Touch release workflow based on Git(Lab). To make this accessible to even more people, here it comes as a write-up:
We host many Git repositories on GitLab, and our primary work is done on the main branches, which contain the bleeding-edge code. When a merge request is deemed critical for stable versions of Ubuntu Touch, we cherry-pick it into a release series branch.
Currently, we land our changes in the main branches and then cherry-pick them to the ubports/24.04.1.x branches. The 'branching off' process for the upcoming 24.04-2.x release means that our current main branches will be copied over to create new branches for this release cycle, namely ubports/24.04-2.x.
This has two major implications. First, any item that hasn't been translated by the time of the branch-off will not receive any more translation updates during the 24.04-2.x cycle. This is why it is crucial that translation work is completed before the branching-off.
Warning of Breaking Changes arriving soon in 26.04-1.x Daily Development UT Images
Second, looking ahead to the release after 24.04-2.x, we will be approaching 26.04-1.x. The OS base will change to Ubuntu 26.04 LTS, hopefully being ready for release to Ubuntu Touch users before the end of the year. We already have a list of features we want to land there. Because we plan to include various major changes, such as the switch from Mir 1 to Mir 2, new calendar and contacts backends, Qt6-based core apps and service components, etc., the likelihood of breaking changes at the beginning of the 26.04-1.x release cycle (which will become the next main branches' target) is very high.
The Ubuntu Touch 24.04-2.0 Release Schedule
The current release schedule is estimated to be:
25 May 2026 [done]
Platform stability freeze 24.04-2.x
25 May 2026 [done]
String freeze 24.04-2.x
15 June 2026 [done]
Branching-off (and unfreeze 26.04-1.x development), UT image release: 24.04-2.0 Beta
22 or 29 June 2026 [coming]
Final freeze for 24.04-2.x, UT image release: 24.04-2.0 RC
6 or 13 July 2026 [coming]
Release version 24.04-2.0
In 2008, I landed my second job, in the network team at Orange
Portails1, the division behind the websites and search engine of the
French telecom operator Orange. The place ran like clockwork: a comprehensive
technical setup, a dedicated team for every part of the business, and room to
focus on what I do best. A few years later, none of that mattered: thanks to an
obsession with the numbers, we could no longer deliver new services on time.
Disclaimer
This is a story I like to tell to warn people about
Goodhart s law.2 As these events happened almost 15 years ago, my
recollection is a bit fuzzy. I left in 2012.
The first years
During my first years, the department operated like a startup. Its cradle was
the French company Echo. They built a search engine. France T l com bought it
and renamed it Voila. It was the most visited search engine in France in the
early 2000s. France T l com consolidated the portal activities into the Wanadoo
Portails division, later renamed Orange Portails.
The technical environment was excellent. We had many internal tools:3 a
ticket system, an RRD-based graphing tool, an IPAM, a reporting tool, and an
SNMP-based alerting tool.4 We deployed our Linux servers with
CFEngine. We installed systems and applications from internal Debian
repositories. We documented everything in a private MediaWiki instance.
Supervision was performed with an ancestor of Xymon. The network
architecture was clean and scalable with little legacy. We onboarded new people
in a day.
It was a nurturing environment for me. I developed several tools:
lldpd, an 802.1AB implementation, Snimpy, a pythonic binding for
Net-SNMP, Wiremaps, a layer-2 discovery tool with a time machine to know
which device is connected where, Kit r , a tool to simulate network
conditions, QCSS-3, a controller for load-balancers, and ipoo, a service
available through a Jabber chatbot and a Greasemonkey script to expose
IP-related information. I added SNMP support for Keepalived and
Quagga. I also started this blog, with articles like
Anycast DNS, TLS-related articles like TLS computational DoS
mitigation, SNMP-related articles like Integration of Net-SNMP into an
event loop, Linux-related articles like Tuning Linux IPv4 route cache,
and an article about VXLAN long before it was cool.
The collapse
When we needed new servers, the on-site team would take a set from the
inventory, install our base Linux distribution on them, put them in the
datacenter, and cable them to the top-of-the-rack switches. We opened a ticket
describing the servers we needed, and one week later, our servers were
available.
Orange wanted to know if this team was performing well, so they asked for KPIs.
They decided to use the number of tickets completed in a year. They asked to
double this number. So instead of one ticket for a new service, we would open
six tickets one per server. By the end of the year, the KPIs had more than
doubled.
Everybody saw it as a success for performance management. So, they asked to do
the same for the next year. Now, we needed to open a ticket per server and per
step. Again, the KPIs doubled. Behind the scenes, the tickets went to different
people and were no longer handled in order. So, for the next year, it was decided to
have meta-tickets and meetings to follow the progress of these tickets. Of
course, all these extra steps pushed the KPI even higher.
This performance management method spread to the other teams.5
Everything became slower. Instead of a couple of weeks, a new service now took
six months. We built a Soviet nail factory. But the KPIs were good, and we
stopped caring.
Let me give you another example. We had to estimate the impact of each night
operation. We weren t half bad: we declared most operations without any
expected impact. Most of the time, there was no impact. One time out of five,
there was a 5-second impact. We were told to try harder to meet our expected
impact. What did we do? We started declaring a 5-second expected impact. One
day, we got a 30-second impact and were told we failed to match the expected
impact. In the end, we declared most operations with a 10-minute expected
impact, and we stopped caring: instead of carefully shifting traffic around, we
allowed ourselves a 5-minute impact. And our KPIs were never better.
An artist's rendering of the evolution of impacts over the years.
KPIs are not bad, but they are easy to break. Use them carefully: let the people
doing the work help choose the metrics, and tie those metrics to the quality of
the service for example, with service level objectives. Otherwise, even
dedicated people stop caring, game the system, and eventually quit.6
Internally, this division was named Hebex. It was located in
Bagnolet (next to Paris) and Sophia-Antipolis (near Nice).
Goodhart s law often gets the credit, but Campbell s law
describes my experience even better: the more you lean on a number to make
decisions, the faster people corrupt it.
At the time, SaaS was not really a thing. I remember we considered,
with a couple of colleagues, selling Wiremaps as a SaaS, with
homomorphic encryption for the database. But who would outsource their
observability stack?
Snalert was a metacircular alerting tool in Perl. It was able to
poll a very large number of SNMP targets in a short timespan. All our
monitoring was SNMP-based, including system monitoring.
My team also managed the rules of many Linux-based firewalls. To
increase our KPIs, we used the same method: rather than accepting one ticket
with a flow matrix, we requested one ticket per flow.
Orange is not unique. Google s promotion process is another
well-known example of a broken KPI. Michael Lynch explains it in Why I
Quit Google to Work for Myself.
I have proposed the deletion of an obsolete
script,
but it makes me feel complicated feelings so I m going to try and
express those. This particular script was written in 2014, but the
concept goes back much further before git was invented.
When I started university in 2003, I seem to remember the computing
society used to run tutorials for first-year students on how to use
Apache Subversion for your group project a vast upgrade on CVS (or
worse, no version control at all). Back then, the idea of viewing
your changesets in a web browser was relatively new while it was
possible to look at an SVN repository through a web UI, features were
limited unless you installed something compicated like
Trac.
Figure 1: Data flow when distributing commits via a mailing list
Perhaps because reading email on your desktop computer (I don t think
I could afford an IBM ThinkPad?) was the only vaguely real-time
notification system available at the time (except I guess SMS, which
cost 10p per text), a common pattern seemed to be to use a
post-commit
hook
to send every single commit to a mailing list, named something like
foo-commits . Indeed, for a long time Fedora had an scm-commits list
which appears to be a topic of recent
discussion.
I can t really explain why people wanted to have every commit sent
to a mailing list except as a way of getting notified of activity I
can t believe people would import raw patches from those lists, ala
LKML, rather than run actual version control commands to fetch the new
source directly. Maybe you d have to go back to NNTP for this.
I do like the vendor-neutrality of the everything-as-text approach,
building on the open ecosystem of SMTP. But I doubt we d see a
widespread resurgence of commit lists now most code hosting must
allow anyone to subscribe to email notifications, I assume, and I
don t see a huge benefit in a mailing list archive of commit messages.
In the case of seL4, I m even more confused about why this script was
committed in 2014, shortly after the kernel was put on GitHub. I can
only assume it was imported from previous infrastructure. I do know
that the implementation is quite Python 2 heavy, with the conversion
between unicode and bytes featuring heavily. So rather than risk
breaking its logic with patching, I think it s time to thank it for
its service and let go.
Go default compatibility, by Helmut Grohne
At the MiniDebConf Hamburg, Andrew Lee
had prepared a talk on how Debian accidentally chooses Go compatibility.
Helmut joined Tobias Quathammer and Andrew Lee in looking into the problem.
Go has a compatibility system where modules declare a desired Go version to be
compatible with. This influences various features such as whether RSA keys
smaller than 1024 bits are accepted. Unfortunately, Debian s way of building Go
packages is unique in setting GO111MODULE=off, which practically implies a
very old compatibility version that enables a number of insecure settings. Most
Linux distributions use the default GO111MODULE=on and therefore consult a
go.mod file that often declares a sensible version. While doing so is the way
for Debian longer term, getting there involves major changes so we also sought
a more short term workaround. We developed a
patch to the Go compiler
that would enable it to pick up a compatibility version from the environment.
Tobias uploaded it to unstable. The next step is
communicating the declared compatibility version
from go.mod to the compiler via the new variable. Then, rebuilding the archive
resolves the immediate symptoms. This does not save us from having to perform
the larger transition to GO111MODULE=on, but this shortcut can be backported
to trixie.
Trimming build-essential, by Helmut Grohne
One of the harder problems of the architecture cross bootstrap is correctly
expressing the Build-Depends of glib during the toolchain bootstrap. It
implicitly depends on build-essential, which happens to depend on libc6-dev.
This poses a cycle. It applies even for cross building, because it is
interpreted for the host architecture and that there is no way of satisfying
this dependency during the toolchain bootstrap.
Given discussions at MiniDebConf Hamburg
with Jochen Sprickerhof and others, a seemingly stupid idea evolved: Let s
delete build-essential. What looks insane on the surface might deserve a
second look. Given how we moved away from C, C++ and autotools, what is in
build-essential no longer is required by much of the archive. With the rise of
debputy, debian/rules no longer has to be a makefile. While the task would
be huge, those packages relevant to architecture bootstrap could explicitly
support building without the implied dependency making their dependencies
explicit. In a number of cases, this amounts to issuing a dependency on
g++-for-host. This dependency requires the use of architecture-prefixed tools.
Therefore, Helmut wrote a debhelper change
that makes it always pass build tools to various build systems. This also
enables more packages to honour environment variables such as CC and CXX.
Python upstream engagement, by Stefano Rivera
Stefano attended PyCon US (at personal expense)
to improve upstream relations and ensure Debian s voice is heard where it needs
to be. On Friday there was a packaging summit
(notes) with good
discussion on the future of the wheel format, and some discussion of the new
abi3t shared library format for free-threaded python.
In preparation for the event, Stefano did a complete review of the current patch
stack.
Stefano s primary goal was to get some of Debian s patches merged during the
sprints, and results were mixed. Some trivial patches
(e.g. GH-150098, made progress
and merged, but the most consequential patch Debian is carrying
is still blocked. Stefano will
continue to try to drive progress on this.
Miscellaneous contributions
Carles worked on po-debconf-manager:
Reviewed Catalan translations for 6 packages, submitted 10 packages to
maintainers, and removed 3 packages from po-debconf-manager.
Carles worked on check-relations:
Continued improving the backend, including importing source package build
dependencies to better support analysis of Debian blends. Added support for
ignoring packages using regular expressions and source package names in response
to user feedback. Used the tool to report 5 new bugs and followed up on
previously reported issues.
Helmut sent a cross build patch on behalf of a customer.
Helmut uploaded debvm and guess_concurrency both featuring improved
reproducibility and documentation.
Helmut continued maintaining rebootstrap and made it correctly handle binNMUs
of gcc-defaults. Additionally, he poked at existing gcc patches giving answers,
rebasing or closing them.
Helmut supported the video team in Hamburg mixing audio.
Helmut continued to report undeclared file conflicts of various kinds and
corresponded with maintainers about them.
Antonio attended a debate during the Brazil Internet Forum
about the impacts of the child protection regulation (ECA Digital) on free
software operating systems.
Antonio worked on Debian CI to improve the system transparency for users. This
included listing any pending jobs explicitly in the job lists for each
package/architecture/suite page, as well as adding a
queue status page that users can check
for an estimate of test latency.
Antonio worked on several Debian CI maintenance tasks, including but not
limited to some monitoring improvements, replacing usage of fonts-font-awesome
with fonts-fork-awesome, and adding the ability in debci to configure a global
notice (which is being used in Debian CI to point to the system status pages).
Antonio started doing some tests related to the change of default Debian CI
backend from lxc to incus-lxc. This helped identify an omission in the creation
of incus-lxc images. It was missing dpkg-dev, which caused a few packages that
assumed its presence to fail. In the end, the incus-lxc backend will be fixed to
include dpkg-dev by default in the image, but that uncovered an undeclared
dependency in gem2deb (Ruby packaging helper) and in ruby-byebug, both
already fixed in unstable.
May included the discovery of several high-severity Linux kernel root
exploits. Stefano updated kernels and rebooted debian.social infrastructure
several times.
Stefano supported the Hamburg miniDebConf s
wafer website during the event, and set up an instance
for the 2027 edition too.
Stefano supported the bursary team issuing bursaries for
DebConf 26.
Stefano uploaded routine updates of python-pip, pystemmer, snowball-data,
snowball (making up a mini, uncoordinated snowball transition),
python-authlib, python-discovery, python-installer, python-mitogen,
python-pipx, python-cachecontrol, platformdirs, and python-virtualenv.
Stefano fixed a small number of bugs in dh-python, culminating in the
7.20260524 upload.
Thorsten finally managed to upload a new upstream version of hplip. He also
uploaded a new upstream version of epson-inkjet-printer-escpr. Last but not
least with the help of other contributors he could fix bugs in lprng.
Lucas and Santiago contributed significantly to the DebConf 26 Content team;
helping to organize the team, review and rate talk proposals.
Lucas also supported a packaging sprint held in India by rebuilding and
publishing the latest results of the Ruby 3.4 transition effort.
Santiago continued contributing to the efforts to organize DebConf 26,
especially supporting the local team with different tasks.
In collaboration with Emmanuel Arias, Santiago is mentoring Aryan Karamtoth,
a GSoC participant that is working to introduce linux live-patching support in
Debian. The GSoC project started in May, with community bonding and coding.
Santiago reviewed a merge request
to prepare the clang-extract package for debian. clang-extract is one of the
building blocks that will help to extract specific functions from large C code,
so only relevant code can be patched, without recompiling the whole original
basecode.
Anupa assisted Jean-Pierre Giraud with the point release announcements for
Debian 13.5 and Debian 12.14.
Colin backported various security fixes from OpenSSH 10.3 to all supported
releases (including LTS and ELTS).
Colin backported IP quality-of-service fixes to OpenSSH in trixie. The
situation there had been unsatisfactory for some time, and upstream reworked
their QoS support in OpenSSH 10.1 in a way that typically produces much better
results.
Colin imported new upstream versions of 26 Python packages, and fixed around
25 RC bugs for the Python team.
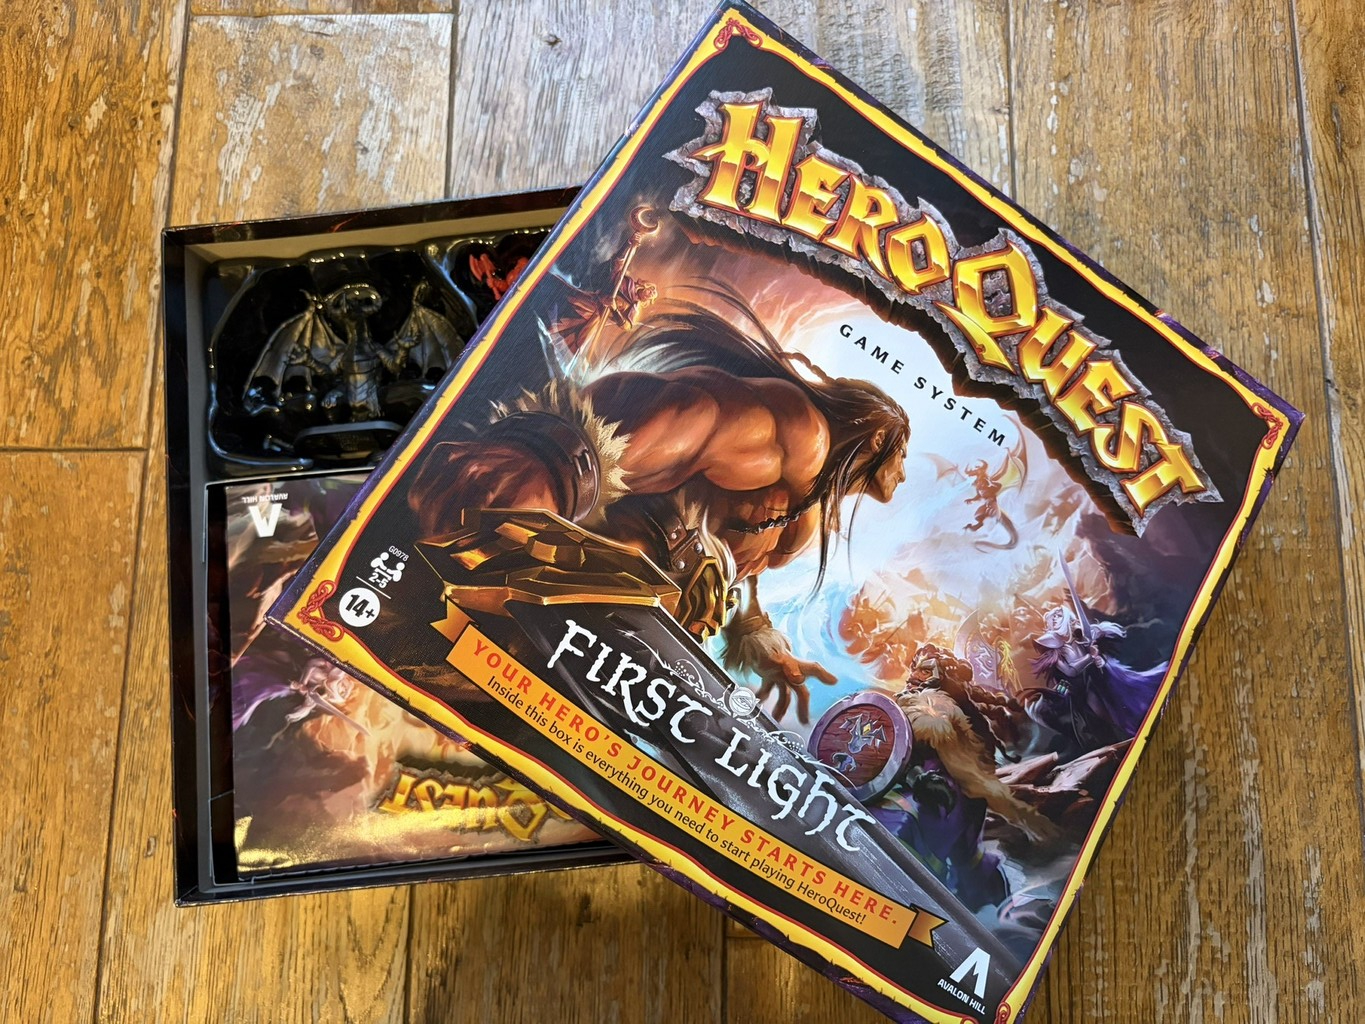
My youngest daughter and I recently started playing the tabletop game
HeroQuest. Specifically, the recently-issued, cut-down variant
HeroQuest: First Light. This is quite advanced for her age, and I'm
a little surprised she's taken to it, but she's really loving it,
It's pushed her to read bits of lore on cards and quest books that is
way above her expected reading level, and we've been exercising her
maths by adding up the gold we find on our quests and calculating what
the heroes can buy with it in the store afterwards.
Originally from 1989,
Hasbro re-issued HeroQuest in 2020. I read about it at the time but didn't
buy it. I wasn't
sure who I would play it with. It also seemed expensive to me. It probably
wasn't unusually expensive in 2020, nor now, for the sheer volume of
finely-sculpted miniatures included.
I also knew I had the original game in the loft, and
I wasn't that keen on buying something I already had,
although untangling the contents from several similar boxed games would
take me many hours, and I wasn't sure how much of the game I would find.
mix of old and new
First Light was compelling because it is much, much cheaper than the full
remake, so I was happy
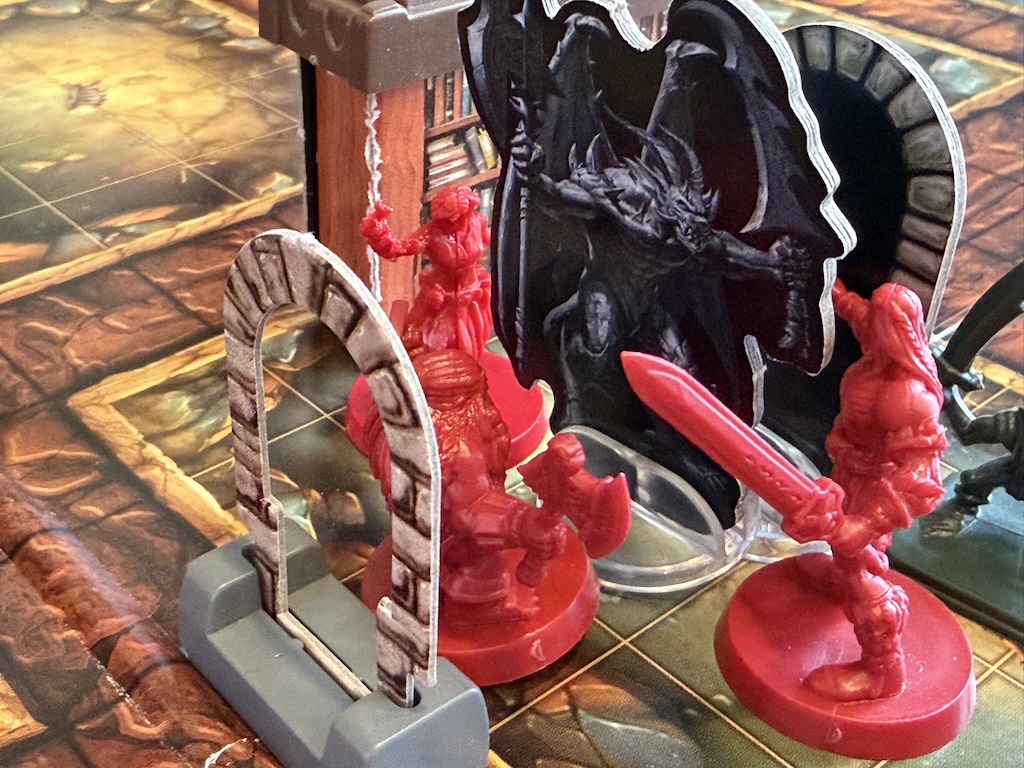
to take a punt. It's cheaper because it doesn't have any plastic monsters or
furniture: instead cardboard cut-outs that stand up on plastic stands. For us,
that is a significant drawback: 3D miniatures are much more immersive, But I
can re-use the plastic miniatures I can find from the original game. First
Light has a newly written adventure, better suited to beginners than the
original game.
The re-issue(s) have new art and new model sculpts that look fantastic. They've
changed anything which tied into Games Workshop's IP and I'm really happy about
that. They've made an effort to add women, almost entirely absent from the
original. I'm certain my daughter wouldn't have tried it otherwise.
I have been looking at seL4 some more recently, and had a small
patch
merged today to remove a legacy Python module from a helper script.
(I was trying to run the script on a system without that module
installed, and it was almost easier to patch it out.)
However, the more I think about this code and how it s used, the more
it seems wrong on at least five other levels.
The patch itself is quite uninteresting; this script was importing the
past module (part of future?) to use the xrange function.
Python 2 used to have separate xrange and range functions, where
range returned a list in memory while xrange generated an
iterator. Because this seL4 script is iterating over a large range of
values, it s important the list is not generated in-memory. But
Python 3 removed the xrange function and just has range return an
object, so it s trivial to avoid the module import.
Having thought carefully some more about the specific line, there s
surely an off-by-one error in it - range iterates over 0 to n-1, so
this line shouldn t be subtracting one if it s looking to test all
32-bit values:
for i in range(2**32-1):
But then again, this is being used for a sanity check of a magic bit
shift algorithm that speeds up division operations to convert CPU
ticks to microseconds on 32-bit arm platforms. Surely if the
algorithm s good, it shouldn t be necessary to validate it
exhaustively against every possible 32-bit value?
Also, 32 bits isn t enough, because this is 64-bit division.
include/api/types.h shows that ticks_t is always a uint64_t, so
if this were a proof by exhaustion it should run to 2**64 (though that
would take infeasibly long).
As discussed in issue
#1352, lots of people have
been running this code with the wrong divisor anyway. But because the
bit shift path is only used on 32-bit platforms, it s not clear to me
that there s even any point in specifying CLK_SHIFT/MAGIC on platforms
which are 64-bit only (e.g. the tx2 port).
And to follow this rabbit hole to the very end, in comments on PR
#1435
and issue #1509 it s clear
that the future of this code is to remove it, as it s 1. unnecessarily
clever (on 64-bit platforms the equivalent code just uses a division,
so performance can t be that important), and 2. the entire concept of
converting to microseconds breaks the seL4 principle of not
abstracting away details of the hardware.
So this has left me unclear on whether my small patch was a good thing
or not, but I certainly learnt something about this corner of seL4
timer handling. And I ve ordered a copy of Hacker s Delight on the
recommendation of a code comment.
I ve been asked a few times if it would be possible to use
virtnbdbackup as some kind of
replication utility, to keep cold standby virtual machines on other libvirt
hosts.
Usually i would tell to use underlying filesystem features (such as zfs
send/recv, with incremental snapshots) to keep cold, standby copies on other
hosts.
As for qcow based virtual machines, using the dirty bitmaps is not only a valid
feature to create backups, but to (incrementally) replicate virtual machines,
too.
I ve released vmsync. A small golang utility
that implements a simple replication tool using the NBD protocol to sync
virtual machines to other hosts.
AI slop is invading the web. A recent story about disallowing LLM-generated
submissions on Lobsters triggered a lot of debate. My personal worst
offenders are LinkedIn articles with AI-generated images and uninspired
articles filled with emojis from people trying to masquerade as experts on a
subject they don t care enough to write themselves. While I am unhappy about
this situation, I rely on LLMs for grammar, copyediting, and
translation. I don t see this as a contradiction.
I am a native French speaker, but I blog in both English and French. When I
started writing this blog in 2011, I was composing in French and translating
to English, but I found it was better to work in the reverse order to
avoid unnatural and non-idiomatic constructions. One of my goals is to write
good English but I never felt it was my strong point.1 For example, verb
tenses are often an issue, even if I mostly stick with the present tense. I
learn the rules and forget them right away. I also don t feel like hiring an
editor for something I see as a hobby.
As an example, I have kept the history of the successive iterations when writing
Scaling Akvorado BMP RIB with sharding :
the first draft, authored with the help of a thesaurus,2
I know that LLMs may alter the author s voice when editing, but the
corrections in the second step are minor. The prompt asks to apply light
stylistic edits, with some guidance around avoiding passive voice, long
sentences, bland verbs, and filler words. It also defines the target audience:
technical with a B2 level in English.
In the following excerpt, I used long time instead of long-standing. The
former is missing a hyphen and applies to people a long-time friend, while
the later relates to a situation a long-standing agreement. I had a hard
time understanding the reason of the second change: the LLM prefers a
defining relative clause to provide the definition of RIB sharding.
As the Internet routing table contains more than 1 million routes, Akvorado
needs to scale to tens of millions of routes. This has been a long
time long-standing challenge, but I expect this issue is now
fixed by using RIB sharding, a method to split that
splits the routing database into several parts to enable concurrent
updates.
In the next modification, the LLM puts device instead of equipment. This is
correct as equipment is an uncountable noun. I know that, but I still fall
into this trap.
When Akvorado does not find a route from a specific device, it falls back to a
route sent by another equipment device.
I ask the LLM to use descriptive verbs and it complies by replacing a
multi-word predicate with a lexically rich verb:
The benchmarks demonstrate it has better performance than
outperforms other packages, both packages for
lookups, insertions, and memory usage.
It also fixes grammar errors. In the next excerpt, a list of routes is a
singular expression. Moreover, stored is a state and I should not use into
as it expresses a change.
The list of routes for each prefix are is not stored
directly into in the prefix tree.
As a last example, consider the following snippet. The require verb
accepts a noun or an object followed by a to-infinitive. I can t use it with
just a to-infinitive.
An alternative would be to have one prefix tree for each peer but it would
require to configure configuring all routers to export
their routes.
As someone who didn t grow up speaking English, I struggle with these grammar
rules despite reading a lot of English material.3 French is more
complex to get started but more systematic. English is full of irregularities.
On each page, I disclose in the footer whether an AI modified the content. There
are three levels:
: no AI or almost no AI (e.g., grammar corrections)
: enhanced (e.g., copyediting)
: generated (e.g., translated from another language, even if human-edited)
Hover or tap the icon to reveal the AI s name and its role in the document.
Example of AI usage disclosure: Claude Sonnet 4.5 edited this article.
The graph below shows which tool altered each post, year by year. Recently, I
applied the grammar skill to past articles. Since 2018,
French articles have been translated with the help of DeepL first, then of
an LLM. Since 2024, English articles are copyedited.
🖼 Graph showing the AI usage over the years. Each level get its own
color.
AI usage over the years. Hover or tap a band for the details.
If you are strongly against any usage of LLMs specifically for writing, I hope
you accept my more nuanced position on the usage of these tools as a trade-off
to provide clearer and more engaging articles. Years of literature on improving
English told us it is important to choose the right word to keep the reader
engaged.
[ ] Good writing consists of mastering the fundamentals (vocabulary,
grammar, the elements of style) and then filling the third level of your
toolbox with the right instruments.
Stephen King, On Writing
Note
Unlike other recent articles, I did not use an LLM to edit this post:
an unnamed person kindly accepted to proofread it. I translated it to French
without using an LLM either.
I am quite happy with the writing tools provided by Kagi. Both the
translate tool and the dictionary are a valuable help to find
different wordings. I also lean on Kagi s research assistant when
researching a topic.
When I was ten, I played Monkey Island 2 in English without having
taken any classes. I used a dictionary to translate word by word and I found
the irregular verbs confusing and not in the dictionary.
The RISC-V CPU architecture has been gaining a lot of popularity since it launched in 2014, and now that the industry is standardizing on the RVA23 level that includes vector support as a mandatory extension, we are likely to see a lot more edge- and IoT devices with the ability to run local LLMs at reasonable speed, and most importantly at very compelling prices.
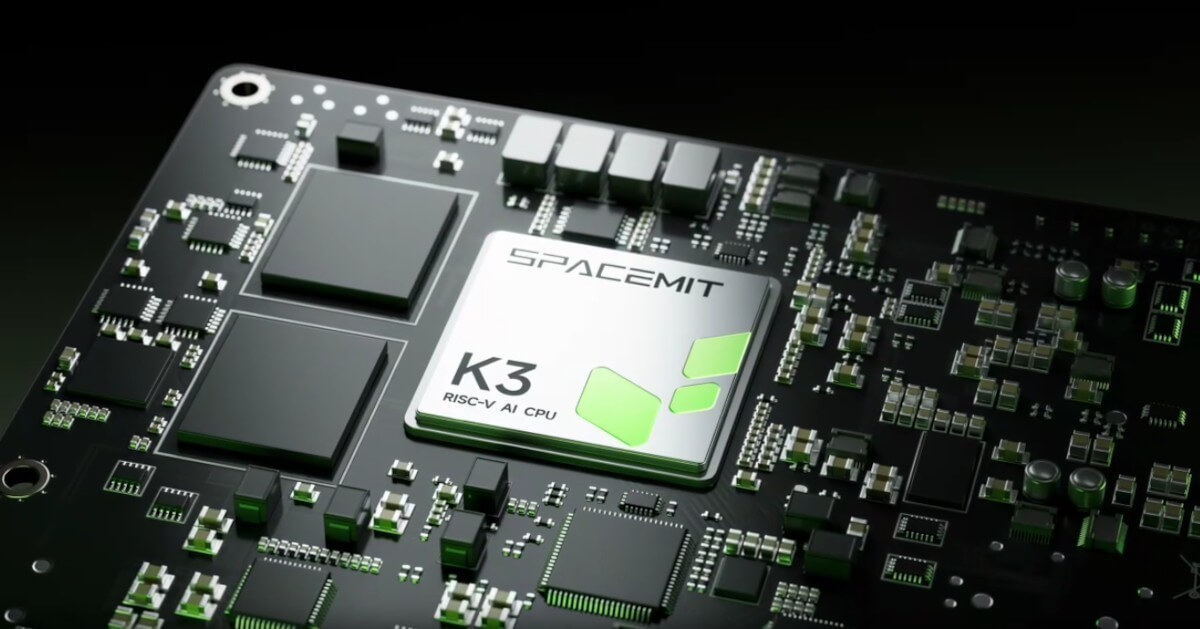
SpacemiT is a Chinese RISC-V CPU manufacturer that launched on May 11th, 2026, their long-anticipated next-gen RISC-V AI chip K3. It is among the earliest RISC-V CPUs that adhere to the RVA23 standard and performance-wise it is quite capable, providing 130 KDMIPS general computing power, 60 TOPS on INT4 which translates to about 15 tokens per second when running a 30 billion parameter large language model.
The aspect that really makes it stand out is:
Comparing the resellers
SpacemiT does not sell anything directly to consumers. Instead you need to buy a board that includes the K3 chip from an integrator. Currently the main resellers are:
All of the above are Chinese companies that ship to customers both inside and outside China. DeepComputing stands out as the only one that actually has done real integration and ships the K3 on a custom board, while the others simply resell the SpacemiT-produced K3 pico-ITX and K3 CoM260 Kit.
Milk-V
Milk-V is a RISC-V specialized integrator, as the name already implies. They sell the K3 under the name Jupiter2. Of all the K3 pico-ITX reseller product pages, the Jupiter2 presentation is the nicest and most detailed. Unfortunately their order page at arace.tech only states that it is a pre-order with no information about shipping schedule, taxes, or other details like what SSD is included (if any). Based on the pictures it does ship with a Milk-V branded case. The 32 GB RAM lists at 504 EUR, which is a very reasonable price. The @MilkV_Official account on X recently promoted the K3.
Documentation and support
As of this writing, the Milk-V Jupiter2 documentation site is just a stub and has no actual content, and only two links to the SpacemiT K3 documentation site. For support there is a web forum with a dedicated Jupiter2 section. There is also a Matrix space, but unlike their other products, there is no dedicated Jupiter (neither v1 nor v2) channel.
Community size and open source involvement
At least one prior Milk-V product was certified by Canonical, which indicates there is some collaboration in progress. Canonical also lists the Milk-V Titan on its official Ubuntu for RISC-V partner-built hardware page.
Sipeed
The Sipeed K3 announcement is well written (in English) with all the relevant details and links to additional PDF manuals. However, their main page at sipeed.com says nothing about the K3, so one must know the subpage URL to access it. They offer both the K3 CoM260 kit compatible with Jetson Orin Nano carrier boards, and the stand-alone K3 pico-ITX-sized motherboard. The CoM260 kit is only 10 USD cheaper than the full pico-ITX motherboard, so choosing the latter is a no-brainer if starting from scratch. The pico-ITX model with 32 GB DDR5 RAM sells for 639 USD. The product page does not mention anything about hard disk size, so you don t really know exactly what you will be getting if placing an order. There is no indication about case, Wi-Fi antennas or power supply either, so most likely they are not included.
Their store.sipeed.com website does not work at all, and their Taobao and AliExpress stores are not public and only accessible to registered users. The order page also says nothing about shipping time, delivery time, or taxes. The X account @SipeedIO is active and recently posted pictures of shipments in progress.
Documentation and support
The main documentation wiki does not yet have any K3 content at the time of writing. There is a Discord channel for general RISC-V discussion, and their MaixHub also has a discussion board, but I didn t find anything K3-specific.
Community size and open source involvement
Sipeed has had at least one of their previous devices certified by Canonical, which indicates they are active in the community.
Note that the other RISC-V company SiFive that also has had hardware certified and officially supported by Canonical is a different company, despite the very similar name.
Banana Pi
Banana Pi announced that they offer both the K3 CoM260 kit and the K3 pico-ITX motherboard version. Their product page for the K3 confusingly shows a MediaTek product in the page banner rather than the SpacemiT K3. Based on the product description and the fact they renamed the product as BPI-SM10, it seems to ship with some carrier board. The product pictures look identical to the SpacemiT documentation and there is no picture of the carrier board, and details are very sparse. The pico-ITX version with 8 GB RAM and 128 GB SSD sells for 293 USD and the CoM260 developer kit with the same specs sells for 287 USD and the 32 GB RAM with 128 GB SSD model sells for 595 USD. The shop page shows only five orders so far and items are currently out of stock. As there was no 32 GB RAM version of the pico-ITX available at all, this isn t an option for me as I want to run 30B parameter models that need the larger memory version.
Of all of these resellers, the Banana Pi website seems the most outdated. It does not have a search feature, it is not mobile-friendly, pictures can t be pinched to zoom in and so forth. Product names are also almost all identical, and as the product listings only show the beginning of the product name, figuring out what product is what requires extra effort that just makes the online purchase experience plain bad.
Documentation and support
I was only able to find the documentation page for the CoM260 kit, but none for the pico-ITX version. For support there is a forum, but the category list does not show any section for K3, and the forum search prohibits using the search term k3 as too short.
Community size and open source involvement
Banana Pi has a long history in the ARM single-board computer market, but their presence in the RISC-V ecosystem is still growing. Their X account @sinovoip has posted only once about the K3 and otherwise promotes their ARM boards. However, their community culture page does express a commitment to open hardware in general, but there is no visible K3-specific community activity.
Firefly
Firefly s K3 product page is comprehensive. Based on the details, they do not offer the K3 pico-ITX variant at all, but only the K3 CoM260 board inside the AIBOX-K3 Firefly RISC-V Edge Mini PC product. This is a feature-complete offering with a Jetson Orin Nano carrier board and case. The AIBOX-K3 with 32 GB RAM and 128 GB SSD in a case sells for 689 USD in their own Firefly.store. Unfortunately it only has HDMI and there is no USB-C with DisplayPort support, which is a deal-breaker for me personally.
Interestingly, Firefly also offers rack-mounted servers with K3 as the CPU.
Documentation and support
The wiki link on the product page is broken. The Firefly wiki does have a section for the AIBOX-K3, but it too has a broken link. It seems that as of the time of writing, there is no wiki section for this product yet.
For support there is a web forum, which does have at least one K3 thread covering guides such as Hermes Agent installation, though broader K3-specific sections are still sparse.
Community size and open source involvement
Firefly s X account @TeeFirefly has had no posts since 2024, and their GitLab/T-Firefly shows mostly 2024 activity, with only one repository updated in 2025 and nothing in 2026. Historically they have built a moderate community around their ARM-based Rockchip boards, with active forums and wiki contributions for those product lines. Their RISC-V K3 offerings are newer, and likely need a lot more polish to be attractive products overall.
DeepComputing
Last, but certainly not least, is the laptop manufacturer DeepComputing that offers a Framework laptop compatible motherboard with the SpacemiT K3 chip. They also sell the plain motherboard, or with the Cooler Master case, which allows one to easily connect it to an external monitor and keyboard and use it as a desktop computer. The plain board with 32 GB RAM and no SSD sells for about 882 EUR. Shipping of the first batch is expected to start by end of June 2026. Their X account @DeepComputingio promotes this DC-ROMA RISC-V Mainboard III as their flagship product, so they seem to put a lot of effort into it.
The overall product design and packaging seems good. Of all the K3 resellers and integrators that I was able to find, DeepComputing is the only one that actually designs their own boards with the K3 processor, while all the other vendors above are simply reselling the vanilla K3 boards with or without a case.
After reviewing all these options I decided to buy the DC-ROMA RISC-V Mainboard III for Framework Laptop 13 with 32 GB RAM, 1 TB SSD and the Cooler Master case, totalling about 1100 EUR.
Documentation and support
DeepComputing maintains product information for their RISC-V hardware at github.com/DC-DeepComputing/Framework, with documentation of the newest Mainboard III (FML13V05) still being finalized ahead of the first batch shipment. They provide community support through Discord and web forum, although the latter has very little activity.
Community size and open source involvement
DeepComputing has established itself as a pioneer in RISC-V laptops, beginning with the DC-ROMA. I have seen their stand at FOSDEM, which shows they are genuinely active in the open source community. Canonical lists DeepComputing s first mainboard / FML13V01 on its official Ubuntu for RISC-V partner-built hardware page, and it seems likely that they will continue to collaborate with Canonical with the new model once it ships. While the underlying Linux enablement depends on SpacemiT s upstream efforts, DeepComputing s involvement helps bridge the gap between reference hardware and consumer-ready products.
Conclusion
After weighing all the options, I ended up placing an order with DeepComputing for their custom K3 board with the Cooler Master case. Despite the premium price, the active community support and the properly documented promise of a complete, working system made it easy to place an order with confidence.
The SpacemiT K3 is poised to be one of the most significant RISC-V chips for local AI workloads, thanks to its RVA23 compliance and high tokens per second potential. Yet the buying experience in mid-2026 remains fragmented and incomplete. Hopefully this is just because the product is new, and they will get the purchase experience polished soon.
What struck me most during this process was how poor the customer experience is across nearly all of these vendor websites: broken links, missing search functions, outdated product banners, pages that show the wrong product entirely, and no information about shipping times, stock levels, taxes, and so on. One wonders why these companies don t fully invest in their web presence.
Personally I would assume they likely have enough customers already, primarily through domestic channels like Taobao and JD.com, that they do not feel any pressure to improve their international-facing sites. However, I did also review what was offered on Taobao, and the product details were very incomplete there too. Taobao, however, has a built-in live chat with almost all sellers, which can be used to ask questions and thus compensate for missing product details.
I don t fully understand why the sales process seems unpolished. The websites feel almost like an afterthought a checkbox to claim global reach while the real business apparently happens elsewhere via closed platforms or via inaccessible reseller channels. It is a frustrating reminder that in the RISC-V hardware world, the technology may be open and global, but the purchase experience is less so.
A new minor release 0.4.27 of RQuantLib,
the first in over a year, arrived on CRAN a couple of minutes ago, has
just now been uploaded to Debian,
and is being built for r2u as well.
QuantLib is a rather
comprehensice free/open-source library for quantitative
finance. RQuantLib
connects (some parts of) it to the R environment and language, and has
been part of CRAN for nearly
twenty-three years (!!) as it was one of the first packages I uploaded
to CRAN.
This release of RQuantLib
brings an update to the interface for all equity options, vanilla and
exotics as well as implied volatilities. We now support the option
maturity via either an actual maturity date, or the (fractional
business-day years) numeric. This uses a clever little Rcpp trick I should discuss in a
separate blog post. We also re-ran compileAttributes() to
re-create the RcppExports.cpp file now using a slightly
improved way of calling Rf_error for an ongoing Rcpp transition, and did some more
standard maintenance. The details from the NEWS file follow as
usual.
Changes in RQuantLib version 0.4.27 (2026-06-07)
All equity option functions can now take either a (fractional)
time span to expiry or a given date, and accept a daycounter
setter.
Two very old schedule helpers had a superfluous
try/catch removed.
The continuous integration setup received a minor
update.
The RcppExports.cpp file was updated to aid a
Rcpp transition.
I finally carved out some time today to prepare and release debsecan-mcp v0.1.2 to PyPI. During this release, I
integrated PyPI's trusted publisher mechanism, which authenticates directly via
GitHub Actions and eliminates the need for manual uploads or static API tokens.
What is New?
There are no feature updates in this release; the changes are strictly focused
on PyPI publishing requirements. This was handled entirely within the Antigravity
IDE.
The primary change replaces the python-apt dependency with python-debian for
version comparison. PyPI rejects packages that reference external Git repositories,
and python-apt lacks an official PyPI release. The original python-apt logic
remains intact: if the system has python-apt installed, the server defaults to
it. Otherwise, it falls back to the comparison logic implemented via the
python-debian NativeVersion class.
What Next?
The next release will introduce a standalone CLI utility called debvulns. It
mirrors debsecan functionality but surfaces the cleaner, richer vulnerability
data already implemented in debsecan-mcp. The code is written, and I will
release it once testing is complete.
I also owe a post explaining my rationale for designing a CLI utility alongside
the MCP server, and my broader thoughts on CLI vs. MCP workflows. I aim to publish
that next week.
Debian LTS/ELTS
This was my hundred-forty-third month that I did some work for the Debian LTS initiative, started by Raphael Hertzog at Freexian.
During my allocated time I uploaded or worked on:
[DLA 4580-1] exim4 security update to fix one CVE related to remote code execution.
[DLA 4591-1] rsync security update to fix five CVEs related to local root privilege escalation.
[#1134340] trixie-pu bug for libcoap3 to fix two CVEs in Trixie; the debdiff was confirmed and the upload was accepted to the proposed update queue.
This was a rather strange month. The details about the embargoed exim4 issue arrived only after I already went to bed and the embargo lift was 18 hours later. Luckily Stretch was not really affected and the uploads for Bullseye and Buster went out on time.
Something similar happened with the embargoed issue of rsync. The info arrived at 8:00 in the morning and the embargo lift was on 2:00 next morning. From an Europeans point of view, the Australians do have strange time zones. But there is more to this than that. Upstream sent more than 50(!) patches for these five CVEs that needed a backport to Bullseye. As things turned out, there is a regression in the upload to Unstable and investigations are ongoing whether this regression is also available in the backported patches for Trixie, Bookworm and Bullseye. So rsync-updates for Buster and Stretch is in the works, but I am afraid they need some more time.
All good things come by threes. Two critical CVEs of hplip appeared and a new upstream version was released by HP. HP is no longer interested in working with distributions and over time more than 80 patches have been accumulated that need a rebase for a new upstream version. For that reason I avoid this package as much as I can, but two critical CVEs did apply some kind of pressure on the maintainer. So I finally managed to do this update and the latest version of hplip is now in Debian. Nevertheless, this feels good :-). Anyway, it is not over yet. HP does not have a public repository nor do they publish patches for these CVEs. So I am still searching for the correct fixes to backport them to Bullseye, Buster and Stretch. The other distributions have the same problem and a silver lining appears on the horizon.
I also prepared an update of gimp for Buster and Stretch, but due to an accident I only managed to release the corresponing ELA in June. The accident was also the reason for only half a week of FD. Thanks to Daniel who took over.
Debian Printing
This month I uploaded a new upstream versions:
This work is generously funded by Freexian!
Debian Lomiri
This month I continued to work on unifying packaging on Debian and Ubuntu. This makes it easier to work on those packages independent of the used platform.
This work is generously funded by Fre(i)e Software GmbH!
Debian Astro
This month I uploaded a new upstream version or a bugfix version of:
Introduction
I have just bought a HP Z4 G4 with W-2125 CPU for $320 and I decided it was a good time to do some benchmarks on Debian package building to see which system I should use for that.
The W-2125 CPU scores only 9,954 on the passmark multithread test but scores 2,546 on single thread [1]. Passmark seems to have some limitations as the only DDR3 system that s important to me at the moment (the HP Z420 workstation my parents use which cost me $750 in 2021) with a E5-2620 CPU scoring 5,325 for multithread and 1,113 for single thread [2]. From the passmark results one would expect that the system is slightly more than twice as fast as the Z420 for operations that involve less than 4 CPU cores.
For the initial tests of the Z4 G4 I ran them with hyper-threading enabled as 4 cores isn t much by today s standards and also the machine in question is going to be less exposed to hostile data and contain less secret data than most of my systems so the security risks of hyper-threading are less of a concern.
I did some tests with a couple of tasks that are very important to me, building SE Linux policy packages (something I may do a dozen times in a day) and building Warzone 2100 (which I do less often but is the most intensive build process I regularly run). At the bottom of this post there are tables with the results from building these packages on my Z640 workstation with a E5-2696 v4 CPU [3], the Z420, and the new machine.
For the Warzone 2100 package I tested building on my Z840 dual CPU system [4]. I didn t test building the SE Linux policy on the Z840 this time because that package can t take advantage of even 22 cores. When I initially got the Z840 running it built the policy packages faster because the Z640 had an older CPU that was slower for single core operations than the CPUs in the Z840.
BTRFS Compression
For some time I have noticed significant differences in compile time on my workstation, a factor of more than 2. I did more tests and noticed that top showed something like the following, those kernel threads are all BTRFS related, except for gfx which is probably something graphical caused by running Chrome with about 300 tabs open.
I had been running BTRFS with the mount option compress=zstd:15 which caused much of the performance problems when building. It was also a random performance issue which I think happened due to the BTRFS 30 second write-back sometimes taking more than 30 seconds during the build process which then caused a second write-back.
I did tests on ZSTD compression levels 5, 8, 10, and 15. 15 was never good and often really bad. 10 was not unbearable but consistently slower. 8 was sometimes as fast as 5 and sometimes quite a bit slower. I didn t test levels below 5 because I need to have some compression and it seemed that the benefits of reducing compression were dropping off below 8.
I found that the BTRFS compression delay is not counted in system time for the process. I think it s the fsync() system calls in the semodule and dpkg-deb programs that cause the delays related to BTRFS compression waiting for kernel threads.
BOINC
I have all my systems other than laptops running BOINC in the background so that CPU power is used for scientific research when I don t have any personal use for it [5]. I believe that it s immoral to waste CPU power when it could be used for research.
In the below table which has test results from building the package with and without BOINC, and with different ZSTD compression levels in BTRFS all the worst entries were from when BOINC was running apart from one where ZSTD level 15 compression was used. The really poor performance with ZSTD level 15 was an outlier, but it wasn t an uncommon outlier so I left it in.
Running BOINC in the background configured to use all CPU cores caused a significant increase in user CPU time (the time a CPU core spent actually running the program). My initial thought was that it s partly related to turbo boost .
The Intel ARK page for the CPU in the Z420 shows that it s main clock speed is 2.0GHz with a 2.5GHz turbo boost [6]. The turbo boost is apparently largely based on temperature and apparently limited to one core, so if the other CPU cores are all being used then the CPU will probably be too hot to have the turbo boost and if it happens it might not happen for my compile processes.
The ARK page for the E5-2699 v4 (which is a similar CPU to the E5-2696 v4 that I m using but is officially documented by Intel) [7] shows that it has a base clock speed of 2.2GHz and a turbo boost speed of 3.6 GHz. 322 vs 244 seconds of user CPU time means running 32% slower which can plausibly be explained by the lack of a 64% turbo boost with a bit of help from the 55MB L3 cache being thrashed.
Turbo boost would only be a noticeable issue for building packages like the SE Linux policy packages which doesn t take much advantage of multi-core CPUs. For a build process to average at best 362% CPU use there has to be large parts of the process that are limited to one or two cores which can potentially give a benefit from turbo-boost.
When building the Warzone 2100 packages most of the build time is running basis-universal which is a multi-threaded program to compress GPU texture data. This usually causes a load average of 300+ on the Z640 or 600+ on the Z840. But the build time is still increased by more than 50% on both the Z640 and the Z840 when BOINC is running in the background, which seems to be an indication that it s not related to turbo boost. I verified that BOINC is running at IDLE schedule priority with the following command:
# chrt -p $(pidof -s einstein_O4MD_2.01_x86_64-pc-linux-gnu)
pid 2974874's current scheduling policy: SCHED_IDLE
pid 2974874's current scheduling priority: 0
In theory this means that BOINC won t affect foreground processes.
Hyper Threading on the W-2125
The best claims I ve seen about HT are 15% to 30% performance boost. The best I ve actually seen in the past is about 18%. Seeing a 10% benefit for building Warzone 2100 is at the low end of the range I expected. 8 virtual cores is not many for a build process that causes a load average of 600+ when running on a system with 44 real cores.
I was surprised to see a 6% performance benefit in hyper-threading for building the SE Linux policy as I didn t think there was enough use of threading or multiple processes to allow that.
Many build scripts use a number of processes that match the number of apparent CPU cores. While make -j 88 might give a theoretical performance benefit on a 44 core system it will also take a lot of RAM and any paging will outweigh the benefits of hyper-threading. On a system with only 4 real cores there s less potential for using too much RAM and as security isn t so important on that system I will leave it on.
Comparing the CPUs
The best results of the Z640 and Z4G4 are only 50% faster than the best results of the Z420.
The Z420 has a E5-2620 CPU which is far from the fastest CPU available for that system the E5-2687W has 8 cores and rates 10,021/1,669 on passmark [8] which is far better than the 5,331/1,114 the E5-2620. The E5-2687W is the fastest CPU that HP lists as supported by the Z420 and it supports DDR3-1666 RAM as opposed to the DDR3-1333 that is the fastest that the E5-2620 supports. With suitable hardware upgrades the Z420 would probably only take about 20% longer to do builds of the SE Linux policy and other packages that can t take advantage of more than 8 CPU cores.
The Z4G4 system has 4 RAM channels which means that you should get some performance benefits from having 4 DIMMs, my system currently has 2 and I haven t yet managed to get more DDR4-2666 DIMMs. But I d still expected a W-2125 CPU with 2*DDR4-2666 DIMMs outperform any E5-26xx CPU with 4*DDR4-DDR-2400 DIMMs for tasks that average less than 4 CPU cores.
In retrospect I would have been better off getting a HP Z820 (two socket server with DDR3 RAM) than the first DDR4 systems I got. It seems that for reasonable size builds a two socket system comes close to twice the speed of a single socket system. I did briefly own a HP ML350 two CPU system with DDR3 RAM but it was too noisy for my intended use as a deskside workstation so I sold it.
Things to Investigate
I plan to do more investigation on BTRFS compression, how to get the best compression without excessive delays and how to recognise when delays are happening. I have some SSDs that have sustained write speeds as low as 15MB/s (Crucial P1 series) so for those I could probably have very high compression levels without slowing the system down.
The fact that BIONC slows things down so much seems to be a bug. When processes are running with the IDLE scheduling class there shouldn t be such significant delays. Is it due to cache thrashing? How can I best get BOINC suitably throttled when I m sitting at my workstation, I don t want BOINC connecting to the local X server (which it repeatedly tries to do). Do I need to tune my kernel for better handling of IDLE scheduling?
When I get more DIMMs in the Z4G4 I need to do more tests to see if it gives an overall performance boost.
Also the Z4G4 system has a BIOS option for sub NUMA which basically means treating the different RAM channels on a single CPU as NUMA zones, I enabled that option which does nothing presumably because I only have 2 DIMMs, the results when I have 4 DIMMs will be interesting. I will also do some NUMA tests on the Z840 to see what benefits it gives.
I have a selection of RAM speeds that will work in the Z4G4, if I have enough spare time I ll test what difference that makes for CPU bound tasks that matter to me.
For package building fsync() is not helpful, if the system crashes before it s done then I will just do the build again. For a build cluster it is probably a good feature and probably doesn t affect aggregate performance when multiple packages are built at the same time, but for the single user case probably not. I will investigate libeatmydata for package building [9].
Conclusion
The progress in CPUs seems to have slowed down a lot recently. The main benefits seem to be in more CPU cores and for newer sockets with more RAM channels.
The CPUs that do have improvements in single core performance are the i9 series (which mostly doesn t come with motherboards supporting ECC) and AMD CPUs (which is rare in enterprise class hardware). Maybe I should get a server with an i9 or AMD CPU for tasks that need a fast turn around with a small number of cores. That would probably outperform any CPU designed for large core counts for things like building the policy and setting up test VMs (which depends on package installation speed that is single core bottlenecked).
The W-21xx CPUs seem to offer little benefit over the E5-26xxv4 CPUs and not a lot of benefit over E5-26xx CPUs (with DDR3). Even the W-22xx CPUs look like they aren t going to offer a lot as they are only an incremental improvement over the W-21xx series. I had considered making the Z4G4 my main desktop workstation after the high end W CPUs become affordable, but it looks like that won t be worth it until such CPUs drop from the current ebay price of $900 to $100.
I think I ll keep waiting for a decent socket LGA3647 or DDR5 based server [10] for my next significant upgrade.
Tables
Building SE Linux Refpolicy
Welcome to the May 2026 report from the Reproducible Builds project.
These reports outline what we ve been up to over the past month, highlighting items of news from elsewhere in the increasingly-important area of software supply-chain security. As ever, if you are interested in contributing to the Reproducible Builds project, please see the Contribute page on our website.
In this month s report, we cover:
Debian to ship reproducible packages in forky and beyond
In a huge change in Debian s reproducibility policy, the Debian Release Team announced that:
we ve decided it s time to say that Debian must ship reproducible packages. Since yesterday, we have enabled our migration software to block migration of new packages that can t be reproduced [on reproduce.debian.net] or existing packages in testing that regress in reproducibility.
That is to say, if newly-uploaded packages are not reproducible, they won t be considered candidates for inclusion in the next stable release of Debian codenamed forky. (Some exceptions may be granted.)
This news generated a number of articles and comments in various news outlets:
Holger Levsen on reproducing official Debian packages
Reproducible Builds developer Holger Levsen gave a talk at the 2026 Hamburg MiniDebconf this year on the topic of reproduce.debian.net - reproducing what is distributed from ftp.d.o.
Holger s talk announced that Debian intends to ship only reproducible packages in forky and beyond (see above), but also talked more broadly about reproducible builds, our testing framework and the Debian archive. That is to say, moving away from testing whether a package is reproducible in a theoretical sense (eg. whether we can build it twice in different environments and achieve the same result in our test system), and attempting to reproduce the same .deb files in the official Debian archive itself. This small-sounding distinction is actually essential, as this is the only means through which the reproducible builds technique can determine whether build systems are compromised are not.
A video (32m37s) of the talk is available, as are Holger s slides.
Reproducible Builds 2026 summit to be held in Gothenburg, Sweden
As initially announced in March 2026, we will be having our yearly Reproducible Builds summit 2026 in Gothenburg Sweden, from September 22 until 24, followed by two days of hacking!
Further information will be provided on our website and on the rb-general mailing list very soon.
Kettle: Attested Builds for Verifiable Software
Andr Arko and Amean Asad published a paper this month on Kettle, a build system that produces cryptographically verifiable provenance for software built inside Trusted Execution Environments :
A Kettle build records the source commit, dependency set, toolchain, build
environment and output artifact digests in a provenance document produced
inside a measured confidential VM. The SHA-256 digest of that document is
committed to the TEE platform s attestation report-data field, so the
hardware-signed attestation report is itself the signature on the provenance,
with the signing identity chaining to the TEE manufacturer s root of trust
rather than to the build infrastructure operator. Because the CVM image is
itself reproducible, its launch measurement is public and stable, which lets
a build requester pre-attest the CVM before submitting any input and
optionally deliver source over a TLS channel terminated inside it, so the
build runs end-to-end confidentially without the host ever seeing source code
in plaintext.
New rebuilderd version announced
rebuilderd, our server designed for monitoring the official package repositories of Linux distributions and attempt to reproduce the observed results there; it powers, amongst other things, reproduce.debian.net.
A new version, 0.27.0, was released this month, with the following headline changes:
The new rebuilderd package is currently available in the extra-testing repository. Note the Arch Linux package is upgraded from v0.25.0 from v0.27.0; please be patient with the database migrations on first restart, and make
yourself familiar with the breaking changes in v0.26.0 too.
Reproducible open source messengers
GitHub developer BarbossHack is maintaining an repository/page on GitHub to track reproducibility status of open source messengers .
Perhaps rebuilderd needs a feature where GOOD packages are also periodically rebuilt in exponential back-off style and compared against current upstream build and also our last GOOD build. This would confirm whether a package is reproducible if built in a short time window but also help uncover longer time window issues that are currently hidden.
Patches
The Reproducible Builds project detects, dissects and attempts to fix as many currently-unreproducible packages as possible. We endeavour to send all of our patches upstream where applicable or possible. This month, we wrote a large number of such patches, including:
Finally, if you are interested in contributing to the Reproducible Builds project, please visit our Contribute page on our website. However, you can get in touch with us via:
This was a particularly busy month for me in terms of Debian
contributions.
It started with a week in Hamburg for the MiniDebConf. I talked to
many colleagues face-to-face and worked on various bugs and
maintenance tasks. I m pleased to have finally found the time to
reproduce and fix the boot-time crashes in the parallel port
subsystem that have been reported
many times recently.
A series of easily exploited kernel LPE (local privilege execution)
issues were published this month, mostly with very little coordination
with distributions. Salvatore and I had to upload fixes for these at
roughly weekly intervals. All of these fixes needed to be applied to
4 different upstream branches (currently 5.10, 6.1, 6.12, and 7.0) and
7 Debian branches (including backports).
This was a particularly busy month for me in terms of Debian
contributions.
It started with a week in Hamburg for the MiniDebConf. I talked to
many colleagues face-to-face and worked on various bugs and
maintenance tasks. I m pleased to have finally found the time to
reproduce and fix the boot-time crashes in the parallel port
subsystem that have been reported
many times recently.
A series of easily exploited kernel LPE (local privilege execution)
issues were published this month, mostly with very little coordination
with distributions. Salvatore and I had to upload fixes for these at
roughly weekly intervals. All of these fixes needed to be applied to
4 different upstream branches (currently 5.10, 6.1, 6.12, and 7.0) and
7 Debian branches (including backports).
Armadillo is a powerful
and expressive C++ template library for linear algebra and scientific
computing. It aims towards a good balance between speed and ease of use,
has a syntax deliberately close to Matlab, and is useful for algorithm
development directly in C++, or quick conversion of research code into
production environments. RcppArmadillo
integrates this library with the R environment and language and is
widely used by (currently) 1272 other packages on CRAN, downloaded 46.6 million
times (per the partial logs from the cloud mirrors of CRAN), and the CSDA paper (preprint
/ vignette) by Conrad and myself has been cited 693 times according
to Google Scholar.
This versions updates to the 15.2.7 upstream Armadillo release made today.
The package has already been updated for Debian, and built for r2u. As the upstream was
modest, we for once skipped reverse-dependency checks. That bet paid off
as CRAN found no issues among
the over 1270 reverse dependencies. However, one package referenced a
package archived today, hence invisible to CRAN and triggered a (false
positive) NOTE of reference to non-existing package . We came close.
Anyway, the package made it CRAN shortly thereafter following
the standard brief email exchange explaining the false-positive nature
of the NOTE.
All changes since the last CRAN release follow.
Changes in
RcppArmadillo version 15.2.7-1 (2026-05-29)
Upgraded to Armadillo release 15.2.7 (Medium Roast Deluxe)
 There has been a video blog post recently published with a review of Ubuntu Touch as an option to opt out of the Android world: https://www.youtube.com/watch?v=wTK6TS3pXgc
Thanks to @SwitchandClick for spending time on this and publishing that video. Much appreciated.
Many Issues amended in upcoming 24.04-2.0 Release
When I watched that video referenced above, I continuously thought: ah... this is fixed in the next major release of Ubuntu Touch, or: ah... this is a known issue that we have on the roadmap..., or: ah... this is done in this ways by design (so it's a feature or basic functionality)...
Let me just state, that most of the criticized aspects will be resolved in upcoming Ubuntu Touch release 24.04-2.0 (the tests in that video blog post have been run on Ubuntu Touch 24.04-1.x):
 Very happy to share that a new package

 Figure 1: Data flow when distributing commits via a mailing list
Perhaps because reading email on your desktop computer (I don t think
I could afford an IBM ThinkPad?) was the only vaguely real-time
notification system available at the time (except I guess SMS, which
cost 10p per text), a common pattern seemed to be to use a



 The RISC-V CPU architecture has been gaining a lot of popularity since it launched in 2014, and now that the industry is standardizing on the RVA23 level that includes vector support as a mandatory extension, we are likely to see a lot more edge- and IoT devices with the ability to run local LLMs at reasonable speed, and most importantly at very compelling prices.
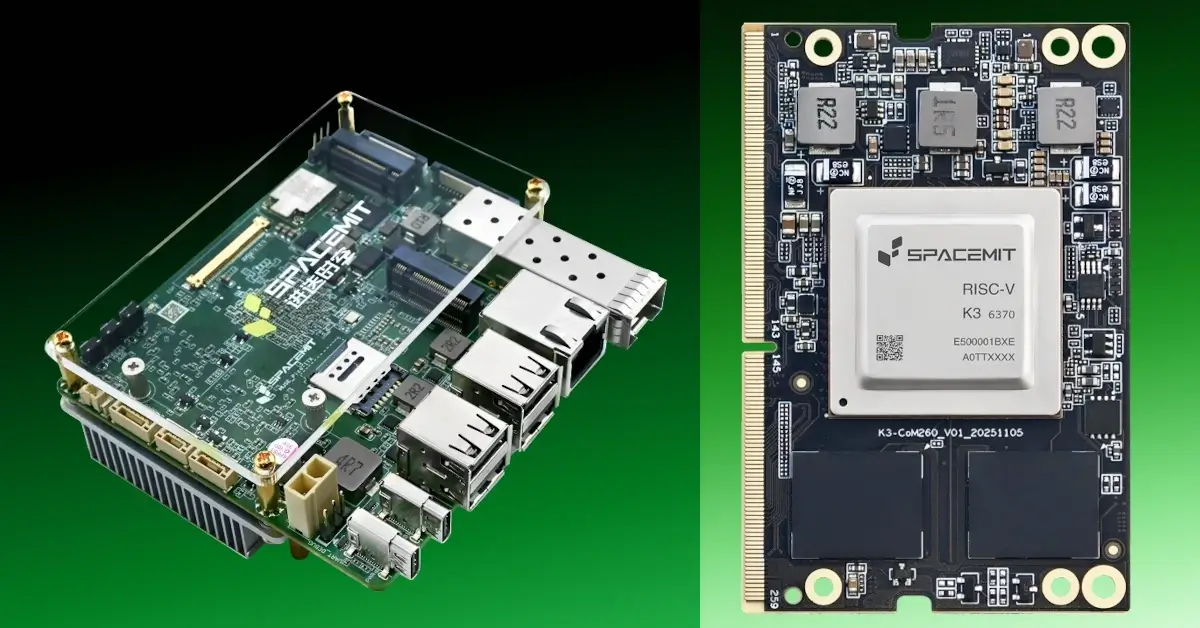
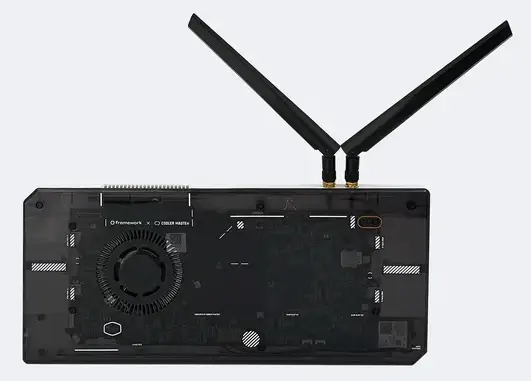
 I finally carved out some time today to prepare and release debsecan-mcp
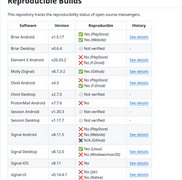


 This was a particularly busy month for me in terms of Debian
contributions.
It started with a week in Hamburg for the MiniDebConf. I talked to
many colleagues face-to-face and worked on various bugs and
maintenance tasks. I m pleased to have finally found the time to
reproduce and fix the
