Search Results: "spa"

2 February 2026

Hellen Chemtai: Career Growth Through Open Source: A Personal Journey

Hello world  ! I am an intern at Outreachy working with the Debian OpenQA team on images testing. We get to know what career opportunities awaits us when we work on open source projects. In open source, we are constantly learning. The community has different sets of skills and a large network of people.

So, how did I start off in this internship

I entered the community with the these skills:

  • MERN (Mongo DB, Express JS , React JS and Node JS) for web development
  • Linux and Shell Scripting for some administrative purposes
  • Containerization using Google Cloud
  • Operating Systems
  • A learning passion for Open Source I contributed to some open source work in the past but it was in terms of documentation and bug hunting

I was a newbie at OpenQA but, I had a month to learn and contribute. Time is a critical resource but so is understanding what you are doing. I followed the installations instructions given but whenever I got errors, I had to research why I got the errors. I took time to understand errors I was solving then continued on with the tasks I wanted to do. I communicated my logic and understanding while working on the task and awaited reviews and feedback. Within a span of two months I had learned a lot by practicing and testing.

The skills I gained

As of today, I gained these technical skills from my work with Debian OpenQA team.

  • Perl the tests that we run are written in this language
  • Ansible configuration ansible configurations and settings for the machines the team runs
  • Git this is needed for code versioning and diving tasks into different branches
  • Linux shell scripting and working with the Debian Operating system
  • Virtual Machines and Operating Systems I constantly view how different operating systems are booted and run on virtual machines during testing
  • Testing I keep watch of needles and ensure the tests work as required
  • Debian I use a Debian system to run my Virtual Machines
  • OpenQA the tool that is used to automate testing of Images

With open source comes the need of constant communication. The community is diverse and the team is usually on different time zones. These are some of the soft / social skills I gained when working with the team

  • Communication this is essential especially in taking tasks with confidence, talking about issues encountered and stating the progress of the tasks
  • Interpersonal skills this is for general communication within the community
  • Flexibility we have to adapt to changes because we are a community of different people with different skills

With these skills and the willingness to learn , open source is a great area to focus on . Aside from your career you will extend your network. My interests are set on open source and Linux in general. Working with a wider network has really skilled me up and I will continue learning. Working with the Debian OpenQA team has been very great. The team is great at communication and I learn every day. The knowledge I gain from the team is helping me build a great career in open source.

1 February 2026

Benjamin Mako Hill: What do people do when they edit Wikipedia through Tor?

Note: I have not published blog posts about my academic papers over the past few years. To ensure that my blog contains a more comprehensive record of my published papers and to surface these for folks who missed them, I will be periodically (re)publishing blog posts about some older published projects. This post is closely based on a previously published post by Kaylea Champion on the Community Data Science Blog.

Many individuals use Tor to reduce their visibility to widespread internet surveillance.
One popular approach to protecting our privacy online is to use the Tor network. Tor protects users from being identified by their IP address, which can be tied to a physical location. However, if you d like to contribute to Wikipedia using Tor, you ll run into a problem. Although most IP addresses can edit without an account, Tor users are blocked from editing.
Tor users attempting to contribute to Wikipedia are shown a screen that informs them that they are not allowed to edit Wikipedia.
Other research by my team has shown that Wikipedia s attempt to block Tor is imperfect and that some people have been able to edit despite the ban. As part of this work, we built a dataset of more than 11,000 contributions to Wikipedia via Tor and used quantitative analysis to show that contributions from Tor were of about the same quality as contributions from other new editors and other contributors without accounts. Of course, given the unusual circumstances Tor-based contributors face, we wondered whether a deeper look at the content of their edits might reveal more about their motives and the kinds of contributions they seek to make. Kaylea Champion (then a student, now faculty at UW Bothell) led a qualitative investigation to explore these questions. Given the challenges of studying anonymity seekers, we designed a novel forensic qualitative approach inspired by techniques common in computer security and criminal investigation. We applied this new technique to a sample of 500 editing sessions and categorized each session based on what the editor seemed to be intending to do. Most of the contributions we found fell into one of the two following categories: Although these were most of what we observed, we also found evidence of several types of contributor intent:
An exploratory mapping of our themes in terms of the value a type of contribution represents to the Wikipedia community and the importance of anonymity in facilitating it. Anonymity-protecting tools play a critical role in facilitating contributions on the right side of the figure, while edits on the left are more likely to occur even when anonymity is impossible. Contributions toward the top reflect valuable forms of participation in Wikipedia, while edits at the bottom reflect damage.
In all, these themes led us to reflect on how the risks individuals face when contributing to online communities sometimes diverge from the risks the communities face in accepting their work. Expressing minoritized perspectives, maintaining community standards even when you may be targeted by the rulebreaker, highlighting injustice, or acting as a whistleblower can be very risky for an individual, and may not be possible without privacy protections. Of course, in platforms seeking to support the public good, such knowledge and accountability may be crucial.

This work was published as a paper at CSCW: Kaylea Champion, Nora McDonald, Stephanie Bankes, Joseph Zhang, Rachel Greenstadt, Andrea Forte, and Benjamin Mako Hill. 2019. A Forensic Qualitative Analysis of Contributions to Wikipedia from Anonymity Seeking Users. Proceedings of the ACM on Human-Computer Interaction. 3, CSCW, Article 53 (November 2019), 26 pages. https://doi.org/10.1145/3359155

This project was conducted by Kaylea Champion, Nora McDonald, Stephanie Bankes, Joseph Zhang, Rachel Greenstadt, Andrea Forte, and Benjamin Mako Hill. This work was supported by the National Science Foundation (awards CNS-1703736 and CNS-1703049) and included the work of two undergraduates supported through an NSF REU supplement.

Russ Allbery: Review: Paladin's Faith

Review: Paladin's Faith, by T. Kingfisher
Series: The Saint of Steel #4
Publisher: Red Wombat Studio
Copyright: 2023
ISBN: 1-61450-614-0
Format: Kindle
Pages: 515
Paladin's Faith is the fourth book in T. Kingfisher's loosely connected series of fantasy novels about the berserker former paladins of the Saint of Steel. You could read this as a standalone, but there are numerous (spoilery) references to the previous books in the series. Marguerite, who was central to the plot of the first book in the series, Paladin's Grace, is a spy with a problem. An internal power struggle in the Red Sail, the organization that she's been working for, has left her a target. She has a plan for how to break their power sufficiently that they will hopefully leave her alone, but to pull it off she's going to need help. As the story opens, she is working to acquire that help in a very Marguerite sort of way: breaking into the office of Bishop Beartongue of the Temple of the White Rat. The Red Sail, the powerful merchant organization Marguerite worked for, makes their money in the salt trade. Marguerite has learned that someone invented a cheap and reproducible way to extract salt from sea water, thus making the salt trade irrelevant. The Red Sail wants to ensure that invention never sees the light of day, and has forced the artificer into hiding. Marguerite doesn't know where they are, but she knows where she can find out: the Court of Smoke, where the artificer has a patron.
Having grown up in Anuket City, Marguerite was familiar with many clockwork creations, not to mention all the ways that they could go horribly wrong. (Ninety-nine times out of a hundred, it was an explosion. The hundredth time, it ran amok and stabbed innocent bystanders, and the artificer would be left standing there saying, "But I had to put blades on it, or how would it rake the leaves?" while the gutters filled up with blood.)
All Marguerite needs to put her plan into motion is some bodyguards so that she's not constantly distracted and anxious about being assassinated. Readers of this series will be unsurprised to learn that the bodyguards she asks Beartongue for are paladins, including a large broody male one with serious self-esteem problems. This is, like the other books in this series, a slow-burn romance with infuriating communication problems and a male protagonist who would do well to seek out a sack of hammers as a mentor. However, it has two things going for it that most books in this series do not: a long and complex plot to which the romance takes a back seat, and Marguerite, who is not particularly interested in playing along with the expected romance developments. There are also two main paladins in this story, not just one, and the other is one of the two female paladins of the Saint of Steel and rather more entertaining than Shane. I generally like court intrigue stories, which is what fills most of this book. Marguerite is an experienced operative, so the reader gets some solid competence porn, and the paladins are fish out of water but are also unexpectedly dangerous, which adds both comedy and satisfying table-turning. I thoroughly enjoyed the maneuvering and the culture clashes. Marguerite is very good at what she does, knows it, and is entirely uninterested in other people's opinions about that, which short-circuits a lot of Shane's most annoying behavior and keeps the story from devolving into mopey angst like some of the books in this series have done. The end of this book takes the plot in a different direction that adds significantly to the world-building, but also has a (thankfully short) depths of despair segment that I endured rather than enjoyed. I am not really in the mood for bleak hopelessness in my fiction at the moment, even if the reader is fairly sure it will be temporary. But apart from that, I thoroughly enjoyed this book from beginning to end. When we finally meet the artificer, they are an absolute delight in that way that Kingfisher is so good at. The whole story is infused with the sense of determined and competent people refusing to stop trying to fix problems. As usual, the romance was not for me and I think the book would have been better without it, but it's less central to the plot and therefore annoyed me less than any of the books in this series so far. My one major complaint is the lack of gnoles, but we get some new and intriguing world-building to make up for it, along with a setup for a fifth book that I am now extremely curious about. By this point in the series, you probably know if you like the general formula. Compared to the previous book, Paladin's Hope, I thought Paladin's Faith was much stronger and more interesting, but it's clearly of the same type. If, like me, you like the plots but not the romance, the plot here is more substantial. You will have to decide if that makes up for a romance in the typical T. Kingfisher configuration. Personally, I enjoyed this quite a bit, except for the short bleak part, and I'm back to eagerly awaiting the next book in the series. Rating: 8 out of 10

31 January 2026

Russ Allbery: Review: Dragon Pearl

Review: Dragon Pearl, by Yoon Ha Lee
Series: Thousand Worlds #1
Publisher: Rick Riordan Presents
Copyright: 2019
ISBN: 1-368-01519-0
Format: Kindle
Pages: 315
Dragon Pearl is a middle-grade space fantasy based on Korean mythology and the first book of a series. Min is a fourteen-year-old girl living on the barely-terraformed world of Jinju with her extended family. Her older brother Jun passed the entrance exams for the Academy and left to join the Thousand Worlds Space Forces, and Min is counting the years until she can do the same. Those plans are thrown into turmoil when an official investigator appears at their door claiming that Jun deserted to search for the Dragon Pearl. A series of impulsive fourteen-year-old decisions lead to Min heading for a spaceport alone, determined to find her brother and prove his innocence. This would be a rather improbable quest for a young girl, but Min is a gumiho, one of the supernaturals who live in the Thousand Worlds alongside non-magical humans. Unlike the more respectable dragons, tigers, goblins, and shamans, gumiho are viewed with suspicion and distrust because their powers are useful for deception. They are natural shapeshifters who can copy the shapes of others, and their Charm ability lets them influence people's thoughts and create temporary illusions of objects such as ID cards. It will take all of Min's powers, and some rather lucky coincidences, to infiltrate the Space Forces and determine what happened to her brother. It's common for reviews of this book to open with a caution that this is a middle-grade adventure novel and you should not expect a story like Ninefox Gambit. I will be boring and repeat that caution. Dragon Pearl has a single first-person viewpoint and a very linear and straightforward plot. Adult readers are unlikely to be surprised by plot twists; the fun is the world-building and seeing how Min manages to work around plot obstacles. The world-building is enjoyable but not very rigorous. Min uses and abuses Charm with the creative intensity of a Dungeons & Dragons min-maxer. Each individual event makes sense given the implication that Min is unusually powerful, but I'm dubious about the surrounding society and lack of protections against Charm given what Min is able to do. Min does say that gumiho are rare and many people think they're extinct, which is a bit of a fig leaf, but you'll need to bring your urban fantasy suspension of disbelief skills to this one. I did like that the world-building conceit went more than skin deep and influenced every part of the world. There are ghosts who are critical to the plot. Terraforming is done through magic, hence the quest for the Dragon Pearl and the miserable state of Min's home planet due to its loss. Medical treatment involves the body's meridians, as does engineering: The starships have meridians similar to those of humans, and engineers partly merge with those meridians to adjust them. This is not the sort of book that tries to build rigorous scientific theories or explain them to the reader, and I'm not sure everything would hang together if you poked at it too hard, but Min isn't interested in doing that poking and the story doesn't try to justify itself. It's mostly a vibe, but it's a vibe that I enjoyed and that is rather different than other space fantasy I've read. The characters were okay but never quite clicked for me, in part because proper character exploration would have required Min take a detour from her quest to find her brother and that was not going to happen. The reader gets occasional glimpses of a military SF cadet story and a friendship on false premises story, but neither have time to breathe because Min drops any entanglement that gets in the way of her quest. She's almost amoral in a way that I found believable but not quite aligned with my reading mood. I also felt a bit wrong-footed by how her friendships developed; saying too much more would be a spoiler, but I was expecting more human connection than I got. I think my primary disappointment with this book was something I knew going in, not in any way its fault, and part of the reason why I'd put off reading it: This is pitched at young teenagers and didn't have quite enough plot and characterization complexity to satisfy me. It's a linear, somewhat episodic adventure story with some neat world-building, and it therefore glides over the spots where an adult novel would have added political and factional complexity. That is exactly as advertised, so it's up to you whether that's the book you're in the mood for. One warning: The text of this book opens with an introduction by Rick Riordan that is just fluff marketing and that spoils the first few chapters of the book. It is unmarked as such at the beginning and tricked me into thinking it was the start of the book proper, and then deeply annoyed me. If you do read this book, I recommend skipping the utterly pointless introduction and going straight to chapter one. Followed by Tiger Honor. Rating: 6 out of 10

28 January 2026

C.J. Collier: Part 2: Taming the Beast Deep Dive into the Proxy-Aware GPU Initialization Action

Part
2: Taming the Beast Deep Dive into the Proxy-Aware GPU Initialization
Action In Part 1 of this series, we laid the network foundation for running
secure Dataproc clusters. Now, let s zoom in on the core component
responsible for installing and configuring NVIDIA GPU drivers and the
associated ML stack in this restricted environment: the
install_gpu_driver.sh script from the LLC-Technologies-Collier/initialization-actions
repository (branch gpu-202601). This isn t just any installation script; it has been significantly
enhanced to handle the nuances of Secure Boot and to operate seamlessly
behind an HTTP/S proxy.

The
Challenge: Installing GPU Drivers Without Direct Internet Our goal was to create a Dataproc custom image with NVIDIA GPU
drivers, sign the kernel modules for Secure Boot, and ensure the entire
process works seamlessly when the build VM and the eventual cluster
nodes have no direct internet access, relying solely on an HTTP/S proxy.
This involved:
  1. Proxy-Aware Build: Ensuring all build steps within
    the custom image creation process (package downloads, driver downloads,
    GPG keys, etc.) correctly use the customer s proxy.
  2. Secure Boot Signing: Integrating kernel module
    signing using keys managed in GCP Secret Manager, especially when
    drivers are built from source.
  3. Conda Environment: Reliably and speedily installing
    a complex Conda environment with PyTorch, TensorFlow, Rapids, and other
    GPU-accelerated libraries through the proxy.
  4. Dataproc Integration: Making sure the custom image
    works correctly with Dataproc s own startup, agent processes, and
    cluster-specific configurations like YARN.

The
Development Journey: Key Enhancements in
install_gpu_driver.sh To address these challenges, the script incorporates several key
features:
  • Robust Proxy Handling (set_proxy
    function):
    • Challenge: Initial script versions had spotty proxy
      support. Many tools like apt, curl,
      gpg, and even gsutil failed in proxy-only
      environments.
    • Enhancements: The set_proxy function
      (also used in gce-proxy-setup.sh) was completely overhauled
      to parse various proxy metadata (http-proxy,
      https-proxy, proxy-uri,
      no-proxy). Critically, environment variables
      (HTTP_PROXY, HTTPS_PROXY,
      NO_PROXY) are now set before any network
      operations. NO_PROXY is carefully set to include
      .google.com and .googleapis.com to allow
      direct access to Google APIs via Private Google Access. System-wide
      trust stores (OS, Java, Conda) are updated with the proxy s CA
      certificate if provided via http-proxy-pem-uri.
      gcloud, apt, dnf, and
      dirmngr are also configured to use the proxy.
  • Reliable GPG Key Fetching (import_gpg_keys
    function):
    • Challenge: Importing GPG keys for repositories
      often failed as keyservers use non-HTTP ports (e.g., 11371) blocked by
      firewalls, and gpg --recv-keys is not proxy-friendly.
    • Solution: A new import_gpg_keys
      function now fetches keys over HTTPS using curl, which
      respects the environment s proxy settings. This replaced all direct
      gpg --recv-keys calls.
  • GCS Caching is King:
    • Challenge: Repeatedly downloading large files
      (drivers, CUDA, source code) through a proxy is slow and
      inefficient.
    • Solution: Implemented extensive GCS caching for
      NVIDIA drivers, CUDA runfiles, NVIDIA Open Kernel Module source
      tarballs, compiled kernel modules, and even packed Conda environments.
      Scripts now check a GCS bucket (dataproc-temp-bucket)
      before hitting the internet.
    • Impact: Dramatically speeds up subsequent runs and
      init action execution times on cluster nodes after the cache is
      warmed.
  • Conda Environment Stability & Speed:
    • Challenge: Large Conda environments are prone to
      solver conflicts and slow installation times.
    • Solution: Integrated Mamba for faster package
      solving. Refined package lists for better compatibility. Added logic to
      force-clean and rebuild the Conda environment cache on GCS and locally
      if inconsistencies are detected (e.g., driver installed but Conda env
      not fully set up).
  • Secure Boot & Kernel Module Signing:
    • Challenge: Custom-compiled kernel modules must be
      signed to load when Secure Boot is enabled.
    • Solution: The script integrates with GCP Secret
      Manager to fetch signing keys. The build_driver_from_github
      function now includes robust steps to compile, sign (using
      sign-file), install, and verify the signed modules.
  • Custom Image Workflow & Deferred Configuration:
    • Challenge: Cluster-specific settings (like YARN GPU
      configuration) should not be baked into the image.
    • Solution: The install_gpu_driver.sh
      script detects when it s run during image creation
      (--metadata invocation-type=custom-images). In this mode,
      it defers cluster-specific setups to a systemd service
      (dataproc-gpu-config.service) that runs on the first boot
      of a cluster instance. This ensures that YARN and Spark configurations
      are applied in the context of the running cluster, not at image build
      time.

Conclusion of Part 2 The install_gpu_driver.sh initialization action is more
than just an installer; it s a carefully crafted tool designed to handle
the complexities of secure, proxied environments. Its robust proxy
support, comprehensive GCS caching, refined Conda management, Secure
Boot signing capabilities, and awareness of the custom image build
lifecycle make it a critical enabler. In Part 3, we ll explore how the LLC-Technologies-Collier/custom-images
repository (branch proxy-exercise-2025-11) uses this
initialization action to build the complete, ready-to-deploy Secure Boot
GPU custom images.

C.J. Collier: Dataproc GPUs, Secure Boot, & Proxies

Part
1: Building a Secure Network Foundation for Dataproc with GPUs &
SWP Welcome to the first post in our series on running GPU-accelerated
Dataproc workloads in secure, enterprise-grade environments. Many
organizations need to operate within VPCs that have no direct internet
egress, instead routing all traffic through a Secure Web Proxy (SWP).
Additionally, security mandates often require the use of Shielded VMs
with Secure Boot enabled. This series will show you how to meet these
requirements for your Dataproc GPU clusters. In this post, we ll focus on laying the network foundation using
tools from the LLC-Technologies-Collier/cloud-dataproc
repository (branch proxy-sync-2026-01).

The Challenge: Network
Isolation & Control Before we can even think about custom images or GPU drivers, we need
a network environment that:
  1. Prevents direct internet access from Dataproc cluster nodes.
  2. Forces all egress traffic through a manageable and auditable
    SWP.
  3. Provides the necessary connectivity for Dataproc to function and for
    us to build images later.
  4. Supports Secure Boot for all VMs.

The Toolkit:
LLC-Technologies-Collier/cloud-dataproc To make setting up and tearing down these complex network
environments repeatable and consistent, we ve developed a set of bash
scripts within the gcloud directory of the
cloud-dataproc repository. These scripts handle the
creation of VPCs, subnets, firewall rules, service accounts, and the
Secure Web Proxy itself. Key Script:
gcloud/bin/create-dpgce-private This script is the cornerstone for creating the private, proxied
environment. It automates:
  • VPC and Subnet creation (for the cluster, SWP, and management).
  • Setup of Certificate Authority Service and Certificate Manager for
    SWP TLS interception.
  • Deployment of the SWP Gateway instance.
  • Configuration of a Gateway Security Policy to control egress.
  • Creation of necessary firewall rules.
  • Result: Cluster nodes in this VPC have NO default
    internet route and MUST use the SWP.
Configuration via env.json We use a single env.json file to drive the
configuration. This file will also be used by the
custom-images scripts in Part 3. This env.json
should reside in your custom-images repository clone, and
you ll symlink it into the cloud-dataproc/gcloud
directory. Running the Setup:
# Assuming you have cloud-dataproc and custom-images cloned side-by-side
# And your env.json is in the custom-images root
cd cloud-dataproc/gcloud
# Symlink to the env.json in custom-images
ln -sf ../../custom-images/env.json env.json
# Run the creation script, but don't create a cluster yet
bash bin/create-dpgce-private --no-create-cluster
cd ../../custom-images

Node
Configuration: The Metadata Startup Script for Runtime For the Dataproc cluster nodes to function correctly in this proxied
environment, they need to be configured to use the SWP on boot. We
achieve this using a GCE metadata startup script. The script startup_script/gce-proxy-setup.sh (from the
custom-images repository) is designed to be run on each
cluster node at boot. It reads metadata like http-proxy and
http-proxy-pem-uri (which our cluster creation scripts in
Part 4 will pass) to configure the OS environment, package managers, and
other tools to use the SWP. Upload this script to your GCS bucket:
# Run from the custom-images repository root
gsutil cp startup_script/gce-proxy-setup.sh gs://$(jq -r .BUCKET env.json)/custom-image-deps/
This script is essential for the runtime behavior of the
cluster nodes.

Conclusion of Part 1 With the cloud-dataproc scripts, we ve laid the
groundwork by provisioning a secure VPC with controlled egress through
an SWP. We ve also prepared the essential node-level proxy configuration
script (gce-proxy-setup.sh) in GCS, ready to be used by our
clusters. Stay tuned for Part 2, where we ll dive into the
install_gpu_driver.sh initialization action from the
LLC-Technologies-Collier/initialization-actions repository
(branch gpu-202601) and how it s been adapted to install
all GPU-related software through the proxy during the image build
process.

27 January 2026

Elana Hashman: A beginner's guide to improving your digital security

In 2017, I led a series of workshops aimed at teaching beginners a better understanding of encryption, how the internet works, and their digital security. Nearly a decade later, there is still a great need to share reliable resources and guides on improving these skills. I have worked professionally in computer security one way or another for well over a decade, at many major technology companies and in many open source software projects. There are many inaccurate and unreliable resources out there on this subject, put together by well-meaning people without a background in security, which can lead to sharing misinformation, exaggeration and fearmongering. I hope that I can offer you a trusted, curated list of high impact things that you can do right now, using whichever vetted guide you prefer. In addition, I also include how long it should take, why you should do each task, and any limitations. This guide is aimed at improving your personal security, and does not apply to your work-owned devices. Always assume your company can monitor all of your messages and activities on work devices. What can I do to improve my security right away? I put together this list in order of effort, easiest tasks first. You should be able to complete many of the low effort tasks in a single hour. The medium to high effort tasks are very much worth doing, but may take you a few days or even weeks to complete them. Low effort (<15 minutes) Upgrade your software to the latest versions Why? I don't know anyone who hasn't complained about software updates breaking features, introducing bugs, and causing headaches. If it ain't broke, why upgrade, right? Well, alongside all of those annoying bugs and breaking changes, software updates also include security fixes, which will protect your device from being exploited by bad actors. Security issues can be found in software at any time, even software that's been available for many years and thought to be secure. You want to install these as soon as they are available. Recommendation: Turn on automatic upgrades and always keep your devices as up-to-date as possible. If you have some software you know will not work if you upgrade it, at least be sure to upgrade your laptop and phone operating system (iOS, Android, Windows, etc.) and web browser (Chrome, Safari, Firefox, etc.). Do not use devices that do not receive security support (e.g. old Android or iPhones). Guides: Limitations: This will prevent someone from exploiting known security issues on your devices, but it won't help if your device was already compromised. If this is a concern, doing a factory reset, upgrade, and turning on automatic upgrades may help. This also won't protect against all types of attacks, but it is a necessary foundation. Use Signal Why? Signal is a trusted, vetted, secure messaging application that allows you to send end-to-end encrypted messages and make video/phone calls. This means that only you and your intended recipient can decrypt the messages and someone cannot intercept and read your messages, in contrast to texting (SMS) and other insecure forms of messaging. Other applications advertise themselves as end-to-end encrypted, but Signal provides the strongest protections. Recommendation: I recommend installing the Signal app and using it! My mom loves that she can video call me on Wi-Fi on my Android phone. It also supports group chats. I use it as a secure alternative to texting (SMS) and other chat platforms. I also like Signal's "disappearing messages" feature which I enable by default because it automatically deletes messages after a certain period of time. This avoids your messages taking up too much storage. Guides: Limitations: Signal is only able to protect your messages in transit. If someone has access to your phone or the phone of the person you sent messages to, they will still be able to read them. As a rule of thumb, if you don't want someone to read something, don't write it down! Meet in person or make an encrypted phone call where you will not be overheard. If you are talking to someone you don't know, assume your messages are as public as posting on social media. Set passwords and turn on device encryption Why? Passwords ensure that someone else can't unlock your device without your consent or knowledge. They also are required to turn on device encryption, which protects your information on your device from being accessed when it is locked. Biometric (fingerprint or face ID) locking provides some privacy, but your fingerprint or face ID can be used against your wishes, whereas if you are the only person who knows your password, only you can use it. Recommendation: Always set passwords and have device encryption enabled in order to protect your personal privacy. It may be convenient to allow kids or family members access to an unlocked device, but anyone else can access it, too! Use strong passwords that cannot be guessed avoid using names, birthdays, phone numbers, addresses, or other public information. Using a password manager will make creating and managing passwords even easier. Disable biometric unlock, or at least know how to disable it. Most devices will enable disk encryption by default, but you should double-check. Guides: Limitations: If your device is unlocked, the password and encryption will provide no protections; the device must be locked for this to protect your privacy. It is possible, though unlikely, for someone to gain remote access to your device (for example through malware or stalkerware), which would bypass these protections. Some forensic tools are also sophisticated enough to work with physical access to a device that is turned on and locked, but not a device that is turned off/freshly powered on and encrypted. If you lose your password or disk encryption key, you may lose access to your device. For this reason, Windows and Apple laptops can make a cloud backup of your disk encryption key. However, a cloud backup can potentially be disclosed to law enforcement. Install an ad blocker Why? Online ad networks are often exploited to spread malware to unsuspecting visitors. If you've ever visited a regular website and suddenly seen an urgent, flashing pop-up claiming your device was hacked, it is often due to a bad ad. Blocking ads provides an additional layer of protection against these kinds of attacks. Recommendation: I recommend everyone uses an ad blocker at all times. Not only are ads annoying and disruptive, but they can even result in your devices being compromised! Guides: Limitations: Sometimes the use of ad blockers can break functionality on websites, which can be annoying, but you can temporarily disable them to fix the problem. These may not be able to block all ads or all tracking, but they make browsing the web much more pleasant and lower risk! Some people might also be concerned that blocking ads might impact the revenue of their favourite websites or creators. In this case, I recommend either donating directly or sharing the site with a wider audience, but keep using the ad blocker for your safety. Enable HTTPS-Only Mode Why? The "S" in "HTTPS" stands for "secure". This feature, which can be enabled on your web browser, ensures that every time you visit a website, your connection is always end-to-end encrypted (just like when you use Signal!) This ensures that someone can't intercept what you search for, what pages on websites you visit, and any information you or the website share such as your banking details. Recommendation: I recommend enabling this for everyone, though with improvements in web browser security and adoption of HTTPS over the years, your devices will often do this by default! There is a small risk you will encounter some websites that do not support HTTPS, usually older sites. Guides: Limitations: HTTPS protects the information on your connection to a website. It does not hide or protect the fact that you visited that website, only the information you accessed. If the website is malicious, HTTPS does not provide any protection. In certain settings, like when you use a work-managed computer that was set up for you, it can still be possible for your IT Department to see what you are browsing, even over an HTTPS connection, because they have administrator access to your computer and the network. Medium to high effort (1+ hours) These tasks require more effort but are worth the investment. Set up a password manager Why? It is not possible for a person to remember a unique password for every single website and app that they use. I have, as of writing, 556 passwords stored in my password manager. Password managers do three important things very well:
  1. They generate secure passwords with ease. You don't need to worry about getting your digits and special characters just right; the app will do it for you, and generate long, secure passwords.
  2. They remember all your passwords for you, and you just need to remember one password to access all of them. The most common reason people's accounts get hacked online is because they used the same password across multiple websites, and one of the websites had all their passwords leaked. When you use a unique password on every website, it doesn't matter if your password gets leaked!
  3. They autofill passwords based on the website you're visiting. This is important because it helps prevent you from getting phished. If you're tricked into visiting an evil lookalike site, your password manager will refuse to fill the password.
Recommendation: These benefits are extremely important, and setting up a password manager is often one of the most impactful things you can do for your digital security. However, they take time to get used to, and migrating all of your passwords into the app (and immediately changing them!) can take a few minutes at a time... over weeks. I recommend you prioritize the most important sites, such as your email accounts, banking/financial sites, and cellphone provider. This process will feel like a lot of work, but you will get to enjoy the benefits of never having to remember new passwords and the autofill functionality for websites. My recommended password manager is 1Password, but it stores passwords in the cloud and costs money. There are some good free options as well if cost is a concern. You can also use web browser- or OS-based password managers, but I do not prefer these. Guides: Limitations: Many people are concerned about the risk of using a password manager causing all of their passwords to be compromised. For this reason, it's very important to use a vetted, reputable password manager that has passed audits, such as 1Password or Bitwarden. It is also extremely important to choose a strong password to unlock your password manager. 1Password makes this easier by generating a secret to strengthen your unlock password, but I recommend using a long, memorable password in any case. Another risk is that if you forget your password manager's password, you will lose access to all your passwords. This is why I recommend 1Password, which has you set up an Emergency Kit to recover access to your account. Set up two-factor authentication (2FA) for your accounts Why? If your password is compromised in a website leak or due to a phishing attack, two-factor authentication will require a second piece of information to log in and potentially thwart the intruder. This provides you with an extra layer of security on your accounts. Recommendation: You don't necessarily need to enable 2FA on every account, but prioritize enabling it on your most important accounts (email, banking, cellphone, etc.) There are typically a few different kinds: email-based (which is why your email account's security is so important), text message or SMS-based (which is why your cell phone account's security is so important), app-based, and hardware token-based. Email and text message 2FA are fine for most accounts. You may want to enable app- or hardware token-based 2FA for your most sensitive accounts. Guides: Limitations: The major limitation is that if you lose access to 2FA, you can be locked out of an account. This can happen if you're travelling abroad and can't access your usual cellphone number, if you break your phone and you don't have a backup of your authenticator app, or if you lose your hardware-based token. For this reason, many websites will provide you with "backup tokens" you can print them out and store them in a secure location or use your password manager. I also recommend if you use an app, you choose one that will allow you to make secure backups, such as Ente. You are also limited by the types of 2FA a website supports; many don't support app- or hardware token-based 2FA. Remove your information from data brokers Why? This is a problem that mostly affects people in the US. It surprises many people that information from their credit reports and other public records is scraped and available (for free or at a low cost) online through "data broker" websites. I have shocked friends who didn't believe this was an issue by searching for their full names and within 5 minutes being able to show them their birthday, home address, and phone number. This is a serious privacy problem! Recommendation: Opt out of any and all data broker websites to remove this information from the internet. This is especially important if you are at risk of being stalked or harassed. Guides: Limitations: It can take time for your information to be removed once you opt out, and unfortunately search engines may have cached your information for a while longer. This is also not a one-and-done process. New data brokers are constantly popping up and some may not properly honour your opt out, so you will need to check on a regular basis (perhaps once or twice a year) to make sure your data has been properly scrubbed. This also cannot prevent someone from directly searching public records to find your information, but that requires much more effort. "Recommended security measures" I think beginners should avoid We've covered a lot of tasks you should do, but I also think it's important to cover what not to do. I see many of these tools recommended to security beginners, and I think that's a mistake. For each tool, I will explain my reasoning around why I don't think you should use it, and the scenarios in which it might make sense to use. "Secure email" What is it? Many email providers, such as Proton Mail, advertise themselves as providing secure email. They are often recommended as a "more secure" alternative to typical email providers such as GMail. What's the problem? Email is fundamentally insecure by design. The email specification (RFC-3207) states that any publicly available email server MUST NOT require the use of end-to-end encryption in transit. Email providers can of course provide additional security by encrypting their copies of your email, and providing you access to your email by HTTPS, but the messages themselves can always be sent without encryption. Some platforms such as Proton Mail advertise end-to-end encrypted emails so long as you email another Proton user. This is not truly email, but their own internal encrypted messaging platform that follows the email format. What should I do instead? Use Signal to send encrypted messages. NEVER assume the contents of an email are secure. Who should use it? I don't believe there are any major advantages to using a service such as this one. Even if you pay for a more "secure" email provider, the majority of your emails will still be delivered to people who don't. Additionally, while I don't use or necessarily recommend their service, Google offers an Advanced Protection Program for people who may be targeted by state-level actors. PGP/GPG Encryption What is it? PGP ("Pretty Good Privacy") and GPG ("GNU Privacy Guard") are encryption and cryptographic signing software. They are often recommended to encrypt messages or email. What's the problem? GPG is decades old and its usability has always been terrible. It is extremely easy to accidentally send a message that you thought was encrypted without encryption! The problems with PGP/GPG have been extensively documented. What should I do instead? Use Signal to send encrypted messages. Again, NEVER use email for sensitive information. Who should use it? Software developers who contribute to projects where there is a requirement to use GPG should continue to use it until an adequate alternative is available. Everyone else should live their lives in PGP-free bliss. Installing a "secure" operating system (OS) on your phone What is it? There are a number of self-installed operating systems for Android phones, such as GrapheneOS, that advertise as being "more secure" than using the version of the Android operating system provided by your phone manufacturer. They often remove core Google APIs and services to allow you to "de-Google" your phone. What's the problem? These projects are relatively niche, and don't have nearly enough resourcing to be able to respond to the high levels of security pressure Android experiences (such as against the forensic tools I mentioned earlier). You may suddenly lose security support with no notice, as with CalyxOS. You need a high level of technical know-how and a lot of spare time to maintain your device with a custom operating system, which is not a reasonable expectation for the average person. By stripping all Google APIs such as Google Play Services, some useful apps can no longer function. And some law enforcement organizations have gone as far as accusing people who install GrapheneOS on Pixel phones to be engaging in criminal activity. What should I do instead? For the best security on an Android device, use a phone manufactured by Google or Samsung (smaller manufacturers are more unreliable), or consider buying an iPhone. Make sure your device is receiving security updates and up-to-date. Who should use it? These projects are great for tech enthusiasts who are interested in contributing to and developing them further. They can be used to give new life to old phones that are not receiving security or software updates. They are also great for people with an interest in free and open source software and digital autonomy. But these tools are not a good choice for a general audience, nor do they provide more practical security than using an up-to-date Google or Samsung Android phone. Virtual Private Network (VPN) Services What is it? A virtual private network or VPN service can provide you with a secure tunnel from your device to the location that the VPN operates. This means that if I am using my phone in Seattle connected to a VPN in Amsterdam, if I access a website, it appears to the website that my phone is located in Amsterdam. What's the problem? VPN services are frequently advertised as providing security or protection from nefarious bad actors, or helping protect your privacy. These benefits are often far overstated, and there are predatory VPN providers that can actually be harmful. It costs money and resources to provide a VPN, so free VPN services are especially suspect. When you use a VPN, the VPN provider knows the websites you are visiting in order to provide you with the service. Free VPN providers may sell this data in order to cover the cost of providing the service, leaving you with less security and privacy. The average person does not have the knowledge to be able to determine if a VPN service is trustworthy or not. VPNs also don't provide any additional encryption benefits if you are already using HTTPS. They may provide a small amount of privacy benefit if you are connected to an untrusted network with an attacker. What should I do instead? Always use HTTPS to access websites. Don't connect to untrusted internet providers for example, use cellphone network data instead of a sketchy Wi-Fi access point. Your local neighbourhood coffee shop is probably fine. Who should use it? There are three main use cases for VPNs. The first is to bypass geographic restrictions. A VPN will cause all of your web traffic to appear to be coming from another location. If you live in an area that has local internet censorship policies, you can use a VPN to access the internet from a location that lacks such policies. The second is if you know your internet service provider is actively hostile or malicious. A trusted VPN will protect the visibility of all your traffic, including which websites you visit, from your internet service provider, and the only thing they will be able to see is that you are accessing a VPN. The third use case is to access a network that isn't connected to the public internet, such as a corporate intranet. I strongly discourage the use of VPNs for "general-purpose security." Tor What is it? Tor, "The Onion Router", is a free and open source software project that provides anonymous networking. Unlike with a VPN, where the VPN provider knows who you are and what websites you are requesting, Tor's architecture makes it extremely difficult to determine who sent a request. What's the problem? Tor is difficult to set up properly; similar to PGP-encrypted email, it is possible to accidentally not be connected to Tor and not know the difference. This usability has improved over the years, but Tor is still not a good tool for beginners to use. Due to the way Tor works, it is also extremely slow. If you have used cable or fiber internet, get ready to go back to dialup speeds. Tor also doesn't provide perfect privacy and without a strong understanding of its limitations, it can be possible to deanonymize someone despite using it. Additionally, many websites are able to detect connections from the Tor network and block them. What should I do instead? If you want to use Tor to bypass censorship, it is often better to use a trusted VPN provider, particularly if you need high bandwidth (e.g. for streaming). If you want to use Tor to access a website anonymously, Tor itself might not be enough to protect you. For example, if you need to provide an email address or personal information, you can decline to provide accurate information and use a masked email address. A friend of mine once used the alias "Nunya Biznes" Who should use it? Tor should only be used by people who are experienced users of security tools and understand its strengths and limitations. Tor also is best used on a purpose-built system, such as Tor Browser or Freedom of the Press Foundation's SecureDrop. I want to learn more! I hope you've found this guide to be a useful starting point. I always welcome folks reaching out to me with questions, though I might take a little bit of time to respond. You can always email me. If there's enough interest, I might cover the following topics in a future post: Stay safe out there!

26 January 2026

Otto Kek l inen: Ubuntu Pro subscription - should you pay to use Linux?

Featured image of post Ubuntu Pro subscription - should you pay to use Linux?Ubuntu Pro is a subscription offering for Ubuntu users who want to pay for the assurance of getting quick and high-quality security updates for Ubuntu. I tested it out to see how it works in practice, and to evaluate how well it works as a commercial open source service model for Linux. Anyone running Ubuntu can subscribe to it at ubuntu.com/pro/subscribe by selecting the setup type Desktops for the price of $25 per year (+applicable taxes) for Enterprise users. There is also a free version for personal use. Once you have an account, you can find your activation token at ubuntu.com/pro/dashboard, and use it to activate Ubuntu Pro on your desktop or laptop Ubuntu machine by running sudo pro attach <token>:
$ sudo pro attach aabbcc112233aabbcc112233
Enabling default service esm-apps
Updating package lists
Ubuntu Pro: ESM Apps enabled
Enabling default service esm-infra
Updating package lists
Ubuntu Pro: ESM Infra enabled
Enabling default service livepatch
Installing canonical-livepatch snap
Canonical livepatch enabled.
Unable to determine current instance-id
This machine is now attached to 'Ubuntu Pro Desktop'
You can at any time confirm the Ubuntu Pro status by running:
$ sudo pro status --all
SERVICE ENTITLED STATUS DESCRIPTION
anbox-cloud yes disabled Scalable Android in the cloud
cc-eal yes n/a Common Criteria EAL2 Provisioning Packages
esm-apps yes enabled Expanded Security Maintenance for Applications
esm-infra yes enabled Expanded Security Maintenance for Infrastructure
fips yes n/a NIST-certified FIPS crypto packages
fips-preview yes n/a Preview of FIPS crypto packages undergoing certification with NIST
fips-updates yes disabled FIPS compliant crypto packages with stable security updates
landscape yes enabled Management and administration tool for Ubuntu
livepatch yes disabled Canonical Livepatch service
realtime-kernel yes disabled Ubuntu kernel with PREEMPT_RT patches integrated
  generic yes disabled Generic version of the RT kernel (default)
  intel-iotg yes n/a RT kernel optimized for Intel IOTG platform
  raspi yes n/a 24.04 Real-time kernel optimised for Raspberry Pi
ros yes n/a Security Updates for the Robot Operating System
ros-updates yes n/a All Updates for the Robot Operating System
usg yes disabled Security compliance and audit tools
Enable services with: pro enable <service>
Account: Otto Kekalainen
Subscription: Ubuntu Pro Desktop
Valid until: Thu Mar 3 08:08:38 2026 PDT
Technical support level: essential
For a regular desktop/laptop user the most relevant service is the esm-apps, which delivers extended security updates to many applications typically used on desktop systems. Another relevant command to confirm the current subscription status is:
$ sudo pro security-status
2828 packages installed:
2143 packages from Ubuntu Main/Restricted repository
660 packages from Ubuntu Universe/Multiverse repository
13 packages from third parties
12 packages no longer available for download
To get more information about the packages, run
pro security-status --help
for a list of available options.
This machine is receiving security patching for Ubuntu Main/Restricted
repository until 2029.
This machine is attached to an Ubuntu Pro subscription.
Ubuntu Pro with 'esm-infra' enabled provides security updates for
Main/Restricted packages until 2034.
Ubuntu Pro with 'esm-apps' enabled provides security updates for
Universe/Multiverse packages until 2034. You have received 26 security
updates.
This confirms the scope of the security support. You can even run sudo pro security-status --esm-apps to get a detailed breakdown of the installed software packages in scope for Expanded Security Maintenance (ESM).

Experiences from using Ubuntu Pro for over a year Personally I have been using it on two laptop systems for well over a year now and everything seems to have worked well. I see apt is downloading software updates from https://esm.ubuntu.com/apps/ubuntu, but other than that there aren t any notable signs of Ubuntu Pro being in use. That is a good thing after all one is paying for assurance that everything works with minimum disruptions, so the system that enables smooth sailing should stay in the background and not make too much noise of itself.

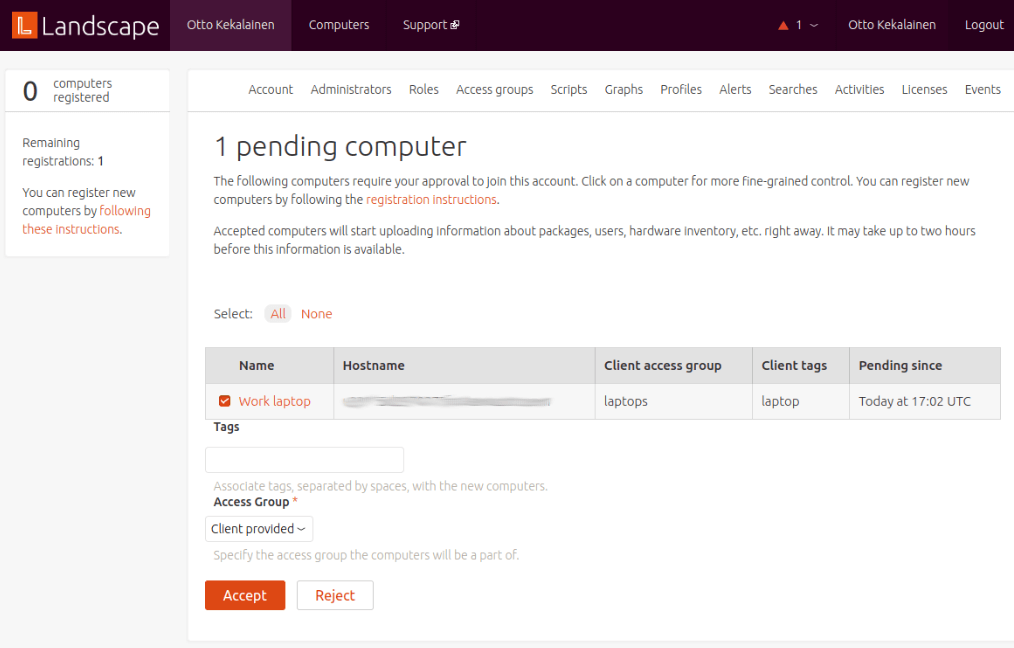
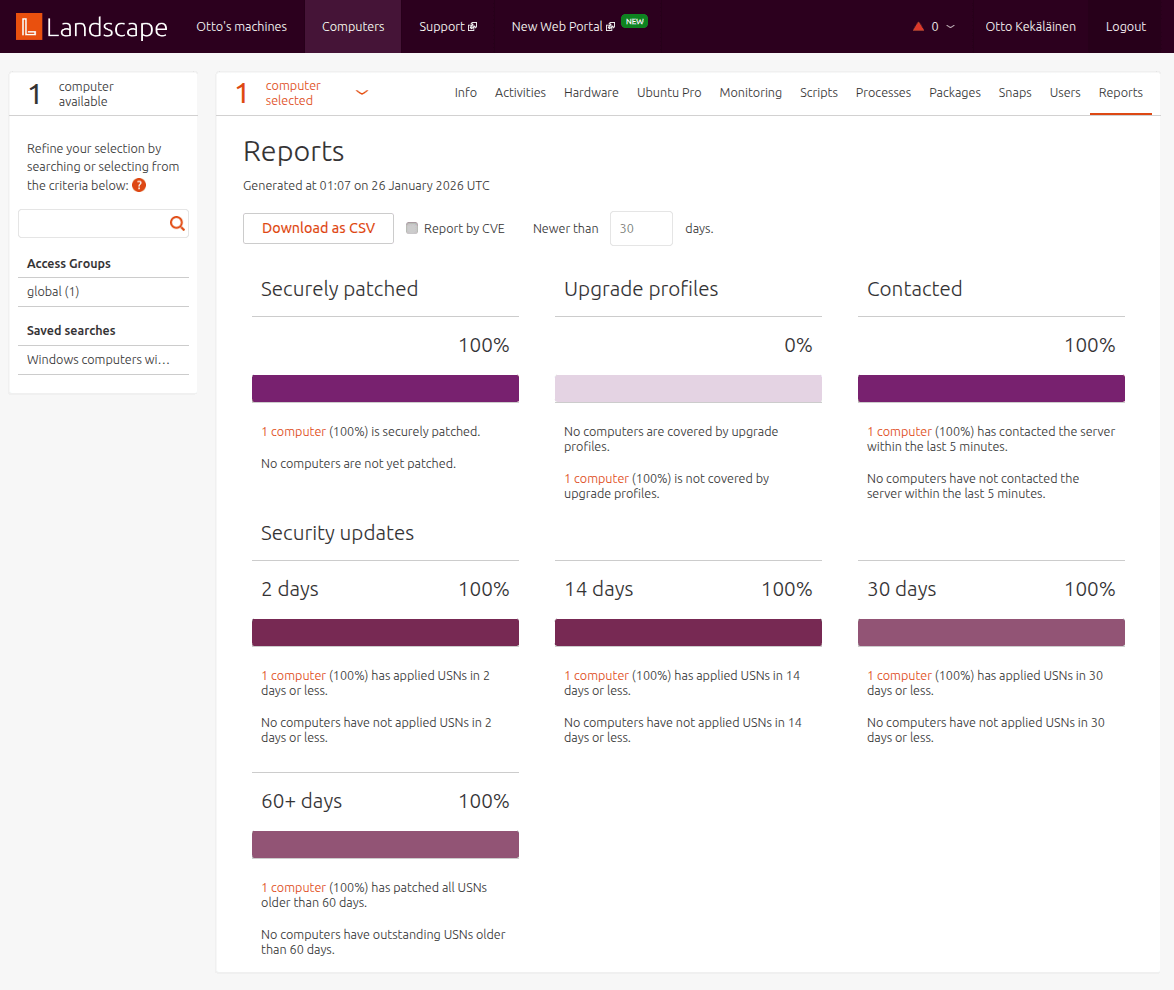
Using Landscape to manage multiple Ubuntu laptops Landscape portal reports showing security update status and resource utilization Landscape.canonical.com is a fleet management system that shows information like security update status and resource utilization for the computers you administer. Ubuntu Pro attached systems under one s account are not automatically visible in Landscape, but have to be enrolled in it. To enroll an Ubuntu Pro attached desktop/laptop to Landscape, first install the required package with sudo apt install landscape-client and then run sudo landscape-config --account-name <account name> to start the configuration wizard. You can find your account name in the Landscape portal. On the last wizard question Request a new registration for this computer now? [y/N] hit y to accept. If successful, the new computer will be visible on the Landscape portal page Pending computers , from where you can click to accept it. Landscape portal page showing pending computer registration If I had a large fleet of computers, Landscape might come in useful. Also it is obvious Landscape is intended primarily for managing server systems. For example, the default alarm trigger on systems being offline, which is common for laptops and desktop computers, is an alert-worthy thing only on server systems. It is good to know that Landscape exists, but on desktop systems I would probably skip it, and only stick to the security updates offered by Ubuntu Pro without using Landscape.

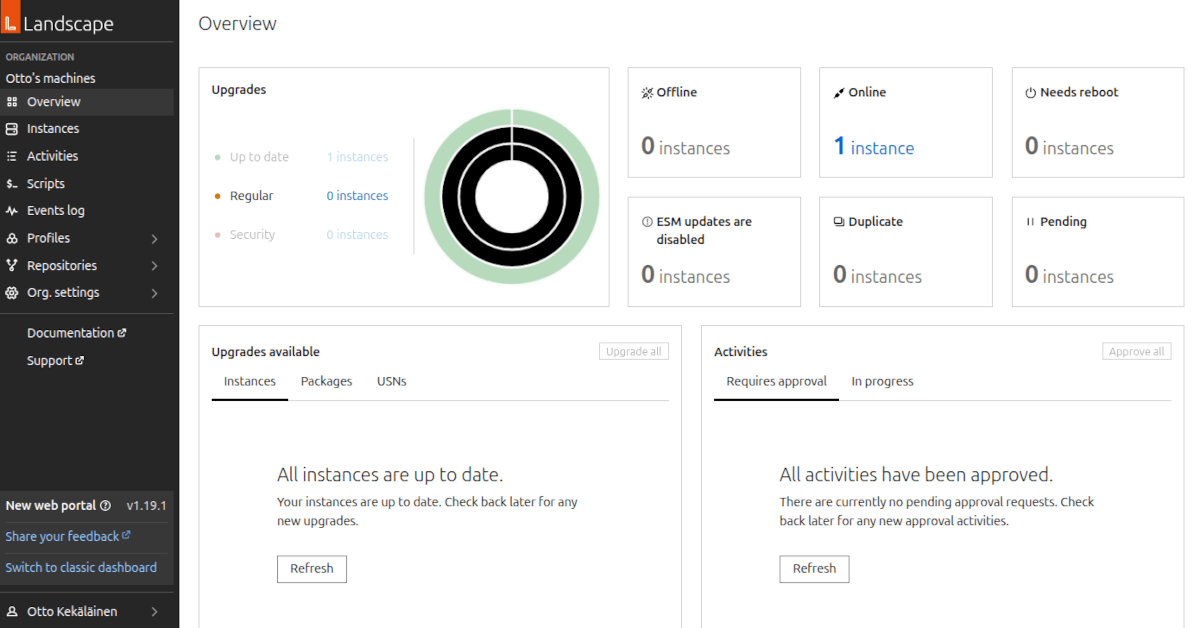
Landscape is evolving The screenshots above are from the current Landscape portal which I have been using so far. Recently Canonical has also launched a new web portal, with a fresh look: New Landscape dashboard with fresh look This shows Canonical is actively investing in the service and it is likely going to sit at the center of their business model for years to come.

Other offerings by Canonical for individual users Canonical, the company behind the world s most popular desktop Linux distribution Ubuntu, has been offering various commercial support services for corporate customers since the company launched back in 2005, but there haven t been any offerings available to individual users since Ubuntu One, with file syncing, a music store and more, was wound down back in 2014. Canonical and the other major Linux companies, Red Hat and SUSE, have always been very enterprise-oriented, presumably because achieving economies of scale is much easier when maintaining standardized corporate environments compared to dealing with a wide range of custom configurations that individual consumer customers might have. I remember some years ago Canonical offered desktop support under the Ubuntu Advantage product name, but the minimum subscription was for 5 desktop systems, which typically isn t an option for a regular home consumer. I am glad to see Ubuntu Pro is now available and I honestly hope people using Ubuntu will opt into it. The more customers it has, the more it incentivizes Canonical to develop and maintain features that are important for desktop and home users.

Pay for Linux because you can, not because you have to Open source is a great software development model for rapid innovation and adoption, but I don t think the business models in the space are yet quite mature. Users who get long-term value should participate more in funding open source maintenance work. While some donation platforms like GitHub Sponsors, OpenCollective and the like have gained popularity in recent years, none of them seem to generate recurring revenue comparable to the scale of how popular open source software is now in 2026. I welcome more paid schemes, such as Ubuntu Pro, as I believe it is beneficial for the whole ecosystem. I also expect more service providers to enter this space and experiment with different open source business models and various forms of decentralized funding. Linux and open source are primarily free as in speech, but as a side effect license fees are hard to enforce and many use Linux without paying for it. The more people, corporations and even countries rely on it to stay sovereign in the information society, the more users should think about how they want to use Linux and who they want to pay to maintain it and other critical parts of the open source ecosystem.

21 January 2026

Evgeni Golov: Validating cloud-init configs without being root

Somehow this whole DevOps thing is all about generating the wildest things from some (usually equally wild) template. And today we're gonna generate YAML from ERB, what could possibly go wrong?! Well, actually, quite a lot, so one wants to validate the generated result before using it to break systems at scale. The YAML we generate is a cloud-init cloud-config, and while checking that we generated a valid YAML document is easy (and we were already doing that), it would be much better if we could check that cloud-init can actually use it. Enter cloud-init schema, or so I thought. Turns out running cloud-init schema is rather broken without root privileges, as it tries to load a ton of information from the running system. This seems like a bug (or multiple), as the data should not be required for the validation of the schema itself. I've not found a way to disable that behavior. Luckily, I know Python. Enter evgeni-knows-better-and-can-write-python:
#!/usr/bin/env python3
import sys
from cloudinit.config.schema import get_schema, validate_cloudconfig_file, SchemaValidationError
try:
    valid = validate_cloudconfig_file(config_path=sys.argv[1], schema=get_schema())
    if not valid:
        raise RuntimeError("Schema is not valid")
except (SchemaValidationError, RuntimeError) as e:
    print(e)
    sys.exit(1)
The canonical1 version if this lives in the Foreman git repo, so go there if you think this will ever receive any updates. The hardest part was to understand thevalidate_cloudconfig_file API, as it will sometimes raise an SchemaValidationError, sometimes a RuntimeError and sometimes just return False. No idea why. But the above just turns it into a couple of printed lines and a non zero exit code, unless of course there are no problems, then you get peaceful silence.

19 January 2026

Russell Coker: Furilabs FLX1s

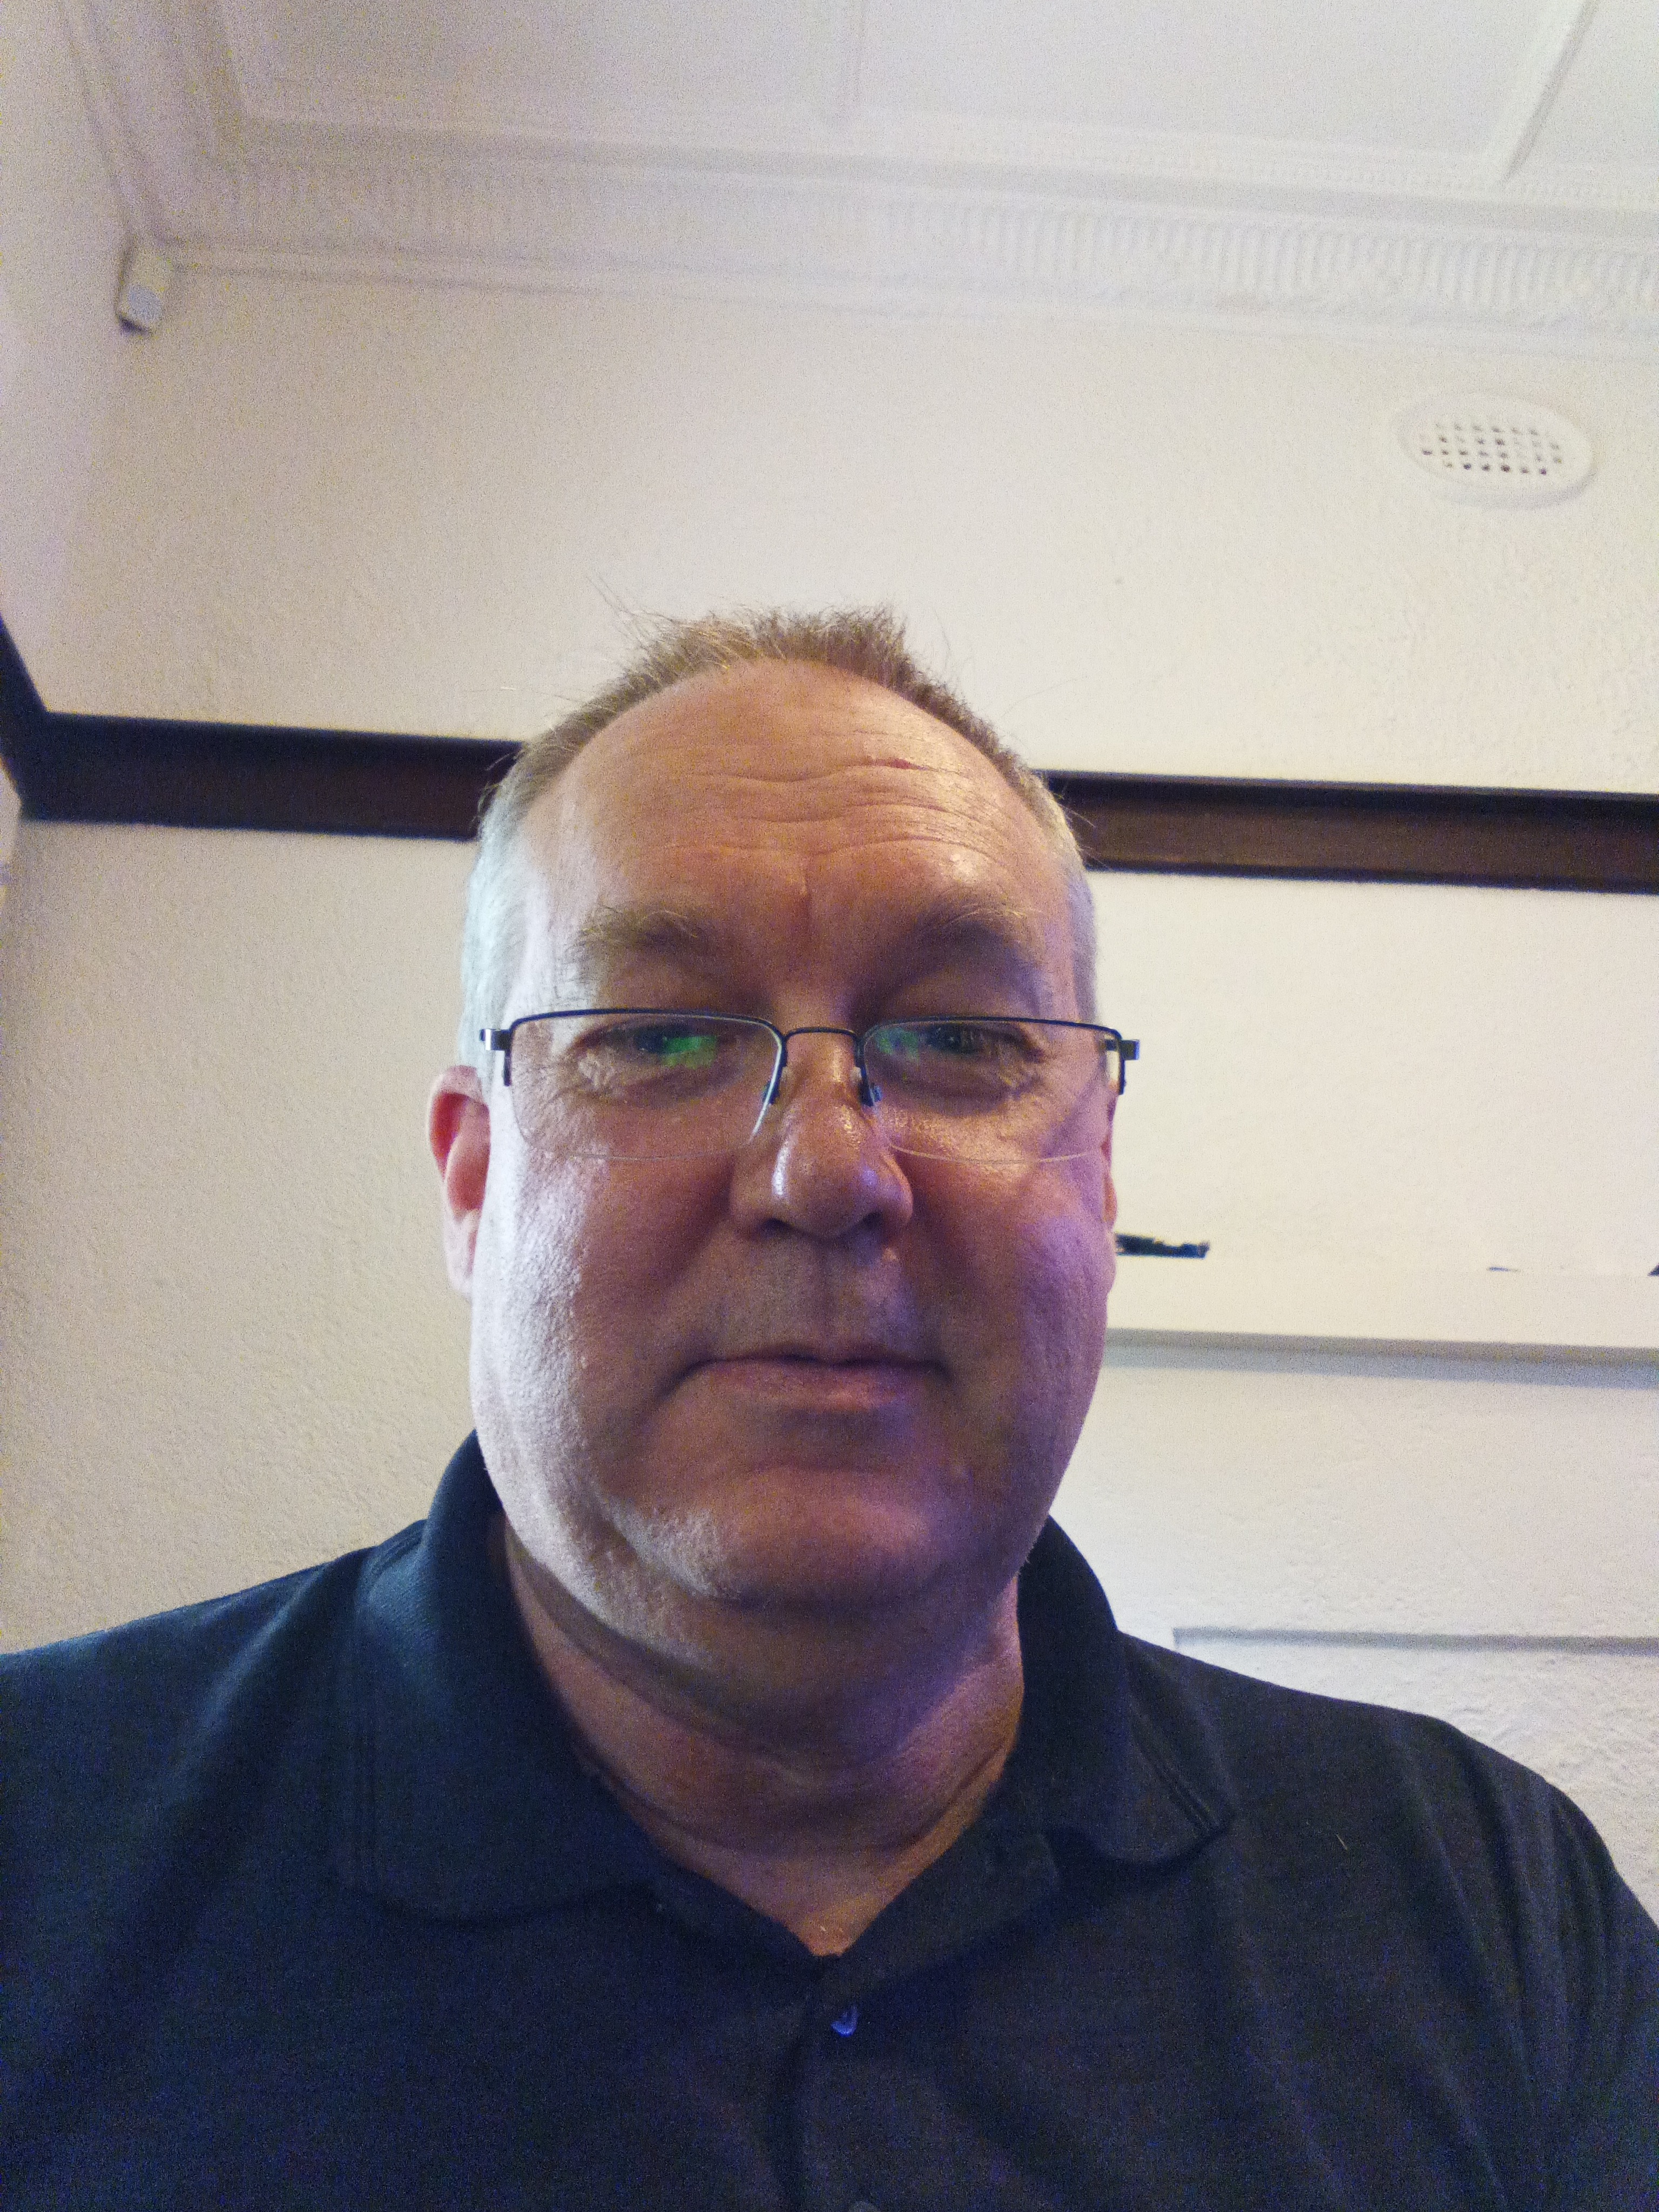
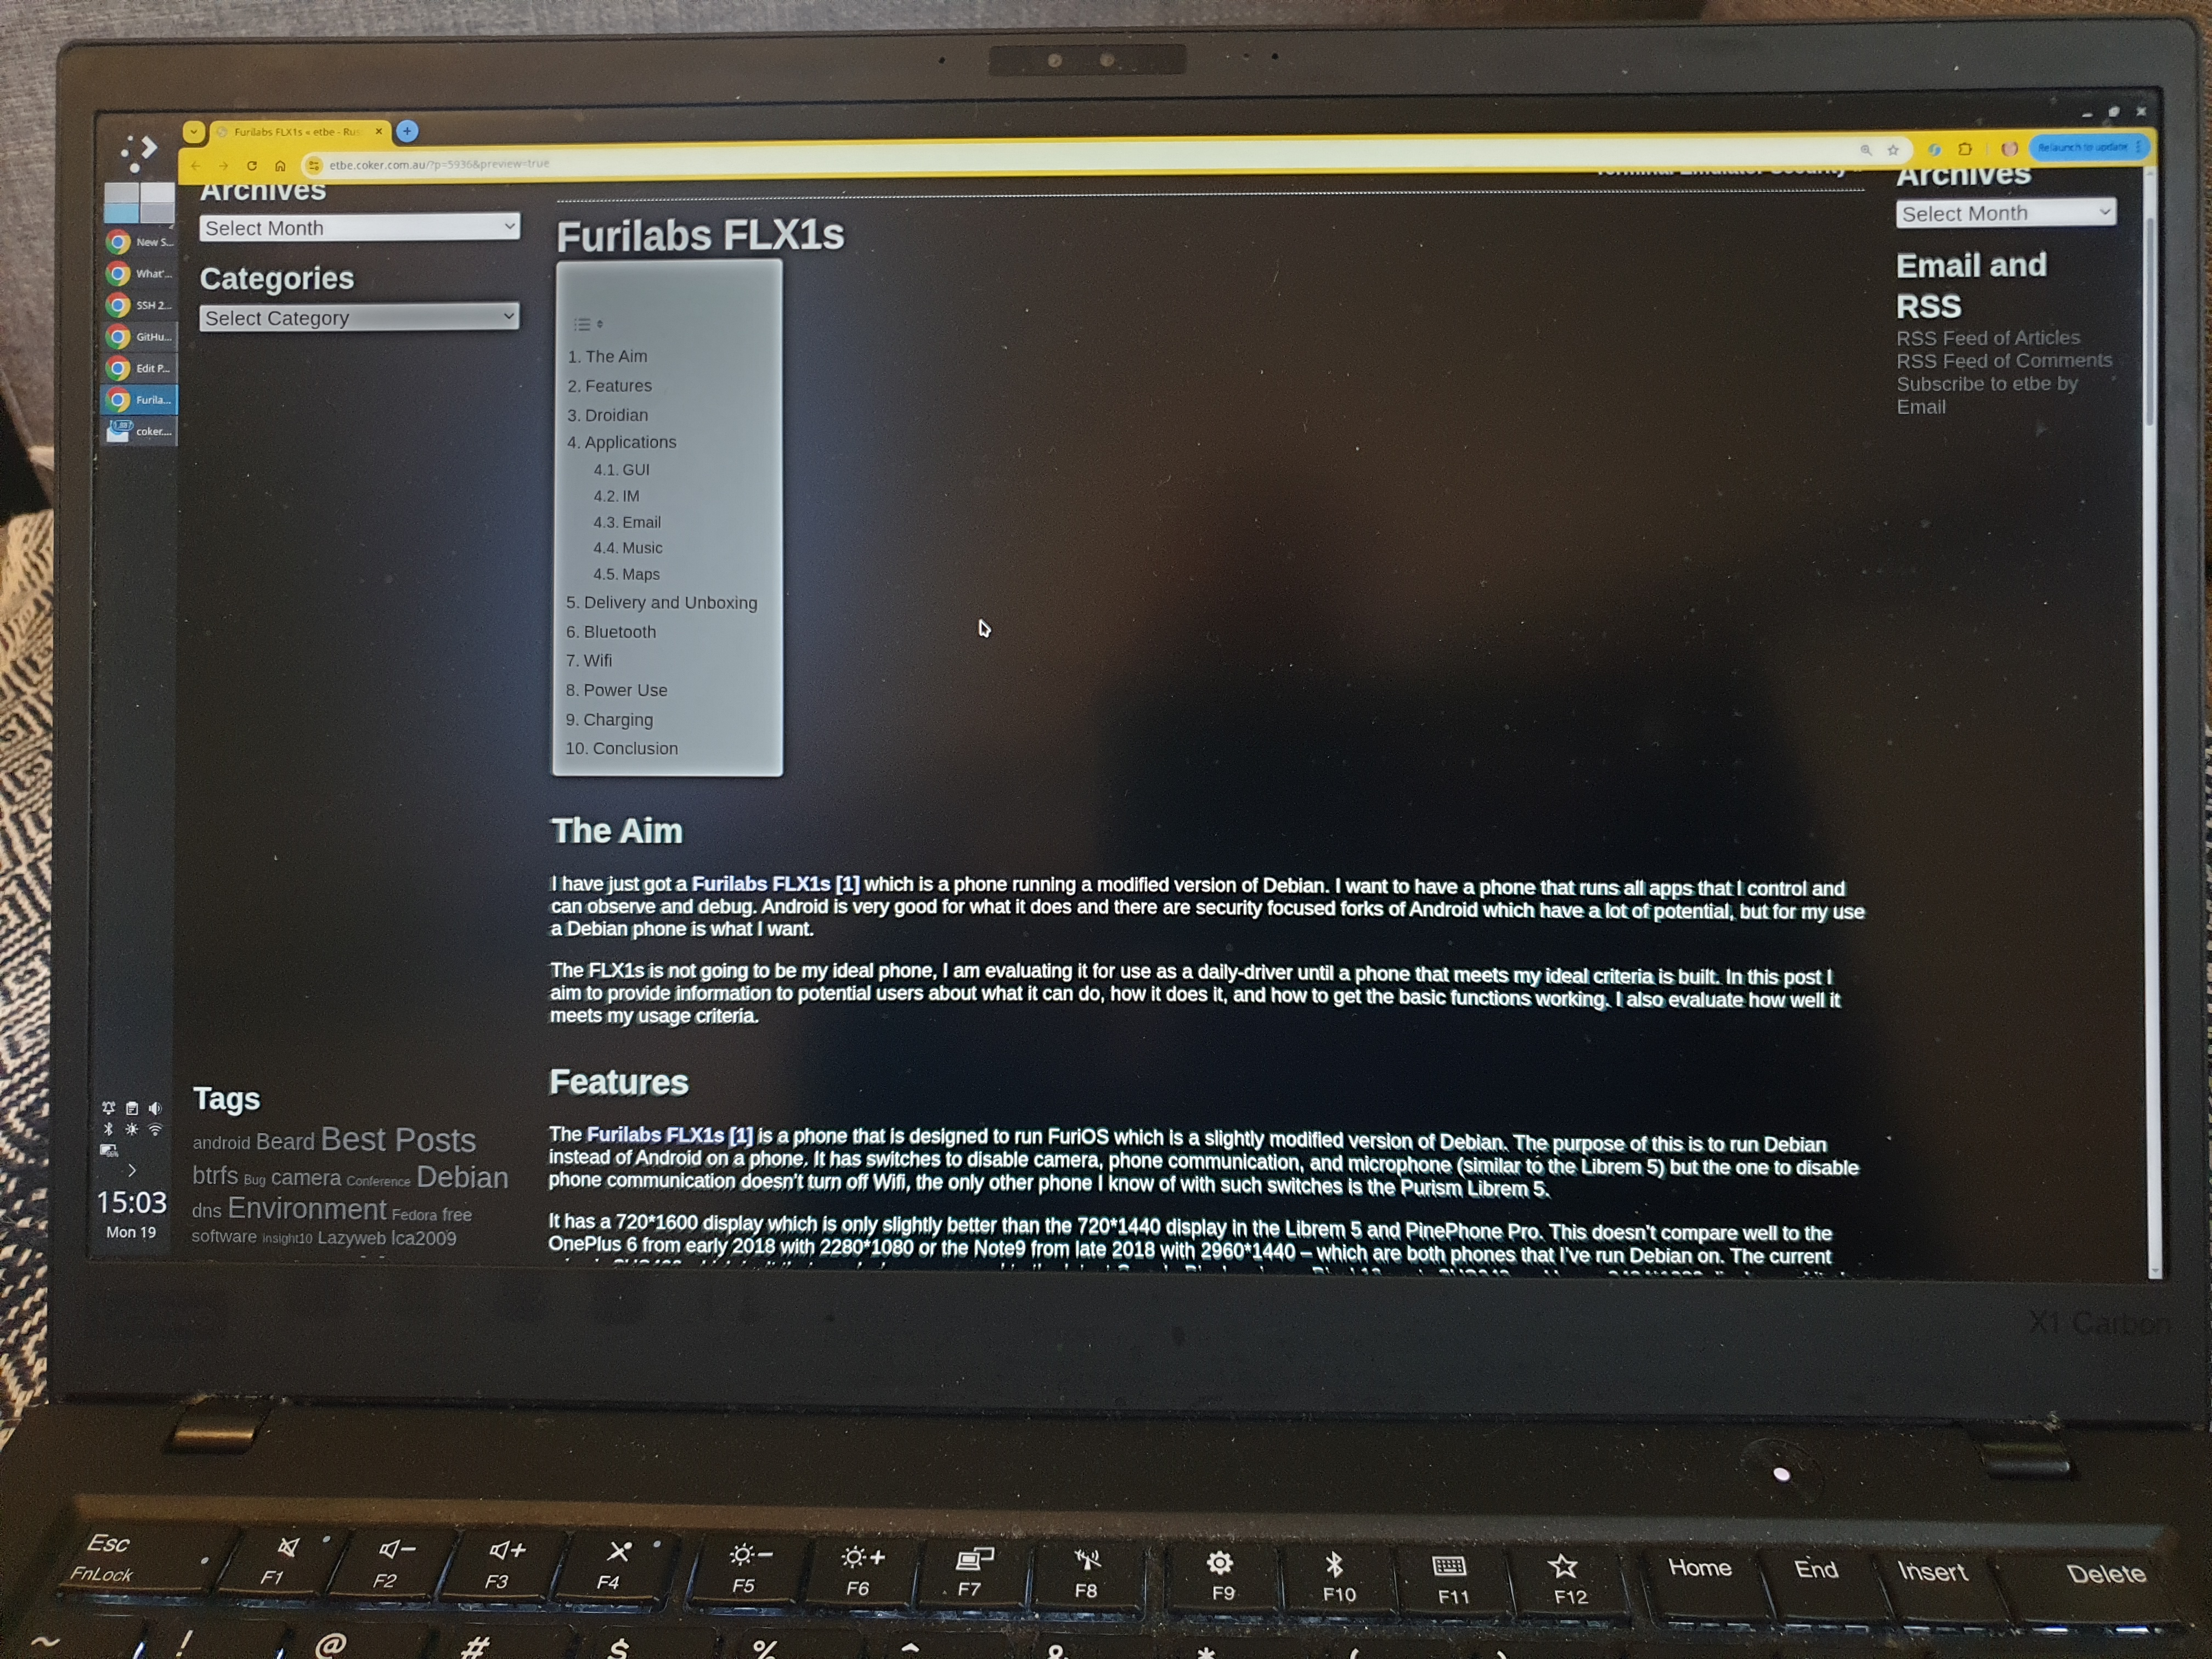
The Aim I have just got a Furilabs FLX1s [1] which is a phone running a modified version of Debian. I want to have a phone that runs all apps that I control and can observe and debug. Android is very good for what it does and there are security focused forks of Android which have a lot of potential, but for my use a Debian phone is what I want. The FLX1s is not going to be my ideal phone, I am evaluating it for use as a daily-driver until a phone that meets my ideal criteria is built. In this post I aim to provide information to potential users about what it can do, how it does it, and how to get the basic functions working. I also evaluate how well it meets my usage criteria. I am not anywhere near an average user. I don t think an average user would ever even see one unless a more technical relative showed one to them. So while this phone could be used by an average user I am not evaluating it on that basis. But of course the features of the GUI that make a phone usable for an average user will allow a developer to rapidly get past the beginning stages and into more complex stuff. Features The Furilabs FLX1s [1] is a phone that is designed to run FuriOS which is a slightly modified version of Debian. The purpose of this is to run Debian instead of Android on a phone. It has switches to disable camera, phone communication, and microphone (similar to the Librem 5) but the one to disable phone communication doesn t turn off Wifi, the only other phone I know of with such switches is the Purism Librem 5. It has a 720*1600 display which is only slightly better than the 720*1440 display in the Librem 5 and PinePhone Pro. This doesn t compare well to the OnePlus 6 from early 2018 with 2280*1080 or the Note9 from late 2018 with 2960*1440 which are both phones that I ve run Debian on. The current price is $US499 which isn t that good when compared to the latest Google Pixel series, a Pixel 10 costs $US649 and has a 2424*1080 display and it also has 12G of RAM while the FLX1s only has 8G. Another annoying thing is how rounded the corners are, it seems that round corners that cut off the content are a standard practice nowadays, in my collection of phones the latest one I found with hard right angles on the display was a Huawei Mate 10 Pro which was released in 2017. The corners are rounder than the Note 9, this annoys me because the screen is not high resolution by today s standards so losing the corners matters. The default installation is Phosh (the GNOME shell for phones) and it is very well configured. Based on my experience with older phone users I think I could give a phone with this configuration to a relative in the 70+ age range who has minimal computer knowledge and they would be happy with it. Additionally I could set it up to allow ssh login and instead of going through the phone support thing of trying to describe every GUI setting to click on based on a web page describing menus for the version of Android they are running I could just ssh in and run diff on the .config directory to find out what they changed. Furilabs have done a very good job of setting up the default configuration, while Debian developers deserve a lot of credit for packaging the apps the Furilabs people have chosen a good set of default apps to install to get it going and appear to have made some noteworthy changes to some of them. Droidian The OS is based on Android drivers (using the same techniques as Droidian [2]) and the storage device has the huge number of partitions you expect from Android as well as a 110G Ext4 filesystem for the main OS. The first issue with the Droidian approach of using an Android kernel and containers for user space code to deal with drivers is that it doesn t work that well. There are 3 D state processes (uninterrupteable sleep which usually means a kernel bug if the process remains in that state) after booting and doing nothing special. My tests running Droidian on the Note 9 also had D state processes, in this case they are D state kernel threads (I can t remember if the Note 9 had regular processes or kernel threads stuck in D state). It is possible for a system to have full functionality in spite of some kernel threads in D state but generally it s a symptom of things not working as well as you would hope. The design of Droidian is inherently fragile. You use a kernel and user space code from Android and then use Debian for the rest. You can t do everything the Android way (with the full OS updates etc) and you also can t do everything the Debian way. The TOW Boot functionality in the PinePhone Pro is really handy for recovery [3], it allows the internal storage to be accessed as a USB mass storage device. The full Android setup with ADB has some OK options for recovery, but part Android and part Debian has less options. While it probably is technically possible to do the same things in regard to OS repair and reinstall the fact that it s different from most other devices means that fixes can t be done in the same way. Applications GUI The system uses Phosh and Phoc, the GNOME system for handheld devices. It s a very different UI from Android, I prefer Android but it is usable with Phosh. IM Chatty works well for Jabber (XMPP) in my tests. It supports Matrix which I didn t test because I don t desire the same program doing Matrix and Jabber and because Matrix is a heavy protocol which establishes new security keys for each login so I don t want to keep logging in on new applications. Chatty also does SMS but I couldn t test that without the SIM caddy. I use Nheko for Matrix which has worked very well for me on desktops and laptops running Debian. Email I am currently using Geary for email. It works reasonably well but is lacking proper management of folders, so I can t just subscribe to the important email on my phone so that bandwidth isn t wasted on less important email (there is a GNOME gitlab issue about this see the Debian Wiki page about Mobile apps [4]). Music Music playing isn t a noteworthy thing for a desktop or laptop, but a good music player is important for phone use. The Lollypop music player generally does everything you expect along with support for all the encoding formats including FLAC0 a major limitation of most Android music players seems to be lack of support for some of the common encoding formats. Lollypop has it s controls for pause/play and going forward and backward one track on the lock screen. Maps The installed map program is gnome-maps which works reasonably well. It gets directions via the Graphhopper API [5]. One thing we really need is a FOSS replacement for Graphhopper in GNOME Maps. Delivery and Unboxing I received my FLX1s on the 13th of Jan [1]. I had paid for it on the 16th of Oct but hadn t received the email with the confirmation link so the order had been put on hold. But after I contacted support about that on the 5th of Jan they rapidly got it to me which was good. They also gave me a free case and screen protector to apologise, I don t usually use screen protectors but in this case it might be useful as the edges of the case don t even extend 0.5mm above the screen. So if it falls face down the case won t help much. When I got it there was an open space at the bottom where the caddy for SIMs is supposed to be. So I couldn t immediately test VoLTE functionality. The contact form on their web site wasn t working when I tried to report that and the email for support was bouncing. Bluetooth As a test of Bluetooth I connected it to my Nissan LEAF which worked well for playing music and I connected it to several Bluetooth headphones. My Thinkpad running Debian/Trixie doesn t connect to the LEAF and to headphones which have worked on previous laptops running Debian and Ubuntu. A friend s laptop running Debian/Trixie also wouldn t connect to the LEAF so I suspect a bug in Trixie, I need to spend more time investigating this. Wifi Currently 5GHz wifi doesn t work, this is a software bug that the Furilabs people are working on. 2.4GHz wifi works fine. I haven t tested running a hotspot due to being unable to get 4G working as they haven t yet shipped me the SIM caddy. Docking This phone doesn t support DP Alt-mode or Thunderbolt docking so it can t drive an external monitor. This is disappointing, Samsung phones and tablets have supported such things since long before USB-C was invented. Samsung DeX is quite handy for Android devices and that type feature is much more useful on a device running Debian than on an Android device. Camera The camera works reasonably well on the FLX1s. Until recently for the Librem 5 the camera didn t work and the camera on my PinePhone Pro currently doesn t work. Here are samples of the regular camera and the selfie camera on the FLX1s and the Note 9. I think this shows that the camera is pretty decent. The selfie looks better and the front camera is worse for the relatively close photo of a laptop screen taking photos of computer screens is an important part of my work but I can probably work around that. I wasn t assessing this camera t find out if it s great, just to find out if I have the sorts of problems I had before and it just worked. The Samsung Galaxy Note series of phones has always had decent specs including good cameras. Even though the Note 9 is old comparing to it is a respectable performance. The lighting was poor for all photos. FLX1s
Note 9
Power Use In 93 minutes having the PinePhone Pro, Librem 5, and FLX1s online with open ssh sessions from my workstation the PinePhone Pro went from 100% battery to 26%, the Librem 5 went from 95% to 69%, and the FLX1s went from 100% to 99%. The battery discharge rate of them was reported as 3.0W, 2.6W, and 0.39W respectively. Based on having a 16.7Wh battery 93 minutes of use should have been close to 4% battery use, but in any case all measurements make it clear that the FLX1s will have a much longer battery life. Including the measurement of just putting my fingers on the phones and feeling the temperature (FLX1s felt cool and the others felt hot). The PinePhone Pro and the Librem 5 have an optional Caffeine mode which I enabled for this test, without that enabled the phone goes into a sleep state and disconnects from Wifi. So those phones would use much less power with caffeine mode enabled, but they also couldn t get fast response to notifications etc. I found the option to enable a Caffeine mode switch on the FLX1s but the power use was reported as being the same both with and without it. Charging One problem I found with my phone is that in every case it takes 22 seconds to negotiate power. Even when using straight USB charging (no BC or PD) it doesn t draw any current for 22 seconds. When I connect it it will stay at 5V and varying between 0W and 0.1W (current rounded off to zero) for 22 seconds or so and then start charging. After the 22 second display the phone will make the tick sound indicating that it s charging and the power meter will measure that it s drawing some current. I added the table from my previous post about phone charging speed [6] with an extra row for the FLX1s. For charging from my PC USB ports the results were the worst ever, the port that does BC did not work at all it was looping trying to negotiate after a 22 second negotiation delay the port would turn off. The non-BC port gave only 2.4W which matches the 2.5W given by the spec for a High-power device which is what that port is designed to give. In a discussion on the Purism forum about the Librem5 charging speed one of their engineers told me that the reason why their phone would draw 2A from that port was because the cable was identifying itself as a USB-C port not a High-power device port. But for some reason out of the 7 phones I tested the FLX1s and the One Plus 6 are the only ones to limit themselves to what the port is apparently supposed to do. Also the One Plus 6 charges slowly on every power supply so I don t know if it is obeying the spec or just sucking. On a cheap AliExpress charger the FLX1s gets 5.9V and on a USB battery it gets 5.8V. Out of all 42 combinations of device and charger I tested these were the only ones to involve more than 5.1V but less than 9V. I welcome comments suggesting an explanation. The case that I received has a hole for the USB-C connector that isn t wide enough for the plastic surrounds on most of my USB-C cables (including the Dell dock). Also to make a connection requires a fairly deep insertion (deeper than the One Plus 6 or the Note 9). So without adjustment I have to take the case off to charge it. It s no big deal to adjust the hole (I have done it with other cases) but it s an annoyance.
Phone Top z640 Bottom Z640 Monitor Ali Charger Dell Dock Battery Best Worst
FLX1s FAIL 5.0V 0.49A 2.4W 4.8V 1.9A 9.0W 5.9V 1.8A 11W 4.8V 2.1A 10W 5.8V 2.1A 12W 5.8V 2.1A 12W 5.0V 0.49A 2.4W
Note9 4.8V 1.0A 5.2W 4.8V 1.6A 7.5W 4.9V 2.0A 9.5W 5.1V 1.9A 9.7W 4.8V 2.1A 10W 5.1V 2.1A 10W 5.1V 2.1A 10W 4.8V 1.0A 5.2W
Pixel 7 pro 4.9V 0.80A 4.2W 4.8V 1.2A 5.9W 9.1V 1.3A 12W 9.1V 1.2A 11W 4.9V 1.8A 8.7W 9.0V 1.3A 12W 9.1V 1.3A 12W 4.9V 0.80A 4.2W
Pixel 8 4.7V 1.2A 5.4W 4.7V 1.5A 7.2W 8.9V 2.1A 19W 9.1V 2.7A 24W 4.8V 2.3A 11.0W 9.1V 2.6A 24W 9.1V 2.7A 24W 4.7V 1.2A 5.4W
PPP 4.7V 1.2A 6.0W 4.8V 1.3A 6.8W 4.9V 1.4A 6.6W 5.0V 1.2A 5.8W 4.9V 1.4A 5.9W 5.1V 1.2A 6.3W 4.8V 1.3A 6.8W 5.0V 1.2A 5.8W
Librem 5 4.4V 1.5A 6.7W 4.6V 2.0A 9.2W 4.8V 2.4A 11.2W 12V 0.48A 5.8W 5.0V 0.56A 2.7W 5.1V 2.0A 10W 4.8V 2.4A 11.2W 5.0V 0.56A 2.7W
OnePlus6 5.0V 0.51A 2.5W 5.0V 0.50A 2.5W 5.0V 0.81A 4.0W 5.0V 0.75A 3.7W 5.0V 0.77A 3.7W 5.0V 0.77A 3.9W 5.0V 0.81A 4.0W 5.0V 0.50A 2.5W
Best 4.4V 1.5A 6.7W 4.6V 2.0A 9.2W 8.9V 2.1A 19W 9.1V 2.7A 24W 4.8V 2.3A 11.0W 9.1V 2.6A 24W
Conclusion The Furilabs support people are friendly and enthusiastic but my customer experience wasn t ideal. It was good that they could quickly respond to my missing order status and the missing SIM caddy (which I still haven t received but believe is in the mail) but it would be better if such things just didn t happen. The phone is quite user friendly and could be used by a novice. I paid $US577 for the FLX1s which is $AU863 by today s exchange rates. For comparison I could get a refurbished Pixel 9 Pro Fold for $891 from Kogan (the major Australian mail-order company for technology) or a refurbished Pixel 9 Pro XL for $842. The Pixel 9 series has security support until 2031 which is probably longer than you can expect a phone to be used without being broken. So a phone with a much higher resolution screen that s only one generation behind the latest high end phones and is refurbished will cost less. For a brand new phone a Pixel 8 Pro which has security updates until 2030 costs $874 and a Pixel 9A which has security updates until 2032 costs $861. Doing what the Furilabs people have done is not a small project. It s a significant amount of work and the prices of their products need to cover that. I m not saying that the prices are bad, just that economies of scale and the large quantity of older stock makes the older Google products quite good value for money. The new Pixel phones of the latest models are unreasonably expensive. The Pixel 10 is selling new from Google for $AU1,149 which I consider a ridiculous price that I would not pay given the market for used phones etc. If I had a choice of $1,149 or a feature phone I d pay $1,149. But the FLX1s for $863 is a much better option for me. If all I had to choose from was a new Pixel 10 or a FLX1s for my parents I d get them the FLX1s. For a FOSS developer a FLX1s could be a mobile test and development system which could be lent to a relative when their main phone breaks and the replacement is on order. It seems to be fit for use as a commodity phone. Note that I give this review on the assumption that SMS and VoLTE will just work, I haven t tested them yet. The UI on the FLX1s is functional and easy enough for a new user while allowing an advanced user to do the things they desire. I prefer the Android style and the Plasma Mobile style is closer to Android than Phosh is, but changing it is something I can do later. Generally I think that the differences between UIs matter more when on a desktop environment that could be used for more complex tasks than on a phone which limits what can be done by the size of the screen. I am comparing the FLX1s to Android phones on the basis of what technology is available. But most people who would consider buying this phone will compare it to the PinePhone Pro and the Librem 5 as they have similar uses. The FLX1s beats both those phones handily in terms of battery life and of having everything just work. But it has the most non free software of the three and the people who want the $2000 Librem 5 that s entirely made in the US won t want the FLX1s. This isn t the destination for Debian based phones, but it s a good step on the way to it and I don t think I ll regret this purchase.

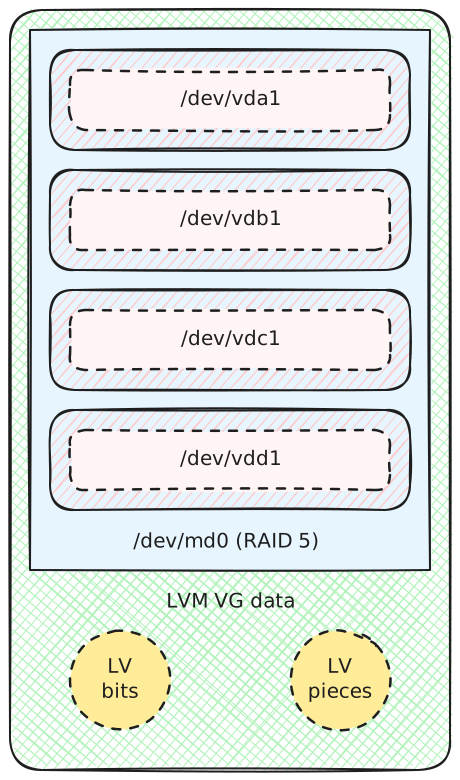
Vincent Bernat: RAID 5 with mixed-capacity disks on Linux

Standard RAID solutions waste space when disks have different sizes. Linux software RAID with LVM uses the full capacity of each disk and lets you grow storage by replacing one or two disks at a time.1 We start with four disks of equal size:
$ lsblk -Mo NAME,TYPE,SIZE
NAME TYPE  SIZE
vda  disk  101M
vdb  disk  101M
vdc  disk  101M
vdd  disk  101M
We create one partition on each of them:
$ sgdisk --zap-all --new=0:0:0 -t 0:fd00 /dev/vda
$ sgdisk --zap-all --new=0:0:0 -t 0:fd00 /dev/vdb
$ sgdisk --zap-all --new=0:0:0 -t 0:fd00 /dev/vdc
$ sgdisk --zap-all --new=0:0:0 -t 0:fd00 /dev/vdd
$ lsblk -Mo NAME,TYPE,SIZE
NAME   TYPE  SIZE
vda    disk  101M
 vda1 part  100M
vdb    disk  101M
 vdb1 part  100M
vdc    disk  101M
 vdc1 part  100M
vdd    disk  101M
 vdd1 part  100M
We set up a RAID 5 device by assembling the four partitions:2
$ mdadm --create /dev/md0 --level=raid5 --bitmap=internal --raid-devices=4 \
>   /dev/vda1 /dev/vdb1 /dev/vdc1 /dev/vdd1
$ lsblk -Mo NAME,TYPE,SIZE
    NAME          TYPE    SIZE
    vda           disk    101M
   vda1        part    100M
    vdb           disk    101M
   vdb1        part    100M
    vdc           disk    101M
   vdc1        part    100M
    vdd           disk    101M
   vdd1        part    100M
  md0           raid5 292.5M
$ cat /proc/mdstat
md0 : active raid5 vdd1[4] vdc1[2] vdb1[1] vda1[0]
      299520 blocks super 1.2 level 5, 512k chunk, algorithm 2 [4/4] [UUUU]
      bitmap: 0/1 pages [0KB], 65536KB chunk
We use LVM to create logical volumes on top of the RAID 5 device.
$ pvcreate /dev/md0
  Physical volume "/dev/md0" successfully created.
$ vgcreate data /dev/md0
  Volume group "data" successfully created
$ lvcreate -L 100m -n bits data
  Logical volume "bits" created.
$ lvcreate -L 100m -n pieces data
  Logical volume "pieces" created.
$ mkfs.ext4 -q /dev/data/bits
$ mkfs.ext4 -q /dev/data/pieces
$ lsblk -Mo NAME,TYPE,SIZE
    NAME          TYPE    SIZE
    vda           disk    101M
   vda1        part    100M
    vdb           disk    101M
   vdb1        part    100M
    vdc           disk    101M
   vdc1        part    100M
    vdd           disk    101M
   vdd1        part    100M
  md0           raid5 292.5M
     data-bits   lvm     100M
     data-pieces lvm     100M
$ vgs
  VG   #PV #LV #SN Attr   VSize   VFree
  data   1   2   0 wz--n- 288.00m 88.00m
This gives us the following setup:
One RAID 5 device built from four partitions from four disks of equal capacity. The RAID device is part of an LVM volume group with two logical volumes.
RAID 5 setup with disks of equal capacity
We replace /dev/vda with a bigger disk. We add it back to the RAID 5 array after copying the partitions from /dev/vdb:
$ cat /proc/mdstat
md0 : active (auto-read-only) raid5 vdb1[1] vdd1[4] vdc1[2]
      299520 blocks super 1.2 level 5, 512k chunk, algorithm 2 [4/3] [_UUU]
      bitmap: 0/1 pages [0KB], 65536KB chunk
$ sgdisk --replicate=/dev/vda /dev/vdb
$ sgdisk --randomize-guids /dev/vda
$ mdadm --manage /dev/md0 --add /dev/vda1
$ cat /proc/mdstat
md0 : active raid5 vda1[5] vdb1[1] vdd1[4] vdc1[2]
      299520 blocks super 1.2 level 5, 512k chunk, algorithm 2 [4/4] [UUUU]
      bitmap: 0/1 pages [0KB], 65536KB chunk
We do not use the additional capacity: this setup would not survive the loss of /dev/vda because we have no spare capacity. We need a second disk replacement, like /dev/vdb:
$ cat /proc/mdstat
md0 : active (auto-read-only) raid5 vda1[5] vdd1[4] vdc1[2]
      299520 blocks super 1.2 level 5, 512k chunk, algorithm 2 [4/3] [U_UU]
      bitmap: 0/1 pages [0KB], 65536KB chunk
$ sgdisk --replicate=/dev/vdb /dev/vdc
$ sgdisk --randomize-guids /dev/vdb
$ mdadm --manage /dev/md0 --add /dev/vdb1
$ cat /proc/mdstat
md0 : active raid5 vdb1[6] vda1[5] vdd1[4] vdc1[2]
      299520 blocks super 1.2 level 5, 512k chunk, algorithm 2 [4/4] [UUUU]
      bitmap: 0/1 pages [0KB], 65536KB chunk
We create a new RAID 1 array by using the free space on /dev/vda and /dev/vdb:
$ sgdisk --new=0:0:0 -t 0:fd00 /dev/vda
$ sgdisk --new=0:0:0 -t 0:fd00 /dev/vdb
$ mdadm --create /dev/md1 --level=raid1 --bitmap=internal --raid-devices=2 \
>   /dev/vda2 /dev/vdb2
$ cat /proc/mdstat
md1 : active raid1 vdb2[1] vda2[0]
      101312 blocks super 1.2 [2/2] [UU]
      bitmap: 0/1 pages [0KB], 65536KB chunk
md0 : active raid5 vdb1[6] vda1[5] vdd1[4] vdc1[2]
      299520 blocks super 1.2 level 5, 512k chunk, algorithm 2 [4/4] [UUUU]
      bitmap: 0/1 pages [0KB], 65536KB chunk
We add /dev/md1 to the volume group:
$ pvcreate /dev/md1
  Physical volume "/dev/md1" successfully created.
$ vgextend data /dev/md1
  Volume group "data" successfully extended
$ vgs
  VG   #PV #LV #SN Attr   VSize   VFree
  data   2   2   0 wz--n- 384.00m 184.00m
$  lsblk -Mo NAME,TYPE,SIZE
       NAME          TYPE    SIZE
       vda           disk    201M
      vda1        part    100M
     vda2        part    100M
       vdb           disk    201M
      vdb1        part    100M
     vdb2        part    100M
  md1           raid1  98.9M
       vdc           disk    101M
      vdc1        part    100M
       vdd           disk    101M
      vdd1        part    100M
     md0           raid5 292.5M
        data-bits   lvm     100M
        data-pieces lvm     100M
This gives us the following setup:3
One RAID 5 device built from four partitions and one RAID 1 device built from two partitions. The two last disks are smaller. The two RAID devices are part of a single LVM volume group.
Setup mixing both RAID 1 and RAID 5
We extend our capacity further by replacing /dev/vdc:
$ cat /proc/mdstat
md1 : active (auto-read-only) raid1 vda2[0] vdb2[1]
      101312 blocks super 1.2 [2/2] [UU]
      bitmap: 0/1 pages [0KB], 65536KB chunk
md0 : active (auto-read-only) raid5 vda1[5] vdd1[4] vdb1[6]
      299520 blocks super 1.2 level 5, 512k chunk, algorithm 2 [4/3] [UU_U]
      bitmap: 0/1 pages [0KB], 65536KB chunk
$ sgdisk --replicate=/dev/vdc /dev/vdb
$ sgdisk --randomize-guids /dev/vdc
$ mdadm --manage /dev/md0 --add /dev/vdc1
$ cat /proc/mdstat
md1 : active (auto-read-only) raid1 vda2[0] vdb2[1]
      101312 blocks super 1.2 [2/2] [UU]
      bitmap: 0/1 pages [0KB], 65536KB chunk
md0 : active raid5 vdc1[7] vda1[5] vdd1[4] vdb1[6]
      299520 blocks super 1.2 level 5, 512k chunk, algorithm 2 [4/4] [UUUU]
      bitmap: 0/1 pages [0KB], 65536KB chunk
Then, we convert /dev/md1 from RAID 1 to RAID 5:
$ mdadm --grow /dev/md1 --level=5 --raid-devices=3 --add /dev/vdc2
mdadm: level of /dev/md1 changed to raid5
mdadm: added /dev/vdc2
$ cat /proc/mdstat
md1 : active raid5 vdc2[2] vda2[0] vdb2[1]
      202624 blocks super 1.2 level 5, 64k chunk, algorithm 2 [3/3] [UUU]
      bitmap: 0/1 pages [0KB], 65536KB chunk
md0 : active raid5 vdc1[7] vda1[5] vdd1[4] vdb1[6]
      299520 blocks super 1.2 level 5, 512k chunk, algorithm 2 [4/4] [UUUU]
      bitmap: 0/1 pages [0KB], 65536KB chunk
$ pvresize /dev/md1
$ vgs
  VG   #PV #LV #SN Attr   VSize   VFree
  data   2   2   0 wz--n- 482.00m 282.00m
This gives us the following layout:
Two RAID 5 devices built from four disks of different sizes. The last disk is smaller and contains only one partition, while the others have two partitions: one for /dev/md0 and one for /dev/md1. The two RAID devices are part of a single LVM volume group.
RAID 5 setup with mixed-capacity disks using partitions and LVM
We further extend our capacity by replacing /dev/vdd:
$ cat /proc/mdstat
md0 : active (auto-read-only) raid5 vda1[5] vdc1[7] vdb1[6]
      299520 blocks super 1.2 level 5, 512k chunk, algorithm 2 [4/3] [UUU_]
      bitmap: 0/1 pages [0KB], 65536KB chunk
md1 : active (auto-read-only) raid5 vda2[0] vdc2[2] vdb2[1]
      202624 blocks super 1.2 level 5, 64k chunk, algorithm 2 [3/3] [UUU]
      bitmap: 0/1 pages [0KB], 65536KB chunk
$ sgdisk --replicate=/dev/vdd /dev/vdc
$ sgdisk --randomize-guids /dev/vdd
$ mdadm --manage /dev/md0 --add /dev/vdd1
$ cat /proc/mdstat
md0 : active raid5 vdd1[4] vda1[5] vdc1[7] vdb1[6]
      299520 blocks super 1.2 level 5, 512k chunk, algorithm 2 [4/4] [UUUU]
      bitmap: 0/1 pages [0KB], 65536KB chunk
md1 : active (auto-read-only) raid5 vda2[0] vdc2[2] vdb2[1]
      202624 blocks super 1.2 level 5, 64k chunk, algorithm 2 [3/3] [UUU]
      bitmap: 0/1 pages [0KB], 65536KB chunk
We grow the second RAID 5 array:
$ mdadm --grow /dev/md1 --raid-devices=4 --add /dev/vdd2
mdadm: added /dev/vdd2
$ cat /proc/mdstat
md0 : active raid5 vdd1[4] vda1[5] vdc1[7] vdb1[6]
      299520 blocks super 1.2 level 5, 512k chunk, algorithm 2 [4/4] [UUUU]
      bitmap: 0/1 pages [0KB], 65536KB chunk
md1 : active raid5 vdd2[3] vda2[0] vdc2[2] vdb2[1]
      303936 blocks super 1.2 level 5, 64k chunk, algorithm 2 [4/4] [UUUU]
      bitmap: 0/1 pages [0KB], 65536KB chunk
$ pvresize /dev/md1
$ vgs
  VG   #PV #LV #SN Attr   VSize   VFree
  data   2   2   0 wz--n- 580.00m 380.00m
$ lsblk -Mo NAME,TYPE,SIZE
       NAME          TYPE    SIZE
       vda           disk    201M
      vda1        part    100M
     vda2        part    100M
       vdb           disk    201M
      vdb1        part    100M
     vdb2        part    100M
       vdc           disk    201M
      vdc1        part    100M
     vdc2        part    100M
       vdd           disk    301M
      vdd1        part    100M
      vdd2        part    100M
     md0           raid5 292.5M
        data-bits   lvm     100M
        data-pieces lvm     100M
  md1           raid5 296.8M
You can continue by replacing each disk one by one using the same steps.

  1. This is the same approach Synology uses for its Hybrid RAID and what the OpenMediaVault community calls a Sliced Hybrid RAID.
  2. Write-intent bitmaps speed up recovery of the RAID array after a power failure by marking unsynchronized regions as dirty. They have an impact on performance, but I did not measure it myself. An alternative is to use a partial parity log with --consistency-policy=ppl.
  3. In the lsblk output, /dev/md1 appears unused because the logical volumes do not use any space from it yet. Once you create more logical volumes or extend them, lsblk will reflect the usage.

17 January 2026

Jonathan Dowland: Honest Jon's lightly-used Starships

No man s Sky (or as it s known in our house, "spaceship game") is a space exploration/sandbox game that was originally released 10 years ago. Back then I tried it on my brother s PS4 but I couldn t get into it. In 2022 it launched for the Nintendo Switch1 and the game finally clicked for me. I play it very casually. I mostly don t play at all, except sometimes when there are time-limited expeditions running, which I find refreshing, and usually have some exclusives as a reward for play. One of the many things you can do in the game is collect star ships. I started keeping a list of notable ones I ve found, and I ve decided to occasionally blog about them.
The Horizon Vector NX spaceship
The Horizon Vector NX is a small sporty ship that players on Nintendo Switch could claim within the first month or so after it launched. The colour scheme resembles the original neon switch controllers. Although the ship type occurs naturally in the game in other configurations, I think differently-painted wings are unique to this ship. For most of the last 4 years, my copy of this ship was confined to the Switch, until November 2024, when they added cross-save capability to the game. I was then able to access the ship when playing on Linux (or Mac).

  1. The game runs very well natively on Mac, flawlessly on Steam for Linux, but struggles on the origins switch. It s a marvel it runs there at all.

Ravi Dwivedi: My experiences in Brunei

This post covers my friend Badri and my experiences in Brunei. Brunei officially Brunei Darussalam is a country in Southeast Asia, located on Borneo island. It is one of the few remaining absolute monarchies on Earth. On the morning of the 10th of December 2024, Badri and I reached Brunei International Airport by taking a flight from Kuala Lumpur. Upon arrival at the airport, we had to go through the immigration, of course. However, I forgot to fill my arrival card, which I filled while I was in the queue for my immigration. The immigration officer asked me how much cash I was carrying of each currency. After completing the formalities, the immigration officer stamped my passport and let me in. Take a look at Brunei s entry stamp in my passport.
Brunei entry stamp Brunei entry stamp on my passport. Picture by Ravi Dwivedi, released under CC-BY-SA 4.0.
We exchanged Singapore dollars to get some Brunei dollars at the airport. The Brunei dollar was pegged 1:1 with the Singapore dollar, meaning 1 Singapore dollar equals 1 Brunei dollar. The exchange rate we received at the airport was the same. Our (pre-booked) accommodation was located near Gadong mall. So, we went to the information center at the airport to ask how to get there by public transport. However, the person at the information center told us that they didn t know the public transport routes and suggested we take a taxi instead. We came out of the airport and came across an Indian with a mini bus. He offered to drop us at our accommodation for 10 Brunei dollars ( 630). As we were tired after a sleepless night, we didn t negotiate and took the offer. It felt a bit weird using the minibus as our private taxi. In around half-an-hour, we reach our accommodation. The place was more like a guest house than a hotel. In addition to the rooms, it had common space consisting of a hall, a kitchen and a balcony.
Our room in Brunei Our room in Brunei. Picture by Ravi Dwivedi, released under CC-BY-SA 4.0
Upon reaching the place, we paid for our room in cash, which was 66.70 Singapore dollars (4200 Indian rupees) for two nights. We reached before the check-in time, so we had to wait for our room to get ready before we entered. The room had a double bed and also a place to hang clothes. We slept for a few hours before going out at night. We went into Gadong mall and had coffee at a caf named The Coffee Bean & Tea Leaf. The regular caffe latte I had here been 5.20 Brunei dollars. On another note, the snacks we got us from Kuala Lumpur covered us for the dinner. The next day 11th of December 2024 we went to a nearby restaurant named Nadj for lunch. The owner was from Kerala. Here we ordered: So, our lunch cost a total of 12.80 Brunei dollars (825 rupees). The naan was unusually thick, and didn t like the taste. After the lunch, we planned to visit Brunei s famous Omar Ali Saifuddien Mosque. However, a minibus driver outside of Gadong Mall told us that the mosque would be closed in half-an-hour and suggested we visit the nearby Jame Asr Hassanil Bolkiah Mosque instead.
Jame' Asr Hassanil Bolkiah Mosque Jame Asr Hassanil Bolkiah Mosque. Picture by Ravi Dwivedi, released under CC-BY-SA 4.0
He dropped us there for 1 Brunei dollar per person. The person hailed from Uttar Pradesh and told us about bus routes in Hindi. Buses routes in Brunei were confusing, so the information he gave us was valuable. It was evening, and we had an impression that the mosque and its premises were closed. However, soon enough, we stumbled across an open gate entering the mosque complex. We walked inside for some time, took pictures and exited. Walking in Bandar Seri Begawan wasn t pleasant, though. The pedestrian infrastructure wasn t good. Then we walked back to our place and bought some souvenirs. For dinner and breakfast, we bought bread, fruits and eggs from local shops as we had a kitchen to cook for ourselves. The guest house also had a washing machine (free of charge) which we wanted to use. However, they didn t have detergent. Therefore, we went outside to get some detergent. It was 8 o clock, and most of the shops were closed already. Others had had detergents in large sizes, the ones you would use if you lived there. We ended up getting a small packet at a supermarket. The next day 12th of December we had a flight to Ho Chi Minh City in Vietnam with a long layover in Kuala Lumpur. We had breakfast in the morning and took a bus to Omar Ali Saifuddien Mosque. The mosque was in prayer session, so it was closed for Muslims. Therefore, we just took pictures from the outside and took a bus for the airport.
Omar Ali Saifuddien Mosque Omar Ali Saifuddien Mosque. Picture by Ravi Dwivedi, released under CC-BY-SA 4.0
When the bus reached near the airport, the bus went straight rather than taking a left turn for the airport. Initially, I thought the bus would just take a turn and come back. However, the bus kept going away from the airport. Confused by this, I asked other passengers if the bus was going to the airport. The driver stopped the bus at Muara Town terminal 20 km from the airport. At this point, everyone alighted, except for us. The driver went to a nearby restaurant to have lunch. I felt very uncomfortable stranded in a town which was 20 km from the airport. We had a lot of time, but I was still worried about missing our flight, as I didn t want to get stuck in Brunei. After waiting for 15 minutes, I went inside the restaurant and reminded the driver that we had a flight in a couple of hours and needed to go to the airport. He said he will leave soon. When he was done with his lunch, he drove us to the airport. It was incredibly frustrating. On a positive note, we saw countryside of Brunei that we would have seen otherwise. The bus ride cost us 1 Brunei dollar each.
A couple of houses with trees in the background. A shot of Brunei s countryside. Picture by Ravi Dwivedi, released under CC-BY-SA 4.0.

That s it for this one. Meet you in the next one. Stay tuned for the Vietnam post!

16 January 2026

Freexian Collaborators: Monthly report about Debian Long Term Support, December 2025 (by Santiago Ruano Rinc n)

The Debian LTS Team, funded by [Freexian s Debian LTS offering] (https://www.freexian.com/lts/debian/), is pleased to report its activities for December.

Activity summary During the month of December, 18 contributors have been paid to work on Debian LTS (links to individual contributor reports are located below). The team released 41 DLAs fixing 252 CVEs. The team currently focuses on preparing security updates for Debian 11 bullseye , but also looks for contributing with updates for Debian 12 bookworm , Debian 13 trixie and even Debian unstable. Notable security updates:
  • libsoup2.4 (DLA-4398-1), prepared by Andreas Henrikson, fixing several vulnerabilities.
  • glib2.0 (DLA-4412-1), published by Emilio Pozuelo Monfort, addressing multiple issues.
  • lasso (DLA-4397-1), prepared by Sylvain Beucler, addressing multiple issues, including a critical remote code execution (RCE) vulnerability (CVE-2025-47151)
  • roundcube (DLA 4415-1), prepared by Guilhem Moulin, fixing a cross-site-scripting (XSS) (CVE-2025-68461) and an information disclosure (CVE-2025-68460) vulnerabilities
  • mediawiki (DLA 4428-1), published by Guilhem, fixing multiple vulnerabilities could lead to information disclosure, denial of service or privilege escalation.
  • While the DLA has not been published yet, Charles Henrique Melara proposed upstream fixes for seven CVEs in ffmpeg: https://code.ffmpeg.org/FFmpeg/FFmpeg/pulls/21275.
  • python-apt (DLA 4408-1), prepared by Utkarsh Gupta, in coordination with the Debian Security Team and Julian Andres Klode, the apt s maintainer.
  • libpng1.6 (DLA-4396-1), published by Tobias Frost, completing the work started the previous month.
Notable non-security updates:
  • tzdata (DLA-4403-1), prepared by Emilio, including the latest changes to the leap second list and its expiry date, which was set for the end of December.
Contributions from outside the LTS Team:
  • Christoph Berg, co-maintainer of PostgreSQL in Debian, prepared a postgresql-13 update, released as DLA-4420-1
The LTS Team has also contributed with updates to the latest Debian releases:

Individual Debian LTS contributor reports

Thanks to our sponsors Sponsors that joined recently are in bold.

14 January 2026

Dirk Eddelbuettel: RcppSimdJson 0.1.15 on CRAN: New Upstream, Some Maintenance

A brand new release 0.1.15 of the RcppSimdJson package is now on CRAN. RcppSimdJson wraps the fantastic and genuinely impressive simdjson library by Daniel Lemire and collaborators. Via very clever algorithmic engineering to obtain largely branch-free code, coupled with modern C++ and newer compiler instructions, it results in parsing gigabytes of JSON parsed per second which is quite mindboggling. The best-case performance is faster than CPU speed as use of parallel SIMD instructions and careful branch avoidance can lead to less than one cpu cycle per byte parsed; see the video of the talk by Daniel Lemire at QCon. This version updates to the current 4.2.4 upstream release. It also updates the RcppExports.cpp file with glue between C++ and R. We want move away from using Rf_error() (as Rcpp::stop() is generally preferable). Packages (such as this one) that are declaring an interface have an actual Rf_error() call generated in RcppExports.cpp which can protect which is what current Rcpp code generation does. Long story short, a minor internal reason. The short NEWS entry for this release follows.

Changes in version 0.1.15 (2026-01-14)
  • simdjson was upgraded to version 4.2.4 (Dirk in #97
  • RcppExports.cpp was regenerated to aid a Rcpp transition
  • Standard maintenance updates for continuous integration and URLs

Courtesy of my CRANberries, there is also a diffstat report for this release. For questions, suggestions, or issues please use the issue tracker at the GitHub repo.

This post by Dirk Eddelbuettel originated on his Thinking inside the box blog. If you like this or other open-source work I do, you can now sponsor me at GitHub.

13 January 2026

Louis-Philippe V ronneau: Reducing the size of initramfs kernel images

In the past few years, the size of the kernel images in Debian have been steadily growing. I don't see this as a problem per se, but it has been causing me trouble, as my /boot partition has become too small to accommodate two kernel images at the same time. Since I'm running Debian Unstable on my personal systems and keep them updated with unattended-upgrade, this meant each (frequent) kernel upgrade triggered an error like this one:
update-initramfs: failed for /boot/initrd.img-6.17.11+deb14-amd64 with 1.
dpkg: error processing package initramfs-tools (--configure):
 installed initramfs-tools package post-installation script subprocess returned
 error exit status 1
Errors were encountered while processing:
 initramfs-tools
E: Sub-process /usr/bin/dpkg returned an error code (1)
This would in turn break the automated upgrade process and require me to manually delete the currently running kernel (which works, but isn't great) to complete the upgrade. The "obvious" solution would have been to increase the size of my /boot partition to something larger than the default 456M. Since my systems use full-disk encryption and LVM, this isn't trivial and would have required me to play Tetris and swap files back and forth using another drive. Another solution proposed by anarcat was to migrate to systemd-boot (I'm still using grub), use Unified Kernel Images (UKI) and merge the /boot and /boot/efi partitions. Since I already have a bunch of configurations using grub and I am not too keen on systemd taking over all the things on my computer, I was somewhat reluctant. As my computers are all configured by Puppet, I could of course have done a complete system reinstallation, but again, this was somewhat more involved than what I wanted it to be. After looking online for a while, I finally stumbled on this blog post by Neil Brown detailing how to shrink the size of the initramfs images. With MODULES=dep my images shrunk from 188M to 41M, fixing my issue. Thanks Neil! I was somewhat worried removing kernel modules would break something on my systems, but so far, I only had to manually load the i2c_dev module, as I need it to manage my home monitor's brightness using ddcutil.

12 January 2026

Daniel Kahn Gillmor: AI as a Compression Problem

A recent article in The Atlantic makes the case that very large language models effectively contain much of the works they're trained on. This article is an attempt to popularize the insights in the recent academic paper Extracting books from production language models from Ahmed et al. The authors of the paper demonstrate convincingly that well-known copyrighted textual material can be extracted from the chatbot interfaces of popular commercial LLM services. The Atlantic article cites a podcast quote about the Stable Diffusion AI image-generator model, saying "We took 100,000 gigabytes of images and compressed it to a two-gigabyte file that can re-create any of those and iterations of those". By analogy, this suggests we might think of LLMs (which work on text, not the images handled by Stable Diffusion) as a form of lossy textual compression. The entire text of Moby Dick, the canonical Big American Novel is merely 1.2MiB uncompressed (and less than 0.4MiB losslessly compressed with bzip2 -9). It's not surprising to imagine that a model with hundreds of billions of parameters might contain copies of these works. Warning: The next paragraph contains fuzzy math with no real concrete engineering practice behind it! Consider a hypothetical model with 100 billion parameters, where each parameter is stored as a 16-bit floating point value. The model weights would take 200 GB of storage. If you were to fill the parameter space only with losslessly compressed copies of books like Moby Dick, you could still fit half a million books, more than anyone can read in a lifetime. And lossy compression is typically orders of magnitude less in size than lossless compression, so we're talking about millions of works effectively encoded, with the acceptance of some artifacts being injected in the output. I first encountered this "compression" view of AI nearly three years ago, in Ted Chiang's insightful ChatGPT is a Blurry JPEG of the Web. I was suprised that The Atlantic article didn't cite Chiang's piece. If you haven't read Ted Chiang, i strongly recommend his work, and this piece is a great place to start. Chiang aside, the more recent writing that focuses on the idea of compressed works being "contained" in the model weights seems to be used by people interested in wielding some sort of copyright claims against the AI companies that maintain or provide access to these models. There are many many problems with AI today, but attacking AI companies based on copyright concerns seems similar to going after Al Capone for tax evasion. We should be much more concerned with the effect these projects have on cultural homogeneity, mental health, labor rights, privacy, and social control than whether they're violating copyright in some specific instance.

10 January 2026

Dirk Eddelbuettel: Rcpp 1.1.1 on CRAN: Many Improvements in Semi-Annual Update

rcpp logo Team Rcpp is thrilled to share that an exciting new version 1.1.1 of Rcpp is now on CRAN (and also uploaded to Debian and already built for r2u). Having switchted to C++11 as the minimum standard in the previous 1.1.0 release, this version takes full advantage of it and removes a lot of conditional code catering to older standards that no longer need to be supported. Consequently, the source tarball shrinks by 39% from 3.11 mb to 1.88 mb. That is a big deal. (Size peaked with Rcpp 1.0.12 two years ago at 3.43 mb; relative to its size we are down 45% !!) Removing unused code also makes maintenance easier, and quickens both compilation and installation in general. This release continues as usual with the six-months January-July cycle started with release 1.0.5 in July 2020. Interim snapshots are always available via the r-universe page and repo. We continue to strongly encourage the use of these development released and their testing we tend to run our systems with them too. Rcpp has long established itself as the most popular way of enhancing R with C or C++ code. Right now, 3020 packages on CRAN depend on Rcpp for making analytical code go faster and further. On CRAN, 13.1% of all packages depend (directly) on Rcpp, and 60.9% of all compiled packages do. From the cloud mirror of CRAN (which is but a subset of all CRAN downloads), Rcpp has been downloaded 109.8 million times. The two published papers (also included in the package as preprint vignettes) have, respectively, 2151 (JSS, 2011) and 405 (TAS, 2018) citations, while the the book (Springer useR!, 2013) has another 715. This time, I am not attempting to summarize the different changes. The full list follows below and details all these changes, their respective PRs and, if applicable, issue tickets. Big thanks from all of us to all contributors!
Changes in Rcpp release version 1.1.1 (2026-01-08)
  • Changes in Rcpp API:
    • An unused old R function for a compiler version check has been removed after checking no known package uses it (Dirk in #1395)
    • A narrowing warning is avoided via a cast (Dirk in #1398)
    • Demangling checks have been simplified (I aki in #1401 addressing #1400)
    • The treatment of signed zeros is now improved in the Sugar code (I aki in #1404)
    • Preparations for phasing out use of Rf_error have been made (I aki in #1407)
    • The long-deprecated function loadRcppModules() has been removed (Dirk in #1416 closing #1415)
    • Some non-API includes from R were refactored to accommodate R-devel changes (I aki in #1418 addressing #1417)
    • An accessor to Rf_rnbeta has been removed (Dirk in #1419 also addressing #1420)
    • Code accessing non-API Rf_findVarInFrame now uses R_getVarEx (Dirk in #1423 fixing #1421)
    • Code conditional on the R version now expects at least R 3.5.0; older code has been removed (Dirk in #1426 fixing #1425)
    • The non-API ATTRIB entry point to the R API is no longer used (Dirk in #1430 addressing #1429)
    • The unwind-protect mechanism is now used unconditionally (Dirk in #1437 closing #1436)
  • Changes in Rcpp Attributes:
    • The OpenMP plugin has been generalized for different macOS compiler installations (Kevin in #1414)
  • Changes in Rcpp Documentation:
    • Vignettes are now processed via a new "asis" processor adopted from R.rsp (Dirk in #1394 fixing #1393)
    • R is now cited via its DOI (Dirk)
    • A (very) stale help page has been removed (Dirk in #1428 fixing #1427)
    • The main README.md was updated emphasizing r-universe in favor of the local drat repos (Dirk in #1431)
  • Changes in Rcpp Deployment:
    • A temporary change in R-devel concerning NA part in complex variables was accommodated, and then reverted (Dirk in #1399 fixing #1397)
    • The macOS CI runners now use macos-14 (Dirk in #1405)
    • A message is shown if R.h is included before Rcpp headers as this can lead to errors (Dirk in #1411 closing #1410)
    • Old helper functions use message() to signal they are not used, deprecation and removal to follow (Dirk in #1413 closing #1412)
    • Three tests were being silenced following #1413 (Dirk in #1422)
    • The heuristic whether to run all available tests was refined (Dirk in #1434 addressing #1433)
    • Coverage has been tweaked via additional #nocov tags (Dirk in #1435)
  • Non-release Changes:
    • Two interim non-releases 1.1.0.8.1 and .2 were made in order to unblock CRAN due to changes in R-devel rather than Rcpp

Thanks to my CRANberries, you can also look at a diff to the previous interim release along with pre-releaseds 1.1.0.8, 1.1.0.8.1 and 1.1.0.8.2 that were needed because R-devel all of a sudden decided to move fast and break things. Not our doing. Questions, comments etc should go to the GitHub discussion section list]rcppdevellist off the R-Forge page. Bugs reports are welcome at the GitHub issue tracker as well. Both sections can be searched as well.

This post by Dirk Eddelbuettel originated on his Thinking inside the box blog. If you like this or other open-source work I do, you can sponsor me at GitHub.

Scarlett Gately Moore: I love KDE too much to retire! Snap beta releases trickling in. Stay tuned.

A short but sweet note to say I am coming out of my short retirement to help with snaps again. My time is extremely limited, however we are working hard on getting snaps on CI and I have some newer snaps in beta trickling in for testing. You must install kf6-core24 from beta as well to test them ( this will likely break older kde snaps in the process so beware. ) This is slow going as I work on them during my hour lunch at day job and spare stolen moments. KDE is coming up on its 30th birthday!!! How cool is that! I  KDE Like my work? Consider a donation. Thank you! Donate
8 January 2026

Reproducible Builds: Reproducible Builds in December 2025

Welcome to the December 2025 from the Reproducible Builds project! Our monthly reports outline what we ve been up to over the past month, highlighting items of news from elsewhere in the increasingly-important area of software supply-chain security. As ever, if you are interested in contributing to the Reproducible Builds project, please see the Contribute page on our website.

  1. New orig-check service to validate Debian upstream tarballs
  2. Distribution work
  3. disorderfs updated to FUSE 3
  4. Mailing list updates
  5. Three new academic papers published
  6. Website updates
  7. Upstream patches

New orig-check service to validate Debian upstream tarballs This month, Debian Developer Lucas Nussbaum announced the orig-check service, which attempts to automatically reproduce the generation upstream tarballs (ie. the original source component of a Debian source package), comparing that to the upstream tarball actually shipped with Debian. As of the time of writing, it is possible for a Debian developer to upload a source archive that does not actually correspond to upstream s version. Whilst this is not inherently malicious (it typically indicates some tooling/process issue), the very possibility that a maintainer s version may differ potentially permits a maintainer to make (malicious) changes that would be misattributed to upstream. This service therefore nicely complements the whatsrc.org service, which was reported in our reports for both April and August. The orig-check is dedicated to Lunar, who sadly passed away a year ago.

Distribution work In Arch Linux this month, Robin Candau and Mark Hegreberg worked at making the Arch Linux WSL image bit-for-bit reproducible. Robin also shared some implementation details and future related work on our mailing list. Continuing a series reported in these reports for March, April and July 2025 (etc.), Simon Josefsson has published another interesting article this month, itself a followup to a post Simon published in December 2024 regarding GNU Guix Container Images that are hosted on GitLab. In Debian this month, Micha Lenk posted to the debian-backports-announce mailing list with the news that the Backports archive will now discard binaries generated and uploaded by maintainers: The benefit is that all binary packages [will] get built by the Debian buildds before we distribute them within the archive. Felix Moessbauer of Siemens then filed a bug in the Debian bug tracker to signal their intention to package debsbom, a software bill of materials (SBOM) generator for distributions based on Debian. This generated a discussion on the bug inquiring about the output format as well as a question about how these SBOMs might be distributed. Holger Levsen merged a number of significant changes written by Alper Nebi Yasak to the Debian Installer in order to improve its reproducibility. As noted in Alper s merge request, These are the reproducibility fixes I looked into before bookworm release, but was a bit afraid to send as it s just before the release, because the things like the xorriso conversion changes the content of the files to try to make them reproducible. In addition, 76 reviews of Debian packages were added, 8 were updated and 27 were removed this month adding to our knowledge about identified issues. A new different_package_content_when_built_with_nocheck issue type was added by Holger Levsen. [ ] Arnout Engelen posted to our mailing list reporting that they successfully reproduced the NixOS minimal installation ISO for the 25.11 release without relying on a pre-compiled package archive, with more details on their blog. Lastly, Bernhard M. Wiedemann posted another openSUSE monthly update for his work there.

disorderfs updated to FUSE 3 disorderfs is our FUSE-based filesystem that deliberately introduces non-determinism into system calls to reliably flush out reproducibility issues. This month, however, Roland Clobus upgraded disorderfs* from FUSE 2 to FUSE 3 after its package automatically got removed from Debian testing. Some tests in Debian currently require disorderfs to make the Debian live images reproducible, although disorderfs is not a Debian-specific tool.

Mailing list updates On our mailing list this month:
  • Luca Di Maio announced stampdalf, a filesystem timestamp preservation tool that wraps arbitrary commands and ensures filesystem timestamp reproducibility :
    stampdalf allows you to run any command that modifies files in a directory tree, then automatically resets all timestamps back to their original values. Any new files created during command execution are set to [the UNIX epoch] or a custom timestamp via SOURCE_DATE_EPOCH.
    The project s GitHub page helpfully reveals that the project is pronounced: stamp-dalf (stamp like time-stamp, dalf like Gandalf the wizard) as it s a wizard of time and stamps .)
  • Lastly, Reproducible Builds developer cen1 posted to our list announcing that early/experimental/alpha support for FreeBSD was added to rebuilderd. In their post, cen1 reports that the initial builds are in progress and look quite decent . cen1 also interestingly notes that since the upstream is currently not technically reproducible I had to relax the bit-for-bit identical requirement of rebuilderd [ ] I consider the pkg to be reproducible if the tar is content-identical (via diffoscope), ignoring timestamps and some of the manifest files. .

Three new academic papers published Yogya Gamage and Benoit Baudry of Universit de Montr al, Canada together with Deepika Tiwari and Martin Monperrus of KTH Royal Institute of Technology, Sweden published a paper on The Design Space of Lockfiles Across Package Managers:
Most package managers also generate a lockfile, which records the exact set of resolved dependency versions. Lockfiles are used to reduce build times; to verify the integrity of resolved packages; and to support build reproducibility across environments and time. Despite these beneficial features, developers often struggle with their maintenance, usage, and interpretation. In this study, we unveil the major challenges related to lockfiles, such that future researchers and engineers can address them. [ ]
A PDF of their paper is available online. Benoit Baudry also posted an announcement to our mailing list, which generated a number of replies.
Betul Gokkaya, Leonardo Aniello and Basel Halak of the University of Southampton then published a paper on the A taxonomy of attacks, mitigations and risk assessment strategies within the software supply chain:
While existing studies primarily focus on software supply chain attacks prevention and detection methods, there is a need for a broad overview of attacks and comprehensive risk assessment for software supply chain security. This study conducts a systematic literature review to fill this gap. By analyzing 96 papers published between 2015-2023, we identified 19 distinct SSC attacks, including 6 novel attacks highlighted in recent studies. Additionally, we developed 25 specific security controls and established a precisely mapped taxonomy that transparently links each control to one or more specific attacks. [ ]
A PDF of the paper is available online via the article s canonical page.
Aman Sharma and Martin Monperrus of the KTH Royal Institute of Technology, Sweden along with Benoit Baudry of Universit de Montr al, Canada published a paper this month on Causes and Canonicalization of Unreproducible Builds in Java. The abstract of the paper is as follows:
[Achieving] reproducibility at scale remains difficult, especially in Java, due to a range of non-deterministic factors and caveats in the build process. In this work, we focus on reproducibility in Java-based software, archetypal of enterprise applications. We introduce a conceptual framework for reproducible builds, we analyze a large dataset from Reproducible Central, and we develop a novel taxonomy of six root causes of unreproducibility. [ ]
A PDF of the paper is available online.

Website updates Once again, there were a number of improvements made to our website this month including:

Upstream patches The Reproducible Builds project detects, dissects and attempts to fix as many currently-unreproducible packages as possible. We endeavour to send all of our patches upstream where appropriate. This month, we wrote a large number of such patches, including:

Finally, if you are interested in contributing to the Reproducible Builds project, please visit our Contribute page on our website. However, you can get in touch with us via:

Next.

Previous.