Search Results: "rul"

17 December 2024

Gunnar Wolf: The science of detecting LLM-generated text

This post is a review for Computing Reviews for The science of detecting LLM-generated text , a article published in Communications of the ACM
While artificial intelligence (AI) applications for natural language processing (NLP) are no longer something new or unexpected, nobody can deny the revolution and hype that started, in late 2022, with the announcement of the first public version of ChatGPT. By then, synthetic translation was well established and regularly used, many chatbots had started attending users requests on different websites, voice recognition personal assistants such as Alexa and Siri had been widely deployed, and complaints of news sites filling their space with AI-generated articles were already commonplace. However, the ease of prompting ChatGPT or other large language models (LLMs) and getting extensive answers its text generation quality is so high that it is often hard to discern whether a given text was written by an LLM or by a human has sparked significant concern in many different fields. This article was written to present and compare the current approaches to detecting human- or LLM-authorship in texts. The article presents several different ways LLM-generated text can be detected. The first, and main, taxonomy followed by the authors is whether the detection can be done aided by the LLM s own functions ( white-box detection ) or only by evaluating the generated text via a public application programming interface (API) ( black-box detection ). For black-box detection, the authors suggest training a classifier to discern the origin of a given text. Although this works at first, this task is doomed from its onset to be highly vulnerable to new LLMs generating text that will not follow the same patterns, and thus will probably evade recognition. The authors report that human evaluators find human-authored text to be more emotional and less objective, and use grammar to indicate the tone of the sentiment that should be used when reading the text a trait that has not been picked up by LLMs yet. Human-authored text also tends to have higher sentence-level coherence, with less term repetition in a given paragraph. The frequency distribution for more and less common words is much more homogeneous in LLM-generated texts than in human-written ones. White-box detection includes strategies whereby the LLMs will cooperate in identifying themselves in ways that are not obvious to the casual reader. This can include watermarking, be it rule based or neural based; in this case, both processes become a case of steganography, as the involvement of a LLM is explicitly hidden and spread through the full generated text, aiming at having a low detectability and high recoverability even when parts of the text are edited. The article closes by listing the authors concerns about all of the above-mentioned technologies. Detecting an LLM, be it with or without the collaboration of the LLM s designers, is more of an art than a science, and methods deemed as robust today will not last forever. We also cannot assume that LLMs will continue to be dominated by the same core players; LLM technology has been deeply studied, and good LLM engines are available as free/open-source software, so users needing to do so can readily modify their behavior. This article presents itself as merely a survey of methods available today, while also acknowledging the rapid progress in the field. It is timely and interesting, and easy to follow for the informed reader coming from a different subfield.

Russ Allbery: Review: Iris Kelly Doesn't Date

Review: Iris Kelly Doesn't Date, by Ashley Herring Blake
Series: Bright Falls #3
Publisher: Berkley Romance
Copyright: October 2023
ISBN: 0-593-55058-7
Format: Kindle
Pages: 381
Iris Kelly Doesn't Date is a sapphic romance novel (probably a romantic comedy, although I'm bad at romance subgenres). It is the third book in the Bright Falls series. In the romance style, it has a new set of protagonists, but the protagonists of the previous books appear as supporting characters and reading this will spoil the previous books. Among the friend group we were introduced to in Delilah Green Doesn't Care, Iris was the irrepressible loudmouth. She's bad at secrets, good at saying whatever is on her mind, and has zero desire to either get married or have children. After one of the side plots of Astrid Parker Doesn't Fail, she has sworn off dating entirely. Iris is also now a romance novelist. Her paper store didn't get enough foot traffic to justify staying open, so she switched her planner business to online only and wrote a romance novel that was good enough to get a two-book deal. Now she needs to write a second book and she has absolutely nothing. Her own avoidance of romantic situations is not helping, but neither is her meddling family who are convinced her choices about marriage and family can be overturned with sufficient pestering. She desperately needs to shake up her life, get out of her creative rut, and do something new. Failing that, she'll settle for meeting someone in a bar and having some fun. Stevie is a barista and actress living in Portland. Six months ago, she broke up with Adri, her creative partner, girlfriend of six years, and the first person with whom she had a serious relationship. More precisely, Adri broke up with her. They're still friends, truly, even though that friendship is being seriously strained by Adri dating Vanessa, another member of their small and close-knit friend group. Stevie has occasionally-crippling anxiety, not much luck in finding real acting roles in Portland, and a desperate desire to not make waves. Ren, the fourth member of their friend group, thinks Stevie needs a new relationship, or at least a fling. That's how Stevie, with Ren as backup and encouragement, ends up at the same bar with Iris. The resulting dance and conversation was rather fun for both Stevie and Iris. The attempted one-night stand afterwards was a disaster due to Stevie's anxiety, and neither of them expected to see the other again. Stevie therefore felt safe pretending they'd hit it off to get her friends off her back. When Iris's continued restlessness lands her in an audition for Adri's fundraiser play that she also talked Stevie into performing in, this turns into a full-blown fake dating trope. These books continue to be impossible to put down. I'm not sure what Blake is doing to make the pacing so perfect, but as with the previous books of the series I found this utterly compulsive reading. I started it in the afternoon, took a break in the evening for a few hours, and then finished it at 2am. I wasn't sure if a book focused on Iris would work as well, but I need not have worried. Iris Kelly Doesn't Date is both more dramatic and more trope-centered than the earlier books, but Blake handles that in a way that fits Iris's personality and wasn't annoying even to a reader like me, who has an aversion to many types of relationship drama. The secret is Stevie, and specifically having the other protagonist be someone with severe anxiety.
No was never a very easy word for Stevie when it came to Adri, when it came to anyone, really. She could handle the little stuff do you want a soda, have you seen this movie, do you like onions on your pizza but the big stuff, the stuff that caused disappointed expressions and down-turned mouths... yeah, she sucked at that part. Her anxiety would flare, and she'd spend the next week convinced her friends hated her, she'd die alone and miserable, and wasn't worth a damn to anyone. Then, when said friend or family member eventually got ahold of her to tell her that, no, of course they didn't hate her, why in the world would she think that, her anxiety would crest once again, convincing her that she was terrible at understanding people and could never trust her own brain to make heads or tails of any social situation.
This is a spot-on description of a particular type of anxiety, but also this is the perfect protagonist to pair with Iris. Throughout the series, Iris has always been the ride-or-die friend, the person who may have no idea how to help but who will show up anyway and at least try to distract you. Stevie's anxiety makes Iris feel protective, which reveals one of the best sides of Iris's personality, and then the protectiveness plays off against Iris's own relationship issues and tendency to avoid taking anything too seriously. It's one of those relationships that starts a bit one-sided and then becomes mutually supporting once Stevie gets her feet under her. That's a relationship pattern I really enjoy reading about. As with the rest of the series, the friendship dynamics are great. Here we get to see two friend groups at work: Iris's, which we've seen in the previous two volumes and which expanded interestingly in Astrid Parker Doesn't Fail, and Stevie's, which is new. I liked all of these people, even Adri in her own way (although she's the hardest to like). The previous happily-ever-afters do get a bit awkward here, but Blake tries to make that part of the plot and also avoids most of the problem of somewhat-boring romantic bliss by spreading the friendship connections a bit wider. Stevie's friend group formed at orientation at Reed College, and that let me put my finger on another property of this series: essentially all of the characters are from a very specific social class. They're nearly all arts people (bookstore owner, photographer, interior decorator, actress, writer, director), they've mostly gone to college, and while most of them don't have lots of money, there's always at least one person in each friend group with significant wealth. Jordan, from the previous book, is a bit of an exception since she works in a trade (a carpenter), but she still acts like someone from that same social class. It's a bit like reading Jane Austen novels and realizing that the protagonists are drawn from a very specific and very narrow portion of society. This is not a complaint, to be clear; I have no objections to reading about a very specific social class. But if one has already read lots of books about this class of people, I could see that diminishing the appeal of this series a bit. There are a lot of assumptions baked into the story that aren't really questioned, such as the ubiquity of therapists. (I don't know how Stevie affords one on a barista salary.) There are also some small things in the terminology (therapy speak, for example) and in the specific type of earnestness with which the books attempt to be diverse on most axes other than social class that I suspect may grate a bit for some readers. If that's you, this is your warning. There is a third-act breakup here, just like the previous volumes. There is also a defense of the emotional punch of third-act breakups in romance novels in the book itself, put into Iris's internal monologue, so I suspect that's the author's answer to critics like myself who don't like the trope. I was less frustrated by this one because it fit the drama level of the protagonists, but I'll also know to expect a third-act breakup in any Blake novel I read in the future. But, all that said, the summary once again is that I loved this book and could not put it down. Iris is dramatic and occasionally self-destructive but has a core of earnest empathy that makes her easy to like. She's exactly the sort of extrovert who is soothing to introverts rather than draining because she carries the extrovert load of social situations. Stevie is adorably earnest and thoughtful beneath her anxiety. They two of them are wildly different and yet remarkably good together, and I loved reading their story. Highly recommended, along with the whole series. Start with Delilah Green Doesn't Care; if you like that, you're in for a treat. Content note: This book is also rather sex-forward and pretty explicit in the sex scenes, maybe a touch more than Astrid Parker Doesn't Fail. If that is or is not your thing in romance novels, be aware going in. Rating: 9 out of 10

12 December 2024

Dirk Eddelbuettel: RcppCCTZ 0.2.13 on CRAN: Maintenance

A new release 0.2.13 of RcppCCTZ is now on CRAN. RcppCCTZ uses Rcpp to bring CCTZ to R. CCTZ is a C++ library for translating between absolute and civil times using the rules of a time zone. In fact, it is two libraries. One for dealing with civil time: human-readable dates and times, and one for converting between between absolute and civil times via time zones. And while CCTZ is made by Google(rs), it is not an official Google product. The RcppCCTZ page has a few usage examples and details. This package was the first CRAN package to use CCTZ; by now several others packages (four the last time we counted) include its sources too. Not ideal, but beyond our control. This version include most routine package maintenance as well as one small contributed code improvement. The changes since the last CRAN release are summarised below.

Changes in version 0.2.13 (2024-12-11)
  • No longer set compilation standard as recent R version set a sufficiently high minimum
  • Qualify a call to cctz::format (Michael Quinn in #44)
  • Routine updates to continuous integration and badges
  • Switch to Authors@R in DESCRIPTION

Courtesy of my CRANberries, there is a diffstat report relative to to the previous version. More details are at the RcppCCTZ page; code, issue tickets etc at the GitHub repository. If you like this or other open-source work I do, you can sponsor me at GitHub.

This post by Dirk Eddelbuettel originated on his Thinking inside the box blog. Please report excessive re-aggregation in third-party for-profit settings.

4 December 2024

Dirk Eddelbuettel: corels 0.0.5 on CRAN: Maintenance

An updated version of the corels package is now on CRAN! The Certifiably Optimal RulE ListS (Corels) learner provides interpretable decision rules with an optimality guarantee a nice feature which sets it apart in machine learning. You can learn more about corels at its UBC site. The changes concern mostly maintenance for both the repository (such as continunous integration setup, badges, documentation links, ) and the package level (such as removing the no-longer-requiring C++ compilation standard setter now emitting a NOTE at CRAN.

This post by Dirk Eddelbuettel originated on his Thinking inside the box blog. Please report excessive re-aggregation in third-party for-profit settings.

2 December 2024

Bits from Debian: Bits from the DPL

This is bits from DPL for November. MiniDebConf Toulouse I had the pleasure of attending the MiniDebConf in Toulouse, which featured a range of engaging talks, complementing those from the recent MiniDebConf in Cambridge. Both events were preceded by a DebCamp, which provided a valuable opportunity for focused work and collaboration. DebCamp During these events, I participated in numerous technical discussions on topics such as maintaining long-neglected packages, team-based maintenance, FTP master policies, Debusine, and strategies for separating maintainer script dependencies from runtime dependencies, among others. I was also fortunate that members of the Publicity Team attended the MiniDebCamp, giving us the opportunity to meet in person and collaborate face-to-face. Independent of the ongoing lengthy discussion on the Debian Devel mailing list, I encountered the perspective that unifying Git workflows might be more critical than ensuring all packages are managed in Git. While I'm uncertain whether these two questions--adopting Git as a universal development tool and agreeing on a common workflow for its use--can be fully separated, I believe it's worth raising this topic for further consideration. Attracting newcomers In my own talk, I regret not leaving enough time for questions--my apologies for this. However, I want to revisit the sole question raised, which essentially asked: Is the documentation for newcomers sufficient to attract new contributors? My immediate response was that this question is best directed to new contributors themselves, as they are in the best position to identify gaps and suggest improvements that could make the documentation more helpful. That said, I'm personally convinced that our challenges extend beyond just documentation. I don't get the impression that newcomers are lining up to join Debian only to be deterred by inadequate documentation. The issue might be more about fostering interest and engagement in the first place. My personal impression is that we sometimes fail to convey that Debian is not just a product to download for free but also a technical challenge that warmly invites participation. Everyone who respects our Code of Conduct will find that Debian is a highly diverse community, where joining the project offers not only opportunities for technical contributions but also meaningful social interactions that can make the effort and time truly rewarding. In several of my previous talks (you can find them on my talks page just search for "team," and don't be deterred if you see "Debian Med" in the title; it's simply an example), I emphasized that the interaction between a mentor and a mentee often plays a far more significant role than the documentation the mentee has to read. The key to success has always been finding a way to spark the mentee's interest in a specific topic that resonates with their own passions. Bug of the Day In my presentation, I provided a brief overview of the Bug of the Day initiative, which was launched with the aim of demonstrating how to fix bugs as an entry point for learning about packaging. While the current level of interest from newcomers seems limited, the initiative has brought several additional benefits. I must admit that I'm learning quite a bit about Debian myself. I often compare it to exploring a house's cellar with a flashlight you uncover everything from hidden marvels to things you might prefer to discard. I've also come across traces of incredibly diligent people who have invested their spare time polishing these hidden treasures (what we call NMUs). The janitor, a service in Salsa that automatically updates packages, fits perfectly into this cellar metaphor, symbolizing the ongoing care and maintenance that keep everything in order. I hadn't realized the immense amount of silent work being done behind the scenes--thank you all so much for your invaluable QA efforts. Reproducible builds It might be unfair to single out a specific talk from Toulouse, but I'd like to highlight the one on reproducible builds. Beyond its technical focus, the talk also addressed the recent loss of Lunar, whom we mourn deeply. It served as a tribute to Lunar's contributions and legacy. Personally, I've encountered packages maintained by Lunar and bugs he had filed. I believe that taking over his packages and addressing the bugs he reported is a meaningful way to honor his memory and acknowledge the value of his work. Advent calendar bug squashing I d like to promote an idea originally introduced by Thorsten Alteholz, who in 2011 proposed a Bug Squashing Advent Calendar for the Debian Med team. (For those unfamiliar with the concept of an Advent Calendar, you can find an explanation on Wikipedia.) While the original version included a fun graphical element which we ve had to set aside due to time constraints (volunteers, anyone?) we ve kept the tradition alive by tackling one bug per day from December 1st to 24th each year. This initiative helps clean up issues that have accumulated over the year. Regardless of whether you celebrate the concept of Advent, I warmly recommend this approach as a form of continuous bug-squashing party for every team. Not only does it contribute to the release readiness of your team s packages, but it s also an enjoyable and bonding activity for team members. Best wishes for a cheerful and productive December
Andreas.

20 November 2024

Russell Coker: Solving Spam and Phishing for Corporations

Centralisation and Corporations An advantage of a medium to large company is that it permits specialisation. For example I m currently working in the IT department of a medium sized company and because we have standardised hardware (Dell Latitude and Precision laptops, Dell Precision Tower workstations, and Dell PowerEdge servers) and I am involved in fixing all Linux compatibility issues on that I can fix most problems in a small fraction of the time that I would take to fix on a random computer. There is scope for a lot of debate about the extent to which companies should standardise and centralise things. But for computer problems which can escalate quickly from minor to serious if not approached in the correct manner it s clear that a good deal of centralisation is appropriate. For people doing technical computer work such as programming there s a large portion of the employees who are computer hobbyists who like to fiddle with computers. But if the support system is run well even they will appreciate having computers just work most of the time and for a large portion of the failures having someone immediately recognise the problem, like the issues with NVidia drivers that I have documented so that first line support can implement workarounds without the need for a lengthy investigation. A big problem with email in the modern Internet is the prevalence of Phishing scams. The current corporate approach to this is to send out test Phishing email to people and then force computer security training on everyone who clicks on them. One problem with this is that attackers only need to fool one person on one occasion and when you have hundreds of people doing something on rare occasions that s not part of their core work they will periodically get it wrong. When every test Phishing run finds several people who need extra training it seems obvious to me that this isn t a solution that s working well. I will concede that the majority of people who click on the test Phishing email would probably realise their mistake if asked to enter the password for the corporate email system, but I think it s still clear that this isn t a great solution. Let s imagine for the sake of discussion that everyone in a company was 100% accurate at identifying Phishing email and other scam email, if that was the case would the problem be solved? I believe that even in that hypothetical case it would not be a solved problem due to the wasted time and concentration. People can spend minutes determining if a single email is legitimate. On many occasions I have had relatives and clients forward me email because they are unsure if it s valid, it s great that they seek expert advice when they are unsure about things but it would be better if they didn t have to go to that effort. What we ideally want to do is centralise the anti-Phishing and anti-spam work to a small group of people who are actually good at it and who can recognise patterns by seeing larger quantities of spam. When a spam or Phishing message is sent to 600 people in a company you don t want 600 people to individually consider it, you want one person to recognise it and delete/block all 600. If 600 people each spend one minute considering the matter then that s 10 work hours wasted! The Rationale for Human Filtering For personal email human filtering usually isn t viable because people want privacy. But corporate email isn t private, it s expected that the company can read it under certain circumstances (in most jurisdictions) and having email open in public areas of the office where colleagues might see it is expected. You can visit gmail.com on your lunch break to read personal email but every company policy (and common sense) says to not have actually private correspondence on company systems. The amount of time spent by reception staff in sorting out such email would be less than that taken by individuals. When someone sends a spam to everyone in the company instead of 500 people each spending a couple of minutes working out whether it s legit you have one person who s good at recognising spam (because it s their job) who clicks on a remove mail from this sender from all mailboxes button and 500 messages are deleted and the sender is blocked. Delaying email would be a concern. It s standard practice for CEOs (and C*Os at larger companies) to have a PA receive their email and forward the ones that need their attention. So human vetting of email can work without unreasonable delays. If we had someone checking all email for the entire company probably email to the senior people would never get noticeably delayed and while people like me would get their mail delayed on occasion people doing technical work generally don t have notifications turned on for email because it s a distraction and a fast response isn t needed. There are a few senders where fast response is required, which is mostly corporations sending a click this link within 10 minutes to confirm your password change email. Setting up rules for all such senders that are relevant to work wouldn t be difficult to do. How to Solve This Spam and Phishing became serious problems over 20 years ago and we have had 20 years of evolution of email filtering which still hasn t solved the problem. The vast majority of email addresses in use are run by major managed service providers and they haven t managed to filter out spam/phishing mail effectively so I think we should assume that it s not going to be solved by filtering. There is talk about what AI technology might do for filtering spam/phishing but that same technology can product better crafted hostile email to avoid filters. An additional complication for corporate email filtering is that some criteria that are used to filter personal email don t apply to corporate mail. If someone sends email to me personally about millions of dollars then it s obviously not legit. If someone sends email to a company then it could be legit. Companies routinely have people emailing potential clients about how their products can save millions of dollars and make purchases over a million dollars. This is not a problem that s impossible to solve, it s just an extra difficulty that reduces the efficiency of filters. It seems to me that the best solution to the problem involves having all mail filtered by a human. A company could configure their mail server to not accept direct external mail for any employee s address. Then people could email files to colleagues etc without any restriction but spam and phishing wouldn t be a problem. The issue is how to manage inbound mail. One possibility is to have addresses of the form it+russell.coker@example.com (for me as an employee in the IT department) and you would have a team of people who would read those mailboxes and forward mail to the right people if it seemed legit. Having addresses like it+russell.coker means that all mail to the IT department would be received into folders of the same account and they could be filtered by someone with suitable security level and not require any special configuration of the mail server. So the person who read the is mailbox would have a folder named russell.coker receiving mail addressed to me. The system could be configured to automate the processing of mail from known good addresses (and even domains), so they could just put in a rule saying that when Dell sends DMARC authenticated mail to is+$USER it gets immediately directed to $USER. This is the sort of thing that can be automated in the email client (mail filtering is becoming a common feature in MUAs). For a FOSS implementation of such things the server side of it (including extracting account data from a directory to determine which department a user is in) would be about a day s work and then an option would be to modify a webmail program to have extra functionality for approving senders and sending change requests to the server to automatically direct future mail from the same sender. As an aside I have previously worked on a project that had a modified version of the Horde webmail system to do this sort of thing for challenge-response email and adding certain automated messages to the allow-list. The Change One of the first things to do is configuring the system to add every recipient of an outbound message to the allow list for receiving a reply. Having a script go through the sent-mail folders of all accounts and adding the recipients to the allow lists would be easy and catch the common cases. But even with processing the sent mail folders going from a working system without such things to a system like this will take some time for the initial work of adding addresses to the allow lists, particularly for domain wide additions of all the sites that send password confirmation messages. You would need rules to direct inbound mail to the old addresses to the new style and then address a huge amount of mail that needs to be categorised. If you have 600 employees and the average amount of time taken on the first day is 10 minutes per user then that s 100 hours of work, 12 work days. If you had everyone from the IT department, reception, and executive assistants working on it that would be viable. After about a week there wouldn t be much work involved in maintaining it. Then after that it would be a net win for the company. The Benefits If the average employee spends one minute a day dealing with spam and phishing email then with 600 employees that s 10 hours of wasted time per day. Effectively wasting one employee s work! I m sure that s the low end of the range, 5 minutes average per day doesn t seem unreasonable especially when people are unsure about phishing email and send it to Slack so multiple employees spend time analysing it. So you could have 5 employees being wasted by hostile email and avoiding that would take a fraction of the time of a few people adding up to less than an hour of total work per day. Then there s the training time for phishing mail. Instead of having every employee spend half an hour doing email security training every few months (that s 300 hours or 7.5 working weeks every time you do it) you just train the few experts. In addition to saving time there are significant security benefits to having experts deal with possibly hostile email. Someone who deals with a lot of phishing email is much less likely to be tricked. Will They Do It? They probably won t do it any time soon. I don t think it s expensive enough for companies yet. Maybe government agencies already have equivalent measures in place, but for regular corporations it s probably regarded as too difficult to change anything and the costs aren t obvious. I have been unsuccessful in suggesting that managers spend slightly more on computer hardware to save significant amounts of worker time for 30 years.

18 November 2024

Russ Allbery: Review: Delilah Green Doesn't Care

Review: Delilah Green Doesn't Care, by Ashley Herring Blake
Series: Bright Falls #1
Publisher: Jove
Copyright: February 2022
ISBN: 0-593-33641-0
Format: Kindle
Pages: 374
Delilah Green Doesn't Care is a sapphic romance novel. It's the first of a trilogy, although in the normal romance series fashion each book follows a different protagonist and has its own happy ending. It is apparently classified as romantic comedy, which did not occur to me while reading but which I suppose I can see in retrospect. Delilah Green got the hell out of Bright Falls as soon as she could and tried not to look back. After her father died, her step-mother lavished all of her perfectionist attention on her overachiever step-sister, leaving Delilah feeling like an unwanted ghost. She escaped to New York where there was space for a queer woman with an acerbic personality and a burgeoning career in photography. Her estranged step-sister's upcoming wedding was not a good enough reason to return to the stifling small town of her childhood. The pay for photographing the wedding was, since it amounted to three months of rent and trying to sell photographs in galleries was not exactly a steady living. So back to Bright Falls Delilah goes. Claire never left Bright Falls. She got pregnant young and ended up with a different life than she expected, although not a bad one. Now she's raising her daughter as a single mom, running the town bookstore, and dealing with her unreliable ex. She and Iris are Astrid Parker's best friends and have been since fifth grade, which means she wants to be happy for Astrid's upcoming wedding. There's only one problem: the groom. He's a controlling, boorish ass, but worse, Astrid seems to turn into a different person around him. Someone Claire doesn't like. Then, to make life even more complicated, Claire tries to pick up Astrid's estranged step-sister in Bright Falls's bar without recognizing her. I have a lot of things to say about this novel, but here's the core of my review: I started this book at 4pm on a Saturday because I hadn't read anything so far that day and wanted to at least start a book. I finished it at 11pm, having blown off everything else I had intended to do that evening, completely unable to put it down. It turns out there is a specific type of romance novel protagonist that I absolutely adore: the sarcastic, confident, no-bullshit character who is willing to pick the fights and say the things that the other overly polite and anxious characters aren't able to get out. Astrid does not react well to criticism, for reasons that are far more complicated than it may first appear, and Claire and Iris have been dancing around the obvious problems with her surprise engagement. As the title says, Delilah thinks she doesn't care: she's here to do a job and get out, and maybe she'll get to tweak her annoying step-sister a bit in the process. But that also means that she is unwilling to play along with Astrid's obsessively controlling mother or her obnoxious fiance, and thus, to the barely disguised glee of Claire and Iris, is a direct threat to the tidy life that Astrid's mother is trying to shoehorn her daughter into. This book is a great example of why I prefer sapphic romances: I think this character setup would not work, at least for me, in a heterosexual romance. Delilah's role only works if she's a woman; if a male character were the sarcastic conversational bulldozer, it would be almost impossible to avoid falling into the gender stereotype of a male rescuer. If this were a heterosexual romance trying to avoid that trap, the long-time friend who doesn't know how to directly confront Astrid would have to be the male protagonist. That could work, but it would be a tricky book to write without turning it into a story focused primarily on the subversion of gender roles. Making both protagonists women dodges the problem entirely and gives them so much narrative and conceptual space to simply be themselves, rather than characters obscured by the shadows of societal gender rules. This is also, at it's core, a book about friendship. Claire, Astrid, and Iris have the sort of close-knit friend group that looks exclusive and unapproachable from the outside. Delilah was the stereotypical outsider, mocked and excluded when they thought of her at all. This, at least, is how the dynamics look at the start of the book, but Blake did an impressive job of shifting my understanding of those relationships without changing their essential nature. She fleshes out all of the characters, not just the romantic leads, and adds complexity, nuance, and perspective. And, yes, past misunderstanding, but it's mostly not the cheap sort that sometimes drives romance plots. It's the misunderstanding rooted in remembered teenage social dynamics, the sort of misunderstanding that happens because communication is incredibly difficult, even more difficult when one has no practice or life experience, and requires knowing oneself well enough to even know what to communicate. The encounter between Delilah and Claire in the bar near the start of the book is cornerstone of the plot, but the moment that grabbed me and pulled me in was Delilah's first interaction with Claire's daughter Ruby. That was the point when I knew these were characters I could trust, and Blake never let me down. I love how Ruby is handled throughout this book, with all of the messy complexity of a kid of divorced parents with her own life and her own personality and complicated relationships with both parents that are independent of the relationship their parents have with each other. This is not a perfect book. There's one prank scene that I thought was excessively juvenile and should have been counter-productive, and there's one tricky question of (nonsexual) consent that the book raises and then later seems to ignore in a way that bugged me after I finished it. There is a third-act breakup, which is not my favorite plot structure, but I think Blake handles it reasonably well. I would probably find more niggles and nitpicks if I re-read it more slowly. But it was utterly engrossing reading that exactly matched my mood the day that I picked it up, and that was a fantastic reading experience. I'm not much of a romance reader and am not the traditional audience for sapphic romance, so I'm probably not the person you should be looking to for recommendations, but this is the sort of book that got me to immediately buy all of the sequels and start thinking about a re-read. It's also the sort of book that dragged me back in for several chapters when I was fact-checking bits of my review. Take that recommendation for whatever it's worth. Content note: Reviews of Delilah Green Doesn't Care tend to call it steamy or spicy. I have no calibration for this for romance novels. I did not find it very sex-focused (I have read genre fantasy novels with more sex), but there are several on-page sex scenes if that's something you care about one way or the other. Followed by Astrid Parker Doesn't Fail. Rating: 9 out of 10

14 November 2024

Stefano Zacchiroli: In memory of Lunar

In memory of Lunar I've had the incredible fortune to share the geek path of Lunar through life on multiple occasions. First, in Debian, beginning some 15+ years ago, where we were fellow developers and participated in many DebConf editions together. Then, on the deontology committee of Nos Oignons, a non-profit organization initiated by Lunar to operate Tor relays in France. This was with the goal of diversifying relay operators and increasing access to censorship-resistance technology for everyone in the world. It was something truly innovative and unheard of at the time in France. Later, as a member of the steering committee of Reproducible Builds, a project that Lunar brought to widespread geek popularity with a seminal "Birds of a Feather" session at DebConf13 (and then many other talks with fellow members of the project in the years to come). A decade later, Reproducible Builds is having a major impact throughout the software industry, primarily due to growing fears about the security of the software supply chain. Finally, we had the opportunity to recruit Lunar a couple of years ago at Software Heritage, where he insisted on working until he was able to, as part of a team he loved, and that loved him back. In addition to his numerous technical contributions to the initiative, he also facilitated our first ever multi-day team seminar. The event was so successful that it has been confirmed as a long-awaited yearly recurrence by all team members. I fondly remember one of the last conversations I had with Lunar, a few months ago, when he told me how proud he was not only of having started Nos Oignons and contributed to the ignition of Reproducible Builds, but specifically about the fact that both initiatives were now thriving without being dependent on him. He was likely thinking about a future world without him, but also realizing how impactful his activism had been on the past and present world. Lunar changed the world for the better and left behind a trail of love and fond memories. Che la terra ti sia lieve, compagno. --- Zack

12 November 2024

Paul Tagliamonte: Complex for Whom?

In basically every engineering organization I ve ever regarded as particularly high functioning, I ve sat through one specific recurring conversation which is not a conversation about complexity . Things are good or bad because they are or aren t complex, architectures needs to be redone because it s too complex some refactor of whatever it is won t work because it s too complex. You may have even been a part of some of these conversations or even been the one advocating for simple light-weight solutions. I ve done it. Many times. Rarely, if ever, do we talk about complexity within its rightful context complexity for whom. Is a solution complex because it s complex for the end user? Is it complex if it s complex for an API consumer? Is it complex if it s complex for the person maintaining the API service? Is it complex if it s complex for someone outside the team maintaining it to understand? Complexity within a problem domain I ve come to believe, is fairly zero-sum there s a fixed amount of complexity in the problem to be solved, and you can choose to either solve it, or leave it for those downstream of you to solve that problem on their own. That being said, while I believe there is a lower bound in complexity to contend with for a problem, I do not believe there is an upper bound to the complexity of solutions possible. It is always possible, and in fact, very likely that teams create problems for themselves while trying to solve a problem. The rest of this post is talking to the lower bound. When getting feedback on an early draft of this blog post, I ve been informed that Fred Brooks coined a term for what I call lower bound complexity Essential Complexity , in the paper No Silver Bullet Essence and Accident in Software Engineering , which is a better term and can be used interchangeably.

Complexity Culture In a large enough organization, where the team is high functioning enough to have and maintain trust amongst peers, members of the team will specialize. People will begin to engage with subsets of the work to be done, and begin to have their efficacy measured against that part of the organization s problems. Incentives shift, and over time it becomes increasingly likely that two engineers may have two very different priorities when working on the same system together. Someone accountable for uptime and tasked with responding to outages will begin to resist changes. Someone accountable for rapidly delivering features will resist gates between them and their users. Companies (either wittingly or unwittingly) will deal with this by tasking engineers with both production (feature development) and operational tasks (maintenance), so the difference in incentives isn t usually as bad as it could be. When we get a bunch of folks from far-flung corners of an organization in a room, fire up a slide deck and throw up some aspirational to-be architecture diagram in order to get a sign-off to solve some problem (be it someone needs a credible promotion packet, new feature needs to get delivered, or the system has begun to fail and needs fixing), the initial reaction will, more often than I d like, start to devolve into a discussion of how this is going to introduce a bunch of complexity, going to be hard to maintain, why can t you make it less complex? Right around here is when I start to try and contextualize the conversation happening around me understand what complexity is that being discussed, and understand who is taking on that burden. Think about who should be owning that problem, and work through the tradeoffs involved. Is it best solved here, or left to consumers (be them other systems, developers, or users). Should something become an API call s optional param, taking on all the edge-cases and on, or should users have to implement the logic using the data you return (leaving everyone else to take on all the edge-cases and maintenance)? Should you process the data, or require the user to preprocess it for you? Frequently it s right to make an active and explicit decision to simplify and leave problems to be solved downstream, since they may not actually need to be solved or perhaps you expect consumers will want to own the specifics of how the problem is solved, in which case you leave lots of documentation and examples. Many other times, especially when it s something downstream consumers are likely to hit, it s best solved internal to the system, since the only thing that can come of leaving it unsolved are bugs, frustration and half-correct solutions. This is a grey-space of tradeoffs, not a clear decision tree. No one wants the software manifestation of a katamari ball or a junk drawer, nor does anyone want a half-baked service unable to handle the simplest use-case.

Head-in-sand as a Service Popoffs about how complex something is, are, to a first approximation, best understood as meaning complicated for the person making comments . A lot of the #thoughtleadership believe that an AWS hosted EKS k8s cluster running images built by CI talking to an AWS hosted PostgreSQL RDS is not complex. They re right. Mostly right. This is less complex less complex for them. It s not, however, without complexity and its own tradeoffs it s just complexity that they do not have to deal with. Now they don t have to maintain machines that have pesky operating systems or hard drive failures. They don t have to deal with updating the version of k8s, nor ensuring the backups work. No one has to push some artifact to prod manually. Deployments happen unattended. You click a button and get a cluster. On the other hand, developers outside the ops function need to deal with troubleshooting CI, debugging access control rules encoded in turing complete YAML, permissions issues inside the cluster due to whatever the fuck a service mesh is, everyone needs to learn how to use some k8s tools they only actually use during a bad day, likely while doing some x.509 troubleshooting to connect to the cluster (an internal only endpoint; just port forward it) not to mention all sorts of rules to route packets to their project (a single repo s binary being run in 3 containers on a single vm host). Beyond that, there s the invisible complexity complexity on the interior of a service you depend on. I think about the dozens of teams maintaining the EKS service (which is either run on EC2 instances, or alternately, EC2 instances in a trench coat, moustache and even more shell scripts), the RDS service (also EC2 and shell scripts, but this time accounting for redundancy, backups, availability zones), scores of hypervisors pulled off the shelf (xen, kvm) smashed together with the ones built in-house (firecracker, nitro, etc) running on hardware that has to be refreshed and maintained continuously. Every request processed by network ACL rules, AWS IAM rules, security group rules, using IP space announced to the internet wired through IXPs directly into ISPs. I don t even want to begin to think about the complexity inherent in how those switches are designed. Shitloads of complexity to solve problems you may or may not have, or even know you had. What s more complex? An app running in an in-house 4u server racked in the office s telco closet in the back running off the office Verizon line, or an app running four hypervisors deep in an AWS datacenter? Which is more complex to you? What about to your organization? In total? Which is more prone to failure? Which is more secure? Is the complexity good or bad? What type of Complexity can you manage effectively? Which threaten the system? Which threaten your users?

COMPLEXIVIBES This extends beyond Engineering. Decisions regarding what tools are we able to use be them existing contracts with cloud providers, CIO mandated SaaS products, a list of the only permissible open source projects will incur costs in terms of expressed complexity . Pinning open source projects to a fixed set makes SBOM production less complex . Using only one SaaS provider s product suite (even if its terrible, because it has all the types of tools you need) makes accreditation less complex . If all you have is a contract with Pauly T s lowest price technically acceptable artisinal cloudary and haberdashery, the way you pay for your compute is less complex for the CIO shop, though you will find yourself building your own hosted database template, mechanism to spin up a k8s cluster, and all the operational and technical burden that comes with it. Or you won t and make it everyone else s problem in the organization. Nothing you can do will solve for the fact that you must now deal with this problem somewhere because it was less complicated for the business to put the workloads on the existing contract with a cut-rate vendor. Suddenly, the decision to reduce complexity because of an existing contract vehicle has resulted in a huge amount of technical risk and maintenance burden being onboarded. Complexity you would otherwise externalize has now been taken on internally. With a large enough organizations (specifically, in this case, i m talking about you, bureaucracies), this is largely ignored or accepted as normal since the personnel cost is understood to be free to everyone involved. Doing it this way is more expensive, more work, less reliable and less maintainable, and yet, somehow, is, in a lot of ways, less complex to the organization. It s particularly bad with bureaucracies, since screwing up a contract will get you into much more trouble than delivering a broken product, leaving basically no reason for anyone to care to fix this. I can t shake the feeling that for every story of technical mandates gone awry, somewhere just out of sight there s a decisionmaker optimizing for what they believe to be the least amount of complexity least hassle, fewest unique cases, most consistency as they can. They freely offload complexity from their accreditation and risk acceptance functions through mandates. They will never have to deal with it. That does not change the fact that someone does.

TC;DR (TOO COMPLEX; DIDN T REVIEW) We wish to rid ourselves of systemic Complexity after all, complexity is bad, simplicity is good. Removing upper-bound own-goal complexity ( accidental complexity in Brooks s terms) is important, but once you hit the lower bound complexity, the tradeoffs become zero-sum. Removing complexity from one part of the system means that somewhere else maybe outside your organization or in a non-engineering function must grow it back. Sometimes, the opposite is the case, such as when a previously manual business processes is automated. Maybe that s a good idea. Maybe it s not. All I know is that what doesn t help the situation is conflating complexity with everything we don t like legacy code, maintenance burden or toil, cost, delivery velocity.
  • Complexity is not the same as proclivity to failure. The most reliable systems I ve interacted with are unimaginably complex, with layers of internal protection to prevent complete failure. This has its own set of costs which other people have written about extensively.
  • Complexity is not cost. Sometimes the cost of taking all the complexity in-house is less, for whatever value of cost you choose to use.
  • Complexity is not absolute. Something simple from one perspective may be wildly complex from another. The impulse to burn down complex sections of code is helpful to have generally, but sometimes things are complicated for a reason, even if that reason exists outside your codebase or organization.
  • Complexity is not something you can remove without introducing complexity elsewhere. Just as not making a decision is a decision itself; choosing to require someone else to deal with a problem rather than dealing with it internally is a choice that needs to be considered in its full context.
Next time you re sitting through a discussion and someone starts to talk about all the complexity about to be introduced, I want to pop up in the back of your head, politely asking what does complex mean in this context? Is it lower bound complexity? Is this complexity desirable? Is what they re saying mean something along the lines of I don t understand the problems being solved, or does it mean something along the lines of this problem should be solved elsewhere? Do they believe this will result in more work for them in a way that you don t see? Should this not solved at all by changing the bounds of what we should accept or redefine the understood limits of this system? Is the perceived complexity a result of a decision elsewhere? Who s taking this complexity on, or more to the point, is failing to address complexity required by the problem leaving it to others? Does it impact others? How specifically? What are you not seeing? What can change? What should change?

11 November 2024

Vincent Bernat: Customize Caddy's plugins with Nix

Caddy is an open-source web server written in Go. It handles TLS certificates automatically and comes with a simple configuration syntax. Users can extend its functionality through plugins1 to add features like rate limiting, caching, and Docker integration. While Caddy is available in Nixpkgs, adding extra plugins is not simple.2 The compilation process needs Internet access, which Nix denies during build to ensure reproducibility. When trying to build the following derivation using xcaddy, a tool for building Caddy with plugins, it fails with this error: dial tcp: lookup proxy.golang.org on [::1]:53: connection refused.
  pkgs  :
pkgs.stdenv.mkDerivation  
  name = "caddy-with-xcaddy";
  nativeBuildInputs = with pkgs; [ go xcaddy cacert ];
  unpackPhase = "true";
  buildPhase =
    ''
      xcaddy build --with github.com/caddy-dns/powerdns@v1.0.1
    '';
  installPhase = ''
    mkdir -p $out/bin
    cp caddy $out/bin
  '';
 
Fixed-output derivations are an exception to this rule and get network access during build. They need to specify their output hash. For example, the fetchurl function produces a fixed-output derivation:
  stdenv, fetchurl  :
stdenv.mkDerivation rec  
  pname = "hello";
  version = "2.12.1";
  src = fetchurl  
    url = "mirror://gnu/hello/hello-$ version .tar.gz";
    hash = "sha256-jZkUKv2SV28wsM18tCqNxoCZmLxdYH2Idh9RLibH2yA=";
   ;
 
To create a fixed-output derivation, you need to set the outputHash attribute. The example below shows how to output Caddy s source code, with some plugin enabled, as a fixed-output derivation using xcaddy and go mod vendor.
pkgs.stdenvNoCC.mkDerivation rec  
  pname = "caddy-src-with-xcaddy";
  version = "2.8.4";
  nativeBuildInputs = with pkgs; [ go xcaddy cacert ];
  unpackPhase = "true";
  buildPhase =
    ''
      export GOCACHE=$TMPDIR/go-cache
      export GOPATH="$TMPDIR/go"
      XCADDY_SKIP_BUILD=1 TMPDIR="$PWD" \
        xcaddy build v$ version  --with github.com/caddy-dns/powerdns@v1.0.1
      (cd buildenv* && go mod vendor)
    '';
  installPhase = ''
    mv buildenv* $out
  '';
  outputHash = "sha256-F/jqR4iEsklJFycTjSaW8B/V3iTGqqGOzwYBUXxRKrc=";
  outputHashAlgo = "sha256";
  outputHashMode = "recursive";
 
With a fixed-output derivation, it is up to us to ensure the output is always the same: You can use this derivation to override the src attribute in pkgs.caddy:
pkgs.caddy.overrideAttrs (prev:  
  src = pkgs.stdenvNoCC.mkDerivation   /* ... */  ;
  vendorHash = null;
  subPackages = [ "." ];
 );
Check out the complete example in the GitHub repository. To integrate into a Flake, add github:vincentbernat/caddy-nix as an overlay:
 
  inputs =  
    nixpkgs.url = "nixpkgs";
    flake-utils.url = "github:numtide/flake-utils";
    caddy.url = "github:vincentbernat/caddy-nix";
   ;
  outputs =   self, nixpkgs, flake-utils, caddy  :
    flake-utils.lib.eachDefaultSystem (system:
      let
        pkgs = import nixpkgs  
          inherit system;
          overlays = [ caddy.overlays.default ];
         ;
      in
       
        packages =  
          default = pkgs.caddy.withPlugins  
            plugins = [ "github.com/caddy-dns/powerdns@v1.0.1" ];
            hash = "sha256-F/jqR4iEsklJFycTjSaW8B/V3iTGqqGOzwYBUXxRKrc=";
           ;
         ;
       );
 

Update (2024-11) This flake won t work with Nixpkgs 24.05 or older because it relies on this commit to properly override the vendorHash attribute.


  1. This article uses the term plugins, though Caddy documentation also refers to them as modules since they are implemented as Go modules.
  2. This is a feature request since quite some time. A proposed solution has been rejected. The one described in this article is a bit different and I have proposed it in another pull request.
  3. This is not perfect: if the source code produced by xcaddy changes, the hash would change and the build would fail.

9 November 2024

Jonathan Dowland: Progressively enhancing CGI apps with htmx

I was interested in learning about htmx, so I used it to improve the experience of posting comments on my blog. It seems much of modern web development is structured around having a JavaScript program on the front-end (browser) which exchanges data encoded in JSON asynchronously with the back-end servers. htmx uses a novel (or throwback) approach: it asynchronously fetches snippets of HTML from the back-end, and splices the results into the live page. For example, a htmx-powered button may request a URI on the server, receive HTML in response, and then the button itself would be replaced by the resulting HTML, within the page. I experimented with incorporating it into an existing, old-school CGI web app: IkiWiki, which I became a co-maintainer of this year, and powers my blog. Throughout this project I referred to the excellent book Server-Driven Web Apps with htmx. Comment posting workflow I really value blog comments, but the UX for posting them on my blog was a bit clunky. It went like this:
  1. you load a given page (such as this blog post), which is a static HTML document. There's a link to add a comment to the page.
  2. The link loads a new page which is generated dynamically and served back to you via CGI. This contains a HTML form for you to write your comment.
  3. The form submits to the server via HTTP POST. IkiWiki validates the form content. Various static pages (in particular the one you started on, in Step 1) are regenerated.
  4. the server response to the request in (3) is a HTTP 302 redirect, instructing the browser to go back to the page in Step 1.
First step: fetching a comment form First, I wanted the "add a comment" link to present the edit box in the current page. This step was easiest: add four attributes to the "comment on this page" anchor tag:
hx-get="<CGI ENDPOINT GOES HERE>"
suppresses the normal behaviour of the tag, so clicking on it doesn't load a new page.
issues an asynchronous HTTP GET to the CGI end-point, which returns the full HTML document for the comment edit form
hx-select=".editcomment form"
extract the edit-comment form from within that document
hx-swap=beforeend and hx-target=".addcomment"
append (courtesy of beforeend) the form into the source page after the "add comment" anchor tag (.addcomment)
Now, clicking "comment on this page" loads in the edit-comment box below it without moving you away from the source page. All that without writing any new code! Second step: handling previews
The old Preview Comment page The old Preview Comment page
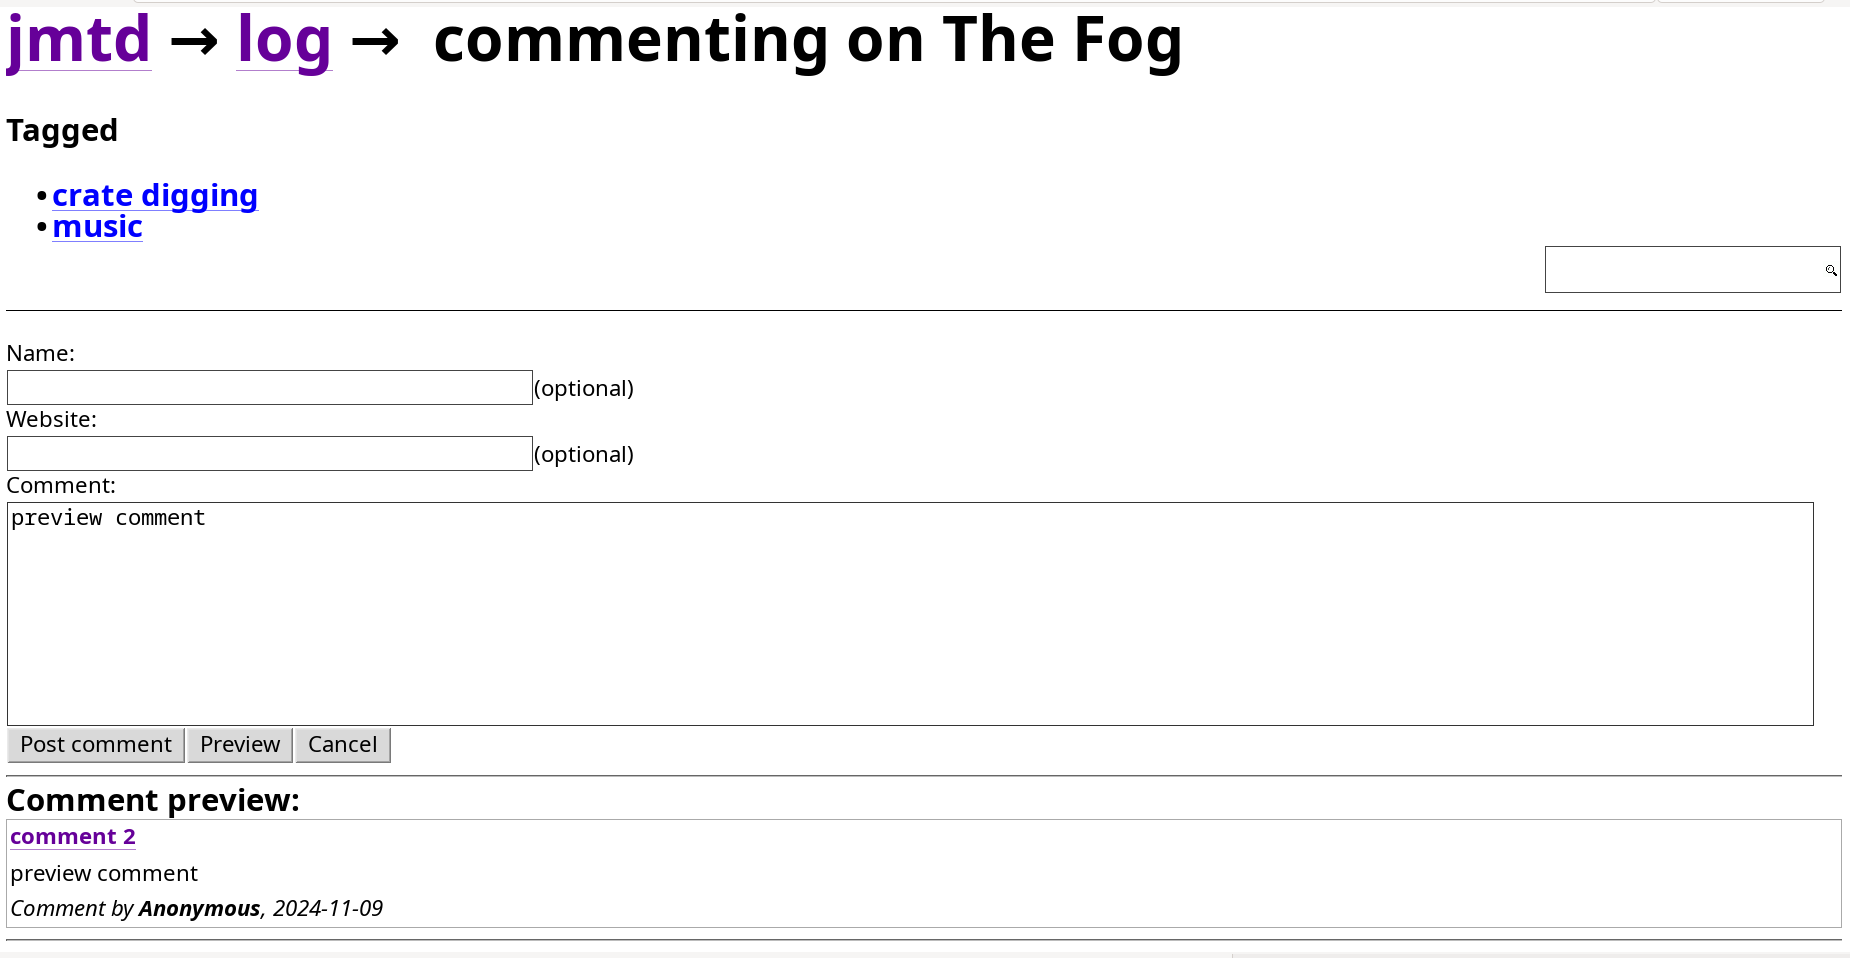
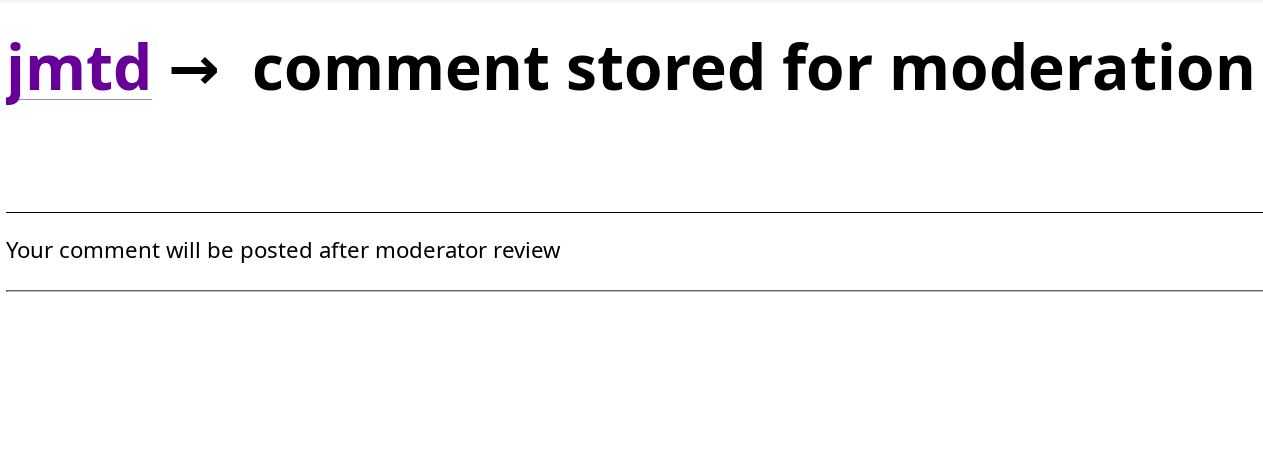
In the traditional workflow, clicking on "Preview" loaded a new page containing the edit form (but not the original page or any existing comments) with a rendering of the comment-in-progress below it. I wasn't originally interested in supporting the "Preview" feature, but I needed to for reasons I'll explain later. Rather than load new pages, I wanted "Preview" to insert a rendering of the comment-in-progress being inserted into the current page's list of comments, marked up to indicate that it's a preview. IkiWiki provides some templates which you can override to customise your site. I've long overridden page.tmpl, the template used for all pages. I needed to add a new empty div tag in order to have a "hook" to target with the previewed comment. The rest of this was achieved with htmx attributes on the "Preview" button, similar to in the last step: hx-post to define a target URI when you click the button (and specify HTTP POST); hx-select to filter the resulting HTML and extract the comment; hx-target to specify where to insert it. Now, clicking "Preview" does not leave the current page, but fetches a rendering of your comment-in-progress, and splices it into the comment list, appropriately marked up to be clear it's a preview. Third step: handling submitted comments IkiWiki is highly configurable, and many different things could happen once you post a comment. On my personal blog, all comments are held for moderation before they are published. The page you were served after submitting a comment was rather bare-bones, a status message "Your comment will be posted after moderator review", without the original page content or comments. I wanted your comment to appear in the page immediately, albeit marked up to indicate it was awaiting review. Since the traditional workflow didn't render or present your comment to you, I had to cheat. handling moderated comments
Moderation message upon submitting a comment Moderation message upon submitting a comment
One of my goals with this project was not to modify IkiWiki itself. I had to break this rule for moderated comments. When returning the "comment is moderated" page, IkiWiki uses HTTP status code 200, the same as for other scenarios. I wrote a tiny patch to return HTTP 202 (Accepted, but not processed) instead. I now have to write some actual JavaScript. htmx emits the htmx:beforeSwap event after an AJAX call returns, but before the corresponding swap is performed. I wrote a function that is triggered on this event, filters for HTTP 202 responses, triggers the "Preview" button, and then alters the result to indicate a moderated, rather than previewed, comment. (That's why I bothered to implement previews). You can read the full function here: jon.js. Summary I've done barely any front-end web development for years and I found working with htmx to be an enjoyable experience. You can leave a comment on this very blog post if you want to see it in action. I couldn't resist adding an easter egg: Brownie points if you can figure out what it is. Adding htmx to an existing CGI-based website let me improve one of the workflows in a gracefully-degrading way (without JavaScript, the old method will continue to work fine) without modifying the existing application itself (well, almost) and without having to write very much code of my own at all: nearly all of the configuration was declarative.

2 November 2024

Dirk Eddelbuettel: Rcpp 1.0.13-1 on CRAN: Hot Fix

rcpp logo A hot-fix release 1.0.13-1, consisting of two small PRs relative to the last regular CRAN release 1.0.13, just arrived on CRAN. When we prepared 1.0.13, we included a change related to the tightening of the C API of R itself. Sadly, we pinned an expected change to comes with next (minor) release 4.4.2 rather than now next (normal aka major) release 4.5.0 . And now that R 4.4.2 is out (as of two days ago) we accidentally broke building against the header file with that check. Whoops. Bugs happen, and we are truly sorry but this is now addressed in 1.0.13-1. The normal (bi-annual) release cycle will resume with 1.0.14 slated for January. As you can see from the NEWS file of the development branch, we have a number of changes coming. You can safely access that release candidate version, either off the default branch at github or via r-universe artifacts. The list below details all changes, as usual. The only other change concerns the now-mandatory use of Authors@R.

Changes in Rcpp release version 1.0.13-1 (2024-11-01)
  • Changes in Rcpp API:
    • Use read-only VECTOR_PTR and STRING_PTR only with with R 4.5.0 or later (Kevin in #1342 fixing #1341)
  • Changes in Rcpp Deployment:
    • Authors@R is now used in DESCRIPTION as mandated by CRAN

Thanks to my CRANberries, you can also look at a diff to the previous release Questions, comments etc should go to the rcpp-devel mailing list off the R-Forge page. Bugs reports are welcome at the GitHub issue tracker as well (where one can also search among open or closed issues). If you like this or other open-source work I do, you can sponsor me at GitHub.

This post by Dirk Eddelbuettel originated on his Thinking inside the box blog. Please report excessive re-aggregation in third-party for-profit settings.

21 October 2024

Russ Allbery: California general election

As usual with these every-two-year posts, probably of direct interest only to California residents. Maybe the more obscure things we're voting on will be a minor curiosity to people elsewhere. I'm a bit late this year, although not as late as last year, so a lot of people may have already voted, but I've been doing this for a while and wanted to keep it up. This post will only be about the ballot propositions. I don't have anything useful to say about the candidates that isn't hyper-local. I doubt anyone who has read my posts will be surprised by which candidates I'm voting for. As always with Calfornia ballot propositions, it's worth paying close attention to which propositions were put on the ballot by the legislature, usually because there's some state law requirement (often that I disagree with) that they be voted on by the public, and propositions that were put on the ballot by voter petition. The latter are often poorly written and have hidden problems. As a general rule of thumb, I tend to default to voting against propositions added by petition. This year, one can conveniently distinguish by number: the single-digit propositions were added by the legislature, and the two-digit ones were added by petition. Proposition 2: YES. Issue $10 billion in bonds for public school infrastructure improvements. I generally vote in favor of spending measures like this unless they have some obvious problem. The opposition argument is a deranged rant against immigrants and government debt and fails to point out actual problems. The opposition argument also claims this will result in higher property taxes and, seriously, if only that were true. That would make me even more strongly in favor of it. Proposition 3: YES. Enshrines the right to marriage without regard to sex or race into the California state constitution. This is already the law given US Supreme Court decisions, but fixing California state law is a long-overdue and obvious cleanup step. One of the quixotic things I would do if I were ever in government, which I will never be, would be to try to clean up the laws to make them match reality, repealing all of the dead clauses that were overturned by court decisions or are never enforced. I am in favor of all measures in this direction even when I don't agree with the direction of the change; here, as a bonus, I also strongly agree with the change. Proposition 4: YES. Issue $10 billion in bonds for infrastructure improvements to mitigate climate risk. This is basically the same argument as Proposition 2. The one drawback of this measure is that it's kind of a mixed grab bag of stuff and probably some of it should be supported out of the general budget rather than bonds, but I consider this a minor problem. We definitely need to ramp up climate risk mitigation efforts. Proposition 5: YES. Reduces the required super-majority to pass local bond measures for affordable housing from 67% to 55%. The fact that this requires a supermajority at all is absurd, California desperately needs to build more housing of any kind however we can, and publicly funded housing is an excellent idea. Proposition 6: YES. Eliminates "involuntary servitude" (in other words, "temporary" slavery) as a legally permissible punishment for crimes in the state of California. I'm one of the people who think the 13th Amendment to the US Constitution shouldn't have an exception for punishment for crimes, so obviously I'm in favor of this. This is one very, very tiny step towards improving the absolutely atrocious prison conditions in the state. Proposition 32: YES. Raises the minimum wage to $18 per hour from the current $16 per hour, over two years, and ties it to inflation. This is one of the rare petition-based propositions that I will vote in favor of because it's very straightforward, we clearly should be raising the minimum wage, and living in California is absurdly expensive because we refuse to build more housing (see Propositions 5 and 33). The opposition argument is the standard lie that a higher minimum wage will increase unemployment, which we know from numerous other natural experiments is simply not true. Proposition 33: NO. Repeals Costa-Hawkins, which prohibits local municipalities from enacting rent control on properties built after 1995. This one is going to split the progressive vote rather badly, I suspect. California has a housing crisis caused by not enough housing supply. It is not due to vacant housing, as much as some people would like you to believe that; the numbers just don't add up. There are way more people living here and wanting to live here than there is housing, so we need to build more housing. Rent control serves a valuable social function of providing stability to people who already have housing, but it doesn't help, and can hurt, the project of meeting actual housing demand. Rent control alone creates a two-tier system where people who have housing are protected but people who don't have housing have an even harder time getting housing than they do today. It's therefore quite consistent with the general NIMBY playbook of trying to protect the people who already have housing by making life harder for the people who do not, while keeping the housing supply essentially static. I am in favor of rent control in conjunction with real measures to increase the housing supply. I am therefore opposed to this proposition, which allows rent control without any effort to increase housing supply. I am quite certain that, if this passes, some municipalities will use it to make constructing new high-density housing incredibly difficult by requiring it all be rent-controlled low-income housing, thus cutting off the supply of multi-tenant market-rate housing entirely. This is already a common political goal in the part of California where I live. Local neighborhood groups advocate for exactly this routinely in local political fights. Give me a mandate for new construction that breaks local zoning obstructionism, including new market-rate housing to maintain a healthy lifecycle of housing aging into affordable housing as wealthy people move into new market-rate housing, and I will gladly support rent control measures as part of that package. But rent control on its own just allocates winners and losers without addressing the underlying problem. Proposition 34: NO. This is an excellent example of why I vote against petition propositions by default. This is a law designed to affect exactly one organization in the state of California: the AIDS Healthcare Foundation. The reason for this targeting is disputed; one side claims it's because of the AHF support for Proposition 33, and another side claims it's because AHF is a slumlord abusing California state funding. I have no idea which side of this is true. I also don't care, because I am fundamentally opposed to writing laws this way. Laws should establish general, fair principles that are broadly applicable, not be written with bizarrely specific conditions (health care providers that operate multifamily housing) that will only be met by a single organization. This kind of nonsense creates bad legal codes and the legal equivalent of technical debt. Just don't do this. Proposition 35: YES. I am, reluctantly, voting in favor of this even though it is a petition proposition because it looks like a useful simplification and cleanup of state health care funding, makes an expiring tax permanent, and is supported by a very wide range of organizations that I generally trust to know what they're talking about. No opposition argument was filed, which I think is telling. Proposition 36: NO. I am resigned to voting down attempts to start new "war on drugs" nonsense for the rest of my life because the people who believe in this crap will never, ever, ever stop. This one has bonus shoplifting fear-mongering attached, something that touches on nasty local politics that have included large retail chains manipulating crime report statistics to give the impression that shoplifting is up dramatically. It's yet another round of the truly horrific California "three strikes" criminal penalty obsession, which completely misunderstands both the causes of crime and the (almost nonexistent) effectiveness of harsh punishment as deterrence.

20 October 2024

Bits from Debian: Ada Lovelace Day 2024 - Interview with some Women in Debian

Alt Ada Lovelace portrait Ada Lovelace Day was celebrated on October 8 in 2024, and on this occasion, to celebrate and raise awareness of the contributions of women to the STEM fields we interviewed some of the women in Debian. Here we share their thoughts, comments, and concerns with the hope of inspiring more women to become part of the Sciences, and of course, to work inside of Debian. This article was simulcasted to the debian-women mail list. Beatrice Torracca 1. Who are you? I am Beatrice, I am Italian. Internet technology and everything computer-related is just a hobby for me, not my line of work or the subject of my academic studies. I have too many interests and too little time. I would like to do lots of things and at the same time I am too Oblomovian to do any. 2. How did you get introduced to Debian? As a user I started using newsgroups when I had my first dialup connection and there was always talk about this strange thing called Linux. Since moving from DR DOS to Windows was a shock for me, feeling like I lost the control of my machine, I tried Linux with Debian Potato and I never strayed away from Debian since then for my personal equipment. 3. How long have you been into Debian? Define "into". As a user... since Potato, too many years to count. As a contributor, a similar amount of time, since early 2000 I think. My first archived email about contributing to the translation of the description of Debian packages dates 2001. 4. Are you using Debian in your daily life? If yes, how? Yes!! I use testing. I have it on my desktop PC at home and I have it on my laptop. The desktop is where I have a local IMAP server that fetches all the mails of my email accounts, and where I sync and back up all my data. On both I do day-to-day stuff (from email to online banking, from shopping to taxes), all forms of entertainment, a bit of work if I have to work from home (GNU R for statistics, LibreOffice... the usual suspects). At work I am required to have another OS, sadly, but I am working on setting up a Debian Live system to use there too. Plus if at work we start doing bioinformatics there might be a Linux machine in our future... I will of course suggest and hope for a Debian system. 5. Do you have any suggestions to improve women's participation in Debian? This is a tough one. I am not sure. Maybe, more visibility for the women already in the Debian Project, and make the newcomers feel seen, valued and welcomed. A respectful and safe environment is key too, of course, but I think Debian made huge progress in that aspect with the Code of Conduct. I am a big fan of promoting diversity and inclusion; there is always room for improvement. Ileana Dumitrescu (ildumi) 1. Who are you? I am just a girl in the world who likes cats and packaging Free Software. 2. How did you get introduced to Debian? I was tinkering with a computer running Debian a few years ago, and I decided to learn more about Free Software. After a search or two, I found Debian Women. 3. How long have you been into Debian? I started looking into contributing to Debian in 2021. After contacting Debian Women, I received a lot of information and helpful advice on different ways I could contribute, and I decided package maintenance was the best fit for me. I eventually became a Debian Maintainer in 2023, and I continue to maintain a few packages in my spare time. 4. Are you using Debian in your daily life? If yes, how? Yes, it is my favourite GNU/Linux operating system! I use it for email, chatting, browsing, packaging, etc. 5. Do you have any suggestions to improve women's participation in Debian? The mailing list for Debian Women may attract more participation if it is utilized more. It is where I started, and I imagine participation would increase if it is more engaging. Kathara Sasikumar (kathara) 1. Who are you? I'm Kathara Sasikumar, 22 years old and a recent Debian user turned Maintainer from India. I try to become a creative person through sketching or playing guitar chords, but it doesn't work! xD 2. How did you get introduced to Debian? When I first started college, I was that overly enthusiastic student who signed up for every club and volunteered for anything that crossed my path just like every other fresher. But then, the pandemic hit, and like many, I hit a low point. COVID depression was real, and I was feeling pretty down. Around this time, the FOSS Club at my college suddenly became more active. My friends, knowing I had a love for free software, pushed me to join the club. They thought it might help me lift my spirits and get out of the slump I was in. At first, I joined only out of peer pressure, but once I got involved, the club really took off. FOSS Club became more and more active during the pandemic, and I found myself spending more and more time with it. A year later, we had the opportunity to host a MiniDebConf at our college. Where I got to meet a lot of Debian developers and maintainers, attending their talks and talking with them gave me a wider perspective on Debian, and I loved the Debian philosophy. At that time, I had been distro hopping but never quite settled down. I occasionally used Debian but never stuck around. However, after the MiniDebConf, I found myself using Debian more consistently, and it truly connected with me. The community was incredibly warm and welcoming, which made all the difference. 3. How long have you been into Debian? Now, I've been using Debian as my daily driver for about a year. 4. Are you using Debian in your daily life? If yes, how? It has become my primary distro, and I use it every day for continuous learning and working on various software projects with free and open-source tools. Plus, I've recently become a Debian Maintainer (DM) and have taken on the responsibility of maintaining a few packages. I'm looking forward to contributing more to the Debian community Rhonda D'Vine (rhonda) 1. Who are you? My name is Rhonda, my pronouns are she/her, or per/pers. I'm 51 years old, working in IT. 2. How did you get introduced to Debian? I was already looking into Linux because of university, first it was SuSE. And people played around with gtk. But when they packaged GNOME and it just didn't even install I looked for alternatives. A working colleague from back then gave me a CD of Debian. Though I couldn't install from it because Slink didn't recognize the pcmcia drive. I had to install it via floppy disks, but apart from that it was quite well done. And the early GNOME was working, so I never looked back. 3. How long have you been into Debian? Even before I was more involved, a colleague asked me whether I could help with translating the release documentation. That was my first contribution to Debian, for the slink release in early 1999. And I was using some other software before on my SuSE systems, and I wanted to continue to use them on Debian obviously. So that's how I got involved with packaging in Debian. But I continued to help with translation work, for a long period of time I was almost the only person active for the German part of the website. 4. Are you using Debian in your daily life? If yes, how? Being involved with Debian was a big part of the reason I got into my jobs since a long time now. I always worked with maintaining Debian (or Ubuntu) systems. Privately I run Debian on my laptop, with occasionally switching to Windows in dual boot when (rarely) needed. 5. Do you have any suggestions to improve women's participation in Debian? There are factors that we can't influence, like that a lot of women are pushed into care work because patriarchal structures work that way, and don't have the time nor energy to invest a lot into other things. But we could learn to appreciate smaller contributions better, and not focus so much on the quantity of contributions. When we look at longer discussions on mailing lists, those that write more mails actually don't contribute more to the discussion, they often repeat themselves without adding more substance. Through working on our own discussion patterns this could create a more welcoming environment for a lot of people. Sophie Brun (sophieb) 1. Who are you? I'm a 44 years old French woman. I'm married and I have 2 sons. 2. How did you get introduced to Debian? In 2004 my boyfriend (now my husband) installed Debian on my personal computer to introduce me to Debian. I knew almost nothing about Open Source. During my engineering studies, a professor mentioned the existence of Linux, Red Hat in particular, but without giving any details. I learnt Debian by using and reading (in advance) The Debian Administrator's Handbook. 3. How long have you been into Debian? I've been a user since 2004. But I only started contributing to Debian in 2015: I had quit my job and I wanted to work on something more meaningful. That's why I joined my husband in Freexian, his company. Unlike most people I think, I started contributing to Debian for my work. I only became a DD in 2021 under gentle social pressure and when I felt confident enough. 4. Are you using Debian in your daily life? If yes, how? Of course I use Debian in my professional life for almost all the tasks: from administrative tasks to Debian packaging. I also use Debian in my personal life. I have very basic needs: Firefox, LibreOffice, GnuCash and Rhythmbox are the main applications I need. Sruthi Chandran (srud) 1. Who are you? A feminist, a librarian turned Free Software advocate and a Debian Developer. Part of Debian Outreach team and DebConf Committee. 2. How did you get introduced to Debian? I got introduced to the free software world and Debian through my husband. I attended many Debian events with him. During one such event, out of curiosity, I participated in a Debian packaging workshop. Just after that I visited a Tibetan community in India and they mentioned that there was no proper Tibetan font in GNU/Linux. Tibetan font was my first package in Debian. 3. How long have you been into Debian? I have been contributing to Debian since 2016 and Debian Developer since 2019. 4. Are you using Debian in your daily life? If yes, how? I haven't used any other distro on my laptop since I got introduced to Debian. 5. Do you have any suggestions to improve women's participation in Debian? I was involved with actively mentoring newcomers to Debian since I started contributing myself. I specially work towards reducing the gender gap inside the Debian and Free Software community in general. In my experience, I believe that visibility of already existing women in the community will encourage more women to participate. Also I think we should reintroduce mentoring through debian-women. T ssia Cam es Ara jo (tassia) 1. Who are you? T ssia Cam es Ara jo, a Brazilian living in Canada. I'm a passionate learner who tries to push myself out of my comfort zone and always find something new to learn. I also love to mentor people on their learning journey. But I don't consider myself a typical geek. My challenge has always been to not get distracted by the next project before I finish the one I have in my hands. That said, I love being part of a community of geeks and feel empowered by it. I love Debian for its technical excellence, and it's always reassuring to know that someone is taking care of the things I don't like or can't do. When I'm not around computers, one of my favorite things is to feel the wind on my cheeks, usually while skating or riding a bike; I also love music, and I'm always singing a melody in my head. 2. How did you get introduced to Debian? As a student, I was privileged to be introduced to FLOSS at the same time I was introduced to computer programming. My university could not afford to have labs in the usual proprietary software model, and what seemed like a limitation at the time turned out to be a great learning opportunity for me and my colleagues. I joined this student-led initiative to "liberate" our servers and build LTSP-based labs - where a single powerful computer could power a few dozen diskless thin clients. How revolutionary it was at the time! And what an achievement! From students to students, all using Debian. Most of that group became close friends; I've married one of them, and a few of them also found their way to Debian. 3. How long have you been into Debian? I first used Debian in 2001, but my first real connection with the community was attending DebConf 2004. Since then, going to DebConfs has become a habit. It is that moment in the year when I reconnect with the global community and my motivation to contribute is boosted. And you know, in 20 years I've seen people become parents, grandparents, children grow up; we've had our own child and had the pleasure of introducing him to the community; we've mourned the loss of friends and healed together. I'd say Debian is like family, but not the kind you get at random once you're born, Debian is my family by choice. 4. Are you using Debian in your daily life? If yes, how? These days I teach at Vanier College in Montr al. My favorite course to teach is UNIX, which I have the pleasure of teaching mostly using Debian. I try to inspire my students to discover Debian and other FLOSS projects, and we are happy to run a FLOSS club with participation from students, staff and alumni. I love to see these curious young minds put to the service of FLOSS. It is like recruiting soldiers for a good battle, and one that can change their lives, as it certainly did mine. 5. Do you have any suggestions to improve women's participation in Debian? I think the most effective way to inspire other women is to give visibility to active women in our community. Speaking at conferences, publishing content, being vocal about what we do so that other women can see us and see themselves in those positions in the future. It's not easy, and I don't like being in the spotlight. It took me a long time to get comfortable with public speaking, so I can understand the struggle of those who don't want to expose themselves. But I believe that this space of vulnerability can open the way to new connections. It can inspire trust and ultimately motivate our next generation. It's with this in mind that I publish these lines. Another point we can't neglect is that in Debian we work on a volunteer basis, and this in itself puts us at a great disadvantage. In our societies, women usually take a heavier load than their partners in terms of caretaking and other invisible tasks, so it is hard to afford the free time needed to volunteer. This is one of the reasons why I bring my son to the conferences I attend, and so far I have received all the support I need to attend DebConfs with him. It is a way to share the caregiving burden with our community - it takes a village to raise a child. Besides allowing us to participate, it also serves to show other women (and men) that you can have a family life and still contribute to Debian. My feeling is that we are not doing super well in terms of diversity in Debian at the moment, but that should not discourage us at all. That's the way it is now, but that doesn't mean it will always be that way. I feel like we go through cycles. I remember times when we had many more active female contributors, and I'm confident that we can improve our ratio again in the future. In the meantime, I just try to keep going, do my part, attract those I can, reassure those who are too scared to come closer. Debian is a wonderful community, it is a family, and of course a family cannot do without us, the women. These interviews were conducted via email exchanges in October, 2024. Thanks to all the wonderful women who participated in this interview. We really appreciate your contributions in Debian and to Free/Libre software.

15 October 2024

Andrew Cater: Mini-DebConf Cambridge 20241013 1300

LATE NEWS I haven't blogged until now: I should have done from Thursday onwards.

It's a joy to be here in Cambridge at ARM HQ. Lots of people I recognise from last year here: lots *not* here because this mini-conference is a month before the next one in Toulouse and many people can't attend both.

Two days worth of chatting, working on bits and pieces, chatting and informal meetings was a very good and useful way to build relationships and let teams find some space for themselves.

Lots of quiet hacking going on - a few loud conversations. A new ARM machine in mini-ITX format - see Steve McIntyre's blog on planet.debian.org about Rock 5 ITX.

Two days worth of talks for Saturday and Sunday. For some people, this is a first time. Lightning talks are particularly good to break down barriers - three slides and five minutes (and the chance for a bit of gamesmanship to break the rules creatively).

Longer talks: a couple from Steve Capper of ARM were particularly helpful to those interested in upcoming development. A couple of the talks in the schedule are traditional: if the release team are here, they tell us what they are doing, for example.

ARM are main sponsors and have been very generous in giving us conference and facilities space. Fast network, coffee and interested people - what's not to like :)[EDIT/UPDATE - And my talk is finished and went fairly well: slides have now been uploaded and the talk is linked from the Mini-DebConf pages]

10 October 2024

Freexian Collaborators: Debian Contributions: Packaging Pydantic v2, Reworking of glib2.0 for cross bootstrap, Python archive rebuilds and more! (by Anupa Ann Joseph)

Debian Contributions: 2024-09 Contributing to Debian is part of Freexian s mission. This article covers the latest achievements of Freexian and their collaborators. All of this is made possible by organizations subscribing to our Long Term Support contracts and consulting services.

Pydantic v2, by Colin Watson Pydantic is a useful library for validating data in Python using type hints: Freexian uses it in a number of projects, including Debusine. Its Debian packaging had been stalled at 1.10.17 in testing for some time, partly due to needing to make sure everything else could cope with the breaking changes introduced in 2.x, but mostly due to needing to sort out packaging of its new Rust dependencies. Several other people (notably Alexandre Detiste, Andreas Tille, Drew Parsons, and Timo R hling) had made some good progress on this, but nobody had quite got it over the line and it seemed a bit stuck. Colin upgraded a few Rust libraries to new upstream versions, packaged rust-jiter, and chased various failures in other packages. This eventually allowed getting current versions of both pydantic-core and pydantic into testing. It should now be much easier for us to stay up to date routinely.

Reworking of glib2.0 for cross bootstrap, by Helmut Grohne Simon McVittie (not affiliated with Freexian) earlier restructured the libglib2.0-dev such that it would absorb more functionality and in particular provide tools for working with .gir files. Those tools practically require being run for their host architecture (practically this means running under qemu-user) which is at odds with the requirements of architecture cross bootstrap. The qemu requirement was expressed in package dependencies and also made people unhappy attempting to use libglib2.0-dev for i386 on amd64 without resorting to qemu. The use of qemu in architecture bootstrap is particularly problematic as it tends to not be ready at the time bootstrapping is needed. As a result, Simon proposed and implemented the introduction of a libgio-2.0-dev package providing a subset of libglib2.0-dev that does not require qemu. Packages should continue to use libglib2.0-dev in their Build-Depends unless involved in architecture bootstrap. Helmut reviewed and tested the implementation and integrated the necessary changes into rebootstrap. He also prepared a patch for libverto to use the new package and proposed adding forward compatibility to glib2.0. Helmut continued working on adding cross-exe-wrapper to architecture-properties and implemented autopkgtests later improved by Simon. The cross-exe-wrapper package now provides a generic mechanism to a program on a different architecture by using qemu when needed only. For instance, a dependency on cross-exe-wrapper:i386 provides a i686-linux-gnu-cross-exe-wrapper program that can be used to wrap an ELF executable for the i386 architecture. When installed on amd64 or i386 it will skip installing or running qemu, but for other architectures qemu will be used automatically. This facility can be used to support cross building with targeted use of qemu in cases where running host code is unavoidable as is the case for GObject introspection. This concludes the joint work with Simon and Niels Thykier on glib2.0 and architecture-properties resolving known architecture bootstrap regressions arising from the glib2.0 refactoring earlier this year.

Analyzing binary package metadata, by Helmut Grohne As Guillem Jover (not affiliated with Freexian) continues to work on adding metadata tracking to dpkg, the question arises how this affects existing packages. The dedup.debian.net infrastructure provides an easy playground to answer such questions, so Helmut gathered file metadata from all binary packages in unstable and performed an explorative analysis. Some results include: Guillem also performed a cursory analysis and reported other problem categories such as mismatching directory permissions for directories installed by multiple packages and thus gained a better understanding of what consistency checks dpkg can enforce.

Python archive rebuilds, by Stefano Rivera Last month Stefano started to write some tooling to do large-scale rebuilds in debusine, starting with finding packages that had already started to fail to build from source (FTBFS) due to the removal of setup.py test. This month, Stefano did some more rebuilds, starting with experimental versions of dh-python. During the Python 3.12 transition, we had added a dependency on python3-setuptools to dh-python, to ease the transition. Python 3.12 removed distutils from the stdlib, but many packages were expecting it to still be available. Setuptools contains a version of distutils, and dh-python was a convenient place to depend on setuptools for most package builds. This dependency was never meant to be permanent. A rebuild without it resulted in mass-filing about 340 bugs (and around 80 more by mistake). A new feature in Python 3.12, was to have unittest s test runner exit with a non-zero return code, if no tests were run. We added this feature, to be able to detect tests that are not being discovered, by mistake. We are ignoring this failure, as we wouldn t want to suddenly cause hundreds of packages to fail to build, if they have no tests. Stefano did a rebuild to see how many packages were affected, and found that around 1000 were. The Debian Python community has not come to a conclusion on how to move forward with this. As soon as Python 3.13 release candidate 2 was available, Stefano did a rebuild of the Python packages in the archive against it. This was a more complex rebuild than the others, as it had to be done in stages. Many packages need other Python packages at build time, typically to run tests. So transitions like this involve some manual bootstrapping, followed by several rounds of builds. Not all packages could be tested, as not all their dependencies support 3.13 yet. The result was around 100 bugs in packages that need work to support Python 3.13. Many other packages will need additional work to properly support Python 3.13, but being able to build (and run tests) is an important first step.

Miscellaneous contributions
  • Carles prepared the update of python-pyaarlo package to a new upstream release.
  • Carles worked on updating python-ring-doorbell to a new upstream release. Unfinished, pending to package a new dependency python3-firebase-messaging RFP #1082958 and its dependency python3-http-ece RFP #1083020.
  • Carles improved po-debconf-manager. Main new feature is that it can open Salsa merge requests. Aiming for a lightning talk in MiniDebConf Toulouse (November) to be functional end to end and get feedback from the wider public for this proof of concept.
  • Carles helped one translator to use po-debconf-manager (added compatibility for bullseye, fixed other issues) and reviewed 17 package templates.
  • Colin upgraded the OpenSSH packaging to 9.9p1.
  • Colin upgraded the various YubiHSM packages to new upstream versions, enabled more tests, fixed yubihsm-shell build failures on some 32-bit architectures, made yubihsm-shell build reproducibly, and fixed yubihsm-connector to apply udev rules to existing devices when the package is installed. As usual, bookworm-backports is up to date with all these changes.
  • Colin fixed quite a bit of fallout from setuptools 72.0.0 removing setup.py test, backported a large upstream patch set to make buildbot work with SQLAlchemy 2.0, and upgraded 25 other Python packages to new upstream versions.
  • Enrico worked with Jakob Haufe to get him up to speed for managing sso.debian.org
  • Rapha l did remove spam entries in the list of teams on tracker.debian.org (see #1080446), and he applied a few external contributions, fixing a rendering issue and replacing the DDPO link with a more useful alternative. He also gave feedback on a couple of merge requests that required more work. As part of the analysis of the underlying problem, he suggested to the ftpmasters (via #1083068) to auto-reject packages having the too-many-contacts lintian error, and he raised the severity of #1076048 to serious to actually have that 4 year old bug fixed.
  • Rapha l uploaded zim and hamster-time-tracker to fix issues with Python 3.12 getting rid of setuptools. He also uploaded a new gnome-shell-extension-hamster to cope with the upcoming transition to GNOME 47.
  • Helmut sent seven patches and sponsored one upload for cross build failures.
  • Helmut uploaded a Nagios/Icinga plugin check-smart-attributes for monitoring the health of physical disks.
  • Helmut collaborated on sbuild reviewing and improving a MR for refactoring the unshare backend.
  • Helmut sent a patch fixing coinstallability of gcc-defaults.
  • Helmut continued to monitor the evolution of the /usr-move. With more and more key packages such as libvirt or fuse3 fixed. We re moving into the boring long-tail of the transition.
  • Helmut proposed updating the meson buildsystem in debhelper to use env2mfile.
  • Helmut continued to update patches maintained in rebootstrap. Due to the work on glib2.0 above, rebootstrap moves a lot further, but still fails for any architecture.
  • Santiago reviewed some Merge Request in Salsa CI, such as: !478, proposed by Otto to extend the information about how to use additional runners in the pipeline and !518, proposed by Ahmed to add support for Ubuntu images, that will help to test how some debian packages, including the complex MariaDB are built on Ubuntu. Santiago also prepared !545, which will make the reprotest job more consistent with the result seen on reproducible-builds.
  • Santiago worked on different tasks related to DebConf 25. Especially he drafted the fundraising brochure (which is almost ready).
  • Thorsten Alteholz uploaded package libcupsfilter to fix the autopkgtest and a dependency problem of this package. After package splix was abandoned by upstream and OpenPrinting.org adopted its maintenance, Thorsten uploaded their first release.
  • Anupa published posts on the Debian Administrators group in LinkedIn and moderated the group, one of the tasks of the Debian Publicity Team.
  • Anupa helped organize DebUtsav 2024. It had over 100 attendees with hand-on sessions on making initial contributions to Linux Kernel, Debian packaging, submitting documentation to Debian wiki and assisting Debian Installations.

9 October 2024

Ben Hutchings: FOSS activity in September 2024

7 October 2024

Reproducible Builds: Reproducible Builds in September 2024

Welcome to the September 2024 report from the Reproducible Builds project! Our reports attempt to outline what we ve been up to over the past month, highlighting news items from elsewhere in tech where they are related. As ever, if you are interested in contributing to the project, please visit our Contribute page on our website. Table of contents:
  1. New binsider tool to analyse ELF binaries
  2. Unreproducibility of GHC Haskell compiler 95% fixed
  3. Mailing list summary
  4. Towards a 100% bit-for-bit reproducible OS
  5. Two new reproducibility-related academic papers
  6. Distribution work
  7. diffoscope
  8. Other software development
  9. Android toolchain core count issue reported
  10. New Gradle plugin for reproducibility
  11. Website updates
  12. Upstream patches
  13. Reproducibility testing framework

New binsider tool to analyse ELF binaries Reproducible Builds developer Orhun Parmaks z has announced a fantastic new tool to analyse the contents of ELF binaries. According to the project s README page:
Binsider can perform static and dynamic analysis, inspect strings, examine linked libraries, and perform hexdumps, all within a user-friendly terminal user interface!
More information about Binsider s features and how it works can be found within Binsider s documentation pages.

Unreproducibility of GHC Haskell compiler 95% fixed A seven-year-old bug about the nondeterminism of object code generated by the Glasgow Haskell Compiler (GHC) received a recent update, consisting of Rodrigo Mesquita noting that the issue is:
95% fixed by [merge request] !12680 when -fobject-determinism is enabled. [ ]
The linked merge request has since been merged, and Rodrigo goes on to say that:
After that patch is merged, there are some rarer bugs in both interface file determinism (eg. #25170) and in object determinism (eg. #25269) that need to be taken care of, but the great majority of the work needed to get there should have been merged already. When merged, I think we should close this one in favour of the more specific determinism issues like the two linked above.

Mailing list summary On our mailing list this month:
  • Fay Stegerman let everyone know that she started a thread on the Fediverse about the problems caused by unreproducible zlib/deflate compression in .zip and .apk files and later followed up with the results of her subsequent investigation.
  • Long-time developer kpcyrd wrote that there has been a recent public discussion on the Arch Linux GitLab [instance] about the challenges and possible opportunities for making the Linux kernel package reproducible , all relating to the CONFIG_MODULE_SIG flag. [ ]
  • Bernhard M. Wiedemann followed-up to an in-person conversation at our recent Hamburg 2024 summit on the potential presence for Reproducible Builds in recognised standards. [ ]
  • Fay Stegerman also wrote about her worry about the possible repercussions for RB tooling of Debian migrating from zlib to zlib-ng as reproducibility requires identical compressed data streams. [ ]
  • Martin Monperrus wrote the list announcing the latest release of maven-lockfile that is designed aid building Maven projects with integrity . [ ]
  • Lastly, Bernhard M. Wiedemann wrote about potential role of reproducible builds in combatting silent data corruption, as detailed in a recent Tweet and scholarly paper on faulty CPU cores. [ ]

Towards a 100% bit-for-bit reproducible OS Bernhard M. Wiedemann began writing on journey towards a 100% bit-for-bit reproducible operating system on the openSUSE wiki:
This is a report of Part 1 of my journey: building 100% bit-reproducible packages for every package that makes up [openSUSE s] minimalVM image. This target was chosen as the smallest useful result/artifact. The larger package-sets get, the more disk-space and build-power is required to build/verify all of them.
This work was sponsored by NLnet s NGI Zero fund.

Distribution work In Debian this month, 14 reviews of Debian packages were added, 12 were updated and 20 were removed, all adding to our knowledge about identified issues. A number of issue types were updated as well. [ ][ ] In addition, Holger opened 4 bugs against the debrebuild component of the devscripts suite of tools. In particular:
  • #1081047: Fails to download .dsc file.
  • #1081048: Does not work with a proxy.
  • #1081050: Fails to create a debrebuild.tar.
  • #1081839: Fails with E: mmdebstrap failed to run error.
Last month, an issue was filed to update the Salsa CI pipeline (used by 1,000s of Debian packages) to no longer test for reproducibility with reprotest s build_path variation. Holger Levsen provided a rationale for this change in the issue, which has already been made to the tests being performed by tests.reproducible-builds.org. This month, this issue was closed by Santiago R. R., nicely explaining that build path variation is no longer the default, and, if desired, how developers may enable it again. In openSUSE news, Bernhard M. Wiedemann published another report for that distribution.

diffoscope diffoscope is our in-depth and content-aware diff utility that can locate and diagnose reproducibility issues. This month, Chris Lamb made the following changes, including preparing and uploading version 278 to Debian:
  • New features:
    • Add a helpful contextual message to the output if comparing Debian .orig tarballs within .dsc files without the ability to fuzzy-match away the leading directory. [ ]
  • Bug fixes:
    • Drop removal of calculated os.path.basename from GNU readelf output. [ ]
    • Correctly invert X% similar value and do not emit 100% similar . [ ]
  • Misc:
    • Temporarily remove procyon-decompiler from Build-Depends as it was removed from testing (via #1057532). (#1082636)
    • Update copyright years. [ ]
For trydiffoscope, the command-line client for the web-based version of diffoscope, Chris Lamb also:
  • Added an explicit python3-setuptools dependency. (#1080825)
  • Bumped the Standards-Version to 4.7.0. [ ]

Other software development disorderfs is our FUSE-based filesystem that deliberately introduces non-determinism into system calls to reliably flush out reproducibility issues. This month, version 0.5.11-4 was uploaded to Debian unstable by Holger Levsen making the following changes:
  • Replace build-dependency on the obsolete pkg-config package with one on pkgconf, following a Lintian check. [ ]
  • Bump Standards-Version field to 4.7.0, with no related changes needed. [ ]

In addition, reprotest is our tool for building the same source code twice in different environments and then checking the binaries produced by each build for any differences. This month, version 0.7.28 was uploaded to Debian unstable by Holger Levsen including a change by Jelle van der Waa to move away from the pipes Python module to shlex, as the former will be removed in Python version 3.13 [ ].

Android toolchain core count issue reported Fay Stegerman reported an issue with the Android toolchain where a part of the build system generates a different classes.dex file (and thus a different .apk) depending on the number of cores available during the build, thereby breaking Reproducible Builds:
We ve rebuilt [tag v3.6.1] multiple times (each time in a fresh container): with 2, 4, 6, 8, and 16 cores available, respectively:
  • With 2 and 4 cores we always get an unsigned APK with SHA-256 14763d682c9286ef .
  • With 6, 8, and 16 cores we get an unsigned APK with SHA-256 35324ba4c492760 instead.

New Gradle plugin for reproducibility A new plugin for the Gradle build tool for Java has been released. This easily-enabled plugin results in:
reproducibility settings [being] applied to some of Gradle s built-in tasks that should really be the default. Compatible with Java 8 and Gradle 8.3 or later.

Website updates There were a rather substantial number of improvements made to our website this month, including:

Upstream patches The Reproducible Builds project detects, dissects and attempts to fix as many currently-unreproducible packages as possible. We endeavour to send all of our patches upstream where appropriate. This month, we wrote a large number of such patches, including:

Reproducibility testing framework The Reproducible Builds project operates a comprehensive testing framework running primarily at tests.reproducible-builds.org in order to check packages and other artifacts for reproducibility. In September, a number of changes were made by Holger Levsen, including:
  • Debian-related changes:
    • Upgrade the osuosl4 node to Debian trixie in anticipation of running debrebuild and rebuilderd there. [ ][ ][ ]
    • Temporarily mark the osuosl4 node as offline due to ongoing xfs_repair filesystem maintenance. [ ][ ]
    • Do not warn about (very old) broken nodes. [ ]
    • Add the risc64 architecture to the multiarch version skew tests for Debian trixie and sid. [ ][ ][ ]
    • Mark the virt 32,64 b nodes as down. [ ]
  • Misc changes:
    • Add support for powercycling OpenStack instances. [ ]
    • Update the fail2ban to ban hosts for 4 weeks in total [ ][ ] and take care to never ban our own Jenkins instance. [ ]
In addition, Vagrant Cascadian recorded a disk failure for the virt32b and virt64b nodes [ ], performed some maintenance of the cbxi4a node [ ][ ] and marked most armhf architecture systems as being back online.

Finally, If you are interested in contributing to the Reproducible Builds project, please visit our Contribute page on our website. However, you can get in touch with us via:

4 October 2024

Jonathan Dowland: synths

Although I've never written about them, I've been interested in music synthesisers for ages. My colleagues know this. Whilst I've been off sick, they had a whip-round and bought me a voucher for Andertons, a UK-based music store, to cheer me up. I'm absolutely floored by this generosity. And so, I'm now on a quest to buy a synthesizer! Although, not my first one.
Alesis Micron on my desk, taunting me Alesis Micron on my desk, taunting me
I bought my first synth, an Alesis Micron, from a colleague at $oldjob, 16 years ago. For various reasons, I've struggled to engage with it, and it's mostly been gathering dust on my desk in all that time. (I might write more about the Micron in a later blog post). "Bad Gear" sums it up better than I could:
So, I'm not truly buying my "first" synth, but for all intents and purposes I'm on a similar journey to if I was, and I thought it might be fun to write about it. Goals I want something which has as many of its parameters presented physically, as knobs or sliders etc., as possible. One reason I've failed to engage with the Micron (so far) is it's at the other end of this spectrum, with hundreds of tunable parameters but a small handful of knobs. To change parameters you have to go diving into menus presented on a really old-fashioned, small LCD display. If you know what you are looking for, you can probably find it; but if you just want to experiment and play around, it's off-putting. Secondly, I want something I can use away from a computer, as much as possible. Computers are my day-job, largely dominate my existing hobbies, and are unavoidable even in some of the others (like 3d printing). Most of the computers I interact with run Linux. And for all its strengths, audio management is not one of them. If I'm going to carve out some of my extremely limited leisure time to explore this stuff, I don't to spend any of it (at least now) fighting Pulseaudio/ALSA/Pipewire/JACK/OSS/whatever, or any of the other foibles that might crop up1. Thirdly, I'd like something which, in its soul, is an instrument. You can get some amazing little synth boxes with a huge number of features in them. Something with a limited number of features but which really feels well put together would suit me better. So next time, I'll write about the 2-3 top candidates on my list. Can you guess what they might be?

  1. To give another example. The other day I sat down to try and use the Micron, which had its audio out wired into an external audio interface, in turn plugged into my laptop's Thunderbolt dock. For a while I couldn't figure out why I couldn't hear anything, until I realised the Thunderbolt dock was having "a moment" and not presenting its USB devices to the laptop. Hobby time window gone!

1 October 2024

Colin Watson: Free software activity in September 2024

Almost all of my Debian contributions this month were sponsored by Freexian. You can also support my work directly via Liberapay. Pydantic My main Debian project for the month turned out to be getting Pydantic back into a good state in Debian testing. I ve used Pydantic quite a bit in various projects, most recently in Debusine, so I have an interest in making sure it works well in Debian. However, it had been stalled on 1.10.17 for quite a while due to the complexities of getting 2.x packaged. This was partly making sure everything else could cope with the transition, but in practice mostly sorting out packaging of its new Rust dependencies. Several other people (notably Alexandre Detiste, Andreas Tille, Drew Parsons, and Timo R hling) had made some good progress on this, but nobody had quite got it over the line and it seemed a bit stuck. Learning Rust is on my to-do list, but merely not knowing a language hasn t stopped me before. So I learned how the Debian Rust team s packaging works, upgraded a few packages to new upstream versions (including rust-half and upstream rust-idna test fixes), and packaged rust-jiter. After a lot of waiting around for various things and chasing some failures in other packages I was eventually able to get current versions of both pydantic-core and pydantic into testing. I m looking forward to being able to drop our clunky v1 compatibility code once debusine can rely on running on trixie! OpenSSH I upgraded the Debian packaging to OpenSSH 9.9p1. YubiHSM I upgraded python-yubihsm, yubihsm-connector, and yubihsm-shell to new upstream versions. I noticed that I could enable some tests in python-yubihsm and yubihsm-shell; I d previously thought the whole test suite required a real YubiHSM device, but when I looked closer it turned out that this was only true for some tests. I fixed yubihsm-shell build failures on some 32-bit architectures (upstream PRs #431, #432), and also made it build reproducibly. Thanks to Helmut Grohne, I fixed yubihsm-connector to apply udev rules to existing devices when the package is installed. As usual, bookworm-backports is up to date with all these changes. Python team setuptools 72.0.0 removed the venerable setup.py test command. This caused some fallout in Debian, some of which was quite non-obvious as packaging helpers sometimes fell back to different ways of running test suites that didn t quite work. I fixed django-guardian, manuel, python-autopage, python-flask-seeder, python-pgpdump, python-potr, python-precis-i18n, python-stopit, serpent, straight.plugin, supervisor, and zope.i18nmessageid. As usual for new language versions, the addition of Python 3.13 caused some problems. I fixed psycopg2, python-time-machine, and python-traits. I fixed build/autopkgtest failures in keymapper, python-django-test-migrations, python-rosettasciio, routes, transmissionrpc, and twisted. buildbot was in a bit of a mess due to being incompatible with SQLAlchemy 2.0. Fortunately by the time I got to it upstream had committed a workable set of patches, and the main difficulty was figuring out what to cherry-pick since they haven t made a new upstream release with all of that yet. I figured this out and got us up to 4.0.3. Adrian Bunk asked whether python-zipp should be removed from trixie. I spent some time investigating this and concluded that the answer was no, but looking into it was an interesting exercise anyway. On the other hand, I looked into flask-appbuilder, concluded that it should be removed, and filed a removal request. I upgraded some embedded CSS files in nbconvert. I upgraded importlib-resources, ipywidgets, jsonpickle, pydantic-settings, pylint (fixing a test failure), python-aiohttp-session, python-apptools, python-asyncssh, python-django-celery-beat, python-django-rules, python-limits, python-multidict, python-persistent, python-pkginfo, python-rt, python-spur, python-zipp, stravalib, transmissionrpc, vulture, zodbpickle, zope.exceptions (adopting it), zope.i18nmessageid, zope.proxy, and zope.security to new upstream versions. debmirror The experimental and *-proposed-updates suites used to not have Contents-* files, and a long time ago debmirror was changed to just skip those files in those suites. They were added to the Debian archive some time ago, but debmirror carried on skipping them anyway. Once I realized what was going on, I removed these unnecessary special cases (#819925, #1080168).

Next.

Previous.