Search Results: "noop"

12 June 2013

Daniel Pocock: When conspiracy theories come true

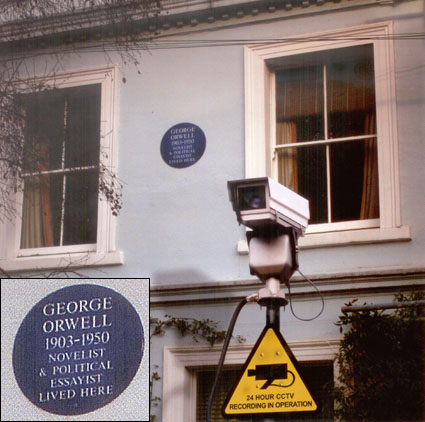
In a blog attempting to join the dots between Australia's intelligence services and the US PRISM program, I speculated that Australia has had extensive access to data harvested by PRISM. My hunch has just been exposed rather dramatically today: Top secret data center under construction to house all our secrets. "There has been no discussion of the project in Senate estimates committee hearings, and the public reports of Parliament's joint committee on intelligence and security make no reference to it." The news story also suggests that the relationship is bi-directional, with data harvested from Australian ISPs cross referenced against US databases from Facebook and Google. From a human rights perspective, the implications of this data sharing are much more dramatic than the NSA just snooping on US citizens within the US. While Australia often tries to portray the image that it is a safe and happy country, it has a dark side. Police are kept busy investigating politicians and Government officials: Prime Minister and her associates connected to a union slush fund, the central bank's banknote printing agency's chief executive and 8 colleagues on conspiracy charges and even a senator on good old fashioned shoplifting and assault charges Exporting PRISM data to a human rights backwater As an Australian, my own rights and those of my family are more heavily protected and respected living in Europe than if I lived in my country of birth. Australia does not have a bill of rights like the US (where PRISM data is harvested) or the European Convention of Human Rights. Once US data is exported to Australia, it can be used to support sinister programs like the indefinite detention of coloured people in sinister desert camps. Just this week, the Government left over 50 bodies of poor refugees for the sharks to eat. For someone with such a lack of a conscience, can you imagine them thinking twice about using PRISM data for unscrupulous purposes? Is US PRISM data at greater risk? Despite the stench of corruption and lip service to human rights, is there any hard evidence that PRISM data will be at greater risk if allowed into the hands of Australians? Death by SMS One former Australian official (having dual-citizenship with Sri Lanka) is accused of facilitating war crimes in the Sri Lankan civil war. At present he is Sri Lanka's ambassador at the UN, giving him the benefit of diplomatic immunity. When he was working for Australia, how much data did he have access to? Isn't it ludicrous that in the name of stopping terrorism, data may have been collected and handed to war criminals on a silver platter? Behind enemy lines Like James Bond in reverse, an Australian official was exposed unofficially engaging in a relationship with a Vietnamese spy colonel. In addition to the $20 million in bribery to win a bank note printing contract, is data being used as a tool to leverage trade negotiations, officially or otherwise? If an Australian official with top-secret clearance ends up under the control of a foreign agent, what is the risk that they would be exploited to obtain PRISM data? Defence minister resignation in Chinese spy scandal In 2009 Australia's defence minister was identified having close links to a Chinese-Australian business woman including all the usual little luxuries: first class flights, apartment rental and joint business deals with family members. He subsequently resigned. Little details were made public. How much PRISM data was directly available to political officials like the defence minister? Disappearing Prime Ministers The disappearance of a serving Prime Minister, Harold Holt, during the cold war remains an unsolved mystery to this day. People continue to ask was he swept out to sea or voluntarily whisked away in a Chinese or Soviet nuclear submarine. While Australia has traditionally had strong ties to Britain and the US, there have been exceptions to the rule. Fortunately this all happened before PRISM and Harold Holt red submarine rumours are no more well-founded than the UFO theories of his abduction. Where did all the data go? As the music industry has found out the hard way, digital data can be copied at will with the originator having no control. The revelations that Britain and Australia are in on the PRISM shenanigans only confirms that this data is seen as a new form of currency for exchange in geo-political posturing. While used weapons take decades to work their way down the chain, data can spread at the speed of light.
11 June 2013

Petter Reinholdtsen: Fixing the Linux black screen of death on machines with Intel HD video

When installing RedHat, Fedora, Debian and Ubuntu on some machines, the screen just turn black when Linux boot, either during installation or on first boot from the hard disk. I've seen it once in a while the last few years, but only recently understood the cause. I've seen it on HP laptops, and on my latest acquaintance the Packard Bell laptop. The reason seem to be in the wiring of some laptops. The system to control the screen background light is inverted, so when Linux try to turn the brightness fully on, it end up turning it off instead. I do not know which Linux drivers are affected, but this post is about the i915 driver used by the Packard Bell EasyNote LV, Thinkpad X40 and many other laptops. The problem can be worked around two ways. Either by adding i915.invert_brightness=1 as a kernel option, or by adding a file in /etc/modprobe.d/ to tell modprobe to add the invert_brightness=1 option when it load the i915 kernel module. On Debian and Ubuntu, it can be done by running these commands as root:
echo options i915 invert_brightness=1   tee /etc/modprobe.d/i915.conf
update-initramfs -u -k all
Since March 2012 there is a mechanism in the Linux kernel to tell the i915 driver which hardware have this problem, and get the driver to invert the brightness setting automatically. To use it, one need to add a row in the intel_quirks array in the driver source drivers/gpu/drm/i915/intel_display.c (look for "static struct intel_quirk intel_quirks"), specifying the PCI device number (vendor number 8086 is assumed) and subdevice vendor and device number. My Packard Bell EasyNote LV got this output from lspci -vvnn for the video card in question:
00:02.0 VGA compatible controller [0300]: Intel Corporation \
    3rd Gen Core processor Graphics Controller [8086:0156] \
    (rev 09) (prog-if 00 [VGA controller])
 Subsystem: Acer Incorporated [ALI] Device [1025:0688]
 Control: I/O+ Mem+ BusMaster+ SpecCycle- MemWINV- VGASnoop- \
    ParErr- Stepping- SE RR- FastB2B- DisINTx+
 Status: Cap+ 66MHz- UDF- FastB2B+ ParErr- DEVSEL=fast >TAbort- \
    <tabort-><mabort->SERR- <perr- intx-="INTx-" latency:="Latency:"><unassigned> [disabled]
 Capabilities: <access denied="denied">
 Kernel driver in use: i915
The resulting intel_quirks entry would then look like this:
struct intel_quirk intel_quirks[] =  
       ...
        /* Packard Bell EasyNote LV11HC needs invert brightness quirk */
	  0x0156, 0x1025, 0x0688, quirk_invert_brightness  ,
       ...
 
According to the kernel module instructions (as seen using modinfo i915), information about hardware needing the invert_brightness flag should be sent to the dri-devel (at) lists.freedesktop.org mailing list to reach the kernel developers. But my email about the laptop sent 2013-06-03 have not yet shown up in the web archive for the mailing list, so I suspect they do not accept emails from non-subscribers. Because of this, I sent my patch also to the Debian bug tracking system instead as BTS report #710938, to make sure the patch is not lost. Unfortunately, it is not enough to fix the kernel to get Laptops with this problem working properly with Linux. If you use Gnome, your worries should be over at this point. But if you use KDE, there is something in KDE ignoring the invert_brightness setting and turning on the screen during login. I've reported it to Debian as BTS report #711237, and have no idea yet how to figure out exactly what subsystem is doing this. Perhaps you can help? Perhaps you know what the Gnome developers did to handle this, and this can give a clue to the KDE developers? Or you know where in KDE the screen brightness is changed during login? If so, please update the BTS report (or get in touch if you do not know how to update BTS).

8 May 2013

Joey Hess: faster dh

With wheezy released, the floodgates are opened on a lot of debhelper changes that have been piling up. Most of these should be pretty minor, but I released one yesterday that will affect all users of dh. Hopefully in a good way. I made dh smarter about selecting which debhelper commands it runs. It can tell when a package does not use the stuff done by a particular command, and skips running the command entirely. So the debian/rules binary of a package using dh will now often look like this:
dh binary
   dh_testroot
   dh_prep
   dh_auto_install
   dh_installdocs
   dh_installchangelogs
   dh_perl
   dh_link
   dh_compress
   dh_fixperms
   dh_installdeb
   dh_gencontrol
   dh_md5sums
   dh_builddeb
Which is pretty close to the optimal hand-crafted debian/rules file (and just about as fast, too). But with the benefit that if you later add, say, cron job files, dh_installcron will automatically start being run too. Hopefully this will not result in any behavior changes, other than packages building faster and with less noise. If there is a bug it'll probably be something missing in the specification of when a command needs to be run. Beyond speed, I hope that this will help to lower the bar to adding new commands to debhelper, and to the default dh sequences. Before, every such new command slowed things down and was annoying. Now more special-purpose commands won't get in the way of packages that don't need them.
The way this works is that debhelper commands can include a "PROMISE" directive. An example from dh_installexamples
# PROMISE: DH NOOP WITHOUT examples
Mostly this specifies the files in debian/ that are used by the command, and whose presence triggers the command to run. There is also a syntax to specify items that can be present in the package build directory to trigger the command to run. (Unfortunatly, dh_perl can't use this. There's no good way to specify when dh_perl needs to run, short of doing nearly as much work as dh_perl would do when run. Oh well.) Note that third-party dh_ commands can include these directives too, if that makes sense.
I'm happy how this turned out, but I could be happier about the implementation. The PROMISE directives need to be maintained along with the code of the command. If another config file is added, they obviously must be updated. Other changes to a command can invalidate the PROMISE directive, and cause unexpected bugs. What would be ideal is to not repeat the inputs of the command in these directives, but instead write the command such that its inputs can be automatically extracted. I played around with some code like this:
$behavior = main_behavior("docs tmp(usr/share/doc/)", sub  
       my $package=shift;
       my $docs=shift;
       my $docdir=shift;
       install($docs, $docdir);
 );
$behavior->($package);
But refactoring all debhelper commands to be written in this style would be a big job. And I was not happy enough with the flexability and expressiveness of this to continue with it. I can however, dream about what this would look like if debhelper were written in Haskell. Then I would have a Debhelper a monad, within which each command executes.
main = runDebhelperIO installDocs
installDocs :: Monad a => Debhelper a
installDocs = do
    docs <- configFile "docs"
    docdir <- tmpDir "usr/share/doc"
    lift $ install docs docdir
To run the command, runDebhelperIO would loop over all the packages and run the action, in the Debhelper IO monad. But, this also allows making an examineDebhelper that takes an action like installDocs, and runs it in a Debhelper Writer monad. That would accumulate a list of all the inputs used by the action, and return it, without performing any side effecting IO actions. It's been 15 years since I last changed the language debhelper was written in. I did that for less gains than this, really. (The issue back then was that shell getopt sucked.) IIRC it was not very hard, and only took a few days. Still, I don't really anticipate reimplementing debhelper in Haskell any time soon. For one thing, individual Haskell binaries are quite large, statically linking all Haskell libraries they use, and so the installed size of debhelper would go up quite a bit. I hope that forthcoming changes will move things toward dynamically linked haskell libraries, and make it more appealing for projects that involve a lot of small commands. So, just a thought experiment for now..

20 February 2013

Vincent Bernat: lldpd 0.7.1

A few weeks ago, a new version of lldpd, a 802.1AB (aka LLDP) implementation for various Unices, has been released. LLDP is an industry standard protocol designed to supplant proprietary Link-Layer protocols such as EDP or CDP. The goal of LLDP is to provide an inter-vendor compatible mechanism to deliver Link-Layer notifications to adjacent network devices. In short, LLDP allows you to know exactly on which port is a server (and reciprocally). To illustrate its use, I have made a xkcd-like strip: xkcd-like strip for the use of LLDP If you would like more information about lldpd, please have a look at its new dedicated website. This blog post is an insight of various technical changes that have affected lldpd since its latest major release one year ago. Lots of C stuff ahead!

Version & changelog UPDATED: Guillem Jover told me how he met the same goals for libbsd :
  1. Save the version from git into .dist-version and use this file if it exists. This allows one to rebuild ./configure from the published tarball without losing the version. This also handles Thorsten Glaser s critic.
  2. Include CHANGELOG in DISTCLEANFILES variable.
Since this is a better solution, I have adopted the appropriate line of codes from libbsd. The two following sections are partly technically outdated.

Automated version In configure.ac, I was previously using a static version number that I had to increase when releasing:
AC_INIT([lldpd], [0.5.7], [bernat@luffy.cx])
Since the information is present in the git tree, this seems a bit redundant (and easy to forget). Taking the version from the git tree is easy:
AC_INIT([lldpd],
        [m4_esyscmd_s([git describe --tags --always --match [0-9]* 2> /dev/null   date +%F])],
        [bernat@luffy.cx])
If the head of the git tree is tagged, you get the exact tag (0.7.1 for example). If it is not, you get the nearest one, the number of commits since it and part of the current hash (0.7.1-29-g2909519 for example). The drawback of this approach is that if you rebuild configure from the released tarball, you don t have the git tree and the version will be a date. Just don t do that.

Automated changelog Generating the changelog from git is a common practice. I had some difficulties to make it right. Here is my attempt (I am using automake):
dist_doc_DATA = README.md NEWS ChangeLog
.PHONY: $(distdir)/ChangeLog
dist-hook: $(distdir)/ChangeLog
$(distdir)/ChangeLog:
        $(AM_V_GEN)if test -d $(top_srcdir)/.git; then \
          prev=$$(git describe --tags --always --match [0-9]* 2> /dev/null) ; \
          for tag in $$(git tag   grep -E '^[0-9]+(\.[0-9]+) 1, $$'   sort -rn); do \
            if [ x"$$prev" = x ]; then prev=$$tag ; fi ; \
            if [ x"$$prev" = x"$$tag" ]; then continue; fi ; \
            echo "$$prev [$$(git log $$prev -1 --pretty=format:'%ai')]:" ; \
            echo "" ; \
            git log --pretty=' - [%h] %s (%an)' $$tag..$$prev ; \
            echo "" ; \
            prev=$$tag ; \
          done > $@ ; \
        else \
          touch $@ ; \
        fi
ChangeLog:
        touch $@
Changelog entries are grouped by version. Since it is a bit verbose, I still maintain a NEWS file with important changes.

Core

C99 I have recently read 21st Century C which has some good bits and also handles the ecosystem around C. I have definitively adopted designated initializers in my coding style. Being a GCC extension since a long time, this is not a major compatibility problem. Without designated initializers:
struct netlink_req req;
struct iovec iov;
struct sockaddr_nl peer;
struct msghdr rtnl_msg;
memset(&req, 0, sizeof(req));
memset(&iov, 0, sizeof(iov));
memset(&peer, 0, sizeof(peer));
memset(&rtnl_msg, 0, sizeof(rtnl_msg));
req.hdr.nlmsg_len = NLMSG_LENGTH(sizeof(struct rtgenmsg));
req.hdr.nlmsg_type = RTM_GETLINK;
req.hdr.nlmsg_flags = NLM_F_REQUEST   NLM_F_DUMP;
req.hdr.nlmsg_seq = 1;
req.hdr.nlmsg_pid = getpid();
req.gen.rtgen_family = AF_PACKET;
iov.iov_base = &req;
iov.iov_len = req.hdr.nlmsg_len;
peer.nl_family = AF_NETLINK;
rtnl_msg.msg_iov = &iov;
rtnl_msg.msg_iovlen = 1;
rtnl_msg.msg_name = &peer;
rtnl_msg.msg_namelen = sizeof(struct sockaddr_nl);
With designated initializers:
struct netlink_req req =  
    .hdr =  
        .nlmsg_len = NLMSG_LENGTH(sizeof(struct rtgenmsg)),
        .nlmsg_type = RTM_GETLINK,
        .nlmsg_flags = NLM_F_REQUEST   NLM_F_DUMP,
        .nlmsg_seq = 1,
        .nlmsg_pid = getpid()  ,
    .gen =   .rtgen_family = AF_PACKET  
 ;
struct iovec iov =  
    .iov_base = &req,
    .iov_len = req.hdr.nlmsg_len
 ;
struct sockaddr_nl peer =   .nl_family = AF_NETLINK  ;
struct msghdr rtnl_msg =  
    .msg_iov = &iov,
    .msg_iovlen = 1,
    .msg_name = &peer,
    .msg_namelen = sizeof(struct sockaddr_nl)
 ;

Logging Logging in lldpd was not extensive. Usually, when receiving a bug report, I asked the reporter to add some additional printf() calls to determine where the problem was. This was clearly suboptimal. Therefore, I have added many log_debug() calls with the ability to filter out some of them. For example, to debug interface discovery, one can run lldpd with lldpd -ddd -D interface. Moreover, I have added colors when logging to a terminal. This may seem pointless but it is now far easier to spot warning messages from debug ones. logging output of lldpd

libevent In lldpd 0.5.7, I was using my own select()-based event loop. It worked but I didn t want to grow a full-featured event loop inside lldpd. Therefore, I switched to libevent. The minimal required version of libevent is 2.0.5. A convenient way to check the changes in API is to use Upstream Tracker, a website tracking API and ABI changes for various libraries. This version of libevent is not available in many stable distributions. For example, Debian Squeeze or Ubuntu Lucid only have 1.4.13. I am also trying to keep compatibility with very old distributions, like RHEL 2, which does not have a packaged libevent at all. For some users, it may be a burden to compile additional libraries. Therefore, I have included libevent source code in lldpd source tree (as a git submodule) and I am only using it if no suitable system libevent is available. Have a look at m4/libevent.m4 and src/daemon/Makefile.am to see how this is done.

Client

Serialization lldpctl is a client querying lldpd to display discovered neighbors. The communication is done through an Unix socket. Each structure to be serialized over this socket should be described with a string. For example:
#define STRUCT_LLDPD_DOT3_MACPHY "(bbww)"
struct lldpd_dot3_macphy  
        u_int8_t                 autoneg_support;
        u_int8_t                 autoneg_enabled;
        u_int16_t                autoneg_advertised;
        u_int16_t                mau_type;
 ;
I did not want to use stuff like Protocol Buffers because I didn t want to copy the existing structures to other structures before serialization (and the other way after deserialization). However, the serializer in lldpd did not allow to handle reference to other structures, lists or circular references. I have written another one which works by annotating a structure with some macros:
struct lldpd_chassis  
    TAILQ_ENTRY(lldpd_chassis) c_entries;
    u_int16_t        c_index;
    u_int8_t         c_protocol;
    u_int8_t         c_id_subtype;
    char            *c_id;
    int              c_id_len;
    char            *c_name;
    char            *c_descr;
    u_int16_t        c_cap_available;
    u_int16_t        c_cap_enabled;
    u_int16_t        c_ttl;
    TAILQ_HEAD(, lldpd_mgmt) c_mgmt;
 ;
MARSHAL_BEGIN(lldpd_chassis)
MARSHAL_TQE  (lldpd_chassis, c_entries)
MARSHAL_FSTR (lldpd_chassis, c_id, c_id_len)
MARSHAL_STR  (lldpd_chassis, c_name)
MARSHAL_STR  (lldpd_chassis, c_descr)
MARSHAL_SUBTQ(lldpd_chassis, lldpd_mgmt, c_mgmt)
MARSHAL_END;
Only pointers need to be annotated. The remaining of the structure can be serialized with just memcpy()1. I think there is still room for improvement. It should be possible to add annotations inside the structure and avoid some duplication. Or maybe, using a C parser? Or using the AST output from LLVM?

Library In lldpd 0.5.7, there are two possible entry points to interact with the daemon:
  1. Through SNMP support. Only information available in LLDP-MIB are exported. Therefore, implementation-specific values are not available. Moreover, SNMP support is currently read-only.
  2. Through lldpctl. Thanks to a contribution from Andreas Hofmeister, the output can be requested to be formatted as an XML document.
Integration of lldpd into a network stack was therefore limited to one of those two channels. As an exemple, you can have a look at how Vyatta made the integration using the second solution. To provide a more robust solution, I have added a shared library, liblldpctl, with a stable and well-defined API. lldpctl is now using it. I have followed those directions2:
  • Consistent naming (all exported symbols are prefixed by lldpctl_). No pollution of the global namespace.
  • Consistent return codes (on errors, all functions returning pointers are returning NULL, all functions returning integers are returning -1).
  • Reentrant and thread-safe. No global variables.
  • One well-documented include file.
  • Reduce the use of boilerplate code. Don t segfault on NULL, accept integer input as string, provide easy iterators,
  • Asynchronous API for input/output. The library delegates reading and writing by calling user-provided functions. Those functions can yield their effects. In this case, the user has to callback the library when data is available for reading or writing. It is therefore possible to integrate the library with any existing event-loop. A thin synchronous layer is provided on top of this API.
  • Opaque types with accessor functions.
Accessing bits of information is done through atoms which are opaque containers of type lldpctl_atom_t. From an atom, you can extract some properties as integers, strings, buffers or other atoms. The list of ports is an atom. A port in this list is also an atom. The list of VLAN present on this port is an atom, as well as each VLAN in this list. The VLAN name is a NULL-terminated string living in the scope of an atom. Accessing a property is done by a handful of functions, like lldpctl_atom_get_str(), using a specific key. For example, here is how to display the list of VLAN assuming you have one port as an atom:
vlans = lldpctl_atom_get(port, lldpctl_k_port_vlans);
lldpctl_atom_foreach(vlans, vlan)  
    vid = lldpctl_atom_get_int(vlan,
                               lldpctl_k_vlan_id));
    name = lldpctl_atom_get_str(vlan,
                                lldpctl_k_vlan_name));
    if (vid && name)
        printf("VLAN %d: %s\n", vid, name);
 
lldpctl_atom_dec_ref(vlans);
Internally, an atom is typed and reference counted. The size of the API is greatly limited thanks to this concept. There are currently more than one hundred pieces of information that can be retrieved from lldpd. Ultimately, the library will also enable the full configuration of lldpd. Currently, many aspects can only be configured through command-line flags. The use of the library does not replace lldpctl which will still be available and be the primary client of the library.

CLI Having a configuration file was requested since a long time. I didn t want to include a parser in lldpd: I am trying to keep it small. It was already possible to configure lldpd through lldpctl. Locations, network policies and power policies were the three items that could be configured this way. So, the next step was to enable lldpctl to read a configuration file, parse it and send the result to lldpd. As a bonus, why not provide a full CLI accepting the same statements with inline help and completion?

Parsing & completion Because of completion, it is difficult to use a YACC generated parser. Instead, I define a tree where each node accepts a word. A node is defined with this function:
struct cmd_node *commands_new(
    struct cmd_node *,
    const char *,
    const char *,
    int(*validate)(struct cmd_env*, void *),
    int(*execute)(struct lldpctl_conn_t*, struct writer*,
        struct cmd_env*, void *),
    void *);
A node is defined by:
  • its parent,
  • an optional accepted static token,
  • an help string,
  • an optional validation function and
  • an optional function to execute if the current token is accepted.
When walking the tree, we maintain an environment which is both a key-value store and a stack of positions in the tree. The validation function can check the environment to see if we are in the right context (we want to accept the keyword foo only once, for example). The execution function can add the current token as a value in the environment but it can also pop the current position in the tree to resume walk from a previous node. As an example, see how nodes for configuration of a coordinate-based location are registered:
/* Our root node */
struct cmd_node *configure_medloc_coord = commands_new(
    configure_medlocation,
    "coordinate", "MED location coordinate configuration",
    NULL, NULL, NULL);
/* The exit node.
   The validate function will check if we have both
   latitude and longitude. */
commands_new(configure_medloc_coord,
    NEWLINE, "Configure MED location coordinates",
    cmd_check_env, cmd_medlocation_coordinate,
    "latitude,longitude");
/* Store latitude. Once stored, we pop two positions
   to go back to the "root" node. The user can only
   enter latitude once. */
commands_new(
    commands_new(
        configure_medloc_coord,
        "latitude", "Specify latitude",
        cmd_check_no_env, NULL, "latitude"),
    NULL, "Latitude as xx.yyyyN or xx.yyyyS",
    NULL, cmd_store_env_value_and_pop2, "latitude");
/* Same thing for longitude */
commands_new(
    commands_new(
        configure_medloc_coord,
        "longitude", "Specify longitude",
        cmd_check_no_env, NULL, "longitude"),
    NULL, "Longitude as xx.yyyyE or xx.yyyyW",
    NULL, cmd_store_env_value_and_pop2, "longitude");
The definition of all commands is still a bit verbose but the system is simple enough yet powerful enough to cover all needed cases.

Readline When faced with a CLI, we usually expect some perks like completion, history handling and help. The most used library to provide such features is the GNU Readline Library. Because this is a GPL library, I have first searched an alternative. There are several of them: From an API point of view, the first three libraries support the GNU Readline API. They also have a common native API. Moreover, this native API also handles tokenization. Therefore, I have developed the first version of the CLI with this API3. Unfortunately, I noticed later this library is not very common in the Linux world and is not available in RHEL. Since I have used the native API, it was not possible to fallback to the GNU Readline library. So, let s switch! Thanks to the appropriate macro from the Autoconf Archive (with small modifications), the compilation and linking differences between the libraries are taken care of. Because GNU Readline library does not come with a tokenizer, I had to write one myself. The API is also badly documented and it is difficult to know which symbol is available in which version. I have limited myself to:
  • readline(), addhistory(),
  • rl_insert_text(),
  • rl_forced_update_display(),
  • rl_bind_key()
  • rl_line_buffer and rl_point.
Unfortunately, the various libedit libraries have a noop for rl_bind_key(). Therefore, completion and online help is not available with them. I have noticed that most BSD come with GNU Readline library preinstalled, so it could be considered as a system library. Nonetheless, linking with libedit to avoid licensing issues is possible and help can be obtained by prefixing the command with help.

OS specific support

BSD support Until version 0.7, lldpd was Linux-only. The rewrite to use Netlink was the occasion to abstract interfaces and to port to other OS. The first port was for Debian GNU/kFreeBSD, then for FreeBSD, OpenBSD and NetBSD. They all share the same source code:
  • getifaddrs() to get the list of interfaces,
  • bpf(4) to attach to an interface to receive and send packets,
  • PF_ROUTE socket to be notified when a change happens.
Each BSD has its own ioctl() to retrieve VLAN, bridging and bonding bits but they are quite similar. The code was usually adapted from ifconfig.c. The BSD ports have the same functionalities than the Linux port, except for NetBSD which lacks support for LLDP-MED inventory since I didn t find a simple way to retrieve DMI related information. They also offer greater security by filtering packets sent. Moreover, OpenBSD allows to lock the filters set on the socket:
/* Install write filter (optional) */
if (ioctl(fd, BIOCSETWF, (caddr_t)&fprog) < 0)  
    rc = errno;
    log_info("privsep", "unable to setup write BPF filter for %s",
        name);
    goto end;
 
/* Lock interface */
if (ioctl(fd, BIOCLOCK, (caddr_t)&enable) < 0)  
    rc = errno;
    log_info("privsep", "unable to lock BPF interface %s",
        name);
    goto end;
 
This is a very nice feature. lldpd is using a privileged process to open the raw socket. The socket is then transmitted to an unprivileged process. Without this feature, the unprivileged process can remove the BPF filters. I have ported the ability to lock a socket filter program to Linux. However, I still have to add a write filter.

OS X support Once FreeBSD was supported, supporting OS X seemed easy. I got sponsored by xcloud.me which provided a virtual Mac server. Making lldpd work with OS X took only two days, including a full hour to guess how to get Apple Xcode without providing a credit card. To help people installing lldpd on OS X, I have also written a lldpd formula for Homebrew which seems to be the most popular package manager for OS X.

Upstart and systemd support Many distributions propose upstart and systemd as a replacement or an alternative for the classic SysV init. Like most daemons, lldpd detaches itself from the terminal and run in the background, by forking twice, once it is ready (for lldpd, this just means we have setup the control socket). While both upstart and systemd can accommodate daemons that behave like this, it is recommended to not fork. How to advertise readiness in this case? With upstart, lldpd will send itself the SIGSTOP signal. upstart will detect this, resume lldpd with SIGCONT and assume it is ready. The code to support upstart is therefore quite simple. Instead of calling daemon(), do this:
const char *upstartjob = getenv("UPSTART_JOB");
if (!(upstartjob && !strcmp(upstartjob, "lldpd")))
    return 0;
log_debug("main", "running with upstart, don't fork but stop");
raise(SIGSTOP);
The job configuration file looks like this:
# lldpd - LLDP daemon
description "LLDP daemon"
start on net-device-up IFACE=lo
stop on runlevel [06]
expect stop
respawn
script
  . /etc/default/lldpd
  exec lldpd $DAEMON_ARGS
end script
systemd provides a socket to achieve the same goal. An application is expected to write READY=1 to the socket when it is ready. With the provided library, this is just a matter of calling sd_notify("READY=1\n"). Since sd_notify() has less than 30 lines of code, I have rewritten it to avoid an external dependency. The appropriate unit file is:
[Unit]
Description=LLDP daemon
Documentation=man:lldpd(8)
[Service]
Type=notify
NotifyAccess=main
EnvironmentFile=-/etc/default/lldpd
ExecStart=/usr/sbin/lldpd $DAEMON_ARGS
Restart=on-failure
[Install]
WantedBy=multi-user.target

OS include files Linux-specific include files were a major pain in previous versions of lldpd. The problems range from missing header files (like linux/if_bonding.h) to the use of kernel-only types. Those headers have a difficult history. They were first shipped with the C library but were rarely synced and almost always outdated. They were then extracted from kernel version with almost no change and lagged behind the kernel version used by the released distribution4. Today, the problem is acknowledged and is being solved by both the distributions which extract the headers from the packaged kernel and by kernel developers with a separation of kernel-only headers from user-space API headers. However, we still need to handle legacy. A good case is linux/ethtool.h:
  • It can just be absent.
  • It can use u8, u16 types which are kernel-only types. To work around this issue, type munging can be setup.
  • It can miss some definition, like SPEED_10000. In this case, you either define the missing bits and find yourself with a long copy of the original header interleaved with #ifdef or conditionally use each symbol. The latest solution is a burden by itself but it also hinders some functionalities that can be available in the running kernel.
The easy solution to all this mess is to just include the appropriate kernel headers into the source tree of the project. Thanks to Google ripping them for its Bionic C library, we know that copying kernel headers into a program does not create a derivative work.

  1. Therefore, the use of u_int16_t and u_int8_t types is a left-over of the previous serializer where the size of all members was important.
  2. For more comprehensive guidelines, be sure to check Writing a C library.
  3. Tokenization is not the only advantage of libedit native API. The API is also cleaner, does not have a global state and has a better documentation. All the implementations are also BSD licensed.
  4. For example, in Debian Sarge, the Linux kernel was a 2.6.8 (2004) while the kernel headers were extracted from some pre-2.6 kernel.

8 October 2012

Jonathan McDowell: KVM + usbmon + Wireshark == win

(This is something I did a few months ago, and I really should have noted down all the details then so I covered everything. However hopefully these notes will remind me enough next time.) When I first wanted to reverse engineer a USB device that only had Windows drivers the "easy" option was to take a Windows machine, install usbsnoop on it and capture the traffic as a bunch of verbose text files. It was a cumbersome procedure. Recently I wanted to do a firmware upgrade of a ZTE 3G modem dongle, partly to provider unlock it and partly to try and enable some voice functionality. I was also hoping to sniff the traffic to see how to drive the voice side of things. These days I don't have a dedicated Windows box, but I do have a Windows 7 KVM virtual machine. I hadn't yet used the USB support in this, but I thought I'd see what it was capable of. Firstly I had to explicitly enable USB2 - the device wasn't happy with the default USB1 only stack that KVM enabled. That involved passing -usb -device usb-ehci,id=ehci to KVM. I also told KVM to grab all the ZTE devices with -device usb-host,bus=ehci.0,vendorid=0x19d2. I dropped a udev rules file into /etc/udev/rules.d to ensure any device nodes created belonged to my normal user. This gave me a Windows setup that could see the USB dongle and install the appropriate drivers. It was also happy to do the firmware update (along with various device resets on the way as it changed USB ID - this is why I needed the udev rule, to ensure every time the device re-appeared it would be seen by the KVM instance without manual intervention). After that was complete I investigated usbmon. modprobe usbmon created the appropriate /dev/usbmon<n> files and I chowned the appropriate bus to my normal user. Once this was done I was able to start Wireshark which rather nicely has full USB decoding support. Firing up the custom app in the Windows KVM guest I could see the traffic going back and forth to each of the device endpoints and work out what was going on. All of this was much more flexible than using a standalone Windows box. Once I figured out that I needed to explicitly enable USB2 I was quite pleased with how simple USB access under KVM was. I also used lvm to create a snapshot of the Windows guest so at the end I could roll back all of the drivers I'd installed for the dongle. And being able to use Wireshark instead of trawling through dense text files helped a lot in seeing the command stream.

5 October 2012

Keith Packard: fd-passing

FD passing for DRI.Next Using the DMA-BUF interfaces to pass DRI objects between the client and server, as discussed in my previous blog posting on DRI-Next, requires that we successfully pass file descriptors over the X protocol socket. Rumor has it that this has been tried and found to be difficult, and so I decided to do a bit of experimentation to see how this could be made to work within the existing X implementation. (All of the examples shown here are licensed under the GPL, version 2 and are available from git://keithp.com/git/fdpassing) Basics of FD passing The kernel internals that support FD passing are actually quite simple POSIX already require that two processes be able to share the same underlying reference to a file because of the semantics of the fork(2) call. Adding some ability to share arbitrary file descriptors between two processes then is far more about how you ask the kernel than the actual file descriptor sharing operation. In Linux, file descriptors can be passed through local network sockets. The sender constructs a mystic-looking sendmsg(2) call, placing the file descriptor in the control field of that operation. The kernel pulls the file descriptor out of the control field, allocates a file descriptor in the target process which references the same file object and then sticks the file descriptor in a queue for the receiving process to fetch. The receiver then constructs a matching call to recvmsg that provides a place for the kernel to stick the new file descriptor. A helper API for testing I first write a stand-alone program that created a socketpair, forked and then passed an fd from the parent to the child. Once that was working, I decided that some short helper functions would make further testing a whole lot easier. Here s a function that writes some data and an optional file descriptor:

ssize_t
sock_fd_write(int sock, void *buf, ssize_t buflen, int fd)
 
    ssize_t     size;
    struct msghdr   msg;
    struct iovec    iov;
    union  
        struct cmsghdr  cmsghdr;
        char        control[CMSG_SPACE(sizeof (int))];
      cmsgu;
    struct cmsghdr  *cmsg;
    iov.iov_base = buf;
    iov.iov_len = buflen;
    msg.msg_name = NULL;
    msg.msg_namelen = 0;
    msg.msg_iov = &iov;
    msg.msg_iovlen = 1;
    if (fd != -1)  
        msg.msg_control = cmsgu.control;
        msg.msg_controllen = sizeof(cmsgu.control);
        cmsg = CMSG_FIRSTHDR(&msg);
        cmsg->cmsg_len = CMSG_LEN(sizeof (int));
        cmsg->cmsg_level = SOL_SOCKET;
        cmsg->cmsg_type = SCM_RIGHTS;
        printf ("passing fd %d\n", fd);
        *((int *) CMSG_DATA(cmsg)) = fd;
      else  
        msg.msg_control = NULL;
        msg.msg_controllen = 0;
        printf ("not passing fd\n");
     
    size = sendmsg(sock, &msg, 0);
    if (size < 0)
        perror ("sendmsg");
    return size;
 
And here s the matching receiver function:
ssize_t
sock_fd_read(int sock, void *buf, ssize_t bufsize, int *fd)
 
    ssize_t     size;
    if (fd)  
        struct msghdr   msg;
        struct iovec    iov;
        union  
            struct cmsghdr  cmsghdr;
            char        control[CMSG_SPACE(sizeof (int))];
          cmsgu;
        struct cmsghdr  *cmsg;
        iov.iov_base = buf;
        iov.iov_len = bufsize;
        msg.msg_name = NULL;
        msg.msg_namelen = 0;
        msg.msg_iov = &iov;
        msg.msg_iovlen = 1;
        msg.msg_control = cmsgu.control;
        msg.msg_controllen = sizeof(cmsgu.control);
        size = recvmsg (sock, &msg, 0);
        if (size < 0)  
            perror ("recvmsg");
            exit(1);
         
        cmsg = CMSG_FIRSTHDR(&msg);
        if (cmsg && cmsg->cmsg_len == CMSG_LEN(sizeof(int)))  
            if (cmsg->cmsg_level != SOL_SOCKET)  
                fprintf (stderr, "invalid cmsg_level %d\n",
                     cmsg->cmsg_level);
                exit(1);
             
            if (cmsg->cmsg_type != SCM_RIGHTS)  
                fprintf (stderr, "invalid cmsg_type %d\n",
                     cmsg->cmsg_type);
                exit(1);
             
            *fd = *((int *) CMSG_DATA(cmsg));
            printf ("received fd %d\n", *fd);
          else
            *fd = -1;
      else  
        size = read (sock, buf, bufsize);
        if (size < 0)  
            perror("read");
            exit(1);
         
     
    return size;
 
With these two functions, I rewrote the simple example as follows:
void
child(int sock)
 
    int fd;
    char    buf[16];
    ssize_t size;
    sleep(1);
    for (;;)  
        size = sock_fd_read(sock, buf, sizeof(buf), &fd);
        if (size <= 0)
            break;
        printf ("read %d\n", size);
        if (fd != -1)  
            write(fd, "hello, world\n", 13);
            close(fd);


void
parent(int sock)
 
    ssize_t size;
    int i;
    int fd;
    fd = 1;
    size = sock_fd_write(sock, "1", 1, 1);
    printf ("wrote %d\n", size);
 
int
main(int argc, char **argv)
 
    int sv[2];
    int pid;
    if (socketpair(AF_LOCAL, SOCK_STREAM, 0, sv) < 0)  
        perror("socketpair");
        exit(1);
     
    switch ((pid = fork()))  
    case 0:
        close(sv[0]);
        child(sv[1]);
        break;
    case -1:
        perror("fork");
        exit(1);
    default:
        close(sv[1]);
        parent(sv[0]);
        break;
     
    return 0;
 
Experimenting with multiple writes I wanted to know what would happen if multiple writes were made, some with file descriptors and some without. So I changed the simple example parent function to look like:
void
parent(int sock)
 
    ssize_t size;
    int i;
    int fd;
    fd = 1;
    size = sock_fd_write(sock, "1", 1, -1);
    printf ("wrote %d without fd\n", size);
    size = sock_fd_write(sock, "1", 1, 1);
    printf ("wrote %d with fd\n", size);
    size = sock_fd_write(sock, "1", 1, -1);
    printf ("wrote %d without fd\n", size);
 
When run, this demonstrates that the reader gets two bytes in the first read along with a file descriptor followed by one byte in a second read, without a file descriptor. This demonstrates that a file descriptor message forms a barrier within the socket; multiple messages will be merged together, but not past a message containing a file descriptor. Reading without accepting a file descriptor What happens when the reader isn t expecting a file descriptor? Does it just get lost? Does the reader not get the message until it asks for the file descriptor? What about the boundary issue described above? Here s my test case:
void
child(int sock)
 
    int fd;
    char    buf[16];
    ssize_t size;
    sleep(1);
    size = sock_fd_read(sock, buf, sizeof(buf), NULL);
    if (size <= 0)
        return;
    printf ("read %d\n", size);
    size = sock_fd_read(sock, buf, sizeof(buf), &fd);
    if (size <= 0)
        return;
    printf ("read %d\n", size);
    if (fd != -1)  
        write(fd, "hello, world\n", 13);
        close(fd);
     
 
void
parent(int sock)
 
    ssize_t size;
    int i;
    int fd;
    fd = 1;
    size = sock_fd_write(sock, "1", 1, 1);
    printf ("wrote %d without fd\n", size);
    size = sock_fd_write(sock, "1", 1, 2);
    printf ("wrote %d with fd\n", size);
 
This shows that the first passed file descriptor is picked up by the first sockfdread call, but the file descriptor is closed. The second file descriptor passed is picked up by the second sockfdread call. Zero-length writes Can a file descriptor be passed without sending any data?
void
parent(int sock)
 
    ssize_t size;
    int i;
    int fd;
    fd = 1;
    size = sock_fd_write(sock, "1", 1, -1);
    printf ("wrote %d without fd\n", size);
    size = sock_fd_write(sock, NULL, 0, 1);
    printf ("wrote %d with fd\n", size);
    size = sock_fd_write(sock, "1", 1, -1);
    printf ("wrote %d without fd\n", size);
 
And the answer is clearly no the file descriptor is not passed when no data are included in the write. A summary of results
  1. read and recvmsg don t merge data across a file descriptor message boundary.
  2. failing to accept an fd in the receiver results in the fd being closed by the kernel.
  3. a file descriptor must be accompanied by some data.
Make X pass file descriptors I d like to get X to pass a file descriptor without completely rewriting the internals of both the library and the X server. Ideally, without making any changes to the existing code paths for regular request processing at all. On the sending side, this seems pretty straightforward we just need to get the X connection file descriptor and call sendmsg directly, passing the desired file descriptor along. In XCB, this could be done by using the xcbtakesocket interface to temporarily hijack the protocol as Xlib does. It s the receiving side where things are messier. Because a bare read will discard any delivered file descriptor, we must make sure to use recvmsg whenever we want to actually capture the file descriptor. Kludge X server fd receiving Because a passed fd creates a barrier in the bytestream, when the X server reads requests from a client, the read will stop sending data after the message with the file descriptor is consumed. Of course, this process consumes the passed file descriptor, and if that call isn t made with recvmsg set up to receive it, the fd will be lost. As a simple kludge, if we pass a meaningless fd with the X request and then the real fd with a following XNoOperation request, the existing request reading code will get the request, discard the meaningless fd and then stop reading at that point due to the barrier. Once into the request processing code, recvmsg can be called to get the real file descriptor and the associated XNoOperation request. I wrote a test for this that demonstrates how this works:
static void
child(int sock)
 
    uint8_t xreq[1024];
    uint8_t xnop[4];
    uint8_t req;
    int i, reqlen;
    ssize_t size, fdsize;
    int fd = -1, *fdp;
    int j;
    sleep (1);
    for (j = 0;; j++)  
        size = sock_fd_read(sock, xreq, sizeof (xreq), NULL);
        printf ("got %d\n", size);
        if (size == 0)
            break;
        i = 0;
        while (i < size)  
            req = xreq[i];
            reqlen = xreq[i+1];
            i += reqlen;
            switch (req)  
            case 0:
                break;
            case 1:
                if (i != size)  
                    fprintf (stderr, "Got fd req, but not at end of input %d < %d\n",
                         i, size);
                 
                fdsize = sock_fd_read(sock, xnop, sizeof (xnop), &fd);
                if (fd == -1)  
                    fprintf (stderr, "no fd received\n");
                  else  
                    FILE    *f = fdopen (fd, "w");
                    fprintf(f, "hello %d\n", j);
                    fflush(f);
                    fclose(f);
                    close(fd);
                    fd = -1;
                 
                break;
            case 2:
                fprintf (stderr, "Unexpected FD passing req\n");
                break;


int
tmp_file(int j)  
    char    name[64];
    sprintf (name, "tmp-file-%d", j);
    return creat(name, 0666);
 
static void
parent(int sock)
 
    uint8_t xreq[32];
    uint8_t xnop[4];
    int i, j;
    int fd;
    for (j = 0; j < 4; j++)  
        /* Write a bunch of regular requests */
        for (i = 0; i < 8; i++)  
            xreq[0] = 0;
            xreq[1] = sizeof (xreq);
            sock_fd_write(sock, xreq, sizeof (xreq), -1);
         
        /* Write our 'pass an fd' request with a 'useless' FD to block the receiver */
        xreq[0] = 1;
        xreq[1] = sizeof(xreq);
        sock_fd_write(sock, xreq, sizeof (xreq), 1);
        /* Pass an fd */
        xnop[0] = 2;
        xnop[1] = sizeof (xnop);
        fd = tmp_file(j);
        sock_fd_write(sock, xnop, sizeof (xnop), fd);
        close(fd);
     
 
Fixing XCB to receive file descriptors Multiple threads may be trying to get replies and events back from the X server at the same time, which means the kludge of having the real fd follow the message will likely lead to the wrong thread getting the file descriptor. Instead, I suspect the best plan will be to fix XCB to internally capture passed file descriptors and save them with the associated reply. Because the file descriptor message will form a barrier in the read stream, xcb can associate any received file descriptor with the last reply in the read data. The X server would then send the reply with an explicit sendmsg call to pass both reply and file descriptor together. Next steps The next thing to do is code up a simple fd passing extension and try to get it working, passing descriptors back and forth to the X server. Once that works, design of the rest of the DRM-Next extension should be pretty straightforward.

20 August 2012

Steve Kemp: Failing to debug a crash with epiphany-browser and webkit

Today I'm in bed, because I have le sniffles, and a painful headache. I'm using epiphany to write this post, via VNC to my main desktop, but I'm hating it as I've somehow evolved into a state where the following crashes my browser: Running under GDB shows nothing terribly helpful:
Program received signal SIGSEGV, Segmentation fault.
0x0000000000000000 in ?? ()
(gdb) bt
#0  0x0000000000000000 in ?? ()
#1  0x00007ffff51a0a46 in ?? () from /usr/lib/libwebkit-1.0.so.2
#2  0x00007ffff3d8f79d in ?? () from /usr/lib/libsoup-2.4.so.1
#3  0x00007ffff2a4947e in g_closure_invoke () from /usr/lib/libgobject-2.0.so.0
#4  0x00007ffff2a5f7f4 in ?? () from /usr/lib/libgobject-2.0.so.0
...
To get more detail I ran "apt-get install epiphany-browser-dbg" - this narrows down the crash, but not in a useful way:
Program received signal SIGSEGV, Segmentation fault.
0x0000000000000000 in ?? ()
(gdb) bt
#0  0x0000000000000000 in ?? ()
#1  0x00007ffff51a0a46 in finishedCallback (session=<value optimized out>, msg=0x7fffd801d9c0, data=<value optimized="optimized" out="out">) at ../WebCore/platform/network/soup/ResourceHandleSoup.cpp:329
#2  0x00007ffff3d8f79d in ?? () from /usr/lib/libsoup-2.4.so.1
#3  0x00007ffff2a4947e in g_closure_invoke () from /usr/lib/libgobject-2.0.so.0
#4  0x00007ffff2a5f7f4 in ?? () from /usr/lib/libgobject-2.0.so.0
..
So this crash happens in ResourceHandleSoup.cpp. Slowly I realized that this came from the webkit package. We see that the last call by name is to the function in line ResourceHandleSoup.cpp:329, that puts us at the last line of this function:
// Called at the end of the message, with all the necessary about the last informations.
// Doesn't get called for redirects.
static void finishedCallback(SoupSession *session, SoupMessage* msg, gpointer data)
 
    RefPtr<ResourceHandle> handle = adoptRef(static_cast<ResourceHandle*>(data));
    // TODO: maybe we should run this code even if there's no client?
    if (!handle)
        return;
    ResourceHandleInternal* d = handle->getInternal();
    ResourceHandleClient* client = handle->client();
    if (!client)
       return;
..
..
    client->didFinishLoading(handle.get());
 
So we see there is some validation that happens, then a call to "didFinishLoading" and somewhere shortly after that it dies. didFinishLoading looks trivial:
void WebCoreSynchronousLoader::didFinishLoading(ResourceHandle*)
 
      g_main_loop_quit(m_mainLoop);
      m_finished = true;
 
So my mental-debugging is stymied. I blame my headache. It looks like there is no obvious NULL-pointer deference, if we pretend client cannot be NULL. So the next step is to get the source, the build-dependencies and then build a debug version of webkit. I ran "apt-get source webkit", then editted the file ./debian/rules to add --enable-debug and rebuilt it:
skx@precious:~/Debian/epiphany/webkit-1.2.7$ DEB_BUILD_OPTIONS="nostrip noopt" debuild -sa
*time passes* The build fails:
  CXX    WebCore/svg/libwebkit_1_0_la-SVGUseElement.lo
../WebCore/svg/SVGUseElement.cpp: In member function  virtual void WebCore::SVGUseElement::insertedIntoDocument() :
../WebCore/svg/SVGUseElement.cpp:125: error:  class WebCore::Document  has no member named  isXHTMLDocument 
../WebCore/svg/SVGUseElement.cpp:125: error:  class WebCore::Document  has no member named  parser 
make[2]: *** [WebCore/svg/libwebkit_1_0_la-SVGUseElement.lo] Error 1
Ugh. So I guess we disable that "--enable-debug", and hope that "nostrip noopt" helps instead. *Thorin sits down and starts singing about gold* Finally the debugging build has finished and I've woken up again. Let us do this thing. I'd looked over the webkit tracker and the crashing bugs list in the meantime, but nothing jumped out at me as being similar to my issue. Anyway without the --enable-debug flag present in the call to ../configure the Debian webkit packages were built, eventually, and installed:
skx@precious:~/Debian/epiphany$ mv libwebkit-dev_1.2.7-0+squeeze2_amd64.deb x.deb
skx@precious:~/Debian/epiphany$ sudo dpkg --install libweb*deb
[sudo] password for skx:
(Reading database ... 173767 files and directories currently installed.)
Preparing to replace libwebkit-1.0-2 1.2.7-0+squeeze2 (using libwebkit-1.0-2_1.2.7-0+squeeze2_amd64.deb) ...
Unpacking replacement libwebkit-1.0-2 ...
Preparing to replace libwebkit-1.0-2-dbg 1.2.7-0+squeeze2 (using libwebkit-1.0-2-dbg_1.2.7-0+squeeze2_amd64.deb) ...
Unpacking replacement libwebkit-1.0-2-dbg ...
Preparing to replace libwebkit-1.0-common 1.2.7-0+squeeze2 (using libwebkit-1.0-common_1.2.7-0+squeeze2_all.deb) ...
Unpacking replacement libwebkit-1.0-common ...
Setting up libwebkit-1.0-common (1.2.7-0+squeeze2) ...
Setting up libwebkit-1.0-2 (1.2.7-0+squeeze2) ...
Setting up libwebkit-1.0-2-dbg (1.2.7-0+squeeze2) ...
skx@precious:~/Debian/epiphany$
Good news everybody: The crash still happens! Firing up GDB should hopefully reveal more details - but sadly it didn't.
Program received signal SIGSEGV, Segmentation fault.
0x0000000000000000 in ?? ()
(gdb) bt
#0  0x0000000000000000 in ?? ()
#1  0x00007ffff51a0a46 in finishedCallback (session=<value optimized="optimized" out="out">, msg=0xb03420, data=<value optimized="optimized" out="out">) at ../WebCore/platform/network/soup/ResourceHandleSoup.cpp:329
..
(gdb) up
#1  0x00007ffff51a0a46 in finishedCallback (session=<value optimized="optimized" out="out">, msg=0xb03420, data=<value optimized="optimized" out="out">) at ../WebCore/platform/network/soup/ResourceHandleSoup.cpp:329
329     client->didFinishLoading(handle.get());
(gdb) p client
$1 = <value optimized out>
At this point my head hurts too much, and I'm stuck. No quote today, I cannot be bothered.

9 June 2012

Neil McGovern: Anti-ACTA Demo my speech

I'm on my way back from the Anti ACTA demo in London, at which I was asked to speak. I was good to see a number of people attend. I bumped into the wonderful Bridget Fox too! Here's my speech:

As I was travelling here on the train, I found myself thinking: why am I here?
What has gone so wrong with the political system that politicians pass laws - the DMCA, the DEA, SOPA, PIPA, ACTA. Laws that look attractive on the surface, but are so deeply flawed. Why have they stopped listening?
But, they haven't stopped listening. They're falling in to a trap set by big businesses with vested interests. The ones with money to influence policy, the lobbying firms, the corporate hospitality arrangements. They hear that the economy is bumbling along the bottom. That many businesses are struggling, and these are hard problems to solve. And suddenly a shining beacon is held out - support our creative industries and all will be well. No one is interested in this new fangled Internet thing anyway. Well, apart from the people stood here today! People like you, and me. People like Julian Huppert - we helped take a motion to the Liberal Democrat Conference to repeal the damaging parts of the Digital Economy Act. The Alliance of Liberals and Democrats in Europe will vote against ACTA, and in three major committees it has already been rejected it. Something has changed. The people who represent us are starting to hear our stories. How we will not put up with censorship, interference and snooping. And let me tell you this. The big industries are scared. Shady back room negotiations so that they may be able to slip it past the public. Thanks to you, this won't work anymore. We have a voice, and it's here today. It's not too late to stop damaging our freedoms. Go visit your elected representatives. Tell them why we need to stop these bad laws. Help them understand that it's not ok to pass these. Write about it, tell people, shout in the streets! We know ACTA is bad. Let's tell the world.

2 May 2012

Matthew Garrett: Anatomy of a Fedora 17 ISO image

My spare time has been limited lately, so progress on producing Mac-bootable Fedora install images has been a bit slow. Thankfully it looks like everything's gong to land in time for Fedora 17[1] so hurrah for that - all that's missing right now are the last couple of patches that make sure the boot picker displays useful labels on the drives.

So how is this accomplished? Here's a hex dump of the first few K of the image.
00000000  45 52 08 00 00 00 90 90  00 00 00 00 00 00 00 00   ER.............. 
00000010  00 00 00 00 00 00 00 00  00 00 00 00 00 00 00 00   ................ 
00000020  33 ed fa 8e d5 bc 00 7c  fb fc 66 31 db 66 31 c9   3...... ..f1.f1. 
00000030  66 53 66 51 06 57 8e dd  8e c5 52 be 00 7c bf 00   fSfQ.W....R.. .. 
00000040  06 b9 00 01 f3 a5 ea 4b  06 00 00 52 b4 41 bb aa   .......K...R.A.. 
00000050  55 31 c9 30 f6 f9 cd 13  72 16 81 fb 55 aa 75 10   U1.0....r...U.u. 
00000060  83 e1 01 74 0b 66 c7 06  f1 06 b4 42 eb 15 eb 00   ...t.f.....B.... 
00000070  5a 51 b4 08 cd 13 83 e1  3f 5b 51 0f b6 c6 40 50   ZQ......?[Q...@P 
00000080  f7 e1 53 52 50 bb 00 7c  b9 04 00 66 a1 b0 07 e8   ..SRP.. ...f.... 
00000090  44 00 0f 82 80 00 66 40  80 c7 02 e2 f2 66 81 3e   D.....f@.....f.> 
000000a0  40 7c fb c0 78 70 75 09  fa bc ec 7b ea 44 7c 00   @ ..xpu.... .D . 
000000b0  00 e8 83 00 69 73 6f 6c  69 6e 75 78 2e 62 69 6e   ....isolinux.bin 
000000c0  20 6d 69 73 73 69 6e 67  20 6f 72 20 63 6f 72 72    missing or corr 
000000d0  75 70 74 2e 0d 0a 66 60  66 31 d2 66 03 06 f8 7b   upt...f f1.f... 
000000e0  66 13 16 fc 7b 66 52 66  50 06 53 6a 01 6a 10 89   f... fRfP.Sj.j.. 
000000f0  e6 66 f7 36 e8 7b c0 e4  06 88 e1 88 c5 92 f6 36   .f.6. .........6 
00000100  ee 7b 88 c6 08 e1 41 b8  01 02 8a 16 f2 7b cd 13   . ....A...... .. 
00000110  8d 64 10 66 61 c3 e8 1e  00 4f 70 65 72 61 74 69   .d.fa....Operati 
00000120  6e 67 20 73 79 73 74 65  6d 20 6c 6f 61 64 20 65   ng system load e 
00000130  72 72 6f 72 2e 0d 0a 5e  ac b4 0e 8a 3e 62 04 b3   rror...^....>b.. 
00000140  07 cd 10 3c 0a 75 f1 cd  18 f4 eb fd 00 00 00 00   ...<.u.......... 
00000150  00 00 00 00 00 00 00 00  00 00 00 00 00 00 00 00   ................ 
This is the boot sector. One of the fun things about ISO9660 is that it doesn't have a boot sector in the usual x86 sense - firmwares are expected to read enough of the filesystem that they can find the bootloader in it and run it directly. x86 isn't really smart enough to manage that, so it uses something called El Torito[2]. In any case, this is usually empty space on an x86 CD. But with an increasing number of systems shipping without optical drives, real CD installs are decreasing in popularity. We use a piece of software called isohybrid that allows the building of ISO9660 images that can be written directly onto a USB stick. Asking a machine to boot off them will execute the boot sector located here, which then loads a real bootloader that's capable of reading ISO and booting the OS. It'll just be ignored when it's on a real CD.

There's one difference here, though. The isohybrid bootsector has been modified so that the first 32 bytes are just noops, and this has been inserted:
00000000  45 52 08 00 00 00 90 90  00 00 00 00 00 00 00 00   ER.............. 
45 52 ("ER") indicates the presence of an Apple partition map. This will become important later. 0800 indicates that it's using 2048-byte sectors. The 9090 is a lie to convince the firmware that it's not a zero-sized disk without representing dangerous code. We need an Apple partition map because some older Macs won't boot off CD unless the CD has one. But it's sitting right at the start of the boot sector, and this code is going to be executed. Thankfully, the entire Apple header decodes to
00000000  45                inc bp
00000001  52                push dx
00000002  0800              or [bx+si],al
00000004  0000              add [bx+si],al
00000006  90                nop
00000007  90                nop
00000008  0000              add [bx+si],al
0000000A  0000              add [bx+si],al
0000000C  0000              add [bx+si],al
0000000E  0000              add [bx+si],al
00000010  0000              add [bx+si],al
00000012  0000              add [bx+si],al
00000014  0000              add [bx+si],al
00000016  0000              add [bx+si],al
00000018  0000              add [bx+si],al
0000001A  0000              add [bx+si],al
0000001C  0000              add [bx+si],al
0000001E  0000              add [bx+si],al
which is completely harmless - we can execute all these instructions without any interesting changes in state. They'll all be undone by the rest of the boot sector.
000001b0  14 05 00 00 00 00 00 00  4c 1e ed 76 00 00 80 00   ........L..v.... 
000001c0  01 00 00 3f a0 89 00 00  00 00 00 50 14 00 00 fe   ...?.......P.... 
000001d0  ff ff ef fe ff ff a4 00  00 00 70 04 00 00 00 fe   ..........p..... 
000001e0  ff ff 00 fe ff ff 44 05  00 00 c0 08 00 00 00 00   ......D......... 
000001f0  00 00 00 00 00 00 00 00  00 00 00 00 00 00 55 aa   ..............U. 
This is the MBR partition table. The aim here was to produce media that would boot via BIOS just as well as it does via EFI, and it turns out that there are some systems that refuse to BIOS-boot off GPT media. So we need an MBR partition map. The first entry covers the entire disk and is of type 0. This is important, because some EFI implementations are strict about MBR parsing - if there's an MBR with overlapping partitions, the entire MBR will be ignored. Inconvenient. Fortunately, we've got the source code to this code, and it turns out that partitions of type 0 are ignored when performing this check. So, there's a partition of type 0.

Why does it cover the entire disk? Once we've booted the OS, we need to be able to read the ISO image contained on the USB stick. That means the kernel needs to be able to mount it, which means we need a partition entry that covers the entire disk. Linux is perfectly happy mounting a filesystem from a partition of type 0.

So, the next partition. This is an EFI boot partition that points at the embedded VFAT El-Torito image. Some firmware will decide that we've got an MBR and so will only boot off a partition that exists in it. So, here's an MBR partition to keep them happy.

The final partition covers the embedded HFS+ image. It's there purely for convenience - it means we can access it under Linux in order to update its contents for testing purposes.
00000200  45 46 49 20 50 41 52 54  00 00 01 00 5c 00 00 00   EFI PART....\... 
00000210  09 27 93 7e 00 00 00 00  01 00 00 00 00 00 00 00   .'.~............ 
00000220  fe 4f 14 00 00 00 00 00  30 00 00 00 00 00 00 00   .O......0....... 
00000230  de 4f 14 00 00 00 00 00  2a 26 0f 37 23 c9 7f 4f   .O......*&.7#..O 
00000240  90 df 5e fe 0a 60 1c b0  10 00 00 00 00 00 00 00   ..^.. .......... 
00000250  80 00 00 00 80 00 00 00  ec 70 63 c1 00 00 00 00   .........pc..... 
00000260  00 00 00 00 00 00 00 00  00 00 00 00 00 00 00 00   ................ 
And here we have the GPT header. Nothing complicated here, other than it indicates that the first partition descriptor is at LBA 0x10, ie byte 0x2000 - that's further into the disk than normal. That leaves us enough space to fit the Apple partition entries.

Why have a GPT at all? The EFI spec says that machines should boot fine from an MBR partition. Sadly, not all seem to. It also lets us represent the HFS+ partition in a way that makes the Mac firmware happy.
00000800  50 4d 00 00 00 00 00 03  00 00 00 01 00 00 00 10   PM.............. 
00000810  41 70 70 6c 65 00 00 00  00 00 00 00 00 00 00 00   Apple........... 
00000820  00 00 00 00 00 00 00 00  00 00 00 00 00 00 00 00   ................ 
00000830  41 70 70 6c 65 5f 70 61  72 74 69 74 69 6f 6e 5f   Apple_partition_ 
00000840  6d 61 70 00 00 00 00 00  00 00 00 00 00 00 00 00   map............. 
00000850  00 00 00 00 00 00 00 0a  00 00 00 03 00 00 00 00   ................ 
00000860  00 00 00 00 00 00 00 00  00 00 00 00 00 00 00 00   ................ 
2K into the disk, here's an Apple partition map. It's 2K into the disk because we set the sector size to 2K in the partition map header. Why did we do that? Because the default is 512 bytes, and if we'd put the partition map at 512 bytes it would have been on top of the GPT header. Why 2K rather than 1K? A couple of reasons. First, the Apple partition map is only used when we boot off an actual CD, and the CD sector size is genuinely 2K. Secondly, because CDs have a sector size of 2K, 2K is a value that's actually been tested in the real world. It's nice to avoid tempting fate.
00001000  50 4d 00 00 00 00 00 03  00 00 00 29 00 00 04 70   PM.........)...p 
00001010  45 46 49 00 00 00 00 00  00 00 00 00 00 00 00 00   EFI............. 
00001020  00 00 00 00 00 00 00 00  00 00 00 00 00 00 00 00   ................ 
00001030  41 70 70 6c 65 5f 48 46  53 00 00 00 00 00 00 00   Apple_HFS....... 
00001040  00 00 00 00 00 00 00 00  00 00 00 00 00 00 00 00   ................ 
00001050  00 00 00 00 00 00 04 70  00 00 00 33 00 00 00 00   .......p...3.... 
00001060  00 00 00 00 00 00 00 00  00 00 00 00 00 00 00 00   ................ 
*
00001800  50 4d 00 00 00 00 00 03  00 00 01 51 00 00 08 c0   PM.........Q.... 
00001810  45 46 49 00 00 00 00 00  00 00 00 00 00 00 00 00   EFI............. 
00001820  00 00 00 00 00 00 00 00  00 00 00 00 00 00 00 00   ................ 
00001830  41 70 70 6c 65 5f 48 46  53 00 00 00 00 00 00 00   Apple_HFS....... 
00001840  00 00 00 00 00 00 00 00  00 00 00 00 00 00 00 00   ................ 
00001850  00 00 00 00 00 00 08 c0  00 00 00 33 00 00 00 00   ...........3.... 
00001860  00 00 00 00 00 00 00 00  00 00 00 00 00 00 00 00   ................ 
The Apple partition map entries. One partition covers the entire disk, the other the embedded HFS+ filesystem. Why do this? Because not all Macs understand EFI El Torito, so won't EFI boot a CD unless there's an Apple partition map. Why have an HFS+ partition at all? Because the same Macs won't boot off FAT.
00002000  a2 a0 d0 eb e5 b9 33 44  87 c0 68 b6 b7 26 99 c7   ......3D..h..&.. 
00002010  d0 84 a5 d4 aa 89 e0 40  81 f9 fc e4 04 e9 c2 99   .......@........ 
00002020  00 00 00 00 00 00 00 00  10 4b 14 00 00 00 00 00   .........K...... 
00002030  00 00 00 00 00 00 00 00  49 53 4f 48 79 62 72 69   ........ISOHybri 
00002040  64 20 49 53 4f 00 49 53  4f 48 79 62 72 69 64 00   d ISO.ISOHybrid. 
00002050  41 70 70 6c 00 00 00 00  00 00 00 00 00 00 00 00   Appl............ 
00002060  00 00 00 00 00 00 00 00  00 00 00 00 00 00 00 00   ................ 
*
00002080  a2 a0 d0 eb e5 b9 33 44  87 c0 68 b6 b7 26 99 c7   ......3D..h..&.. 
00002090  68 d5 e0 27 72 83 c6 4c  a7 ae 92 dd ed 6c 89 71   h..'r..L.....l.q 
000020a0  a4 00 00 00 00 00 00 00  13 05 00 00 00 00 00 00   ................ 
000020b0  00 00 00 00 00 00 00 00  49 53 4f 48 79 62 72 69   ........ISOHybri 
000020c0  64 00 41 70 70 6c 65 00  41 70 70 6c 00 00 00 00   d.Apple.Appl.... 
000020d0  00 00 00 00 00 00 00 00  00 00 00 00 00 00 00 00   ................ 
*
00002100  00 53 46 48 00 00 aa 11  aa 11 00 30 65 43 ec ac   .SFH.......0eC.. 
00002110  68 d5 e0 27 72 83 c6 4c  a7 ae 92 dd ed 6c 89 71   h..'r..L.....l.q 
00002120  44 05 00 00 00 00 00 00  03 0e 00 00 00 00 00 00   D............... 
00002130  00 00 00 00 00 00 00 00  49 53 4f 48 79 62 72 69   ........ISOHybri 
00002140  64 00 41 70 70 6c 65 00  41 70 70 6c 00 00 00 00   d.Apple.Appl.... 
00002150  00 00 00 00 00 00 00 00  00 00 00 00 00 00 00 00   ................ 
Three GPT entries - one covers the entire CD, one covers the embedded FAT filesystem, one covers the embedded EFI filesystem. That ensures that they're all accessible to the firmware.
00008000  01 43 44 30 30 31 01 00  4c 49 4e 55 58 20 20 20   .CD001..LINUX    
00008010  20 20 20 20 20 20 20 20  20 20 20 20 20 20 20 20                    
00008020  20 20 20 20 20 20 20 20  46 65 64 6f 72 61 2d 4c           Fedora-L 
00008030  69 76 65 43 44 20 20 20  20 20 20 20 20 20 20 20   iveCD            
00008040  20 20 20 20 20 20 20 20  00 00 00 00 00 00 00 00           ........ 
00008050  c4 12 05 00 00 05 12 c4  00 00 00 00 00 00 00 00   ................ 
00008060  00 00 00 00 00 00 00 00  00 00 00 00 00 00 00 00   ................ 
00008070  00 00 00 00 00 00 00 00  01 00 00 01 01 00 00 01   ................ 
00008080  00 08 08 00 40 00 00 00  00 00 00 40 15 00 00 00   ....@......@.... 
00008090  00 00 00 00 00 00 00 17  00 00 00 00 22 00 1d 00   ............"... 
000080a0  00 00 00 00 00 1d 00 08  00 00 00 00 08 00 70 05   ..............p. 
000080b0  01 09 30 36 f0 02 00 00  01 00 00 01 01 00 20 20   ..06..........   
000080c0  20 20 20 20 20 20 20 20  20 20 20 20 20 20 20 20                    
The ISO9660 superblock. This is completely standard. From here on there's nothing terribly surprising - the CD filesystem itself is entirely normal. The only slight oddity is that we have three embedded El Torito images. The first of these is a BIOS-bootable disk image. That'll be executed whenever the CD is put in a non-EFI machine. The second is a VFAT EFI boot image. That's used for the majority of EFI systems. The third is an HFS+ EFI boot image. There's no strict requirement for the HFS+ one to be an El Torito image - CD booting on Macs is already handled by the Apple partition map. Storing it as an El Torito is purely for convenience, since it guarantees correct alignment and avoids us having to parse the entire ISO9660 image to find its location when generating the partition maps.

In summary: Three partition maps, three bootable images, support for BIOS, UEFI and Mac platforms, works whether it's burned to a CD or written directly to a USB stick. I'm pretty pleased with that.

[1] Other than an awkward bug where something goes horribly wrong during Radeon graphics init, so Radeon-based Macs aren't working too well at the moment. We're working on it.

[2] The world decided that writing a real ISO9660 driver for BIOS was hard, so came up with El Torito. El Torito is a spec for embedding disk images inside ISO9660. There's a pointer to the disk image in the Cd header, so the BIOS simply reads a few blocks off CD, finds that pointer and then sets up a bunch of disk i/o interrupts to point at the embedded filesystem rather than a real disk. From that point on, the El Torito image simply behaves like a floppy or hard drive. This was a reasonable compromise given how resource limited older BIOS implementations were.

For reasons that aren't entirely clear, UEFI doesn't mandate that implementations support ISO9660. So even though our firmware is now sufficiently capable that the only thing standing between it and emacs is someone being sufficiently bored, we still use El Torito. Fortunately the spec allows multiple El Torito images to be embedded, so we can include one that's bootable by BIOS systems and another that's bootable by UEFI systems.

comment count unavailable comments

14 January 2012

Ben Hutchings: IGMP denial of service in Linux (CVE-2012-0207)

The bug report Simon McVittie reported in Debian bug #654876 that his laptop running Linux 3.0 or 3.1 would sometimes crash (panic) while idle. He initially suspected a driver bug, but the screen did not show any information about where the original fault occurred. However, using netconsole, he was able to capture a full log of the crash. This showed that a packet received through the wireless interface was being processed by IGMP, which then divided by zero. IGMP IGMP is part of the IPv4 protocol suite, supporting multicast routing. Every multicast address corresponds to a dynamic set of hosts, called a multicast group. Multicast routers can send query messages asking which hosts belong to which groups, and hosts using multicast report back at intervals. Routers can then limit forwarding of multicast packets to the interfaces where the group has members. More sophisticated switches can also snoop IGMP and use it to limit their multicast forwarding. There are unfortunately three different versions with semi-compatible message formats. In version 1, the maximum reporting interval (Max Response Time) is fixed as 10 seconds, but from version 2 it is specified in query messages. The Linux IGMP implementation supports all three versions. It distinguishes query messages as specified in RFC 3376 section 7.1: v3 messages are longer than v1 or v2; v2 messages have a non-zero Max Response Time whereas v1 messages always have zero. It is possible to force use of a specific protocol version, but normally if there are multiple multicast routers using different protocol versions it will respond according to the earliest protocol version in use so that all routers can understand its responses. Source and fix for the bug Linux 2.6.36 included two fixes to the version selection logic. Unfortunately, the second of these introduced the bug in question. While v2 query messages cannot possibly have zero Max Response Time (as that would make them v1), v3 query messages can. What this means is unspecified, but the Linux IGMP code previously treated it as the minimum valid value of 1/10 second. But in the case where a v3 query is received and a v2 query has also recently been received, this is no longer done. This results in a reporting interval of 0 seconds and a division by zero when deciding the initial random delay. The fix for this is pretty obvious. It is included in Linux 3.0.17, 3.1.9, 3.2.1, and the Debian package version 3.1.8-2. Security impact This is easily exploitable for denial of service within a local network. Linux does not check the destination address of IGMP queries, so it may also be possible to attack a target through its unicast address from several hops away. The attacker only needs to send a single IGMPv2 query followed by a single IGMPv3 query with zero Max Response Time. All systems running Linux 2.6.36 or later (up to the above fixed versions) with any active IPv4 multicast listeners (other than for the 'all hosts' address) are vulnerable.

4 January 2012

Kartik Mistry: Wikipedia takes Ahmedabad

* This post is almost translation of my this post on Gujarati blog (with some corrections and additions etc). If you re not interested in Wikipedia, move on. So, as I mentioned here and here, Wikipedians in Ahmedabad planned event: Wikipedia Takes Ahmedabad. We gathered at Gandhi Ashram. Met Noopur again and some volunteers were already there at 8 AM. I never been to Ashram since long time. This place has something, you know it, folks! People started coming around 8.30 and we quickly divided them based upon their interests on 4 routes we already decided. Most of people went to old city s route 1 and our route 2 had odd 6 (and 2 coordinaters) people only. Good. Less is always good. Noopur and Anirudh gave introduction to wikipedia, creative commons license and some basic rules and todo. We then left for Swaminarayan Temple at Sahibaug. We asked for permission to take photographs and we got it after meeting main swamiji there along with nice sweets and he promised to send professional picture for wikipedia to use. We then left for Delhi Darwaja. Ahmedabad has numbers of old fort gates. We covered some of them and moved to Kalupur Railway Station. Palak and Chirag were caught by traffic police and we should take care of following rules from next time. Point noted for next photowalk. We then left for Zulta Minar. This is well known for its carving and some myths associated with it. We discussed some points regarding uploading pictures, categories and left for Raipur Darwaja. This place is famous for Bhajiyas. We didn t taste it but had again fun taking pictures, talking to police and had smile before we leave for home. Only bad thing I ve got in this walk is that due to some or other reason my phone s touch screen seems stopped working :( That s another topic, but I couldn t call Noopur/Anirudh for lunch etc due to that :) You can view all uploaded pictures at: Categories: Ahmedabad 1 Most of Ahmedabad is covered due to event. Time to write articles?

31 October 2011

Russell Coker: Links October 2011

Ron has written an interesting blog post about the US as a lottery economy [1]. Most people won t win the lottery (literally or metaphorically) so they remain destined for poverty. Tim Connors wrote an informative summary of the issues relating to traffic light timing and pedestrians/cyclists [2]. I have walked between Southgate and the Crown Casino area many times and have experienced the problem he describes many times. Scientific American has an interesting article about a new global marketplace for scientific research [3]. The concept is that instead of buying a wide range of research equipment (and hiring people to run it) you can outsource non-core research for a lower cost. Svante P bo gave an interesting TED talk about his work analysing human DNA to determine prehistoric human migration patterns [4]. Among other things he determined that 2.5% of the DNA from modern people outside Africa came from the Neandertals. Lisa wrote an informative article about Emotional Support Animals (as opposed to Service Animals such as guide dogs) for disabled people [5]. It seems that the US law is quite similar to Australian law in that reasonable accommodations have to be made for disabled people which includes allowing pets in rental properties even if such pets aren t officially ESAs. Beyond Zero Emissions has an interesting article about electricity prices which explains how wind power forces prices down [6]. This should offset the new carbon tax . Problogger has an article listing some of the ways that infographics can be used on the web [7]. This can be for blog posts or just for your personal understanding. Petter Reinholdtsen wrote a handy post about ripping DVDs which also explains how to do it when the DVD has errors [8], I haven t yet ripped a DVD but this one is worth noting for when I do. Miriam has written about the Fantastic Park ICT training for 8-12yo kids [9]. It s run in Spain (and all the links are in Spanish but Google Translation works well) and is a camp to teach children about computers and robotics using Lego Wedo among other things. We need to have more of these things in other countries. The Atlantic Cities has an interesting article comparing grid and cul-de-sac based urban designs [10]. Apparently the cul-de-sac design forces an increase in car use and therefore an increase in fatal accidents while also decreasing the health benefits of walking. Having lived in both grid and cul-de-sac based urban areas I have personally experienced the benefits of the grid based layout. Sarah Chayes wrote an interesting LA Times article about governments being taken over by corruption [11]. She argues that arbitrary criminal government leads to an increase in religious fundamentelism. Michael Lewis has an insightful article in Vanity Fair about the bankruptcy of US states and cities [12]. Ben Goldacre gave an interesting TED talk about bad medical science [13]. He starts with the quackery that is published in tabloid newspapers and then moves on to deliberate scientific fraud by medical companies. Geoff Mulgan gave an interesting TED talk about the Studio Schools in the UK which are based around group project work [14]. The main thing I took from this is that the best method of teaching varies by subject and by student. So instead of having a monolithic education department controlling everything we should have schools aimed at particular career paths and learning methods. Sophos has an interesting article about the motion sensors of smart phones being used to transcribe keyboard input based on vibration [15]. This attack could be launched by convincing a target to install a trojan application on their phone. It s probably best to regard your phone with suspicion nowadays. Simon Josefsson wrote a good article explaining how to use a GPG smart-card to authenticate ssh sessions with particular reference to running backups over ssh [16]. C ran wrote a good article explaining how to use all the screen space when playing DVDs on a wide screen display with mplayer [17]. Charles Stross has an informative blog post about Wall St Journal circulation fraud [18]. Apparently the WSJ was faking readership numbers to get more money from advertisers, this should lead to law suits and more problems for Rupert Murdoch. Is everything associated with Wall St corrupt?

29 July 2011

Jaldhar Vyas: hello_minix-i386.deb

NEW YORK, Jul 29, 2011 PreventaConf The crowd of thousands gathered here to attend PreventaConf 2011 were abuzz over the unveiling of the culmination of 3 years of aimless arsing about^ww^w concentrated development which has led to the porting of dpkg to the MINIX 3 operating system. dselect on Minix Women fainted, men wept openly, medical personnel were kept busy dealing with the many instances of heart seizure, multisensory hallucination and spontaneous combustion which accompanied this momentous event. Much remains to be done. Still this is a major milestone of which the Debian Minix developers are justifiably proud.

28 July 2011

Ian Wienand: The quickest way to do nothing

As I was debugging something recently, an instruction popped up that seemed a little incongruous:
lea 0x0(%edi,%eiz,1),%edi
Now this is an interesting instruction on a few levels. Firstly, %eiz is a psuedo-register that simply equates to zero somewhat like MIPS r0; I don't think it is really in common usage. But when you look closer, this instruction is a fancy way of doing nothing. It's a little clearer in Intel syntax mode:
lea    edi,[edi+eiz*1+0x0]
So we can see that this is using scaled indexed addressing mode to load into %edi the value in %edi plus 0 * 1 with an offset of 0x0; i.e. put the value of %edi into %edi, i.e. do nothing. So why would this appear? What we can see from the disassembley is that this single instruction takes up an impressive 7 bytes:
8048489:	8d bc 27 00 00 00 00	lea    edi,[edi+eiz*1+0x0]
Now, compare that to a standard nop which requires just a single byte to encode. Thus to pad out 7 bytes of space would require 7 nop instructions to be issued, which is a significantly slower way of doing nothing! Let's investigate just how much... Below is a simple program that does nothing in a tight-loop; firstly using nops and then the lea do-nothing method.
#include <stdio.h>
#include <stdint.h>
#include <time.h>
typedef uint64_t cycle_t;
static inline cycle_t
i386_get_cycles(void)
 
        cycle_t result;
        __asm__ __volatile__("rdtsc" : "=A" (result));
        return result;
 
#define get_cycles i386_get_cycles
int main()  
	int i;
	uint64_t t1, t2;
	t1 = get_cycles();
	/* nop do nothing */
	while (i < 100000)  
		__asm__ __volatile__("nop;nop;nop");
		i++;
	 
	t2 = get_cycles();
	printf("%ld\n", t2 - t1);
	i = 0;
	t1 = get_cycles();
	/* lea do-nothing */
	while (i < 100000)  
		__asm__ __volatile__("lea 0x0(%edi,%eiz,1),%edi");
		i++;
	 
	t2 = get_cycles();
	printf("%ld\n", t2 - t1);
 
Firstly, you'll notice that rather than the 7-bytes mentioned before, we're comparing 3-byte sequences. That's because the lea instruction ends up encoded as:
 8048388:       8d 3c 27                lea    (%edi,%eiz,1),%edi
When you hand-code this instruction, you can't actually convince the assembler to pad out those extra zeros for the zero displacement because it realises it doesn't need them, so why would it waste the space! So, how did they get in there in the original disassembley? If gas is trying to align something by padding, it has built-in sequences for the most efficient way of doing that for different sizes (you can see it in i386_align_code of gas/config/tc-i386.c which adds the extra 4 bytes in directly). Anyway, we can build and test this out (note you need the special -mindex-reg flag passed to gas to use the %eiz syntax):
$ gcc -O3 -Wa,-mindex-reg  -o wait wait.c
$ ./wait
300072
189945
So, if you need 3-bytes of padding in your code for some reason, it's ~160% slower to pad out 3-bytes with no-ops rather than a single larger instruction (at least on my aging Pentium M laptop). So now you can rest easy knowing that even though your code is doing nothing, it is doing it in the most efficient manner possible!

17 July 2011

Cyril Brulebois: Thoughts on multiple webcams

Keeping an eye on something with a webcam is really easy: just a matter of setting up for example (c)vlc to multicast from /dev/videoX to the network, and done. Example:
# Streaming:
cvlc v4l2:///dev/video0 --no-audio --sout "#transcode vcodec=mp2v,vb=3072 :std access=udp,mux=ts,dst=224.0.0.1 "
# Playing, possibly on a remote machine:
vlc udp://@224.0.0.1:1234
Notes: Possible problems: Where to go from here:

8 March 2011

Sam Hartman: V6 Really is that Hard

Sometimes I begin to think that we ve solved most of the challenges to IPv6 deployment. Then something happens. This time it was a DAP-1522 access-point. Not a NAT, not a router, just a layer 2 device. A while after deploying the device, I noticed that sometimes mail failed to work. After attempting to debug the problem was that the device wasn t getting an IPv6 address. The router appeared to be sending out advertizments. Other machines on the same subnet were working fine. This laptop had associated with the new access point. The default configuration helpfully includes IGMP snooping. The IGMP snooping detected that no one subscribed to any IPv4 multicast group corresponding to the router advertizements and thus didn t forward them to the wireless link. We have a long way to go if layer 2 devices sold today are incompatible with v6 in their default configurations.

22 January 2011

Matthew Palmer: Debugging Debian Installer

I've been doing a bit of work recently on the netcfg portion of Debian Installer, with the largest work so far being adding IPv6 support. Unlike most of the rest of d-i, netcfg is written in C, and as such suffers from some difficulties in the realm of debugging. Worse, the whole d-i environment is rather bereft of the usual debugging tools (strace, lsof, etc) -- but most importantly, in this case, gdb. Thanks to some hints from Julien Cristau, I was reminded of the existence of gdbserver, a small part of gdb that allows you to debug a program running on a remote machine, using a copy of gdb running on your local machine. It's designed for debugging embedded systems, I think, because all of the heavy lifting (symbol lookups, etc) happens on your local machine, not where gdbserver is running. Here are the steps I took to get a useful gdbserver session inside d-i:
  1. Get the gdb sources (apt-get source gdb) and drop into the gdbserver tree (cd gdb-x.y.z/gdb/gdbserver)
  2. Configure gdbserver to build a static binary (LDFLAGS=-static ./configure). This is necessary because you don't want to have to faff around with library dependencies inside the d-i environment. Then build gdbserver (make).
  3. Copy gdbserver over to your d-i machine/VM (I like using netcat; nc -l -p 31310 >/bin/gdbserver on the d-i machine, and nc IPADDR 31310 <gdbserver where you built gdbserver), then make it executable (chmod /bin/gdbserver)
  4. Fire up gdbserver in d-i, attaching it to the process you wish to debug: gdbserver host:31337 --attach PID
  5. Now things get a little trickier... on your local machine, you need to have an unstripped copy of the binary you're debugging. For me, this is easy, because I'm building netcfg myself (to keep the symbols, I just run DEB_BUILD_OPTIONS=noopt dpkg-buildpackage -b -rfakeroot) but I'm not sure what you'd do if you were just tracing around for fun.
  6. Once you've got your binary, just run gdb BINARY on your host machine to start gdb running.
  7. For the "even trickier" part of the show, your local machine also needs copies of all the libraries your binary is linked against. If you don't have this, when you try to debug you'll get all sorts of "wrong library or version mismatch?" errors, and your backtraces will likely break (amongst other things). Again, for me, this is easy, because I'm only running the d-i initrd, but if you're debugging something later in the installation process you might need to unpack some udebs somewhere. All I have to do is keep the initrd build tree around (which lives in the installer tree, under build/tmp/netboot/tree). Once you've got your tree of libraries, you can continue.
  8. You need to tell gdb about that tree of libraries, by running the following in gdb: set solib-absolute-prefix /path/to/library/tree
  9. Now, tell gdb to connect to your gdbserver: target remote IPADDR:31337 -- gdb should tell you "Remote debugging using IPADDR:31337", and the gdbserver should say "Remote debugging from host LOCALIP:31337".
  10. Now, you should be able to interact with the program being debugged just like any other. Enjoy!

2 November 2010

Francois Marier: RAID1 alternative for SSD drives

I recently added a solid-state drive to my desktop computer to take advantage of the performance boost rumored to come with these drives. For reliability reasons, I've always tried to use software RAID1 to avoid having to reinstall my machine from backups should a hard drive fail. While this strategy is fairly cheap with regular hard drives, it's not really workable with SSD drives which are still an order of magnitude more expensive.

The strategy I settled on is this one:This setup has the benefit of using a very small SSD to speed up the main partition while keeping all important data on the larger mirrored drives.

Resetting the SSDThe first thing I did, given that I purchased a second-hand drive, was to completely erase the drive and mark all sectors as empty using an ATA secure erase. Because SSDs have a tendency to get slower as data is added to them, it is necessary to clear the drive in a way that will let the controller know that every byte is now free to be used again.

There is a lot of advice on the web on how to do this and many tutorials refer to an old piece of software called Secure Erase. There is a much better solution on Linux: issuing the commands directly using hdparm.

Partitioning the SSDOnce the drive is empty, it's time to create partitions on it. I'm not sure how important it is to align the partitions to the SSD erase block size on newer drives, but I decided to follow Ted Ts'o's instructions anyways.

Another thing I did is leave 20% of the drive unpartitioned. I've often read that SSDs are faster the more free space they have so I figured that limiting myself to 80% of the drive should help the drive maintain its peak performance over time. In fact, I've heard that extra unused unpartitionable space is one of the main differences between the value and extreme series of Intel SSDs. I'd love to see an official confirmation of this from Intel of course!

Keeping the RAID1 array in sync with the SSDOnce I added the solid-state drive to my computer and copied my root partition on it, I adjusted my fstab and grub settings to boot from that drive. I also setup the following cron job (running twice daily) to keep a copy of my root partition on the old RAID1 drives (mounted on /mnt):
nice ionice -c3 rsync -aHx --delete --exclude=/proc/* --exclude=/sys/* --exclude=/tmp/* --exclude=/home/* --exclude=/mnt/* --exclude=/lost+found/* --exclude=/data/* /* /mnt/

Tuning the SSDFinally, after reading this excellent LWN article, I decided to tune the SSD drive (/dev/sda) by adjusting three things:


Is there anything else I should be doing to make sure I get the most out of my SSD?

3 October 2010

Michal &#268;iha&#345;: Configuring system for SSD

I decided to upgrade my notebook to SSD disk. The disk replacement went easy, installed fresh Debian on it and now comes the tricky part how to properly tune system to use as much as SSD can provide. The first obvious thing for me is changing IO scheduler. But which one to choose? Most of howtos seem to suggest noop or deadline, without stating benefits of each. For now I've chosen deadline, without string coninfidence, that I'm doing the right thing. The next major part of tips includes removing filesystem journalling. Well I think journalling exists for good reason and disabling it won't help me much (no, I really don't want to wait for fsck after each crash). The last tweak seems to be using tmpfs for any temporary data (/tmp) or even for logs. For /tmp it might make sense, on cost of loosing available memory (or swapping it out, what really does not help the SSD anyway). However I definitely don't want to loose my logs on every reboot. Maybe I'm missing some bit, but the only important thing seems to be the IO scheduler.
Filed under: Debian Linux 5 comments Flattr this

11 September 2010

Iustin Pop: New harddrive: WD6000HLHX

While SSDs are all the rage nowadays (and for good reason), I don't trust them yet for my important storage, as I'm not familiar with their failure behaviour. So when one of my hard-drives recently started misbehaving, I bought the new WD Raptor model. Since some people might be interested in how it performs in some synthetic tests under Linux, here are some fio results. Now, I admit that 10K RPM for desktop is a want versus need discussion, but nevertheless, these hard-drives are (for their capacity) quite affordable, compared to SSDs, and faster than a regular 7200 RPM drive. So:
# smartctl -i /dev/ 
 
Device Model:     WDC WD6000HLHX-01JJPV0
Serial Number:    WD-WXA1C20U0627
Firmware Version: 04.05G04
User Capacity:    600,127,266,816 bytes
The older hard-drive I'm comparing to is also a WD Raptor, the WD3000GLFS model (yes, I'm a sucker for shiny hardware). A few of the SMART capabilities seems to have changed (e.g. a new Phy Event Counter has been added, CRC errors within host-to-device FIS, and the SCT Status Version is now 3 instead of 2, the Temperature History Size is now 478 instead of 128), but nothing significantly different that I can see. First, the IOPS test: nothing changed here. To be honest, even the WD3000 model had pretty good performance. The fio job definition is:
[global]
filename=$ DRIVE 
iodepth=$ IODEPTH 
bs=$ BS 
ramp_time=10
runtime=120
[rate-iops]
rw=randread
ioscheduler=noop
ioengine=libaio
direct=1
I did tests for block sizes of 512 and 4096 bytes (but the results were so close that I only used the 512 bytes ones), and at queue depths of 1, 2, 4, 8, 16 and 24 (not 32 as AFAIK the SATA protocol only allows a max queue depth of 31, and I wanted to test only the drive's queue). So: IOPS graph As I said, nothing really changed, but starting at 130 IOPS and reaching more than 200 IOPS at queue depth 8 (which again, is not so much used at home) is nice. Next, the bandwidth tests. This uses the standard disk-zone-profile job shipped with fio:
[global]
bs=64k
direct=1
rw=read
ioengine=libaio
iodepth=2
zonesize=256m
zoneskip=2g
write_bw_log
[disk_zoning]
filename=$ DRIVE 
Here the changes are significant. Whereas the previous generation topped at around 110MB/s, the new model tops at over 140MB/s: Bandwidth graph I'm not sure what makes the old model vary so much at the start of the test (I repeated the measurement twice, and it looks the same), but in any case, there a few conclusions to be drawn: So, I can say I'm pretty happy. The 300GB model was a tiny bit too small for me, but the new size is great, and it seems the sequential read/write speed is also good. Let's see how long they will last though, HDD failures are (unwanted) friends of mine

Next.

Previous.
