Search Results: "ag"

5 March 2009

Sami Haahtinen: Debian Xen dom0 Upgrade woes

I finally decided that it's time for me to upgrade my Xen installation. It used to run etch with backported Xen, because the etch version was increasingly difficult to work with. I also acknowledge that some of the issues I've been having are simply caused by yours truly, but even still the Debian Xen installation is way too fragile to my taste. I've already considered installing XenServer Express locally and running the hosts on it. The big drawback has been that XenCenter (the tool that is used to manage XenServer) is windows only and it doesn't work with wine. So you can imagine my desperation... Anyway, the latest upgrade from etch to lenny was painful as usual. The first part went smoothly, bit of sed magic on sources.list and a few upgrade commands (carefully picking the Xen packages out of the upgrade set). So in the end I had a working lenny installation with backported Xen. Next I made sure that there was nothing major going on in my network (one of the virtual machines acts as my local firewall) and took a deep breath before upgrading the rest of the packages. I knew to be careful about xendomains -script which has reliably restored my virtual machines after reboot to a broken host so I had always ended up restarting my virtual machines after reboot. I carefully cleared XENDOMAINS_AUTO and set XENDOMAINS_RESTORE to false in /etc/default/xendomains so that the virtual machines would be saved but not restored or restarted on reboot. After the normal pre-boot checks I went for it. Oddly enough everything worked normally and the system came up after a bit of waiting. I checked the bridges and everything appeared normal, so it was time to try and restore a single domain to see that everything actually did work as planned.
Hydrogen:~# xm restore /var/lib/xen/save/Aluminium
Error: Device 0 (vif) could not be connected. Hotplug scripts not working.

Oof, Googling for the issue revealed that there were others that had suffered from the same problem on various different platforms the problems were caused by different things. One would assume that the problem is in the vif-bridge script that is mentioned in the xend-config.sxp file as the script that brings up the vif, but after many hours of tial and error and pointless googling (over gprs connection), I couldn't find any solution to the problem. It was time to call it a day (it was almost 3 am already...) During the night I had a new idea about the possible cause. What if the problem isn't in xend, but somewhere else. I fired up udevadm monitor to see what udev saw and it wasn't much. I'm not an expert with udev, but from previous encounters I had a vague feeling that there was supposed to be more events flying around. I wasn't able to pinpoint what was wrong so I decided to purge xen-utils, of which I had 2 versions installed: 3.2-1 and 3.0.2. I also removed everything related to xenstore. After reinstalling the current versions and restoring my configuration files the first host came up just fine. I still had problems resuming the virtual machines and I ended up rebooting them again, which was nothing new, but at least they were running again. In the end I don't know what was the actual cause for udev not handling the devices properly, but I'm happy to have them all running again. And I learned a valuable lesson of all this: udev is an important part of Xen, make sure it works properly.
Decklin Foster: You're talking about things I haven't done yet

I've been converting all my Mercurial repositories to Git. One of the motivations for this was hg's poor handling of branches and tags: branches are just another metadata field on a commit, and tags are entries in a text file called .hgtags that is tracked in the repository(!). Git has its flaws as well, but I prefer its view that branches and tags are just refs, which are pointers that exist at the repository level and are pushed or pulled around in much the same way as the objects they refer to. The excellent hg-to-git.py script included in contrib created Git tags corresponding to my old Mercurial tags, but of course didn't modify the actual commits. So I still had a .hgtags file in my Git repository, and a boilerplate commit of the form "Add tag foo for changeset bar" each time I added to it (recall that .hgtags is just another file. Thankfully, I never had to deal with two branches where I added different tags...). I wanted to remove these. Git has a 'filter-branch' command that can totally rewrite or expunge commits; this is of course a horrible idea for already published code, but there's no harm in using while initially preparing a repository. While I appreciate git's object model and speed, I must agree with its detractors that the user interface is terrible. It took some tinkering to get git-filter-branch to do what I wanted, so I'm writing this to save my notes for next time (and in case someone else is searching for how to do this). Here's the command I arrived at:
git filter-branch \
    --tag-name-filter cat \
    --index-filter 'git update-index --remove .hgtags'
    --commit-filter \
        'if [ $# = 3 ] && git diff-tree --quiet $1 $3; then
             skip_commit "$@"
         else
             git commit-tree "$@"
         fi' \
    HEAD
The tag name filter is always necessary if you want tags to be updated to point to the corresponding commits on the new, rewritten branch. I consider this a UI failure -- when a branch is rewritten, the ref is modified, and the old one moved to refs/original. Tags, on the other hand, stay where they are, without any indication on the new branch that this is where you might want to move that old tag and sign it again or whatever. IMHO they ought to be handled the same as branches. The index filter is simply an efficient way of removing the unwanted file from all commits. This and the tag filter are both covered in the manual page. Writing a commit filter is a little more obscure. After .hgtags is removed from the index, we may end up at one of those useless "Added tag foo" commits and have no changes to record in the commit. By default, of course, filter-branch still records these -- the commit message might be useful, or something. But I want to suppress them. The commit filter is called with a tree -- you're at the point between write-tree and commit-tree (I recommend Git from the bottom up if you're confused here.) It gets that tree ($1), and then "-p PARENT" for each parent, just like commit-tree. So, if this is a normal commit with one parent, there will be 3 arguments. (If there's only one argument, there is no parent, i.e., the first commit, and if there are more, then it's a merge.) This is the only case we want to mess with. If there are no changes between our tree and the parent's tree, then it's one of those no-op commits, and we can skip it (skip_commit, a shell function defined by filter-tree, uses some deep magic to hand us the original parent again next time). I think diffing the index and the parent would work as well, but this seemed clearer. It still feels like a hack, so I'd love to hear from anyone who can suggest improvements. Since this is a special case, maybe it's better off being implemented in hg-to-git.py itself. There's always more than one way to do it. Update: Teemu Likonen points out that the next version of Git (1.6.2, not yet in unstable) will have a --prune-empty option which makes this particular problem totally trivial. I am starting to get the feeling that the Git developers are all reading our minds... :-)

Martin F. Krafft: Don't get fooled by the cost-average effect

I have a bit of money invested in stocks and funds, passively managed by my bank. I ve made a bit with risky speculations, and I ve lost about the same amount with the markets dive of the last 18 months. Net benefit: zero cash, a bit of experience. Time to move on I am not an interesting customer, so I was all the more surprised to get a call from an employee of the bank the other day. He identified himself as Crisis Manager or something similarly ridiculous, mentioned at least 20 times that he was a regular employee and wouldn t receive provisions, and he also kept assuring me that he s doing himself what he s suggesting to me: leveraging the cost-average effect. I turned him down, probably a bit too briskily. Let s investigate why. Banks are good at devising ingenious tricks to fool people; it s their business after all. One of those tricks is the so-called cost-average effect. It s awesome, they say, because it is the first product that adapts to the ever-changing market: when prices are up, it buys smaller numbers of shares, and in low times, it stocks up on them by buying larger quantities, automatically. Fancy, no? It isn t, because the entire idea is to get your signature on a contract that obliges you to pay a fixed sum each month, with which shares are then bought. Obviously, when prices are up, numbers you get for your money are low, and vice versa. Observe how well the banks manage to turn that basic rule into a selling point. They are good at that. In fact, that s probably all they re good at. Obviously , inflation is also factored in, so the monthly fixed sum actually increases by a projected 5% each year, which they call inflation protection . While this strategy investing fixed-sum installments rather than lump sums certainly has its benefits, and can level out the risk of throwing a large sum of money at the market, it is commonly considered a suboptimal strategy, especially when employed over longer spans of time. For more information, I refer you to the frequently cited article Nobody gains from dollar cost averaging analytical, numerical and empirical results , published in the 1992/1993 issue of the Financial Services Review journal. So why would the bank approach me with this offer ? Let s go hypothetical and check out Ashley s investment practices: Ashley bought a fund five years ago at 100 per share, and it s now down to 80 . The loss is thus 20%, a -4% factor (20% / 5 years) that affects the overall performance of the portfolio. Ashley doesn t really care much about the percentages. After all, the only thing that counts is the worth of the shares when sold right now. Everything else is history and only influences the size of the tears one weeps in times like this, which is a psychological malfunction, not a function of the financial markets crisis. The bank, however, does not like negative performance values. Positive percentages yield happy (blinded?) customers, who get much more enthusiastic (greedy?) to put more money into the giant machine that makes the banks tick which is still in the process of blowing up into their faces. But negative performance values cause investors to become conservative and leery. They d rather hold on to their hard-earned cash for fear of losing more. That s the flip-side of aforementioned psychological malfunction, and this is the core of the reason why some of the big investors get bigger even in times like this they do not succomb to the feeling . The banks, however, need cash, and loads of it, and while the state is busy printing notes, they take every chance to get more. Private clients are wonderful prey, as they are less informed about the system than investors. So, to get cash from the clients, the banks have to circumvent the psychological malfunction. They cannot boost the market value share, but there are two values that factor into a percentage, and the cost-average effect, sold as the best thing since sliced bread, is nothing but a way to affect the other number: the sale price, the divisor. If the fund stays below the original sale price (100 ), each time Ashley pumps more cash into the machinery each month, this divisor decreases, effectively decreasing the percentage value. In the long run, this yields happier customers, who are willing to put more money in, especially if the performance turns positive. The baseline is now lower, so a return to previous heights would correspond to larger performance values than ever before. Obviously, a positive market causes the baseline to grow, but the cost-average deals continues to pay off for the banks. Since Ashley put that signature on the contract, the bank has a guaranteed cash flow for the contract s duration, while Ashley wonders why the percentage remains dampened. Cost-average means decreasing the percentage, in good as well as in bad times. Just now, the bank doesn t have to work so hard to get even more money from you. It gets worse: usually, those contracts are embedded in some sort of life insurance deals with grand promises in 40 years to come, and over all that time, it ll be quite clear who wins and who loses. Scary, huh? I was going to end with the advice to stay away from the cost-average effect, but I think I can just as well make it more general: if you don t understand a deal, don t sign it. If you abide by that rule, you would stay away from cost-average effect deals all by yourself. Maybe my little writeup has helped, nonetheless. NP: DJ Ti sto: Live at Innercity
Eddy Petrișor: Glest: how upstream can be a real dick

At some point in the past, when I was still thinking that Glest can be packaged in a sane way, I had a conversation with upstream developer martinho on the Glest forum (they call it board) about them integrating a patch in order to support big endian machines.

After some messages on their board, it was clear that they don't want to integrate any patches and started to throw out random fake arguments against the integration of my patch and other patches.

When he figured out that I replied and debunked all of his fake arguments, he went on and actually removed my posts from the forum. It was so weird since I have never seen that kind of behaviour before and some of his posts and other people's posts were replies to my posts and things didn't made any sense after the deletion.

At that moment I have managed to save one small bit of the conversation via Google's cache, but now I have finally decided to make it public.


Note: Back then, I kept this post private in the hope that I was maybe too involved in the conversation at that moment to make a rational decision about it, and hoped things would get better in time. They didn't. Meanwhile they migrated to another forum software and they said they lost most/all(?) of the previous content from the old forum.


Here is the conversation bit I managed to save.
Original text is in italic font. Regular font is for my current comments for clearing up the context of the discussion. The text retains the BB syntax and [quote]-d text is martinho's own words.


[quote="martinho"]thebohemian, eddyd,

I think you guys are missing the point, this is not the place for any [/quote]

Congrats, you are avoiding to answer the points I have raised.

[quote]
- The Glest project is made by a bunch of friends for fun, we ask for nothing, we answer to no one. So I beg you not co complain, because it is out of order.
[/quote]

In that case I don't see the point of the "development" forum. care to explain?
And, from my PoV, these are your users you're arrogantly dismissing.


The following was a reply to my request to add big endian support through a patch I provided at that time. The patch wasn't complete to actually make glest work on BE machines, but it didn't broke little endian support at all. He was trying to argue that there were no valid big endian machines on which the game would run. Integrating the patch would have made my life a lot easier in continuing the work on the patch.

[quote]
- Our target plarforms are PCs running Windows (I'm responsible for this) or Linux (matze is the boss here). We don't care if Glest doesn't run in a big endian dishwasher with Solaris.
[/quote]

Linux on PowerPC is a viable platform. So is Mac OS X on PowerPC.


I made the mistake of saying that some parts of the code where not that clean and could be improved. More on that below.

[quote]
- One of the keys of Glest success is how extremely clean our code is. Bringing random people in would break this, and we are not going to do it. [/quote]

So you are the only keepers of true knowledge of clean code? Hahahaha!

There were at least 3 patches that provided this through word/double-word swapping. I don't see how embedding the patch can affect the unity of the code.

BTW, you are aware you can "carve" people into coding in your style before accepting in, aren't you?


I suggested using int8, uint8, int16, uint16 in order to make sure that the parameters are of the expected fixed size since plain char, int, long, long long have different sizes depending on the architecture. The usage of int and int16 was inconsistent and I also suggested using always the numbered variants.

I said the approach that was then taken in code was not portable and that was the reason for the proposed change.

[quote]
- Glest has been coded with portability in mind, some of your comments about portability are really naive (compilers don't care if you declare function parameters with fixed byte length, they just use whatever is the fastest int in the platform). Fixed length data types are used when needed,
[/quote]

What? When did I say anything about that? I said the code uses inconsistently "int" and "int16" and should use the later always because the code assumes the sizes on i386, which are not always applicable - see long on amd64.


If you mean that I can't enforce the width of the parameter, then you should know better, those types are defined in a platform dependent way to be platform independent. Yes, there are cases where [b]on the stack[/b] the size of the passed data is bigger (they might be padded), but that is transparent to the functions and, in spite of that, the functions will see the proper values for the parameters.

Also, the packing behaviour is compiler and architecture dependent, and some compilers produce the weirdest packing (if you are allowed access to such docs, look for Green Hills compilers' for V850 and you'll be stunned).


Please, don't make a fool of yourself by trying to discredit me, just not to loose face.

Later he just removed my posts not to loose face.


As a sane programmer, I made my patch to do the swapping only on big endian platforms, and the code was enabled in through the precompiler, so there was no performance hit on the little endian arches.

Of course, any more-than-newbie programmer would agree that having two data sets for a single game is stupid and is better to do the swapping in the application itself to avoid space wastage and maintaing an alternate big endian data set.

[quote]
no more, no less. About endianness, we don't care. If we wanted to fix the problem anyway, the right way is to do the byte swap in the data, this is how it is done in commercial games, since it is more efficient.
[/quote]

You just proved how much bullshit you can deliver in one phrase just for the sake of winning an argument. All portable games and all applications that have data files prefer to do swapping on the spot just because swapping the data on the disk (or providing BE and LE data) is plain stupid and inefficient from a disk and bandwidth PoV.

For Glest, swapping the data after reading from disk is not even affecting performance in a manner that could be significant or noticed, not even for a processor running at 500MHz, since that would be done only on load, once, and just for the bits of data which are relevant; these are mostly headers, since the actual data, in most cases, is just a long byte vector. This translates in not more than 3 or 4 instructions in assembler (an init, an exchange, an increment and/or a loop instruction), and that would happen before starting a game, which is dead time anyway and wouldn't be noticed unless the data would be huge (order of hundreds of MB or GB) and the whole data set would need swapping.

Even if the data itself (not headers) represents data which needs to be swapped, that is still irrelevant in terms of speed.


BTW, the reason that in commercial games it might be done like that is because there the games are distributed in a package per platform anyway and having two data sets is not an issue since they are using the same amount of CDs/DVDs, but doing the same for a game like Glest would mean doubling the storage used and it would increase the complexity for a release, not to count the confusion of the users.

I still doubt commercial games do this, but I might be wrong.

Colin Watson: Bug triage, redux

I've been a bit surprised by the strong positive response to my previous post. People generally seemed to think it was quite non-ranty; maybe I should clean the rust off my flamethrower. :-) My hope was that I'd be able to persuade people to change some practices, so I guess that's a good thing. Of course, there are many very smart people doing bug triage very well, and I don't want to impugn their fine work. Like its medical namesake, bug triage is a skilled discipline. While it's often repetitive, and there are lots of people showing up with similar symptoms, a triage nurse can really make a difference by spotting urgent cases, cleaning up some of the initial blood, and referring the patient quickly to a doctor for attention. Or, if a pattern of cases suddenly appears, a triage nurse might be able to warn of an incipient epidemic. [Note: I have no medical experience, so please excuse me if I'm talking crap here. :-)] The bug triagers who do this well are an absolute godsend; especially when they respond to repetitive tasks with tremendously useful pieces of automation like bughelper. The cases I have trouble with are more like somebody showing up untrained, going through everyone in the waiting room, and telling each of them that they just need to go home, get some rest, and stop complaining so much. Sometimes of course they'll be right, but without taking the time to understand the problem they're probably going to do more harm than good. Ian Jackson reminded me that it's worth mentioning the purpose of bug reports on free software: namely, to improve the software. The GNU Project has some advice to maintainers on this. I think sometimes we stray into regarding bug reports more like support tickets. In that case it would be appropriate to focus on resolving each case as quickly as possible, if necessary by means of a workaround rather than by a software change, and only bother the developers when necessary. This is the wrong way to look at bug reports, though. The reason that we needed to set up a bug triage community in Ubuntu was that we had a relatively low developer-to-package ratio and a very high user-to-developer ratio, and we were getting a lot of bug reports that weren't fleshed out enough for a developer to investigate them without spending a lot of time in back-and-forth with the reporter, so a number of people volunteered to take care of the initial back-and-forth so that good clear bug reports could be handed over to developers. This is all well and good, and indeed I encouraged it because I was personally finding myself unable to keep up with incoming bugs and actually fix anything at the same time. Somewhere along the way, though, some people got the impression that what we wanted was a first-line support firewall to try to defend developers from users, which of course naturally leads to ideas such as closing wishlist bugs containing ideas because obviously those important developers wouldn't want to be bothered by them, and closing old bugs because clearly they must just be getting in developers' way. Let me be clear about this now: I absolutely appreciate help getting bug reports into a state where I can deal with them efficiently, but I do not want to be defended from my users! I don't have a basis from which to state that all developers feel the same way, but my guess is that most do. Antti-Juhani Kaijanaho said he'd experienced most of these problems in Debian. I hadn't actually intended my post to go to Planet Debian - I'd forgotten that the "ubuntu" category on my blog goes there too, which generally I see as a feature, but if I'd remembered that I would have been a little clearer that I was talking about Ubuntu bug triage. If I had been talking about Debian bug triage I'd probably have emphasised different things. Nevertheless, it's interesting that at least one Debian (and non-Ubuntu) developer had experienced similar problems. Justin Dugger mentions a practice of marking duplicate bugs invalid that he has problems with. I agree that this is suboptimal and try not to do it myself. That said, this is not something I object to to the same extent. Given that the purpose of bugs is to improve the software, the real goal is to be able to spend more time fixing bugs, not to get bugs into the ideal state when the underlying problem has already been solved. If it's a choice between somebody having to spend time tracking down the exact duplicate bug number versus fixing another bug, I know which I'd take. Obviously, when doing this, it's worth apologising that you weren't able to find the original bug number, and explaining what the user can do if they believe that you're mistaken (particularly if it's a bug that's believed to be fixed); the stock text people often use for this doesn't seem informative enough to me. Sebastien Bacher commented that preferred bug triage practices differ among teams: for instance, the Ubuntu desktop team deals with packages that are very much to the forefront of users' attention and so get a lot of duplicate bugs. Indeed - and bug triagers who are working closely with the desktop team on this are almost certainly doing things the way the developers on the desktop team prefer, so I have no problem with that. The best advice I can give bug triagers is that their ultimate aim is to help developers, and so they should figure out which developers they need to work with and go and talk to them! That way, rather than duplicating work or being counterproductive, they can tailor their work to be most effective. Everybody wins.

Eddy Petrișor: Glest fuckyou: From the book of 'we want people to think we're open'

The Glest FAQFuckYou says (emphasis is mine):

[..] as a rule of thumb we don t integrate any patches in our mainline, since that would require us to check them first and then maintain them, however feel free to post them at the board.


Glest development sucks. I really hope Glest Advanced Engine effort takes speed and replaces Glest.

This is the main reason I don't feel any incentive to maintain this package in Debian.

Russell Coker: SE Linux Lenny Status Update

I previously described four levels of SE Linux support on the desktop [1]. Last night I updated my APT repository of SE Linux packages for Lenny (as described on my document about installing SE Linux [2]). I included a new policy package that supports logging in to a graphical session via gdm in either unconfined_t or user_t. This covers all the functionality I described as target 2 (some restricted users). I have tested this to a moderate degree. Target 3 was having all users restricted and no unconfined_t domain (the policy module unconfined.pp not being linked into the running policy). I had previously done a large part of the work towards that goal in preparation for running a SE Linux Play Machine (with public root password) [3] on Lenny - but until last night I had not published it. The combination of the policy needed to run with no unconfined_t domain and the policy to allow logging in as user_t via gdm should mean that a desktop system with gdm for graphical login that has no unconfined_t domain will work - but I have not tested this. So target 3 is likely to have been achieved, if testing reveals any problems in this regard then I ll release another policy update. So now the only remaining target is MLS. Also I have been setting up a mail server with a MySQL database for user account data and using Courier-Maildrop for delivery, so I ve written policy for that and also made some other improvements to the policy regarding complex mail servers.

4 March 2009

Uwe Hermann: Building an ARM cross-toolchain with binutils, gcc, newlib, and gdb from source

I've been planning to write about building custom ARM toolchains for a while (I used stuff from gnuarm.com in the past, but I switched to the lastest and greatest upstream versions at some point). Among other things, recent upstream versions now have ARM Cortex support. First you will need a few base utilities and libs:
  $ apt-get install flex bison libgmp3-dev libmpfr-dev autoconf texinfo build-essential
Then you can use my tiny build-arm-toolchain script, which will download, build, and install the whole toolchain:
  $ cat build-arm-toolchain
  #!/bin/sh
  # Written by Uwe Hermann <uwe@hermann-uwe.de>, released as public domain.
  TARGET=arm-elf                         # Or: TARGET=arm-none-eabi
  PREFIX=/tmp/arm-cortex-toolchain       # Install location of your final toolchain
  PARALLEL="-j 2"                        # Or: PARALLEL=""
  BINUTILS=binutils-2.19.1
  GCC=gcc-4.3.3
  NEWLIB=newlib-1.17.0
  GDB=gdb-6.8
  export PATH="$PATH:$PREFIX/bin"
  mkdir build
  wget -c http://ftp.gnu.org/gnu/binutils/$BINUTILS.tar.bz2
  tar xfvj $BINUTILS.tar.bz2
  cd build
  ../$BINUTILS/configure --target=$TARGET --prefix=$PREFIX --enable-interwork --enable-multilib \
    --with-gnu-as --with-gnu-ld --disable-nls
  make $PARALLEL
  make install
  cd ..
  rm -rf build/* $BINUTILS $BINUTILS.tar.bz2
  wget -c ftp://ftp.gnu.org/gnu/gcc/$GCC/$GCC.tar.bz2
  tar xfvj $GCC.tar.bz2
  cd build
  ../$GCC/configure --target=$TARGET --prefix=$PREFIX --enable-interwork --enable-multilib \
    --enable-languages="c" --with-newlib --without-headers --disable-shared --with-gnu-as --with-gnu-ld
  make $PARALLEL all-gcc
  make install-gcc
  cd ..
  rm -rf build/* $GCC.tar.bz2
  wget -c ftp://sources.redhat.com/pub/newlib/$NEWLIB.tar.gz
  tar xfvz $NEWLIB.tar.gz
  cd build
  ../$NEWLIB/configure --target=$TARGET --prefix=$PREFIX --enable-interwork --enable-multilib \
    --with-gnu-as --with-gnu-ld --disable-nls
  make $PARALLEL
  make install
  cd ..
  rm -rf build/* $NEWLIB $NEWLIB.tar.gz
  # Yes, you need to build gcc again!
  cd build
  ../$GCC/configure --target=$TARGET --prefix=$PREFIX --enable-interwork --enable-multilib \
    --enable-languages="c,c++" --with-newlib --disable-shared --with-gnu-as --with-gnu-ld
  make $PARALLEL
  make install
  cd ..
  rm -rf build/* $GCC
  wget -c ftp://ftp.gnu.org/gnu/gdb/$GDB.tar.bz2
  tar xfvj $GDB.tar.bz2
  cd build
  ../$GDB/configure --target=$TARGET --prefix=$PREFIX --enable-interwork --enable-multilib
  make $PARALLEL
  make install
  cd ..
  rm -rf build $GDB $GDB.tar.bz2
The final toolchain is located in /tmp/arm-cortex-toolchain per default, and is ca. 170 MB in size. I explicitly created the build script in such a way that it minimizes the amount of disk space used during the build (ca. 1.2 GB or so, compared to more than 3 GB in the "naive" approach). Using the "-j 2" option for make (see script) you can speed up the build quite a bit on multi-core machines (ca. 30 minutes vs. 60 minutes on an AMD X2 dual-core box). Also, you can change the script to build for other target variants if you want to (arm-elf or arm-none-eabi, for example). Checkout the blog entry How to build arm gnu gcc toolchain for Mac OS X by Piotr Esden-Tempski for similar instructions for Mac OS X users. Oh, and while I'm at it does anybody have any idea why there are no pre-built toolchains for embedded (microcontroller) ARM targets in Debian? There are some toolchains for other microcontroller architectures (avr, m68hc1x, h8300, z80) but not too much other stuff. Is there some specific reason for the missing ARM toolchains (other than "nobody cared enough yet")? I have heard about Emdebian, but from a quick look that seems to be more intended for toolchains with Linux/libc, not for microcontroller firmware (i.e. no MMU, no Linux, no libc etc.), but maybe I'm wrong?

Gintautas Miliauskas: Peer reviewed blogging

Here's an idea: what if there was a website where you could upload a topical blog post, which would then be reviewed and edited by experts in the area and then posted on that website? Such a process would ensure that articles are at least well-named, appropriately tagged, well-structured and not methodologically deficient, and could result in a database of articles of decent quality. Would you upload your blog posts that are juicier in terms of content to such a site? Would you volunteer to do reviews and editing?
Jose Carlos Garcia Sogo: Innovation in netbooks

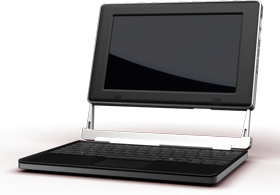
After the release of Asus Eee PC and the discovery of the market that was eager to buy cheap and wearable computers every laptop manufacturer has jumped into the hype and released their own versions of netbooks, with different success.
But somehow it was a cloning phase. Vendors were just cloning what Asus did, with more or less changes, but without innovating. Now, it seems that the path has opened again, from the open source and open hardware front, and it has been released AlwaysInnovating s touchbook. It is a netbook with a detachable keyboard (it is even sold separated) and built upon an ARM processor from Texas Instruments, and a 8GB microSD card. Thus they claim the battery last from 10 to 15h with the keyboard, and 3 to 5h in touchscreen mode.
As is said above, the whole machine is open source based. Software is based upon OpenEmbedded, and hardware schematics of the board are released under GPL on Beagleboard project. They say that you can also install Ubuntu, Android or even Windows CE on it. Update: Just discovered that AlwaysInnovating is a Gr goire Gentil startup. Gr gory is a Civil Engineer from cole des ponts et Chauss es. We know how to build things :-D

Russell Coker: You Have the Right to Not Search My Bag

This afternoon I was in a Safeway/Woolworths store (an Australian supermarket chain) and the lady on the checkout asked to inspect my backpack on the way out. The conversation went as follows:
Checkout Lady: Can I inspect your bag?
Me: Sure. - I put my backpack on the counter
CL: Could you open it for me?
Me: It s OK, you can do it.
CL: I m not allowed to open your bag, can you open it?
Me: I don t mind, you can open it. We iterated over the last two lines a few times, when it became clear that no progress was going to be made I asked Can I go now? and left. It seems rather pointless to demand to search someone s bag if you are not permitted to open it. Not that they have any power to search bags anyway. I discussed this with a police officer about 20 years ago and was told that store staff can do nothing other than refuse to allow you into their store in future if you don t agree to a bag search. Stores claim that it s a condition of entry that your bag be searched, but apparently that was not enforceable. Of course the law could have changed recently, I guess it would only require a terrorist threat related to supermarket products (baking soda can make your bread rise explosively) to get the law changed. The last time my bag was searched was when leaving a JB Hi-Fi store. I had a brand new EeePC (purchased from a different store) in one hand and a bag in the other. The EeePC was identical to ones that they had on display and they didn t even ask about it. It seems hardly worth the effort of searching bags when anyone can carry out expensive gear in their hand without being questioned.

Dirk Eddelbuettel: RQuantLib 0.2.11

The changes in Rcpp that I blogged about a few days ago required a few small changes in RQuantLib. Not really much more that prefixing std:: in a number of variable declarations and a few member function calls -- so this is definitely a minor maintenance release. New source and binary packages have already been pushed to CRAN and Debian.

3 March 2009

Lucas Nussbaum: PhD !

This blog post is long overdue, but like Lenny, it was finally released. Yes, I defended my PhD thesis on December 4th. So I m officially a Doctor from the Universit Joseph Fourier Grenoble. The general context of my thesis is distributed systems, like peer-to-peer systems and applications running on HPC (High Performance Computing) cluster and grids. More specifically, I worked on methods and tools to study such systems, trying to answer the following questions: take a given application that will run on a distributed system. What can we learn or verify about its performance or its characteristics? Will it scale well, even with 1000 or 10000 nodes? Does this app perform better than this another app? Under which conditions? (that s probably the hardest question, because you need to be able to run both apps under the same conditions if you want a fair comparison!) My work involved studying basic building blocks that can be used to study distributed systems, like network emulators (Dummynet, Linux s traffic control subsystem, NISTNet). I also designed P2PLab, which allows to emulate network-centric peer-to-peer systems using a cluster, targetting experiments with thousands of emulated instances of the application. For example, it allowed to run experiments with ~15000 emulated BitTorrent nodes using 160 real machines. So what s next? Well, my first-priority plan is to make use of my PhD to apply to an academic position (maitre de conf rences, i.e assistant professor). If you know an open position where I would be a good fit, don t hesitate to tell me! Of course, this plan might very well fail (I will know around end of June). In that case, I ll probably be looking for a job, likely Free-Software-related. Again, if you hear of something for me, ping me!

Vincent Fourmond: Weird crash with linux 2.6.26

I've had a rather funny crash for the second time now. It goes like this: the interface is freezing (processing event extremely slowly), it is nearly impossible to do anything (but apparently, everything works, just extremely slowly !). Kernel keep on saying this:
Mar  3 18:56:50 tanyaivinco kernel: [ 2385.443069] hdd: status timeout: status=0xd0   Busy  
Mar  3 18:56:50 tanyaivinco kernel: [ 2385.443069] ide: failed opcode was: unknown
Mar  3 18:56:56 tanyaivinco kernel: [ 2393.777714] hdd: status timeout: status=0xd0   Busy  
Mar  3 18:56:56 tanyaivinco kernel: [ 2393.777714] ide: failed opcode was: unknown
Mar  3 18:57:01 tanyaivinco kernel: [ 2398.982260] hdd: status timeout: status=0xd0   Busy  
Mar  3 18:57:01 tanyaivinco kernel: [ 2398.982260] ide: failed opcode was: unknown
One of the funny things is that this time like the previous one, at the beginning of the problem, there is always this kernel message, for which I could find no documentation:
Mar  3 18:56:35 tanyaivinco kernel: [ 2367.012218] Clocksource tsc unstable (delta = 4686267423 ns)
If anyone ever came across this, or has clue, I'm interested !

Uwe Hermann: How to use the full size of your (x)term when connecting to some other box serially with minicom

minicom terminal size 1 Just as a reminder for myself, as I'll probably need this more often in the future (and maybe it's helpful for others): Per default, if you use a big xterm (232x74 in my case) where you start minicom, the $COLUMNS and $LINES environment variables will be 80x24 nevertheless, and those applications which honor them (vim, for example) will be too small and not use the full xterm size of 232x74.
  $ minicom
  $ echo $COLUMNS; echo $LINES
  80
  24
minicom terminal size 2 You can fix that like this:
  $ eval  resize 
  $ echo $COLUMNS; echo $LINES
  232
  74
After you do eval resize the variables are updated and vim will use the full xterm size. That's all.

Miguel Gea: My .dupload.conf file

I've prepared a private autobuilder. As I've setup the incoming using scp, I don't need to gpg sign each package. But dupload complained saying that the package is not gpg signed. Lurking in dupload code, I found It's possible overriding the default preupload for my default host:

package config;

$default_host = "eragon";
$cfg 'eragon' =
fqdn => "eragon",
method => "scp",
incoming => "/data/autobuilder/incoming/unstable",
# files pass on to dinstall on ftp-master which sends emails itself
dinstall_runs => 1,
;

$cfg 'eragon' preupload 'changes' = '/bin/true';
1;

Jon Dowland: sorting out backups

I'm busy re-working how I handle backups of my personal files. A very useful recent discussion on some available features and technologies is at Theodore T'so's blog: http://thunk.org/tytso/blog/2009/01/12/wanted-incremental-backup-solutions-that-use-a-database/. From that post I discovered a package 'archfs' which provides a FUSE-powered filesystem view of an rdiff-backup history. I found a stale ITP for this package and have adopted it, so keep your eyes out for that. Looking at how I am going to approach things, I think the Debian package of anacron might need some work. I'm planning on looking at the issues there a bit more closely and feeding back to the maintainer when I do.

Asheesh Laroia: Segmentation grace

Ladies and gentlemen, it seems that Google has finally done it: they shipped Multics for 386 (and compatible). NoiseBridge, this evening: I descended the stairs after teaching my introduction to programming class and found Geoff Schmidt in our San Francisco hacker space. I sat next to Geoff and overheard a lovely conversation with Mike Kan. Geoff told the sad tale of a beautiful, efficient, and dead operating system: Multics. Multics was written in the 1960s as a fast operating system for many users to share an expensive mainframe. It posed design problems never seriously tackled before, and after a decade, it had a practically perfect implementation for each of them. To achieve speed, it expected help from the hardware: registers on the processor split memory into different "segments," creating safe zones for each program to run in. The segment system was powerful and secure enough that a running process could execute code from another without the operating system kernel getting involved. The result was a fantasy come true: protection rings creating legendary security, the flexibility of a multi-user, multi-tasking operating system, and all this at hardly any performance overhead. (Naturally, such perfection is the result of years of work at MIT. So is Geoff.) This perfection came at a price: while Multics was uniquely well-designed and well-integrated, it expected specific support from the hardware it ran on. Geoff's expression deflated, and he pointed out that another operating system arrived on the scene: UNIX. Anyone could study the UNIX source code, and it ran on whatever you gave it. UNIX (a joke on the name Multics) eventually won by being worse: it was slow, unreliable, and worst of all: incorrect. But anyone could read it and make it work on the computer he happened to have. By the mid-1970s, UNIX's dominance over Multics was clear. Geoff skipped forward a decade to the 1980s. Intel had wanted to build a CPU that could be used as a modern computer, and users had shown that the puny memory protection system offered by the 286 wasn't adequate. The chip designers went back to the drawing board, and they brought back features that Multics invented: segmentation registers and protection rings. When shown these powerful, complex features, today's operating systems mostly ignore these Multics tricks and do the least work possible to build a UNIX-like flat memory model. Mike interrupted and howled about how he can't buy a "real Macintosh" anymore; Apple's computers were once based on a simple architecture, but now they are built with the same complex Intel CPUs everyone else uses. But I am writing this because of the release of Google Native Client, a browser extension that allows your computer to securely run machine code written by untrusted people on the Internet. How can it achieve this fantasy? The Wikipedia article summarizes the native client research paper:
Native Client is notable for its novel sandboxing technique which makes use of the x86 architecture's rarely-used segmentation facility.

Michal &#268;iha&#345;: Thought about email footers

Have you ever thought what you send in email footer?
The information contained in this e-mail is private & confidential and may also be legally privileged. If you are not the intended recipient, please notify us, preferably by e-mail, and do not read, copy or disclose the contents of this message to anyone.
If I'm not the intended recipient (supposing I know how to guess this), how am I supposed to notify you, when I should not read the contents, so I should not know about fact that I should notify you?

Wouter Verhelst: GFDL 1.3

Yeah, yeah, I may be living under a rock these days. Anyway, I just noticed that the GFDL v1.3 is out; it has been for four months or so. There aren't many changes; apart from some minor wording changes that have little to no effect on the meaning of the license, there are two new sections: the first adds details on what happens when you violate the license (basically, it gets temporarily terminated, which can become permanent if you do not fix it in a reasonable timeframe or under some other circumstances); the second allows one to change the license from GFDL to CC-BY-SA under certain circumstances (where "certain circumstances" in practice basically means "you're wikipedia", although it isn't written as such). And that's it. Nothing groundbreaking, nothing to follow up on the FDLv2 discussion drafts that were released about two-and-a-half years ago. Me, I find that disappointing. When the initial discussion drafts were put out on the web, I was thrilled; I spent some time reading them and providing comments. However, nothing happened on those drafts beyond initially getting them out there. It would appear that today, the FSF has even managed to lose the comments that were made. I guess they don't really care about the FDL as much as they do about the GPL.

Next.

Previous.